# base14 Scout > Reduce downtime drastically! This file contains all documentation content in a single document following the llmstxt.org standard. ## Getting Started with base14 Scout, OpenTelemetry Native Observability Platform Pick the path that matches your environment and goals. Each track is designed for a quick win and a clear next step. ### I want a 5-minute setup - [5-Minute Quick Start](/guides/quick-start) - [Hello World - Send Your First Trace](/instrument/apps/hello-world) ### I am deploying a collector - [Docker Compose](/instrument/collector-setup/docker-compose-example) - [Kubernetes Helm](/instrument/collector-setup/kubernetes-helm-setup) - [OpenTelemetry Operator](/instrument/collector-setup/opentelemetry-operator-setup) - [Linux](/instrument/collector-setup/linux-setup) - [Otel Binary](/instrument/collector-setup/otel-collector-binary-example) ### I need application instrumentation - [Auto-instrumentation overview](/instrument/apps/auto-instrumentation) - [Custom instrumentation overview](/instrument/apps/custom-instrumentation) - [Node.js](/instrument/apps/auto-instrumentation/nodejs) - [Go](/instrument/apps/auto-instrumentation/go) - [Java](/instrument/apps/custom-instrumentation/java) - [Python](/instrument/apps/auto-instrumentation/fast-api) ### I need infrastructure telemetry - [AWS ECS](/instrument/collector-setup/ecs-setup) - [Kubernetes](/instrument/collector-setup/kubernetes-helm-setup) - [Docker](/instrument/collector-setup/docker-compose-example) ### I want to use the CLI - [Install Scout CLI](/scout-cli/installation) - [Generate an OTel Collector config](/scout-cli/otel-config/config-init) - [Validate a collector config](/scout-cli/otel-config/config-validate) - [Query logs, traces, and metrics](/scout-cli/scout-access/logs) ### I want CI/CD observability - [GitHub Actions Observability](/guides/cicd-observability/github-actions-observability) ### I want to explore data in Scout - [traceX](/operate/tracex) - [LogX](/operate/logx) - [Create Your First Dashboard](/guides/create-your-first-dashboard) --- ## AI Agent Observability with OpenTelemetry - Tracing Multi-Agent Systems and Tool Calls ## AI Agent Observability Instrument AI agents with OpenTelemetry to trace the **whole conversation** - model calls, tool invocations, agent handoffs, and the downstream API and database work each decision triggers - in a single correlated view. An agent is not a single LLM call. It is a loop: the model reasons, calls a tool, reads the result, calls another agent, and eventually answers. When that loop misbehaves - a tool times out, a sub-agent returns garbage, a retry storm burns tokens - the LLM is rarely the root cause. The failure lives in the tool call, the handoff, or the downstream service. To debug it you need telemetry that spans the entire agent execution, not just the chat completion. This guide is the framework-agnostic companion to the language-specific [LLM Observability](./llm-observability.md) guides. It focuses on the **agent layer**: the spans, attributes, and conventions that turn a scattered set of LLM calls into a coherent agent timeline. Code samples use the OpenTelemetry Python SDK, but every pattern is portable - the attribute names are the [OpenTelemetry GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/), so the same telemetry works with any OpenTelemetry backend, including base14 Scout. ![AI agent timeline showing one conversation across an orchestrator, a billing sub-agent, tool calls, and downstream Stripe and database spans](/img/docs/agent-timeline.svg) :::tip TL;DR Bind every span an agent produces - LLM calls, tool calls, sub-agent handoffs, and downstream HTTP and database work - with three attributes: `gen_ai.conversation.id`, `gen_ai.agent.name`, and `gen_ai.operation.name`. Emit `invoke_agent` spans for agent steps and `execute_tool` spans for tool calls, and thread the conversation ID through the whole call stack. The result is a single agent timeline in base14 Scout that shows exactly where an agent run spent time and where it failed. ::: :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### AI Agent Observability Overview This guide shows you how to: - Model an agent run as a conversation-level timeline, not isolated LLM calls - Use the GenAI agent operation types (`invoke_agent`, `execute_tool`, `create_agent`, `chat`) - Bind every span in a run with `gen_ai.conversation.id` and propagate it to downstream HTTP, database, and queue work - Instrument tool calls with the `gen_ai.tool.*` attributes and proper error handling - Trace Model Context Protocol (MCP) tool calls as `execute_tool` spans - Trace multi-agent orchestration and handoffs so each agent gets its own swim lane - Record agent metrics and evaluation results for cost, latency, and quality - Handle content capture, PII, and the experimental semantic-convention opt-in ### Who This Guide Is For This documentation is designed for: - **AI engineers**: building tool-using or multi-agent systems and needing to see why a run was slow, expensive, or wrong - **Backend developers**: embedding agents into existing services and wanting agent spans correlated with HTTP and database telemetry - **Platform teams**: standardizing agent observability across frameworks (LangGraph, custom orchestration, MCP servers) on one open standard - **DevOps and SRE**: operating agents in production with cost, error-rate, and quality alerting ### Prerequisites This guide builds on the base OpenTelemetry setup covered elsewhere. Before starting, ensure you have: - A working OpenTelemetry SDK setup (tracer and meter providers, OTLP exporter). See [LLM Observability](./llm-observability.md) for the Python bootstrap, or the [Rust](./rust-llm-observability.md) and [Java](./spring-ai-llm-observability.md) guides for those stacks. - **Scout Collector** configured and reachable from your application - See [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../instrument/collector-setup/kubernetes-helm-setup.md) for production - Auto-instrumentation for your web framework and HTTP client, so downstream work joins the trace automatically. See [Auto-Instrumentation](../../instrument/apps/auto-instrumentation/index.md). - Familiarity with GenAI spans for LLM calls (the `chat` operation). This guide extends that model to the agent and tool layers. #### Compatibility Matrix | Component | Minimum Version | Recommended | | ----------------------- | --------------- | ----------- | | opentelemetry-sdk | 1.39.0 | 1.39+ | | opentelemetry-api | 1.39.0 | 1.39+ | | GenAI semantic conv. | 1.36 (baseline) | 1.37+ | | Python (samples) | 3.12 | 3.13+ | ### The Agent Timeline The core idea of agent observability is that **a GenAI span is not just an LLM call**. When an agent decides to call a tool, that tool might query a database, hit a third-party API, or enqueue a background job. All of that work is part of the same agent run and belongs in the same trace. Three attributes bind an agent run together. Set them on **every** span the run produces: | Attribute | Purpose | | ----------------------- | --------------------------------------------- | | `gen_ai.conversation.id`| Shared ID linking all operations in a run | | `gen_ai.agent.name` | Which agent produced the span | | `gen_ai.operation.name` | What kind of operation the span represents | With those in place, a single agent run reads as one timeline: ```text showLineNumbers title="Agent timeline for one conversation" POST /chat 6.1s [auto: HTTP] └─ invoke_agent orchestrator 6.0s [agent] ├─ chat claude-sonnet-4 1.2s [LLM: plan] ├─ execute_tool search_orders 0.9s [tool] │ └─ db.query SELECT orders 18ms [auto: DB] ├─ invoke_agent billing 2.4s [handoff] │ ├─ chat claude-sonnet-4 1.1s [LLM] │ └─ execute_tool issue_refund 1.2s [tool] │ └─ HTTP POST api.stripe.com 1.1s [auto: httpx] └─ chat claude-sonnet-4 1.3s [LLM: final answer] ``` Every span above carries the same `gen_ai.conversation.id`. The auto-instrumented `db.query` and `HTTP POST` spans join the trace because they run inside the tool-call span's context - so a slow refund shows up as a slow Stripe call under a specific tool under a specific agent, not as an unattributed blip somewhere in the system. ### Agent Operation Types The GenAI semantic conventions define `gen_ai.operation.name` values that classify each span. Use them consistently - backends and dashboards group and filter on this attribute. | `gen_ai.operation.name` | Span represents | | ----------------------- | ------------------------------------------------ | | `create_agent` | Creating/registering an agent (e.g. Assistants) | | `invoke_agent` | One agent taking a turn or being handed control | | `chat` | An LLM chat completion | | `execute_tool` | A tool or function call made by an agent | | `embeddings` | Generating vector embeddings | | `generate_content` | A multimodal content-generation call | Most agent frameworks only need `invoke_agent`, `chat`, and `execute_tool`. Use `create_agent` for remote agent services (OpenAI Assistants, AWS Bedrock Agents) where agent creation is a distinct, observable step. ### Instrumenting the Agent Layer Framework auto-instrumentation (LangChain callbacks, provider instrumentors) usually owns the `chat` spans. You own the **agent-layer** and **conversation-layer** attributes. A good division of labor: > Let the framework instrumentation own the LLM-layer spans, and you own the > agent-layer and conversation-layer attributes. #### The invoke_agent Span Wrap each agent turn in an `invoke_agent` span that carries the three binding attributes. This is the parent under which the agent's LLM and tool spans nest: ```python showLineNumbers title="agent.py - invoke_agent span" from opentelemetry import trace tracer = trace.get_tracer("gen_ai.agent") async def run_agent(agent_name, state, conversation_id): """Run one agent turn under an invoke_agent span.""" with tracer.start_as_current_span( f"invoke_agent {agent_name}" ) as span: # The three binding attributes span.set_attribute( "gen_ai.operation.name", "invoke_agent" ) span.set_attribute("gen_ai.agent.name", agent_name) span.set_attribute( "gen_ai.conversation.id", conversation_id ) # Optional agent metadata span.set_attribute("gen_ai.agent.id", state.agent_id) result = await agent_logic(state) span.set_attribute( "gen_ai.response.finish_reasons", [result.finish_reason], ) return result ``` #### Threading the Conversation ID The conversation ID is only useful if it reaches **every** span, including downstream HTTP clients, database queries, and queue workers. Because those spans are auto-instrumented and created deep in library code, you cannot set the attribute on them directly. Two portable options: 1. **Set it at the root and read it back.** Store the conversation ID on the first span of the run, and have your agent code re-read it and set it on each child span it creates. 2. **Propagate it as baggage.** OpenTelemetry [baggage](https://opentelemetry.io/docs/concepts/signals/baggage/) travels with the context across async boundaries and process hops. A span processor can then copy it onto every span, including auto-instrumented ones. The baggage approach keeps the conversation ID flowing without threading it through every function signature: ```python showLineNumbers title="conversation.py - baggage + span processor" from opentelemetry import baggage, context from opentelemetry.sdk.trace import SpanProcessor def set_conversation(conversation_id): """Attach the conversation ID to the current context.""" return context.attach( baggage.set_baggage( "gen_ai.conversation.id", conversation_id ) ) class ConversationSpanProcessor(SpanProcessor): """Copy the conversation ID from baggage onto every span.""" def on_start(self, span, parent_context=None): conversation_id = baggage.get_baggage( "gen_ai.conversation.id", parent_context ) if conversation_id: span.set_attribute( "gen_ai.conversation.id", conversation_id ) ``` Register `ConversationSpanProcessor` on the tracer provider alongside your `BatchSpanProcessor`. Now the auto-instrumented `db.query` and `HTTP POST` spans carry the conversation ID too, and the whole run stays linked. > **Note**: Baggage is propagated over the wire via the `baggage` HTTP header. > Do not put secrets or PII in baggage - treat the conversation ID as an opaque > correlation key. ### Tool Call Observability Tool calls are **where most agentic failures live**. A model that picks the wrong tool, passes malformed arguments, or mishandles a tool error will fail even when every `chat` span looks healthy. Instrument tool calls as first-class `execute_tool` spans. #### The execute_tool Span ```python showLineNumbers title="tools.py - execute_tool span" import json from opentelemetry import trace tracer = trace.get_tracer("gen_ai.tool") async def call_tool(tool, arguments, call_id): """Run a tool under an execute_tool span.""" with tracer.start_as_current_span( f"execute_tool {tool.name}" ) as span: span.set_attribute( "gen_ai.operation.name", "execute_tool" ) span.set_attribute("gen_ai.tool.name", tool.name) span.set_attribute("gen_ai.tool.call.id", call_id) span.set_attribute( "gen_ai.tool.description", tool.description ) # Arguments and result capture PII - see PII section span.set_attribute( "gen_ai.tool.call.arguments", json.dumps(arguments)[:2000], ) try: result = await tool.run(**arguments) except Exception as e: span.record_exception(e) span.set_attribute("error.type", type(e).__name__) raise span.set_attribute( "gen_ai.tool.call.result", json.dumps(result)[:2000], ) return result ``` #### Tool Call Attribute Reference | Attribute | Type | Required | Description | | ----------------------------- | ------ | ----------- | ------------------------- | | `gen_ai.operation.name` | string | Yes | Always `"execute_tool"` | | `gen_ai.tool.name` | string | Recommended | Tool/function name | | `gen_ai.tool.call.id` | string | Recommended | Unique ID for this call | | `gen_ai.tool.description` | string | Recommended | What the tool does | | `gen_ai.tool.type` | string | Recommended | `function`, `extension` | | `gen_ai.tool.call.arguments` | string | Opt-in | JSON arguments (PII risk) | | `gen_ai.tool.call.result` | string | Opt-in | JSON result (PII risk) | | `error.type` | string | Conditional | Exception class on failure| Setting `error.type` and recording the exception is what lets base14 Scout highlight the failing tool in the timeline and lets you query for the tools that fail most often. #### MCP Tools The [Model Context Protocol (MCP)](https://modelcontextprotocol.io/) is a common way for agents to reach external tools. An MCP `tools/call` is just a tool invocation, so model it as an `execute_tool` span with the same `gen_ai.tool.*` attributes, adding MCP-specific context: ```python showLineNumbers title="mcp_tools.py - MCP call as execute_tool" with tracer.start_as_current_span( f"execute_tool {tool_name}" ) as span: span.set_attribute("gen_ai.operation.name", "execute_tool") span.set_attribute("gen_ai.tool.name", tool_name) span.set_attribute("gen_ai.tool.type", "function") # MCP context span.set_attribute("mcp.server.name", server_name) span.set_attribute("mcp.method.name", "tools/call") result = await mcp_session.call_tool(tool_name, arguments) ``` Because the MCP client's transport is auto-instrumented, the underlying HTTP or stdio call nests under this span automatically - so a slow or failing MCP server is attributed to the exact tool the agent invoked. If you run your own MCP server with Scout, see the [Scout MCP guides](../../scout-mcp/setup.md) for setup and usage. ### Multi-Agent Orchestration In a multi-agent system, one agent hands control to another: an orchestrator calls a specialist, a planner delegates to a worker. Two rules keep these handoffs readable in the timeline. #### Rule 1: The Caller Emits the Handoff Span The **calling** agent emits the `invoke_agent` span for the agent it invokes - not the agent being called. This makes orchestration explicit: the span sits under the orchestrator, so the timeline shows who delegated to whom. ```python showLineNumbers title="orchestrator.py - handoff ownership" async def orchestrator(state, conversation_id): with tracer.start_as_current_span( "invoke_agent orchestrator" ) as span: span.set_attribute( "gen_ai.operation.name", "invoke_agent" ) span.set_attribute( "gen_ai.agent.name", "orchestrator" ) span.set_attribute( "gen_ai.conversation.id", conversation_id ) # The orchestrator emits the handoff span for "billing" with tracer.start_as_current_span( "invoke_agent billing" ) as handoff: handoff.set_attribute( "gen_ai.operation.name", "invoke_agent" ) handoff.set_attribute( "gen_ai.agent.name", "billing" ) handoff.set_attribute( "gen_ai.conversation.id", conversation_id ) return await billing_agent(state) ``` The `billing` agent then emits its own `chat` and `execute_tool` spans under its own `gen_ai.agent.name`, so its work appears in the billing swim lane. #### Rule 2: Every Agent Gets a Distinct Name Give each agent - including sub-agents - a distinct `gen_ai.agent.name`. Spans that omit it collapse into an `Unknown` swim lane, and you lose the ability to tell which agent did what or attribute cost per agent. When you fan out to parallel sub-agents, name each one. ### Agent Metrics Agent runs need the same GenAI metrics as LLM calls, dimensioned by agent and tool so you can answer "which agent is slowest?" and "which tool fails most?". Reuse the metric definitions from the [LLM Observability guide](./llm-observability.md#token-and-cost-tracking) and add agent/tool attributes when recording: | Metric | Type | Key attributes | | ---------------------------------- | --------- | ---------------------------------- | | `gen_ai.client.token.usage` | Histogram | `gen_ai.agent.name`, model | | `gen_ai.client.operation.duration` | Histogram | `gen_ai.operation.name`, agent | | `gen_ai.client.cost` | Counter | `gen_ai.agent.name`, model | | `gen_ai.client.error.count` | Counter | `gen_ai.tool.name`, `error.type` | Recording `gen_ai.agent.name` on both spans and metrics lets you build `sum(gen_ai.client.cost) by (gen_ai.agent.name)` to find your most expensive agent, and `sum(gen_ai.client.error.count) by (gen_ai.tool.name)` to find your flakiest tool. ### Evaluation and Quality Agent quality - did it use the right tool, was the final answer correct, did it hallucinate - is a first-class observability concern. Attach evaluation results as `gen_ai.evaluation.result` events on the relevant span: ```python showLineNumbers title="eval.py - evaluation event" span.add_event( "gen_ai.evaluation.result", attributes={ "gen_ai.evaluation.name": "tool_selection", "gen_ai.evaluation.score.value": 1.0, "gen_ai.evaluation.score.label": "correct", }, ) ``` Record the same score as a `gen_ai.evaluation.score` histogram to track quality trends over time. See the [evaluation section of the LLM Observability guide](./llm-observability.md#evaluation-and-quality-metrics) for the metric definition and dashboard patterns. ### Content Capture, PII and Security The richest agent-debugging attributes also carry the most sensitive data: - `gen_ai.input.messages` / `gen_ai.output.messages` - full prompts and responses - `gen_ai.system_instructions` - your system prompt - `gen_ai.tool.call.arguments` / `gen_ai.tool.call.result` - tool inputs and outputs These **capture PII and sensitive data by default when enabled**. Protect them: - **Keep content capture off by default.** Enable it deliberately, and prefer non-production environments for full capture. - **Redact at the application layer** before setting attributes, and truncate long payloads (2000 characters is a practical limit). - **Redact at the collector** with the [`redaction`](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/processor/redactionprocessor) or `attributes` processor as a safety net, so sensitive fields never reach the backend. #### Enabling the Latest GenAI Conventions The GenAI semantic conventions are still under active development. Newer instrumentations gate the latest attribute shapes behind an environment variable so existing pipelines do not break: ```bash showLineNumbers title="Terminal" export OTEL_SEMCONV_STABILITY_OPT_IN=gen_ai_latest_experimental ``` Set this when you want the current message and tool-call attribute formats. Without it, instrumentations default to the transition baseline. Pin your collector and backend expectations to the same convention version. ### Production Configuration Agents send telemetry to a local OpenTelemetry Collector, which authenticates to base14 Scout and forwards traces, metrics, and logs. Point your application at the collector with `OTEL_EXPORTER_OTLP_ENDPOINT`, and configure the collector to export to Scout: ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 redaction: allow_all_keys: true blocked_values: - "[0-9]{16}" # credit card numbers - "[\\w.]+@[\\w.]+" # email addresses batch: timeout: 10s send_batch_size: 1024 send_batch_max_size: 2048 exporters: otlphttp/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true debug: verbosity: basic service: extensions: [health_check, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, redaction, batch] exporters: [otlphttp/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, redaction, batch] exporters: [otlphttp/b14, debug] ``` The `redaction` processor in the traces and logs pipelines strips sensitive values from captured content before it leaves your environment. For the full collector reference and deployment options, see [OpenTelemetry Collector Setup](../../instrument/collector-setup/otel-collector-config.md). ### Troubleshooting #### Common Issues ##### Issue: Spans show an "Unknown" agent A span is missing `gen_ai.agent.name`, so the backend cannot assign it to a swim lane. **Solutions:** 1. Set `gen_ai.agent.name` on every `invoke_agent`, `chat`, and `execute_tool` span the agent produces 2. For sub-agents, give each a distinct name - do not reuse the parent's 3. Verify the attribute is set before the span ends, not after ##### Issue: The conversation does not link end to end LLM and tool spans appear, but downstream HTTP and database spans are not part of the same conversation. **Solutions:** 1. Confirm `gen_ai.conversation.id` is set on the root agent span 2. If using baggage, verify `ConversationSpanProcessor` is registered on the tracer provider and that baggage is attached to the active context 3. Ensure downstream calls run **inside** the agent span's context so they inherit the trace ##### Issue: Tool spans are missing Tool calls do not appear as `execute_tool` spans. **Solutions:** 1. Wrap tool execution explicitly - framework auto-instrumentation covers LLM calls but often not custom tools 2. Check that the tool wrapper runs inside the `invoke_agent` span's context 3. For MCP tools, ensure the transport (HTTP/stdio) instrumentation is enabled so the underlying call nests under the `execute_tool` span ### Performance Considerations Agent instrumentation overhead is negligible next to model and tool latency. A tool call or LLM completion takes hundreds of milliseconds to seconds; span creation adds microseconds. - **Span creation**: ~1-5 microseconds per span - **Attribute setting**: ~0.5 microseconds per attribute - **Baggage propagation**: negligible; a single small header - **Content capture**: the main cost - large argument/result payloads inflate span size, so truncate and gate capture behind a flag ### FAQ #### What is the difference between LLM observability and agent observability? LLM observability traces individual model calls - model, tokens, cost, latency. Agent observability traces the **whole run**: the loop of LLM calls, tool calls, and sub-agent handoffs, plus the downstream work each triggers, all bound by a conversation ID. Agent failures usually live in the tool calls and handoffs, not the model call - which is exactly what the agent layer makes visible. #### Do I need an agent framework to get agent observability? No. The conventions are framework-agnostic. Whether you use LangGraph, another framework, or hand-rolled orchestration, you emit `invoke_agent` and `execute_tool` spans with the GenAI attributes. Frameworks with OpenTelemetry support give you some spans for free; you still own the conversation ID and agent names. #### How do I trace multi-agent handoffs? The calling agent emits the `invoke_agent` span for the agent it delegates to, and every agent uses a distinct `gen_ai.agent.name`. This produces one swim lane per agent and makes the delegation structure explicit in the timeline. #### Are MCP tool calls traced? Yes. Model an MCP `tools/call` as an `execute_tool` span with the `gen_ai.tool.*` attributes plus MCP context (`mcp.server.name`, `mcp.method.name`). The auto-instrumented transport nests the underlying call under that span. #### Can I see the arguments an agent passed to a tool? Yes, via `gen_ai.tool.call.arguments` and `gen_ai.tool.call.result`. These capture PII by default, so redact and truncate them, keep capture off in production unless needed, and add a collector redaction processor as a backstop. #### How do I find the most expensive or slowest agent? Record `gen_ai.agent.name` on both spans and metrics, then query `sum(gen_ai.client.cost) by (gen_ai.agent.name)` for cost and `histogram_quantile` over `gen_ai.client.operation.duration` grouped by agent for latency. ### What's Next? #### Language-Specific Guides - [LLM Observability (Python)](./llm-observability.md) - full Python setup with FastAPI, LangGraph, and multi-provider LLMs - [Rust LLM Observability](./rust-llm-observability.md) - manual GenAI instrumentation in Rust - [Java AI Observability](./spring-ai-llm-observability.md) - Spring AI with the three-layer instrumentation model #### Framework Guides - [LangGraph Instrumentation](../../instrument/apps/auto-instrumentation/langgraph.md) \- node wrapping, conditional routing, tool-calling nodes - [LlamaIndex Instrumentation](../../instrument/apps/auto-instrumentation/llamaindex.md) \- RAG, structured output, self-correction loops - [Vercel AI SDK Instrumentation](../../instrument/apps/auto-instrumentation/vercel-ai-sdk.md) \- TypeScript multi-stage agent pipelines #### Scout Platform Features - [Monitor AI agents in Scout](https://base14.io/scout/llm-observability) - track token usage, tool failures, and agent latency - [Creating Alerts](../creating-alerts-with-logx.md) - alert on tool error rates, cost spikes, or evaluation regressions - [Create Your First Dashboard](../create-your-first-dashboard.md) - build agent cost and reliability dashboards ### References - [Instrumenting AI Agents with OpenTelemetry (Honeycomb)](https://www.honeycomb.io/blog/instrumenting-ai-agents-agent-timeline-opentelemetry-guide) - [Inside the LLM Call: GenAI Observability with OpenTelemetry](https://opentelemetry.io/blog/2026/genai-observability/) - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [OpenTelemetry GenAI Agent Spans](https://opentelemetry.io/docs/specs/semconv/gen-ai/gen-ai-agent-spans/) - [Model Context Protocol](https://modelcontextprotocol.io/) ### Related Guides - [LLM Observability][llm-o11y] - the Python end-to-end foundation this guide builds on - [LangGraph Instrumentation][langgraph] - framework-specific agent tracing - [Scout MCP Setup][scout-mcp] - run and observe an MCP server with Scout - [OpenTelemetry Collector Setup][collector] - full collector configuration - [Scout Exporter][scout-exporter] - configure base14 Scout authentication [llm-o11y]: ./llm-observability.md [langgraph]: ../../instrument/apps/auto-instrumentation/langgraph.md [scout-mcp]: ../../scout-mcp/setup.md [collector]: ../../instrument/collector-setup/otel-collector-config.md [scout-exporter]: ../../instrument/collector-setup/scout-exporter.md --- ## AI Observability Overview - LLM and Agent Instrumentation with OpenTelemetry ## AI Observability Instrument AI and LLM applications with OpenTelemetry to get **unified traces** that connect HTTP requests, agent orchestration, LLM API calls, and database queries in a single view. ### The Problem Traditional APM tools (Datadog, New Relic) capture HTTP and database telemetry. Specialized AI tools (LangSmith, Weights & Biases) capture LLM traces. Neither shows the full picture: | Tool Type | Captures | Misses | | ----------------- | ---------------------------------- | ---------------------------------------- | | Traditional APM | HTTP requests, DB queries, latency | Model name, tokens, cost, prompt content | | AI-specific tools | LLM calls, prompts, model metadata | HTTP context, DB queries, infrastructure | | **OpenTelemetry** | **All of the above in one trace** | - | With OpenTelemetry, a single trace shows that a slow HTTP response was caused by a specific LLM call in a specific agent, which also triggered 3 database queries and a fallback to a different provider. ### When to Use AI Observability | Use Case | Recommendation | | ------------------------------------------------ | ----------------------------------------------------------------------- | | Track LLM token usage and costs | AI Observability | | Monitor agent pipeline performance | AI Observability | | Evaluate LLM output quality over time | AI Observability | | Debug slow AI requests end-to-end | AI Observability | | Attribute costs to agents or business operations | AI Observability | | Standard HTTP/database monitoring only | [Auto-instrumentation](../../instrument/apps/auto-instrumentation/) | | Generic custom spans and metrics | [Custom instrumentation](../../instrument/apps/custom-instrumentation/) | ### Guides | Guide | What It Covers | | ----------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | | [AI Agent Observability](./agent-observability) | Framework-agnostic concepts and patterns: the agent timeline, GenAI operation types, conversation-id propagation, tool-call (`execute_tool`) instrumentation, MCP tools, multi-agent handoffs, agent metrics and evaluation | | [LLM Observability](./llm-observability) | End-to-end guide (Python): GenAI semantic conventions, token/cost metrics, agent pipeline spans, evaluation tracking, PII scrubbing, production deployment | | [Rust LLM Observability](./rust-llm-observability) | End-to-end guide (Rust): GenAI semantic conventions, multi-provider LLM with fallback, token/cost metrics, multi-stage pipeline spans, retry observability, Docker deployment | | [Spring AI LLM Observability](./spring-ai-llm-observability) | End-to-end guide (Java): Three-layer instrumentation (Java Agent + Spring AI + manual OTel), GenAI semantic conventions, tool calling, RAG, domain metrics, Docker deployment | | [LangGraph Instrumentation](../../instrument/apps/auto-instrumentation/langgraph) | Framework-specific: LangGraph node wrapping, conditional edge routing, tool-calling nodes, state management, pipeline traces | | [LlamaIndex Instrumentation](../../instrument/apps/auto-instrumentation/llamaindex) | Framework-specific: LlamaIndex structured output, self-correction loops, multi-provider LLM factory, YAML prompt management | | [Vercel AI SDK Instrumentation](../../instrument/apps/auto-instrumentation/vercel-ai-sdk) | Framework-specific: Vercel AI SDK v6 LanguageModelV3Middleware, multi-stage pipeline spans, concurrent stage execution, Bun + Hono + pgvector | ### What Gets Instrumented AI observability builds on top of auto and custom instrumentation, adding an LLM-specific layer: #### Auto-Instrumentation Layer (zero code changes) - **HTTP requests** via FastAPI/Django/Flask instrumentors (Python), tower-http TraceLayer (Rust), Java Agent (Spring WebFlux) - **Database queries** via SQLAlchemy/Django ORM instrumentors (Python), SQLx tracing (Rust), Java Agent (JDBC/R2DBC) - **Outbound HTTP** via httpx/requests instrumentors (Python), Java Agent (captures raw LLM API calls) - **Log correlation** via logging instrumentor (Python), OpenTelemetryTracingBridge (Rust), Java Agent (Logback/Log4j) #### Custom AI Layer (GenAI semantic conventions) - **LLM spans** with model, provider, token counts, cost - **Prompt/completion events** with PII scrubbing - **Agent spans** with pipeline orchestration context - **Tool-call spans** (`execute_tool`) with tool name, arguments, result, and error type - where most agentic failures live - **Multi-agent handoffs** bound by `gen_ai.conversation.id` so a full run reads as one timeline across agents and downstream services - **Evaluation events** with quality scores and pass/fail - **Cost metrics** with attribution by agent and business operation - **Retry/fallback tracking** with error type classification #### Example: Unified Trace ```text showLineNumbers title="Single trace spanning all layers" POST /api/generate 4.2s [auto: HTTP] ├─ db.query SELECT context 15ms [auto: DB] ├─ invoke_agent enrich 1.8s [custom: agent] │ └─ gen_ai.chat claude-sonnet-4 1.7s [custom: LLM] │ └─ HTTP POST api.anthropic.com 1.7s [auto: httpx] ├─ invoke_agent draft 2.3s [custom: agent] │ └─ gen_ai.chat claude-sonnet-4 2.2s [custom: LLM] │ └─ HTTP POST api.anthropic.com 2.2s [auto: httpx] └─ db.query INSERT result 5ms [auto: DB] ``` ### Key Concepts #### GenAI Semantic Conventions OpenTelemetry defines [GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) for standardized LLM telemetry. Key attributes: | Attribute | Example | Purpose | | ---------------------------- | ------------------- | --------------------- | | `gen_ai.operation.name` | `"invoke_agent"` | Operation type | | `gen_ai.provider.name` | `"anthropic"` | LLM provider | | `gen_ai.request.model` | `"claude-sonnet-4"` | Model used | | `gen_ai.usage.input_tokens` | `1240` | Tokens consumed | | `gen_ai.usage.output_tokens` | `320` | Tokens generated | | `gen_ai.conversation.id` | `"conv-8f2a"` | Binds a full agent run| | `gen_ai.agent.name` | `"draft"` | Agent in pipeline | | `gen_ai.tool.name` | `"search_orders"` | Tool an agent invoked | For the agent-specific attributes (`gen_ai.conversation.id`, `gen_ai.tool.*`, multi-agent handoffs), see the [AI Agent Observability guide](./agent-observability). #### GenAI Metrics Custom metrics for dashboards and alerting: | Metric | Type | Purpose | | ---------------------------------- | --------- | -------------------------------- | | `gen_ai.client.token.usage` | Histogram | Token consumption by model/agent | | `gen_ai.client.operation.duration` | Histogram | LLM call latency | | `gen_ai.client.cost` | Counter | Cost in USD by model/agent | | `gen_ai.evaluation.score` | Histogram | Output quality scores | | `gen_ai.client.error.count` | Counter | Errors by provider/type | ### Next Steps 1. **Follow the [LLM Observability guide](./llm-observability)** for a complete Python setup walkthrough 2. **Follow the [Rust LLM Observability guide](./rust-llm-observability)** for Rust AI applications with manual GenAI instrumentation 3. **Follow the [Spring AI LLM Observability guide](./spring-ai-llm-observability)** for Java Spring AI applications with three-layer instrumentation 4. **Set up [auto-instrumentation](../../instrument/apps/auto-instrumentation/)** for your web framework if you haven't already 5. **Configure the [OpenTelemetry Collector](../../instrument/collector-setup/docker-compose-example.md)** to export telemetry to base14 Scout --- ## LLM Observability with OpenTelemetry - Unified AI Application Tracing Guide ## LLM Observability Implement unified observability for AI and LLM applications using OpenTelemetry. This guide shows you how to trace every layer of an AI application - from HTTP requests through agent orchestration to LLM API calls and database queries - in a single correlated trace using the OpenTelemetry Python SDK and base14 Scout. AI applications introduce observability challenges that traditional APM tools were not designed for. An LLM call is not just an HTTP request - it carries semantic meaning: which model was used, how many tokens were consumed, what it cost, whether the output passed quality evaluation. Tools like LangSmith or Weights & Biases capture LLM-specific telemetry but operate in isolation, creating blind spots between your application layer (HTTP, database) and your AI layer (prompts, models, agents). OpenTelemetry bridges this gap with GenAI semantic conventions that let you capture LLM-specific context alongside standard application telemetry. Whether you are building AI agents with LangGraph, LangChain, or custom orchestration, instrumenting LLM calls from Anthropic, OpenAI, or Google, or trying to understand why your AI pipeline is slow and expensive, this guide provides production-ready patterns for unified AI observability. You will learn how to combine auto-instrumentation for HTTP and database layers with custom instrumentation for LLM calls, token tracking, cost attribution, and quality evaluation - all visible in a single trace on base14 Scout. ![LLM observability dashboard in Scout](/img/docs/llm-o11y.png) :::tip TL;DR Use OpenTelemetry GenAI semantic conventions to trace LLM calls with model, token, and cost attributes alongside auto-instrumented HTTP and database spans. This gives you a single trace from HTTP request through agent orchestration to LLM completion, with token tracking and cost attribution per provider and model. ::: :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### LLM Observability Overview This guide demonstrates how to: - Set up unified OpenTelemetry for an AI application (traces + metrics) - Use auto-instrumentation for HTTP, database, and external API layers - Create custom LLM spans following OpenTelemetry GenAI semantic conventions - Track token usage and calculate cost per LLM call - Attribute costs to specific agents and business operations - Instrument agent pipelines (LangGraph or custom) with parent-child spans - Record evaluation metrics for LLM output quality tracking - Scrub PII from prompts and completions before recording in telemetry - Deploy with Docker Compose and the OpenTelemetry Collector - Export traces and metrics to base14 Scout ### Who This Guide Is For This documentation is designed for: - **AI/ML engineers**: building LLM-powered features and needing visibility into model performance, cost, and quality - **Backend developers**: adding AI capabilities (chat, agents, RAG) to existing applications and wanting unified tracing - **Platform teams**: standardizing observability across AI services and traditional microservices - **Engineering teams**: migrating from LangSmith, Weights & Biases, or Helicone to open-standard observability with OpenTelemetry - **DevOps engineers**: deploying AI applications with production monitoring, cost alerting, and quality tracking ### Prerequisites Before starting, ensure you have: - **Python 3.12 or later** installed (3.13+ recommended) - **An LLM API key** from at least one provider (Anthropic, OpenAI, or Google) - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../instrument/collector-setup/kubernetes-helm-setup.md) for production deployment - Basic understanding of OpenTelemetry concepts (traces, spans, metrics) #### Compatibility Matrix | Component | Minimum Version | Recommended | | ----------------- | --------------- | ----------- | | Python | 3.12 | 3.13+ | | opentelemetry-sdk | 1.39.0 | 1.39+ | | opentelemetry-api | 1.39.0 | 1.39+ | | FastAPI | 0.115+ | 0.128+ | | SQLAlchemy | 2.0 | 2.0.45+ | | LangGraph | 0.2+ | 1.0.6+ | | Anthropic SDK | 0.40+ | 0.76+ | | OpenAI SDK | 1.0+ | 1.60+ | | Google GenAI SDK | 1.0+ | 1.59+ | ### The Unified Trace The core value of OpenTelemetry for AI applications is the **unified trace** - a single trace ID that connects every layer of a request, from HTTP entry to LLM completion and back. Here is what a trace looks like for an AI pipeline request: ```text showLineNumbers title="Unified trace for POST /campaigns/{id}/run" POST /campaigns/{id}/run 8.4s [auto: FastAPI] ├─ db.query SELECT connections 12ms [auto: SQLAlchemy] ├─ pipeline.run 8.3s [custom: pipeline] │ ├─ invoke_agent research 80ms [custom: agent] │ │ └─ db.query SELECT ... tsvector 45ms [auto: SQLAlchemy] │ ├─ invoke_agent enrich 2.1s [custom: agent] │ │ └─ gen_ai.chat claude-sonnet-4 2.0s [custom: LLM] │ │ └─ HTTP POST api.anthropic.com 1.9s [auto: httpx] │ ├─ invoke_agent score 1.8s [custom: agent] │ │ └─ gen_ai.chat claude-sonnet-4 1.7s [custom: LLM] │ │ └─ HTTP POST api.anthropic.com 1.7s [auto: httpx] │ ├─ invoke_agent draft 3.2s [custom: agent] │ │ └─ gen_ai.chat claude-sonnet-4 3.1s [custom: LLM] │ │ └─ HTTP POST api.anthropic.com 3.1s [auto: httpx] │ └─ invoke_agent evaluate 1.1s [custom: agent] │ └─ gen_ai.chat claude-sonnet-4 1.0s [custom: LLM] │ └─ HTTP POST api.anthropic.com 0.9s [auto: httpx] └─ db.query INSERT prospects 8ms [auto: SQLAlchemy] ``` Three types of spans work together: - **Auto-instrumented spans** (no code changes): FastAPI HTTP requests, SQLAlchemy database queries, httpx outbound HTTP calls - **Custom LLM spans**: Model name, token counts, cost, prompt/ completion events following GenAI semantic conventions - **Custom agent spans**: Pipeline orchestration, agent names, business context like campaign ID The auto-instrumented `httpx` span captures the raw HTTP call to `api.anthropic.com`. The custom `gen_ai.chat` span wraps it, adding LLM-specific context: which model, how many tokens, what it cost. The custom `invoke_agent` span wraps both, adding business context: which agent, which campaign. All three are children of the same trace. ### Installation Install the core OpenTelemetry packages and auto-instrumentation libraries: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash showLineNumbers title="Terminal" pip install \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging ``` ```mdx-code-block ``` ```bash showLineNumbers title="Terminal" uv add \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging ``` ```mdx-code-block ``` ```bash showLineNumbers title="Terminal" poetry add \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging ``` ```mdx-code-block ``` > **Note**: The `httpx` instrumentor is key for AI applications. Most Python LLM > SDKs (Anthropic, OpenAI) use httpx internally, so this instrumentor > automatically captures all LLM API calls at the HTTP level without any changes > to your LLM code. ### Auto-Instrumentation Setup Auto-instrumentation provides the foundation layer: HTTP spans, database spans, outbound API call spans, and log correlation. Set this up first - it requires no changes to your business logic. #### Telemetry Initialization ```python showLineNumbers title="telemetry.py" from opentelemetry import metrics, trace from opentelemetry.exporter.otlp.proto.http.metric_exporter import ( OTLPMetricExporter, ) from opentelemetry.exporter.otlp.proto.http.trace_exporter import ( OTLPSpanExporter, ) from opentelemetry.instrumentation.httpx import HTTPXClientInstrumentor from opentelemetry.instrumentation.logging import LoggingInstrumentor from opentelemetry.instrumentation.sqlalchemy import ( SQLAlchemyInstrumentor, ) from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import ( PeriodicExportingMetricReader, ) from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor def setup_telemetry(engine=None): """Initialize unified observability for traces and metrics.""" resource = Resource.create( { "service.name": "my-ai-service", "service.version": "1.0.0", "deployment.environment": "development", "environment": "development", } ) # Traces trace_provider = TracerProvider(resource=resource) trace_provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter( endpoint="http://localhost:4318/v1/traces" ) ) ) trace.set_tracer_provider(trace_provider) # Metrics metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter( endpoint="http://localhost:4318/v1/metrics" ), export_interval_millis=10000, ) metric_provider = MeterProvider( resource=resource, metric_readers=[metric_reader] ) metrics.set_meter_provider(metric_provider) # Auto-instrumentation HTTPXClientInstrumentor().instrument() LoggingInstrumentor().instrument(set_logging_format=True) if engine: SQLAlchemyInstrumentor().instrument( engine=engine.sync_engine ) return ( trace.get_tracer("my-ai-service"), metrics.get_meter("my-ai-service"), ) ``` #### Instrumenting FastAPI FastAPI instrumentation must be applied after the app is created: ```python showLineNumbers title="main.py" from fastapi import FastAPI from opentelemetry.instrumentation.fastapi import ( FastAPIInstrumentor, ) from my_app.telemetry import setup_telemetry # Initialize telemetry BEFORE creating the app tracer, meter = setup_telemetry(engine) app = FastAPI(title="My AI Service") # Instrument AFTER creation FastAPIInstrumentor.instrument_app(app) ``` #### What Auto-Instrumentation Captures | Instrumentor | Captures | | ------------ | -------------------------------------------- | | `FastAPI` | HTTP method, path, status code, duration | | `SQLAlchemy` | SQL statement, parameters, query duration | | `httpx` | Outbound URL, status, headers, duration | | `Logging` | Adds `trace_id` and `span_id` to log records | Auto-instrumentation alone gives you visibility into the application and infrastructure layers. But an LLM API call appears as a generic `HTTP POST` to `api.anthropic.com` - you cannot see the model name, token count, or cost. Custom instrumentation fills this gap. ### Custom LLM Instrumentation Custom instrumentation adds LLM-specific context to spans using OpenTelemetry GenAI semantic conventions. This is where AI observability diverges from standard APM. #### GenAI Span Attributes The OpenTelemetry GenAI semantic conventions define standard attributes for LLM operations. Using them ensures your telemetry works with any OpenTelemetry-compatible backend. The following example shows a provider-agnostic `generate` function with full GenAI span instrumentation. Each LLM provider returns token counts differently — the tabs below show the provider-specific response handling: ```python showLineNumbers title="llm.py - span setup (common to all providers)" from opentelemetry import trace tracer = trace.get_tracer("gen_ai.client") async def generate( prompt: str, system: str, model: str, provider: str, agent_name: str | None = None, campaign_id: str | None = None, ) -> str: """Generate LLM completion with full OTel instrumentation.""" with tracer.start_as_current_span( f"gen_ai.chat {model}" ) as span: # Required attributes (GenAI semconv) span.set_attribute("gen_ai.operation.name", "chat") span.set_attribute("gen_ai.provider.name", provider) # Conditionally required span.set_attribute("gen_ai.request.model", model) # Recommended span.set_attribute( "gen_ai.request.temperature", 0.7 ) span.set_attribute( "gen_ai.request.max_tokens", 1024 ) span.set_attribute( "server.address", "api.anthropic.com" ) # Business context (custom attributes) if agent_name: span.set_attribute( "gen_ai.agent.name", agent_name ) if campaign_id: span.set_attribute("campaign_id", campaign_id) # Call provider (see tabs below for response handling) response = await call_provider( provider, model, system, prompt ) # Record response attributes on span span.set_attribute( "gen_ai.response.model", response.model ) span.set_attribute( "gen_ai.usage.input_tokens", response.input_tokens, ) span.set_attribute( "gen_ai.usage.output_tokens", response.output_tokens, ) return response.content ``` ```mdx-code-block ``` ```python showLineNumbers title="providers/anthropic.py" from anthropic import AsyncAnthropic async def call_anthropic( model: str, system: str, prompt: str, temperature: float, max_tokens: int, ) -> LLMResponse: client = AsyncAnthropic(api_key=api_key) response = await client.messages.create( model=model, max_tokens=max_tokens, temperature=temperature, system=system, messages=[ {"role": "user", "content": prompt} ], ) content = "" if response.content: block = response.content[0] if hasattr(block, "text"): content = block.text return LLMResponse( content=content, input_tokens=response.usage.input_tokens, output_tokens=response.usage.output_tokens, model=response.model, response_id=response.id, finish_reason=response.stop_reason, ) ``` ```mdx-code-block ``` ```python showLineNumbers title="providers/openai.py" from openai import AsyncOpenAI async def call_openai( model: str, system: str, prompt: str, temperature: float, max_tokens: int, ) -> LLMResponse: client = AsyncOpenAI(api_key=api_key) response = await client.chat.completions.create( model=model, max_tokens=max_tokens, temperature=temperature, messages=[ {"role": "system", "content": system}, {"role": "user", "content": prompt}, ], ) choice = response.choices[0] if response.choices else None content = ( choice.message.content if choice and choice.message else "" ) usage = response.usage return LLMResponse( content=content or "", input_tokens=usage.prompt_tokens if usage else 0, output_tokens=( usage.completion_tokens if usage else 0 ), model=response.model, response_id=response.id, finish_reason=( choice.finish_reason if choice else None ), ) ``` ```mdx-code-block ``` ```python showLineNumbers title="providers/google.py" from google import genai from google.genai.types import GenerateContentConfig async def call_google( model: str, system: str, prompt: str, temperature: float, max_tokens: int, ) -> LLMResponse: client = genai.Client(api_key=api_key) config = GenerateContentConfig( system_instruction=system, temperature=temperature, max_output_tokens=max_tokens, ) response = await client.aio.models.generate_content( model=model, contents=prompt, config=config, ) content = response.text or "" usage = response.usage_metadata input_tokens = ( usage.prompt_token_count if usage and usage.prompt_token_count else 0 ) output_tokens = ( usage.candidates_token_count if usage and usage.candidates_token_count else 0 ) return LLMResponse( content=content, input_tokens=input_tokens, output_tokens=output_tokens, model=model, response_id=None, finish_reason=None, ) ``` ```mdx-code-block ``` #### GenAI Span Attribute Reference | Attribute | Type | Required | Description | | -------------------------------- | -------- | ----------- | ----------------------------- | | `gen_ai.operation.name` | string | Yes | Operation type: `"chat"` | | `gen_ai.provider.name` | string | Yes | Provider: `"anthropic"`, etc. | | `gen_ai.request.model` | string | Conditional | Model requested | | `gen_ai.response.model` | string | Recommended | Model actually used | | `gen_ai.usage.input_tokens` | int | Recommended | Input tokens consumed | | `gen_ai.usage.output_tokens` | int | Recommended | Output tokens generated | | `gen_ai.request.temperature` | float | Recommended | Sampling temperature | | `gen_ai.request.max_tokens` | int | Recommended | Max tokens requested | | `gen_ai.response.id` | string | Recommended | Provider response ID | | `gen_ai.response.finish_reasons` | string[] | Recommended | Why generation stopped | | `server.address` | string | Recommended | Provider API host | #### Prompt and Completion Events Record prompts and completions as span events for debugging. Always scrub PII before recording (see [PII and Security](#pii-and-security)): ```python showLineNumbers title="llm.py - recording events" # Before calling the LLM span.add_event( "gen_ai.user.message", attributes={ "gen_ai.prompt": scrub_prompt(prompt)[:1000], "gen_ai.system_instructions": scrub_prompt(system)[:500], }, ) # After receiving the response span.add_event( "gen_ai.assistant.message", attributes={ "gen_ai.completion": scrub_completion( response.content )[:2000], }, ) ``` > **Note**: Truncate prompts and completions to keep span sizes reasonable. 1000 > characters for prompts and 2000 for completions is a practical limit. #### Error Handling Record exceptions on spans and track error metrics: ```python showLineNumbers title="llm.py - error handling" try: response = await provider.generate( model=model, system=system, prompt=prompt, temperature=temperature, max_tokens=max_tokens, ) except Exception as e: span.record_exception(e) span.set_attribute( "error.type", type(e).__name__ ) error_counter.add( 1, { "gen_ai.provider.name": provider_name, "gen_ai.request.model": model, "error.type": type(e).__name__, }, ) raise ``` ### Token and Cost Tracking Token usage and cost are the most critical metrics for AI applications. Auto-instrumentation cannot capture these - the information is inside the LLM SDK response, not in HTTP headers. #### Defining GenAI Metrics ```python showLineNumbers title="llm.py - metric definitions" from opentelemetry import metrics meter = metrics.get_meter("gen_ai.client") token_usage = meter.create_histogram( name="gen_ai.client.token.usage", description="Tokens used per LLM call", unit="{token}", ) operation_duration = meter.create_histogram( name="gen_ai.client.operation.duration", description="Duration of GenAI operations", unit="s", ) cost_counter = meter.create_counter( name="gen_ai.client.cost", description="Cost of GenAI operations in USD", unit="usd", ) ``` #### Recording Token Usage Record input and output tokens separately for analysis: ```python showLineNumbers title="llm.py - recording tokens" base_attrs = { "gen_ai.operation.name": "chat", "gen_ai.provider.name": provider, "gen_ai.request.model": model, "gen_ai.response.model": response.model, "server.address": server_address, } # Separate input/output for per-direction analysis token_usage.record( response.input_tokens, {**base_attrs, "gen_ai.token.type": "input"}, ) token_usage.record( response.output_tokens, {**base_attrs, "gen_ai.token.type": "output"}, ) operation_duration.record(duration_seconds, base_attrs) ``` #### Cost Calculation and Attribution Define pricing per model and record costs with business context for attribution: ```mdx-code-block ``` ```python showLineNumbers title="pricing.py - Anthropic models" MODEL_PRICING = { "claude-opus-4-20250514": { "input": 15.0, "output": 75.0, }, "claude-sonnet-4-20250514": { "input": 3.0, "output": 15.0, }, "claude-haiku-3-5-20241022": { "input": 0.80, "output": 4.0, }, } ``` ```mdx-code-block ``` ```python showLineNumbers title="pricing.py - OpenAI models" MODEL_PRICING = { "gpt-4o": {"input": 2.50, "output": 10.0}, "gpt-4o-mini": {"input": 0.15, "output": 0.60}, "o1": {"input": 15.0, "output": 60.0}, "o1-mini": {"input": 1.10, "output": 4.40}, } ``` ```mdx-code-block ``` ```python showLineNumbers title="pricing.py - Google models" MODEL_PRICING = { "gemini-3-flash": {"input": 0.50, "output": 3.0}, "gemini-3-pro-preview": { "input": 2.0, "output": 12.0, }, "gemini-2.5-pro": { "input": 1.25, "output": 10.0, }, "gemini-2.5-flash": { "input": 0.30, "output": 2.50, }, } ``` ```mdx-code-block ``` All pricing is per million tokens. The cost calculation and metric recording is the same regardless of provider: ```python showLineNumbers title="llm.py - cost calculation" def calculate_cost( model: str, input_tokens: int, output_tokens: int ) -> float: """Calculate cost in USD for a model call.""" pricing = MODEL_PRICING.get( model, {"input": 0.0, "output": 0.0} ) return ( input_tokens * pricing["input"] + output_tokens * pricing["output"] ) / 1_000_000 # Record cost with business context cost = calculate_cost( model, response.input_tokens, response.output_tokens ) cost_attrs = {**base_attrs} if agent_name: cost_attrs["gen_ai.agent.name"] = agent_name if campaign_id: cost_attrs["campaign_id"] = campaign_id cost_counter.add(cost, cost_attrs) # Also record on span for per-request visibility span.set_attribute("gen_ai.usage.cost_usd", cost) ``` This enables queries like: ```text showLineNumbers title="Example queries in base14 Scout" # Cost by agent sum(gen_ai.client.cost) by (gen_ai.agent.name) # Token usage by model sum(gen_ai.client.token.usage) by (gen_ai.request.model) # Cost per campaign sum(gen_ai.client.cost) by (campaign_id) ``` ### Agent Pipeline Observability Agent orchestration frameworks like LangGraph do not have OpenTelemetry auto-instrumentation. Custom spans are required to track which agent is executing, how long each step takes, and where errors occur. #### Wrapping Agent Nodes Create a wrapper function that adds an OTel span around each agent in your pipeline: ```python showLineNumbers title="graph.py" from opentelemetry import trace tracer = trace.get_tracer("gen_ai.agent") def wrap_agent(name, agent_fn, needs_session=False): """Wrap an agent function with OTel agent span.""" async def wrapped(state): with tracer.start_as_current_span( f"invoke_agent {name}" ) as span: # Required attributes (GenAI agent semconv) span.set_attribute( "gen_ai.operation.name", "invoke_agent" ) span.set_attribute("gen_ai.agent.name", name) # Business context span.set_attribute( "campaign_id", state.campaign_id ) if needs_session: result = await agent_fn(state, session) else: result = await agent_fn(state) span.set_attribute( "errors_count", len(result.errors) ) return result return wrapped ``` #### Building the Pipeline ```python showLineNumbers title="graph.py - pipeline construction" from langgraph.graph import END, START, StateGraph def create_pipeline(session): """Create instrumented LangGraph pipeline.""" graph = StateGraph(AgentState) graph.add_node( "research", wrap_agent( "research", research_agent, needs_session=True, ), ) graph.add_node( "enrich", wrap_agent("enrich", enrich_agent), ) graph.add_node( "score", wrap_agent("score", score_agent), ) graph.add_node( "draft", wrap_agent("draft", draft_agent), ) graph.add_node( "evaluate", wrap_agent("evaluate", evaluate_agent), ) graph.add_edge(START, "research") graph.add_edge("research", "enrich") graph.add_edge("enrich", "score") graph.add_edge("score", "draft") graph.add_edge("draft", "evaluate") graph.add_edge("evaluate", END) return graph.compile() ``` #### Pipeline-Level Span Wrap the entire pipeline run in a parent span to capture aggregate metrics: ```python showLineNumbers title="graph.py - pipeline run" async def run_pipeline( campaign_id, target_keywords, target_titles, session, score_threshold=50, quality_threshold=60, ): """Run pipeline with top-level observability span.""" with tracer.start_as_current_span( "pipeline.run" ) as span: span.set_attribute("campaign_id", campaign_id) span.set_attribute( "target_keywords", target_keywords ) initial_state = AgentState( campaign_id=campaign_id, target_keywords=target_keywords, target_titles=target_titles, score_threshold=score_threshold, quality_threshold=quality_threshold, ) pipeline = create_pipeline(session) result = await pipeline.ainvoke(initial_state) # Record pipeline outcome on span span.set_attribute( "prospects_found", len(result.prospects) ) span.set_attribute( "drafts_generated", len(result.drafts) ) span.set_attribute( "evaluations_passed", sum( 1 for e in result.evaluations if e.passed ), ) return result ``` ### Evaluation and Quality Metrics LLM output quality is a first-class observability concern. The OpenTelemetry GenAI semantic conventions define evaluation events and metrics for tracking quality over time. #### Recording Evaluation Events ```python showLineNumbers title="agents/evaluate.py" from opentelemetry import metrics, trace tracer = trace.get_tracer("gen_ai.evaluation") meter = metrics.get_meter("gen_ai.evaluation") evaluation_score = meter.create_histogram( name="gen_ai.evaluation.score", description="Quality evaluation scores (0-1 normalized)", unit="1", ) async def evaluate_draft(draft, campaign_id, threshold): """Evaluate draft quality with OTel events.""" with tracer.start_as_current_span( "evaluate.draft" ) as span: span.set_attribute( "prospect_id", draft.prospect_id ) score = await run_quality_check(draft) passed = score >= threshold span.set_attribute("quality_score", score) span.set_attribute("passed", passed) # GenAI evaluation event (semconv) span.add_event( "gen_ai.evaluation.result", attributes={ "gen_ai.evaluation.name": ( "email_quality" ), "gen_ai.evaluation.score.value": score, "gen_ai.evaluation.score.label": ( "passed" if passed else "failed" ), "gen_ai.evaluation.explanation": ( feedback[:200] ), }, ) # Record metric for dashboards evaluation_score.record( score / 100.0, { "gen_ai.evaluation.name": ( "email_quality" ), "gen_ai.evaluation.score.label": ( "passed" if passed else "failed" ), "campaign_id": campaign_id, }, ) return EvaluationResult( quality_score=score, passed=passed, feedback=feedback, ) ``` #### GenAI Evaluation Event Attributes | Attribute | Type | Description | | ------------------------------- | ------ | ----------------------------------------- | | `gen_ai.evaluation.name` | string | Evaluation name (e.g., `"email_quality"`) | | `gen_ai.evaluation.score.value` | number | Raw score value | | `gen_ai.evaluation.score.label` | string | `"passed"` or `"failed"` | | `gen_ai.evaluation.explanation` | string | Human-readable feedback | ### PII and Security LLM prompts and completions often contain personally identifiable information. Recording raw prompts in telemetry creates a compliance risk. Scrub PII before adding prompt or completion events to spans. #### PII Scrubbing ```python showLineNumbers title="pii.py" import re from dataclasses import dataclass @dataclass class PIIPattern: name: str pattern: re.Pattern[str] replacement: str DEFAULT_PATTERNS = [ PIIPattern( "email", re.compile( r"\b[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+" r"\.[A-Z|a-z]{2,}\b" ), "[EMAIL]", ), PIIPattern( "phone", re.compile( r"(?:\+?1[-.\s]?)?\(?[0-9]{3}\)?[-.\s]?" r"[0-9]{3}[-.\s]?[0-9]{4}\b" ), "[PHONE]", ), PIIPattern( "linkedin", re.compile( r"https?://(?:www\.)?linkedin\.com" r"/in/[A-Za-z0-9_-]+/?" ), "[LINKEDIN_URL]", ), PIIPattern( "ssn", re.compile(r"\b\d{3}[-]?\d{2}[-]?\d{4}\b"), "[SSN]", ), ] def scrub_pii(text: str) -> str: """Replace PII with safe placeholders.""" result = text for p in DEFAULT_PATTERNS: result = p.pattern.sub(p.replacement, result) return result ``` #### Applying PII Scrubbing to Telemetry Always scrub before recording span events: ```python showLineNumbers title="llm.py - PII-safe events" from my_app.pii import scrub_pii # Record prompt with PII scrubbed and truncated span.add_event( "gen_ai.user.message", attributes={ "gen_ai.prompt": scrub_pii(prompt)[:1000], "gen_ai.system_instructions": scrub_pii(system)[:500], }, ) # Record completion with PII scrubbed and truncated span.add_event( "gen_ai.assistant.message", attributes={ "gen_ai.completion": scrub_pii( response.content )[:2000], }, ) ``` #### Security Considerations - **Never record raw prompts** that may contain user data, API keys, or credentials in span attributes or events - **Truncate content** to avoid oversized spans (1000 chars for prompts, 2000 for completions) - **Disable prompt recording** in production if compliance requirements prohibit it - the GenAI span attributes (model, tokens, cost) still provide full operational visibility - **Use the OTel Collector `attributes` processor** to redact sensitive fields before export if additional filtering is needed - **GDPR/HIPAA**: If prompts may contain regulated data, consider recording only token counts and model metadata, not content ### Production Configuration #### Environment Variables ```bash showLineNumbers title=".env" # Application OTEL_SERVICE_NAME=my-ai-service OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_ENABLED=true SCOUT_ENVIRONMENT=development # LLM Provider LLM_PROVIDER=anthropic LLM_MODEL=claude-sonnet-4-20250514 ANTHROPIC_API_KEY=sk-ant-... # Fallback (optional) FALLBACK_PROVIDER=google FALLBACK_MODEL=gemini-3-flash GOOGLE_API_KEY=... ``` #### OpenTelemetry Collector Configuration ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 batch: timeout: 10s send_batch_size: 1024 send_batch_max_size: 2048 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlphttp/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: basic sampling_initial: 5 sampling_thereafter: 200 service: extensions: [health_check, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlphttp/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlphttp/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlphttp/b14, debug] ``` #### Docker Compose Deployment ```yaml showLineNumbers title="compose.yml" services: app: build: . ports: - "8000:8000" environment: - DATABASE_URL=postgresql+asyncpg://postgres:postgres@postgres:5432/mydb - OTEL_SERVICE_NAME=my-ai-service - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_ENABLED=true - ANTHROPIC_API_KEY=${ANTHROPIC_API_KEY} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} depends_on: postgres: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-f", "http://localhost:8000/health"] interval: 60s timeout: 5s retries: 3 postgres: image: postgres:18 environment: POSTGRES_DB: mydb POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" - "55679:55679" environment: - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-https://collector.base14.io} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} ``` ### Retry and Fallback Observability LLM APIs are inherently unreliable. Retries and provider fallbacks should be observable so you can track error rates, retry frequency, and fallback triggers. #### Retry Metrics ```python showLineNumbers title="llm.py - retry instrumentation" from opentelemetry import metrics from tenacity import ( RetryCallState, retry, stop_after_attempt, wait_exponential, ) meter = metrics.get_meter("gen_ai.client") retry_counter = meter.create_counter( name="gen_ai.client.retry.count", description="Number of retry attempts", unit="{retry}", ) fallback_counter = meter.create_counter( name="gen_ai.client.fallback.count", description="Number of fallback triggers", unit="{fallback}", ) error_counter = meter.create_counter( name="gen_ai.client.error.count", description="Number of errors by type", unit="{error}", ) def on_retry(retry_state: RetryCallState): """Record retry metric before each attempt.""" error_type = "unknown" if ( retry_state.outcome and retry_state.outcome.exception() ): error_type = type( retry_state.outcome.exception() ).__name__ retry_counter.add( 1, { "gen_ai.provider.name": provider_name, "error.type": error_type, "retry.attempt": ( retry_state.attempt_number ), }, ) @retry( stop=stop_after_attempt(3), wait=wait_exponential( multiplier=1, min=1, max=10 ), before_sleep=on_retry, ) async def generate(self, model, system, prompt, **kw): """LLM call with automatic retry.""" ... ``` #### Fallback Instrumentation When the primary provider fails, record the fallback trigger on both the span and as a metric: ```python showLineNumbers title="llm.py - fallback tracking" except Exception as e: span.record_exception(e) span.set_attribute("error.type", type(e).__name__) if use_fallback and provider != fallback_provider: span.set_attribute( "gen_ai.fallback.triggered", True ) fallback_counter.add( 1, { "gen_ai.provider.name": provider, "gen_ai.fallback.provider": ( fallback_provider ), "error.type": type(e).__name__, }, ) # Retry with fallback provider return await self.generate( prompt=prompt, system=system, provider=fallback_provider, model=fallback_model, use_fallback=False, ) raise ``` ### Troubleshooting #### Verify Telemetry Is Working Check that the OTel Collector is receiving data: ```bash showLineNumbers title="Verify collector health" # Check collector health curl http://localhost:13133 # View recent traces in zpages debug UI # Open http://localhost:55679/debug/tracez in a browser ``` #### Enable Debug Mode Set debug-level logging to see span exports: ```python showLineNumbers title="Debug logging" import logging logging.getLogger("opentelemetry").setLevel( logging.DEBUG ) ``` #### Common Issues ##### Issue: LLM spans not appearing in traces The custom `gen_ai.chat` span exists but is not connected to the HTTP request trace. **Solutions:** 1. Ensure `setup_telemetry()` is called **before** creating the FastAPI app 2. Verify `HTTPXClientInstrumentor().instrument()` is called during setup - this creates the parent HTTP span that the custom span nests under 3. Check that the `gen_ai.chat` span is created inside an async context where the trace context is propagated ##### Issue: Token counts are zero **Solutions:** 1. Check your LLM SDK version - older versions may not expose `usage` on the response object 2. Verify the provider response object has `input_tokens` and `output_tokens` fields (naming varies by provider) 3. For Google GenAI, check `response.usage_metadata` instead of `response.usage` ##### Issue: Cost metrics not accurate **Solutions:** 1. Verify your `MODEL_PRICING` dictionary contains the exact model ID string returned by the provider (e.g., `claude-sonnet-4-20250514`, not `claude-sonnet-4`) 2. Check that cost is calculated with `/1_000_000` (pricing is per million tokens) ##### Issue: Spans not exported to Scout **Solutions:** 1. Confirm the OTel Collector is running: `curl http://localhost:13133` 2. Check collector logs: `docker compose logs otel-collector` 3. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` points to the collector, not directly to Scout 4. Ensure `SCOUT_CLIENT_ID` and `SCOUT_CLIENT_SECRET` are set in the collector environment ### Performance Considerations OpenTelemetry overhead is negligible relative to LLM API latency. A typical LLM call takes 1-5 seconds; span creation and metric recording add microseconds. #### Impact Factors - **Span creation**: ~1-5 microseconds per span - **Attribute setting**: ~0.5 microseconds per attribute - **Metric recording**: ~1 microsecond per record - **Batch export**: Happens in background thread, no request impact #### Optimization Strategies ##### 1. Use BatchSpanProcessor in Production The `BatchSpanProcessor` batches spans before export, avoiding per-span network calls: ```python showLineNumbers title="Production trace setup" trace_provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint=endpoint), max_queue_size=2048, max_export_batch_size=512, schedule_delay_millis=5000, ) ) ``` ##### 2. Truncate Prompt and Completion Events Long prompts and completions increase span payload size. Always truncate: ```python showLineNumbers title="Truncation" span.add_event( "gen_ai.user.message", attributes={ "gen_ai.prompt": scrub_pii(prompt)[:1000], }, ) ``` ##### 3. Disable Prompt Recording in High-Volume Scenarios If you process thousands of LLM calls per minute and do not need prompt data in traces, skip the event recording: ```python showLineNumbers title="Conditional recording" if settings.record_prompts: span.add_event( "gen_ai.user.message", attributes={ "gen_ai.prompt": scrub_pii(prompt)[:1000], }, ) ``` ##### 4. Use the Collector Memory Limiter The OTel Collector `memory_limiter` processor prevents out-of-memory issues under heavy load: ```yaml showLineNumbers title="otel-collector-config.yaml" processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 ``` ### FAQ #### Does OpenTelemetry add latency to LLM calls? No. Span creation takes microseconds. LLM API calls take seconds. The overhead is unmeasurable in practice. `BatchSpanProcessor` exports spans in a background thread, so export does not block request handling. #### How do I track cost across multiple LLM providers? Use the `gen_ai.client.cost` counter metric with `gen_ai.provider.name` and `gen_ai.request.model` attributes. Define a pricing dictionary per model and calculate cost from token counts. This gives you `sum(cost) by (provider)` in your dashboards. #### Can I see the actual prompts and completions in traces? Yes, if you record them as `gen_ai.user.message` and `gen_ai.assistant.message` span events. Always scrub PII first. You can disable prompt recording in production for compliance. #### How does this compare to LangSmith? LangSmith provides deep LLM-specific tracing but operates in isolation from your HTTP and database telemetry. OpenTelemetry gives you a single trace that spans all layers. You can see that a slow HTTP response was caused by a specific LLM call in a specific agent, and that the same request also ran 3 database queries. LangSmith cannot show that correlation. #### Do I need to instrument each LLM provider separately? No. Use a provider-agnostic abstraction (like the `LLMClient` pattern shown in this guide) that wraps all providers with the same span structure. The `gen_ai.provider.name` attribute identifies which provider handled each call. #### How do I monitor LLM evaluation quality over time? Record `gen_ai.evaluation.score` as a histogram metric with `gen_ai.evaluation.name` and `gen_ai.evaluation.score.label` attributes. This lets you track pass rates, score distributions, and quality trends per evaluation type in your dashboards. #### What if my agent framework supports tracing natively? Some frameworks (e.g., LangChain) have their own tracing. You can still use OpenTelemetry alongside or instead. The key advantage of OpenTelemetry is portability - your traces work with any backend (base14 Scout, Jaeger, Grafana Tempo, etc.) without vendor lock-in. #### How do I reduce trace volume for high-throughput AI apps? Use head-based sampling in the OTel Collector or SDK. For AI applications, a practical approach is to sample 100% of error traces and a percentage of successful traces. The `probabilistic_sampler` processor in the collector handles this. #### Can I track which agent is the most expensive? Yes. Set `gen_ai.agent.name` as an attribute on both the `gen_ai.chat` span and the `gen_ai.client.cost` metric. This enables `sum(gen_ai.client.cost) by (gen_ai.agent.name)` in your dashboards. #### How do I add observability to an existing AI app? Start with auto-instrumentation (FastAPI, SQLAlchemy, httpx) - this requires no code changes. Then add custom LLM spans in your LLM client layer. Finally, add agent-level spans if you use an orchestration framework. Each layer adds value independently. ### What's Next? #### Advanced Topics - [Python Custom Instrumentation][py-custom] - Manual tracing and metrics for Python applications - [FastAPI Auto-Instrumentation][fastapi-auto] - Comprehensive FastAPI instrumentation guide #### Scout Platform Features - [Monitor LLM costs and latency in Scout](https://base14.io/scout/llm-observability) \- Track token usage, provider costs, and response quality across all your LLM operations - [Creating Alerts](../creating-alerts-with-logx.md) - Set up alerts for LLM error rates, cost spikes, or quality degradation - [Create Your First Dashboard](../create-your-first-dashboard.md) \- Build dashboards for token usage, cost attribution, and evaluation scores #### Deployment and Operations - [Docker Compose Setup][docker-setup] - Local development with the OTel Collector - [Kubernetes Helm Setup][k8s-setup] - Production deployment - [Scout Exporter][scout-exporter] - Configure authentication with base14 Scout ### Complete Example The [AI Sales Intelligence](https://github.com/base14/examples/tree/main/python/ai-sales-intelligence) example application implements every pattern described in this guide. It is a FastAPI + LangGraph + multi-provider LLM application with full OpenTelemetry instrumentation. #### Project Structure ```text showLineNumbers title="Project structure" ai-sales-intelligence/ ├── src/sales_intelligence/ │ ├── telemetry.py # OTel setup (auto + custom) │ ├── llm.py # LLM client with GenAI spans │ ├── graph.py # LangGraph pipeline with agent spans │ ├── agents/ │ │ ├── research.py # Database search agent │ │ ├── enrich.py # LLM enrichment agent │ │ ├── score.py # LLM scoring agent │ │ ├── draft.py # LLM email draft agent │ │ └── evaluate.py # LLM quality evaluation agent │ ├── pii.py # PII scrubbing for telemetry │ ├── config.py # Provider-agnostic settings │ ├── main.py # FastAPI application │ └── middleware/ │ └── metrics.py # HTTP request metrics ├── otel-collector-config.yaml ├── compose.yml └── pyproject.toml ``` #### Key Files | File | Demonstrates | | -------------- | ----------------------------------------------- | | `telemetry.py` | Auto-instrumentation setup | | `llm.py` | GenAI spans, token/cost metrics, retry/fallback | | `graph.py` | Agent pipeline spans with LangGraph | | `evaluate.py` | Evaluation events and quality metrics | | `pii.py` | PII scrubbing before telemetry recording | | `config.py` | Provider-agnostic settings with Pydantic | | `compose.yml` | Docker deployment with OTel Collector | ### References - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [OpenTelemetry Python SDK](https://opentelemetry.io/docs/languages/python/) - [OpenTelemetry Collector Configuration](https://opentelemetry.io/docs/collector/configuration/) - [LangGraph Documentation](https://langchain-ai.github.io/langgraph/) ### Related Guides - [Python Custom Instrumentation][py-custom] - Manual tracing and metrics fundamentals - [FastAPI Auto-Instrumentation][fastapi-auto] - Comprehensive FastAPI setup - [Docker Compose Setup][docker-setup] - Local collector deployment - [Scout Exporter][scout-exporter] - Configure base14 Scout authentication [py-custom]: ../../instrument/apps/custom-instrumentation/python.md [fastapi-auto]: ../../instrument/apps/auto-instrumentation/fast-api.md [docker-setup]: ../../instrument/collector-setup/docker-compose-example.md [scout-exporter]: ../../instrument/collector-setup/scout-exporter.md [k8s-setup]: ../../instrument/collector-setup/kubernetes-helm-setup.md --- ## Rust LLM Observability with OpenTelemetry - AI Application Tracing Guide ## Rust LLM Observability Implement unified observability for Rust AI and LLM applications using OpenTelemetry. This guide shows you how to trace every layer of a Rust AI application - from HTTP requests through pipeline orchestration to LLM API calls and database queries - in a single correlated trace using the OpenTelemetry Rust SDK and base14 Scout. You will instrument a multi-stage AI pipeline that retrieves data from PostgreSQL, analyzes trends with a fast LLM, generates structured narratives with a capable LLM, and assembles the final output - with every stage, token count, and cost captured in telemetry. Rust AI applications introduce observability challenges that generic APM tooling was not designed for. An LLM call is not just an HTTP request - it carries semantic meaning: which model was used, how many tokens were consumed, what it cost, whether the response was a fallback from another provider. Unlike Python or Node.js, Rust has no auto-instrumentation libraries for LLM SDKs like `async-openai` or Anthropic HTTP clients. You need manual spans following OpenTelemetry GenAI semantic conventions, custom metrics for token and cost tracking, and careful integration with the `tracing` ecosystem that Rust applications depend on. The payoff is complete visibility: a single trace that shows exactly which model answered, how long it took, what it cost, and whether retries or provider fallbacks were involved. Whether you are building AI pipelines with Axum, integrating OpenAI or Anthropic via `async-openai` or raw HTTP clients, or running local models through Ollama, this guide provides production-ready patterns for unified AI observability in Rust. You will learn how to set up three-pillar telemetry (traces, metrics, logs), create GenAI spans with the correct semantic conventions, define six standard LLM metrics, implement retry and fallback observability, and deploy with Docker Compose and the OpenTelemetry Collector - all visible in a single trace on base14 Scout. :::tip TL;DR Instrument Rust AI applications with OpenTelemetry by creating manual GenAI spans with `tracing::info_span!`, defining six standard LLM metrics with `LazyLock`, and bridging `tracing` to the OTLP exporter. This gives you unified traces from HTTP entry through pipeline stages to individual LLM completions, with token and cost tracking per provider and model. ::: > **Note:** For general LLM observability patterns applicable to any language, > see the [LLM Observability guide](../llm-observability). This guide focuses > specifically on Rust integration patterns. For basic Axum instrumentation > without AI, see the > [Axum guide](../../instrument/apps/auto-instrumentation/axum.md). :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### Who This Guide Is For This documentation is designed for: - **Rust AI developers**: building LLM-powered features with `async-openai`, Anthropic HTTP clients, or custom providers and needing visibility into model performance, cost, and pipeline throughput - **Backend developers**: adding AI capabilities (report generation, analysis, chat) to existing Axum or Actix-web applications and wanting unified tracing across all layers - **Platform teams**: standardizing observability across Rust AI services and traditional microservices using OpenTelemetry - **Engineering teams**: migrating from proprietary AI observability tools to open-standard OpenTelemetry - **DevOps engineers**: deploying Rust AI applications with production monitoring, cost alerting, and pipeline health tracking ### Rust LLM Observability Overview This guide demonstrates how to: - Set up three-pillar OpenTelemetry for a Rust AI application (traces + metrics + logs) - Create custom LLM spans following OpenTelemetry GenAI semantic conventions - Define GenAI metrics for token usage, cost, duration, errors, retries, and fallbacks - Instrument multi-stage AI pipelines with parent-child spans - Track token usage and calculate cost per LLM call - Implement multi-provider LLM support with retry and fallback observability - Correlate trace IDs with database records for end-to-end debugging - Deploy with Docker Compose and the OpenTelemetry Collector - Export traces, metrics, and logs to base14 Scout ### Prerequisites Before starting, ensure you have: - **Rust 1.85 or later** installed (1.92+ recommended for edition 2024 support) - **An LLM API key** from at least one provider (OpenAI, Anthropic, or Google) - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../instrument/collector-setup/kubernetes-helm-setup.md) for production deployment - Basic understanding of OpenTelemetry concepts (traces, spans, metrics) - Familiarity with the Rust `tracing` crate #### Compatibility Matrix | Component | Minimum Version | Recommended | | --------------------- | --------------- | ----------- | | Rust | 1.85 | 1.92+ | | opentelemetry | 0.28 | 0.32+ | | opentelemetry_sdk | 0.28 | 0.32+ | | opentelemetry-otlp | 0.28 | 0.32+ | | tracing-opentelemetry | 0.29 | 0.33+ | | tracing | 0.1 | 0.1+ | | tracing-subscriber | 0.3 | 0.3+ | | async-openai | 0.25+ | 0.33+ | | Axum | 0.7+ | 0.8+ | | SQLx | 0.7+ | 0.8+ | ### The Unified Trace The core value of OpenTelemetry for Rust AI applications is the **unified trace** - a single trace ID that connects every layer of a request, from HTTP entry through pipeline stages to LLM completions and back. Here is what a trace looks like for an AI pipeline request: ```text showLineNumbers title="Unified trace for POST /api/reports" POST /api/reports 6.8s [HTTP: tower-http] ├─ pipeline report 6.7s [custom: orchestrator] │ ├─ pipeline_stage retrieve 45ms [custom: pipeline] │ │ └─ db.query SELECT data_points 12ms [SQLx] │ ├─ pipeline_stage analyze 2.1s [custom: pipeline] │ │ └─ gen_ai.chat gpt-4.1-mini 2.0s [custom: LLM] │ ├─ pipeline_stage generate 4.3s [custom: pipeline] │ │ └─ gen_ai.chat gpt-4.1 4.2s [custom: LLM] │ └─ pipeline_stage format 5ms [custom: pipeline] └─ db.query INSERT reports 8ms [SQLx] ``` Three types of spans work together: - **HTTP spans** (tower-http `TraceLayer`): Capture request method, path, status code, and latency automatically - **Custom LLM spans**: Model name, provider, token counts, cost, prompt/completion events following GenAI semantic conventions - **Custom pipeline spans**: Stage names, data point counts, business context like report ID and trace ID correlation The HTTP span captures the incoming request. The pipeline span orchestrates stages. Each `gen_ai.chat` span wraps an LLM call, adding provider, model, token, and cost context. All are children of the same trace - giving you full visibility from HTTP entry to LLM completion. ### Installation Add the OpenTelemetry and tracing dependencies to your `Cargo.toml`: ```toml showLineNumbers title="Cargo.toml" [dependencies] # Web Framework axum = { version = "0.8", features = ["macros"] } tower = { version = "0.5", features = ["full"] } tower-http = { version = "0.6", features = ["trace", "cors", "timeout", "request-id"] } # Async Runtime tokio = { version = "1", features = ["full", "tracing"] } # Database sqlx = { version = "0.8", features = [ "runtime-tokio", "tls-rustls", "postgres", "macros", "uuid", "chrono", "json" ] } # LLM Providers async-openai = { version = "0.33", features = ["chat-completion"] } reqwest = { version = "0.12", features = ["json"] } # OpenTelemetry opentelemetry = "0.32" opentelemetry_sdk = { version = "0.32", features = [ "rt-tokio", "logs", "metrics" ] } opentelemetry-otlp = { version = "0.32", features = [ "grpc-tonic", "trace", "logs", "metrics" ] } opentelemetry-appender-tracing = "0.32" # Tracing tracing = "0.1" tracing-subscriber = { version = "0.3", features = [ "env-filter", "json" ] } tracing-opentelemetry = "0.33" # Utilities serde = { version = "1", features = ["derive"] } serde_json = "1" uuid = { version = "1", features = ["v4", "serde"] } chrono = { version = "0.4", features = ["serde"] } anyhow = "1" dotenvy = "0.15" ``` > **Note:** The `opentelemetry`, `opentelemetry_sdk`, and `opentelemetry-otlp` > crates must use the same version. The `tracing-opentelemetry` version must be > compatible - check the > [tracing-opentelemetry compatibility matrix](https://github.com/open-telemetry/opentelemetry-rust/tree/main/opentelemetry-tracing) > for the correct pairing. ### Telemetry Initialization Initialize the three OpenTelemetry pillars - traces, metrics, and logs - with OTLP gRPC export. This runs once at application startup. ```rust showLineNumbers title="src/telemetry/init.rs" use opentelemetry::KeyValue; use opentelemetry::global; use opentelemetry_appender_tracing::layer::OpenTelemetryTracingBridge; use opentelemetry_otlp::WithExportConfig; use opentelemetry_sdk::{ Resource, logs::SdkLoggerProvider, metrics::{PeriodicReader, SdkMeterProvider}, trace::SdkTracerProvider, }; use std::time::Duration; use tracing_opentelemetry::OpenTelemetryLayer; use tracing_subscriber::{ EnvFilter, Layer, layer::SubscriberExt, util::SubscriberInitExt, }; use crate::config::Config; pub struct TelemetryGuard { pub tracer_provider: SdkTracerProvider, pub logger_provider: SdkLoggerProvider, pub meter_provider: SdkMeterProvider, } impl TelemetryGuard { pub fn shutdown(&self) { if let Err(e) = self.tracer_provider.shutdown() { eprintln!("Error shutting down tracer provider: {e}"); } if let Err(e) = self.logger_provider.shutdown() { eprintln!("Error shutting down logger provider: {e}"); } if let Err(e) = self.meter_provider.shutdown() { eprintln!("Error shutting down meter provider: {e}"); } } } pub fn init_telemetry( config: &Config, ) -> anyhow::Result { let resource = Resource::builder() .with_service_name(config.otel_service_name.clone()) .with_attribute(KeyValue::new("service.version", "1.0.0")) .with_attribute(KeyValue::new( "service.namespace", "examples", )) .with_attribute(KeyValue::new( "deployment.environment", config.environment.clone(), )) .with_attribute(KeyValue::new( "environment", config.environment.clone(), )) .build(); // --- Traces --- let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .with_resource(resource.clone()) .build(); global::set_tracer_provider(tracer_provider.clone()); // --- Metrics --- let metric_exporter = opentelemetry_otlp::MetricExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let metric_reader = PeriodicReader::builder(metric_exporter) .with_interval(Duration::from_secs(15)) .build(); let meter_provider = SdkMeterProvider::builder() .with_reader(metric_reader) .with_resource(resource.clone()) .build(); global::set_meter_provider(meter_provider.clone()); // --- Logs --- let log_exporter = opentelemetry_otlp::LogExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let logger_provider = SdkLoggerProvider::builder() .with_batch_exporter(log_exporter) .with_resource(resource) .build(); // Bridge tracing logs to OpenTelemetry let otel_log_layer = OpenTelemetryTracingBridge::new(&logger_provider); let tracer = global::tracer(config.otel_service_name.clone()); let telemetry_layer = OpenTelemetryLayer::new(tracer); let env_filter = EnvFilter::try_from_default_env() .unwrap_or_else(|_| { EnvFilter::new("info,tower_http=debug") }); let fmt_layer = if config.is_production() { tracing_subscriber::fmt::layer().json().boxed() } else { tracing_subscriber::fmt::layer().pretty().boxed() }; tracing_subscriber::registry() .with(env_filter) .with(telemetry_layer) .with(otel_log_layer) .with(fmt_layer) .init(); tracing::info!( service = %config.otel_service_name, endpoint = %config.otel_exporter_endpoint, "Telemetry initialized with OTLP trace, metric, \ and log export" ); Ok(TelemetryGuard { tracer_provider, logger_provider, meter_provider, }) } ``` Key points: - **`TelemetryGuard`** holds all three providers and flushes pending telemetry on shutdown - call `shutdown()` before process exit to avoid losing the final batch - **`OpenTelemetryLayer`** converts `tracing` spans into OpenTelemetry spans with proper parent-child relationships - **`OpenTelemetryTracingBridge`** routes structured log events (from `tracing::info!`, `tracing::warn!`, etc.) to the OTLP log exporter - **`EnvFilter`** respects `RUST_LOG` environment variable for runtime log level control #### Application Startup Wire the telemetry guard into your `main` function and ensure graceful shutdown: ```rust showLineNumbers title="src/main.rs" #[tokio::main] async fn main() -> anyhow::Result<()> { let config = Config::from_env(); let telemetry_guard = init_telemetry(&config)?; tracing::info!( port = config.port, environment = %config.environment, "Starting ai-report-generator" ); // ... build router, start server ... axum::serve(listener, app) .with_graceful_shutdown(shutdown_signal()) .await?; tracing::info!("Server shutdown complete"); telemetry_guard.shutdown(); Ok(()) } ``` ### Custom LLM Instrumentation Rust has no auto-instrumentation libraries for LLM SDKs. You create manual spans following the [OpenTelemetry GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/). This gives you the same standardized telemetry that Python and Node.js auto-instrumentors produce. #### GenAI Span Attributes Every LLM call gets a `gen_ai.chat` span with these attributes: | Attribute | Type | Description | | -------------------------------- | ------ | ----------------------------------- | | `gen_ai.operation.name` | string | Always `"chat"` for completions | | `gen_ai.provider.name` | string | `"openai"`, `"anthropic"`, etc. | | `gen_ai.request.model` | string | Model requested (e.g., `"gpt-4.1"`) | | `gen_ai.request.temperature` | float | Sampling temperature | | `gen_ai.request.max_tokens` | int | Max output tokens requested | | `gen_ai.response.model` | string | Model actually used | | `gen_ai.usage.input_tokens` | int | Prompt tokens consumed | | `gen_ai.usage.output_tokens` | int | Completion tokens generated | | `gen_ai.response.finish_reasons` | string | `"stop"`, `"length"`, etc. | | `server.address` | string | API endpoint host | | `server.port` | int | API endpoint port | #### Creating GenAI Spans Use `tracing::info_span!` with `tracing::field::Empty` for attributes that are only known after the LLM call completes: ```rust showLineNumbers title="src/llm/client.rs" use opentelemetry::KeyValue; use tracing::Instrument; use tracing_opentelemetry::OpenTelemetrySpanExt; pub async fn generate_once( &self, provider: &dyn Provider, provider_name: &str, req: &GenerateRequest, ) -> anyhow::Result { let span_display_name = format!("gen_ai.chat {}", req.model); let start = std::time::Instant::now(); let span = tracing::info_span!( "gen_ai.chat", otel.name = %span_display_name, gen_ai.operation.name = "chat", gen_ai.provider.name = %provider_name, gen_ai.request.model = %req.model, gen_ai.request.temperature = req.temperature, gen_ai.request.max_tokens = req.max_tokens as i64, server.address = %server_addr, server.port = server_port, // Filled after LLM response gen_ai.response.model = tracing::field::Empty, gen_ai.usage.input_tokens = tracing::field::Empty, gen_ai.usage.output_tokens = tracing::field::Empty, gen_ai.usage.cost_usd = tracing::field::Empty, gen_ai.response.finish_reasons = tracing::field::Empty, report.stage = %req.stage, otel.status_code = tracing::field::Empty, error.type = tracing::field::Empty, ); // Record prompt and system instructions as span events { let mut user_event_attrs = vec![KeyValue::new( "gen_ai.prompt", truncate(&req.prompt, 1000), )]; if !req.system.is_empty() { user_event_attrs.push(KeyValue::new( "gen_ai.system_instructions", truncate(&req.system, 500), )); } span.add_event( "gen_ai.user.message", user_event_attrs, ); } // Execute LLM call within the span let result = provider .generate(req) .instrument(span.clone()) .await; match result { Ok(mut resp) => { resp.provider = provider_name.to_string(); resp.cost_usd = calculate_cost( &resp.model, resp.input_tokens, resp.output_tokens, ); // Fill response attributes span.record( "gen_ai.response.model", resp.model.as_str(), ); span.record( "gen_ai.usage.input_tokens", resp.input_tokens as i64, ); span.record( "gen_ai.usage.output_tokens", resp.output_tokens as i64, ); span.record( "gen_ai.usage.cost_usd", resp.cost_usd, ); if !resp.finish_reason.is_empty() { span.record( "gen_ai.response.finish_reasons", resp.finish_reason.as_str(), ); } // Record completion as a span event span.add_event( "gen_ai.assistant.message", vec![KeyValue::new( "gen_ai.completion", truncate(&resp.content, 2000), )], ); Ok(resp) } Err(err) => { span.record("otel.status_code", "ERROR"); span.record( "error.type", classify_error(&err), ); GEN_AI_ERROR_COUNT.add( 1, &[ KeyValue::new( "gen_ai.provider.name", provider_name.to_string(), ), KeyValue::new( "gen_ai.request.model", req.model.clone(), ), ], ); Err(err) } } } ``` Key patterns: - **`tracing::field::Empty`** declares span fields that are filled later with `span.record()` - this is how you handle attributes that depend on the LLM response - **`.instrument(span.clone())`** executes the async LLM call within the span context, so the span duration matches the actual API call - **`span.add_event()`** uses `opentelemetry::KeyValue` (not `tracing` fields) to record prompt and completion content as structured span events - **`otel.name`** overrides the span display name in your trace viewer to show the model name > **Note:** The complete `generate_once` function also records GenAI metrics > (token usage, cost, duration) alongside the span attributes shown above. See > [Token and Cost Tracking](#token-and-cost-tracking) for the metric recording > code that runs in the same `Ok(resp)` branch. #### Error Classification Classify LLM errors into standardized types for filtering and alerting: ```rust showLineNumbers title="src/llm/client.rs" fn classify_error(err: &anyhow::Error) -> &'static str { let msg = err.to_string().to_lowercase(); if msg.contains("rate limit") || msg.contains("429") { "rate_limit" } else if msg.contains("timeout") || msg.contains("timed out") || msg.contains("deadline") { "timeout" } else if msg.contains("401") || msg.contains("403") || msg.contains("auth") || msg.contains("api key") { "auth_error" } else if msg.contains("400") || msg.contains("422") || msg.contains("invalid") { "invalid_request" } else if msg.contains("500") || msg.contains("502") || msg.contains("503") || msg.contains("server") { "server_error" } else if msg.contains("connect") || msg.contains("dns") || msg.contains("network") || msg.contains("reset") { "network_error" } else { "unknown_error" } } ``` This lets you alert on `error.type = "rate_limit"` separately from `error.type = "timeout"` in Scout dashboards. ### Token and Cost Tracking Define GenAI metrics following the OpenTelemetry GenAI semantic conventions. These metrics power dashboards for token consumption, cost attribution, and provider reliability. #### Metric Definitions ```rust showLineNumbers title="src/telemetry/metrics.rs" use opentelemetry::{ global, metrics::{Counter, Histogram, Meter}, }; use std::sync::LazyLock; pub static METER: LazyLock = LazyLock::new(|| global::meter("ai-report-generator")); // --- GenAI Contract Metrics (6 required) --- pub static GEN_AI_TOKEN_USAGE: LazyLock> = LazyLock::new(|| { METER .f64_histogram("gen_ai.client.token.usage") .with_description( "Number of tokens used per LLM call", ) .with_unit("{token}") .build() }); pub static GEN_AI_OPERATION_DURATION: LazyLock> = LazyLock::new(|| { METER .f64_histogram("gen_ai.client.operation.duration") .with_description( "Duration of LLM operations in seconds", ) .with_unit("s") .build() }); pub static GEN_AI_COST: LazyLock> = LazyLock::new(|| { METER .f64_counter("gen_ai.client.cost") .with_description( "Estimated cost of LLM operations in USD", ) .with_unit("usd") .build() }); pub static GEN_AI_RETRY_COUNT: LazyLock> = LazyLock::new(|| { METER .u64_counter("gen_ai.client.retry.count") .with_description("Number of LLM call retries") .with_unit("{retry}") .build() }); pub static GEN_AI_FALLBACK_COUNT: LazyLock> = LazyLock::new(|| { METER .u64_counter("gen_ai.client.fallback.count") .with_description( "Number of LLM fallback activations", ) .with_unit("{fallback}") .build() }); pub static GEN_AI_ERROR_COUNT: LazyLock> = LazyLock::new(|| { METER .u64_counter("gen_ai.client.error.count") .with_description("Number of LLM call errors") .with_unit("{error}") .build() }); ``` #### Recording Token and Cost Metrics After each successful LLM call, record token usage with provider and model dimensions: ```rust showLineNumbers title="src/llm/client.rs" use crate::telemetry::metrics::{ GEN_AI_COST, GEN_AI_OPERATION_DURATION, GEN_AI_TOKEN_USAGE, }; // Inside the Ok(resp) branch of generate_once: let op_kv = KeyValue::new("gen_ai.operation.name", "chat"); let provider_kv = KeyValue::new( "gen_ai.provider.name", provider_name.to_string(), ); let model_kv = KeyValue::new( "gen_ai.request.model", resp.model.clone(), ); GEN_AI_TOKEN_USAGE.record( f64::from(resp.input_tokens), &[ KeyValue::new("gen_ai.token.type", "input"), op_kv.clone(), provider_kv.clone(), model_kv.clone(), ], ); GEN_AI_TOKEN_USAGE.record( f64::from(resp.output_tokens), &[ KeyValue::new("gen_ai.token.type", "output"), op_kv.clone(), provider_kv.clone(), model_kv.clone(), ], ); GEN_AI_OPERATION_DURATION.record( duration, &[op_kv.clone(), provider_kv.clone(), model_kv.clone()], ); GEN_AI_COST.add( resp.cost_usd, &[op_kv, provider_kv, model_kv], ); ``` The `gen_ai.token.type` dimension (`"input"` or `"output"`) lets you build dashboards that break down token consumption by direction, provider, and model. #### Cost Calculation Load model pricing from a configuration file and calculate cost per call: ```rust showLineNumbers title="src/llm/pricing.rs" pub fn calculate_cost( model: &str, input_tokens: u32, output_tokens: u32, ) -> f64 { // PRICING maps model name to PriceEntry { input, output } // where input/output are price per million tokens match PRICING.get(model) { Some(entry) => { (f64::from(input_tokens) * entry.input / 1_000_000.0) + (f64::from(output_tokens) * entry.output / 1_000_000.0) } None => 0.0, } } ``` This feeds the `gen_ai.client.cost` counter metric for per-model and per-provider cost dashboards. ### Pipeline Observability AI applications typically involve multi-stage pipelines. Each stage gets its own span, creating a clear parent-child hierarchy in your traces. #### Pipeline Orchestrator The orchestrator span wraps the entire pipeline and extracts the trace ID for database correlation: ```rust showLineNumbers title="src/pipeline/orchestrator.rs" use opentelemetry::trace::TraceContextExt; use tracing_opentelemetry::OpenTelemetrySpanExt; #[tracing::instrument( name = "pipeline report", skip(pool, llm_client), fields( report.id, report.indicators_count, report.duration_ms, ) )] pub async fn generate_report( pool: &PgPool, llm_client: &LlmClient, model_capable: &str, model_fast: &str, request: &ReportRequest, ) -> Result { let start = std::time::Instant::now(); // Extract trace ID for database correlation let span = tracing::Span::current(); let context = span.context(); let otel_span = context.span(); let trace_id = otel_span .span_context() .trace_id() .to_string(); // Stage 1: Retrieve data from PostgreSQL let data = retrieve::retrieve( pool, &request.indicators, request.start_date, request.end_date, ).await?; // Stage 2: Analyze trends via LLM (fast model) let analysis = analyze::analyze( llm_client, model_fast, &data.indicators, ).await?; // Stage 3: Generate narrative via LLM (capable model) let narrative = generate::generate( llm_client, model_capable, &data.indicators, &analysis, ).await?; // Stage 4: Format final report let duration = start.elapsed(); let report = format::format_report(FormatParams { trace_id, duration, // ... })?; // Record domain metrics REPORT_GENERATION_DURATION.record( duration.as_secs_f64(), &[], ); REPORT_DATA_POINTS.record( report.total_data_points as f64, &[], ); REPORT_SECTIONS.record( report.sections.len() as f64, &[], ); span.record("report.id", report.id.to_string()); span.record( "report.indicators_count", report.indicators_used.len(), ); span.record( "report.duration_ms", report.generation_duration_ms, ); Ok(report) } ``` #### Pipeline Stage Spans Each stage uses `#[tracing::instrument]` with stage-specific fields: ```rust showLineNumbers title="src/pipeline/retrieve.rs" #[tracing::instrument( name = "pipeline_stage retrieve", skip(pool), fields( pipeline.stage = "retrieve", report.indicators_count, report.data_points, ) )] pub async fn retrieve( pool: &PgPool, indicator_codes: &[String], start_date: NaiveDate, end_date: NaiveDate, ) -> Result { let indicators = query_indicator_data( pool, indicator_codes, start_date, end_date, ) .await .map_err(AppError::Database)?; let total_data_points: usize = indicators.iter().map(|i| i.values.len()).sum(); let span = tracing::Span::current(); span.record( "report.indicators_count", indicators.len(), ); span.record("report.data_points", total_data_points); Ok(RetrieveResult { indicators, total_data_points }) } ``` ```rust showLineNumbers title="src/pipeline/analyze.rs" #[tracing::instrument( name = "pipeline_stage analyze", skip(llm_client, data), fields( pipeline.stage = "analyze", analysis.trends_found, analysis.key_findings, ) )] pub async fn analyze( llm_client: &LlmClient, model: &str, data: &[IndicatorData], ) -> Result { // Build data summary and prompt (omitted for brevity) let system = include_str!("../../data/schema-context.txt") .to_string(); let resp = llm_client .generate(&GenerateRequest { model: model.to_string(), system, prompt, temperature: 0.3, max_tokens: 2048, stage: "analyze".to_string(), }) .await .map_err(|e| AppError::Llm(e.to_string()))?; // Parse JSON response and preserve provider let provider = resp.provider.clone(); let mut analysis = parse_analysis_response( &resp.content, resp.input_tokens, resp.output_tokens, resp.cost_usd, )?; analysis.provider = provider; let span = tracing::Span::current(); span.record( "analysis.trends_found", analysis.trends.len(), ); span.record( "analysis.key_findings", analysis.key_findings.len(), ); Ok(analysis) } ``` The resulting trace shows clear parent-child relationships: `pipeline report` → `pipeline_stage analyze` → `gen_ai.chat gpt-4.1-mini`. Each stage is independently timed and attributed. #### Trace ID Correlation Store the OpenTelemetry trace ID alongside business data in your database. This lets you jump from a database record directly to its trace in Scout: ```sql showLineNumbers title="db/schema.sql" CREATE TABLE reports ( id UUID PRIMARY KEY, title TEXT NOT NULL, -- ... other fields ... trace_id TEXT, created_at TIMESTAMPTZ DEFAULT NOW() ); ``` Extract the trace ID from the current span context: ```rust showLineNumbers title="Extract trace ID" use opentelemetry::trace::TraceContextExt; use tracing_opentelemetry::OpenTelemetrySpanExt; let span = tracing::Span::current(); let context = span.context(); let trace_id = context .span() .span_context() .trace_id() .to_string(); ``` ### Retry and Fallback Observability LLM APIs are unreliable. Retries and provider fallbacks must be observable to understand real-world reliability. #### Retry with Exponential Backoff ```rust showLineNumbers title="src/llm/client.rs" pub async fn generate_with_retry( &self, provider: &dyn Provider, provider_name: &str, req: &GenerateRequest, ) -> anyhow::Result { let max_retries: u32 = 3; let mut last_err = None; for attempt in 0..max_retries { match self.generate_once( provider, provider_name, req, ).await { Ok(resp) => return Ok(resp), Err(err) => { tracing::warn!( attempt = attempt + 1, max_retries, provider = provider_name, model = %req.model, error = %err, "LLM call failed, retrying" ); if attempt > 0 { GEN_AI_RETRY_COUNT.add(1, &[ KeyValue::new( "gen_ai.provider.name", provider_name.to_string(), ), KeyValue::new( "gen_ai.request.model", req.model.clone(), ), ]); } last_err = Some(err); if attempt < max_retries - 1 { // Exponential backoff: 1s, 2s, 4s // (capped at 10s) let base = Duration::from_secs(1) * 2u32.pow(attempt); let base = base.min( Duration::from_secs(10), ); // 25% jitter to avoid thundering herd let jitter_ms = fastrand::u64( 0..=base.as_millis() as u64 / 4, ); let delay = base + Duration::from_millis(jitter_ms); tokio::time::sleep(delay).await; } } } } Err(last_err.unwrap_or_else(|| { anyhow::anyhow!("all retries exhausted") })) } ``` #### Provider Fallback When the primary provider fails after all retries, fall back to a secondary provider: ```rust showLineNumbers title="src/llm/client.rs" pub async fn generate( &self, req: &GenerateRequest, ) -> anyhow::Result { let result = self.generate_with_retry( self.primary.as_ref(), &self.primary_provider, req, ).await; match result { Ok(resp) => Ok(resp), Err(primary_err) => { if let Some(ref fallback) = self.fallback { tracing::warn!( primary_provider = %self.primary_provider, fallback_provider = %self.fallback_provider, error = %primary_err, "Primary provider failed, falling back" ); GEN_AI_FALLBACK_COUNT.add(1, &[]); let fallback_req = GenerateRequest { model: self.fallback_model.clone(), ..req.clone() }; self.generate_with_retry( fallback.as_ref(), &self.fallback_provider, &fallback_req, ).await } else { Err(anyhow::anyhow!( "primary provider {} failed \ after retries: {}", self.primary_provider, primary_err )) } } } } ``` Each retry creates a new `gen_ai.chat` span, so you see every attempt in the trace. The `gen_ai.client.retry.count` and `gen_ai.client.fallback.count` metrics let you build reliability dashboards and alert on degradation. ### HTTP Instrumentation Use tower-http's `TraceLayer` with custom `MakeSpan` and `OnResponse` implementations to capture HTTP metrics and set OpenTelemetry status codes: ```rust showLineNumbers title="src/main.rs" use tower_http::trace::{MakeSpan, OnResponse, TraceLayer}; #[derive(Clone)] struct HttpMakeSpan; impl MakeSpan for HttpMakeSpan { fn make_span(&mut self, request: &Request) -> Span { let method = request.method().as_str(); let path = request.uri().path(); tracing::info_span!( "HTTP request", otel.name = %format!("{} {}", method, path), http.method = %method, http.route = %path, http.target = %request.uri(), http.scheme = "http", http.flavor = ?request.version(), http.user_agent = request.headers() .get("user-agent") .and_then(|v| v.to_str().ok()) .unwrap_or(""), http.response.status_code = tracing::field::Empty, otel.status_code = tracing::field::Empty, ) } } #[derive(Clone)] struct HttpOnResponse; impl OnResponse for HttpOnResponse { fn on_response( self, response: &Response, latency: Duration, span: &Span, ) { let status = response.status().as_u16(); span.record( "http.response.status_code", status as i64, ); if status >= 500 { span.record("otel.status_code", "ERROR"); } else { span.record("otel.status_code", "OK"); } let latency_ms = latency.as_secs_f64() * 1000.0; let status_class = format!("{}xx", status / 100); HTTP_REQUESTS_TOTAL.add(1, &[ KeyValue::new( "http.status_code", status.to_string(), ), KeyValue::new( "http.status_class", status_class.clone(), ), ]); HTTP_REQUEST_DURATION.record(latency_ms, &[ KeyValue::new( "http.status_code", status.to_string(), ), KeyValue::new( "http.status_class", status_class, ), ]); tracing::info!( http.response.status_code = status, latency_ms = latency_ms, "finished processing request" ); } } // Apply to router let app = Router::new() .route("/api/reports", post(create_report)) .route("/api/reports", get(list_reports)) .layer( TraceLayer::new_for_http() .make_span_with(HttpMakeSpan) .on_response(HttpOnResponse), ); ``` ### Multi-Provider LLM Architecture ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The provider trait pattern lets you support multiple LLM backends (OpenAI, Anthropic, Google, Ollama) with consistent telemetry: ```rust showLineNumbers title="src/llm/mod.rs" #[derive(Debug, Clone)] pub struct GenerateRequest { pub model: String, pub system: String, pub prompt: String, pub temperature: f32, pub max_tokens: u32, pub stage: String, } #[derive(Debug, Clone)] pub struct GenerateResponse { pub content: String, pub model: String, pub input_tokens: u32, pub output_tokens: u32, pub cost_usd: f64, pub finish_reason: String, pub provider: String, } #[async_trait::async_trait] pub trait Provider: Send + Sync { async fn generate( &self, req: &GenerateRequest, ) -> anyhow::Result; fn name(&self) -> &str; } ``` The `LlmClient` wraps this trait with retry, fallback, and telemetry logic. Each provider implementation only needs to implement the `Provider` trait - all observability happens in the client layer. ```mdx-code-block ``` Uses the `async-openai` crate. Google and Ollama work through OpenAI-compatible endpoints with a different base URL: ```rust showLineNumbers title="src/llm/openai.rs" use async_openai::{ Client, config::OpenAIConfig, types::chat::{ ChatCompletionRequestMessage, ChatCompletionRequestSystemMessage, ChatCompletionRequestSystemMessageContent, ChatCompletionRequestUserMessage, ChatCompletionRequestUserMessageContent, CreateChatCompletionRequest, }, }; pub struct OpenAIProvider { client: Client, provider_name: String, } impl OpenAIProvider { pub fn new(api_key: &str) -> Self { let config = OpenAIConfig::new() .with_api_key(api_key); Self { client: Client::with_config(config), provider_name: "openai".to_string(), } } pub fn new_google(api_key: &str) -> Self { let config = OpenAIConfig::new() .with_api_key(api_key) .with_api_base( "https://generativelanguage.googleapis.com\ /v1beta/openai", ); Self { client: Client::with_config(config), provider_name: "google".to_string(), } } pub fn new_ollama(base_url: &str) -> Self { let config = OpenAIConfig::new() .with_api_key("ollama") .with_api_base(format!("{base_url}/v1")); Self { client: Client::with_config(config), provider_name: "ollama".to_string(), } } } #[async_trait::async_trait] impl Provider for OpenAIProvider { async fn generate( &self, req: &GenerateRequest, ) -> anyhow::Result { let messages = vec![ ChatCompletionRequestMessage::System( ChatCompletionRequestSystemMessage { content: ChatCompletionRequestSystemMessageContent::Text( req.system.clone(), ), name: None, }, ), ChatCompletionRequestMessage::User( ChatCompletionRequestUserMessage { content: ChatCompletionRequestUserMessageContent::Text( req.prompt.clone(), ), name: None, }, ), ]; #[allow(deprecated)] let request = CreateChatCompletionRequest { model: req.model.clone(), messages, temperature: Some(req.temperature), max_completion_tokens: Some(req.max_tokens), ..Default::default() }; let response = self.client.chat().create(request).await?; let content = response .choices .first() .and_then(|c| c.message.content.clone()) .unwrap_or_default(); let finish_reason = response .choices .first() .and_then(|c| c.finish_reason) .map(|r| format!("{r:?}").to_lowercase()) .unwrap_or_default(); let (input_tokens, output_tokens) = match &response.usage { Some(u) => (u.prompt_tokens, u.completion_tokens), None => (0, 0), }; Ok(GenerateResponse { content, model: response.model, input_tokens, output_tokens, cost_usd: 0.0, finish_reason, provider: String::new(), }) } fn name(&self) -> &str { &self.provider_name } } ``` ```mdx-code-block ``` Uses raw `reqwest` HTTP client since Anthropic has a different API format: ```rust showLineNumbers title="src/llm/anthropic.rs" use reqwest::header::{ CONTENT_TYPE, HeaderMap, HeaderValue, }; pub struct AnthropicProvider { client: reqwest::Client, api_key: String, } impl AnthropicProvider { pub fn new(api_key: &str) -> Self { Self { client: reqwest::Client::new(), api_key: api_key.to_string(), } } } #[async_trait::async_trait] impl Provider for AnthropicProvider { async fn generate( &self, req: &GenerateRequest, ) -> anyhow::Result { let mut headers = HeaderMap::new(); headers.insert( "x-api-key", HeaderValue::from_str(&self.api_key)?, ); headers.insert( "anthropic-version", HeaderValue::from_static("2023-06-01"), ); headers.insert( CONTENT_TYPE, HeaderValue::from_static("application/json"), ); let body = serde_json::json!({ "model": req.model, "max_tokens": req.max_tokens, "system": req.system, "messages": [{ "role": "user", "content": req.prompt, }], }); let response = self .client .post("https://api.anthropic.com/v1/messages") .headers(headers) .json(&body) .send() .await?; let status = response.status(); if !status.is_success() { let error_body = response.text().await.unwrap_or_default(); return Err(anyhow::anyhow!( "Anthropic API error ({}): {}", status, error_body )); } let resp: serde_json::Value = response.json().await?; let content = resp["content"] .as_array() .and_then(|arr| arr.first()) .and_then(|c| c["text"].as_str()) .unwrap_or_default() .to_string(); let input_tokens = resp["usage"]["input_tokens"] .as_u64() .unwrap_or(0) as u32; let output_tokens = resp["usage"]["output_tokens"] .as_u64() .unwrap_or(0) as u32; Ok(GenerateResponse { content, model: resp["model"] .as_str() .unwrap_or(&req.model) .to_string(), input_tokens, output_tokens, cost_usd: 0.0, finish_reason: resp["stop_reason"] .as_str() .unwrap_or_default() .to_string(), provider: String::new(), }) } fn name(&self) -> &str { "anthropic" } } ``` ```mdx-code-block ``` Provider initialization selects the backend based on configuration: ```rust showLineNumbers title="src/main.rs - Provider initialization" let primary: Arc = match config .llm_provider .as_str() { "anthropic" => Arc::new( AnthropicProvider::new(api_key), ), "google" => Arc::new( OpenAIProvider::new_google(api_key), ), "ollama" => Arc::new( OpenAIProvider::new_ollama(&base_url), ), _ => Arc::new(OpenAIProvider::new(api_key)), }; let llm_client = Arc::new(LlmClient { primary, fallback, primary_provider: config.llm_provider.clone(), fallback_provider: config.fallback_provider.clone(), fallback_model: config.fallback_model.clone(), }); ``` ### PII and Security LLM prompts and completions often contain sensitive data. Truncate and sanitize content before recording in span events. #### Content Truncation Always truncate prompt and completion content before adding to span events to avoid oversized spans and limit sensitive data exposure: ```rust showLineNumbers title="src/llm/client.rs" fn truncate(s: &str, max: usize) -> String { if s.len() <= max { s.to_string() } else { // Safe for multi-byte UTF-8 s.char_indices() .take_while(|&(i, _)| i < max) .map(|(_, c)| c) .collect() } } // Usage in span events span.add_event( "gen_ai.user.message", vec![KeyValue::new( "gen_ai.prompt", truncate(&req.prompt, 1000), )], ); span.add_event( "gen_ai.assistant.message", vec![KeyValue::new( "gen_ai.completion", truncate(&resp.content, 2000), )], ); ``` #### Security Considerations - **Truncate prompts** to 1000 characters and completions to 2000 characters to limit data exposure in telemetry - **Never record API keys** in span attributes or events - load keys from environment variables, not configuration files - **Use the OpenTelemetry Collector** `filter` processor to drop sensitive spans before they leave your network - **Strip HTTP headers** like `Authorization` from HTTP spans - tower-http's `TraceLayer` does not record headers by default, which is the safe behavior - **Consider disabling prompt/completion events** in production if your data is subject to GDPR, HIPAA, or PCI-DSS compliance requirements by removing the `add_event` calls ### Running Your Application ```mdx-code-block ``` Run with console output and debug logging: ```bash showLineNumbers title="Terminal" export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 export OTEL_SERVICE_NAME=ai-report-generator export LLM_PROVIDER=openai export OPENAI_API_KEY=sk-... export DATABASE_URL=postgres://postgres:postgres@localhost:5432/report_generator cargo run ``` ```mdx-code-block ``` Set environment-specific configuration: ```bash showLineNumbers title="Terminal" export SCOUT_ENVIRONMENT=production export OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4317 export OTEL_SERVICE_NAME=ai-report-generator export RUST_LOG=info,tower_http=info cargo run --release ``` ```mdx-code-block ``` Deploy the application, PostgreSQL, and OpenTelemetry Collector together: ```yaml showLineNumbers title="compose.yml" services: app: build: context: . dockerfile: Dockerfile ports: - "8080:8080" environment: - APP_PORT=8080 - DATABASE_URL=postgres://postgres:postgres@postgres:5432/report_generator?sslmode=disable - LLM_PROVIDER=${LLM_PROVIDER:-openai} - LLM_MODEL_CAPABLE=${LLM_MODEL_CAPABLE:-gpt-4.1} - LLM_MODEL_FAST=${LLM_MODEL_FAST:-gpt-4.1-mini} - FALLBACK_PROVIDER=${FALLBACK_PROVIDER:-anthropic} - FALLBACK_MODEL=${FALLBACK_MODEL:-claude-haiku-4-5-20251001} - OLLAMA_BASE_URL=${OLLAMA_BASE_URL:-http://host.docker.internal:11434} - OPENAI_API_KEY=${OPENAI_API_KEY:-} - ANTHROPIC_API_KEY=${ANTHROPIC_API_KEY:-} - GOOGLE_API_KEY=${GOOGLE_API_KEY:-} - OTEL_SERVICE_NAME=ai-report-generator - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4317 - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} depends_on: postgres: condition: service_healthy otel-collector: condition: service_started healthcheck: test: [ "CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:8080/api/health", ] interval: 10s timeout: 5s retries: 3 start_period: 15s postgres: image: postgres:18 environment: POSTGRES_DB: report_generator POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres ports: - "5432:5432" volumes: - pgdata:/var/lib/postgresql - ./db/schema.sql:/docker-entrypoint-initdb.d/01-schema.sql - ./db/seed.sql:/docker-entrypoint-initdb.d/02-seed.sql healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 otel-collector: image: otel/opentelemetry-collector-contrib:0.146.1 command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./config/otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" - "55679:55679" environment: - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-https://collector.base14.io} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} volumes: pgdata: ``` #### OpenTelemetry Collector Configuration ```yaml showLineNumbers title="config/otel-collector-config.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*/health.*")' batch: timeout: 10s send_batch_size: 1024 send_batch_max_size: 2048 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: detailed sampling_initial: 100 sampling_thereafter: 100 extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s service: extensions: [health_check, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, attributes, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] ``` #### Dockerfile Multi-stage build for minimal production images: ```dockerfile showLineNumbers title="Dockerfile" FROM rust:1.92-alpine AS builder WORKDIR /build RUN apk add --no-cache musl-dev openssl-dev \ openssl-libs-static pkgconfig protobuf-dev COPY Cargo.toml Cargo.lock ./ RUN mkdir src && echo "fn main() {}" > src/main.rs RUN cargo build --release 2>/dev/null || true RUN rm -rf src COPY src ./src COPY data ./data RUN touch src/main.rs && cargo build --release --bin server FROM alpine:3.23 RUN apk add --no-cache ca-certificates tzdata wget \ && adduser -D -g '' -u 1001 appuser WORKDIR /app COPY --from=builder /build/target/release/server . COPY --from=builder /build/_shared/pricing.json /app/_shared/pricing.json USER appuser EXPOSE 8080 HEALTHCHECK --interval=30s --timeout=5s \ --start-period=15s --retries=3 \ CMD wget -q --spider http://localhost:8080/api/health \ || exit 1 CMD ["./server"] ``` ```mdx-code-block ``` ### Troubleshooting #### Verify Telemetry Is Working Check that spans are being exported by looking for the telemetry initialization log: ```bash showLineNumbers title="Terminal" docker compose logs app 2>&1 | grep "Telemetry initialized" ``` #### Enable Debug Logging ```bash showLineNumbers title="Terminal" export RUST_LOG=debug,h2=info,hyper=info ``` This enables debug output for your application while suppressing noisy HTTP/2 and Hyper transport logs. #### Check Collector Health ```bash showLineNumbers title="Terminal" curl http://localhost:13133/health # {"status":"Server available","..."} ``` ##### Issue: No spans appearing in Scout **Solutions:** 1. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` points to the collector (e.g., `http://otel-collector:4317` in Docker, `http://localhost:4317` locally) 2. Check that `telemetry_guard.shutdown()` is called before process exit - the batch exporter flushes on shutdown 3. Add a `debug` exporter to the collector config to see incoming spans in collector logs ##### Issue: Spans missing parent-child relationships **Solutions:** 1. Ensure async operations use `.instrument(span.clone())` to propagate the span context across `await` points 2. Use `#[tracing::instrument]` on async functions - it automatically creates child spans 3. Enable `tracing` feature on `tokio` in Cargo.toml: `tokio = { features = ["tracing"] }` ##### Issue: Metrics not appearing **Solutions:** 1. Verify `PeriodicReader` interval - metrics are batched and exported every 15 seconds by default 2. Check that `global::set_meter_provider()` is called before any metric instruments are created 3. Ensure the collector `metrics` pipeline is configured with the OTLP receiver ##### Issue: LLM span attributes are empty **Solutions:** 1. Check that `span.record()` is called with the correct field name matching the `tracing::info_span!` declaration 2. Verify `tracing::field::Empty` fields are declared in the span macro - you cannot record fields that were not declared 3. Ensure `.instrument(span.clone())` is used, not `.instrument(tracing::Span::current())` ### Performance Considerations #### Expected Impact | Metric | Without OTel | With OTel | Delta | | ------------- | ------------ | --------- | ---------- | | Latency (p99) | baseline | +0.5-1ms | < 1ms | | Memory | baseline | +5-10 MB | minimal | | CPU | baseline | +1-2% | negligible | Rust's zero-cost abstractions mean OpenTelemetry overhead is minimal compared to Python or Node.js. The batch exporter handles I/O asynchronously, so span creation is nearly free. #### Optimization Tips ##### 1. Use Batch Export The default `with_batch_exporter()` is already optimal. Avoid `SimpleSpanProcessor` in production - it blocks on every span. ##### 2. Tune Metric Export Interval ```rust showLineNumbers title="Adjust interval for high-throughput" let metric_reader = PeriodicReader::builder(metric_exporter) .with_interval(Duration::from_secs(30)) // 30s for lower overhead .build(); ``` ##### 3. Filter Noisy Spans at the Collector Drop health check and readiness probe spans in the collector rather than in application code: ```yaml showLineNumbers title="config/otel-collector-config.yaml" processors: filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*/health.*")' ``` ##### 4. Limit Attribute Sizes Truncate prompt and completion content to avoid oversized spans: ```rust showLineNumbers title="Truncation limits" // Prompts: 1000 chars max truncate(&req.prompt, 1000) // Completions: 2000 chars max truncate(&resp.content, 2000) // System instructions: 500 chars max truncate(&req.system, 500) ``` ##### 5. Conditional Span Recording Skip detailed span events in high-throughput scenarios: ```rust showLineNumbers title="Conditional recording" if config.record_prompt_events { span.add_event( "gen_ai.user.message", vec![KeyValue::new( "gen_ai.prompt", truncate(&req.prompt, 1000), )], ); } ``` ### FAQ #### How much overhead does OpenTelemetry add to Rust applications? Less than 1ms per request in most cases. Rust's zero-cost abstractions and the batch exporter design mean span creation is a few microseconds. The OTLP gRPC export happens asynchronously and does not block request processing. #### What Rust crates do I need for OpenTelemetry LLM tracing? Yes. The `tracing` crate is the idiomatic Rust instrumentation API. The `tracing-opentelemetry` crate bridges `tracing` spans to OpenTelemetry spans. The `opentelemetry` crate provides the export pipeline (OTLP, metrics, logs). You write code using `tracing` macros and the OpenTelemetry SDK handles export. #### Should I use the tracing crate or OpenTelemetry API directly in Rust? You can, but it is not recommended for Rust applications. The `tracing` ecosystem integrates with Tokio, tower, SQLx, and most Rust libraries. Using the OpenTelemetry API directly would miss automatic span propagation across async boundaries and structured log integration. #### Does Rust have auto-instrumentation for LLM APIs like Python does? No. Rust does not have LLM auto-instrumentation libraries like Python's `opentelemetry-instrumentation-anthropic` or Node.js instrumentors. You create GenAI spans manually, which gives you full control over which attributes to record and how to handle provider-specific response formats. #### How do I track costs across multiple LLM providers? Use the `gen_ai.client.cost` counter metric with `gen_ai.provider.name` and `gen_ai.request.model` dimensions. Load pricing from a configuration file and calculate cost per call based on input/output token counts. The metric dimensions let you build per-provider and per-model cost dashboards. #### Can I use Ollama (local models) with the same instrumentation? Yes. The provider trait pattern abstracts away the backend. Ollama exposes an OpenAI-compatible API, so you can use the same `async-openai` client pointed at `http://localhost:11434/v1`. All GenAI spans and metrics work identically - only `gen_ai.provider.name` and `server.address` change. #### How do I reduce trace volume from LLM applications? Use the collector's `filter` processor to drop noisy spans (health checks, readiness probes). For high-volume applications, use the collector's `probabilistic_sampler` processor. You can also disable prompt/completion span events to reduce span size while keeping the core GenAI attributes. #### What happens if the collector is unavailable? The batch exporter buffers spans in memory and retries export. If the collector remains unavailable, buffered spans are eventually dropped. Your application continues to run normally - telemetry export is non-blocking. Configure the collector with health checks and ensure it starts before your application in Docker Compose. #### How do I correlate traces with database records? Extract the trace ID from the current span context using `span.context().span().span_context().trace_id()` and store it in a `trace_id` column in your database table. This lets you query Scout for the exact trace that produced a specific database record. #### How do I export OpenTelemetry data over HTTP instead of gRPC in Rust? Yes. Replace `with_tonic()` with `with_http()` in the exporter builders and point to port 4318 instead of 4317. gRPC is recommended for production because it supports streaming and has lower overhead for high-volume telemetry. ### What's Next? #### Advanced Topics - [LLM Observability (Python)](../llm-observability) - Python equivalent with auto-instrumentation patterns - [Axum Instrumentation](../../instrument/apps/auto-instrumentation/axum.md) — General Axum APM without AI-specific patterns - [Rust Custom Instrumentation](../../instrument/apps/custom-instrumentation/rust.md) - Manual OpenTelemetry SDK usage for Rust #### Scout Platform Features - [Creating Alerts](../creating-alerts-with-logx.md) - Set up alerts for LLM error rates and cost thresholds - [Dashboards and Alerts](../../operate/dashboards-and-alerts.md) - Build dashboards for LLM metrics in Scout #### Deployment and Operations - [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) - Collector deployment guide - [Kubernetes Helm Setup](../../instrument/collector-setup/kubernetes-helm-setup.md) - Production Kubernetes deployment ### Complete Example The full working implementation is available in the examples repository: **[rust/ai-report-generator](https://github.com/base-14/examples/tree/main/rust/ai-report-generator)** This example implements: - Axum REST API with 5 endpoints - PostgreSQL with SQLx for data storage - Multi-provider LLM support (OpenAI, Anthropic, Google, Ollama) with automatic fallback - 4-stage pipeline (retrieve → analyze → generate → format) - Full GenAI semantic convention spans and metrics - Three-pillar telemetry (traces, metrics, logs) via OTLP - Docker Compose deployment with collector - Trace ID correlation in database records - Token usage tracking and cost calculation #### Quick Start ```bash showLineNumbers title="Terminal" cd rust/ai-report-generator # Set your API key export OPENAI_API_KEY=sk-... # Start all services docker compose up -d # Generate a report curl -X POST http://localhost:8080/api/reports \ -H "Content-Type: application/json" \ -d '{ "indicators": ["GDP", "UNRATE", "CPIAUCSL"], "start_date": "2020-01-01", "end_date": "2023-12-01" }' ``` #### Project Structure ```text showLineNumbers title="Project layout" src/ ├── main.rs # Server, router, HTTP spans ├── config.rs # Environment configuration ├── telemetry/ │ ├── init.rs # OTEL SDK initialization │ └── metrics.rs # GenAI + HTTP + domain metrics ├── llm/ │ ├── mod.rs # Provider trait, request/response │ ├── client.rs # Retry, fallback, GenAI spans │ ├── openai.rs # OpenAI/Google/Ollama provider │ ├── anthropic.rs # Anthropic provider │ └── pricing.rs # Cost calculation ├── pipeline/ │ ├── orchestrator.rs # Pipeline coordinator │ ├── retrieve.rs # Stage 1: DB queries │ ├── analyze.rs # Stage 2: LLM analysis │ ├── generate.rs # Stage 3: LLM narrative │ └── format.rs # Stage 4: Report assembly ├── db/ # Database queries ├── routes/ # HTTP handlers └── error.rs # Error types ``` ### References - [OpenTelemetry Rust SDK](https://opentelemetry.io/docs/languages/rust/) - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [tracing-opentelemetry crate](https://docs.rs/tracing-opentelemetry/) - [async-openai crate](https://docs.rs/async-openai/) ### Related Guides - [LLM Observability (Python)](../llm-observability) - Python equivalent of this guide with auto-instrumentation patterns - [Axum Instrumentation](../../instrument/apps/auto-instrumentation/axum.md) — General Axum APM setup - [Rust Custom Instrumentation](../../instrument/apps/custom-instrumentation/rust.md) - Manual OpenTelemetry SDK for Rust - [Vercel AI SDK](../../instrument/apps/auto-instrumentation/vercel-ai-sdk.md) — TypeScript AI pipeline monitoring --- ## Spring AI OpenTelemetry Instrumentation - Java LLM Tracing & Metrics Guide import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ## Java AI Observability Implement unified observability for Java AI applications using OpenTelemetry and Spring AI. This guide shows you how to instrument a conversational AI customer support agent with three-layer instrumentation unique to the Java ecosystem — the OpenTelemetry Java Agent for zero-code auto-capture of HTTP and database spans, Spring AI's built-in Micrometer observations bridged to OpenTelemetry for ChatModel and VectorStore spans, and manual OpenTelemetry API calls for GenAI semantic convention spans with token, cost, and pipeline context. The result is a single correlated trace that connects every layer of your AI application, from HTTP entry through intent classification, RAG retrieval, tool calling, and LLM completion. Java AI applications have a distinct observability advantage over other languages. An LLM call is not just an HTTP request - it carries semantic meaning: which model was used, how many tokens were consumed, what it cost, whether the response was a fallback from another provider. Java uniquely offers three composable instrumentation layers: the OpenTelemetry Java Agent (`-javaagent` flag) provides zero-code auto-instrumentation for HTTP server/client spans, JDBC queries, and R2DBC connections. Spring AI emits Micrometer observations for ChatModel and VectorStore operations, which the `micrometer-tracing-bridge-otel` dependency bridges directly into OpenTelemetry. And the manual OpenTelemetry API (`GlobalOpenTelemetry.getTracer()` / `getMeter()`) adds GenAI semantic convention attributes and custom metrics that neither auto layer provides. All three layers share the same trace context, producing a unified trace with zero instrumentation gaps. Whether you are building AI support systems with Spring AI, integrating OpenAI, Anthropic, or Ollama as LLM providers, or running local models for development, this guide provides production-ready patterns for unified AI observability in Java. You will learn how to set up three-pillar telemetry (traces, metrics, logs), create GenAI spans with the correct semantic conventions, define 11 standard metrics covering token usage, cost, duration, errors, retries, and fallbacks, instrument a 6-stage AI support pipeline with parent-child spans, implement Spring AI tool calling with `@Tool` methods, set up RAG with pgvector and track retrieval quality metrics, implement multi-provider LLM support with retry and fallback observability, track domain-specific business metrics like conversation duration and escalation rates, and deploy with Docker Compose and the OpenTelemetry Collector - all visible in a single trace on base14 Scout. :::info Cross-references For general LLM observability patterns applicable to any language, see the [LLM Observability guide](../llm-observability). This guide focuses specifically on Java and Spring AI integration patterns. For Rust AI applications, see the [Rust LLM Observability guide](../rust-llm-observability). For non-AI Java web application instrumentation, check if a Spring Boot auto-instrumentation guide is available under [auto-instrumentation](../../../instrument/apps/auto-instrumentation/). ::: :::tip TL;DR Add the OpenTelemetry Java Agent (`-javaagent`), Spring AI's Micrometer bridge (`micrometer-tracing-bridge-otel`), and manual `GlobalOpenTelemetry` calls to get unified traces across HTTP, database, LLM, and pipeline layers. This guide covers Spring Boot 4.0.3 + Spring AI 2.0 with OpenAI, Anthropic, and Ollama. ::: :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### Who This Guide Is For This documentation is designed for: - **Java/Spring AI developers**: building LLM-powered features (customer support, chatbots, AI assistants) and needing visibility into model performance, cost, and pipeline throughput - **Backend developers**: adding AI capabilities to existing Spring Boot applications and wanting unified tracing across HTTP, database, and LLM layers - **Platform teams**: standardizing observability across Java AI services and traditional microservices using OpenTelemetry - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-standard OpenTelemetry - **DevOps engineers**: deploying Java AI applications with production monitoring, cost alerting, and pipeline health tracking ### Overview This guide demonstrates how to: - Set up three-layer OpenTelemetry for a Java AI application (Java Agent + Spring AI + manual OTel API) - Create custom LLM spans following OpenTelemetry GenAI semantic conventions - Define GenAI metrics for token usage, cost, duration, errors, retries, and fallbacks - Instrument a 6-stage AI support pipeline with parent-child spans - Implement Spring AI tool calling with observability (`@Tool` methods) - Set up RAG with pgvector and track retrieval quality metrics - Implement multi-provider LLM support (OpenAI, Anthropic, Ollama) with retry and fallback observability - Track domain-specific business metrics (conversation duration, escalation rates, tool success) - Deploy with Docker Compose and the OpenTelemetry Collector ### Prerequisites Before starting, ensure you have: - **Java 25+** installed (21+ minimum) - **Spring Boot 4.0.3+** - **Spring AI 2.0+** (BOM `2.0.0-M2` or later) - **Scout Collector** configured and accessible from your application - see [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) for local development - **Basic understanding of OpenTelemetry concepts** (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ------------------------ | --------------- | ------------------- | | Java | 21 | 25+ | | Spring Boot | 3.4+ | 4.0.3+ | | Spring AI | 1.0.0 | 2.0.0-M2+ | | OpenTelemetry Java Agent | 2.0.0 | 2.25+ | | OpenTelemetry API | 1.40.0 | 1.52+ | | PostgreSQL (pgvector) | 15 | 18+ | ### The Unified Trace The core value of OpenTelemetry for Java AI applications is the **unified trace** - a single trace ID that connects every instrumentation layer, from HTTP entry through pipeline orchestration to LLM completions and database queries. Here is what a trace looks like for a customer support chat request that spans all three layers: ```text showLineNumbers title="Single trace spanning all three instrumentation layers" POST /api/chat 3.8s [Layer 1: Java Agent] ├─ support_conversation 3.7s [Layer 3: Manual OTel] │ ├─ classify_intent 0.4s [Layer 3: Manual OTel] │ │ └─ gen_ai.chat gpt-4.1-mini 0.3s [Layer 3: Manual OTel] │ │ └─ ChatModel 0.3s [Layer 2: Spring AI] │ │ └─ HTTP POST api.openai.com 0.3s [Layer 1: Java Agent] │ ├─ rag_retrieval 0.1s [Layer 3: Manual OTel] │ │ └─ VectorStore 0.1s [Layer 2: Spring AI] │ │ └─ db.query pgvector 15ms [Layer 1: Java Agent] │ ├─ generate_response 3.1s [Layer 3: Manual OTel] │ │ └─ gen_ai.chat gpt-4.1 3.0s [Layer 3: Manual OTel] │ │ └─ ChatModel 3.0s [Layer 2: Spring AI] │ │ ├─ HTTP POST api.openai.com 1.2s [Layer 1: Java Agent] │ │ ├─ @Tool getOrderStatus 8ms [Layer 2: Spring AI] │ │ │ └─ db.query orders 5ms [Layer 1: Java Agent] │ │ └─ HTTP POST api.openai.com 1.7s [Layer 1: Java Agent] │ └─ escalation_check 1ms [Layer 3: Manual OTel] ``` Three instrumentation layers work together in a single trace: - **Layer 1 - Java Agent** (zero-code): Captures the outermost HTTP server span, outbound HTTP client spans to LLM APIs, and JDBC database query spans - all without any code changes - **Layer 2 - Spring AI** (Micrometer bridge): Adds ChatModel call spans, VectorStore query spans, and `@Tool` method execution spans as children of the current trace context - **Layer 3 - Manual OTel API**: Adds GenAI semantic convention attributes (model, tokens, cost), pipeline orchestration spans (`support_conversation`, `classify_intent`, `rag_retrieval`), and custom metrics The Java Agent provides context propagation that ties everything together. Spring AI observations nest inside that context. Manual spans add the GenAI-specific metadata that neither auto layer provides. The result is a trace where you can see that a 3.8-second customer support response spent 0.4 seconds on intent classification with `gpt-4.1-mini`, 0.1 seconds on RAG retrieval, and 3.1 seconds on response generation with `gpt-4.1` including a tool call to look up order status. ### Three-Layer Architecture Java AI applications benefit from a three-layer instrumentation approach that no other language ecosystem matches. Each layer captures telemetry at a different level of abstraction, and all three compose into unified traces through shared OpenTelemetry context propagation. | Layer | Source | What It Captures | | ------------------ | ------------------------------------------------------------ | ----------------------------------------------------------------------- | | 1. Java Agent | `opentelemetry-javaagent.jar` (zero-code) | HTTP server/client spans, JDBC/R2DBC queries, Spring WebFlux | | 2. Spring AI | Micrometer observations via `micrometer-tracing-bridge-otel` | ChatModel calls, VectorStore operations, tool execution | | 3. Manual OTel API | `GlobalOpenTelemetry.getTracer()` / `getMeter()` | GenAI semantic convention spans, custom metrics, pipeline orchestration | #### Layer 1: Java Agent (Zero-Code Auto-Instrumentation) The OpenTelemetry Java Agent attaches to the JVM via the `-javaagent` flag and automatically instruments HTTP, database, and messaging frameworks with zero code changes. It provides the outermost spans in every trace and handles context propagation between all layers. What it captures: - **HTTP server spans** - Spring WebFlux incoming requests with method, path, status code, and latency - **HTTP client spans** - outbound calls to LLM provider APIs (OpenAI, Anthropic) with URL, status, and duration - **JDBC spans** - tool database queries (order lookups, product searches) with SQL statement and execution time - **R2DBC spans** - reactive database access for conversation persistence Configuration is entirely via environment variables. No code changes or dependency additions are needed - the agent injects instrumentation at the bytecode level. The Dockerfile downloads the agent JAR and attaches it at startup: ```dockerfile showLineNumbers title="Dockerfile" FROM gradle:9.2.1-jdk25 AS builder WORKDIR /app COPY build.gradle settings.gradle ./ COPY gradle ./gradle COPY src ./src RUN gradle build -x test --no-daemon FROM eclipse-temurin:25-jre WORKDIR /app ADD https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.25.0/opentelemetry-javaagent.jar /app/opentelemetry-javaagent.jar COPY --from=shared pricing.json /app/pricing.json COPY --from=builder /app/build/libs/ai-customer-support-0.0.1-SNAPSHOT.jar /app/app.jar EXPOSE 8080 ENTRYPOINT ["java", \ "-javaagent:/app/opentelemetry-javaagent.jar", \ "-jar", "/app/app.jar"] ``` The agent is configured through environment variables in the Docker Compose service definition: ```yaml showLineNumbers title="compose.yml (agent environment variables)" environment: OTEL_SERVICE_NAME: ai-customer-support OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_INSTRUMENTATION_COMMON_DEFAULT_ENABLED: "true" ``` #### Layer 2: Spring AI Observations (Micrometer Bridge) Spring AI emits Micrometer observations for ChatModel and VectorStore operations. The `micrometer-tracing-bridge-otel` dependency bridges these observations directly into OpenTelemetry, so they appear as child spans in the same trace context established by the Java Agent. What it captures: - **ChatModel call spans** - model name, provider, and call duration for every `chatModel.call()` invocation - **VectorStore query spans** - similarity search operations against pgvector - **Tool execution spans** - `@Tool` method invocations triggered by the LLM's tool-calling protocol Configuration is in `application.yml`. The `management.otlp` section configures the OTLP export endpoints, `management.tracing` sets the sampling rate, and `spring.ai.chat.observations` controls whether prompt/completion content is included in spans: ```yaml showLineNumbers title="src/main/resources/application.yml" management: endpoints: web: exposure: include: health,info,metrics otlp: tracing: endpoint: ${OTEL_EXPORTER_OTLP_ENDPOINT:http://localhost:4318}/v1/traces metrics: export: url: ${OTEL_EXPORTER_OTLP_ENDPOINT:http://localhost:4318}/v1/metrics tracing: sampling: probability: 1.0 spring: ai: chat: observations: include-input: false include-output: false ``` Setting `include-input` and `include-output` to `false` prevents prompt and completion content from being recorded in Micrometer observation spans. This is a production safety default - prompt content may contain PII. If you need content capture for debugging, the manual OTel layer (Layer 3) provides PII-scrubbed content recording controlled by the `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT` environment variable. #### Layer 3: Manual OTel API (GenAI Semantic Conventions) Direct use of `GlobalOpenTelemetry.getTracer()` and `GlobalOpenTelemetry.getMeter()` provides the GenAI-specific telemetry that neither the Java Agent nor Spring AI observations capture. This layer adds OpenTelemetry GenAI semantic convention attributes to LLM spans, defines custom metrics for token usage and cost tracking, and creates pipeline orchestration spans that give business context to traces. What it captures: - **`gen_ai.chat {model}` spans** with full GenAI semantic convention attributes (`gen_ai.operation.name`, `gen_ai.provider.name`, `gen_ai.request.model`, `gen_ai.usage.input_tokens`, `gen_ai.usage.output_tokens`, `gen_ai.usage.cost_usd`, `gen_ai.response.finish_reasons`) - **Custom GenAI metrics** - token usage histograms, cost counters, duration histograms, error counters, retry counters, fallback counters - **Domain-specific pipeline spans** - `support_conversation`, `classify_intent`, `rag_retrieval`, `generate_response`, `escalation_check` Why this layer is needed: Spring AI's Micrometer observations record that a ChatModel call happened and how long it took, but they do not include GenAI semantic conventions like token counts, cost, error classification, or the specific model that responded (which may differ from the requested model after fallback). The manual OTel API adds this layer. The tracer and meter are initialized from `GlobalOpenTelemetry`, which the Java Agent populates at startup: ```java showLineNumbers title="Tracer and Meter initialization pattern" private static final Tracer tracer = GlobalOpenTelemetry.getTracer("ai-customer-support"); private static final Meter meter = GlobalOpenTelemetry.getMeter("ai-customer-support"); ``` #### How the Layers Compose The three layers compose through OpenTelemetry's context propagation. The Java Agent creates the outermost HTTP server span and propagates the trace context to all child operations. When Spring AI's Micrometer-bridged observations start, they pick up the current trace context and create child spans. When manual `tracer.spanBuilder()` calls start, they also inherit the current context. The result is a single trace where Layer 1 provides the HTTP and database frame, Layer 2 adds AI framework observations, and Layer 3 adds GenAI semantic convention attributes and custom metrics. No explicit context passing is needed between layers - `Span.current()` and `span.makeCurrent()` handle the composition automatically. ### Installation Add the following dependencies to your `build.gradle`. The project uses Spring Boot 4.0.3 with the Spring AI BOM for version management: ```groovy showLineNumbers title="build.gradle" plugins { id 'java' id 'org.springframework.boot' version '4.0.3' id 'io.spring.dependency-management' version '1.1.7' } java { toolchain { languageVersion = JavaLanguageVersion.of(25) } } dependencyManagement { imports { mavenBom "org.springframework.ai:spring-ai-bom:2.0.0-M2" } } dependencies { // Web (reactive) implementation 'org.springframework.boot:spring-boot-starter-webflux' // Observability implementation 'org.springframework.boot:spring-boot-starter-actuator' implementation 'io.micrometer:micrometer-tracing-bridge-otel' implementation 'io.opentelemetry:opentelemetry-exporter-otlp' implementation 'io.opentelemetry:opentelemetry-api' // Spring AI - LLM providers implementation 'org.springframework.ai:spring-ai-starter-model-openai' implementation 'org.springframework.ai:spring-ai-starter-model-anthropic' implementation 'org.springframework.ai:spring-ai-starter-model-ollama' // Spring AI - pgvector RAG implementation 'org.springframework.ai:spring-ai-starter-vector-store-pgvector' // Database (reactive + JDBC for pgvector) implementation 'org.springframework.boot:spring-boot-starter-data-r2dbc' implementation 'org.springframework.boot:spring-boot-starter-jdbc' implementation 'org.postgresql:r2dbc-postgresql' implementation 'org.postgresql:postgresql' // JSON implementation 'com.fasterxml.jackson.core:jackson-databind' } ``` Key dependency groups: - **Observability bridge**: `micrometer-tracing-bridge-otel` connects Spring AI's Micrometer observations to OpenTelemetry. `opentelemetry-exporter-otlp` sends telemetry to the Collector. `opentelemetry-api` provides the manual tracer/meter API for Layer 3. - **Spring AI providers**: Each `spring-ai-starter-model-{provider}` dependency brings in the ChatModel implementation for that provider. You can include multiple providers for fallback support. - **Spring AI BOM**: The `spring-ai-bom:2.0.0-M2` import manages version alignment across all Spring AI dependencies. - **Dual database drivers**: R2DBC for reactive conversation persistence, JDBC for pgvector RAG and Spring AI tool methods (which use `JdbcTemplate`). The OpenTelemetry Java Agent is not a Gradle dependency - it is downloaded separately and attached via the `-javaagent` JVM flag. The Dockerfile handles this automatically by downloading the agent JAR from the [OpenTelemetry Java Agent releases](https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases) page. For local development without Docker, download the JAR manually and pass it as a JVM argument: ```bash showLineNumbers title="Local development agent setup" curl -L -o opentelemetry-javaagent.jar \ https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.25.0/opentelemetry-javaagent.jar java -javaagent:opentelemetry-javaagent.jar \ -jar build/libs/ai-customer-support-0.0.1-SNAPSHOT.jar ``` ### Spring AI OpenTelemetry Configuration This section covers every configuration surface in the application: Spring Boot OTLP export settings, provider-specific Spring AI configuration, application properties for LLM routing, and the provider resolution logic that maps configuration strings to Spring AI bean names. #### Spring Boot OpenTelemetry Configuration The `management:` block in `application.yml` configures how Spring Boot exports telemetry to the OpenTelemetry Collector. This was introduced in the [Three-Layer Architecture](#layer-2-spring-ai-observations-micrometer-bridge) section - here is the full breakdown of each setting: ```yaml showLineNumbers title="src/main/resources/application.yml" management: endpoints: web: exposure: include: health,info,metrics otlp: tracing: endpoint: ${OTEL_EXPORTER_OTLP_ENDPOINT:http://localhost:4318}/v1/traces metrics: export: url: ${OTEL_EXPORTER_OTLP_ENDPOINT:http://localhost:4318}/v1/metrics tracing: sampling: probability: 1.0 ``` - **`management.endpoints.web.exposure.include`** - Exposes Actuator endpoints for health checks, application info, and Micrometer metrics. These are useful for Kubernetes liveness/readiness probes and debugging metric registration. - **`management.otlp.tracing.endpoint`** - The OTLP HTTP endpoint for trace export. Defaults to `http://localhost:4318/v1/traces` for local development. In Docker Compose, the `OTEL_EXPORTER_OTLP_ENDPOINT` environment variable overrides this to point at the Collector container. - **`management.otlp.metrics.export.url`** - The OTLP HTTP endpoint for metric export. Uses the same base URL as traces but with the `/v1/metrics` path. - **`management.tracing.sampling.probability`** - Controls the sampling rate. `1.0` means 100% of traces are sampled - appropriate for development and low-traffic production. For high-traffic services, reduce this to `0.1` (10%) or use the Collector's tail-sampling processor for more intelligent sampling. #### Provider Configuration Spring AI auto-configures a ChatModel bean for each provider that has a starter dependency on the classpath. Each provider requires its own configuration block under `spring.ai`. The application supports OpenAI, Anthropic, and Ollama - you configure the one you want to use and set `app.llm.provider` to select it at runtime. **OpenAI** ```yaml showLineNumbers title="src/main/resources/application.yml" spring: ai: openai: api-key: ${OPENAI_API_KEY:} chat: options: model: ${LLM_MODEL_CAPABLE:gpt-4.1} temperature: ${DEFAULT_TEMPERATURE:0.3} embedding: options: model: ${EMBEDDING_MODEL:text-embedding-3-small} ``` OpenAI is the default provider. The `api-key` is read from the `OPENAI_API_KEY` environment variable. The `chat.options.model` sets the default model for ChatModel calls - this can be overridden per-request via `ChatOptions.builder()`. The `embedding.options.model` configures the embedding model used by the pgvector VectorStore for RAG retrieval. **Anthropic** ```yaml showLineNumbers title="src/main/resources/application.yml" spring: ai: anthropic: api-key: ${ANTHROPIC_API_KEY:} chat: options: model: ${LLM_MODEL_CAPABLE:claude-sonnet-4-6} ``` Anthropic is configured as either the primary or fallback provider. Note that Anthropic does not provide an embedding model through Spring AI, so the application uses OpenAI embeddings for RAG even when Anthropic is the primary chat provider. **Ollama** ```yaml showLineNumbers title="src/main/resources/application-ollama.yml" spring: autoconfigure: exclude: - org.springframework.ai.model.openai.autoconfigure.OpenAiChatAutoConfiguration - org.springframework.ai.model.openai.autoconfigure.OpenAiEmbeddingAutoConfiguration - org.springframework.ai.model.openai.autoconfigure.OpenAiImageAutoConfiguration - org.springframework.ai.model.openai.autoconfigure.OpenAiAudioSpeechAutoConfiguration - org.springframework.ai.model.openai.autoconfigure.OpenAiAudioTranscriptionAutoConfiguration - org.springframework.ai.model.openai.autoconfigure.OpenAiModerationAutoConfiguration - org.springframework.ai.model.anthropic.autoconfigure.AnthropicChatAutoConfiguration ai: ollama: embedding: options: model: embeddinggemma vectorstore: pgvector: dimensions: 768 app: llm: provider: ollama model-capable: qwen3:latest model-fast: gemma3:4b fallback-provider: ollama fallback-model: gemma3:12b ``` The Ollama profile (`application-ollama.yml`) disables OpenAI and Anthropic auto-configuration since those providers are not needed when running locally. It also switches the embedding model to `embeddinggemma` and reduces pgvector dimensions to 768 to match the local embedding model's output size. Activate this profile with `SPRING_PROFILES_ACTIVE=ollama`. #### Application Properties The `AppConfig` record maps the `app.llm` configuration section to a type-safe Java record using Spring Boot's `@ConfigurationProperties`: ```java showLineNumbers title="src/main/java/com/example/support/config/AppConfig.java" @ConfigurationProperties(prefix = "app.llm") public record AppConfig( String provider, String modelCapable, String modelFast, String fallbackProvider, String fallbackModel, int maxTokens, double temperature ) {} ``` These properties control LLM routing at the application level. The corresponding YAML configuration provides defaults that environment variables can override: ```yaml showLineNumbers title="src/main/resources/application.yml" app: llm: provider: ${LLM_PROVIDER:openai} model-capable: ${LLM_MODEL_CAPABLE:gpt-4.1} model-fast: ${LLM_MODEL_FAST:gpt-4.1-mini} fallback-provider: ${FALLBACK_PROVIDER:anthropic} fallback-model: ${FALLBACK_MODEL:claude-haiku-4-5-20251001} max-tokens: ${DEFAULT_MAX_TOKENS:1024} temperature: ${DEFAULT_TEMPERATURE:0.3} ``` - **`provider`** - The primary LLM provider (`openai`, `anthropic`, or `ollama`). Determines which ChatModel bean is used for all LLM calls. - **`model-capable`** - The high-quality model used for response generation and complex tasks. Maps to `config.modelCapable()` in Java. - **`model-fast`** - The faster, cheaper model used for intent classification and simple tasks. Maps to `config.modelFast()` in Java. - **`fallback-provider`** / **`fallback-model`** - The provider and model to use when the primary provider fails after all retries are exhausted. - **`max-tokens`** / **`temperature`** - Default generation parameters applied to every LLM call via `ChatOptions`. #### Provider Resolution The `LlmConfig` class resolves the provider string from configuration to the correct Spring AI `ChatModel` bean. Spring AI auto-configures a ChatModel bean for each provider on the classpath - `LlmConfig.resolveChatModel()` maps the provider name to the Spring-managed bean name: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmConfig.java" @Configuration public class LlmConfig { public static final Map PROVIDER_SERVERS = Map.of( "openai", "api.openai.com", "anthropic", "api.anthropic.com", "google", "generativelanguage.googleapis.com", "ollama", "localhost" ); public static final Map PROVIDER_PORTS = Map.of( "openai", 443, "anthropic", 443, "google", 443, "ollama", 11434 ); public static ChatModel resolveChatModel( String provider, Map chatModels ) { String beanName = switch (provider) { case "openai" -> "openAiChatModel"; case "anthropic" -> "anthropicChatModel"; case "ollama" -> "ollamaChatModel"; default -> throw new IllegalArgumentException( "Unknown LLM provider: " + provider); }; var model = chatModels.get(beanName); if (model == null) { throw new IllegalStateException( "ChatModel bean '" + beanName + "' not found. " + "Available: " + chatModels.keySet()); } return model; } } ``` The `PROVIDER_SERVERS` and `PROVIDER_PORTS` maps provide OpenTelemetry `server.address` and `server.port` span attributes for each provider. These are standard OTel attributes that help correlate LLM spans with network-level telemetry. The `resolveChatModel()` method uses a switch expression to map the provider string (`"openai"`, `"anthropic"`, `"ollama"`) to the Spring AI bean name (`"openAiChatModel"`, `"anthropicChatModel"`, `"ollamaChatModel"`). If the provider string does not match any known provider, it throws an `IllegalArgumentException`. If the bean exists but was not auto-configured (for example, missing API key), it throws an `IllegalStateException` listing the available beans for debugging. #### Environment Variables The application uses environment variables for all sensitive and deployment-specific configuration. Here is the complete set: ```bash showLineNumbers title=".env.example" APP_PORT=8080 DB_HOST=localhost DB_PORT=5432 DB_NAME=support DB_USER=postgres DB_PASSWORD=postgres LLM_PROVIDER=openai LLM_MODEL_CAPABLE=gpt-4.1 LLM_MODEL_FAST=gpt-4.1-mini FALLBACK_PROVIDER=anthropic FALLBACK_MODEL=claude-haiku-4-5-20251001 OLLAMA_BASE_URL=http://localhost:11434 DEFAULT_TEMPERATURE=0.3 DEFAULT_MAX_TOKENS=1024 OPENAI_API_KEY= ANTHROPIC_API_KEY= GOOGLE_API_KEY= OTEL_SERVICE_NAME=ai-customer-support OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 ``` The `OTEL_SERVICE_NAME` and `OTEL_EXPORTER_OTLP_ENDPOINT` variables are used by both the Java Agent (Layer 1) and Spring Boot Actuator (Layer 2). The Java Agent reads them directly; Spring Boot references them via `${...}` placeholders in `application.yml`. This means a single environment variable controls both layers. ### Custom LLM Instrumentation This section covers the core GenAI span creation in `LlmService` - the Layer 3 manual instrumentation that adds OpenTelemetry GenAI semantic convention attributes, error classification, and content capture to every LLM call. #### The GenAI Span The `generateOnce()` method creates a `gen_ai.chat {model}` span for each LLM call. This span follows the [OpenTelemetry GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) and carries all the attributes needed to understand model usage, performance, and cost. Here is the full method with annotations for each section: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" private LlmResponse generateOnce( ChatModel chatModel, String providerName, String model, String systemPrompt, String userPrompt, String stage, List toolCallbacks ) { String spanName = "gen_ai.chat " + model; long start = System.nanoTime(); Span span = tracer.spanBuilder(spanName) .setAttribute("gen_ai.operation.name", "chat") .setAttribute("gen_ai.provider.name", providerName) .setAttribute("gen_ai.request.model", model) .setAttribute("server.address", LlmConfig.PROVIDER_SERVERS.getOrDefault(providerName, "unknown")) .setAttribute("server.port", (long) LlmConfig.PROVIDER_PORTS.getOrDefault(providerName, 443)) .setAttribute("gen_ai.request.temperature", config.temperature()) .setAttribute("gen_ai.request.max_tokens", (long) config.maxTokens()) .startSpan(); if (stage != null && !stage.isEmpty()) { span.setAttribute("support.stage", stage); } try (Scope ignored = span.makeCurrent()) { // ... content capture, prompt building, ChatModel call ... var generation = response.getResult(); var metadata = generation.getMetadata(); var usage = response.getMetadata().getUsage(); String content = generation.getOutput().getText(); int inputTokens = usage != null ? (int) usage.getPromptTokens() : 0; int outputTokens = usage != null ? (int) usage.getCompletionTokens() : 0; String responseModel = response.getMetadata().getModel() != null ? response.getMetadata().getModel() : model; String finishReason = metadata.getFinishReason() != null ? metadata.getFinishReason() : ""; double costUsd = pricing.calculateCost( responseModel, inputTokens, outputTokens); double duration = (System.nanoTime() - start) / 1_000_000_000.0; span.setAttribute("gen_ai.response.model", responseModel); span.setAttribute("gen_ai.usage.input_tokens", (long) inputTokens); span.setAttribute("gen_ai.usage.output_tokens", (long) outputTokens); span.setAttribute("gen_ai.usage.cost_usd", costUsd); if (!finishReason.isEmpty()) { span.setAttribute("gen_ai.response.finish_reasons", finishReason); } // ... metric recording, return ... } catch (Exception e) { // ... error handling ... } finally { span.end(); } } ``` The span is structured in three phases: **Request attributes** (set before `startSpan()`): These describe what the application asked for - the operation type, provider, model, server address, temperature, and max tokens. Setting them on the builder ensures they are available from the start of the span, which matters for streaming scenarios where the span may be visible before the response arrives. **Response attributes** (set after `chatModel.call()`): These describe what the LLM returned - the actual model that responded (which may differ from the requested model after provider routing), token counts, cost, and finish reason. The `gen_ai.response.model` attribute is particularly important for fallback scenarios where the response model differs from `gen_ai.request.model`. **Custom attributes**: The `support.stage` attribute is a domain-specific addition that links the LLM span to the pipeline stage that triggered it (`classify_intent`, `generate_response`, etc.). This is not part of the GenAI semantic conventions but is valuable for filtering and grouping spans by business context. #### Error Handling on Spans When an LLM call fails, the span records both the OpenTelemetry error status and a classified error type. The `catch` block in `generateOnce()` sets the span status to `ERROR` and adds an `error.type` attribute with a categorized error string: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); span.setAttribute("error.type", classifyError(e)); errorCounter.add(1, Attributes.of( AttributeKey.stringKey("gen_ai.provider.name"), providerName, AttributeKey.stringKey("gen_ai.request.model"), model, AttributeKey.stringKey("error.type"), classifyError(e) )); throw e; } finally { span.end(); } ``` The `classifyError()` method maps exception messages to standardized error categories. This avoids high-cardinality error strings in your telemetry backend and enables meaningful alerting on error type: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" static String classifyError(Exception e) { if (e == null) return "unknown_error"; String msg = e.getMessage() != null ? e.getMessage().toLowerCase() : ""; if (msg.contains("rate limit") || msg.contains("429")) return "rate_limit"; if (msg.contains("timeout") || msg.contains("timed out") || msg.contains("deadline")) return "timeout"; if (msg.contains("401") || msg.contains("403") || msg.contains("auth") || msg.contains("api key")) return "auth_error"; if (msg.contains("400") || msg.contains("422") || msg.contains("invalid")) return "invalid_request"; if (msg.contains("500") || msg.contains("502") || msg.contains("503") || msg.contains("server")) return "server_error"; if (msg.contains("connect") || msg.contains("dns") || msg.contains("network") || msg.contains("reset")) return "network_error"; return "unknown_error"; } ``` The classification produces one of seven values: `rate_limit`, `timeout`, `auth_error`, `invalid_request`, `server_error`, `network_error`, or `unknown_error`. These categories are intentionally coarse - they produce low-cardinality metric labels that work well with alerting rules. For example, you can alert on `error.type = rate_limit` to detect when your API key is hitting quota limits, or on `error.type = auth_error` to detect expired or revoked credentials. #### Span Events (Content Capture) The `generateOnce()` method optionally records prompt and completion content as span events. Content capture is gated behind the `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT` environment variable and is disabled by default: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" this.captureContent = "true".equalsIgnoreCase( System.getenv("OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT")); ``` When enabled, three span events are recorded on each LLM call: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" try (Scope ignored = span.makeCurrent()) { if (captureContent) { span.addEvent("gen_ai.user.message", Attributes.of( AttributeKey.stringKey("gen_ai.prompt"), truncate(piiFilter.scrub(userPrompt), 1000) )); if (systemPrompt != null && !systemPrompt.isEmpty()) { span.addEvent("gen_ai.user.message", Attributes.of( AttributeKey.stringKey("gen_ai.system_instructions"), truncate(systemPrompt, 500) )); } } var prompt = buildPrompt(systemPrompt, userPrompt, model, toolCallbacks); ChatResponse response = chatModel.call(prompt); // ... response processing ... if (captureContent) { span.addEvent("gen_ai.assistant.message", Attributes.of( AttributeKey.stringKey("gen_ai.completion"), truncate(piiFilter.scrub(content), 2000) )); } // ... } ``` Each span event captures a different part of the conversation: | Event Name | Attribute | Content | Max Length | | -------------------------- | ---------------------------- | ------------- | ---------- | | `gen_ai.user.message` | `gen_ai.prompt` | User input | 1000 chars | | `gen_ai.user.message` | `gen_ai.system_instructions` | System prompt | 500 chars | | `gen_ai.assistant.message` | `gen_ai.completion` | LLM response | 2000 chars | Two safety measures protect sensitive data in span events: 1. **PII filtering** - User input and LLM responses pass through `piiFilter.scrub()` before recording. This replaces patterns like email addresses, phone numbers, and credit card numbers with redaction markers. The system prompt is not PII-filtered because it is developer-authored content that should not contain user data. 2. **Truncation** - All content is truncated to prevent span events from becoming excessively large. User prompts are capped at 1000 characters, system prompts at 500, and completions at 2000. These limits balance debuggability with storage costs. Content capture is off by default for good reason: prompt content may contain PII, proprietary data, or information subject to compliance requirements (GDPR, HIPAA, SOC 2). Enable it only in environments where content inspection is appropriate - development, staging, or production with explicit data handling agreements. Set the environment variable in your deployment: ```bash showLineNumbers OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=true ``` #### GenAI Semantic Conventions Reference The following table summarizes all GenAI attributes set on `gen_ai.chat` spans. These follow the [OpenTelemetry GenAI semantic conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/gen-ai-spans/): | Attribute | Example Value | Source | | -------------------------------- | ------------------- | ----------------------------------- | | `gen_ai.operation.name` | `"chat"` | Hardcoded | | `gen_ai.provider.name` | `"openai"` | `config.provider()` | | `gen_ai.request.model` | `"gpt-4.1"` | Method parameter | | `gen_ai.request.temperature` | `0.3` | `config.temperature()` | | `gen_ai.request.max_tokens` | `1024` | `config.maxTokens()` | | `gen_ai.response.model` | `"gpt-4.1"` | `response.getMetadata().getModel()` | | `gen_ai.usage.input_tokens` | `150` | `usage.getPromptTokens()` | | `gen_ai.usage.output_tokens` | `380` | `usage.getCompletionTokens()` | | `gen_ai.usage.cost_usd` | `0.00234` | `pricing.calculateCost()` | | `gen_ai.response.finish_reasons` | `"stop"` | `metadata.getFinishReason()` | | `server.address` | `"api.openai.com"` | `LlmConfig.PROVIDER_SERVERS` | | `server.port` | `443` | `LlmConfig.PROVIDER_PORTS` | | `support.stage` | `"classify_intent"` | Method parameter (custom) | | `error.type` | `"rate_limit"` | `classifyError()` (on error only) | ### Token and Cost Tracking Token usage and cost are central to LLM observability. Unlike traditional API calls where cost is roughly proportional to request count, LLM costs scale with token consumption - a single request can cost 100x more than another depending on prompt length and response size. This section covers how the application defines GenAI metrics, calculates cost from a pricing table, and records both metrics and span attributes for every LLM call. #### GenAI Metrics Definition Six metrics are defined in the `LlmService` constructor using the OpenTelemetry `Meter` API. These metrics follow the naming patterns from the OpenTelemetry GenAI semantic conventions: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" this.tracer = GlobalOpenTelemetry.getTracer("ai-customer-support"); Meter meter = GlobalOpenTelemetry.getMeter("ai-customer-support"); this.tokenUsage = meter.histogramBuilder("gen_ai.client.token.usage") .setUnit("{token}").build(); this.operationDuration = meter.histogramBuilder("gen_ai.client.operation.duration") .setUnit("s").build(); this.costCounter = meter.counterBuilder("gen_ai.client.cost") .ofDoubles().setUnit("usd").build(); this.retryCounter = meter.counterBuilder("gen_ai.client.retry.count") .build(); this.fallbackCounter = meter.counterBuilder("gen_ai.client.fallback.count") .build(); this.errorCounter = meter.counterBuilder("gen_ai.client.error.count") .build(); ``` Each metric serves a specific observability purpose: - **`gen_ai.client.token.usage`** - Histogram of token counts per LLM call. Recorded twice per successful call: once with `gen_ai.token.type = "input"` and once with `gen_ai.token.type = "output"`. Histograms capture the distribution, so you can compute p50, p95, and p99 token usage for capacity planning and anomaly detection. - **`gen_ai.client.operation.duration`** - Histogram of LLM call duration in seconds. Captures end-to-end latency including network round-trip, model inference, and any tool-calling loops. Use this to track model performance degradation over time. - **`gen_ai.client.cost`** - Monotonic counter of estimated cost in USD. Incremented on every successful call. Use this for real-time cost dashboards and budget alerting. - **`gen_ai.client.retry.count`** - Counter of retry attempts. Incremented when an LLM call fails and is retried (not on the first attempt). A rising retry rate signals provider instability. - **`gen_ai.client.fallback.count`** - Counter of fallback activations. Incremented when the primary provider fails all retries and the application switches to the fallback provider. - **`gen_ai.client.error.count`** - Counter of LLM call errors. Carries `error.type` as a label for classification (`rate_limit`, `timeout`, `auth_error`, etc.). All metrics carry a common set of labels (attributes) for grouping and filtering: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" private static Attributes providerModelAttrs(String provider, String model) { return Attributes.of( AttributeKey.stringKey("gen_ai.operation.name"), "chat", AttributeKey.stringKey("gen_ai.provider.name"), provider, AttributeKey.stringKey("gen_ai.request.model"), model ); } private static Attributes withTokenType(Attributes base, String tokenType) { return base.toBuilder() .put(AttributeKey.stringKey("gen_ai.token.type"), tokenType) .build(); } ``` #### Metrics Reference | Metric Name | Type | Unit | Labels | Recorded In | | ---------------------------------- | ------------- | --------- | -------------------------------------------------------------------------------------------- | --------------------- | | `gen_ai.client.token.usage` | Histogram | `{token}` | `gen_ai.operation.name`, `gen_ai.provider.name`, `gen_ai.request.model`, `gen_ai.token.type` | `generateOnce()` | | `gen_ai.client.operation.duration` | Histogram | `s` | `gen_ai.operation.name`, `gen_ai.provider.name`, `gen_ai.request.model` | `generateOnce()` | | `gen_ai.client.cost` | DoubleCounter | `usd` | `gen_ai.operation.name`, `gen_ai.provider.name`, `gen_ai.request.model` | `generateOnce()` | | `gen_ai.client.retry.count` | LongCounter | - | `gen_ai.operation.name`, `gen_ai.provider.name`, `gen_ai.request.model` | `generateWithRetry()` | | `gen_ai.client.fallback.count` | LongCounter | - | - | `generate()` | | `gen_ai.client.error.count` | LongCounter | - | `gen_ai.provider.name`, `gen_ai.request.model`, `error.type` | `generateOnce()` | #### Cost Calculation The `Pricing` class loads model pricing data at application startup and calculates per-call costs based on input and output token counts. This decouples cost calculation from the LLM call path - pricing data can be updated without redeploying the application. ```java showLineNumbers title="src/main/java/com/example/support/llm/Pricing.java" @Component public class Pricing { private static final Logger log = LoggerFactory.getLogger(Pricing.class); private static final double FALLBACK_INPUT = 3.0; private static final double FALLBACK_OUTPUT = 15.0; private static final double PER_MILLION = 1_000_000.0; private Map models = Map.of(); @JsonIgnoreProperties(ignoreUnknown = true) record PricingFile(String version, Map models) {} @JsonIgnoreProperties(ignoreUnknown = true) public record ModelPricing( String provider, double input, double output ) {} @PostConstruct void loadPricing() { var objectMapper = new ObjectMapper(); String pricingFile = System.getenv("PRICING_FILE"); try { InputStream stream; if (pricingFile != null && Files.exists(Path.of(pricingFile))) { stream = Files.newInputStream(Path.of(pricingFile)); log.info("Loaded pricing from {}", pricingFile); } else { stream = getClass().getClassLoader() .getResourceAsStream("pricing.json"); if (stream == null) { log.warn("No pricing.json found, " + "using fallback pricing"); return; } log.info("Loaded pricing from classpath"); } var file = objectMapper.readValue(stream, PricingFile.class); this.models = file.models(); log.info("Loaded pricing v{} with {} models", file.version(), models.size()); } catch (IOException e) { log.warn("Failed to load pricing.json: {}", e.getMessage()); } } public double calculateCost( String model, int inputTokens, int outputTokens ) { var pricing = models.get(model); double inputRate = pricing != null ? pricing.input() : FALLBACK_INPUT; double outputRate = pricing != null ? pricing.output() : FALLBACK_OUTPUT; return (inputTokens * inputRate + outputTokens * outputRate) / PER_MILLION; } public boolean hasModel(String model) { return models.containsKey(model); } } ``` Key design decisions in the pricing implementation: - **`@PostConstruct` loading** - Pricing data is loaded once at startup, not on every LLM call. This avoids file I/O in the hot path. - **External file override** - The `PRICING_FILE` environment variable allows deploying updated pricing without rebuilding the application. If not set, the classpath `pricing.json` is used. - **Fallback rates** - If a model is not found in the pricing table, fallback rates of $3.00/M input and $15.00/M output are used. These are intentionally high to make unknown models visible in cost dashboards. - **Per-million pricing** - Rates are stored as dollars per million tokens (the standard unit used by LLM providers), and the `calculateCost()` method divides by 1,000,000 to produce the actual cost per call. #### How Metrics Are Recorded Metrics are recorded at three points in the call chain, each capturing a different aspect of LLM operations. **Successful calls in `generateOnce()`** - Token usage, duration, and cost are recorded after a successful ChatModel call: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" var attrs = providerModelAttrs(providerName, responseModel); tokenUsage.record(inputTokens, withTokenType(attrs, "input")); tokenUsage.record(outputTokens, withTokenType(attrs, "output")); operationDuration.record(duration, attrs); costCounter.add(costUsd, attrs); return new LlmResponse(content, responseModel, providerName, inputTokens, outputTokens, costUsd, finishReason); ``` The token histogram is recorded twice - once for input tokens and once for output tokens - with the `gen_ai.token.type` label distinguishing them. This allows separate analysis of prompt size versus completion size. **Retries in `generateWithRetry()`** - The retry counter is incremented on each retry attempt (not on the first attempt): ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" for (int attempt = 0; attempt < MAX_RETRIES; attempt++) { try { return generateOnce(chatModel, providerName, model, systemPrompt, userPrompt, stage, toolCallbacks); } catch (Exception e) { // ... if (attempt > 0) { retryCounter.add(1, providerModelAttrs(providerName, model)); } // ... } } ``` **Fallbacks in `generate()`** - The fallback counter is incremented when the primary provider exhausts all retries and the application switches to the fallback: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" log.warn("Primary provider {} failed, falling back to {}", config.provider(), config.fallbackProvider()); fallbackCounter.add(1); ``` **Errors in `generateOnce()`** - The error counter is incremented in the catch block with the classified error type as a label: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); span.setAttribute("error.type", classifyError(e)); errorCounter.add(1, Attributes.of( AttributeKey.stringKey("gen_ai.provider.name"), providerName, AttributeKey.stringKey("gen_ai.request.model"), model, AttributeKey.stringKey("error.type"), classifyError(e) )); throw e; } ``` Cost is recorded in two places - as a span attribute (`gen_ai.usage.cost_usd`) for per-request visibility in traces, and as a metric counter (`gen_ai.client.cost`) for aggregated dashboards and alerting. The span attribute lets you see the cost of a single request when investigating a trace. The metric counter lets you build a real-time cost dashboard that sums cost across all requests, grouped by provider and model. ### Pipeline Observability The support pipeline orchestrates six stages - classify intent, retrieve RAG context, generate response, scrub PII, check escalation, and persist results. Each stage runs as a child span under a single parent `support_conversation` span, producing a trace that shows the full request lifecycle with timing and attributes at every step. The `SupportPipeline` class is the orchestrator. Its `process()` method handles the reactive layer (load or create conversation, add user message, fetch history), then delegates to `runPipeline()` on a bounded elastic scheduler for the blocking pipeline work. Here is `runPipeline()` - the parent span and the six-stage flow: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/SupportPipeline.java" private PipelineResult runPipeline( String userMessage, UUID conversationId, List history ) { long startNanos = System.nanoTime(); Span span = tracer.spanBuilder("support_conversation") .setAttribute("support.conversation_id", conversationId.toString()) .startSpan(); try (Scope ignored = span.makeCurrent()) { // 1. Classify intent (fast model) IntentResult intent = intentClassifier.classify(userMessage); span.setAttribute("support.intent", intent.intent().name()); span.setAttribute("support.confidence", intent.confidence()); // 2. Retrieve RAG context var ragDocs = contextRetriever.retrieve(userMessage); span.setAttribute("support.rag_matches", ragDocs.size()); // 3. Generate response (capable model) String conversationHistory = conversationService.formatHistory(history); LlmResponse response = responseGenerator.generate( userMessage, intent, ragDocs, conversationHistory); // 4. PII scrub String content = piiFilter.scrub(response.content()); // 5. Check escalation int turns = history.size() / 2 + 1; EscalationDecision escalation = escalationRouter.evaluate(intent, turns, 0); span.setAttribute( "support.should_escalate", escalation.shouldEscalate()); // 6. Record domain metrics if (!ragDocs.isEmpty()) { Double topScore = ragDocs.getFirst().getScore(); if (topScore != null) { metrics.recordRagSimilarity( topScore, intent.intent().name()); } } metrics.recordConversationTurns( turns, intent.intent().name(), false); if (escalation.shouldEscalate()) { metrics.recordEscalation( escalation.reason(), escalation.priority().name()); } double durationSec = (System.nanoTime() - startNanos) / 1_000_000_000.0; metrics.recordConversationDuration( durationSec, intent.intent().name(), escalation.shouldEscalate()); // Record totals int totalTokens = intent.inputTokens() + intent.outputTokens() + response.inputTokens() + response.outputTokens(); span.setAttribute("support.total_turns", (long) turns); span.setAttribute("support.total_tokens", (long) totalTokens); span.setAttribute("support.total_cost_usd", response.costUsd()); return new PipelineResult( content, intent, escalation, response.model(), response.provider(), response.inputTokens(), response.outputTokens(), response.costUsd(), conversationId); } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); throw new RuntimeException( "Pipeline failed: " + e.getMessage(), e); } finally { span.end(); } } ``` The span lifecycle follows the standard OpenTelemetry pattern: create with `spanBuilder()`, set initial attributes, make it current with `makeCurrent()` inside a try-with-resources so child spans automatically parent to it, set additional attributes as the pipeline progresses, call `setStatus(ERROR)` in the catch block, and call `end()` in the finally block. The `makeCurrent()` call is the key - it puts this span on the thread-local context so that every child span created by `intentClassifier.classify()`, `contextRetriever.retrieve()`, and the other stages automatically becomes a child of `support_conversation`. The parent span accumulates summary attributes as each stage completes: `support.intent` and `support.confidence` after classification, `support.rag_matches` after retrieval, `support.should_escalate` after the escalation check, and `support.total_turns`, `support.total_tokens`, and `support.total_cost_usd` at the end. This means you can filter traces by intent, escalation status, or token count without expanding the span tree. Each pipeline stage creates its own child span with a `support.stage` attribute. Here are the four stage spans. **IntentClassifier** - The `classify_intent` span wraps a fast-model LLM call that returns structured JSON with the detected intent, confidence score, sub-category, and extracted entities: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/IntentClassifier.java" public IntentResult classify(String userMessage) { Span span = tracer.spanBuilder("classify_intent") .setAttribute("support.stage", "classify") .startSpan(); try (Scope ignored = span.makeCurrent()) { LlmResponse response = llmService.generateFast( SYSTEM_PROMPT, userMessage, "classify"); IntentResult result = parseResponse(response); span.setAttribute("support.intent", result.intent().name()); span.setAttribute("support.confidence", result.confidence()); span.setAttribute( "support.sub_category", result.subCategory()); if (!result.entities().isEmpty()) { span.setAttribute( "support.entities", String.join(",", result.entities())); } return result; } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); return IntentResult.fallback(); } finally { span.end(); } } ``` The `parseResponse()` method parses the LLM's JSON output, strips any markdown code fences, and extracts the intent, confidence, sub-category, and entities fields. If JSON parsing fails (malformed response, unexpected format), it falls back to `Intent.QUERY` with a confidence of 0.3 and a sub-category of `"parse_error"` - the pipeline continues with a degraded classification rather than failing entirely. **ContextRetriever** - The `rag_retrieval` span wraps the vector similarity search: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/ContextRetriever.java" public List retrieve(String userMessage) { Span span = tracer.spanBuilder("rag_retrieval") .setAttribute("support.stage", "retrieve") .startSpan(); try (Scope ignored = span.makeCurrent()) { List results = vectorStore.similaritySearch( SearchRequest.builder() .query(userMessage) .topK(TOP_K) .build() ); span.setAttribute("support.matches_found", results.size()); if (!results.isEmpty()) { Double topScore = results.getFirst().getScore(); if (topScore != null) { span.setAttribute( "support.top_similarity", topScore); } } return results; } catch (Exception e) { span.setStatus( io.opentelemetry.api.trace.StatusCode.ERROR, e.getMessage()); return List.of(); } finally { span.end(); } } ``` Like the classifier, the retriever returns an empty list on failure rather than propagating the exception - the pipeline generates a response without RAG context rather than failing the entire request. **ResponseGenerator** - The `generate_response` span wraps the capable-model LLM call that produces the final customer-facing response: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/ResponseGenerator.java" public LlmResponse generate( String userMessage, IntentResult intent, List ragContext, String conversationHistory ) { Span span = tracer.spanBuilder("generate_response") .setAttribute("support.stage", "generate") .setAttribute("support.rag_matches_used", ragContext.size()) .startSpan(); try (Scope ignored = span.makeCurrent()) { String ragSection = contextRetriever.formatContext(ragContext); String historySection = conversationHistory != null && !conversationHistory.isEmpty() ? "Previous conversation:\n" + conversationHistory + "\n" : ""; String systemPrompt = SYSTEM_PROMPT_TEMPLATE.formatted( intent.intent().name(), intent.confidence() * 100, ragSection, historySection ); LlmResponse response = llmService.generateCapable( systemPrompt, userMessage, "generate", toolCallbacks); span.setAttribute("gen_ai.usage.input_tokens", (long) response.inputTokens()); span.setAttribute("gen_ai.usage.output_tokens", (long) response.outputTokens()); span.setAttribute("gen_ai.usage.cost_usd", response.costUsd()); return response; } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); throw e; } finally { span.end(); } } ``` The response generator does not catch-and-continue like the classifier and retriever - a failed response generation is a hard failure that propagates up to the parent span. The `rag_matches_used` attribute is set at span creation time so it appears even if the LLM call fails, which helps diagnose whether failures correlate with RAG context size. **EscalationRouter** - The `escalation_check` span wraps the rule-based escalation evaluation: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/EscalationRouter.java" public EscalationDecision evaluate( IntentResult intent, int conversationTurns, int toolErrors ) { Span span = tracer.spanBuilder("escalation_check") .setAttribute("support.stage", "route") .setAttribute("support.conversation_turns", (long) conversationTurns) .startSpan(); try (Scope ignored = span.makeCurrent()) { EscalationDecision decision = checkTriggers(intent, conversationTurns, toolErrors); span.setAttribute("support.should_escalate", decision.shouldEscalate()); if (decision.shouldEscalate()) { span.setAttribute("support.escalation_reason", decision.reason()); span.setAttribute("support.escalation_priority", decision.priority().name()); } return decision; } finally { span.end(); } } ``` The `checkTriggers()` method evaluates five rules in priority order: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/EscalationRouter.java" EscalationDecision checkTriggers( IntentResult intent, int conversationTurns, int toolErrors ) { // Explicit ESCALATE intent - immediate if (intent.intent() == Intent.ESCALATE) { return EscalationDecision.escalate( "explicit_request", EscalationPriority.HIGH, "Customer explicitly requested human agent"); } // Complaint + low confidence (< 0.6) - auto-escalate if (intent.intent() == Intent.COMPLAINT && intent.confidence() < 0.6) { return EscalationDecision.escalate( "low_confidence_complaint", EscalationPriority.HIGH, "Complaint with low classification confidence"); } // 2+ tool errors - escalate with context if (toolErrors >= 2) { return EscalationDecision.escalate( "tool_errors", EscalationPriority.MEDIUM, "Multiple tool call failures (" + toolErrors + ")"); } // Low intent confidence (< 0.5) - offer human agent if (intent.confidence() < 0.5) { return EscalationDecision.escalate( "low_confidence", EscalationPriority.LOW, "Low intent classification confidence"); } // > 5 turns without resolution - suggest escalation if (conversationTurns > 5) { return EscalationDecision.escalate( "long_conversation", EscalationPriority.LOW, "Conversation exceeds 5 turns without resolution"); } return EscalationDecision.noEscalation(); } ``` The rules are ordered by urgency. An explicit escalation request or a low-confidence complaint triggers HIGH priority - these go to the front of the human agent queue. Tool errors indicate the AI cannot fulfil the request and get MEDIUM priority. Low confidence and long conversations get LOW priority as soft suggestions. The span records `support.escalation_reason` and `support.escalation_priority` only when escalation triggers, keeping clean traces for normal conversations. #### Tool Calling Spring AI provides the `@Tool` and `@ToolParam` annotations for declarative tool definitions. The LLM decides when to call a tool based on the tool's description, and Spring AI handles the function-calling protocol with the provider. Each tool method receives typed parameters, executes business logic (typically a database query), and returns a result that Spring AI serializes back to the LLM. Here is an example tool method from `OrderTools` - the `getOrderStatus` tool that looks up an order by ID: ```java showLineNumbers title="src/main/java/com/example/support/tools/OrderTools.java" @Tool(description = "Look up order status and tracking info " + "by order ID (e.g. ORD-12345)") public Map getOrderStatus( @ToolParam(description = "Order ID, e.g. ORD-12345") String orderId ) { log.info("Tool call: getOrderStatus({})", orderId); metrics.recordToolCall("getOrderStatus", true); var rows = jdbc.queryForList( """ SELECT o.order_id, o.status, o.tracking_number, o.estimated_delivery, o.total_amount, o.created_at, c.name as customer_name FROM orders o JOIN customers c ON o.customer_id = c.id WHERE o.order_id = ? """, orderId); if (rows.isEmpty()) { return Map.of("error", "Order not found: " + orderId); } return rows.getFirst(); } ``` Every `@Tool` method calls `metrics.recordToolCall()` with the tool name and success status, feeding the `support.tool_calls` counter metric. The JDBC query runs under the OpenTelemetry Java Agent's auto-instrumentation, so the database call appears as a child span of the `gen_ai.chat` span without any manual instrumentation. Tool callbacks are assembled in the `ResponseGenerator` constructor using Spring AI's `MethodToolCallbackProvider`: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/ResponseGenerator.java" this.toolCallbacks = List.of( MethodToolCallbackProvider.builder() .toolObjects(orderTools, productTools) .build() .getToolCallbacks() ); ``` This scans the `orderTools` and `productTools` beans for `@Tool`-annotated methods and builds `ToolCallback` instances for each one. The callbacks are then passed to `LlmService.generateCapable()`, which constructs `ToolCallingChatOptions` when tools are present: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" if (toolCallbacks != null && !toolCallbacks.isEmpty()) { var options = ToolCallingChatOptions.builder() .model(model) .temperature(config.temperature()) .maxTokens(config.maxTokens()) .toolCallbacks(toolCallbacks) .build(); return new Prompt(messages, options); } ``` The `ToolCallingChatOptions` extends the standard `ChatOptions` with tool callback support. Spring AI handles the multi-turn tool-calling loop internally — the LLM requests a tool call, Spring AI executes the matching `@Tool` method, sends the result back to the LLM, and the LLM produces its final response. All of this happens within the single `chatModel.call(prompt)` invocation. The application exposes six tools across two classes: | Tool | Class | Description | | ----------------- | ------------ | --------------------------------------------- | | `getOrderStatus` | OrderTools | Look up order status and tracking by order ID | | `getOrderHistory` | OrderTools | Get recent orders by customer email | | `initiateReturn` | OrderTools | Initiate a return for a delivered order | | `getReturnStatus` | OrderTools | Check return status by return ID | | `searchProducts` | ProductTools | Search product catalog by name or category | | `getProductInfo` | ProductTools | Get product details by SKU | #### RAG Retrieval The RAG pipeline uses pgvector for vector storage with Spring AI's `PgVectorStore` abstraction. The vector store is configured in `VectorStoreConfig` with an HNSW index for fast approximate nearest-neighbor search: ```java showLineNumbers title="src/main/java/com/example/support/config/VectorStoreConfig.java" @Bean PgVectorStore vectorStore( EmbeddingModel embeddingModel, DataSource dataSource, @Value("${spring.ai.vectorstore.pgvector.dimensions:1536}") int dimensions ) { return PgVectorStore.builder( new JdbcTemplate(dataSource), embeddingModel) .dimensions(dimensions) .distanceType(PgDistanceType.COSINE_DISTANCE) .indexType(PgIndexType.HNSW) .initializeSchema(true) .build(); } ``` The `dimensions` parameter defaults to 1536 (OpenAI's `text-embedding-ada-002` output size) but is configurable for other embedding models. The `HNSW` index type provides fast approximate search at the cost of more memory than IVFFlat. `COSINE_DISTANCE` is the standard similarity metric for text embeddings. `initializeSchema(true)` creates the `vector_store` table and index on startup if they do not exist. The `DataSource` uses HikariCP connection pooling: ```java showLineNumbers title="src/main/java/com/example/support/config/VectorStoreConfig.java" @Bean DataSource dataSource( @Value("${spring.datasource.url}") String url, @Value("${spring.datasource.username}") String username, @Value("${spring.datasource.password}") String password ) { var ds = new HikariDataSource(); ds.setJdbcUrl(url); ds.setUsername(username); ds.setPassword(password); return ds; } ``` On startup, `KnowledgeBaseService` loads knowledge base articles into the vector store. It implements `ApplicationRunner` so it runs after the Spring context is fully initialized: ```java showLineNumbers title="src/main/java/com/example/support/service/KnowledgeBaseService.java" @Override public void run(ApplicationArguments args) { int existing = jdbcTemplate.queryForObject( "SELECT COUNT(*) FROM vector_store", Integer.class); if (existing > 0) { log.info("Vector store already populated with {} " + "documents, skipping KB load", existing); return; } log.info("Loading KB articles into vector store..."); List> articles = jdbcTemplate.queryForList( "SELECT id, intent, question, answer, category " + "FROM kb_articles"); List docs = articles.stream() .map(row -> { String content = row.get("question") + "\n\n" + row.get("answer"); Map metadata = Map.of( "intent", row.get("intent"), "category", row.get("category") != null ? row.get("category") : "", "source", "kb_article", "article_id", row.get("id").toString() ); return new Document(content, metadata); }) .toList(); vectorStore.add(docs); log.info("Loaded {} KB articles into vector store", docs.size()); } ``` The startup check (`SELECT COUNT(*) FROM vector_store`) prevents duplicate embeddings on restart. Each document combines the question and answer text, with metadata for intent, category, source type, and article ID. The `vectorStore.add()` call handles embedding generation (via the configured `EmbeddingModel`) and insertion in a single operation. At query time, `ContextRetriever.retrieve()` runs a similarity search with `topK(5)`: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/ContextRetriever.java" List results = vectorStore.similaritySearch( SearchRequest.builder() .query(userMessage) .topK(TOP_K) .build() ); ``` The returned documents are formatted for the system prompt by `formatContext()`: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/ContextRetriever.java" public String formatContext(List documents) { if (documents.isEmpty()) { return ""; } var sb = new StringBuilder( "Relevant knowledge base articles:\n\n"); for (int i = 0; i < documents.size(); i++) { var doc = documents.get(i); sb.append("--- Article ").append(i + 1) .append(" ---\n"); sb.append(doc.getText()).append("\n\n"); } return sb.toString(); } ``` This produces a numbered list of articles injected into the system prompt, so the LLM can reference specific knowledge base content in its response. The top similarity score is recorded as both a span attribute (`support.top_similarity` on the `rag_retrieval` span) and a metric (`support.rag.similarity` histogram) for tracking retrieval quality over time. ### Retry and Fallback Observability The `LlmService` implements a two-tier resilience strategy: retry with exponential backoff within a single provider, and fallback to an alternate provider when all retries are exhausted. Both tiers are instrumented with metrics. The `generateWithRetry()` method handles the retry loop for a single provider: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" private LlmResponse generateWithRetry( ChatModel chatModel, String providerName, String model, String systemPrompt, String userPrompt, String stage, List toolCallbacks ) { Exception lastError = null; for (int attempt = 0; attempt < MAX_RETRIES; attempt++) { try { return generateOnce( chatModel, providerName, model, systemPrompt, userPrompt, stage, toolCallbacks); } catch (Exception e) { lastError = e; log.warn("LLM call failed (attempt {}/{}): " + "provider={} model={} error={}", attempt + 1, MAX_RETRIES, providerName, model, e.getMessage()); if (attempt > 0) { retryCounter.add(1, providerModelAttrs(providerName, model)); } if (attempt < MAX_RETRIES - 1) { sleep(backoffWithJitter(attempt)); } } } log.error("All {} retries exhausted for provider={}", MAX_RETRIES, providerName, lastError); return null; } ``` The retry loop makes up to `MAX_RETRIES` (3) attempts. On failure, it records the retry attempt to the `gen_ai.client.retry.count` counter (skipping the first attempt since that is not a retry). The backoff uses exponential delay with jitter: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" private long backoffWithJitter(int attempt) { long base = Math.min( MIN_BACKOFF_MS * (1L << attempt), MAX_BACKOFF_MS); long jitter = ThreadLocalRandom.current() .nextLong(0, base / 4 + 1); return base + jitter; } ``` This produces delays of approximately 1s, 2s, and 4s for attempts 0, 1, and 2, capped at 10s, with up to 25% random jitter added to prevent thundering-herd retries across concurrent requests. The method returns `null` after exhausting all retries rather than throwing - this signals the caller to try the fallback provider. The `generate()` method orchestrates the primary-to-fallback flow: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" public LlmResponse generate( String systemPrompt, String userPrompt, String model, String stage, List toolCallbacks ) { var resp = generateWithRetry( primaryModel, config.provider(), model, systemPrompt, userPrompt, stage, toolCallbacks); if (resp != null) { return resp; } log.warn("Primary provider {} failed, falling back to {}", config.provider(), config.fallbackProvider()); fallbackCounter.add(1); resp = generateWithRetry( fallbackModel, config.fallbackProvider(), config.fallbackModel(), systemPrompt, userPrompt, stage, toolCallbacks); if (resp != null) { return resp; } throw new RuntimeException( "All LLM providers failed after retries"); } ``` The flow is: try the primary provider with up to 3 retries. If all fail ( `generateWithRetry` returns `null`), increment `gen_ai.client.fallback.count` and try the fallback provider with another 3 retries. If both providers fail, throw a `RuntimeException` that propagates up to the pipeline's catch block and sets the parent span status to ERROR. In telemetry, retries and fallbacks surface through three metrics defined in the LLM metrics section: - `gen_ai.client.retry.count` - incremented on each retry attempt (not the initial attempt), labeled with `gen_ai.provider.name` and `gen_ai.request.model`. A steady increase indicates provider instability. - `gen_ai.client.fallback.count` - incremented once per fallback activation. Any non-zero value means the primary provider failed completely for at least one request. - `gen_ai.client.error.count` - incremented on every failed `generateOnce()` call, labeled with `error.type` (rate_limit, timeout, auth_error, invalid_request, server_error, network_error, unknown_error). This gives visibility into why retries are happening. ### Domain Metrics The GenAI metrics from the previous sections cover LLM operational concerns — token usage, cost, latency, errors. Domain metrics capture the business-level signals that tell you whether the AI application is actually working for your users: how long conversations last, how many turns they take, when they escalate to humans, which tools the LLM calls, and how relevant the RAG results are. `SupportMetrics` defines five domain-specific metrics using the OpenTelemetry Meter API: ```java showLineNumbers title="src/main/java/com/example/support/telemetry/SupportMetrics.java" @Component public class SupportMetrics { private final DoubleHistogram conversationDuration; private final DoubleHistogram conversationTurns; private final LongCounter escalationCount; private final LongCounter toolCallCount; private final DoubleHistogram ragSimilarity; public SupportMetrics() { Meter meter = GlobalOpenTelemetry.getMeter( "ai-customer-support"); this.conversationDuration = meter .histogramBuilder("support.conversation.duration") .setUnit("s") .setDescription("Duration of customer support " + "conversations") .build(); this.conversationTurns = meter .histogramBuilder("support.conversation.turns") .setUnit("{turn}") .setDescription("Number of turns in customer " + "support conversations") .build(); this.escalationCount = meter .counterBuilder("support.escalation.count") .setDescription( "Number of escalated conversations") .build(); this.toolCallCount = meter .counterBuilder("support.tool_calls") .setDescription("Number of tool calls made") .build(); this.ragSimilarity = meter .histogramBuilder("support.rag.similarity") .setDescription("Top similarity score from " + "RAG retrieval") .build(); } public void recordConversationDuration( double seconds, String intent, boolean escalated ) { conversationDuration.record(seconds, Attributes.of( AttributeKey.stringKey("support.intent"), intent, AttributeKey.booleanKey("support.escalated"), escalated )); } public void recordConversationTurns( int turns, String intent, boolean resolved ) { conversationTurns.record(turns, Attributes.of( AttributeKey.stringKey("support.intent"), intent, AttributeKey.booleanKey("support.resolved"), resolved )); } public void recordEscalation(String reason, String priority) { escalationCount.add(1, Attributes.of( AttributeKey.stringKey("support.escalation_reason"), reason, AttributeKey.stringKey("support.escalation_priority"), priority )); } public void recordToolCall(String toolName, boolean success) { toolCallCount.add(1, Attributes.of( AttributeKey.stringKey("support.tool_name"), toolName, AttributeKey.booleanKey("support.tool_success"), success )); } public void recordRagSimilarity( double similarity, String intent ) { ragSimilarity.record(similarity, Attributes.of( AttributeKey.stringKey("support.intent"), intent )); } } ``` Each metric is recorded at a specific point in the pipeline: - `support.conversation.duration` and `support.conversation.turns` - recorded at the end of `SupportPipeline.runPipeline()`, after all stages complete. Duration is measured from the start of `runPipeline()` in seconds. Turns are calculated as `history.size() / 2 + 1` (each turn is a user-assistant pair). - `support.escalation.count` - recorded in `SupportPipeline.runPipeline()` immediately after the escalation check, only when `escalation.shouldEscalate()` returns true. - `support.tool_calls` - recorded inside each `@Tool` method in `OrderTools` and `ProductTools`. Every tool call increments the counter with the tool name and success status. - `support.rag.similarity` - recorded in `SupportPipeline.runPipeline()` after RAG retrieval, using the top document's similarity score. | Metric | Type | Unit | Labels | Business Purpose | | ------------------------------- | --------- | -------- | ---------------------------------------------------------- | ------------------------------------------------------------------- | | `support.conversation.duration` | Histogram | `s` | `support.intent`, `support.escalated` | Track resolution time by intent type and escalation status | | `support.conversation.turns` | Histogram | `{turn}` | `support.intent`, `support.resolved` | Detect long conversations that may need UX improvements | | `support.escalation.count` | Counter | - | `support.escalation_reason`, `support.escalation_priority` | Monitor escalation rate and reasons for human handoff | | `support.tool_calls` | Counter | - | `support.tool_name`, `support.tool_success` | Track which tools the LLM uses and their success rate | | `support.rag.similarity` | Histogram | - | `support.intent` | Monitor retrieval quality - low scores indicate knowledge base gaps | ### PII and Security AI applications handle user input that may contain personally identifiable information - email addresses, social security numbers, credit card numbers, phone numbers. The `PiiFilter` scrubs PII from both response content (returned to the client) and telemetry data (exported to the collector) so sensitive data does not leak into traces or logs. The filter uses regex patterns for four PII categories: ```java showLineNumbers title="src/main/java/com/example/support/filter/PiiFilter.java" @Component public class PiiFilter { private static final String REDACTED = "[REDACTED]"; private record PiiPattern(String name, Pattern pattern) {} private static final List PATTERNS = List.of( new PiiPattern("email", Pattern.compile( "\\b[A-Za-z0-9._%+-]+@[A-Za-z0-9.-]+" + "\\.[A-Za-z]{2,}\\b")), new PiiPattern("ssn", Pattern.compile("\\b\\d{3}-\\d{2}-\\d{4}\\b")), new PiiPattern("credit_card", Pattern.compile( "\\b\\d{4}[- ]?\\d{4}[- ]?\\d{4}[- ]?" + "\\d{4}\\b")), new PiiPattern("phone", Pattern.compile( "(?:\\+?1[-.]?)?\\(?\\d{3}\\)?[-.]?" + "\\d{3}[-.]?\\d{4}")) ); public String scrub(String text) { if (text == null || text.isEmpty()) return text; String result = text; boolean piiFound = false; for (var pii : PATTERNS) { var matcher = pii.pattern().matcher(result); if (matcher.find()) { piiFound = true; log.warn("PII detected (type={}), redacting", pii.name()); result = matcher.replaceAll(REDACTED); } } if (piiFound) { Span current = Span.current(); current.addEvent("support.pii_detected", Attributes.of( AttributeKey.booleanKey( "support.pii_redacted"), true )); } return result; } } ``` When PII is detected and redacted, the filter adds a `support.pii_detected` span event to the current active span with `support.pii_redacted = true`. This provides an audit trail in traces - you can see that PII was present and scrubbed without the trace containing the actual PII data. The filter is applied at two points in the pipeline: 1. **Response content** - `PiiFilter.scrub()` is called on the LLM response in `SupportPipeline.runPipeline()` before returning content to the client: ```java showLineNumbers title="src/main/java/com/example/support/pipeline/SupportPipeline.java" // 4. PII scrub String content = piiFilter.scrub(response.content()); ``` 2. **Span events** - In `LlmService.generateOnce()`, the PII filter scrubs prompt and completion content before writing it to span events: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" if (captureContent) { span.addEvent("gen_ai.user.message", Attributes.of( AttributeKey.stringKey("gen_ai.prompt"), truncate(piiFilter.scrub(userPrompt), 1000) )); // ... } ``` ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" if (captureContent) { span.addEvent("gen_ai.assistant.message", Attributes.of( AttributeKey.stringKey("gen_ai.completion"), truncate(piiFilter.scrub(content), 2000) )); } ``` Content capture itself is gated by the `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT` environment variable. The application checks this at startup: ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" this.captureContent = "true".equalsIgnoreCase( System.getenv( "OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT")); ``` When this variable is unset or set to anything other than `"true"`, no prompt or completion content is written to span events at all - a defense-in-depth approach where PII filtering is the second layer after the content capture gate. Additional security practices in the application: - **API keys via environment variables** - Provider API keys (`OPENAI_API_KEY`, `ANTHROPIC_API_KEY`, `GOOGLE_API_KEY`) are injected via environment variables, never hardcoded in source or configuration files. - **Content truncation limits** - Prompts are truncated to 1000 characters, system instructions to 500 characters, and completions to 2000 characters before writing to span events. This prevents large payloads from inflating trace storage costs. - **PII scrubbing before telemetry export** - The PII filter runs before content reaches OpenTelemetry span events, so sensitive data never leaves the application process. - **Spring AI observation content capture** - Spring AI's built-in Micrometer observations (Layer 2) have their own content capture setting (`spring.ai.chat.observations.include-input` / `spring.ai.chat.observations.include-output`) which defaults to false. This means Spring AI's auto-generated spans also do not capture content by default. ### Running Your Application **Development** In development, run directly with Gradle without the Java Agent. Spring AI's Micrometer observations and your manual OpenTelemetry spans still work - the Java Agent just adds the automatic HTTP/JDBC layer on top. Set your environment variables and start the application: ```bash showLineNumbers # Set environment variables export OPENAI_API_KEY=sk-... export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 export OTEL_SERVICE_NAME=ai-customer-support # Run with Spring Boot ./gradlew bootRun ``` For local development with Ollama (no API key needed): ```bash showLineNumbers SPRING_PROFILES_ACTIVE=ollama ./gradlew bootRun ``` Console output shows Spring AI observations and your manual spans. If you add a `debug` exporter to a local collector, you will see full span details in the collector logs. Without the Java Agent, you get Layer 2 (Spring AI Micrometer observations) and Layer 3 (manual OpenTelemetry API spans) but not Layer 1 (auto HTTP/JDBC spans). This is fine for development - the two manual layers provide full GenAI context. **Production** In production, attach the OpenTelemetry Java Agent for the full three-layer instrumentation stack: ```bash showLineNumbers java -javaagent:/path/to/opentelemetry-javaagent.jar \ -Dotel.service.name=ai-customer-support \ -Dotel.exporter.otlp.endpoint=http://collector:4318 \ -Dotel.exporter.otlp.protocol=http/protobuf \ -Dotel.traces.exporter=otlp \ -Dotel.metrics.exporter=otlp \ -Dotel.logs.exporter=otlp \ -jar app.jar ``` Configure sampling to control trace volume in high-traffic environments: ```yaml showLineNumbers title="application-production.yml" management: tracing: sampling: probability: 0.1 # 10% sampling for high-traffic ``` Set resource attributes to identify the deployment in your observability backend: ```bash showLineNumbers export OTEL_RESOURCE_ATTRIBUTES="service.name=ai-customer-support,deployment.environment=demo,environment=demo,service.version=1.2.0" ``` For production, always route telemetry through an OpenTelemetry Collector rather than exporting directly from the application. The collector provides buffering, retry logic, and filtering that protects both your application and your backend. **Docker Compose** The Docker Compose setup runs the application with the Java Agent, a PostgreSQL database with pgvector, and the OpenTelemetry Collector - the full production stack locally. The `Dockerfile` uses a multi-stage build that compiles the application, then downloads the Java Agent into the runtime image: ```dockerfile showLineNumbers title="Dockerfile" FROM gradle:9.2.1-jdk25 AS builder WORKDIR /app COPY build.gradle settings.gradle ./ COPY gradle ./gradle COPY src ./src RUN gradle build -x test --no-daemon FROM eclipse-temurin:25-jre WORKDIR /app ADD https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.25.0/opentelemetry-javaagent.jar /app/opentelemetry-javaagent.jar COPY --from=shared pricing.json /app/pricing.json COPY --from=builder /app/build/libs/ai-customer-support-0.0.1-SNAPSHOT.jar /app/app.jar EXPOSE 8080 ENTRYPOINT ["java", \ "-javaagent:/app/opentelemetry-javaagent.jar", \ "-jar", "/app/app.jar"] ``` The `compose.yml` wires together the application, database, and collector: ```yaml showLineNumbers title="compose.yml" services: app: build: context: . additional_contexts: shared: ../../_shared ports: - "8080:8080" environment: SPRING_R2DBC_URL: r2dbc:postgresql://postgres:5432/support SPRING_DATASOURCE_URL: jdbc:postgresql://postgres:5432/support DB_HOST: postgres DB_PORT: "5432" DB_NAME: support DB_USER: postgres DB_PASSWORD: postgres LLM_PROVIDER: ${LLM_PROVIDER:-openai} LLM_MODEL_CAPABLE: ${LLM_MODEL_CAPABLE:-gpt-4.1} LLM_MODEL_FAST: ${LLM_MODEL_FAST:-gpt-4.1-mini} FALLBACK_PROVIDER: ${FALLBACK_PROVIDER:-anthropic} FALLBACK_MODEL: ${FALLBACK_MODEL:-claude-haiku-4-5-20251001} OLLAMA_BASE_URL: ${OLLAMA_BASE_URL:-http://host.docker.internal:11434} OPENAI_API_KEY: ${OPENAI_API_KEY:-} ANTHROPIC_API_KEY: ${ANTHROPIC_API_KEY:-} GOOGLE_API_KEY: ${GOOGLE_API_KEY:-} DEFAULT_TEMPERATURE: ${DEFAULT_TEMPERATURE:-0.3} DEFAULT_MAX_TOKENS: ${DEFAULT_MAX_TOKENS:-1024} EMBEDDING_MODEL: ${EMBEDDING_MODEL:-text-embedding-3-small} EMBEDDING_DIMENSIONS: ${EMBEDDING_DIMENSIONS:-1536} EMBEDDING_PROVIDER: ${EMBEDDING_PROVIDER:-openai} PRICING_FILE: /app/pricing.json SPRING_PROFILES_ACTIVE: ${SPRING_PROFILES_ACTIVE:-} OTEL_SERVICE_NAME: ai-customer-support OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_INSTRUMENTATION_COMMON_DEFAULT_ENABLED: "true" OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT: ${OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT:-false} depends_on: postgres: condition: service_healthy otel-collector: condition: service_started healthcheck: test: [ "CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:8080/api/health", ] interval: 10s timeout: 5s retries: 10 start_period: 30s postgres: image: pgvector/pgvector:pg18 ports: - "5432:5432" environment: POSTGRES_DB: support POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres volumes: - ./db/schema.sql:/docker-entrypoint-initdb.d/01-schema.sql - ./db/seed.sql:/docker-entrypoint-initdb.d/02-seed.sql - pgdata:/var/lib/postgresql healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 otel-collector: image: otel/opentelemetry-collector-contrib:0.146.0 command: ["--config=/etc/otel-collector-config.yaml"] ports: - "4317:4317" - "4318:4318" - "13133:13133" volumes: - ./config/otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro environment: SCOUT_CLIENT_ID: ${SCOUT_CLIENT_ID:-} SCOUT_CLIENT_SECRET: ${SCOUT_CLIENT_SECRET:-} SCOUT_TOKEN_URL: ${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} SCOUT_ENDPOINT: ${SCOUT_ENDPOINT:-https://collector.base14.io} SCOUT_ENVIRONMENT: ${SCOUT_ENVIRONMENT:-development} healthcheck: test: ["NONE"] volumes: pgdata: ``` Start the stack and verify: ```bash showLineNumbers # Start all services docker compose up -d # Check health docker compose ps curl http://localhost:8080/api/health # View logs docker compose logs -f app ``` The OpenTelemetry Collector configuration handles telemetry routing, filtering, and export. This configuration includes the health check and zpages extensions for collector diagnostics, a noise filter for health check and HikariCP housekeeping spans, retry logic for the exporter, and a debug exporter for local development: ```yaml showLineNumbers title="config/otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*/health.*")' - 'IsMatch(name, ".*/actuator.*")' # HikariCP connection pool runs keepalive queries every ~30s on a # housekeeper thread. The JDBC auto-instrumentation creates orphan # single-span traces for these (no parent HTTP/pipeline context). # Drop them to avoid polluting the trace store. - 'attributes["thread.name"] != nil and IsMatch(attributes["thread.name"], "HikariPool.*housekeeper")' batch: timeout: 10s send_batch_size: 1024 send_batch_max_size: 2048 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: detailed sampling_initial: 100 sampling_thereafter: 100 service: extensions: [health_check, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, attributes, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] ``` Key collector configuration details: - **`health_check`** on port 13133 - used by Docker health checks and load balancers to verify the collector is running - **`zpages`** on port 55679 - provides live debugging pages at `/debug/tracez` and `/debug/pipelinez` for inspecting the collector's internal state - **`oauth2client`** - authenticates with base14 Scout using OAuth2 client credentials - **`memory_limiter`** - caps the collector at 512 MiB with a 128 MiB spike buffer, preventing OOM in constrained environments - **`filter/noisy`** - drops health check, actuator, and HikariCP housekeeper spans that add volume without diagnostic value - **`retry_on_failure`** - retries failed exports with exponential backoff from 1s to 30s, for up to 5 minutes total - **`debug` exporter** - logs detailed span information locally, invaluable during development and initial deployment validation ### Troubleshooting Verify your deployment is working by sending a health check and a test message: ```bash showLineNumbers # Health check curl http://localhost:8080/api/health # Send a test message curl -X POST http://localhost:8080/api/chat \ -H "Content-Type: application/json" \ -d '{"message": "What is the status of order ORD-10001?"}' ``` The response should include the AI-generated answer along with metadata like model name, token counts, and cost. The corresponding trace should appear in your observability backend within a few seconds. Enable debug logging to diagnose instrumentation issues: ```bash showLineNumbers # Enable Java Agent debug logging OTEL_LOG_LEVEL=debug docker compose up # Enable Spring AI observation logging # Add to application.yml or pass as -D flag: # logging.level.org.springframework.ai=DEBUG ``` #### No traces appearing Check that the collector endpoint URL matches between the application and the collector. The application sends to `http://otel-collector:4318` (the Docker service name), not `localhost`: ```bash showLineNumbers # Check collector logs for incoming data docker compose logs otel-collector # Verify the Java Agent loaded docker compose logs app | grep "opentelemetry-javaagent" ``` Confirm the Java Agent JAR path in the Dockerfile matches the download URL. If the path is wrong, the JVM starts without the agent silently - no error, just no Layer 1 spans. #### Spring AI spans missing Verify that `micrometer-tracing-bridge-otel` is in your `build.gradle` dependencies. This bridge is what connects Spring AI's Micrometer observations to OpenTelemetry. Without it, Spring AI creates observations but they never become OpenTelemetry spans. Check that sampling is not set to zero: ```yaml showLineNumbers title="application.yml" management: tracing: sampling: probability: 1.0 # Must be > 0; 1.0 for development ``` #### Duplicate spans from Java Agent and Spring AI The Java Agent auto-instruments HTTP clients (Netty, Apache HttpClient, etc.), and Spring AI creates its own ChatModel observation spans. This means a single LLM call produces both an HTTP span (from the agent) and a ChatModel span (from Spring AI). This is expected behavior, not a bug - the HTTP span shows network timing while the ChatModel span shows model-level metadata. If the volume is excessive, the `filter/noisy` processor in the collector configuration can drop specific span patterns. But in most cases, both spans provide useful and non-overlapping information. #### pgvector connection errors The application uses two separate database connections: R2DBC for reactive repository operations and JDBC for pgvector vector store and tool-calling queries. Both must be configured: ```yaml showLineNumbers title="application.yml" spring: r2dbc: url: r2dbc:postgresql://postgres:5432/support datasource: url: jdbc:postgresql://postgres:5432/support ``` Verify the pgvector extension is enabled in the database: ```sql showLineNumbers CREATE EXTENSION IF NOT EXISTS vector; ``` The seed SQL scripts (`db/schema.sql`) handle this automatically, but if you are connecting to an existing database, you need the extension installed manually. #### Tool calls not showing in traces Verify tools are registered via `MethodToolCallbackProvider` and that you are using `ToolCallingChatOptions` (not plain `ChatOptions`) when building prompts for tool-enabled calls: ```java showLineNumbers // Correct: ToolCallingChatOptions enables tool discovery var options = ToolCallingChatOptions.builder() .model(model) .toolCallbacks(toolCallbacks) .build(); // Wrong: plain ChatOptions ignores tool callbacks var options = ChatOptions.builder() .model(model) .build(); ``` Each `@Tool` method should call `SupportMetrics.recordToolCall()` to record the tool invocation in your custom metrics. Without this call, the tool executes but no `support.tool.calls` metric is emitted. ### Performance Considerations Three-layer instrumentation adds measurable but minimal overhead to each request: | Layer | Latency Overhead | Memory | CPU | | -------------------- | ----------------------- | ----------- | ---------- | | Java Agent | 1-3ms per span | ~50MB heap | <1% | | Spring AI Micrometer | <1ms per observation | Negligible | Negligible | | Manual OTel API | <0.5ms per span | Negligible | Negligible | | Combined | 2-5ms per request | ~60MB total | 1-2% | For an AI application where LLM calls take 500ms-5s each, the 2-5ms instrumentation overhead is negligible - well under 1% of total request latency. Five practices to optimize instrumentation performance in production: 1. **Use sampling for high-traffic services.** Set `management.tracing.sampling.probability` to 0.1-0.5 in production. A 10% sample rate captures enough data for trend analysis while reducing trace volume by 90%. For AI applications with relatively low request volume (compared to CRUD APIs), you may keep 1.0 sampling. 2. **The memory_limiter processor prevents collector OOM.** The collector configuration sets a 512 MiB limit with a 128 MiB spike buffer. When the collector approaches the limit, it drops new telemetry rather than crashing. This protects the collector process in memory-constrained container environments. 3. **BatchSpanProcessor batches exports to reduce network calls.** The Java Agent uses `BatchSpanProcessor` by default, which buffers spans and exports them in batches (default: every 5 seconds or 512 spans, whichever comes first). This means individual span creation never blocks on network I/O. 4. **Content capture is disabled by default.** The `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT` environment variable defaults to false. Enabling it adds JSON serialization overhead for every prompt and completion - significant for large payloads. Only enable content capture during debugging or for specific trace sampling. 5. **Filter noisy spans in the collector.** The `filter/noisy` processor drops health check, actuator, and HikariCP housekeeper spans. In a Spring Boot application, actuator endpoints alone can generate dozens of spans per minute. Filtering these at the collector level (rather than the application) means the application still exports them for debugging if you temporarily remove the filter. ### FAQ #### How much overhead does OpenTelemetry add to a Spring AI application? Combined overhead is 2-5ms per request with approximately 60MB additional heap usage. For AI applications where LLM calls dominate latency (500ms-5s per call), this is less than 1% overhead. The Java Agent's `BatchSpanProcessor` ensures span creation never blocks on network I/O, and the Micrometer observation layer adds sub-millisecond overhead per observation. #### Do I need all three OpenTelemetry layers or can I use fewer? Yes. Each layer is independent: - **Layer 1 only (Java Agent)**: Add `-javaagent` flag. You get HTTP, JDBC, and R2DBC spans with zero code changes, but no GenAI attributes. - **Layer 2 only (Spring AI Micrometer)**: Add `micrometer-tracing-bridge-otel` to dependencies. You get ChatModel and VectorStore spans with model names and token counts. - **Layer 3 only (Manual OTel API)**: Use `GlobalOpenTelemetry.getTracer()`. You get full GenAI semantic conventions, custom metrics, and pipeline context. - **Layer 1 + 2**: Auto HTTP/JDBC spans plus Spring AI observations. Good coverage without any manual instrumentation code. - **Layer 2 + 3**: Spring AI observations plus manual GenAI spans. Full AI context without the Java Agent JAR. The full three-layer stack provides the most complete traces, but any combination works. #### What Spring AI versions are compatible? This guide uses Spring AI 2.0.0-M2 with Spring Boot 4.0.3. The key requirement is that Spring AI must emit Micrometer observations (available since Spring AI 1.0.0-M1). The `micrometer-tracing-bridge-otel` dependency must match your Spring Boot version's Micrometer version - Spring Boot's dependency management BOM handles this automatically. #### How do I reduce trace volume in production? Four approaches, from least to most aggressive: 1. **Sampling**: Set `management.tracing.sampling.probability` to 0.1-0.5. 2. **Collector filtering**: The `filter/noisy` processor drops health checks, actuator endpoints, and HikariCP housekeeping spans. 3. **Head-based sampling at the collector**: Add a `probabilistic_sampler` processor to the collector pipeline for additional server-side sampling. 4. **Disable Layer 1**: Remove the Java Agent to eliminate HTTP/JDBC auto-spans while keeping the AI-specific spans from Layers 2 and 3. #### Can I use the OpenTelemetry Java Agent with Spring AI at the same time? No. The Java Agent instruments at the bytecode level (HTTP clients, JDBC drivers) while Spring AI observations operate at the application framework level (ChatModel, VectorStore). They share the same OpenTelemetry context, so their spans appear as parent-child in the same trace. The only overlap is HTTP client spans - the Java Agent creates an HTTP span for the outbound LLM API call, and Spring AI creates a ChatModel observation span. Both carry useful but different information (network timing vs. model metadata). #### How do I add a new LLM provider (e.g., Google Gemini)? Add the Spring AI starter for the provider to `build.gradle`: ```groovy showLineNumbers implementation 'org.springframework.ai:spring-ai-starter-model-vertex-ai-gemini' ``` Then register the ChatModel bean and add a case in `LlmConfig.resolveChatModel()` to map the provider name to the bean. The three-layer instrumentation works automatically - the Java Agent captures the HTTP call to Google's API, Spring AI emits a ChatModel observation, and `LlmService.generateOnce()` creates the GenAI span with the correct `gen_ai.provider.name` attribute. #### How do I track costs across multiple providers? The `LlmService` loads pricing data from `pricing.json`, which maps model names to per-token input and output costs. Each `generateOnce()` call calculates cost using `pricing.calculateCost(responseModel, inputTokens, outputTokens)` and records it to both the span attribute (`gen_ai.usage.cost_usd`) and the `gen_ai.client.cost` metric counter. To add a new model, add its pricing to `pricing.json`. To aggregate costs, query the `gen_ai.client.cost` metric grouped by `gen_ai.provider.name` and `gen_ai.request.model`. #### How should I handle PII in production telemetry? The application applies two layers of PII protection: 1. **Content capture gate**: The `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT` environment variable (default: false) controls whether prompts and completions are written to span events at all. In production, leave this disabled. 2. **PII filter**: When content capture is enabled, the `PiiFilter` scrubs email addresses, phone numbers, SSNs, and credit card numbers before writing to span events. This is a defense-in-depth measure. Span attributes like model name, token counts, and cost never contain PII and are always safe to export. #### Can I deploy to Kubernetes instead of Docker Compose? Yes. The Docker Compose setup translates directly to Kubernetes: - The `app` service becomes a Deployment with the same environment variables - The `postgres` service becomes a StatefulSet or a managed database service - The `otel-collector` becomes a DaemonSet or a sidecar container - Environment variables from `.env` move to Kubernetes Secrets and ConfigMaps - The collector config becomes a ConfigMap mounted as a volume The application code and Dockerfile do not change. Only the orchestration layer differs. #### How do I debug missing GenAI attributes on spans? If spans appear but lack `gen_ai.*` attributes, the issue is in Layer 3 (manual instrumentation). Check these in order: 1. **Verify `GlobalOpenTelemetry.getTracer()` returns a real tracer.** If the Java Agent is not loaded or the SDK is not initialized, it returns a no-op tracer that creates spans silently discarded. 2. **Check that `span.setAttribute()` calls use the correct attribute names.** The GenAI semantic conventions use underscores (`gen_ai.request.model`), not dots or hyphens. 3. **Confirm the span is ended.** Attributes set on a span after `span.end()` are ignored. The `try/finally` pattern in `generateOnce()` ensures the span is always ended. 4. **Look at the debug exporter output.** The collector's `debug` exporter logs every span with all attributes. If the attributes are present in the debug output but missing in your backend, the issue is in the backend's indexing, not the instrumentation. ### What's Next #### Advanced Topics - [Custom Java Instrumentation](../../instrument/apps/custom-instrumentation/java.md) - manual spans and metrics for non-AI Java applications - [Spring Boot Auto-Instrumentation](../../instrument/apps/auto-instrumentation/spring-boot.md) - zero-code instrumentation for Spring Boot web applications - [LLM Observability](../llm-observability) - Python patterns for LLM observability - [Rust LLM Observability](../rust-llm-observability) - Rust patterns with manual GenAI instrumentation #### Scout Platform Features - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - set up cost, latency, and error rate alerts - [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) — visualize AI metrics #### Deployment and Operations - [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) - collector deployment reference ### Complete Example The following files form a working deployment of the AI customer support application with full three-layer observability. The complete source code is available at [github.com/base-14/examples/tree/main/java/ai-customer-support](https://github.com/base-14/examples/tree/main/java/ai-customer-support). #### build.gradle The dependencies include Spring AI with three LLM providers, the Micrometer OpenTelemetry bridge, the OpenTelemetry API, pgvector for RAG, and both R2DBC and JDBC database drivers: ```groovy showLineNumbers title="build.gradle" plugins { id 'java' id 'org.springframework.boot' version '4.0.3' id 'io.spring.dependency-management' version '1.1.7' } group = 'com.example' version = '0.0.1-SNAPSHOT' java { toolchain { languageVersion = JavaLanguageVersion.of(25) } } repositories { mavenCentral() } dependencyManagement { imports { mavenBom "org.springframework.ai:spring-ai-bom:2.0.0-M2" } } dependencies { // Web (reactive) implementation 'org.springframework.boot:spring-boot-starter-webflux' // Observability implementation 'org.springframework.boot:spring-boot-starter-actuator' implementation 'io.micrometer:micrometer-tracing-bridge-otel' implementation 'io.opentelemetry:opentelemetry-exporter-otlp' implementation 'io.opentelemetry:opentelemetry-api' // Spring AI - LLM providers implementation 'org.springframework.ai:spring-ai-starter-model-openai' implementation 'org.springframework.ai:spring-ai-starter-model-anthropic' implementation 'org.springframework.ai:spring-ai-starter-model-ollama' // Spring AI - pgvector RAG implementation 'org.springframework.ai:spring-ai-starter-vector-store-pgvector' // Database (reactive + JDBC for pgvector) implementation 'org.springframework.boot:spring-boot-starter-data-r2dbc' implementation 'org.springframework.boot:spring-boot-starter-jdbc' implementation 'org.postgresql:r2dbc-postgresql' implementation 'org.postgresql:postgresql' // JSON implementation 'com.fasterxml.jackson.core:jackson-databind' // Test testImplementation 'org.springframework.boot:spring-boot-starter-test' testImplementation 'io.projectreactor:reactor-test' } bootJar { mainClass = 'com.example.support.Application' } tasks.named('test') { useJUnitPlatform() } ``` #### LlmService.java (abbreviated) The core LLM call method that creates GenAI spans with semantic convention attributes, records token usage and cost metrics, and handles content capture with PII filtering. See the [Custom LLM Instrumentation](#custom-llm-instrumentation) section for the full walkthrough. ```java showLineNumbers title="src/main/java/com/example/support/llm/LlmService.java" private LlmResponse generateOnce( ChatModel chatModel, String providerName, String model, String systemPrompt, String userPrompt, String stage, List toolCallbacks ) { String spanName = "gen_ai.chat " + model; long start = System.nanoTime(); Span span = tracer.spanBuilder(spanName) .setAttribute("gen_ai.operation.name", "chat") .setAttribute("gen_ai.provider.name", providerName) .setAttribute("gen_ai.request.model", model) .setAttribute("gen_ai.request.temperature", config.temperature()) .setAttribute("gen_ai.request.max_tokens", (long) config.maxTokens()) .startSpan(); try (Scope ignored = span.makeCurrent()) { // ... prompt building and content capture (see Custom LLM Instrumentation section) ChatResponse response = chatModel.call(prompt); // Extract token usage, cost, finish reason // ... see Custom LLM Instrumentation section span.setAttribute("gen_ai.response.model", responseModel); span.setAttribute("gen_ai.usage.input_tokens", (long) inputTokens); span.setAttribute("gen_ai.usage.output_tokens", (long) outputTokens); span.setAttribute("gen_ai.usage.cost_usd", costUsd); // Record metrics tokenUsage.record(inputTokens, withTokenType(attrs, "input")); tokenUsage.record(outputTokens, withTokenType(attrs, "output")); operationDuration.record(duration, attrs); costCounter.add(costUsd, attrs); return new LlmResponse(content, responseModel, providerName, inputTokens, outputTokens, costUsd, finishReason); } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); errorCounter.add(1, /* ... */); throw e; } finally { span.end(); } } ``` #### SupportPipeline.java (abbreviated) The 6-stage pipeline that orchestrates intent classification, RAG retrieval, response generation, PII scrubbing, escalation routing, and metrics recording under a single parent span. See the [Pipeline Observability](#pipeline-observability) section for the full walkthrough. ```java showLineNumbers title="src/main/java/com/example/support/pipeline/SupportPipeline.java" private PipelineResult runPipeline( String userMessage, UUID conversationId, List history ) { long startNanos = System.nanoTime(); Span span = tracer.spanBuilder("support_conversation") .setAttribute("support.conversation_id", conversationId.toString()) .startSpan(); try (Scope ignored = span.makeCurrent()) { // 1. Classify intent (fast model) IntentResult intent = intentClassifier.classify(userMessage); span.setAttribute("support.intent", intent.intent().name()); // 2. Retrieve RAG context var ragDocs = contextRetriever.retrieve(userMessage); span.setAttribute("support.rag_matches", ragDocs.size()); // 3. Generate response (capable model) LlmResponse response = responseGenerator.generate( userMessage, intent, ragDocs, conversationHistory); // 4. PII scrub String content = piiFilter.scrub(response.content()); // 5. Check escalation EscalationDecision escalation = escalationRouter.evaluate(intent, turns, 0); // 6. Record domain metrics // ... see Pipeline Orchestration section return new PipelineResult(content, intent, escalation, response.model(), response.provider(), response.inputTokens(), response.outputTokens(), response.costUsd(), conversationId); } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); throw new RuntimeException("Pipeline failed: " + e.getMessage(), e); } finally { span.end(); } } ``` #### compose.yml See the [Docker Compose tab](#running-your-application) above for the full `compose.yml` and `Dockerfile`. #### otel-collector-config.yaml See the [Docker Compose tab](#running-your-application) above for the full collector configuration with all production essentials: `retry_on_failure`, `debug` exporter, `health_check`/`zpages` extensions, `filter/noisy` processor, and `memory_limiter`. ### References - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [Spring AI Documentation](https://docs.spring.io/spring-ai/reference/) - [OpenTelemetry Java Agent](https://opentelemetry.io/docs/zero-code/java/agent/) - [OpenTelemetry Java SDK](https://opentelemetry.io/docs/languages/java/) - [Micrometer Tracing](https://micrometer.io/docs/tracing) ### Related Guides - [LLM Observability](../llm-observability) - Python patterns for AI application tracing - [Rust LLM Observability](../rust-llm-observability) - Rust patterns with manual GenAI instrumentation - [Spring Boot Auto-Instrumentation](../../instrument/apps/auto-instrumentation/spring-boot.md) - zero-code OpenTelemetry for Spring Boot web applications - [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) --- ## ArgoCD Monitoring with OpenTelemetry - Metrics, Sync Status & Health ## ArgoCD ArgoCD is a declarative GitOps continuous delivery tool for Kubernetes that exposes Prometheus-format metrics from three core components: the application controller (`:8082/metrics`), the API server (`:8083/metrics`), and the repo server (`:8084/metrics`). The OpenTelemetry Collector scrapes these endpoints using the Prometheus receiver, collecting metrics across application sync status, health state, reconciliation performance, Git request latency, and gRPC request rates. This guide configures the receiver, connects to an ArgoCD installation on Kubernetes, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | ArgoCD | 2.5 | 2.13+ | | OTel Collector Contrib | 0.90.0 | 0.127+ | | base14 Scout | Any | - | Before starting: - ArgoCD must be running on a Kubernetes cluster - Metrics ports (8082, 8083, 8084) must be accessible from the host or pod running the Collector - ArgoCD exposes metrics by default - no additional configuration is needed on the ArgoCD side - OTel Collector installed - see [Kubernetes Helm Setup](../../instrument/collector-setup/kubernetes-helm-setup.md) ### What You'll Monitor - **Application State** (controller): sync status (synced, out-of-sync), health status (healthy, degraded, missing, unknown), app count per cluster and project, orphaned resource count - **Reconciliation** (controller): reconciliation duration per destination cluster, kubectl execution count and duration, kubectl request/response sizes - **Cluster** (controller): cluster connection status, cluster cache age, API resource objects count, cluster event totals - **API Server**: ArgoCD version info, gRPC request rates and totals by method, kubectl and Redis request performance - **Repository Operations** (repo-server): Git request duration and count by repo and request type (fetch, ls-remote), manifest generation time, pending request count - **Notifications** (optional): Go runtime and process metrics for the notifications controller Full metric list: port-forward each component and run `curl -s http://localhost:{port}/metrics` against your ArgoCD installation. ### Access Setup ArgoCD exposes Prometheus metrics by default on all components. No additional configuration is needed to enable the endpoints. Each component exposes metrics on a dedicated port: | Component | Default Port | Endpoint | | ------------------------------- | ------------ | ---------- | | argocd-application-controller | 8082 | `/metrics` | | argocd-server | 8083 | `/metrics` | | argocd-repo-server | 8084 | `/metrics` | | argocd-applicationset-controller| 8080 | `/metrics` | | argocd-notifications-controller | 9001 | `/metrics` | #### Manifest Install When installed via plain manifests (`kubectl apply`), ArgoCD creates dedicated metrics services: | Service Name | Port | | ----------------------------------------- | ---- | | `argocd-metrics` | 8082 | | `argocd-server-metrics` | 8083 | | `argocd-repo-server` | 8084 | | `argocd-notifications-controller-metrics` | 9001 | Verify the endpoints are working: ```bash showLineNumbers title="Verify access (manifest install)" # Port-forward the application controller metrics kubectl -n argocd port-forward svc/argocd-metrics 8082:8082 # In another terminal, check metrics curl -s http://localhost:8082/metrics | head -20 # Verify a key ArgoCD metric exists curl -s http://localhost:8082/metrics | grep argocd_app_info ``` #### Helm Install When installed via the Helm chart (`argo/argo-cd`), metrics services are **not created by default**. Enable them in your Helm values: ```yaml showLineNumbers title="values.yaml" controller: metrics: enabled: true server: metrics: enabled: true repoServer: metrics: enabled: true notifications: metrics: enabled: true ``` Or pass the flags directly: ```bash showLineNumbers title="Helm install with metrics" helm install argocd argo/argo-cd \ --namespace argocd --create-namespace \ --set controller.metrics.enabled=true \ --set server.metrics.enabled=true \ --set repoServer.metrics.enabled=true \ --set notifications.metrics.enabled=true ``` With metrics enabled, the Helm chart creates these services: | Service Name | Port | | ----------------------------------------- | ---- | | `argocd-application-controller-metrics` | 8082 | | `argocd-server-metrics` | 8083 | | `argocd-repo-server-metrics` | 8084 | | `argocd-notifications-controller-metrics` | 9001 | Verify: ```bash showLineNumbers title="Verify access (Helm install)" kubectl -n argocd port-forward svc/argocd-application-controller-metrics 8082:8082 curl -s http://localhost:8082/metrics | grep argocd_app_info ``` In Kubernetes, the Collector typically runs as a sidecar or DaemonSet and accesses these ports via the cluster network. No port-forwarding is needed in that case. ### Configuration ArgoCD has three primary components that expose metrics. The Collector configuration uses one scrape job per component. #### Manifest Install ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: argocd-application-controller scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-metrics.argocd.svc.cluster.local:8082 - job_name: argocd-server scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-server-metrics.argocd.svc.cluster.local:8083 - job_name: argocd-repo-server scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-repo-server.argocd.svc.cluster.local:8084 processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Helm Install When using the Helm chart with metrics services enabled, the service names differ: ```yaml showLineNumbers title="config/otel-collector.yaml (Helm)" receivers: prometheus: config: scrape_configs: - job_name: argocd-application-controller scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-application-controller-metrics.argocd.svc.cluster.local:8082 - job_name: argocd-server scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-server-metrics.argocd.svc.cluster.local:8083 - job_name: argocd-repo-server scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-repo-server-metrics.argocd.svc.cluster.local:8084 processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Kubernetes Service Discovery For dynamic scrape target discovery, use `kubernetes_sd_configs` instead of static targets. This automatically discovers ArgoCD metrics services: ```yaml showLineNumbers title="config/otel-collector.yaml (service discovery)" receivers: prometheus: config: scrape_configs: - job_name: argocd scrape_interval: 30s kubernetes_sd_configs: - role: endpoints namespaces: names: - argocd relabel_configs: - source_labels: [__meta_kubernetes_service_name] regex: "argocd-metrics|argocd-server-metrics|argocd-repo-server|argocd-application-controller-metrics|argocd-repo-server-metrics" action: keep - source_labels: [__meta_kubernetes_service_name] target_label: argocd_component ``` This approach works with both manifest and Helm installations. #### Filtering Metrics ArgoCD components expose Go runtime and process metrics alongside ArgoCD-specific metrics. The server also exposes standard gRPC metrics. To collect only relevant metrics: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" receivers: prometheus: config: scrape_configs: - job_name: argocd-application-controller scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-metrics.argocd.svc.cluster.local:8082 metric_relabel_configs: - source_labels: [__name__] regex: "argocd_.*" action: keep - job_name: argocd-server scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-server-metrics.argocd.svc.cluster.local:8083 metric_relabel_configs: - source_labels: [__name__] regex: "argocd_.*|grpc_server_.*" action: keep - job_name: argocd-repo-server scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - argocd-repo-server.argocd.svc.cluster.local:8084 metric_relabel_configs: - source_labels: [__name__] regex: "argocd_.*|grpc_server_.*" action: keep ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for successful scrape kubectl logs -n \ | grep -i "argocd" # Verify ArgoCD controller metrics directly kubectl -n argocd port-forward svc/argocd-metrics 8082:8082 curl -s http://localhost:8082/metrics \ | grep argocd_app_info # Check server metrics kubectl -n argocd port-forward svc/argocd-server-metrics 8083:8083 curl -s http://localhost:8083/metrics \ | grep grpc_server_handled_total ``` ### Troubleshooting #### Connection refused on metrics port **Cause**: Collector cannot reach ArgoCD pods at the configured service address. **Fix**: 1. Verify the metrics services exist: `kubectl -n argocd get svc | grep metrics` 2. Service names differ between manifest and Helm installs - see [Access Setup](#access-setup) 3. Check network policies - ArgoCD creates NetworkPolicy resources that may block Collector access 4. Confirm the Collector pod can reach the argocd namespace #### No application metrics (argocd_app_info missing) **Cause**: No ArgoCD Applications have been created yet. **Fix**: 1. ArgoCD only emits `argocd_app_*` metrics when at least one Application CR exists 2. Create a sample Application to verify: `kubectl -n argocd get applications` 3. Once an Application is synced, `argocd_app_info`, `argocd_app_reconcile`, and `argocd_cluster_*` metrics appear #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `kubectl logs ` 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly 3. Confirm the pipeline includes both the receiver and exporter #### Partial metrics - only some components reporting **Cause**: Not all ArgoCD component endpoints are configured in the scrape config. **Fix**: 1. Verify all three scrape jobs are present in the Collector config 2. Check that service names match your install method (manifest vs Helm) 3. Verify each service is reachable: `kubectl -n argocd port-forward svc/ :` #### Helm install - no metrics services found **Cause**: The Helm chart does not create metrics services by default. **Fix**: 1. Enable metrics in Helm values: `controller.metrics.enabled=true`, `server.metrics.enabled=true`, `repoServer.metrics.enabled=true` 2. Upgrade: `helm upgrade argocd argo/argo-cd -n argocd -f values.yaml` 3. Verify: `kubectl -n argocd get svc | grep metrics` ### FAQ #### Does this work with ArgoCD installed via Helm? Yes. Enable metrics services in the Helm values by setting `controller.metrics.enabled`, `server.metrics.enabled`, and `repoServer.metrics.enabled` to `true`. The Helm chart creates dedicated metrics services with different names than the manifest install - see [Access Setup](#access-setup) for the full mapping. Verify your service names with `kubectl -n argocd get svc`. #### How do I monitor ArgoCD in a multi-cluster setup? Each ArgoCD instance manages one or more target clusters. Deploy one Collector config per ArgoCD control plane. The `argocd_cluster_info` metric includes a `server` label identifying the managed cluster, and `argocd_cluster_connection_status` reports whether each cluster is reachable. #### Which component exposes sync status metrics? The application controller (port 8082) emits all application state metrics. The `argocd_app_info` metric includes `sync_status` and `health_status` labels: ```text argocd_app_info{name="guestbook",sync_status="OutOfSync",health_status="Missing",...} 1 ``` The server (port 8083) only exposes API/gRPC request metrics and ArgoCD version info (`argocd_info`). #### Can I use Kubernetes service discovery instead of static targets? Yes. See the [Kubernetes Service Discovery](#kubernetes-service-discovery) section above. This approach uses `kubernetes_sd_configs` with `relabel_configs` to match ArgoCD metrics services automatically and works with both manifest and Helm installations. #### What is the difference between manifest and Helm service names? The service names for metrics differ between install methods: | Component | Manifest | Helm (metrics enabled) | | ------------------- | ----------------------------------------- | ----------------------------------------- | | Application Controller | `argocd-metrics` | `argocd-application-controller-metrics` | | Server | `argocd-server-metrics` | `argocd-server-metrics` | | Repo Server | `argocd-repo-server` | `argocd-repo-server-metrics` | | Notifications | `argocd-notifications-controller-metrics` | `argocd-notifications-controller-metrics` | Always verify with `kubectl -n argocd get svc` to confirm the service names in your environment. #### How do I monitor ArgoCD with Prometheus? ArgoCD exposes Prometheus-format metrics on dedicated endpoints (ports 8082, 8083, 8084) for the application controller, API server, and repo server. Scrape these endpoints using the OpenTelemetry Collector's Prometheus receiver or a native Prometheus ServiceMonitor. See [Configuration](#configuration) for complete scrape configs. #### What metrics does ArgoCD expose? ArgoCD exposes metrics across five categories: `argocd_app_info` (sync and health status per application), `argocd_app_reconcile` (reconciliation duration), `argocd_git_request_total` (Git fetch/ls-remote counts and duration), `argocd_cluster_connection_status` (managed cluster connectivity), and `grpc_server_handled_total` (API request rates). Run `curl http://localhost:8082/metrics` against a running instance for the full list. #### What is the default ArgoCD metrics endpoint? The application controller exposes metrics at `:8082/metrics`, the API server at `:8083/metrics`, and the repo server at `:8084/metrics`. These are enabled by default in manifest installs. For Helm installs, set `controller.metrics.enabled`, `server.metrics.enabled`, and `repoServer.metrics.enabled` to `true`. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../create-your-first-dashboard.md) - **Monitor More Components**: Add monitoring for [etcd](../../instrument/component/etcd.md), [Consul](../../instrument/component/consul.md), and other components - **Fine-tune Collection**: Use `metric_relabel_configs` to focus on application sync and health metrics for production alerting ### Related Guides - [OTel Collector Configuration](../../instrument/collector-setup/otel-collector-config.md) - Advanced collector configuration - [Kubernetes Helm Setup](../../instrument/collector-setup/kubernetes-helm-setup.md) - Production deployment on Kubernetes - [Docker Compose Setup](../../instrument/collector-setup/docker-compose-example.md) - Run the Collector locally - [Creating Alerts](../creating-alerts-with-logx.md) - Alert on ArgoCD metrics - [etcd Monitoring](../../instrument/component/etcd.md) - Often co-deployed with ArgoCD on Kubernetes --- ## GitHub Actions Observability with OpenTelemetry CI/CD pipelines are critical infrastructure. Builds slow down over weeks, flaky tests waste developer time, and when a pipeline breaks, diagnosing the root cause means clicking through GitHub's UI one run at a time. The **Scout OpenTelemetry CI/CD Action** solves this by exporting your GitHub Actions workflow runs as OpenTelemetry traces. Each workflow becomes a trace, each job becomes a child span, and each step becomes a span within its job. You get the same structured observability for your pipelines that you already have for your applications. ### Time to Complete 10-15 minutes ### What You'll Accomplish - Export GitHub Actions workflows as OpenTelemetry traces to Scout - Visualize pipeline execution as a trace waterfall (workflow → jobs → steps) - Identify slow steps and failure patterns across your CI/CD pipelines - Set up monitoring without modifying your existing workflows ### How It Works The action runs after your workflow completes and uses the GitHub API to fetch the full run data - jobs, steps, timestamps, and outcomes. It converts this data into OpenTelemetry traces following the [CICD semantic conventions](https://opentelemetry.io/docs/specs/semconv/attributes-registry/cicd/) and exports them to your OTLP endpoint. The resulting trace hierarchy looks like this: ```text Workflow Run (root span) ├── Job: build (child span) │ ├── Step: Checkout code │ ├── Step: Install dependencies │ ├── Step: Run tests │ └── Step: Build artifact └── Job: deploy (child span) ├── Step: Download artifact └── Step: Deploy to production ``` Each span includes timing data, status (success/failure), and GitHub metadata like the commit SHA, branch, actor, and run URL. ### Prerequisites - A Scout account with OAuth2 credentials (client ID, client secret, and tenant name) - A GitHub repository with one or more workflows ### Option A: Workflow Run Trigger (Recommended) This approach creates a dedicated monitoring workflow that triggers automatically after any workflow completes. It requires no changes to your existing workflows. Create a new file at `.github/workflows/otel-export.yml`: ```yaml name: Export CI/CD Traces to Scout on: workflow_run: workflows: ["*"] types: - completed jobs: otel-export: runs-on: ubuntu-latest steps: - name: Export workflow trace uses: base-14/otel-cicd-action@v1.0.0 with: otlpEndpoint: ${{ secrets.SCOUT_OTLP_ENDPOINT }} otelServiceName: my-repo-ci githubToken: ${{ secrets.GITHUB_TOKEN }} runId: ${{ github.event.workflow_run.id }} tokenUrl: >- https://id.b14.dev/realms/${{ secrets.SCOUT_TENANT }}/protocol/openid-connect/token appName: ${{ secrets.SCOUT_CLIENT_ID }} apiKey: ${{ secrets.SCOUT_CLIENT_SECRET }} audience: b14collector ``` #### Required Secrets Add these secrets to your repository under **Settings → Secrets and variables → Actions**: | Secret | Description | | --------------------- | --------------------------------------------- | | `SCOUT_OTLP_ENDPOINT` | Your Scout OTLP endpoint (provided via email) | | `SCOUT_TENANT` | Your Scout tenant name | | `SCOUT_CLIENT_ID` | OAuth2 client ID from Scout | | `SCOUT_CLIENT_SECRET` | OAuth2 client secret from Scout | `GITHUB_TOKEN` is provided automatically by GitHub Actions. #### How It Works The `workflow_run` event fires after any workflow in your repository completes. The `runId` input points to the completed workflow's run ID (`github.event.workflow_run.id`), so the action fetches and exports that run's data - not its own. ### Option B: In-Workflow Job If you prefer to keep the export step within a specific workflow, add it as a final job that runs regardless of whether previous jobs succeed or fail. ```yaml name: CI Pipeline on: push: branches: [main] pull_request: jobs: build: runs-on: ubuntu-latest steps: - uses: actions/checkout@v4 - name: Install dependencies run: npm ci - name: Run tests run: npm test - name: Build run: npm run build deploy: needs: build runs-on: ubuntu-latest steps: - name: Deploy run: echo "Deploying..." otel-export: needs: [build, deploy] if: always() runs-on: ubuntu-latest steps: - name: Export workflow trace uses: base-14/otel-cicd-action@v1.0.0 with: otlpEndpoint: ${{ secrets.SCOUT_OTLP_ENDPOINT }} otelServiceName: my-repo-ci githubToken: ${{ secrets.GITHUB_TOKEN }} tokenUrl: >- https://id.b14.dev/realms/${{ secrets.SCOUT_TENANT }}/protocol/openid-connect/token appName: ${{ secrets.SCOUT_CLIENT_ID }} apiKey: ${{ secrets.SCOUT_CLIENT_SECRET }} audience: b14collector ``` Key details: - **`needs: [build, deploy]`** - waits for all jobs to finish before exporting - **`if: always()`** - ensures the export runs even if a previous job fails, so you capture traces for broken builds too - **`runId`** is omitted - it defaults to the current workflow run ID ### Configuration Reference | Input | Required | Default | Description | | ----------------- | -------- | ------------------ | --------------------------------------------------------------------- | | `otlpEndpoint` | Yes | - | OTLP endpoint to export traces to | | `otlpHeaders` | No | `""` | Additional HTTP headers for the OTLP endpoint | | `otelServiceName` | No | `""` | OpenTelemetry service name for the exported traces | | `githubToken` | No | `secrets.GITHUB_TOKEN` | Repository token with workflow read permissions | | `runId` | No | `env.GITHUB_RUN_ID` | Workflow run ID to export (defaults to the current run) | | `extraAttributes` | No | - | Extra resource attributes to add to each span | | `tokenUrl` | No | `""` | OAuth2 token endpoint URL for `client_credentials` flow | | `appName` | No | `""` | OAuth2 client ID (application name) for `client_credentials` flow | | `apiKey` | No | `""` | OAuth2 client secret (API key) for `client_credentials` flow | | `audience` | No | `""` | OAuth2 audience for `client_credentials` flow | The action also produces one output: - **`traceId`** - the OpenTelemetry trace ID of the root span, which you can use to link directly to the trace in Scout ### Viewing Traces in Scout Once the action runs, your workflow traces appear in Scout's trace explorer - traceX. #### Finding Your Traces 1. Open **traceX** in Scout 2. Filter by the `otelServiceName` you configured (e.g., `my-repo-ci`) 3. You'll see one trace per workflow run, with the workflow name as the root span #### Reading the Trace Waterfall ![GitHub Actions trace waterfall in Scout traceX](/img/github-actions/github-actions-tracex.png) The trace waterfall shows the full execution timeline: - **Root span** - the workflow run, showing total duration and final status - **Job spans** - each job appears as a child of the root span, with its own start time and duration - **Step spans** - each step within a job is a child of the job span Parallel jobs appear side by side in the waterfall, making it easy to see which jobs ran concurrently and which ran sequentially. Failed steps are highlighted, so you can immediately spot where a pipeline broke. #### Useful Filters - **`service.name`** - filter by repository or project - **Status** - filter for failed traces to see broken builds - **Duration** - sort by duration to find your slowest pipelines ### Verification 1. Trigger a workflow run in your repository 2. Open **traceX** in Scout and filter by your `otelServiceName` 3. Confirm a new trace appears with the workflow name as the root span ### Practical Example: Finding Slow Steps A common use case is identifying which steps slow down your pipeline over time. Here's how to use traces in Scout to find bottlenecks. #### Scenario Your CI pipeline used to complete in 3 minutes but now takes 8 minutes. You want to find out which step is responsible. #### Approach 1. Open a recent trace for the workflow in Scout 2. Look at the trace waterfall - the longest spans immediately stand out 3. Compare with an older trace to see what changed #### Common Bottlenecks | Symptom | Likely cause | Fix | | --------------------------- | ------------------------------------------ | -------------------------------------------- | | Long checkout step | Large repository or LFS objects | Use `fetch-depth: 1` for shallow clone | | Slow dependency install | No caching configured | Add dependency caching (actions/cache) | | Long test suite | Tests running sequentially | Parallelize test jobs or use test sharding | | Slow Docker build | No layer caching | Use Docker build cache or registry caching | | Long deployment step | Waiting for health checks or approvals | Review timeout and health check configuration | By comparing traces across multiple runs, you can also spot regressions — a step that was 30 seconds last week but is now 2 minutes points to a specific change worth investigating. ### Troubleshooting #### Action Fails with 401 Unauthorized This typically means the Scout OAuth2 credentials are incorrect or the token request is failing. Verify your credentials by requesting a token directly: ```bash curl -X POST "$SCOUT_TOKEN_URL" \ -H "Content-Type: application/x-www-form-urlencoded" \ -d "grant_type=client_credentials&client_id=$CLIENT_ID&client_secret=$API_KEY&audience=$AUDIENCE" ``` If this returns a valid access token, your credentials are correct and the issue is likely in how the secrets are configured in your repository. If you get an error, double-check the `tokenUrl`, `appName`, `apiKey`, and `audience` values in your Scout account. #### No Traces Appearing in Scout 1. **Check the action logs** - expand the "Export workflow trace" step in the GitHub Actions UI to see any error messages 2. **Verify credentials** - ensure `SCOUT_TENANT`, `SCOUT_CLIENT_ID`, and `SCOUT_CLIENT_SECRET` are set correctly in repository secrets 3. **Check the endpoint** - confirm `otlpEndpoint` matches the Scout endpoint provided to you during onboarding 4. **Verify network access** - GitHub-hosted runners need outbound HTTPS access to both the Scout API and the identity provider #### Workflow Run Trigger Not Firing The `workflow_run` event only triggers for workflows on the default branch. If you're testing on a feature branch, use Option B (in-workflow job) instead, or merge the `otel-export.yml` file to your default branch first. #### Traces Missing Steps If some steps don't appear in the trace, they may have been skipped by conditional logic (`if:` conditions). Skipped steps are not included in the GitHub API response and won't appear as spans. ### What's Next? - [Create Your First Dashboard](../create-your-first-dashboard.md) - build dashboards to visualize CI/CD metrics over time - [Creating Alerts with LogX](../creating-alerts-with-logx.md) - set up alerts for pipeline failures or duration regressions - [Quick Start](../quick-start.md) - get Scout set up for application observability alongside your CI/CD traces --- ## CI/CD Observability - Monitor Your Pipelines with OpenTelemetry ## CI/CD Observability Monitor your CI/CD pipelines with OpenTelemetry and base14 Scout. Trace workflow execution, track deployment health, and identify bottlenecks across your delivery pipelines. ### Guides - **[GitHub Actions Observability](./github-actions-observability.md)** - Export GitHub Actions workflows as OpenTelemetry traces. Identify slow steps, track failure patterns, and gain full visibility into your CI pipelines. - **[ArgoCD Monitoring](./argocd.md)** - Collect ArgoCD Prometheus metrics with the OpenTelemetry Collector. Monitor application sync status, health, reconciliation, and Git operations. --- ## Create Your First Dashboard This guide walks you through creating your first dashboard in Scout. You'll learn how to explore available metrics, build queries correctly, and visualize your telemetry data in Grafana. ### Time to Complete 15-20 minutes ### What You'll Accomplish - Identify a metric to monitor - Build a correct query in Grafana - Save and organize your first dashboard ### Prerequisites - Access to Scout dashboard with Grafana - Telemetry data flowing from your instrumented applications - Basic understanding of your services and environments ### Step 1: Start from the Metrics Collected Dashboard Before creating a dashboard, explore the pre-built **Metrics Collected** dashboard to understand what data is available. 1. Open the **Metrics Collected** dashboard 2. Select: - **Environment** - Choose the desired environment (e.g., production, staging) - **Service Name** - Pick the service you want to monitor 3. Find the **metric you want to visualize** (from the list or search) 4. Use this dashboard to inspect: - **Last 5 values** of the metric - **Resource Attributes** and **Attributes** - Note these for filtering later > **Note**: Record the metric name and relevant attributes. You'll use these > when writing queries later. ### Step 2: Create a New Dashboard and Add a Panel 1. Go to **Dashboards → New → New Dashboard** 2. Add a **New Panel** ### Step 3: Configure Data Source and Query Settings #### Always Select DS_ScoutAltCH for Data Source Always choose **DS_ScoutAltCH** as your data source. #### Query Settings by Table Configure the query settings based on which table you're using. The key difference is the **Timestamp Column** setting. | Table | Database | Column Type | Timestamp Column | Date Column | | ------------------------ | -------------- | ----------- | ---------------- | ----------- | | `otel_metrics_sum` | `` | `DateTime64` | `TimeUnix` | Leave default | | `otel_metrics_gauge` | `` | `DateTime64` | `TimeUnix` | Leave default | | `otel_metrics_histogram` | `` | `DateTime64` | `TimeUnix` | Leave default | | `otel_metrics_summary` | `` | `DateTime64` | `TimeUnix` | Leave default | | `otel_logs` | `` | `DateTime64` | `TimestampTime` | Leave default | | `otel_traces` | `` | `DateTime64` | `Timestamp` | Leave default | > **Important**: For metrics tables, use `TimeUnix`. For logs, use > `TimestampTime`. For traces, use `Timestamp`. ### Step 4: Write Your Query Use this template for your query: ```sql SELECT ... FROM $table WHERE $timeFilter AND ServiceName = '' AND = '' AND ResourceAttributes['environment'] = '' ``` #### Required WHERE Conditions Each query **must include** the following WHERE conditions: 1. **`$timeFilter`** - Grafana's time range filter (always required) 2. **`ServiceName = 'value'`** - The service you're monitoring 3. **` = 'value'`** - Use `MetricName` for metrics/logs, `SpanName` for traces 4. **`ResourceAttributes['environment'] = 'value'`** - The environment (e.g., production, staging) #### Time Series Configuration For time series queries, make sure the **Step** field below the query is set to **`1m`** (1 minute). #### Adding More Filters You can add more filters based on `Attributes` or `ResourceAttributes` for deeper insights: ```sql AND Attributes['http.method'] = 'GET' AND ResourceAttributes['host.name'] = 'server-01' ``` ### Step 5: Example Panel Query Here's a complete example for a CPU usage metric (gauge): ```sql SELECT $timeSeries AS t, avg(Value) AS cpu_usage FROM otel_metrics_gauge WHERE $timeFilter AND ServiceName = 'backend-service' AND MetricName = 'system.cpu.usage' AND ResourceAttributes['environment'] = 'production' GROUP BY t ORDER BY t ``` ### Step 6: Save and Organize Once your panel displays data correctly: 1. Click **Apply** to save the panel 2. Click **Save dashboard** (disk icon in top right) 3. Give your dashboard a descriptive name 4. Save it in the **Drafts** folder initially 5. Review the dashboard with your team or QA 6. Move it to the appropriate folder once approved #### Recommended Folder Organization - **Drafts** - Work-in-progress dashboards - **Production** - Approved production monitoring dashboards - **Development** - Development environment dashboards - **Team-specific folders** - Organized by team or service ### Verification Use this checklist to confirm your dashboard is ready: Before finalizing your dashboard, verify: - [ ] Data Source = `DS_ScoutAltCH` - [ ] Correct table and timestamp settings - [ ] `$timeFilter` included in query - [ ] Step = `1m` for time series - [ ] Required filters: ServiceName, MetricName/SpanName, environment - [ ] Dashboard saved under correct folder ### Best Practices #### Query Performance - Always include `$timeFilter` to limit data scanning - Add ServiceName filter to reduce query scope - Use specific metric names rather than wildcards #### Dashboard Organization - Group related panels together - Use descriptive panel titles and descriptions - Keep dashboards focused on specific services or use cases ### Troubleshooting #### No Data Displayed 1. Verify the time range includes data 2. Check that ServiceName matches exactly (case-sensitive) 3. Confirm MetricName is spelled correctly 4. Verify environment filter matches your data #### Query Errors 1. Ensure `$timeFilter` is included in WHERE clause 2. Verify table name matches query settings 3. Check timestamp column is correctly configured 4. Validate SQL syntax (commas, quotes, brackets) ### Next Steps - [Creating Alerts with LogX](creating-alerts-with-logx.md) - Set up alerts based on your dashboard queries - [Quick Start](quick-start.md) - Get Scout set up and sending data ### References - [Grafana Dashboard Documentation](https://grafana.com/docs/grafana/latest/dashboards/) \- Learn about dashboard basics and panel types - [Time Series Panel](https://grafana.com/docs/grafana/latest/panels-visualizations/visualizations/time-series/) \- Understanding time series visualizations in Grafana --- ## Creating Alerts with LogX LogX provides a streamlined workflow for creating alerts based on your log queries. This guide walks you through the process of exporting an alert query from LogX and setting it up in Grafana's alerting system. ### Time to Complete 15-20 minutes ### What You'll Accomplish - Generate an alert-ready LogX query - Add the query to a Grafana panel - Create and configure a Grafana alert rule ### Prerequisites - Access to LogX and Grafana in Scout - Logs flowing into Scout for the service you want to alert on - Permissions to create dashboards and alert rules ### Overview The alert creation process involves three main steps: 1. **Explore Alert Query from LogX**: Use the "Explore Alert Query" button to generate a ClickHouse query based on your current filters and search criteria. 2. **Add Query to Dashboard**: Create or add the query to a Grafana dashboard with the correct datasource configuration. 3. **Create Alert Rule**: Configure the alert rule from the dashboard panel with thresholds and notification settings. ### Step 1: Explore Alert Query from LogX #### Generate the Query 1. Open the **LogX** application in Scout 2. Configure your log filters: - Select the service you want to monitor - Add resource attribute filters (e.g., `host.name`, `deployment.environment`) - Add log attribute filters as needed - Apply body search terms or regex patterns 3. Verify your filters are showing the logs you want to alert on 4. Click the **"Explore Alert Query"** button in the header controls #### Understanding the Generated Query The exported query is a ClickHouse SQL statement that: - Counts log entries matching your filters - Includes all active filters (resource attributes, log attributes, body search) - Returns a single numeric value (count of matching logs) Example query structure: ```sql SELECT count(*) as value FROM $table WHERE $timeFilter AND ServiceName = 'api-service' AND ResourceAttributes['environment'] = 'production' AND ResourceAttributes['host.name'] IN ('server-1', 'server-2') ``` #### Copy the Query 1. In the **Alert Query Dialog**, review the generated SQL query 2. Click the **"Copy Explore Query"** button to copy it to your clipboard 3. Close the dialog ### Step 2: Add Query to a Dashboard #### Create or Open a Dashboard 1. Navigate to **Dashboards** 2. Either: - Create a new dashboard by clicking **"New Dashboard"** - Open an existing dashboard where you want to add the alert #### Add a New Panel 1. Click **"Add"** → **"Visualization"** to add a new panel 2. Configure the panel settings: #### Configure the Datasource In the query editor: 1. **Datasource**: Select `DS_ScoutAltCH` (Scout Altinity ClickHouse datasource) 2. Click on the **Query Options** or **Settings** (gear icon) 3. Configure the following settings: - **Database**: Enter your organization name (e.g., `acme-corp`) - **Table**: Enter `otel_logs` - **Timestamp Type**: Select `DateTime64` - **Timestamp Column**: Enter `Timestamp` #### Add Your Query 1. Switch to **SQL Editor** mode (toggle button or "Edit SQL" option) 2. Paste the alert query you copied from LogX #### Configure the Visualization 1. Set panel title (e.g., "Production API Errors") 2. Configure value options, thresholds, and colors as needed 3. Click **"Apply"** to save the panel #### Save the Dashboard 1. Click **"Save dashboard"** (disk icon) 2. Give your dashboard a meaningful name 3. Optionally add it to a folder 4. Click **"Save"** ### Step 3: Create Alert Rule Now that you have a dashboard panel with your log query, you're ready to create the alert rule. 1. On your dashboard, locate the panel you just created 2. Click the **panel title** or **three dots (⋮)** menu 3. Select **"More..."** → **"New alert rule"** That's it! Now you can follow the comprehensive [Creating Alerts in Grafana](https://grafana.com/docs/grafana/latest/alerting/alerting-rules/create-grafana-managed-rule/) guide to configure your alert rule, set thresholds, configure notifications, and test your alert. The general alerting guide covers: - Setting alert rule names and descriptions - Defining query conditions and thresholds - Configuring evaluation behavior and timing - Adding alert details and templates - Setting up notifications and contact points - Testing and troubleshooting alerts - Best practices for alerting ### Verification 1. Use **Preview alerts** to confirm the rule evaluates successfully 2. Set a short evaluation interval temporarily to validate behavior 3. Trigger a known log condition and verify the alert transitions to Firing ### Best Practices #### Query Optimization 1. **Use Specific Filters**: Narrow down logs to reduce query load - Filter by service name - Use environment filters - Apply relevant attribute filters 2. **Avoid Wildcards**: Be specific in your search patterns - Good: `ServiceName = 'api-service'` - Avoid: `ServiceName LIKE '%api%'` ### Troubleshooting If the alert doesn't fire as expected: 1. Confirm the panel query returns a non-zero value in the time range 2. Verify the table is `otel_logs` and the timestamp column is `Timestamp` 3. Ensure the rule uses the same datasource and query as the panel 4. Check that the evaluation interval matches your log volume ### Next Steps - [Dashboards and Alerts](../operate/dashboards-and-alerts.md) - General dashboard and alerting overview - [Grafana Alerting Documentation](https://grafana.com/docs/grafana/latest/alerting/) \- Official Grafana alerting guide --- ## Creating Alerts with pgX pgX provides a streamlined workflow for creating alerts based on the panels in the app. This guide walks you through exporting an alert query from a pgX panel and setting it up in Grafana's alerting system. :::note Running this in production pgX is the PostgreSQL monitoring app in base14 Scout. [Check out base14 pgX](https://base14.io/scout/pgx). ::: ### Time to Complete 15-20 minutes ### What You'll Accomplish - Generate an alert-ready pgX query from any time-series or stat panel - Add the query to a Grafana panel - Create and configure a Grafana alert rule ### Prerequisites - Access to pgX and Grafana in Scout - pgX configured and showing data for the database you want to alert on - Permissions to create dashboards and alert rules ### Overview The alert creation process involves three main steps: 1. **Show Alert Query from pgX**: Use the panel's **Show alert query** menu item to generate a ClickHouse query based on the panel's current filters and metric. 2. **Add Query to Dashboard**: Create or add the query to a Grafana dashboard with the correct datasource configuration. 3. **Create Alert Rule**: Configure the alert rule from the dashboard panel with thresholds and notification settings. ### Step 1: Show Alert Query from pgX #### Generate the Query 1. Open the **pgX** application in Scout 2. Configure your panel filters at the top of the page: - Select the **Environment** and **Cluster** you want to monitor - On the Queries tab, optionally narrow by Database, User, or Query Type 3. Pick the panel you want to alert on. The **Show alert query** option is available on time-series and stat panels (the three-dot menu in the top-right corner of each panel) 4. Click the panel's three-dot menu, then click **Show alert query** #### Understanding the Generated Query The exported query is a ClickHouse SQL statement that: - Reads the same metric the panel reads - Carries over the panel's environment, cluster, database, user, and query-type filters as literal values - Uses Vertamedia macros for the time range, table, and bucket alignment so the alert engine can re-evaluate it against any time window Example query structure: ```sql SELECT $timeSeries as t, anyLast(Value) FROM $table WHERE $timeFilter AND MetricName = 'pg_up' AND ServiceName in ('pgdashex') AND Attributes['cluster'] = 'prod-db' GROUP BY t ORDER BY t ``` The macros are expanded by the ClickHouse datasource at evaluation time: | Macro | Expands to | |-------|------------| | `$timeFilter` | `TimeUnix >= toDateTime64(...) AND TimeUnix <= toDateTime64(...)` | | `$table` | The configured database and table (e.g. `acme-corp.otel_metrics_gauge`) | | `$timeSeries` | A bucketed millisecond timestamp aligned to the evaluation interval | #### Copy the Query 1. In the **Alert Query** dialog, review the generated SQL query 2. Click the **"Copy Query"** button to copy it to your clipboard 3. Close the dialog ### Step 2: Add Query to a Dashboard #### Create or Open a Dashboard 1. Navigate to **Dashboards** 2. Either: - Create a new dashboard by clicking **"New Dashboard"** - Open an existing dashboard where you want to add the alert #### Add a New Panel 1. Click **"Add"** → **"Visualization"** to add a new panel 2. Configure the panel settings: #### Configure the Datasource In the query editor: 1. **Datasource**: Select `DS_ScoutAltCH` (Scout Altinity ClickHouse datasource) 2. Click on the **Query Options** or **Settings** (gear icon) 3. Configure the following settings: - **Database**: Enter your organization name (e.g., `acme-corp`) - **Table**: Enter `otel_metrics_gauge` - **Timestamp Type**: Select `DateTime64` - **Timestamp Column**: Enter `TimeUnix` #### Add Your Query 1. Switch to **SQL Editor** mode (toggle button or "Edit SQL" option) 2. Paste the alert query you copied from pgX #### Configure the Visualization 1. Set panel title (e.g., "PostgreSQL Up") 2. Configure value options, thresholds, and colors as needed 3. Click **"Apply"** to save the panel #### Save the Dashboard 1. Click **"Save dashboard"** (disk icon) 2. Give your dashboard a meaningful name 3. Optionally add it to a folder 4. Click **"Save"** ### Step 3: Create Alert Rule Now that you have a dashboard panel with your pgX query, you're ready to create the alert rule. 1. On your dashboard, locate the panel you just created 2. Click the **panel title** or **three dots (⋮)** menu 3. Select **"More..."** → **"New alert rule"** That's it! Now you can follow the comprehensive [Creating Alerts in Grafana](https://grafana.com/docs/grafana/latest/alerting/alerting-rules/create-grafana-managed-rule/) guide to configure your alert rule, set thresholds, configure notifications, and test your alert. The general alerting guide covers: - Setting alert rule names and descriptions - Defining query conditions and thresholds - Configuring evaluation behavior and timing - Adding alert details and templates - Setting up notifications and contact points - Testing and troubleshooting alerts - Best practices for alerting ### Verification 1. Use **Preview alerts** to confirm the rule evaluates successfully 2. Set a short evaluation interval temporarily to validate behavior 3. Trigger a known database condition and verify the alert transitions to Firing (e.g., stop the monitored database to test a `pg_up` alert) ### Best Practices #### Query Scoping 1. **Pick a specific cluster**: Always set the cluster filter in pgX before exporting — alerts on the implicit "all clusters" set are usually noisy 2. **Pick a specific database/user/query** when alerting on per-query metrics (Queries tab drawer) so the alert tracks one concrete thing ### Troubleshooting If the alert doesn't fire as expected: 1. Confirm the panel query returns a non-zero value in the chosen time range 2. Verify the table is `otel_metrics_gauge` and the timestamp column is `TimeUnix` with type `DateTime64` 3. Ensure the rule uses the same datasource and query as the panel 4. Use an evaluation interval of at least 5 minutes — narrower windows can give zero data points ### Next Steps - [Dashboards and Alerts](../operate/dashboards-and-alerts.md) - General dashboard and alerting overview - [Grafana Alerting Documentation](https://grafana.com/docs/grafana/latest/alerting/) \- Official Grafana alerting guide --- ## Flutter Mobile Observability Mobile apps face observability challenges that backend services do not: devices run on battery, connectivity is unreliable, and the OS can kill your app at any time. OpenTelemetry gives you traces, metrics, and error data from your Flutter app exported to any OTLP-compatible collector. This guide walks you through adding the `scout_flutter` SDK, initializing it in your app, and verifying that spans reach your collector. :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### Time to Complete 15-20 minutes ### What You'll Accomplish - Add the `scout_flutter` SDK to your Flutter project - Initialize zero-config RUM in your app entry point - Verify spans are flowing to your collector ### Prerequisites - **Flutter SDK 3.7.0+** and **Dart SDK 3.7.0+** installed - A running **OpenTelemetry Collector** with an OTLP endpoint (see [Docker Compose Setup](../instrument/collector-setup/docker-compose-example.md) for local development) - An existing Flutter app to instrument ### Telemetry Architecture Before instrumenting your app, decide how telemetry gets from the device to Scout. There are two deployment models. #### Recommended: OTel Collector with API Gateway ![Flutter RUM Architecture](/img/docs/flutter-rum-architecture.png) Devices send OTLP data to a load balancer or API gateway, which handles authentication and rate limiting. The gateway forwards traffic to an OTel collector that applies server-side sampling before exporting to Scout. #### Alternative: Direct to Scout Devices send OTLP data directly to the Scout ingestion endpoint, authenticating with OAuth tokens that the app manages. #### Comparison | | Collector + API Gateway | Direct to Scout | | :--- | :--- | :--- | | **Authentication** | API gateway handles auth centrally - app only needs an API key or static token | App must manage OAuth token lifecycle (acquire, refresh, retry on 401) | | **Credential security** | Credentials stay on your infra - app ships a lightweight key that the gateway validates | OAuth client secret must be embedded or fetched at runtime - risk of extraction from APK/IPA | | **Rate limiting** | API gateway enforces per-device or per-app rate limits - protects backend from traffic spikes | No rate limiting - a buggy release can flood Scout with telemetry | | **Server-side sampling** | OTel collector applies tail sampling (e.g. keep all errors, sample 10% of healthy spans) - reduces cost without losing signal | All sampling must happen on-device - you lose the ability to make sampling decisions with full context | | **Buffering and retry** | Collector buffers and retries on export failure - device fire-and-forget | App must handle retry logic and local buffering if Scout is unreachable | | **Schema evolution** | Collector processors can rename attributes, drop PII, or add resource attributes without app updates | Any schema change requires an app release and user update | | **Network efficiency** | Gateway can terminate TLS at the edge, compress, and batch - lower overhead per device | Each device opens its own TLS connection to Scout - more overhead at scale | | **Operational cost** | Requires running a collector and gateway (but these are standard infra components) | No additional infra to manage | | **Deployment complexity** | Moderate - collector + gateway config | Low - just configure the Scout endpoint in the app | | **Best for** | Production apps with multiple devices, teams that want control over sampling and PII | Prototypes, internal tools, or apps with a small user base | :::tip Recommendation Use the **Collector + API Gateway** approach for production apps. The ability to rate limit, sample server-side, strip PII, and rotate credentials without app updates far outweighs the small infra cost. Reserve **Direct to Scout** for prototypes or internal tools where simplicity matters more than control. ::: ### Step 1: Add the SDK The `scout_flutter` SDK is a single package with one `initialize()` call — it auto-captures the full RUM set (taps, navigation, errors, native crashes, ANR, HTTP, frame metrics, logs) and exports OTLP, with no pipeline to hand-build. It is published on [pub.dev](https://pub.dev/packages/scout_flutter). Add it to your `pubspec.yaml`: ```yaml title="pubspec.yaml" dependencies: scout_flutter: ^0.2.0 ``` Then install: ```bash flutter pub get ``` ### Step 2: Initialize Telemetry Initialize the SDK before `runApp()` in `lib/main.dart`: ```dart title="lib/main.dart" import 'dart:async'; import 'package:flutter/material.dart'; import 'package:scout_flutter/scout_flutter.dart'; Future main() async { WidgetsFlutterBinding.ensureInitialized(); // Fire-and-forget — never block app startup on SDK init. unawaited(ScoutFlutter.initialize( config: ScoutFlutterConfig( serviceName: 'my-app', endpoint: 'https://otel.example.com', headers: const {'Authorization': 'Bearer '}, ), )); runApp(ScoutFlutter.observeScroll(child: const MyApp())); } ``` Attach `ScoutFlutter.navigatorObserver` to every `Navigator` for screen tracking. See the [SDK reference](../instrument/mobile/flutter.md) for the full configuration surface. Then run: ```bash flutter run ``` ### Step 3: Verify Telemetry Once the app is running, confirm spans are reaching your collector. 1. **Check collector logs** - look for incoming OTLP requests: ```bash docker logs otel-collector 2>&1 | grep -i "traces" ``` 2. **Look for expected span names**: - `screen_view`, `user_interaction`, `http.request`, `app_startup`, `error`, `native_crash`, `anr` 3. **Open Scout** - navigate to the Traces view and filter by `service.name = your-app-name`. You should see spans arriving within 30 seconds of app activity. > **Troubleshooting**: If no spans appear, check that the > `OTEL_TRACE_ENDPOINT` environment variable or hardcoded endpoint matches your > collector's OTLP receiver address. See > [Troubleshooting Missing Telemetry Data](./troubleshooting-missing-data.md) > for common issues. ### Next Steps - [Scout Flutter SDK reference](../instrument/mobile/flutter.md) - full configuration and capability reference - [Create Your First Dashboard](./create-your-first-dashboard.md) - build dashboards from your mobile telemetry data - [Creating Alerts with LogX](./creating-alerts-with-logx.md) - set up alerts on crash rates, ANR counts, or slow screen loads - [Troubleshooting Missing Telemetry Data](./troubleshooting-missing-data.md) - diagnose issues when spans are not arriving --- ## 5-Minute Quick Start Get Scout up and running in less than 5 minutes. This guide will help you deploy an OpenTelemetry collector, configure it to send data to Scout, and start collecting telemetry from your applications and infrastructure. ### Time to Complete 5-10 minutes ### What You'll Accomplish - Deploy an OpenTelemetry collector in your environment - Configure the Scout exporter to send data to the Scout backend - Start collecting telemetry data from your applications and components - Verify data is flowing to Scout ### Prerequisites - Access to your Scout account and API credentials - Docker, Kubernetes, or Linux environment for collector deployment - Basic familiarity with YAML configuration files ### Step 1: Deploy the OpenTelemetry Collector Deploy the OpenTelemetry collector in your environment based on your infrastructure. Choose from Docker, Kubernetes, Linux, or AWS ECS options. #### Docker Compose Perfect for local development and testing environments. Download the configuration and deploy using Docker Compose. See the [Docker Compose Setup Guide](../instrument/collector-setup/docker-compose-example.md) for detailed instructions. #### Kubernetes Ideal for production deployments on EKS, GKE, or AKS. Install using Helm charts for simplified deployment and management. See the [Kubernetes Helm Setup Guide](../instrument/collector-setup/kubernetes-helm-setup.md) for detailed instructions. #### Linux For direct installation on Linux servers or virtual machines. Download and install the collector binary with automated setup scripts. See the [Linux Setup Guide](../instrument/collector-setup/linux-setup.md) for detailed instructions. #### AWS ECS For containerized applications running on Amazon ECS. Deploy as a sidecar or daemon on Fargate and EC2 launch types. See the [ECS Setup Guide](../instrument/collector-setup/ecs-setup.md) for detailed instructions on Fargate and EC2 deployments. ### Step 2: Configure the OpenTelemetry Collector Once your collector is deployed, configure it to receive telemetry and send data to Scout. Here's a complete configuration example: ```yaml showLineNumbers # Extensions provide additional capabilities to the collector extensions: oauth2client: client_id: __YOUR_CLIENT_ID__ client_secret: __YOUR_CLIENT_SECRET__ endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token tls: insecure_skip_verify: true # Receivers define how telemetry data enters the collector receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 # Processors modify or enrich telemetry data processors: resource: attributes: - key: deployment.environment value: production action: upsert - key: environment value: production action: upsert - key: service.namespace value: my-namespace action: upsert # Exporters define where telemetry data is sent exporters: otlp/scout: endpoint: https://api.scout.base14.io:4317 auth: authenticator: oauth2client tls: insecure_skip_verify: true # Service section ties everything together service: extensions: [oauth2client] pipelines: traces: receivers: [otlp] processors: [resource] exporters: [otlp/scout] metrics: receivers: [otlp] processors: [resource] exporters: [otlp/scout] logs: receivers: [otlp] processors: [resource] exporters: [otlp/scout] ``` #### Configuration Breakdown - **OAuth Extension**: Handles authentication with Scout using OAuth2 client credentials flow - **OTLP Receiver**: Accepts telemetry data on ports 4317 (gRPC) and 4318 (HTTP) - **Resource Processor**: Adds environment metadata to all telemetry signals - **Scout Exporter**: Sends data to Scout backend using authenticated OTLP #### Quick Setup Steps 1. Get your OAuth credentials (client ID and secret) from the Scout dashboard 2. Update the configuration with your credentials 3. Save the configuration to `otel-collector-config.yaml` 4. Restart the collector to apply changes See the [Scout Exporter Configuration Guide](../instrument/collector-setup/scout-exporter.md) for complete details and authentication options. ### Step 3: Start Collecting Data Now that your collector is running, start sending telemetry data: #### From Applications Instrument your applications to send traces, metrics, and logs: - **Auto-instrumentation**: Get started quickly with zero-code instrumentation for popular frameworks. See [Auto-instrumentation Guides](/instrument/apps/auto-instrumentation/) - **Custom instrumentation**: Add application-specific telemetry. See [Custom Instrumentation Guides](/instrument/apps/custom-instrumentation/) #### From Components Collect metrics and logs from your infrastructure components: - **Databases**: [PostgreSQL](../instrument/component/postgres.md), [MongoDB](../instrument/component/mongodb.md), [Redis](../instrument/component/redis.md) - **Message Queues**: [RabbitMQ](../instrument/component/rabbitmq.md) - **Web Servers**: [nginx](../instrument/component/nginx.md) #### From AWS Infrastructure Monitor your AWS resources automatically: - [Application Load Balancer](../instrument/infra/aws/elb.md) - [RDS Databases](../instrument/infra/aws/rds.md) - [ElastiCache](../instrument/infra/aws/elasticache.md) - [VPC Flow Logs](../instrument/infra/aws/aws-vpc.md) ### Verification 1. Log in to your Scout dashboard 2. Navigate to the **Traces**, **Metrics**, or **Logs** section 3. Verify that data is appearing from your collector 4. Explore the service map to see your application topology ### What's Next? Now that you have Scout running, explore these topics: - **Send your first trace**: Run a [Hello World app](/instrument/apps/hello-world) in any of 9 languages to see traces, logs, and metrics flowing through your collector - **Fine-tune your collector**: Review the [OTel Collector Configuration Guide](../instrument/collector-setup/otel-collector-config.md) to optimize your collector setup - **Create dashboards**: Build custom visualizations for your metrics - **Set up alerts**: Configure alerts to get notified about issues. See [Creating Alerts with LogX](creating-alerts-with-logx.md) - **Transform data**: Apply filters and transformations to your telemetry. See [Filters and Transformations](/category/filters-and-transformations) ### Troubleshooting If you're not seeing data in Scout: 1. **Check collector logs**: Verify the collector is running without errors 2. **Verify connectivity**: Ensure your collector can reach the Scout backend 3. **Check credentials**: Confirm your API token is valid and properly configured 4. **Review configuration**: Validate your YAML configuration syntax ### Related Guides - [Introduction](../introduction.md) - Complete overview of Scout's capabilities - [Docker Compose Setup](../instrument/collector-setup/docker-compose-example.md) \- Detailed Docker setup - [OTel Collector Configuration](../instrument/collector-setup/otel-collector-config.md) \- Advanced collector configuration - [Scout Exporter](../instrument/collector-setup/scout-exporter.md) - Exporter configuration details - [Dashboards and Alerts](../operate/dashboards-and-alerts.md) - Create visualizations and alerts --- ## Troubleshooting Missing Telemetry Data This guide provides a systematic approach to debug telemetry pipeline issues by starting with Grafana dashboards, then moving to the OpenTelemetry Collector, and finally to your application. ### Step 1: Check OTel Collector Data Flow Dashboard Start by checking the **OTel Collector Data Flow** dashboard in Grafana. #### If No Data in Dashboard There's an issue in the pipeline. Check the collector logs. ##### Viewing Collector Logs **Docker:** ```bash docker logs otel-collector --tail=100 ``` **Kubernetes:** ```bash kubectl logs -n --tail=100 ``` **Linux Service:** ```bash sudo journalctl -u otel-collector -n 100 ``` ##### What to Look For in Logs **Successful startup:** ```text Everything is ready. Begin running and processing data. ``` **Configuration errors:** ```text error decoding config invalid configuration ``` **Authentication errors:** ```text rpc error: code = Unauthenticated 401 Unauthorized ``` **Connection errors:** ```text connection refused failed to connect ``` **If logs show errors:** Validate your collector configuration using: ```bash otelcol validate --config=/path/to/otel-collector-config.yaml ``` Or use [otelbin.io](https://www.otelbin.io/). **If no errors in logs and application is not throwing errors:** Verify the receiver is configured in the pipeline: ```yaml service: pipelines: metrics: receivers: [otlp] # Ensure your receiver is listed exporters: [otlp] ``` #### If Data Appears in Dashboard Proceed to Step 2. ### Step 2: Check Metrics Collected Dashboard Go to the **Metrics Collected** dashboard and select your environment. #### If You See Your Service and Data Your telemetry is flowing correctly. Use the correct filters and dashboard options to view your data. #### If No Data for Your Service Check your application logs to verify it's successfully exporting telemetry. **Look for:** - OpenTelemetry SDK initialization messages - Successful telemetry export confirmations - Any SDK errors or warnings **If application shows no errors:** Verify the receiver is used in the collector pipeline (see Step 1). ### Related Guides - [Collector Configuration](../instrument/collector-setup/otel-collector-config.md) Detailed collector configuration guide - [Auto Instrumentation](../instrument/apps/auto-instrumentation/express.md) Automatic application instrumentation - [Custom Instrumentation](../instrument/apps/custom-instrumentation/python.md) Manual application instrumentation --- ## Actix Web OpenTelemetry Instrumentation - Complete APM Setup Guide ## Actix Web Implement OpenTelemetry instrumentation for Rust Actix Web applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to instrument your Actix Web application to collect traces, metrics, and logs from HTTP requests, database queries, background jobs, and custom business logic using the OpenTelemetry Rust SDK. Actix Web is a mature, high-performance Rust web framework, alongside the Tokio-based [Axum](./axum.md). Rust applications built with Actix Web benefit from the powerful `tracing` ecosystem combined with OpenTelemetry exporters. With the `tracing-actix-web` crate, you can automatically capture spans from every HTTP request, monitor SQLx database queries, trace distributed transactions across microservices, and identify performance bottlenecks with minimal runtime overhead. Actix Web's actor-based architecture and `tracing-actix-web` middleware provide seamless integration with OpenTelemetry's context propagation. Whether you're implementing observability for the first time, migrating from other monitoring solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Rust Actix Web OpenTelemetry instrumentation. :::tip TL;DR Add `tracing-actix-web` middleware with `tracing-opentelemetry` to export spans via OTLP. SQLx queries and HTTP requests are traced automatically. Use `BatchSpanProcessor` for production and export to base14 Scout via the OpenTelemetry Collector. ::: > **Note:** This guide provides a practical Actix Web-focused overview based > on the official OpenTelemetry documentation. For complete Rust language > information, please consult the > [official OpenTelemetry Rust documentation](https://opentelemetry.io/docs/languages/rust/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Rust developers:** implementing observability and distributed tracing for Actix Web applications - **DevOps engineers:** deploying Rust applications with production monitoring requirements - **Engineering teams:** migrating from other APM solutions to OpenTelemetry - **Developers:** debugging performance issues, slow database queries, or async runtime problems - **Platform teams:** standardizing observability across multiple Rust services ### Overview This comprehensive guide demonstrates how to: - Install and configure OpenTelemetry SDK for Actix Web applications - Set up tracing with `tracing-actix-web` for automatic HTTP span collection - Configure OTLP export for traces, metrics, and logs to Scout Collector - Implement custom instrumentation for business-critical operations - Monitor SQLx database queries and connection pools - Instrument a PostgreSQL-backed job queue with W3C trace propagation - Deploy instrumented Actix Web applications to production - Troubleshoot common instrumentation issues and optimize performance - Include trace IDs in API error responses ### Prerequisites Before starting, ensure you have: - **Rust 1.92 or later** (stable toolchain recommended) - Edition 2024 required - **Actix Web 4.12 or later** web framework - **Cargo** for dependency management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Production deployments should use a dedicated Scout Collector instance - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | --------------------- | --------------- | ------------------- | | Rust | 1.80.0 | 1.92.0+ | | Actix Web | 4.0.0 | 4.12+ | | tracing-actix-web | 0.7.0 | 0.7+ | | OpenTelemetry | 0.27.0 | 0.32+ | | tracing-opentelemetry | 0.28.0 | 0.33+ | | SQLx | 0.7.0 | 0.8.6+ | ### Required Packages Add the following dependencies to your `Cargo.toml`: ```toml showLineNumbers title="Cargo.toml" [package] name = "actix-postgres" version = "1.0.0" edition = "2024" rust-version = "1.92" [[bin]] name = "api" path = "src/main.rs" [[bin]] name = "worker" path = "src/bin/worker.rs" [dependencies] # Web Framework actix-web = "4.12" actix-rt = "2" tracing-actix-web = "0.7" # Async Runtime tokio = { version = "1.49.0", features = ["full", "tracing"] } # Database sqlx = { version = "0.8.6", features = [ "runtime-tokio", "tls-rustls", "postgres", "macros", "migrate", "uuid", "time", "json", ] } # OpenTelemetry opentelemetry = "0.32" opentelemetry_sdk = { version = "0.32", features = ["rt-tokio", "logs"] } opentelemetry-otlp = { version = "0.32", features = ["grpc-tonic", "trace", "logs"] } opentelemetry-appender-tracing = "0.32" # Tracing tracing = "0.1.44" tracing-subscriber = { version = "0.3", features = ["env-filter", "json"] } tracing-opentelemetry = "0.33" # Authentication jsonwebtoken = { version = "10.3.0", features = ["rust_crypto"] } argon2 = "0.5.3" # Serialization serde = { version = "1.0.228", features = ["derive"] } serde_json = "1.0" # Utilities uuid = { version = "1.19.0", features = ["v4", "serde"] } time = { version = "0.3.47", features = ["serde", "formatting", "macros"] } thiserror = "2.0.17" anyhow = "1.0.100" dotenvy = "0.15" ``` ### Configuration OpenTelemetry Rust instrumentation can be configured using multiple approaches depending on your deployment requirements and preferences. Choose the method that best fits your application architecture. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The recommended approach is to create a dedicated telemetry module. This provides the most flexibility and keeps configuration separate from your application bootstrap. ```rust showLineNumbers title="src/telemetry/init.rs" use opentelemetry::KeyValue; use opentelemetry::global; use opentelemetry_appender_tracing::layer::OpenTelemetryTracingBridge; use opentelemetry_otlp::WithExportConfig; use opentelemetry_sdk::{Resource, logs::SdkLoggerProvider, trace::SdkTracerProvider}; use std::time::Duration; use tracing_opentelemetry::OpenTelemetryLayer; use tracing_subscriber::{EnvFilter, Layer, layer::SubscriberExt, util::SubscriberInitExt}; use crate::config::Config; pub struct TelemetryGuard { pub tracer_provider: SdkTracerProvider, pub logger_provider: SdkLoggerProvider, } impl TelemetryGuard { pub fn shutdown(&self) { if let Err(e) = self.tracer_provider.shutdown() { eprintln!("Error shutting down tracer provider: {e}"); } if let Err(e) = self.logger_provider.shutdown() { eprintln!("Error shutting down logger provider: {e}"); } } } pub fn init_telemetry(config: &Config) -> anyhow::Result { let resource = Resource::builder() .with_service_name(config.otel_service_name.clone()) .with_attribute(KeyValue::new("service.version", "1.0.0")) .with_attribute(KeyValue::new("service.namespace", "examples")) .with_attribute(KeyValue::new( "deployment.environment", config.environment.clone(), )) .with_attribute(KeyValue::new( "environment", config.environment.clone(), )) .build(); let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .with_resource(resource.clone()) .build(); global::set_tracer_provider(tracer_provider.clone()); let log_exporter = opentelemetry_otlp::LogExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let logger_provider = SdkLoggerProvider::builder() .with_batch_exporter(log_exporter) .with_resource(resource) .build(); let otel_log_layer = OpenTelemetryTracingBridge::new(&logger_provider); let tracer = global::tracer(config.otel_service_name.clone()); let telemetry_layer = OpenTelemetryLayer::new(tracer); let env_filter = EnvFilter::try_from_default_env().unwrap_or_else(|_| EnvFilter::new("info,sqlx=warn")); let fmt_layer = if config.is_production() { tracing_subscriber::fmt::layer().json().boxed() } else { tracing_subscriber::fmt::layer().pretty().boxed() }; tracing_subscriber::registry() .with(env_filter) .with(telemetry_layer) .with(otel_log_layer) .with(fmt_layer) .init(); tracing::info!( service = %config.otel_service_name, endpoint = %config.otel_exporter_endpoint, "Telemetry initialized with OTLP trace and log export" ); Ok(TelemetryGuard { tracer_provider, logger_provider, }) } ``` ```mdx-code-block ``` For containerized deployments or environments where configuration is managed externally, you can rely on environment variables: ```rust showLineNumbers title="src/telemetry/init.rs" use std::env; pub fn init_telemetry_from_env() -> anyhow::Result { let config = Config::from_env(); init_telemetry(&config) } ``` With this configuration, use environment variables to control behavior: ```bash showLineNumbers export OTEL_SERVICE_NAME=actix-postgres export OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 export RUST_LOG=info,sqlx=warn ``` ```mdx-code-block ``` For applications using a configuration struct pattern: ```rust showLineNumbers title="src/config.rs" use std::env; #[derive(Debug, Clone)] pub struct Config { pub port: u16, pub environment: String, pub database_url: String, pub jwt_secret: String, pub jwt_expires_in_hours: i64, pub otel_service_name: String, pub otel_exporter_endpoint: String, } impl Config { pub fn from_env() -> Self { dotenvy::dotenv().ok(); Self { port: env::var("PORT") .unwrap_or_else(|_| "8080".to_string()) .parse() .expect("PORT must be a number"), environment: env::var("ENVIRONMENT") .unwrap_or_else(|_| "development".to_string()), database_url: env::var("DATABASE_URL") .expect("DATABASE_URL must be set"), jwt_secret: env::var("JWT_SECRET") .expect("JWT_SECRET must be set"), jwt_expires_in_hours: env::var("JWT_EXPIRES_IN_HOURS") .unwrap_or_else(|_| "168".to_string()) .parse() .expect("JWT_EXPIRES_IN_HOURS must be a number"), otel_service_name: env::var("OTEL_SERVICE_NAME") .unwrap_or_else(|_| "actix-postgres".to_string()), otel_exporter_endpoint: env::var("OTEL_EXPORTER_OTLP_ENDPOINT") .unwrap_or_else(|_| "http://localhost:4317".to_string()), } } pub fn is_production(&self) -> bool { self.environment == "production" } } ``` ```mdx-code-block ``` #### Configuring TracingLogger Middleware Actix Web uses the `tracing-actix-web` crate for automatic HTTP request instrumentation. Unlike Axum's Tower-based `TraceLayer`, Actix Web uses `TracingLogger` as native middleware: ```rust showLineNumbers title="src/main.rs" use actix_web::{App, HttpServer, web}; use tracing_actix_web::TracingLogger; use config::Config; use database::create_pool; use jobs::JobQueue; use repository::{ArticleRepository, FavoriteRepository, UserRepository}; use services::{ArticleService, AuthService}; use telemetry::init_telemetry; #[actix_web::main] async fn main() -> anyhow::Result<()> { let config = Config::from_env(); let telemetry_guard = init_telemetry(&config)?; tracing::info!( port = config.port, environment = %config.environment, "Starting server" ); let pool = create_pool(&config).await?; let user_repo = UserRepository::new(pool.clone()); let article_repo = ArticleRepository::new(pool.clone()); let favorite_repo = FavoriteRepository::new(pool.clone()); let job_queue = JobQueue::new(pool.clone()); let auth_service = AuthService::new(user_repo, &config); let article_service = ArticleService::new(article_repo, favorite_repo, job_queue); let pool_data = web::Data::new(pool); let auth_data = web::Data::new(auth_service); let article_data = web::Data::new(article_service); let bind_addr = format!("0.0.0.0:{}", config.port); tracing::info!(addr = %bind_addr, "Server listening"); HttpServer::new(move || { App::new() .wrap(TracingLogger::default()) .wrap(actix_web::middleware::Compress::default()) .app_data(pool_data.clone()) .app_data(auth_data.clone()) .app_data(article_data.clone()) .configure(routes::configure) }) .bind(&bind_addr)? .run() .await?; tracing::info!("Server shutdown complete"); telemetry_guard.shutdown(); Ok(()) } ``` `TracingLogger::default()` creates a span for every HTTP request with method, path, status code, and duration - no custom `MakeSpan` or `OnResponse` implementations needed. #### Shared State with `web::Data` Actix Web uses `web::Data` (backed by `Arc`) for shared application state, unlike Axum's `State` extractor: ```rust showLineNumbers title="src/main.rs" let pool_data = web::Data::new(pool); let auth_data = web::Data::new(auth_service); let article_data = web::Data::new(article_service); HttpServer::new(move || { App::new() .app_data(pool_data.clone()) .app_data(auth_data.clone()) .app_data(article_data.clone()) .configure(routes::configure) }) ``` #### Scout Collector Integration When using Scout Collector, configure your Actix Web application to send telemetry data to the Scout Collector endpoint: ```rust showLineNumbers title="src/telemetry/init.rs" let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; ``` > **Scout Dashboard Integration**: After configuration, your traces will appear > in the Scout Dashboard. Navigate to the Traces section to view request flows, > identify performance bottlenecks, and analyze distributed transactions across > your Rust services. ### Production Configuration #### Docker Production Configuration For containerized Actix Web applications: ```dockerfile showLineNumbers title="Dockerfile" # Build stage FROM rust:1.92-alpine AS builder WORKDIR /app RUN apk add --no-cache musl-dev openssl-dev pkgconfig COPY Cargo.toml Cargo.lock ./ RUN mkdir src && \ echo "fn main() {}" > src/main.rs && \ mkdir -p src/bin && \ echo "fn main() {}" > src/bin/worker.rs && \ echo "" > src/lib.rs RUN cargo build --release 2>/dev/null || true RUN rm -rf src COPY src ./src COPY migrations ./migrations RUN touch src/main.rs src/lib.rs && \ cargo build --release --bin api # Runtime stage FROM alpine:3.21 WORKDIR /app RUN apk add --no-cache ca-certificates tzdata wget && \ adduser -D -g '' -u 1001 appuser COPY --from=builder /app/target/release/api . COPY --from=builder /app/migrations ./migrations USER appuser EXPOSE 8080 HEALTHCHECK --interval=30s --timeout=5s --start-period=5s --retries=3 \ CMD wget -q --spider http://localhost:8080/api/health || exit 1 CMD ["./api"] ``` Actix Web applications with background workers require a separate Dockerfile for the worker binary: ```dockerfile showLineNumbers title="Dockerfile.worker" FROM rust:1.92-alpine AS builder WORKDIR /app RUN apk add --no-cache musl-dev openssl-dev pkgconfig COPY Cargo.toml Cargo.lock ./ RUN mkdir src && echo "fn main() {}" > src/main.rs && \ mkdir -p src/bin && echo "fn main() {}" > src/bin/worker.rs && \ echo "" > src/lib.rs RUN cargo build --release 2>/dev/null || true RUN rm -rf src COPY src ./src COPY migrations ./migrations RUN touch src/main.rs src/lib.rs src/bin/worker.rs && \ cargo build --release --bin worker FROM alpine:3.21 WORKDIR /app RUN apk add --no-cache ca-certificates tzdata && \ adduser -D -g '' -u 1001 appuser COPY --from=builder /app/target/release/worker . COPY --from=builder /app/migrations ./migrations USER appuser CMD ["./worker"] ``` #### Docker Compose Configuration ```yaml showLineNumbers title="compose.yml" services: api: build: context: . dockerfile: Dockerfile ports: - "8080:8080" environment: PORT: "8080" ENVIRONMENT: development DATABASE_URL: postgres://postgres:postgres@postgres:5432/actix_postgres_app?sslmode=disable JWT_SECRET: your-super-secret-jwt-key-change-in-production OTEL_SERVICE_NAME: actix-postgres-api OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 RUST_LOG: info,sqlx=warn depends_on: postgres: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "wget", "-q", "--spider", "http://localhost:8080/api/health"] interval: 10s timeout: 5s retries: 5 worker: build: context: . dockerfile: Dockerfile.worker environment: ENVIRONMENT: development DATABASE_URL: postgres://postgres:postgres@postgres:5432/actix_postgres_app?sslmode=disable JWT_SECRET: your-super-secret-jwt-key-change-in-production OTEL_SERVICE_NAME: actix-postgres-worker OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 RUST_LOG: info,sqlx=warn depends_on: postgres: condition: service_healthy otel-collector: condition: service_started postgres: image: postgres:18.2-alpine3.23 environment: POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres POSTGRES_DB: actix_postgres_app ports: - "5432:5432" volumes: - postgres_data:/var/lib/postgresql/data healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otel-config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otel-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" env_file: - path: .env required: false environment: - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-http://localhost:4318} - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} volumes: postgres_data: ``` #### OpenTelemetry Collector Configuration ```yaml showLineNumbers title="config/otel-config.yaml" extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s health_check: endpoint: 0.0.0.0:13133 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: limit_mib: 256 check_interval: 1s batch: timeout: 10s send_batch_size: 1024 filter/noisy: traces: span: - 'IsMatch(name, ".*/api/health")' exporters: otlp_http/b14: endpoint: ${env:SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: basic service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlp_http/b14, debug] ``` #### Production Environment Variables ```bash showLineNumbers title=".env.production" OTEL_SERVICE_NAME=actix-postgres-api OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 RUST_LOG=info,sqlx=warn ENVIRONMENT=production DATABASE_URL=postgres://user:pass@db:5432/production ``` ### Metrics OpenTelemetry can collect custom metrics from your Actix Web application for resource utilization, request rates, error counts, and business metrics. #### Defining Custom Metrics Create a metrics module with static metric definitions using `LazyLock`: ```rust showLineNumbers title="src/telemetry/metrics.rs" use opentelemetry::{ global, metrics::{Counter, Histogram, Meter}, }; use std::sync::LazyLock; pub static METER: LazyLock = LazyLock::new(|| global::meter("actix-postgres")); pub static HTTP_REQUESTS_TOTAL: LazyLock> = LazyLock::new(|| { METER .u64_counter("http.requests.total") .with_description("Total number of HTTP requests") .with_unit("{request}") .build() }); pub static HTTP_REQUEST_DURATION: LazyLock> = LazyLock::new(|| { METER .f64_histogram("http.request.duration") .with_description("HTTP request duration in milliseconds") .with_unit("ms") .with_boundaries(vec![ 1.0, 5.0, 10.0, 25.0, 50.0, 100.0, 250.0, 500.0, 1000.0, 2500.0, 5000.0, 10000.0, ]) .build() }); pub static ARTICLES_CREATED: LazyLock> = LazyLock::new(|| { METER.u64_counter("articles.created") .with_description("Total articles created").build() }); pub static ARTICLES_UPDATED: LazyLock> = LazyLock::new(|| { METER.u64_counter("articles.updated") .with_description("Total articles updated").build() }); pub static ARTICLES_DELETED: LazyLock> = LazyLock::new(|| { METER.u64_counter("articles.deleted") .with_description("Total articles deleted").build() }); pub static FAVORITES_ADDED: LazyLock> = LazyLock::new(|| { METER.u64_counter("favorites.added") .with_description("Total favorites added").build() }); pub static FAVORITES_REMOVED: LazyLock> = LazyLock::new(|| { METER.u64_counter("favorites.removed") .with_description("Total favorites removed").build() }); pub static USERS_REGISTERED: LazyLock> = LazyLock::new(|| { METER.u64_counter("users.registered") .with_description("Total users registered").build() }); pub static JOBS_ENQUEUED: LazyLock> = LazyLock::new(|| { METER.u64_counter("jobs.enqueued") .with_description("Total jobs enqueued").build() }); pub static JOBS_COMPLETED: LazyLock> = LazyLock::new(|| { METER.u64_counter("jobs.completed") .with_description("Total jobs completed successfully").build() }); pub static JOBS_FAILED: LazyLock> = LazyLock::new(|| { METER.u64_counter("jobs.failed") .with_description("Total jobs failed").build() }); ``` #### Recording Business Metrics Track business-specific events in service methods: ```rust showLineNumbers title="src/services/article.rs" use crate::telemetry::{ARTICLES_CREATED, ARTICLES_DELETED, FAVORITES_ADDED}; ARTICLES_CREATED.add(1, &[]); tracing::info!(article_id = article.id, slug = %article.slug, "Article created"); ``` ### SQLx Database Monitoring OpenTelemetry integrates with SQLx through the tracing ecosystem to provide comprehensive database query monitoring. #### Configuring SQLx Connection Pool ```rust showLineNumbers title="src/database/pool.rs" use sqlx::postgres::{PgPool, PgPoolOptions}; pub async fn create_pool(config: &Config) -> Result { let pool = PgPoolOptions::new() .max_connections(20) .min_connections(5) .acquire_timeout(Duration::from_secs(30)) .idle_timeout(Duration::from_secs(600)) .max_lifetime(Duration::from_secs(1800)) .connect(&config.database_url) .await?; tracing::info!("Database connection pool created"); Ok(pool) } ``` #### Instrumenting Repository Methods Use the `#[instrument]` macro for automatic span creation on repository methods: ```rust showLineNumbers title="src/repository/article.rs" use tracing::instrument; #[derive(Clone)] pub struct ArticleRepository { pool: PgPool, } impl ArticleRepository { pub fn new(pool: PgPool) -> Self { Self { pool } } #[instrument(name = "db.article.create", skip(self))] pub async fn create( &self, slug: &str, title: &str, description: &str, body: &str, author_id: i32, ) -> Result { sqlx::query_as!( Article, r#" INSERT INTO articles (slug, title, description, body, author_id) VALUES ($1, $2, $3, $4, $5) RETURNING id, slug, title, description, body, author_id, favorites_count, created_at, updated_at "#, slug, title, description, body, author_id ) .fetch_one(&self.pool) .await } #[instrument(name = "db.article.find_by_slug", skip(self))] pub async fn find_by_slug(&self, slug: &str) -> Result, sqlx::Error> { sqlx::query_as!(Article, "SELECT * FROM articles WHERE slug = $1", slug) .fetch_optional(&self.pool) .await } } ``` ### Custom Manual Instrumentation #### Creating Custom Spans with the Instrument Macro Use the `#[instrument]` macro from the `tracing` crate on service methods: ```rust showLineNumbers title="src/services/article.rs" use tracing::instrument; #[derive(Clone)] pub struct ArticleService { article_repo: ArticleRepository, favorite_repo: FavoriteRepository, job_queue: JobQueue, } impl ArticleService { #[instrument(name = "article.create", skip(self, input), fields(author_id))] pub async fn create( &self, author_id: i32, input: CreateArticleInput, ) -> AppResult { let slug = self.generate_slug(&input.title); let final_slug = if self.article_repo.exists_by_slug(&slug).await? { format!("{}-{}", slug, time::OffsetDateTime::now_utc().unix_timestamp()) } else { slug }; let article = self.article_repo .create(&final_slug, &input.title, input.description.as_deref().unwrap_or(""), &input.body, author_id) .await?; if let Err(e) = self.job_queue .enqueue_notification(article.id, &article.title).await { tracing::warn!(article_id = article.id, error = %e, "Failed to enqueue notification"); } ARTICLES_CREATED.add(1, &[]); tracing::info!(article_id = article.id, slug = %article.slug, "Article created"); Ok(ArticleResponse { article: ArticleDto::from(article) }) } #[instrument(name = "article.delete", skip(self))] pub async fn delete(&self, slug: &str, user_id: i32) -> AppResult<()> { let article = self.article_repo.find_by_slug(slug).await? .ok_or(AppError::NotFound("Article not found".to_string()))?; if article.author_id != user_id { return Err(AppError::Forbidden); } self.article_repo.delete(article.id).await?; ARTICLES_DELETED.add(1, &[]); tracing::info!(article_id = article.id, "Article deleted"); Ok(()) } #[instrument(name = "article.favorite", skip(self))] pub async fn favorite(&self, slug: &str, user_id: i32) -> AppResult { let article = self.article_repo.find_by_slug(slug).await? .ok_or(AppError::NotFound("Article not found".to_string()))?; let already_favorited = self.favorite_repo.exists(user_id, article.id).await?; if !already_favorited { self.favorite_repo.create(user_id, article.id).await?; self.article_repo.increment_favorites(article.id).await?; FAVORITES_ADDED.add(1, &[]); tracing::info!(article_id = article.id, user_id, "Article favorited"); } let updated = self.article_repo.find_by_id(article.id).await? .ok_or(AppError::Internal("Failed to fetch article".to_string()))?; Ok(ArticleResponse { article: ArticleDto::from(updated) }) } } ``` #### Error Handling with Trace IDs Actix Web uses the `ResponseError` trait for error handling. Include trace IDs in error responses so users can reference them in support requests: ```rust showLineNumbers title="src/error.rs" use actix_web::{HttpResponse, http::StatusCode}; use opentelemetry::trace::TraceContextExt; use serde_json::json; use thiserror::Error; use tracing::Span; use tracing_opentelemetry::OpenTelemetrySpanExt; #[derive(Error, Debug)] pub enum AppError { #[error("Authentication required")] Unauthorized, #[error("Invalid credentials")] InvalidCredentials, #[error("Forbidden")] Forbidden, #[error("Not found: {0}")] NotFound(String), #[error("Conflict: {0}")] Conflict(String), #[error("Validation error: {0}")] Validation(String), #[error("Database error: {0}")] Database(#[from] sqlx::Error), #[error("JWT error: {0}")] Jwt(#[from] jsonwebtoken::errors::Error), #[error("Internal error: {0}")] Internal(String), } fn get_trace_id() -> Option { let span = Span::current(); let context = span.context(); let span_ref = context.span(); let span_context = span_ref.span_context(); if span_context.is_valid() { Some(span_context.trace_id().to_string()) } else { None } } impl actix_web::ResponseError for AppError { fn status_code(&self) -> StatusCode { match self { AppError::Unauthorized | AppError::InvalidCredentials | AppError::Jwt(_) => StatusCode::UNAUTHORIZED, AppError::Forbidden => StatusCode::FORBIDDEN, AppError::NotFound(_) => StatusCode::NOT_FOUND, AppError::Conflict(_) => StatusCode::CONFLICT, AppError::Validation(_) => StatusCode::BAD_REQUEST, AppError::Database(_) | AppError::Internal(_) => StatusCode::INTERNAL_SERVER_ERROR, } } fn error_response(&self) -> HttpResponse { let status = self.status_code(); let error_message = match self { AppError::Database(e) => { tracing::error!(error = %e, "Database error"); "Internal server error".to_string() } AppError::Internal(msg) => { tracing::error!(error = %msg, "Internal error"); "Internal server error".to_string() } _ => self.to_string(), }; let body = if let Some(trace_id) = get_trace_id() { json!({ "error": error_message, "status": status.as_u16(), "trace_id": trace_id, }) } else { json!({ "error": error_message, "status": status.as_u16(), }) }; HttpResponse::build(status).json(body) } } pub type AppResult = Result; ``` #### Authentication Middleware with FromRequest Actix Web uses the `FromRequest` trait for extractors. This pattern differs from Axum's middleware layers: ```rust showLineNumbers title="src/middleware/auth.rs" use actix_web::{FromRequest, HttpRequest, dev::Payload, web}; use std::future::{Ready, ready}; use crate::{error::AppError, services::AuthService}; pub struct AuthUser(pub i32); impl FromRequest for AuthUser { type Error = AppError; type Future = Ready>; fn from_request(req: &HttpRequest, _payload: &mut Payload) -> Self::Future { let result = extract_and_validate(req, false); ready(result.map(|id| AuthUser(id.expect("token required")))) } } pub struct OptionalAuthUser(pub Option); impl FromRequest for OptionalAuthUser { type Error = AppError; type Future = Ready>; fn from_request(req: &HttpRequest, _payload: &mut Payload) -> Self::Future { let result = extract_and_validate(req, true); ready(result.map(OptionalAuthUser)) } } fn extract_and_validate(req: &HttpRequest, optional: bool) -> Result, AppError> { let auth_service = req .app_data::>() .ok_or(AppError::Internal("AuthService not configured".to_string()))?; let token = req.headers() .get("Authorization") .and_then(|value| value.to_str().ok()) .and_then(|header| header.strip_prefix("Bearer ")); match token { Some(token) => match auth_service.validate_token(token) { Ok(user_id) => Ok(Some(user_id)), Err(_) if optional => Ok(None), Err(e) => Err(e), }, None if optional => Ok(None), None => Err(AppError::Unauthorized), } } ``` #### Route Definitions ```rust showLineNumbers title="src/routes.rs" use actix_web::web; use crate::handlers; pub fn configure(cfg: &mut web::ServiceConfig) { cfg.route("/api/health", web::get().to(handlers::health_check)) .route("/api/register", web::post().to(handlers::register)) .route("/api/login", web::post().to(handlers::login)) .route("/api/user", web::get().to(handlers::get_user)) .route("/api/articles", web::get().to(handlers::list_articles)) .route("/api/articles", web::post().to(handlers::create_article)) .route("/api/articles/{slug}", web::get().to(handlers::get_article)) .route("/api/articles/{slug}", web::put().to(handlers::update_article)) .route("/api/articles/{slug}", web::delete().to(handlers::delete_article)) .route("/api/articles/{slug}/favorite", web::post().to(handlers::favorite_article)) .route("/api/articles/{slug}/favorite", web::delete().to(handlers::unfavorite_article)); } ``` ### Job Queue with Trace Propagation This application uses a PostgreSQL-native job queue with `FOR UPDATE SKIP LOCKED` for concurrent-safe job processing, and W3C Trace Context propagation to link producer and consumer spans. #### Enqueuing Jobs (Producer) The job queue captures the current trace context and stores it as JSON in the `trace_context` column: ```rust showLineNumbers title="src/jobs/queue.rs" use serde::{Deserialize, Serialize}; use sqlx::{PgPool, Row}; use std::collections::HashMap; use tracing::{Span, instrument}; use crate::telemetry::{JOBS_COMPLETED, JOBS_ENQUEUED, JOBS_FAILED}; #[derive(Clone)] pub struct JobQueue { pool: PgPool, } impl JobQueue { pub fn new(pool: PgPool) -> Self { Self { pool } } #[instrument(name = "job.enqueue", skip(self, payload))] pub async fn enqueue( &self, kind: &str, payload: T, ) -> Result { let trace_context = self.capture_trace_context(); let payload_json = serde_json::to_value(&payload) .unwrap_or(serde_json::Value::Null); let row = sqlx::query( r#" INSERT INTO jobs (kind, payload, trace_context) VALUES ($1, $2, $3) RETURNING id "#, ) .bind(kind) .bind(&payload_json) .bind(&trace_context) .fetch_one(&self.pool) .await?; let job_id: i64 = row.get("id"); JOBS_ENQUEUED.add(1, &[]); tracing::info!(job_id, kind, "Job enqueued"); Ok(job_id) } pub async fn dequeue(&self) -> Result, sqlx::Error> { let result = sqlx::query( r#" UPDATE jobs SET status = 'processing', started_at = NOW(), attempts = attempts + 1 WHERE id = ( SELECT id FROM jobs WHERE status = 'pending' AND scheduled_at <= NOW() AND attempts < max_attempts ORDER BY priority DESC, scheduled_at ASC FOR UPDATE SKIP LOCKED LIMIT 1 ) RETURNING id, kind, payload, status, attempts, trace_context "#, ) .fetch_optional(&self.pool) .await?; Ok(result.map(|row| Job { id: row.get("id"), kind: row.get("kind"), payload: row.get("payload"), status: row.get("status"), attempts: row.get("attempts"), trace_context: row.get("trace_context"), })) } fn capture_trace_context(&self) -> Option { use opentelemetry::trace::TraceContextExt; use tracing_opentelemetry::OpenTelemetrySpanExt; let span = Span::current(); let context = span.context(); let otel_span = context.span(); let span_context = otel_span.span_context(); if span_context.is_valid() { let mut carrier = HashMap::new(); carrier.insert( "traceparent".to_string(), format!( "00-{}-{}-{:02x}", span_context.trace_id(), span_context.span_id(), span_context.trace_flags().to_u8() ), ); Some(serde_json::to_value(&carrier).unwrap_or(serde_json::Value::Null)) } else { None } } } ``` #### Processing Jobs (Consumer) The worker binary extracts the trace context from job data and restores the parent span, linking the consumer trace to the original HTTP request: ```rust showLineNumbers title="src/bin/worker.rs" use std::collections::HashMap; use opentelemetry::propagation::TextMapPropagator; use opentelemetry_sdk::propagation::TraceContextPropagator; use tracing::Instrument; use tracing_opentelemetry::OpenTelemetrySpanExt; async fn process_job(job_queue: &JobQueue) -> anyhow::Result<()> { let Some(job) = job_queue.dequeue().await? else { return Ok(()); }; let parent_context = extract_trace_context(&job.trace_context); let span = tracing::info_span!( "job.process", job_id = job.id, job_kind = %job.kind, ); let _ = span.set_parent(parent_context); async { tracing::info!(job_id = job.id, kind = %job.kind, "Processing job"); let result = match job.kind.as_str() { "notification" => NotificationHandler::handle(&job).await, _ => { tracing::warn!(job_id = job.id, kind = %job.kind, "Unknown job kind"); Err(anyhow::anyhow!("Unknown job kind: {}", job.kind)) } }; match result { Ok(()) => { job_queue.complete(job.id).await?; tracing::info!(job_id = job.id, "Job completed"); } Err(e) => { job_queue.fail(job.id, &e.to_string()).await?; tracing::error!(job_id = job.id, error = %e, "Job failed"); } } Ok(()) } .instrument(span) .await } fn extract_trace_context( trace_context: &Option, ) -> opentelemetry::Context { let Some(ctx_value) = trace_context else { return opentelemetry::Context::new(); }; let carrier: HashMap = match serde_json::from_value(ctx_value.clone()) { Ok(c) => c, Err(_) => return opentelemetry::Context::new(), }; let propagator = TraceContextPropagator::new(); propagator.extract(&carrier) } ``` ### Running Your Instrumented Application ```mdx-code-block ``` ```bash showLineNumbers RUST_LOG=debug cargo run --bin api # In a separate terminal, start the worker RUST_LOG=debug cargo run --bin worker ``` ```mdx-code-block ``` ```bash showLineNumbers export OTEL_SERVICE_NAME=actix-postgres-api export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4317 export RUST_LOG=info,sqlx=warn export ENVIRONMENT=production ./target/release/api ``` ```mdx-code-block ``` ```bash showLineNumbers docker compose up --build docker compose logs -f api worker docker compose down ``` ```mdx-code-block ``` ### Troubleshooting #### Health Check Endpoint ```rust showLineNumbers title="src/handlers/health.rs" use actix_web::{HttpResponse, web}; use serde_json::json; use sqlx::{PgPool, Row}; pub async fn health_check(pool: web::Data) -> HttpResponse { let db_status = sqlx::query("SELECT 1 as one") .fetch_one(pool.get_ref()) .await .map(|row: sqlx::postgres::PgRow| { let _: i32 = row.get("one"); "healthy" }) .unwrap_or("unhealthy"); if db_status == "healthy" { HttpResponse::Ok().json(json!({ "status": "ok", "database": db_status, "service": "actix-postgres", })) } else { HttpResponse::ServiceUnavailable().json(json!({ "status": "error", "database": db_status, })) } } ``` #### Debug Mode Enable debug logging to troubleshoot instrumentation issues: ```bash showLineNumbers export RUST_LOG=debug,opentelemetry=debug,tracing_opentelemetry=debug cargo run --bin api ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify Scout Collector endpoint is reachable: ```bash showLineNumbers curl -v http://scout-collector:4317/v1/traces ``` 2. Check environment variables: ```bash showLineNumbers echo $OTEL_EXPORTER_OTLP_ENDPOINT echo $OTEL_SERVICE_NAME ``` 3. Enable debug logging and check for export errors 4. Verify network connectivity between your app and Scout Collector ##### Issue: Missing database query spans **Solutions:** 1. Ensure SQLx logging level is set to at least `warn`: ```rust showLineNumbers EnvFilter::new("info,sqlx=warn") ``` 2. Verify you're using async SQLx methods that emit tracing spans 3. Check that `tracing-opentelemetry` layer is properly configured ##### Issue: Worker jobs not linked to original request trace **Solutions:** 1. Verify `capture_trace_context()` is called during `enqueue()` 2. Check that the `trace_context` column exists in the jobs table 3. Ensure the worker calls `span.set_parent(parent_context)` before processing ##### Issue: High memory usage **Solutions:** 1. Reduce `max_queue_size` in batch processor configuration 2. Ensure spans are being exported successfully 3. Check for span attribute size limits ### Security Considerations #### Protecting Sensitive Data Avoid adding sensitive information to span attributes: ```rust showLineNumbers // Bad - exposes sensitive data tracing::info!(user.password = %password, "Login attempt"); // Good - uses safe identifiers tracing::info!(user.id = user_id, user.role = %role, "Login attempt"); ``` #### Sanitizing SQL Statements SQLx parameterized queries prevent values from appearing in tracing spans: ```rust showLineNumbers let user = sqlx::query_as!( User, "SELECT * FROM users WHERE email = $1 AND password_hash = $2", email, password_hash ) .fetch_optional(&pool) .await?; ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard - Use parameterized queries to avoid logging sensitive values - Audit span attributes regularly for sensitive data leaks ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead to Rust Actix Web applications: - **Average latency increase**: < 1ms per request - **CPU overhead**: Less than 1% in production with batch processor - **Memory overhead**: ~20-50MB depending on queue size and traffic #### Optimization Best Practices ##### 1. Use Batch Processor in Production The `BatchSpanProcessor` is used by default with `with_batch_exporter`: ```rust showLineNumbers let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .build(); ``` ##### 2. Use Appropriate Log Levels ```rust showLineNumbers // Production: minimal logging let env_filter = EnvFilter::new("info,sqlx=warn"); // Development: verbose logging let env_filter = EnvFilter::new("debug,sqlx=debug"); ``` ##### 3. Skip Health Check Endpoints The OTel Collector filter processor removes health check spans: ```yaml showLineNumbers processors: filter/noisy: traces: span: - 'IsMatch(name, ".*/api/health")' ``` ### Frequently Asked Questions #### Does OpenTelemetry impact Rust application performance? OpenTelemetry adds approximately < 1ms of latency per request in typical Actix Web applications. Rust's zero-cost abstractions and the efficient `tracing` crate minimize overhead. With batch processing, the performance impact is negligible for most production workloads. #### What is the difference between Actix Web and Axum instrumentation? Actix Web uses `tracing-actix-web` with `TracingLogger` middleware, while Axum uses `tower-http` with `TraceLayer`. Actix Web shares state via `web::Data`, while Axum uses `State` extractors. Error handling in Actix Web uses the `ResponseError` trait, and authentication uses `FromRequest` extractors instead of middleware layers. #### Which Rust versions are supported? OpenTelemetry Rust supports Rust 1.80+ with edition 2021 or 2024. Rust 1.92+ is recommended for optimal compatibility and performance. #### Can I use OpenTelemetry with async Rust and Tokio? Yes. The `tracing` crate handles async context propagation automatically, and `tracing-opentelemetry` bridges tracing spans to OpenTelemetry. Use `opentelemetry_sdk` with the `rt-tokio` feature for Tokio runtime support. #### How do I trace async tasks spawned with tokio::spawn? Use `tracing::Instrument` to propagate context to spawned tasks: ```rust showLineNumbers use tracing::Instrument; let span = tracing::info_span!("background_task"); tokio::spawn(async move { // Work here is traced under the span }.instrument(span)); ``` #### How do I propagate traces to background job workers? Store the W3C `traceparent` header in your job payload when enqueuing, then extract it with `TraceContextPropagator` in the worker and set it as the parent context using `span.set_parent()`. See the [Job Queue](#job-queue-with-trace-propagation) section. #### How do I handle multi-tenant applications? Record the tenant as a field on the request span, then filter by it in Scout: ```rust showLineNumbers tracing::info_span!( "request", tenant.id = %tenant_id, tenant.name = %tenant_name ); ``` #### How do I monitor SQLx connection pool health? SQLx emits tracing spans for pool operations. Monitor these for connection acquisition times and pool exhaustion. Configure the pool with appropriate `acquire_timeout` and `max_connections` settings. #### Can I include trace IDs in error responses? Yes. Use the `get_trace_id()` helper function in your `ResponseError` implementation to extract the current trace ID and include it in JSON error responses. See the [Error Handling](#error-handling-with-trace-ids) section. ### What's Next? #### Advanced Topics - **[PostgreSQL Monitoring Best Practices](../../component/postgres.md)** - Optimize database observability with connection pooling metrics #### Scout Platform Features - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - Set up alerts for error rates, latency thresholds, and custom metrics - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Set up Scout Collector for local development - **[Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md)** - Production deployment ### Complete Example #### Project Structure ```text actix-postgres/ ├── src/ │ ├── main.rs # API bootstrap with TracingLogger │ ├── lib.rs # Library exports │ ├── config.rs # Configuration │ ├── error.rs # Error handling with trace IDs │ ├── routes.rs # Route definitions │ ├── bin/ │ │ └── worker.rs # Background job worker │ ├── telemetry/ │ │ ├── init.rs # OTLP trace/log initialization │ │ ├── metrics.rs # 12 custom metrics │ │ └── mod.rs │ ├── handlers/ │ │ ├── health.rs │ │ ├── auth.rs │ │ └── articles.rs │ ├── services/ │ │ ├── auth.rs # #[instrument] on all methods │ │ └── article.rs # #[instrument] on all methods │ ├── repository/ │ │ ├── user.rs # SQLx with #[instrument] │ │ ├── article.rs │ │ └── favorite.rs │ ├── middleware/ │ │ └── auth.rs # FromRequest extractors │ ├── database/ │ │ └── pool.rs │ ├── models/ │ │ ├── user.rs │ │ └── article.rs │ └── jobs/ │ ├── queue.rs # SKIP LOCKED + W3C trace propagation │ └── notification.rs ├── config/ │ └── otel-config.yaml # Collector configuration ├── migrations/ │ └── 20260214000001_initial.sql ├── compose.yml ├── Dockerfile ├── Dockerfile.worker ├── Cargo.toml └── Cargo.lock ``` #### Environment Variables ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=actix-postgres-api OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 RUST_LOG=info,sqlx=warn DATABASE_URL=postgres://postgres:postgres@localhost:5432/actix_postgres_app JWT_SECRET=your-secret-key ``` This complete example is available in our [GitHub examples repository](https://github.com/base-14/examples/tree/main/rust/actix-postgres). ### References - [Official OpenTelemetry Rust Documentation](https://opentelemetry.io/docs/languages/rust/) - [tracing-actix-web Crate](https://docs.rs/tracing-actix-web) - [tracing-opentelemetry Crate](https://docs.rs/tracing-opentelemetry) - [Actix Web Documentation](https://actix.rs/docs/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Rust Custom Instrumentation](../custom-instrumentation/rust.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language --- ## Angular OpenTelemetry - Browser Traces, Metrics, Logs ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## Angular :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### Introduction Implement OpenTelemetry instrumentation for Angular applications to bring real user monitoring (RUM), distributed tracing, and front-end observability to single-page apps. This guide shows you how to auto-instrument document loads, user interactions, and `fetch`/`XHR` calls in the browser, then propagate W3C trace context to your backend so a single trace spans the browser, your API, and your database. It covers all three OpenTelemetry signals from the browser: **traces** (page loads, interactions, route changes, and API calls), **metrics** (Core Web Vitals as histograms), and **logs** (uncaught errors and failed requests as ERROR records, correlated to the trace that caused them). The backend adds HTTP and runtime metrics plus trace-correlated logs, so the browser and API tell one story. The example app is **Angular 22**, which is **zoneless by default**. The instrumentation is identical on a zone.js application; the only difference is how an interaction's asynchronous work is parented inside the browser. Both variants are covered under [Context Propagation](#context-propagation-zoneless-vs-zonejs). Whether you are migrating from a commercial RUM product, debugging why a page feels slow, or connecting a slow API call back to the click that caused it, this guide gives you production-ready configuration. :::tip TL;DR Initialize the browser SDK in `main.ts` before `bootstrapApplication`. Register the `WebTracerProvider` with the default `StackContextManager` (`provider.register()` - no zone.js needed), and call `setGlobalMeterProvider()` and `setGlobalLoggerProvider()` so metrics and logs are not silently dropped. Add `@opentelemetry/auto-instrumentations-web` for document-load, fetch, XHR, and interaction spans, set `propagateTraceHeaderCorsUrls` to your API origin so the `traceparent` header links the browser trace to your backend, record Core Web Vitals as metric histograms, and emit uncaught errors as ERROR logs. ::: ### Who This Guide Is For This documentation is designed for: - **Angular developers**: adding browser tracing, metrics, and error logs to standalone, signal-based Angular apps. - **Front-end engineers**: connecting slow user interactions to the API and database calls behind them with one end-to-end trace. - **Full-stack teams**: correlating browser spans, Web Vitals, and error logs with existing backend instrumentation across a shared trace id. - **Platform teams**: standardizing web observability across several Angular apps with a consistent, zoneless-ready setup. - **SRE and DevOps**: deploying instrumented Angular SPAs behind nginx and a collector with correct CORS in both directions. ### Overview #### Prerequisites Before starting, ensure you have: - **Node.js 24.15+ or 26+** to build the app (the Angular 22 engines range). - **Angular 20 or later** - the example uses `provideBrowserGlobalErrorListeners()` (added in v20) and zoneless change detection (stable in v20, default in v21); this guide uses **Angular 22**. The browser SDK setup itself works on any standalone Angular (16+), but the error-handling wiring shown here needs v20+. - **A Scout Collector** reachable from the browser over OTLP/HTTP, with traces, metrics, and logs pipelines. - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development. - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production. - A backend API that accepts cross-origin requests and echoes back CORS headers (this guide uses Express + Postgres). - Basic understanding of OpenTelemetry concepts (traces, spans, metrics, logs, attributes). #### Compatibility Matrix | Component | Minimum Version | Recommended | | -------------------------------------------- | --------------- | ----------- | | Angular | 20.0.0 | 22.0.4 | | Node.js (build) | 24.15.0 | 26.x | | @opentelemetry/api | 1.9.0 | 1.9.1 | | @opentelemetry/api-logs | 0.200.0 | 0.219.0 | | @opentelemetry/sdk-trace-web | 2.0.0 | 2.8.0 | | @opentelemetry/sdk-metrics | 2.0.0 | 2.8.0 | | @opentelemetry/sdk-logs | 0.200.0 | 0.219.0 | | @opentelemetry/auto-instrumentations-web | 0.50.0 | 0.64.0 | | @opentelemetry/exporter-trace-otlp-http | 0.200.0 | 0.219.0 | | @opentelemetry/exporter-metrics-otlp-http | 0.200.0 | 0.219.0 | | @opentelemetry/exporter-logs-otlp-http | 0.200.0 | 0.219.0 | | web-vitals | 4.0.0 | 5.3.0 | | opentelemetry-collector-contrib | 0.120.0 | 0.153.0 | Angular 21 and later ship **zoneless** by default (`ng new` no longer adds zone.js). The setup below assumes zoneless; the zone.js opt-in is a three-line delta shown later. #### Instrumented Components | Signal | Source | Emitted as | | ------- | ------------------------------------------ | ------------------ | | Traces | `instrumentation-document-load` | document-load span | | Traces | `instrumentation-user-interaction` | click/submit span | | Traces | `instrumentation-fetch` / `-xml-http-request` | HTTP client span | | Traces | Custom `Router.events` subscription | `router.navigation` span | | Metrics | `web-vitals` library | histograms (`web_vitals.*`) | | Logs | Custom Angular `ErrorHandler` | ERROR log (best-effort) | | Logs | Custom `HttpClient` interceptor | ERROR log (trace-correlated) | The backend (Express + Node SDK) adds `http.server.request.duration` and runtime metrics plus trace-correlated `pino` logs, so the browser and API share one trace id across all three signals. A complete, runnable version of everything in this guide lives in [base-14/examples/nodejs/angular-fullstack-otel](https://github.com/base-14/examples/tree/main/nodejs/angular-fullstack-otel). ### Installation Install the browser SDK for all three signals, the web auto-instrumentations, the OTLP/HTTP exporters, and the Web Vitals library. ```mdx-code-block ``` ```bash npm install \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-trace-web \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @opentelemetry/instrumentation \ @opentelemetry/auto-instrumentations-web \ web-vitals ``` ```mdx-code-block ``` ```bash yarn add \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-trace-web \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @opentelemetry/instrumentation \ @opentelemetry/auto-instrumentations-web \ web-vitals ``` ```mdx-code-block ``` ```bash pnpm add \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-trace-web \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @opentelemetry/instrumentation \ @opentelemetry/auto-instrumentations-web \ web-vitals ``` ```mdx-code-block ``` The OpenTelemetry JS packages move on a few separate version lines: the SDK packages `sdk-trace-web`, `sdk-metrics`, and `resources` are on the stable `2.x` line (2.8.0), `semantic-conventions` is on the `1.x` line (1.41.1), and `api-logs`, `sdk-logs`, `instrumentation`, plus the OTLP exporters share the `0.2xx` experimental line (0.219.0), while `auto-instrumentations-web` tracks its own contrib line (0.64.0). Keep `@opentelemetry/api` to a single version (1.9.1) so the bundle does not pull duplicate copies. ### Configuration Telemetry settings differ between a development build (`ng serve`) and a production build (`ng build`). Angular's environment files are the simplest place to keep them, but a runtime config file or container environment also works. ```mdx-code-block ``` ```typescript title="src/environments/environment.ts" showLineNumbers // Production build config (used by `ng build`). The browser runs on the host in // every mode of this example, so the collector/API are reached via localhost. // The whole local stack runs as a single `development` environment (matching the // backend DEPLOY_ENV and the collector's SCOUT_ENVIRONMENT default) so one trace // carries one environment. For a real deployment, set this to `production` and // override the endpoints (e.g. a runtime assets/config.json). export const environment = { production: true, otelServiceName: 'angular-browser', deploymentEnvironment: 'development', otelCollectorUrl: 'http://localhost:4318', apiBaseUrl: 'http://localhost:3000/api', // Only attach `traceparent` to our own API (don't leak trace headers cross-site). apiTraceUrls: [/^http:\/\/localhost:3000/] as RegExp[], }; ``` Angular swaps in `environment.development.ts` during `ng serve` via the `fileReplacements` entry in `angular.json`, so dev and prod can point at different collector and API origins without code changes. ```mdx-code-block ``` For container images that must be configurable without a rebuild, load a JSON file from `assets/` at startup instead of compiling values into the bundle. ```json title="src/assets/otel-config.json" { "otelServiceName": "angular-browser", "deploymentEnvironment": "production", "otelCollectorUrl": "https://collector.example.com", "apiBaseUrl": "https://api.example.com" } ``` For this variant, refactor `initBrowserTelemetry` to accept the config object (instead of reading the compiled-in `environment`), then fetch the file and pass it in before bootstrap: ```typescript title="src/main.ts (runtime variant)" // initBrowserTelemetry(cfg: OtelConfig) reads endpoints from cfg, not environment const cfg = await fetch('/assets/otel-config.json').then((r) => r.json()); initBrowserTelemetry(cfg); ``` Fetch the config before bootstrap so the SDK starts with the right endpoints. The trade-off is one extra request before bootstrap. ```mdx-code-block ``` The browser exports straight to the collector, so the collector decides which SPA origins it trusts. Set the OTLP HTTP receiver's CORS allow-list to every origin the app is served from, and run a pipeline for each signal. ```yaml title="config/otel-config.yaml" receivers: otlp: protocols: http: endpoint: 0.0.0.0:4318 cors: allowed_origins: - http://localhost:4200 # ng serve (dev) - http://localhost:8080 # nginx container allowed_headers: - "*" service: pipelines: traces: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] ``` ```mdx-code-block ``` ### Production Configuration #### Build-time vs runtime configuration Compiling endpoints into the bundle (the `environment.ts` approach) is simplest and fastest, but it bakes the collector and API URLs into the image. If you ship one image to several environments, prefer the runtime `config.json` approach so the same artifact reads its endpoints at startup. #### Serving the built app The `@angular/build:application` builder emits the browser bundle under `dist//browser`. Serve it from any static host. With nginx, add an SPA fallback so deep links resolve to `index.html`: ```nginx title="frontend/nginx.conf" server { listen 80; # SPA fallback: Angular handles client-side routes, so unknown paths must # return index.html rather than 404 (deep links like /items, /about). location / { root /usr/share/nginx/html; try_files $uri $uri/ /index.html; } } ``` ```dockerfile title="frontend/Dockerfile" # Build the Angular bundle, then serve the static output from nginx. FROM node:24-alpine AS build WORKDIR /app COPY package*.json ./ RUN npm ci COPY . . RUN npm run build FROM nginx:alpine COPY --from=build /app/dist/frontend/browser /usr/share/nginx/html COPY nginx.conf /etc/nginx/conf.d/default.conf ``` #### Export cadence and batching Each signal exports off the interaction path on its own schedule. The `BatchSpanProcessor` and `BatchLogRecordProcessor` buffer spans and log records and flush on a timer; the `PeriodicExportingMetricReader` exports metrics every `exportIntervalMillis` (10 seconds in the example). For chatty UIs, raise the span processor's `maxQueueSize` and `maxExportBatchSize` so bursts are not dropped. Because Core Web Vitals and last-moment errors are reported as the page is hidden, force a flush of all three providers on `visibilitychange` and `pagehide` (shown in the bootstrap below) so that data is not lost with the tab. #### Reverse-proxy alternative to collector CORS Instead of opening CORS on the collector, you can serve the collector under the same origin as the SPA through a reverse proxy (for example, proxy `/v1/traces`, `/v1/metrics`, and `/v1/logs` on the app's domain to the collector). Same-origin export removes the browser preflight entirely. Point `otelCollectorUrl` at the app origin and drop the `cors` block from the receiver. ### Angular-Specific Features #### Initialize before bootstrap Call the SDK setup in `main.ts` **before** `bootstrapApplication`, so the document-load span and the earliest interactions are captured. The Angular Router is not available here (it only exists after dependency injection is up), so router tracing is wired separately from the root component. ```typescript title="src/main.ts" showLineNumbers import { bootstrapApplication } from '@angular/platform-browser'; import { appConfig } from './app/app.config'; import { App } from './app/app'; import { initBrowserTelemetry } from './app/telemetry/browser-telemetry'; initBrowserTelemetry(); bootstrapApplication(App, appConfig) .catch((err) => console.error(err)); ``` #### HttpClient uses the fetch backend In Angular 22, `fetch` is the default `HttpClient` backend and `withFetch()` is deprecated, so `provideHttpClient()` alone routes requests through it. Because HttpClient calls go through `fetch()`, the OpenTelemetry fetch instrumentation captures them and injects the `traceparent` header automatically. Register the custom `ErrorHandler` (for uncaught errors) and the HTTP error interceptor (for failed requests) here too - both emit ERROR logs, covered under [Errors as logs](#errors-as-logs). ```typescript title="src/app/app.config.ts" showLineNumbers import { ApplicationConfig, ErrorHandler, provideBrowserGlobalErrorListeners, } from '@angular/core'; import { provideRouter } from '@angular/router'; import { provideHttpClient, withInterceptors } from '@angular/common/http'; import { routes } from './app.routes'; import { TelemetryErrorHandler } from './telemetry/error-handler'; import { errorLogInterceptor } from './telemetry/error-interceptor'; export const appConfig: ApplicationConfig = { providers: [ provideBrowserGlobalErrorListeners(), { provide: ErrorHandler, useClass: TelemetryErrorHandler }, provideRouter(routes), // Fetch backend is the v22 default (OTel fetch instrumentation captures it + // attaches traceparent); interceptor emits a correlated log on failure. provideHttpClient(withInterceptors([errorLogInterceptor])), ], }; ``` #### Router navigation spans The web auto-instrumentations cover document load, fetch, XHR, and user interactions, but **not** Angular's client-side Router. Subscribe to `Router.events`, filter for `NavigationEnd`, and emit a span per navigation. ```typescript title="src/app/telemetry/router-tracing.ts" showLineNumbers import { Router, NavigationEnd } from '@angular/router'; import { filter } from 'rxjs/operators'; import { trace } from '@opentelemetry/api'; // The OTel web auto-instrumentations cover document-load, fetch/XHR, and user // interactions, but not Angular's client-side Router. Subscribe to NavigationEnd // so each SPA route change shows up as its own span. export function initRouterTracing(router: Router): void { const tracer = trace.getTracer('angular-router'); router.events .pipe(filter((e): e is NavigationEnd => e instanceof NavigationEnd)) .subscribe((e) => { const span = tracer.startSpan('router.navigation'); span.setAttributes({ 'route.path': e.urlAfterRedirects, 'nav.id': e.id, 'page.url': window.location.href, }); span.end(); }); } ``` Wire it from the root component, where the `Router` is available via injection: ```typescript title="src/app/app.ts" showLineNumbers import { Component, inject } from '@angular/core'; import { RouterOutlet, RouterLink, Router } from '@angular/router'; import { initRouterTracing } from './telemetry/router-tracing'; @Component({ selector: 'app-root', imports: [RouterOutlet, RouterLink], templateUrl: './app.html', styleUrl: './app.css', }) export class App { constructor() { initRouterTracing(inject(Router)); } } ``` #### Context Propagation (zoneless vs zone.js) The distributed trace - browser to API to database - links through the injected `traceparent` header, which does **not** depend on the context manager. Only in-browser parenting of an interaction's asynchronous work differs between the two modes. ```mdx-code-block ``` Angular 22 ships zoneless, so there is no zone.js to hook. Register the tracer provider with no arguments to install the default `StackContextManager` and the W3C trace context propagator. Metrics and logs have no `register()` equivalent, so their providers are set global explicitly - miss that step and every metric and log is silently dropped (see [Why metrics/logs go missing](#no-metrics-or-logs-reach-the-collector)). ```typescript title="src/app/telemetry/browser-telemetry.ts" showLineNumbers import { WebTracerProvider, BatchSpanProcessor } from '@opentelemetry/sdk-trace-web'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { MeterProvider, PeriodicExportingMetricReader, AggregationType, type ViewOptions, } from '@opentelemetry/sdk-metrics'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { LoggerProvider, BatchLogRecordProcessor } from '@opentelemetry/sdk-logs'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-http'; import { metrics } from '@opentelemetry/api'; import { logs } from '@opentelemetry/api-logs'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION } from '@opentelemetry/semantic-conventions'; import { registerInstrumentations } from '@opentelemetry/instrumentation'; import { getWebAutoInstrumentations } from '@opentelemetry/auto-instrumentations-web'; import { environment } from '../../environments/environment'; import { setupWebVitals } from './web-vitals'; let initialized = false; // Per-vital histogram bucket boundaries - see "Core Web Vitals as metrics". const VITAL_VIEWS: ViewOptions[] = [ /* ... */ ]; // Call once before Angular bootstraps so document-load + early interactions are // captured. export function initBrowserTelemetry(): void { if (initialized || typeof window === 'undefined') { return; } initialized = true; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: environment.otelServiceName, [ATTR_SERVICE_VERSION]: '1.0.0', 'deployment.environment.name': environment.deploymentEnvironment, environment: environment.deploymentEnvironment, }); // --- Traces --- const tracerProvider = new WebTracerProvider({ resource, spanProcessors: [ new BatchSpanProcessor( new OTLPTraceExporter({ url: `${environment.otelCollectorUrl}/v1/traces` }), ), ], }); // Zoneless: installs the StackContextManager + W3C propagator and sets the // global TracerProvider. tracerProvider.register(); // --- Metrics --- const meterProvider = new MeterProvider({ resource, readers: [ new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${environment.otelCollectorUrl}/v1/metrics` }), exportIntervalMillis: 10000, }), ], views: VITAL_VIEWS, }); // No register() sugar for metrics/logs: without setGlobal*, getMeter/getLogger // return Noop and every data point is silently dropped. metrics.setGlobalMeterProvider(meterProvider); // --- Logs --- const loggerProvider = new LoggerProvider({ resource, processors: [ new BatchLogRecordProcessor( new OTLPLogExporter({ url: `${environment.otelCollectorUrl}/v1/logs` }), ), ], }); logs.setGlobalLoggerProvider(loggerProvider); // Vitals and last-moment error logs emit as the page hides; flush all signals // then so nothing is lost with the tab. const flush = (): void => { void tracerProvider.forceFlush(); void meterProvider.forceFlush(); void loggerProvider.forceFlush(); }; window.addEventListener('visibilitychange', () => { if (document.visibilityState === 'hidden') { flush(); } }); window.addEventListener('pagehide', flush); registerInstrumentations({ instrumentations: [ getWebAutoInstrumentations({ '@opentelemetry/instrumentation-user-interaction': { eventNames: ['click', 'submit'], }, '@opentelemetry/instrumentation-fetch': { propagateTraceHeaderCorsUrls: environment.apiTraceUrls, }, '@opentelemetry/instrumentation-xml-http-request': { propagateTraceHeaderCorsUrls: environment.apiTraceUrls, }, }), ], }); setupWebVitals(); } ``` The dual-key resource attributes (`deployment.environment.name` plus a lowercase `environment`) keep the SDK aligned with the current semantic conventions while satisfying dashboards that filter on the short key. The same `resource` is shared across all three providers so traces, metrics, and logs carry identical service identity. ```mdx-code-block ``` If your app still uses zone.js (Angular 20 or earlier, or an explicit opt-in), add the `ZoneContextManager` so an interaction span becomes the parent of the async work it triggers. This is **not** part of the zoneless example - it is the three-line delta for a zone-based app. Metrics and logs are unchanged. ```bash npm install @opentelemetry/context-zone zone.js ``` ```typescript title="src/app/telemetry/browser-telemetry.ts (zone-based delta)" import 'zone.js'; import { ZoneContextManager } from '@opentelemetry/context-zone'; // ...build the tracer provider as above, then register with the zone manager: tracerProvider.register({ contextManager: new ZoneContextManager() }); ``` The difference shows up only across an asynchronous boundary. Work that runs synchronously inside an interaction handler nests under it either way - in this example the `fetch` fires synchronously on `subscribe`, so it parents correctly under `items.load` and `click` even when zoneless (verified in the span tree below). `ZoneContextManager` additionally propagates context across async gaps (a later microtask, `setTimeout`, or an awaited call), so a `fetch` issued after such a gap still nests under the interaction. Without it, that deferred `fetch` starts a new root unless you wrap it in `startActiveSpan`. Either way the distributed link to the API is unchanged - it rides the `traceparent` header. ```mdx-code-block ``` ### Custom Instrumentation #### Manual spans around HttpClient Wrap a request in a manual span when you want application-level timing (`items.load`) around the auto-generated `fetch` span. `startActiveSpan` makes the manual span the active parent, so the fetch nests under it even without zone.js because the subscribe fires synchronously. The second button (`items.load.missing`) fires a request that 404s, which drives the correlated error log shown later. ```typescript title="src/app/items/items.ts" showLineNumbers import { Component, inject, signal } from '@angular/core'; import { HttpClient } from '@angular/common/http'; import { trace, SpanStatusCode } from '@opentelemetry/api'; import { environment } from '../../environments/environment'; interface Item { id: number; name: string; price: string; } @Component({ selector: 'app-items', imports: [], templateUrl: './items.html', styleUrl: './items.css', }) export class Items { private http = inject(HttpClient); items = signal([]); loadItems(): void { const tracer = trace.getTracer('angular-items'); // startActiveSpan makes items.load the active parent; the fetch fired // synchronously on subscribe nests under it even without zone.js. tracer.startActiveSpan('items.load', (span) => { this.http.get(`${environment.apiBaseUrl}/items`).subscribe({ next: (data) => { this.items.set(data); span.end(); }, error: (err) => { span.recordException(err); span.setStatus({ code: SpanStatusCode.ERROR }); span.end(); }, }); }); } // Demo: failing request inside an active span -> interceptor emits a correlated log. triggerApiError(): void { const tracer = trace.getTracer('angular-items'); tracer.startActiveSpan('items.load.missing', (span) => { this.http.get(`${environment.apiBaseUrl}/missing`).subscribe({ next: () => span.end(), error: (err) => { span.recordException(err); span.setStatus({ code: SpanStatusCode.ERROR }); span.end(); }, }); }); } // Demo: uncaught throw -> ErrorHandler emits a best-effort (uncorrelated) log. triggerError(): void { throw new Error('Demo: uncaught error from Items page'); } } ``` #### Core Web Vitals as metrics Record Core Web Vitals as **metric histograms**, one instrument per vital. The `web-vitals` library reports CLS, INP, LCP, FCP, and TTFB through callbacks; each callback records a measurement tagged with the page path and the library's rating (`good` / `needs-improvement` / `poor`). ```typescript title="src/app/telemetry/web-vitals.ts" showLineNumbers import { metrics, type Histogram } from '@opentelemetry/api'; import { onCLS, onFCP, onINP, onLCP, onTTFB, type Metric } from 'web-vitals'; // Web Vitals as histograms (not spans) so RUM can report p75/p95; one instrument // per vital for per-vital bucket Views (see browser-telemetry.ts). export function setupWebVitals(): void { // Acquire after the global MeterProvider is set (else Noop meter, dropped). const meter = metrics.getMeter('web-vitals', '1.0.0'); const cls = meter.createHistogram('web_vitals.cls', { unit: '1', description: 'Cumulative Layout Shift', }); const lcp = meter.createHistogram('web_vitals.lcp', { unit: 'ms', description: 'Largest Contentful Paint', }); const inp = meter.createHistogram('web_vitals.inp', { unit: 'ms', description: 'Interaction to Next Paint', }); const fcp = meter.createHistogram('web_vitals.fcp', { unit: 'ms', description: 'First Contentful Paint', }); const ttfb = meter.createHistogram('web_vitals.ttfb', { unit: 'ms', description: 'Time to First Byte', }); const record = (histogram: Histogram) => (metric: Metric): void => { histogram.record(metric.value, { 'web_vital.rating': metric.rating, 'page.path': window.location.pathname, }); }; onCLS(record(cls)); onLCP(record(lcp)); onINP(record(inp)); onFCP(record(fcp)); onTTFB(record(ttfb)); } ``` Default histogram buckets (0, 5, 10, 25, ...) fit neither a CLS score (roughly 0 to 1) nor millisecond timings, so give each instrument its own bucket boundaries with a `View`. These are the `VITAL_VIEWS` elided from the bootstrap above: ```typescript title="src/app/telemetry/browser-telemetry.ts (VITAL_VIEWS)" const VITAL_VIEWS: ViewOptions[] = [ { instrumentName: 'web_vitals.cls', aggregation: { type: AggregationType.EXPLICIT_BUCKET_HISTOGRAM, options: { boundaries: [0.05, 0.1, 0.15, 0.25, 0.5, 1] }, }, }, { instrumentName: 'web_vitals.lcp', aggregation: { type: AggregationType.EXPLICIT_BUCKET_HISTOGRAM, options: { boundaries: [500, 1000, 1500, 2000, 2500, 3000, 4000, 5000, 7500, 10000] }, }, }, { instrumentName: 'web_vitals.inp', aggregation: { type: AggregationType.EXPLICIT_BUCKET_HISTOGRAM, options: { boundaries: [50, 100, 150, 200, 300, 500, 750, 1000] }, }, }, { instrumentName: 'web_vitals.fcp', aggregation: { type: AggregationType.EXPLICIT_BUCKET_HISTOGRAM, options: { boundaries: [500, 1000, 1500, 1800, 2500, 3000, 4000, 6000] }, }, }, { instrumentName: 'web_vitals.ttfb', aggregation: { type: AggregationType.EXPLICIT_BUCKET_HISTOGRAM, options: { boundaries: [100, 200, 400, 600, 800, 1200, 1800, 3000] }, }, }, ]; ``` ##### Web Vitals: spans vs metrics An earlier version of this example recorded each vital as a short-lived span (`web_vital.lcp`, and so on). That works and puts page performance in the trace stream, but it is the wrong shape for real user monitoring: - **Core Web Vitals are distributions, not events.** Google scores a site at the **p75** of each vital across real sessions. A metric `Histogram` aggregates measurements into buckets in the SDK, so the backend computes p75 and p95 directly; a pile of individual spans has to be aggregated downstream before it means anything. - **Spans are per-event and unbounded.** One span per vital per page view is a lot of zero-duration spans that clutter traces and cost storage, without giving you the percentile view you actually want. - **Bucketing is explicit and cheap.** Per-vital `View` boundaries (a CLS score needs different buckets than an LCP in milliseconds) keep the histogram meaningful and small. Use a **span** (or a span event) when you want a single vital tied to one specific trace for debugging a single session. Use a **metric histogram** - as this example does - for fleet-wide RUM percentiles. The two are not exclusive, but percentiles are the common need, so metrics are the default here. #### Errors as logs Browser errors are emitted as **ERROR logs**, on two paths. Failed HTTP requests go through an `HttpClient` interceptor that captures the active trace context and re-enters it when it emits, so the log carries the trace id of the request that failed. Everything else - uncaught throws, and the global `error` and `unhandledrejection` events - lands in a custom `ErrorHandler`, which emits a best-effort log (usually without a trace id in a zoneless app, because the originating span has already unwound). ```typescript title="src/app/telemetry/error-interceptor.ts" showLineNumbers import { HttpErrorResponse, HttpInterceptorFn } from '@angular/common/http'; import { context } from '@opentelemetry/api'; import { logs, SeverityNumber } from '@opentelemetry/api-logs'; import { catchError, throwError } from 'rxjs'; // Trace-correlated ERROR log for every failed HttpClient request. catchError runs // async, after the zoneless context has unwound, so we capture the context here // (synchronous, caller's span still active) and re-enter it at emit - emit() // stamps the trace id from the active context, so this is what keeps the log // correlated. export const errorLogInterceptor: HttpInterceptorFn = (req, next) => { const activeContext = context.active(); return next(req).pipe( catchError((err: HttpErrorResponse) => { const logger = logs.getLogger('browser-http'); context.with(activeContext, () => { logger.emit({ severityNumber: SeverityNumber.ERROR, severityText: 'ERROR', body: `HTTP ${req.method} ${req.urlWithParams} failed: ${err.status} ${err.message}`, attributes: { 'http.request.method': req.method, 'url.full': req.urlWithParams, 'http.response.status_code': err.status, 'error.type': err.name, }, }); }); return throwError(() => err); }), ); }; ``` ```typescript title="src/app/telemetry/error-handler.ts" showLineNumbers import { ErrorHandler, Injectable } from '@angular/core'; import { logs, SeverityNumber } from '@opentelemetry/api-logs'; // Single capture point for uncaught errors in a zoneless app (Angular errors + // the window error/unhandledrejection events via provideBrowserGlobalErrorListeners). // Correlation is best-effort: the span has usually unwound by the time an error // lands here, so logs may have no trace id. For correlated HTTP-failure logs see // error-interceptor. @Injectable() export class TelemetryErrorHandler implements ErrorHandler { private logger = logs.getLogger('browser-errors'); handleError(error: unknown): void { const err = error instanceof Error ? error : new Error(String(error)); this.logger.emit({ severityNumber: SeverityNumber.ERROR, severityText: 'ERROR', body: err.message, attributes: { 'exception.type': err.name, 'exception.message': err.message, 'exception.stacktrace': err.stack ?? '', 'page.path': window.location.pathname, }, }); console.error(error); } } ``` #### Reading the active trace id To surface the current trace id (for a support widget or a "copy trace id" button), read it from the active span context: ```typescript import { trace } from '@opentelemetry/api'; const span = trace.getActiveSpan(); const traceId = span?.spanContext().traceId; ``` ### Backend Signals The Express API is auto-instrumented with the OpenTelemetry Node SDK, which adds the API leg of every trace plus its own metrics and logs. Two details make the browser and API tell one story: - **Metrics**: enabling a `PeriodicExportingMetricReader` turns on `http.server.request.duration` and runtime metrics automatically. Set `OTEL_SEMCONV_STABILITY_OPT_IN=http` so the metric uses the stable name (`http.server.request.duration`) rather than the deprecated `http.server.duration`. - **Logs**: `pino` records are auto-bridged to OTLP by the Node auto-instrumentations, with `trace_id` and `span_id` injected, so a backend log line links to the exact request span. ```typescript title="backend/src/instrumentation.ts" showLineNumbers import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-proto'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-proto'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-proto'; import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { BatchLogRecordProcessor } from '@opentelemetry/sdk-logs'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION } from '@opentelemetry/semantic-conventions'; const env = process.env.DEPLOY_ENV || 'development'; const base = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; // http.server.request.duration + runtime-node metrics and pino log-bridging are // automatic once a reader/processor exists. Stable metric name needs // OTEL_SEMCONV_STABILITY_OPT_IN=http (compose.yaml). const sdk = new NodeSDK({ resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: 'angular-items-api', [ATTR_SERVICE_VERSION]: '1.0.0', 'deployment.environment.name': env, environment: env, }), traceExporter: new OTLPTraceExporter({ url: `${base}/v1/traces` }), metricReaders: [ new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${base}/v1/metrics` }), exportIntervalMillis: 10000, }), ], logRecordProcessors: [ new BatchLogRecordProcessor(new OTLPLogExporter({ url: `${base}/v1/logs` })), ], instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-runtime-node': { enabled: true }, }), ], }); sdk.start(); ``` Preload the SDK with `node -r ./dist/instrumentation.js ./dist/server.js` so it patches Express, `pg`, and `pino` before they are imported. The API must also allow the `traceparent` and `tracestate` request headers so the browser's trace context survives the cross-origin call: ```typescript title="backend/src/server.ts" showLineNumbers import express from 'express'; import cors from 'cors'; import pino from 'pino'; import { pool } from './db'; const app = express(); // Auto-bridged + trace-correlated by instrumentation-pino (via the -r preload). const log = pino(); // allowedHeaders must include traceparent/tracestate so the browser fetch can // propagate trace context and stay in one trace with the server span. app.use( cors({ origin: ['http://localhost:4200', 'http://localhost:8080'], allowedHeaders: ['Content-Type', 'traceparent', 'tracestate'], }), ); app.get('/api/items', async (_req, res) => { const { rows } = await pool.query('SELECT id, name, price FROM items ORDER BY id'); log.info({ count: rows.length }, 'served items'); res.json(rows); }); app.get('/healthz', (_req, res) => { res.json({ ok: true }); }); const port = Number(process.env.PORT || 3000); app.listen(port, () => log.info(`angular-items-api listening on :${port}`)); ``` ### Running Your Application #### Development Run the collector and API (see the example's `compose.yaml`), then start the Angular dev server: ```bash ng serve ``` Open `http://localhost:4200`, interact with the page, and watch signals arrive at the collector. The dev origin (`http://localhost:4200`) must be in the collector's CORS allow-list and the API's CORS policy. #### Full stack with Docker Compose ```bash docker compose up --build ``` Open `http://localhost:8080/items`, click **Load items**, navigate between routes, and click **Trigger API error** and **Trigger error**. #### Expected span tree A single "Load items" click produces one trace across three services: ```text click (angular-browser) (user-interaction instrumentation) └─ items.load (manual span in loadItems()) └─ HTTP GET http://localhost:3000/api/items (browser fetch instrumentation) └─ GET /api/items (angular-items-api, Express) └─ pg.query:SELECT items (Postgres) ``` #### Verifying in the collector With the collector's `debug` exporter on, the browser fetch span and the backend spans share one trace id: ```text Span #0 Trace ID : 5d6d4c8814af19ee... Name : HTTP GET -> http.url: Str(http://localhost:3000/api/items) -> service.name: Str(angular-browser) Span #1 Trace ID : 5d6d4c8814af19ee... Name : GET /api/items -> service.name: Str(angular-items-api) Span #2 Trace ID : 5d6d4c8814af19ee... Name : pg.query:SELECT items ``` Alongside the traces you should see: - **Metrics**: `web_vitals.{cls,fcp,lcp,ttfb}` histograms from the browser (INP needs a real measured interaction, so it may not appear under a scripted drive), plus `http.server.request.duration` and `runtime.node.*` from the backend. - **Logs**: the backend `served items` `pino` record carrying `trace_id` / `span_id`; a browser interceptor ERROR log with a non-zero trace id after **Trigger API error**; and an `ErrorHandler` ERROR log (best-effort, no trace id) after **Trigger error**. - One `router.navigation` span per client-side route change. ### Troubleshooting #### The browser span and the API span are in different traces The `traceparent` header is not making it to the API. This needs two fixes, because CORS is involved in both directions: 1. **SDK side**: add the API origin to `propagateTraceHeaderCorsUrls` on the fetch and XHR instrumentations. Without it, OpenTelemetry will not inject `traceparent` on cross-origin requests. 2. **API side**: allow the `traceparent` and `tracestate` request headers in the API's CORS policy. If the API does not echo them back as allowed headers, the browser strips them before the request leaves. ```typescript title="backend CORS (Express example)" app.use(cors({ origin: ['http://localhost:4200', 'http://localhost:8080'], allowedHeaders: ['Content-Type', 'traceparent', 'tracestate'], })); ``` #### Backend-only OPTIONS traces with no browser parent Because the SPA (`:8080`) and API (`:3000`) are cross-origin, every API call fires a CORS **preflight `OPTIONS`** first, and browsers do not allow custom headers such as `traceparent` on a preflight. Each preflight therefore starts its own backend-only trace with no browser parent. This is expected: the actual `GET`/`POST` request carries the `traceparent` and links the browser to the API. If a trace looks "browser-less", check that you are looking at the real request, not its `OPTIONS` preflight (or a browser-only trace such as `documentLoad`). #### No metrics or logs reach the collector Traces call `provider.register()`, which sets the global tracer, but metrics and logs have no such sugar. If you skip `metrics.setGlobalMeterProvider()` or `logs.setGlobalLoggerProvider()`, then `getMeter()` / `getLogger()` return a No-op implementation and every measurement or log is silently dropped - no error, just nothing. Set both globals during bootstrap, and acquire meters and loggers **after** that (as `setupWebVitals()` does). #### A deferred interaction span does not parent its async fetch (zoneless) A synchronous fetch nests fine without zone.js (see the span tree above). But if the request is issued after an async gap - a `setTimeout`, a later microtask, or an `await` before the call - the active-context link is lost in zoneless mode and the fetch starts a new root. If you need that deferred work parented, either wrap it in a manual `startActiveSpan` (as the `items.load` example does) or opt into `ZoneContextManager`. The distributed link to the API is unaffected either way. #### No spans at all, or the document-load span is missing `initBrowserTelemetry()` is not running early enough, or not at all. Confirm it is called in `main.ts` **before** `bootstrapApplication`. If only the document-load span is missing, the SDK is starting after the page has already loaded - move the call ahead of bootstrap. #### Signals are created but never reach the collector Check the collector's OTLP HTTP receiver CORS. A browser preflight (`OPTIONS`) that the collector rejects shows up as a CORS error in the browser console and nothing in the collector. Add the SPA origin to `allowed_origins`, confirm `otelCollectorUrl` points at the collector's `:4318` endpoint (the exporters append `/v1/traces`, `/v1/metrics`, `/v1/logs`), and confirm the collector has a pipeline for each signal. ### Security Considerations - **No PII in span attributes, metric labels, or log bodies**: browser telemetry is visible to anyone with collector access. Do not put emails, tokens, or session ids into attributes, and avoid query strings that carry secrets in `http.url` or `url.full`. - **Scope CORS origins**: list exact SPA origins in the collector receiver and the API. Never use `*` for `allowed_origins` in production - it lets any site post telemetry to your collector. - **Scope trace propagation**: keep `propagateTraceHeaderCorsUrls` limited to your own API origins so the `traceparent` header is never sent to third-party domains. - **Header filtering**: if you add request/response headers to spans, allow-list the safe ones rather than capturing everything (avoid `authorization`, `cookie`, `set-cookie`). - **Transport security**: serve the collector endpoint over HTTPS in production so telemetry is encrypted in transit. ### Performance Considerations - **Runtime overhead**: span creation and histogram recording are cheap (object allocation plus a timestamp). Every signal exports off the interaction path - spans and logs through batch processors, metrics through a periodic reader (10 s here) - so user-facing latency is unaffected. - **Batch tuning**: raise the span processor's `maxQueueSize` and `maxExportBatchSize` for chatty UIs so interaction-span bursts are not dropped; lower a flush interval if you want data to appear sooner while debugging. - **What not to span**: avoid creating a span per animation frame, scroll event, or mousemove. Restrict `instrumentation-user-interaction` to meaningful events (`click`, `submit`) as the example does. - **Web Vitals cost**: the `web-vitals` callbacks fire a handful of times per page, and each records a single histogram measurement - negligible. ### FAQ #### Does OpenTelemetry work with zoneless Angular? Yes. Angular 21 and later are zoneless by default. Register the `WebTracerProvider` with the default `StackContextManager` by calling `provider.register()` with no arguments. The browser-to-API trace links through the `traceparent` header, which is independent of the context manager, so distributed tracing works the same with or without zone.js. #### Do I need zone.js for OpenTelemetry in Angular? No. zone.js is optional in modern Angular. You only need the `ZoneContextManager` (and zone.js) if you want an interaction's asynchronous work nested under the interaction span inside the browser. Distributed tracing to your API and database works without zone.js. #### Why is my Angular browser span in a different trace than my API span? The `traceparent` header is not reaching your API. Either the request URL is not in `propagateTraceHeaderCorsUrls` (so the header is not injected), or the API's CORS policy does not allow the `traceparent` and `tracestate` headers (so the browser strips them). Fix both. If instead you are looking at a lone backend `OPTIONS` trace, that is the CORS preflight - preflights cannot carry `traceparent`, so the real request is the one that links. #### Should I record Core Web Vitals as spans or metrics in Angular? Record them as metric histograms. Core Web Vitals are fleet-wide distributions (Google scores at p75), and a `Histogram` aggregates into buckets so the backend computes p75 and p95 without storing every event. A short-lived span per vital is fine for debugging a single session but does not aggregate into percentiles, so metrics are the better fit for real user monitoring. #### How do I trace Angular route changes? The web auto-instrumentations do not cover Angular's Router. Subscribe to `Router.events`, filter for `NavigationEnd`, and emit a span per navigation with the resolved route path as an attribute. #### How do I capture uncaught Angular errors with OpenTelemetry? Emit them as ERROR logs. Provide a custom `ErrorHandler` that calls `logger.emit` with `SeverityNumber.ERROR`; `provideBrowserGlobalErrorListeners()` forwards the window `error` and `unhandledrejection` events into it, so a plain `window.onerror` listener misses framework-intercepted errors. For failed HTTP requests, an `HttpClient` interceptor emits a log that carries the active trace id. #### Why are my Angular browser metrics or logs missing? Traces call `provider.register()`, which sets the global tracer, but metrics and logs have no such sugar. Call `metrics.setGlobalMeterProvider()` and `logs.setGlobalLoggerProvider()` during bootstrap. Without the global set, `getMeter()` and `getLogger()` return a No-op implementation and every data point is silently dropped. #### Where do I initialize the browser SDK in Angular? In `main.ts`, before `bootstrapApplication`, so the document-load span and early interactions are captured. Wire router tracing from the root component constructor, because the Router is only available through dependency injection. #### Does Angular HttpClient go through the OpenTelemetry fetch instrumentation? Yes. In Angular 22, `fetch` is the default `HttpClient` backend and `withFetch()` is deprecated, so HttpClient requests run through `fetch()` and are captured by `instrumentation-fetch`, which also injects `traceparent`. #### How do I send Angular browser telemetry to a collector on another origin? The browser posts OTLP over HTTP directly from the SPA origin, so the collector's OTLP HTTP receiver must allow that origin via CORS. Add every origin the SPA is served from to the receiver's `allowed_origins` list. #### Can I use Core Web Vitals with OpenTelemetry in Angular? Yes. The `web-vitals` library reports CLS, INP, LCP, FCP, and TTFB through callbacks. Record each as a `Histogram` measurement when its callback fires, tagged with the page path and rating, so page performance aggregates into p75 and p95 alongside your request traces. ### What's Next? - Add custom metrics (interaction counters, feature-usage rates) alongside the Web Vitals histograms. - Instrument additional interactions (`submit`, custom events) and forms. - Enrich browser error logs with release/version attributes for triage. - Roll the same three-signal pattern out to other front-end apps for consistent RUM. ### Complete Example The full project - Angular 22 SPA, Express + Postgres API, and a pre-configured collector - is available at [base-14/examples/nodejs/angular-fullstack-otel](https://github.com/base-14/examples/tree/main/nodejs/angular-fullstack-otel). ```text angular-fullstack-otel/ ├── compose.yaml ├── config/otel-config.yaml # collector: OTLP-in (CORS), traces+metrics+logs ├── backend/ # Express 5 + Postgres, Node OTel SDK │ ├── src/instrumentation.ts # NodeSDK: traces + metrics + logs │ ├── src/server.ts # API + pino logging │ └── schema.sql └── frontend/ # Angular 22 SPA ├── src/app/telemetry/ │ ├── browser-telemetry.ts # bootstrap: tracer + meter + logger providers │ ├── router-tracing.ts # NavigationEnd -> span │ ├── error-handler.ts # ErrorHandler -> best-effort ERROR log │ ├── error-interceptor.ts # HttpClient failure -> correlated ERROR log │ └── web-vitals.ts # Core Web Vitals -> metric histograms ├── Dockerfile └── nginx.conf ``` Run it: ```bash git clone https://github.com/base-14/examples cd examples/nodejs/angular-fullstack-otel docker compose up --build # open http://localhost:8080/items ``` base14 Scout turns these browser-to-database traces, Web Vitals, and correlated logs into [end-to-end application performance monitoring](https://base14.io/scout/apm) without locking you into a single vendor's agent. ### References - [OpenTelemetry JavaScript](https://opentelemetry.io/docs/languages/js/) - [OpenTelemetry browser instrumentation](https://opentelemetry.io/docs/languages/js/getting-started/browser/) - [auto-instrumentations-web](https://www.npmjs.com/package/@opentelemetry/auto-instrumentations-web) - [web-vitals](https://github.com/GoogleChrome/web-vitals) - [Angular zoneless guide](https://angular.dev/guide/zoneless) - [W3C Trace Context](https://www.w3.org/TR/trace-context/) ### Related Guides - [React browser instrumentation](./react.md) - full browser RUM powered by the Scout React SDK. - [Next.js instrumentation](./nextjs-scout.md) - server and client tracing for a full-stack React framework. - [Next.js full-stack instrumentation](./nextjs-fullstack.md) - browser and server in one trace across all three signals, with browser OTLP routed through a same-origin API route instead of collector CORS. - [Express instrumentation](./express.md) - the API tier that receives the propagated trace context. - [Node.js instrumentation](./nodejs.md) - the Node SDK behind the backend in this guide. --- ## Axum OpenTelemetry Instrumentation - Complete APM Setup Guide ## Axum Implement OpenTelemetry instrumentation for Rust Axum applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to instrument your Axum application to collect traces, metrics, and logs from HTTP requests, database queries, background jobs, and custom business logic using the OpenTelemetry Rust SDK. Axum is a Tokio-based async Rust web framework. [Actix Web](./actix-web.md) is the other widely used Rust option. Rust applications built with Axum benefit from the powerful `tracing` ecosystem combined with OpenTelemetry exporters. With the `tracing-opentelemetry` crate, you can automatically capture spans from your application, monitor SQLx database queries, trace distributed transactions across microservices, and identify performance bottlenecks with minimal runtime overhead. Whether you're implementing observability for the first time, migrating from other monitoring solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Rust Axum OpenTelemetry instrumentation. :::tip TL;DR Add `tower-http` TraceLayer with `tracing-opentelemetry` to export spans via OTLP. SQLx queries and HTTP requests are traced automatically through tower middleware. Use `BatchSpanProcessor` for production and export to base14 Scout via the OpenTelemetry Collector. ::: > **Note:** This guide provides a practical Axum-focused overview based on the > official OpenTelemetry documentation. For complete Rust language information, > please consult the > [official OpenTelemetry Rust documentation](https://opentelemetry.io/docs/languages/rust/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Rust developers:** implementing observability and distributed tracing for Axum web applications - **DevOps engineers:** deploying Rust applications with production monitoring requirements - **Engineering teams:** migrating from other APM solutions to OpenTelemetry - **Developers:** debugging performance issues, slow database queries, or async runtime problems - **Platform teams:** standardizing observability across multiple Rust services ### Overview This comprehensive guide demonstrates how to: - Install and configure OpenTelemetry SDK for Axum applications - Set up tracing with `tracing-opentelemetry` for automatic span collection - Configure OTLP export for traces, metrics, and logs to Scout Collector - Implement custom instrumentation for business-critical operations - Monitor SQLx database queries and connection pools - Deploy instrumented Axum applications to development, staging, and production environments - Troubleshoot common instrumentation issues and optimize performance - Secure sensitive data in telemetry exports ### Prerequisites Before starting, ensure you have: - **Rust 1.80 or later** (stable toolchain recommended) - For best performance and compatibility, Rust 1.92+ is recommended - Edition 2021 or 2024 required - **Axum 0.7 or later** web framework - Axum 0.8.8+ is recommended for optimal OpenTelemetry support - **Cargo** for dependency management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Production deployments should use a dedicated Scout Collector instance - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | --------------------- | --------------- | ------------------- | | Rust | 1.80.0 | 1.92.0+ | | Axum | 0.7.0 | 0.8.8+ | | OpenTelemetry | 0.27.0 | 0.32+ | | tracing-opentelemetry | 0.28.0 | 0.33+ | | SQLx | 0.7.0 | 0.8.6+ | ### Required Packages Add the following dependencies to your `Cargo.toml`: ```toml showLineNumbers title="Cargo.toml" [dependencies] # Web Framework axum = { version = "0.8.8", features = ["macros"] } tower = { version = "0.5.2", features = ["full"] } tower-http = { version = "0.6.8", features = ["trace", "cors", "timeout", "request-id"] } # Async Runtime tokio = { version = "1.49", features = ["full", "tracing"] } # Database (optional) sqlx = { version = "0.8.6", features = ["runtime-tokio", "postgres", "macros"] } # OpenTelemetry opentelemetry = "0.32" opentelemetry_sdk = { version = "0.32", features = ["rt-tokio", "logs"] } opentelemetry-otlp = { version = "0.32", features = ["grpc-tonic", "trace", "logs"] } opentelemetry-appender-tracing = "0.32" # Tracing tracing = "0.1" tracing-subscriber = { version = "0.3", features = ["env-filter", "json"] } tracing-opentelemetry = "0.33" # Serialization serde = { version = "1.0", features = ["derive"] } serde_json = "1.0" ``` ### Configuration OpenTelemetry Rust instrumentation can be configured using multiple approaches depending on your deployment requirements and preferences. Choose the method that best fits your application architecture. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The recommended approach is to create a dedicated telemetry module. This provides the most flexibility and keeps configuration separate from your application bootstrap. ```rust showLineNumbers title="src/telemetry/init.rs" use std::time::Duration; use opentelemetry::KeyValue; use opentelemetry::global; use opentelemetry_appender_tracing::layer::OpenTelemetryTracingBridge; use opentelemetry_otlp::WithExportConfig; use opentelemetry_sdk::{Resource, logs::SdkLoggerProvider, trace::SdkTracerProvider}; use tracing_opentelemetry::OpenTelemetryLayer; use tracing_subscriber::{EnvFilter, Layer, layer::SubscriberExt, util::SubscriberInitExt}; pub struct TelemetryGuard { pub tracer_provider: SdkTracerProvider, pub logger_provider: SdkLoggerProvider, } impl TelemetryGuard { pub fn shutdown(&self) { if let Err(e) = self.tracer_provider.shutdown() { eprintln!("Error shutting down tracer provider: {e}"); } if let Err(e) = self.logger_provider.shutdown() { eprintln!("Error shutting down logger provider: {e}"); } } } pub fn init_telemetry(service_name: &str, otlp_endpoint: &str) -> anyhow::Result { let resource = Resource::builder() .with_service_name(service_name.to_string()) .with_attribute(KeyValue::new("service.version", "1.0.0")) .with_attribute(KeyValue::new("service.namespace", "production")) .with_attribute(KeyValue::new("deployment.environment", "production")) .with_attribute(KeyValue::new("environment", "production")) .build(); // Configure trace exporter let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(otlp_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .with_resource(resource.clone()) .build(); global::set_tracer_provider(tracer_provider.clone()); // Configure log exporter let log_exporter = opentelemetry_otlp::LogExporter::builder() .with_tonic() .with_endpoint(otlp_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let logger_provider = SdkLoggerProvider::builder() .with_batch_exporter(log_exporter) .with_resource(resource) .build(); // Bridge tracing logs to OpenTelemetry let otel_log_layer = OpenTelemetryTracingBridge::new(&logger_provider); // Create OpenTelemetry tracing layer let tracer = global::tracer(service_name.to_string()); let telemetry_layer = OpenTelemetryLayer::new(tracer); // Configure environment filter let env_filter = EnvFilter::try_from_default_env() .unwrap_or_else(|_| EnvFilter::new("info,sqlx=warn,tower_http=debug")); // Initialize subscriber tracing_subscriber::registry() .with(env_filter) .with(telemetry_layer) .with(otel_log_layer) .with(tracing_subscriber::fmt::layer()) .init(); tracing::info!( service = %service_name, endpoint = %otlp_endpoint, "Telemetry initialized with OTLP trace and log export" ); Ok(TelemetryGuard { tracer_provider, logger_provider, }) } ``` ```mdx-code-block ``` For containerized deployments or environments where configuration is managed externally, you can rely on environment variables: ```rust showLineNumbers title="src/telemetry/init.rs" use std::env; pub fn init_telemetry_from_env() -> anyhow::Result { let service_name = env::var("OTEL_SERVICE_NAME") .unwrap_or_else(|_| "rust-axum-app".to_string()); let otlp_endpoint = env::var("OTEL_EXPORTER_OTLP_ENDPOINT") .unwrap_or_else(|_| "http://localhost:4317".to_string()); init_telemetry(&service_name, &otlp_endpoint) } ``` With this configuration, use environment variables to control behavior: ```bash showLineNumbers export OTEL_SERVICE_NAME=rust-axum-app export OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 export RUST_LOG=info,sqlx=warn,tower_http=debug ``` ```mdx-code-block ``` For applications using a configuration struct pattern: ```rust showLineNumbers title="src/config.rs" use serde::Deserialize; #[derive(Debug, Clone, Deserialize)] pub struct Config { #[serde(default = "default_port")] pub port: u16, #[serde(default = "default_environment")] pub environment: String, #[serde(default = "default_service_name")] pub otel_service_name: String, #[serde(default = "default_otel_endpoint")] pub otel_exporter_endpoint: String, pub database_url: String, } fn default_port() -> u16 { 8080 } fn default_environment() -> String { "development".to_string() } fn default_service_name() -> String { "rust-axum-app".to_string() } fn default_otel_endpoint() -> String { "http://localhost:4317".to_string() } impl Config { pub fn from_env() -> Self { dotenvy::dotenv().ok(); envy::from_env().expect("Failed to load config from environment") } pub fn is_production(&self) -> bool { self.environment == "production" } } ``` ```mdx-code-block ``` #### Configuring Tower HTTP Tracing Layer Add the Tower HTTP tracing layer to your Axum router for automatic HTTP request instrumentation: ```rust showLineNumbers title="src/main.rs" use std::time::Duration; use axum::http::{Request, Response}; use tower_http::trace::{MakeSpan, OnResponse, TraceLayer}; use tracing::Span; #[derive(Clone)] struct HttpMakeSpan; impl MakeSpan for HttpMakeSpan { fn make_span(&mut self, request: &Request) -> Span { let method = request.method().as_str(); let path = request.uri().path(); tracing::info_span!( "HTTP request", otel.name = %format!("{} {}", method, path), http.method = %method, http.route = %path, http.target = %request.uri(), http.scheme = "http", http.response.status_code = tracing::field::Empty, otel.status_code = tracing::field::Empty, ) } } #[derive(Clone)] struct HttpOnResponse; impl OnResponse for HttpOnResponse { fn on_response(self, response: &Response, latency: Duration, span: &Span) { let status = response.status().as_u16(); span.record("http.response.status_code", status as i64); if status >= 500 { span.record("otel.status_code", "ERROR"); } else { span.record("otel.status_code", "OK"); } tracing::info!( http.response.status_code = status, latency_ms = latency.as_secs_f64() * 1000.0, "finished processing request" ); } } ``` #### Scout Collector Integration When using Scout Collector, configure your Axum application to send telemetry data to the Scout Collector endpoint: ```rust showLineNumbers title="src/telemetry/init.rs" pub fn init_telemetry_with_scout( service_name: &str, scout_endpoint: &str, scout_api_key: Option<&str>, ) -> anyhow::Result { let mut headers = tonic::metadata::MetadataMap::new(); if let Some(api_key) = scout_api_key { headers.insert("x-scout-api-key", api_key.parse()?); } let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(scout_endpoint) .with_metadata(headers.clone()) .with_timeout(Duration::from_secs(10)) .build()?; // ... rest of configuration } ``` > **Scout Dashboard Integration**: After configuration, your traces will appear > in the Scout Dashboard. Navigate to the Traces section to view request flows, > identify performance bottlenecks, and analyze distributed transactions across > your Rust services. ### Production Configuration Production deployments require additional configuration for optimal performance, reliability, and resource utilization. This section covers production-specific settings and best practices. #### Batch Span Processor (Default for Production) The `BatchSpanProcessor` is used by default when calling `with_batch_exporter`: ```rust showLineNumbers title="src/telemetry/init.rs" use opentelemetry_sdk::trace::{BatchConfigBuilder, SdkTracerProvider}; pub fn init_production_telemetry( service_name: &str, otlp_endpoint: &str, ) -> anyhow::Result { let resource = Resource::builder() .with_service_name(service_name.to_string()) .with_attribute(KeyValue::new("service.version", env!("CARGO_PKG_VERSION"))) .with_attribute(KeyValue::new("deployment.environment", "production")) .with_attribute(KeyValue::new("environment", "production")) .build(); let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(otlp_endpoint) .with_timeout(Duration::from_secs(30)) .build()?; // Configure batch processor for production let batch_config = BatchConfigBuilder::default() .with_max_queue_size(2048) .with_scheduled_delay(Duration::from_secs(5)) .with_max_export_batch_size(512) .build(); let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .with_resource(resource) .build(); global::set_tracer_provider(tracer_provider.clone()); // ... rest of configuration } ``` **Benefits of BatchSpanProcessor:** - Reduces network requests by batching span exports - Lower CPU overhead compared to immediate export - Prevents network saturation during traffic spikes - Configurable batching for optimal throughput #### Resource Attributes Add rich context to all telemetry data with resource attributes: ```rust showLineNumbers title="src/telemetry/init.rs" use std::net::IpAddr; fn build_resource(service_name: &str, environment: &str) -> Resource { let hostname = hostname::get() .map(|h| h.to_string_lossy().to_string()) .unwrap_or_else(|_| "unknown".to_string()); Resource::builder() .with_service_name(service_name.to_string()) .with_attribute(KeyValue::new("service.version", env!("CARGO_PKG_VERSION"))) .with_attribute(KeyValue::new("service.namespace", "production")) .with_attribute(KeyValue::new("deployment.environment", environment.to_string())) .with_attribute(KeyValue::new("environment", environment.to_string())) .with_attribute(KeyValue::new("host.name", hostname)) .with_attribute(KeyValue::new( "process.runtime.name", "rustc".to_string() )) .with_attribute(KeyValue::new( "process.runtime.version", env!("CARGO_PKG_RUST_VERSION") )) .build() } ``` #### Environment-Based Configuration Use environment variables to manage configuration across deployments: ```rust showLineNumbers title="src/telemetry/init.rs" pub fn init_telemetry(config: &Config) -> anyhow::Result { let resource = build_resource(&config.otel_service_name, &config.environment); let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(&config.otel_exporter_endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .with_resource(resource.clone()) .build(); global::set_tracer_provider(tracer_provider.clone()); // Configure format layer based on environment let env_filter = EnvFilter::try_from_default_env() .unwrap_or_else(|_| EnvFilter::new("info,sqlx=warn,tower_http=debug")); let fmt_layer = if config.is_production() { tracing_subscriber::fmt::layer().json().boxed() } else { tracing_subscriber::fmt::layer().pretty().boxed() }; // ... rest of configuration } ``` #### Production Environment Variables Create a production environment configuration: ```bash showLineNumbers title=".env.production" # Service Configuration OTEL_SERVICE_NAME=rust-axum-app RUST_LOG=info,sqlx=warn,tower_http=info # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4317 SCOUT_API_KEY=your-scout-api-key # Application Settings PORT=8080 ENVIRONMENT=production DATABASE_URL=postgres://user:pass@db:5432/production ``` #### Docker Production Configuration For containerized Axum applications, configure OpenTelemetry in your Docker setup: ```dockerfile showLineNumbers title="Dockerfile" # Build stage FROM rust:1.80-alpine AS builder WORKDIR /app RUN apk add --no-cache musl-dev openssl-dev pkgconfig # Copy dependency files first for caching COPY Cargo.toml Cargo.lock ./ # Create dummy source to build dependencies RUN mkdir src && \ echo "fn main() {}" > src/main.rs # Build dependencies only RUN cargo build --release 2>/dev/null || true # Remove dummy source and copy actual source RUN rm -rf src COPY src ./src # Build the actual application RUN touch src/main.rs && cargo build --release # Runtime stage FROM alpine:3.21 WORKDIR /app RUN apk add --no-cache ca-certificates tzdata && \ adduser -D -g '' -u 1001 appuser COPY --from=builder /app/target/release/api . USER appuser ENV OTEL_SERVICE_NAME=rust-axum-app ENV OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 EXPOSE 8080 CMD ["./api"] ``` ```yaml showLineNumbers title="docker-compose.yml" services: rust-app: build: . environment: OTEL_SERVICE_NAME: rust-axum-app OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4317 DATABASE_URL: postgres://user:pass@postgres:5432/production RUST_LOG: info,sqlx=warn depends_on: - postgres - scout-collector ports: - "8080:8080" scout-collector: image: base14/scout-collector:latest ports: - "4317:4317" - "4318:4318" postgres: image: postgres:16-alpine environment: POSTGRES_PASSWORD: password ``` ### Metrics In addition to traces, OpenTelemetry can collect metrics from your Axum application to monitor resource utilization, request rates, error counts, and custom business metrics. #### Defining Custom Metrics Create a metrics module with static metric definitions: ```rust showLineNumbers title="src/telemetry/metrics.rs" use std::sync::LazyLock; use opentelemetry::{ global, metrics::{Counter, Histogram, Meter}, }; pub static METER: LazyLock = LazyLock::new(|| global::meter("rust-axum-app")); pub static HTTP_REQUESTS_TOTAL: LazyLock> = LazyLock::new(|| { METER .u64_counter("http.requests.total") .with_description("Total number of HTTP requests") .with_unit("{request}") .build() }); pub static HTTP_REQUEST_DURATION: LazyLock> = LazyLock::new(|| { METER .f64_histogram("http.request.duration") .with_description("HTTP request duration in milliseconds") .with_unit("ms") .with_boundaries(vec![ 1.0, 5.0, 10.0, 25.0, 50.0, 100.0, 250.0, 500.0, 1000.0, 2500.0, 5000.0, ]) .build() }); pub static ARTICLES_CREATED: LazyLock> = LazyLock::new(|| { METER .u64_counter("articles.created") .with_description("Total articles created") .build() }); pub static USERS_REGISTERED: LazyLock> = LazyLock::new(|| { METER .u64_counter("users.registered") .with_description("Total users registered") .build() }); ``` #### Recording HTTP Metrics Record metrics in your Tower HTTP response handler: ```rust showLineNumbers title="src/main.rs" use crate::telemetry::{HTTP_REQUESTS_TOTAL, HTTP_REQUEST_DURATION}; use opentelemetry::KeyValue; impl OnResponse for HttpOnResponse { fn on_response(self, response: &Response, latency: Duration, span: &Span) { let status = response.status().as_u16(); let latency_ms = latency.as_secs_f64() * 1000.0; let status_class = format!("{}xx", status / 100); // Record metrics HTTP_REQUESTS_TOTAL.add( 1, &[ KeyValue::new("http.status_code", status.to_string()), KeyValue::new("http.status_class", status_class.clone()), ], ); HTTP_REQUEST_DURATION.record( latency_ms, &[ KeyValue::new("http.status_code", status.to_string()), KeyValue::new("http.status_class", status_class), ], ); span.record("http.response.status_code", status as i64); if status >= 500 { span.record("otel.status_code", "ERROR"); } else { span.record("otel.status_code", "OK"); } } } ``` #### Custom Business Metrics Track business-specific events and KPIs: ```rust showLineNumbers title="src/services/article.rs" use crate::telemetry::{ARTICLES_CREATED, ARTICLES_DELETED}; impl ArticleService { pub async fn create(&self, author_id: i32, input: CreateArticleInput) -> AppResult
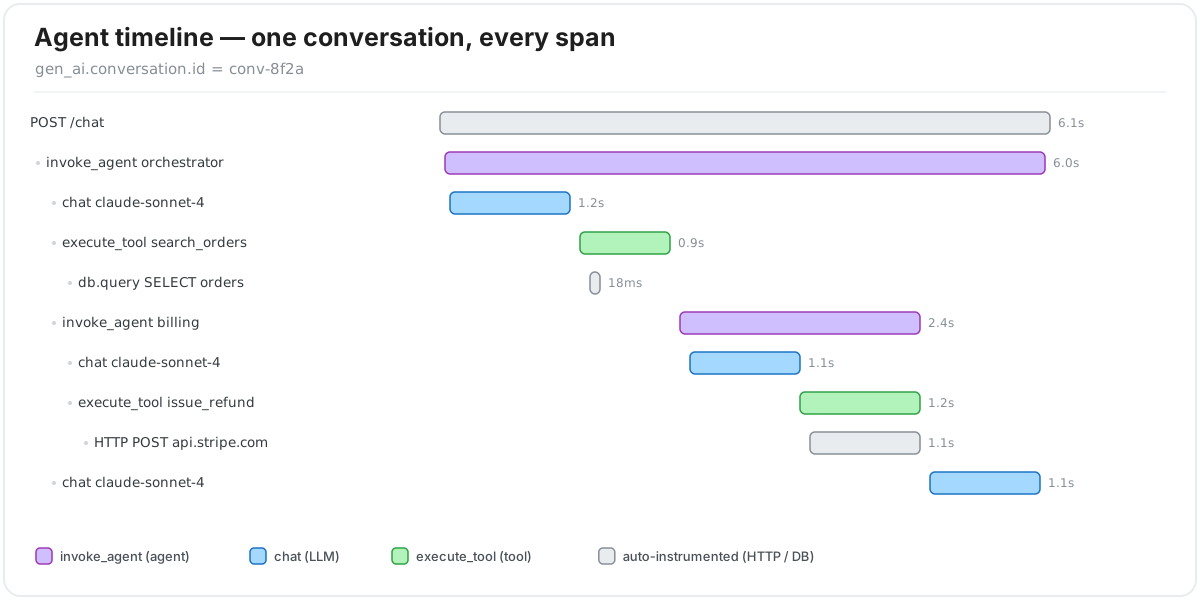
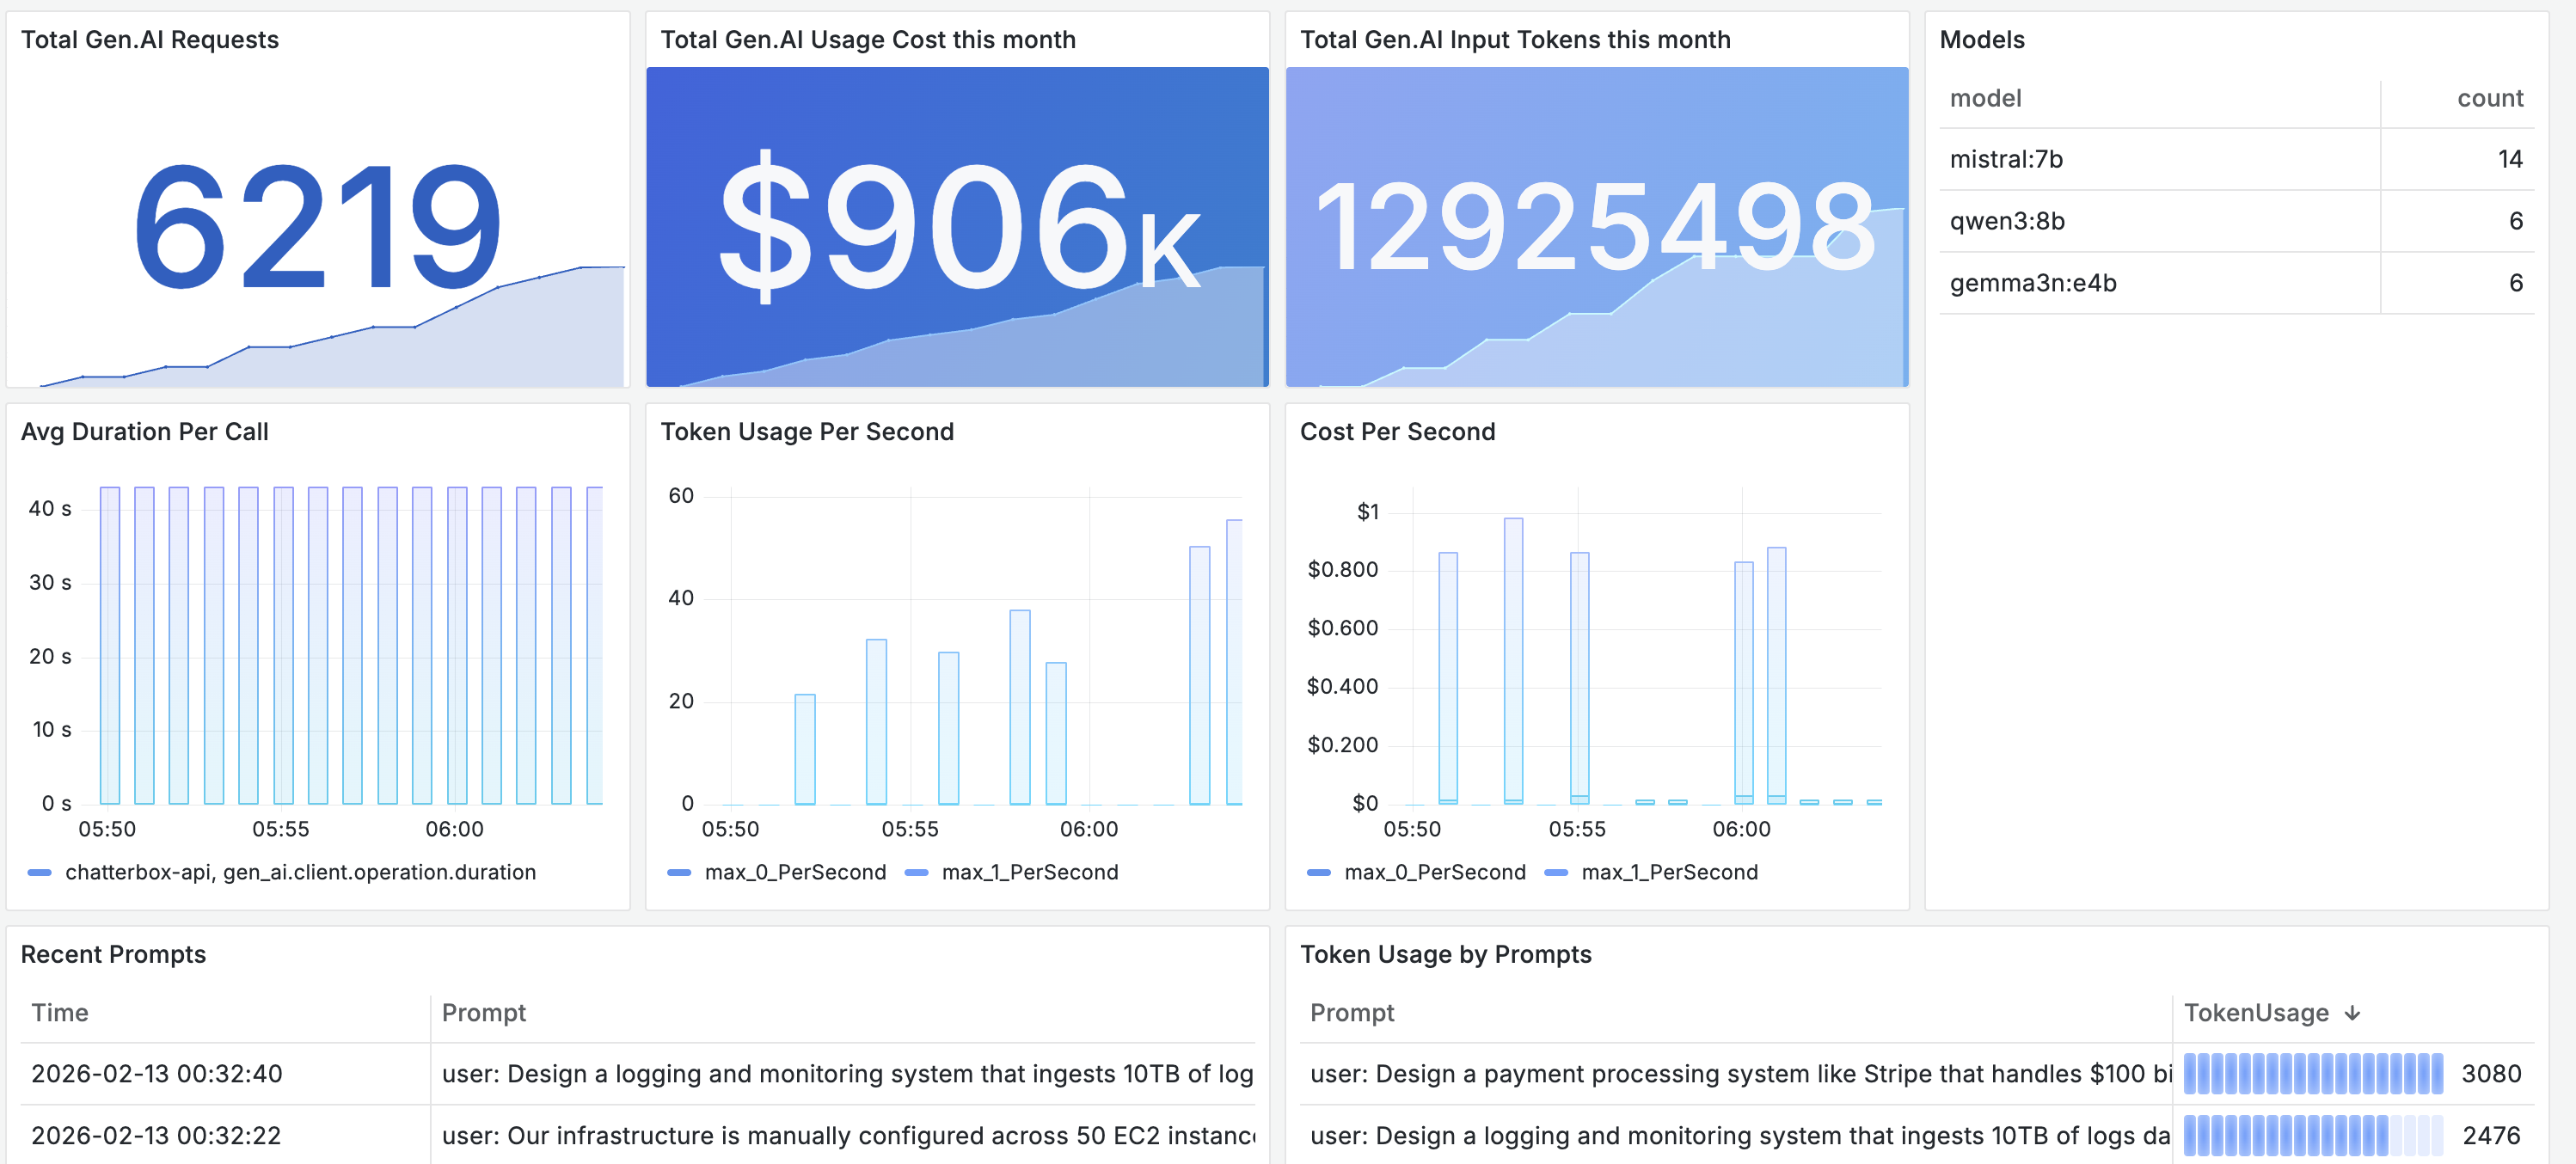
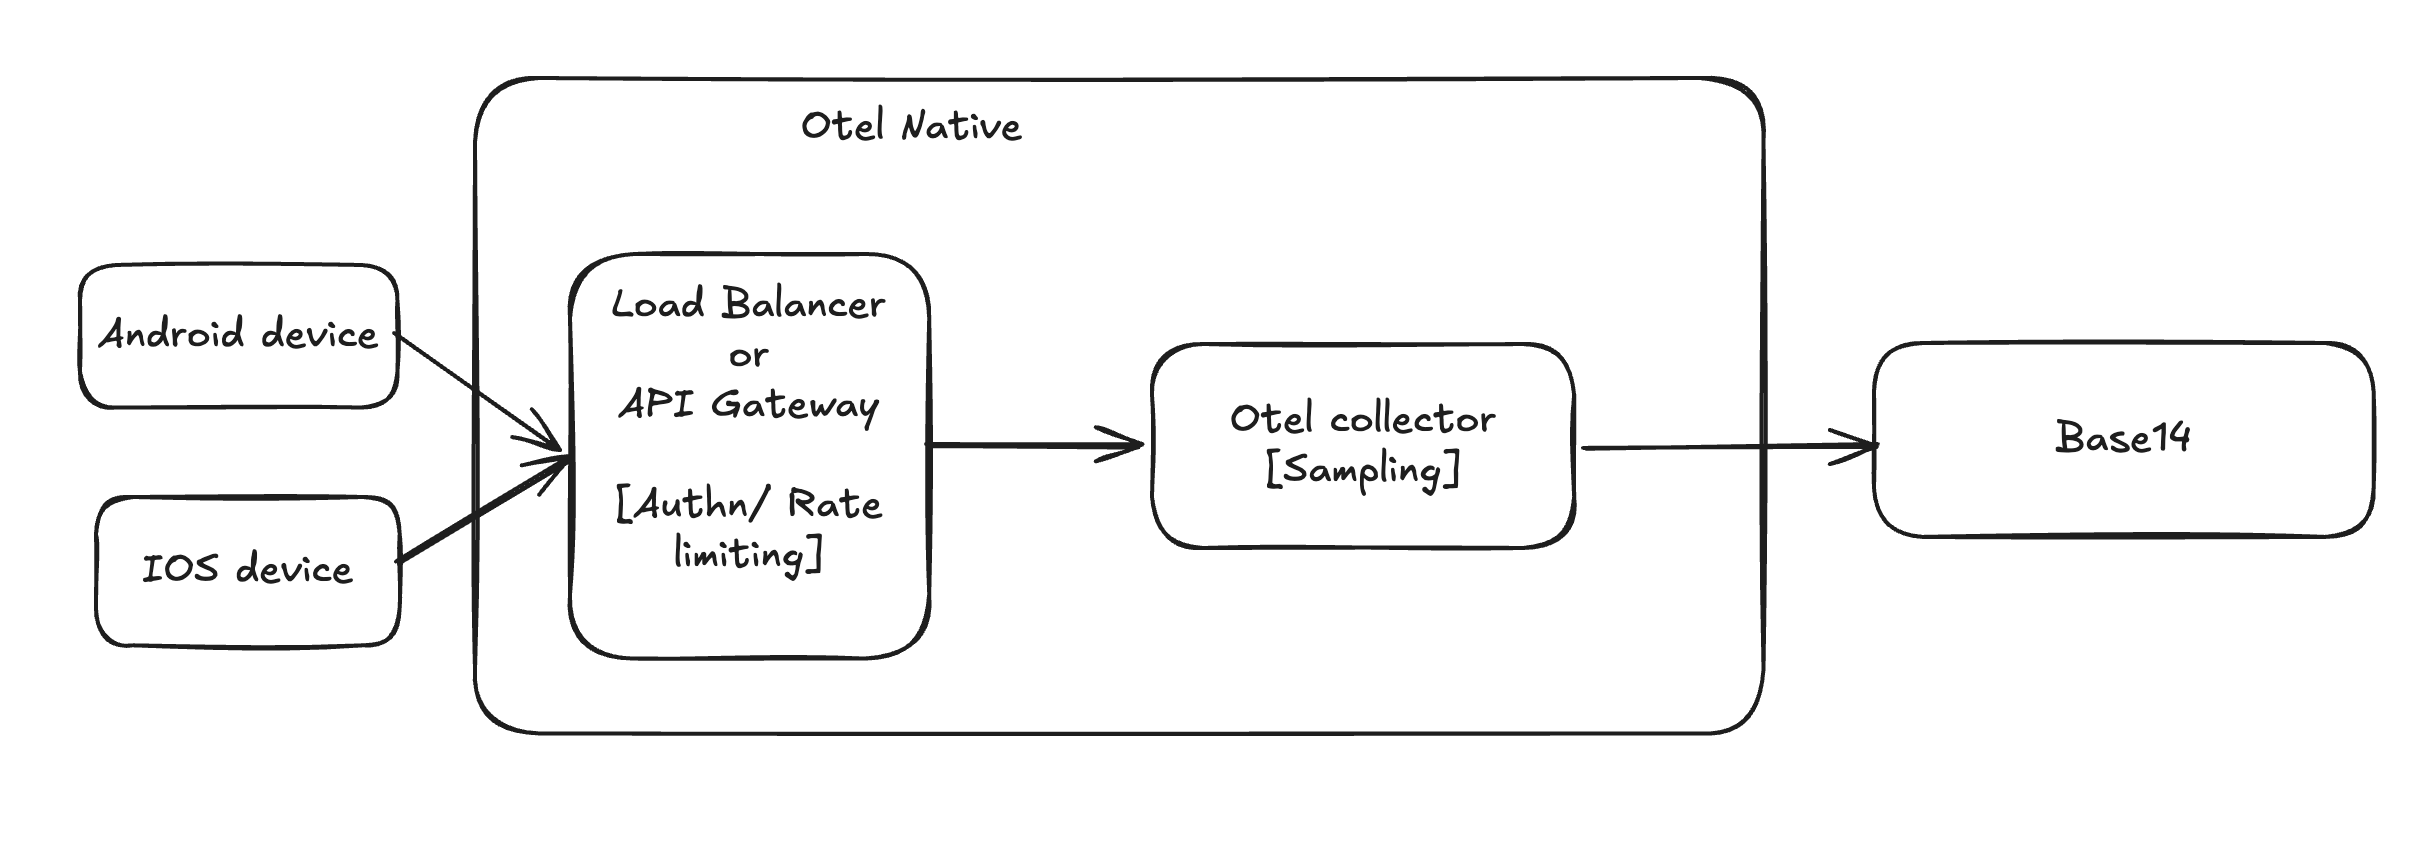
{ // ... create article logic // Record business metric ARTICLES_CREATED.add(1, &[]); tracing::info!(article_id = article.id, "Article created"); Ok(article) } pub async fn delete(&self, slug: &str, user_id: i32) -> AppResult<()> { // ... delete article logic ARTICLES_DELETED.add(1, &[]); Ok(()) } } ``` ### SQLx Database Monitoring OpenTelemetry integrates with SQLx through the tracing ecosystem to provide comprehensive database query monitoring. #### Automatic Query Tracing SQLx automatically emits tracing spans when queries are executed. Ensure your environment filter includes SQLx: ```rust showLineNumbers let env_filter = EnvFilter::try_from_default_env() .unwrap_or_else(|_| EnvFilter::new("info,sqlx=warn,tower_http=debug")); ``` #### Configuring SQLx Connection Pool Configure your database pool with proper settings: ```rust showLineNumbers title="src/database/pool.rs" use sqlx::postgres::{PgPool, PgPoolOptions}; pub async fn create_pool(database_url: &str) -> Result { let pool = PgPoolOptions::new() .max_connections(20) .min_connections(5) .acquire_timeout(Duration::from_secs(30)) .idle_timeout(Duration::from_secs(600)) .max_lifetime(Duration::from_secs(1800)) .connect(database_url) .await?; tracing::info!("Database connection pool created"); Ok(pool) } ``` #### Instrumenting Repository Methods Use the `#[instrument]` macro for automatic span creation: ```rust showLineNumbers title="src/repository/article.rs" use tracing::instrument; #[derive(Clone)] pub struct ArticleRepository { pool: PgPool, } impl ArticleRepository { pub fn new(pool: PgPool) -> Self { Self { pool } } #[instrument(name = "db.article.create", skip(self))] pub async fn create( &self, slug: &str, title: &str, description: &str, body: &str, author_id: i32, ) -> Result { sqlx::query_as!( Article, r#" INSERT INTO articles (slug, title, description, body, author_id) VALUES ($1, $2, $3, $4, $5) RETURNING id, slug, title, description, body, author_id, favorites_count, created_at, updated_at "#, slug, title, description, body, author_id ) .fetch_one(&self.pool) .await } #[instrument(name = "db.article.find_by_slug", skip(self))] pub async fn find_by_slug(&self, slug: &str) -> Result, sqlx::Error> { sqlx::query_as!( Article, "SELECT * FROM articles WHERE slug = $1", slug ) .fetch_optional(&self.pool) .await } } ``` **SQLx span attributes include:** - `db.system` - Database type (postgresql) - `db.name` - Database name - `db.statement` - SQL query - `db.operation` - Operation type (SELECT, INSERT, UPDATE, DELETE) ### Custom Manual Instrumentation While automatic instrumentation covers most Axum components, you can add custom instrumentation for business logic, external API calls, or performance-critical code paths. #### Creating Custom Spans with the Instrument Macro Use the `#[instrument]` macro from the `tracing` crate: ```rust showLineNumbers title="src/services/article.rs" use tracing::instrument; #[derive(Clone)] pub struct ArticleService { article_repo: ArticleRepository, favorite_repo: FavoriteRepository, job_queue: JobQueue, } impl ArticleService { #[instrument(name = "article.create", skip(self, input), fields(author_id))] pub async fn create( &self, author_id: i32, input: CreateArticleInput, ) -> AppResult { let slug = self.generate_slug(&input.title); let article = self .article_repo .create(&slug, &input.title, &input.description, &input.body, author_id) .await?; // Enqueue background job if let Err(e) = self.job_queue.enqueue_notification(article.id, &article.title).await { tracing::warn!(article_id = article.id, error = %e, "Failed to enqueue notification"); } ARTICLES_CREATED.add(1, &[]); tracing::info!(article_id = article.id, slug = %slug, "Article created"); Ok(ArticleResponse::from(article)) } #[instrument(name = "article.delete", skip(self))] pub async fn delete(&self, slug: &str, user_id: i32) -> AppResult<()> { let article = self .article_repo .find_by_slug(slug) .await? .ok_or(AppError::NotFound("Article not found".to_string()))?; if article.author_id != user_id { return Err(AppError::Forbidden); } self.article_repo.delete(article.id).await?; ARTICLES_DELETED.add(1, &[]); tracing::info!(article_id = article.id, "Article deleted"); Ok(()) } } ``` #### Adding Attributes to Current Spans Enrich existing spans with additional context: ```rust showLineNumbers title="src/middleware/auth.rs" use tracing::Span; pub async fn auth_middleware( State(state): State, mut request: Request, next: Next, ) -> Result { let token = extract_token(&request)?; let claims = state.auth_service.validate_token(&token)?; // Add user context to current span Span::current().record("user.id", claims.user_id); Span::current().record("user.role", &claims.role); request.extensions_mut().insert(claims); Ok(next.run(request).await) } ``` #### Exception Handling and Error Tracking Capture errors in custom spans: ```rust showLineNumbers title="src/services/external_api.rs" use tracing::{instrument, Span}; pub struct ExternalApiClient { client: reqwest::Client, base_url: String, } impl ExternalApiClient { #[instrument(name = "external_api.fetch", skip(self))] pub async fn fetch_data(&self, endpoint: &str) -> Result { let url = format!("{}/{}", self.base_url, endpoint); let response = self.client .get(&url) .send() .await .map_err(|e| { Span::current().record("otel.status_code", "ERROR"); tracing::error!(error = %e, "External API request failed"); AppError::ExternalService(e.to_string()) })?; let status = response.status(); Span::current().record("http.response.status_code", status.as_u16() as i64); if !status.is_success() { Span::current().record("otel.status_code", "ERROR"); return Err(AppError::ExternalService(format!("HTTP {}", status))); } response.json().await.map_err(|e| { tracing::error!(error = %e, "Failed to parse response"); AppError::ExternalService(e.to_string()) }) } } ``` #### Using Semantic Conventions Follow OpenTelemetry semantic conventions for consistent attribute naming: ```rust showLineNumbers // HTTP semantic conventions tracing::info_span!( "http.request", http.method = %method, http.url = %url, http.status_code = tracing::field::Empty, http.request.header.content_type = "application/json" ); // Database semantic conventions tracing::info_span!( "db.query", db.system = "postgresql", db.name = "production", db.operation = "SELECT", db.statement = "SELECT * FROM users WHERE id = $1" ); // Messaging semantic conventions tracing::info_span!( "messaging.process", messaging.system = "redis", messaging.destination = "jobs_queue", messaging.operation = "process" ); ``` ### Running Your Instrumented Application ```mdx-code-block ``` For local development, use console output to verify instrumentation: ```rust showLineNumbers title="src/telemetry/init.rs" pub fn init_development_telemetry() -> anyhow::Result<()> { let env_filter = EnvFilter::try_from_default_env() .unwrap_or_else(|_| EnvFilter::new("debug,sqlx=info,tower_http=debug")); tracing_subscriber::registry() .with(env_filter) .with(tracing_subscriber::fmt::layer().pretty()) .init(); Ok(()) } ``` Start your Axum server: ```bash RUST_LOG=debug cargo run ``` You'll see span output in the console for each request: ```text 2024-01-15T10:30:45.123Z DEBUG HTTP request{otel.name="GET /api/articles" http.method="GET"} at src/main.rs:52 2024-01-15T10:30:45.125Z DEBUG db.article.list at src/repository/article.rs:45 2024-01-15T10:30:45.130Z INFO finished processing request http.response.status_code=200 latency_ms=7.2 ``` ```mdx-code-block ``` For production deployments, ensure the Scout Collector endpoint is properly configured: ```bash showLineNumbers # Set environment variables export OTEL_SERVICE_NAME=rust-axum-app-production export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4317 export RUST_LOG=info,sqlx=warn export ENVIRONMENT=production # Run the application ./target/release/api ``` ```mdx-code-block ``` Run your instrumented Axum application in Docker: ```bash showLineNumbers # Build the image docker build -t rust-axum-app:latest . # Run with Scout Collector docker run -d \ --name rust-axum-app \ -e OTEL_SERVICE_NAME=rust-axum-app \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 \ -e DATABASE_URL=postgres://user:pass@db:5432/production \ -p 8080:8080 \ rust-axum-app:latest ``` Or use Docker Compose (see [Production Configuration](#production-configuration) section for complete example). ```mdx-code-block ``` ### Troubleshooting #### Verifying OpenTelemetry Installation Test your OpenTelemetry configuration by creating a test span: ```rust showLineNumbers title="src/main.rs" #[tokio::main] async fn main() -> anyhow::Result<()> { let config = Config::from_env(); let telemetry_guard = init_telemetry(&config)?; // Test span tracing::info_span!("startup_check").in_scope(|| { tracing::info!("OpenTelemetry is working!"); }); // ... rest of application startup // Ensure clean shutdown telemetry_guard.shutdown(); Ok(()) } ``` #### Health Check Endpoint Create a health check endpoint to verify telemetry export: ```rust showLineNumbers title="src/handlers/health.rs" use axum::{Json, extract::State}; use serde::Serialize; #[derive(Serialize)] pub struct HealthResponse { status: String, service: String, version: String, } #[tracing::instrument(name = "health.check", skip(state))] pub async fn health_check(State(state): State) -> Json { // Verify database connectivity let db_status = sqlx::query("SELECT 1") .fetch_one(&state.pool) .await .is_ok(); tracing::info!(db_healthy = db_status, "Health check performed"); Json(HealthResponse { status: if db_status { "ok" } else { "degraded" }.to_string(), service: std::env::var("OTEL_SERVICE_NAME").unwrap_or_default(), version: env!("CARGO_PKG_VERSION").to_string(), }) } ``` #### Debug Mode Enable debug logging to troubleshoot instrumentation issues: ```bash export RUST_LOG=debug,opentelemetry=debug,tracing_opentelemetry=debug cargo run ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify Scout Collector endpoint is reachable: ```bash curl -v http://scout-collector:4317/v1/traces ``` 2. Check environment variables: ```bash echo $OTEL_EXPORTER_OTLP_ENDPOINT echo $OTEL_SERVICE_NAME ``` 3. Enable debug logging and check for export errors 4. Verify network connectivity between your app and Scout Collector ##### Issue: Missing database query spans **Solutions:** 1. Ensure SQLx logging level is set to at least `warn`: ```rust EnvFilter::new("info,sqlx=warn") ``` 2. Verify you're using async SQLx methods that emit tracing spans 3. Check that `tracing-opentelemetry` layer is properly configured ##### Issue: High memory usage **Solutions:** 1. Reduce `max_queue_size` in batch processor configuration 2. Ensure spans are being exported successfully 3. Check for span attribute size limits ##### Issue: Performance degradation **Solutions:** 1. Use batch processor instead of simple processor 2. Reduce logging verbosity in production 3. Skip health check endpoints from tracing ### Security Considerations #### Protecting Sensitive Data Avoid adding sensitive information to span attributes: ```rust showLineNumbers // Bad - exposes sensitive data tracing::info!( user.password = %password, // Never include passwords! credit_card = %card_number, // Never include payment data! user.ssn = %social_security // Never include PII! ); // Good - uses safe identifiers tracing::info!( user.id = user_id, user.role = %role, payment.provider = "stripe", payment.status = "completed" ); ``` #### Sanitizing SQL Statements Configure SQLx to avoid logging sensitive query parameters: ```rust showLineNumbers // Use parameterized queries - values are not logged let user = sqlx::query_as!( User, "SELECT * FROM users WHERE email = $1 AND password_hash = $2", email, password_hash ) .fetch_optional(&pool) .await?; ``` #### Filtering Sensitive HTTP Headers Skip sensitive headers in your tracing configuration: ```rust showLineNumbers impl MakeSpan for HttpMakeSpan { fn make_span(&mut self, request: &Request) -> Span { // Don't include Authorization header in spans tracing::info_span!( "HTTP request", http.method = %request.method(), http.route = %request.uri().path(), // Omit: http.request.header.authorization ) } } ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard - Use parameterized queries to avoid logging sensitive values - Audit span attributes regularly for sensitive data leaks ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead to Rust Axum applications: - **Average latency increase**: < 1ms per request - **CPU overhead**: < 1% in production with batch processor - **Memory overhead**: ~20-50MB depending on queue size and traffic **Impact varies based on:** - Number of spans generated per request - Span processor type (Batch vs Simple) - Application request volume - Complexity of traced operations #### Optimization Best Practices ##### 1. Use Batch Processor in Production ```rust showLineNumbers // Good - batches exports, low overhead let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .build(); // Avoid in production - exports every span immediately let tracer_provider = SdkTracerProvider::builder() .with_simple_exporter(trace_exporter) .build(); ``` ##### 2. Skip Non-Critical Endpoints ```rust showLineNumbers impl MakeSpan for HttpMakeSpan { fn make_span(&mut self, request: &Request) -> Span { let path = request.uri().path(); // Skip tracing for health checks if path == "/health" || path == "/metrics" { return tracing::Span::none(); } // ... normal span creation } } ``` ##### 3. Use Appropriate Log Levels ```rust showLineNumbers // Production: minimal logging let env_filter = EnvFilter::new("info,sqlx=warn,tower_http=info"); // Development: verbose logging let env_filter = EnvFilter::new("debug,sqlx=debug,tower_http=debug"); ``` ##### 4. Limit Attribute Values ```rust showLineNumbers // Truncate long values let truncated_body = if body.len() > 1000 { format!("{}...", &body[..1000]) } else { body.to_string() }; tracing::info!(request.body = %truncated_body); ``` ### Frequently Asked Questions #### Does OpenTelemetry impact Rust application performance? OpenTelemetry adds approximately < 1ms of latency per request in typical Axum applications. Rust's zero-cost abstractions and the efficient `tracing` crate minimize overhead. With proper configuration (batch processor), the performance impact is negligible for most production workloads. #### Which Rust versions are supported? OpenTelemetry Rust supports Rust 1.80+ with edition 2021 or 2024. Rust 1.92+ is recommended for optimal compatibility and performance. See the [Prerequisites](#prerequisites) section for detailed version compatibility. #### Can I use OpenTelemetry with async Rust and Tokio? Yes! OpenTelemetry Rust is designed for async applications. The `tracing` crate handles async context propagation automatically, and `tracing-opentelemetry` bridges tracing spans to OpenTelemetry. Use `opentelemetry_sdk` with the `rt-tokio` feature for Tokio runtime support. #### How do I trace async tasks spawned with tokio::spawn? Use `tracing::Instrument` to propagate context to spawned tasks: ```rust use tracing::Instrument; let span = tracing::info_span!("background_task"); tokio::spawn(async move { // Work here is traced under the span }.instrument(span)); ``` #### Can I use OpenTelemetry alongside other observability tools? Yes, OpenTelemetry can run alongside tools like Prometheus or Jaeger during migration periods. The `tracing` ecosystem allows multiple subscribers. However, running multiple exporters simultaneously will increase overhead. #### How do I handle multi-tenant applications? Record the tenant as a field on the request span, then filter by it in Scout: ```rust tracing::info_span!( "request", tenant.id = %tenant_id, tenant.name = %tenant_name ).in_scope(|| { // Request handling }); ``` #### What's the difference between tracing and OpenTelemetry? `tracing` is Rust's native instrumentation library for structured logging and spans. `tracing-opentelemetry` bridges tracing spans to OpenTelemetry format for export to APM backends. Use `tracing` for instrumentation and OpenTelemetry for export. #### How do I monitor SQLx connection pool health? SQLx emits tracing spans for connection pool operations. Monitor these spans for connection acquisition times and pool exhaustion: ```rust // This query automatically emits tracing spans let result = sqlx::query("SELECT 1").fetch_one(&pool).await?; ``` #### Can I customize which operations are instrumented? Yes! Use the `#[instrument]` macro selectively and configure the `EnvFilter` to control which modules emit spans. You can also use `Span::none()` to skip tracing entirely for specific operations. ### What's Next? Now that your Axum application is instrumented with OpenTelemetry, explore these resources to maximize your observability: #### Advanced Topics - **[PostgreSQL Monitoring Best Practices](../../component/postgres.md)** - Optimize database observability with connection pooling metrics and query performance analysis #### Scout Platform Features - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - Set up intelligent alerts for error rates, latency thresholds, and custom metrics - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Set up Scout Collector for local development and testing ### Complete Example Here's a complete working example of an Axum application with OpenTelemetry instrumentation: #### Cargo.toml ```toml showLineNumbers title="Cargo.toml" [package] name = "rust-axum-otel" version = "1.0.0" edition = "2024" rust-version = "1.92" [dependencies] axum = { version = "0.8.8", features = ["macros"] } tower = { version = "0.5.2", features = ["full"] } tower-http = { version = "0.6.8", features = ["trace", "cors", "timeout"] } tokio = { version = "1.49", features = ["full", "tracing"] } sqlx = { version = "0.8.6", features = ["runtime-tokio", "postgres"] } opentelemetry = "0.32" opentelemetry_sdk = { version = "0.32", features = ["rt-tokio", "logs"] } opentelemetry-otlp = { version = "0.32", features = ["grpc-tonic", "trace", "logs"] } opentelemetry-appender-tracing = "0.32" tracing = "0.1" tracing-subscriber = { version = "0.3", features = ["env-filter", "json"] } tracing-opentelemetry = "0.33" serde = { version = "1.0", features = ["derive"] } serde_json = "1.0" anyhow = "1.0" ``` #### Telemetry Module ```rust showLineNumbers title="src/telemetry.rs" use std::time::Duration; use opentelemetry::KeyValue; use opentelemetry::global; use opentelemetry_appender_tracing::layer::OpenTelemetryTracingBridge; use opentelemetry_otlp::WithExportConfig; use opentelemetry_sdk::{Resource, logs::SdkLoggerProvider, trace::SdkTracerProvider}; use tracing_opentelemetry::OpenTelemetryLayer; use tracing_subscriber::{EnvFilter, Layer, layer::SubscriberExt, util::SubscriberInitExt}; pub struct TelemetryGuard { tracer_provider: SdkTracerProvider, logger_provider: SdkLoggerProvider, } impl TelemetryGuard { pub fn shutdown(&self) { let _ = self.tracer_provider.shutdown(); let _ = self.logger_provider.shutdown(); } } pub fn init(service_name: &str, endpoint: &str) -> anyhow::Result { let resource = Resource::builder() .with_service_name(service_name.to_string()) .with_attribute(KeyValue::new("service.version", "1.0.0")) .build(); let trace_exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(endpoint) .with_timeout(Duration::from_secs(10)) .build()?; let tracer_provider = SdkTracerProvider::builder() .with_batch_exporter(trace_exporter) .with_resource(resource.clone()) .build(); global::set_tracer_provider(tracer_provider.clone()); let log_exporter = opentelemetry_otlp::LogExporter::builder() .with_tonic() .with_endpoint(endpoint) .build()?; let logger_provider = SdkLoggerProvider::builder() .with_batch_exporter(log_exporter) .with_resource(resource) .build(); let tracer = global::tracer(service_name.to_string()); tracing_subscriber::registry() .with(EnvFilter::try_from_default_env().unwrap_or_else(|_| EnvFilter::new("info"))) .with(OpenTelemetryLayer::new(tracer)) .with(OpenTelemetryTracingBridge::new(&logger_provider)) .with(tracing_subscriber::fmt::layer()) .init(); Ok(TelemetryGuard { tracer_provider, logger_provider }) } ``` #### Main Application ```rust showLineNumbers title="src/main.rs" use std::net::SocketAddr; use axum::{Router, routing::get, Json}; use serde::Serialize; use tokio::net::TcpListener; mod telemetry; #[derive(Serialize)] struct HealthResponse { status: String, } #[tracing::instrument(name = "health.check")] async fn health_check() -> Json { tracing::info!("Health check requested"); Json(HealthResponse { status: "ok".to_string() }) } #[tokio::main] async fn main() -> anyhow::Result<()> { let service_name = std::env::var("OTEL_SERVICE_NAME") .unwrap_or_else(|_| "rust-axum-app".to_string()); let endpoint = std::env::var("OTEL_EXPORTER_OTLP_ENDPOINT") .unwrap_or_else(|_| "http://localhost:4317".to_string()); let guard = telemetry::init(&service_name, &endpoint)?; tracing::info!(service = %service_name, "Starting server"); let app = Router::new().route("/health", get(health_check)); let addr = SocketAddr::from(([0, 0, 0, 0], 8080)); let listener = TcpListener::bind(addr).await?; tracing::info!(%addr, "Server listening"); axum::serve(listener, app).await?; guard.shutdown(); Ok(()) } ``` #### Environment Variables ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=rust-axum-app OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 RUST_LOG=info,sqlx=warn ``` This complete example is available in our [GitHub examples repository](https://github.com/base-14/examples/tree/main/rust/axum-postgres). ### References - [Official OpenTelemetry Rust Documentation](https://opentelemetry.io/docs/languages/rust/) - [tracing-opentelemetry Crate](https://docs.rs/tracing-opentelemetry) - [Axum Documentation](https://docs.rs/axum) ### Related Guides - [Rust LLM Observability][rust-llm] - GenAI semantic conventions, token/cost tracking, multi-provider LLM with fallback for Rust AI apps - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Rust Custom Instrumentation](../custom-instrumentation/rust.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language [rust-llm]: ../../../../guides/ai-observability/rust-llm-observability --- ## BullMQ OpenTelemetry Instrumentation - Job & Queue Tracing ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## BullMQ :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview Implement OpenTelemetry instrumentation for [BullMQ](https://bullmq.io) to get distributed tracing and metrics across your Redis-backed background jobs. This guide shows you how to connect the enqueue side and the worker side into a single trace, capture per-job spans with timing and error status, and export queue-depth metrics so you can alert on backlog and failure rate. BullMQ is a Redis-backed queue used to move slow or unreliable work - email, notifications, webhooks, report generation, image processing - out of the request path. Because the producer and the worker run in different processes and communicate through Redis, a job that fails or runs slowly is hard to debug without a trace that spans both sides. OpenTelemetry gives you that end-to-end view. Unlike database drivers or HTTP frameworks, BullMQ has **no dedicated auto-instrumentation package** in the OpenTelemetry contrib bundle. Observability comes from two pieces working together: the [`instrumentation-ioredis`](https://www.npmjs.com/package/@opentelemetry/instrumentation-ioredis) package, which automatically traces the Redis commands BullMQ runs, and a small amount of manual instrumentation that creates a job span and propagates trace context through the job payload. This guide covers both. :::tip TL;DR BullMQ jobs are not auto-traced end-to-end. Add `@opentelemetry/instrumentation-ioredis` to get the underlying Redis command spans, then on the producer inject the active context into the job data with `propagation.inject`, and in the worker extract it with `propagation.extract` and wrap the work in `tracer.startActiveSpan` inside `context.with`. Export queue depth with OpenTelemetry observable gauges reading BullMQ's `getWaitingCount()` / `getActiveCount()` family. ::: ### Who This Guide Is For This documentation is designed for: - **Node.js backend engineers** running BullMQ workers in production who need to see why a job is slow or failing. - **Teams migrating from New Relic or Datadog** that had queue dashboards and want equivalent visibility on an OpenTelemetry-native stack. - **NestJS developers** using `@nestjs/bullmq` who want producer-to-worker traces across the dependency injection layer. - **Platform / SRE teams** standardizing background-job observability and alerts (backlog, failure rate, processing latency) across services. - **Developers debugging distributed flows** where an HTTP request enqueues a job and the real work happens asynchronously in another process. ### Prerequisites Before starting, ensure you have: - **Node.js 18.x or later** (20.x LTS recommended for production) - **BullMQ 5.x** (`bullmq`) - **Redis 6.2 or later** (BullMQ requires Redis; 7.x recommended) - **Scout Collector** configured and reachable - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production - Basic understanding of OpenTelemetry concepts (traces, spans, context) - Familiarity with the BullMQ `Queue` and `Worker` APIs #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ------------------------------------------ | --------------- | ------------------- | | Node.js | 18.0.0 | 20.x LTS | | BullMQ | 5.0.0 | 5.x | | Redis | 6.2.0 | 7.x | | @opentelemetry/sdk-node | 0.45.0 | 0.54+ | | @opentelemetry/instrumentation-ioredis | 0.40.0 | 0.45+ | | @opentelemetry/api | 1.7.0 | 1.9+ | #### What Gets Instrumented | Signal source | How | Automatic? | | ------------------------------ | ------------------------------------- | ---------- | | Redis commands (queue ops) | `instrumentation-ioredis` | Yes | | Job span (process lifecycle) | manual `startActiveSpan` | No | | Producer -> worker context | `propagation.inject` / `extract` | No | | Job counters / duration | manual metrics instruments | No | | Queue depth (waiting/active) | observable gauges over BullMQ counts | No | The runnable source for every snippet below lives in the [base14 examples repo](https://github.com/base-14/examples/tree/main/nodejs/nestjs-postgres) under `src/jobs/`. ### Installation Install the OpenTelemetry SDK, the OTLP exporter, and the IORedis instrumentation. BullMQ uses [ioredis](https://github.com/redis/ioredis) under the hood, so the IORedis instrumentation is what captures its Redis traffic. ```mdx-code-block ``` ```bash showLineNumbers npm install --save \ @opentelemetry/sdk-node \ @opentelemetry/api \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/instrumentation-http \ @opentelemetry/instrumentation-ioredis \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` ```mdx-code-block ``` ```bash showLineNumbers yarn add \ @opentelemetry/sdk-node \ @opentelemetry/api \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/instrumentation-http \ @opentelemetry/instrumentation-ioredis \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` ```mdx-code-block ``` ```bash showLineNumbers pnpm add \ @opentelemetry/sdk-node \ @opentelemetry/api \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/instrumentation-http \ @opentelemetry/instrumentation-ioredis \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` ```mdx-code-block ``` ### Configuration Initialize the SDK **before** any BullMQ or ioredis code runs, so the Redis client is wrapped. Load this file first via `node --require ./instrumentation.js` or as the first import in your worker entry point. ```mdx-code-block ``` ```typescript showLineNumbers title="src/instrumentation.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { HttpInstrumentation } from '@opentelemetry/instrumentation-http'; import { IORedisInstrumentation } from '@opentelemetry/instrumentation-ioredis'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME } from '@opentelemetry/semantic-conventions'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const sdk = new NodeSDK({ resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || 'bullmq-worker', }), traceExporter: new OTLPTraceExporter({ url: `${otlpEndpoint}/v1/traces`, }), instrumentations: [ new HttpInstrumentation(), new IORedisInstrumentation({ // Keep payloads small and free of secrets in span attributes dbStatementSerializer: (cmdName, cmdArgs) => `${cmdName} ${cmdArgs.slice(0, 2).join(' ')}`, }), ], }); sdk.start(); process.on('SIGTERM', () => { sdk.shutdown().finally(() => process.exit(0)); }); ``` ```mdx-code-block ``` ```bash showLineNumbers title=".env" # Service identification OTEL_SERVICE_NAME=bullmq-worker OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=jobs # Exporter OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 # BullMQ connection REDIS_URL=redis://redis:6379 ``` ```mdx-code-block ``` ```yaml showLineNumbers title="docker-compose.yml" services: worker: build: . command: ['node', '--require', './dist/instrumentation.js', 'dist/worker.js'] environment: - OTEL_SERVICE_NAME=bullmq-worker - OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 - REDIS_URL=redis://redis:6379 depends_on: - redis - scout-collector redis: image: redis:7-alpine ports: - '6379:6379' scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4318:4318' ``` ```mdx-code-block ``` > All approaches export traces and metrics to the base14 Scout observability > backend through the OTLP endpoint. ### Traces A complete BullMQ trace has two halves that live in different processes: the **producer** that enqueues the job during an HTTP request, and the **worker** that processes it later. The Redis commands in between are traced automatically by the IORedis instrumentation. The job span and the link between the two halves are manual. #### Automatic Redis Spans Once `IORedisInstrumentation` is registered, every Redis command BullMQ issues - `LPUSH`, `BRPOPLPUSH`, `HSET`, `XADD`, and so on - becomes a span. This shows you how long enqueue and dequeue operations take and surfaces Redis latency, but it does **not** group the work of a single job or connect the producer to the worker. For that, add the job span and propagate context. #### Propagate Context on Enqueue On the producer, inject the active trace context into the job payload before calling `queue.add`. BullMQ serializes job data to Redis, so the W3C `traceparent` travels with the job. ```typescript showLineNumbers title="src/jobs/notification.producer.ts" import { Queue } from 'bullmq'; import { context, propagation, trace } from '@opentelemetry/api'; const notificationsQueue = new Queue('notifications', { connection: { url: process.env.REDIS_URL }, }); export async function enqueueArticlePublished(payload: { articleId: string; title: string; authorId: string; }): Promise { // Capture the current trace context into a carrier object const carrier: Record = {}; propagation.inject(context.active(), carrier); const job = await notificationsQueue.add( 'article.published', { ...payload, traceContext: carrier }, { attempts: 3, backoff: { type: 'exponential', delay: 1000 }, }, ); trace.getActiveSpan()?.setAttribute('job.id', job.id ?? ''); return job.id; } ``` #### Start the Job Span on the Worker In the worker, pull the carrier back out of the job data, restore it as the parent context, and create a `CONSUMER` span for the job. Everything that runs inside `context.with` - including the automatic Redis and database spans - becomes a child of the job span, and the whole thing is linked back to the request that enqueued it. ```typescript showLineNumbers title="src/jobs/notification.worker.ts" import { Worker, Job } from 'bullmq'; import { context, propagation, trace, metrics, SpanKind, SpanStatusCode, } from '@opentelemetry/api'; const tracer = trace.getTracer('notification-worker'); const meter = metrics.getMeter('notification-worker'); const jobsCompleted = meter.createCounter('jobs.completed', { description: 'Number of jobs completed successfully', }); const jobsFailed = meter.createCounter('jobs.failed', { description: 'Number of jobs that failed', }); const jobDuration = meter.createHistogram('jobs.duration', { description: 'Duration of job processing in milliseconds', unit: 'ms', }); new Worker( 'notifications', async (job: Job) => { const startTime = Date.now(); const { traceContext, ...payload } = job.data; const parentContext = propagation.extract( context.active(), traceContext ?? {}, ); await context.with(parentContext, async () => { await tracer.startActiveSpan( 'job.process', { kind: SpanKind.CONSUMER, attributes: { 'job.id': job.id, 'job.name': job.name, 'job.queue': job.queueName, 'job.attempt': job.attemptsMade + 1, }, }, async (span) => { try { await handleArticlePublished(payload); span.setStatus({ code: SpanStatusCode.OK }); jobsCompleted.add(1, { queue: job.queueName }); } catch (error) { span.setStatus({ code: SpanStatusCode.ERROR, message: error instanceof Error ? error.message : String(error), }); span.recordException( error instanceof Error ? error : new Error(String(error)), ); jobsFailed.add(1, { queue: job.queueName }); throw error; } finally { const duration = Date.now() - startTime; jobDuration.record(duration, { queue: job.queueName }); span.setAttribute('job.duration_ms', duration); span.end(); } }, ); }); }, { connection: { url: process.env.REDIS_URL } }, ); ``` #### Trace Hierarchy ```text HTTP Request Span (root: POST /articles) ├── PostgreSQL INSERT Span (create article) ├── Redis LPUSH Span (enqueue: ioredis instrumentation) │ └── (later, in the worker process — linked via traceparent in job data) job.process Span (CONSUMER, kind=consumer) ├── article.publish.update Span │ └── PostgreSQL UPDATE Span └── notification.send Span ``` ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics Spans explain one job; metrics tell you about the queue as a whole - throughput, failure rate, and backlog. Two kinds are useful for BullMQ: per-job counters and a histogram (recorded in the worker, shown above), and queue-depth gauges (sampled on an interval). #### Enable the Meter Provider If you are not already exporting metrics, add an OTLP metric reader to the SDK config from the Configuration section: ```typescript showLineNumbers title="src/instrumentation.ts" import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; // inside new NodeSDK({ ... }) metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 15000, }), ``` #### Queue-Depth Gauges BullMQ exposes live counts per state. Read them on an interval and report them through OpenTelemetry observable gauges. These are the metrics you alert on: rising `waiting` means the workers cannot keep up, and rising `failed` means something is broken downstream. ```typescript showLineNumbers title="src/jobs/queue-metrics.ts" import { metrics } from '@opentelemetry/api'; import { Queue } from 'bullmq'; const meter = metrics.getMeter('job-queue-metrics'); const queue = new Queue('notifications', { connection: { url: process.env.REDIS_URL }, }); let stats = { waiting: 0, active: 0, delayed: 0, failed: 0, completed: 0 }; const states = ['waiting', 'active', 'delayed', 'failed', 'completed'] as const; for (const state of states) { meter .createObservableGauge(`job_queue_${state}`, { description: `Number of ${state} jobs in the queue`, }) .addCallback((result) => result.observe(stats[state], { queue: 'notifications' }), ); } setInterval(async () => { const [waiting, active, delayed, failed, completed] = await Promise.all([ queue.getWaitingCount(), queue.getActiveCount(), queue.getDelayedCount(), queue.getFailedCount(), queue.getCompletedCount(), ]); stats = { waiting, active, delayed, failed, completed }; }, 5000); ``` > View these metrics in your base14 Scout dashboard to chart throughput, failure > ratio, and queue backlog, and to alert when `waiting` or `failed` climbs. ##### Reference [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) ### Production Configuration In production, batch span export and tune the worker so instrumentation does not become the bottleneck. ```typescript showLineNumbers title="src/instrumentation.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { IORedisInstrumentation } from '@opentelemetry/instrumentation-ioredis'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; const sdk = new NodeSDK({ resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || 'bullmq-worker', [ATTR_SERVICE_VERSION]: process.env.APP_VERSION || '1.0.0', 'deployment.environment.name': process.env.NODE_ENV || 'development', 'environment': process.env.NODE_ENV || 'development', }), spanProcessors: [ new BatchSpanProcessor( new OTLPTraceExporter({ url: `${process.env.OTEL_EXPORTER_OTLP_ENDPOINT}/v1/traces`, }), { maxQueueSize: 2048, maxExportBatchSize: 512, scheduledDelayMillis: 5000, }, ), ], instrumentations: [new IORedisInstrumentation()], }); sdk.start(); ``` ```dockerfile showLineNumbers title="Dockerfile" FROM node:20-alpine WORKDIR /app COPY package*.json ./ RUN npm ci --omit=dev COPY . . RUN npm run build ENV NODE_ENV=production ENV OTEL_SERVICE_NAME=bullmq-worker # Load instrumentation before the worker CMD ["node", "--require", "./dist/instrumentation.js", "dist/worker.js"] ``` For high-throughput queues, run multiple worker processes and set BullMQ `concurrency` per worker. Each process exports its own spans and metrics with a distinct `service.instance.id`, and the job spans still link back to the originating request through the propagated context. ### Framework-Specific Features #### Framework Integration BullMQ's `Queue` and `Worker` API is the same regardless of the web framework in front of it, so the instrumentation code is identical: `propagation.inject` before `queue.add` on the producer, then `propagation.extract` → `context.with` → `startActiveSpan` on the worker. Only three things vary - where the producer lives, whether the worker shares the web process, and how the SDK is bootstrapped. | Framework | Producer injects in | Worker runs as | SDK bootstrap | |-----------|--------------------|----------------|---------------| | Express | route/service helper | standalone process | `telemetry.ts` preloaded (`node -r ./telemetry`) | | Fastify | `jobs/tasks/*.ts` | standalone process | `telemetry.ts` preloaded | | Hono | `jobs/tasks/*.ts` | standalone process | `telemetry.ts` preloaded | | Next.js | `lib/queue.ts` wrapper | separate process (not the Next server) | `instrumentation.ts` `register()` hook | | NestJS | `@InjectQueue` service | `@Processor` / `WorkerHost` | `instrumentation.ts` preloaded | The span code does not change between these - copy the producer and worker snippets from the [Traces](#traces) section as-is. NestJS is the only one where the decorators move where that code sits, shown below. Working versions of each live in the [base14 examples repo](https://github.com/base-14/examples/tree/main/nodejs). #### NestJS (@nestjs/bullmq) With `@nestjs/bullmq`, the producer is a service that injects the queue and the worker is a `WorkerHost`. The OpenTelemetry calls are identical - inject on enqueue, extract and `startActiveSpan` in `process`. ```typescript showLineNumbers title="src/jobs/notification.service.ts" import { Injectable } from '@nestjs/common'; import { InjectQueue } from '@nestjs/bullmq'; import { Queue } from 'bullmq'; import { context, propagation, trace } from '@opentelemetry/api'; @Injectable() export class NotificationService { constructor( @InjectQueue('notifications') private notificationsQueue: Queue, ) {} async notifyArticlePublished(articleId: string, title: string) { const carrier: Record = {}; propagation.inject(context.active(), carrier); const job = await this.notificationsQueue.add( 'article.published', { articleId, title, traceContext: carrier }, { attempts: 3, backoff: { type: 'exponential', delay: 1000 } }, ); trace.getActiveSpan()?.setAttribute('job.id', job.id ?? ''); return job.id; } } ``` ```typescript showLineNumbers title="src/jobs/notification.processor.ts" import { Processor, WorkerHost } from '@nestjs/bullmq'; import { Job } from 'bullmq'; import { context, propagation, trace, SpanKind, SpanStatusCode, } from '@opentelemetry/api'; const tracer = trace.getTracer('notification-processor'); @Processor('notifications') export class NotificationProcessor extends WorkerHost { async process(job: Job): Promise { const { traceContext, ...payload } = job.data; const parentContext = propagation.extract(context.active(), traceContext); await context.with(parentContext, async () => { await tracer.startActiveSpan( 'job.process', { kind: SpanKind.CONSUMER, attributes: { 'job.id': job.id } }, async (span) => { try { await this.handle(payload); span.setStatus({ code: SpanStatusCode.OK }); } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR }); throw error; } finally { span.end(); } }, ); }); } private async handle(payload: unknown): Promise { // business logic } } ``` See the full NestJS implementation, including metrics and structured logs, in the [base14 example](https://github.com/base-14/examples/tree/main/nodejs/nestjs-postgres). #### FlowProducer and Child Jobs BullMQ `FlowProducer` creates parent/child job trees. Inject context into each job's data the same way; the child worker extracts its own job's carrier so each node in the flow links back to the request that started it. ### Custom Instrumentation Add child spans inside the job span for the meaningful steps of your work, so a slow job points you at the exact operation: ```typescript showLineNumbers title="src/jobs/notification.processor.ts" import { trace, SpanStatusCode } from '@opentelemetry/api'; const tracer = trace.getTracer('notification-processor'); async function sendNotification(recipient: string): Promise { await tracer.startActiveSpan( 'notification.send', { attributes: { 'notification.recipient': recipient } }, async (span) => { try { await deliver(recipient); span.setStatus({ code: SpanStatusCode.OK }); } finally { span.end(); } }, ); } ``` To correlate logs with traces, attach the active trace and span IDs to log records: ```typescript showLineNumbers import { trace } from '@opentelemetry/api'; const span = trace.getActiveSpan(); logger.info('Article published', { 'trace.id': span?.spanContext().traceId, 'span.id': span?.spanContext().spanId, }); ``` ### Running Your Application Start Redis, the collector, the worker, and the producer, then trigger a job and follow it in Scout. ```bash showLineNumbers # Start infrastructure docker compose up -d redis scout-collector # Run the worker (instrumentation loaded first) node --require ./dist/instrumentation.js dist/worker.js # In another terminal, run the producer / API node --require ./dist/instrumentation.js dist/server.js # Enqueue a job curl -X POST http://localhost:3000/articles \ -H 'Content-Type: application/json' \ -d '{"title":"Hello","authorId":"u_1"}' ``` Expected span hierarchy for the request and the job (two linked traces): the `POST /articles` request span with a Redis `LPUSH` child, then a `job.process` consumer span in the worker carrying the same trace ID, with its own database and `notification.send` children. ### Troubleshooting #### Issue: Worker jobs appear as separate, disconnected traces The most common problem. The worker is starting a new root span because no context was propagated. Confirm the producer calls `propagation.inject` into the job data **and** the worker calls `propagation.extract` and runs the span inside `context.with(parentContext, ...)`. The carrier key in the job payload (`traceContext`) must match on both sides. #### Issue: No Redis spans at all The SDK started after the BullMQ/ioredis modules were imported, so the client was never wrapped. Load `instrumentation.ts` first - use `node --require ./instrumentation.js` or make it the very first import in your entry file. #### Issue: Job span has no children for database or HTTP calls Those calls are running outside `context.with`. Make sure all of the job's work happens inside the `startActiveSpan` callback so the active context is set when the database and HTTP instrumentations create their spans. #### Issue: Retried jobs are confusing in the trace view Each attempt runs the worker again and creates a new `job.process` span linked to the original enqueue. Use the `job.attempt` attribute (`job.attemptsMade + 1`) to distinguish attempts, and set the span status to ERROR on the failing attempts. #### Issue: Queue-depth gauges always read zero The `Queue` instance used for metrics must point at the same Redis connection and queue name as the workers. Verify `REDIS_URL` and the queue name match, and that the sampling `setInterval` is actually running in a live process. ### Security Considerations - **Do not put secrets in job data.** Job payloads are stored in Redis and, if you add them as span attributes, exported to your backend. Pass identifiers, not credentials or PII. - **Trim Redis statement attributes.** The `dbStatementSerializer` shown in the SDK config truncates command arguments so queue contents are not captured verbatim in spans. - **Secure Redis.** Use authentication and TLS (`rediss://`) in production; BullMQ inherits the connection security you configure on ioredis. - **Be deliberate about attributes.** Only attach business fields you are comfortable storing centrally (article IDs are fine; email bodies are not). ### Performance Considerations - **Overhead.** Expect roughly 0.5-2ms added per job from span creation and context propagation, low single-digit CPU increase, and 15-35MB additional memory on the worker process. Redis round trips dominate job latency, not the instrumentation. - **Batch export.** Use `BatchSpanProcessor` (Production Configuration) so export happens off the hot path. - **Sample queue metrics sensibly.** A 5s gauge interval is plenty; polling BullMQ counts too aggressively adds Redis load for little benefit. - **Filter noisy Redis commands** if needed via the IORedis instrumentation hooks, but keep the queue operations you care about. ### FAQ #### Does OpenTelemetry auto-instrument BullMQ? No. There is no dedicated BullMQ package in `auto-instrumentations-node`. The Redis commands BullMQ issues are traced automatically by `instrumentation-ioredis`, and you add manual spans plus context propagation for job-level, producer-to-worker tracing. #### How do I trace a BullMQ job from producer to worker? Inject the active context into the job data with `propagation.inject` on enqueue, then extract it with `propagation.extract` in the worker and run the job span inside `context.with`. This stitches the enqueue and process spans into one trace. #### Why do my BullMQ jobs show up as disconnected traces? BullMQ does not carry trace context across Redis on its own. Without injecting context into the job data and extracting it in the worker, the worker starts a fresh root span, so the job looks like a separate trace. #### How do I monitor BullMQ queue depth with OpenTelemetry? Use observable gauges that read `getWaitingCount()`, `getActiveCount()`, `getDelayedCount()`, `getFailedCount()`, and `getCompletedCount()` on an interval, reporting one gauge per state with a `queue` attribute. #### Does instrumentation-ioredis cover BullMQ completely? It covers the Redis command layer, which is the transport. It does not group a job's work into one span or link producer and worker - that is what the manual job span and context propagation add. #### How much overhead does OpenTelemetry add to BullMQ workers? Roughly 0.5-2ms per job and low single-digit CPU, with 15-35MB extra memory per worker process when using the batch span processor. The Redis and downstream calls dominate job time. #### Can I trace BullMQ flows and child jobs? Yes. With `FlowProducer`, inject context into each job's data. Every child worker extracts its own carrier, so each node in the flow links back to the originating request. #### How do I trace failed and retried jobs? Each retry re-runs the worker and creates a new `job.process` span. Record the exception and set the span status to ERROR on failures, and use the `job.attempt` attribute to tell attempts apart. #### Does this work with NestJS @nestjs/bullmq? Yes. The producer service and the `WorkerHost` processor use the exact same `propagation.inject` / `propagation.extract` and `startActiveSpan` calls; only the BullMQ wiring differs. #### How do I propagate context through delayed or scheduled jobs? The same way - context is injected into the job data at enqueue time and travels with the job in Redis regardless of how long it is delayed. The worker extracts it whenever the job eventually runs. #### Should I sample BullMQ traces? This guide does not cover sampling. Export the spans your workers produce and let the collector handle volume centrally. ### What's Next - Build a queue dashboard in Scout from the `jobs.*` and `job_queue_*` metrics. - Set alerts on `job_queue_waiting` (backlog) and the `jobs.failed` rate. - Add child spans for the slow steps inside your jobs. For teams standardizing background-job observability across services, base14 Scout gives you [unified traces, metrics, and logs](https://base14.io/scout) for producers and workers in one place. ### Complete Example A complete NestJS + BullMQ + PostgreSQL application with producer-to-worker tracing, job metrics, queue-depth gauges, and trace-correlated logs is available in the base14 examples repository. ```text nestjs-postgres/ ├── src/ │ ├── instrumentation / telemetry.ts # SDK + ioredis instrumentation │ └── jobs/ │ ├── notification.service.ts # producer: inject context, enqueue │ ├── notification.processor.ts # worker: extract context, job span │ └── job-metrics.service.ts # queue-depth observable gauges └── docker-compose.yml ``` ```bash showLineNumbers git clone https://github.com/base-14/examples.git cd examples/nodejs/nestjs-postgres npm install docker compose up -d npm run start:dev ``` ### References - [BullMQ Documentation](https://docs.bullmq.io/) - [OpenTelemetry JavaScript SDK](https://opentelemetry.io/docs/languages/js/) - [IORedis Instrumentation](https://www.npmjs.com/package/@opentelemetry/instrumentation-ioredis) - [OpenTelemetry Context Propagation](https://opentelemetry.io/docs/concepts/context-propagation/) ### Related Guides - [NestJS Instrumentation](./nestjs.md) - Structured TypeScript framework that uses BullMQ for background jobs - [Express Instrumentation](./express.md) - Enqueue jobs from an Express API - [Fastify Instrumentation](./fastify.md) - High-performance Node.js web framework - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up the collector for local development --- ## Celery OpenTelemetry Instrumentation - Task Tracing & Propagation Implement OpenTelemetry instrumentation for Celery applications to enable comprehensive distributed task queue monitoring, end-to-end tracing, and observability. This guide shows you how to auto-instrument your Celery workers and task producers to collect traces and metrics from task execution, message queues, and result backends using the OpenTelemetry Python SDK. Celery is a distributed task queue rather than a web framework. It commonly runs alongside web apps built with [FastAPI](./fast-api.md), [Flask](./flask.md), and [Django](./django.md). Celery applications benefit from automatic instrumentation that captures task lifecycle events including task publishing, worker processing, retries, and failures. With OpenTelemetry, you can trace distributed transactions from HTTP requests through message brokers (RabbitMQ, Redis) to worker execution, monitor task performance and queue depths, debug slow or failing tasks, and identify bottlenecks in your async processing pipeline without significant code changes. Whether you're implementing observability for the first time, migrating from commercial APM solutions, or troubleshooting production issues with distributed task queues, this guide provides production-ready configurations and best practices for Celery OpenTelemetry instrumentation. :::tip TL;DR Install `opentelemetry-instrumentation-celery` and initialize the SDK with `CeleryInstrumentor().instrument()` before starting your workers. Set `OTEL_EXPORTER_OTLP_ENDPOINT` and `OTEL_SERVICE_NAME`, then use `opentelemetry-instrument celery worker` to auto-inject context propagation across task producers and consumers. Traces flow end-to-end from HTTP request through the broker (RabbitMQ or Redis) to worker execution with no changes to your task code. ::: > **Note:** This guide provides a practical Celery-focused overview based on the > official OpenTelemetry documentation. For complete Python language > information, please consult the > [official OpenTelemetry Python documentation](https://opentelemetry.io/docs/languages/python/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Python developers**: implementing observability for Celery task queues and distributed systems for the first time - **DevOps engineers**: deploying Celery workers with production monitoring requirements and distributed tracing needs - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to OpenTelemetry - **Developers**: debugging slow tasks, failed retries, or tracing issues across HTTP requests and async task execution - **Platform teams**: standardizing observability across multiple Python services using Celery for background processing ### Overview This comprehensive guide demonstrates how to: - Install and configure OpenTelemetry SDK for Celery applications - Set up automatic instrumentation for task publishing and worker execution - Propagate trace context across async boundaries (HTTP → Celery → Worker) - Configure production-ready telemetry export to Scout Collector - Implement custom instrumentation for business-critical task operations - Collect and analyze traces, metrics, and logs from distributed task processing - Deploy instrumented Celery workers to development, staging, and production - Troubleshoot common instrumentation issues and optimize performance - Secure sensitive data in telemetry exports ### Prerequisites Before starting, ensure you have: - **Python 3.9 or later** installed - Python 3.11+ is recommended for best performance - Python 3.13 is fully supported - **Celery 5.3 or later** installed - Celery 5.4+ is recommended for optimal OpenTelemetry support - **Message broker** configured (RabbitMQ or Redis) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Production deployments should use a dedicated Scout Collector instance - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ---------------- | --------------- | ------------------- | | Python | 3.9.0 | 3.11.0+ | | Celery | 5.3.0 | 5.4.0+ | | RabbitMQ | 3.8.0 | 3.13.0+ | | Redis | 6.0.0 | 7.0.0+ | | opentelemetry-\* | 1.20.0 | 1.27+ | ### Required Packages Install the following packages using pip or add them to your `requirements.txt`: ```plaintext showLineNumbers title="requirements.txt" opentelemetry-api opentelemetry-sdk opentelemetry-exporter-otlp opentelemetry-instrumentation-celery ``` For comprehensive auto-instrumentation including Redis, SQLAlchemy, and other libraries commonly used with Celery: ```plaintext showLineNumbers title="requirements.txt" opentelemetry-distro opentelemetry-exporter-otlp opentelemetry-instrumentation-celery opentelemetry-instrumentation-redis opentelemetry-instrumentation-sqlalchemy opentelemetry-instrumentation-logging ``` Install with pip: ```bash pip install opentelemetry-distro opentelemetry-exporter-otlp \ opentelemetry-instrumentation-celery opentelemetry-instrumentation-redis ``` Or using Poetry: ```bash poetry add opentelemetry-distro opentelemetry-exporter-otlp \ opentelemetry-instrumentation-celery opentelemetry-instrumentation-redis ``` ### Configuration OpenTelemetry Celery instrumentation can be configured using multiple approaches depending on your deployment requirements and preferences. Choose the method that best fits your application architecture. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The recommended approach uses the `opentelemetry-instrument` CLI command which automatically instruments all supported libraries without code changes: ```bash showLineNumbers # Start Celery worker with auto-instrumentation opentelemetry-instrument celery -A myapp.tasks worker --loglevel=info ``` Configure via environment variables: ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=celery-worker OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true ``` This approach automatically instruments: - **Celery**: Task execution, worker operations, task publishing - **Redis**: Result backend operations, broker commands - **SQLAlchemy**: Database queries within tasks - **Logging**: Trace-correlated log records ```mdx-code-block ``` For more control over instrumentation timing, use Celery's `worker_process_init` signal: ```python showLineNumbers title="myapp/telemetry.py" from celery.signals import worker_process_init from opentelemetry.instrumentation.celery import CeleryInstrumentor @worker_process_init.connect(weak=False) def init_celery_tracing(*args, **kwargs): """Initialize tracing for Celery worker processes.""" CeleryInstrumentor().instrument() ``` Import this module in your Celery app to ensure it runs on worker startup: ```python showLineNumbers title="myapp/tasks.py" from celery import Celery from . import telemetry # Import to trigger signal registration app = Celery("tasks", broker="amqp://localhost") @app.task def process_task(task_id: int): return {"task_id": task_id, "status": "completed"} ``` ```mdx-code-block ``` For full control over OpenTelemetry configuration: ```python showLineNumbers title="myapp/telemetry.py" import os from celery.signals import worker_process_init from opentelemetry import trace, metrics from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter from opentelemetry.instrumentation.celery import CeleryInstrumentor from opentelemetry.sdk.resources import Resource from opentelemetry.semconv.resource import ResourceAttributes def init_telemetry(): """Initialize OpenTelemetry tracing and metrics.""" service_name = os.getenv("OTEL_SERVICE_NAME", "celery-worker") endpoint = os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4318") resource = Resource(attributes={ ResourceAttributes.SERVICE_NAME: service_name, ResourceAttributes.SERVICE_VERSION: "1.0.0", }) # Setup trace provider with batch processor trace.set_tracer_provider(TracerProvider(resource=resource)) tracer_provider = trace.get_tracer_provider() span_exporter = OTLPSpanExporter(endpoint=f"{endpoint}/v1/traces") span_processor = BatchSpanProcessor(span_exporter) tracer_provider.add_span_processor(span_processor) # Setup metrics provider metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"{endpoint}/v1/metrics") ) metrics.set_meter_provider( MeterProvider(resource=resource, metric_readers=[metric_reader]) ) @worker_process_init.connect(weak=False) def init_celery_tracing(*args, **kwargs): """Initialize tracing for Celery worker processes.""" init_telemetry() CeleryInstrumentor().instrument() ``` ```mdx-code-block ``` For containerized deployments, rely entirely on environment variables with minimal code: ```python showLineNumbers title="myapp/telemetry.py" from celery.signals import worker_process_init from opentelemetry.instrumentation.celery import CeleryInstrumentor @worker_process_init.connect(weak=False) def init_celery_tracing(*args, **kwargs): CeleryInstrumentor().instrument() ``` Configure all settings via environment: ```bash showLineNumbers title=".env" # Service identification OTEL_SERVICE_NAME=celery-worker OTEL_SERVICE_VERSION=1.0.0 # Exporter configuration OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_COMPRESSION=gzip # Enable all exporters OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp # Resource attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=myapp ``` ```mdx-code-block ``` #### Scout Collector Integration When using Scout Collector, configure your Celery application to send telemetry data to the Scout Collector endpoint: ```python showLineNumbers title="myapp/telemetry.py" import os from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.sdk.resources import Resource from opentelemetry.semconv.resource import ResourceAttributes def init_telemetry(): """Initialize OpenTelemetry with Scout Collector.""" resource = Resource(attributes={ ResourceAttributes.SERVICE_NAME: os.getenv("OTEL_SERVICE_NAME", "celery-worker"), ResourceAttributes.SERVICE_VERSION: os.getenv("APP_VERSION", "1.0.0"), }) # Scout Collector endpoint scout_endpoint = os.getenv("SCOUT_COLLECTOR_ENDPOINT", "http://localhost:4318") trace.set_tracer_provider(TracerProvider(resource=resource)) tracer_provider = trace.get_tracer_provider() span_exporter = OTLPSpanExporter(endpoint=f"{scout_endpoint}/v1/traces") span_processor = BatchSpanProcessor(span_exporter) tracer_provider.add_span_processor(span_processor) ``` > **Scout Dashboard Integration**: After configuration, your Celery task traces > will appear in the Scout Dashboard. Navigate to the Traces section to view > task execution flows, identify slow tasks, and analyze distributed > transactions across your services. ### Production Configuration Production deployments require additional configuration for optimal performance, reliability, and resource utilization. #### Batch Span Processor (Recommended for Production) The `BatchSpanProcessor` is essential for production as it reduces network overhead by batching span exports: ```python showLineNumbers title="myapp/telemetry.py" from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.sdk.resources import Resource from opentelemetry.semconv.resource import ResourceAttributes import os def init_telemetry(): """Initialize OpenTelemetry with production settings.""" resource = Resource(attributes={ ResourceAttributes.SERVICE_NAME: os.getenv("OTEL_SERVICE_NAME"), ResourceAttributes.SERVICE_VERSION: os.getenv("APP_VERSION", "1.0.0"), ResourceAttributes.DEPLOYMENT_ENVIRONMENT: os.getenv("ENVIRONMENT", "development"), }) trace.set_tracer_provider(TracerProvider(resource=resource)) tracer_provider = trace.get_tracer_provider() # Configure batch processor for production span_processor = BatchSpanProcessor( OTLPSpanExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT") ), max_queue_size=2048, # Maximum spans in queue schedule_delay_millis=5000, # Export every 5 seconds export_timeout_millis=30000, # 30 second timeout max_export_batch_size=512 # Export up to 512 spans at once ) tracer_provider.add_span_processor(span_processor) ``` #### Resource Attributes Add rich context to all telemetry data: ```python showLineNumbers title="myapp/telemetry.py" import socket from opentelemetry.sdk.resources import Resource from opentelemetry.semconv.resource import ResourceAttributes resource = Resource(attributes={ ResourceAttributes.SERVICE_NAME: os.getenv("OTEL_SERVICE_NAME", "celery-worker"), ResourceAttributes.SERVICE_VERSION: os.getenv("APP_VERSION", "1.0.0"), ResourceAttributes.DEPLOYMENT_ENVIRONMENT: os.getenv("ENVIRONMENT", "development"), ResourceAttributes.SERVICE_NAMESPACE: os.getenv("SERVICE_NAMESPACE", "myapp"), ResourceAttributes.SERVICE_INSTANCE_ID: socket.gethostname(), ResourceAttributes.HOST_NAME: socket.gethostname(), "cloud.provider": os.getenv("CLOUD_PROVIDER", "aws"), "cloud.region": os.getenv("AWS_REGION", "us-east-1"), "k8s.pod.name": os.getenv("K8S_POD_NAME"), "k8s.namespace.name": os.getenv("K8S_NAMESPACE"), }) ``` #### Production Environment Variables ```bash showLineNumbers title=".env.production" # Service Configuration OTEL_SERVICE_NAME=celery-worker-production APP_VERSION=2.1.3 SERVICE_NAMESPACE=production ENVIRONMENT=demo # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4318 # Batch Processor Settings OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 # Exporter Settings OTEL_EXPORTER_OTLP_COMPRESSION=gzip OTEL_EXPORTER_OTLP_TIMEOUT=30000 # Celery Configuration CELERY_BROKER_URL=amqp://user:pass@rabbitmq:5672// CELERY_RESULT_BACKEND=redis://redis:6379/0 # Infrastructure Context CLOUD_PROVIDER=aws AWS_REGION=us-east-1 ``` #### Docker Production Configuration ```dockerfile showLineNumbers title="Dockerfile" FROM python:3.13-slim RUN groupadd -r celeryuser && useradd -r -g celeryuser -m celeryuser WORKDIR /app RUN apt-get update && apt-get install -y curl && rm -rf /var/lib/apt/lists/* USER celeryuser RUN curl -sSL https://install.python-poetry.org | python3 - ENV PATH="/home/celeryuser/.local/bin:$PATH" COPY --chown=celeryuser:celeryuser pyproject.toml poetry.lock* ./ RUN poetry install --no-root COPY --chown=celeryuser:celeryuser . . ``` ```yaml showLineNumbers title="compose.yaml" services: celery_worker: build: . command: poetry run opentelemetry-instrument celery -A myapp.tasks worker --loglevel=info environment: OTEL_SERVICE_NAME: celery-worker OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED: "true" CELERY_BROKER_URL: amqp://guest:guest@rabbitmq:5672// CELERY_RESULT_BACKEND: redis://redis:6379/0 depends_on: - rabbitmq - redis - otel-collector otel-collector: image: otel/opentelemetry-collector-contrib:latest command: ["--config=/etc/otelcol-config.yaml"] volumes: - ./config/otelcol-config.yaml:/etc/otelcol-config.yaml:ro ports: - "4318:4318" - "4317:4317" ``` ### Distributed Tracing Across Async Boundaries The most critical aspect of Celery instrumentation is propagating trace context across async boundaries. Without context propagation, Celery workers start new traces, breaking the correlation between HTTP requests and task execution. #### Understanding Context Propagation ```text POST /tasks/ Trace ID: abc123 ├── INSERT task_db (PostgreSQL) ├── apply_async/process_task ─► RabbitMQ ─► run/process_task ├── process_task │ └── heavy_processing └── SETEX (Redis) ``` Without context propagation, the worker would create a new trace ID, making it impossible to correlate the HTTP request with task execution. #### Injecting Trace Context (Producer Side) When publishing tasks from a web framework (FastAPI, Django, Flask), inject the trace context into Celery task headers: ```python showLineNumbers title="app/api/endpoints.py" from fastapi import FastAPI, Depends from opentelemetry.propagate import inject from . import tasks app = FastAPI() @app.post("/tasks/") def create_task(task_data: dict): # Create database record, etc. db_task = create_task_record(task_data) # Inject trace context into Celery task headers headers = {} inject(headers) # Publish task with trace context tasks.process_task.apply_async( args=[db_task.id], headers=headers ) return {"task_id": db_task.id, "status": "queued"} ``` #### Extracting Context (Worker Side) The Celery instrumentation automatically extracts context from task headers when properly configured. For custom span creation within tasks: ```python showLineNumbers title="myapp/tasks.py" from celery import Celery from opentelemetry import trace from opentelemetry.propagate import extract from opentelemetry.context import attach, detach celery = Celery("tasks", broker="amqp://localhost") @celery.task(bind=True) def process_task(self, task_id: int): tracer = trace.get_tracer(__name__) # Create custom span within the propagated context with tracer.start_as_current_span("process_task") as span: span.set_attribute("task.id", task_id) # Business logic with nested spans with tracer.start_span("heavy_processing") as processing_span: result = perform_processing(task_id) processing_span.set_attribute("processing.duration_ms", result.duration) span.set_attribute("task.status", "completed") return {"task_id": task_id, "status": "completed"} ``` #### Complete Producer-Consumer Example ```python showLineNumbers title="app/main.py" from fastapi import FastAPI from opentelemetry.propagate import inject from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from . import tasks from .telemetry import setup_telemetry app = FastAPI() setup_telemetry(app) @app.post("/orders/") def create_order(order_data: dict): """Create order and queue async processing.""" order = Order.create(**order_data) # Propagate trace context to Celery headers = {} inject(headers) # Queue multiple tasks with same trace context tasks.validate_inventory.apply_async(args=[order.id], headers=headers) tasks.process_payment.apply_async(args=[order.id], headers=headers) tasks.send_confirmation.apply_async(args=[order.id], headers=headers) return {"order_id": order.id} ``` ```python showLineNumbers title="myapp/tasks.py" from celery import Celery from opentelemetry import trace import logging logger = logging.getLogger(__name__) celery = Celery("tasks") @celery.task def validate_inventory(order_id: int): logger.info(f"Validating inventory for order {order_id}") tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("validate_inventory") as span: span.set_attribute("order.id", order_id) # Validation logic return {"order_id": order_id, "inventory_valid": True} @celery.task def process_payment(order_id: int): logger.info(f"Processing payment for order {order_id}") tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("process_payment") as span: span.set_attribute("order.id", order_id) # Payment logic return {"order_id": order_id, "payment_status": "completed"} @celery.task def send_confirmation(order_id: int): logger.info(f"Sending confirmation for order {order_id}") tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("send_confirmation") as span: span.set_attribute("order.id", order_id) # Email logic return {"order_id": order_id, "email_sent": True} ``` ### Custom Manual Instrumentation While automatic instrumentation covers task lifecycle events, add custom instrumentation for business logic and performance-critical operations. #### Creating Custom Spans in Tasks ```python showLineNumbers title="myapp/tasks.py" from celery import Celery from opentelemetry import trace import time celery = Celery("tasks") @celery.task def generate_report(report_id: int, params: dict): tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("generate_report") as span: span.set_attribute("report.id", report_id) span.set_attribute("report.type", params.get("type", "standard")) # Data gathering phase with tracer.start_span("gather_data") as data_span: data = gather_report_data(report_id, params) data_span.set_attribute("data.records_count", len(data)) data_span.add_event("Data gathered", attributes={ "records": len(data) }) # Processing phase with tracer.start_span("process_data") as process_span: processed = process_data(data) process_span.set_attribute("processing.duration_ms", processed.duration) # Rendering phase with tracer.start_span("render_report") as render_span: report = render_report(processed, params.get("format", "pdf")) render_span.set_attribute("report.size_bytes", len(report)) span.set_status(trace.Status(trace.StatusCode.OK)) return {"report_id": report_id, "status": "completed"} ``` #### Adding Attributes to Current Span ```python showLineNumbers title="myapp/tasks.py" from opentelemetry import trace @celery.task(bind=True) def process_order(self, order_id: int): current_span = trace.get_current_span() # Add business context current_span.set_attributes({ "order.id": order_id, "celery.task.name": self.name, "celery.task.id": self.request.id, "celery.task.retries": self.request.retries, }) order = Order.get(order_id) current_span.set_attributes({ "order.total": order.total, "order.items_count": len(order.items), "customer.tier": order.customer.tier, }) return process(order) ``` #### Exception Handling and Error Tracking ```python showLineNumbers title="myapp/tasks.py" from celery import Celery from opentelemetry import trace from opentelemetry.trace import Status, StatusCode celery = Celery("tasks") @celery.task(bind=True, max_retries=3) def risky_task(self, data: dict): tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("risky_task") as span: span.set_attribute("task.data_size", len(str(data))) try: result = perform_risky_operation(data) span.set_status(Status(StatusCode.OK)) return result except TransientError as e: span.record_exception(e) span.set_status(Status(StatusCode.ERROR, str(e))) span.set_attribute("error.retryable", True) # Retry with exponential backoff raise self.retry(exc=e, countdown=2 ** self.request.retries) except PermanentError as e: span.record_exception(e) span.set_status(Status(StatusCode.ERROR, str(e))) span.set_attribute("error.retryable", False) raise ``` #### Custom Business Metrics ```python showLineNumbers title="myapp/metrics.py" from opentelemetry import metrics meter = metrics.get_meter("myapp.tasks", "1.0.0") # Task execution counter tasks_executed = meter.create_counter( "tasks.executed", unit="tasks", description="Total number of tasks executed" ) # Task duration histogram task_duration = meter.create_histogram( "tasks.duration", unit="ms", description="Task execution duration" ) # Active tasks gauge active_tasks = meter.create_up_down_counter( "tasks.active", unit="tasks", description="Currently executing tasks" ) ``` ```python showLineNumbers title="myapp/tasks.py" import time from .metrics import tasks_executed, task_duration, active_tasks @celery.task def monitored_task(task_id: int): active_tasks.add(1, attributes={"task.type": "monitored"}) start_time = time.time() try: result = perform_work(task_id) tasks_executed.add(1, attributes={ "task.type": "monitored", "task.status": "success" }) return result except Exception as e: tasks_executed.add(1, attributes={ "task.type": "monitored", "task.status": "error", "error.type": type(e).__name__ }) raise finally: duration_ms = (time.time() - start_time) * 1000 task_duration.record(duration_ms, attributes={"task.type": "monitored"}) active_tasks.add(-1, attributes={"task.type": "monitored"}) ``` ### Running Your Instrumented Application #### Development Mode For local development with console output: ```bash # Set environment variables export OTEL_SERVICE_NAME=celery-worker-dev export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 export OTEL_TRACES_EXPORTER=console export OTEL_METRICS_EXPORTER=console # Start worker with auto-instrumentation opentelemetry-instrument celery -A myapp.tasks worker --loglevel=debug ``` #### Production Mode ```bash # Set production environment variables export OTEL_SERVICE_NAME=celery-worker-production export APP_VERSION=2.1.0 export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4318 export OTEL_TRACES_EXPORTER=otlp export OTEL_METRICS_EXPORTER=otlp export OTEL_LOGS_EXPORTER=otlp export OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true # Start worker opentelemetry-instrument celery -A myapp.tasks worker \ --loglevel=info \ --concurrency=4 \ --prefetch-multiplier=4 ``` #### Docker Deployment ```bash # Build the image docker build -t celery-worker:latest . # Run worker with Scout Collector docker run -d \ --name celery-worker \ -e OTEL_SERVICE_NAME=celery-worker \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 \ -e CELERY_BROKER_URL=amqp://guest:guest@rabbitmq:5672// \ -e CELERY_RESULT_BACKEND=redis://redis:6379/0 \ celery-worker:latest ``` ### Troubleshooting #### Verifying OpenTelemetry Installation Test your OpenTelemetry configuration: ```python # test_telemetry.py from opentelemetry import trace tracer = trace.get_tracer("test") with tracer.start_as_current_span("test_span") as span: span.set_attribute("test", "value") print(f"OpenTelemetry is working!") print(f"Tracer provider: {trace.get_tracer_provider().__class__.__name__}") print(f"Active span: {span.name}") ``` Run with instrumentation: ```bash opentelemetry-instrument python test_telemetry.py ``` #### Health Check Task Create a health check task to verify telemetry export: ```python showLineNumbers title="myapp/tasks.py" from celery import Celery from opentelemetry import trace celery = Celery("tasks") @celery.task def health_check(): """Health check task that creates a test span.""" tracer = trace.get_tracer("health_check") with tracer.start_as_current_span("health_check_task") as span: span.set_attribute("service.name", "celery-worker") span.set_attribute("health.status", "ok") return { "status": "ok", "tracer_provider": trace.get_tracer_provider().__class__.__name__, } ``` #### Debug Mode Enable debug logging: ```bash export OTEL_LOG_LEVEL=debug export OTEL_PYTHON_LOG_LEVEL=debug opentelemetry-instrument celery -A myapp.tasks worker --loglevel=debug ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify Scout Collector endpoint is reachable: ```bash curl -v http://scout-collector:4318/v1/traces ``` 2. Check environment variables are set: ```bash echo $OTEL_EXPORTER_OTLP_ENDPOINT echo $OTEL_SERVICE_NAME ``` 3. Enable debug logging and check for export errors 4. Verify the worker is using `opentelemetry-instrument` command ##### Issue: Traces not correlated between HTTP requests and Celery tasks **Solutions:** 1. Ensure trace context is injected when publishing tasks: ```python headers = {} inject(headers) task.apply_async(args=[...], headers=headers) ``` 2. Verify Celery instrumentation is installed: ```bash pip show opentelemetry-instrumentation-celery ``` 3. Check that both producer and worker use the same OTLP endpoint ##### Issue: Missing task execution spans **Solutions:** 1. Ensure `worker_process_init` signal is properly connected 2. Verify instrumentation runs before task execution 3. Check that `CeleryInstrumentor().instrument()` is called ##### Issue: High memory usage in workers **Solutions:** 1. Use `BatchSpanProcessor` instead of `SimpleSpanProcessor` 2. Reduce `max_queue_size` in BatchSpanProcessor 3. Increase `schedule_delay_millis` to batch more spans ### Security Considerations #### Protecting Sensitive Data Avoid adding sensitive information to span attributes: ```python # Bad - exposes sensitive data span.set_attributes({ "user.password": user.password, # Never! "payment.card_number": card_number, # Never! "user.ssn": social_security_number, # Never! }) # Good - uses safe identifiers span.set_attributes({ "user.id": user.id, "payment.status": "completed", "payment.provider": "stripe", }) ``` #### Sanitizing Task Arguments Be careful with task arguments that may contain sensitive data: ```python showLineNumbers title="myapp/tasks.py" @celery.task def process_user_data(user_id: int, data: dict): tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("process_user_data") as span: # Good - only record safe identifiers span.set_attribute("user.id", user_id) span.set_attribute("data.keys", list(data.keys())) # Bad - never record raw user data # span.set_attribute("user.data", str(data)) return process(user_id, data) ``` #### Filtering Sensitive Headers Configure instrumentation to skip sensitive headers: ```python showLineNumbers from opentelemetry.instrumentation.celery import CeleryInstrumentor CeleryInstrumentor().instrument( # Skip recording certain headers request_hook=lambda span, task_id, args, kwargs: None, ) ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized identifiers - Configure data retention policies in Scout Dashboard - Audit span attributes regularly for sensitive data leaks - Consider using span sampling for high-volume sensitive operations ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead: - **Average latency increase**: 0.5-2ms per task - **CPU overhead**: Less than 1% with BatchSpanProcessor - **Memory overhead**: ~30-50MB depending on queue size **Impact varies based on:** - Number of enabled instrumentations - Span processor type (Batch vs Simple) - Task execution volume - Number of custom spans per task #### Optimization Best Practices ##### 1. Use BatchSpanProcessor in Production ```python # Good - batches exports, low overhead span_processor = BatchSpanProcessor(exporter) # Bad - exports every span immediately span_processor = SimpleSpanProcessor(exporter) ``` ##### 2. Limit Custom Span Creation ```python # Good - single span for task with tracer.start_as_current_span("process_order") as span: validate(order) charge(order) fulfill(order) # Avoid - excessive spans for simple operations with tracer.start_as_current_span("process_order"): with tracer.start_span("validate"): validate(order) with tracer.start_span("charge"): charge(order) with tracer.start_span("fulfill"): fulfill(order) ``` ##### 3. Conditional Span Recording ```python span = trace.get_current_span() # Only compute expensive attributes if recording if span.is_recording(): span.set_attribute("data.summary", expensive_computation()) ``` ##### 4. Optimize Attribute Sizes ```python # Good - bounded attribute span.set_attribute("task.result", str(result)[:1000]) # Bad - unbounded attribute span.set_attribute("task.result", str(large_result)) ``` ### Frequently Asked Questions #### Does OpenTelemetry impact Celery task performance? OpenTelemetry adds approximately 0.5-2ms overhead per task with proper configuration (BatchSpanProcessor). This is negligible for most workloads. For high-frequency tasks (>1000/second), consider using sampling. #### Which Celery versions are supported? OpenTelemetry supports Celery 5.3+ with Python 3.9+. Celery 5.4+ with Python 3.11+ is recommended for optimal compatibility and performance. #### How do I trace tasks across multiple services? Use `inject()` when publishing tasks and ensure all services send telemetry to the same Scout Collector. The trace context is automatically propagated through Celery task headers. #### Can I use OpenTelemetry with Celery Beat (scheduled tasks)? Yes! Celery Beat scheduled tasks are automatically instrumented. Each scheduled execution creates a new trace. For correlation with external triggers, inject context when scheduling dynamic tasks. #### How do I monitor task retries? Retries are automatically captured as span events. Use custom attributes to track retry counts: ```python span.set_attribute("celery.task.retries", self.request.retries) span.set_attribute("celery.task.max_retries", self.max_retries) ``` #### Can I use both RabbitMQ and Redis as brokers? Yes, OpenTelemetry instruments both brokers. The `rabbitmq` and `redis` receiver components in the collector can gather infrastructure metrics from both. #### How do I correlate Celery logs with traces? Enable log instrumentation to automatically inject trace IDs: ```bash export OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true ``` Logs will include `trace_id` and `span_id` for correlation in Scout Dashboard. #### What's the difference between task traces and worker metrics? **Task traces** show individual task execution with timing and attributes. Use traces to debug specific task failures or performance issues. **Worker metrics** provide aggregated statistics (queue depth, task rate, worker utilization). Use metrics for monitoring overall system health and capacity planning. #### How do I handle multi-tenant Celery applications? Add tenant context to spans: ```python span.set_attributes({ "tenant.id": tenant_id, "tenant.name": tenant_name, }) ``` Filter traces by tenant in Scout Dashboard. #### Can I disable instrumentation for specific tasks? Use the `@celery.task` decorator options or check task name in hooks: ```python @celery.task(typing=False) # Disable type checking, not instrumentation # Or filter in custom hook def task_hook(span, task_id, args, kwargs): if "health_check" in span.name: span.set_attribute("otel.ignore", True) ``` ### What's Next? Now that your Celery application is instrumented with OpenTelemetry, explore these resources: #### Advanced Topics - **[Custom Python Instrumentation](../custom-instrumentation/python.md)** - Deep dive into manual tracing and advanced patterns - **[FastAPI Instrumentation](./fast-api.md)** - Instrument your API layer for complete request-to-task tracing - **[Redis Monitoring](../../component/redis.md)** - Monitor Celery result backend performance #### Scout Platform Features - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - Set up alerts for task failures, queue depth, and latency thresholds - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** - Build custom dashboards for Celery task monitoring #### Deployment and Operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Set up Scout Collector for local development - **[Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md)** - Production Kubernetes deployment ### Complete Example Here's a complete working example of a FastAPI + Celery application with OpenTelemetry instrumentation: #### Project Structure ```plaintext celery-demo/ ├── celery_demo/ │ ├── __init__.py │ ├── config.py │ ├── main.py │ ├── tasks.py │ └── telemetry.py ├── config/ │ └── otelcol-config.yaml ├── compose.yaml ├── Dockerfile ├── pyproject.toml └── .env ``` #### Dependencies ```toml showLineNumbers title="pyproject.toml" [project] name = "celery-demo" version = "0.1.0" requires-python = ">=3.11" dependencies = [ "fastapi>=0.124.0", "uvicorn[standard]>=0.38.0", "celery>=5.4.0", "redis>=5.0.0", "sqlalchemy>=2.0.0", "opentelemetry-distro>=0.48b0", "opentelemetry-exporter-otlp>=1.27.0", "opentelemetry-instrumentation-celery>=0.48b0", "opentelemetry-instrumentation-fastapi>=0.48b0", "opentelemetry-instrumentation-sqlalchemy>=0.48b0", "opentelemetry-instrumentation-redis>=0.48b0", "opentelemetry-instrumentation-logging>=0.48b0", ] ``` #### Telemetry Setup ```python showLineNumbers title="celery_demo/telemetry.py" import logging import os from celery.signals import worker_process_init from opentelemetry import trace, metrics from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor from opentelemetry.instrumentation.celery import CeleryInstrumentor from opentelemetry.instrumentation.redis import RedisInstrumentor from opentelemetry.instrumentation.logging import LoggingInstrumentor from opentelemetry.sdk.resources import Resource from opentelemetry.semconv.resource import ResourceAttributes logger = logging.getLogger(__name__) OTEL_SERVICE_NAME = os.getenv("OTEL_SERVICE_NAME", "celery-demo") OTEL_ENDPOINT = os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4318") @worker_process_init.connect(weak=False) def init_celery_tracing(*args, **kwargs): """Initialize tracing for Celery worker processes.""" logger.info("Initializing OpenTelemetry for Celery worker") init_telemetry() CeleryInstrumentor().instrument() def init_telemetry(): """Initialize OpenTelemetry tracing and metrics.""" resource = Resource(attributes={ ResourceAttributes.SERVICE_NAME: OTEL_SERVICE_NAME, ResourceAttributes.SERVICE_VERSION: "1.0.0", }) # Setup trace provider trace.set_tracer_provider(TracerProvider(resource=resource)) tracer_provider = trace.get_tracer_provider() span_exporter = OTLPSpanExporter(endpoint=f"{OTEL_ENDPOINT}/v1/traces") span_processor = BatchSpanProcessor(span_exporter) tracer_provider.add_span_processor(span_processor) # Enable logging instrumentation LoggingInstrumentor().instrument(set_logging_format=True) # Setup metrics provider metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"{OTEL_ENDPOINT}/v1/metrics") ) metrics.set_meter_provider( MeterProvider(resource=resource, metric_readers=[metric_reader]) ) logger.info(f"OpenTelemetry initialized for service: {OTEL_SERVICE_NAME}") def setup_telemetry(app, engine): """Configure auto-instrumentation for all components.""" init_telemetry() FastAPIInstrumentor.instrument_app(app) SQLAlchemyInstrumentor().instrument(engine=engine) CeleryInstrumentor().instrument() RedisInstrumentor().instrument() logger.info("OpenTelemetry auto-instrumentation setup complete") ``` #### FastAPI Application ```python showLineNumbers title="celery_demo/main.py" from fastapi import FastAPI, Depends from sqlalchemy.orm import Session from opentelemetry.propagate import inject from . import models, tasks from .database import SessionLocal, engine from .telemetry import setup_telemetry models.Base.metadata.create_all(bind=engine) app = FastAPI() setup_telemetry(app, engine) def get_db(): db = SessionLocal() try: yield db finally: db.close() @app.get("/ping") async def ping(): return {"message": "pong"} @app.post("/tasks/") def create_task(task_data: dict, db: Session = Depends(get_db)): db_task = models.Task(title=task_data.get("title")) db.add(db_task) db.commit() db.refresh(db_task) # Propagate trace context to Celery headers = {} inject(headers) tasks.process_task.apply_async(args=[db_task.id], headers=headers) return {"task_id": db_task.id, "status": "queued"} ``` #### Celery Tasks ```python showLineNumbers title="celery_demo/tasks.py" from celery import Celery from opentelemetry import trace import os import time import logging logger = logging.getLogger(__name__) RABBITMQ_HOST = os.getenv("RABBITMQ_HOST", "rabbitmq") REDIS_HOST = os.getenv("REDIS_HOST", "redis") celery = Celery( "tasks", broker=f"amqp://guest:guest@{RABBITMQ_HOST}//", backend=f"redis://{REDIS_HOST}:6379/0", ) @celery.task def process_task(task_id: int): logger.info(f"Starting to process task {task_id}") tracer = trace.get_tracer(__name__) with tracer.start_as_current_span("process_task") as span: span.set_attribute("task.id", task_id) with tracer.start_span("heavy_processing") as processing_span: time.sleep(2) # Simulate processing processing_span.set_attribute("processing.duration_ms", 2000) span.set_attribute("task.status", "completed") logger.info(f"Task {task_id} completed successfully") return {"task_id": task_id, "status": "completed"} ``` #### Environment Variables ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=celery-demo OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true ``` This complete example is available in our [GitHub examples repository](https://github.com/base-14/examples/tree/main/scout-collector/docker/celery-demo). With instrumentation in place, you can [trace distributed Celery tasks in Scout](https://base14.io/scout/traces) — follow task execution across workers and brokers with full context propagation. ### References - [Official OpenTelemetry Celery Instrumentation](https://opentelemetry-python-contrib.readthedocs.io/en/latest/instrumentation/celery/celery.html) - [OpenTelemetry Python Documentation](https://opentelemetry.io/docs/languages/python/) - [Celery Documentation](https://docs.celeryq.dev/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language --- ## Django OpenTelemetry Instrumentation - ORM, Celery & DRF Tracing :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Django is a high-level Python web framework that encourages rapid development and clean, pragmatic design. As one of the most popular web frameworks for building data-driven applications, Django applications often handle complex business logic, database interactions, and background tasks—making observability critical for maintaining performance and reliability at scale. Django is a batteries-included Python framework. For lighter or async-first options see [Flask](./flask.md), [FastAPI](./fast-api.md), and [Litestar](./litestar.md). This guide demonstrates how to instrument Django applications with OpenTelemetry for comprehensive distributed tracing, metrics collection, and application performance monitoring. We'll cover automatic instrumentation of Django's ORM, views, middleware, template rendering, and Celery background tasks, providing visibility into every layer of your application stack. Django's "batteries-included" philosophy extends to observability through OpenTelemetry's automatic instrumentation libraries. Unlike manual instrumentation approaches, Django applications can achieve comprehensive tracing with minimal code changes—automatically capturing database queries, HTTP requests, cache operations, and asynchronous task execution. We'll explore both automatic and custom instrumentation patterns, including Django-specific considerations like N+1 query detection, PII masking for GDPR compliance, and management command tracing. :::tip TL;DR Install `opentelemetry-instrumentation-django` and `opentelemetry-instrumentation-psycopg`, then initialize tracing in `manage.py` or your WSGI/ASGI entry point using `DjangoInstrumentor().instrument()`. Django's ORM queries, views, middleware, and Celery tasks are traced automatically with no per-view code changes required. ::: ### Who This Guide Is For This guide is designed for: - **Django Developers** building web applications with complex ORM queries and needing visibility into database performance and N+1 query issues - **Backend Engineers** working with Django REST Framework APIs and requiring end-to-end request tracing across services - **DevOps Teams** deploying Django applications with Celery workers and needing distributed tracing across synchronous and asynchronous tasks - **Data Platform Engineers** managing Django-powered data applications with PostgreSQL and requiring query-level performance insights - **Technical Leads** implementing observability standards across Django microservices and ensuring PII compliance in telemetry data ### Overview This guide covers Django OpenTelemetry instrumentation using the official OpenTelemetry Python SDK and Django-specific auto-instrumentation packages. The approach leverages Django's middleware system and signal framework for comprehensive, low-overhead tracing. #### What You'll Learn - Installing and configuring OpenTelemetry SDK for Django with automatic instrumentation - Instrumenting Django ORM queries with full SQL visibility and parameter binding - Tracing Django views, middleware, and template rendering automatically - Setting up Celery distributed tracing for background tasks with context propagation - Implementing Django management command instrumentation for batch jobs - Detecting and resolving N+1 database query issues using span attributes - Masking PII data in traces for GDPR and HIPAA compliance - Configuring Django REST Framework for API endpoint tracing - Optimizing telemetry overhead for high-traffic Django applications - Deploying instrumented Django apps with Gunicorn, uWSGI, or ASGI servers #### Prerequisites **System Requirements:** - **Python:** 3.9+ (3.13+ recommended for latest features) - **Django:** 3.2+ (5.0+ LTS recommended) - **PostgreSQL:** 12+ (18+ recommended) or other supported databases - **Celery:** 5.0+ for background task tracing (optional) - **Redis:** 6.0+ for caching and Celery broker (optional) **Supported Django Versions:** | Django Version | Python Version | OpenTelemetry Support | Status | | -------------- | -------------- | --------------------- | ----------- | | 5.2 LTS | 3.10+ | ✅ Full | Recommended | | 5.1 | 3.10+ | ✅ Full | Current | | 5.0 LTS | 3.10+ | ✅ Full | Supported | | 4.2 LTS | 3.8+ | ✅ Full | Supported | | 4.1 | 3.8+ | ✅ Full | Legacy | | 3.2 LTS | 3.6+ | ⚠️ Limited | EOL (2024) | | 2.x | 3.5+ | ❌ Not supported | EOL | **Instrumented Components:** OpenTelemetry Django instrumentation automatically traces: - ✅ **HTTP Requests** - Django views (function-based and class-based) - ✅ **Database Queries** - Django ORM queries with SQL and parameters - ✅ **Template Rendering** - Django template engine execution - ✅ **Middleware** - All middleware in the processing chain - ✅ **Cache Operations** - Django cache framework (Redis, Memcached) - ✅ **Celery Tasks** - Background task execution with distributed context - ✅ **Management Commands** - Custom Django management commands - ✅ **Django REST Framework** - API endpoints and serializers - ✅ **Authentication** - Login, logout, and permission checks - ✅ **Signals** - Django signal dispatching (with custom instrumentation) :::info Example Application This guide references the [django-postgres example](https://github.com/base-14/examples/tree/main/python/django-postgres) featuring: - **Framework**: Django 5.2 LTS with Django REST Framework - **Database**: PostgreSQL 18 with Django ORM - **Background Jobs**: Celery 5.4+ with Redis broker - **Features**: PII masking, N+1 query detection, JWT authentication - **Deployment**: Gunicorn WSGI server with Docker and Kubernetes ::: ### Installation & Setup Django OpenTelemetry instrumentation requires the core SDK and Django-specific auto-instrumentation packages. The setup process installs dependencies and initializes tracing in your Django application's startup code. import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; **pip (Recommended)** Install OpenTelemetry SDK and Django instrumentation: ```bash title="Terminal" showLineNumbers # Install core OpenTelemetry SDK pip install opentelemetry-api opentelemetry-sdk # Install Django auto-instrumentation pip install opentelemetry-instrumentation-django # Install database instrumentation (PostgreSQL) pip install opentelemetry-instrumentation-psycopg # Install Celery instrumentation (optional) pip install opentelemetry-instrumentation-celery # Install Redis instrumentation (optional) pip install opentelemetry-instrumentation-redis # Install OTLP exporter (send traces to collector) pip install opentelemetry-exporter-otlp # Freeze dependencies pip freeze > requirements.txt ``` **Poetry** Add dependencies to `pyproject.toml`: ```toml title="pyproject.toml" showLineNumbers [tool.poetry.dependencies] python = "^3.10" django = "^5.2" psycopg = {extras = ["binary"], version = "^3.3"} celery = "^5.4" redis = "^5.0" # OpenTelemetry dependencies opentelemetry-api = "^1.41" opentelemetry-sdk = "^1.41" opentelemetry-instrumentation-django = "^0.62b0" opentelemetry-instrumentation-psycopg = "^0.62b0" opentelemetry-instrumentation-celery = "^0.62b0" opentelemetry-instrumentation-redis = "^0.62b0" opentelemetry-exporter-otlp = "^1.41" ``` Install dependencies: ```bash poetry install ``` **Pipenv** Add to `Pipfile`: ```toml title="Pipfile" showLineNumbers [packages] django = "~=5.2" psycopg = {extras = ["binary"], version = "~=3.3"} celery = "~=5.4" redis = "~=5.0" opentelemetry-api = "~=1.41" opentelemetry-sdk = "~=1.41" opentelemetry-instrumentation-django = "~=0.62b0" opentelemetry-instrumentation-psycopg = "~=0.62b0" opentelemetry-instrumentation-celery = "~=0.62b0" opentelemetry-instrumentation-redis = "~=0.62b0" opentelemetry-exporter-otlp = "~=1.41" ``` Install: ```bash pipenv install ``` **Auto-Instrumentation Bootstrap** Use the OpenTelemetry bootstrap command to automatically install all instrumentation packages: ```bash title="Terminal" showLineNumbers # Install bootstrap tool pip install opentelemetry-bootstrap # Auto-detect and install instrumentation for installed packages opentelemetry-bootstrap -a install # This automatically installs: # - opentelemetry-instrumentation-django # - opentelemetry-instrumentation-psycopg # - opentelemetry-instrumentation-celery # - opentelemetry-instrumentation-redis # (based on your installed packages) ``` **Note:** This approach is convenient but installs all detected instrumentations. For production, explicitly specify dependencies in `requirements.txt`. :::tip Django Auto-Instrumentation Django's auto-instrumentation uses middleware injection to capture all HTTP requests automatically. Unlike Flask, you don't need to manually initialize the instrumentor in most cases—adding the middleware is sufficient. ::: ### Configuration Django OpenTelemetry configuration involves initializing the SDK in your application startup and configuring middleware to capture HTTP requests. #### Basic Initialization Create a tracing initialization module: ```python title="myproject/tracing.py" showLineNumbers """OpenTelemetry tracing initialization for Django.""" import os from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.grpc.trace_exporter import OTLPSpanExporter from opentelemetry.sdk.resources import Resource from opentelemetry.instrumentation.django import DjangoInstrumentor from opentelemetry.instrumentation.psycopg import PsycopgInstrumentor def initialize_tracing(): """Initialize OpenTelemetry tracing for Django application.""" # Create resource with service information resource = Resource.create({ "service.name": os.getenv("OTEL_SERVICE_NAME", "django-order-service"), "service.version": os.getenv("APP_VERSION", "1.0.0"), "deployment.environment.name": os.getenv("ENVIRONMENT", "development"), "environment": os.getenv("ENVIRONMENT", "development"), }) # Create tracer provider provider = TracerProvider(resource=resource) # Configure OTLP exporter otlp_exporter = OTLPSpanExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4317"), insecure=os.getenv("OTEL_EXPORTER_OTLP_INSECURE", "true") == "true", ) # Add batch span processor provider.add_span_processor(BatchSpanProcessor(otlp_exporter)) # Set as global tracer provider trace.set_tracer_provider(provider) # Instrument Django automatically DjangoInstrumentor().instrument() # Instrument PostgreSQL PsycopgInstrumentor().instrument() print("OpenTelemetry tracing initialized successfully") ``` #### Django Settings Configuration Update your `settings.py`: ```python title="myproject/settings.py" showLineNumbers # Django settings for instrumented application import os from pathlib import Path BASE_DIR = Path(__file__).resolve().parent.parent # SECURITY WARNING: keep the secret key used in production secret! SECRET_KEY = os.getenv("DJANGO_SECRET_KEY", "dev-secret-key-change-in-production") DEBUG = os.getenv("DEBUG", "True") == "True" ALLOWED_HOSTS = os.getenv("ALLOWED_HOSTS", "localhost,127.0.0.1").split(",") # Application definition INSTALLED_APPS = [ 'django.contrib.admin', 'django.contrib.auth', 'django.contrib.contenttypes', 'django.contrib.sessions', 'django.contrib.messages', 'django.contrib.staticfiles', 'rest_framework', 'orders', # Your app ] MIDDLEWARE = [ 'django.middleware.security.SecurityMiddleware', 'django.contrib.sessions.middleware.SessionMiddleware', 'django.middleware.common.CommonMiddleware', 'django.middleware.csrf.CsrfViewMiddleware', 'django.contrib.auth.middleware.AuthenticationMiddleware', 'django.contrib.messages.middleware.MessageMiddleware', 'django.middleware.clickjacking.XFrameOptionsMiddleware', ] ROOT_URLCONF = 'myproject.urls' # Database configuration DATABASES = { 'default': { 'ENGINE': 'django.db.backends.postgresql', 'NAME': os.getenv('DB_NAME', 'orders'), 'USER': os.getenv('DB_USER', 'postgres'), 'PASSWORD': os.getenv('DB_PASSWORD', 'postgres'), 'HOST': os.getenv('DB_HOST', 'localhost'), 'PORT': os.getenv('DB_PORT', '5432'), } } # Celery Configuration (optional) CELERY_BROKER_URL = os.getenv('CELERY_BROKER_URL', 'redis://localhost:6379/0') CELERY_RESULT_BACKEND = os.getenv('CELERY_RESULT_BACKEND', 'redis://localhost:6379/0') # OpenTelemetry Configuration OTEL_SERVICE_NAME = os.getenv('OTEL_SERVICE_NAME', 'django-order-service') OTEL_EXPORTER_OTLP_ENDPOINT = os.getenv('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4317') ``` #### Initialize in WSGI/ASGI Application Update your WSGI or ASGI application file: ```python title="myproject/wsgi.py" showLineNumbers """ WSGI config for myproject. Initializes OpenTelemetry tracing before application starts. """ import os from django.core.wsgi import get_wsgi_application # Set Django settings module os.environ.setdefault('DJANGO_SETTINGS_MODULE', 'myproject.settings') # Initialize OpenTelemetry tracing BEFORE creating WSGI application from myproject.tracing import initialize_tracing initialize_tracing() # Create WSGI application application = get_wsgi_application() ``` For ASGI (Django Channels): ```python title="myproject/asgi.py" showLineNumbers """ ASGI config for myproject. """ import os from django.core.asgi import get_asgi_application os.environ.setdefault('DJANGO_SETTINGS_MODULE', 'myproject.settings') # Initialize tracing before ASGI application from myproject.tracing import initialize_tracing initialize_tracing() application = get_asgi_application() ``` #### Environment Variables Configure tracing via environment variables: ```bash title=".env" showLineNumbers # Django configuration DJANGO_SECRET_KEY=your-secret-key-here DEBUG=False ALLOWED_HOSTS=localhost,api.example.com ENVIRONMENT=development # Database DB_NAME=orders DB_USER=django DB_PASSWORD=secure-password DB_HOST=postgres DB_PORT=5432 # OpenTelemetry configuration OTEL_SERVICE_NAME=django-order-service OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 OTEL_EXPORTER_OTLP_INSECURE=true OTEL_SEMCONV_STABILITY_OPT_IN=http,database APP_VERSION=1.0.0 # Celery (optional) CELERY_BROKER_URL=redis://localhost:6379/0 CELERY_RESULT_BACKEND=redis://localhost:6379/0 ``` `OTEL_SEMCONV_STABILITY_OPT_IN=http,database` opts the instrumentation into the stable HTTP and database semantic conventions (for example `http.request.method`, `http.response.status_code`, and `db.query.text`). Without it, the instrumentation keeps emitting the older experimental attribute names (`http.method`, `http.status_code`, `db.statement`). Use `http/dup` and `database/dup` instead to emit both old and new during a migration. #### Docker Compose Configuration ```yaml title="docker-compose.yml" showLineNumbers version: '3.9' services: django-app: build: . command: gunicorn myproject.wsgi:application --bind 0.0.0.0:8000 --workers 4 ports: - '8000:8000' environment: OTEL_SERVICE_NAME: django-order-service OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4317 OTEL_EXPORTER_OTLP_INSECURE: 'true' DB_HOST: postgres DB_NAME: orders DB_USER: django DB_PASSWORD: django123 CELERY_BROKER_URL: redis://redis:6379/0 ENVIRONMENT: docker depends_on: - postgres - redis - scout-collector celery-worker: build: . command: celery -A myproject worker --loglevel=info environment: OTEL_SERVICE_NAME: django-celery-worker OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4317 DB_HOST: postgres CELERY_BROKER_URL: redis://redis:6379/0 depends_on: - postgres - redis - scout-collector postgres: image: postgres:18-alpine environment: POSTGRES_DB: orders POSTGRES_USER: django POSTGRES_PASSWORD: django123 volumes: - postgres_data:/var/lib/postgresql/data redis: image: redis:7-alpine ports: - '6379:6379' scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4317:4317' volumes: postgres_data: ``` :::info Scout Integration When using [Base14 Scout](https://base14.io/scout), configure the OTLP endpoint to point to your Scout Collector with authentication headers. Scout provides managed infrastructure optimized for Django applications with high query volume. ::: ### Traces Traces follow a request through your Django application, from the incoming URL route, through middleware and the view, into ORM queries, cache lookups, outbound HTTP calls, and Celery task dispatch, and back out as the response. #### Automatic Trace Collection Once `DjangoInstrumentor` is applied, every request is traced with no per-view code: **Captured Information:** - HTTP method, resolved URL pattern, and status code for each view - Request duration and a span-by-span timing breakdown - Django ORM queries (psycopg / MySQL), including the executed SQL - Redis cache operations (with `RedisInstrumentor`) - Celery task enqueue and execution spans (with `CeleryInstrumentor`) - Exceptions recorded on the failing span with stack traces - Distributed context propagation across services (W3C Trace Context) **Trace Hierarchy:** ```text HTTP Request Span (root: GET /api/orders/) ├── Middleware Span (AuthenticationMiddleware) ├── OrderViewSet.retrieve Span │ ├── ORM Query Span (SELECT ... FROM orders) │ └── Redis GET Span (cache lookup) └── Celery Enqueue Span (send_receipt task) ``` #### Key Tracing Features - **Automatic HTTP tracking**: every URL route is traced with no code changes - **ORM visibility**: Django ORM and raw SQL queries appear as child spans with the executed statement - **CBV and DRF support**: function views, class-based views, and DRF ViewSets are all traced with their resolved route - **Error capturing**: unhandled exceptions and error handlers are recorded with full stack traces - **Context propagation**: distributed traces follow requests across HTTP and Celery boundaries > View traces in your base14 Scout dashboard to follow request flows and find > the slow span in a chain. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics Metrics aggregate runtime measurements over time, such as request rate, latency distributions, and error counts. Where traces explain a single request, metrics power dashboards and alerts across all of them. #### Enable the Meter Provider Configure a `MeterProvider` with an OTLP exporter alongside your tracer setup so metrics are exported to Scout: ```python title="otel_config.py" showLineNumbers import os from opentelemetry import metrics from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.sdk.resources import Resource from opentelemetry.exporter.otlp.proto.grpc.metric_exporter import ( OTLPMetricExporter, ) # Same OTLP endpoint and gRPC transport as the tracer setup above resource = Resource.create( {"service.name": os.getenv("OTEL_SERVICE_NAME", "django-order-service")} ) reader = PeriodicExportingMetricReader( OTLPMetricExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4317"), insecure=os.getenv("OTEL_EXPORTER_OTLP_INSECURE", "true") == "true", ), export_interval_millis=15000, ) metrics.set_meter_provider(MeterProvider(resource=resource, metric_readers=[reader])) ``` #### Custom Business Metrics Django auto-instrumentation already emits the standard HTTP server metrics, including the `http.server.request.duration` histogram (its sample count gives you request rate, latency percentiles, and error ratio per route), so there is no need to hand-roll request latency. Reserve custom metrics for business events the instrumentation cannot see, such as domain actions: ```python title="apps/articles/views.py" showLineNumbers from opentelemetry import metrics meter = metrics.get_meter("django-app") articles_created = meter.create_counter( "articles.created", unit="1", description="Articles created", ) # Inside the view, after the article is persisted: articles_created.add(1, {"author_id": str(user_id)}) ``` > View metrics in your base14 Scout dashboard to chart request rate, latency > percentiles, and error ratio per route from the automatic HTTP histogram, > alongside your custom business counters. ##### Reference [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) ### Production Configuration Production deployments require optimized sampling, secure credential management, and performance tuning for high-traffic Django applications. #### Production Tracing Initialization ```python title="myproject/tracing.py" showLineNumbers """Production-optimized OpenTelemetry tracing configuration.""" import os from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.sdk.trace.sampling import TraceIdRatioBased, ParentBased from opentelemetry.exporter.otlp.proto.grpc.trace_exporter import OTLPSpanExporter from opentelemetry.sdk.resources import Resource from opentelemetry.instrumentation.django import DjangoInstrumentor from opentelemetry.instrumentation.psycopg import PsycopgInstrumentor from opentelemetry.instrumentation.redis import RedisInstrumentor def initialize_tracing(): """Initialize production-grade OpenTelemetry tracing.""" # Create resource with comprehensive service information resource = Resource.create({ "service.name": os.getenv("OTEL_SERVICE_NAME", "django-order-service"), "service.version": os.getenv("APP_VERSION", "1.0.0"), "deployment.environment.name": os.getenv("ENVIRONMENT", "development"), "environment": os.getenv("ENVIRONMENT", "development"), "cloud.provider": os.getenv("CLOUD_PROVIDER", "aws"), "cloud.region": os.getenv("AWS_REGION", "us-east-1"), "k8s.cluster.name": os.getenv("K8S_CLUSTER", "production"), "k8s.namespace.name": os.getenv("K8S_NAMESPACE", "default"), "k8s.pod.name": os.getenv("HOSTNAME", "unknown"), }) # Configure sampling (10% of traces in production) sample_rate = float(os.getenv("OTEL_TRACE_SAMPLE_RATE", "0.1")) sampler = ParentBased(root=TraceIdRatioBased(sample_rate)) # Create tracer provider with sampler provider = TracerProvider(resource=resource, sampler=sampler) # Configure OTLP exporter with authentication otlp_exporter = OTLPSpanExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "https://scout.base14.io:4317"), headers={ "authorization": f"Bearer {os.getenv('SCOUT_API_KEY', '')}", }, insecure=False, ) # Configure batch span processor with production settings batch_processor = BatchSpanProcessor( otlp_exporter, max_queue_size=2048, max_export_batch_size=512, schedule_delay_millis=5000, export_timeout_millis=30000, ) provider.add_span_processor(batch_processor) trace.set_tracer_provider(provider) # Instrument Django with exclude patterns DjangoInstrumentor().instrument( excluded_urls="health/,readiness/,liveness/,metrics/,favicon.ico" ) # Instrument database PsycopgInstrumentor().instrument(enable_commenter=True, commenter_options={}) # Instrument Redis RedisInstrumentor().instrument() print(f"OpenTelemetry initialized: {resource.attributes.get('service.name')} " f"v{resource.attributes.get('service.version')} " f"(sample rate: {sample_rate})") ``` #### Gunicorn Production Configuration ```python title="gunicorn.conf.py" showLineNumbers """Gunicorn configuration for production deployment.""" import multiprocessing import os # Server socket bind = "0.0.0.0:8000" backlog = 2048 # Worker processes workers = int(os.getenv("GUNICORN_WORKERS", multiprocessing.cpu_count() * 2 + 1)) worker_class = "sync" worker_connections = 1000 max_requests = 1000 max_requests_jitter = 50 timeout = 30 keepalive = 5 # Logging accesslog = "-" errorlog = "-" loglevel = os.getenv("LOG_LEVEL", "info") access_log_format = '%(h)s %(l)s %(u)s %(t)s "%(r)s" %(s)s %(b)s "%(f)s" "%(a)s" trace_id=%(L)s' # Process naming proc_name = "django-order-service" # Server hooks for tracing initialization def on_starting(server): """Initialize OpenTelemetry before workers start.""" from myproject.tracing import initialize_tracing initialize_tracing() def post_worker_init(worker): """Log worker initialization.""" print(f"Worker {worker.pid} initialized with OpenTelemetry tracing") ``` #### Dockerfile (Multi-Stage Build) ```dockerfile title="Dockerfile" showLineNumbers # Stage 1: Build dependencies FROM python:3.13-slim AS builder WORKDIR /app # Install system dependencies RUN apt-get update && apt-get install -y \ gcc \ postgresql-client \ libpq-dev \ && rm -rf /var/lib/apt/lists/* # Copy requirements and install dependencies COPY requirements.txt . RUN pip wheel --no-cache-dir --no-deps --wheel-dir /app/wheels -r requirements.txt # Stage 2: Runtime image FROM python:3.13-slim WORKDIR /app # Install runtime dependencies RUN apt-get update && apt-get install -y \ libpq5 \ && rm -rf /var/lib/apt/lists/* # Copy wheels from builder COPY --from=builder /app/wheels /wheels COPY --from=builder /app/requirements.txt . # Install Python packages RUN pip install --no-cache /wheels/* # Copy application code COPY . . # Create non-root user RUN useradd -m -u 1000 django && chown -R django:django /app USER django # Environment variables ENV PYTHONUNBUFFERED=1 ENV DJANGO_SETTINGS_MODULE=myproject.settings ENV OTEL_PYTHON_DJANGO_INSTRUMENT=true # Expose port EXPOSE 8000 # Health check HEALTHCHECK --interval=30s --timeout=3s --start-period=40s --retries=3 \ CMD python -c "import requests; requests.get('http://localhost:8000/health/')" # Run Gunicorn CMD ["gunicorn", "myproject.wsgi:application", "--config", "gunicorn.conf.py"] ``` #### Kubernetes Deployment ```yaml title="k8s/deployment.yaml" showLineNumbers apiVersion: apps/v1 kind: Deployment metadata: name: django-order-service labels: app: django-order-service spec: replicas: 3 selector: matchLabels: app: django-order-service template: metadata: labels: app: django-order-service annotations: prometheus.io/scrape: 'true' prometheus.io/port: '8000' spec: containers: - name: django-app image: django-order-service:latest ports: - containerPort: 8000 name: http env: - name: OTEL_SERVICE_NAME value: django-order-service - name: OTEL_EXPORTER_OTLP_ENDPOINT value: http://scout-collector:4317 - name: SCOUT_API_KEY valueFrom: secretKeyRef: name: scout-credentials key: api-key - name: OTEL_TRACE_SAMPLE_RATE value: '0.1' - name: ENVIRONMENT value: demo - name: APP_VERSION value: '1.0.0' - name: K8S_NAMESPACE valueFrom: fieldRef: fieldPath: metadata.namespace - name: HOSTNAME valueFrom: fieldRef: fieldPath: metadata.name - name: DB_HOST value: postgres-service - name: DB_NAME value: orders - name: DB_USER valueFrom: secretKeyRef: name: postgres-credentials key: username - name: DB_PASSWORD valueFrom: secretKeyRef: name: postgres-credentials key: password - name: CELERY_BROKER_URL value: redis://redis-service:6379/0 resources: requests: memory: '512Mi' cpu: '250m' limits: memory: '1Gi' cpu: '1000m' livenessProbe: httpGet: path: /health/ port: 8000 initialDelaySeconds: 30 periodSeconds: 10 readinessProbe: httpGet: path: /readiness/ port: 8000 initialDelaySeconds: 10 periodSeconds: 5 --- apiVersion: v1 kind: Service metadata: name: django-order-service spec: selector: app: django-order-service ports: - protocol: TCP port: 80 targetPort: 8000 type: ClusterIP ``` ### Django-Specific Features Django's auto-instrumentation automatically captures views, ORM queries, middleware, and template rendering without manual span creation. #### View Auto-Instrumentation All Django views are automatically instrumented: ```python title="orders/views.py" showLineNumbers """Django views with automatic tracing.""" from django.shortcuts import render, get_object_or_404 from django.http import JsonResponse from django.views import View from django.views.decorators.http import require_http_methods from rest_framework import viewsets from rest_framework.decorators import api_view from .models import Order from .serializers import OrderSerializer # Function-based view (automatically traced) @require_http_methods(["GET"]) def order_list(request): """Get all orders - span name: 'GET /orders/'""" orders = Order.objects.all().select_related('user') data = [{"id": o.id, "product": o.product_name, "amount": str(o.amount)} for o in orders] return JsonResponse({"orders": data}) # Function-based view with parameter def order_detail(request, order_id): """Get order by ID - span name: 'GET /orders/{order_id}/'""" order = get_object_or_404(Order, id=order_id) return JsonResponse({ "id": order.id, "product": order.product_name, "amount": str(order.amount), "status": order.status }) # Class-based view (automatically traced) class OrderCreateView(View): """Create order - span name: 'POST /orders/create/'""" def post(self, request): # Business logic automatically traced order = Order.objects.create( user_id=request.user.id, product_name=request.POST.get('product'), amount=request.POST.get('amount'), status='pending' ) return JsonResponse({"id": order.id, "status": "created"}, status=201) # Django REST Framework ViewSet (automatically traced) class OrderViewSet(viewsets.ModelViewSet): """ API endpoint for orders. Each action creates span: 'GET /api/orders/', 'POST /api/orders/', etc. """ queryset = Order.objects.all() serializer_class = OrderSerializer def get_queryset(self): # Query optimization automatically traced queryset = super().get_queryset() return queryset.select_related('user').prefetch_related('items') def perform_create(self, serializer): # Custom logic traced as part of the request span order = serializer.save() # Trigger async task (traced separately) from .tasks import process_order process_order.delay(order.id) ``` #### Django ORM Query Instrumentation Database queries are automatically traced with full SQL visibility: ```python title="orders/models.py" showLineNumbers """Django models with automatic query tracing.""" from django.db import models from django.contrib.auth.models import User from decimal import Decimal class Order(models.Model): """Order model - all queries automatically traced.""" user = models.ForeignKey(User, on_delete=models.CASCADE, related_name='orders') product_name = models.CharField(max_length=200) amount = models.DecimalField(max_digits=10, decimal_places=2) status = models.CharField(max_length=50, default='pending') created_at = models.DateTimeField(auto_now_add=True) updated_at = models.DateTimeField(auto_now=True) class Meta: db_table = 'orders' indexes = [ models.Index(fields=['user', 'status']), models.Index(fields=['created_at']), ] def __str__(self): return f"Order {self.id} - {self.product_name}" # Custom manager methods are traced @classmethod def get_user_orders(cls, user_id): """Get orders for user - traced as SELECT query with JOIN.""" return cls.objects.filter(user_id=user_id).select_related('user') @classmethod def get_recent_orders(cls, limit=10): """Get recent orders - traced with LIMIT clause.""" return cls.objects.order_by('-created_at')[:limit] class OrderItem(models.Model): """Order line items.""" order = models.ForeignKey(Order, on_delete=models.CASCADE, related_name='items') product_sku = models.CharField(max_length=100) quantity = models.IntegerField(default=1) unit_price = models.DecimalField(max_digits=10, decimal_places=2) class Meta: db_table = 'order_items' ``` ```python title="orders/services.py" showLineNumbers """Business logic with ORM query tracing.""" from django.db import transaction from django.db.models import Sum, Count, Q from opentelemetry import trace from .models import Order, OrderItem tracer = trace.get_tracer(__name__) class OrderService: """Service layer with automatic query tracing.""" @staticmethod def create_order_with_items(user, items_data): """ Create order with items in transaction. All queries traced automatically with transaction context. """ with transaction.atomic(): # INSERT query automatically traced order = Order.objects.create( user=user, product_name=items_data[0]['product'], amount=sum(item['quantity'] * item['price'] for item in items_data), status='pending' ) # Bulk INSERT traced order_items = [ OrderItem( order=order, product_sku=item['sku'], quantity=item['quantity'], unit_price=item['price'] ) for item in items_data ] OrderItem.objects.bulk_create(order_items) return order @staticmethod def get_order_analytics(user_id): """ Aggregate query automatically traced. Span includes: SELECT COUNT(*), SUM(amount), GROUP BY """ return Order.objects.filter(user_id=user_id).aggregate( total_orders=Count('id'), total_spent=Sum('amount') ) @staticmethod def search_orders(query): """ Complex query with Q objects - traced with full WHERE clause. """ return Order.objects.filter( Q(product_name__icontains=query) | Q(status__icontains=query) ).select_related('user').prefetch_related('items') ``` #### Middleware Tracing All middleware in the processing chain is automatically traced: ```python title="myproject/middleware.py" showLineNumbers """Custom middleware with automatic tracing.""" from opentelemetry import trace from django.utils.deprecation import MiddlewareMixin tracer = trace.get_tracer(__name__) class CustomHeaderMiddleware(MiddlewareMixin): """ Custom middleware - automatically creates child span. Span name: 'CustomHeaderMiddleware.process_request' """ def process_request(self, request): # Get current span (created by Django instrumentation) current_span = trace.get_current_span() # Add custom attributes current_span.set_attribute("http.custom_header", request.META.get('HTTP_X_CUSTOM', 'none')) current_span.set_attribute("request.user.authenticated", request.user.is_authenticated) if request.user.is_authenticated: current_span.set_attribute("user.id", str(request.user.id)) current_span.set_attribute("user.username", request.user.username) return None def process_response(self, request, response): # Add response attributes current_span = trace.get_current_span() current_span.set_attribute("http.response.body.size", len(response.content)) return response class PerformanceMonitoringMiddleware(MiddlewareMixin): """Monitor slow requests with custom spans.""" def process_view(self, request, view_func, view_args, view_kwargs): # Create custom span for view execution with tracer.start_as_current_span("view_execution") as span: span.set_attribute("view.name", view_func.__name__) span.set_attribute("view.module", view_func.__module__) # View execution happens here (automatically traced) return None ``` #### Template Rendering Tracing Django template rendering is automatically traced: ```python title="orders/views.py" showLineNumbers """Template views with automatic rendering traces.""" from django.shortcuts import render from .models import Order def order_list_html(request): """ Render template - creates two child spans: 1. SELECT query for Order.objects.all() 2. Template rendering: 'orders/list.html' """ orders = Order.objects.all().select_related('user') # Template rendering automatically traced return render(request, 'orders/list.html', { 'orders': orders, 'title': 'Order List' }) def order_detail_html(request, order_id): """ Complex template with includes - each template traced separately: - 'orders/detail.html' - 'orders/includes/order_summary.html' - 'orders/includes/order_items.html' """ order = Order.objects.get(id=order_id) return render(request, 'orders/detail.html', {'order': order}) ``` #### Celery Task Tracing Celery tasks are automatically traced with distributed context propagation: ```python title="orders/tasks.py" showLineNumbers """Celery tasks with automatic distributed tracing.""" from celery import shared_task from opentelemetry import trace from django.core.mail import send_mail from .models import Order tracer = trace.get_tracer(__name__) @shared_task def process_order(order_id): """ Process order asynchronously. Automatically creates span: 'orders.tasks.process_order' Trace context propagated from parent request. """ # Get current span (linked to original request via trace context) current_span = trace.get_current_span() current_span.set_attribute("order.id", order_id) # Database query traced automatically order = Order.objects.select_related('user').get(id=order_id) # Business logic if order.amount > 1000: # Call external service (traced if instrumented) validate_high_value_order(order) # Update status (UPDATE query traced) order.status = 'processing' order.save() # Send notification (SMTP traced if instrumented) send_order_confirmation_email(order) current_span.set_attribute("order.status", "completed") return {"order_id": order_id, "status": "processed"} @shared_task def send_order_confirmation_email(order): """Send email - traced as child span.""" with tracer.start_as_current_span("send_confirmation_email") as span: span.set_attribute("email.to", order.user.email) span.set_attribute("order.id", order.id) send_mail( subject=f'Order Confirmation - {order.id}', message=f'Your order for {order.product_name} has been confirmed.', from_email='noreply@example.com', recipient_list=[order.user.email], ) def validate_high_value_order(order): """Custom validation with manual span.""" with tracer.start_as_current_span("validate_high_value_order") as span: span.set_attribute("order.id", order.id) span.set_attribute("order.amount", float(order.amount)) # Complex validation logic if order.amount > 10000: span.set_attribute("validation.requires_approval", True) # Trigger approval workflow else: span.set_attribute("validation.auto_approved", True) ``` Initialize Celery with tracing: ```python title="myproject/celery.py" showLineNumbers """Celery configuration with OpenTelemetry.""" import os from celery import Celery from celery.signals import worker_process_init # Set Django settings module os.environ.setdefault('DJANGO_SETTINGS_MODULE', 'myproject.settings') app = Celery('myproject') app.config_from_object('django.conf:settings', namespace='CELERY') app.autodiscover_tasks() @worker_process_init.connect def init_tracing_on_worker(**kwargs): """Initialize OpenTelemetry in Celery worker process.""" from myproject.tracing import initialize_tracing initialize_tracing() print("OpenTelemetry initialized in Celery worker") ``` ### Custom Instrumentation While Django auto-instrumentation covers most use cases, custom spans are needed for specific business logic or external integrations. #### Manual Span Creation ```python title="orders/services.py" showLineNumbers """Custom instrumentation for business logic.""" from opentelemetry import trace from opentelemetry.trace import Status, StatusCode from django.db import transaction from .models import Order tracer = trace.get_tracer(__name__) class PaymentService: """Payment processing with custom instrumentation.""" @staticmethod def process_payment(order_id, payment_method): """Process payment with custom span.""" with tracer.start_as_current_span("process_payment") as span: span.set_attribute("order.id", order_id) span.set_attribute("payment.method", payment_method) try: # Get order (automatically traced) order = Order.objects.get(id=order_id) span.set_attribute("payment.amount", float(order.amount)) # Validate payment method PaymentService._validate_payment_method(payment_method) # Call external payment gateway transaction_id = PaymentService._charge_payment_gateway( order.amount, payment_method ) span.set_attribute("payment.transaction_id", transaction_id) span.set_status(Status(StatusCode.OK)) return {"success": True, "transaction_id": transaction_id} except Exception as e: span.set_status(Status(StatusCode.ERROR, str(e))) span.record_exception(e) raise @staticmethod def _validate_payment_method(method): """Validation with custom span.""" with tracer.start_as_current_span("validate_payment_method") as span: span.set_attribute("payment.method", method) valid_methods = ["credit_card", "debit_card", "paypal"] if method not in valid_methods: span.set_status(Status(StatusCode.ERROR, "Invalid payment method")) raise ValueError(f"Invalid payment method: {method}") span.set_attribute("validation.result", "valid") @staticmethod def _charge_payment_gateway(amount, method): """External API call with custom span.""" with tracer.start_as_current_span( "payment_gateway.charge", kind=trace.SpanKind.CLIENT ) as span: span.set_attribute("payment.amount", float(amount)) span.set_attribute("payment.method", method) span.set_attribute("payment.gateway", "stripe") # Simulate external API call import requests response = requests.post( "https://api.stripe.com/v1/charges", json={"amount": float(amount), "method": method}, timeout=10 ) span.set_attribute("http.response.status_code", response.status_code) if response.status_code == 200: transaction_id = response.json().get("id") span.set_attribute("payment.transaction_id", transaction_id) return transaction_id else: span.set_status(Status(StatusCode.ERROR, "Payment failed")) raise Exception("Payment gateway error") ``` #### Django Management Command Tracing ```python title="orders/management/commands/process_pending_orders.py" showLineNumbers """Management command with custom instrumentation.""" from django.core.management.base import BaseCommand from opentelemetry import trace from orders.models import Order from orders.tasks import process_order tracer = trace.get_tracer(__name__) class Command(BaseCommand): help = 'Process all pending orders' def add_arguments(self, parser): parser.add_argument('--limit', type=int, default=100, help='Max orders to process') parser.add_argument('--dry-run', action='store_true', help='Dry run mode') def handle(self, *args, **options): """Execute command with custom tracing.""" with tracer.start_as_current_span("management_command.process_pending_orders") as span: limit = options['limit'] dry_run = options['dry_run'] span.set_attribute("command.limit", limit) span.set_attribute("command.dry_run", dry_run) # Query pending orders (automatically traced) pending_orders = Order.objects.filter(status='pending')[:limit] count = pending_orders.count() span.set_attribute("orders.pending_count", count) if dry_run: self.stdout.write(f"[DRY RUN] Would process {count} orders") span.set_attribute("command.result", "dry_run") return # Process each order processed = 0 failed = 0 for order in pending_orders: with tracer.start_as_current_span("process_single_order") as order_span: order_span.set_attribute("order.id", order.id) try: # Trigger Celery task (traced separately) process_order.delay(order.id) processed += 1 order_span.set_status(trace.Status(trace.StatusCode.OK)) except Exception as e: failed += 1 order_span.set_status(trace.Status(trace.StatusCode.ERROR, str(e))) order_span.record_exception(e) span.set_attribute("orders.processed_count", processed) span.set_attribute("orders.failed_count", failed) self.stdout.write(self.style.SUCCESS( f'Processed {processed} orders, {failed} failed' )) ``` #### N+1 Query Detection Add custom span attributes to detect N+1 query patterns: ```python title="orders/utils.py" showLineNumbers """Utilities for detecting N+1 queries.""" from django.db import connection, reset_queries from django.conf import settings from opentelemetry import trace from functools import wraps tracer = trace.get_tracer(__name__) def detect_n_plus_one(func): """Decorator to detect N+1 query patterns.""" @wraps(func) def wrapper(*args, **kwargs): if not settings.DEBUG: return func(*args, **kwargs) reset_queries() result = func(*args, **kwargs) # Analyze query patterns queries = connection.queries query_count = len(queries) # Get current span current_span = trace.get_current_span() current_span.set_attribute("db.query_count", query_count) # Detect potential N+1 similar_queries = {} for query in queries: sql = query['sql'].split('WHERE')[0] # Group by base query similar_queries[sql] = similar_queries.get(sql, 0) + 1 # Flag if any query executed multiple times max_repetitions = max(similar_queries.values()) if similar_queries else 0 if max_repetitions > 5: current_span.set_attribute("db.potential_n_plus_one", True) current_span.set_attribute("db.max_query_repetitions", max_repetitions) return result return wrapper ``` Usage: ```python title="orders/views.py" showLineNumbers from orders.utils import detect_n_plus_one @detect_n_plus_one def get_all_orders_with_users(request): """This will flag N+1 if select_related is missing.""" # BAD: N+1 query (flagged in span attributes) orders = Order.objects.all() for order in orders: print(order.user.username) # Separate query for each order # GOOD: Optimized query orders = Order.objects.all().select_related('user') for order in orders: print(order.user.username) # No extra queries return JsonResponse({"count": len(orders)}) ``` ### Running Your Application Django applications can run with various WSGI/ASGI servers. OpenTelemetry instrumentation works with all standard deployment methods. #### Development Server ```bash title="Terminal" showLineNumbers # Run Django development server with tracing python manage.py runserver # Access application curl http://localhost:8000/orders/ # Run Celery worker (separate terminal) celery -A myproject worker --loglevel=info # Run Celery beat (scheduled tasks) celery -A myproject beat --loglevel=info ``` #### Gunicorn (Production WSGI) ```bash title="Terminal" showLineNumbers # Run with Gunicorn gunicorn myproject.wsgi:application \ --bind 0.0.0.0:8000 \ --workers 4 \ --config gunicorn.conf.py # With environment variables OTEL_SERVICE_NAME=django-order-service \ OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 \ SCOUT_API_KEY=your_api_key \ gunicorn myproject.wsgi:application --bind 0.0.0.0:8000 ``` #### uWSGI (Alternative WSGI) ```ini title="uwsgi.ini" showLineNumbers [uwsgi] module = myproject.wsgi:application master = true processes = 4 socket = /tmp/myproject.sock chmod-socket = 666 vacuum = true die-on-term = true # OpenTelemetry environment env = OTEL_SERVICE_NAME=django-order-service env = OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 ``` Run: ```bash uwsgi --ini uwsgi.ini ``` #### Daphne (ASGI for Django Channels) ```bash title="Terminal" showLineNumbers # Run with Daphne for async/WebSocket support daphne -b 0.0.0.0 -p 8000 myproject.asgi:application # With environment variables OTEL_SERVICE_NAME=django-channels \ daphne myproject.asgi:application ``` #### Docker Deployment ```bash title="Terminal" showLineNumbers # Build Docker image docker build -t django-order-service:latest . # Run container docker run -p 8000:8000 \ -e OTEL_SERVICE_NAME=django-order-service \ -e OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 \ -e SCOUT_API_KEY=your_api_key \ -e DB_HOST=postgres \ -e DB_NAME=orders \ django-order-service:latest # Run with Docker Compose docker-compose up -d # Check logs docker-compose logs -f django-app # Run migrations docker-compose exec django-app python manage.py migrate # Create superuser docker-compose exec django-app python manage.py createsuperuser ``` #### Kubernetes Deployment ```bash title="Terminal" showLineNumbers # Deploy to Kubernetes kubectl apply -f k8s/deployment.yaml # Check pod status kubectl get pods -l app=django-order-service # View logs kubectl logs -f deployment/django-order-service # Run migrations (one-time job) kubectl run django-migrate --rm -i --tty \ --image=django-order-service:latest \ --restart=Never \ --command -- python manage.py migrate # Access application kubectl port-forward deployment/django-order-service 8000:8000 curl http://localhost:8000/orders/ ``` ### Troubleshooting #### Issue 1: No Traces Generated **Symptoms:** Django application starts but no traces appear in collector. **Diagnosis:** ```python # Add debug logging to tracing initialization import logging logging.basicConfig(level=logging.DEBUG) from myproject.tracing import initialize_tracing initialize_tracing() ``` **Solution:** Ensure Django instrumentation is initialized before application starts: ```python title="myproject/wsgi.py" showLineNumbers # INCORRECT: Instrumentation after WSGI app creation from django.core.wsgi import get_wsgi_application application = get_wsgi_application() from myproject.tracing import initialize_tracing # TOO LATE! initialize_tracing() # CORRECT: Instrumentation before WSGI app from myproject.tracing import initialize_tracing initialize_tracing() # Initialize first from django.core.wsgi import get_wsgi_application application = get_wsgi_application() ``` #### Issue 2: Database Queries Not Traced **Symptoms:** HTTP requests create spans but SQL queries are missing. **Solution:** Instrument the database driver explicitly: ```python title="myproject/tracing.py" showLineNumbers from opentelemetry.instrumentation.psycopg import PsycopgInstrumentor # For PostgreSQL with psycopg PsycopgInstrumentor().instrument(enable_commenter=True) # For MySQL from opentelemetry.instrumentation.pymysql import PyMySQLInstrumentor PyMySQLInstrumentor().instrument() # For SQLite (Django default DB for development) from opentelemetry.instrumentation.sqlite3 import SQLite3Instrumentor SQLite3Instrumentor().instrument() ``` #### Issue 3: Celery Tasks Not Linked to Parent Trace **Symptoms:** Celery task spans exist but are disconnected from the originating HTTP request. **Solution:** Ensure Celery instrumentation is initialized in worker process: ```python title="myproject/celery.py" showLineNumbers from celery import Celery from celery.signals import worker_process_init, worker_process_shutdown from opentelemetry.instrumentation.celery import CeleryInstrumentor app = Celery('myproject') @worker_process_init.connect def init_celery_tracing(**kwargs): """Initialize tracing in each worker process.""" from myproject.tracing import initialize_tracing initialize_tracing() # Instrument Celery CeleryInstrumentor().instrument() @worker_process_shutdown.connect def shutdown_tracing(**kwargs): """Clean shutdown of tracing.""" from opentelemetry import trace trace.get_tracer_provider().shutdown() ``` #### Issue 4: High Memory Usage with Tracing **Symptoms:** Django application memory grows continuously with tracing enabled. **Solution:** Configure batch span processor limits: ```python title="myproject/tracing.py" showLineNumbers from opentelemetry.sdk.trace.export import BatchSpanProcessor # Reduce memory footprint batch_processor = BatchSpanProcessor( otlp_exporter, max_queue_size=1024, # Reduced from default 2048 max_export_batch_size=256, # Reduced from default 512 schedule_delay_millis=3000, # Export more frequently ) ``` #### Issue 5: Middleware Order Causing Issues **Symptoms:** Some requests traced, others not, or tracing interferes with authentication. **Solution:** Django's auto-instrumentation injects middleware automatically. Ensure proper ordering: ```python title="settings.py" showLineNumbers MIDDLEWARE = [ # OpenTelemetry middleware injected here automatically (first) 'django.middleware.security.SecurityMiddleware', 'django.contrib.sessions.middleware.SessionMiddleware', 'django.middleware.common.CommonMiddleware', 'django.middleware.csrf.CsrfViewMiddleware', 'django.contrib.auth.middleware.AuthenticationMiddleware', # After session # Custom middleware after auth 'myproject.middleware.CustomHeaderMiddleware', ] ``` ### Security Considerations #### PII Data Masking Django applications often handle sensitive user data. Implement custom span processors to mask PII: ```python title="myproject/tracing.py" showLineNumbers """PII masking for Django tracing.""" import re from opentelemetry.sdk.trace import SpanProcessor, ReadableSpan class PIIMaskingSpanProcessor(SpanProcessor): """Mask PII data in span attributes.""" EMAIL_PATTERN = re.compile(r'[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}') PHONE_PATTERN = re.compile(r'\b\d{3}[-.]?\d{3}[-.]?\d{4}\b') SSN_PATTERN = re.compile(r'\b\d{3}-\d{2}-\d{4}\b') def on_start(self, span: "ReadableSpan", parent_context=None) -> None: """Mask PII in span name and attributes on span start.""" # Get writable span if hasattr(span, '_name'): span._name = self._mask_pii(span._name) def on_end(self, span: ReadableSpan) -> None: """Mask PII in final span data.""" if hasattr(span, 'attributes'): for key, value in span.attributes.items(): if isinstance(value, str): span.attributes[key] = self._mask_pii(value) def _mask_pii(self, text: str) -> str: """Mask sensitive patterns in text.""" if not isinstance(text, str): return text # Mask email addresses text = self.EMAIL_PATTERN.sub('***@***.**', text) # Mask phone numbers text = self.PHONE_PATTERN.sub('***-***-****', text) # Mask SSN text = self.SSN_PATTERN.sub('***-**-****', text) return text def shutdown(self) -> None: pass def force_flush(self, timeout_millis: int = 30000) -> bool: return True # Add to tracer provider def initialize_tracing(): # ... existing setup ... provider.add_span_processor(PIIMaskingSpanProcessor()) provider.add_span_processor(BatchSpanProcessor(otlp_exporter)) ``` #### SQL Parameter Obfuscation Database queries may contain sensitive values. The query text lands on the span as `db.query.text` only when `OTEL_SEMCONV_STABILITY_OPT_IN` includes `database` and `opentelemetry-instrumentation-psycopg` is `>=0.62b0`; on older versions, or without the opt-in, the attribute is named `db.statement` instead. ```python title="myproject/tracing.py" showLineNumbers """SQL query sanitization.""" from opentelemetry.instrumentation.psycopg import PsycopgInstrumentor # Enable SQL commenter to identify queries, but disable parameter logging PsycopgInstrumentor().instrument( enable_commenter=True, commenter_options={ "db_driver": True, "db_framework": True, "opentelemetry_values": False, # Don't include parameter values } ) ``` Custom query sanitization: ```python title="myproject/middleware.py" showLineNumbers """Sanitize database queries in spans.""" import re from opentelemetry import trace class QuerySanitizationMiddleware: """Sanitize SQL queries to remove sensitive data.""" def __init__(self, get_response): self.get_response = get_response def __call__(self, request): response = self.get_response(request) # Post-process spans to sanitize queries current_span = trace.get_current_span() if hasattr(current_span, 'attributes'): if 'db.query.text' in current_span.attributes: # Replace parameter values with placeholders sql = current_span.attributes['db.query.text'] # Remove values: WHERE email = 'user@example.com' -> WHERE email = ? sanitized = re.sub(r"= '.*?'", "= ?", sql) current_span.attributes['db.query.text'] = sanitized return response ``` #### GDPR Compliance For GDPR compliance, exclude user-identifying information: ```python title="myproject/tracing.py" showLineNumbers """GDPR-compliant tracing configuration.""" def initialize_tracing_gdpr_compliant(): """Initialize tracing without collecting user PII.""" # ... existing setup ... # Instrument Django with URL exclusions from opentelemetry.instrumentation.django import DjangoInstrumentor DjangoInstrumentor().instrument( # Exclude endpoints that handle PII excluded_urls="admin/,accounts/profile/,api/users/", # Disable automatic user context request_hook=None, response_hook=None, ) # Configure span limits to prevent large payloads from opentelemetry.sdk.trace import TracerProvider provider = TracerProvider( resource=resource, span_limits=SpanLimits( max_attributes=32, max_events=32, max_links=32, max_attribute_length=256, ), ) ``` ### Performance Considerations #### Tracing Overhead Metrics Measured performance impact of OpenTelemetry on Django applications: | Configuration | Latency (p50) | Latency (p99) | Throughput | Memory | | ------------------ | ------------- | ------------- | ---------- | ------- | | **No Tracing** | 15ms | 45ms | 8,000 rps | 250MB | | **Tracing (100%)** | 16ms (+6%) | 50ms (+11%) | 7,500 rps | 320MB | | **Tracing (10%)** | 15ms (+<1%)| 46ms (+2%) | 7,900 rps | 270MB | **Key Findings:** - Sampling at 10% reduces overhead to negligible levels - ORM query tracing adds ~1ms per complex query - Template rendering tracing: <0.5ms overhead - Celery task tracing: <2ms overhead per task #### Optimization Strategies ##### 1. Exclude High-Volume Endpoints ```python title="myproject/tracing.py" showLineNumbers from opentelemetry.instrumentation.django import DjangoInstrumentor # Don't trace health checks, metrics, static files DjangoInstrumentor().instrument( excluded_urls="health/,readiness/,metrics/,static/,media/,favicon.ico" ) ``` ##### 2. Optimize ORM Queries to Reduce Spans ```python title="orders/views.py" showLineNumbers # BAD: Creates N+1 query spans def get_orders_bad(request): orders = Order.objects.all() # 1 query for order in orders: print(order.user.username) # N queries (N spans!) # GOOD: Single query with JOIN (1 span) def get_orders_good(request): orders = Order.objects.select_related('user').all() # 1 query for order in orders: print(order.user.username) # No extra queries ``` ##### 3. Batch Span Export Configuration ```python title="myproject/tracing.py" showLineNumbers from opentelemetry.sdk.trace.export import BatchSpanProcessor # Optimized for high-throughput Django apps batch_processor = BatchSpanProcessor( otlp_exporter, max_queue_size=2048, max_export_batch_size=512, schedule_delay_millis=5000, # Export every 5 seconds export_timeout_millis=30000, ) ``` ##### 4. Disable Tracing in Tests ```python title="myproject/settings.py" showLineNumbers # Disable tracing in test environment import sys TESTING = 'test' in sys.argv if TESTING: OTEL_SDK_DISABLED = True ``` Or use environment variable: ```bash OTEL_SDK_DISABLED=true python manage.py test ``` ### FAQ #### Do I need to manually instrument Django views with OpenTelemetry? **No.** Django's auto-instrumentation automatically traces all views (function-based and class-based) when you call `DjangoInstrumentor().instrument()`. No decorators or manual span creation required for basic request/response tracing. #### How do I trace Django management commands? Use custom spans in your management command's `handle()` method: ```python from opentelemetry import trace tracer = trace.get_tracer(__name__) class Command(BaseCommand): def handle(self, *args, **options): with tracer.start_as_current_span("management_command.my_command"): # Your command logic here pass ``` #### Can I use OpenTelemetry with Django REST Framework? **Yes.** Django REST Framework views and viewsets are automatically instrumented through Django's middleware. Each API endpoint creates a span with the HTTP method and path (e.g., `GET /api/orders/`). #### How do I detect N+1 queries in Django with OpenTelemetry tracing? Check span attributes for `db.query_count`. High counts (>10 queries per request) often indicate N+1 issues. Use the custom decorator shown in the "Custom Instrumentation" section to automatically flag potential N+1 patterns. #### Does OpenTelemetry tracing work with Celery background tasks in Django? **Yes.** Install `opentelemetry-instrumentation-celery` and instrument in your Celery worker initialization. Trace context automatically propagates from Django views to Celery tasks, creating a distributed trace across synchronous and asynchronous operations. #### How do I mask PII data in traces? Implement a custom `SpanProcessor` (see "Security Considerations" section) that filters sensitive data patterns (emails, phone numbers, SSNs) from span names and attributes before export. #### Can I trace async Django views (ASGI)? **Yes.** OpenTelemetry supports ASGI applications. Initialize tracing in your `asgi.py` file before creating the ASGI application, and async views will be traced automatically. #### What is the performance overhead of OpenTelemetry tracing in Django? With 10% sampling, overhead is typically <1% for latency and ~8% for memory. Without sampling (100% tracing), expect ~6% latency increase and ~30% memory increase. See "Performance Considerations" for detailed metrics. #### How do I send traces to Base14 Scout? Point the OTLP exporter at your Scout endpoint on port 4317 and pass your API key as a bearer token in the headers: ```python OTLPSpanExporter( endpoint="https://scout.base14.io:4317", headers={"authorization": f"Bearer {os.getenv('SCOUT_API_KEY')}"}, ) ``` #### Can I trace template rendering? **Yes.** Template rendering is automatically traced when using `render()` or `TemplateResponse`. Each template creates a child span showing rendering time. #### How do I trace multiple databases? Django's database instrumentation traces all configured databases automatically. Span attributes include `db.namespace` to differentiate between databases (with the `database` semconv opt-in set; older builds emit the deprecated `db.name`). #### Can I disable tracing for specific views? Use the `excluded_urls` parameter in `DjangoInstrumentor().instrument()`: ```python DjangoInstrumentor().instrument( excluded_urls="admin/,debug/,internal/" ) ``` ### What's Next Now that you have Django instrumented with OpenTelemetry, explore advanced observability patterns: #### Advanced Tracing Topics - **[Custom Instrumentation for Python](/instrument/apps/custom-instrumentation/python)** \- Deep dive into manual span creation and context propagation - **[All framework guides](/instrument/apps/auto-instrumentation/)** \- Auto-instrumentation overview for every language #### Scout Platform Features - **[Base14 Scout Dashboard](https://base14.io/scout)** - Visualize Django traces with ORM query insights and N+1 detection - **Service Map Visualization** - Understand dependencies between Django, Celery, and external services - **Alert Configuration** - Set up alerts for slow database queries and high error rates #### Deployment & Operations - **Docker Instrumentation** - Deploy instrumented Django apps in containers - **Kubernetes Deployment** - Run Django with sidecar collectors and service mesh - **AWS Deployment** - Deploy to ECS, Elastic Beanstalk, or Lambda with tracing ### Complete Example Here's a complete Django application with OpenTelemetry instrumentation, including ORM queries, views, Celery tasks, and custom business logic. #### Project Structure ```text django-order-service/ ├── manage.py ├── myproject/ │ ├── __init__.py │ ├── settings.py │ ├── urls.py │ ├── wsgi.py │ ├── asgi.py │ ├── celery.py │ └── tracing.py ├── orders/ │ ├── __init__.py │ ├── models.py │ ├── views.py │ ├── serializers.py │ ├── tasks.py │ ├── services.py │ └── management/ │ └── commands/ │ └── process_pending_orders.py ├── requirements.txt ├── Dockerfile ├── docker-compose.yml └── gunicorn.conf.py ``` #### Complete Settings Configuration ```python title="myproject/settings.py" showLineNumbers """Django settings with OpenTelemetry configuration.""" import os from pathlib import Path BASE_DIR = Path(__file__).resolve().parent.parent SECRET_KEY = os.getenv('DJANGO_SECRET_KEY', 'dev-secret-change-in-production') DEBUG = os.getenv('DEBUG', 'False') == 'True' ALLOWED_HOSTS = os.getenv('ALLOWED_HOSTS', 'localhost').split(',') INSTALLED_APPS = [ 'django.contrib.admin', 'django.contrib.auth', 'django.contrib.contenttypes', 'django.contrib.sessions', 'django.contrib.messages', 'django.contrib.staticfiles', 'rest_framework', 'orders', ] MIDDLEWARE = [ 'django.middleware.security.SecurityMiddleware', 'django.contrib.sessions.middleware.SessionMiddleware', 'django.middleware.common.CommonMiddleware', 'django.middleware.csrf.CsrfViewMiddleware', 'django.contrib.auth.middleware.AuthenticationMiddleware', 'django.contrib.messages.middleware.MessageMiddleware', 'django.middleware.clickjacking.XFrameOptionsMiddleware', ] ROOT_URLCONF = 'myproject.urls' DATABASES = { 'default': { 'ENGINE': 'django.db.backends.postgresql', 'NAME': os.getenv('DB_NAME', 'orders'), 'USER': os.getenv('DB_USER', 'postgres'), 'PASSWORD': os.getenv('DB_PASSWORD', 'postgres'), 'HOST': os.getenv('DB_HOST', 'localhost'), 'PORT': os.getenv('DB_PORT', '5432'), } } # Celery Configuration CELERY_BROKER_URL = os.getenv('CELERY_BROKER_URL', 'redis://localhost:6379/0') CELERY_RESULT_BACKEND = os.getenv('CELERY_RESULT_BACKEND', 'redis://localhost:6379/0') # OpenTelemetry OTEL_SERVICE_NAME = os.getenv('OTEL_SERVICE_NAME', 'django-order-service') OTEL_EXPORTER_OTLP_ENDPOINT = os.getenv('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4317') # Static files STATIC_URL = '/static/' STATIC_ROOT = os.path.join(BASE_DIR, 'staticfiles') ``` #### Running the Example ```bash title="Terminal" showLineNumbers # Clone the examples repository git clone https://github.com/base-14/examples.git cd examples/python/django-postgres # Create virtual environment python -m venv venv source venv/bin/activate # On Windows: venv\Scripts\activate # Install dependencies pip install -r requirements.txt # Start infrastructure docker-compose up -d postgres redis scout-collector # Run migrations python manage.py migrate # Create superuser python manage.py createsuperuser # Run development server python manage.py runserver # In another terminal: Run Celery worker celery -A myproject worker --loglevel=info # Test endpoints # Create order curl -X POST http://localhost:8000/api/orders/ \ -H "Content-Type: application/json" \ -d '{"product_name":"Widget","amount":"99.99","status":"pending"}' # Get all orders curl http://localhost:8000/api/orders/ # Process pending orders (management command) python manage.py process_pending_orders --limit 10 # View traces in Scout Dashboard open https://scout.base14.io ``` #### Expected Trace Output When you create an order via `POST /api/orders/`, you should see: ```text POST /api/orders/ (250ms) ├── OrderViewSet.create (200ms) │ ├── SELECT FROM auth_user WHERE id = ? (5ms) │ ├── INSERT INTO orders (...) VALUES (...) (10ms) │ ├── celery.apply_async: process_order (5ms) │ └── serializer.save (15ms) └── Celery Task: process_order (150ms) [separate trace, linked] ├── SELECT FROM orders WHERE id = ? (5ms) ├── validate_high_value_order (30ms) ├── UPDATE orders SET status = ? WHERE id = ? (8ms) └── send_confirmation_email (100ms) ``` :::tip Complete Example Repository The full example application with Docker Compose, Kubernetes manifests, management commands, and PII masking is available at: **[https://github.com/base-14/examples/tree/main/python/django-postgres](https://github.com/base-14/examples/tree/main/python/django-postgres)** This includes production-ready configurations for AWS, GCP, and Azure deployments. ::: Once telemetry is flowing, you can [analyze Django request traces in Scout](https://base14.io/scout/apm) — monitor view performance, ORM query patterns, and Celery task execution from a single pane. ### References #### Official Documentation - **[Django Documentation](https://docs.djangoproject.com/)** \- Official Django framework documentation - **[OpenTelemetry Python SDK](https://opentelemetry.io/docs/languages/python/)** \- Core OpenTelemetry Python documentation - **[Django Instrumentation](https://opentelemetry-python-contrib.readthedocs.io/en/latest/instrumentation/django/django.html)** \- Official Django auto-instrumentation docs - **[Celery Documentation](https://docs.celeryproject.org/)** \- Distributed task queue documentation #### Tools & Resources - **[Base14 Scout](https://base14.io/scout)** \- Managed OpenTelemetry platform for Django applications - **[Django Debug Toolbar](https://django-debug-toolbar.readthedocs.io/)** \- Development tool for query analysis - **[Django REST Framework](https://www.django-rest-framework.org/)** \- API framework with automatic instrumentation ### Related Guides - [Flask Instrumentation](/instrument/apps/auto-instrumentation/flask) - Lightweight Python framework instrumentation - [FastAPI Instrumentation](/instrument/apps/auto-instrumentation/fast-api) - Async Python API framework - [Celery Tracing](/instrument/apps/auto-instrumentation/celery) - Distributed task queue instrumentation - [Python Custom Instrumentation](/instrument/apps/custom-instrumentation/python) \- Manual spans and advanced patterns - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up the collector for local development --- ## .NET Aspire OpenTelemetry Instrumentation - Multi-Service Tracing ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## .NET Aspire Implement OpenTelemetry instrumentation for .NET Aspire applications to capture distributed traces, metrics, and structured logs across an orchestrated set of .NET microservices. This guide shows you how to wire OpenTelemetry through Aspire's ServiceDefaults convention, point the OTLP exporter at a local OTel Collector, and forward telemetry to base14 Scout - all without using Azure Monitor as the destination. .NET Aspire is an opinionated stack for cloud-native .NET apps. For general .NET instrumentation, see the [.NET guide](./dotnet.md). .NET Aspire is Microsoft's first-party orchestration framework for .NET microservices. It ships with OpenTelemetry support out of the box, opinionated service-discovery and resilience defaults, and a local dashboard for resource state and lifecycle inspection. Aspire's value to a Scout customer is that it standardizes the observability shape across every service in your distributed application: a single `AddServiceDefaults()` call in each project's `Program.cs` produces consistent OTel traces, metrics, and logs without per-service boilerplate. Whether you are migrating an Aspire app from Application Insights, building greenfield on Aspire 13, or evaluating Aspire as the orchestration layer between Scout and your services, this guide covers the production-ready setup: ServiceDefaults wiring, AppHost resource declaration, the OTLP-endpoint override knob, and the gotchas around `WithEndpoint` URL serialization, custom-source registration, and the dashboard's relationship with telemetry when you target an external destination. :::tip TL;DR Reference `Aspire.Hosting.AppHost` 13.2.4 and `Aspire.Hosting.PostgreSQL` 13.2.4 on your AppHost project. Add a `ServiceDefaults` class library that exposes `AddServiceDefaults(this IHostApplicationBuilder)` and registers ASP.NET Core, HttpClient, EF Core, and Runtime instrumentation alongside any custom `ActivitySource`s and `Meter`s. In `AppHost.cs`, declare an OTel Collector container with `builder.AddContainer(...)` and override `OTEL_EXPORTER_OTLP_ENDPOINT` on each project to point at the collector's `grpc` endpoint - declared with `WithHttpEndpoint`, not `WithEndpoint`, so the exporter receives an `http://` URL it can parse. ::: > **Note:** This guide is Aspire-specific. For the general ASP.NET Core > OpenTelemetry setup (including SqlClient and JWT) see the > [ASP.NET Core guide](./dotnet.md). For the broader Aspire framework > documentation, see the > [official .NET Aspire docs](https://learn.microsoft.com/dotnet/aspire/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **.NET microservice developers:** building or maintaining Aspire-orchestrated services and wanting consistent observability across them. - **Engineering teams:** migrating from Application Insights to OTel plus Scout and looking for a vendor-neutral export path that works in dev, CI, and production. - **DevOps engineers:** running Aspire workloads in CI or headless customer environments and needing a Compose-mode fallback that does not require the AppHost. - **Platform teams:** standardizing on the ServiceDefaults pattern across multiple Aspire applications and looking for the canonical OpenTelemetry registration shape. ### Overview This guide demonstrates how to: - Configure .NET Aspire 13 AppHost with PostgreSQL, an OTel Collector container, and two .NET project resources. - Build a `ServiceDefaults` class library that registers OpenTelemetry, resilience, service discovery, and health checks for every Aspire-managed project. - Wire a custom `ActivitySource` and `Meter` into the OpenTelemetry tracer and meter providers so business spans and counters export to the collector. - Override Aspire's default OTLP destination so telemetry flows to base14 Scout via a local OTel Collector instead of the Aspire dashboard's bundled OTLP receiver. - Run the same application code in two modes: Aspire AppHost for local development, or a parallel Compose stack for CI and headless customer environments. - Avoid the common 13.x gotchas: `tcp://` URL serialization on `WithEndpoint`, ephemeral project ports, missing custom-source registration, and dashboard cert trust on macOS. ### Prerequisites Before starting, ensure you have: - **.NET 10.0 SDK** installed (Aspire 13 supports .NET 8+; 10 is recommended). - Verify with `dotnet --version`. - **Aspire CLI** installed (`dotnet tool install -g Aspire.Cli`). - AppHost projects that set `AspireUseCliBundle=true` resolve the orchestration and dashboard binaries from the CLI at build time. - **Docker Desktop** with Apple Silicon native daemon and Rosetta enabled for the `postgres:18.3` x86 image. - **base14 Scout account** for OAuth2 export credentials. - See [Scout setup guide](https://docs.base14.io/get-started/scout-setup). - **NuGet** for package management. - Basic familiarity with OpenTelemetry concepts (traces, spans, metrics, resource attributes). #### Compatibility Matrix | Component | Minimum | Recommended | | --- | --- | --- | | .NET SDK | 8.0 | 10.0.400+ | | ASP.NET Core | 8.0 | 10.0+ | | .NET Aspire (AppHost + Hosting.*) | 9.5 | 13.5.2+ | | OpenTelemetry .NET (core) | 1.10 | 1.18.0 | | OpenTelemetry.Instrumentation.AspNetCore | 1.10 | 1.18.0 | | OpenTelemetry.Instrumentation.Http | 1.10 | 1.18.0 | | OpenTelemetry.Instrumentation.EntityFrameworkCore | 1.0-rc | 1.15.1-beta.1 (contrib beta) | | OpenTelemetry.Instrumentation.Runtime | 1.10 | 1.18.0 | | Entity Framework Core | 8.0 | 10.0.11 | | Npgsql.EntityFrameworkCore.PostgreSQL | 8.0 | 10.0.3 | | OTel Collector contrib | 0.140 | 0.151.0 | > Aspire requires .NET 8 minimum. .NET Framework 4.8 is **not** supported. > The OpenTelemetry instrumentation packages do not always release lockstep > with the core SDK; pin per-package using the recommended versions above. ### Required Packages #### AppHost project ```xml showLineNumbers title="AppHost/AppHost.csproj" Exe net10.0 true true ``` The `Aspire.AppHost.Sdk` MSBuild SDK is referenced as a child `` element; the project root SDK stays `Microsoft.NET.Sdk`. Setting `true` enables source generation of the `Projects.*` typed resource names (`Projects.ArticlesApi`, `Projects.NotifySvc`) used by `builder.AddProject("name")`. #### ServiceDefaults project ```xml showLineNumbers title="ServiceDefaults/ServiceDefaults.csproj" net10.0 true ``` `true` and the `` together let ServiceDefaults call `WebApplication`-typed extension methods. ### Quick Start Clone the [`csharp/aspire-postgres`](https://github.com/base-14/examples/tree/main/csharp/aspire-postgres) example and run it in Aspire mode: ```bash git clone https://github.com/base-14/examples.git cd examples/csharp/aspire-postgres cp .env.example .env # Edit .env with your Scout credentials. make up # dotnet run --project AppHost/AppHost.csproj ``` The AppHost prints two log lines on startup: ```text info: Aspire.Hosting.DistributedApplication[0] Now listening on: http://localhost:15888 info: Aspire.Hosting.DistributedApplication[0] Login to the dashboard at http://localhost:15888/login?t=<32-char-token> ``` Use the second URL (the login token regenerates each run; Aspire 13 has dashboard auth on by default). Then in another terminal: ```bash make test-api # exercises all 6 endpoints + cross-service trace make verify-scout # confirms exports landed in Scout (requires SCOUT_*) ``` ### .NET Aspire OpenTelemetry Concepts #### ServiceDefaults: the cross-cutting OTel registration Aspire's idiomatic shape is to put OTel configuration in a shared ServiceDefaults class library that every project references. Each project's `Program.cs` calls `builder.AddServiceDefaults()` and `app.MapDefaultEndpoints()` to opt into the shared OTel, resilience, and health-check setup. ```csharp showLineNumbers title="ServiceDefaults/Extensions.cs" public static class ServiceDefaultsExtensions { public const string ArticlesActivitySourceName = "AspirePostgres.Articles"; public const string ArticlesMeterName = "AspirePostgres.Articles"; public static TBuilder AddServiceDefaults(this TBuilder builder) where TBuilder : IHostApplicationBuilder { builder.ConfigureOpenTelemetry(); builder.AddDefaultHealthChecks(); builder.Services.AddServiceDiscovery(); builder.Services.ConfigureHttpClientDefaults(http => { http.AddStandardResilienceHandler(); http.AddServiceDiscovery(); }); return builder; } public static TBuilder ConfigureOpenTelemetry(this TBuilder builder) where TBuilder : IHostApplicationBuilder { builder.Logging.AddOpenTelemetry(logging => { logging.IncludeFormattedMessage = true; logging.IncludeScopes = true; logging.ParseStateValues = true; }); // Stamps TraceId/SpanId onto every log record so logs correlate with traces. builder.Logging.Configure(options => { options.ActivityTrackingOptions = ActivityTrackingOptions.TraceId | ActivityTrackingOptions.SpanId | ActivityTrackingOptions.ParentId; }); builder.Services.AddOpenTelemetry() .WithMetrics(metrics => metrics .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddRuntimeInstrumentation() .AddMeter(ArticlesMeterName)) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(o => o.RecordException = true) .AddHttpClientInstrumentation() .AddEntityFrameworkCoreInstrumentation() .AddSource(ArticlesActivitySourceName)); if (!string.IsNullOrWhiteSpace(builder.Configuration["OTEL_EXPORTER_OTLP_ENDPOINT"])) { builder.Services.AddOpenTelemetry().UseOtlpExporter(); } return builder; } } ``` Three patterns are critical here: 1. **`.AddSource("AspirePostgres.Articles")`** registers the custom `ActivitySource` on the tracer provider. Without this call, custom spans are silently dropped by the SDK. 2. **`.AddMeter("AspirePostgres.Articles")`** registers the custom `Meter` on the meter provider. Same rule: without it, your `articles.created` counter never reaches the OTLP exporter. 3. **`ActivityTrackingOptions.TraceId | SpanId | ParentId`** on `builder.Logging.Configure(...)` stamps every `ILogger` record with the active span's trace context. Without it, exported logs reach the OTLP destination but with empty `trace_id` / `span_id` fields, breaking log-trace correlation in Scout. #### AppHost orchestration The AppHost's `Program.cs` declares resources and wires them together: ```csharp showLineNumbers title="AppHost/AppHost.cs" var builder = DistributedApplication.CreateBuilder(args); var postgres = builder.AddPostgres("pg").WithImageTag("18.3"); var articlesDb = postgres.AddDatabase("articles"); var collector = builder.AddContainer( "otel-collector", "otel/opentelemetry-collector-contrib", "0.151.0") .WithBindMount("../config/otel-collector.yaml", "/etc/otel-collector.yaml") .WithArgs("--config=/etc/otel-collector.yaml") .WithHttpEndpoint(port: 4317, targetPort: 4317, name: "grpc") .WithHttpEndpoint(port: 4318, targetPort: 4318, name: "http"); var collectorGrpc = collector.GetEndpoint("grpc"); var notify = builder.AddProject("notify-svc") .WithHttpEndpoint(port: 8081, env: "ASPNETCORE_HTTP_PORTS") .WithEnvironment("OTEL_EXPORTER_OTLP_ENDPOINT", collectorGrpc) .WithEnvironment("OTEL_EXPORTER_OTLP_PROTOCOL", "grpc") .WithEnvironment("OTEL_SERVICE_NAME", "notify-svc") .WaitFor(collector); builder.AddProject("articles-api") .WithHttpEndpoint(port: 8080, env: "ASPNETCORE_HTTP_PORTS") .WithReference(articlesDb) .WithEnvironment("Notify__BaseUrl", notify.GetEndpoint("http")) .WithEnvironment("OTEL_EXPORTER_OTLP_ENDPOINT", collectorGrpc) .WithEnvironment("OTEL_EXPORTER_OTLP_PROTOCOL", "grpc") .WithEnvironment("OTEL_SERVICE_NAME", "articles-api") .WaitFor(postgres) .WaitFor(collector); builder.Build().Run(); ``` #### The OTLP override knob Aspire defaults `OTEL_EXPORTER_OTLP_ENDPOINT` on each project resource to its bundled dashboard OTLP receiver. The AppHost override above replaces that default with the local OTel Collector container's gRPC endpoint, which then forwards to base14 Scout via `otlphttp` with OAuth2 authentication. This is the single config switch that takes Aspire from "telemetry to local dashboard only" to "telemetry to a vendor-neutral backend." No SDK code changes; just the env var override. ServiceDefaults' `ConfigureOpenTelemetry` only attaches the OTLP exporter when `OTEL_EXPORTER_OTLP_ENDPOINT` is set (see `Extensions.cs`). In Aspire mode AppHost always sets it, in Compose mode `compose.yml` sets it. If you unset the env var entirely (e.g., running a project standalone outside Aspire and Compose), no OTLP exporter is registered and telemetry stays in-process. That is intentional - it keeps the SDK from spamming connection-refused warnings to a non-existent collector. The Aspire dashboard's resource panel, console log panel, and lifecycle events continue to work normally; only the dashboard's Traces and Metrics tabs go empty in this configuration. To populate them as well, add a second `AddOtlpExporter` call inside `ConfigureOpenTelemetry` that targets `${DOTNET_DASHBOARD_OTLP_ENDPOINT_URL}` (Aspire injects this automatically). The example keeps the simpler single-exporter shape so the data flow remains unambiguous. ### Custom Instrumentation For business-level spans and metrics that auto-instrumentation cannot produce, add a custom `ActivitySource` and `Meter`: ```csharp showLineNumbers title="ArticlesApi/Telemetry/AppMetrics.cs" using System.Diagnostics; using System.Diagnostics.Metrics; public static class AppMetrics { public const string MeterName = "AspirePostgres.Articles"; public const string ActivitySourceName = "AspirePostgres.Articles"; public static readonly Meter Meter = new(MeterName); public static readonly ActivitySource ActivitySource = new(ActivitySourceName); public static readonly Counter ArticlesCreated = Meter.CreateCounter("articles.created", description: "Total articles created"); } ``` Use them inside your endpoint logic: ```csharp showLineNumbers using var activity = AppMetrics.ActivitySource.StartActivity("article.create"); // ... save article to db ... AppMetrics.ArticlesCreated.Add(1); activity?.SetTag("article.id", article.Id); ``` The `using` declaration scopes the activity to the method; the SDK closes it when the method returns. The `article.id` tag becomes a queryable attribute in Scout. For more depth on .NET custom instrumentation patterns (parent-child spans, async propagation, error recording, baggage), see [Custom .NET instrumentation](../custom-instrumentation/csharp.md). ### Migrating from Azure-Monitor-anchored Aspire apps Existing Aspire applications instrumented with the Azure Monitor OpenTelemetry distro (`Azure.Monitor.OpenTelemetry.AspNetCore`) emit OTel-shaped data already; Microsoft itself has done the wire-format work. Migrating to Scout is a configuration change in three steps: 1. **Remove the Azure Monitor distro package** from the project's `.csproj`: ```bash dotnet remove package Azure.Monitor.OpenTelemetry.AspNetCore ``` 2. **Add the vendor-neutral OTLP exporter packages** that this guide pins, and change the `Program.cs` (or `ServiceDefaults`) registration from `builder.Services.AddOpenTelemetry().UseAzureMonitor(...)` to `builder.Services.AddOpenTelemetry().UseOtlpExporter()` plus the instrumentation calls listed in the ServiceDefaults section above. 3. **Override `OTEL_EXPORTER_OTLP_ENDPOINT`** at the AppHost level to point at a Scout-forwarding OTel Collector. No code changes in the projects. For a dual-export period during validation, keep both exporters live; the .NET OpenTelemetry SDK supports multiple exporters on the same TracerProvider. Once Scout dashboards confirm parity with Application Insights, remove the Azure Monitor package. A complete step-by-step migration playbook with KQL-to-Scout dashboard query mappings will land in a follow-up guide; this section is the high-level shape. ### Production Configuration #### Resource attributes Add `service.namespace` and `deployment.environment` so Scout dashboards can filter across environments and service families: ```csharp showLineNumbers title="ServiceDefaults/Extensions.cs" var environment = builder.Configuration["SCOUT_ENVIRONMENT"] ?? builder.Environment.EnvironmentName.ToLowerInvariant(); builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddAttributes(new[] { new KeyValuePair("deployment.environment", environment), new KeyValuePair("environment", environment), new KeyValuePair("service.namespace", "examples"), })) .WithMetrics(metrics => metrics // ... instrumentation registration ... ) .WithTracing(tracing => tracing // ... instrumentation registration ... ); ``` `service.name` is set automatically from `OTEL_SERVICE_NAME` by the OpenTelemetry SDK defaults, which Aspire injects per project resource. #### Batch processor tuning The OTLP exporter batches by default. For high-throughput services, set: ```bash OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_EXPORT_TIMEOUT=30000 ``` For metrics, raise the export interval if Scout's metric ingest rate-limits your traffic: ```bash OTEL_METRIC_EXPORT_INTERVAL=10000 ``` #### Sampling The defaults trace 100% of requests, which is appropriate for development. Production deployments behind a load balancer should switch to a head-based sampler: ```bash OTEL_TRACES_SAMPLER=parentbased_traceidratio OTEL_TRACES_SAMPLER_ARG=0.1 ``` That samples 10% of root traces; child spans inherit the parent decision via W3C `traceparent`. For more nuanced sampling (per-route, per-error), implement a custom `Sampler` in code. ### Security Considerations - **Do not log secrets in spans.** EF Core's contrib instrumentation can optionally include SQL parameter values; the default in 1.15.1-beta.1 is to omit them. Confirm with `OpenTelemetry.Instrumentation.EntityFrameworkCore` release notes if you change the default. - **Redact PII before logging.** Application logs flow through the OTel logging provider into the collector and onward to Scout. Apply redaction at the application layer or at the collector via a `transform` processor. - **Protect the OAuth2 client credentials** in the collector config. The example reads them from `.env` via Aspire's `IConfiguration`; production deployments should pull them from an environment-aware secret store (Azure Key Vault, AWS Secrets Manager, doppler, etc.) and never commit them to git. - **Aspire dashboard auth is on by default** in 13.x. Do not disable it for any deployment beyond local development. ### Performance Considerations - **Aspire dashboard overhead.** The dashboard runs as a separate .NET process and consumes ~50-100 MB of resident memory. It is appropriate for local development; do not deploy to production. Use Compose mode or a cloud-deployed shape (`aspire publish`, Aspire 9.5+) for production. - **Sampling defaults.** With a 100% trace sampler, every HTTP request emits spans. At low traffic this is fine; at high traffic the OTLP exporter and collector become the bottleneck. Switch to head-based sampling at 1-10% for production. - **Async export.** The `BatchSpanProcessor` exports asynchronously, so request latency is not blocked on the collector. With the default batch size, end-to-end export delay is 5-10 seconds. - **`postgres:18.3` first pull on Apple Silicon** is ~310 MB and runs under Rosetta. Expect 60-120 seconds for the first cold start; subsequent runs reuse the cached image. ### Troubleshooting #### Spans and metrics never appear in Scout The most common cause is that Aspire serialized the collector's gRPC endpoint as `tcp://localhost:4317` instead of `http://localhost:4317`. Use `WithHttpEndpoint(port: 4317, targetPort: 4317, name: "grpc")` (not `WithEndpoint`) when declaring the OTel Collector container. Confirm the injected env var with: ```bash ps eww $(pgrep -f ArticlesApi) | tr ' ' '\n' | grep OTEL_EXPORTER_OTLP_ENDPOINT ``` The value should start with `http://`. #### Custom spans and counters not exporting You forgot `.AddSource("Your.Source.Name")` and `.AddMeter("Your.Meter.Name")` in `ConfigureOpenTelemetry`. The SDK silently drops anything not registered on the tracer or meter provider. Names must match exactly between the registration and the `new ActivitySource(...)` / `new Meter(...)` call site. #### Aspire chooses an ephemeral port for my project Aspire assigns ephemeral host ports to project resources by default. Pin a known port with: ```csharp .WithHttpEndpoint(port: 8080, env: "ASPNETCORE_HTTP_PORTS") ``` The `port:` argument requests a fixed published port; the `env:` argument tells Aspire to also inject `ASPNETCORE_HTTP_PORTS=8080` so Kestrel binds to the same target port inside the .NET runtime. DCP proxies between them. #### Dashboard URL prints but the page returns 401 You are missing the `?t=` part of the URL. Aspire 13.x has dashboard auth on by default; the token is regenerated each run. Use the full URL from the `Login to the dashboard at` log line, not just `http://localhost:15888/`. #### Macros: `dotnet workload install aspire` fails or hangs You do not need it. Aspire 9.5+ uses the package-only AppHost SDK (``). NuGet restores the SDK on `dotnet restore`; no workload install required. #### Compose-mode build fails with `useradd: exit code 9` The .NET runtime image (`mcr.microsoft.com/dotnet/aspnet:10.0`) ships with a non-root `app` user pre-created since the .NET 8 release. Drop the `groupadd` / `useradd` lines from your Dockerfile and use `USER app` directly. #### Behind a corporate proxy Set `HTTPS_PROXY` and `NO_PROXY` on the AppHost process. The proxy applies to NuGet restores, Docker pulls (configured separately on Docker Desktop), and the OTel Collector's outbound connection to Scout. NoProxy should include `localhost,127.0.0.1` so dashboard access stays direct. ### FAQ #### Why does .NET Aspire need a custom OTLP destination instead of the dashboard? The Aspire dashboard ships with a built-in OTLP receiver intended for local development. To export to base14 Scout, override `OTEL_EXPORTER_OTLP_ENDPOINT` on each project resource to point at a local OTel Collector container. The collector then forwards to Scout via `otlphttp` with OAuth2 authentication. #### Which .NET and Aspire versions are supported? .NET 8.0 minimum, .NET 10.0 recommended. Aspire 9.5+ uses the package-only AppHost SDK; 13.x is the current generation. .NET Framework 4.8 is not supported. #### Why does `WithEndpoint` produce a `tcp://` URL that breaks the .NET OTLP exporter? Aspire serializes `EndpointReference` values according to the endpoint kind. `WithEndpoint(...)` produces `tcp://` for raw TCP endpoints. The .NET OTLP exporter requires `http://` or `https://`. Use `WithHttpEndpoint(...)` for any endpoint a .NET project will reach via OTLP, including OTLP/gRPC, since gRPC runs over HTTP/2. #### How do I pin a stable port for an Aspire project resource? Call `WithHttpEndpoint(port: 8080, env: "ASPNETCORE_HTTP_PORTS")` on the project resource. The `port:` argument requests a fixed host port; the `env:` argument tells Aspire to also inject `ASPNETCORE_HTTP_PORTS` so Kestrel binds to the same port inside the .NET runtime. #### Does .NET Aspire register custom `ActivitySource`s and `Meter`s automatically? No. Custom `ActivitySource`s require `.AddSource(name)` on the TracerProviderBuilder, and custom `Meter`s require `.AddMeter(name)` on the MeterProviderBuilder. Without these calls, the SDK never wires the source to the OTLP exporter. #### How do I migrate from Application Insights to OpenTelemetry plus Scout? Remove the `Azure.Monitor.OpenTelemetry.AspNetCore` distro package, add `OpenTelemetry.Exporter.OpenTelemetryProtocol`, and override `OTEL_EXPORTER_OTLP_ENDPOINT` at the AppHost level to point at a Scout-forwarding collector. Keep both exporters live during a dual-export validation period. #### Can I run an Aspire example without Aspire AppHost? Yes. The example ships a parallel `compose.yml` stack that runs the same .NET projects as Docker containers without Aspire AppHost. Both modes use the same application code; only env-var sources differ. ### What's Next - Clone the [`csharp/aspire-postgres`](https://github.com/base-14/examples/tree/main/csharp/aspire-postgres) example and run it end-to-end. - Review the [Custom .NET instrumentation guide](../custom-instrumentation/csharp.md) for parent-child spans, async propagation, and error recording patterns. - Set up [Scout dashboards for .NET services](https://docs.base14.io/dashboards/dotnet) to visualize the metrics and traces this guide produces. - Read the [Application Insights migration playbook](https://docs.base14.io/migrate/application-insights) (publishing soon) for KQL-to-Scout query mappings and a stepwise dual-export cutover plan. #### Related Guides - [.NET Custom Instrumentation](../custom-instrumentation/csharp.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language ### References - [.NET Aspire documentation](https://learn.microsoft.com/dotnet/aspire/) - [.NET Aspire OpenTelemetry overview][aspire-otel-docs] - [OpenTelemetry .NET SDK](https://opentelemetry.io/docs/languages/net/) - [OpenTelemetry .NET on GitHub][otel-dotnet-gh] - [OpenTelemetry .NET Contrib on GitHub][otel-dotnet-contrib-gh] - [Migrate Application Insights to Azure Monitor OpenTelemetry][appinsights-migration] - [base14 Scout](https://base14.io) [aspire-otel-docs]: https://learn.microsoft.com/dotnet/aspire/fundamentals/telemetry [otel-dotnet-gh]: https://github.com/open-telemetry/opentelemetry-dotnet [otel-dotnet-contrib-gh]: https://github.com/open-telemetry/opentelemetry-dotnet-contrib [appinsights-migration]: https://learn.microsoft.com/azure/azure-monitor/app/migrate-to-opentelemetry --- ## ASP.NET Core OpenTelemetry Instrumentation - Complete APM Setup Guide ## ASP.NET Core Implement OpenTelemetry instrumentation for .NET ASP.NET Core applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your ASP.NET Core application to collect traces, metrics, and logs from HTTP requests, database queries, background jobs, and custom business logic using the OpenTelemetry .NET SDK. This guide covers OpenTelemetry for .NET applications. For cloud-native apps using .NET Aspire, see the [.NET Aspire guide](./dotnet-aspire.md). .NET applications benefit from first-class OpenTelemetry support with automatic instrumentation for ASP.NET Core, Entity Framework Core, HttpClient, SQL Server, and dozens of commonly used libraries. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database bottlenecks without significant code changes. Whether you're implementing observability for the first time, migrating from commercial APM solutions like Application Insights, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for .NET OpenTelemetry instrumentation. :::tip TL;DR Add the `OpenTelemetry.Extensions.Hosting` and `OpenTelemetry.AutoInstrumentation` NuGet packages, then wire up `builder.Services.AddOpenTelemetry()` in `Program.cs` to register ASP.NET Core, Entity Framework Core, and HttpClient instrumentation in one call. Configure the OTLP exporter with your Scout collector endpoint and set `OTEL_SERVICE_NAME` - no additional code is needed for HTTP request traces, database spans, or outbound call tracking. ::: > **Note:** This guide provides a practical ASP.NET Core-focused overview based > on the official OpenTelemetry documentation. For complete .NET language > information, please consult the > [official OpenTelemetry .NET documentation](https://opentelemetry.io/docs/languages/net/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **.NET developers:** implementing observability and distributed tracing for ASP.NET Core applications - **DevOps engineers:** deploying .NET applications with production monitoring requirements - **Engineering teams:** migrating from Application Insights, DataDog, or other commercial APM solutions - **Developers:** debugging performance issues, slow database queries, or N+1 problems in .NET applications - **Platform teams:** standardizing observability across multiple .NET services ### Overview This comprehensive guide demonstrates how to: - Install and configure OpenTelemetry SDK for ASP.NET Core applications - Set up automatic instrumentation for HTTP requests, database queries, and popular libraries - Configure production-ready telemetry export to Scout Collector - Implement custom instrumentation for business-critical operations - Collect and analyze traces, metrics, and logs - Deploy instrumented .NET applications to development, staging, and production environments - Troubleshoot common instrumentation issues and optimize performance - Secure sensitive data in telemetry exports ### Prerequisites Before starting, ensure you have: - **.NET 8.0 or later** (LTS version recommended) - .NET 10.0 (LTS) is recommended; .NET 9.0 (STS) is out of support - .NET 6.0+ is supported but may require additional configuration - **ASP.NET Core 8.0 or later** installed - **NuGet** for package management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Production deployments should use a dedicated Scout Collector instance - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ----------------- | --------------- | ------------------- | | .NET SDK | 6.0.0 | 10.0+ | | ASP.NET Core | 6.0.0 | 10.0+ | | OpenTelemetry | 1.7.0 | 1.11+ | | Entity Framework | 6.0.0 | 10.0+ | ### Required Packages Install the following NuGet packages: ```bash showLineNumbers dotnet add package OpenTelemetry.Exporter.OpenTelemetryProtocol dotnet add package OpenTelemetry.Extensions.Hosting dotnet add package OpenTelemetry.Instrumentation.AspNetCore dotnet add package OpenTelemetry.Instrumentation.Http dotnet add package OpenTelemetry.Instrumentation.SqlClient dotnet add package OpenTelemetry.Instrumentation.Runtime ``` Or add them to your `.csproj` file: ```xml showLineNumbers title="Api.csproj" ``` ### Configuration OpenTelemetry .NET instrumentation can be configured using multiple approaches depending on your deployment requirements and preferences. Choose the method that best fits your application architecture. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The recommended approach is to create a dedicated telemetry extension method. This provides the most flexibility and keeps configuration separate from your application bootstrap. ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" using OpenTelemetry.Exporter; using OpenTelemetry.Logs; using OpenTelemetry.Metrics; using OpenTelemetry.Resources; using OpenTelemetry.Trace; namespace Api.Telemetry; public static class TelemetrySetup { public static WebApplicationBuilder AddTelemetry(this WebApplicationBuilder builder) { var serviceName = builder.Configuration["OTEL_SERVICE_NAME"] ?? "dotnet-app"; builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService(serviceName) .AddAttributes([ new KeyValuePair("deployment.environment", builder.Environment.EnvironmentName.ToLowerInvariant()), new KeyValuePair("environment", builder.Environment.EnvironmentName.ToLowerInvariant()) ])) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(options => { options.RecordException = true; }) .AddHttpClientInstrumentation() .AddSqlClientInstrumentation(options => { options.SetDbStatementForText = true; options.RecordException = true; }) .AddSource("MyApp.Services") .AddOtlpExporter()) .WithMetrics(metrics => metrics .SetExemplarFilter(ExemplarFilterType.TraceBased) .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddRuntimeInstrumentation() .AddMeter("MyApp.Metrics") .AddOtlpExporter()); builder.Logging.AddOpenTelemetry(logging => { logging.IncludeFormattedMessage = true; logging.IncludeScopes = true; logging.AddOtlpExporter(); }); return builder; } } ``` Use it in your `Program.cs`: ```csharp showLineNumbers title="Program.cs" using Api.Telemetry; var builder = WebApplication.CreateBuilder(args); builder.AddTelemetry(); // ... rest of configuration ``` This configuration automatically instruments: - **ASP.NET Core**: HTTP requests, middleware, controllers, Minimal APIs - **HttpClient**: Outbound HTTP requests - **SQL Server**: Database queries via SqlClient - **Runtime**: GC, thread pool, and process metrics ```mdx-code-block ``` For simpler applications, configure OpenTelemetry directly in `Program.cs`: ```csharp showLineNumbers title="Program.cs" using OpenTelemetry.Resources; using OpenTelemetry.Trace; using OpenTelemetry.Metrics; using OpenTelemetry.Logs; var builder = WebApplication.CreateBuilder(args); var serviceName = builder.Configuration["OTEL_SERVICE_NAME"] ?? "dotnet-app"; builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource.AddService(serviceName)) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddOtlpExporter()) .WithMetrics(metrics => metrics .AddAspNetCoreInstrumentation() .AddOtlpExporter()); builder.Logging.AddOpenTelemetry(logging => { logging.IncludeFormattedMessage = true; logging.AddOtlpExporter(); }); var app = builder.Build(); app.Run(); ``` ```mdx-code-block ``` For containerized deployments, OpenTelemetry .NET respects standard environment variables: ```csharp showLineNumbers title="Program.cs" builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService(Environment.GetEnvironmentVariable("OTEL_SERVICE_NAME") ?? "dotnet-app")) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddOtlpExporter()) // Uses OTEL_EXPORTER_OTLP_ENDPOINT automatically .WithMetrics(metrics => metrics .AddAspNetCoreInstrumentation() .AddOtlpExporter()); ``` Configure with environment variables: ```bash showLineNumbers export OTEL_SERVICE_NAME=dotnet-app export OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 export OTEL_TRACES_EXPORTER=otlp export OTEL_METRICS_EXPORTER=otlp export OTEL_LOGS_EXPORTER=otlp ``` ```mdx-code-block ``` If you want to enable only specific instrumentations: ```csharp showLineNumbers title="Program.cs" builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource.AddService("dotnet-app")) .WithTracing(tracing => tracing // Only enable specific instrumentations .AddAspNetCoreInstrumentation(options => { options.RecordException = true; options.Filter = context => { // Skip health check endpoints return !context.Request.Path.StartsWithSegments("/health"); }; }) .AddHttpClientInstrumentation(options => { options.RecordException = true; }) // Add custom ActivitySources .AddSource("MyApp.AuthService") .AddSource("MyApp.ArticleService") .AddOtlpExporter()); ``` ```mdx-code-block ``` #### Configuring Instrumentation Options Fine-tune instrumentation for your needs: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(options => { options.RecordException = true; options.EnrichWithHttpRequest = (activity, request) => { activity.SetTag("http.request_content_type", request.ContentType); }; options.EnrichWithHttpResponse = (activity, response) => { activity.SetTag("http.response_content_length", response.ContentLength); }; options.Filter = context => { // Skip static files and health checks var path = context.Request.Path.Value ?? ""; return !path.StartsWith("/health") && !path.StartsWith("/favicon") && !path.StartsWith("/static"); }; }) .AddSqlClientInstrumentation(options => { options.SetDbStatementForText = true; options.SetDbStatementForStoredProcedure = true; options.RecordException = true; options.EnableConnectionLevelAttributes = true; })); ``` #### Scout Collector Integration When using Scout Collector, configure your .NET application to send telemetry data to the Scout Collector endpoint: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" public static WebApplicationBuilder AddTelemetry(this WebApplicationBuilder builder) { var serviceName = builder.Configuration["OTEL_SERVICE_NAME"] ?? "dotnet-app"; var scoutEndpoint = builder.Configuration["OTEL_EXPORTER_OTLP_ENDPOINT"] ?? "http://localhost:4317"; var scoutApiKey = builder.Configuration["SCOUT_API_KEY"]; builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService(serviceName) .AddAttributes([ new KeyValuePair("deployment.environment", builder.Environment.EnvironmentName.ToLowerInvariant()), new KeyValuePair("environment", builder.Environment.EnvironmentName.ToLowerInvariant()) ])) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(o => o.RecordException = true) .AddHttpClientInstrumentation() .AddSqlClientInstrumentation(o => o.SetDbStatementForText = true) .AddOtlpExporter(options => { options.Endpoint = new Uri(scoutEndpoint); if (!string.IsNullOrEmpty(scoutApiKey)) { options.Headers = $"x-scout-api-key={scoutApiKey}"; } })); return builder; } ``` > **Scout Dashboard Integration**: After configuration, your traces will appear > in the Scout Dashboard. Navigate to the Traces section to view request flows, > identify performance bottlenecks, and analyze distributed transactions across > your .NET services. ### Production Configuration Production deployments require additional configuration for optimal performance, reliability, and resource utilization. This section covers production-specific settings and best practices. #### Batch Span Processor (Default) The OTLP exporter uses batch processing by default. Configure batch settings for production: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation() .AddOtlpExporter(options => { options.Endpoint = new Uri(scoutEndpoint); options.ExportProcessorType = ExportProcessorType.Batch; options.BatchExportProcessorOptions = new BatchExportProcessorOptions { MaxQueueSize = 2048, ScheduledDelayMilliseconds = 5000, ExporterTimeoutMilliseconds = 30000, MaxExportBatchSize = 512 }; })); ``` **Benefits of Batch Processing:** - Reduces network requests by up to 95% - Lower CPU overhead compared to immediate export - Prevents network saturation during traffic spikes - Configurable batching for optimal throughput #### Resource Attributes Add rich context to all telemetry data with resource attributes: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService( serviceName: serviceName, serviceVersion: Assembly.GetExecutingAssembly() .GetName().Version?.ToString() ?? "1.0.0", serviceInstanceId: Environment.MachineName) .AddAttributes([ new KeyValuePair("deployment.environment", builder.Environment.EnvironmentName.ToLowerInvariant()), new KeyValuePair("environment", builder.Environment.EnvironmentName.ToLowerInvariant()), new KeyValuePair("service.namespace", "production"), new KeyValuePair("host.name", Environment.MachineName), new KeyValuePair("process.runtime.name", ".NET"), new KeyValuePair("process.runtime.version", Environment.Version.ToString()), ])); ``` These attributes help you: - Filter traces by environment, region, or instance - Correlate issues with specific deployments - Analyze performance across different infrastructure - Debug production incidents faster #### Environment-Based Configuration Use `appsettings.json` for environment-specific configuration: ```json showLineNumbers title="appsettings.json" { "OTEL_SERVICE_NAME": "dotnet-app", "OTEL_EXPORTER_OTLP_ENDPOINT": "http://localhost:4317", "Logging": { "LogLevel": { "Default": "Information", "Microsoft.AspNetCore": "Warning" } } } ``` ```json showLineNumbers title="appsettings.Production.json" { "OTEL_SERVICE_NAME": "dotnet-app-production", "OTEL_EXPORTER_OTLP_ENDPOINT": "https://scout-collector.example.com:4317", "SCOUT_API_KEY": "", "Logging": { "LogLevel": { "Default": "Warning", "Microsoft.AspNetCore": "Warning" } } } ``` #### Production Environment Variables Configure production settings via environment variables: ```bash showLineNumbers title=".env.production" # Service Configuration OTEL_SERVICE_NAME=dotnet-app-production ASPNETCORE_ENVIRONMENT=Production # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4317 SCOUT_API_KEY=your-scout-api-key # Database ConnectionStrings__DefaultConnection=Server=db;Database=Production;User Id=app;Password=secret; # JWT Jwt__Secret=your-production-jwt-secret-minimum-32-characters ``` #### Docker Production Configuration For containerized .NET applications, configure OpenTelemetry in your Docker setup: ```dockerfile showLineNumbers title="Dockerfile" # Build stage FROM mcr.microsoft.com/dotnet/sdk:10.0 AS build WORKDIR /src # Copy project files COPY *.csproj ./ RUN dotnet restore # Copy source and build COPY . . RUN dotnet publish -c Release -o /app/publish /p:UseAppHost=false # Runtime stage FROM mcr.microsoft.com/dotnet/aspnet:10.0 AS runtime WORKDIR /app # Install curl for healthcheck RUN apt-get update && apt-get install -y curl && rm -rf /var/lib/apt/lists/* COPY --from=build /app/publish . ENV ASPNETCORE_ENVIRONMENT=Production ENV OTEL_SERVICE_NAME=dotnet-app ENV OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 EXPOSE 8080 ENTRYPOINT ["dotnet", "Api.dll"] ``` ```yaml showLineNumbers title="docker-compose.yml" services: api: build: . environment: ASPNETCORE_ENVIRONMENT: Production ASPNETCORE_HTTP_PORTS: "8080" ConnectionStrings__DefaultConnection: "Server=sqlserver;Database=App;User Id=sa;Password=YourStrong@Passw0rd;TrustServerCertificate=true" Jwt__Secret: "your-super-secret-jwt-key-minimum-32-characters-long" OTEL_SERVICE_NAME: dotnet-app OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 depends_on: - sqlserver - otel-collector ports: - "8080:8080" otel-collector: image: otel/opentelemetry-collector-contrib:latest ports: - "4317:4317" - "4318:4318" sqlserver: image: mcr.microsoft.com/azure-sql-edge:latest environment: ACCEPT_EULA: "Y" MSSQL_SA_PASSWORD: "YourStrong@Passw0rd" ``` ### Metrics In addition to traces, OpenTelemetry can collect metrics from your .NET application to monitor resource utilization, request rates, error counts, and custom business metrics. #### Automatic HTTP Metrics ASP.NET Core instrumentation automatically collects HTTP-related metrics: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithMetrics(metrics => metrics .SetExemplarFilter(ExemplarFilterType.TraceBased) .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddRuntimeInstrumentation() .AddOtlpExporter()); ``` **Automatic metrics include:** - `http.server.request.duration` - HTTP request duration histogram - `http.server.active_requests` - Currently active requests - `http.client.request.duration` - Outbound HTTP request duration - `process.runtime.dotnet.gc.collections.count` - GC collections - `process.runtime.dotnet.threadpool.threads.count` - Thread pool size #### Custom Business Metrics Create custom metrics to track business-specific events and KPIs: ```csharp showLineNumbers title="Telemetry/Metrics.cs" using System.Diagnostics.Metrics; namespace Api.Telemetry; public static class AppMetrics { private static readonly Meter Meter = new("MyApp.Metrics"); public static readonly Counter UsersRegistered = Meter.CreateCounter("users.registered", description: "Total users registered"); public static readonly Counter LoginAttempts = Meter.CreateCounter("auth.login.attempts", description: "Total login attempts"); public static readonly Counter LoginFailures = Meter.CreateCounter("auth.login.failures", description: "Total failed login attempts"); public static readonly Counter ArticlesCreated = Meter.CreateCounter("articles.created", description: "Total articles created"); public static readonly Counter ArticlesUpdated = Meter.CreateCounter("articles.updated", description: "Total articles updated"); public static readonly Counter ArticlesDeleted = Meter.CreateCounter("articles.deleted", description: "Total articles deleted"); public static readonly Histogram OrderValue = Meter.CreateHistogram("orders.value", unit: "USD", description: "Distribution of order values"); } ``` Use metrics in your services: ```csharp showLineNumbers title="Services/ArticleService.cs" public async Task CreateAsync(int userId, CreateArticleRequest request) { // ... create article logic // Record business metric AppMetrics.ArticlesCreated.Add(1); logger.LogInformation("Article created: {ArticleId} by user {UserId}", article.Id, userId); return response; } ``` #### Viewing Metrics in Scout Dashboard After configuring metrics export, navigate to the Scout Dashboard to: - View HTTP request rate and latency percentiles (p50, p95, p99) - Monitor error rates and status code distributions - Track custom business metrics in real-time - Create alerts based on metric thresholds - Build custom dashboards combining metrics and traces ### Entity Framework Core Database Monitoring OpenTelemetry automatically instruments Entity Framework Core to provide comprehensive database query monitoring. #### Automatic Query Tracing EF Core emits diagnostic events that are captured by OpenTelemetry: ```csharp showLineNumbers title="Program.cs" builder.Services.AddDbContext(options => options.UseSqlServer(connectionString) .EnableSensitiveDataLogging(builder.Environment.IsDevelopment()) .EnableDetailedErrors(builder.Environment.IsDevelopment())); ``` #### Configuring SQL Client Instrumentation Fine-tune SQL Client instrumentation for security and performance: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithTracing(tracing => tracing .AddSqlClientInstrumentation(options => { // Capture SQL statements (disable in production for sensitive data) options.SetDbStatementForText = true; options.SetDbStatementForStoredProcedure = true; // Record exceptions as span events options.RecordException = true; // Add connection-level attributes options.EnableConnectionLevelAttributes = true; // Custom enrichment options.Enrich = (activity, eventName, rawObject) => { if (rawObject is SqlCommand command) { activity.SetTag("db.command_type", command.CommandType.ToString()); } }; })); ``` **SQL span attributes include:** - `db.system` - Database type (mssql) - `db.name` - Database name - `db.statement` - SQL query - `db.operation.name` - Operation type - `server.address` - Database server #### Detecting N+1 Queries Use OpenTelemetry traces to identify N+1 query problems: ```csharp showLineNumbers // Bad: N+1 query pattern (visible in traces as multiple DB spans) var articles = await context.Articles.ToListAsync(); foreach (var article in articles) { var author = await context.Users.FindAsync(article.AuthorId); // N+1! } // Good: Optimized with eager loading (single query in trace) var articles = await context.Articles .Include(a => a.Author) .ToListAsync(); ``` In Scout Dashboard, N+1 queries appear as: - Multiple identical database spans within a single request trace - High span count for simple operations - Repeated query patterns with different parameters ### Custom Manual Instrumentation While automatic instrumentation covers most ASP.NET Core components, you can add custom instrumentation for business logic, external API calls, or performance-critical code paths. #### Creating Custom Spans with ActivitySource Use `ActivitySource` for custom span creation: ```csharp showLineNumbers title="Services/ArticleService.cs" using System.Diagnostics; using Api.Telemetry; using OpenTelemetry.Trace; namespace Api.Services; public class ArticleService { private static readonly ActivitySource ActivitySource = new("MyApp.ArticleService"); private readonly AppDbContext _context; private readonly ILogger _logger; public ArticleService(AppDbContext context, ILogger logger) { _context = context; _logger = logger; } public async Task CreateAsync(int userId, CreateArticleRequest request) { using var activity = ActivitySource.StartActivity("article.create"); activity?.SetTag("user.id", userId); var slug = GenerateSlug(request.Title); activity?.SetTag("article.slug", slug); var article = new Article { Slug = slug, Title = request.Title, Description = request.Description, Body = request.Body, AuthorId = userId }; _context.Articles.Add(article); await _context.SaveChangesAsync(); activity?.SetTag("article.id", article.Id); AppMetrics.ArticlesCreated.Add(1); _logger.LogInformation("Article created: {ArticleId} by user {UserId}", article.Id, userId); return ToArticleResponse(article); } } ``` Don't forget to register your ActivitySource: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation() .AddSource("MyApp.ArticleService") .AddSource("MyApp.AuthService") .AddOtlpExporter()); ``` #### Adding Attributes to Current Spans Enrich existing spans with additional context: ```csharp showLineNumbers title="Middleware/UserContextMiddleware.cs" using System.Diagnostics; public class UserContextMiddleware { private readonly RequestDelegate _next; public UserContextMiddleware(RequestDelegate next) { _next = next; } public async Task InvokeAsync(HttpContext context) { var activity = Activity.Current; if (context.User.Identity?.IsAuthenticated == true) { var userId = context.User.FindFirst("sub")?.Value; var userRole = context.User.FindFirst("role")?.Value; activity?.SetTag("user.id", userId); activity?.SetTag("user.role", userRole); activity?.SetTag("user.authenticated", true); } await _next(context); } } ``` #### Exception Handling and Error Tracking Capture exceptions in custom spans: ```csharp showLineNumbers title="Services/ArticleService.cs" public async Task UpdateAsync(string slug, int userId, UpdateArticleRequest request) { using var activity = ActivitySource.StartActivity("article.update"); activity?.SetTag("article.slug", slug); activity?.SetTag("user.id", userId); try { var article = await _context.Articles .FirstOrDefaultAsync(a => a.Slug == slug); if (article is null) return null; if (article.AuthorId != userId) { var ex = new UnauthorizedAccessException("Not authorized to update this article"); activity?.SetStatus(ActivityStatusCode.Error, ex.Message); activity?.AddException(ex); throw ex; } // ... update logic activity?.SetTag("article.id", article.Id); AppMetrics.ArticlesUpdated.Add(1); return ToArticleResponse(article); } catch (Exception ex) { _logger.LogError(ex, "Failed to update article {Slug}", slug); activity?.SetStatus(ActivityStatusCode.Error, ex.Message); activity?.AddException(ex); throw; } } ``` #### Error Handling with Trace ID Include trace IDs in error responses for easier debugging: ```csharp showLineNumbers title="Middleware/ExceptionMiddleware.cs" using System.Diagnostics; public static class ExceptionMiddlewareExtensions { public static IApplicationBuilder UseExceptionHandling(this IApplicationBuilder app) { return app.UseExceptionHandler(errorApp => { errorApp.Run(async context => { var traceId = Activity.Current?.TraceId.ToString(); context.Response.StatusCode = StatusCodes.Status500InternalServerError; context.Response.ContentType = "application/json"; await context.Response.WriteAsJsonAsync(new { error = "Internal server error", trace_id = traceId }); }); }); } } ``` #### Using Semantic Conventions Follow OpenTelemetry semantic conventions for consistent attribute naming: ```csharp showLineNumbers // HTTP semantic conventions activity?.SetTag("http.method", "POST"); activity?.SetTag("http.url", "https://api.example.com/users"); activity?.SetTag("http.status_code", 201); activity?.SetTag("http.request.header.content_type", "application/json"); // Database semantic conventions activity?.SetTag("db.system", "mssql"); activity?.SetTag("db.name", "production"); activity?.SetTag("db.statement", "SELECT * FROM Users WHERE Id = @Id"); activity?.SetTag("db.operation", "SELECT"); // Messaging semantic conventions activity?.SetTag("messaging.system", "rabbitmq"); activity?.SetTag("messaging.destination", "orders_queue"); activity?.SetTag("messaging.operation", "process"); ``` ### Running Your Instrumented Application ```mdx-code-block ``` For local development, console output is enabled by default: ```csharp showLineNumbers title="Program.cs" var builder = WebApplication.CreateBuilder(args); builder.AddTelemetry(); if (builder.Environment.IsDevelopment()) { builder.Logging.AddConsole(); } var app = builder.Build(); app.Run(); ``` Start your application: ```bash dotnet run ``` You'll see trace output in the console for each request. ```mdx-code-block ``` For production deployments, ensure the Scout Collector endpoint is properly configured: ```bash showLineNumbers # Set environment variables export OTEL_SERVICE_NAME=dotnet-app-production export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4317 export ASPNETCORE_ENVIRONMENT=Production # Run the application dotnet run --configuration Release ``` ```mdx-code-block ``` Run your instrumented .NET application in Docker: ```bash showLineNumbers # Build the image docker build -t dotnet-app:latest . # Run with Scout Collector docker run -d \ --name dotnet-app \ -e OTEL_SERVICE_NAME=dotnet-app \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 \ -e ConnectionStrings__DefaultConnection="Server=db;Database=App;..." \ -p 8080:8080 \ dotnet-app:latest ``` Or use Docker Compose (see [Production Configuration](#production-configuration) section for complete example). ```mdx-code-block ``` ### Troubleshooting #### Verifying OpenTelemetry Installation Create a health check endpoint to verify telemetry: ```csharp showLineNumbers title="Endpoints/HealthEndpoints.cs" using System.Diagnostics; using System.Reflection; public static class HealthEndpoints { private static readonly ActivitySource ActivitySource = new("MyApp.Health"); public static void MapHealthEndpoints(this IEndpointRouteBuilder app) { app.MapGet("/health", () => { using var activity = ActivitySource.StartActivity("health.check"); activity?.SetTag("service.name", Environment.GetEnvironmentVariable("OTEL_SERVICE_NAME")); activity?.SetTag("runtime.version", Environment.Version.ToString()); return Results.Ok(new { status = "ok", timestamp = DateTime.UtcNow, version = Assembly.GetExecutingAssembly() .GetName().Version?.ToString() }); }); app.MapGet("/health/telemetry", () => { using var activity = ActivitySource.StartActivity("telemetry.check"); return Results.Ok(new { status = "ok", telemetry = new { trace_id = Activity.Current?.TraceId.ToString(), span_id = Activity.Current?.SpanId.ToString(), service_name = Environment.GetEnvironmentVariable("OTEL_SERVICE_NAME"), endpoint = Environment.GetEnvironmentVariable("OTEL_EXPORTER_OTLP_ENDPOINT") } }); }); } } ``` Test the endpoints: ```bash curl http://localhost:8080/health/telemetry ``` #### Debug Mode Enable debug logging to troubleshoot instrumentation issues: ```json showLineNumbers title="appsettings.Development.json" { "Logging": { "LogLevel": { "Default": "Debug", "OpenTelemetry": "Debug", "Microsoft.AspNetCore": "Information" } } } ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify Scout Collector endpoint is reachable: ```bash curl -v http://scout-collector:4317 ``` 2. Check environment variables: ```bash echo $OTEL_EXPORTER_OTLP_ENDPOINT echo $OTEL_SERVICE_NAME ``` 3. Enable debug logging and check for export errors 4. Verify network connectivity between your app and Scout Collector ##### Issue: Missing database query spans **Solutions:** 1. Ensure `OpenTelemetry.Instrumentation.SqlClient` package is installed 2. Verify SQL Client instrumentation is configured: ```csharp .AddSqlClientInstrumentation(options => { options.SetDbStatementForText = true; }) ``` 3. Check that you're using `SqlClient` (not third-party providers) ##### Issue: High memory usage **Solutions:** 1. Configure batch processor settings to reduce queue size 2. Ensure spans are being exported successfully 3. Limit span attribute sizes ##### Issue: Performance degradation **Solutions:** 1. Use batch processor (default) instead of simple processor 2. Filter out high-frequency endpoints like health checks 3. Reduce logging verbosity in production ### Security Considerations #### Protecting Sensitive Data Avoid adding sensitive information to span attributes: ```csharp showLineNumbers // Bad - exposes sensitive data activity?.SetTag("user.password", password); // Never include passwords! activity?.SetTag("credit_card.number", cardNumber); // Never include payment data! activity?.SetTag("user.ssn", socialSecurity); // Never include PII! // Good - uses safe identifiers activity?.SetTag("user.id", userId); activity?.SetTag("user.role", role); activity?.SetTag("payment.provider", "stripe"); activity?.SetTag("payment.status", "completed"); ``` #### Sanitizing SQL Statements Disable SQL statement capture in production if queries contain sensitive data: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithTracing(tracing => tracing .AddSqlClientInstrumentation(options => { // Only enable in development options.SetDbStatementForText = builder.Environment.IsDevelopment(); options.SetDbStatementForStoredProcedure = builder.Environment.IsDevelopment(); })); ``` #### Filtering Sensitive HTTP Headers Skip sensitive headers in your tracing configuration: ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" builder.Services.AddOpenTelemetry() .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(options => { options.EnrichWithHttpRequest = (activity, request) => { // Only capture safe headers activity.SetTag("http.request.header.content_type", request.ContentType); // Don't capture Authorization header }; })); ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard - Disable SQL statement capture for sensitive queries - Audit span attributes regularly for sensitive data leaks ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead to .NET applications: - **Average latency increase**: 1-2ms per request - **CPU overhead**: Less than 2% in production with batch processor - **Memory overhead**: ~30-50MB depending on queue size and traffic **Impact varies based on:** - Number of enabled instrumentations - Span processor type (Batch vs Simple) - Application request volume - Complexity of database queries #### Optimization Best Practices ##### 1. Use Batch Processor (Default) ```csharp showLineNumbers // Good - batches exports, low overhead (default) .AddOtlpExporter(options => { options.ExportProcessorType = ExportProcessorType.Batch; }) // Avoid - exports every span immediately .AddOtlpExporter(options => { options.ExportProcessorType = ExportProcessorType.Simple; }) ``` ##### 2. Filter Non-Critical Endpoints ```csharp showLineNumbers .AddAspNetCoreInstrumentation(options => { options.Filter = context => { var path = context.Request.Path.Value ?? ""; return !path.StartsWith("/health") && !path.StartsWith("/metrics") && !path.StartsWith("/favicon"); }; }) ``` ##### 3. Conditional Span Recording ```csharp showLineNumbers var activity = Activity.Current; // Only add expensive attributes if activity is being recorded if (activity?.IsAllDataRequested == true) { activity.SetTag("expensive.attribute", ComputeExpensiveValue()); } ``` ##### 4. Limit Attribute Values ```csharp showLineNumbers // Truncate long values var truncatedBody = requestBody.Length > 1000 ? requestBody[..1000] + "..." : requestBody; activity?.SetTag("http.request.body", truncatedBody); ``` ### Frequently Asked Questions #### Does OpenTelemetry impact .NET application performance? OpenTelemetry adds approximately 1-2ms of latency per request in typical ASP.NET Core applications. With proper configuration (batch processor), the performance impact is minimal and acceptable for most production workloads. #### Which .NET versions are supported? OpenTelemetry supports .NET 6.0+ with full support. .NET 8.0+ is recommended for optimal compatibility and performance. See the [Prerequisites](#prerequisites) section for detailed version compatibility. #### Can I use OpenTelemetry with background services? Yes! You can instrument `IHostedService` and `BackgroundService` implementations using `ActivitySource`: ```csharp public class MyBackgroundService : BackgroundService { private static readonly ActivitySource ActivitySource = new("MyApp.BackgroundService"); protected override async Task ExecuteAsync(CancellationToken stoppingToken) { while (!stoppingToken.IsCancellationRequested) { using var activity = ActivitySource.StartActivity("process_job"); // ... process job } } } ``` #### Can I use OpenTelemetry alongside Application Insights? Yes, you can run OpenTelemetry alongside Application Insights during migration periods. However, running multiple telemetry systems simultaneously will multiply the overhead, so plan your migration carefully. Consider using the Azure Monitor OpenTelemetry exporter as a replacement. #### How do I handle multi-tenant applications? Add tenant context to spans using tags: ```csharp Activity.Current?.SetTag("tenant.id", tenantId); Activity.Current?.SetTag("tenant.name", tenantName); ``` Then filter traces by tenant in Scout Dashboard. #### What's the difference between traces and metrics? **Traces** show the complete request flow through your application with timing details for each operation. Use traces to debug slow requests and understand distributed transactions. **Metrics** provide aggregated statistics over time (request rate, error rate, latency percentiles). Use metrics for monitoring overall application health and setting alerts. #### How do I propagate trace context to message queues? Inject the W3C `traceparent` header into the message when publishing and extract it in the consumer, so the two sides join one trace: ```csharp // When publishing var activity = Activity.Current; message.Headers["traceparent"] = activity?.Id; // When consuming var traceparent = message.Headers["traceparent"]; using var activity = ActivitySource.StartActivity( "process_message", ActivityKind.Consumer, traceparent); ``` #### Can I customize which endpoints are instrumented? Yes! Use the `Filter` option in ASP.NET Core instrumentation: ```csharp options.Filter = context => { return !context.Request.Path.StartsWithSegments("/internal"); }; ``` ### What's Next? Now that your .NET application is instrumented with OpenTelemetry, explore these resources to maximize your observability: #### Advanced Topics - **[PostgreSQL Monitoring Best Practices](../../component/postgres.md)** - Optimize database observability with query performance analysis #### Scout Platform Features - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - Set up intelligent alerts for error rates, latency thresholds, and custom metrics - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Set up Scout Collector for local development and testing ### Complete Example Here's a complete working example of an ASP.NET Core application with OpenTelemetry instrumentation: #### Project File ```xml showLineNumbers title="Api.csproj" net10.0 enable enable ``` #### Telemetry Setup ```csharp showLineNumbers title="Telemetry/TelemetrySetup.cs" using OpenTelemetry.Logs; using OpenTelemetry.Metrics; using OpenTelemetry.Resources; using OpenTelemetry.Trace; namespace Api.Telemetry; public static class TelemetrySetup { public static WebApplicationBuilder AddTelemetry(this WebApplicationBuilder builder) { var serviceName = builder.Configuration["OTEL_SERVICE_NAME"] ?? "dotnet-app"; builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService(serviceName) .AddAttributes([ new KeyValuePair("deployment.environment", builder.Environment.EnvironmentName.ToLowerInvariant()), new KeyValuePair("environment", builder.Environment.EnvironmentName.ToLowerInvariant()) ])) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(o => o.RecordException = true) .AddHttpClientInstrumentation() .AddSqlClientInstrumentation(o => o.SetDbStatementForText = true) .AddSource("MyApp.Services") .AddOtlpExporter()) .WithMetrics(metrics => metrics .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddRuntimeInstrumentation() .AddMeter("MyApp.Metrics") .AddOtlpExporter()); builder.Logging.AddOpenTelemetry(logging => { logging.IncludeFormattedMessage = true; logging.AddOtlpExporter(); }); return builder; } } ``` #### Metrics Definition ```csharp showLineNumbers title="Telemetry/Metrics.cs" using System.Diagnostics.Metrics; namespace Api.Telemetry; public static class AppMetrics { private static readonly Meter Meter = new("MyApp.Metrics"); public static readonly Counter ArticlesCreated = Meter.CreateCounter("articles.created", description: "Total articles created"); } ``` #### Instrumented Service ```csharp showLineNumbers title="Services/ArticleService.cs" using System.Diagnostics; using Api.Telemetry; namespace Api.Services; public class ArticleService { private static readonly ActivitySource ActivitySource = new("MyApp.Services"); public async Task
CreateAsync(CreateArticleRequest request) { using var activity = ActivitySource.StartActivity("article.create"); var article = new Article { Title = request.Title, Body = request.Body }; // Save to database... activity?.SetTag("article.id", article.Id); AppMetrics.ArticlesCreated.Add(1); return article; } } ``` #### Program Entry Point ```csharp showLineNumbers title="Program.cs" using Api.Telemetry; var builder = WebApplication.CreateBuilder(args); builder.AddTelemetry(); var app = builder.Build(); app.MapGet("/health", () => Results.Ok(new { status = "ok" })); app.Run(); ``` #### Environment Variables ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=dotnet-app OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 ASPNETCORE_ENVIRONMENT=Development ``` This complete example is available in our [GitHub examples repository](https://github.com/base-14/examples/tree/main/csharp/dotnet-sqlserver). ### References - [Official OpenTelemetry .NET Documentation](https://opentelemetry.io/docs/languages/net/) - [ASP.NET Core Documentation](https://learn.microsoft.com/aspnet/core) - [OpenTelemetry .NET GitHub](https://github.com/open-telemetry/opentelemetry-dotnet) ### Related Guides - [.NET Custom Instrumentation](../custom-instrumentation/csharp.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development --- ## Elixir Phoenix OpenTelemetry Instrumentation - Complete APM Setup Guide ## Elixir Phoenix Implement OpenTelemetry instrumentation for `Phoenix` applications to collect traces; monitor HTTP requests and database queries using the Elixir OTel SDK. > **Note:** This guide provides a concise overview based on the official > OpenTelemetry documentation. For complete information, please consult the > [official OpenTelemetry documentation](https://opentelemetry.io/docs/languages/erlang/). :::tip TL;DR Add `opentelemetry_phoenix` and `opentelemetry_ecto` to your `mix.exs` deps, then call `OpentelemetryPhoenix.setup()` and `OpentelemetryEcto.setup/1` in your application's `start/2` function. HTTP requests and Ecto database queries are traced automatically and exported to base14 Scout via OTLP. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide walks through setting up automatic OpenTelemetry instrumentation for Phoenix applications, including HTTP request tracing, database query monitoring with Ecto, and log correlation. The instrumentation automatically exports telemetry data to Scout Collector for visualization. ### Prerequisites Before starting, ensure you have: - Elixir 1.13 or later installed - Phoenix application set up - Access to package installation (Mix) - Scout collector endpoint ### Required Packages Install the following necessary packages by adding them to `mix.exs` and running `mix deps.get`. ```elixir title="mix.exs" showLineNumbers defp deps do [ # OpenTelemetry core packages {:opentelemetry, "~> 1.3"}, {:opentelemetry_exporter, "~> 1.6"}, # Automatic instrumentation for Phoenix and Ecto {:opentelemetry_phoenix, "~> 1.1"}, {:opentelemetry_ecto, "~> 1.1"} ] end ``` After adding the dependencies, install them: ```bash mix deps.get ``` ### Traces Traces give us the big picture of what happens when a request is made to an application. Whether your application is a monolith with a single database or a sophisticated mesh of services, traces are essential to understanding the full "path" a request takes in your application. #### Auto Instrumentation of Traces ##### Step 1: Initialize OpenTelemetry Instrumentation Add the following setup calls in your application module's `start/2` function: ```elixir title="lib/phoenix_app/application.ex" showLineNumbers def start(_type, _args) do # Initialize Phoenix instrumentation OpentelemetryPhoenix.setup() # Initialize Ecto instrumentation OpentelemetryEcto.setup([:phoenix_app, :repo]) # ... rest of your application setup end ``` ##### Step 2: Configure OpenTelemetry Exporter Add OpenTelemetry configuration to your runtime configuration: ```elixir title="config/runtime.exs" showLineNumbers import Config # OpenTelemetry resource configuration config :opentelemetry, resource: [ service: [ name: "phoenix-app", version: "1.0.0" ] ] # OpenTelemetry exporter configuration config :opentelemetry_exporter, otlp_protocol: :http_protobuf, otlp_endpoint: "http://localhost:4318" ``` > Replace `localhost:4318` with your Scout collector endpoint. [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ##### Step 3: Configure Logger with Trace Context Add trace context to your logs for correlation: ```elixir title="config/config.exs" showLineNumbers config :logger, :default_formatter, format: "$time [$level] $message trace_id=$otel_trace_id span_id=$otel_span_id\n", metadata: [:otel_trace_id, :otel_span_id] ``` > View these traces in base14 Scout observability backend. That's it! Head over to Scout to visualize the traces. ### References - [OpenTelemetry Erlang Documentation](https://opentelemetry.io/docs/languages/erlang/) - [Phoenix Framework Documentation](https://hexdocs.pm/phoenix/telemetry.html) - [Sample Phoenix application with OpenTelemetry instrumentation](https://github.com/base-14/examples/tree/main/elixir/phoenix18-ecto3-postgres) ### Related Guides - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Deploy collector on Kubernetes --- ## Elysia (Bun) OpenTelemetry Instrumentation - Complete APM Setup Guide ## Elysia (Bun) Implement OpenTelemetry instrumentation for Elysia applications running on the Bun runtime to enable distributed tracing, custom metrics, and structured logging. This guide shows you how to use the OpenTelemetry Node.js SDK with Bun's `--preload` flag, create manual spans for Elysia route handlers, auto-instrument PostgreSQL queries through Drizzle ORM, and propagate trace context across services -- all without relying on `getNodeAutoInstrumentations()`. Elysia is a Bun-first framework that shares its lightweight, middleware-driven design with [Hono](./hono.md). Elysia on Bun requires a different instrumentation approach than traditional Node.js frameworks. Because Bun does not use Node's `http` module internally, HTTP auto-instrumentation cannot intercept Elysia requests. Instead, you create targeted manual spans with a `traced()` wrapper function and rely on `@opentelemetry/instrumentation-pg` for automatic database span generation. The result is a lean, precise instrumentation setup with full control over span names, attributes, and context propagation. Whether you're building with Bun for its startup speed, migrating from Node.js-based frameworks, or evaluating Elysia for a new microservice, this guide provides production-ready configurations for OpenTelemetry on the Bun runtime. :::tip TL;DR Create a `tracing.ts` file with `NodeSDK` + `PgInstrumentation` + `LoggerProvider`, preload it with `bun run --preload ./src/tracing.ts`, and wrap route handlers with a `traced()` helper that calls `tracer.startActiveSpan()`. Database spans from Drizzle ORM are captured automatically through the `pg` driver instrumentation. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Elysia developers**: adding observability to Bun-based APIs for the first time - **Bun adopters**: navigating the differences between Bun and Node.js OpenTelemetry support - **DevOps engineers**: deploying Elysia/Bun services with production monitoring and container orchestration - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-source observability - **Backend developers**: debugging performance issues or tracing requests across multiple Bun-based microservices ### Overview This guide demonstrates how to: - Set up the OpenTelemetry Node.js SDK on the Bun runtime - Preload instrumentation with `bun run --preload` for early initialization - Create manual spans for Elysia route handlers using a `traced()` wrapper - Auto-instrument PostgreSQL queries via `@opentelemetry/instrumentation-pg` - Build a custom OTel logger with `@opentelemetry/api-logs` and stdout mirror - Implement custom metrics with `articles.created` counters - Propagate trace context across services with `propagation.inject/extract` - Use Elysia's `t.Object()` validation with type-safe request bodies - Export traces, metrics, and logs to base14 Scout via OTLP HTTP - Deploy with Docker using `oven/bun:1.3-alpine` base images #### Prerequisites Before starting, ensure you have: - **Bun 1.3 or later** installed - **Elysia 1.4 or later** installed in your project - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment - **Basic understanding** of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | ---------------------------- | --------------- | ------------------- | ---------------------------------- | | **Bun** | 1.1.0 | 1.3.x | Node.js compat layer required | | **Elysia** | 1.0.0 | 1.4.x | Latest v1 with plugin system | | **TypeScript** | 5.0.0 | 6.0.x | Bun includes TS transpiler | | **OpenTelemetry SDK** | 0.200.0 | 0.214+ | Core SDK for traces/metrics | | **@opentelemetry/api-logs** | 0.200.0 | 0.214+ | LogRecord API for structured logs | | **instrumentation-pg** | 0.60.0 | 0.66.0+ | PostgreSQL auto-instrumentation | | **PostgreSQL** | 15.0 | 18.x | For database instrumentation | | **Drizzle ORM** | 0.40.0 | 0.45.x | Type-safe SQL via node-postgres | #### Instrumented Components | Component | Method | What You Get | | ---------------- | ------------------- | --------------------------------------------- | | HTTP routes | Manual spans | Route-level traces with status codes | | PostgreSQL | Auto (pg driver) | Query spans with statement and duration | | Drizzle ORM | Auto (via pg) | All Drizzle queries appear as database spans | | Business metrics | Custom counter | `articles.created` count | | Logging | OTel LoggerProvider | Structured logs with trace/span correlation | | Cross-service | Manual propagation | Distributed traces across Bun services | #### Example Application The complete working example is available at [elysia-postgres](https://github.com/base-14/examples/tree/main/bun/elysia-postgres). It includes two Elysia services (app + notify), PostgreSQL with Drizzle ORM, and a Scout Collector configuration. ### Installation #### Core Packages Install the required OpenTelemetry and application packages with Bun: ```bash showLineNumbers bun add @opentelemetry/api bun add @opentelemetry/sdk-node bun add @opentelemetry/sdk-metrics bun add @opentelemetry/exporter-trace-otlp-http bun add @opentelemetry/exporter-metrics-otlp-http bun add @opentelemetry/resources bun add @opentelemetry/semantic-conventions bun add @opentelemetry/instrumentation-pg ``` #### Logging Packages ```bash showLineNumbers bun add @opentelemetry/api-logs bun add @opentelemetry/sdk-logs bun add @opentelemetry/exporter-logs-otlp-http ``` #### Application Packages ```bash showLineNumbers bun add elysia bun add drizzle-orm pg bun add -d drizzle-kit @types/pg typescript ``` :::info Why not `getNodeAutoInstrumentations()`? Bun's runtime does not use Node.js's internal `http` module for its HTTP server. The `@opentelemetry/instrumentation-http` package -- which `getNodeAutoInstrumentations()` relies on -- monkey-patches Node's `http` module and has no effect on Elysia/Bun request handling. Instead, use targeted instrumentations like `@opentelemetry/instrumentation-pg` for database spans and create manual spans for HTTP route handlers. ::: #### Tracing Setup Create a `tracing.ts` file that initializes the OpenTelemetry SDK, metric reader, and logger provider. This file runs before your application code via Bun's `--preload` flag. ```typescript showLineNumbers title="src/tracing.ts" import { logs } from "@opentelemetry/api-logs"; import { OTLPLogExporter } from "@opentelemetry/exporter-logs-otlp-http"; import { OTLPMetricExporter } from "@opentelemetry/exporter-metrics-otlp-http"; import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-http"; import { PgInstrumentation } from "@opentelemetry/instrumentation-pg"; import { resourceFromAttributes } from "@opentelemetry/resources"; import { BatchLogRecordProcessor, LoggerProvider } from "@opentelemetry/sdk-logs"; import { PeriodicExportingMetricReader } from "@opentelemetry/sdk-metrics"; import { NodeSDK } from "@opentelemetry/sdk-node"; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from "@opentelemetry/semantic-conventions"; const endpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT ?? "http://localhost:4318"; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME ?? "elysia-articles", [ATTR_SERVICE_VERSION]: process.env.OTEL_SERVICE_VERSION ?? "1.0.0", }); const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${endpoint}/v1/traces` }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${endpoint}/v1/metrics` }), exportIntervalMillis: parseInt( process.env.OTEL_METRIC_EXPORT_INTERVAL || "10000" ), }), instrumentations: [new PgInstrumentation({ requireParentSpan: true })], }); sdk.start(); const loggerProvider = new LoggerProvider({ processors: [ new BatchLogRecordProcessor( new OTLPLogExporter({ url: `${endpoint}/v1/logs` }) ), ], }); logs.setGlobalLoggerProvider(loggerProvider); process.on("SIGTERM", async () => { await loggerProvider.shutdown(); await sdk.shutdown(); process.exit(0); }); ``` Key details in this setup: - **OTLP HTTP exporters** with explicit `/v1/traces`, `/v1/metrics`, and `/v1/logs` paths -- Bun's fetch-based HTTP client works reliably with HTTP exporters (not gRPC) - **`PgInstrumentation`** with `requireParentSpan: true` so database spans only appear within the context of a request span, not from connection pool health checks - **Separate `LoggerProvider`** because the `NodeSDK` `logRecordProcessor` option may not initialize correctly on all Bun versions -- setting the global logger provider explicitly is more reliable - **`SIGTERM` handler** for graceful shutdown in containerized deployments ### Configuration #### Environment Variables ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=elysia-articles OTEL_SERVICE_VERSION=1.0.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_METRIC_EXPORT_INTERVAL=10000 DATABASE_URL=postgresql://postgres:postgres@localhost:5432/elysia_articles NOTIFY_URL=http://localhost:8081 PORT=8080 ``` #### Custom OTel Logger Instead of using Pino or another logging library, this setup uses the OpenTelemetry Logs API directly. Every log entry is emitted as an OTel `LogRecord` with automatic trace correlation, plus a JSON line to stdout for local debugging. ```typescript showLineNumbers title="src/logger.ts" import { trace, context as otelContext } from "@opentelemetry/api"; import { logs, SeverityNumber } from "@opentelemetry/api-logs"; const otelLogger = logs.getLogger("elysia-articles"); type LogAttrs = Record; function emit( severityNumber: SeverityNumber, severityText: string, message: string, attrs?: LogAttrs ) { const span = trace.getActiveSpan(); const ctx = span?.spanContext(); otelLogger.emit({ severityNumber, severityText, body: message, context: otelContext.active(), attributes: { ...attrs, ...(ctx ? { trace_id: ctx.traceId, span_id: ctx.spanId } : {}), }, }); const record: Record = { ts: new Date().toISOString(), level: severityText, msg: message, ...attrs, ...(ctx ? { trace_id: ctx.traceId, span_id: ctx.spanId } : {}), }; const line = JSON.stringify(record); if (severityNumber >= SeverityNumber.ERROR) { process.stderr.write(`${line}\n`); } else { process.stdout.write(`${line}\n`); } } export const logger = { info: (msg: string, attrs?: LogAttrs) => emit(SeverityNumber.INFO, "INFO", msg, attrs), warn: (msg: string, attrs?: LogAttrs) => emit(SeverityNumber.WARN, "WARN", msg, attrs), error: (msg: string, attrs?: LogAttrs) => emit(SeverityNumber.ERROR, "ERROR", msg, attrs), }; ``` This approach has two advantages over Pino on Bun: it avoids the `pino-opentelemetry-transport` worker thread (which has inconsistent behavior on Bun), and it emits `LogRecord` objects with proper `context` for automatic trace/span ID correlation in Scout. #### Database with Drizzle ORM Drizzle ORM uses the `node-postgres` (`pg`) adapter, which means every query flows through a `pg.Pool` instance. The `PgInstrumentation` in `tracing.ts` hooks into that pool to generate database spans automatically. ```typescript showLineNumbers title="src/schema.ts" import { pgTable, serial, text, timestamp, varchar } from "drizzle-orm/pg-core"; export const articles = pgTable("articles", { id: serial().primaryKey(), title: varchar({ length: 255 }).notNull(), body: text().notNull(), createdAt: timestamp("created_at", { precision: 3 }).notNull().defaultNow(), updatedAt: timestamp("updated_at", { precision: 3 }).notNull().defaultNow(), }); ``` ```typescript showLineNumbers title="src/db.ts" import { drizzle } from "drizzle-orm/node-postgres"; import { Pool } from "pg"; import * as schema from "./schema"; const pool = new Pool({ connectionString: process.env.DATABASE_URL }); export const db = drizzle(pool, { schema }); ``` Because `tracing.ts` is preloaded before `db.ts` is imported, the `pg` module is already instrumented when the pool is created. Every Drizzle query -- `db.select()`, `db.insert()`, `db.update()`, `db.delete()` -- produces a `pg.query` span with the SQL statement and execution time. #### Docker Compose The full development stack with both Elysia services, PostgreSQL, and the Scout Collector: ```yaml showLineNumbers title="compose.yml" services: app: build: ./app ports: - "8080:8080" environment: PORT: "8080" DATABASE_URL: postgresql://postgres:postgres@db:5432/elysia_articles NOTIFY_URL: http://notify:8081 OTEL_SERVICE_NAME: elysia-articles OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_METRIC_EXPORT_INTERVAL: "10000" OTEL_RESOURCE_ATTRIBUTES: deployment.environment=${SCOUT_ENVIRONMENT:-development},environment=${SCOUT_ENVIRONMENT:-development},service.namespace=examples depends_on: db: condition: service_healthy otel-collector: condition: service_started healthcheck: test: [ "CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:8080/api/health", ] interval: 10s timeout: 5s retries: 10 start_period: 20s notify: build: ./notify ports: - "8081:8081" environment: PORT: "8081" OTEL_SERVICE_NAME: elysia-notify OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_METRIC_EXPORT_INTERVAL: "10000" OTEL_RESOURCE_ATTRIBUTES: deployment.environment=${SCOUT_ENVIRONMENT:-development},environment=${SCOUT_ENVIRONMENT:-development},service.namespace=examples depends_on: otel-collector: condition: service_started healthcheck: test: [ "CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:8081/api/health", ] interval: 10s timeout: 5s retries: 5 start_period: 10s db: image: postgres:18-alpine environment: POSTGRES_DB: elysia_articles POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres ports: - "5432:5432" volumes: - pgdata:/var/lib/postgresql/data - ./db/init.sql:/docker-entrypoint-initdb.d/init.sql:ro healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 3s retries: 10 otel-collector: image: otel/opentelemetry-collector-contrib:0.148.0 command: ["--config=/etc/otel/config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otel/config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" environment: SCOUT_ENDPOINT: ${SCOUT_ENDPOINT:-http://localhost:4318} SCOUT_CLIENT_ID: ${SCOUT_CLIENT_ID:-} SCOUT_CLIENT_SECRET: ${SCOUT_CLIENT_SECRET:-} SCOUT_TOKEN_URL: ${SCOUT_TOKEN_URL:-http://localhost/token} SCOUT_ENVIRONMENT: ${SCOUT_ENVIRONMENT:-development} healthcheck: test: ["NONE"] volumes: pgdata: ``` #### Scout Collector Integration The collector uses OAuth2 authentication to forward telemetry to Scout. Set these environment variables before running `docker compose up`: ```bash showLineNumbers export SCOUT_ENDPOINT=https://your-scout-endpoint.base14.io export SCOUT_CLIENT_ID=your-client-id export SCOUT_CLIENT_SECRET=your-client-secret export SCOUT_TOKEN_URL=https://auth.base14.io/oauth/token export SCOUT_ENVIRONMENT=development ``` The collector configuration uses the `oauth2client` extension for authentication, `batch` processor for efficient export, and `memory_limiter` for safety. Health check spans are filtered out via the `filter/noisy` processor to reduce noise. ### Production Configuration #### Production Environment Variables ```bash showLineNumbers title=".env.production" OTEL_SERVICE_NAME=elysia-articles OTEL_SERVICE_VERSION=1.2.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_METRIC_EXPORT_INTERVAL=60000 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,service.namespace=articles DATABASE_URL=postgresql://app_user:secure_password@db-primary:5432/articles_prod NOTIFY_URL=http://notify:8081 PORT=8080 ``` In production, increase `OTEL_METRIC_EXPORT_INTERVAL` to `60000` (60 seconds) to reduce metric export frequency and collector load. #### Dockerfile Both services use a multi-stage build with `oven/bun:1.3-alpine` for minimal image size. The `--preload` flag in the `CMD` ensures tracing initializes before the application. ```dockerfile showLineNumbers title="app/Dockerfile" FROM oven/bun:1.3-alpine AS deps WORKDIR /app COPY package.json bun.lock* ./ RUN bun install --frozen-lockfile FROM oven/bun:1.3-alpine RUN addgroup -g 1001 -S appgroup && adduser -S appuser -u 1001 -G appgroup WORKDIR /app COPY --from=deps /app/node_modules ./node_modules COPY package.json ./ COPY src ./src/ RUN chown -R appuser:appgroup /app USER appuser HEALTHCHECK --interval=10s --timeout=5s --start-period=15s --retries=5 \ CMD wget --no-verbose --tries=1 --spider http://localhost:8080/api/health || exit 1 EXPOSE 8080 CMD ["bun", "run", "--preload", "./src/tracing.ts", "./src/index.ts"] ``` The `oven/bun:1.3-alpine` image is roughly 100MB -- significantly smaller than most Node.js images. Bun's built-in TypeScript transpiler means no separate build step is needed. #### Multi-Service Tracing The example application consists of two Bun services that communicate via HTTP. Trace context flows from the app service to the notify service through W3C `traceparent` headers, creating a single distributed trace across both services. **Outgoing side** -- inject trace context into fetch headers: ```typescript showLineNumbers title="src/notification.ts" import { context, propagation } from "@opentelemetry/api"; import { logger } from "./logger"; const notifyUrl = process.env.NOTIFY_URL ?? "http://localhost:8081"; export async function notifyArticleCreated(articleId: number, title: string) { const headers: Record = { "Content-Type": "application/json" }; propagation.inject(context.active(), headers); try { const res = await fetch(`${notifyUrl}/notify`, { method: "POST", headers, body: JSON.stringify({ event: "article.created", article_id: articleId, title }), }); if (!res.ok) { logger.warn("Notify service returned non-OK", { status: res.status }); } } catch (err) { logger.warn("Notify service unreachable", { error: String(err) }); } } ``` `propagation.inject()` writes the `traceparent` and `tracestate` headers into the plain object. Bun's native `fetch` sends these headers to the downstream service. **Incoming side** -- extract trace context and create a child span: ```typescript showLineNumbers title="notify/src/index.ts" import { Elysia, t } from "elysia"; import { trace, SpanKind, context, propagation } from "@opentelemetry/api"; import { logger } from "./logger"; const tracer = trace.getTracer("elysia-notify"); const PORT = parseInt(process.env.PORT || "8081"); const app = new Elysia() .get("/api/health", () => ({ status: "healthy", service: "elysia-notify" })) .post("/notify", async ({ body, request }) => { const carrier: Record = {}; request.headers.forEach((value, key) => { carrier[key] = value; }); const parentCtx = propagation.extract(context.active(), carrier); return trace.getTracer("elysia-notify").startActiveSpan( "POST /notify", { kind: SpanKind.SERVER }, parentCtx, async (span) => { logger.info("Notification received", { event: String(body.event), article_id: Number(body.article_id), }); span.setAttribute("notification.event", String(body.event)); span.setAttribute("notification.article_id", Number(body.article_id)); span.end(); return { status: "received" }; } ); }) .listen(PORT); logger.info("Notify service started", { port: PORT }); ``` The notify service converts `request.headers` (a `Headers` object) into a plain object so `propagation.extract()` can read the `traceparent` header. The extracted context is passed as the third argument to `startActiveSpan`, creating a child span that links back to the originating request in the app service. ### Elysia-Specific Features #### Plugin System Elysia uses a plugin-based architecture where route groups are defined as separate `Elysia` instances and composed with `.use()`: ```typescript showLineNumbers title="src/index.ts" import { Elysia } from "elysia"; import { trace, SpanKind, SpanStatusCode } from "@opentelemetry/api"; import { logger } from "./logger"; import { healthRoutes } from "./routes/health"; import { articleRoutes } from "./routes/article"; const tracer = trace.getTracer("elysia-articles"); const PORT = parseInt(process.env.PORT || "8080"); const app = new Elysia() .onError(({ code, error, set, request }) => { const url = new URL(request.url); return tracer.startActiveSpan( `${request.method} ${url.pathname}`, { kind: SpanKind.SERVER }, (span) => { if (code === "VALIDATION") { logger.warn("Validation failed", { path: url.pathname }); span.setAttribute("http.response.status_code", 422); span.setStatus({ code: SpanStatusCode.ERROR, message: "Validation failed" }); span.end(); set.status = 422; return { error: "Validation failed", details: error.message, meta: { trace_id: span.spanContext().traceId }, }; } logger.error("Unhandled error", { error: String(error) }); span.setAttribute("http.response.status_code", 500); span.setStatus({ code: SpanStatusCode.ERROR, message: String(error) }); span.end(); set.status = 500; return { error: "Internal server error", meta: { trace_id: span.spanContext().traceId }, }; } ); }) .use(healthRoutes) .use(articleRoutes) .listen(PORT); logger.info("Elysia articles server started", { port: PORT }); ``` The `onError` hook creates a span for every unhandled error, capturing the HTTP method, path, and status code. Validation errors from Elysia's built-in `t.Object()` validators return 422 with a trace ID in the response body. #### Type-Safe Routes with Validation Elysia provides compile-time type inference from runtime validators. When you define a body schema with `t.Object()`, both request validation and TypeScript types are derived from a single source: ```typescript showLineNumbers .post( "/", async ({ body, set }) => traced("POST /api/articles", set, async () => { const [article] = await db .insert(articles) .values({ title: body.title, body: body.body }) .returning(); // body.title and body.body are type-checked at compile time set.status = 201; return { data: article, meta: { trace_id: getTraceId() } }; }), { body: t.Object({ title: t.String({ minLength: 1 }), body: t.String({ minLength: 1 }), }), } ) ``` If validation fails, Elysia throws a `VALIDATION` error that the `onError` hook captures and wraps in a span (see above). #### The `traced()` Wrapper Pattern Since Elysia on Bun cannot use HTTP auto-instrumentation, every route handler is wrapped with a `traced()` function that manages span lifecycle: ```typescript showLineNumbers title="src/routes/article.ts" const tracer = trace.getTracer("elysia-articles"); function traced( name: string, set: { status?: number | string }, fn: () => Promise ): Promise { return tracer.startActiveSpan(name, { kind: SpanKind.SERVER }, async (span) => { try { const result = await fn(); const status = typeof set.status === "number" ? set.status : 200; span.setAttribute("http.response.status_code", status); if (status >= 400) span.setStatus({ code: SpanStatusCode.ERROR }); span.end(); return result; } catch (err) { span.setAttribute("http.response.status_code", 500); span.setStatus({ code: SpanStatusCode.ERROR, message: String(err) }); span.end(); throw err; } }); } ``` This wrapper: - Creates a `SERVER` span with the route name (e.g., `GET /api/articles`) - Reads the response status code from Elysia's `set` object after the handler completes - Marks spans as `ERROR` for 4xx and 5xx responses - Ensures `span.end()` is called in both success and error paths - Propagates the active context so that database queries within `fn()` become child spans #### Drizzle ORM Auto-Tracing via PgInstrumentation Because Drizzle ORM uses the `pg` driver internally, all database operations are automatically instrumented. A single route handler like this: ```typescript showLineNumbers const [rows, [{ total }]] = await Promise.all([ db .select() .from(articles) .orderBy(desc(articles.createdAt)) .limit(perPage) .offset(offset), db.select({ total: count() }).from(articles), ]); ``` Generates a span hierarchy like: ```text GET /api/articles (SERVER) ├── pg.query:SELECT (CLIENT) — article rows └── pg.query:SELECT (CLIENT) — count query ``` Each `pg.query` span includes the SQL statement (with parameter values obfuscated by default), execution duration, database name, and host. #### onError Hook The global `onError` hook ensures that even failed requests produce spans with meaningful error information: ```typescript showLineNumbers .onError(({ code, error, set, request }) => { const url = new URL(request.url); return tracer.startActiveSpan( `${request.method} ${url.pathname}`, { kind: SpanKind.SERVER }, (span) => { if (code === "VALIDATION") { span.setAttribute("http.response.status_code", 422); span.setStatus({ code: SpanStatusCode.ERROR, message: "Validation failed" }); span.end(); set.status = 422; return { error: "Validation failed", details: error.message }; } // ... handle other errors } ); }) ``` Elysia's error codes (`VALIDATION`, `NOT_FOUND`, `INTERNAL_SERVER_ERROR`, `PARSE`) let you distinguish error types in span attributes for targeted alerting. ### Custom Instrumentation #### Business Metrics with Counters Track application-level metrics alongside trace data. The `articles.created` counter increments every time a new article is successfully inserted: ```typescript showLineNumbers title="src/routes/article.ts" import { metrics } from "@opentelemetry/api"; const meter = metrics.getMeter("elysia-articles"); const articlesCreated = meter.createCounter("articles.created", { description: "Number of articles created", }); // Inside the POST handler: const [article] = await db .insert(articles) .values({ title: body.title, body: body.body }) .returning(); articlesCreated.add(1); ``` This counter is exported via the `PeriodicExportingMetricReader` configured in `tracing.ts` and appears in Scout as a time-series metric. #### Trace ID in Responses Every API response includes a `trace_id` field so callers can reference the exact trace when reporting issues: ```typescript showLineNumbers function getTraceId(): string { return trace.getActiveSpan()?.spanContext().traceId ?? ""; } // Used in responses: return { data: article, meta: { trace_id: getTraceId() } }; ``` This is especially useful during development and debugging -- the trace ID links directly to the full distributed trace in Scout. #### Manual Spans with startActiveSpan For operations that need additional detail beyond what `traced()` provides, create nested spans directly: ```typescript showLineNumbers import { trace, SpanKind } from "@opentelemetry/api"; const tracer = trace.getTracer("elysia-articles"); async function enrichArticle(articleId: number) { return tracer.startActiveSpan( "enrichArticle", { kind: SpanKind.INTERNAL }, async (span) => { span.setAttribute("article.id", articleId); try { const result = await performEnrichment(articleId); span.end(); return result; } catch (err) { span.recordException(err as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (err as Error).message, }); span.end(); throw err; } } ); } ``` When called inside a `traced()` handler, this span becomes a child of the route span, creating a detailed breakdown of the request processing steps. #### Complete Route Example Here is the full article routes file with all instrumentation patterns combined -- the `traced()` wrapper, business counter, trace ID in responses, type-safe validation, and notification with context propagation: ```typescript showLineNumbers title="src/routes/article.ts" import { Elysia, t } from "elysia"; import { eq, desc, count, sql } from "drizzle-orm"; import { trace, SpanKind, SpanStatusCode } from "@opentelemetry/api"; import { metrics } from "@opentelemetry/api"; import { db } from "../db"; import { articles } from "../schema"; import { logger } from "../logger"; import { notifyArticleCreated } from "../notification"; const tracer = trace.getTracer("elysia-articles"); const meter = metrics.getMeter("elysia-articles"); const articlesCreated = meter.createCounter("articles.created", { description: "Number of articles created", }); function getTraceId(): string { return trace.getActiveSpan()?.spanContext().traceId ?? ""; } function traced( name: string, set: { status?: number | string }, fn: () => Promise ): Promise { return tracer.startActiveSpan(name, { kind: SpanKind.SERVER }, async (span) => { try { const result = await fn(); const status = typeof set.status === "number" ? set.status : 200; span.setAttribute("http.response.status_code", status); if (status >= 400) span.setStatus({ code: SpanStatusCode.ERROR }); span.end(); return result; } catch (err) { span.setAttribute("http.response.status_code", 500); span.setStatus({ code: SpanStatusCode.ERROR, message: String(err) }); span.end(); throw err; } }); } export const articleRoutes = new Elysia({ prefix: "/api/articles" }) .get("/", async ({ query, set }) => traced("GET /api/articles", set, async () => { const page = Number(query.page) || 1; const perPage = Number(query.per_page) || 20; const offset = (page - 1) * perPage; const [rows, [{ total }]] = await Promise.all([ db .select() .from(articles) .orderBy(desc(articles.createdAt)) .limit(perPage) .offset(offset), db.select({ total: count() }).from(articles), ]); logger.info("Listed articles", { page, per_page: perPage, total }); return { data: rows, meta: { page, per_page: perPage, total, trace_id: getTraceId(), }, }; }) ) .post( "/", async ({ body, set }) => traced("POST /api/articles", set, async () => { const [article] = await db .insert(articles) .values({ title: body.title, body: body.body }) .returning(); articlesCreated.add(1); logger.info("Article created", { id: article.id, title: article.title }); await notifyArticleCreated(article.id, article.title); set.status = 201; return { data: article, meta: { trace_id: getTraceId() } }; }), { body: t.Object({ title: t.String({ minLength: 1 }), body: t.String({ minLength: 1 }), }), } ) .get("/:id", async ({ params, set }) => traced("GET /api/articles/:id", set, async () => { const id = Number(params.id); if (isNaN(id) || !Number.isInteger(id) || id < 1) { logger.warn("Invalid article ID format", { raw_id: params.id }); set.status = 400; return { error: "Invalid ID format", details: "ID must be a positive integer", meta: { trace_id: getTraceId() }, }; } const [article] = await db .select() .from(articles) .where(eq(articles.id, id)); if (!article) { logger.warn("Article not found", { id }); set.status = 404; return { error: "Article not found", meta: { trace_id: getTraceId() } }; } return { data: article, meta: { trace_id: getTraceId() } }; }) ) .put( "/:id", async ({ params, body, set }) => traced("PUT /api/articles/:id", set, async () => { const id = Number(params.id); if (isNaN(id) || !Number.isInteger(id) || id < 1) { set.status = 400; return { error: "Invalid ID format", meta: { trace_id: getTraceId() }, }; } const updates: Record = { updatedAt: new Date(), }; if (body.title) updates.title = body.title; if (body.body) updates.body = body.body; const [article] = await db .update(articles) .set(updates) .where(eq(articles.id, id)) .returning(); if (!article) { logger.warn("Article not found for update", { id }); set.status = 404; return { error: "Article not found", meta: { trace_id: getTraceId() } }; } logger.info("Article updated", { id }); return { data: article, meta: { trace_id: getTraceId() } }; }), { body: t.Partial( t.Object({ title: t.String({ minLength: 1 }), body: t.String({ minLength: 1 }), }) ), } ) .delete("/:id", async ({ params, set }) => traced("DELETE /api/articles/:id", set, async () => { const id = Number(params.id); if (isNaN(id) || !Number.isInteger(id) || id < 1) { set.status = 400; return { error: "Invalid ID format", meta: { trace_id: getTraceId() } }; } const [article] = await db .delete(articles) .where(eq(articles.id, id)) .returning(); if (!article) { logger.warn("Article not found for delete", { id }); set.status = 404; return { error: "Article not found", meta: { trace_id: getTraceId() } }; } logger.info("Article deleted", { id }); set.status = 204; }) ); ``` ### Running Your Application ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Start the application in development mode with watch and preload: ```bash showLineNumbers bun run --watch --preload ./src/tracing.ts ./src/index.ts ``` Or use the `package.json` scripts: ```bash showLineNumbers bun run dev ``` ```mdx-code-block ``` ```bash showLineNumbers docker compose up --build docker compose logs -f app notify docker compose down ``` ```mdx-code-block ``` #### Verification After starting the application, create an article and verify spans are generated: ```bash showLineNumbers curl -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Hello Elysia", "body": "First post with OpenTelemetry tracing"}' ``` Expected response: ```json { "data": { "id": 1, "title": "Hello Elysia", "body": "First post with OpenTelemetry tracing", "createdAt": "2026-03-31T10:00:00.000Z", "updatedAt": "2026-03-31T10:00:00.000Z" }, "meta": { "trace_id": "a1b2c3d4e5f6a1b2c3d4e5f6a1b2c3d4" } } ``` The `trace_id` in the response maps to this span hierarchy in Scout: ```text elysia-articles: POST /api/articles (SERVER, 201) ├── pg.query:INSERT (CLIENT) — insert article └── elysia-notify: POST /notify (SERVER) └── [notification processing] ``` List articles to verify pagination and database spans: ```bash showLineNumbers curl http://localhost:8080/api/articles?page=1&per_page=10 ``` Check the health endpoint: ```bash showLineNumbers curl http://localhost:8080/api/health ``` ### Troubleshooting #### Common Issues ##### Issue: Preload not loading tracing.ts **Symptoms**: No spans or metrics appear. Application starts normally but the collector receives no data. **Solutions:** 1. Verify the `--preload` flag is before the entry point in the command: ```bash showLineNumbers # Correct bun run --preload ./src/tracing.ts ./src/index.ts # Wrong — preload after entry point is ignored bun run ./src/index.ts --preload ./src/tracing.ts ``` 2. Check that `tracing.ts` does not import any application modules (it should only import `@opentelemetry/*` packages) 3. Confirm the file path is relative to the working directory, not the `src` folder ##### Issue: PgInstrumentation not capturing database spans **Symptoms**: Route spans appear but no `pg.query` child spans. **Solutions:** 1. Ensure `tracing.ts` is preloaded before `pg` is imported. The instrumentation must patch `pg` before any `Pool` or `Client` is created 2. Verify you are using `pg` (node-postgres), not `postgres` (postgres.js) -- `PgInstrumentation` only supports the `pg` package 3. Check that `requireParentSpan: true` is not filtering out spans -- try setting it to `false` temporarily to confirm spans appear ##### Issue: Manual context propagation not linking traces **Symptoms**: The app service and notify service produce separate, unlinked traces instead of a single distributed trace. **Solutions:** 1. Verify `propagation.inject()` is called within an active span context. If called outside a `traced()` wrapper, there is no active context to propagate 2. On the receiving side, convert `request.headers` to a plain object before calling `propagation.extract()` -- the W3C propagator expects a simple key-value carrier, not a `Headers` instance 3. Pass the extracted context as the third argument to `startActiveSpan`: ```typescript showLineNumbers const parentCtx = propagation.extract(context.active(), carrier); tracer.startActiveSpan("span-name", { kind: SpanKind.SERVER }, parentCtx, (span) => { // ... }); ``` ##### Issue: OTLP export failures on Bun **Symptoms**: Console shows connection errors or timeout warnings from OTLP exporters. **Solutions:** 1. Use HTTP exporters (port 4318), not gRPC (port 4317). Bun does not support gRPC natively 2. Verify the endpoint URL includes the signal-specific path: `http://collector:4318/v1/traces` (not just `http://collector:4318`) 3. Check that the collector is running and reachable from the Bun process. In Docker Compose, use the service name as hostname ##### Issue: LoggerProvider not emitting logs **Symptoms**: Trace and metric data appears in Scout but no log records. **Solutions:** 1. Ensure `logs.setGlobalLoggerProvider(loggerProvider)` is called in `tracing.ts` after creating the `LoggerProvider` 2. Verify the logger calls `otelLogger.emit()` with the `context` field set to `otelContext.active()` for trace correlation 3. Check that the log exporter URL ends with `/v1/logs` #### Debug Mode Enable verbose SDK logging to diagnose initialization issues: ```bash showLineNumbers OTEL_LOG_LEVEL=debug bun run --preload ./src/tracing.ts ./src/index.ts ``` ### Security Considerations #### SQL Query Obfuscation `PgInstrumentation` obfuscates SQL parameter values by default. Query statements appear in spans as: ```text INSERT INTO "articles" ("title", "body") VALUES ($1, $2) RETURNING * ``` Parameter values (`$1`, `$2`) are never captured in span attributes. To verify this behavior, avoid setting `enhancedDatabaseReporting: true` in production: ```typescript showLineNumbers // Safe default — parameter values are obfuscated new PgInstrumentation({ requireParentSpan: true }) // AVOID in production — captures actual parameter values new PgInstrumentation({ enhancedDatabaseReporting: true }) ``` #### PII Protection Prevent sensitive data from leaking into telemetry: ```typescript showLineNumbers // BAD: Captures user email in span span.setAttribute("user.email", email); // GOOD: Only capture non-sensitive identifiers span.setAttribute("user.id", userId); span.setAttribute("user.email_domain", email.split("@")[1]); ``` For the custom OTel logger, be cautious with structured attributes: ```typescript showLineNumbers // BAD: Logs request body that might contain passwords logger.info("Request received", { body: JSON.stringify(req.body) }); // GOOD: Log only safe identifiers logger.info("Article created", { id: article.id, title: article.title }); ``` #### Compliance Considerations For GDPR, HIPAA, or PCI-DSS compliance: - Never log PII in span attributes or log record attributes - Use pseudonymization for user identifiers when possible - Configure data retention policies in your observability backend - Implement attribute filtering at the collector level using the `transform` processor ### Performance Considerations #### Bun Runtime Advantages Bun's startup time is typically 3-5x faster than Node.js, which means the overhead of preloading `tracing.ts` is minimal -- usually under 100ms. The OpenTelemetry SDK initialization adds roughly 50-80ms to cold start, compared to 150-300ms on Node.js. #### Expected Impact | Metric | Typical Impact | High-Traffic Impact | | ------------ | -------------- | ------------------- | | Latency | +1-2ms | +2-4ms | | CPU overhead | 2-4% | 4-8% | | Memory | +30-60MB | +60-120MB | Bun's lower baseline memory usage means the absolute overhead of OpenTelemetry is smaller than on Node.js. #### Batch Export Tuning The `PeriodicExportingMetricReader` and `BatchLogRecordProcessor` buffer data before export. Adjust these for your traffic patterns: ```typescript showLineNumbers // Development: frequent exports for fast feedback metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${endpoint}/v1/metrics` }), exportIntervalMillis: 10000, // every 10 seconds }), // Production: less frequent exports to reduce overhead metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${endpoint}/v1/metrics` }), exportIntervalMillis: 60000, // every 60 seconds }), ``` #### Skip Health Check Spans Health check endpoints generate high-volume, low-value spans. The collector configuration filters these out with the `filter/noisy` processor: ```yaml showLineNumbers filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*health.*")' ``` This keeps health checks functional for container orchestrators while preventing span noise in Scout. ### FAQ #### Does OpenTelemetry work with Bun? Yes. Bun supports the OpenTelemetry Node.js SDK (`@opentelemetry/sdk-node`) through its Node.js compatibility layer. The `NodeSDK` class, OTLP HTTP exporters, and targeted instrumentations like `@opentelemetry/instrumentation-pg` work correctly. However, `getNodeAutoInstrumentations()` does not fully work because Bun does not use Node's internal `http`, `net`, `dns`, or `fs` modules for its core operations. #### Why do I need manual spans in Elysia instead of auto-instrumentation? Bun's HTTP server does not go through Node.js's `http.createServer()`, so `@opentelemetry/instrumentation-http` has nothing to patch. The `traced()` wrapper pattern gives you explicit control over span names (e.g., `GET /api/articles/:id` instead of generic `HTTP GET`) and lets you set response status codes from Elysia's `set` object. #### How does Drizzle ORM get instrumented without explicit setup? Drizzle ORM with the `drizzle-orm/node-postgres` adapter delegates all SQL execution to a `pg.Pool` instance. The `PgInstrumentation` patches the `pg` module at the driver level, so every query that flows through the pool -- whether from Drizzle's query builder, raw SQL, or transactions -- generates a `pg.query` span automatically. #### How do I propagate trace context between Bun services? On the sending side, call `propagation.inject(context.active(), headers)` to write `traceparent` and `tracestate` headers into a plain object, then pass that object to `fetch`. On the receiving side, extract headers into a plain object and call `propagation.extract(context.active(), carrier)` to get the parent context. Pass this context to `startActiveSpan` as the third argument. #### What is the difference between OTLP HTTP and gRPC on Bun? Use OTLP HTTP (port 4318). Bun does not have native gRPC support, and the `@grpc/grpc-js` package has compatibility issues on Bun. HTTP exporters work reliably with Bun's native `fetch` implementation and support HTTP proxies and load balancers. #### How do I use Drizzle ORM vs Prisma with OpenTelemetry on Bun? Drizzle ORM with `node-postgres` works well because `PgInstrumentation` patches the underlying `pg` driver. Prisma uses its own query engine binary, which bypasses the `pg` driver entirely -- `PgInstrumentation` cannot capture Prisma queries. If you use Prisma, you need Prisma's built-in tracing integration (`previewFeatures = ["tracing"]`) or its OpenTelemetry extension. #### Can I use Pino logging instead of the custom OTel logger? You can, but the `pino-opentelemetry-transport` package uses Node.js worker threads, which have inconsistent behavior on Bun. The custom OTel logger approach in this guide uses `@opentelemetry/api-logs` directly, avoiding worker threads entirely while providing the same trace correlation and structured log export. #### How do I add custom attributes to all spans? Set `OTEL_RESOURCE_ATTRIBUTES` as an environment variable: ```bash showLineNumbers OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=articles ``` These attributes are added to the resource and appear on every span, metric, and log record exported by the service. #### What happens if the collector is unavailable? The OTLP HTTP exporters fail silently -- your application continues to handle requests normally. Spans, metrics, and logs are buffered in memory and dropped when the buffer is full. When the collector comes back online, new telemetry data is exported normally. There is no automatic retry of dropped data. #### How do I monitor multiple Elysia services in a single trace? Each service needs its own `tracing.ts` with a unique `OTEL_SERVICE_NAME`. Use `propagation.inject()` on outgoing requests and `propagation.extract()` on incoming requests to link spans across services. The example in this guide demonstrates this with the `elysia-articles` and `elysia-notify` services. ### What's Next #### Related Guides - [Express Instrumentation](./express.md) - Most widely used Node.js framework - [Fastify Instrumentation](./fastify.md) - Performance-focused alternative - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerting for Elysia services - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards for Bun service metrics #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local collector configuration - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment ### Complete Example #### Project Structure ```text elysia-postgres/ ├── app/ │ ├── src/ │ │ ├── tracing.ts # OTel SDK initialization (preloaded) │ │ ├── index.ts # Elysia app entry point │ │ ├── logger.ts # Custom OTel logger with stdout mirror │ │ ├── db.ts # Drizzle + pg pool │ │ ├── schema.ts # Drizzle table schema │ │ ├── notification.ts # Outgoing fetch with propagation.inject │ │ └── routes/ │ │ ├── article.ts # Article CRUD with traced() wrapper │ │ └── health.ts # Health check endpoint │ ├── Dockerfile # oven/bun:1.3-alpine multi-stage │ ├── package.json │ └── tsconfig.json ├── notify/ │ ├── src/ │ │ ├── tracing.ts # OTel SDK for notify service │ │ ├── index.ts # Notify service with propagation.extract │ │ └── logger.ts # Shared logger pattern │ ├── Dockerfile │ └── package.json ├── config/ │ └── otel-config.yaml # Scout Collector configuration ├── db/ │ └── init.sql # PostgreSQL schema ├── compose.yml # Full development stack └── README.md ``` #### Running the Example ```bash showLineNumbers git clone https://github.com/base-14/examples.git cd examples/bun/elysia-postgres docker compose up --build ``` #### Testing ```bash showLineNumbers # Create an article curl -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Test Article", "body": "Testing OpenTelemetry with Elysia on Bun"}' # List articles curl http://localhost:8080/api/articles # Get a specific article curl http://localhost:8080/api/articles/1 # Update an article curl -X PUT http://localhost:8080/api/articles/1 \ -H "Content-Type: application/json" \ -d '{"title": "Updated Title"}' # Delete an article curl -X DELETE http://localhost:8080/api/articles/1 # Health check curl http://localhost:8080/api/health ``` #### Dependencies ```json showLineNumbers title="app/package.json" { "name": "elysia-postgres-app", "version": "1.0.0", "private": true, "scripts": { "start": "bun run --preload ./src/tracing.ts ./src/index.ts", "dev": "bun run --watch --preload ./src/tracing.ts ./src/index.ts" }, "dependencies": { "elysia": "^1.4.28", "drizzle-orm": "^0.45.2", "pg": "^8.20.0", "@opentelemetry/api": "^1.9.1", "@opentelemetry/api-logs": "^0.214.0", "@opentelemetry/sdk-node": "^0.214.0", "@opentelemetry/sdk-metrics": "^2.6.1", "@opentelemetry/sdk-logs": "^0.214.0", "@opentelemetry/exporter-trace-otlp-http": "^0.214.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.214.0", "@opentelemetry/exporter-logs-otlp-http": "^0.214.0", "@opentelemetry/instrumentation-pg": "^0.66.0", "@opentelemetry/resources": "^2.6.1", "@opentelemetry/semantic-conventions": "^1.40.0" }, "devDependencies": { "drizzle-kit": "^0.31.10", "@types/pg": "^8.20.0", "typescript": "^6.0.2" } } ``` #### GitHub Repository For the complete working example, see the [Elysia PostgreSQL Example](https://github.com/base-14/examples/tree/main/bun/elysia-postgres) repository. ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [Elysia Documentation](https://elysiajs.com/) - [Bun Documentation](https://bun.sh/docs) - [Drizzle ORM Documentation](https://orm.drizzle.team/) - [@opentelemetry/instrumentation-pg](https://www.npmjs.com/package/@opentelemetry/instrumentation-pg) - [OpenTelemetry Logs API](https://opentelemetry.io/docs/specs/otel/logs/) --- ## Express.js OpenTelemetry Instrumentation - Traces & Metrics Setup Implement OpenTelemetry instrumentation for Express.js applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your Express.js application to collect traces and metrics from HTTP requests, database queries, Redis operations, background jobs, and WebSocket connections using the OpenTelemetry Node.js SDK with minimal code changes. Express is the most widely used Node.js web framework. [Fastify](./fastify.md) is a performance-focused alternative, and [NestJS](./nestjs.md) adds a structured, opinionated layer on top of it. Express.js applications benefit from automatic instrumentation of the framework itself, as well as popular libraries including MongoDB (Mongoose), Redis (IORedis, which also captures BullMQ queue traffic), Socket.IO, and dozens of commonly used Node.js components. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database query bottlenecks without significant code modifications. The async-native design of Node.js works seamlessly with OpenTelemetry's context propagation, ensuring accurate parent-child span relationships across async operations. Whether you're implementing observability for the first time, migrating from commercial APM solutions like DataDog or New Relic, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Express.js OpenTelemetry instrumentation. You'll learn how to set up auto-instrumentation, configure custom spans for business logic, optimize performance, and deploy with Docker. :::tip TL;DR Create a `telemetry.ts` file that initializes `NodeSDK` with `getNodeAutoInstrumentations()` and import it as the very first line of your entry point - this single step auto-instruments Express routes, MongoDB (Mongoose), Redis, and HTTP clients. Set `OTEL_SERVICE_NAME` and `OTEL_EXPORTER_OTLP_ENDPOINT` to point at your Scout collector, and use `BatchSpanProcessor` in production to minimize request latency overhead. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry instrumentation for Express.js applications - Configure automatic request and response tracing for HTTP endpoints - Instrument database operations with Mongoose auto-instrumentation - Implement custom spans for business logic and external API calls - Collect and export HTTP metrics using custom middleware - Configure production-ready telemetry with BatchSpanProcessor - Export telemetry data to base14 Scout via OTLP - Deploy instrumented applications with Docker and Docker Compose - Troubleshoot common instrumentation issues - Optimize performance impact in production environments ### Who This Guide Is For This documentation is designed for: - **Express.js developers**: implementing observability and distributed tracing for the first time in Node.js applications - **DevOps engineers**: deploying Express.js applications with production monitoring requirements and container orchestration - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-source observability - **Backend developers**: debugging performance issues, N+1 queries, or async operation bottlenecks in Express.js services - **Platform teams**: standardizing observability across multiple Express.js microservices with consistent instrumentation patterns ### Prerequisites Before starting, ensure you have: - **Node.js 24.0.0 or later** installed (Krypton LTS recommended, active until April 2028) - **Express 5.0.0 or later** installed in your project (5.0.1+ recommended for latest security) - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment - **Basic understanding** of OpenTelemetry concepts (traces, spans, attributes) - Access to npm for package installation #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | ------------------------- | --------------- | ------------------- | -------------------------------------- | | **Node.js** | 24.0.0 | 24.x LTS | Krypton - Active until April 2028 | | **Express** | 5.0.0 | 5.0.1+ | Latest v5 with improved security | | **TypeScript** (optional) | 5.0.0 | 5.7.2+ | For type safety | | **OpenTelemetry SDK** | 0.200.0 | 0.208+ | Core SDK for traces and metrics | | **Mongoose** (optional) | 8.0.0 | 8.20.1+ | For MongoDB (**v9 not yet supported**) | | **IORedis** (optional) | 5.0.0 | 5.4.2+ | For Redis instrumentation | #### Supported Libraries OpenTelemetry automatically instruments these commonly used libraries: - **Web frameworks**: Express, HTTP/HTTPS - **Databases**: MongoDB (Mongoose), PostgreSQL, MySQL - **Caching**: Redis (IORedis), Memcached - **Job Queues**: BullMQ - **Real-time**: Socket.IO - **HTTP Clients**: axios, node-fetch, http/https ### Installation #### Core Packages Install the required OpenTelemetry packages for Express.js instrumentation: ```bash npm install @opentelemetry/api npm install @opentelemetry/sdk-node npm install @opentelemetry/auto-instrumentations-node npm install @opentelemetry/exporter-trace-otlp-http npm install @opentelemetry/exporter-metrics-otlp-http npm install @opentelemetry/resources npm install @opentelemetry/semantic-conventions ``` #### Optional Instrumentation Libraries Add these packages to instrument additional components: ```bash # MongoDB/Mongoose instrumentation npm install @opentelemetry/instrumentation-mongoose # Redis instrumentation npm install @opentelemetry/instrumentation-ioredis # Winston logging instrumentation npm install @opentelemetry/instrumentation-winston ``` #### Complete Requirements File For production applications, add all dependencies to `package.json`: ```json title="package.json" showLineNumbers { "dependencies": { "express": "^5.0.1", "mongoose": "^8.20.1", "ioredis": "^5.4.2", "@opentelemetry/api": "^1.9.0", "@opentelemetry/api-logs": "^0.208.0", "@opentelemetry/sdk-node": "^0.208.0", "@opentelemetry/sdk-logs": "^0.208.0", "@opentelemetry/auto-instrumentations-node": "^0.67.2", "@opentelemetry/exporter-trace-otlp-http": "^0.208.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.208.0", "@opentelemetry/exporter-logs-otlp-http": "^0.208.0", "@opentelemetry/instrumentation-express": "^0.57.0", "@opentelemetry/instrumentation-http": "^0.208.0", "@opentelemetry/instrumentation-mongodb": "^0.61.0", "@opentelemetry/instrumentation-mongoose": "^0.55.0", "@opentelemetry/instrumentation-ioredis": "^0.56.0", "@opentelemetry/instrumentation-winston": "^0.53.0", "@opentelemetry/resources": "^2.2.0", "@opentelemetry/semantic-conventions": "^1.29.0" } } ``` > For a complete list of dependencies including security, validation, and other > libraries, see the > [complete example](https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb/package.json). Then install all dependencies: ```bash npm install ``` ### Configuration Express.js OpenTelemetry instrumentation can be configured in multiple ways depending on your application architecture and deployment requirements. This section covers different setup approaches and advanced configuration options. #### Setup Approaches Choose the initialization method that best fits your application architecture: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ##### Separate Telemetry Module (Recommended) For better code organization and reusability, create a dedicated telemetry module. This approach is recommended for production applications. ```typescript title="src/telemetry.ts" showLineNumbers import { NodeSDK } from "@opentelemetry/sdk-node"; import { getNodeAutoInstrumentations } from "@opentelemetry/auto-instrumentations-node"; import { MongooseInstrumentation } from "@opentelemetry/instrumentation-mongoose"; import { WinstonInstrumentation } from "@opentelemetry/instrumentation-winston"; import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-http"; import { OTLPMetricExporter } from "@opentelemetry/exporter-metrics-otlp-http"; import { PeriodicExportingMetricReader } from "@opentelemetry/sdk-metrics"; import { resourceFromAttributes } from "@opentelemetry/resources"; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from "@opentelemetry/semantic-conventions"; export function setupTelemetry(): NodeSDK { const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || "express-app", [ATTR_SERVICE_VERSION]: process.env.APP_VERSION || "1.0.0", "deployment.environment": process.env.NODE_ENV || "development", "environment": process.env.NODE_ENV || "development", }); const endpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || "http://localhost:4318"; const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${endpoint}/v1/traces`, }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${endpoint}/v1/metrics`, }), exportIntervalMillis: 60000, }), instrumentations: [ getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-fs": { enabled: false, }, "@opentelemetry/instrumentation-express": { enabled: true, }, "@opentelemetry/instrumentation-http": { enabled: true, }, "@opentelemetry/instrumentation-ioredis": { enabled: true, }, }), new MongooseInstrumentation({ requireParentSpan: false, }), new WinstonInstrumentation(), ], }); sdk.start(); console.log("✅ OpenTelemetry SDK initialized"); process.on("SIGTERM", () => { sdk .shutdown() .then(() => console.log("OpenTelemetry SDK shut down successfully")) .catch((error) => console.error("Error shutting down OpenTelemetry SDK", error), ) .finally(() => process.exit(0)); }); return sdk; } ``` This configuration automatically captures: - HTTP request method, path, status code, and duration - Request and response headers (configurable) - Query parameters and path parameters - MongoDB queries (via Mongoose) - Redis operations (via IORedis) - Error and exception information ```mdx-code-block ``` ##### Instrumentation Entry Point Pattern Create a separate instrumentation file that Node.js loads before your main application using the `--import` flag. This ensures OpenTelemetry is initialized before any application code runs. ```typescript title="src/instrumentation.ts" showLineNumbers import { setupTelemetry } from "./telemetry.js"; setupTelemetry(); ``` Then use the Node.js `--import` flag to load instrumentation first: ```bash node --import ./dist/instrumentation.js dist/index.js ``` In `package.json` scripts: ```json title="package.json" showLineNumbers { "scripts": { "build": "tsc", "start": "node --import ./dist/instrumentation.js dist/index.js" } } ``` **Main application file**: ```typescript title="src/index.ts" showLineNumbers import express from "express"; import { connectDatabase } from "./database.js"; // Instrumentation is already loaded via --import flag const app = express(); app.use(express.json()); app.get("/", (req, res) => { res.json({ message: "Hello World" }); }); const PORT = process.env.APP_PORT || 3000; async function startServer() { await connectDatabase(); app.listen(PORT, () => { console.log(`Server running on port ${PORT}`); }); } startServer(); ``` ```mdx-code-block ``` ##### Environment Variables Configuration Configure OpenTelemetry entirely through environment variables for container-friendly deployments: ```bash title=".env" showLineNumbers # Application NODE_ENV=development APP_PORT=3000 APP_VERSION=1.0.0 # OpenTelemetry OTEL_SERVICE_NAME=express-app OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 # MongoDB MONGODB_URI=mongodb://mongo:27017/express-app # Redis REDIS_URL=redis://redis:6379 ``` Update your telemetry module to use environment variables: ```typescript title="src/telemetry.ts" showLineNumbers const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || "express-app", [ATTR_SERVICE_VERSION]: process.env.APP_VERSION || "1.0.0", "deployment.environment": process.env.NODE_ENV || "development", "environment": process.env.NODE_ENV || "development", }); const endpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || "http://localhost:4318"; ``` ```mdx-code-block ``` ##### Selective Instrumentation Control which components are instrumented by enabling or disabling specific auto-instrumentations: ```typescript title="src/telemetry.ts" showLineNumbers const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${endpoint}/v1/traces`, }), instrumentations: [ getNodeAutoInstrumentations({ // Disable filesystem instrumentation (reduces overhead) "@opentelemetry/instrumentation-fs": { enabled: false, }, // Enable Express with custom configuration "@opentelemetry/instrumentation-express": { enabled: true, ignoreLayersType: ["request_handler"], // Skip specific middleware }, // Enable HTTP with endpoint exclusions "@opentelemetry/instrumentation-http": { enabled: true, ignoreIncomingPaths: ["/health", "/metrics", "/favicon.ico"], }, // Enable MongoDB "@opentelemetry/instrumentation-mongodb": { enabled: true, }, // Enable Redis "@opentelemetry/instrumentation-ioredis": { enabled: true, }, }), ], }); ``` ```mdx-code-block ``` ##### Scout Collector Integration Configure direct integration with base14 Scout collector: ```typescript title="src/telemetry.ts" showLineNumbers const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${process.env.SCOUT_ENDPOINT}/v1/traces`, headers: { Authorization: `Bearer ${process.env.SCOUT_TOKEN}`, }, }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${process.env.SCOUT_ENDPOINT}/v1/metrics`, headers: { Authorization: `Bearer ${process.env.SCOUT_TOKEN}`, }, }), exportIntervalMillis: 60000, }), // ... rest of configuration }); ``` Environment variables for Scout: ```bash title=".env" showLineNumbers SCOUT_ENDPOINT=https://your-tenant.base14.io:4318 SCOUT_TOKEN=your_bearer_token ``` ```mdx-code-block ``` ### Traces Traces provide the complete picture of what happens when a request flows through your Express.js application. They capture the entire lifecycle from the incoming HTTP request, through your business logic, database queries, external API calls, and finally the response sent back to the client. #### Automatic Trace Collection Once instrumented, Express.js automatically captures detailed trace information for every request: **Captured Information:** - HTTP method, path, and status code - Request duration and timing breakdown - Request and response headers (configurable) - Query parameters and path parameters - MongoDB queries (operation, collection, execution time) - Redis operations (command, key, execution time) - WebSocket connections (via Socket.IO) - Error and exception stack traces - Distributed trace context propagation (W3C Trace Context) **Trace Hierarchy:** ```text HTTP Request Span (root) ├── Express Router Span │ ├── Auth Middleware Span │ ├── Route Handler Span │ │ ├── MongoDB Query Span (Mongoose) │ │ ├── Redis GET Span (IORedis) │ │ ├── BullMQ Job Enqueue Span │ │ └── Custom Business Logic Span │ └── Response Middleware Span └── HTTP Response Span ``` #### Key Tracing Features - **Automatic HTTP tracking**: Every endpoint is automatically traced with no code changes - **Error capturing**: Exceptions are automatically recorded with full stack traces - **Context propagation**: Distributed traces work across microservices using W3C Trace Context headers - **Custom attributes**: Add business-specific metadata to spans (covered in Custom Instrumentation section) - **Async support**: Full support for async/await patterns with correct context preservation > View traces in your base14 Scout dashboard to analyze request flows and > identify bottlenecks. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics OpenTelemetry metrics capture runtime measurements of your Express.js application including HTTP request counts, latencies, response status codes, and custom business metrics. Unlike traces that show individual request flows, metrics aggregate data over time for monitoring trends and alerting. #### Custom Metrics Create custom metrics to track business operations: ```typescript title="src/utils/metrics.ts" showLineNumbers import { metrics } from "@opentelemetry/api"; const meter = metrics.getMeter("express-app", "1.0.0"); export const articleMetrics = { created: meter.createCounter("articles.created.total", { description: "Total number of articles created", unit: "1", }), published: meter.createCounter("articles.published.total", { description: "Total number of articles published", unit: "1", }), publishDuration: meter.createHistogram("article.publish.duration", { description: "Duration of article publish job processing", unit: "ms", }), contentSize: meter.createHistogram("article.content.size", { description: "Size of article content in characters", unit: "characters", }), favorited: meter.createCounter("articles.favorited.total", { description: "Total number of article favorites", unit: "1", }), }; export const authMetrics = { loginSuccess: meter.createCounter("users.login.success.total", { description: "Total number of successful login attempts", unit: "1", }), loginFailed: meter.createCounter("users.login.failed.total", { description: "Total number of failed login attempts", unit: "1", }), }; export const jobMetrics = { enqueued: meter.createCounter("jobs.enqueued.total", { description: "Total number of jobs enqueued", unit: "1", }), completed: meter.createCounter("jobs.completed.total", { description: "Total number of jobs completed successfully", unit: "1", }), processingTime: meter.createHistogram("jobs.processing.duration", { description: "Duration of job processing", unit: "ms", }), }; ``` **Usage in controllers**: ```typescript title="src/controllers/article.controller.ts" showLineNumbers import { articleMetrics } from "../utils/metrics.js"; export async function createArticle(req, res) { const article = await Article.create(req.body); articleMetrics.created.add(1); articleMetrics.contentSize.record(article.content.length); res.status(201).json(article); } ``` #### Available Metrics Once configured, these metrics are automatically collected: | Metric Name | Type | Description | Attributes | | --------------------------- | --------- | ------------------------ | ---------- | | `articles.created.total` | Counter | Total articles created | - | | `articles.published.total` | Counter | Total articles published | - | | `articles.favorited.total` | Counter | Total favorites | - | | `users.login.success.total` | Counter | Successful logins | - | | `users.login.failed.total` | Counter | Failed login attempts | - | | `jobs.enqueued.total` | Counter | Jobs enqueued | job.type | | `jobs.processing.duration` | Histogram | Job processing time | job.type | | `article.publish.duration` | Histogram | Publish duration | - | | `article.content.size` | Histogram | Content size | - | > View these metrics in base14 Scout to create dashboards, set up alerts, and > monitor application health. ### Production Configuration Production environments require careful configuration of OpenTelemetry to balance observability needs with performance and reliability. This section covers production-ready patterns. #### BatchSpanProcessor Configuration Configure BatchSpanProcessor parameters for optimal performance: ```typescript title="src/telemetry.ts" showLineNumbers import { BatchSpanProcessor } from "@opentelemetry/sdk-trace-node"; import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-http"; const batchProcessor = new BatchSpanProcessor( new OTLPTraceExporter({ url: "http://otel-collector:4318/v1/traces", }), { maxQueueSize: 2048, // Maximum spans in queue scheduledDelayMillis: 5000, // Export every 5 seconds maxExportBatchSize: 512, // Maximum spans per export exportTimeoutMillis: 30000, // Timeout for export operation }, ); ``` #### Resource Attributes for Production Add comprehensive resource attributes to identify your service: ```typescript title="src/telemetry.ts" showLineNumbers import os from "os"; import { resourceFromAttributes } from "@opentelemetry/resources"; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from "@opentelemetry/semantic-conventions"; const resource = resourceFromAttributes({ // Service identification [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || "express-app", [ATTR_SERVICE_VERSION]: process.env.APP_VERSION || "1.0.0", // Deployment information "deployment.environment": process.env.NODE_ENV || "development", "environment": process.env.NODE_ENV || "development", "deployment.region": process.env.AWS_REGION || "us-east-1", // Instance identification "service.instance.id": os.hostname(), "host.name": os.hostname(), "host.type": "container", // Container information (if applicable) "container.id": process.env.HOSTNAME || "", "container.name": process.env.CONTAINER_NAME || "", // Kubernetes information (if applicable) "k8s.namespace.name": process.env.K8S_NAMESPACE || "", "k8s.pod.name": process.env.K8S_POD_NAME || "", }); ``` #### Environment-Based Configuration Use environment variables to configure telemetry without code changes: ```typescript title="src/config.ts" showLineNumbers export const config = { app: { env: process.env.NODE_ENV || "development", port: parseInt(process.env.APP_PORT || "3000", 10), version: process.env.APP_VERSION || "1.0.0", }, otel: { serviceName: process.env.OTEL_SERVICE_NAME || "express-app", endpoint: process.env.OTEL_EXPORTER_OTLP_ENDPOINT || "http://localhost:4318", }, mongodb: { uri: process.env.MONGODB_URI || "mongodb://localhost:27017/express-app", }, redis: { url: process.env.REDIS_URL || "redis://localhost:6379", }, }; ``` #### Docker Compose Configuration Example `compose.yml` for production-like deployment: ```yaml title="compose.yml" showLineNumbers services: app: build: . ports: - "3000:3000" environment: NODE_ENV: development APP_VERSION: "1.0.0" OTEL_SERVICE_NAME: express-app OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 MONGODB_URI: mongodb://mongo:27017/express-app REDIS_URL: redis://redis:6379 depends_on: - mongo - redis - otel-collector mongo: image: mongo:8.0-noble ports: - "27017:27017" volumes: - mongo_data:/data/db redis: image: redis:8-alpine ports: - "6379:6379" otel-collector: image: otel/opentelemetry-collector-contrib:0.115.1 command: ["--config=/etc/otelcol-contrib/config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otelcol-contrib/config.yaml ports: - "4317:4317" # OTLP gRPC - "4318:4318" # OTLP HTTP - "55679:55679" # zpages for debugging volumes: mongo_data: ``` > For a production-ready compose configuration with health checks, networks, and > env_file support, see the > [complete example](https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb/compose.yml). #### Environment Variables Template Create a `.env.example` file for your team: ```bash title=".env.example" showLineNumbers # Application NODE_ENV=development APP_PORT=3000 APP_VERSION=1.0.0 # OpenTelemetry OTEL_SERVICE_NAME=express-mongodb-app OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.version=1.0.0 # MongoDB MONGODB_URI=mongodb://mongo:27017/express-app # Redis (for BullMQ job queue) REDIS_URL=redis://redis:6379 # JWT Authentication JWT_SECRET=your-secret-key-change-in-development JWT_EXPIRES_IN=7d # Security CORS_ORIGIN=* RATE_LIMIT_WINDOW_MS=900000 RATE_LIMIT_MAX=100 # base14 Scout Configuration (Required - set these via environment or .env.local) SCOUT_ENDPOINT=https://your-tenant.base14.io:4318 SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token ``` #### Dockerfile with OpenTelemetry Build a production-ready Docker image: ```dockerfile title="Dockerfile" showLineNumbers FROM node:24-alpine AS builder WORKDIR /app RUN apk add --no-cache python3 make g++ COPY package*.json tsconfig.json ./ RUN npm install COPY src ./src RUN npm run build RUN npm prune --production # Runtime stage FROM node:24-alpine WORKDIR /app RUN apk add --no-cache curl RUN addgroup -S appuser && \ adduser -D -S -G appuser appuser COPY --from=builder --chown=appuser:appuser /app/dist ./dist COPY --from=builder --chown=appuser:appuser /app/node_modules ./node_modules COPY --chown=appuser:appuser package*.json ./ USER appuser EXPOSE 3000 HEALTHCHECK --interval=5m --timeout=5s --start-period=10s --retries=3 \ CMD curl -f http://localhost:3000/api/health || exit 1 CMD ["node", "--import", "./dist/instrumentation.js", "dist/index.js"] ``` #### Graceful Shutdown Implement graceful shutdown to flush pending spans: ```typescript title="src/index.ts" showLineNumbers import http from "http"; import { setupTelemetry } from "./telemetry.js"; import { createApp } from "./app.js"; import { connectDatabase, disconnectDatabase } from "./database.js"; // Initialize telemetry FIRST const sdk = setupTelemetry(); const app = createApp(); const server = http.createServer(app); async function gracefulShutdown(signal: string) { console.log(`${signal} received, shutting down gracefully...`); // 1. Stop accepting new connections server.close(() => { console.log("HTTP server closed"); }); // 2. Shutdown OpenTelemetry SDK (flush pending spans) await sdk.shutdown(); console.log("OpenTelemetry SDK shut down"); // 3. Disconnect from database await disconnectDatabase(); console.log("Database disconnected"); process.exit(0); } process.on("SIGTERM", () => gracefulShutdown("SIGTERM")); process.on("SIGINT", () => gracefulShutdown("SIGINT")); const PORT = process.env.APP_PORT || 3000; server.listen(PORT, () => { console.log(`Server running on port ${PORT}`); }); ``` ### Framework-Specific Features Express.js integration with OpenTelemetry automatically instruments several framework components and commonly used libraries. This section covers automatic instrumentation for databases, caching, background jobs, and WebSockets. #### MongoDB/Mongoose Database Instrumentation OpenTelemetry automatically instruments Mongoose database queries, providing detailed visibility into database operations. **Installation:** ```bash npm install @opentelemetry/instrumentation-mongoose ``` **Automatic Instrumentation:** ```typescript title="src/telemetry.ts" showLineNumbers import { MongooseInstrumentation } from "@opentelemetry/instrumentation-mongoose"; const sdk = new NodeSDK({ instrumentations: [ new MongooseInstrumentation({ requireParentSpan: false, // Create spans even without parent }), ], }); ``` This automatically captures: - MongoDB operation (find, insertOne, updateOne, deleteOne) - Collection name - Query execution time - Database connection details - N+1 query detection (via span hierarchy) **Example traced query:** ```text HTTP POST /api/v1/articles └── article.create (custom span) └── mongodb.insertOne (auto-instrumented) Collection: articles Duration: 15ms ``` > **Note**: Mongoose 9.x is not yet supported by the instrumentation package. > Use Mongoose 8.x (8.20.1+ recommended). #### Redis/IORedis Instrumentation Automatically trace Redis operations: ```typescript title="src/telemetry.ts" showLineNumbers const sdk = new NodeSDK({ instrumentations: [ getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-ioredis": { enabled: true, }, }), ], }); ``` This captures: - Redis command (GET, SET, HGET, LPUSH, etc.) - Key names - Command execution time - Connection details #### Background Jobs (BullMQ) with Trace Propagation Trace background jobs with context propagation: ```typescript title="src/jobs/publishArticleJob.ts" showLineNumbers import { Queue, Worker, Job } from "bullmq"; import { trace } from "@opentelemetry/api"; // Create job queue const publishQueue = new Queue("article-publish", { connection: { url: process.env.REDIS_URL }, }); // Enqueue job with trace context export async function enqueuePublishJob(articleId: string) { await publishQueue.add("publish-article", { articleId, // Trace context is automatically propagated by IORedis instrumentation }); } // Job worker with tracing const worker = new Worker("article-publish", async (job: Job) => { const tracer = trace.getTracer("article-job"); const span = tracer.startSpan("article.publish"); try { span.setAttributes({ "article.id": job.data.articleId, "job.id": job.id, }); // Publish article logic await Article.findByIdAndUpdate(job.data.articleId, { published: true, publishedAt: new Date(), }); span.addEvent("article_published"); return { success: true }; } catch (error) { span.recordException(error as Error); throw error; } finally { span.end(); } }); ``` #### WebSocket (Socket.IO) Tracing Trace WebSocket connections and events: ```typescript title="src/socket.ts" showLineNumbers import { Server } from "socket.io"; import { trace } from "@opentelemetry/api"; import http from "http"; const tracer = trace.getTracer("socket-io"); export function setupWebSocket(server: http.Server) { const io = new Server(server, { cors: { origin: "*" }, }); io.on("connection", (socket) => { const span = tracer.startSpan("websocket.connection"); span.setAttributes({ "socket.id": socket.id, "socket.transport": socket.conn.transport.name, }); span.addEvent("client_connected", { "socket.id": socket.id, }); socket.on("subscribe:articles", () => { socket.join("articles"); span.addEvent("subscribed_to_articles"); socket.emit("subscribed", { channel: "articles" }); }); socket.on("disconnect", () => { span.addEvent("client_disconnected"); span.end(); }); }); return io; } ``` ### Custom Instrumentation While auto-instrumentation captures HTTP requests and database queries, custom instrumentation lets you trace business logic, add contextual attributes, and instrument specific operations. #### Creating Custom Spans with Utility Function Create a reusable utility for consistent span management: ```typescript title="src/utils/tracing.ts" showLineNumbers import { trace, SpanStatusCode, context as otelContext, type Span, } from "@opentelemetry/api"; type AsyncSpanFn = (span: Span) => Promise; export function withSpan( tracerName: string, spanName: string, fn: AsyncSpanFn, ): Promise { const tracer = trace.getTracer(tracerName); const span = tracer.startSpan(spanName); return otelContext.with( trace.setSpan(otelContext.active(), span), async () => { try { const result = await fn(span); span.setStatus({ code: SpanStatusCode.OK }); return result; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } }, ); } ``` **Usage in controller**: ```typescript title="src/controllers/article.controller.ts" showLineNumbers import { withSpan } from "../utils/tracing.js"; export async function createArticle(req, res) { return withSpan("article-controller", "article.create", async (span) => { const article = await Article.create(req.body); span.setAttributes({ "article.id": article._id.toString(), "article.title": article.title, "article.published": article.published, }); span.addEvent("article_created", { "article.id": article._id.toString(), }); res.status(201).json(article); }); } ``` #### Adding Custom Attributes to Active Span Enrich the automatically created span with custom data: ```typescript title="src/middleware/auth.middleware.ts" showLineNumbers import { trace, SpanStatusCode } from "@opentelemetry/api"; export async function authenticate(req, res, next) { const currentSpan = trace.getActiveSpan(); try { const authHeader = req.headers.authorization; if (!authHeader?.startsWith("Bearer ")) { if (currentSpan) { currentSpan.addEvent("auth_failed", { reason: "missing_token" }); } return res.status(401).json({ error: "Authentication required" }); } const token = authHeader.substring(7); const payload = verifyToken(token); const user = await User.findById(payload.userId); if (!user) { if (currentSpan) { currentSpan.addEvent("auth_failed", { reason: "user_not_found" }); } return res.status(401).json({ error: "User not found" }); } req.user = user; // Add user context to active span if (currentSpan) { currentSpan.setAttributes({ "user.id": user._id.toString(), "user.email": user.email, "user.role": user.role, }); currentSpan.addEvent("auth_success"); } next(); } catch (error) { if (currentSpan) { currentSpan.recordException(error as Error); currentSpan.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); } next(error); } } ``` #### Error Handling and Status Record errors and set span status appropriately: ```typescript title="src/controllers/article.controller.ts" showLineNumbers import { trace, SpanStatusCode } from "@opentelemetry/api"; export async function getArticle(req, res) { const tracer = trace.getTracer("article-controller"); const span = tracer.startSpan("article.get"); try { const article = await Article.findById(req.params.id); if (!article) { span.setAttributes({ "article.id": req.params.id, "article.found": false, }); span.setStatus({ code: SpanStatusCode.ERROR, message: "Article not found", }); span.end(); return res.status(404).json({ error: "Article not found" }); } span.setAttributes({ "article.id": article._id.toString(), "article.title": article.title, "article.found": true, }); span.setStatus({ code: SpanStatusCode.OK }); res.json(article); } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } } ``` #### Span Events for Business Operations Add timestamped events to track important operations: ```typescript title="src/controllers/favorite.controller.ts" showLineNumbers import { withSpan } from "../utils/tracing.js"; export async function favoriteArticle(req, res) { return withSpan("favorite-controller", "article.favorite", async (span) => { const article = await Article.findById(req.params.id); span.setAttributes({ "article.id": article._id.toString(), "user.id": req.user._id.toString(), }); // Add event for favorite action span.addEvent("article_favorited", { "article.id": article._id.toString(), "article.title": article.title, "user.id": req.user._id.toString(), timestamp: new Date().toISOString(), }); // Update favorites count article.favorites.push(req.user._id); await article.save(); span.setAttributes({ "article.favorites_count": article.favorites.length, }); res.json(article); }); } ``` #### Semantic Conventions Use OpenTelemetry semantic conventions for consistent attribute naming: ```typescript title="src/middleware/request-logger.middleware.ts" showLineNumbers import { trace } from "@opentelemetry/api"; import { ATTR_HTTP_REQUEST_METHOD, ATTR_HTTP_ROUTE, ATTR_HTTP_RESPONSE_STATUS_CODE, ATTR_USER_AGENT_ORIGINAL, } from "@opentelemetry/semantic-conventions"; export function requestLogger(req, res, next) { const currentSpan = trace.getActiveSpan(); if (currentSpan && currentSpan.isRecording()) { // Use semantic convention constants currentSpan.setAttributes({ [ATTR_HTTP_REQUEST_METHOD]: req.method, [ATTR_HTTP_ROUTE]: req.route?.path || req.path, [ATTR_USER_AGENT_ORIGINAL]: req.get("user-agent") || "", "http.request.body.size": JSON.stringify(req.body).length, }); res.on("finish", () => { currentSpan.setAttributes({ [ATTR_HTTP_RESPONSE_STATUS_CODE]: res.statusCode, "http.response.body.size": res.get("content-length") || 0, }); }); } next(); } ``` ### Running Your Application #### Development Mode Run with console output for local development: ```bash # Set environment to development export NODE_ENV=development export OTEL_SERVICE_NAME=express-app # Run with ts-node (TypeScript) npm run dev # or ts-node src/index.ts ``` **package.json scripts**: ```json title="package.json" showLineNumbers { "scripts": { "dev": "ts-node src/index.ts", "build": "tsc", "start": "node --import ./dist/instrumentation.js dist/index.js" } } ``` #### Production Mode Run with OTLP exporter pointing to Scout Collector: ```bash # Build TypeScript npm run build # Set production environment variables export NODE_ENV=development export OTEL_SERVICE_NAME=express-app export OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 export APP_VERSION=1.0.0 # Run with instrumentation npm start # Runs: node --import ./dist/instrumentation.js dist/index.js ``` #### Docker Deployment Build and run with Docker: ```bash # Build image docker build -t express-app:latest . # Run container docker run -d \ --name express-app \ -p 3000:3000 \ -e NODE_ENV=development \ -e OTEL_SERVICE_NAME=express-app \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 \ -e MONGODB_URI=mongodb://mongo:27017/express-app \ -e REDIS_URL=redis://redis:6379 \ express-app:latest ``` Or use Docker Compose: ```bash # Start all services (app, MongoDB, Redis, OTel Collector) docker compose up --build # View logs docker compose logs -f app # Stop services docker compose down ``` ### Troubleshooting #### Verifying Instrumentation Create a test endpoint to verify OpenTelemetry is working: ```typescript title="src/routes/health.ts" showLineNumbers import { trace } from "@opentelemetry/api"; router.get("/health", (req, res) => { const currentSpan = trace.getActiveSpan(); if (currentSpan && currentSpan.isRecording()) { const spanContext = currentSpan.spanContext(); return res.json({ status: "healthy", tracing: "enabled", trace_id: spanContext.traceId, span_id: spanContext.spanId, }); } return res.json({ status: "healthy", tracing: "disabled", }); }); ``` #### Common Issues ##### Issue: No traces appearing in Scout **Solutions:** 1. **Verify OTLP endpoint is accessible**: ```bash curl http://otel-collector:4318/v1/traces # Should return 405 Method Not Allowed (endpoint exists) ``` 2. **Check telemetry initialization happens BEFORE app creation**: ```typescript // ❌ WRONG ORDER import { createApp } from "./app.js"; import { setupTelemetry } from "./telemetry.js"; setupTelemetry(); // Too late! // ✅ CORRECT ORDER import { setupTelemetry } from "./telemetry.js"; setupTelemetry(); // First! import { createApp } from "./app.js"; ``` 3. **Enable console exporter to verify spans are being created**: ```typescript import { ConsoleSpanExporter } from "@opentelemetry/sdk-trace-base"; import { BatchSpanProcessor } from "@opentelemetry/sdk-trace-node"; const sdk = new NodeSDK({ spanProcessors: [new BatchSpanProcessor(new ConsoleSpanExporter())], }); ``` ##### Issue: Redis spans missing after upgrading ioredis `@opentelemetry/instrumentation-ioredis` patches ioredis versions `>=2.0.0 <6` only. On ioredis 6.x the module is not patched, so Redis client spans stop appearing while the application continues to work. Stay on ioredis 5.x until the instrumentation supports ioredis 6. ##### Issue: Database queries not traced **Solutions:** 1. **Ensure Mongoose instrumentation is registered BEFORE creating connection**: ```typescript // ✅ CORRECT ORDER const sdk = new NodeSDK({ instrumentations: [new MongooseInstrumentation()], }); sdk.start(); await mongoose.connect(MONGODB_URI); ``` 2. **Check Mongoose version compatibility**: ```bash npm list mongoose # Must be 8.x (9.x not yet supported) ``` ##### Issue: High memory usage or performance degradation **Solutions:** 1. **Configure BatchSpanProcessor with appropriate limits**: ```typescript const batchProcessor = new BatchSpanProcessor(exporter, { maxQueueSize: 2048, // Reduce if memory is constrained scheduledDelayMillis: 5000, // Increase to batch more spans maxExportBatchSize: 512, }); ``` 2. **Exclude high-volume endpoints**: ```typescript instrumentations: [ getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-http": { ignoreIncomingPaths: ["/health", "/metrics", "/favicon.ico"], }, }), ]; ``` ##### Issue: Background jobs losing trace context **Solutions:** 1. **Verify IORedis instrumentation is enabled** (BullMQ uses Redis): ```typescript instrumentations: [ getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-ioredis": { enabled: true, }, }), ]; ``` 2. **Use manual span creation in job workers**: ```typescript const worker = new Worker("queue-name", async (job) => { const tracer = trace.getTracer("job-worker"); const span = tracer.startSpan("process-job"); try { // Job logic with proper tracing } finally { span.end(); } }); ``` ### Security Considerations #### Sensitive Data in Spans Avoid capturing sensitive information in span attributes: **Bad Example (DON'T DO THIS)**: ```typescript // ❌ NEVER capture sensitive data span.setAttribute("user.password", password); span.setAttribute("credit_card.number", cardNumber); span.setAttribute("user.ssn", ssn); span.setAttribute("api_key", apiKey); span.setAttribute("auth_token", token); ``` **Good Example (DO THIS INSTEAD)**: ```typescript // ✅ GOOD - Reference IDs and metadata only span.setAttribute("user.id", user.id); span.setAttribute("payment.method", "credit_card"); span.setAttribute("payment.last4", cardNumber.slice(-4)); span.setAttribute("user.email_domain", email.split("@")[1]); span.setAttribute("api_key.prefix", apiKey.substring(0, 8)); ``` #### HTTP Header Filtering Filter sensitive headers from traces: ```typescript title="src/middleware/sanitize-headers.ts" showLineNumbers import { trace } from "@opentelemetry/api"; export function sanitizeHeaders(req) { const currentSpan = trace.getActiveSpan(); if (currentSpan) { // ✅ Safe headers to capture const safeHeaders = { "content-type": req.get("content-type"), "user-agent": req.get("user-agent"), accept: req.get("accept"), "x-request-id": req.get("x-request-id"), }; currentSpan.setAttributes({ "http.request.headers": JSON.stringify(safeHeaders), }); // ❌ NEVER capture these headers: // - authorization // - cookie // - x-api-key // - proxy-authorization } } ``` #### Query Parameter Sanitization Sanitize query parameters before adding to spans: ```typescript title="src/utils/sanitize.ts" showLineNumbers export function sanitizeQueryParams( params: Record, ): Record { const sensitiveKeys = ["password", "token", "api_key", "secret", "ssn"]; const sanitized: Record = {}; for (const [key, value] of Object.entries(params)) { if (sensitiveKeys.some((sk) => key.toLowerCase().includes(sk))) { sanitized[key] = "[REDACTED]"; } else { sanitized[key] = value; } } return sanitized; } // Usage const currentSpan = trace.getActiveSpan(); if (currentSpan) { currentSpan.setAttribute( "http.query", JSON.stringify(sanitizeQueryParams(req.query)), ); } ``` #### Environment Variable Security Never commit sensitive values to version control: ```bash title=".env" showLineNumbers # ❌ BAD - Don't commit .env files with real secrets SECRET_KEY=actual-secret-key-here MONGODB_URI=mongodb://admin:password123@mongo:27017/db JWT_SECRET=my-super-secret-jwt-key ``` In production, use environment-specific secrets management: - AWS Secrets Manager - HashiCorp Vault - Kubernetes Secrets - Azure Key Vault - Google Cloud Secret Manager ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead when properly configured: | Metric | Impact | Notes | | ----------- | -------------------- | ------------------------------------------------- | | **Latency** | +0.5-2ms per request | Mostly from span creation and context propagation | | **CPU** | +2-5% | Primarily during span export operations | | **Memory** | +10-50MB | BatchSpanProcessor queue and SDK overhead | | **Network** | +1-5KB per trace | OTLP HTTP with gzip compression | **Impact Factors**: - Number of spans per request - Span attribute size and count - Export frequency (BatchSpanProcessor schedule) - Number of active requests - Enabled instrumentations #### Optimization Strategies ##### 1. Use BatchSpanProcessor in Production Always use `BatchSpanProcessor` (never `SimpleSpanProcessor`) for production: ```typescript title="src/telemetry.ts" showLineNumbers import { BatchSpanProcessor } from "@opentelemetry/sdk-trace-node"; // ✅ GOOD - Batches spans for efficient export const batchProcessor = new BatchSpanProcessor(exporter, { maxQueueSize: 2048, scheduledDelayMillis: 5000, maxExportBatchSize: 512, }); // ❌ BAD - Exports each span immediately (only for debugging) // const simpleProcessor = new SimpleSpanProcessor(exporter); ``` ##### 2. Skip Non-Critical Endpoints Exclude health checks and metrics endpoints: ```typescript title="src/telemetry.ts" showLineNumbers const sdk = new NodeSDK({ instrumentations: [ getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-http": { ignoreIncomingPaths: [ "/health", "/metrics", "/favicon.ico", "/robots.txt", ], }, }), ], }); ``` ##### 3. Limit Attribute Sizes Prevent large attributes from consuming memory: ```typescript title="src/utils/tracing.ts" showLineNumbers export function addSafeAttribute( span: Span, key: string, value: string | number | boolean, maxLength: number = 256, ) { if (typeof value === "string" && value.length > maxLength) { value = value.substring(0, maxLength) + "... (truncated)"; } span.setAttribute(key, value); } // Usage addSafeAttribute(span, "article.content", article.content, 500); addSafeAttribute(span, "http.request.body", JSON.stringify(req.body), 1024); ``` ##### 4. Optimize Metric Export Intervals Adjust metric export frequency for production: ```typescript title="src/telemetry.ts" showLineNumbers const sdk = new NodeSDK({ metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: "http://otel-collector:4318/v1/metrics", }), // ✅ Production: Export every 60 seconds (reduces network overhead) exportIntervalMillis: 60000, }), }); ``` ### FAQ #### Does Express.js OpenTelemetry instrumentation work with async/await? Yes, OpenTelemetry fully supports Express.js async/await patterns. The NodeSDK automatically preserves context across async operations, ensuring parent-child span relationships are maintained correctly. All automatically instrumented libraries (Mongoose, IORedis, etc.) work seamlessly with async/await. #### What is the performance impact of Express.js instrumentation? Typical overhead is 0.5-2ms added latency per request, 2-5% CPU increase, and 10-50MB additional memory usage. This impact is minimal and acceptable for most production applications. Using BatchSpanProcessor and excluding high-volume endpoints further reduces overhead. #### Which Node.js and Express versions does OpenTelemetry support? - **Node.js**: 24.0.0+ (Krypton LTS recommended, active until April 2028) - **Express**: 5.0.0+ (5.0.1+ recommended for latest security improvements) - **OpenTelemetry SDK**: 0.200+ (always use latest stable version for bug fixes) - Full TypeScript support with type definitions included #### How do I instrument MongoDB and Mongoose queries in Express.js? Install `@opentelemetry/instrumentation-mongoose` and register it in your NodeSDK instrumentations array before connecting to MongoDB. All Mongoose queries are automatically traced with operation name, collection, query execution time, and database details. N+1 queries are visible in the span hierarchy. ```typescript import { MongooseInstrumentation } from "@opentelemetry/instrumentation-mongoose"; const sdk = new NodeSDK({ instrumentations: [new MongooseInstrumentation()], }); sdk.start(); await mongoose.connect(MONGODB_URI); // Connect AFTER SDK start ``` **Note**: Mongoose 9.x is not yet supported. Use Mongoose 8.x (8.20.1+ recommended). #### How does distributed tracing work across Express.js microservices? OpenTelemetry uses W3C Trace Context headers (`traceparent`, `tracestate`) to propagate trace context between services. Express HTTP instrumentation automatically extracts these headers from incoming requests and injects them into outgoing HTTP calls, enabling end-to-end distributed traces across your entire microservices architecture. #### What's the difference between traces and metrics in Express.js? - **Traces**: Show individual request flows with detailed timing and call hierarchy (e.g., "this specific API call took 150ms with 3 database queries") - **Metrics**: Aggregate measurements over time for monitoring trends (e.g., "average response time is 120ms, 99th percentile is 500ms") Use both together: traces for debugging specific issues, metrics for monitoring overall health and setting up alerts. #### How do I debug N+1 database query problems in Express.js? View the span hierarchy in base14 Scout TraceX. N+1 queries appear as many sequential database spans under a single parent span. For example, a list endpoint that loads 10 articles with separate author queries will show 1 articles query span followed by 10 author query spans, making the N+1 pattern obvious. #### Can I use OpenTelemetry with TypeScript in Express.js? Yes, OpenTelemetry has full first-class TypeScript support with comprehensive type definitions. All examples in this guide use TypeScript syntax. The instrumentation works identically with JavaScript - just omit type annotations. #### How do I instrument background jobs with BullMQ? Create manual spans in BullMQ workers to trace job execution. Trace context is automatically propagated through Redis (via IORedis instrumentation). Ensure IORedis instrumentation is enabled in your NodeSDK configuration. #### Does instrumentation affect WebSocket connections (Socket.IO)? Yes, Socket.IO connections can be traced by creating manual spans for connection events. Each connection creates a span tracking the connection lifetime, subscriptions, and events. See the Framework-Specific Features section for full Socket.IO tracing examples. #### How do I handle multi-tenancy in Express.js traces? Add tenant identification to span attributes using the active span or request middleware: ```typescript const currentSpan = trace.getActiveSpan(); if (currentSpan) { currentSpan.setAttributes({ "tenant.id": req.tenant.id, "tenant.name": req.tenant.name, }); } ``` Then filter and query by tenant attributes in base14 Scout dashboard. ### What's Next? #### Advanced Topics - [OpenTelemetry Collector Configuration](../../collector-setup/otel-collector-config.md) \- Advanced collector features, processors, and exporters #### base14 Scout Platform Features - [Creating Alerts with LogX](../../../guides/creating-alerts-with-logx.md) - Set up alerts based on traces and metrics - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards for Express.js applications #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment with collector - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production Kubernetes deployment - [Scout Exporter Configuration](../../collector-setup/scout-exporter.md) - Configure authentication and endpoints ### Complete Example A complete production-ready example with Express 5.x, TypeScript, MongoDB (Mongoose), Redis, BullMQ, Socket.IO, and comprehensive OpenTelemetry instrumentation is available at: **GitHub**: [base-14/examples/nodejs/express-typescript-mongodb](https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb) **Features**: - Full auto-instrumentation with NodeSDK - Custom spans, metrics, and events - Background job tracing with BullMQ - WebSocket tracing with Socket.IO - Production Docker deployment - 74.31% test coverage with Vitest - Security: Helmet, CORS, rate limiting, JWT, XSS protection - Graceful shutdown handling #### Complete package.json ```json title="package.json" showLineNumbers { "name": "express-typescript-mongodb-otel", "version": "1.0.0", "type": "module", "description": "Express.js + TypeScript + MongoDB + OpenTelemetry example", "scripts": { "build": "tsc", "start": "node --import ./dist/instrumentation.js dist/index.js", "dev": "ts-node src/index.ts", "test": "vitest run", "test:coverage": "vitest run --coverage" }, "engines": { "node": ">=24.0.0" }, "dependencies": { "@opentelemetry/api": "^1.9.0", "@opentelemetry/api-logs": "^0.208.0", "@opentelemetry/sdk-node": "^0.208.0", "@opentelemetry/sdk-logs": "^0.208.0", "@opentelemetry/auto-instrumentations-node": "^0.67.2", "@opentelemetry/exporter-trace-otlp-http": "^0.208.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.208.0", "@opentelemetry/exporter-logs-otlp-http": "^0.208.0", "@opentelemetry/instrumentation-express": "^0.57.0", "@opentelemetry/instrumentation-http": "^0.208.0", "@opentelemetry/instrumentation-mongodb": "^0.61.0", "@opentelemetry/instrumentation-mongoose": "^0.55.0", "@opentelemetry/instrumentation-ioredis": "^0.56.0", "@opentelemetry/instrumentation-winston": "^0.53.0", "@opentelemetry/resources": "^2.2.0", "@opentelemetry/semantic-conventions": "^1.29.0", "express": "^5.0.1", "mongoose": "^8.20.1", "ioredis": "^5.4.2" }, "devDependencies": { "@types/express": "^5.0.0", "@types/node": "^24.10.1", "typescript": "^5.7.2", "vitest": "^4.0.15", "@vitest/coverage-v8": "^4.0.15" } } ``` > For additional dependencies like BullMQ, Socket.IO, security libraries, and > more, see the > [complete example](https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb). #### Additional Configuration Files For complete production-ready configuration files, see the example repository: - [src/telemetry.ts][example-telemetry] - Complete telemetry setup with logs, metrics, and traces - [.env.example][example-env] - All environment variables with Scout configuration - [Dockerfile][example-dockerfile] - Multi-stage production build - [compose.yml][example-compose] - Full stack with health checks and networks [example-telemetry]: https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb/src/telemetry.ts [example-env]: https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb/.env.example [example-dockerfile]: https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb/Dockerfile [example-compose]: https://github.com/base-14/examples/tree/main/nodejs/express-typescript-mongodb/compose.yml With instrumentation configured, you can [track Express.js endpoints in Scout APM](https://base14.io/scout/apm) — monitor route latency, middleware performance, and downstream service calls in real time. ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [Express.js Documentation](https://expressjs.com/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) - [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Related Guides - [Angular Instrumentation](./angular.md) - browser front-end that propagates trace context into an Express API - [NestJS Instrumentation](./nestjs.md) - Structured framework that runs on top of Express - [Next.js Instrumentation](./nextjs-scout.md) - Full-stack React framework on Node.js - [Fastify Instrumentation](./fastify.md) - High-performance Node.js web framework - [Hono Instrumentation](./hono.md) - Lightweight, edge-first Node.js framework --- ## FastAPI OpenTelemetry Instrumentation - Traces, Metrics & Logs Setup Implement OpenTelemetry instrumentation for FastAPI applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your FastAPI application to collect traces and metrics from HTTP requests, database queries, and external API calls using the OpenTelemetry Python SDK with minimal code changes. FastAPI is a modern, async-first Python framework in the same ASGI space as [Litestar](./litestar.md). [Flask](./flask.md) and [Django](./django.md) are the established synchronous options. FastAPI applications benefit from automatic instrumentation of the framework itself, as well as popular libraries including SQLAlchemy, Redis, PostgreSQL, and dozens of commonly used Python components. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database query bottlenecks without significant code modifications. The async-native design of FastAPI works seamlessly with OpenTelemetry's context propagation. Whether you're implementing observability for the first time, migrating from commercial APM solutions like DataDog or New Relic, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for FastAPI OpenTelemetry instrumentation. You'll learn how to set up auto-instrumentation, configure custom spans for business logic, optimize performance, and deploy with Docker. :::tip TL;DR Install `opentelemetry-instrumentation-fastapi` and call `FastAPIInstrumentor().instrument_app(app)` at startup. SQLAlchemy, Redis, and HTTP client libraries are instrumented automatically via the bootstrap command. Use `BatchSpanProcessor` with the OTLP exporter to send traces and metrics to base14 Scout with no changes to your route handlers. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry instrumentation for FastAPI applications - Configure automatic request and response tracing for HTTP endpoints - Instrument database operations with SQLAlchemy auto-instrumentation - Implement custom spans for business logic and external API calls - Collect and export HTTP metrics using custom middleware - Configure production-ready telemetry with BatchSpanProcessor - Export telemetry data to base14 Scout via OTLP - Deploy instrumented applications with Docker and Docker Compose - Troubleshoot common instrumentation issues - Optimize performance impact in production environments ### Who This Guide Is For This documentation is designed for: - **FastAPI developers**: implementing observability and distributed tracing for the first time in async Python applications - **DevOps engineers**: deploying FastAPI applications with production monitoring requirements and container orchestration - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-source observability - **Backend developers**: debugging performance issues, slow database queries, or async operation bottlenecks in FastAPI services - **Platform teams**: standardizing observability across multiple FastAPI microservices with consistent instrumentation patterns ### Prerequisites Before starting, ensure you have: - **Python 3.9 or later** installed (Python 3.13+ recommended for best performance) - **FastAPI 0.100.0 or later** installed in your project (0.115.6+ recommended) - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment - **Basic understanding** of OpenTelemetry concepts (traces, spans, attributes) - Access to package installation via `pip` or your preferred package manager #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | --------------------------------- | --------------- | ------------------- | ------------------------------------------------------ | | **Python** | 3.9 | 3.13+ | Python 3.13+ offers best performance and type system | | **FastAPI** | 0.100.0 | 0.115.6+ | Full Pydantic v2 and modern dependency injection | | **OpenTelemetry SDK** | 1.20.0 | 1.29+ | Core SDK for traces and metrics | | **OpenTelemetry Instrumentation** | 0.41b0 | 0.50b0+ | FastAPI auto-instrumentation | | **SQLAlchemy** (optional) | 1.4+ | 2.0.36+ | For database instrumentation | | **Pydantic** | 2.0+ | 2.10+ | Included with FastAPI, v2 required for modern patterns | #### Supported Libraries OpenTelemetry automatically instruments these commonly used libraries: - **Web frameworks**: FastAPI, Starlette - **Databases**: SQLAlchemy, asyncpg, psycopg2, pymongo - **HTTP clients**: requests, httpx, aiohttp - **Task queues**: Celery (with additional instrumentation) - **Caching**: Redis, memcached ### Installation #### Core Packages Install the required OpenTelemetry packages for FastAPI instrumentation: ```bash pip install opentelemetry-api pip install opentelemetry-sdk pip install opentelemetry-instrumentation-fastapi pip install opentelemetry-exporter-otlp ``` #### Optional Instrumentation Libraries Add these packages to instrument additional components: ```bash # HTTP client instrumentation pip install opentelemetry-instrumentation-requests pip install opentelemetry-instrumentation-httpx # Database instrumentation pip install opentelemetry-instrumentation-sqlalchemy # Redis instrumentation pip install opentelemetry-instrumentation-redis ``` #### Complete Requirements File For production applications, add all dependencies to `requirements.txt`: ```plaintext title="requirements.txt" showLineNumbers # Web framework fastapi[all] uvicorn[standard] # OpenTelemetry core opentelemetry-api opentelemetry-sdk opentelemetry-exporter-otlp # OpenTelemetry instrumentation opentelemetry-instrumentation-fastapi opentelemetry-instrumentation-requests opentelemetry-instrumentation-sqlalchemy # Optional: Application dependencies sqlalchemy psycopg2-binary pydantic-settings ``` Then install all dependencies: ```bash pip install -r requirements.txt ``` ### Configuration FastAPI OpenTelemetry instrumentation can be configured in multiple ways depending on your application architecture and deployment requirements. This section covers different setup approaches and advanced configuration options. #### Setup Approaches Choose the initialization method that best fits your application architecture: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ##### Inline Configuration (Quick Start) The simplest approach is to configure OpenTelemetry directly in your main application file. This works well for small applications and development environments. ```python title="main.py" showLineNumbers from fastapi import FastAPI from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from opentelemetry import trace from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter # Configure trace provider with service name resource = Resource.create({"service.name": "my-fastapi-service"}) trace.set_tracer_provider(TracerProvider(resource=resource)) # Set up trace exporter trace.get_tracer_provider().add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint="http://localhost:4318/v1/traces") ) ) # Create FastAPI app app = FastAPI() # Instrument the FastAPI app FastAPIInstrumentor.instrument_app(app) @app.get("/") def root(): return {"message": "Hello World"} ``` This configuration automatically captures: - HTTP request method, path, and status code - Request duration and timing - Error and exception information - Request headers (configurable) - Query parameters and path parameters ```mdx-code-block ``` ##### Separate Telemetry Module (Recommended) For better code organization and reusability, create a dedicated telemetry module. This approach is recommended for production applications. ```python title="app/telemetry.py" showLineNumbers import os from opentelemetry import trace, metrics from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter def setup_telemetry(otel_endpoint: str) -> None: """ Initialize OpenTelemetry tracing and metrics. Args: otel_endpoint: OTLP collector endpoint (e.g., "localhost:4318") """ # Get service name from environment or use default service_name = os.getenv("OTEL_SERVICE_NAME", "fastapi-app") # Create resource with service identification resource = Resource.create({ "service.name": service_name, "service.version": os.getenv("APP_VERSION", "1.0.0"), "deployment.environment": os.getenv("ENVIRONMENT", "development"), "environment": os.getenv("ENVIRONMENT", "development") }) # Configure trace provider provider = TracerProvider(resource=resource) provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint=f"http://{otel_endpoint}/v1/traces") ) ) trace.set_tracer_provider(provider) # Configure metrics provider metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"http://{otel_endpoint}/v1/metrics"), export_interval_millis=5000 # Export every 5 seconds ) metrics.set_meter_provider( MeterProvider(resource=resource, metric_readers=[metric_reader]) ) ``` Then use it in your main application file: ```python title="app/main.py" showLineNumbers from fastapi import FastAPI from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from opentelemetry.instrumentation.requests import RequestsInstrumentor import os from .telemetry import setup_telemetry # Initialize telemetry before creating the app otel_endpoint = os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "localhost:4318") setup_telemetry(otel_endpoint) # Create FastAPI app app = FastAPI() # Instrument FastAPI and HTTP clients FastAPIInstrumentor.instrument_app(app) RequestsInstrumentor().instrument() @app.get("/") def root(): return {"message": "Hello World"} ``` ```mdx-code-block ``` ##### CLI Auto-Instrumentation (Zero-Code) The simplest approach for containerized deployments uses the OpenTelemetry CLI tool for zero-code instrumentation. This is the **recommended starting point** for new projects. **Installation:** ```bash # Install the distro package (includes CLI tools) pip install opentelemetry-distro pip install opentelemetry-exporter-otlp # Bootstrap auto-instrumentation (installs all available instrumentations) opentelemetry-bootstrap -a install ``` **Development mode** (console output): ```bash opentelemetry-instrument \ --traces_exporter console \ --metrics_exporter console \ --service_name fastapi-app \ uvicorn app.main:app --reload ``` **Production mode** (OTLP export): ```bash # Set environment variables export OTEL_SERVICE_NAME="fastapi-app" export OTEL_EXPORTER_OTLP_ENDPOINT="http://localhost:4318" export OTEL_TRACES_EXPORTER="otlp" export OTEL_METRICS_EXPORTER="otlp" # Run with auto-instrumentation (no code changes needed!) opentelemetry-instrument uvicorn app.main:app --host 0.0.0.0 --port 8000 ``` **Docker deployment:** ```dockerfile title="Dockerfile" showLineNumbers FROM python:3.12-slim WORKDIR /app # Install dependencies including OpenTelemetry COPY requirements.txt . RUN pip install --no-cache-dir -r requirements.txt && \ pip install opentelemetry-distro opentelemetry-exporter-otlp && \ opentelemetry-bootstrap -a install # Copy application COPY ./app ./app # Run with auto-instrumentation CMD ["opentelemetry-instrument", "uvicorn", "app.main:app", "--host", "0.0.0.0", "--port", "8000"] ``` **Advantages:** - ✅ Zero code changes required - ✅ Automatic instrumentation of FastAPI, database clients, HTTP clients - ✅ Easy to enable/disable via environment variables - ✅ Perfect for containerized deployments **When to use:** Production deployments where you want automatic instrumentation without modifying application code. ```mdx-code-block ``` #### Advanced Configuration Fine-tune instrumentation behavior for specific requirements: ```mdx-code-block ``` ##### Selective Instrumentation To instrument only specific components or exclude certain endpoints: ```python title="main.py" showLineNumbers from fastapi import FastAPI from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from opentelemetry import trace # ... telemetry setup ... app = FastAPI() # Instrument with custom configuration FastAPIInstrumentor.instrument_app( app, excluded_urls="/health,/metrics,/docs,/openapi.json", # Skip these endpoints tracer_provider=trace.get_tracer_provider(), ) @app.get("/health") def health_check(): """This endpoint won't be traced""" return {"status": "healthy"} @app.get("/api/users") def get_users(): """This endpoint will be traced""" return {"users": []} ``` ```mdx-code-block ``` #### Approach 5: Request/Response Hooks Add custom attributes to spans using hooks for advanced use cases: ```python title="app/main.py" showLineNumbers from typing import Any from fastapi import FastAPI from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from opentelemetry.trace import Span app = FastAPI() def server_request_hook(span: Span, scope: dict[str, Any]) -> None: """ Hook called when a request is received. Add custom attributes based on request data. """ if span and span.is_recording(): # Add custom business context span.set_attribute("app.user_tier", scope.get("user_tier", "free")) span.set_attribute("app.request_id", scope.get("request_id")) # Add query parameters as attributes query_string = scope.get("query_string", b"").decode() if query_string: span.set_attribute("http.query_string", query_string) def client_request_hook(span: Span, scope: dict[str, Any]) -> None: """Hook for outbound HTTP requests.""" if span and span.is_recording(): span.set_attribute("app.calling_service", "fastapi-app") def client_response_hook(span: Span, message: dict[str, Any]) -> None: """Hook called when a response is received.""" if span and span.is_recording(): # Track response metadata content_type = message.get("headers", {}).get("content-type") if content_type: span.set_attribute("http.response.content_type", content_type) # Instrument with hooks FastAPIInstrumentor.instrument_app( app, server_request_hook=server_request_hook, client_request_hook=client_request_hook, client_response_hook=client_response_hook, ) ``` ```mdx-code-block ``` #### Approach 6: HTTP Header Capture Capture and sanitize HTTP headers automatically: ```python title="app/main.py" showLineNumbers from fastapi import FastAPI from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor app = FastAPI() # Configure header capture with sanitization FastAPIInstrumentor.instrument_app( app, # Capture specific request headers (lowercase with underscores) http_capture_headers_server_request=[ "content-type", "user-agent", "accept", "x-request-id", ], # Capture specific response headers http_capture_headers_server_response=[ "content-type", "content-length", "x-correlation-id", ], # IMPORTANT: Sanitize sensitive headers (never capture these) # This prevents accidental leaking of secrets # Note: Even if listed above, these will be redacted excluded_urls="/health,/metrics", ) # Headers appear as span attributes: # http.request.header.content_type # http.request.header.user_agent # http.response.header.content_type ``` **Security Note:** Never capture authorization headers, cookies, API keys, or any authentication tokens. Use sanitization to protect sensitive data. ```mdx-code-block ``` ### Traces Traces provide the complete picture of what happens when a request flows through your FastAPI application. They capture the entire lifecycle from the incoming HTTP request, through your business logic, database queries, external API calls, and finally the response sent back to the client. #### Automatic Trace Collection Once instrumented, FastAPI automatically captures detailed trace information for every request: **Captured Information:** - HTTP method, path, and status code - Request duration and timing breakdown - Request and response headers (configurable) - Query parameters and path parameters - Error and exception stack traces - Distributed trace context propagation (W3C Trace Context) **Trace Hierarchy:** ```text HTTP Request Span (root) ├── Route Handler Span │ ├── Database Query Span │ ├── External API Call Span │ └── Business Logic Span └── Response Span ``` #### Key Tracing Features - **Automatic HTTP tracking**: Every endpoint is automatically traced with no code changes - **Error capturing**: Exceptions are automatically recorded with full stack traces - **Context propagation**: Distributed traces work across microservices using W3C Trace Context headers - **Custom attributes**: Add business-specific metadata to spans (covered in Custom Instrumentation section) - **Async support**: Full support for FastAPI's async/await patterns > View traces in your base14 Scout dashboard to analyze request flows and > identify bottlenecks. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics OpenTelemetry metrics capture runtime measurements of your FastAPI application including HTTP request counts, latencies, response status codes, and custom business metrics. Unlike traces that show individual request flows, metrics aggregate data over time for monitoring trends and alerting. #### Custom Metrics Middleware Create a custom middleware to capture HTTP metrics for all requests: ```python title="app/metrics_middleware.py" showLineNumbers import os import time from starlette.middleware.base import BaseHTTPMiddleware from opentelemetry.metrics import get_meter class MetricsMiddleware(BaseHTTPMiddleware): def __init__(self, app): super().__init__(app) service_name = os.getenv("OTEL_SERVICE_NAME", "fastapi-app") self.meter = get_meter(service_name) # Create metrics instruments self.http_requests_counter = self.meter.create_counter( name="http.server.requests", unit="1", description="Total number of HTTP requests" ) self.http_request_duration = self.meter.create_histogram( name="http.server.duration", unit="ms", description="HTTP request duration in milliseconds" ) async def dispatch(self, request, call_next): start_time = time.time() # Process request response = await call_next(request) # Calculate duration duration_ms = (time.time() - start_time) * 1000 # Record metrics with attributes attributes = { "http.method": request.method, "http.route": request.url.path, "http.status_code": response.status_code, } self.http_requests_counter.add(1, attributes) self.http_request_duration.record(duration_ms, attributes) return response ``` Add the middleware to your FastAPI application: ```python title="app/main.py" showLineNumbers from fastapi import FastAPI from .metrics_middleware import MetricsMiddleware from .telemetry import setup_telemetry # Initialize telemetry setup_telemetry("localhost:4318") app = FastAPI() # Add metrics middleware BEFORE FastAPI instrumentation app.add_middleware(MetricsMiddleware) # Then add FastAPI instrumentation from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor FastAPIInstrumentor.instrument_app(app) ``` #### Available Metrics Once configured, these metrics are automatically collected: | Metric Name | Type | Description | Attributes | | ----------------------------- | ------------- | --------------------------- | -------------------------- | | `http.server.requests` | Counter | Total HTTP requests | method, route, status_code | | `http.server.duration` | Histogram | Request duration in ms | method, route, status_code | | `http.server.active_requests` | UpDownCounter | Currently active requests | method, route | | `http.server.response.size` | Histogram | Response body size in bytes | method, route, status_code | > View these metrics in base14 Scout to create dashboards, set up alerts, and > monitor application health. ### Production Configuration Production environments require careful configuration of OpenTelemetry to balance observability needs with performance and reliability. This section covers production-ready patterns. #### BatchSpanProcessor Configuration Configure BatchSpanProcessor parameters for optimal performance: ```python title="app/telemetry.py" showLineNumbers from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter # Production-optimized batch processor batch_processor = BatchSpanProcessor( OTLPSpanExporter(endpoint="http://otel-collector:4318/v1/traces"), max_queue_size=2048, # Maximum spans in queue schedule_delay_millis=5000, # Export every 5 seconds max_export_batch_size=512, # Maximum spans per export export_timeout_millis=30000 # Timeout for export operation ) trace.get_tracer_provider().add_span_processor(batch_processor) ``` #### Resource Attributes for Production Add comprehensive resource attributes to identify your service: ```python title="app/telemetry.py" showLineNumbers import os import socket from opentelemetry.sdk.resources import Resource resource = Resource.create({ # Service identification "service.name": os.getenv("OTEL_SERVICE_NAME", "fastapi-app"), "service.version": os.getenv("APP_VERSION", "1.0.0"), "service.namespace": os.getenv("SERVICE_NAMESPACE", "production"), # Deployment information "deployment.environment": os.getenv("ENVIRONMENT", "development"), "environment": os.getenv("ENVIRONMENT", "development"), "deployment.region": os.getenv("AWS_REGION", "us-east-1"), # Instance identification "service.instance.id": socket.gethostname(), "host.name": socket.gethostname(), "host.type": os.getenv("HOST_TYPE", "container"), # Container information (if applicable) "container.id": os.getenv("HOSTNAME", ""), "container.name": os.getenv("CONTAINER_NAME", ""), # Kubernetes information (if applicable) "k8s.namespace.name": os.getenv("K8S_NAMESPACE", ""), "k8s.pod.name": os.getenv("K8S_POD_NAME", ""), "k8s.deployment.name": os.getenv("K8S_DEPLOYMENT_NAME", ""), }) ``` #### Environment-Based Configuration Use environment variables to configure telemetry without code changes: ```python title="app/telemetry.py" showLineNumbers import os import logging from opentelemetry import trace, metrics from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor, ConsoleSpanExporter from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter logger = logging.getLogger(__name__) def setup_telemetry() -> None: """Initialize telemetry with environment-based configuration.""" # Get configuration from environment otel_endpoint = os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4318") environment = os.getenv("ENVIRONMENT", "development") service_name = os.getenv("OTEL_SERVICE_NAME", "fastapi-app") # Create resource resource = Resource.create({ "service.name": service_name, "deployment.environment": environment, "environment": environment, "service.version": os.getenv("APP_VERSION", "dev"), }) # Configure trace provider provider = TracerProvider(resource=resource) # Add exporters based on environment if environment == "development": # Console exporter for development provider.add_span_processor(BatchSpanProcessor(ConsoleSpanExporter())) logger.info("Using console exporter for traces") else: # OTLP exporter for production/staging provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint=f"{otel_endpoint}/v1/traces"), max_queue_size=2048, schedule_delay_millis=5000, ) ) logger.info(f"Using OTLP exporter at {otel_endpoint}") trace.set_tracer_provider(provider) # Configure metrics if environment != "development": metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"{otel_endpoint}/v1/metrics"), export_interval_millis=5000 ) metrics.set_meter_provider( MeterProvider(resource=resource, metric_readers=[metric_reader]) ) ``` #### Docker Compose Configuration Example `docker-compose.yml` for production-like deployment: ```yaml title="docker-compose.yml" showLineNumbers services: app: build: . ports: - "8000:8000" environment: # Application config ENVIRONMENT: development APP_VERSION: "1.2.0" # OpenTelemetry config OTEL_SERVICE_NAME: fastapi-app OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 # Database config DB_HOST: postgres DB_PORT: 5432 DB_NAME: myapp depends_on: - postgres - otel-collector command: uvicorn app.main:app --host 0.0.0.0 --port 8000 postgres: image: postgres:18 environment: POSTGRES_PASSWORD: password POSTGRES_DB: myapp volumes: - postgres_data:/var/lib/postgresql/data otel-collector: image: otel/opentelemetry-collector-contrib:latest command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - "4318:4318" # OTLP HTTP receiver - "55679:55679" # zpages for debugging volumes: postgres_data: ``` #### Environment Variables Template Create a `.env.example` file for your team: ```bash title=".env.example" showLineNumbers # Application ENVIRONMENT=development APP_VERSION=1.0.0 SERVICE_NAMESPACE=my-company # OpenTelemetry OTEL_SERVICE_NAME=fastapi-app OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 # Database DB_HOST=postgres DB_PORT=5432 DB_NAME=myapp DB_USER=postgres DB_PASSWORD=changeme # Security (for production, use secrets management) SECRET_KEY=your-secret-key-here JWT_ALGORITHM=HS256 JWT_EXPIRE_MINUTES=60 ``` #### Dockerfile with OpenTelemetry Build a production-ready Docker image: ```dockerfile title="Dockerfile" showLineNumbers FROM python:3.11-slim WORKDIR /app # Install system dependencies RUN apt-get update && apt-get install -y \ gcc \ && rm -rf /var/lib/apt/lists/* # Copy requirements and install Python dependencies COPY requirements.txt . RUN pip install --no-cache-dir -r requirements.txt # Copy application code COPY ./app ./app # Create non-root user RUN useradd -m -u 1000 appuser && chown -R appuser:appuser /app USER appuser # Health check HEALTHCHECK --interval=30s --timeout=3s --start-period=5s --retries=3 \ CMD python -c "import requests; requests.get('http://localhost:8000/health')" # Run application CMD ["uvicorn", "app.main:app", "--host", "0.0.0.0", "--port", "8000"] ``` ### Framework-Specific Features FastAPI's integration with OpenTelemetry automatically instruments several framework components and commonly used libraries. This section covers automatic instrumentation for databases, HTTP clients, and other integrations. #### SQLAlchemy Database Instrumentation OpenTelemetry automatically instruments SQLAlchemy database queries, providing detailed visibility into database operations. **Installation:** ```bash pip install opentelemetry-instrumentation-sqlalchemy ``` **Automatic Instrumentation:** ```python title="app/database.py" showLineNumbers from sqlalchemy import create_engine from sqlalchemy.orm import sessionmaker from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor # Create database engine DATABASE_URL = "postgresql://user:password@localhost:5432/mydb" engine = create_engine(DATABASE_URL) # Instrument SQLAlchemy BEFORE creating sessions SQLAlchemyInstrumentor().instrument( engine=engine, service="fastapi-app", enable_commenter=True, # Add SQL comments with trace context ) SessionLocal = sessionmaker(autocommit=False, autoflush=False, bind=engine) ``` This automatically captures: - SQL query text with parameters - Query execution time - Database connection details - Transaction boundaries - N+1 query detection (via span hierarchy) **Example Traced Query:** ```python title="app/routers/users.py" showLineNumbers from fastapi import APIRouter, Depends from sqlalchemy.orm import Session from ..database import SessionLocal from .. import models router = APIRouter() def get_db(): db = SessionLocal() try: yield db finally: db.close() @router.get("/users/{user_id}") def get_user(user_id: int, db: Session = Depends(get_db)): # This query is automatically traced with full SQL details user = db.query(models.User).filter(models.User.id == user_id).first() if not user: raise HTTPException(status_code=404, detail="User not found") return user ``` #### HTTP Client Instrumentation Trace outbound HTTP requests to external APIs and services. **For `requests` library:** ```bash pip install opentelemetry-instrumentation-requests ``` ```python title="app/main.py" showLineNumbers from opentelemetry.instrumentation.requests import RequestsInstrumentor # Instrument requests library globally RequestsInstrumentor().instrument() # Now all requests calls are automatically traced import requests @app.get("/external-api") async def call_external_api(): # This HTTP call is automatically traced response = requests.get("https://api.example.com/data") return response.json() ``` **For `httpx` library (async HTTP):** ```bash pip install opentelemetry-instrumentation-httpx ``` ```python title="app/main.py" showLineNumbers from opentelemetry.instrumentation.httpx import HTTPXClientInstrumentor import httpx # Instrument httpx globally HTTPXClientInstrumentor().instrument() @app.get("/async-external-api") async def call_async_external_api(): async with httpx.AsyncClient() as client: # This async HTTP call is automatically traced response = await client.get("https://api.example.com/data") return response.json() ``` #### Dependency Injection with Tracing FastAPI's dependency injection system works seamlessly with OpenTelemetry: ```python title="app/dependencies.py" showLineNumbers from typing import Annotated from fastapi import Depends, Header, HTTPException from opentelemetry import trace tracer = trace.get_tracer(__name__) def get_current_user(token: Annotated[str, Header()]) -> dict[str, str]: """Dependency that validates user token - automatically traced""" with tracer.start_as_current_span("validate_user_token"): # Token validation logic if not validate_token(token): raise HTTPException(status_code=401, detail="Invalid token") return get_user_from_token(token) @app.get("/protected") def protected_endpoint( user: Annotated[dict[str, str], Depends(get_current_user)] ) -> dict[str, dict[str, str]]: """The dependency span appears as a child of the HTTP request span""" return {"user": user} ``` #### Background Tasks with Tracing Trace FastAPI background tasks: ```python title="app/main.py" showLineNumbers from fastapi import BackgroundTasks from opentelemetry import trace tracer = trace.get_tracer(__name__) def send_email(email: str, message: str) -> None: """Background task - create manual span""" with tracer.start_as_current_span("send_email") as span: span.set_attribute("email.to", email) span.set_attribute("email.message_length", len(message)) # Email sending logic print(f"Sending email to {email}") @app.post("/register") async def register_user( email: str, background_tasks: BackgroundTasks ) -> dict[str, str]: # Add background task background_tasks.add_task(send_email, email, "Welcome!") return {"message": "User registered"} ``` ### Custom Instrumentation While auto-instrumentation captures HTTP requests and database queries, custom instrumentation lets you trace business logic, add contextual attributes, and instrument specific operations. #### Creating Custom Spans Add manual spans to trace specific operations: ```python title="app/services/order_service.py" showLineNumbers from typing import Annotated from fastapi import APIRouter, HTTPException, Body from pydantic import BaseModel from opentelemetry import trace router = APIRouter() tracer = trace.get_tracer(__name__) class OrderCreate(BaseModel): product_id: int quantity: int payment_method: str order_type: str amount: float class OrderResponse(BaseModel): order_id: int status: str @router.post("/orders") async def create_order( order: Annotated[OrderCreate, Body()] ) -> OrderResponse: # Parent span is automatically the HTTP request span with tracer.start_as_current_span("create_order") as span: # Add custom attributes span.set_attribute("order.type", order.order_type) span.set_attribute("order.amount", order.amount) span.set_attribute("order.quantity", order.quantity) # Nested span for inventory check with tracer.start_as_current_span("check_inventory") as inventory_span: inventory_span.set_attribute("product.id", order.product_id) available = await check_product_availability(order.product_id) inventory_span.set_attribute("inventory.available", available) if not available: span.set_status(trace.Status(trace.StatusCode.ERROR, "Out of stock")) raise HTTPException(status_code=400, detail="Product out of stock") # Nested span for payment processing with tracer.start_as_current_span("process_payment") as payment_span: payment_span.set_attribute("payment.method", order.payment_method) payment_result = await process_payment(order) payment_span.set_attribute("payment.transaction_id", payment_result["transaction_id"]) span.add_event("Order created successfully") return OrderResponse(order_id=123, status="created") ``` #### Adding Custom Attributes Enrich spans with business-specific metadata: ```python title="app/routers/posts.py" showLineNumbers from fastapi import APIRouter, HTTPException from pydantic import BaseModel from opentelemetry import trace router = APIRouter() class Post(BaseModel): id: int title: str author_id: int category: str published: bool @router.get("/posts/{post_id}") async def get_post(post_id: int) -> Post: # Get current span (automatically created by FastAPI instrumentation) current_span = trace.get_current_span() # Add custom attributes to existing span current_span.set_attribute("post.id", post_id) current_span.set_attribute("user.action", "view_post") # Fetch post post = await fetch_post_from_db(post_id) if not post: current_span.set_attribute("post.found", False) raise HTTPException(status_code=404, detail="Post not found") current_span.set_attribute("post.found", True) current_span.set_attribute("post.author_id", post.author_id) current_span.set_attribute("post.category", post.category) current_span.set_attribute("post.published", post.published) return post ``` #### Error Handling and Status Record errors and exceptions in spans: ```python title="app/services/external_api.py" showLineNumbers from opentelemetry import trace from opentelemetry.trace import Status, StatusCode import requests tracer = trace.get_tracer(__name__) def call_external_service(url: str): with tracer.start_as_current_span("external_api_call") as span: span.set_attribute("http.url", url) try: response = requests.get(url, timeout=5) response.raise_for_status() span.set_attribute("http.status_code", response.status_code) span.set_status(Status(StatusCode.OK)) return response.json() except requests.exceptions.Timeout as e: # Record exception details span.record_exception(e) span.set_status(Status(StatusCode.ERROR, "Request timeout")) raise except requests.exceptions.HTTPError as e: span.record_exception(e) span.set_status(Status(StatusCode.ERROR, f"HTTP {response.status_code}")) raise except Exception as e: span.record_exception(e) span.set_status(Status(StatusCode.ERROR, "Unknown error")) raise ``` #### Span Events Add timestamped events to spans for debugging: ```python title="app/services/data_processor.py" showLineNumbers from typing import Any from opentelemetry import trace tracer = trace.get_tracer(__name__) async def process_large_dataset(data: list[dict[str, Any]]) -> dict[str, int]: """Process large dataset in chunks with tracing.""" with tracer.start_as_current_span("process_dataset") as span: span.set_attribute("dataset.size", len(data)) span.add_event("Processing started") # Process in chunks chunk_size = 100 processed_count = 0 for i in range(0, len(data), chunk_size): chunk = data[i:i + chunk_size] await process_chunk(chunk) processed_count += len(chunk) # Add event for each chunk span.add_event( "Chunk processed", attributes={ "chunk.index": i // chunk_size, "chunk.size": len(chunk), "total.processed": processed_count } ) span.add_event("Processing completed") span.set_attribute("dataset.processed", processed_count) return {"processed": processed_count} ``` #### Semantic Conventions Use OpenTelemetry semantic conventions for consistent attribute naming: ```python title="app/services/user_service.py" showLineNumbers from opentelemetry import trace from opentelemetry.semconv.trace import SpanAttributes tracer = trace.get_tracer(__name__) @app.post("/login") async def login(username: str, password: str): with tracer.start_as_current_span("user.login") as span: # Use semantic conventions for HTTP attributes span.set_attribute(SpanAttributes.HTTP_METHOD, "POST") span.set_attribute(SpanAttributes.HTTP_ROUTE, "/login") # Use semantic conventions for user attributes span.set_attribute(SpanAttributes.ENDUSER_ID, username) # Authentication logic if authenticate(username, password): span.set_attribute("auth.success", True) return {"token": generate_token(username)} else: span.set_attribute("auth.success", False) span.set_status(Status(StatusCode.ERROR, "Authentication failed")) raise HTTPException(status_code=401, detail="Invalid credentials") ``` ### Running Your Application #### Development Mode Run with console output for local development: ```python title="app/telemetry.py" showLineNumbers from opentelemetry.sdk.trace.export import ConsoleSpanExporter, BatchSpanProcessor # Development configuration - print spans to console if os.getenv("ENVIRONMENT") == "development": console_processor = BatchSpanProcessor(ConsoleSpanExporter()) trace.get_tracer_provider().add_span_processor(console_processor) ``` Start the application: ```bash # Set environment to development export ENVIRONMENT=development export OTEL_SERVICE_NAME=fastapi-app # Run with uvicorn uvicorn app.main:app --reload --host 0.0.0.0 --port 8000 ``` #### Production Mode Run with OTLP exporter pointing to Scout Collector: ```bash # Set production environment variables export ENVIRONMENT=development export OTEL_SERVICE_NAME=fastapi-app export OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 export APP_VERSION=1.0.0 # Run with production settings uvicorn app.main:app --host 0.0.0.0 --port 8000 --workers 4 ``` #### Docker Deployment Build and run with Docker: ```bash # Build image docker build -t fastapi-app:latest . # Run container docker run -d \ --name fastapi-app \ -p 8000:8000 \ -e OTEL_SERVICE_NAME=fastapi-app \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 \ -e ENVIRONMENT=development \ fastapi-app:latest ``` Or use Docker Compose (see Production Configuration section above). ### Troubleshooting #### Verifying Instrumentation Create a test endpoint to verify OpenTelemetry is working: ```python title="app/main.py" showLineNumbers from opentelemetry import trace @app.get("/health") def health_check(): """Health check endpoint that verifies tracing""" current_span = trace.get_current_span() if current_span.is_recording(): return { "status": "healthy", "tracing": "enabled", "trace_id": format(current_span.get_span_context().trace_id, '032x'), "span_id": format(current_span.get_span_context().span_id, '016x') } else: return { "status": "healthy", "tracing": "disabled" } ``` #### Common Issues ##### Issue: No traces appearing in Scout **Solutions:** 1. Verify OTLP endpoint is accessible: ```bash curl http://otel-collector:4318/v1/traces ``` 2. Check telemetry initialization happens before FastAPI app creation: ```python # Correct order: setup_telemetry() # First app = FastAPI() # Second FastAPIInstrumentor.instrument_app(app) # Third ``` 3. Enable console exporter to verify spans are being created: ```python from opentelemetry.sdk.trace.export import ConsoleSpanExporter trace.get_tracer_provider().add_span_processor( BatchSpanProcessor(ConsoleSpanExporter()) ) ``` ##### Issue: ImportError for OpenTelemetry packages **Solutions:** 1. Verify all packages are installed: ```bash pip list | grep opentelemetry ``` 2. Reinstall with specific versions: ```bash pip install --upgrade opentelemetry-api opentelemetry-sdk pip install --upgrade opentelemetry-instrumentation-fastapi ``` 3. Check for conflicting packages: ```bash pip check ``` ##### Issue: Database queries not traced **Solutions:** 1. Ensure SQLAlchemy instrumentation is called BEFORE creating the engine: ```python from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor engine = create_engine(DATABASE_URL) SQLAlchemyInstrumentor().instrument(engine=engine) ``` 2. Verify the instrumentation package is installed: ```bash pip install opentelemetry-instrumentation-sqlalchemy ``` ##### Issue: High memory usage or performance degradation **Solutions:** 1. Configure BatchSpanProcessor with appropriate limits: ```python batch_processor = BatchSpanProcessor( exporter, max_queue_size=2048, # Reduce if memory is constrained schedule_delay_millis=5000, # Increase to batch more spans max_export_batch_size=512 ) ``` 2. Exclude high-volume endpoints: ```python FastAPIInstrumentor.instrument_app( app, excluded_urls="/health,/metrics" ) ``` ##### Issue: Middleware ordering problems **Solution:** Ensure correct middleware order (metrics before instrumentation): ```python app = FastAPI() app.add_middleware(MetricsMiddleware) # Custom middleware first FastAPIInstrumentor.instrument_app(app) # Then instrument ``` ### Security Considerations #### Sensitive Data in Spans Avoid capturing sensitive information in span attributes: **Bad Example:** ```python # DON'T DO THIS span.set_attribute("user.password", password) span.set_attribute("credit_card.number", card_number) span.set_attribute("user.ssn", ssn) ``` **Good Example:** ```python # DO THIS INSTEAD span.set_attribute("user.id", user_id) # Reference, not sensitive data span.set_attribute("payment.method", "credit_card") # Type, not details span.set_attribute("user.email_domain", email.split("@")[1]) # Partial info ``` #### HTTP Header Filtering Filter sensitive headers from traces: ```python title="app/telemetry.py" showLineNumbers from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor # Exclude sensitive headers from capture FastAPIInstrumentor.instrument_app( app, http_capture_headers_server_request=["content-type", "user-agent"], # DO NOT include: authorization, cookie, api-key, etc. ) ``` #### SQL Query Obfuscation SQLAlchemy instrumentation automatically obfuscates query parameters, but verify this is enabled: ```python title="app/database.py" showLineNumbers from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor SQLAlchemyInstrumentor().instrument( engine=engine, enable_commenter=True, # Query parameters are automatically obfuscated ) ``` #### Environment Variable Security Never commit sensitive values to version control: ```bash title=".env" showLineNumbers # ❌ BAD - Don't commit this file SECRET_KEY=actual-secret-key DB_PASSWORD=actual-password # ✅ GOOD - Use secrets management in production # AWS Secrets Manager, Vault, Kubernetes Secrets, etc. ``` In production, use environment-specific secrets management: - AWS Secrets Manager - HashiCorp Vault - Kubernetes Secrets - Azure Key Vault ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead when properly configured: | Metric | Impact | Notes | | ----------- | -------------------- | ------------------------- | | **Latency** | +0.5-2ms per request | Mostly from span creation | | **CPU** | +2-5% | Primarily during export | | **Memory** | +10-50MB | BatchSpanProcessor queue | | **Network** | +1-5KB per trace | OTLP compressed payload | #### Optimization Strategies ##### 1. Use BatchSpanProcessor in Production Always use `BatchSpanProcessor` (never `SimpleSpanProcessor`) for production: ```python title="app/telemetry.py" showLineNumbers from opentelemetry.sdk.trace.export import BatchSpanProcessor # ✅ GOOD - Batches spans for efficient export batch_processor = BatchSpanProcessor( exporter, max_queue_size=2048, schedule_delay_millis=5000, max_export_batch_size=512 ) # ❌ BAD - Exports each span immediately (only for debugging) # simple_processor = SimpleSpanProcessor(exporter) ``` ##### 2. Skip Non-Critical Endpoints Exclude health checks and metrics endpoints: ```python title="app/main.py" showLineNumbers FastAPIInstrumentor.instrument_app( app, excluded_urls="/health,/metrics,/favicon.ico,/docs,/openapi.json" ) ``` ##### 3. Limit Attribute Sizes Prevent large attributes from consuming memory: ```python title="app/services/data_service.py" showLineNumbers def add_safe_attribute(span, key: str, value: str, max_length: int = 256): """Add attribute with size limit""" if isinstance(value, str) and len(value) > max_length: value = value[:max_length] + "... (truncated)" span.set_attribute(key, value) # Usage span = trace.get_current_span() add_safe_attribute(span, "response.body", large_response) ``` ##### 5. Optimize Database Instrumentation For high-traffic endpoints with many queries: ```python title="app/database.py" showLineNumbers from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor # Disable commenter for performance (optional) SQLAlchemyInstrumentor().instrument( engine=engine, enable_commenter=False, # Reduces overhead slightly ) ``` ### FAQ #### Does FastAPI instrumentation work with async/await? Yes, OpenTelemetry fully supports FastAPI's async/await patterns. Context propagation works automatically across async operations, ensuring parent-child span relationships are maintained correctly. #### What is the performance impact of OpenTelemetry on FastAPI? Typical overhead is 0.5-2ms added latency per request, 2-5% CPU increase, and 10-50MB additional memory. This impact is minimal and acceptable for most production applications. #### Which Python and FastAPI versions are supported? - **Python**: 3.9+ minimum (Python 3.13+ recommended for best performance) - **FastAPI**: 0.100.0+ (0.115.6+ recommended for Pydantic v2) - **OpenTelemetry**: SDK 1.20+ (1.29+ recommended, always use latest stable) #### How do I instrument SQLAlchemy database queries? Install `opentelemetry-instrumentation-sqlalchemy` and instrument your engine: ```python from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor SQLAlchemyInstrumentor().instrument(engine=engine) ``` All queries will automatically be traced with full SQL details. #### How does distributed tracing work across microservices? OpenTelemetry uses W3C Trace Context headers (`traceparent`, `tracestate`) to propagate trace context between services. FastAPI instrumentation automatically extracts and injects these headers, enabling distributed traces across your entire system. #### What's the difference between traces and metrics? - **Traces**: Show individual request flows with detailed timing (e.g., "this specific request took 150ms") - **Metrics**: Aggregate measurements over time (e.g., "average response time is 120ms") Use both: traces for debugging specific issues, metrics for monitoring overall health. #### How do I detect N+1 database queries in FastAPI with OpenTelemetry? View the span hierarchy in base14 Scout. N+1 queries appear as many sequential database spans under a single parent span. The trace visualization clearly shows the query pattern, making N+1 issues obvious. #### Can I use OpenTelemetry with Pydantic v2? Yes, OpenTelemetry works with both Pydantic v1 and v2. FastAPI automatically handles Pydantic model serialization, and instrumentation captures the HTTP layer regardless of Pydantic version. #### How do I instrument background tasks and Celery? For FastAPI background tasks, manually create spans (see Background Tasks section). For Celery, install `opentelemetry-instrumentation-celery`: ```bash pip install opentelemetry-instrumentation-celery ``` #### Does OpenTelemetry instrumentation affect FastAPI WebSocket connections? FastAPI WebSocket connections are automatically traced. Each WebSocket connection creates a long-lived span that tracks the entire connection duration and messages exchanged. #### How do I handle multi-tenancy in traces? Add tenant identification to resource attributes or span attributes: ```python span.set_attribute("tenant.id", tenant_id) span.set_attribute("tenant.name", tenant_name) ``` Then filter and query by tenant in base14 Scout. ### What's Next? #### Advanced Topics - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans, metrics, and advanced patterns - [OpenTelemetry Collector Configuration](../../collector-setup/otel-collector-config.md) \- Advanced collector features #### base14 Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts based on traces and metrics - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production Kubernetes deployment - [Scout Exporter Configuration](../../collector-setup/scout-exporter.md) - Configure authentication and endpoints ### Complete Example Here's a complete production-ready FastAPI application with OpenTelemetry instrumentation: #### Complete requirements.txt ```plaintext title="requirements.txt" showLineNumbers # Web framework fastapi[all]==0.115.6 uvicorn[standard]==0.32.0 # Database sqlalchemy==2.0.36 psycopg2-binary==2.9.10 alembic==1.14.0 # Authentication python-jose[cryptography]==3.3.0 passlib[bcrypt]==1.7.4 python-multipart==0.0.20 # OpenTelemetry core opentelemetry-api==1.29.0 opentelemetry-sdk==1.29.0 opentelemetry-exporter-otlp==1.29.0 # OpenTelemetry instrumentation opentelemetry-instrumentation-fastapi==0.50b0 opentelemetry-instrumentation-sqlalchemy==0.50b0 opentelemetry-instrumentation-requests==0.50b0 opentelemetry-instrumentation-httpx==0.50b0 # Utilities pydantic==2.10.3 pydantic-settings==2.6.1 python-dotenv==1.0.1 ``` #### Complete telemetry.py ```python title="app/telemetry.py" showLineNumbers import os import socket from opentelemetry import trace, metrics from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor, ConsoleSpanExporter from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter def setup_telemetry(otel_endpoint: str = None): """ Initialize OpenTelemetry tracing and metrics with production-ready configuration. Args: otel_endpoint: OTLP collector endpoint (e.g., "localhost:4318") """ # Get configuration from environment service_name = os.getenv("OTEL_SERVICE_NAME", "fastapi-app") environment = os.getenv("ENVIRONMENT", "development") otel_endpoint = otel_endpoint or os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "localhost:4318") # Create comprehensive resource attributes resource = Resource.create({ "service.name": service_name, "service.version": os.getenv("APP_VERSION", "1.0.0"), "service.namespace": os.getenv("SERVICE_NAMESPACE", "default"), "deployment.environment": environment, "environment": environment, "service.instance.id": socket.gethostname(), "host.name": socket.gethostname(), }) # Configure trace provider provider = TracerProvider(resource=resource) # Add OTLP exporter for production/staging if environment in ["production", "staging"]: otlp_processor = BatchSpanProcessor( OTLPSpanExporter(endpoint=f"http://{otel_endpoint}/v1/traces"), max_queue_size=2048, schedule_delay_millis=5000, max_export_batch_size=512, export_timeout_millis=30000 ) provider.add_span_processor(otlp_processor) else: # Add console exporter for development console_processor = BatchSpanProcessor(ConsoleSpanExporter()) provider.add_span_processor(console_processor) trace.set_tracer_provider(provider) # Configure metrics provider metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"http://{otel_endpoint}/v1/metrics"), export_interval_millis=5000 ) metrics.set_meter_provider( MeterProvider(resource=resource, metric_readers=[metric_reader]) ) print(f"✅ OpenTelemetry initialized: {service_name} ({environment})") ``` #### Complete main.py ```python title="app/main.py" showLineNumbers import os from fastapi import FastAPI from fastapi.middleware.cors import CORSMiddleware from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor from opentelemetry.instrumentation.requests import RequestsInstrumentor from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor from .telemetry import setup_telemetry from .metrics_middleware import MetricsMiddleware from .database import engine from .routers import users, posts # Initialize telemetry FIRST otel_endpoint = os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "localhost:4318") setup_telemetry(otel_endpoint) # Instrument SQLAlchemy SQLAlchemyInstrumentor().instrument(engine=engine) # Create FastAPI app app = FastAPI( title="FastAPI with OpenTelemetry", version="1.0.0", description="Production-ready FastAPI with full observability" ) # Add CORS middleware app.add_middleware( CORSMiddleware, allow_origins=["*"], allow_credentials=True, allow_methods=["*"], allow_headers=["*"], ) # Add custom metrics middleware app.add_middleware(MetricsMiddleware) # Instrument FastAPI (excludes health/metrics endpoints) FastAPIInstrumentor.instrument_app( app, excluded_urls="/health,/metrics" ) # Instrument HTTP clients RequestsInstrumentor().instrument() # Include routers app.include_router(users.router, prefix="/api", tags=["users"]) app.include_router(posts.router, prefix="/api", tags=["posts"]) @app.get("/") def root(): return {"message": "Hello World", "status": "operational"} @app.get("/health") def health_check(): from opentelemetry import trace current_span = trace.get_current_span() return { "status": "healthy", "tracing": "enabled" if current_span.is_recording() else "disabled" } ``` #### Repository Link A complete working example with database integration, authentication, and full instrumentation is available at: [GitHub: base-14/examples/python/fastapi-postgres](https://github.com/base-14/examples/tree/main/python/fastapi-postgres) Once telemetry is flowing, you can [monitor FastAPI performance in Scout APM](https://base14.io/scout/apm) — track request latency, error rates, and database query traces across all your endpoints. ### References - [Official OpenTelemetry Python Documentation](https://opentelemetry.io/docs/languages/python/) - [FastAPI Documentation](https://fastapi.tiangolo.com/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) - [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Related Guides - [Django Instrumentation](./django.md) - Full-featured Python framework with ORM - [Flask Instrumentation](./flask.md) - Lightweight Python web framework - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language --- ## Fastify OpenTelemetry Instrumentation - Complete APM Setup Guide ## Fastify Implement OpenTelemetry instrumentation for Fastify applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your Fastify application to collect traces and metrics from HTTP requests, database queries, Redis operations, background jobs, and custom business logic using the OpenTelemetry Node.js SDK with minimal code changes. Fastify is a performance-focused alternative to [Express](./express.md), with a minimal core similar to the edge-first [Hono](./hono.md). Fastify applications benefit from automatic instrumentation of the framework itself, as well as popular libraries including PostgreSQL (pg), Redis (IORedis), BullMQ, Drizzle ORM, and dozens of commonly used Node.js components. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database query bottlenecks without significant code modifications. Fastify's plugin-based architecture and high-performance design work seamlessly with OpenTelemetry's context propagation, ensuring accurate parent-child span relationships across async operations. Whether you're implementing observability for the first time, migrating from commercial APM solutions like DataDog or New Relic, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Fastify OpenTelemetry instrumentation. You'll learn how to set up auto-instrumentation, configure custom spans for business logic, optimize performance, and deploy with Docker. :::tip TL;DR Create a `telemetry.ts` file that initializes `NodeSDK` with `getNodeAutoInstrumentations()` and import it as the very first line of your entry point - this auto-instruments Fastify routes, PostgreSQL (`pg`), Redis (IORedis), and HTTP clients without touching route code. Set `OTEL_SERVICE_NAME` and `OTEL_EXPORTER_OTLP_ENDPOINT`, and propagate trace context explicitly into BullMQ job data so worker spans link back to the originating request. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry instrumentation for Fastify applications - Configure automatic request and response tracing for HTTP endpoints - Instrument database operations with PostgreSQL auto-instrumentation - Implement custom spans for business logic and external API calls - Trace background jobs with BullMQ and propagate context to workers - Configure production-ready telemetry with BatchSpanProcessor - Export telemetry data to base14 Scout via OTLP - Deploy instrumented applications with Docker and Docker Compose - Troubleshoot common instrumentation issues - Optimize performance impact in production environments ### Who This Guide Is For This documentation is designed for: - **Fastify developers**: implementing observability and distributed tracing for the first time in Node.js applications - **DevOps engineers**: deploying Fastify applications with production monitoring requirements and container orchestration - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-source observability - **Backend developers**: debugging performance issues, slow queries, or async operation bottlenecks in Fastify services - **Platform teams**: standardizing observability across multiple Fastify microservices with consistent instrumentation patterns ### Prerequisites Before starting, ensure you have: - **Node.js 24.0.0 or later** installed (latest LTS recommended) - **Fastify 5.0.0 or later** installed in your project - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment - **Basic understanding** of OpenTelemetry concepts (traces, spans, attributes) - Access to npm for package installation #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | ------------------------- | --------------- | ------------------- | --------------------------------- | | **Node.js** | 24.0.0 | 24.x LTS | Latest LTS with ESM support | | **Fastify** | 5.0.0 | 5.7.1+ | Latest v5 with improved hooks | | **TypeScript** (optional) | 5.0.0 | 5.9.3+ | For type safety | | **OpenTelemetry SDK** | 0.200.0 | 0.211+ | Core SDK for traces and metrics | | **PostgreSQL** (optional) | 15.0 | 18.x | For database instrumentation | | **Redis** (optional) | 7.0 | 8.x | For IORedis instrumentation | | **Drizzle ORM** (optional)| 0.40.0 | 0.45.1+ | Type-safe SQL builder | #### Supported Libraries OpenTelemetry automatically instruments these commonly used libraries: - **Web frameworks**: Fastify, HTTP/HTTPS - **Databases**: PostgreSQL (pg), MySQL, SQLite - **Caching**: Redis (IORedis), Memcached - **Job Queues**: BullMQ - **HTTP Clients**: axios, node-fetch, http/https - **Logging**: Pino (with trace correlation) ### Installation #### Core Packages Install the required OpenTelemetry packages for Fastify instrumentation: ```bash showLineNumbers npm install @opentelemetry/api npm install @opentelemetry/sdk-node npm install @opentelemetry/auto-instrumentations-node npm install @opentelemetry/exporter-trace-otlp-http npm install @opentelemetry/exporter-metrics-otlp-http npm install @opentelemetry/resources npm install @opentelemetry/semantic-conventions ``` #### Optional Instrumentation Libraries Add these packages for specific component instrumentation: ```bash showLineNumbers # Fastify-specific instrumentation (included in auto-instrumentations) npm install @opentelemetry/instrumentation-fastify # Logs export (optional) npm install @opentelemetry/api-logs npm install @opentelemetry/sdk-logs npm install @opentelemetry/exporter-logs-otlp-http # Pino trace correlation (optional) npm install pino-opentelemetry-transport ``` ### Configuration Choose the initialization method that best fits your application architecture: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` #### SDK Configuration File (Recommended) Create a `telemetry.ts` file that initializes OpenTelemetry before any other imports. This is the recommended approach for Fastify applications. ```typescript showLineNumbers title="src/telemetry.ts" /** * OpenTelemetry instrumentation setup for Fastify application. * * CRITICAL: This file MUST be imported before any other modules * to ensure auto-instrumentation captures all dependencies. */ import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const serviceName = process.env.OTEL_SERVICE_NAME || 'fastify-app'; const serviceVersion = process.env.OTEL_SERVICE_VERSION || '1.0.0'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: serviceName, [ATTR_SERVICE_VERSION]: serviceVersion, }); const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${otlpEndpoint}/v1/traces`, }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 60000, }), instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const url = req.url || ''; // Skip health checks and metrics endpoints return url === '/health' || url === '/metrics'; }, }, '@opentelemetry/instrumentation-fs': { enabled: false, // Disable noisy filesystem instrumentation }, }), ], }); sdk.start(); // Graceful shutdown process.on('SIGTERM', () => { sdk .shutdown() .then(() => console.log('OpenTelemetry SDK shut down')) .catch((err) => console.error('Error shutting down SDK', err)) .finally(() => process.exit(0)); }); export { sdk }; ``` Import this file as the first line in your application entry point: ```typescript showLineNumbers title="src/index.ts" import './telemetry.js'; import { createApp } from './app.js'; import { config } from './config/index.js'; const start = async () => { const app = await createApp(); await app.listen({ port: config.port, host: config.host }); app.log.info(`Server running at http://${config.host}:${config.port}`); }; start(); ``` ```mdx-code-block ``` #### Environment Variables Only For simpler setups or container deployments, configure via environment variables: ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=fastify-app OTEL_SERVICE_VERSION=1.0.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_NODE_RESOURCE_DETECTORS=env,host,os,process ``` Then use a minimal telemetry file: ```typescript showLineNumbers title="src/telemetry.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; const sdk = new NodeSDK({ instrumentations: [getNodeAutoInstrumentations()], }); sdk.start(); ``` ```mdx-code-block ``` #### With Log Export For complete observability including structured logs: ```typescript showLineNumbers title="src/telemetry.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { BatchLogRecordProcessor } from '@opentelemetry/sdk-logs'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || 'fastify-app', [ATTR_SERVICE_VERSION]: process.env.OTEL_SERVICE_VERSION || '1.0.0', }); const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${otlpEndpoint}/v1/traces`, }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 60000, }), logRecordProcessor: new BatchLogRecordProcessor( new OTLPLogExporter({ url: `${otlpEndpoint}/v1/logs`, }) ), instrumentations: [getNodeAutoInstrumentations()], }); sdk.start(); ``` ```mdx-code-block ``` #### Scout Collector Integration Configure for base14 Scout with OAuth2 authentication: ```yaml showLineNumbers title="config/otel-config.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: batch: timeout: 5s send_batch_size: 512 resource: attributes: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlphttp/scout: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client extensions: oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} health_check: endpoint: 0.0.0.0:13133 service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/scout] metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/scout] logs: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/scout] ``` ```mdx-code-block ``` ### Production Configuration #### Resource Attributes Configure resource attributes for production deployments: ```typescript showLineNumbers title="src/telemetry.ts" import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, ATTR_SERVICE_NAMESPACE, ATTR_DEPLOYMENT_ENVIRONMENT_NAME, ATTR_HOST_NAME, } from '@opentelemetry/semantic-conventions'; import os from 'os'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || 'fastify-app', [ATTR_SERVICE_VERSION]: process.env.OTEL_SERVICE_VERSION || '1.0.0', [ATTR_SERVICE_NAMESPACE]: process.env.SERVICE_NAMESPACE || 'production', [ATTR_DEPLOYMENT_ENVIRONMENT_NAME]: process.env.NODE_ENV || 'development', [ATTR_HOST_NAME]: os.hostname(), 'service.instance.id': process.env.HOSTNAME || crypto.randomUUID(), }); ``` #### Production Environment Variables ```bash showLineNumbers title=".env.production" # Service identification OTEL_SERVICE_NAME=fastify-api OTEL_SERVICE_VERSION=1.2.3 SERVICE_NAMESPACE=production # Collector endpoint OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 # Resource attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,service.namespace=api # Sampling (reduce volume in high-traffic scenarios) OTEL_TRACES_SAMPLER=parentbased_traceidratio OTEL_TRACES_SAMPLER_ARG=0.1 ``` #### Docker Deployment ```dockerfile showLineNumbers title="Dockerfile" # Build stage FROM node:24-alpine AS builder WORKDIR /app COPY package*.json ./ RUN npm ci --only=production=false COPY . . RUN npm run build # Runtime stage FROM node:24-alpine AS runtime WORKDIR /app # Create non-root user RUN addgroup -g 1001 -S nodejs && \ adduser -S nodejs -u 1001 # Copy built application COPY --from=builder --chown=nodejs:nodejs /app/dist ./dist COPY --from=builder --chown=nodejs:nodejs /app/node_modules ./node_modules COPY --from=builder --chown=nodejs:nodejs /app/package.json ./ USER nodejs EXPOSE 3000 # Health check HEALTHCHECK --interval=30s --timeout=10s --start-period=10s --retries=3 \ CMD wget -qO- http://localhost:3000/health || exit 1 CMD ["node", "dist/index.js"] ``` #### Docker Compose Configuration ```yaml showLineNumbers title="compose.yml" services: app: build: context: . target: runtime ports: - "3000:3000" environment: NODE_ENV: production PORT: "3000" DATABASE_URL: postgresql://postgres:postgres@postgres:5432/app REDIS_URL: redis://redis:6379 OTEL_SERVICE_NAME: fastify-api OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_RESOURCE_ATTRIBUTES: deployment.environment=development,environment=development depends_on: postgres: condition: service_healthy redis: condition: service_healthy otel-collector: condition: service_healthy healthcheck: test: ["CMD", "wget", "-qO-", "http://localhost:3000/health"] interval: 30s timeout: 10s retries: 3 networks: - app-network worker: build: context: . target: runtime command: ["node", "dist/jobs/worker.js"] environment: NODE_ENV: production DATABASE_URL: postgresql://postgres:postgres@postgres:5432/app REDIS_URL: redis://redis:6379 OTEL_SERVICE_NAME: fastify-worker OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 depends_on: - postgres - redis - otel-collector networks: - app-network otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otelcol-config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otelcol-config.yaml:ro ports: - "4317:4317" - "4318:4318" env_file: - .env healthcheck: test: ["CMD", "curl", "-f", "http://localhost:13133/health"] interval: 10s timeout: 5s retries: 3 networks: - app-network networks: app-network: driver: bridge ``` ### Framework-Specific Instrumentation #### Fastify Hooks and Plugins Fastify's hook system integrates naturally with OpenTelemetry: ```typescript showLineNumbers title="src/app.ts" import Fastify, { FastifyInstance, FastifyError } from 'fastify'; import cors from '@fastify/cors'; import helmet from '@fastify/helmet'; import rateLimit from '@fastify/rate-limit'; import { trace } from '@opentelemetry/api'; export async function createApp(): Promise { const fastify = Fastify({ logger: true, requestIdLogLabel: 'requestId', genReqId: () => crypto.randomUUID(), }); // Security plugins await fastify.register(helmet); await fastify.register(cors, { origin: true }); await fastify.register(rateLimit, { max: 100, timeWindow: '1 minute' }); // Error handler with trace context fastify.setErrorHandler((error: FastifyError, request, reply) => { const span = trace.getActiveSpan(); const traceId = span?.spanContext()?.traceId; fastify.log.error({ err: error, traceId }, 'Request error'); const statusCode = error.statusCode ?? 500; reply.code(statusCode).send({ error: error.message, statusCode, ...(traceId && { traceId }), }); }); return fastify; } ``` #### Automatic Route Instrumentation OpenTelemetry automatically instruments Fastify routes: ```typescript showLineNumbers title="src/routes/articles.ts" import { FastifyPluginAsync } from 'fastify'; import * as articleService from '../services/article.js'; const articlesRoutes: FastifyPluginAsync = async (fastify) => { // GET /api/articles - automatically traced fastify.get('/', async (request, reply) => { const { limit, offset, author } = request.query as { limit?: number; offset?: number; author?: string; }; const result = await articleService.findArticles( { limit, offset, author }, request.user?.id ); return result; }); // POST /api/articles - automatically traced fastify.post('/', { preHandler: [fastify.authenticate] }, async (request) => { const { title, description, body } = request.body as { title: string; description?: string; body: string; }; return articleService.createArticle(request.user!.id, { title, description, body, }); }); }; export default articlesRoutes; ``` #### PostgreSQL with Drizzle ORM Database queries are automatically instrumented: ```typescript showLineNumbers title="src/db/index.ts" import { drizzle } from 'drizzle-orm/node-postgres'; import pg from 'pg'; import * as schema from './schema.js'; const pool = new pg.Pool({ connectionString: process.env.DATABASE_URL, max: 20, idleTimeoutMillis: 30000, connectionTimeoutMillis: 2000, }); export const db = drizzle(pool, { schema }); export async function closeDatabase(): Promise { await pool.end(); } ``` ### Custom Instrumentation #### Business Logic Spans Add custom spans for business-critical operations: ```typescript showLineNumbers title="src/services/article.ts" import { trace, SpanStatusCode } from '@opentelemetry/api'; import { db } from '../db/index.js'; import { articles, users } from '../db/schema.js'; const tracer = trace.getTracer('article-service'); export async function createArticle( authorId: number, input: { title: string; description?: string; body: string } ) { return tracer.startActiveSpan('article.create', async (span) => { try { span.setAttribute('user.id', authorId); const slug = generateSlug(input.title); const [newArticle] = await db .insert(articles) .values({ slug, title: input.title, description: input.description || null, body: input.body, authorId, }) .returning(); span.setAttribute('article.id', newArticle.id); span.setAttribute('article.slug', newArticle.slug); span.setStatus({ code: SpanStatusCode.OK }); // Enqueue background job (fire and forget) enqueueNotification(newArticle).catch((err) => { console.error('Failed to enqueue notification', err); }); return newArticle; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } }); } ``` #### External API Calls Instrument external service calls with error handling: ```typescript showLineNumbers title="src/services/external.ts" import { trace, SpanStatusCode, SpanKind } from '@opentelemetry/api'; const tracer = trace.getTracer('external-service'); export async function fetchExternalData(resourceId: string): Promise { return tracer.startActiveSpan( 'external.fetch', { kind: SpanKind.CLIENT }, async (span) => { try { span.setAttribute('external.resource_id', resourceId); span.setAttribute('http.url', `https://api.example.com/${resourceId}`); const response = await fetch( `https://api.example.com/resources/${resourceId}`, { headers: { Authorization: `Bearer ${process.env.API_TOKEN}` }, } ); span.setAttribute('http.status_code', response.status); if (!response.ok) { throw new Error(`External API error: ${response.status}`); } const data = await response.json(); span.setStatus({ code: SpanStatusCode.OK }); return data; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } } ); } ``` #### Background Job Tracing with BullMQ Propagate trace context to background workers: ```typescript showLineNumbers title="src/jobs/tasks/notification.ts" import { Queue } from 'bullmq'; import { context, propagation } from '@opentelemetry/api'; const notificationQueue = new Queue('notifications', { connection: { host: 'localhost', port: 6379 }, }); interface ArticleCreatedData { articleId: number; articleSlug: string; authorId: number; authorName: string; title: string; traceContext?: Record; } export async function enqueueArticleCreatedNotification( data: Omit ): Promise { // Capture current trace context const traceContext: Record = {}; propagation.inject(context.active(), traceContext); await notificationQueue.add('article-created', { ...data, traceContext, }); } ``` Process jobs with trace context restoration: ```typescript showLineNumbers title="src/jobs/worker.ts" import '../telemetry.js'; import { Worker, Job } from 'bullmq'; import { trace, context, propagation, SpanStatusCode } from '@opentelemetry/api'; const tracer = trace.getTracer('notification-worker'); const worker = new Worker( 'notifications', async (job) => { // Restore parent trace context const parentContext = job.data.traceContext ? propagation.extract(context.active(), job.data.traceContext) : context.active(); return context.with(parentContext, async () => { return tracer.startActiveSpan( `job.${job.name}`, { attributes: { 'job.id': job.id || 'unknown', 'job.name': job.name, 'job.queue': 'notifications', 'job.attempt': job.attemptsMade + 1, }, }, async (span) => { try { // Process the job await processJob(job); span.setStatus({ code: SpanStatusCode.OK }); } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } } ); }); }, { connection: { host: 'localhost', port: 6379 }, concurrency: 5 } ); ``` ### Running Your Application #### Development Mode Run with console output for debugging: ```bash showLineNumbers # Start the application npm run dev # In a separate terminal, start the worker npm run dev:worker ``` #### Production Mode ```bash showLineNumbers # Build npm run build # Start with environment variables NODE_ENV=production \ OTEL_SERVICE_NAME=fastify-api \ OTEL_EXPORTER_OTLP_ENDPOINT=http://collector:4318 \ node dist/index.js ``` #### Docker Deployment ```bash showLineNumbers # Build and run with Docker Compose docker compose up --build # View logs docker compose logs -f app worker # Stop services docker compose down ``` ### Troubleshooting #### Verification Test Test that instrumentation is working: ```typescript showLineNumbers title="scripts/verify-telemetry.ts" import { trace } from '@opentelemetry/api'; const tracer = trace.getTracer('verification'); async function verify() { const span = tracer.startSpan('verification.test'); span.setAttribute('test.attribute', 'value'); console.log('Trace ID:', span.spanContext().traceId); span.end(); } verify(); ``` #### Health Check Endpoint Implement a health check that includes telemetry status: ```typescript showLineNumbers title="src/routes/health.ts" import { FastifyPluginAsync } from 'fastify'; import { trace } from '@opentelemetry/api'; import { db } from '../db/index.js'; const healthRoutes: FastifyPluginAsync = async (fastify) => { fastify.get('/health', async () => { const span = trace.getActiveSpan(); const traceId = span?.spanContext()?.traceId; // Check database connectivity try { await db.execute('SELECT 1'); } catch (error) { return { status: 'unhealthy', database: 'disconnected', traceId, }; } return { status: 'healthy', database: 'connected', traceId, timestamp: new Date().toISOString(), }; }); }; export default healthRoutes; ``` #### Debug Mode Enable verbose OpenTelemetry logging: ```bash showLineNumbers # Enable debug logging OTEL_LOG_LEVEL=debug npm run dev ``` #### Common Issues ##### Issue: No traces appearing in Scout **Solutions:** 1. Verify collector connectivity: ```bash curl -f http://localhost:4318/v1/traces ``` 2. Check environment variables are set correctly 3. Ensure telemetry.ts is imported first in index.ts 4. Verify Scout credentials in collector config ##### Issue: Missing database spans **Solutions:** 1. Ensure `@opentelemetry/auto-instrumentations-node` is installed 2. Verify the pg driver is being used (not pg-native) 3. Check that telemetry initialization happens before database import ##### Issue: Background job traces not linked **Solutions:** 1. Verify trace context is being propagated to job data 2. Ensure worker imports telemetry.ts before other modules 3. Check that context.with() wraps the job processor ##### Issue: High memory usage **Solutions:** 1. Reduce batch size in exporter configuration 2. Enable sampling for high-traffic endpoints 3. Disable filesystem instrumentation ### Security Considerations #### Sensitive Data Protection Avoid capturing sensitive information in spans: ```typescript showLineNumbers title="src/services/auth.ts" // BAD: Captures password span.setAttribute('user.password', password); // GOOD: Only capture non-sensitive identifiers span.setAttribute('user.id', userId); span.setAttribute('user.email_domain', email.split('@')[1]); ``` #### SQL Query Obfuscation Configure database instrumentation to obfuscate queries: ```typescript showLineNumbers title="src/telemetry.ts" instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-pg': { enhancedDatabaseReporting: false, // Don't include query parameters }, }), ], ``` #### HTTP Header Filtering Filter sensitive headers from HTTP spans: ```typescript showLineNumbers title="src/telemetry.ts" instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { headersToSpanAttributes: { server: { requestHeaders: ['x-request-id', 'user-agent'], responseHeaders: ['x-request-id'], }, }, }, }), ], ``` #### Compliance Considerations For GDPR, HIPAA, or PCI-DSS compliance: - Never log PII (names, emails, addresses) in span attributes - Use pseudonymization for user identifiers when possible - Configure data retention policies in your observability backend - Implement attribute filtering at the collector level ### Performance Considerations #### Expected Impact | Metric | Typical Impact | High-Traffic Impact | | ------------- | -------------- | ------------------- | | Latency | +1-3ms | +2-5ms | | CPU overhead | 2-5% | 5-10% | | Memory | +50-100MB | +100-200MB | #### Impact Factors - Number of spans per request - Attribute count and size - Batch export frequency - Sampling configuration #### Optimization Best Practices ##### 1. Use Sampling in Production ```typescript showLineNumbers title="src/telemetry.ts" import { TraceIdRatioBasedSampler } from '@opentelemetry/sdk-trace-base'; const sdk = new NodeSDK({ sampler: new TraceIdRatioBasedSampler(0.1), // Sample 10% of traces // ... }); ``` ##### 2. Skip Non-Critical Endpoints ```typescript showLineNumbers '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const url = req.url || ''; return url === '/health' || url === '/metrics' || url === '/favicon.ico'; }, }, ``` ##### 3. Limit Attribute Sizes ```typescript showLineNumbers span.setAttribute('request.body', JSON.stringify(body).slice(0, 1000)); ``` ##### 4. Configure Batch Export ```typescript showLineNumbers import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; const batchProcessor = new BatchSpanProcessor(traceExporter, { maxQueueSize: 2048, maxExportBatchSize: 512, scheduledDelayMillis: 5000, exportTimeoutMillis: 30000, }); ``` ##### 5. Disable Unnecessary Instrumentations ```typescript showLineNumbers instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, }), ], ``` ### FAQ #### What is the performance impact of OpenTelemetry on Fastify? OpenTelemetry typically adds 1-3ms latency per request with 2-5% CPU overhead. For high-traffic applications, use sampling to reduce this impact. The BatchSpanProcessor helps minimize overhead by buffering spans and exporting them in batches. #### Which versions of Fastify are supported? OpenTelemetry instrumentation supports Fastify 3.x and later. This guide focuses on Fastify 5.x which provides improved hooks and TypeScript support. For older versions, the same instrumentation approach works with minor adjustments. #### How do I instrument Fastify with PostgreSQL and Drizzle ORM? PostgreSQL queries are automatically instrumented through the `pg` driver. Drizzle ORM uses `pg` under the hood, so all queries are captured as database spans. No additional configuration is needed beyond the standard auto-instrumentation setup. #### How do I reduce trace volume in production? Use sampling to capture a percentage of traces: ```typescript sampler: new TraceIdRatioBasedSampler(0.1) // 10% sampling ``` You can also exclude health checks and static assets from tracing using `ignoreIncomingRequestHook`. #### How do I handle multi-tenancy in traces? Add tenant context as span attributes: ```typescript span.setAttribute('tenant.id', request.headers['x-tenant-id']); span.setAttribute('tenant.name', tenantName); ``` This allows filtering traces by tenant in Scout Dashboard. #### What's the difference between traces and metrics? **Traces** capture the journey of individual requests through your system, showing timing and relationships between operations. Use traces for debugging specific requests and understanding request flow. **Metrics** are aggregated measurements over time (counters, gauges, histograms). Use metrics for dashboards, alerting, and capacity planning. #### How do I debug slow database queries with OpenTelemetry? Database spans include query timing and (optionally) the SQL statement. In Scout Dashboard, filter spans by `db.system = postgresql` and sort by duration to find slow queries. The span attributes include table names and operation types. #### How do I trace background jobs with BullMQ? Inject trace context when enqueuing jobs and extract it in the worker: ```typescript // Producer: inject context propagation.inject(context.active(), jobData.traceContext); // Consumer: extract and restore context const parentContext = propagation.extract(context.active(), job.data.traceContext); context.with(parentContext, () => { /* process job */ }); ``` #### Can I use OpenTelemetry with Fastify plugins? Yes, plugins are automatically instrumented as part of the request lifecycle. Custom plugin operations can be wrapped in spans using the tracer API for additional visibility. #### How do I correlate Pino logs with traces? Use `pino-opentelemetry-transport` to automatically inject trace IDs into log entries: ```typescript import pino from 'pino'; const logger = pino({ transport: { targets: [ { target: 'pino-opentelemetry-transport', level: 'info' }, { target: 'pino-pretty', level: 'debug' }, ], }, }); ``` #### How do I export metrics to Prometheus? OpenTelemetry metrics can be exported to Prometheus via the collector or directly using the Prometheus exporter. For Fastify applications, you can also expose a `/metrics` endpoint using `prom-client` alongside OpenTelemetry metrics. ### What's Next? #### Related Guides - [NestJS Instrumentation](./nestjs.md) - Structured framework built on Fastify - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerting for Fastify services - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development configuration - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment ### Complete Example #### Project Structure ```plain fastify-postgres/ ├── src/ │ ├── telemetry.ts # OpenTelemetry initialization (import first!) │ ├── index.ts # Application entry point │ ├── app.ts # Fastify app configuration │ ├── config/ │ │ └── index.ts # Environment configuration │ ├── db/ │ │ ├── index.ts # Database connection │ │ └── schema.ts # Drizzle schema │ ├── routes/ │ │ ├── health.ts # Health check endpoint │ │ ├── auth.ts # Authentication routes │ │ └── articles.ts # Article CRUD routes │ ├── services/ │ │ ├── article.ts # Article business logic │ │ └── redis.ts # Redis client │ └── jobs/ │ ├── queue.ts # BullMQ queue setup │ ├── worker.ts # Background worker │ └── tasks/ │ └── notification.ts ├── config/ │ └── otel-config.yaml # Collector configuration ├── compose.yml # Docker Compose ├── Dockerfile ├── package.json └── tsconfig.json ``` #### Dependencies ```json showLineNumbers title="package.json" { "name": "fastify-postgres", "version": "1.0.0", "type": "module", "engines": { "node": ">=24.0.0" }, "dependencies": { "@fastify/cors": "^11.2.0", "@fastify/helmet": "^13.0.2", "@fastify/jwt": "^10.0.0", "@fastify/rate-limit": "^10.3.0", "@opentelemetry/api": "^1.9.0", "@opentelemetry/auto-instrumentations-node": "^0.69.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.211.0", "@opentelemetry/exporter-trace-otlp-http": "^0.211.0", "@opentelemetry/resources": "^2.4.0", "@opentelemetry/sdk-metrics": "^2.4.0", "@opentelemetry/sdk-node": "^0.211.0", "@opentelemetry/semantic-conventions": "^1.39.0", "bullmq": "^5.66.7", "drizzle-orm": "^0.45.1", "fastify": "^5.7.1", "ioredis": "^5.9.2", "pg": "^8.17.2", "pino": "^10.3.0" }, "devDependencies": { "@types/node": "^24.0.0", "tsx": "^4.21.0", "typescript": "^5.9.3" } } ``` #### GitHub Repository For a complete working example, see the [Fastify PostgreSQL Example](https://github.com/base-14/examples/tree/main/nodejs/fastify-postgres) repository. ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [Fastify Documentation](https://fastify.dev/docs/latest/) - [OpenTelemetry Fastify Instrumentation](https://www.npmjs.com/package/@opentelemetry/instrumentation-fastify) - [BullMQ Documentation](https://docs.bullmq.io/) - [Drizzle ORM Documentation](https://orm.drizzle.team/) --- ## Flask OpenTelemetry Instrumentation - SQLAlchemy & Celery Tracing :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Flask is a lightweight WSGI web application framework designed to make getting started quick and easy, with the ability to scale up to complex applications. As a micro-framework, Flask provides the essentials for building web applications without imposing rigid structure, making it ideal for APIs, microservices, and rapid prototyping. Flask is a lightweight WSGI microframework. [Django](./django.md) is the batteries-included alternative, while [FastAPI](./fast-api.md) and [Litestar](./litestar.md) are modern async-first options. This guide demonstrates how to instrument Flask applications with OpenTelemetry for comprehensive distributed tracing, metrics collection, and application performance monitoring. We'll cover automatic instrumentation of Flask routes, SQLAlchemy queries, blueprint-based applications, and Celery background tasks—all while maintaining Flask's minimalist philosophy and flexibility. Unlike Django's batteries-included approach with automatic middleware injection, Flask instrumentation requires explicit initialization in your application factory or startup code. This manual approach provides fine-grained control over what gets traced and how, making it ideal for microservices architectures where minimal overhead is critical. We'll explore both automatic and custom instrumentation patterns, including Flask-specific considerations like request context propagation, blueprint isolation, and extension compatibility. :::tip TL;DR Initialize `FlaskInstrumentor` inside your `create_app()` factory, then instrument SQLAlchemy and Celery separately after each extension is initialized. Use the OTLP exporter to send spans to base14 Scout with no changes to your route logic. ::: ### Who This Guide Is For This guide is designed for: - **Flask Developers** building RESTful APIs and microservices requiring lightweight tracing with minimal performance overhead - **API Engineers** working with Flask-RESTful or Flask-RESTX and needing endpoint-level observability across distributed services - **Microservices Teams** deploying Flask applications in containers and requiring distributed tracing across service boundaries - **Backend Developers** using Flask with SQLAlchemy and needing query-level performance insights without ORM overhead - **Technical Leads** implementing observability in Flask applications using the application factory pattern and blueprints ### Overview This guide covers Flask OpenTelemetry instrumentation using the official OpenTelemetry Python SDK and Flask-specific auto-instrumentation packages. The approach leverages Flask's request hooks and context locals for comprehensive tracing. #### What You'll Learn - Installing and configuring OpenTelemetry SDK for Flask with automatic instrumentation - Instrumenting Flask routes and blueprints with minimal code changes - Tracing SQLAlchemy queries with full SQL visibility and parameter binding - Setting up application factory pattern with centralized tracing initialization - Implementing Celery distributed tracing for background tasks - Tracing Flask extensions (Flask-Login, Flask-JWT-Extended, Flask-CORS) - Managing request context propagation across blueprints and utilities - Detecting slow database queries and N+1 patterns using span attributes - Optimizing telemetry overhead for high-throughput Flask APIs - Deploying instrumented Flask apps with Gunicorn, uWSGI, or gevent workers #### Prerequisites **System Requirements:** - **Python:** 3.9+ (3.13+ recommended for latest features) - **Flask:** 2.0+ (3.0+ recommended) - **PostgreSQL:** 12+ (18+ recommended) or other supported databases - **Celery:** 5.0+ for background task tracing (optional) - **Redis:** 6.0+ for caching and Celery broker (optional) **Supported Flask Versions:** | Flask Version | Python Version | OpenTelemetry Support | Status | | ------------- | -------------- | --------------------- | ----------- | | 3.1+ | 3.9+ | ✅ Full | Recommended | | 3.0 | 3.8+ | ✅ Full | Current | | 2.3 | 3.8+ | ✅ Full | Supported | | 2.0-2.2 | 3.7+ | ✅ Full | Legacy | | 1.1 | 3.5+ | ⚠️ Limited | EOL | | 0.x | 2.7+ | ❌ Not supported | EOL | **Instrumented Components:** OpenTelemetry Flask instrumentation automatically traces: - ✅ **HTTP Requests** - All Flask routes and blueprints - ✅ **Database Queries** - SQLAlchemy ORM and Core queries - ✅ **Template Rendering** - Jinja2 template execution - ✅ **Cache Operations** - Redis and Memcached operations - ✅ **Celery Tasks** - Background task execution with distributed context - ✅ **HTTP Clients** - Requests library and httpx calls - ✅ **Extensions** - Flask-Login, Flask-JWT-Extended, Flask-CORS - ✅ **Before/After Request Hooks** - Flask request lifecycle - ✅ **Error Handlers** - Exception handling and error responses - ✅ **Blueprints** - Modular application components :::info Example Application This guide references the [flask-postgres example](https://github.com/base-14/examples/tree/main/python/flask-postgres) featuring: - **Framework**: Flask 3.1+ with application factory pattern - **Database**: PostgreSQL 18 with SQLAlchemy 2.0 - **Background Jobs**: Celery 5.4+ with Redis broker - **Features**: Blueprint-based architecture, JWT authentication, PII masking - **Deployment**: Gunicorn WSGI server with Docker and Kubernetes ::: ### Installation & Setup Flask OpenTelemetry instrumentation requires the core SDK and Flask-specific auto-instrumentation packages. The setup process installs dependencies and initializes tracing in your application factory. import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; **pip (Recommended)** Install OpenTelemetry SDK and Flask instrumentation: ```bash title="Terminal" showLineNumbers # Install core OpenTelemetry SDK pip install opentelemetry-api opentelemetry-sdk # Install Flask auto-instrumentation pip install opentelemetry-instrumentation-flask # Install SQLAlchemy instrumentation pip install opentelemetry-instrumentation-sqlalchemy # Install Celery instrumentation (optional) pip install opentelemetry-instrumentation-celery # Install Redis instrumentation (optional) pip install opentelemetry-instrumentation-redis # Install Requests instrumentation (optional) pip install opentelemetry-instrumentation-requests # Install OTLP exporter pip install opentelemetry-exporter-otlp # Freeze dependencies pip freeze > requirements.txt ``` **Poetry** Add dependencies to `pyproject.toml`: ```toml title="pyproject.toml" showLineNumbers [tool.poetry.dependencies] python = "^3.10" flask = "^3.1" sqlalchemy = "^2.0" psycopg2-binary = "^2.9" celery = "^5.4" redis = "^5.0" # OpenTelemetry dependencies opentelemetry-api = "^1.27" opentelemetry-sdk = "^1.27" opentelemetry-instrumentation-flask = "^0.48b0" opentelemetry-instrumentation-sqlalchemy = "^0.48b0" opentelemetry-instrumentation-celery = "^0.48b0" opentelemetry-instrumentation-redis = "^0.48b0" opentelemetry-instrumentation-requests = "^0.48b0" opentelemetry-exporter-otlp = "^1.27" ``` Install dependencies: ```bash poetry install ``` **Pipenv** Add to `Pipfile`: ```toml title="Pipfile" showLineNumbers [packages] flask = "~=3.1" sqlalchemy = "~=2.0" psycopg2-binary = "~=2.9" celery = "~=5.4" redis = "~=5.0" opentelemetry-api = "~=1.27" opentelemetry-sdk = "~=1.27" opentelemetry-instrumentation-flask = "~=0.48b0" opentelemetry-instrumentation-sqlalchemy = "~=0.48b0" opentelemetry-instrumentation-celery = "~=0.48b0" opentelemetry-instrumentation-redis = "~=0.48b0" opentelemetry-instrumentation-requests = "~=0.48b0" opentelemetry-exporter-otlp = "~=1.27" ``` Install: ```bash pipenv install ``` **Auto-Instrumentation Bootstrap** Use the OpenTelemetry bootstrap command: ```bash title="Terminal" showLineNumbers # Install bootstrap tool pip install opentelemetry-bootstrap # Auto-detect and install instrumentation opentelemetry-bootstrap -a install # This automatically installs: # - opentelemetry-instrumentation-flask # - opentelemetry-instrumentation-sqlalchemy # - opentelemetry-instrumentation-celery # - opentelemetry-instrumentation-redis # (based on detected packages) ``` :::tip Flask Application Factory Pattern Flask best practices recommend using the application factory pattern for scalability and testing. This guide demonstrates tracing initialization within the factory function for centralized configuration. ::: ### Configuration Flask OpenTelemetry configuration involves initializing the SDK and instrumenting your Flask application instance. Unlike Django, Flask requires explicit instrumentation calls. #### Application Factory with Tracing Create an application factory with integrated tracing: ```python title="app/__init__.py" showLineNumbers """Flask application factory with OpenTelemetry tracing.""" import os from flask import Flask from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.exporter.otlp.proto.grpc.trace_exporter import OTLPSpanExporter from opentelemetry.sdk.resources import Resource from opentelemetry.instrumentation.flask import FlaskInstrumentor from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor from opentelemetry.instrumentation.redis import RedisInstrumentor def create_app(config_name='default'): """Create and configure Flask application with tracing.""" app = Flask(__name__) # Load configuration app.config.from_object(f'config.{config_name.capitalize()}Config') # Initialize OpenTelemetry initialize_tracing(app) # Initialize extensions from app.extensions import db, migrate, redis_client db.init_app(app) migrate.init_app(app, db) # Register blueprints from app.routes.orders import orders_bp from app.routes.health import health_bp app.register_blueprint(orders_bp, url_prefix='/api/orders') app.register_blueprint(health_bp, url_prefix='/health') return app def initialize_tracing(app): """Initialize OpenTelemetry tracing for Flask application.""" # Create resource with service information resource = Resource.create({ "service.name": os.getenv("OTEL_SERVICE_NAME", "flask-order-service"), "service.version": os.getenv("APP_VERSION", "1.0.0"), "deployment.environment.name": os.getenv("ENVIRONMENT", "development"), "environment": os.getenv("ENVIRONMENT", "development"), }) # Create tracer provider provider = TracerProvider(resource=resource) # Configure OTLP exporter otlp_exporter = OTLPSpanExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4317"), insecure=os.getenv("OTEL_EXPORTER_OTLP_INSECURE", "true") == "true", ) # Add batch span processor provider.add_span_processor(BatchSpanProcessor(otlp_exporter)) # Set as global tracer provider trace.set_tracer_provider(provider) # Instrument Flask application FlaskInstrumentor().instrument_app(app) # Instrument SQLAlchemy from app.extensions import db SQLAlchemyInstrumentor().instrument( engine=db.engine, enable_commenter=True, ) # Instrument Redis RedisInstrumentor().instrument() app.logger.info(f"OpenTelemetry initialized: {resource.attributes.get('service.name')}") ``` #### Configuration Classes ```python title="config.py" showLineNumbers """Flask configuration classes.""" import os from datetime import timedelta class Config: """Base configuration.""" SECRET_KEY = os.getenv('SECRET_KEY', 'dev-secret-change-in-production') # Database SQLALCHEMY_DATABASE_URI = os.getenv( 'DATABASE_URL', 'postgresql://postgres:postgres@localhost:5432/orders' ) SQLALCHEMY_TRACK_MODIFICATIONS = False SQLALCHEMY_ECHO = os.getenv('SQLALCHEMY_ECHO', 'False') == 'True' # Redis REDIS_URL = os.getenv('REDIS_URL', 'redis://localhost:6379/0') # Celery CELERY_BROKER_URL = os.getenv('CELERY_BROKER_URL', 'redis://localhost:6379/0') CELERY_RESULT_BACKEND = os.getenv('CELERY_RESULT_BACKEND', 'redis://localhost:6379/0') # OpenTelemetry OTEL_SERVICE_NAME = os.getenv('OTEL_SERVICE_NAME', 'flask-order-service') OTEL_EXPORTER_OTLP_ENDPOINT = os.getenv('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4317') class DevelopmentConfig(Config): """Development configuration.""" DEBUG = True SQLALCHEMY_ECHO = True class ProductionConfig(Config): """Production configuration.""" DEBUG = False SQLALCHEMY_ECHO = False # Production-specific settings SQLALCHEMY_POOL_SIZE = 20 SQLALCHEMY_POOL_RECYCLE = 3600 class TestingConfig(Config): """Testing configuration.""" TESTING = True SQLALCHEMY_DATABASE_URI = 'sqlite:///:memory:' OTEL_SDK_DISABLED = True # Disable tracing in tests config = { 'development': DevelopmentConfig, 'production': ProductionConfig, 'testing': TestingConfig, 'default': DevelopmentConfig } ``` #### Environment Variables ```bash title=".env" showLineNumbers # Flask configuration FLASK_APP=wsgi.py FLASK_ENV=development SECRET_KEY=your-secret-key-here # Database DATABASE_URL=postgresql://postgres:postgres@localhost:5432/orders SQLALCHEMY_ECHO=False # Redis REDIS_URL=redis://localhost:6379/0 # Celery CELERY_BROKER_URL=redis://localhost:6379/0 CELERY_RESULT_BACKEND=redis://localhost:6379/0 # OpenTelemetry OTEL_SERVICE_NAME=flask-order-service OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 OTEL_EXPORTER_OTLP_INSECURE=true OTEL_SEMCONV_STABILITY_OPT_IN=http,database APP_VERSION=1.0.0 ENVIRONMENT=development ``` `OTEL_SEMCONV_STABILITY_OPT_IN=http,database` opts the instrumentation into the stable HTTP and database semantic conventions (for example `http.request.method`, `http.response.status_code`, and `db.query.text`). Without it, the instrumentation keeps emitting the older experimental attribute names (`http.method`, `http.status_code`, `db.statement`). Use `http/dup` and `database/dup` instead to emit both old and new during a migration. #### WSGI Entry Point ```python title="wsgi.py" showLineNumbers """WSGI entry point for Flask application.""" import os from app import create_app # Create application instance config_name = os.getenv('FLASK_ENV', 'development') app = create_app(config_name) if __name__ == '__main__': # Development server with auto-reload app.run( host='0.0.0.0', port=int(os.getenv('PORT', 5000)), debug=os.getenv('DEBUG', 'True') == 'True' ) ``` #### Docker Compose Configuration ```yaml title="docker-compose.yml" showLineNumbers version: '3.9' services: flask-app: build: . command: gunicorn wsgi:app --bind 0.0.0.0:5000 --workers 4 ports: - '5000:5000' environment: FLASK_ENV: production OTEL_SERVICE_NAME: flask-order-service OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4317 DATABASE_URL: postgresql://flask:flask123@postgres:5432/orders REDIS_URL: redis://redis:6379/0 CELERY_BROKER_URL: redis://redis:6379/0 depends_on: - postgres - redis - scout-collector celery-worker: build: . command: celery -A app.celery_app worker --loglevel=info environment: FLASK_ENV: production OTEL_SERVICE_NAME: flask-celery-worker OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4317 DATABASE_URL: postgresql://flask:flask123@postgres:5432/orders REDIS_URL: redis://redis:6379/0 CELERY_BROKER_URL: redis://redis:6379/0 depends_on: - postgres - redis - scout-collector postgres: image: postgres:18-alpine environment: POSTGRES_DB: orders POSTGRES_USER: flask POSTGRES_PASSWORD: flask123 volumes: - postgres_data:/var/lib/postgresql/data ports: - '5432:5432' redis: image: redis:7-alpine ports: - '6379:6379' scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4317:4317' volumes: postgres_data: ``` :::info Scout Integration When using [Base14 Scout](https://base14.io/scout), configure the OTLP endpoint to point to your Scout Collector with authentication headers. Scout provides managed infrastructure optimized for Flask microservices. ::: ### Traces Traces follow a request through your Flask application, from the incoming route, through view functions and blueprints, into SQLAlchemy queries, Redis calls, and Celery task dispatch, and back out as the response. #### Automatic Trace Collection Once `FlaskInstrumentor` (plus the SQLAlchemy, Redis, and Celery instrumentors) is applied, every request is traced with no per-view code. Outbound HTTP calls need their own instrumentor (`RequestsInstrumentor` / `URLLib3Instrumentor`): **Captured Information:** - HTTP method, route rule, and status code for each view - Request duration and a span-by-span timing breakdown - SQLAlchemy queries, including the executed SQL (`SQLAlchemyInstrumentor`) - Redis commands (`RedisInstrumentor`) - Celery task enqueue and execution spans (`CeleryInstrumentor`) - Exceptions recorded on the failing span with stack traces - Distributed context propagation across services (W3C Trace Context) **Trace Hierarchy:** ```text HTTP Request Span (root: GET /api/orders/) ├── orders.get_order Span │ ├── SQLAlchemy Query Span (SELECT ... FROM orders) │ └── Redis GET Span (cache lookup) └── Celery Enqueue Span (send_receipt task) ``` #### Key Tracing Features - **Automatic HTTP tracking**: every route is traced with no code changes - **SQLAlchemy visibility**: ORM and Core queries appear as child spans with the executed SQL - **Error capturing**: unhandled exceptions and error handlers are recorded with full stack traces - **Context propagation**: distributed traces follow requests across HTTP and Celery boundaries - **Blueprint support**: views registered on blueprints are traced with their resolved route rule > View traces in your base14 Scout dashboard to follow request flows and find > the slow span in a chain. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics Metrics aggregate runtime measurements over time, such as request rate, latency distributions, and error counts. Where traces explain a single request, metrics power dashboards and alerts across all of them. #### Enable the Meter Provider Configure a `MeterProvider` with an OTLP exporter alongside your tracer setup so metrics are exported to Scout: ```python title="app/telemetry.py" showLineNumbers import os from opentelemetry import metrics from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.sdk.resources import Resource from opentelemetry.exporter.otlp.proto.grpc.metric_exporter import ( OTLPMetricExporter, ) # Same OTLP endpoint and gRPC transport as the tracer setup above resource = Resource.create( {"service.name": os.getenv("OTEL_SERVICE_NAME", "flask-order-service")} ) reader = PeriodicExportingMetricReader( OTLPMetricExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4317"), insecure=os.getenv("OTEL_EXPORTER_OTLP_INSECURE", "true") == "true", ), export_interval_millis=15000, ) metrics.set_meter_provider(MeterProvider(resource=resource, metric_readers=[reader])) ``` #### Custom Business Metrics Flask auto-instrumentation already emits the standard HTTP server metrics, including the `http.server.request.duration` histogram (its sample count gives you request rate, latency percentiles, and error ratio per route), so there is no need to hand-roll request latency. Reserve custom metrics for business events the instrumentation cannot see, such as domain actions: ```python title="app/routes/articles.py" showLineNumbers from opentelemetry import metrics meter = metrics.get_meter("flask-app") articles_created = meter.create_counter( "articles.created", unit="1", description="Articles created", ) # Inside the view, after the article is persisted: articles_created.add(1, {"author_id": str(g.current_user.id)}) ``` > View metrics in your base14 Scout dashboard to chart request rate, latency > percentiles, and error ratio per route from the automatic HTTP histogram, > alongside your custom business counters. ##### Reference [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) ### Production Configuration Production deployments require optimized sampling, secure credential management, and performance tuning for high-traffic Flask APIs. #### Production Tracing Initialization ```python title="app/__init__.py" showLineNumbers """Production-optimized Flask tracing configuration.""" import os from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor from opentelemetry.sdk.trace.sampling import TraceIdRatioBased, ParentBased from opentelemetry.exporter.otlp.proto.grpc.trace_exporter import OTLPSpanExporter from opentelemetry.sdk.resources import Resource from opentelemetry.instrumentation.flask import FlaskInstrumentor from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor from opentelemetry.instrumentation.redis import RedisInstrumentor from opentelemetry.instrumentation.requests import RequestsInstrumentor def initialize_production_tracing(app): """Initialize production-grade OpenTelemetry tracing.""" # Create resource with comprehensive metadata resource = Resource.create({ "service.name": os.getenv("OTEL_SERVICE_NAME", "flask-order-service"), "service.version": os.getenv("APP_VERSION", "1.0.0"), "deployment.environment.name": os.getenv("ENVIRONMENT", "development"), "environment": os.getenv("ENVIRONMENT", "development"), "cloud.provider": os.getenv("CLOUD_PROVIDER", "aws"), "cloud.region": os.getenv("AWS_REGION", "us-east-1"), "k8s.cluster.name": os.getenv("K8S_CLUSTER", "production"), "k8s.namespace.name": os.getenv("K8S_NAMESPACE", "default"), "k8s.pod.name": os.getenv("HOSTNAME", "unknown"), }) # Configure sampling (10% in production) sample_rate = float(os.getenv("OTEL_TRACE_SAMPLE_RATE", "0.1")) sampler = ParentBased(root=TraceIdRatioBased(sample_rate)) # Create tracer provider with sampler provider = TracerProvider(resource=resource, sampler=sampler) # Configure OTLP exporter with authentication otlp_exporter = OTLPSpanExporter( endpoint=os.getenv("OTEL_EXPORTER_OTLP_ENDPOINT", "https://scout.base14.io:4317"), headers={ "authorization": f"Bearer {os.getenv('SCOUT_API_KEY', '')}", }, insecure=False, ) # Configure batch span processor with production settings batch_processor = BatchSpanProcessor( otlp_exporter, max_queue_size=2048, max_export_batch_size=512, schedule_delay_millis=5000, export_timeout_millis=30000, ) provider.add_span_processor(batch_processor) trace.set_tracer_provider(provider) # Instrument Flask with excluded paths FlaskInstrumentor().instrument_app( app, excluded_urls="health,readiness,metrics,favicon.ico" ) # Instrument SQLAlchemy with query commenter from app.extensions import db SQLAlchemyInstrumentor().instrument( engine=db.engine, enable_commenter=True, commenter_options={ "db_driver": True, "db_framework": True, } ) # Instrument external HTTP calls RequestsInstrumentor().instrument() # Instrument Redis RedisInstrumentor().instrument() app.logger.info( f"OpenTelemetry initialized: {resource.attributes.get('service.name')} " f"v{resource.attributes.get('service.version')} (sample rate: {sample_rate})" ) ``` #### Gunicorn Production Configuration ```python title="gunicorn.conf.py" showLineNumbers """Gunicorn configuration for production Flask deployment.""" import multiprocessing import os # Server socket bind = "0.0.0.0:5000" backlog = 2048 # Worker processes workers = int(os.getenv("GUNICORN_WORKERS", multiprocessing.cpu_count() * 2 + 1)) worker_class = "sync" # Or "gevent" for async workers worker_connections = 1000 max_requests = 1000 max_requests_jitter = 50 timeout = 30 keepalive = 5 # Logging accesslog = "-" errorlog = "-" loglevel = os.getenv("LOG_LEVEL", "info") access_log_format = '%(h)s %(l)s %(u)s %(t)s "%(r)s" %(s)s %(b)s "%(f)s" "%(a)s"' # Process naming proc_name = "flask-order-service" # Server hooks def on_starting(server): """Server starting hook.""" print("Gunicorn server starting with OpenTelemetry tracing enabled") def post_worker_init(worker): """Worker initialization hook.""" print(f"Worker {worker.pid} initialized") ``` #### Dockerfile (Multi-Stage Build) ```dockerfile title="Dockerfile" showLineNumbers # Stage 1: Build dependencies FROM python:3.13-slim AS builder WORKDIR /app # Install system dependencies RUN apt-get update && apt-get install -y \ gcc \ postgresql-client \ libpq-dev \ && rm -rf /var/lib/apt/lists/* # Copy requirements and install COPY requirements.txt . RUN pip wheel --no-cache-dir --no-deps --wheel-dir /app/wheels -r requirements.txt # Stage 2: Runtime image FROM python:3.13-slim WORKDIR /app # Install runtime dependencies RUN apt-get update && apt-get install -y \ libpq5 \ && rm -rf /var/lib/apt/lists/* # Copy wheels from builder COPY --from=builder /app/wheels /wheels COPY --from=builder /app/requirements.txt . # Install Python packages RUN pip install --no-cache /wheels/* # Copy application code COPY . . # Create non-root user RUN useradd -m -u 1000 flask && chown -R flask:flask /app USER flask # Environment variables ENV PYTHONUNBUFFERED=1 ENV FLASK_APP=wsgi.py # Expose port EXPOSE 5000 # Health check HEALTHCHECK --interval=30s --timeout=3s --start-period=40s --retries=3 \ CMD python -c "import requests; requests.get('http://localhost:5000/health/')" # Run Gunicorn CMD ["gunicorn", "wsgi:app", "--config", "gunicorn.conf.py"] ``` #### Kubernetes Deployment ```yaml title="k8s/deployment.yaml" showLineNumbers apiVersion: apps/v1 kind: Deployment metadata: name: flask-order-service labels: app: flask-order-service spec: replicas: 3 selector: matchLabels: app: flask-order-service template: metadata: labels: app: flask-order-service spec: containers: - name: flask-app image: flask-order-service:latest ports: - containerPort: 5000 name: http env: - name: FLASK_ENV value: production - name: OTEL_SERVICE_NAME value: flask-order-service - name: OTEL_EXPORTER_OTLP_ENDPOINT value: http://scout-collector:4317 - name: SCOUT_API_KEY valueFrom: secretKeyRef: name: scout-credentials key: api-key - name: OTEL_TRACE_SAMPLE_RATE value: '0.1' - name: ENVIRONMENT value: demo - name: APP_VERSION value: '1.0.0' - name: DATABASE_URL valueFrom: secretKeyRef: name: postgres-credentials key: connection-string - name: REDIS_URL value: redis://redis-service:6379/0 resources: requests: memory: '256Mi' cpu: '250m' limits: memory: '512Mi' cpu: '500m' livenessProbe: httpGet: path: /health/ port: 5000 initialDelaySeconds: 30 periodSeconds: 10 readinessProbe: httpGet: path: /health/ready port: 5000 initialDelaySeconds: 10 periodSeconds: 5 --- apiVersion: v1 kind: Service metadata: name: flask-order-service spec: selector: app: flask-order-service ports: - protocol: TCP port: 80 targetPort: 5000 type: ClusterIP ``` ### Flask-Specific Features Flask's auto-instrumentation automatically captures routes, database queries, and template rendering. The minimalist design allows fine-grained control over what gets traced. #### Route Auto-Instrumentation All Flask routes are automatically instrumented: ```python title="app/routes/orders.py" showLineNumbers """Flask routes with automatic tracing.""" from flask import Blueprint, request, jsonify from opentelemetry import trace from app.models import Order, db from app.tasks import process_order orders_bp = Blueprint('orders', __name__) tracer = trace.get_tracer(__name__) # Function-based route (automatically traced) # Span name: "GET /api/orders/" @orders_bp.route('/', methods=['GET']) def get_orders(): """Get all orders - automatically creates span.""" orders = Order.query.all() return jsonify([order.to_dict() for order in orders]) # Route with parameter (automatically traced) # Span name: "GET /api/orders/" @orders_bp.route('/', methods=['GET']) def get_order(order_id): """Get order by ID.""" order = Order.query.get_or_404(order_id) return jsonify(order.to_dict()) # POST route with request body # Span name: "POST /api/orders/" @orders_bp.route('/', methods=['POST']) def create_order(): """Create new order.""" data = request.get_json() # Database insert automatically traced order = Order( product_name=data['product_name'], amount=data['amount'], status='pending' ) db.session.add(order) db.session.commit() # Trigger background task (traced separately) process_order.delay(order.id) return jsonify(order.to_dict()), 201 # Error handling (automatically traced) @orders_bp.route('/', methods=['DELETE']) def delete_order(order_id): """Delete order.""" order = Order.query.get_or_404(order_id) db.session.delete(order) db.session.commit() return '', 204 # Custom span with manual instrumentation @orders_bp.route('/analytics', methods=['GET']) def get_analytics(): """Get order analytics with custom span.""" with tracer.start_as_current_span("calculate_analytics") as span: total_orders = Order.query.count() pending_orders = Order.query.filter_by(status='pending').count() span.set_attribute("analytics.total_orders", total_orders) span.set_attribute("analytics.pending_orders", pending_orders) return jsonify({ "total_orders": total_orders, "pending_orders": pending_orders }) ``` #### Blueprint-Based Architecture Flask blueprints are automatically instrumented: ```python title="app/routes/health.py" showLineNumbers """Health check blueprint.""" from flask import Blueprint, jsonify from app.extensions import db, redis_client health_bp = Blueprint('health', __name__) @health_bp.route('/', methods=['GET']) def health(): """Basic health check - excluded from tracing via config.""" return jsonify({"status": "healthy"}) @health_bp.route('/ready', methods=['GET']) def readiness(): """Readiness check with dependencies.""" try: # Check database connection db.session.execute('SELECT 1') # Check Redis connection redis_client.ping() return jsonify({"status": "ready"}) except Exception as e: return jsonify({"status": "not ready", "error": str(e)}), 503 ``` #### SQLAlchemy Query Instrumentation Database queries are automatically traced: ```python title="app/models.py" showLineNumbers """SQLAlchemy models with automatic query tracing.""" from datetime import datetime from app.extensions import db class Order(db.Model): """Order model - all queries automatically traced.""" __tablename__ = 'orders' id = db.Column(db.Integer, primary_key=True) product_name = db.Column(db.String(200), nullable=False) amount = db.Column(db.Numeric(10, 2), nullable=False) status = db.Column(db.String(50), default='pending') created_at = db.Column(db.DateTime, default=datetime.utcnow) updated_at = db.Column(db.DateTime, default=datetime.utcnow, onupdate=datetime.utcnow) def to_dict(self): """Convert to dictionary.""" return { 'id': self.id, 'product_name': self.product_name, 'amount': float(self.amount), 'status': self.status, 'created_at': self.created_at.isoformat(), 'updated_at': self.updated_at.isoformat() } @classmethod def get_by_status(cls, status): """Get orders by status - traced as SELECT query.""" return cls.query.filter_by(status=status).all() @classmethod def get_recent(cls, limit=10): """Get recent orders - traced with ORDER BY and LIMIT.""" return cls.query.order_by(cls.created_at.desc()).limit(limit).all() class OrderService: """Business logic with automatic query tracing.""" @staticmethod def create_order_with_validation(data): """Create order with validation.""" # All database operations traced automatically order = Order( product_name=data['product_name'], amount=data['amount'], status='pending' ) db.session.add(order) db.session.commit() return order @staticmethod def get_order_analytics(): """Complex aggregation query - automatically traced.""" from sqlalchemy import func result = db.session.query( Order.status, func.count(Order.id).label('count'), func.sum(Order.amount).label('total') ).group_by(Order.status).all() return [ { 'status': row.status, 'count': row.count, 'total': float(row.total or 0) } for row in result ] ``` #### Before/After Request Hooks Flask request hooks are automatically traced: ```python title="app/__init__.py" showLineNumbers """Flask hooks with custom attributes.""" from flask import request from opentelemetry import trace def register_hooks(app): """Register Flask request hooks with tracing.""" @app.before_request def before_request(): """Before request hook - adds custom attributes.""" # Get current span and add custom attributes current_span = trace.get_current_span() current_span.set_attribute("user_agent.original", request.user_agent.string) current_span.set_attribute("http.request.method", request.method) current_span.set_attribute("url.path", request.path) if request.is_json: current_span.set_attribute("http.request.content_type", "application/json") @app.after_request def after_request(response): """After request hook - records response details.""" current_span = trace.get_current_span() # Record response attributes current_span.set_attribute("http.response.status_code", response.status_code) current_span.set_attribute("http.response.body.size", response.content_length or 0) return response @app.errorhandler(Exception) def handle_exception(e): """Global error handler - records exceptions in span.""" current_span = trace.get_current_span() current_span.record_exception(e) current_span.set_status(trace.Status(trace.StatusCode.ERROR, str(e))) return jsonify({"error": str(e)}), 500 ``` #### Celery Task Tracing Celery tasks with distributed context propagation: ```python title="app/celery_app.py" showLineNumbers """Celery configuration with OpenTelemetry.""" import os from celery import Celery from celery.signals import worker_process_init from opentelemetry.instrumentation.celery import CeleryInstrumentor def make_celery(app): """Create Celery instance with Flask app context.""" celery = Celery( app.import_name, broker=app.config['CELERY_BROKER_URL'], backend=app.config['CELERY_RESULT_BACKEND'] ) celery.conf.update(app.config) # Ensure Flask app context in tasks class ContextTask(celery.Task): def __call__(self, *args, **kwargs): with app.app_context(): return self.run(*args, **kwargs) celery.Task = ContextTask return celery @worker_process_init.connect def init_celery_tracing(**kwargs): """Initialize tracing in Celery worker process.""" from app import create_app app = create_app('production') # Instrument Celery tasks CeleryInstrumentor().instrument() print("OpenTelemetry initialized in Celery worker") ``` ```python title="app/tasks.py" showLineNumbers """Celery tasks with automatic tracing.""" from app.celery_app import make_celery from app import create_app from opentelemetry import trace app = create_app() celery = make_celery(app) tracer = trace.get_tracer(__name__) @celery.task def process_order(order_id): """ Process order asynchronously. Automatically creates span: 'app.tasks.process_order' """ from app.models import Order, db # Current span linked to original request current_span = trace.get_current_span() current_span.set_attribute("order.id", order_id) # Query automatically traced order = Order.query.get(order_id) if order.amount > 1000: # Custom validation span with tracer.start_as_current_span("validate_high_value_order") as span: span.set_attribute("order.amount", float(order.amount)) # Validation logic pass # Update status (UPDATE query traced) order.status = 'processing' db.session.commit() return {"order_id": order_id, "status": "processed"} ``` ### Custom Instrumentation While Flask auto-instrumentation covers most use cases, custom spans are needed for specific business logic. #### Manual Span Creation ```python title="app/services/payment.py" showLineNumbers """Payment service with custom instrumentation.""" from opentelemetry import trace from opentelemetry.trace import Status, StatusCode import requests tracer = trace.get_tracer(__name__) class PaymentService: """Payment processing with custom spans.""" @staticmethod def process_payment(order_id, amount, method): """Process payment with detailed tracing.""" with tracer.start_as_current_span("process_payment") as span: span.set_attribute("order.id", order_id) span.set_attribute("payment.amount", float(amount)) span.set_attribute("payment.method", method) try: # Validate payment method PaymentService._validate_method(method) # Call external gateway transaction_id = PaymentService._charge_gateway(amount, method) span.set_attribute("payment.transaction_id", transaction_id) span.set_status(Status(StatusCode.OK)) return { "success": True, "transaction_id": transaction_id } except Exception as e: span.set_status(Status(StatusCode.ERROR, str(e))) span.record_exception(e) raise @staticmethod def _validate_method(method): """Validate payment method.""" with tracer.start_as_current_span("validate_payment_method") as span: span.set_attribute("payment.method", method) valid_methods = ["credit_card", "debit_card", "paypal"] if method not in valid_methods: span.set_status(Status(StatusCode.ERROR, "Invalid method")) raise ValueError(f"Invalid payment method: {method}") @staticmethod def _charge_gateway(amount, method): """Charge payment gateway - external API call.""" with tracer.start_as_current_span( "payment_gateway.charge", kind=trace.SpanKind.CLIENT ) as span: span.set_attribute("payment.gateway", "stripe") span.set_attribute("payment.amount", float(amount)) # External HTTP call (auto-instrumented by requests library) response = requests.post( "https://api.stripe.com/v1/charges", json={"amount": float(amount), "method": method}, timeout=10 ) span.set_attribute("http.response.status_code", response.status_code) if response.status_code == 200: transaction_id = response.json().get("id") span.set_attribute("payment.transaction_id", transaction_id) return transaction_id else: span.set_status(Status(StatusCode.ERROR, "Payment failed")) raise Exception("Payment gateway error") ``` #### Context Manager for Business Logic ```python title="app/utils/tracing.py" showLineNumbers """Custom tracing utilities.""" from opentelemetry import trace from functools import wraps import time tracer = trace.get_tracer(__name__) def trace_function(name=None): """Decorator to automatically trace function execution.""" def decorator(func): @wraps(func) def wrapper(*args, **kwargs): span_name = name or f"{func.__module__}.{func.__name__}" with tracer.start_as_current_span(span_name) as span: # Add function metadata span.set_attribute("function.name", func.__name__) span.set_attribute("function.module", func.__module__) # Record arguments (be careful with PII!) if kwargs: span.set_attribute("function.kwargs_count", len(kwargs)) start_time = time.time() try: result = func(*args, **kwargs) duration_ms = (time.time() - start_time) * 1000 span.set_attribute("function.duration_ms", duration_ms) return result except Exception as e: span.record_exception(e) span.set_status(trace.Status(trace.StatusCode.ERROR, str(e))) raise return wrapper return decorator # Usage @trace_function("calculate_order_total") def calculate_total(order_items): """Calculate order total - automatically traced.""" return sum(item['price'] * item['quantity'] for item in order_items) ``` #### Flask Extension Instrumentation ```python title="app/extensions.py" showLineNumbers """Flask extensions with tracing integration.""" from flask_sqlalchemy import SQLAlchemy from flask_migrate import Migrate from flask_redis import FlaskRedis from opentelemetry import trace db = SQLAlchemy() migrate = Migrate() redis_client = FlaskRedis() tracer = trace.get_tracer(__name__) def init_extensions(app): """Initialize Flask extensions with tracing.""" db.init_app(app) migrate.init_app(app, db) redis_client.init_app(app) # Add custom event listeners for database operations @event.listens_for(db.engine, "before_cursor_execute") def before_cursor_execute(conn, cursor, statement, parameters, context, executemany): """Log SQL queries in current span.""" current_span = trace.get_current_span() current_span.add_event("sql_query_start", { "db.query.text": statement[:100], # Truncate long queries }) app.logger.info("Extensions initialized with OpenTelemetry tracing") ``` ### Running Your Application Flask applications can run with various WSGI servers. OpenTelemetry instrumentation works with all standard deployment methods. #### Development Server ```bash title="Terminal" showLineNumbers # Run Flask development server export FLASK_APP=wsgi.py export FLASK_ENV=development flask run --host=0.0.0.0 --port=5000 # Or using Python directly python wsgi.py # Run Celery worker (separate terminal) celery -A app.celery_app worker --loglevel=info # Test endpoints curl http://localhost:5000/api/orders/ curl -X POST http://localhost:5000/api/orders/ \ -H "Content-Type: application/json" \ -d '{"product_name":"Widget","amount":"99.99"}' ``` #### Gunicorn (Production) ```bash title="Terminal" showLineNumbers # Run with Gunicorn gunicorn wsgi:app --bind 0.0.0.0:5000 --workers 4 # With configuration file gunicorn wsgi:app --config gunicorn.conf.py # With environment variables OTEL_SERVICE_NAME=flask-order-service \ OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 \ SCOUT_API_KEY=your_api_key \ gunicorn wsgi:app --bind 0.0.0.0:5000 ``` #### uWSGI ```ini title="uwsgi.ini" showLineNumbers [uwsgi] module = wsgi:app master = true processes = 4 socket = /tmp/flask-app.sock chmod-socket = 666 vacuum = true die-on-term = true # OpenTelemetry environment env = OTEL_SERVICE_NAME=flask-order-service env = OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 ``` Run: ```bash uwsgi --ini uwsgi.ini ``` #### Docker Deployment ```bash title="Terminal" showLineNumbers # Build Docker image docker build -t flask-order-service:latest . # Run container docker run -p 5000:5000 \ -e OTEL_SERVICE_NAME=flask-order-service \ -e OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 \ -e SCOUT_API_KEY=your_api_key \ flask-order-service:latest # Run with Docker Compose docker-compose up -d # Check logs docker-compose logs -f flask-app # Run database migrations docker-compose exec flask-app flask db upgrade ``` #### Kubernetes Deployment ```bash title="Terminal" showLineNumbers # Deploy to Kubernetes kubectl apply -f k8s/deployment.yaml # Check pod status kubectl get pods -l app=flask-order-service # View logs kubectl logs -f deployment/flask-order-service # Run migrations kubectl run flask-migrate --rm -i --tty \ --image=flask-order-service:latest \ --restart=Never \ --command -- flask db upgrade # Port forward for testing kubectl port-forward deployment/flask-order-service 5000:5000 curl http://localhost:5000/api/orders/ ``` ### Troubleshooting #### Issue 1: No Traces Generated **Symptoms:** Flask application starts but no traces appear in collector. **Solution:** Ensure instrumentation is called on the Flask app instance: ```python # INCORRECT: Instrumenting before app creation from opentelemetry.instrumentation.flask import FlaskInstrumentor FlaskInstrumentor().instrument() # No app provided! from flask import Flask app = Flask(__name__) # CORRECT: Instrument specific app instance from flask import Flask app = Flask(__name__) from opentelemetry.instrumentation.flask import FlaskInstrumentor FlaskInstrumentor().instrument_app(app) # Instrument this specific app ``` #### Issue 2: SQLAlchemy Queries Not Traced **Symptoms:** HTTP requests create spans but database queries are missing. **Solution:** Instrument SQLAlchemy engine after database initialization: ```python from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor # Initialize database from app.extensions import db db.init_app(app) # IMPORTANT: Instrument engine after init_app SQLAlchemyInstrumentor().instrument( engine=db.engine, enable_commenter=True ) ``` #### Issue 3: Blueprint Routes Not Traced **Symptoms:** Some routes traced, blueprint routes missing. **Solution:** Register blueprints before instrumenting Flask app: ```python # INCORRECT order FlaskInstrumentor().instrument_app(app) app.register_blueprint(orders_bp) # Too late! # CORRECT order app.register_blueprint(orders_bp) app.register_blueprint(health_bp) FlaskInstrumentor().instrument_app(app) # Instrument after blueprints ``` #### Issue 4: Celery Tasks Not Linked to Requests **Symptoms:** Celery task spans exist but disconnected from originating request. **Solution:** Initialize Celery instrumentation in worker process: ```python from celery.signals import worker_process_init from opentelemetry.instrumentation.celery import CeleryInstrumentor @worker_process_init.connect def init_celery_tracing(**kwargs): """Initialize in each worker process.""" # Initialize OpenTelemetry from app import initialize_tracing app = create_app() initialize_tracing(app) # Instrument Celery CeleryInstrumentor().instrument() ``` #### Issue 5: High Memory Usage **Symptoms:** Flask application memory grows continuously. **Solution:** Configure batch span processor limits: ```python from opentelemetry.sdk.trace.export import BatchSpanProcessor batch_processor = BatchSpanProcessor( otlp_exporter, max_queue_size=1024, # Reduced from default max_export_batch_size=256, schedule_delay_millis=3000, ) ``` ### Security Considerations #### PII Data Masking Implement custom span processor to mask sensitive data: ```python title="app/tracing.py" showLineNumbers """PII masking span processor.""" import re from opentelemetry.sdk.trace import SpanProcessor, ReadableSpan class PIIMaskingProcessor(SpanProcessor): """Mask PII in span attributes.""" EMAIL_PATTERN = re.compile(r'[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}') PHONE_PATTERN = re.compile(r'\b\d{3}[-.]?\d{3}[-.]?\d{4}\b') CREDIT_CARD_PATTERN = re.compile(r'\b\d{4}[-\s]?\d{4}[-\s]?\d{4}[-\s]?\d{4}\b') def on_start(self, span: "ReadableSpan", parent_context=None): """Mask PII on span start.""" if hasattr(span, '_name'): span._name = self._mask(span._name) def on_end(self, span: ReadableSpan): """Mask PII on span end.""" if hasattr(span, 'attributes'): for key, value in list(span.attributes.items()): if isinstance(value, str): span.attributes[key] = self._mask(value) def _mask(self, text): """Mask sensitive patterns.""" if not isinstance(text, str): return text text = self.EMAIL_PATTERN.sub('***@***.**', text) text = self.PHONE_PATTERN.sub('***-***-****', text) text = self.CREDIT_CARD_PATTERN.sub('****-****-****-****', text) return text def shutdown(self): pass def force_flush(self, timeout_millis=30000): return True ``` #### SQL Parameter Sanitization ```python # Enable SQL commenter without parameter values SQLAlchemyInstrumentor().instrument( engine=db.engine, enable_commenter=True, commenter_options={ "db_driver": True, "opentelemetry_values": False, # Don't log parameters } ) ``` #### Request Header Filtering ```python title="app/__init__.py" showLineNumbers """Filter sensitive headers.""" @app.before_request def filter_sensitive_headers(): """Remove sensitive headers from tracing.""" current_span = trace.get_current_span() # Don't trace authorization headers # current_span.set_attribute("http.authorization", request.headers.get("Authorization")) # Only log that auth is present if request.headers.get("Authorization"): current_span.set_attribute("http.auth.present", True) ``` ### Performance Considerations #### Tracing Overhead Metrics | Configuration | Latency (p50) | Latency (p99) | Throughput | Memory | | ------------------ | ------------- | ------------- | ---------- | ------- | | **No Tracing** | 8ms | 25ms | 12,000 rps | 180MB | | **Tracing (100%)** | 9ms (+12%) | 30ms (+20%) | 11,000 rps | 250MB | | **Tracing (10%)** | 8ms (+<1%) | 26ms (+4%) | 11,800 rps | 195MB | #### Optimization Strategies ##### 1. Exclude High-Volume Endpoints ```python FlaskInstrumentor().instrument_app( app, excluded_urls="health,readiness,metrics,static,favicon.ico" ) ``` ##### 2. Optimize Database Queries ```python # BAD: N+1 query problem orders = Order.query.all() for order in orders: print(order.user.username) # N queries! # GOOD: Eager loading from sqlalchemy.orm import joinedload orders = Order.query.options(joinedload(Order.user)).all() for order in orders: print(order.user.username) # Single query ``` ##### 3. Batch Span Export ```python batch_processor = BatchSpanProcessor( otlp_exporter, max_queue_size=2048, max_export_batch_size=512, schedule_delay_millis=5000, ) ``` ##### 4. Disable Tracing in Tests ```python # config.py class TestingConfig(Config): TESTING = True OTEL_SDK_DISABLED = True ``` ### FAQ #### Do I need to manually instrument Flask routes with OpenTelemetry? **No.** Flask's auto-instrumentation automatically traces all routes when you call `FlaskInstrumentor().instrument_app(app)`. No decorators required. #### How do I trace Flask blueprints? Blueprints are automatically instrumented when registered before calling `instrument_app()`. Ensure blueprints are registered first, then instrument. #### Can I use OpenTelemetry with Flask-RESTful? **Yes.** Flask-RESTful resources are automatically instrumented through Flask's route system. Each resource method creates a span. #### How do I trace SQLAlchemy queries in a Flask app with OpenTelemetry? Install `opentelemetry-instrumentation-sqlalchemy` and instrument the engine after `db.init_app(app)`: ```python from opentelemetry.instrumentation.sqlalchemy import SQLAlchemyInstrumentor SQLAlchemyInstrumentor().instrument(engine=db.engine) ``` #### Does OpenTelemetry tracing work with the Flask application factory? **Yes.** Initialize tracing inside your `create_app()` function after creating the app instance but before returning it. #### How do I trace Celery tasks from Flask? Install `opentelemetry-instrumentation-celery` and initialize in the worker process using `@worker_process_init` signal. Trace context automatically propagates from Flask to Celery. #### Can I exclude specific Flask routes from OpenTelemetry tracing? **Yes.** Use the `excluded_urls` parameter: ```python FlaskInstrumentor().instrument_app(app, excluded_urls="health,metrics") ``` #### What is the performance overhead of OpenTelemetry tracing in Flask? With 10% sampling, overhead is typically <1% for latency and ~8% for memory. Without sampling (100% tracing), expect ~12% latency increase. #### How do I send traces to Base14 Scout? Point the OTLP exporter at your Scout endpoint on port 4317 and pass your API key as a bearer token in the headers: ```python OTLPSpanExporter( endpoint="https://scout.base14.io:4317", headers={"authorization": f"Bearer {os.getenv('SCOUT_API_KEY')}"}, ) ``` #### Can I trace template rendering? **Yes.** Jinja2 template rendering is automatically traced when using `render_template()`. Each template creates a child span. #### How do I trace before/after request hooks? Flask hooks are automatically traced. Add custom attributes in hooks using `trace.get_current_span()`. #### Does tracing work with gevent workers? **Yes.** OpenTelemetry works with gevent and eventlet WSGI workers. Context propagation is maintained across greenlets. ### What's Next Now that you have Flask instrumented with OpenTelemetry, explore advanced observability patterns: #### Advanced Tracing Topics - **[Custom Instrumentation for Python](/instrument/apps/custom-instrumentation/python)** \- Deep dive into manual span creation and context propagation - **[All framework guides](/instrument/apps/auto-instrumentation/)** \- Auto-instrumentation overview for every language #### Scout Platform Features - **[Base14 Scout Dashboard](https://base14.io/scout)** - Visualize Flask traces with route-level insights - **Service Map Visualization** - Understand dependencies between Flask microservices - **Alert Configuration** - Set up alerts for slow routes and high error rates #### Deployment & Operations - **Docker Instrumentation** - Deploy instrumented Flask apps in containers - **Kubernetes Deployment** - Run Flask with sidecar collectors - **AWS Lambda** - Deploy Flask with AWS Lambda + API Gateway tracing ### Complete Example Here's a complete Flask application with OpenTelemetry instrumentation, including routes, SQLAlchemy, blueprints, and Celery tasks. #### Project Structure ```text flask-order-service/ ├── app/ │ ├── __init__.py │ ├── extensions.py │ ├── models.py │ ├── celery_app.py │ ├── tasks.py │ ├── routes/ │ │ ├── __init__.py │ │ ├── orders.py │ │ └── health.py │ └── services/ │ └── payment.py ├── config.py ├── wsgi.py ├── requirements.txt ├── Dockerfile ├── docker-compose.yml └── gunicorn.conf.py ``` #### Running the Example ```bash title="Terminal" showLineNumbers # Clone the examples repository git clone https://github.com/base-14/examples.git cd examples/python/flask-postgres # Create virtual environment python -m venv venv source venv/bin/activate # Install dependencies pip install -r requirements.txt # Start infrastructure docker-compose up -d postgres redis scout-collector # Initialize database export FLASK_APP=wsgi.py flask db upgrade # Run development server flask run # In another terminal: Run Celery worker celery -A app.celery_app worker --loglevel=info # Test endpoints curl http://localhost:5000/api/orders/ curl -X POST http://localhost:5000/api/orders/ \ -H "Content-Type: application/json" \ -d '{"product_name":"Widget","amount":"99.99"}' # View traces in Scout open https://scout.base14.io ``` #### Expected Trace Output ```text POST /api/orders/ (150ms) ├── create_order (120ms) │ ├── INSERT INTO orders (...) (15ms) │ ├── celery.apply_async (5ms) │ └── db.session.commit (10ms) └── Celery Task: process_order (100ms) [linked trace] ├── SELECT FROM orders WHERE id = ? (8ms) ├── validate_high_value_order (30ms) └── UPDATE orders SET status = ? (10ms) ``` :::tip Complete Example Repository The full example application with Docker Compose, Kubernetes manifests, and production configurations is available at: **[https://github.com/base-14/examples/tree/main/python/flask-postgres](https://github.com/base-14/examples/tree/main/python/flask-postgres)** ::: ### References #### Official Documentation - **[Flask Documentation](https://flask.palletsprojects.com/)** \- Official Flask framework documentation - **[OpenTelemetry Python SDK](https://opentelemetry.io/docs/languages/python/)** \- Core OpenTelemetry Python documentation - **[Flask Instrumentation](https://opentelemetry-python-contrib.readthedocs.io/en/latest/instrumentation/flask/flask.html)** \- Official Flask auto-instrumentation docs - **[SQLAlchemy Documentation](https://www.sqlalchemy.org/)** \- ORM and Core documentation #### Tools & Resources - **[Base14 Scout](https://base14.io/scout)** \- Managed OpenTelemetry platform for Flask microservices - **[Flask-RESTful](https://flask-restful.readthedocs.io/)** \- REST API extension for Flask - **[Flask-SQLAlchemy](https://flask-sqlalchemy.palletsprojects.com/)** \- Flask extension for SQLAlchemy ### Related Guides - [Django Instrumentation](/instrument/apps/auto-instrumentation/django) - Full-featured Python framework with ORM - [FastAPI Instrumentation](/instrument/apps/auto-instrumentation/fast-api) - Modern async Python framework - [Celery Tracing](/instrument/apps/auto-instrumentation/celery) - Distributed task queue instrumentation - [Python Custom Instrumentation](/instrument/apps/custom-instrumentation/python) \- Manual spans and advanced patterns - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up the collector for local development --- ## Go stdlib OpenTelemetry Instrumentation - net/http + pgx ## Go stdlib + Postgres ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction This guide instruments a Go service that uses only the **standard library `net/http`**, the `pgx/v5` Postgres driver, and the OpenTelemetry Go SDK - no Echo, Fiber, Chi, or Gin involved. Go 1.22 added pattern-based routing (`GET /api/articles/{id}`) directly to `http.ServeMux`, which removed the main reason most teams pulled in a third-party router. The result is a production service with full server, client, and database tracing and zero framework dependency. This guide builds on the [Go instrumentation guide](./go.md) with a complete standard-library and PostgreSQL example. Three OpenTelemetry contrib packages do most of the work. `otelhttp` wraps the mux to emit server spans on every inbound request and instruments outbound `http.Client` calls so W3C `traceparent` headers propagate automatically across services. `otelpgx` plugs into the pgx pool config to emit `pool.acquire`, `prepare`, and `query` spans on every database call. `otelslog` bridges Go's `log/slog` into the OTel logs pipeline so structured JSON logs flow to the same collector as your traces and metrics. If you already export traces to Datadog, New Relic, or Honeycomb, the same SDK setup works for Base14 Scout - swap the OTLP endpoint, wire up the collector's `oauth2client` extension for Scout's bearer token, and the rest of the code is identical. This guide covers prerequisites, installation, configuration, production hardening, custom instrumentation, troubleshooting, security, performance, and a complete worked example based on [go/stdlib-postgres](https://github.com/base-14/examples/tree/main/go/stdlib-postgres). :::tip TL;DR Wrap `http.ServeMux` with `otelhttp.NewHandler`, set `cfg.ConnConfig.Tracer = otelpgx.NewTracer()` on the pgxpool config, and install `propagation.TraceContext` as the global propagator. Initialize a `TracerProvider`, `MeterProvider`, and `LoggerProvider` once in `main`, defer their `Shutdown` calls, and point `OTEL_EXPORTER_OTLP_ENDPOINT` at your collector. You now have HTTP, database, and log telemetry without any framework dependency. ::: ### Who This Guide Is For This documentation is designed for: - **Go developers** building services on `net/http` 1.22+ who want full HTTP, database, and log telemetry without adopting Echo, Fiber, or Chi. - **Backend engineers** running Go services on Postgres via `pgx`, including teams migrating from `database/sql` + ORMs to native pgx for connection pooling and `LISTEN`/`NOTIFY`. - **Platform engineers** standardizing OTel across mixed-framework Go fleets where the lowest common denominator is the standard library. - **DevOps and SRE teams** deploying distroless Go binaries to Kubernetes and needing trace/log correlation that survives without shells, package managers, or runtime dependencies in the container. - **Developers migrating from Datadog, New Relic, or Dynatrace** APM agents to vendor-neutral OpenTelemetry on Base14 Scout. ### Overview #### Prerequisites Before starting, ensure you have: - **Go 1.22 or later** for `ServeMux` pattern routing (`GET /api/x/{id}`). Go 1.26+ recommended for the latest runtime metrics integration. - **PostgreSQL 14 or later**. The example uses Postgres 18. - **Docker and Docker Compose v2** for local multi-service testing. - **OpenTelemetry Collector** (Contrib distribution) running locally or remotely. The example bundles `otel/opentelemetry-collector-contrib:0.149.0`. - **Base14 Scout credentials** (`SCOUT_ENDPOINT`, `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, `SCOUT_TOKEN_URL`) if you want to forward telemetry to Scout. Skip these for local-only development. #### Compatibility Matrix | Component | Version | Notes | | -------------------------- | ----------------- | -------------------------------------------------- | | Go | 1.22+ | 1.22 required for mux pattern routing | | Go (recommended) | 1.26 | Used by the reference example | | pgx | v5.9+ | `pgxpool` for connection pooling | | PostgreSQL | 14, 15, 16, 17, 18 | Tested on 18 | | otelhttp | v0.68+ | Server handler + client transport | | otelpgx | v0.10+ | pgx tracer plugin | | otelslog bridge | v0.18+ | `log/slog` → OTel logs pipeline | | OTel Go SDK | v1.43+ | `go.opentelemetry.io/otel` | | OTel logs SDK | v0.19+ | `sdk/log`, `exporters/otlp/otlplog/otlploghttp` | | OpenTelemetry Collector | 0.149+ | Contrib build (oauth2client extension) | | Distroless base image | static-debian12 | `gcr.io/distroless/static-debian12:nonroot` | #### Instrumented Components | Component | What's Captured | | ----------------------- | --------------------------------------------------------------------- | | `http.ServeMux` (server)| Server span per request, route pattern, status code, latency | | `http.Client` (outbound)| Client span per request, traceparent injection, propagated context | | pgx connection pool | `pool.acquire`, `pool.connect`, `prepare`, `query` spans | | Postgres queries | SQL statement (parameterized), rows affected, duration | | `log/slog` | OTLP log records with trace_id/span_id, severity, body, attributes | | Outbound traceparent | W3C `traceparent` header on every otelhttp-instrumented request | | Custom metric | `articles.created` Int64Counter, exported every 60 s | | Process resource attrs | `process.runtime.name=go`, `process.pid`, telemetry SDK info | The complete reference application lives in [go/stdlib-postgres](https://github.com/base-14/examples/tree/main/go/stdlib-postgres) and ships an articles API on port 8080 plus a notify service on port 8081. Both export OTLP/HTTP to a collector, which forwards to Scout over TLS with an OAuth2 client-credentials flow. ### Installation The Go SDK is a set of Go modules - there is no agent or pre-shipped binary. Add them to `go.mod` and the rest is library code. ```mdx-code-block ``` ```bash go get go.opentelemetry.io/otel \ go.opentelemetry.io/otel/sdk \ go.opentelemetry.io/otel/sdk/metric \ go.opentelemetry.io/otel/sdk/log \ go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp \ go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp \ go.opentelemetry.io/otel/exporters/otlp/otlplog/otlploghttp \ go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp \ go.opentelemetry.io/contrib/bridges/otelslog \ github.com/exaring/otelpgx \ github.com/jackc/pgx/v5 ``` ```mdx-code-block ``` ```go title="app/go.mod" showLineNumbers module stdlib-articles go 1.26.1 require ( github.com/exaring/otelpgx v0.10.0 github.com/jackc/pgx/v5 v5.9.2 go.opentelemetry.io/contrib/bridges/otelslog v0.18.0 go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp v0.68.0 go.opentelemetry.io/otel v1.43.0 go.opentelemetry.io/otel/exporters/otlp/otlplog/otlploghttp v0.19.0 go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp v1.43.0 go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp v1.43.0 go.opentelemetry.io/otel/log v0.19.0 go.opentelemetry.io/otel/metric v1.43.0 go.opentelemetry.io/otel/sdk v1.43.0 go.opentelemetry.io/otel/sdk/log v0.19.0 go.opentelemetry.io/otel/sdk/metric v1.43.0 go.opentelemetry.io/otel/trace v1.43.0 ) ``` After updating `go.mod`, run `go mod tidy && go mod download`. ```mdx-code-block ``` ```dockerfile title="app/Dockerfile" showLineNumbers FROM golang:1.26-alpine AS builder WORKDIR /src COPY go.mod go.sum ./ RUN go mod download COPY . . RUN CGO_ENABLED=0 GOOS=linux go build -ldflags="-s -w" -o /out/app . FROM gcr.io/distroless/static-debian12:nonroot WORKDIR /app COPY --from=builder /out/app /app/app USER nonroot:nonroot EXPOSE 8080 ENTRYPOINT ["/app/app"] ``` `CGO_ENABLED=0` produces a static binary that runs on the distroless `static-debian12:nonroot` image - no glibc, no shell, no package manager. The OTel Go SDK is pure Go, so no extra packages or runtime dependencies are needed. ```mdx-code-block ``` ### Configuration The SDK reads OTLP endpoint, service name, and resource attributes from environment variables. Three places they typically come from: shell exports for local runs, Docker Compose for end-to-end testing, and an explicit `resource.New` call inside `initTelemetry` for code-controlled defaults. ```mdx-code-block ``` ```bash title=".env.example" showLineNumbers # Local development APP_PORT=8080 DATABASE_URL=postgres://postgres:postgres@db:5432/stdlib_articles?sslmode=disable NOTIFY_URL=http://notify:8081/notify # OpenTelemetry SDK OTEL_SERVICE_NAME=stdlib-articles OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=examples # Scout (only needed in the collector environment) SCOUT_ENDPOINT=https://your-scout-endpoint SCOUT_CLIENT_ID=your-client-id SCOUT_CLIENT_SECRET=your-client-secret SCOUT_TOKEN_URL=https://your-token-url SCOUT_ENVIRONMENT=development ``` `OTEL_SERVICE_NAME` lands in the `service.name` resource attribute, which Scout uses to group spans, logs, and metrics into a single service view. `OTEL_RESOURCE_ATTRIBUTES` accepts comma-separated `key=value` pairs and augments whatever you set in code. ```mdx-code-block ``` ```yaml title="compose.yml" showLineNumbers services: app: build: ./app ports: - "8080:8080" environment: APP_PORT: "8080" DATABASE_URL: postgres://postgres:postgres@db:5432/stdlib_articles?sslmode=disable NOTIFY_URL: http://notify:8081/notify OTEL_SERVICE_NAME: stdlib-articles OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_RESOURCE_ATTRIBUTES: deployment.environment=${SCOUT_ENVIRONMENT:-development},environment=${SCOUT_ENVIRONMENT:-development},service.namespace=examples depends_on: db: condition: service_healthy otel-collector: condition: service_started notify: build: ./notify ports: - "8081:8081" environment: NOTIFY_PORT: "8081" OTEL_SERVICE_NAME: stdlib-notify OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_RESOURCE_ATTRIBUTES: deployment.environment=${SCOUT_ENVIRONMENT:-development},environment=${SCOUT_ENVIRONMENT:-development},service.namespace=examples depends_on: otel-collector: condition: service_started ``` The Compose file pins `OTEL_EXPORTER_OTLP_ENDPOINT` to the Docker DNS name of the collector service. No host networking, no `host.docker.internal` games, and no host-side OTLP listener required. ```mdx-code-block ``` ```go title="app/telemetry.go" showLineNumbers package main import ( "context" "fmt" "strings" "time" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/exporters/otlp/otlplog/otlploghttp" "go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp" "go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp" "go.opentelemetry.io/otel/log/global" "go.opentelemetry.io/otel/propagation" sdklog "go.opentelemetry.io/otel/sdk/log" sdkmetric "go.opentelemetry.io/otel/sdk/metric" "go.opentelemetry.io/otel/sdk/resource" sdktrace "go.opentelemetry.io/otel/sdk/trace" semconv "go.opentelemetry.io/otel/semconv/v1.26.0" ) type shutdownFunc func(context.Context) error func initTelemetry(ctx context.Context, serviceName, endpoint string) (shutdownFunc, error) { res, err := resource.New(ctx, resource.WithFromEnv(), resource.WithProcess(), resource.WithTelemetrySDK(), resource.WithAttributes( semconv.ServiceName(serviceName), semconv.ServiceVersion("1.0.0"), ), ) if err != nil { return nil, fmt.Errorf("resource: %w", err) } traceExp, err := otlptracehttp.New(ctx, otlptracehttp.WithEndpoint(stripScheme(endpoint)), otlptracehttp.WithInsecure(), ) if err != nil { return nil, fmt.Errorf("trace exporter: %w", err) } tp := sdktrace.NewTracerProvider( sdktrace.WithBatcher(traceExp), sdktrace.WithResource(res), sdktrace.WithSampler(sdktrace.AlwaysSample()), ) metricExp, err := otlpmetrichttp.New(ctx, otlpmetrichttp.WithEndpoint(stripScheme(endpoint)), otlpmetrichttp.WithInsecure(), ) if err != nil { return nil, fmt.Errorf("metric exporter: %w", err) } mp := sdkmetric.NewMeterProvider( sdkmetric.WithReader(sdkmetric.NewPeriodicReader(metricExp, sdkmetric.WithInterval(60*time.Second))), sdkmetric.WithResource(res), ) logExp, err := otlploghttp.New(ctx, otlploghttp.WithEndpoint(stripScheme(endpoint)), otlploghttp.WithInsecure(), ) if err != nil { return nil, fmt.Errorf("log exporter: %w", err) } lp := sdklog.NewLoggerProvider( sdklog.WithResource(res), sdklog.WithProcessor(sdklog.NewBatchProcessor(logExp)), ) otel.SetTracerProvider(tp) otel.SetMeterProvider(mp) global.SetLoggerProvider(lp) otel.SetTextMapPropagator(propagation.NewCompositeTextMapPropagator( propagation.TraceContext{}, propagation.Baggage{}, )) return func(ctx context.Context) error { var errs []error if err := tp.Shutdown(ctx); err != nil { errs = append(errs, err) } if err := mp.Shutdown(ctx); err != nil { errs = append(errs, err) } if err := lp.Shutdown(ctx); err != nil { errs = append(errs, err) } if len(errs) > 0 { return fmt.Errorf("shutdown: %v", errs) } return nil }, nil } func stripScheme(endpoint string) string { if s := strings.TrimPrefix(endpoint, "https://"); s != endpoint { return s } return strings.TrimPrefix(endpoint, "http://") } ``` `resource.WithFromEnv()` merges anything in `OTEL_RESOURCE_ATTRIBUTES`, `WithProcess()` adds `process.pid`, `process.runtime.name=go`, and `process.runtime.version`, and `WithTelemetrySDK()` records the SDK version. The composite propagator handles W3C `traceparent` and `baggage`. ```mdx-code-block ``` ### Production Configuration #### Batch and exporter tuning The defaults work for most services. The two knobs you usually touch: - **Trace batch size and timeout** - `sdktrace.WithBatcher(exp, sdktrace.WithMaxExportBatchSize(512), sdktrace.WithBatchTimeout(5*time.Second))` for high-throughput services. - **Metric export interval** - the example uses 60 s (`sdkmetric.WithInterval(60*time.Second)`). Drop to 15-30 s for tighter alerting; raise to 120 s for low-traffic batch jobs. #### GZIP compression on the OTLP exporter Enable GZIP at the exporter layer for the leg between collector and Scout: ```yaml title="config/otel-config.yaml" showLineNumbers exporters: otlp_http/scout: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s ``` The Go SDK exporter (`otlptracehttp`, `otlpmetrichttp`, `otlploghttp`) defaults to `gzip` compression on the wire from the app to the collector; no extra setup needed there. #### Distroless multi-stage Dockerfile The example builds a static binary on `golang:1.26-alpine` and ships it on `gcr.io/distroless/static-debian12:nonroot`. The runtime image has no shell, no package manager, and a non-root UID by default: ```dockerfile title="app/Dockerfile" showLineNumbers FROM golang:1.26-alpine AS builder WORKDIR /src COPY go.mod go.sum ./ RUN go mod download COPY . . RUN CGO_ENABLED=0 GOOS=linux go build -ldflags="-s -w" -o /out/app . FROM gcr.io/distroless/static-debian12:nonroot WORKDIR /app COPY --from=builder /out/app /app/app USER nonroot:nonroot EXPOSE 8080 ENTRYPOINT ["/app/app"] ``` `-ldflags="-s -w"` strips DWARF and symbol tables, cutting the binary to ~15 MB. Distroless `static-debian12` adds about 2 MB on top of that, so the final image is in the 17-20 MB range. #### Multi-service distributed tracing The example wires two services - `stdlib-articles` (port 8080) and `stdlib-notify` (port 8081). The articles service calls notify with a `http.Client` whose transport is `otelhttp.NewTransport(http.DefaultTransport)`. That transport injects W3C `traceparent` on the outbound request. The notify service wraps its mux with `otelhttp.NewHandler`, which extracts the same header into a child span. Both traces share one `trace_id`: ```text http.server (stdlib-articles) POST /api/articles ├── prepare (otelpgx) ├── query (otelpgx) INSERT INTO articles ... └── HTTP POST (otelhttp.client) └── http.server (stdlib-notify) POST /notify ``` This works without any code in the application beyond the otelhttp wrappers and a global `propagation.TraceContext` propagator. ### Framework-Specific Features #### Server-side: otelhttp.NewHandler around ServeMux ```go title="app/main.go" showLineNumbers mux := http.NewServeMux() mux.HandleFunc("GET /api/health", handler.Health) articles.Register(mux) server := &http.Server{ Addr: ":" + port, Handler: otelhttp.NewHandler(mux, "http.server", otelhttp.WithSpanNameFormatter(func(_ string, r *http.Request) string { return r.Method + " " + r.URL.Path }), ), ReadHeaderTimeout: 5 * time.Second, } ``` `otelhttp.NewHandler` produces one server span per request with attributes for HTTP method, route, status code, and duration. The `WithSpanNameFormatter` callback overrides the default `"HTTP {method}"` with the more searchable `"GET /api/articles/{id}"` shape. #### Client-side: otelhttp.NewTransport ```go title="app/service/notification.go" showLineNumbers package service import ( "bytes" "context" "encoding/json" "fmt" "io" "net/http" "time" "stdlib-articles/model" "go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp" ) type Notifier struct { url string client *http.Client } func NewNotifier(url string) *Notifier { return &Notifier{ url: url, client: &http.Client{ Transport: otelhttp.NewTransport(http.DefaultTransport), Timeout: 5 * time.Second, }, } } func (n *Notifier) NotifyArticleCreated(ctx context.Context, article *model.Article) error { if n.url == "" { return nil } payload := map[string]any{ "event": "article.created", "article_id": article.ID, "title": article.Title, } body, err := json.Marshal(payload) if err != nil { return err } req, err := http.NewRequestWithContext(ctx, http.MethodPost, n.url, bytes.NewReader(body)) if err != nil { return err } req.Header.Set("Content-Type", "application/json") resp, err := n.client.Do(req) if err != nil { return err } defer resp.Body.Close() _, _ = io.Copy(io.Discard, resp.Body) if resp.StatusCode >= 400 { return fmt.Errorf("notify returned status %d", resp.StatusCode) } return nil } ``` The key call is `http.NewRequestWithContext(ctx, ...)`. Without that, the transport has no parent span context to propagate. Forget it and you'll see two disconnected traces in Scout instead of one. #### pgx tracer with otelpgx ```go title="app/main.go" showLineNumbers func newPool(ctx context.Context, dsn string) (*pgxpool.Pool, error) { cfg, err := pgxpool.ParseConfig(dsn) if err != nil { return nil, err } cfg.ConnConfig.Tracer = otelpgx.NewTracer() pool, err := pgxpool.NewWithConfig(ctx, cfg) if err != nil { return nil, err } pingCtx, cancel := context.WithTimeout(ctx, 10*time.Second) defer cancel() if err := pool.Ping(pingCtx); err != nil { pool.Close() return nil, err } return pool, nil } ``` `otelpgx.NewTracer()` plugs into pgx's `Tracer` interface and emits four span kinds: | Span name | When | | ---------------- | ------------------------------------------------- | | `pool.connect` | New connection added to the pool | | `pool.acquire` | Goroutine checks out a connection | | `prepare` | Statement preparation | | `query` | `Exec`, `Query`, or `QueryRow` | Spans carry `db.system=postgresql`, `db.statement` (parameterized SQL with literals replaced by placeholders), and `db.operation` (e.g. `INSERT`, `SELECT`). #### Repository code is unchanged Once `cfg.ConnConfig.Tracer` is set, repository code just uses `pool.Query` and `pool.QueryRow` normally. Spans appear as long as you pass `ctx` through to the query call: ```go title="app/repository/article.go" showLineNumbers func (r *ArticleRepository) GetByID(ctx context.Context, id int64) (*model.Article, error) { var a model.Article err := r.pool.QueryRow(ctx, ` SELECT id, title, body, created_at, updated_at FROM articles WHERE id = $1 `, id).Scan(&a.ID, &a.Title, &a.Body, &a.CreatedAt, &a.UpdatedAt) if errors.Is(err, pgx.ErrNoRows) { return nil, ErrNotFound } if err != nil { return nil, err } return &a, nil } ``` #### slog bridged to OTel logs with trace context ```go title="app/middleware/logger.go" showLineNumbers package middleware import ( "context" "log/slog" "os" "go.opentelemetry.io/contrib/bridges/otelslog" "go.opentelemetry.io/otel/trace" ) // NewLogger returns a slog.Logger that writes JSON to stdout AND bridges to // the OTel logs pipeline. Trace and span IDs from context are added to every // record so logs correlate with traces in Scout. func NewLogger(serviceName string) *slog.Logger { stdoutHandler := traceContextHandler{ Handler: slog.NewJSONHandler(os.Stdout, &slog.HandlerOptions{Level: slog.LevelInfo}), } otelHandler := otelslog.NewHandler(serviceName) return slog.New(multiHandler{handlers: []slog.Handler{stdoutHandler, otelHandler}}). With("service", serviceName) } type traceContextHandler struct { slog.Handler } func (h traceContextHandler) Handle(ctx context.Context, r slog.Record) error { sc := trace.SpanFromContext(ctx).SpanContext() if sc.IsValid() { r.AddAttrs( slog.String("trace_id", sc.TraceID().String()), slog.String("span_id", sc.SpanID().String()), ) } return h.Handler.Handle(ctx, r) } ``` Two important details: 1. The `multiHandler` fans out every record to *both* the stdout JSON handler and the OTel bridge, so you can `docker compose logs -f app` for local tail and still ship logs to Scout. 2. `traceContextHandler` wraps the JSON handler so the stdout copy also gets `trace_id`/`span_id`. The OTel bridge attaches them on its side independently. Both copies stay correlated. ### Custom Instrumentation #### Counter metric on a successful create ```go title="app/main.go" showLineNumbers createdCounter, err := otel.Meter("stdlib-articles").Int64Counter("articles.created") if err != nil { log.Fatalf("counter: %v", err) } ``` ```go title="app/handler/article.go" showLineNumbers article, err := h.repo.Create(r.Context(), req.Title, req.Body) if err != nil { h.logger.ErrorContext(r.Context(), "Failed to create article", "error", err) writeError(r.Context(), w, http.StatusInternalServerError, "INTERNAL_ERROR", "Failed to create article") return } h.created.Add(r.Context(), 1) h.logger.InfoContext(r.Context(), "Article created", "article_id", article.ID) ``` The counter exports every 60 s through the meter provider. In Scout this shows up as the `articles.created` metric, broken down by `service.name=stdlib-articles` and `deployment.environment`. #### Trace ID echoed in the response API consumers can quote the trace ID in support tickets so you can pull the full trace in Scout without grepping logs: ```go title="app/handler/article.go" showLineNumbers func envelope(ctx context.Context, data any) map[string]any { return map[string]any{ "data": data, "meta": map[string]any{"trace_id": traceID(ctx)}, } } func traceID(ctx context.Context) string { sc := trace.SpanFromContext(ctx).SpanContext() if !sc.IsValid() { return "" } return sc.TraceID().String() } ``` A successful `POST /api/articles` then returns: ```json { "data": { "id": 42, "title": "...", "body": "..." }, "meta": { "trace_id": "0af7651916cd43dd8448eb211c80319c" } } ``` #### Manual spans for business logic For arbitrary work you want to time, grab a tracer once and start spans explicitly: ```go import "go.opentelemetry.io/otel" tracer := otel.Tracer("stdlib-articles") func chargeCustomer(ctx context.Context, customerID string) error { ctx, span := tracer.Start(ctx, "charge_customer") defer span.End() span.SetAttributes( attribute.String("customer.id", customerID), ) if err := stripeCharge(ctx, customerID); err != nil { span.RecordError(err) span.SetStatus(codes.Error, "stripe charge failed") return err } return nil } ``` `tracer.Start` automatically becomes a child of whatever span lives in `ctx` (server span, parent business span, etc.). ### Running Your Application #### Local with Docker Compose ```bash git clone https://github.com/base-14/examples.git cd examples/go/stdlib-postgres cp .env.example .env # edit .env with your Scout credentials (or leave defaults for local-only) docker compose up -d --build ``` #### Smoke test the API The example ships an end-to-end test script that exercises every endpoint, checks distributed trace correlation, verifies log fields, and confirms the `articles.created` metric reaches the collector: ```bash make test-api ``` #### Verify a single request manually ```bash # Health curl http://localhost:8080/api/health # Create an article (triggers the notify call) curl -X POST http://localhost:8080/api/articles \ -H 'Content-Type: application/json' \ -d '{"title":"hello","body":"first article"}' # Response includes trace_id you can search in Scout ``` #### Expected span hierarchy in Scout For a `POST /api/articles` call you should see: ```text POST /api/articles service.name=stdlib-articles ├── pool.acquire instrumentation_scope=otelpgx ├── prepare instrumentation_scope=otelpgx ├── query INSERT INTO articles ... db.statement, db.operation=INSERT └── HTTP POST http.client, traceparent injected └── POST /notify service.name=stdlib-notify ``` All five spans share a single `trace_id`. The notify service appears as a sibling resource (`service.name=stdlib-notify`) inside the same trace. #### Run a single service in dev mode For tight feedback loops without rebuilding the container, run the binary directly against an existing collector: ```bash cd app DATABASE_URL='postgres://postgres:postgres@localhost:5432/stdlib_articles?sslmode=disable' \ OTEL_SERVICE_NAME=stdlib-articles \ OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 \ NOTIFY_URL=http://localhost:8081/notify \ go run . ``` Note: when running outside Docker, swap the Compose hostnames (`db`, `notify`, `otel-collector`) for `localhost`. ### Troubleshooting #### Trace context is lost between services **Symptom**: the notify service shows up as a separate trace instead of a child of the articles service. **Cause**: the outbound HTTP request was built with `http.NewRequest` instead of `http.NewRequestWithContext`. The otelhttp transport pulls the parent span out of `req.Context()`; without it, the transport starts a new root trace. **Fix**: ```go req, err := http.NewRequestWithContext(ctx, http.MethodPost, n.url, bytes.NewReader(body)) ``` Also confirm the global propagator is registered: ```go otel.SetTextMapPropagator(propagation.NewCompositeTextMapPropagator( propagation.TraceContext{}, propagation.Baggage{}, )) ``` #### pgx queries don't produce spans **Symptom**: HTTP server spans appear, but no `query` or `pool.acquire` spans show up underneath. **Cause**: usually one of: - `cfg.ConnConfig.Tracer = otelpgx.NewTracer()` was set on the wrong config (e.g., on a fresh `pgx.Connect` config rather than the pool config returned by `pgxpool.ParseConfig`). - The repository code calls `pool.Query` with `context.Background()` instead of the request context. - The collector's `filter/noisy` processor is dropping `pool.acquire` and `connect` spans intentionally (the example does this - check the config). **Fix**: pass `r.Context()` through every repository method, and verify the tracer is attached to the pool config before calling `pgxpool.NewWithConfig`. #### `otelhttp.NewHandler` is logging twice or producing wrong route names **Symptom**: every request span is named `HTTP GET` or `HTTP POST` without a path; route patterns are missing. **Cause**: default span naming uses just the method. The mux pattern is attached as an attribute but not in the name. **Fix**: pass a span name formatter: ```go otelhttp.NewHandler(mux, "http.server", otelhttp.WithSpanNameFormatter(func(_ string, r *http.Request) string { return r.Method + " " + r.URL.Path }), ) ``` For high-cardinality paths (e.g. `/api/articles/{id}`), prefer the route pattern over the raw URL path: ```go otelhttp.WithSpanNameFormatter(func(_ string, r *http.Request) string { if r.Pattern != "" { return r.Method + " " + r.Pattern } return r.Method + " " + r.URL.Path }) ``` `http.Request.Pattern` (Go 1.23+) holds the matched mux route, so paths like `/api/articles/42` collapse to `GET /api/articles/{id}` in span names. #### OTLP export fails with `connection refused` **Symptom**: stderr shows `failed to export traces: ... connect: connection refused`. **Cause**: the collector isn't reachable at the configured endpoint. **Fix checklist**: 1. `docker compose ps` - is `otel-collector` running and healthy? 2. From the app container, `wget -O- http://otel-collector:13133` should return the collector health endpoint. 3. `OTEL_EXPORTER_OTLP_ENDPOINT` must be the *base* URL (`http://otel-collector:4318`), not the per-signal path. 4. Use `otlptracehttp.WithInsecure()` for plain HTTP between app and collector. TLS is normally only used between collector and Scout. #### Logs are missing `trace_id` and `span_id` **Symptom**: stdout JSON logs land in the right shape but have no trace correlation fields. **Cause**: handlers are using `slog.Info` (no context) instead of `slog.InfoContext(ctx, ...)`. Without the context argument, slog never hits the `Handle(ctx, ...)` path that injects trace IDs. **Fix**: thread context through every log call: ```go h.logger.InfoContext(r.Context(), "Article created", "article_id", article.ID) ``` ### Security Considerations - **PII in span attributes** - `db.statement` carries the parameterized SQL with literal values replaced. otelpgx already does this by default. For HTTP attributes, otelhttp redacts the query string by default; do not add `?token=...` style tokens to URLs. - **Authorization headers** - otelhttp does not capture request or response headers by default. If you opt in via `otelhttp.WithFilter`/`otelhttp.WithPublicEndpoint`, add an explicit redaction step for `Authorization`, `Cookie`, and `Set-Cookie`. - **SQL parameter values** - otelpgx records `db.statement` with placeholders (`$1`, `$2`); the actual values are *not* attached as span attributes. If you ever switch to a tracer that does, route them through a span processor that drops or hashes them. - **Distroless attack surface** - shipping on `gcr.io/distroless/static-debian12:nonroot` means no shell, no `apt`, no setuid binaries, and a non-root UID. Vulnerability scanners consistently report 0-2 CVEs against the runtime image vs. 30+ for a full Debian/Ubuntu base. - **Outbound TLS to Scout** - the collector's `oauth2client` extension obtains a bearer token from Scout's token URL and renews it automatically. Set `tls.insecure_skip_verify: true` only for local testing; production should pin the Scout CA or accept the system trust store. - **Compliance scope** - if you need GDPR/HIPAA/SOC2 attestation for the telemetry path, run the collector in your own VPC and use a private link (Scout supports VPC peering). Avoid emitting end-user identifiers as span attributes; use a hashed `user.id` if you need cardinality. ### Performance Considerations The Go SDK is one of the fastest OTel SDKs in production, partly because the runtime is goroutine-friendly and partly because everything is library-based with no agent. | Workload | Without OTel | With OTel | Overhead | | ------------------------ | ------------ | --------- | ----------------------- | | `GET /api/health` | 0.4 ms | 0.5 ms | +0.1 ms | | `GET /api/articles/{id}` | 1.8 ms | 2.1 ms | +0.3 ms | | `POST /api/articles` | 4.2 ms | 4.7 ms | +0.5 ms (incl. notify) | | Postgres `SELECT` p99 | 0.9 ms | 1.0 ms | +0.1 ms (otelpgx) | | RSS at idle | 12 MB | 22 MB | +10 MB (SDK + buffers) | | CPU at 1k RPS | 8% | 11% | +3 percentage points | (Numbers are illustrative; measure on your hardware.) #### Tuning batch processors The trace SDK batches by default (max 512 spans, 5 s timeout). For high-throughput services you can raise the queue size to absorb traffic spikes without dropping: ```go sdktrace.NewTracerProvider( sdktrace.WithBatcher(traceExp, sdktrace.WithMaxExportBatchSize(512), sdktrace.WithMaxQueueSize(8192), sdktrace.WithBatchTimeout(5*time.Second), ), ) ``` #### Filter health checks at the collector Wrapping `/api/health` with otelhttp produces a span every time Kubernetes probes the pod. The example collector drops these in the traces pipeline so they never reach Scout: ```yaml title="config/otel-config.yaml" showLineNumbers processors: filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*health.*")' - 'name == "pool.acquire" and instrumentation_scope.name == "github.com/exaring/otelpgx"' - 'name == "connect" and instrumentation_scope.name == "github.com/exaring/otelpgx"' ``` That cuts the trace volume by 60-80% on a typical microservice. #### Goroutine cost Each request runs in its own goroutine. The SDK's per-span allocations are pooled, so a high-RPS service might allocate ~1 KB per span on hot paths. The goroutine-local context plumbing adds negligible per-request cost. ### FAQ #### Why use net/http instead of a Go web framework with OpenTelemetry? Go 1.22 added pattern-based routing (e.g. `GET /api/articles/{id}`) to `net/http`, removing the main reason most teams reached for Echo, Fiber, or Chi. Wrapping `ServeMux` with `otelhttp.NewHandler` gives you full server-span coverage with zero framework dependency, no middleware chains, and no router-specific OTel contrib package. #### How do I trace pgx queries with OpenTelemetry? Set `cfg.ConnConfig.Tracer = otelpgx.NewTracer()` before calling `pgxpool.NewWithConfig`. Every query, prepare, and pool acquire becomes a span attached to the parent HTTP server span via context. Pass `ctx` to `pool.Query`, `pool.QueryRow`, and `pool.Exec`. #### How much overhead does OpenTelemetry add to a Go net/http service? Roughly 0.1-0.3 ms added latency per request, 1-3% CPU at 1k RPS, and 8-15 MB extra resident memory for the SDK. Postgres queries gain about 50-150 microseconds from the otelpgx tracer. The biggest variable is network egress to the collector, not in-process overhead. #### Does W3C traceparent propagate automatically between Go services? Yes, when both client and server use otelhttp. Wrap the outbound `http.Client` with `otelhttp.NewTransport` on the caller and `otelhttp.NewHandler` on the receiver. The `traceparent` header is injected and parsed automatically when you set `propagation.TraceContext` as the global propagator. #### How do I correlate Go slog logs with traces? Use the `go.opentelemetry.io/contrib/bridges/otelslog` package to forward records to the OTel logs pipeline, and a small custom `slog.Handler` that reads `trace.SpanFromContext(ctx)` to add `trace_id` and `span_id` to every record before the JSON encoder runs. The example does both via a `multiHandler` that fans out to stdout and OTLP. #### Can I run OpenTelemetry-instrumented Go binaries on distroless images? Yes. The OTel Go SDK is pure Go, so a `CGO_ENABLED=0` static build runs on `gcr.io/distroless/static-debian12:nonroot` with no extra packages. The example app and notify service both use this image and the final container is in the 17-20 MB range. #### What is the difference between otelhttp.NewHandler and otelhttp.NewMiddleware? `NewHandler` wraps an entire `http.Handler` (typically `ServeMux`) and produces one server span per request. `NewMiddleware` returns a middleware function for routers that compose middleware explicitly. For stdlib `net/http`, `NewHandler` is the canonical entry point. #### How do I expose the trace ID to API consumers in Go? Read `trace.SpanFromContext(ctx).SpanContext().TraceID().String()` inside the handler and embed it in the response body (for example in a `meta` envelope). This lets clients quote the trace ID in support tickets so you can pull the full trace in Scout. The example does this in the `envelope()` helper. #### Do I need a Go agent or auto-instrumentation binary? No. Unlike Java or Python, Go instrumentation is library-based - you import `otelhttp`, `otelpgx`, and `otelslog` and call them explicitly. There is no `java -javaagent` equivalent for production Go binaries. There is an experimental eBPF-based auto-instrumentation project, but for stdlib services the library approach is simpler and faster. #### How do I disable noisy spans like pgx pool.acquire? Drop them at the collector with a `filter` processor on the traces pipeline. The example config filters span names matching `.*health.*` and `pool.acquire`/`connect` spans from otelpgx so the trace UI stays focused on real query work. See the `filter/noisy` processor in `config/otel-config.yaml`. #### Can I use OpenTelemetry with database/sql instead of pgx? Yes - swap otelpgx for `otelsql` (`github.com/XSAM/otelsql`) and wrap your `sql.DB` driver. The rest of the setup (otelhttp, otelslog, exporters) is identical. The example uses pgx because pgxpool is the most widely-used native Postgres driver for Go. #### How do I stop sending dev OTLP traffic over the public internet? Run the OTel collector locally in Docker Compose and point `OTEL_EXPORTER_OTLP_ENDPOINT` at it (`http://otel-collector:4318`). The collector authenticates to Scout with `oauth2client` and forwards over TLS. Your laptop and your CI never need direct outbound TLS to Scout. ### What's Next - **Add custom business metrics** - histograms for latency per business flow, gauges for queue depth, async counters for cache hit rate. See [custom instrumentation](../custom-instrumentation/go.md). - **Wire up Postgres pool metrics** - otelpgx exposes `pgxpool.Stat()`-derived gauges via a callback observer (open connections, idle connections, acquire wait time). - **Profile in production** - the SDK plays well with Go's `runtime/pprof` and `net/http/pprof`. Start with span-level latency, then drop to pprof for hot paths the spans surface. - **Add Redis or NATS** - the same pattern works with `otelredis` and `otelnats`. Wrap the client, pass `ctx`, you're done. - **Move to gRPC** - swap `otelhttp` for `otelgrpc.NewServerHandler` and `otelgrpc.NewClientHandler`. Same propagation, same span shape. For end-to-end Go observability beyond a single service - log search, trace exploration, alerting, and dashboarding without rolling your own Grafana stack - see how teams use [Base14 Scout for production Go observability](https://www.base14.io). ### Complete Example The full reference implementation lives at [go/stdlib-postgres](https://github.com/base-14/examples/tree/main/go/stdlib-postgres): ```text go/stdlib-postgres/ ├── app/ # stdlib-articles (port 8080) │ ├── main.go # bootstraps OTel + pgx pool + mux │ ├── telemetry.go # tracer + meter + logger providers │ ├── handler/ │ │ ├── article.go # CRUD handlers + envelope helpers │ │ └── health.go # /api/health │ ├── middleware/ │ │ └── logger.go # slog handler with trace context │ ├── model/ │ │ └── article.go # Article struct + Schema constant │ ├── repository/ │ │ └── article.go # pgx queries │ ├── service/ │ │ └── notification.go # otelhttp-instrumented client │ ├── go.mod │ ├── go.sum │ └── Dockerfile # multi-stage, distroless ├── notify/ # stdlib-notify (port 8081) │ ├── main.go # /notify endpoint, span receiver │ ├── telemetry.go # mirrors app/telemetry.go │ ├── logger.go # slog + otelslog bridge │ ├── go.mod / go.sum / Dockerfile ├── config/ │ └── otel-config.yaml # collector w/ oauth2client → Scout ├── scripts/ │ ├── test-api.sh # full e2e API + observability check │ └── verify-scout.sh # confirms data lands in Scout ├── compose.yml # app + notify + db + collector ├── Makefile # build, lint, docker-up, test-api ├── .env.example └── README.md ``` #### Run it ```bash git clone https://github.com/base-14/examples.git cd examples/go/stdlib-postgres cp .env.example .env # fill in Scout credentials, or leave defaults for local-only docker compose up -d --build # all-in-one functional + observability smoke test make test-api # scout export verification (requires real credentials) make verify-scout ``` The `test-api.sh` script does an end-to-end check: it runs every CRUD endpoint, extracts the `trace_id` from a `POST /api/articles` response, greps the notify service logs for the same trace ID, greps the collector logs for matching spans, and waits for the periodic metric flush to verify `articles.created` reaches the collector. A passing run looks like: ```text === stdlib-postgres API Testing Script === Target: http://localhost:8080 [PASS] Health check (HTTP 200) [PASS] Create article (HTTP 201) [PASS] Get article (HTTP 200) [PASS] List articles (HTTP 200) [PASS] Update article (HTTP 200) [PASS] Delete article (HTTP 204) [PASS] 400 - Invalid ID format (HTTP 400) [PASS] 404 - Article not found (HTTP 404) [PASS] 422 - Empty body (HTTP 422) [PASS] Distributed trace - notify service received matching trace_id [PASS] Collector received spans with matching trace_id [PASS] Logs contain trace_id field [PASS] Logs contain span_id field [PASS] WARN log present for error conditions [PASS] articles.created metric found in collector === Results === Passed: 15 / 15 ``` ### References - [OpenTelemetry Go SDK](https://opentelemetry.io/docs/languages/go/) - [otelhttp contrib package](https://pkg.go.dev/go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp) - [otelpgx](https://github.com/exaring/otelpgx) - [otelslog bridge](https://pkg.go.dev/go.opentelemetry.io/contrib/bridges/otelslog) - [pgx v5](https://github.com/jackc/pgx) - [Go 1.22 ServeMux pattern routing](https://pkg.go.dev/net/http#ServeMux) - [Distroless container images](https://github.com/GoogleContainerTools/distroless) - [W3C Trace Context](https://www.w3.org/TR/trace-context/) - [OpenTelemetry Collector oauth2client extension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/oauth2clientauthextension) ### Related Guides - [Go Custom Instrumentation](../custom-instrumentation/go.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language - [Hello World](/instrument/apps/hello-world) - verify your collector before adding any app code. --- ## Go OpenTelemetry Instrumentation - Echo, Fiber, Chi & GORM Tracing ## Go :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Implement OpenTelemetry instrumentation for Go applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability across your high-performance web services. This guide shows you how to instrument popular Go web frameworks including Echo, Fiber, and Chi, along with database clients (GORM, sqlx), Redis, background job queues (Asynq, River), and gRPC services using the OpenTelemetry Go SDK. Go applications benefit from automatic instrumentation of HTTP servers, database queries, Redis operations, gRPC calls, and message queues. With OpenTelemetry, you can trace requests through goroutines, monitor context propagation, identify slow database queries, debug concurrent operations, and track distributed transactions across microservices with minimal performance overhead. Whether you're implementing observability for the first time, migrating from commercial APM solutions like New Relic or Datadog, troubleshooting performance issues in production, or building high-throughput microservices, this guide provides production-ready configurations and best practices for Go OpenTelemetry instrumentation with Base14 Scout. This guide covers OpenTelemetry for Go services. For a complete worked example with the standard library and PostgreSQL, see the [Go stdlib and PostgreSQL guide](./go-stdlib-postgres.md). :::tip TL;DR Initialize a `TracerProvider` once in `main`, set it as the global provider, then add the framework middleware (e.g., `otelecho`, `otelfiber`, `otelhttp`) to automatically trace every incoming request. Pass `context.Context` explicitly through your call stack so database, Redis, and background-job spans attach to the same trace. ::: ### Who This Guide Is For This documentation is designed for: - **Go developers**: implementing observability and distributed tracing for web services and microservices - **Backend engineers**: deploying Go applications with production monitoring requirements and SLO tracking - **DevOps teams**: standardizing observability across multiple Go services in containerized environments - **Performance engineers**: debugging goroutine bottlenecks, database query performance, and concurrent operations - **Microservices architects**: building observable distributed systems with gRPC, message queues, and service meshes ### Prerequisites Before starting, ensure you have: - **Go 1.21 or later** (1.22+ recommended for production) - **Web framework** (Echo, Fiber, Chi, Gin, or standard `net/http`) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) - Familiarity with Go context propagation and middleware patterns #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | -------------------------------- | --------------- | ------------------- | | Go | 1.20 | 1.22+ | | go.opentelemetry.io/otel | 1.20.0 | 1.32+ | | go.opentelemetry.io/contrib | 1.20.0 | 1.32+ | | Echo (labstack/echo) | 4.10.0 | 4.13.0+ | | Fiber (gofiber/fiber) | 2.50.0 | 2.52.0+ | | Chi (go-chi/chi) | 5.0.0 | 5.1.0+ | | GORM | 1.25.0 | 1.25.12+ | | sqlx (jmoiron/sqlx) | 1.3.0 | 1.4.0+ | | Redis (go-redis/redis) | 9.0.0 | 9.7.0+ | | Asynq (hibiken/asynq) | 0.24.0 | 0.24.1+ | | River (riverqueue/river) | 0.11.0 | 0.14.0+ | ### Installation Install the OpenTelemetry SDK and instrumentation packages: ```bash showLineNumbers title="Install OpenTelemetry for Go" go get go.opentelemetry.io/otel \ go.opentelemetry.io/otel/sdk \ go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp \ go.opentelemetry.io/otel/sdk/resource \ go.opentelemetry.io/otel/semconv/v1.26.0 ``` Install framework-specific instrumentation: ```bash showLineNumbers title="Install framework instrumentation" # Echo framework go get go.opentelemetry.io/contrib/instrumentation/github.com/labstack/echo/otelecho # Fiber framework go get go.opentelemetry.io/contrib/instrumentation/github.com/gofiber/fiber/v2/otelfiber # Chi router (manual middleware) go get go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp # GORM go get go.opentelemetry.io/contrib/instrumentation/gorm.io/gorm/otelgorm # Database drivers go get go.opentelemetry.io/contrib/instrumentation/database/sql/otelsql # Redis go get go.opentelemetry.io/contrib/instrumentation/github.com/go-redis/redis/v9/otelredis # gRPC go get go.opentelemetry.io/contrib/instrumentation/google.golang.org/grpc/otelgrpc ``` ### Configuration ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Create a dedicated package for OpenTelemetry initialization: ```go showLineNumbers title="internal/tracing/tracing.go" package tracing import ( "context" "log" "os" "time" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp" "go.opentelemetry.io/otel/propagation" "go.opentelemetry.io/otel/sdk/resource" sdktrace "go.opentelemetry.io/otel/sdk/trace" semconv "go.opentelemetry.io/otel/semconv/v1.26.0" ) func InitTracer(serviceName, serviceVersion string) (func(context.Context) error, error) { ctx := context.Background() // Create OTLP HTTP exporter exporter, err := otlptracehttp.New(ctx, otlptracehttp.WithEndpoint(getEnv("OTEL_EXPORTER_OTLP_ENDPOINT", "localhost:4318")), otlptracehttp.WithInsecure(), // Use WithTLSClientConfig for production ) if err != nil { return nil, err } // Create resource with service information res, err := resource.New(ctx, resource.WithAttributes( semconv.ServiceName(serviceName), semconv.ServiceVersion(serviceVersion), semconv.DeploymentEnvironment(getEnv("DEPLOYMENT_ENV", "development")), ), resource.WithHost(), resource.WithOS(), resource.WithProcess(), resource.WithContainer(), ) if err != nil { return nil, err } // Create tracer provider with batch span processor tp := sdktrace.NewTracerProvider( sdktrace.WithBatcher(exporter, sdktrace.WithMaxQueueSize(2048), sdktrace.WithMaxExportBatchSize(512), sdktrace.WithBatchTimeout(5*time.Second), ), sdktrace.WithResource(res), ) // Set global tracer provider otel.SetTracerProvider(tp) // Set global propagator for context propagation otel.SetTextMapPropagator(propagation.NewCompositeTextMapPropagator( propagation.TraceContext{}, propagation.Baggage{}, )) log.Println("OpenTelemetry initialized successfully") // Return shutdown function return tp.Shutdown, nil } func getEnv(key, defaultValue string) string { if value := os.Getenv(key); value != "" { return value } return defaultValue } ``` Use in your main application: ```go showLineNumbers title="cmd/server/main.go" package main import ( "context" "log" "os" "os/signal" "syscall" "time" "github.com/labstack/echo/v4" "go.opentelemetry.io/contrib/instrumentation/github.com/labstack/echo/otelecho" "your-module/internal/tracing" ) func main() { // Initialize OpenTelemetry shutdown, err := tracing.InitTracer("echo-api", "1.0.0") if err != nil { log.Fatalf("Failed to initialize tracer: %v", err) } defer func() { ctx, cancel := context.WithTimeout(context.Background(), 5*time.Second) defer cancel() if err := shutdown(ctx); err != nil { log.Printf("Error shutting down tracer: %v", err) } }() // Create Echo server with tracing middleware e := echo.New() e.Use(otelecho.Middleware("echo-api")) // Define routes e.GET("/", handleRoot) e.GET("/users/:id", handleGetUser) // Start server with graceful shutdown go func() { if err := e.Start(":8080"); err != nil { log.Printf("Server error: %v", err) } }() // Wait for interrupt signal quit := make(chan os.Signal, 1) signal.Notify(quit, syscall.SIGINT, syscall.SIGTERM) <-quit ctx, cancel := context.WithTimeout(context.Background(), 10*time.Second) defer cancel() if err := e.Shutdown(ctx); err != nil { log.Fatal(err) } } func handleRoot(c echo.Context) error { return c.String(200, "Hello, World!") } func handleGetUser(c echo.Context) error { return c.JSON(200, map[string]string{"id": c.Param("id")}) } ``` ```mdx-code-block ``` For containerized deployments: ```bash showLineNumbers title=".env" # Service identification OTEL_SERVICE_NAME=go-api OTEL_SERVICE_VERSION=1.0.0 DEPLOYMENT_ENV=development # Exporter configuration OTEL_EXPORTER_OTLP_ENDPOINT=scout-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf # Resource attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=backend # Sampling (optional) OTEL_TRACES_SAMPLER=parentbased_always_on ``` ```mdx-code-block ``` ```go showLineNumbers title="internal/tracing/production.go" package tracing import ( "context" "crypto/tls" "go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp" sdktrace "go.opentelemetry.io/otel/sdk/trace" ) func InitProductionTracer(serviceName string) (func(context.Context) error, error) { ctx := context.Background() // Create OTLP exporter with TLS exporter, err := otlptracehttp.New(ctx, otlptracehttp.WithEndpoint(os.Getenv("OTEL_EXPORTER_OTLP_ENDPOINT")), otlptracehttp.WithTLSClientConfig(&tls.Config{ MinVersion: tls.VersionTLS12, }), otlptracehttp.WithHeaders(map[string]string{ "Authorization": "Bearer " + os.Getenv("SCOUT_API_KEY"), }), ) if err != nil { return nil, err } // Resource with Kubernetes/container metadata res, err := resource.New(ctx, resource.WithAttributes( semconv.ServiceName(serviceName), semconv.ServiceVersion(os.Getenv("SERVICE_VERSION")), semconv.DeploymentEnvironment(os.Getenv("DEPLOYMENT_ENV")), semconv.ServiceInstanceID(os.Getenv("HOSTNAME")), semconv.K8SPodName(os.Getenv("K8S_POD_NAME")), semconv.K8SNamespaceName(os.Getenv("K8S_NAMESPACE")), semconv.ContainerID(os.Getenv("CONTAINER_ID")), ), resource.WithHost(), resource.WithProcess(), ) if err != nil { return nil, err } tp := sdktrace.NewTracerProvider( sdktrace.WithBatcher(exporter, sdktrace.WithMaxQueueSize(2048), sdktrace.WithMaxExportBatchSize(512), ), sdktrace.WithResource(res), sdktrace.WithSampler(sdktrace.ParentBased(sdktrace.AlwaysSample())), ) otel.SetTracerProvider(tp) otel.SetTextMapPropagator(propagation.NewCompositeTextMapPropagator( propagation.TraceContext{}, propagation.Baggage{}, )) return tp.Shutdown, nil } ``` ```mdx-code-block ``` ### Framework-Specific Instrumentation ```mdx-code-block ``` #### Echo Framework ```go showLineNumbers title="Echo with GORM and Asynq" package main import ( "github.com/labstack/echo/v4" "go.opentelemetry.io/contrib/instrumentation/github.com/labstack/echo/otelecho" "go.opentelemetry.io/contrib/instrumentation/gorm.io/gorm/otelgorm" "gorm.io/driver/postgres" "gorm.io/gorm" ) func main() { // Initialize tracing shutdown, _ := tracing.InitTracer("echo-api", "1.0.0") defer shutdown(context.Background()) // Setup GORM with OpenTelemetry db, err := gorm.Open(postgres.Open(os.Getenv("DATABASE_URL")), &gorm.Config{}) if err != nil { log.Fatal(err) } // Add GORM OpenTelemetry plugin if err := db.Use(otelgorm.NewPlugin()); err != nil { log.Fatal(err) } // Create Echo server e := echo.New() // Add OpenTelemetry middleware (should be first) e.Use(otelecho.Middleware("echo-api")) // Routes e.GET("/users", func(c echo.Context) error { var users []User // This query is automatically traced if err := db.WithContext(c.Request().Context()).Find(&users).Error; err != nil { return err } return c.JSON(200, users) }) e.GET("/users/:id", func(c echo.Context) error { var user User // Context propagation maintains trace hierarchy if err := db.WithContext(c.Request().Context()). First(&user, c.Param("id")).Error; err != nil { return err } return c.JSON(200, user) }) e.Start(":8080") } type User struct { ID uint `gorm:"primaryKey"` Name string Email string } ``` ```mdx-code-block ``` #### Fiber Framework ```go showLineNumbers title="Fiber with sqlx and River" package main import ( "github.com/gofiber/fiber/v2" "go.opentelemetry.io/contrib/instrumentation/github.com/gofiber/fiber/v2/otelfiber" "go.opentelemetry.io/contrib/instrumentation/database/sql/otelsql" "github.com/jmoiron/sqlx" _ "github.com/lib/pq" ) func main() { // Initialize tracing shutdown, _ := tracing.InitTracer("fiber-api", "1.0.0") defer shutdown(context.Background()) // Setup sqlx with OpenTelemetry db, err := otelsql.Open("postgres", os.Getenv("DATABASE_URL"), otelsql.WithAttributes( semconv.DBSystemPostgreSQL, ), ) if err != nil { log.Fatal(err) } defer db.Close() // Register stats for monitoring if err := otelsql.RegisterDBStatsMetrics(db, otelsql.WithAttributes( semconv.DBSystemPostgreSQL, )); err != nil { log.Fatal(err) } sqlxDB := sqlx.NewDb(db, "postgres") // Create Fiber app app := fiber.New() // Add OpenTelemetry middleware app.Use(otelfiber.Middleware()) // Routes app.Get("/users", func(c *fiber.Ctx) error { ctx := c.UserContext() var users []User // Query is automatically traced if err := sqlxDB.SelectContext(ctx, &users, "SELECT * FROM users"); err != nil { return err } return c.JSON(users) }) app.Get("/users/:id", func(c *fiber.Ctx) error { ctx := c.UserContext() id := c.Params("id") var user User // Context propagation maintains trace if err := sqlxDB.GetContext(ctx, &user, "SELECT * FROM users WHERE id = $1", id); err != nil { return err } return c.JSON(user) }) app.Listen(":8080") } ``` ```mdx-code-block ``` #### Chi Router ```go showLineNumbers title="Chi with custom middleware" package main import ( "net/http" "github.com/go-chi/chi/v5" "go.opentelemetry.io/contrib/instrumentation/net/http/otelhttp" ) func main() { // Initialize tracing shutdown, _ := tracing.InitTracer("chi-api", "1.0.0") defer shutdown(context.Background()) r := chi.NewRouter() // Add OpenTelemetry middleware r.Use(func(next http.Handler) http.Handler { return otelhttp.NewHandler(next, "chi-api") }) r.Get("/", func(w http.ResponseWriter, r *http.Request) { w.Write([]byte("Hello, World!")) }) r.Get("/users/{id}", func(w http.ResponseWriter, r *http.Request) { userID := chi.URLParam(r, "id") // Custom span for business logic ctx := r.Context() tracer := otel.Tracer("chi-api") ctx, span := tracer.Start(ctx, "getUserByID") defer span.End() span.SetAttributes(attribute.String("user.id", userID)) // Your business logic here w.Write([]byte("User: " + userID)) }) http.ListenAndServe(":8080", r) } ``` ```mdx-code-block ``` ### Database Instrumentation ```mdx-code-block ``` #### GORM (Echo/Gin) ```go showLineNumbers title="GORM with OpenTelemetry plugin" package database import ( "gorm.io/driver/postgres" "gorm.io/gorm" "go.opentelemetry.io/contrib/instrumentation/gorm.io/gorm/otelgorm" ) func NewDB(dsn string) (*gorm.DB, error) { db, err := gorm.Open(postgres.Open(dsn), &gorm.Config{}) if err != nil { return nil, err } // Add OpenTelemetry plugin if err := db.Use(otelgorm.NewPlugin( otelgorm.WithDBName("myapp"), otelgorm.WithAttributes( semconv.DBSystemPostgreSQL, ), )); err != nil { return nil, err } return db, nil } // Usage in handler func GetUsers(c echo.Context) error { ctx := c.Request().Context() var users []User // Automatically traced query if err := db.WithContext(ctx). Preload("Orders"). Where("active = ?", true). Find(&users).Error; err != nil { return err } return c.JSON(200, users) } ``` ```mdx-code-block ``` #### sqlx (Fiber) ```go showLineNumbers title="sqlx with otelsql" package database import ( "database/sql" "github.com/jmoiron/sqlx" "go.opentelemetry.io/contrib/instrumentation/database/sql/otelsql" semconv "go.opentelemetry.io/otel/semconv/v1.26.0" ) func NewSqlxDB(dsn string) (*sqlx.DB, error) { // Register driver with OpenTelemetry db, err := otelsql.Open("postgres", dsn, otelsql.WithAttributes(semconv.DBSystemPostgreSQL), otelsql.WithSpanOptions(otelsql.SpanOptions{ Ping: true, RowsNext: true, DisableErrSkip: true, DisableQuery: false, QueryFormatter: nil, }), ) if err != nil { return nil, err } // Register DB stats metrics if err := otelsql.RegisterDBStatsMetrics(db, otelsql.WithAttributes(semconv.DBSystemPostgreSQL)); err != nil { return nil, err } return sqlx.NewDb(db, "postgres"), nil } // Repository pattern with context type UserRepository struct { db *sqlx.DB } func (r *UserRepository) GetByID(ctx context.Context, id int) (*User, error) { var user User // Query is automatically traced err := r.db.GetContext(ctx, &user, `SELECT id, name, email FROM users WHERE id = $1`, id) return &user, err } func (r *UserRepository) List(ctx context.Context) ([]User, error) { var users []User // Automatically traced err := r.db.SelectContext(ctx, &users, `SELECT id, name, email FROM users ORDER BY created_at DESC`) return users, err } ``` ```mdx-code-block ``` ### Redis Instrumentation ```go showLineNumbers title="Redis with OpenTelemetry" package cache import ( "context" "github.com/redis/go-redis/v9" "go.opentelemetry.io/contrib/instrumentation/github.com/redis/go-redis/v9/redisotel" ) func NewRedisClient(addr string) *redis.Client { rdb := redis.NewClient(&redis.Options{ Addr: addr, }) // Add OpenTelemetry hooks if err := redisotel.InstrumentTracing(rdb); err != nil { panic(err) } // Optional: Add metrics if err := redisotel.InstrumentMetrics(rdb); err != nil { panic(err) } return rdb } // Usage in service type CacheService struct { redis *redis.Client } func (s *CacheService) Get(ctx context.Context, key string) (string, error) { // Automatically traced return s.redis.Get(ctx, key).Result() } func (s *CacheService) Set(ctx context.Context, key, value string, ttl time.Duration) error { // Automatically traced return s.redis.Set(ctx, key, value, ttl).Err() } ``` ### Background Jobs #### Asynq (Task Queue) ```go showLineNumbers title="Asynq with tracing" package jobs import ( "context" "encoding/json" "github.com/hibiken/asynq" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/trace" ) const TypeEmailDelivery = "email:delivery" type EmailPayload struct { UserID int Email string } // Task creation with trace context func NewEmailDeliveryTask(ctx context.Context, userID int, email string) (*asynq.Task, error) { tracer := otel.Tracer("asynq-tasks") _, span := tracer.Start(ctx, "CreateEmailTask") defer span.End() payload, err := json.Marshal(EmailPayload{ UserID: userID, Email: email, }) if err != nil { span.RecordError(err) return nil, err } span.SetAttributes( attribute.Int("user.id", userID), attribute.String("task.type", TypeEmailDelivery), ) return asynq.NewTask(TypeEmailDelivery, payload), nil } // Handler with tracing func HandleEmailDeliveryTask(ctx context.Context, t *asynq.Task) error { tracer := otel.Tracer("asynq-handler") ctx, span := tracer.Start(ctx, "HandleEmailDelivery") defer span.End() var p EmailPayload if err := json.Unmarshal(t.Payload(), &p); err != nil { span.RecordError(err) return err } span.SetAttributes( attribute.Int("user.id", p.UserID), attribute.String("email", p.Email), ) // Send email if err := sendEmail(ctx, p.Email); err != nil { span.RecordError(err) return err } return nil } func sendEmail(ctx context.Context, email string) error { tracer := otel.Tracer("email-sender") _, span := tracer.Start(ctx, "sendEmail") defer span.End() // Email sending logic span.SetAttributes(attribute.String("email.to", email)) return nil } ``` #### River (PostgreSQL-native queue) ```go showLineNumbers title="River with tracing" package jobs import ( "context" "github.com/riverqueue/river" "go.opentelemetry.io/otel" ) type EmailArgs struct { UserID int Email string } func (EmailArgs) Kind() string { return "email" } type EmailWorker struct { river.WorkerDefaults[EmailArgs] } func (w *EmailWorker) Work(ctx context.Context, job *river.Job[EmailArgs]) error { tracer := otel.Tracer("river-worker") ctx, span := tracer.Start(ctx, "EmailWorker.Work") defer span.End() span.SetAttributes( attribute.Int("user.id", job.Args.UserID), attribute.String("job.kind", job.Kind), attribute.Int("job.attempt", job.Attempt), ) // Process email if err := processEmail(ctx, job.Args); err != nil { span.RecordError(err) return err } return nil } ``` ### Custom Instrumentation For business logic and application-specific operations: ```go showLineNumbers title="services/order_service.go" package services import ( "context" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/codes" "go.opentelemetry.io/otel/trace" ) type OrderService struct { db *gorm.DB cache *redis.Client } func (s *OrderService) CreateOrder(ctx context.Context, userID int, items []OrderItem) (*Order, error) { tracer := otel.Tracer("order-service") ctx, span := tracer.Start(ctx, "OrderService.CreateOrder") defer span.End() span.SetAttributes( attribute.Int("user.id", userID), attribute.Int("items.count", len(items)), ) // Validate inventory ctx, validateSpan := tracer.Start(ctx, "validateInventory") available, err := s.checkInventory(ctx, items) if err != nil { validateSpan.RecordError(err) validateSpan.SetStatus(codes.Error, "inventory check failed") validateSpan.End() return nil, err } validateSpan.SetAttributes(attribute.Bool("inventory.available", available)) validateSpan.End() if !available { span.SetStatus(codes.Error, "insufficient inventory") return nil, ErrInsufficientInventory } // Create order ctx, createSpan := tracer.Start(ctx, "createOrderRecord") order := &Order{ UserID: userID, Items: items, Total: calculateTotal(items), } if err := s.db.WithContext(ctx).Create(order).Error; err != nil { createSpan.RecordError(err) createSpan.SetStatus(codes.Error, "database error") createSpan.End() return nil, err } createSpan.SetAttributes(attribute.Int("order.id", int(order.ID))) createSpan.End() // Process payment ctx, paymentSpan := tracer.Start(ctx, "processPayment") if err := s.processPayment(ctx, order.ID, order.Total); err != nil { paymentSpan.RecordError(err) paymentSpan.SetStatus(codes.Error, "payment failed") paymentSpan.End() return nil, err } paymentSpan.End() span.SetStatus(codes.Ok, "order created successfully") return order, nil } func (s *OrderService) checkInventory(ctx context.Context, items []OrderItem) (bool, error) { // Business logic return true, nil } func (s *OrderService) processPayment(ctx context.Context, orderID uint, amount float64) error { tracer := otel.Tracer("payment-service") _, span := tracer.Start(ctx, "processPayment") defer span.End() span.SetAttributes( attribute.Int("order.id", int(orderID)), attribute.Float64("payment.amount", amount), ) // Payment processing logic return nil } func calculateTotal(items []OrderItem) float64 { var total float64 for _, item := range items { total += item.Price * float64(item.Quantity) } return total } ``` ### Running Your Application #### Development Mode ```bash showLineNumbers # With environment variables export OTEL_EXPORTER_OTLP_ENDPOINT=localhost:4318 export DEPLOYMENT_ENV=development go run cmd/server/main.go ``` #### Production Mode ```bash showLineNumbers # Build optimized binary go build -ldflags="-s -w" -o server cmd/server/main.go # Run with production config export OTEL_SERVICE_NAME=go-api export OTEL_EXPORTER_OTLP_ENDPOINT=scout-collector:4318 export DEPLOYMENT_ENV=development ./server ``` #### Docker Deployment ```dockerfile showLineNumbers title="Dockerfile" FROM golang:1.22-alpine AS builder WORKDIR /app COPY go.mod go.sum ./ RUN go mod download COPY . . RUN CGO_ENABLED=0 GOOS=linux go build -ldflags="-s -w" -o server cmd/server/main.go FROM alpine:latest RUN apk --no-cache add ca-certificates WORKDIR /root/ COPY --from=builder /app/server . ENV OTEL_SERVICE_NAME=go-api ENV DEPLOYMENT_ENV=demo EXPOSE 8080 CMD ["./server"] ``` ```yaml showLineNumbers title="docker-compose.yml" version: '3.8' services: go-api: build: . ports: - '8080:8080' environment: - OTEL_SERVICE_NAME=go-api - OTEL_SERVICE_VERSION=1.0.0 - OTEL_EXPORTER_OTLP_ENDPOINT=scout-collector:4318 - DATABASE_URL=postgres://user:pass@postgres:5432/godb - REDIS_URL=redis:6379 depends_on: - postgres - redis - scout-collector postgres: image: postgres:16-alpine environment: POSTGRES_DB: godb POSTGRES_USER: user POSTGRES_PASSWORD: pass redis: image: redis:7-alpine scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4318:4318' ``` ### Troubleshooting #### Issue: No Traces Appearing in Scout **Solutions:** 1. Verify collector connectivity: ```go // Test exporter connection exporter, err := otlptracehttp.New(context.Background(), otlptracehttp.WithEndpoint("localhost:4318"), otlptracehttp.WithInsecure(), ) if err != nil { log.Fatal("Failed to create exporter:", err) } ``` 1. Enable debug logging: ```go import "go.opentelemetry.io/otel/exporters/stdout/stdouttrace" // Use console exporter for debugging exporter, _ := stdouttrace.New(stdouttrace.WithPrettyPrint()) ``` 1. Verify tracer provider is set: ```go if otel.GetTracerProvider() == nil { log.Fatal("Tracer provider not initialized") } ``` #### Issue: Missing Context in Goroutines **Solutions:** Always pass context to goroutines: ```go // WRONG - loses trace context go func() { span := trace.SpanFromContext(context.Background()) // nil! }() // CORRECT - preserve context go func(ctx context.Context) { span := trace.SpanFromContext(ctx) // Works! }(ctx) ``` #### Issue: Database Queries Not Traced **Solutions:** 1. Ensure you're using `WithContext`: ```go // WRONG - no context db.Find(&users) // CORRECT - with context db.WithContext(ctx).Find(&users) ``` 1. For sqlx, use `Context` methods: ```go // WRONG db.Select(&users, query) // CORRECT db.SelectContext(ctx, &users, query) ``` #### Issue: High Memory Usage **Solutions:** Reduce batch sizes and queue limits: ```go sdktrace.WithBatcher(exporter, sdktrace.WithMaxQueueSize(1024), // Reduced sdktrace.WithMaxExportBatchSize(256), // Reduced ) ``` ### Performance Considerations OpenTelemetry adds minimal overhead to Go applications: **Expected Impact:** - **Latency**: +0.1-0.5ms per request - **CPU**: +1-3% in production - **Memory**: +5-15MB for trace buffers - **Goroutines**: +2-3 additional goroutines for exporter #### Optimization Best Practices ##### 1. Use Batch Span Processor ```go showLineNumbers tp := sdktrace.NewTracerProvider( sdktrace.WithBatcher(exporter, sdktrace.WithMaxQueueSize(2048), sdktrace.WithBatchTimeout(5*time.Second), ), ) ``` ##### 2. Skip Health Check Endpoints ```go showLineNumbers app.Use(func(next http.Handler) http.Handler { return http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) { // Skip tracing for health checks if r.URL.Path == "/health" || r.URL.Path == "/metrics" { next.ServeHTTP(w, r) return } otelhttp.NewHandler(next, "api").ServeHTTP(w, r) }) }) ``` ##### 3. Disable Query Parameter Logging ```go showLineNumbers otelsql.Open("postgres", dsn, otelsql.WithSpanOptions(otelsql.SpanOptions{ DisableQuery: true, // Don't log full queries }), ) ``` ##### 5. Reuse HTTP Clients ```go showLineNumbers // Create once, reuse var httpClient = &http.Client{ Transport: otelhttp.NewTransport(http.DefaultTransport), } ``` ### Security Considerations #### Sensitive Data Protection ```go showLineNumbers // BAD - Exposes sensitive data span.SetAttributes( attribute.String("user.password", password), attribute.String("credit_card", ccNumber), ) // GOOD - Use safe identifiers span.SetAttributes( attribute.Int("user.id", userID), attribute.String("payment.method", "credit_card"), ) ``` #### SQL Query Sanitization ```go showLineNumbers // Parameters are automatically sanitized by otelsql db.SelectContext(ctx, &users, "SELECT * FROM users WHERE email = $1", email) // Safe ``` ### FAQ #### Does OpenTelemetry work with all Go web frameworks? Yes, OpenTelemetry supports Echo, Fiber, Chi, Gin, and standard `net/http` through various instrumentation packages. #### What is the performance impact of OpenTelemetry on Go applications? Minimal: +0.1-0.5ms latency, +1-3% CPU, +5-15MB memory. Go's efficient goroutines make OpenTelemetry very lightweight. #### Can I trace GORM, sqlx, and standard database/sql? Yes, use `otelgorm` for GORM, `otelsql` for sqlx and database/sql. All SQL queries are automatically traced. #### How do I propagate OpenTelemetry trace context across goroutines in Go? Pass context to goroutines: `go func(ctx context.Context) { ... }(ctx)` to maintain trace hierarchy. #### Does OpenTelemetry work with gRPC in Go? Yes, use `go.opentelemetry.io/contrib/instrumentation/google.golang.org/grpc/otelgrpc` for automatic gRPC tracing. #### Can I trace Asynq and River background jobs? Yes, add custom spans in task handlers using `otel.Tracer()` as shown in the Background Jobs section. #### How do I handle context propagation across services? OpenTelemetry automatically propagates context via HTTP headers using W3C Trace Context and Baggage. #### What's the difference between traces and metrics? Traces show request flow through your app. Metrics aggregate performance data. Both are supported by OpenTelemetry. #### Can I trace GORM and sqlx database queries with OpenTelemetry in Go? Yes. Use `otelgorm` for GORM and `otelsql` for sqlx and `database/sql`. Each query becomes a span with the SQL recorded on it. Set `DisableQuery: true` in `otelsql.SpanOptions` to keep the query text out of spans. ### What's Next? #### Framework-Specific Examples - [Echo Example](https://github.com/base-14/examples/tree/main/go/echo-postgres) \- Echo + GORM + Asynq - [Fiber Example](https://github.com/base-14/examples/tree/main/go/fiber-postgres) \- Fiber + sqlx + River - [Chi Example](https://github.com/base-14/examples/tree/main/go/chi-inmemory) \- Chi + in-memory #### Advanced Topics - [Custom Go Instrumentation](../custom-instrumentation/go.md) - Advanced patterns and custom exporters #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for latency and errors - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment ### Complete Example ```bash showLineNumbers title="go.mod" module github.com/example/go-api go 1.22 require ( github.com/labstack/echo/v4 v4.13.0 go.opentelemetry.io/contrib/instrumentation/github.com/labstack/echo/otelecho v0.54.0 go.opentelemetry.io/contrib/instrumentation/gorm.io/gorm/otelgorm v0.54.0 go.opentelemetry.io/otel v1.32.0 go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp v1.32.0 go.opentelemetry.io/otel/sdk v1.32.0 gorm.io/driver/postgres v1.5.12 gorm.io/gorm v1.25.12 ) ``` Complete working examples: [GitHub: base-14/examples/go](https://github.com/base-14/examples/tree/main/go) With traces flowing, you can [explore Go service traces in Scout](https://base14.io/scout/traces) — follow requests across HTTP handlers, gRPC calls, and database operations with full distributed context. ### References - [Official OpenTelemetry Go Documentation](https://opentelemetry.io/docs/languages/go/) - [OpenTelemetry Go SDK](https://pkg.go.dev/go.opentelemetry.io/otel) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Go Custom Instrumentation](../custom-instrumentation/go.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development - [Kubernetes Deployment](../../collector-setup/kubernetes-helm-setup.md) - Production setup --- ## Hono OpenTelemetry Instrumentation - HTTP, Database & Redis Tracing ## Hono Implement OpenTelemetry instrumentation for Hono applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your Hono application to collect traces and metrics from HTTP requests, database queries, Redis operations, background jobs, and custom business logic using the OpenTelemetry Node.js SDK with minimal code changes. Hono applications benefit from automatic instrumentation of HTTP and database layers, combined with the `@hono/otel` middleware for framework-specific span generation. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database query bottlenecks. Hono's lightweight design and middleware architecture work seamlessly with OpenTelemetry's context propagation, ensuring accurate parent-child span relationships across async operations including BullMQ background jobs. As a lightweight, middleware-first framework, Hono is a leaner alternative to [Express](./express.md) and shares its modern design with [Elysia](./elysia.md) on the Bun runtime. The instrumentation approach in this guide carries over to both. Whether you're implementing observability for the first time, migrating from commercial APM solutions like DataDog or New Relic, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Hono OpenTelemetry instrumentation. :::tip TL;DR Create a `telemetry.ts` file, initialize the OpenTelemetry Node.js SDK there, and import it as the very first line of your entry point before any other module. Add `@hono/otel` middleware and `@opentelemetry/auto-instrumentations-node` to get automatic HTTP, PostgreSQL, and Redis spans with no additional instrumentation code. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry instrumentation for Hono applications - Configure automatic request tracing with `@hono/otel` middleware - Instrument database operations with PostgreSQL auto-instrumentation - Implement custom spans for business logic with `startActiveSpan` - Trace background jobs with BullMQ and propagate context to workers - Bridge Pino structured logging with OpenTelemetry trace correlation - Configure Prometheus metrics alongside OpenTelemetry - Validate request input with Zod via `@hono/zod-validator` - Export telemetry data to base14 Scout via OTLP HTTP - Deploy instrumented applications with Docker and Docker Compose ### Who This Guide Is For This documentation is designed for: - **Hono developers**: implementing observability and distributed tracing for the first time in Node.js applications - **DevOps engineers**: deploying Hono applications with production monitoring requirements and container orchestration - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-source observability - **Backend developers**: debugging performance issues, slow queries, or async operation bottlenecks in Hono services - **Platform teams**: standardizing observability across multiple Hono microservices with consistent instrumentation patterns ### Prerequisites Before starting, ensure you have: - **Node.js 24.0.0 or later** installed (latest LTS recommended) - **Hono 4.0.0 or later** installed in your project - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment - **Basic understanding** of OpenTelemetry concepts (traces, spans, attributes) - Access to npm for package installation #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | ------------------------- | --------------- | ------------------- | ----------------------------- | | **Node.js** | 24.0.0 | 24.x LTS | Latest LTS with ESM support | | **Hono** | 4.0.0 | 4.11.9+ | Latest v4 with middleware | | **TypeScript** (optional) | 5.0.0 | 5.9.3+ | For type safety | | **OpenTelemetry SDK** | 0.200.0 | 0.212+ | Core SDK for traces/metrics | | **PostgreSQL** (optional) | 15.0 | 18.x | For database instrumentation | | **Redis** (optional) | 7.0 | 8.x | For IORedis instrumentation | | **Drizzle ORM** (optional)| 0.40.0 | 0.45.1+ | Type-safe SQL builder | #### Supported Libraries OpenTelemetry automatically instruments these commonly used libraries: - **Web frameworks**: Hono (via @hono/otel), HTTP/HTTPS - **Databases**: PostgreSQL (pg), MySQL, SQLite - **Caching**: Redis (IORedis), Memcached - **Job Queues**: BullMQ - **HTTP Clients**: fetch, axios, http/https - **Logging**: Pino (with trace correlation) ### Installation #### Core Packages Install the required OpenTelemetry packages for Hono instrumentation: ```bash showLineNumbers npm install @opentelemetry/api npm install @opentelemetry/sdk-node npm install @opentelemetry/auto-instrumentations-node npm install @opentelemetry/exporter-trace-otlp-http npm install @opentelemetry/exporter-metrics-otlp-http npm install @opentelemetry/resources npm install @opentelemetry/semantic-conventions ``` #### Hono-Specific Packages ```bash showLineNumbers npm install @hono/otel npm install @hono/node-server npm install @hono/zod-validator ``` #### Optional Instrumentation Libraries ```bash showLineNumbers # Logs export npm install @opentelemetry/api-logs npm install @opentelemetry/sdk-logs npm install @opentelemetry/exporter-logs-otlp-http # Pino trace correlation npm install pino pino-opentelemetry-transport # Prometheus metrics npm install prom-client ``` ### Configuration Choose the initialization method that best fits your application architecture: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` #### SDK Configuration File (Recommended) Create a `telemetry.ts` file that initializes OpenTelemetry before any other imports. This is the recommended approach for Hono applications. ```typescript showLineNumbers title="src/telemetry.ts" /** * OpenTelemetry instrumentation setup for Hono application. * * CRITICAL: This file MUST be imported before any other modules * to ensure auto-instrumentation captures all dependencies. */ import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { BatchLogRecordProcessor } from '@opentelemetry/sdk-logs'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const serviceName = process.env.OTEL_SERVICE_NAME || 'hono-postgres-app'; const serviceVersion = process.env.OTEL_SERVICE_VERSION || '1.0.0'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: serviceName, [ATTR_SERVICE_VERSION]: serviceVersion, }); const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: `${otlpEndpoint}/v1/traces`, }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 60000, }), logRecordProcessor: new BatchLogRecordProcessor( new OTLPLogExporter({ url: `${otlpEndpoint}/v1/logs`, }) ), instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const url = req.url || ''; return url === '/health' || url === '/metrics'; }, }, '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-pg': { requireParentSpan: true }, }), ], }); sdk.start(); process.on('SIGTERM', () => { sdk .shutdown() .then(() => console.log('OpenTelemetry SDK shut down')) .catch((err) => console.error('Error shutting down SDK', err)) .finally(() => process.exit(0)); }); export { sdk }; ``` Import this file as the first line in your application entry point: ```typescript showLineNumbers title="src/index.ts" import './telemetry.js'; import { serve } from '@hono/node-server'; import { app } from './app.js'; import { config } from './config/index.js'; const start = async () => { serve({ fetch: app.fetch, port: config.port, hostname: config.host, }); console.log(`Server running at http://${config.host}:${config.port}`); }; start(); ``` ```mdx-code-block ``` #### Environment Variables Only For simpler setups or container deployments: ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=hono-postgres-app OTEL_SERVICE_VERSION=1.0.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp ``` Then use a minimal telemetry file: ```typescript showLineNumbers title="src/telemetry.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; const sdk = new NodeSDK({ instrumentations: [getNodeAutoInstrumentations()], }); sdk.start(); ``` ```mdx-code-block ``` #### Scout Collector Integration Configure for base14 Scout with OAuth2 authentication: ```yaml showLineNumbers title="config/otel-config.yaml" extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s health_check: endpoint: 0.0.0.0:13133 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: limit_mib: 256 check_interval: 1s batch: timeout: 10s send_batch_size: 1024 resource: attributes: - key: deployment.environment value: ${env:SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${env:SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${env:SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: detailed service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] ``` ```mdx-code-block ``` ### Production Configuration #### Docker Deployment ```dockerfile showLineNumbers title="Dockerfile" # Stage 1: Dependencies FROM node:24.13.1-alpine3.23 AS deps WORKDIR /app COPY package.json package-lock.json* ./ RUN npm ci --ignore-scripts # Stage 2: Builder FROM node:24.13.1-alpine3.23 AS builder WORKDIR /app COPY --from=deps /app/node_modules ./node_modules COPY . . RUN npm run build # Stage 3: Runtime FROM node:24.13.1-alpine3.23 AS runtime WORKDIR /app RUN apk add --no-cache curl gcompat ENV NODE_ENV=production COPY --from=deps /app/node_modules ./node_modules COPY --from=builder /app/dist ./dist COPY --from=builder /app/package.json ./ COPY --from=builder /app/drizzle ./drizzle RUN addgroup --system --gid 1001 nodejs && \ adduser --system --uid 1001 hono && \ chown -R hono:nodejs /app USER hono EXPOSE 3000 CMD ["node", "dist/index.js"] ``` #### Docker Compose Configuration ```yaml showLineNumbers title="compose.yml" services: db-migrate: build: context: . target: runtime command: ["node", "dist/db/migrate.js"] environment: DATABASE_URL: postgresql://postgres:postgres@postgres:5432/hono_app depends_on: postgres: condition: service_healthy networks: - app-network app: build: context: . target: runtime ports: - "3000:3000" environment: NODE_ENV: development PORT: "3000" JWT_SECRET: dev-secret-key-change-in-production-must-be-32-chars DATABASE_URL: postgresql://postgres:postgres@postgres:5432/hono_app REDIS_URL: redis://redis:6379 OTEL_SERVICE_NAME: hono-postgres-app OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 depends_on: db-migrate: condition: service_completed_successfully redis: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-f", "http://localhost:3000/health"] interval: 30s timeout: 10s retries: 3 networks: - app-network worker: build: context: . target: runtime command: ["node", "dist/jobs/worker.js"] environment: NODE_ENV: development DATABASE_URL: postgresql://postgres:postgres@postgres:5432/hono_app REDIS_URL: redis://redis:6379 OTEL_SERVICE_NAME: hono-postgres-worker OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 depends_on: db-migrate: condition: service_completed_successfully redis: condition: service_healthy networks: - app-network postgres: image: postgres:18.2-alpine3.23 environment: POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres POSTGRES_DB: hono_app ports: - "5433:5432" healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 networks: - app-network redis: image: redis:8.6.0-alpine3.23 ports: - "6379:6379" healthcheck: test: ["CMD", "redis-cli", "ping"] interval: 5s timeout: 5s retries: 5 networks: - app-network otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otelcol-config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otelcol-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" env_file: - path: .env required: false environment: SCOUT_ENDPOINT: ${SCOUT_ENDPOINT:-http://localhost:4318} SCOUT_CLIENT_ID: ${SCOUT_CLIENT_ID:-} SCOUT_CLIENT_SECRET: ${SCOUT_CLIENT_SECRET:-} SCOUT_TOKEN_URL: ${SCOUT_TOKEN_URL:-} SCOUT_ENVIRONMENT: ${SCOUT_ENVIRONMENT:-development} networks: - app-network networks: app-network: driver: bridge ``` ### Framework-Specific Instrumentation #### Hono Middleware and Plugins Hono's middleware system integrates with OpenTelemetry via `@hono/otel`: ```typescript showLineNumbers title="src/app.ts" import { Hono } from 'hono'; import { cors } from 'hono/cors'; import { secureHeaders } from 'hono/secure-headers'; import { httpInstrumentationMiddleware } from '@hono/otel'; import { trace } from '@opentelemetry/api'; import client from 'prom-client'; import type { Variables } from './types/index.js'; const app = new Hono<{ Variables: Variables }>(); // Prometheus metrics const register = new client.Registry(); register.setDefaultLabels({ app: 'hono-postgres' }); client.collectDefaultMetrics({ register }); const httpRequestsTotal = new client.Counter({ name: 'http_requests_total', help: 'Total HTTP requests', labelNames: ['method', 'route', 'status_code'] as const, registers: [register], }); const httpRequestDuration = new client.Histogram({ name: 'http_request_duration_seconds', help: 'HTTP request duration in seconds', labelNames: ['method', 'route', 'status_code'] as const, buckets: [0.001, 0.005, 0.01, 0.025, 0.05, 0.1, 0.25, 0.5, 1, 2.5, 5, 10], registers: [register], }); // Global middleware app.use('*', httpInstrumentationMiddleware()); app.use('*', secureHeaders()); app.use('*', cors({ origin: '*' })); // Metrics collection middleware app.use('*', async (c, next) => { const start = performance.now(); await next(); const duration = (performance.now() - start) / 1000; const route = c.req.routePath || c.req.path; httpRequestsTotal.inc({ method: c.req.method, route, status_code: c.res.status.toString(), }); httpRequestDuration.observe( { method: c.req.method, route, status_code: c.res.status.toString() }, duration ); }); // Prometheus metrics endpoint app.get('/metrics', async (c) => { const metrics = await register.metrics(); return c.text(metrics, 200, { 'Content-Type': register.contentType }); }); // Global error handler with trace ID app.onError((err, c) => { const span = trace.getActiveSpan(); const traceId = span?.spanContext()?.traceId; return c.json( { error: err.message, statusCode: 500, ...(traceId && { traceId }), }, 500 ); }); export { app, register }; ``` #### Pino Logger with OpenTelemetry Bridge Structured logging with automatic trace correlation: ```typescript showLineNumbers title="src/services/logger.ts" import pino, { Logger, LoggerOptions } from 'pino'; import { trace } from '@opentelemetry/api'; import { logs as otelLogs, SeverityNumber } from '@opentelemetry/api-logs'; const isDevelopment = process.env.NODE_ENV === 'development'; function createLoggerOptions(name: string): LoggerOptions { return { level: process.env.LOG_LEVEL || 'info', name, formatters: { log(object: Record) { const span = trace.getActiveSpan(); if (span) { const { traceId, spanId } = span.spanContext(); return { ...object, traceId, spanId }; } return object; }, }, hooks: { logMethod(inputArgs, method, level) { const levelLabel = pino.levels.labels[level] || 'info'; const [objOrMsg, ...rest] = inputArgs; let msg = ''; let obj: Record = {}; if (typeof objOrMsg === 'string') { msg = objOrMsg; } else if (typeof objOrMsg === 'object' && objOrMsg !== null) { obj = objOrMsg as Record; msg = rest[0] as string || ''; } if (levelLabel === 'warn' || levelLabel === 'error' || levelLabel === 'fatal') { const logger = otelLogs.getLogger('pino-otel-bridge'); const span = trace.getActiveSpan(); const spanContext = span?.spanContext(); const severityMap: Record = { warn: SeverityNumber.WARN, error: SeverityNumber.ERROR, fatal: SeverityNumber.FATAL, }; logger.emit({ severityNumber: severityMap[levelLabel] || SeverityNumber.INFO, severityText: levelLabel.toUpperCase(), body: msg, attributes: { ...obj, ...(spanContext && { 'trace.id': spanContext.traceId, 'span.id': spanContext.spanId, }), }, }); } method.apply(this, inputArgs); }, }, transport: isDevelopment ? { target: 'pino-pretty' } : undefined, }; } export function createLogger(name: string): Logger { return pino(createLoggerOptions(name)); } ``` #### Drizzle ORM with PostgreSQL Database queries are automatically instrumented through the `pg` driver: ```typescript showLineNumbers title="src/db/schema.ts" import { pgTable, varchar, text, timestamp, integer, uniqueIndex, index, } from 'drizzle-orm/pg-core'; import { relations } from 'drizzle-orm'; export const users = pgTable('users', { id: integer('id').primaryKey().generatedAlwaysAsIdentity(), email: varchar('email', { length: 255 }).notNull().unique(), passwordHash: varchar('password_hash', { length: 255 }).notNull(), name: varchar('name', { length: 255 }).notNull(), bio: text('bio'), image: varchar('image', { length: 500 }), createdAt: timestamp('created_at', { withTimezone: true }).defaultNow().notNull(), updatedAt: timestamp('updated_at', { withTimezone: true }).defaultNow().notNull(), }, (table) => [uniqueIndex('users_email_idx').on(table.email)]); export const articles = pgTable('articles', { id: integer('id').primaryKey().generatedAlwaysAsIdentity(), slug: varchar('slug', { length: 255 }).notNull().unique(), title: varchar('title', { length: 255 }).notNull(), description: text('description'), body: text('body').notNull(), authorId: integer('author_id').notNull() .references(() => users.id, { onDelete: 'cascade' }), favoritesCount: integer('favorites_count').default(0).notNull(), createdAt: timestamp('created_at', { withTimezone: true }).defaultNow().notNull(), updatedAt: timestamp('updated_at', { withTimezone: true }).defaultNow().notNull(), }, (table) => [ uniqueIndex('articles_slug_idx').on(table.slug), index('articles_author_id_idx').on(table.authorId), ]); export type User = typeof users.$inferSelect; export type NewUser = typeof users.$inferInsert; export type Article = typeof articles.$inferSelect; export type NewArticle = typeof articles.$inferInsert; ``` ```typescript showLineNumbers title="src/db/index.ts" import { drizzle } from 'drizzle-orm/node-postgres'; import pg from 'pg'; import * as schema from './schema.js'; const pool = new pg.Pool({ connectionString: process.env.DATABASE_URL, max: 10, idleTimeoutMillis: 30000, connectionTimeoutMillis: 2000, }); export const db = drizzle(pool, { schema }); ``` #### Zod Request Validation Use `@hono/zod-validator` for type-safe request validation: ```typescript showLineNumbers title="src/validators/article.ts" import { z } from 'zod'; export const createArticleSchema = z.object({ title: z.string().min(1, 'Title is required').max(255), description: z.string().max(1000).optional(), body: z.string().min(1, 'Body is required'), }); export const updateArticleSchema = z.object({ title: z.string().min(1).max(255).optional(), description: z.string().max(1000).optional(), body: z.string().min(1).optional(), }); ``` ```typescript showLineNumbers title="src/routes/articles.ts" import { zValidator } from '@hono/zod-validator'; import { createArticleSchema } from '../validators/article.js'; articlesRouter.post( '/', authenticate, zValidator('json', createArticleSchema), async (c) => { const data = c.req.valid('json'); const { id: userId } = c.get('user'); const article = await createArticle(userId, data); return c.json({ article }, 201); } ); ``` ### Custom Instrumentation #### Business Logic Spans with startActiveSpan Add custom spans for business-critical operations: ```typescript showLineNumbers title="src/services/article.ts" import { trace, SpanStatusCode } from '@opentelemetry/api'; import { db } from '../db/index.js'; import { articles, users } from '../db/schema.js'; import { enqueueArticleCreatedNotification } from '../jobs/tasks/notification.js'; const tracer = trace.getTracer('article-service'); export async function createArticle( authorId: number, input: { title: string; description?: string; body: string } ) { return tracer.startActiveSpan('article.create', async (span) => { try { span.setAttribute('user.id', authorId); const slug = generateSlug(input.title); const [newArticle] = await db .insert(articles) .values({ slug, title: input.title, description: input.description || null, body: input.body, authorId, }) .returning(); span.setAttribute('article.id', newArticle.id); span.setAttribute('article.slug', newArticle.slug); span.setStatus({ code: SpanStatusCode.OK }); enqueueArticleCreatedNotification({ articleId: newArticle.id, articleSlug: newArticle.slug, authorId, authorName: '', title: newArticle.title, }).catch((err) => { console.error('Failed to enqueue notification', err); }); return newArticle; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } }); } ``` #### Background Job Tracing with BullMQ ##### Producer: Inject Trace Context ```typescript showLineNumbers title="src/jobs/tasks/notification.ts" import { context, propagation, trace, SpanKind } from '@opentelemetry/api'; import { notificationQueue } from '../queue.js'; const tracer = trace.getTracer('notification-tasks'); function getTraceContext(): Record { const traceContext: Record = {}; propagation.inject(context.active(), traceContext); return traceContext; } export async function enqueueArticleCreatedNotification( payload: ArticleCreatedPayload ): Promise { return tracer.startActiveSpan( 'job.enqueue.article-created', { kind: SpanKind.PRODUCER }, async (span) => { try { span.setAttribute('article.id', payload.articleId); span.setAttribute('messaging.system', 'bullmq'); span.setAttribute('messaging.destination.name', 'notifications'); span.setAttribute('messaging.operation.type', 'publish'); const job = await notificationQueue.add('article-created', { ...payload, traceContext: getTraceContext(), }); span.setAttribute('job.id', job.id || 'unknown'); span.addEvent('job_enqueued'); } finally { span.end(); } } ); } ``` ##### Consumer: Extract and Restore Trace Context ```typescript showLineNumbers title="src/jobs/worker.ts" import '../telemetry.js'; import { Worker, Job } from 'bullmq'; import { trace, context, propagation, SpanStatusCode, SpanKind, } from '@opentelemetry/api'; const tracer = trace.getTracer('notification-worker'); const worker = new Worker( 'notifications', async (job) => { const parentContext = job.data.traceContext ? propagation.extract(context.active(), job.data.traceContext) : context.active(); return context.with(parentContext, async () => { return tracer.startActiveSpan( `job.${job.name}`, { kind: SpanKind.CONSUMER, attributes: { 'job.id': job.id || 'unknown', 'job.name': job.name, 'job.queue': 'notifications', 'job.attempt': job.attemptsMade + 1, 'messaging.system': 'bullmq', 'messaging.destination.name': 'notifications', 'messaging.operation.type': 'process', }, }, async (span) => { try { switch (job.name) { case 'article-created': await processArticleCreated(job); break; default: console.warn(`Unknown job type: ${job.name}`); } span.setStatus({ code: SpanStatusCode.OK }); } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } } ); }); }, { connection: { host: 'localhost', port: 6379 }, concurrency: 5 } ); ``` ### Running Your Application ```mdx-code-block ``` ```bash showLineNumbers npm run dev # In a separate terminal npm run dev:worker ``` ```mdx-code-block ``` ```bash showLineNumbers npm run build NODE_ENV=production \ OTEL_SERVICE_NAME=hono-postgres-app \ OTEL_EXPORTER_OTLP_ENDPOINT=http://collector:4318 \ node dist/index.js ``` ```mdx-code-block ``` ```bash showLineNumbers docker compose up --build docker compose logs -f app worker docker compose down ``` ```mdx-code-block ``` ### Troubleshooting #### Health Check Endpoint ```typescript showLineNumbers title="src/routes/health.ts" import { Hono } from 'hono'; import { trace } from '@opentelemetry/api'; import { checkDatabaseHealth } from '../db/index.js'; const healthRouter = new Hono(); healthRouter.get('/', async (c) => { const span = trace.getActiveSpan(); const traceId = span?.spanContext()?.traceId; const dbHealthy = await checkDatabaseHealth(); return c.json({ status: dbHealthy ? 'healthy' : 'unhealthy', database: dbHealthy ? 'connected' : 'disconnected', traceId, timestamp: new Date().toISOString(), }); }); export default healthRouter; ``` #### Debug Mode ```bash showLineNumbers OTEL_LOG_LEVEL=debug npm run dev ``` #### Common Issues ##### Issue: No traces appearing in Scout **Solutions:** 1. Verify collector connectivity: ```bash showLineNumbers curl -f http://localhost:4318/v1/traces ``` 2. Ensure `telemetry.ts` is imported first in `index.ts` 3. Check environment variables are set correctly 4. Verify Scout credentials in collector config ##### Issue: Missing database spans **Solutions:** 1. Ensure `@opentelemetry/auto-instrumentations-node` is installed 2. Verify the `pg` driver is being used (not `pg-native`) 3. Check that telemetry initialization happens before database import ##### Issue: Background job traces not linked **Solutions:** 1. Verify trace context is propagated to job data with `propagation.inject` 2. Ensure worker imports `telemetry.ts` before other modules 3. Check that `context.with()` wraps the job processor ##### Issue: High memory usage **Solutions:** 1. Reduce batch size in exporter configuration 2. Disable filesystem instrumentation (already disabled in recommended config) ### Security Considerations #### Sensitive Data Protection ```typescript showLineNumbers // BAD: Captures password span.setAttribute('user.password', password); // GOOD: Only capture non-sensitive identifiers span.setAttribute('user.id', userId); span.setAttribute('user.email_domain', email.split('@')[1]); ``` #### SQL Query Obfuscation ```typescript showLineNumbers title="src/telemetry.ts" instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-pg': { enhancedDatabaseReporting: false, }, }), ], ``` #### Compliance Considerations For GDPR, HIPAA, or PCI-DSS compliance: - Never log PII in span attributes - Use pseudonymization for user identifiers when possible - Configure data retention policies in your observability backend - Implement attribute filtering at the collector level ### Performance Considerations #### Expected Impact | Metric | Typical Impact | High-Traffic Impact | | ------------ | -------------- | ------------------- | | Latency | +1-3ms | +2-5ms | | CPU overhead | 2-5% | 5-10% | | Memory | +50-100MB | +100-200MB | #### Optimization Best Practices ##### 1. Skip Non-Critical Endpoints ```typescript showLineNumbers '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const url = req.url || ''; return url === '/health' || url === '/metrics' || url === '/favicon.ico'; }, }, ``` ##### 2. Disable Unnecessary Instrumentations ```typescript showLineNumbers instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, }), ], ``` ### FAQ #### What is the performance impact of OpenTelemetry on Hono? OpenTelemetry typically adds 1-3ms latency per request with 2-5% CPU overhead. The `BatchSpanProcessor` minimizes impact by buffering spans for batch export. #### Which versions of Hono are supported? This guide focuses on Hono 4.x with `@hono/otel` middleware. The same auto-instrumentation approach works with any Hono version since HTTP-level instrumentation is framework-agnostic. #### How does Hono OpenTelemetry middleware compare to Fastify? `@hono/otel` is a Hono middleware that creates spans with route-parameterized names. Fastify uses hooks and plugins. Both achieve the same result — automatic HTTP span generation with method, route, and status code. #### How do I instrument Hono with PostgreSQL and Drizzle ORM? PostgreSQL queries are automatically instrumented through the `pg` driver. Drizzle ORM uses `pg` under the hood, so all queries appear as database spans without additional configuration. #### How do I trace background jobs with BullMQ? Inject trace context when enqueuing with `propagation.inject()` and extract it in the worker with `propagation.extract()`. Wrap the worker processor in `context.with(parentContext, ...)` to link consumer spans to the producer. #### How do I correlate Pino logs with traces? The custom `createLogger` function adds `traceId` and `spanId` to every log entry automatically. Warn, error, and fatal logs are also emitted to the OTel log provider for export alongside traces. #### Can I use Prometheus metrics alongside OpenTelemetry? Yes. The example uses `prom-client` for Prometheus-compatible metrics exposed at `/metrics`, alongside OpenTelemetry metrics exported via OTLP. Both can coexist. #### How do I handle multi-tenancy in traces? Set a `tenant.id` attribute on the active span from the tenant header, then filter by it in Scout: ```typescript showLineNumbers span.setAttribute('tenant.id', request.headers['x-tenant-id']); ``` #### How do I reduce trace volume in production? Use `ignoreIncomingRequestHook` to skip health checks and static assets, and disable unnecessary instrumentations like filesystem and DNS. #### What's the difference between OTLP HTTP and gRPC? This guide uses OTLP HTTP (port 4318) which works through HTTP proxies and load balancers. OTLP gRPC (port 4317) offers slightly better performance but requires HTTP/2 support. Both are fully supported by Scout Collector. ### What's Next? #### Related Guides - [Fastify Instrumentation](./fastify.md) - High-performance Node.js framework - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerting for Hono services - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development configuration - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment ### Complete Example #### Project Structure ```text hono-postgres/ ├── src/ │ ├── telemetry.ts # OTel SDK initialization (import first!) │ ├── index.ts # Application entry point │ ├── app.ts # Hono app with @hono/otel middleware │ ├── config/ │ │ └── index.ts # Environment configuration │ ├── db/ │ │ ├── schema.ts # Drizzle schema (users, articles, favorites) │ │ ├── index.ts # Database connection pool │ │ └── migrate.ts # Drizzle migration runner │ ├── services/ │ │ ├── logger.ts # Pino + OTel bridge │ │ ├── article.ts # Article CRUD with custom spans │ │ └── user.ts # Auth operations with custom spans │ ├── routes/ │ │ ├── health.ts # Health check endpoints │ │ ├── auth.ts # Authentication routes │ │ └── articles.ts # Article CRUD routes │ ├── middleware/ │ │ └── auth.ts # JWT authentication │ ├── validators/ │ │ ├── user.ts # Zod schemas for auth │ │ └── article.ts # Zod schemas for articles │ └── jobs/ │ ├── queue.ts # BullMQ queue setup │ ├── worker.ts # Background worker (CONSUMER) │ └── tasks/ │ └── notification.ts # Job producers (PRODUCER) ├── config/ │ └── otel-config.yaml # Collector configuration ├── compose.yml ├── Dockerfile ├── package.json └── tsconfig.json ``` #### Dependencies ```json showLineNumbers title="package.json" { "name": "hono-postgres", "version": "1.0.0", "type": "module", "engines": { "node": ">=24.0.0" }, "dependencies": { "@hono/node-server": "^1.19.9", "@hono/otel": "^1.1.0", "@hono/zod-validator": "^0.7.6", "@opentelemetry/api": "^1.9.0", "@opentelemetry/api-logs": "^0.212.0", "@opentelemetry/auto-instrumentations-node": "^0.69.0", "@opentelemetry/exporter-logs-otlp-http": "^0.212.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.212.0", "@opentelemetry/exporter-trace-otlp-http": "^0.212.0", "@opentelemetry/resources": "^2.5.1", "@opentelemetry/sdk-logs": "^0.212.0", "@opentelemetry/sdk-metrics": "^2.5.1", "@opentelemetry/sdk-node": "^0.212.0", "@opentelemetry/semantic-conventions": "^1.39.0", "bullmq": "^5.69.1", "drizzle-orm": "^0.45.1", "hono": "^4.11.9", "ioredis": "^5.9.3", "pg": "^8.18.0", "pino": "^10.3.1", "prom-client": "^15.1.3", "zod": "^4.3.6" } } ``` #### GitHub Repository For a complete working example, see the [Hono PostgreSQL Example](https://github.com/base-14/examples/tree/main/nodejs/hono-postgres) repository. ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [Hono Documentation](https://hono.dev/docs/) - [@hono/otel Middleware](https://www.npmjs.com/package/@hono/otel) - [BullMQ Documentation](https://docs.bullmq.io/) - [Drizzle ORM Documentation](https://orm.drizzle.team/) ### Related Guides - [Fastify Instrumentation](./fastify.md) - Similar Node.js web framework - [Express.js Instrumentation](./express.md) - Classic Node.js framework - [NestJS Instrumentation](./nestjs.md) - TypeScript-first framework - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local collector configuration --- ## Auto-Instrumentation Overview - Zero-Code OpenTelemetry Setup ## Auto-Instrumentation Auto-instrumentation provides **zero-code observability** by automatically capturing traces, metrics, and logs from your application and its dependencies. This is the fastest way to get started with OpenTelemetry. If you want to verify your collector is working first, try the [Hello World guide](/instrument/apps/hello-world). ### When to Use Auto-Instrumentation | Use Case | Recommendation | | --------------------------------- | ----------------------------------------------------------- | | Quick proof-of-concept | ✅ Auto-instrumentation | | Standard HTTP/database operations | ✅ Auto-instrumentation | | Business-specific metrics | ❌ Use [custom instrumentation](../custom-instrumentation/) | | Fine-grained span control | ❌ Use [custom instrumentation](../custom-instrumentation/) | | Legacy framework not supported | ❌ Use [custom instrumentation](../custom-instrumentation/) | ### Frameworks by Language #### Python | Framework | Guide | What's Instrumented | | ---------- | -------------------------- | -------------------------------------------------------------------------------- | | Django | [Django](./django) | HTTP requests, ORM queries, middleware, templates, Celery tasks | | Flask | [Flask](./flask) | HTTP requests, Jinja2 templates, SQLAlchemy | | FastAPI | [FastAPI](./fast-api) | HTTP requests, async handlers, Pydantic validation | | Litestar | [Litestar](./litestar) | HTTP requests, asyncpg, SQLAlchemy, httpx, msgspec validation | | Celery | [Celery](./celery) | Task execution, retries, worker lifecycle | | LangChain | [LangChain](./langchain) | Agent runs, LLM calls, tool execution, RAG retrieval, token/cost tracking | | LangGraph | [LangGraph](./langgraph) | Agent pipelines, LLM calls, tool nodes, conditional routing, token/cost tracking | | LlamaIndex | [LlamaIndex](./llamaindex) | LLM calls, structured output, token/cost tracking, quality evaluation | #### Node.js | Framework | Guide | What's Instrumented | | ----------------- | -------------------- | ------------------------------------------------- | | Express | [Express](./express) | HTTP requests, middleware, routing | | Fastify | [Fastify](./fastify) | HTTP requests, hooks, plugins, PostgreSQL, BullMQ | | Hono | [Hono](./hono) | HTTP requests, middleware, PostgreSQL, BullMQ | | Elysia (Bun) | [Elysia](./elysia) | HTTP requests, middleware, structured logging | | tRPC | [tRPC](./trpc) | Procedures, Prisma queries, PostgreSQL | | NestJS | [NestJS](./nestjs) | Controllers, services, guards, interceptors | | Next.js | [Next.js](./nextjs-scout) | SSR, route handlers, outbound fetch — direct OTLP to Scout, no collector | | Next.js (full-stack) | [Next.js Full-Stack](./nextjs-fullstack) | Browser + server traces, error boundaries, Web Vitals, OTLP proxy route | | Next.js (collector) | [Next.js Collector](./nextjs) | SSR, API routes, middleware, React components — exports to your collector | | Node.js (generic) | [Node.js](./nodejs) | HTTP, filesystem, child processes | | Vercel AI SDK | [Vercel AI SDK](./vercel-ai-sdk) | LLM calls, AI pipelines, token/cost tracking | #### Frontend / Browser | Framework | Guide | What's Instrumented | | --------- | -------------------- | -------------------------------------------------------------- | | Angular | [Angular](./angular) | Browser traces, Core Web Vitals metrics, error logs (zoneless) | | React | [React](./react) | Routes, clicks, fetch/XHR, Core Web Vitals, error logs | #### Java / JVM | Framework | Guide | What's Instrumented | | ----------------- | ------------------------------------------ | -------------------------------------- | | Spring Boot | [Spring Boot](./spring-boot) | REST controllers, JPA, JDBC, messaging | | Spring Boot (alt) | [Alternatives](./spring-boot-alternatives) | Micrometer, manual agent setup | | Quarkus | [Quarkus](./quarkus) | REST endpoints, Hibernate, Kafka | | Micronaut | [Micronaut](./micronaut) | HTTP endpoints, Hibernate JPA, logs | | Ktor (Kotlin) | [Ktor](./ktor) | HTTP routing, Exposed ORM, logs | #### Ruby | Framework | Guide | What's Instrumented | | ------------------------ | ------------------------------ | ----------------------------------------------- | | Rails 6+ (Ruby 3.1+) | [Rails](./rails) | Controllers, ActiveRecord, ActionCable, Sidekiq | | Rails 5.x–6.1 (EOL Ruby) | [Rails Legacy](./rails-legacy) | Controllers, ActiveRecord (pinned SDK versions) | #### Go | Framework | Guide | What's Instrumented | | -------------------- | -------------------------------------------------- | ------------------------------------------------ | | Go (net/http) | [Go](./go) | HTTP handlers, database/sql, gRPC | | Go stdlib + Postgres | [Go stdlib + Postgres](./go-stdlib-postgres) | net/http server + client, pgx queries, slog logs | #### Rust | Framework | Guide | What's Instrumented | | --------- | ------------------------ | ------------------------------------------- | | Actix Web | [Actix Web](./actix-web) | HTTP requests, middleware, database queries | | Axum | [Axum](./axum) | Handlers, middleware, tower layers | #### PHP | Framework | Guide | What's Instrumented | | --------------- | ------------------------ | --------------------------------------------------------------- | | Laravel | [Laravel](./laravel) | HTTP requests, Eloquent, queues, caching | | Slim 4 / Slim 3 | [Slim](./slim) | HTTP requests, MongoDB, metrics, log correlation | | Symfony | [Symfony](./symfony) | HTTP requests, Doctrine ORM, HTTP client, logs | | WordPress | [WordPress](./wordpress) | HTTP requests, WP lifecycle, template selection, mysqli queries | #### .NET | Framework | Guide | What's Instrumented | | ------------ | ------------------------------ | ----------------------------------------- | | ASP.NET Core | [.NET](./dotnet) | HTTP requests, EF Core, HttpClient | | .NET Aspire | [.NET Aspire](./dotnet-aspire) | Multi-service tracing, HTTP, EF Core | #### Elixir | Framework | Guide | What's Instrumented | | --------- | --------------------------- | ----------------------------------- | | Phoenix | [Phoenix](./elixir-phoenix) | Controllers, Ecto, LiveView, PubSub | #### Mobile / Cross-Platform | Framework | Guide | What's Instrumented | | --------- | ------------------------------- | ----------------------------------------------------------------- | | Flutter | [Flutter](../../mobile/flutter) | HTTP requests, crash handling, app lifecycle, distributed tracing | ### How Auto-Instrumentation Works import ThemedImage from '@theme/ThemedImage'; ### Next Steps 1. **Choose your framework** from the tables above 2. **Follow the guide** to add auto-instrumentation 3. **Add [custom instrumentation](../custom-instrumentation/)** for business-specific telemetry --- ## Ktor OpenTelemetry Instrumentation - Java Agent, Exposed ORM & Netty Tracing ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Implement OpenTelemetry instrumentation for Kotlin Ktor applications using the OpenTelemetry Java Agent for zero-code distributed tracing, Exposed ORM query monitoring, and structured log correlation. The Java Agent attaches to the JVM at startup and automatically instruments HTTP requests, JDBC queries, Netty server operations, and outgoing HTTP client calls without any code changes. Ktor is JetBrains' Kotlin-first framework. On the JVM it sits alongside [Spring Boot](./spring-boot.md) and the compile-time [Micronaut](./micronaut.md). Ktor applications benefit from the Java Agent's comprehensive coverage of the JVM ecosystem including JDBC (via Exposed ORM), HikariCP connection pools, Java HTTP clients, and Netty. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and correlate logs with traces using a single `-javaagent` flag. Whether you're implementing observability for the first time, migrating from commercial APM solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations for Ktor OpenTelemetry instrumentation. > **Note:** This guide provides a practical Ktor-focused overview based on > the official OpenTelemetry documentation. For complete Java agent > information, please consult the > [official OpenTelemetry Java documentation](https://opentelemetry.io/docs/languages/java/). :::tip TL;DR Download the OpenTelemetry Java Agent JAR, set `JAVA_TOOL_OPTIONS="-javaagent:/path/to/opentelemetry-javaagent.jar"`, and configure `OTEL_SERVICE_NAME` + `OTEL_EXPORTER_OTLP_ENDPOINT`. HTTP requests, Exposed/JDBC queries, Netty I/O, and HTTP client calls are traced automatically with zero code changes. The agent injects `trace_id` and `span_id` into SLF4J MDC for log correlation. Works seamlessly with Kotlin coroutines. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Kotlin developers**: building Ktor APIs and implementing observability for the first time - **Cloud-native teams**: running Ktor microservices in Kubernetes or Docker - **DevOps engineers**: deploying Kotlin/JVM applications with production monitoring - **Engineering teams**: migrating from Datadog, New Relic, or other commercial APM solutions - **Platform teams**: standardizing observability across JVM services (Ktor, Micronaut, Spring Boot) ### Overview This guide demonstrates how to: - Attach the OpenTelemetry Java Agent to Ktor applications for zero-code instrumentation - Configure trace export to Scout Collector via environment variables - Set up structured JSON logging with automatic trace context correlation - Wire custom metrics and spans using the OpenTelemetry API with Kotlin idioms - Deploy instrumented applications with Docker Compose (app + notify + PostgreSQL + collector) - Trace requests across multiple Ktor services (distributed tracing) - Troubleshoot common instrumentation issues ### Prerequisites Before starting, ensure you have: - **Java 17 or later** (Java 21+ recommended for best performance) - Eclipse Temurin or any OpenJDK distribution - **Kotlin 2.0 or later** (Kotlin 2.2+ recommended) - **Ktor 2.x or 3.x** installed - Ktor 3.x is recommended for optimal compatibility - **Gradle 8.x** for build management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | -------------------------- | --------------- | ------------------- | | Java | 17 | 21+ | | Kotlin | 1.9.0 | 2.2.0+ | | Ktor | 2.0.0 | 3.2.0+ | | Gradle | 8.0 | 8.10+ | | OpenTelemetry Java Agent | 1.0.0 | 2.26+ | | Exposed ORM | 0.40.0 | 0.61.0+ | | PostgreSQL Driver | 42.5.0 | Latest stable | #### Instrumented Components (Automatic) The Java Agent instruments these components with zero code changes: | Component | Coverage | | --------------------- | ------------------------------------------------- | | Ktor HTTP Server | Routes, handlers, request/response attributes | | Netty | Server I/O, connection handling | | Exposed / JDBC | All SQL queries, transactions, connection pools | | Java HTTP Client | Outgoing HTTP calls, W3C trace propagation | | HikariCP | Connection pool metrics | | Logback | MDC injection of trace_id and span_id | | Flyway | Database migration spans | | Kotlin Coroutines | Trace context propagation across suspensions | #### Example Application This guide references the [ktor-postgres](https://github.com/base-14/examples/tree/main/kotlin/ktor-postgres) example: a Ktor 3.2 REST API with Exposed ORM, a notification microservice, and full OpenTelemetry instrumentation. ### Installation #### Step 1: Download the OpenTelemetry Java Agent Download the latest agent JAR from the official releases: ```bash curl -L -o opentelemetry-javaagent.jar \ https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.26.1/opentelemetry-javaagent.jar ``` #### Step 2: Attach the Agent to the JVM The agent attaches via the `-javaagent` JVM flag. The simplest approach is the `JAVA_TOOL_OPTIONS` environment variable: ```bash export JAVA_TOOL_OPTIONS="-javaagent:/path/to/opentelemetry-javaagent.jar" ``` This works regardless of how you start your application (Gradle, java -jar, etc.). #### Step 3: Add the OpenTelemetry API Dependency (Optional) For custom metrics and manual spans, add the OpenTelemetry API to your build. This is optional if you only need automatic instrumentation: ```kotlin title="build.gradle.kts" showLineNumbers plugins { kotlin("jvm") version "2.2.0" kotlin("plugin.serialization") version "2.2.0" id("io.ktor.plugin") version "3.2.0" id("com.gradleup.shadow") version "8.3.6" } dependencies { // Ktor core implementation("io.ktor:ktor-server-core:3.2.0") implementation("io.ktor:ktor-server-netty:3.2.0") implementation("io.ktor:ktor-server-content-negotiation:3.2.0") implementation("io.ktor:ktor-serialization-kotlinx-json:3.2.0") implementation("io.ktor:ktor-server-status-pages:3.2.0") // Database (Exposed ORM + PostgreSQL) implementation("org.jetbrains.exposed:exposed-core:0.61.0") implementation("org.jetbrains.exposed:exposed-dao:0.61.0") implementation("org.jetbrains.exposed:exposed-jdbc:0.61.0") implementation("org.jetbrains.exposed:exposed-kotlin-datetime:0.61.0") implementation("com.zaxxer:HikariCP:6.2.1") implementation("org.postgresql:postgresql:42.7.7") // Flyway migrations implementation("org.flywaydb:flyway-core:12.2.0") runtimeOnly("org.flywaydb:flyway-database-postgresql:12.2.0") // Optional: OTel API for custom metrics and spans implementation("io.opentelemetry:opentelemetry-api:1.48.0") // Logging implementation("ch.qos.logback:logback-classic:1.5.18") implementation("net.logstash.logback:logstash-logback-encoder:8.1") } ``` The `opentelemetry-api` dependency is a compile-time-only API. The Java Agent provides the implementation at runtime. ### Configuration ```mdx-code-block ``` Configure the agent entirely through environment variables: ```bash title=".env" # OpenTelemetry Java Agent OTEL_SERVICE_NAME=ktor-app OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_METRIC_EXPORT_INTERVAL=10000 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development ``` The agent reads these variables at startup. No application code or config files need to change. ```mdx-code-block ``` Ktor uses programmatic configuration. Here's the application entry point with database and service wiring: ```kotlin title="src/main/kotlin/com/example/Application.kt" showLineNumbers package com.example import com.example.plugins.configureRouting import com.example.plugins.configureSerialization import com.example.repository.ArticleRepository import com.example.service.NotificationClient import com.example.service.TelemetryService import com.zaxxer.hikari.HikariConfig import com.zaxxer.hikari.HikariDataSource import io.ktor.server.engine.* import io.ktor.server.netty.* import org.flywaydb.core.Flyway import org.jetbrains.exposed.sql.Database fun main() { embeddedServer(Netty, serverConfig { module(Application::module) }) { connector { port = 8080 } }.start(wait = true) } fun Application.module() { val dataSource = HikariDataSource(HikariConfig().apply { jdbcUrl = "jdbc:postgresql://${env("DB_HOST", "localhost")}:${env("DB_PORT", "5432")}/${env("DB_NAME", "ktor_articles")}" username = env("DB_USER", "postgres") password = env("DB_PASSWORD", "postgres") maximumPoolSize = 10 }) Flyway.configure() .dataSource(dataSource) .locations("classpath:db/migration") .load() .migrate() Database.connect(dataSource) val articleRepository = ArticleRepository() val notificationClient = NotificationClient(env("NOTIFY_URL", "http://localhost:8081")) val telemetryService = TelemetryService() configureSerialization() configureRouting(articleRepository, notificationClient, telemetryService, dataSource) } private fun env(name: String, default: String): String = System.getenv(name) ?: default ``` The Java Agent instruments HikariCP, JDBC, and Netty automatically regardless of how you configure the application. ```mdx-code-block ``` Run the full observability stack locally: ```yaml title="compose.yml" showLineNumbers services: otel-collector: image: otel/opentelemetry-collector-contrib:0.148.0 command: ["--config=/etc/otel/config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otel/config.yaml:ro ports: - "4317:4317" - "4318:4318" environment: SCOUT_ENDPOINT: ${SCOUT_ENDPOINT:-http://localhost:4318} SCOUT_CLIENT_ID: ${SCOUT_CLIENT_ID:-} SCOUT_CLIENT_SECRET: ${SCOUT_CLIENT_SECRET:-} SCOUT_TOKEN_URL: ${SCOUT_TOKEN_URL:-http://localhost/token} restart: unless-stopped db: image: postgres:18-alpine environment: POSTGRES_DB: ktor_articles POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres ports: - "5432:5432" volumes: - pgdata:/var/lib/postgresql/data healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 restart: unless-stopped app: build: ./app ports: - "8080:8080" environment: DB_HOST: db DB_PORT: "5432" DB_NAME: ktor_articles DB_USER: postgres DB_PASSWORD: postgres NOTIFY_URL: http://notify:8081 OTEL_SERVICE_NAME: ktor-articles OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_METRIC_EXPORT_INTERVAL: "10000" OTEL_LOGS_EXPORTER: otlp depends_on: db: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-sf", "http://localhost:8080/api/health"] interval: 10s timeout: 5s start_period: 30s retries: 10 restart: unless-stopped volumes: pgdata: ``` ```mdx-code-block ``` #### Configure Structured Logging Set up Logback with JSON output. The Java Agent automatically injects `trace_id` and `span_id` into the SLF4J MDC: ```xml title="src/main/resources/logback.xml" showLineNumbers trace_id span_id ``` Every log line includes `trace_id` and `span_id` automatically. #### Scout Collector Integration Configure trace export to Scout with OAuth2 authentication: ```bash title=".env" SCOUT_ENDPOINT=https://your-tenant.base14.io/v1/traces SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token OTEL_SERVICE_NAME=ktor-app OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 ``` > **Scout Dashboard Integration**: After configuration, your traces will > appear in the Scout Dashboard. Navigate to the Traces section to view > request flows, identify bottlenecks, and analyze distributed transactions. ### Production Configuration #### Production Environment Variables ```bash title=".env.production" OTEL_SERVICE_NAME=ktor-app OTEL_SERVICE_VERSION=2.1.3 OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com/v1/traces OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_COMPRESSION=gzip OTEL_EXPORTER_OTLP_TIMEOUT=10000 # Batch Span Processor (Production Optimized) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 OTEL_METRIC_EXPORT_INTERVAL=30000 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,host.name=${HOSTNAME} ``` #### Docker Production Configuration Multi-stage Dockerfile that builds a shadow JAR and bakes in the OpenTelemetry Java Agent: ```dockerfile title="Dockerfile" showLineNumbers FROM eclipse-temurin:24-jdk AS builder WORKDIR /app COPY gradle/ gradle/ COPY gradlew settings.gradle.kts build.gradle.kts ./ RUN chmod +x gradlew && ./gradlew dependencies --no-daemon COPY src/ src/ RUN ./gradlew shadowJar --no-daemon FROM eclipse-temurin:24-jre WORKDIR /app RUN apt-get update -qq && \ apt-get install -y --no-install-recommends curl && \ rm -rf /var/lib/apt/lists/* ARG OTEL_AGENT_VERSION=2.26.1 ADD https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v${OTEL_AGENT_VERSION}/opentelemetry-javaagent.jar /app/opentelemetry-javaagent.jar RUN addgroup --gid 1001 appgroup && \ adduser --uid 1001 --gid 1001 --disabled-password --gecos "" appuser && \ chown appuser:appgroup /app/opentelemetry-javaagent.jar COPY --from=builder --chown=appuser:appgroup /app/build/libs/app.jar /app/app.jar USER appuser EXPOSE 8080 ENV JAVA_TOOL_OPTIONS="-javaagent:/app/opentelemetry-javaagent.jar" ENTRYPOINT ["java", "-jar", "/app/app.jar"] ``` Key details: - **Multi-stage build** separates Gradle build from runtime image - **Shadow JAR** bundles all Kotlin/Ktor dependencies into `app.jar` - **OTel Java Agent** downloaded and baked into the image - **`JAVA_TOOL_OPTIONS`** attaches the agent on every JVM start - **Non-root user** (`appuser:1001`) for security #### Multi-Service Distributed Tracing For architectures with multiple services, each gets its own `OTEL_SERVICE_NAME`. The Java Agent automatically propagates W3C `traceparent` headers on outgoing HTTP requests. Here's the notification client from the example app: ```kotlin title="src/main/kotlin/com/example/service/NotificationClient.kt" showLineNumbers package com.example.service import kotlinx.coroutines.Dispatchers import kotlinx.coroutines.withContext import kotlinx.serialization.encodeToString import kotlinx.serialization.json.Json import org.slf4j.LoggerFactory import java.net.URI import java.net.http.HttpClient import java.net.http.HttpRequest import java.net.http.HttpResponse class NotificationClient(private val notifyUrl: String) { private val logger = LoggerFactory.getLogger(NotificationClient::class.java) private val httpClient = HttpClient.newHttpClient() suspend fun notify(payload: Map) { withContext(Dispatchers.IO) { val json = Json.encodeToString(payload) val request = HttpRequest.newBuilder() .uri(URI.create("$notifyUrl/notify")) .header("Content-Type", "application/json") .POST(HttpRequest.BodyPublishers.ofString(json)) .build() val response = httpClient.send(request, HttpResponse.BodyHandlers.ofString()) logger.info("Notification sent: status={}", response.statusCode()) } } } ``` The Java Agent instruments `java.net.http.HttpClient` automatically, injecting the `traceparent` header. Trace context is maintained across the `withContext(Dispatchers.IO)` coroutine switch. Add the notification service to Docker Compose: ```yaml title="compose.yml (excerpt)" services: app: environment: OTEL_SERVICE_NAME: ktor-articles NOTIFY_URL: http://notify:8081 notify: build: ./notify environment: OTEL_SERVICE_NAME: ktor-notify OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_LOGS_EXPORTER: otlp ports: - "8081:8081" ``` In Scout Dashboard, you'll see the full distributed trace: ```plaintext ktor-articles: POST /api/articles +-- INSERT INTO articles ... +-- POST http://notify:8081/notify +-- ktor-notify: POST /notify (linked trace) ``` ### Ktor-Specific Features #### Automatic HTTP Request Tracing The Java Agent instruments Ktor's Netty-based HTTP server automatically. Every request creates a root span with: - `http.method` - Request method (GET, POST, etc.) - `http.route` - Matched route pattern (e.g., `/api/articles/{id}`) - `http.status_code` - Response status code - `url.path` - Request URI path Ktor DSL routing maps directly to span names: ```kotlin routing { route("/api/articles") { get { // Auto-instrumented: creates span "GET /api/articles" } get("/{id}") { // Auto-instrumented: creates span "GET /api/articles/{id}" // Uses route pattern, not the actual ID (low cardinality) } post { // Auto-instrumented: creates span "POST /api/articles" } } } ``` #### Exposed ORM Query Tracing All Exposed queries are traced automatically via JDBC instrumentation. Each query creates a span with: - `db.system` - Database type (`postgresql`) - `db.name` - Database name - `db.statement` - SQL query (parameters obfuscated) - `db.operation` - Operation type (`SELECT`, `INSERT`, `UPDATE`, `DELETE`) ```kotlin // These are all automatically traced: // Exposed DSL query suspend fun findAll(page: Int, perPage: Int) = dbQuery { val total = Articles.selectAll().count() val articles = Articles.selectAll() .orderBy(Articles.createdAt, SortOrder.DESC) .limit(perPage) .offset((page.toLong() - 1) * perPage.toLong()) .map { it.toDto() } articles to total } // Exposed insert suspend fun create(title: String, body: String) = dbQuery { Articles.insert { it[Articles.title] = title it[Articles.body] = body it[createdAt] = OffsetDateTime.now() it[updatedAt] = OffsetDateTime.now() } } ``` In Scout Dashboard, you'll see spans like: ```plaintext SELECT ... FROM articles ORDER BY ... (db.system=postgresql, db.operation=SELECT) INSERT INTO articles ... (db.system=postgresql, db.operation=INSERT) ``` #### Kotlin Coroutines Support The Java Agent propagates trace context across coroutine boundaries automatically. Suspend functions, `withContext` dispatcher switches, and `newSuspendedTransaction` all maintain proper trace context: ```kotlin // Trace context is preserved across the coroutine switch suspend fun dbQuery(block: suspend () -> T): T = newSuspendedTransaction(Dispatchers.IO) { block() } // This suspend function inherits the parent span's context suspend fun notify(payload: Map) { withContext(Dispatchers.IO) { // HTTP call here is still linked to the parent trace httpClient.send(request, HttpResponse.BodyHandlers.ofString()) } } ``` #### Flyway Migration Tracing Database migrations executed by Flyway during application startup are automatically traced. Each migration file creates a span, giving you visibility into startup time. #### Logback Trace-Log Correlation The Java Agent automatically injects `trace_id` and `span_id` into the SLF4J MDC. Combined with `logstash-logback-encoder`, every JSON log line includes trace context: ```json { "message": "Article created: id=42, title=Hello", "logger_name": "com.example.routes.ArticleRoutes", "level": "INFO", "trace_id": "a1b2c3d4e5f6a1b2c3d4e5f6a1b2c3d4", "span_id": "1a2b3c4d5e6f7a8b" } ``` This is fully automatic — no custom MDC manipulation needed. ### Custom Instrumentation #### Custom Business Metrics Create a telemetry service to register and increment custom counters: ```kotlin title="src/main/kotlin/com/example/service/TelemetryService.kt" showLineNumbers package com.example.service import io.opentelemetry.api.GlobalOpenTelemetry import io.opentelemetry.api.metrics.LongCounter class TelemetryService { private val articlesCreated: LongCounter = GlobalOpenTelemetry.getMeter("ktor-articles") .counterBuilder("articles.created") .setDescription("Total number of articles created") .build() fun incrementArticlesCreated() { articlesCreated.add(1) } } ``` Use it in your route handler: ```kotlin title="src/main/kotlin/com/example/routes/ArticleRoutes.kt (excerpt)" post { val request = call.receive() val article = repository.create(request.title!!, request.body!!) telemetryService.incrementArticlesCreated() logger.info("Article created: id={}, title={}", article.id, article.title) try { notificationClient.notify(mapOf( "event" to "article.created", "article_id" to article.id.toString(), "title" to article.title )) } catch (e: Exception) { logger.warn("Failed to send notification: {}", e.message) } call.respond(HttpStatusCode.Created, ArticleResponse( data = article, meta = TraceMeta(traceId = currentTraceId()) )) } ``` #### Including Trace ID in API Responses Include the trace ID in API responses so clients can correlate their requests with backend traces: ```kotlin private fun currentTraceId(): String { val span = Span.current() val ctx = span.spanContext return if (ctx.isValid) ctx.traceId else "" } ``` #### Manual Span Creation Create custom spans for business-critical operations: ```kotlin title="src/main/kotlin/com/example/service/ReportService.kt" showLineNumbers package com.example.service import io.opentelemetry.api.GlobalOpenTelemetry import io.opentelemetry.api.trace.SpanKind import io.opentelemetry.api.trace.StatusCode class ReportService { private val tracer = GlobalOpenTelemetry.getTracer("report-service", "1.0.0") suspend fun generateReport(userId: Long, reportType: String): ByteArray { val span = tracer.spanBuilder("generate_report") .setSpanKind(SpanKind.INTERNAL) .setAttribute("report.type", reportType) .setAttribute("user.id", userId) .startSpan() return span.makeCurrent().use { scope -> try { val report = buildReport(userId, reportType) span.setAttribute("report.size_bytes", report.size.toLong()) span.setStatus(StatusCode.OK) report } catch (e: Exception) { span.recordException(e) span.setStatus(StatusCode.ERROR, e.message ?: "Unknown error") throw e } finally { span.end() } } } } ``` ### Running Your Instrumented Application #### Development Mode Run locally with Gradle and the Java Agent: ```bash # Download the agent (one-time) curl -L -o opentelemetry-javaagent.jar \ https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.26.1/opentelemetry-javaagent.jar # Set environment variables export JAVA_TOOL_OPTIONS="-javaagent:./opentelemetry-javaagent.jar" export OTEL_SERVICE_NAME=ktor-app-dev export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 # Run with Gradle ./gradlew run ``` #### Docker Deployment Run the full stack with Docker Compose: ```bash # Start all services docker compose up --build # Wait for services to be healthy (~30 seconds) docker compose ps # Verify the app is running curl http://localhost:8080/api/health ``` Expected health check response: ```json { "status": "healthy", "database": "connected" } ``` #### Verifying Instrumentation Make test requests and check that traces appear: ```bash # Create an article curl -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Hello OpenTelemetry", "body": "Tracing with Ktor"}' # List articles curl http://localhost:8080/api/articles # Get a specific article curl http://localhost:8080/api/articles/1 ``` The expected span hierarchy for a create request: ```plaintext POST /api/articles (SERVER - java-agent) +-- HikariCP getConnection (INTERNAL - java-agent) +-- INSERT INTO articles ... (CLIENT - java-agent/jdbc) +-- POST http://notify:8081/notify (CLIENT - java-agent/http) +-- ktor-notify: POST /notify (SERVER - java-agent) ``` For a list request: ```plaintext GET /api/articles (SERVER - java-agent) +-- HikariCP getConnection (INTERNAL - java-agent) +-- SELECT ... FROM articles ... (CLIENT - java-agent/jdbc) +-- SELECT COUNT(*) FROM articles (CLIENT - java-agent/jdbc) ``` Check for: - **Spans** with correct `service.name` and proper nesting - **Logs** with `trace_id` and `span_id` in the JSON output - **Metrics** with `articles.created` counter incrementing ### Troubleshooting #### Verifying Agent Attachment ```bash # Check that the agent is loaded docker compose logs app | grep -i "opentelemetry" # Verify JAVA_TOOL_OPTIONS is set docker compose exec app env | grep JAVA_TOOL_OPTIONS ``` You should see: ```plaintext [otel.javaagent] opentelemetry-javaagent - version: 2.26.1 ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify the agent JAR is present and attached: ```bash ls -la /app/opentelemetry-javaagent.jar echo $JAVA_TOOL_OPTIONS ``` 2. Check the collector endpoint is reachable: ```bash curl -v http://otel-collector:4318/v1/traces ``` 3. Enable debug logging on the agent: ```bash export OTEL_JAVAAGENT_DEBUG=true ``` 4. Check collector logs for errors: ```bash docker compose logs otel-collector ``` ##### Issue: No JDBC/Exposed query spans **Solutions:** 1. Verify the agent is attached (see above). JDBC instrumentation is included by default. 2. Check that the database connection is working: ```bash curl http://localhost:8080/api/health ``` 3. Ensure HikariCP is connecting successfully — check app logs for pool initialization messages. ##### Issue: No trace context propagation between services **Solutions:** 1. Verify both services have the Java Agent attached: ```bash docker compose logs app | head -20 docker compose logs notify | head -20 ``` 2. Ensure the HTTP client being used is supported. The standard `java.net.http.HttpClient` used in the example is instrumented automatically. ##### Issue: Log correlation not working (missing trace_id) **Solutions:** 1. Verify `logstash-logback-encoder` is in dependencies: ```bash ./gradlew dependencies | grep logstash ``` 2. Check that `logback.xml` uses `LogstashEncoder` with MDC key names: ```xml trace_id span_id ``` ##### Issue: High memory usage **Solutions:** 1. Reduce the batch queue size: ```bash export OTEL_BSP_MAX_QUEUE_SIZE=1024 ``` 2. Set JVM heap limits: ```bash export JAVA_TOOL_OPTIONS="-javaagent:/app/opentelemetry-javaagent.jar -Xmx512m" ``` ### Security Considerations #### SQL Parameter Obfuscation The Java Agent automatically obfuscates SQL parameter values in database spans: ```sql -- What gets executed (never sent to collector) SELECT * FROM users WHERE email = 'user@example.com' AND api_key = 'sk-abc123' -- What appears in the span (obfuscated) SELECT * FROM users WHERE email = ? AND api_key = ? ``` #### Protecting Sensitive Data Never add sensitive information to span attributes: ```kotlin // Bad - exposes sensitive data span.setAttribute("user.password", user.password) // Never! span.setAttribute("user.email", user.email) // PII risk // Good - uses safe identifiers span.setAttribute("user.id", user.id) span.setAttribute("user.role", user.role) ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - SQL obfuscation is enabled by default - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard ### Performance Considerations #### Expected Performance Impact The OpenTelemetry Java Agent adds minimal overhead to Ktor applications: - **Average latency increase**: 3-5ms per request - **CPU overhead**: Less than 5% with batch processing - **Memory overhead**: ~50-80MB for the agent itself - **Startup time**: ~1-3 seconds additional for agent initialization #### Optimization Best Practices ##### 1. Use Batch Span Processing ```bash OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 ``` ##### 2. Enable GZIP Compression ```bash OTEL_EXPORTER_OTLP_COMPRESSION=gzip ``` Reduces network bandwidth by 70-80%. ##### 3. Filter Health Check Endpoints ```yaml title="config/otel-config.yaml (excerpt)" processors: filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*health.*")' ``` ##### 4. Disable Unused Instrumentation ```bash OTEL_INSTRUMENTATION_KAFKA_ENABLED=false OTEL_INSTRUMENTATION_GRPC_ENABLED=false ``` ### Frequently Asked Questions #### Does the OpenTelemetry Java Agent impact Ktor performance? The agent adds approximately 3-5ms of latency per request. With batch processing and GZIP compression, the overhead is minimal. The agent uses bytecode manipulation at class load time, so there's a small startup cost (~1-3 seconds) but negligible runtime impact. #### Which Ktor versions are supported? The OpenTelemetry Java Agent supports Ktor 2.x and 3.x running on Netty. Ktor 3.x with Kotlin 2.x is recommended for optimal compatibility. #### Are Exposed ORM queries traced automatically? Yes. The agent intercepts all JDBC calls, which includes every query Exposed executes through its JDBC layer. Spans include the SQL statement (parameters obfuscated), database name, and operation type. #### Does the Java Agent work with Kotlin coroutines? Yes. The agent propagates trace context across coroutine boundaries automatically. Suspend functions, `withContext` dispatcher switches, and `newSuspendedTransaction` all maintain proper trace context. #### Can I use the Java Agent with GraalVM native images? No. The Java Agent relies on JVM bytecode manipulation, which is not available in GraalVM native images. For native images, use the OpenTelemetry SDK with manual instrumentation. #### What is the difference between the Java Agent and Ktor's built-in tracing? The **Java Agent** provides comprehensive zero-code instrumentation for HTTP, JDBC, Netty, and 100+ libraries. Ktor's built-in `CallLogging` plugin only covers HTTP request logging. The agent is recommended for full observability. #### Can I use the Java Agent alongside other APM tools? Yes, the agent can coexist with tools like New Relic or Datadog during migration periods. Running multiple JVM agents simultaneously increases startup time and memory usage. #### How do I instrument Ktor WebSockets? The Java Agent instruments WebSocket frames automatically when using Ktor's WebSocket plugin on Netty. Each WebSocket connection creates a span. #### How do I add tenant context in multi-tenant applications? Use a Ktor interceptor to add tenant attributes: ```kotlin intercept(ApplicationCallPipeline.Monitoring) { val tenantId = call.request.headers["X-Tenant-ID"] if (tenantId != null) { Span.current().setAttribute("tenant.id", tenantId) } } ``` #### Does `kotlinx.serialization` affect tracing? No. Serialization happens within the already-instrumented HTTP handler span. There's no separate serialization instrumentation needed. #### How do I correlate logs with traces in Ktor? The Java Agent automatically injects `trace_id` and `span_id` into the SLF4J MDC. Use Logback with `logstash-encoder` to output JSON logs that include these fields for trace-log correlation. ### What's Next? Now that your Ktor application is instrumented with OpenTelemetry, explore these resources: #### Advanced Topics - **Custom Java Instrumentation** - Manual tracing, custom spans, and advanced instrumentation patterns - **PostgreSQL Monitoring Best Practices** - Database observability with connection pooling metrics and query performance analysis #### Scout Platform Features - **Creating Alerts** - Set up alerts for error rates, latency thresholds, and custom metrics - **Dashboard Creation** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **Docker Compose Setup** - Set up Scout Collector for local development #### Related Guides - [Spring Boot Instrumentation](./spring-boot.md) - Most widely used JVM web framework - [Quarkus Instrumentation](./quarkus.md) - Kubernetes-native JVM framework - [Java Custom Instrumentation](../custom-instrumentation/java.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language ### Complete Example #### Project Structure ```plaintext ktor-postgres/ +-- app/ | +-- src/main/ | | +-- kotlin/com/example/ | | | +-- Application.kt | | | +-- model/ | | | | +-- Article.kt | | | +-- plugins/ | | | | +-- Routing.kt | | | | +-- Serialization.kt | | | +-- repository/ | | | | +-- ArticleRepository.kt | | | +-- routes/ | | | | +-- ArticleRoutes.kt | | | | +-- HealthRoutes.kt | | | +-- service/ | | | +-- NotificationClient.kt | | | +-- TelemetryService.kt | | +-- resources/ | | +-- logback.xml | | +-- db/migration/ | | +-- V1__create_articles.sql | +-- build.gradle.kts | +-- Dockerfile +-- notify/ | +-- src/main/kotlin/com/example/notify/ | | +-- Application.kt | +-- build.gradle.kts | +-- Dockerfile +-- config/ | +-- otel-config.yaml +-- compose.yml +-- .env.example +-- scripts/ +-- test-api.sh +-- verify-scout.sh ``` #### Running the Example ```bash # Clone the examples repository git clone https://github.com/base-14/examples.git cd examples/kotlin/ktor-postgres # Copy environment file cp .env.example .env # Start the stack docker compose up --build # Wait for services to be healthy (~30 seconds) curl http://localhost:8080/api/health # Run the full test suite ./scripts/test-api.sh ``` #### Testing the API ```bash # Create an article curl -s -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "OpenTelemetry with Ktor", "body": "Full observability"}' | jq . # List articles curl -s http://localhost:8080/api/articles | jq . # Update an article curl -s -X PUT http://localhost:8080/api/articles/1 \ -H "Content-Type: application/json" \ -d '{"title": "Updated Title"}' | jq . # Delete an article curl -s -X DELETE http://localhost:8080/api/articles/1 ``` #### Expected Trace Output ```plaintext POST /api/articles (3ms) +-- HikariCP getConnection (1ms) +-- INSERT INTO articles ... (4ms) +-- POST http://notify:8081/notify (15ms) +-- [ktor-notify] POST /notify (8ms) ``` Once telemetry is flowing, you can monitor Ktor request performance in Scout — track Exposed query times, HTTP client latency, and error rates from a unified dashboard. ### References - [Official OpenTelemetry Java Documentation](https://opentelemetry.io/docs/languages/java/) - [OpenTelemetry Java Agent](https://github.com/open-telemetry/opentelemetry-java-instrumentation) - [Supported Libraries (Java Agent)](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/docs/supported-libraries.md) - [Ktor Documentation](https://ktor.io/docs/welcome.html) - [Exposed ORM Documentation](https://jetbrains.github.io/Exposed/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) --- ## LangChain OpenTelemetry Instrumentation - Callback Handler Tracing Guide ## LangChain Instrument a LangChain agent with OpenTelemetry to get one trace across the whole request: the HTTP call, the agent run, every LLM turn, each tool invocation, the RAG retrieval, and the database write. This guide takes two paths. First, zero-code auto-instrumentation that produces traces in minutes. Then a hand-written callback handler that emits clean GenAI semantic-convention spans when you need control over names, attributes, cost metrics, and content capture. Both paths rest on the same mechanism: **a LangChain callback handler**. The zero-code library injects one for you; the custom path is you writing your own. The example is a small SRE runbook assistant. You POST an incident question; a tool-calling agent retrieves the relevant runbook from a pgvector store, inspects service metrics, logs, and status through tools, and returns a cited diagnosis. That shape - agent, tools, retrieval, database - is where a flat log stream stops being enough. Your own agent will differ in the details; the handler is the same either way. :::tip TL;DR For a quick start, `pip install opentelemetry-instrumentation-langchain` and call `LangchainInstrumentor().instrument()` - traces appear in Scout with no code changes. For production-grade GenAI spans, attach a custom `BaseCallbackHandler` that maps LangChain's `run_id` / `parent_run_id` run tree to OpenTelemetry spans with `gen_ai.*` attributes, token and cost metrics, and content capture off by default. ::: :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### LangChain vs LangGraph LangChain 1.x agents built with `create_agent` are **LangGraph graphs under the hood** - a stateful `model` / `tools` graph, not the old `AgentExecutor` loop. This guide covers the high-level `create_agent` API and callback-handler instrumentation, where you observe the agent as a run tree without touching graph internals. The [LangGraph guide](./langgraph.md) covers the complementary case: a hand-built `StateGraph` where you wrap each node and edge with spans yourself. If you build graphs by hand, read that guide; if you use `create_agent` and want the agent, tools, and retrieval traced, stay here. ### Who This Guide Is For This documentation is designed for: - **AI/ML engineers**: building LangChain agents and needing visibility into which tool ran, how many tokens a turn used, and where latency accrues. - **Backend developers**: adding an agent endpoint to an existing FastAPI service and wanting one trace across HTTP, agent, LLM, and database. - **Platform teams**: standardizing GenAI observability on OpenTelemetry semantic conventions instead of a vendor-specific tracer. - **DevOps and SRE engineers**: deploying LangChain services with cost tracking, error visibility, and unified traces in production. ### Overview This guide demonstrates how to: - Enable zero-code LangChain tracing with OpenLLMetry auto-instrumentation. - Understand why every LangChain instrumentor is a callback handler. - Build a custom `OTelCallbackHandler` that emits GenAI-semconv spans for chains, chat models, tools, and retrievers. - Parent spans correctly across threads and `await` boundaries using the run tree, not the ambient context. - Record token, cost, and duration metrics per LLM call. - Capture prompts and completions safely, off by default, with PII scrubbing. - Handle real failures and graceful degradation without leaking spans. - Read the resulting span tree and avoid the common pitfalls. - Wire the collector to base14 Scout with the dual-key environment convention. ### Prerequisites Before starting, ensure you have: - **Python 3.10 or later** installed. That is the floor for LangChain 1.x and the OpenTelemetry SDK, which is what the callback handler needs. - **A running collector** reachable over OTLP - see [Docker Compose Setup](../../collector-setup/docker-compose-example.md). - **PostgreSQL 18 with pgvector** for the runbook store (the compose file below provisions it). - **An LLM**: a local [Ollama](https://ollama.com) model works with no API key; Anthropic, OpenAI, and Google are configurable alternatives. - Basic familiarity with OpenTelemetry traces, spans, and metrics. #### Compatibility Matrix What the instrumentation itself needs: | Component | Minimum | Recommended | | ------------------------------------------ | ------- | ----------- | | Python | 3.10 | 3.13+ | | langchain | 1.3 | 1.3.13+ | | langchain-core | 1.4 | 1.4.9+ | | opentelemetry-sdk / api | 1.40.0 | 1.40+ | | opentelemetry-instrumentation-langchain | 0.62 | 0.62.1+ | The `BaseCallbackHandler` lifecycle this guide builds on has been stable since LangChain 0.1, so the handler ports back further than the table suggests. The `create_agent` API is the part that needs 1.x. Everything else depends on what your app already uses. The example app happens to run FastAPI, SQLAlchemy, and pgvector on PostgreSQL 18, and pins Python 3.14 for unrelated reasons - none of that is required to instrument LangChain. Swap in your own web framework and datastore; the handler does not care. `create_agent` pulls LangGraph in transitively. For LangGraph's own node and graph spans, see [LangGraph](./langgraph.md). Treat every package as version-sensitive and re-pin at build time; the LangChain and OpenLLMetry lines move quickly. ### Installation ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash showLineNumbers title="Terminal" # Core - LangChain plus the OpenTelemetry SDK and an OTLP exporter pip install \ langchain langchain-core \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http # Zero-code path only, for the quick start below pip install opentelemetry-instrumentation-langchain # Whichever LLM provider you use pip install langchain-ollama # langchain-anthropic | langchain-openai | langchain-google-genai # Instrumentation for the rest of your stack, so LangChain spans # join the same trace as your HTTP and database calls pip install \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx ``` ```mdx-code-block ``` ```bash showLineNumbers title="Terminal" # Core - LangChain plus the OpenTelemetry SDK and an OTLP exporter uv add \ langchain langchain-core \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http # Zero-code path only, for the quick start below uv add opentelemetry-instrumentation-langchain # Whichever LLM provider you use uv add langchain-ollama # langchain-anthropic | langchain-openai | langchain-google-genai # Instrumentation for the rest of your stack, so LangChain spans # join the same trace as your HTTP and database calls uv add \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx ``` ```mdx-code-block ``` :::warning Package name collision The PyPI name `opentelemetry-instrumentation-langchain` is **Traceloop's OpenLLMetry** package, not the official OpenTelemetry GenAI SIG one. `pip install opentelemetry-instrumentation-langchain` installs Traceloop's build. It is mature and exports to any OTLP collector, so it is the right choice to start. The official SIG instrumentation ships from the `opentelemetry-python-contrib` source tree and is the emerging `gen_ai`-native standard to track. See [Choosing an Approach](#choosing-an-approach). ::: ### Configuration Instrumentation is configured entirely through environment variables. These are the standard OpenTelemetry ones, read by the SDK itself: ```bash showLineNumbers title=".env" OTEL_SERVICE_NAME=your-agent-service OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_RESOURCE_ATTRIBUTES=deployment.environment.name=production OTEL_SEMCONV_STABILITY_OPT_IN=gen_ai_latest_experimental ``` | Variable | Default | What it controls | | -------- | ------- | ---------------- | | `OTEL_SERVICE_NAME` | unset | Becomes `service.name` on every span. Set it, or your agent shows up as `unknown_service`. | | `OTEL_EXPORTER_OTLP_ENDPOINT` | `http://localhost:4318` | OTLP HTTP endpoint of your collector. | | `OTEL_RESOURCE_ATTRIBUTES` | unset | Comma-separated resource attributes. Use it for `deployment.environment.name`. | | `OTEL_SEMCONV_STABILITY_OPT_IN` | unset | Set to `gen_ai_latest_experimental` to opt into the current GenAI conventions rather than the frozen older set. | Then there is content capture, which is the one GenAI-specific decision and the one that carries privacy consequences. Each path has its own flag, and they default in opposite directions: | Path | Variable | Default | | ---- | -------- | ------- | | Custom callback handler | `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT` | `false` | | OpenLLMetry auto-instrumentation | `TRACELOOP_TRACE_CONTENT` | **`true`** | If you start with the zero-code path, prompts and completions are recorded unless you turn them off: ```bash showLineNumbers title="Terminal" export TRACELOOP_TRACE_CONTENT=false ``` See [Content Capture and PII](#content-capture-and-pii) before enabling either in production. :::tip One switch for the whole thing Worth copying from the example app: a single `INSTRUMENTATION_MODE` setting with values `auto`, `callback`, and `off`, read once at startup. It lets you compare the two paths against the same workload and kill instrumentation outright without a redeploy. Your own app config (model names, datastore URLs, API keys) stays separate from this and has no bearing on the telemetry. ::: ### Quick Start: Auto-Instrumentation The fastest path to a trace is zero-code. Enable OpenLLMetry's `LangchainInstrumentor` once, before you build the agent, and every LangChain run emits spans. ```python showLineNumbers title="src/runbook_assistant/telemetry/auto.py" """Zero-code LangChain instrumentation via OpenLLMetry (Traceloop).""" import logging logger = logging.getLogger(__name__) _enabled = False def enable_auto_instrumentation() -> None: global _enabled if _enabled: return from opentelemetry.instrumentation.langchain import LangchainInstrumentor LangchainInstrumentor().instrument() _enabled = True logger.info("OpenLLMetry LangChain auto-instrumentation enabled") ``` That is the entire integration. Point the OTLP exporter at your collector (see [Scout Wiring](#scout-wiring)), send a request, and the trace appears in Scout. With the agent answering an incident question, the auto-instrumented trace looks like this: ```text POST /api/v1/diagnose SERVER (FastAPI) └─ invoke_agent LangGraph INTERNAL └─ LangGraph.workflow INTERNAL ├─ execute_task model INTERNAL (graph node) │ └─ ChatOllama.chat CLIENT (LLM turn) │ └─ POST /api/chat CLIENT (httpx → Ollama) └─ execute_task tools INTERNAL (graph node) ├─ execute_tool search_runbooks INTERNAL │ └─ vector_db_retrieve VectorStoreRetriever CLIENT (retrieval) └─ execute_tool query_metrics INTERNAL (repeats model → tools until the agent answers) ``` Notice how much shows up for free: the agent run, each LangGraph node (`model`, `tools`), the LLM turns, the tool calls, and the vector retrieval. The LLM spans carry token usage, and the whole tree nests under the FastAPI server span, so the agent shares a trace with your HTTP and database telemetry. #### Auto-Instrumentation Is a Callback Handler `LangchainInstrumentor().instrument()` works by monkeypatching `langchain_core.callbacks.BaseCallbackManager.__init__` to inject its own callback handler into every run. Traceloop OpenLLMetry, the official OTel GenAI SIG instrumentation, and OpenInference all do the same thing - they add a handler for you. LangChain emits observability through callback handlers. Auto-instrumentation injects one; the deep dive below is you writing your own. #### Where Auto-Instrumentation Falls Short The zero-code trace is excellent for exploration, but a few things make a custom handler worthwhile. These are observed from OpenLLMetry 0.62.1 against a local `ChatOllama` model: - **Framework-centric span names.** The LLM span is `ChatOllama.chat`, not the GenAI-semconv `chat {model}`; the agent is `invoke_agent LangGraph` rather than your service name; retrieval is `vector_db_retrieve VectorStoreRetriever`. - **Model field is `unknown`.** For Ollama, `gen_ai.request.model` and `gen_ai.response.model` come through as `"unknown"`; the real model name is only in a proprietary `traceloop.association.properties.ls_model_name` attribute. - **Proprietary attributes.** Every span carries `traceloop.*` association properties alongside the `gen_ai.*` ones. - **Content on by default.** Auto-instrumentation records the full prompt, system message, tool arguments, and retrieved documents in span attributes such as `gen_ai.input.messages` and `gen_ai.task.input`. Crucially, it **ignores** `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT`; it is gated by OpenLLMetry's own `TRACELOOP_TRACE_CONTENT` (default `true`). To turn content off, set `TRACELOOP_TRACE_CONTENT=false`. None of these block you - they are the reasons a team with compliance or naming requirements moves to the custom handler next. ### Callback-Handler Deep Dive #### Why Callbacks A LangChain run is a **tree**. Every step - the agent, each LLM call, each tool, each retrieval - has a `run_id`, and every child step carries its parent's id as `parent_run_id`. LangChain reports lifecycle events for each node to any registered callback handler: | LangChain event | Fires when | | -------------------------------------- | ------------------------------ | | `on_chain_start` / `on_chain_end` | a chain or agent run begins | | `on_chat_model_start` / `on_llm_end` | an LLM turn begins and returns | | `on_tool_start` / `on_tool_end` | a tool is invoked | | `on_retriever_start` / `on_retriever_end` | a retriever runs | | `on_*_error` | any of the above raises | Mapping that run tree onto an OpenTelemetry span tree is the whole job: start a span on each `*_start`, end it on the matching `*_end`, and parent each span on its `parent_run_id`'s span. #### Telemetry Setup Bootstrap the SDK once, before the app serves traffic. This wires the OTLP exporters for all three signals, the dual-key environment resource, and base auto-instrumentation for httpx, SQLAlchemy, and logging. ```python showLineNumbers title="src/runbook_assistant/telemetry/setup.py" def build_resource() -> Resource: """Resource with the dual-key environment convention.""" s = get_settings() return Resource.create( { "service.name": s.otel_service_name, "service.version": _APP_VERSION, # Dual-key: Scout UI filters on lowercase `environment`. "deployment.environment.name": s.scout_environment, "environment": s.scout_environment, } ) ``` ```python showLineNumbers title="src/runbook_assistant/telemetry/setup.py" def setup_telemetry(engine: Any = None) -> tuple[trace.Tracer, metrics.Meter]: resource = build_resource() endpoint = os.environ.get( "OTEL_EXPORTER_OTLP_ENDPOINT", "http://localhost:4318" ) trace_provider = TracerProvider(resource=resource) trace_provider.add_span_processor( BatchSpanProcessor(OTLPSpanExporter(endpoint=f"{endpoint}/v1/traces")) ) trace.set_tracer_provider(trace_provider) # Required for the GenAI token, cost, duration, and error instruments # in the Metrics section below - without a meter provider they no-op. reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"{endpoint}/v1/metrics"), export_interval_millis=10_000, ) metrics.set_meter_provider( MeterProvider(resource=resource, metric_readers=[reader]) ) # OTLP logs carry the active trace_id/span_id for trace<>log correlation. log_provider = LoggerProvider(resource=resource) log_provider.add_log_record_processor( BatchLogRecordProcessor(OTLPLogExporter(endpoint=f"{endpoint}/v1/logs")) ) _logs.set_logger_provider(log_provider) HTTPXClientInstrumentor().instrument() LoggingInstrumentor().instrument(set_logging_format=True) if engine is not None: SQLAlchemyInstrumentor().instrument(engine=engine.sync_engine) return ( trace.get_tracer("langchain-agent"), metrics.get_meter("langchain-agent"), ) ``` If you take the zero-code path, call `enable_auto_instrumentation()` at the end of this function, after the providers exist and before the agent is built. The httpx instrumentation matters more than it looks: LangChain has no embeddings callback event, and Ollama chat and embeddings both go over HTTP. So even without a semantic span, the `POST /api/chat` and `POST /api/embed` transport calls show up as CLIENT spans under the LLM and retrieval steps. #### Build the Callback Handler The handler keeps a `run_id -> span` map and a small `_RunState` per run. The central correctness point is `_parent_ctx`: it parents a new span on the **stored** parent span, never on `trace.get_current_span()`, because LangChain callbacks can fire on worker threads or across `await`. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" class OTelCallbackHandler(BaseCallbackHandler): def __init__( self, tracer: trace.Tracer | None = None, agent_name: str = "agent", data_source_id: str = "knowledge_base", conversation_id: str | None = None, ) -> None: self._tracer = tracer or trace.get_tracer("langchain.callback") self._agent_name = agent_name self._data_source_id = data_source_id self._conversation_id = conversation_id self._runs: dict[UUID, _RunState] = {} self._metrics = get_metrics() self._capture = get_settings().capture_content def _parent_ctx(self, parent_run_id: UUID | None) -> otel_context.Context | None: if parent_run_id is not None and parent_run_id in self._runs: return trace.set_span_in_context(self._runs[parent_run_id].span) return None def _start(self, run_id, parent_run_id, name, kind) -> Span: span = self._tracer.start_span( name, context=self._parent_ctx(parent_run_id), kind=kind ) self._runs[run_id] = _RunState(span, time.perf_counter()) return span ``` :::danger Parent on the run tree, not the ambient context Because callbacks can arrive off the request thread, `trace.get_current_span()` may point at the wrong span, or none. Always resolve the parent from your own `run_id -> span` map via `parent_run_id`. Skipping this is the most common cause of mis-nested LangChain traces. ::: ##### The chain (agent) span The root chain run - the one with no `parent_run_id` - becomes the `invoke_agent` span, named after your service. Intermediate LangGraph node runs (`model`, `tools`) are collapsed to a pass-through so the tree shows the meaningful chat, tool, and retrieval spans instead of graph plumbing. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def on_chain_start( self, serialized, inputs, *, run_id, parent_run_id=None, tags=None, metadata=None, **kwargs, ) -> None: if parent_run_id is None: span = self._start( run_id, None, f"invoke_agent {self._agent_name}", SpanKind.INTERNAL ) span.set_attribute("gen_ai.operation.name", "invoke_agent") span.set_attribute("gen_ai.agent.name", self._agent_name) if self._conversation_id: span.set_attribute("gen_ai.conversation.id", self._conversation_id) else: # Skip the span for intermediate LangGraph nodes; pass-through keeps # child spans nested under the nearest real ancestor. parent = self._runs.get(parent_run_id) if parent is not None: self._runs[run_id] = _RunState( parent.span, parent.start, owns_span=False ) ``` Whether you collapse node runs or keep them is a judgment call. Collapsing gives a clean agent-centric tree; keeping them mirrors the auto-instrumented view where `execute_task model` and `execute_task tools` are visible. This example collapses them - see [Reading the Span Tree](#reading-the-span-tree). ##### The chat model span `on_chat_model_start` opens a `chat {model}` CLIENT span. The model and provider come from the run metadata (`ls_model_name`, `ls_provider`), which is how the handler gets the real model name that auto-instrumentation reports as `unknown`. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def _start_llm(self, run_id, parent_run_id, metadata, messages) -> None: meta = metadata or {} model = meta.get("ls_model_name", "unknown") provider = meta.get("ls_provider", "unknown") span = self._start(run_id, parent_run_id, f"chat {model}", SpanKind.CLIENT) span.set_attribute("gen_ai.operation.name", "chat") span.set_attribute("gen_ai.provider.name", provider) span.set_attribute("gen_ai.request.model", model) ``` `on_llm_end` reads token usage and the finish reason off the result, sets the usage attributes, and records the metrics. The finish reason is provider-aware: Ollama reports `done_reason`, while cloud providers use `stop_reason` or `finish_reason`. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def on_llm_end(self, response: LLMResult, *, run_id: UUID, **kwargs) -> None: state = self._runs.get(run_id) if state is None: return span = state.span in_tok, out_tok, finish, resp_model = _usage_from_result(response) provider = getattr(span, "attributes", {}).get("gen_ai.provider.name", "unknown") model = resp_model or "unknown" if resp_model: span.set_attribute("gen_ai.response.model", resp_model) if finish: span.set_attribute("gen_ai.response.finish_reasons", [finish]) span.set_attribute("gen_ai.usage.input_tokens", in_tok) span.set_attribute("gen_ai.usage.output_tokens", out_tok) attrs = { "gen_ai.operation.name": "chat", "gen_ai.provider.name": provider, "gen_ai.request.model": model, } self._metrics.record_tokens(attrs, in_tok, out_tok) self._metrics.record_duration(attrs, time.perf_counter() - state.start) cost = calculate_cost(model, in_tok, out_tok) if cost: span.set_attribute("gen_ai.usage.cost_usd", cost) self._metrics.add_cost(attrs, cost) self._end(run_id) ``` ##### The tool span `on_tool_start` opens an `execute_tool {name}` INTERNAL span with the GenAI tool attributes. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def on_tool_start( self, serialized, input_str, *, run_id, parent_run_id=None, **kwargs, ) -> None: name = (serialized or {}).get("name") or "tool" span = self._start( run_id, parent_run_id, f"execute_tool {name}", SpanKind.INTERNAL ) span.set_attribute("gen_ai.operation.name", "execute_tool") span.set_attribute("gen_ai.tool.name", name) span.set_attribute("gen_ai.tool.type", "function") if self._capture and input_str: from runbook_assistant.pii import scrub span.set_attribute("gen_ai.tool.call.arguments", scrub(input_str)) ``` ##### The retrieval span `on_retriever_start` opens a `retrieval {data_source}` CLIENT span; on end, the handler records how many chunks came back as a custom `app.*` attribute. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def on_retriever_start( self, serialized, query, *, run_id, parent_run_id=None, **kwargs, ) -> None: span = self._start( run_id, parent_run_id, f"retrieval {self._data_source_id}", SpanKind.CLIENT, ) span.set_attribute("gen_ai.operation.name", "retrieval") span.set_attribute("gen_ai.data_source.id", self._data_source_id) def on_retriever_end(self, documents, *, run_id: UUID, **kwargs) -> None: state = self._runs.get(run_id) if state is not None: state.span.set_attribute("app.retrieval.chunk_count", len(documents or [])) self._end(run_id) ``` Custom attributes use the `app.*` prefix so they never collide with reserved `gen_ai.*` names - `app.retrieval.chunk_count` here, and you might add `app.retrieval.score_threshold` or similar. #### The Resulting Spans With the custom handler, the same incident question produces a clean, semconv-named tree: ```text POST /api/v1/diagnose SERVER (FastAPI) └─ invoke_agent runbook_assistant INTERNAL ├─ chat qwen3.5:9B CLIENT (LLM turn, picks tools) │ └─ POST /api/chat CLIENT (httpx → Ollama) ├─ execute_tool search_runbooks INTERNAL │ └─ retrieval runbooks CLIENT │ ├─ POST /api/embed CLIENT (httpx → Ollama) │ └─ SELECT runbooks CLIENT (pgvector query) ├─ execute_tool query_metrics INTERNAL ├─ execute_tool search_logs INTERNAL ├─ execute_tool get_service_status INTERNAL └─ chat qwen3.5:9B CLIENT (LLM turn, writes answer) └─ INSERT diagnoses CLIENT (SQLAlchemy) ``` The attributes on each span type: | Span | Kind | Key attributes | | ----------------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------- | | `invoke_agent runbook_assistant` | INTERNAL | `gen_ai.operation.name=invoke_agent`, `gen_ai.agent.name`, `gen_ai.conversation.id` | | `chat qwen3.5:9B` | CLIENT | `gen_ai.operation.name=chat`, `gen_ai.provider.name`, `gen_ai.request.model`, `gen_ai.response.model`, `gen_ai.response.finish_reasons`, `gen_ai.usage.input_tokens`, `gen_ai.usage.output_tokens` | | `execute_tool {name}` | INTERNAL | `gen_ai.operation.name=execute_tool`, `gen_ai.tool.name`, `gen_ai.tool.type=function` | | `retrieval runbooks` | CLIENT | `gen_ai.operation.name=retrieval`, `gen_ai.data_source.id`, `app.retrieval.chunk_count` | Compared with the auto-instrumented trace, the model name is correct rather than `unknown`, span names follow the GenAI conventions, there are no proprietary attributes, and content is absent unless you opt in. ### Metrics The handler records GenAI metrics on every LLM turn using dedicated instruments, so cost and token usage aggregate in dashboards independent of the spans. ```python showLineNumbers title="src/runbook_assistant/telemetry/metrics.py" class GenAIMetrics: def __init__(self) -> None: meter = metrics.get_meter("gen_ai.client") self._tokens = meter.create_histogram( "gen_ai.client.token.usage", unit="{token}", description="Tokens used per LLM call", ) self._duration = meter.create_histogram( "gen_ai.client.operation.duration", unit="s", description="Duration of GenAI operations", ) self._cost = meter.create_counter( "gen_ai.client.cost", unit="usd", description="Cost of GenAI operations in USD", ) self._errors = meter.create_counter( "gen_ai.client.error.count", unit="{error}", description="GenAI errors by type", ) def record_tokens(self, attrs, input_tokens, output_tokens) -> None: self._tokens.record(input_tokens, {**attrs, "gen_ai.token.type": "input"}) self._tokens.record(output_tokens, {**attrs, "gen_ai.token.type": "output"}) def add_error(self, attrs) -> None: self._errors.add(1, attrs) ``` Cost comes from a small per-model price table. Unknown models return `0.0` so the calculation never raises - local Ollama has no per-token price, so cost is zero there and non-zero once you point the agent at a cloud provider. ```python showLineNumbers title="src/runbook_assistant/cost.py" PRICING: dict[str, tuple[float, float]] = { "claude-sonnet-4-6": (3.0, 15.0), "claude-opus-4-8": (5.0, 25.0), "gpt-4o": (2.5, 10.0), "gemini-2.5-pro": (1.25, 10.0), } def calculate_cost(model: str, input_tokens: int, output_tokens: int) -> float: rates = PRICING.get(model) or PRICING.get(_normalize(model)) if not rates: return 0.0 in_rate, out_rate = rates return (input_tokens * in_rate + output_tokens * out_rate) / 1_000_000 ``` With `gen_ai.request.model` and `gen_ai.provider.name` on the metric points, a dashboard query like `sum(gen_ai.client.cost) by (gen_ai.request.model)` gives per-model spend, and the token histogram splits input from output via `gen_ai.token.type`. ### Content Capture and PII Prompts and completions are **off by default**. The handler captures them only when `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=true`, and even then it runs the text through a scrubber first and records it as a span event, not a raw attribute. ```python showLineNumbers title="src/runbook_assistant/pii.py" _EMAIL = re.compile(r"[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\.[a-zA-Z]{2,}") _IPV4 = re.compile(r"\b(?:\d{1,3}\.){3}\d{1,3}\b") _BEARER = re.compile(r"(?i)bearer\s+[a-z0-9._-]+") _APIKEY = re.compile(r"\b(sk-|key-)[A-Za-z0-9]{8,}\b") def scrub(text: str, limit: int = 1000) -> str: if not text: return "" text = _EMAIL.sub("[email]", text) text = _IPV4.sub("[ip]", text) text = _BEARER.sub("[token]", text) text = _APIKEY.sub("[key]", text) return text[:limit] ``` :::warning Auto-instrumentation captures content by default The custom handler above respects `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT`. OpenLLMetry auto-instrumentation does **not** - it records full prompts, tool arguments, and retrieved documents by default and is controlled by its own `TRACELOOP_TRACE_CONTENT` variable. If you run auto mode in an environment with sensitive data, set `TRACELOOP_TRACE_CONTENT=false` explicitly. ::: ### Error Handling The handler distinguishes a real failure from a failure the agent recovers from. A failed LLM call records the exception, sets `error.type`, and marks the span `ERROR`. A tool that fails but that the agent works around marks the tool span `ERROR` while leaving the parent `invoke_agent` span green, adding an event instead - the request succeeded, so the agent span should not read as failed. ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def _error(self, run_id: UUID, error: BaseException) -> None: state = self._runs.pop(run_id, None) if state is None or not state.owns_span: return span = state.span span.record_exception(error) span.set_attribute("error.type", type(error).__name__) span.set_status(Status(StatusCode.ERROR, str(error))) span.end() def on_tool_error(self, error, *, run_id, parent_run_id=None, **kwargs) -> None: self._error(run_id, error) parent = self._runs.get(parent_run_id) if parent_run_id else None if parent is not None: parent.span.add_event( "tool_execution_failed", {"error.type": type(error).__name__} ) ``` Retrieval failure follows the same graceful-degradation shape: the retriever span is marked `ERROR`, and the parent gets a `rag_retrieval_degraded` event rather than an error status. Because every `_error` path pops the `run_id` from the map, a failed run never orphans a span or leaks a stored context. Record the error on the metric side too. Spans tell you about one failed request; the `gen_ai.client.error.count` counter tells you the rate, and it survives sampling: ```python showLineNumbers title="src/runbook_assistant/telemetry/callback.py" def on_llm_error(self, error, *, run_id: UUID, **kwargs) -> None: state = self._runs.get(run_id) self._metrics.add_error( { "gen_ai.operation.name": "chat", "error.type": type(error).__name__, # Read provider from your own run state, not from the span "gen_ai.provider.name": state.provider if state else "unknown", } ) self._error(run_id, error) ``` Keep `provider` and `model` on your `_RunState` rather than reading them back off the span. `Span.attributes` exists on the SDK's `ReadableSpan` but not on the tracing API, so a sampled-out run hands you a `NonRecordingSpan` and the attribute silently degrades to `unknown` on the metric point. ### Reading the Span Tree A few things to look for, and the pitfalls that produce a confusing trace: - **Two LLM turns per diagnosis.** The first `chat` span chooses tools; the final one writes the answer. If you see only one, the agent answered without calling a tool. - **Retrieval nests under its tool.** `retrieval runbooks` is a child of `execute_tool search_runbooks`, and the `POST /api/embed` and `SELECT runbooks` spans nest under retrieval - embedding then vector query. - **LangGraph node noise.** In auto mode you also see `execute_task model` and `execute_task tools`; the custom handler collapses those. If your custom trees look too deep, you are keeping node runs instead of collapsing them. - **Orphan or mis-nested spans** almost always mean a span was parented on the ambient context instead of the run tree. Re-check `_parent_ctx`. - **Double instrumentation.** Running `auto` and `callback` together double-instruments every operation. Pick exactly one mode. ### Integration Patterns There are three places to attach a callback handler; this example uses the first, one handler per request, so each diagnosis gets its own `conversation_id`. ```python showLineNumbers title="src/runbook_assistant/main.py" @app.post("/api/v1/diagnose", response_model=DiagnoseResponse) async def diagnose(req: DiagnoseRequest) -> DiagnoseResponse: conversation_id = str(uuid.uuid4()) callbacks = app.state.handler_factory(conversation_id) answer = run_diagnosis(app.state.agent, req.question, callbacks) ... ``` ```python showLineNumbers title="src/runbook_assistant/agent.py" def run_diagnosis(agent, question, callbacks=None) -> str: result = agent.invoke( {"messages": [{"role": "user", "content": question}]}, config={"callbacks": callbacks or []}, ) messages = result.get("messages", []) return messages[-1].content if messages else "" ``` - **Per-invocation** (shown): pass `config={"callbacks": [...]}` on each `invoke`. Best when per-request context like a conversation id matters. - **Constructor**: pass `callbacks=[...]` when building the model or chain. The handler applies to every call through that object. - **Global**: register a handler on the callback manager once at startup so it applies process-wide. This is effectively what auto-instrumentation does. ### The Example Application The code excerpts throughout this guide come from a working reference app, an SRE runbook assistant, at [base-14/examples/python/ai-runbook-assistant](https://github.com/base-14/examples/tree/main/python/ai-runbook-assistant). Clone it if you want a running trace to compare yours against. The snippets below are trimmed for readability - helpers like `_RunState`, `get_settings`, and the PII scrubber live in that repo rather than in the text here. The pieces the handler observes are ordinary LangChain. The agent is built with `create_agent`, which returns a LangGraph-backed graph: ```python showLineNumbers title="src/runbook_assistant/agent.py" from langchain.agents import create_agent def build_agent(retriever: Any) -> Any: return create_agent( model=build_chat_model(), tools=build_tools(retriever), system_prompt=SYSTEM_PROMPT, ) ``` Tools are plain `@tool` functions; their docstrings are the descriptions the model sees. `search_runbooks` wraps the pgvector retriever, the rest read a fixture so the example runs offline and the captured trace is reproducible. ```python showLineNumbers title="src/runbook_assistant/tools.py" def build_search_runbooks(retriever: Any) -> Any: @tool def search_runbooks(query: str) -> str: """Search the SRE runbook knowledge base for relevant procedures.""" docs = retriever.invoke(query) if not docs: return "No matching runbooks found." return "\n\n".join( f"# {d.metadata.get('title', 'runbook')}\n{d.page_content}" for d in docs ) return search_runbooks ``` The retriever is a `PGVector` store over local `embeddinggemma` embeddings. The LLM is provider-agnostic - Ollama by default, with Anthropic, OpenAI, and Google selectable by environment variable. ```python showLineNumbers title="src/runbook_assistant/retriever.py" def build_retriever(connection_string: str) -> tuple[Any, Any]: from langchain_ollama import OllamaEmbeddings from langchain_postgres import PGVector s = get_settings() embeddings = OllamaEmbeddings(model=s.embedding_model, base_url=s.ollama_base_url) store = PGVector( embeddings=embeddings, collection_name="runbooks", connection=connection_string, use_jsonb=True, ) return store.as_retriever(search_kwargs={"k": 3}), store ``` The `INSTRUMENTATION_MODE` setting selects the path; the app builds the handler factory accordingly and passes the handlers to each `invoke`. ```python showLineNumbers title="src/runbook_assistant/main.py" if s.instrumentation_mode == "callback": app.state.handler_factory = lambda conversation_id: [ OTelCallbackHandler( agent_name="runbook_assistant", data_source_id=s.data_source_id, conversation_id=conversation_id, ) ] else: app.state.handler_factory = lambda _conversation_id: [] ``` ### Choosing an Approach Every option here works by injecting a LangChain callback handler; they differ in semantic conventions, maturity, and defaults. | Approach | Package | Conventions | Notes | | -------------------------------- | ------------------------------------------------ | ------------------------------ | --------------------------------------------------------------------- | | **OpenLLMetry (Traceloop)** | `opentelemetry-instrumentation-langchain` | `gen_ai.*` plus `traceloop.*` | Mature, exports to any OTLP collector. **Lead with this.** Content on by default; owns the PyPI name. | | **Official OTel GenAI SIG** | contrib `instrumentation-genai` (source for now) | `gen_ai.*` native | Emerging standard; being packaged as `opentelemetry-instrumentation-genai-langchain`. Track it. | | **OpenInference (Arize)** | `openinference-instrumentation-langchain` | own `llm.*` / `openinference.*` | Needs a translation step for `gen_ai.*` alignment. | | **LangSmith `[otel]`** | `langsmith[otel]` | LangSmith model | Defaults to LangSmith cloud; override with `OTEL_EXPORTER_OTLP_ENDPOINT`. | | **Custom callback handler** | your code | exactly what you emit | Full control over names, attributes, cost, and content. This guide. | A practical rule: start with OpenLLMetry, move to the custom handler when you need clean semconv names, correct model fields, custom retrieval attributes, or content off by default. Watch the official SIG package and adopt it once it is pip-installable and covers your needs. ### Related Conventions and Frameworks Where this fits alongside neighbouring conventions and frameworks: - **Tools as MCP.** The [Model Context Protocol](https://modelcontextprotocol.io) is a common tool layer, and agents increasingly expose tools as MCP servers. If your tools run in-process, the callback handler traces them as `execute_tool` spans. Once they sit behind an MCP server, OpenTelemetry's [MCP spans](https://github.com/open-telemetry/semantic-conventions/tree/main/docs/gen-ai) cover that hop instead. - **Agent spans.** The `invoke_agent` and `execute_tool` spans follow the OpenTelemetry GenAI [agent and framework span conventions](https://github.com/open-telemetry/semantic-conventions/tree/main/docs/gen-ai), which supersede the older generic chat-span definitions. - **Agent to agent.** Multi-agent A2A messaging is out of scope here; the handler traces a single agent's run tree. - **Other frameworks.** `create_agent` is one of several agent APIs (LangGraph, OpenAI Agents SDK, Google ADK, Claude Agent SDK, Pydantic AI, CrewAI). This guide uses it because it is the idiomatic LangChain 1.x agent and pairs with the [LangGraph guide](./langgraph.md). ### Scout Wiring Route the SDK's OTLP output to a collector that forwards to base14 Scout. The collector authenticates with `oauth2client` and applies the dual-key environment on the way out. ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*/healthz.*")' - 'IsMatch(name, ".*/readyz.*")' batch: timeout: 10s send_batch_size: 1024 send_batch_max_size: 2048 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: detailed service: extensions: [health_check, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, attributes, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] ``` The dual-key environment is deliberate: the SDK resource sets `deployment.environment.name` and the collector upserts both `deployment.environment` and a lowercase `environment` with the same value, because the Scout UI filters on `environment`. `filter/noisy` drops health-probe spans from the traces pipeline only. The `debug` exporter prints every batch to the collector log, which is what the troubleshooting steps below read; drop it once you are past first setup. #### Docker Compose Substitute your own application for the `app` service. The parts that matter for telemetry are the two `OTEL_*` variables pointing at the collector, and the collector service itself. ```yaml showLineNumbers title="compose.yaml" services: app: build: . ports: - "8000:8000" environment: - OTEL_SERVICE_NAME=your-agent-service - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_SEMCONV_STABILITY_OPT_IN=gen_ai_latest_experimental - OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=${OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT:-false} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} # If your LLM runs on the host rather than in a container - OLLAMA_BASE_URL=${OLLAMA_BASE_URL:-http://host.docker.internal:11434} extra_hosts: - "host.docker.internal:host-gateway" # needed on Linux, not Docker Desktop depends_on: otel-collector: condition: service_started otel-collector: image: otel/opentelemetry-collector-contrib:0.153.0 command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" environment: - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-https://collector.base14.io} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} ``` The collector needs Scout credentials in its own environment, not your app's. Your app only ever talks OTLP to `otel-collector:4318` and stays unaware of Scout entirely, which is what lets you point the same app at a different backend by editing one file. If your models run on the host rather than in a container, `extra_hosts` is what makes `host.docker.internal` resolve on Linux. Docker Desktop provides it without the entry. ### Running Your Application ```bash showLineNumbers title="Terminal" # start the stack (collector picks up Scout creds from the environment) docker compose up -d # send an incident question curl -s -X POST http://localhost:8000/api/v1/diagnose \ -H 'Content-Type: application/json' \ -d '{"question": "orders-service is returning 500s and the logs show connection pool exhausted. What is the likely cause?"}' ``` If you adopted the single-switch pattern from [Configuration](#configuration), you can flip between the two paths without a code change and compare the traces against the same workload: ```bash showLineNumbers title="Terminal" INSTRUMENTATION_MODE=auto docker compose up -d --force-recreate app ``` ### Troubleshooting #### Verify Telemetry Is Working The collector's `debug` exporter prints spans as they arrive. Send a request, then read the collector's log. If you run it under Docker Compose: ```bash showLineNumbers title="Terminal" docker compose logs otel-collector --since=1m | grep -E "Name|gen_ai" ``` With the custom handler attached you should see `invoke_agent`, `chat`, `execute_tool`, and `retrieval` spans. With auto-instrumentation you get the OpenLLMetry names instead - `LangGraph.workflow`, `ChatOllama.chat`, and `execute_task` nodes. #### Common Issues | Symptom | Cause and fix | | ---------------------------------------- | ---------------------------------------------------------------------------------------------- | | No GenAI spans, only HTTP and DB | Neither path is active, or the handler was never passed to `invoke`. Pass it in `config={"callbacks": [...]}`. | | Spans appear but mis-nested | Parenting on the ambient context. Parent on the run tree via `parent_run_id`. | | `gen_ai.request.model` is `unknown` | Auto-instrumentation with Ollama. Use the custom handler, which reads `ls_model_name` from run metadata. | | Every operation traced twice | Auto-instrumentation and a custom handler are both active. Run exactly one. | | Metrics missing, spans fine | No `MeterProvider` installed. See [Telemetry Setup](#telemetry-setup). | | Prompts show up unexpectedly | Auto-instrumentation captures content by default. Set `TRACELOOP_TRACE_CONTENT=false`. | | No traces reach Scout | Check the collector `oauth2client` credentials and that the SDK points at the collector's OTLP port. | ### Security Considerations - **Content is off by default** in the custom handler; keep it off in production unless you have a specific need, and scrub before recording. - **Auto-instrumentation is the opposite** - set `TRACELOOP_TRACE_CONTENT=false` in any environment with sensitive prompts. - **Scrub tool arguments and queries**, not just prompts. Incident text often carries IPs, hostnames, and tokens; the `scrub` helper handles the common cases and truncates. - **Protect collector credentials** with environment variables or a secret store; never commit `SCOUT_CLIENT_SECRET`. ### Performance Considerations - **The handler is cheap.** It stores a `run_id -> span` entry and sets attributes; the cost is dwarfed by the LLM call. Spans export in a background thread via `BatchSpanProcessor`. - **Collapse graph node runs** if you do not need `model` / `tools` node spans - fewer spans per trace, lower export volume. - **Sample in production.** Head or tail sampling on the collector keeps trace volume manageable while preserving errors and slow requests. - **Batch exports** are already configured; tune `send_batch_size` and `timeout` for your throughput. ### FAQ #### How does LangChain OpenTelemetry tracing differ from LangSmith? LangSmith gives deep LangChain-specific traces but sits apart from your HTTP, database, and infrastructure telemetry. OpenTelemetry produces one trace across every layer, so a slow `/diagnose` response links to the exact LLM call, tool invocation, vector query, and SQL `INSERT` that caused it. It is also vendor-neutral: the same spans flow to base14 Scout or any OTLP backend. #### Does a LangChain callback handler add latency? No. Starting and ending a span takes microseconds; LLM calls take seconds. The handler only stores a `run_id -> span` map and sets attributes, and spans export in a background thread off the request path. #### Which LangChain versions does this guide support? LangChain 1.3+ with `langchain-core` 1.4+, where the agent is built with `create_agent` and is LangGraph-backed. The callback API has been stable across the 1.x line. #### How do I trace tool calls in a LangChain agent? Implement `on_tool_start` and `on_tool_end` in a callback handler and emit an `execute_tool` span with `gen_ai.tool.name` and `gen_ai.tool.type`. The zero-code OpenLLMetry library does this for you; the custom handler here shows the exact mapping. #### How do I track LLM cost with LangChain and OpenTelemetry? Read `usage_metadata` in `on_llm_end` for token counts, multiply by a per-model price table, and record a `gen_ai.client.cost` counter alongside the `gen_ai.client.token.usage` histogram. Attach `gen_ai.request.model` and `gen_ai.provider.name` so you can group cost by model. #### Can I capture prompts and completions in LangChain traces? Yes, but it is off by default. The custom handler captures PII-scrubbed content only when `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=true`. OpenLLMetry auto-instrumentation captures content by default and is controlled by its own `TRACELOOP_TRACE_CONTENT`, so set `TRACELOOP_TRACE_CONTENT=false` to disable it there. #### Should I use auto-instrumentation or a custom callback handler? Start with OpenLLMetry for traces in minutes and no code changes. Move to a custom handler when you need clean `gen_ai` span names, correct model and finish-reason fields, custom retrieval attributes, or content off by default. Both inject a LangChain callback handler. #### Why does that package come from Traceloop, not OpenTelemetry? The PyPI name belongs to Traceloop's OpenLLMetry, not the official OpenTelemetry GenAI SIG. That package is mature and exports to any OTLP collector. The official SIG instrumentation is distributed from the `opentelemetry-python-contrib` source tree and is the emerging `gen_ai`-native standard to track. #### How do MCP tools fit, and are they traced? This example uses in-process LangChain tools, which the callback handler traces as `execute_tool` spans. When tools live behind a Model Context Protocol server, the OpenTelemetry MCP span conventions capture that hop; that is a separate integration and no MCP server runs here. ### What's Next? #### Related Guides - [LangGraph Instrumentation](./langgraph.md) - Hand-built `StateGraph` agents with manual node and edge spans. - [LlamaIndex Instrumentation](./llamaindex.md) - RAG-first framework tracing with the same GenAI conventions. - [FastAPI Instrumentation](./fast-api.md) - The HTTP host that carries the agent endpoint. - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans and advanced patterns. #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Alert on cost spikes, error rates, or slow diagnoses. - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build token, cost, and latency dashboards from the GenAI metrics. #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development with the OpenTelemetry Collector. ### References - [OpenTelemetry GenAI Semantic Conventions](https://github.com/open-telemetry/semantic-conventions/tree/main/docs/gen-ai) - [OpenTelemetry Python SDK](https://opentelemetry.io/docs/languages/python/) - [LangChain Documentation](https://python.langchain.com/) - [OpenLLMetry (Traceloop)](https://github.com/traceloop/openllmetry) - [OpenTelemetry Collector Configuration](https://opentelemetry.io/docs/collector/configuration/) --- ## LangGraph OpenTelemetry Instrumentation - AI Agent Monitoring Guide ## LangGraph Implement OpenTelemetry instrumentation for LangGraph applications to enable comprehensive AI agent pipeline monitoring, LLM cost tracking, and end-to-end trace visibility. This guide shows you how to instrument a LangGraph-powered agent pipeline with custom GenAI semantic convention spans, conditional edge routing observability, tool-calling node traces, multi-provider LLM support, token and cost metrics, PII scrubbing, and production deployment with Docker Compose. LangGraph is a Python framework for stateful LLM agents, in the same space as [LlamaIndex](./llamaindex.md) and the TypeScript [Vercel AI SDK](./vercel-ai-sdk.md). LangGraph applications present unique observability challenges beyond standard LLM calls. An agent pipeline involves multiple nodes executing sequentially or conditionally, each potentially making LLM calls, database queries, or tool invocations. Without instrumentation, you cannot see which node is slow, which routing decision was taken, or how much each agent step costs. OpenTelemetry bridges this gap by letting you wrap every node, edge, and tool call with spans that carry LangGraph-specific context alongside standard HTTP and database telemetry. Whether you're building multi-step agent pipelines, sales automation workflows, RAG systems with agent orchestration, or any application that uses LangGraph's StateGraph for complex control flow, this guide provides production-ready patterns for unified AI agent observability where every node execution, routing decision, LLM call, and database query lives in a single trace on base14 Scout. :::tip TL;DR Install `opentelemetry-sdk` and wrap each LangGraph node with a custom span using the GenAI semantic conventions. Configure the OTLP exporter to send traces to base14 Scout, and use span attributes to capture token counts, LLM costs, and routing decisions at every node and conditional edge. ::: > **Note:** For general LLM observability patterns applicable to any Python > framework, see the > [LLM Observability guide](../../../guides/ai-observability/llm-observability.md). > This guide focuses specifically on LangGraph integration patterns. :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### Who This Guide Is For This documentation is designed for: - **AI/ML engineers**: building LangGraph agent pipelines and needing visibility into node performance, routing decisions, and cost - **Backend developers**: adding agent orchestration to existing FastAPI applications and wanting unified tracing across all layers - **Platform teams**: standardizing observability across AI agent services and traditional microservices - **Engineering teams**: migrating from LangSmith tracing to OpenTelemetry for vendor-neutral observability - **DevOps engineers**: deploying LangGraph applications with production monitoring, cost alerting, and pipeline health tracking ### Overview This guide demonstrates how to: - Set up unified OpenTelemetry for a LangGraph application (traces + metrics + logs) - Wrap LangGraph nodes with `wrap_agent` for automatic span creation - Instrument conditional edge routing with span attributes for routing decisions - Trace tool-calling nodes with dedicated tool spans - Create a pipeline-level parent span for aggregate metrics - Track token usage and calculate cost per LLM call with a pricing table - Record evaluation metrics for agent output quality tracking - Scrub PII from prompts and completions before recording in telemetry - Support multiple LLM providers (Anthropic, OpenAI, Google) through a single interface - Deploy with Docker Compose and the OpenTelemetry Collector ### Prerequisites Before starting, ensure you have: - **Python 3.12 or later** installed (3.13+ recommended) - **An LLM API key** from at least one provider (Anthropic, OpenAI, or Google) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Basic understanding of OpenTelemetry concepts (traces, spans, metrics) - Familiarity with LangGraph's StateGraph API #### Compatibility Matrix | Component | Minimum Version | Recommended | | ----------------- | --------------- | ----------- | | Python | 3.12 | 3.13+ | | LangGraph | 0.2 | 1.0.6+ | | langgraph-core | 0.2 | 0.3.38+ | | langchain-core | 0.3 | 0.3.63+ | | opentelemetry-sdk | 1.39.0 | 1.39+ | | opentelemetry-api | 1.39.0 | 1.39+ | | FastAPI | 0.115+ | 0.128+ | | SQLAlchemy | 2.0 | 2.0.45+ | | Anthropic SDK | 0.40+ | 0.76+ | | OpenAI SDK | 1.0+ | 1.60+ | | Google GenAI SDK | 1.0+ | 1.59+ | ### Installation ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash showLineNumbers title="Terminal" pip install \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging \ langgraph langchain-core \ anthropic openai google-genai \ fastapi uvicorn pydantic-settings \ asyncpg sqlalchemy tenacity httpx ``` ```mdx-code-block ``` ```bash showLineNumbers title="Terminal" uv add \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging \ langgraph langchain-core \ anthropic openai google-genai \ fastapi uvicorn pydantic-settings \ asyncpg sqlalchemy tenacity httpx ``` ```mdx-code-block ``` ### Configuration ```mdx-code-block ``` ```python showLineNumbers title="src/sales_intelligence/telemetry.py" import atexit import logging import os from opentelemetry import _logs, metrics, trace from opentelemetry.exporter.otlp.proto.http._log_exporter import ( OTLPLogExporter, ) from opentelemetry.exporter.otlp.proto.http.metric_exporter import ( OTLPMetricExporter, ) from opentelemetry.exporter.otlp.proto.http.trace_exporter import ( OTLPSpanExporter, ) from opentelemetry.instrumentation.httpx import HTTPXClientInstrumentor from opentelemetry.instrumentation.logging import LoggingInstrumentor from opentelemetry.instrumentation.sqlalchemy import ( SQLAlchemyInstrumentor, ) from opentelemetry.sdk._logs import LoggerProvider, LoggingHandler from opentelemetry.sdk._logs.export import BatchLogRecordProcessor from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import ( PeriodicExportingMetricReader, ) from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor def setup_telemetry( service_name: str, otlp_endpoint: str, engine=None, ) -> tuple[trace.Tracer, metrics.Meter]: """Initialize unified observability: traces, metrics, logs. Auto-instruments HTTP, database, and httpx layers. LangGraph agent spans and GenAI spans are handled by custom instrumentation in graph.py and llm.py. """ if os.environ.get("OTEL_SDK_DISABLED") == "true": return ( trace.get_tracer(service_name), metrics.get_meter(service_name), ) resource = Resource.create({ "service.name": service_name, "service.version": os.getenv("SERVICE_VERSION", "1.0.0"), "deployment.environment": os.getenv( "SCOUT_ENVIRONMENT", "development" ), "environment": os.getenv( "SCOUT_ENVIRONMENT", "development" ), }) trace_provider = TracerProvider(resource=resource) trace_provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter( endpoint=f"{otlp_endpoint}/v1/traces" ) ) ) trace.set_tracer_provider(trace_provider) metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter( endpoint=f"{otlp_endpoint}/v1/metrics" ), export_interval_millis=10000, ) metric_provider = MeterProvider( resource=resource, metric_readers=[metric_reader] ) metrics.set_meter_provider(metric_provider) log_provider = LoggerProvider(resource=resource) log_provider.add_log_record_processor( BatchLogRecordProcessor( OTLPLogExporter( endpoint=f"{otlp_endpoint}/v1/logs" ) ) ) _logs.set_logger_provider(log_provider) logging.getLogger().addHandler( LoggingHandler( level=logging.INFO, logger_provider=log_provider ) ) atexit.register(trace_provider.shutdown) atexit.register(metric_provider.shutdown) atexit.register(log_provider.shutdown) HTTPXClientInstrumentor().instrument() LoggingInstrumentor().instrument(set_logging_format=True) if engine: SQLAlchemyInstrumentor().instrument( engine=engine.sync_engine ) return ( trace.get_tracer(service_name), metrics.get_meter(service_name), ) def instrument_fastapi(app) -> None: from opentelemetry.instrumentation.fastapi import ( FastAPIInstrumentor, ) FastAPIInstrumentor.instrument_app( app, excluded_urls="health", exclude_spans=["receive", "send"], ) ``` ```mdx-code-block ``` ```python showLineNumbers title="src/sales_intelligence/config.py" from functools import lru_cache from pydantic_settings import BaseSettings, SettingsConfigDict class Settings(BaseSettings): model_config = SettingsConfigDict( env_file=".env", env_file_encoding="utf-8", extra="ignore", ) service_name: str = "ai-sales-intelligence" database_url: str = ( "postgresql+asyncpg://postgres:postgres" "@localhost:5432/sales" ) llm_provider: str = "anthropic" llm_model: str = "claude-sonnet-4-20250514" llm_temperature: float = 0.7 llm_timeout: float = 30.0 anthropic_api_key: str = "" openai_api_key: str = "" google_api_key: str = "" fallback_provider: str = "" fallback_model: str = "" score_threshold: int = 50 quality_threshold: int = 60 request_timeout: float = 120.0 otlp_endpoint: str = "http://otel-collector:4318" otel_sdk_disabled: bool = False scout_environment: str = "development" host: str = "0.0.0.0" port: int = 8000 @lru_cache def get_settings() -> Settings: return Settings() ``` ```mdx-code-block ``` For container deployments where configuration is managed externally: ```bash showLineNumbers title=".env" # Application SERVICE_NAME=ai-sales-intelligence DATABASE_URL=postgresql+asyncpg://postgres:postgres@postgres:5432/sales LLM_PROVIDER=anthropic LLM_MODEL=claude-sonnet-4-20250514 LLM_TEMPERATURE=0.7 LLM_TIMEOUT=30.0 REQUEST_TIMEOUT=120.0 HOST=0.0.0.0 PORT=8000 # Agent Pipeline SCORE_THRESHOLD=50 QUALITY_THRESHOLD=60 # LLM Provider Keys ANTHROPIC_API_KEY=sk-ant-... OPENAI_API_KEY= GOOGLE_API_KEY= # Fallback Provider (optional) FALLBACK_PROVIDER=openai FALLBACK_MODEL=gpt-4.1-mini # OpenTelemetry OTLP_ENDPOINT=http://otel-collector:4318 OTEL_SDK_DISABLED=false SCOUT_ENVIRONMENT=production ``` The Pydantic `Settings` class reads all environment variables automatically (see the Pydantic Settings tab). No code changes needed - set the variables and the application picks them up. ```mdx-code-block ``` ### Production Configuration #### OpenTelemetry Collector ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 batch: timeout: 10s send_batch_size: 1024 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true debug: verbosity: basic service: extensions: [health_check, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] ``` #### Docker Compose ```yaml showLineNumbers title="compose.yml" services: app: build: . ports: - "8000:8000" environment: - DATABASE_URL=postgresql+asyncpg://postgres:postgres@postgres:5432/sales - OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_SDK_DISABLED=false - LLM_PROVIDER=${LLM_PROVIDER:-anthropic} - LLM_MODEL=${LLM_MODEL:-claude-sonnet-4-20250514} - ANTHROPIC_API_KEY=${ANTHROPIC_API_KEY:-} - OPENAI_API_KEY=${OPENAI_API_KEY:-} - GOOGLE_API_KEY=${GOOGLE_API_KEY:-} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} depends_on: postgres: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-f", "http://localhost:8000/health"] interval: 60s timeout: 5s retries: 3 postgres: image: postgres:18 environment: POSTGRES_DB: sales POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" environment: - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-https://collector.base14.io} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} ``` #### Dockerfile ```dockerfile showLineNumbers title="Dockerfile" FROM python:3.13-slim WORKDIR /app RUN pip install --no-cache-dir uv && \ apt-get update && apt-get install -y --no-install-recommends curl && \ rm -rf /var/lib/apt/lists/* COPY pyproject.toml uv.lock README.md ./ RUN uv sync --no-dev COPY src/ src/ ENV PYTHONPATH=/app/src EXPOSE 8000 CMD ["uv", "run", "uvicorn", "sales_intelligence.main:app", \ "--host", "0.0.0.0", "--port", "8000"] ``` ### Framework-Specific Features This section covers LangGraph-specific instrumentation patterns that go beyond generic LLM observability. These patterns give you visibility into the agent orchestration layer - which nodes executed, what routing decisions were made, how state flowed through the pipeline, and where time was spent. #### State Definition Define the pipeline state as a TypedDict. LangGraph passes this state object between nodes, and each node returns updates to merge back: ```python showLineNumbers title="src/sales_intelligence/state.py" from dataclasses import dataclass, field from typing import TypedDict @dataclass class Prospect: name: str title: str company: str score: int = 0 enrichment: str = "" draft: str = "" @dataclass class Evaluation: prospect_id: str quality_score: int passed: bool feedback: str = "" class AgentState(TypedDict, total=False): campaign_id: str target_keywords: list[str] target_titles: list[str] score_threshold: int quality_threshold: int prospects: list[Prospect] drafts: list[str] evaluations: list[Evaluation] errors: list[str] ``` #### Node Instrumentation with `wrap_agent` Create a wrapper function that adds an OTel span around each LangGraph node. Every node execution becomes a child span of the pipeline span, carrying the agent name and business context: ```python showLineNumbers title="src/sales_intelligence/graph.py" from opentelemetry import trace from opentelemetry.trace import StatusCode tracer = trace.get_tracer("gen_ai.agent") def wrap_agent(name, agent_fn, needs_session=False): """Wrap a LangGraph node function with an OTel span. Each node receives the full AgentState and returns a partial dict to merge back into the state. """ async def wrapped(state, config=None): with tracer.start_as_current_span( f"invoke_agent {name}" ) as span: span.set_attribute( "gen_ai.operation.name", "invoke_agent" ) span.set_attribute("gen_ai.agent.name", name) span.set_attribute( "campaign_id", state.get("campaign_id", "") ) try: if needs_session: result = await agent_fn(state, session) else: result = await agent_fn(state) errors = result.get("errors", []) span.set_attribute( "agent.errors_count", len(errors) ) return result except Exception as e: span.record_exception(e) span.set_status( StatusCode.ERROR, str(e) ) raise return wrapped ``` #### Conditional Edge Routing LangGraph's conditional edges let you branch the pipeline based on state. Instrument the routing function to record which path was taken and why: ```python showLineNumbers title="src/sales_intelligence/graph.py" def route_after_score(state: AgentState) -> str: """Route based on whether any prospects passed scoring. Records the routing decision as span attributes so you can see in traces why a pipeline skipped drafting. """ span = trace.get_current_span() prospects = state.get("prospects", []) threshold = state.get("score_threshold", 50) qualified = [ p for p in prospects if p.score >= threshold ] span.set_attribute( "routing.total_prospects", len(prospects) ) span.set_attribute( "routing.qualified_count", len(qualified) ) span.set_attribute( "routing.threshold", threshold ) if qualified: span.set_attribute("routing.decision", "draft") return "draft" span.set_attribute("routing.decision", "end") return "end" ``` #### Building the Pipeline with Conditional Edges ```python showLineNumbers title="src/sales_intelligence/graph.py" from langgraph.graph import END, START, StateGraph def create_pipeline(session): """Create instrumented LangGraph pipeline.""" graph = StateGraph(AgentState) graph.add_node( "research", wrap_agent( "research", research_agent, needs_session=True, ), ) graph.add_node( "enrich", wrap_agent("enrich", enrich_agent), ) graph.add_node( "score", wrap_agent("score", score_agent), ) graph.add_node( "draft", wrap_agent("draft", draft_agent), ) graph.add_node( "evaluate", wrap_agent("evaluate", evaluate_agent), ) graph.add_edge(START, "research") graph.add_edge("research", "enrich") graph.add_edge("enrich", "score") graph.add_conditional_edges( "score", route_after_score, {"draft": "draft", "end": END}, ) graph.add_edge("draft", "evaluate") graph.add_edge("evaluate", END) return graph.compile() ``` #### Tool-Calling Nodes When agent nodes invoke tools (database searches, API calls, calculations), wrap each tool invocation with a dedicated span: ```python showLineNumbers title="src/sales_intelligence/agents/research.py" from opentelemetry import trace tracer = trace.get_tracer("gen_ai.agent") async def search_prospects( session, keywords: list[str], titles: list[str], ) -> list[dict]: """Database search tool with OTel instrumentation.""" with tracer.start_as_current_span( "tool.search_prospects" ) as span: span.set_attribute( "gen_ai.operation.name", "tool" ) span.set_attribute( "tool.name", "search_prospects" ) span.set_attribute( "tool.keywords_count", len(keywords) ) span.set_attribute( "tool.titles_count", len(titles) ) query = build_search_query(keywords, titles) results = await session.execute(query) rows = results.fetchall() span.set_attribute( "tool.results_count", len(rows) ) return [dict(r._mapping) for r in rows] async def research_agent(state, session): """Research agent: finds prospects via database search.""" prospects = await search_prospects( session, state["target_keywords"], state["target_titles"], ) return { "prospects": [ Prospect( name=p["name"], title=p["title"], company=p["company"], ) for p in prospects ] } ``` #### Pipeline-Level Parent Span Wrap the entire pipeline run in a parent span to capture aggregate metrics. All node spans become children of this span: ```python showLineNumbers title="src/sales_intelligence/graph.py" async def run_pipeline( campaign_id: str, target_keywords: list[str], target_titles: list[str], session, score_threshold: int = 50, quality_threshold: int = 60, ): """Run the agent pipeline with a top-level span.""" with tracer.start_as_current_span( "pipeline.run" ) as span: span.set_attribute("campaign_id", campaign_id) span.set_attribute( "target_keywords", target_keywords ) span.set_attribute( "pipeline.score_threshold", score_threshold ) span.set_attribute( "pipeline.quality_threshold", quality_threshold, ) initial_state = AgentState( campaign_id=campaign_id, target_keywords=target_keywords, target_titles=target_titles, score_threshold=score_threshold, quality_threshold=quality_threshold, ) pipeline = create_pipeline(session) result = await pipeline.ainvoke(initial_state) span.set_attribute( "pipeline.prospects_found", len(result.get("prospects", [])), ) span.set_attribute( "pipeline.drafts_generated", len(result.get("drafts", [])), ) evaluations = result.get("evaluations", []) span.set_attribute( "pipeline.evaluations_passed", sum(1 for e in evaluations if e.passed), ) return result ``` The resulting trace looks like this: ```text showLineNumbers title="Unified trace for POST /campaigns/{id}/run" POST /campaigns/{id}/run 8.4s [auto: FastAPI] ├─ db.query SELECT connections 12ms [auto: SQLAlchemy] ├─ pipeline.run 8.3s [custom: pipeline] │ ├─ invoke_agent research 80ms [custom: agent] │ │ └─ tool.search_prospects 45ms [custom: tool] │ │ └─ db.query SELECT ... tsvector 40ms [auto: SQLAlchemy] │ ├─ invoke_agent enrich 2.1s [custom: agent] │ │ └─ gen_ai.chat claude-sonnet-4 2.0s [custom: LLM] │ │ └─ HTTP POST api.anthropic.com 1.9s [auto: httpx] │ ├─ invoke_agent score 1.8s [custom: agent] │ │ └─ gen_ai.chat claude-sonnet-4 1.7s [custom: LLM] │ │ └─ HTTP POST api.anthropic.com 1.7s [auto: httpx] │ ├─ invoke_agent draft 3.2s [custom: agent] │ │ └─ gen_ai.chat claude-sonnet-4 3.1s [custom: LLM] │ │ └─ HTTP POST api.anthropic.com 3.1s [auto: httpx] │ └─ invoke_agent evaluate 1.1s [custom: agent] │ └─ gen_ai.chat claude-sonnet-4 1.0s [custom: LLM] │ └─ HTTP POST api.anthropic.com 0.9s [auto: httpx] └─ db.query INSERT prospects 8ms [auto: SQLAlchemy] ``` #### Multi-Provider LLM Factory Support multiple LLM providers through a single interface. Each provider's API calls are automatically captured by the httpx auto-instrumentor, while custom GenAI spans add model-specific context: ```python showLineNumbers title="src/sales_intelligence/llm.py" from anthropic import AsyncAnthropic from openai import AsyncOpenAI from google import genai PROVIDER_SERVERS = { "anthropic": "api.anthropic.com", "openai": "api.openai.com", "gcp.gemini": "generativelanguage.googleapis.com", } async def call_provider( provider: str, model: str, system: str, prompt: str, temperature: float = 0.7, max_tokens: int = 1024, ): if provider == "anthropic": client = AsyncAnthropic() response = await client.messages.create( model=model, max_tokens=max_tokens, temperature=temperature, system=system, messages=[ {"role": "user", "content": prompt} ], ) content = response.content[0].text return LLMResponse( content=content, input_tokens=response.usage.input_tokens, output_tokens=response.usage.output_tokens, model=response.model, ) if provider == "openai": client = AsyncOpenAI() response = await client.chat.completions.create( model=model, max_tokens=max_tokens, temperature=temperature, messages=[ {"role": "system", "content": system}, {"role": "user", "content": prompt}, ], ) choice = response.choices[0] return LLMResponse( content=choice.message.content or "", input_tokens=response.usage.prompt_tokens, output_tokens=response.usage.completion_tokens, model=response.model, ) raise ValueError(f"Unknown provider: {provider!r}") ``` For detailed provider-specific handling including Google Gemini, see the [LLM Observability guide](../../../guides/ai-observability/llm-observability.md#custom-llm-instrumentation). ### Custom Manual Instrumentation #### GenAI Span Attributes Create LLM spans following OpenTelemetry GenAI semantic conventions. Each LLM call within an agent node becomes a child span with model, token, and cost attributes: ```python showLineNumbers title="src/sales_intelligence/llm.py" import time from opentelemetry import trace from opentelemetry.trace import StatusCode tracer = trace.get_tracer("gen_ai.client") async def generate( prompt: str, system: str, model: str, provider: str, agent_name: str | None = None, campaign_id: str | None = None, ) -> str: """Generate LLM completion with GenAI span.""" server_address = PROVIDER_SERVERS.get(provider, "") with tracer.start_as_current_span( f"gen_ai.chat {model}" ) as span: span.set_attribute( "gen_ai.operation.name", "chat" ) span.set_attribute( "gen_ai.provider.name", provider ) span.set_attribute( "gen_ai.request.model", model ) span.set_attribute( "gen_ai.request.temperature", 0.7 ) if server_address: span.set_attribute( "server.address", server_address ) if agent_name: span.set_attribute( "gen_ai.agent.name", agent_name ) if campaign_id: span.set_attribute( "campaign_id", campaign_id ) start = time.perf_counter() try: response = await call_provider( provider, model, system, prompt ) duration = time.perf_counter() - start span.set_attribute( "gen_ai.response.model", response.model ) span.set_attribute( "gen_ai.usage.input_tokens", response.input_tokens, ) span.set_attribute( "gen_ai.usage.output_tokens", response.output_tokens, ) _record_token_metrics( response, model, provider, agent_name, campaign_id, duration, ) return response.content except Exception as e: span.record_exception(e) span.set_status(StatusCode.ERROR, str(e)) span.set_attribute( "error.type", type(e).__name__ ) error_counter.add(1, { "gen_ai.request.model": model, "gen_ai.provider.name": provider, "error.type": type(e).__name__, }) raise ``` #### Custom GenAI Metrics Define metrics following OpenTelemetry GenAI semantic conventions: ```python showLineNumbers title="src/sales_intelligence/llm.py" from opentelemetry import metrics meter = metrics.get_meter("gen_ai.client") token_usage = meter.create_histogram( name="gen_ai.client.token.usage", description="Tokens used per LLM call", unit="{token}", ) operation_duration = meter.create_histogram( name="gen_ai.client.operation.duration", description="Duration of GenAI operations", unit="s", ) cost_counter = meter.create_counter( name="gen_ai.client.cost", description="Cost of GenAI operations in USD", unit="usd", ) error_counter = meter.create_counter( name="gen_ai.client.error.count", description="GenAI operation errors", unit="1", ) ``` #### Token and Cost Tracking Define pricing per model and record cost metrics with business context for attribution by agent and campaign: ```python showLineNumbers title="src/sales_intelligence/llm.py" MODEL_PRICING = { "claude-opus-4-20250514": { "input": 15.0, "output": 75.0, }, "claude-sonnet-4-20250514": { "input": 3.0, "output": 15.0, }, "claude-haiku-3-5-20241022": { "input": 0.80, "output": 4.0, }, "gpt-4o": {"input": 2.50, "output": 10.0}, "gpt-4.1-mini": {"input": 0.40, "output": 1.60}, } def calculate_cost( model: str, input_tokens: int, output_tokens: int, ) -> float: pricing = MODEL_PRICING.get( model, {"input": 0.0, "output": 0.0} ) return ( input_tokens * pricing["input"] + output_tokens * pricing["output"] ) / 1_000_000 def _record_token_metrics( response, model, provider, agent_name, campaign_id, duration, ): base_attrs = { "gen_ai.operation.name": "chat", "gen_ai.provider.name": provider, "gen_ai.request.model": model, } token_usage.record( response.input_tokens, {**base_attrs, "gen_ai.token.type": "input"}, ) token_usage.record( response.output_tokens, {**base_attrs, "gen_ai.token.type": "output"}, ) operation_duration.record(duration, base_attrs) cost = calculate_cost( model, response.input_tokens, response.output_tokens, ) cost_attrs = {**base_attrs} if agent_name: cost_attrs["gen_ai.agent.name"] = agent_name if campaign_id: cost_attrs["campaign_id"] = campaign_id cost_counter.add(cost, cost_attrs) ``` #### Evaluation Metrics Track agent output quality as OpenTelemetry metrics and span events: ```python showLineNumbers title="src/sales_intelligence/agents/evaluate.py" from opentelemetry import metrics, trace tracer = trace.get_tracer("gen_ai.evaluation") meter = metrics.get_meter("gen_ai.evaluation") evaluation_score = meter.create_histogram( name="gen_ai.evaluation.score", description="Quality evaluation scores", unit="1", ) async def evaluate_agent(state): """Evaluate draft quality with OTel events.""" evaluations = [] for draft in state.get("drafts", []): with tracer.start_as_current_span( "evaluate.draft" ) as span: score = await run_quality_check(draft) threshold = state.get( "quality_threshold", 60 ) passed = score >= threshold span.set_attribute("quality_score", score) span.set_attribute("passed", passed) span.add_event( "gen_ai.evaluation.result", attributes={ "gen_ai.evaluation.name": ( "email_quality" ), "gen_ai.evaluation.score.value": ( score ), "gen_ai.evaluation.score.label": ( "passed" if passed else "failed" ), }, ) evaluation_score.record( score / 100.0, { "gen_ai.evaluation.name": ( "email_quality" ), "campaign_id": state.get( "campaign_id", "" ), }, ) evaluations.append( Evaluation( prospect_id=draft.prospect_id, quality_score=score, passed=passed, ) ) return {"evaluations": evaluations} ``` #### PII Scrubbing Scrub PII from all content before recording in span events: ```python showLineNumbers title="src/sales_intelligence/pii.py" import re _PII_PATTERNS = [ (re.compile( r"\b[\w.+-]+@[\w-]+\.[\w.-]+\b" ), "[EMAIL]"), (re.compile( r"\b\d{3}[-.]?\d{3}[-.]?\d{4}\b" ), "[PHONE]"), (re.compile(r"\b\d{3}-\d{2}-\d{4}\b"), "[SSN]"), (re.compile( r"https?://(?:www\.)?linkedin\.com/in/[\w-]+" ), "[LINKEDIN]"), ] def scrub_pii(text: str) -> str: for pattern, replacement in _PII_PATTERNS: text = pattern.sub(replacement, text) return text ``` #### Error Handling with Trace IDs Include trace IDs in API error responses so users can reference them when reporting issues: ```python showLineNumbers title="src/sales_intelligence/main.py" from fastapi import Request from fastapi.responses import JSONResponse from opentelemetry import trace @app.exception_handler(Exception) async def global_error_handler( request: Request, exc: Exception, ): span = trace.get_current_span() trace_id = span.get_span_context().trace_id trace_id_hex = format(trace_id, "032x") return JSONResponse( status_code=500, content={ "error": "Internal server error", "trace_id": trace_id_hex, }, ) ``` ### Running Your Application ```mdx-code-block ``` ```bash showLineNumbers uv run uvicorn sales_intelligence.main:app \ --reload --host 0.0.0.0 --port 8000 ``` ```mdx-code-block ``` ```bash showLineNumbers OTEL_SDK_DISABLED=false \ LLM_PROVIDER=anthropic \ LLM_MODEL=claude-sonnet-4-20250514 \ OTLP_ENDPOINT=http://collector:4318 \ uv run uvicorn sales_intelligence.main:app \ --host 0.0.0.0 --port 8000 ``` ```mdx-code-block ``` ```bash showLineNumbers docker compose up --build curl http://localhost:8000/health docker compose down ``` ```mdx-code-block ``` ### Troubleshooting #### Verify Telemetry Is Working ```bash showLineNumbers curl http://localhost:13133 ``` #### Enable Debug Mode ```python showLineNumbers import logging logging.getLogger("opentelemetry").setLevel(logging.DEBUG) ``` #### Common Issues ##### Issue: No traces appearing in Scout **Solutions:** 1. Confirm the OTel Collector is running: `curl http://localhost:13133` 2. Check collector logs: `docker compose logs otel-collector` 3. Verify `OTLP_ENDPOINT` points to the collector, not directly to Scout 4. Ensure `SCOUT_CLIENT_ID` and `SCOUT_CLIENT_SECRET` are set in the collector environment ##### Issue: Token counts are zero **Solutions:** 1. Check your LLM SDK version - older versions may not expose `usage` on the response object 2. Verify the provider response has `input_tokens` and `output_tokens` (naming varies by provider) 3. For Google GenAI, check `response.usage_metadata` instead of `response.usage` ##### Issue: Agent spans not nested under pipeline span **Solutions:** 1. Ensure `wrap_agent` creates spans inside the pipeline span context - call `pipeline.ainvoke()` within the `pipeline.run` span (see [Pipeline-Level Parent Span](#pipeline-level-parent-span)) 2. Verify `setup_telemetry()` is called **before** creating the FastAPI app 3. Check that async context propagation is working - LangGraph preserves the OTel context across `await` boundaries ##### Issue: Cost metrics not accurate **Solutions:** 1. Verify your `MODEL_PRICING` dictionary contains the exact model ID string returned by the provider (e.g., `claude-sonnet-4-20250514`, not `claude-sonnet-4`) 2. Check that cost is calculated with `/1_000_000` (pricing is per million tokens) ##### Issue: Conditional edge routing not visible in traces **Solutions:** 1. Ensure the routing function reads the current span with `trace.get_current_span()` and sets routing attributes 2. Verify the routing function is called within the span context of the preceding node ### Security Considerations #### Protecting Sensitive Data - **Never record raw prompts** that may contain user data, API keys, or credentials in span attributes or events - **Truncate content** to 500 characters to avoid oversized spans - **Disable content capture** in production if compliance requires it - set `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=false` - **Scrub PII** before recording any content in telemetry (see [PII Scrubbing](#pii-scrubbing) for the regex patterns used) #### SQL Query Obfuscation The SQLAlchemy auto-instrumentor captures SQL statements by default. For sensitive queries, disable enhanced reporting: ```python showLineNumbers SQLAlchemyInstrumentor().instrument( engine=engine.sync_engine, enable_commenter=False, ) ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Use opt-in content capture - disabled by default in this guide - Record only token counts and model metadata, not prompt content - Audit span attributes regularly for sensitive data leaks - Use the OTel Collector `attributes` processor to redact fields before export if additional filtering is needed ### Performance Considerations OpenTelemetry overhead is negligible relative to LLM API latency. A typical LLM call takes 1-5 seconds; span creation adds microseconds. #### Optimization Strategies ##### 1. Use BatchSpanProcessor ```python showLineNumbers trace_provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint=endpoint), max_queue_size=2048, max_export_batch_size=512, ) ) ``` ##### 2. Truncate Content Events Always truncate prompts and completions to keep span sizes reasonable: ```python showLineNumbers scrub_pii(prompt)[:500] ``` ##### 3. Disable Content Capture in High-Volume Scenarios ```bash showLineNumbers OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=false ``` ##### 4. Skip Health Check Endpoints Exclude high-frequency health checks from tracing: ```python showLineNumbers FastAPIInstrumentor.instrument_app( app, excluded_urls="health,metrics" ) ``` ### FAQ #### Does OpenTelemetry add latency to LLM calls? No. Span creation takes microseconds. LLM API calls take seconds. The overhead is unmeasurable. `BatchSpanProcessor` exports spans in a background thread. #### How does this differ from LangSmith tracing? LangSmith provides deep LangGraph-specific tracing but operates in isolation from your HTTP and database telemetry. OpenTelemetry gives you a single trace that spans all layers - you can see that a slow HTTP response was caused by a specific agent node making an LLM call, and that the same request also ran database queries. LangSmith cannot show that correlation. #### Which LangGraph versions are supported? This guide supports LangGraph 0.2+ and recommends 1.0.6+. The `StateGraph` API and `add_conditional_edges` have been stable since 0.2. The `wrap_agent` pattern works with any version that supports async node functions. #### How do I trace conditional routing in LangGraph with OpenTelemetry? Use `trace.get_current_span()` inside your routing function to record attributes like `routing.decision` and `routing.qualified_count`. See [Conditional Edge Routing](#conditional-edge-routing) for the full pattern. #### How do I track cost across multiple providers? Use the `gen_ai.client.cost` counter metric with `gen_ai.provider.name` and `gen_ai.request.model` attributes. Define pricing per model and calculate from token counts. This enables `sum(gen_ai.client.cost) by (gen_ai.agent.name)` in your dashboards. #### Can I see prompts and completions in traces? Yes, if you set `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=true`. Content is PII-scrubbed and truncated to 500 characters. Disable in production for compliance. #### How do I add and trace a new agent node in LangGraph? Create the agent function, wrap it with `wrap_agent("name", fn)`, add the node to the `StateGraph` with `graph.add_node()`, and connect it with `add_edge` or `add_conditional_edges`. The `wrap_agent` wrapper automatically handles span creation. #### How does OpenTelemetry trace propagation work in LangGraph subgraphs? LangGraph subgraphs execute within the same Python async context. OpenTelemetry automatically propagates the trace context across `await` boundaries, so subgraph node spans appear as children of the parent graph's span without additional configuration. #### How do I trace tool calls in a LangGraph agent with OpenTelemetry? Wrap each tool invocation with a dedicated span using `tracer.start_as_current_span("tool.")`. Set `gen_ai.operation.name` to `"tool"` and `tool.name` to the specific tool. See [Tool-Calling Nodes](#tool-calling-nodes) for the full pattern. #### Can I use this with LangChain alongside LangGraph? Yes. LangGraph builds on top of `langchain-core`. The `wrap_agent` pattern works regardless of whether your node functions use LangChain components internally. The GenAI spans capture the LLM calls at the provider SDK level, not the framework level. ### What's Next? #### Related Guides - [FastAPI Instrumentation](./fast-api.md) - Common API host for agents - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Alert on cost spikes, error rates, or quality degradation - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build dashboards for token usage, cost attribution, and evaluation scores #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development with the OTel Collector ### Complete Example #### Project Structure ```text showLineNumbers ai-sales-intelligence/ ├── src/sales_intelligence/ │ ├── main.py # FastAPI app with lifespan │ ├── config.py # Pydantic Settings │ ├── telemetry.py # OTel initialization (auto + custom) │ ├── state.py # AgentState TypedDict │ ├── llm.py # LLM client with GenAI spans │ ├── graph.py # LangGraph pipeline with agent spans │ ├── pii.py # PII scrubbing for telemetry │ ├── agents/ │ │ ├── research.py # Database search agent │ │ ├── enrich.py # LLM enrichment agent │ │ ├── score.py # LLM scoring agent │ │ ├── draft.py # LLM email draft agent │ │ └── evaluate.py # LLM quality evaluation agent │ └── middleware/ │ └── metrics.py # HTTP request metrics ├── otel-collector-config.yaml ├── compose.yml ├── Dockerfile └── pyproject.toml ``` #### Key Files | File | Demonstrates | | -------------- | --------------------------------------------------- | | `telemetry.py` | OTel setup (traces + metrics + logs) | | `llm.py` | GenAI spans, token/cost metrics, retry/fallback | | `graph.py` | LangGraph pipeline, `wrap_agent`, conditional edges | | `state.py` | TypedDict state flowing through nodes | | `evaluate.py` | Evaluation events and quality metrics | | `research.py` | Tool-calling node with database search | | `pii.py` | PII scrubbing before telemetry recording | | `config.py` | Provider-agnostic settings with Pydantic | | `compose.yml` | Docker deployment with OTel Collector | #### GitHub Repository For a complete working example, see the [AI Sales Intelligence](https://github.com/base-14/examples/tree/main/python/ai-sales-intelligence) repository. ### References - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [OpenTelemetry Python SDK](https://opentelemetry.io/docs/languages/python/) - [LangGraph Documentation](https://langchain-ai.github.io/langgraph/) - [OpenTelemetry Collector Configuration](https://opentelemetry.io/docs/collector/configuration/) --- ## Laravel OpenTelemetry Instrumentation - Eloquent, Queues & HTTP Implement OpenTelemetry instrumentation for Laravel applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your Laravel application to collect traces and metrics from HTTP requests, database queries, background jobs, cache operations, and custom business logic using the OpenTelemetry PHP SDK. Laravel is a full-featured PHP framework built on Symfony components. [Symfony](./symfony.md) is the underlying toolkit, and [Slim](./slim.md) is a lighter micro-framework alternative. Laravel applications benefit from automatic instrumentation of popular frameworks and libraries including Eloquent ORM, HTTP client requests (Guzzle), Redis, queue workers, and dozens of commonly used packages. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database bottlenecks without significant code changes. Whether you're implementing observability for the first time, migrating from commercial APM solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Laravel OpenTelemetry instrumentation. > **Note:** This guide provides a practical Laravel-focused overview based on the > official OpenTelemetry documentation. For complete PHP language information, > please consult the [official OpenTelemetry PHP documentation](https://opentelemetry.io/docs/languages/php/). :::tip TL;DR Install the OpenTelemetry PHP extension and SDK packages via Composer, then register the `OtelSdkServiceProvider` in your Laravel app. HTTP requests, Eloquent queries, Redis, and queue jobs are traced automatically - no per-route or per-model code changes required. Export traces to base14 Scout via OTLP. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Laravel developers**: implementing observability and distributed tracing for the first time - **DevOps engineers**: deploying Laravel applications with production monitoring requirements - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions - **Developers**: debugging performance issues, slow database queries, or N+1 problems in Laravel applications - **Platform teams**: standardizing observability across multiple Laravel services ### Overview This comprehensive guide demonstrates how to: - Install and configure OpenTelemetry SDK and PHP extension for Laravel applications - Set up automatic instrumentation for HTTP requests, database queries, and popular packages - Configure production-ready telemetry export to Scout Collector - Implement custom instrumentation for business-critical operations - Collect and analyze traces, metrics, and performance data - Deploy instrumented Laravel applications to development, staging, and production environments - Troubleshoot common instrumentation issues and optimize performance - Secure sensitive data in telemetry exports ### Prerequisites Before starting, ensure you have: - **PHP 8.0 or later** (PHP 8.1+ recommended for best performance and compatibility) - For production deployments, PHP 8.2+ is recommended - JIT support in PHP 8.0+ improves instrumentation performance - **Laravel 8.0 or later** installed - Laravel 10.x or 11.x is recommended for optimal OpenTelemetry support - Laravel 8.x and 9.x are supported but may require additional configuration - **Composer 2.0+** for dependency management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Production deployments should use a dedicated Scout Collector instance - **Build tools** for compiling the OpenTelemetry PHP extension (gcc, make, autoconf) - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | |-----------|----------------|---------------------| | PHP | 8.0.0 | 8.2.0+ | | Laravel | 8.0.0 | 11.0.0+ | | Composer | 2.0.0 | 2.7.0+ | | OpenTelemetry PHP Extension | 1.0.0 | Latest stable | | OpenTelemetry SDK | 1.0.0 | 1.6+ | ### Installation #### Step 1: Install OpenTelemetry PHP Extension The OpenTelemetry PHP extension provides automatic instrumentation capabilities. ##### Install Build Dependencies ```bash showLineNumbers # Ubuntu/Debian sudo apt-get install gcc make autoconf # Alpine Linux (Docker) apk add --no-cache autoconf build-base # macOS xcode-select --install ``` ##### Install Extension via PECL ```bash showLineNumbers pecl install opentelemetry ``` ##### Enable Extension in php.ini Add the extension to your `php.ini` file: ```ini showLineNumbers title="php.ini" [opentelemetry] extension=opentelemetry.so ``` ##### Verify Installation ```bash showLineNumbers php -m | grep opentelemetry ``` Expected output: ```plaintext opentelemetry ``` #### Step 2: Install Required Packages Install the necessary OpenTelemetry packages via Composer: ```bash showLineNumbers composer require \ open-telemetry/sdk \ open-telemetry/exporter-otlp \ open-telemetry/opentelemetry-auto-laravel ``` **Optional packages for additional functionality:** ```bash showLineNumbers # For PSR-18 HTTP client instrumentation (Guzzle, etc.) composer require open-telemetry/opentelemetry-auto-psr18 # For complete auto-instrumentation (includes all available instrumentations) composer require open-telemetry/opentelemetry-auto-slim ``` ### Configuration OpenTelemetry Laravel instrumentation can be configured using multiple approaches depending on your deployment requirements and preferences. Choose the method that best fits your application architecture. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The recommended approach for Laravel is using environment variables. This provides flexibility and keeps configuration separate from your application code. #### Configure .env File ```bash showLineNumbers title=".env" # OpenTelemetry Configuration OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=laravel-app OTEL_SERVICE_VERSION=1.0.0 OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_PROPAGATORS=baggage,tracecontext ``` This configuration automatically instruments all supported Laravel components including: - **Laravel Core**: HTTP routing, middleware, controllers, views - **Eloquent ORM**: Database queries, model events - **HTTP Clients**: Guzzle, PSR-18 clients - **Databases**: MySQL, PostgreSQL, SQLite, SQL Server - **Caching**: Redis, Memcached, File cache - **Queue Workers**: Redis, Database, SQS queues - **External APIs**: HTTP requests with distributed trace propagation ```mdx-code-block ``` For applications requiring programmatic configuration, create a custom service provider: ```php showLineNumbers title="app/Providers/OpenTelemetryServiceProvider.php" merge( ResourceInfo::create( Attributes::create([ 'service.name' => config('app.name'), 'service.version' => config('app.version', '1.0.0'), 'deployment.environment' => config('app.env'), 'environment' => config('app.env'), ]) ) ); // Create transport for OTLP exporter $transport = (new OtlpHttpTransportFactory())->create( config('otel.exporter.endpoint', 'http://localhost:4318'), 'application/x-protobuf' ); $exporter = new SpanExporter($transport); $tracerProvider = new TracerProvider( new BatchSpanProcessor($exporter), null, $resource ); Sdk::builder() ->setTracerProvider($tracerProvider) ->build(); } } ``` Register the service provider in `config/app.php`: ```php showLineNumbers title="config/app.php" 'providers' => [ // Other Service Providers App\Providers\OpenTelemetryServiceProvider::class, ], ``` ```mdx-code-block ``` For early initialization, configure OpenTelemetry in your bootstrap files: ```php showLineNumbers title="bootstrap/app.php" ``` For containerized deployments, configure environment variables in your Dockerfile or docker-compose.yml: ```yaml showLineNumbers title="docker-compose.yml" version: '3.8' services: laravel-app: build: . environment: # Application Settings APP_NAME: laravel-app APP_ENV: production # OpenTelemetry Configuration OTEL_PHP_AUTOLOAD_ENABLED: "true" OTEL_SERVICE_NAME: laravel-app OTEL_SERVICE_VERSION: "1.0.0" OTEL_TRACES_EXPORTER: otlp OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4318 OTEL_PROPAGATORS: baggage,tracecontext depends_on: - scout-collector ports: - "8000:8000" scout-collector: image: base14/scout-collector:latest ports: - "4318:4318" ``` ```mdx-code-block ``` #### Scout Collector Integration When using Scout Collector, configure your Laravel application to send telemetry data to the Scout Collector endpoint with OAuth2 authentication: ```bash showLineNumbers title=".env" # Scout Collector Configuration OTEL_EXPORTER_OTLP_ENDPOINT=https://your-tenant.base14.io/v1/traces SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token # Service Configuration OTEL_SERVICE_NAME=laravel-app OTEL_SERVICE_VERSION=1.0.0 OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf ``` > **Scout Dashboard Integration**: After configuration, your traces will appear > in the Scout Dashboard. Navigate to the Traces section to view request flows, > identify performance bottlenecks, and analyze distributed transactions across > your Laravel services. ### Production Configuration Production deployments require additional configuration for optimal performance, reliability, and resource utilization. This section covers production-specific settings and best practices. #### Production Environment Variables Create a production-optimized environment configuration: ```bash showLineNumbers title=".env.production" # Application Settings APP_NAME=laravel-app-production APP_ENV=production APP_DEBUG=false # OpenTelemetry Service Configuration OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=laravel-app OTEL_SERVICE_VERSION=2.1.3 OTEL_SERVICE_NAMESPACE=production # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com/v1/traces SCOUT_CLIENT_ID=prod_client_id SCOUT_CLIENT_SECRET=prod_secret_key SCOUT_TOKEN_URL=https://scout-collector.example.com/oauth/token # Exporter Settings OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_COMPRESSION=gzip OTEL_EXPORTER_OTLP_TIMEOUT=10 # Propagators OTEL_PROPAGATORS=baggage,tracecontext,b3 # Batch Span Processor Settings (Production Optimized) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY_MILLIS=5000 OTEL_BSP_EXPORT_TIMEOUT_MILLIS=30000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 # Resource Attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,host.name=${HOSTNAME},cloud.provider=aws,cloud.region=us-east-1 ``` **Benefits of production configuration:** - GZIP compression reduces network bandwidth by 70-80% - Batch processing minimizes network requests by 95% - Resource attributes enable filtering by environment and infrastructure - Configurable timeouts prevent hanging exports #### Docker Production Configuration For containerized Laravel applications, configure OpenTelemetry in your Docker setup: ```dockerfile showLineNumbers title="Dockerfile" FROM php:8.2-fpm-alpine # Install system dependencies RUN apk add --no-cache \ autoconf \ build-base \ postgresql-dev \ libzip-dev \ zip \ unzip # Install PHP extensions RUN docker-php-ext-install pdo pdo_pgsql zip opcache # Install OpenTelemetry extension RUN pecl install opentelemetry && \ docker-php-ext-enable opentelemetry # Install Composer COPY --from=composer:latest /usr/bin/composer /usr/bin/composer WORKDIR /var/www/html # Copy application files COPY composer.json composer.lock ./ RUN composer install --no-dev --optimize-autoloader --no-scripts COPY . . # Generate optimized autoloader RUN composer dump-autoload --optimize # Set production environment ENV APP_ENV=production ENV OTEL_PHP_AUTOLOAD_ENABLED=true ENV OTEL_SERVICE_NAME=laravel-app ENV OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 # Optimize Laravel for production RUN php artisan config:cache && \ php artisan route:cache && \ php artisan view:cache EXPOSE 8000 CMD ["php", "artisan", "serve", "--host=0.0.0.0", "--port=8000"] ``` ```yaml showLineNumbers title="docker-compose.prod.yml" version: '3.8' services: laravel-app: build: . environment: APP_NAME: laravel-app APP_ENV: production APP_DEBUG: "false" # OpenTelemetry Configuration OTEL_PHP_AUTOLOAD_ENABLED: "true" OTEL_SERVICE_NAME: laravel-app OTEL_SERVICE_VERSION: "${APP_VERSION:-1.0.0}" OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4318 OTEL_EXPORTER_OTLP_COMPRESSION: gzip # Database DB_CONNECTION: pgsql DB_HOST: postgres DB_PORT: 5432 DB_DATABASE: laravel_production DB_USERNAME: laravel DB_PASSWORD: "${DB_PASSWORD}" # Resource Attributes OTEL_RESOURCE_ATTRIBUTES: "deployment.environment=demo,environment=demo,service.instance.id=${HOSTNAME}" depends_on: - postgres - scout-collector ports: - "8000:8000" networks: - app-network scout-collector: image: base14/scout-collector:latest ports: - "4318:4318" networks: - app-network postgres: image: postgres:16-alpine environment: POSTGRES_DB: laravel_production POSTGRES_USER: laravel POSTGRES_PASSWORD: "${DB_PASSWORD}" volumes: - postgres-data:/var/lib/postgresql/data networks: - app-network networks: app-network: driver: bridge volumes: postgres-data: ``` #### Resource Attributes Configuration Add rich context to all telemetry data with resource attributes: ```bash showLineNumbers title=".env" OTEL_RESOURCE_ATTRIBUTES="deployment.environment=development,environment=development,service.namespace=ecommerce,service.instance.id=${HOSTNAME},host.name=${HOSTNAME},host.type=container,cloud.provider=aws,cloud.region=us-east-1,k8s.pod.name=${K8S_POD_NAME},k8s.namespace.name=${K8S_NAMESPACE}" ``` These attributes help you: - Filter traces by environment, region, or instance - Correlate issues with specific deployments - Analyze performance across different infrastructure - Debug production incidents faster #### Health Check Implementation Create health check endpoints to verify telemetry export: ```php showLineNumbers title="routes/api.php" json([ 'status' => 'ok', 'timestamp' => now()->toIso8601String(), 'environment' => config('app.env'), ]); } public function telemetry(): JsonResponse { $otelEnabled = extension_loaded('opentelemetry'); return response()->json([ 'status' => 'ok', 'telemetry' => [ 'extension_loaded' => $otelEnabled, 'service_name' => env('OTEL_SERVICE_NAME'), 'service_version' => env('OTEL_SERVICE_VERSION'), 'exporter_endpoint' => env('OTEL_EXPORTER_OTLP_ENDPOINT'), 'php_version' => PHP_VERSION, 'laravel_version' => app()->version(), ], ]); } } ``` ### Eloquent Database Monitoring OpenTelemetry automatically instruments Eloquent ORM to provide comprehensive database query monitoring and performance insights. #### Automatic Query Tracing Once configured, all Eloquent queries are automatically traced with detailed information: ```php // This query is automatically instrumented $users = User::where('active', true) ->with('posts') ->limit(10) ->get(); // The trace will show: // - SQL query statement // - Database name and operation // - Query duration // - Bindings (obfuscated for security) ``` #### Query Builder and Raw SQL All database interactions are automatically traced: ```php showLineNumbers // Query Builder (automatically traced) $articles = DB::table('articles') ->join('users', 'articles.user_id', '=', 'users.id') ->where('articles.published', true) ->orderBy('articles.created_at', 'desc') ->get(); // Raw SQL queries (automatically traced) $results = DB::select('SELECT * FROM users WHERE active = ?', [true]); // Transactions (automatically traced with span hierarchy) DB::transaction(function () { $order = Order::create([...]); $order->items()->createMany([...]); }); ``` **Span attributes include:** - `db.system` - Database type (mysql, pgsql, sqlite) - `db.name` - Database name - `db.statement` - SQL query (obfuscated) - `db.operation` - Operation type (SELECT, INSERT, UPDATE, DELETE) - `db.sql.table` - Table name #### Detecting N+1 Queries Use OpenTelemetry traces to identify and fix N+1 query problems: ```php // Bad: N+1 query pattern (visible in traces as multiple DB spans) $posts = Post::limit(10)->get(); foreach ($posts as $post) { echo $post->author->name; // Triggers 10 additional queries } // Good: Optimized with eager loading (single query in trace) $posts = Post::with('author')->limit(10)->get(); foreach ($posts as $post) { echo $post->author->name; // No additional queries } ``` In Scout Dashboard, N+1 queries will appear as: - Multiple identical database spans within a single request trace - High span count for simple operations - Repeated query patterns with different parameters ### Custom Manual Instrumentation While automatic instrumentation covers most Laravel components, you can add custom instrumentation for business logic, external API calls, or performance-critical code paths. #### Creating Custom Spans Create custom spans for important business operations: ```php showLineNumbers title="app/Http/Controllers/OrderController.php" getTracer('orders-controller', '1.0.0'); return $tracer->spanBuilder('create_order') ->setSpanKind(SpanKind::KIND_SERVER) ->setAttribute('user.id', $request->user()->id) ->setAttribute('order.items_count', count($request->items)) ->startSpan() ->activate(function ($span) use ($request) { try { $span->addEvent('Validating order data'); $order = Order::create([ 'user_id' => $request->user()->id, 'items' => $request->items, 'total_amount' => $request->total_amount, ]); $span->addEvent('Order saved successfully', [ 'order.id' => $order->id, 'order.total' => $order->total_amount, ]); // Process payment in nested span $this->processPayment($order); // Send confirmation email in nested span $this->sendConfirmation($order); $span->setStatus(StatusCode::STATUS_OK); return response()->json($order, 201); } catch (\Exception $e) { $span->recordException($e); $span->setStatus(StatusCode::STATUS_ERROR, $e->getMessage()); return response()->json(['error' => $e->getMessage()], 422); } }); } private function processPayment(Order $order): void { $tracer = Globals::tracerProvider()->getTracer('orders-controller', '1.0.0'); $tracer->spanBuilder('process_payment') ->setSpanKind(SpanKind::KIND_INTERNAL) ->startSpan() ->activate(function ($span) use ($order) { // Payment processing logic $span->setAttribute('payment.amount', $order->total_amount); $span->setAttribute('payment.status', 'completed'); }); } private function sendConfirmation(Order $order): void { $tracer = Globals::tracerProvider()->getTracer('orders-controller', '1.0.0'); $tracer->spanBuilder('send_confirmation_email') ->setSpanKind(SpanKind::KIND_INTERNAL) ->startSpan() ->activate(function ($span) use ($order) { // Email sending logic $span->addEvent('Email queued', [ 'email.to' => $order->user->email, ]); }); } } ``` #### Adding Middleware for Request Context Enrich all requests with user context: ```php showLineNumbers title="app/Http/Middleware/AddTraceContext.php" isRecording()) { // Add request attributes $span->setAttribute('http.route', $request->route()?->getName()); $span->setAttribute('http.request_id', $request->header('X-Request-ID')); // Add user context if authenticated if ($request->user()) { $span->setAttribute('user.id', $request->user()->id); $span->setAttribute('user.email', $request->user()->email); $span->setAttribute('user.authenticated', true); } } return $next($request); } } ``` Register the middleware in `app/Http/Kernel.php`: ```php showLineNumbers title="app/Http/Kernel.php" protected $middleware = [ // ... other middleware \App\Http\Middleware\AddTraceContext::class, ]; ``` #### Instrumenting External API Calls Add custom instrumentation for external API calls: ```php showLineNumbers title="app/Services/ExternalApiClient.php" getTracer('external-api-client', '1.0.0'); return $tracer->spanBuilder('external_api_call') ->setSpanKind(SpanKind::KIND_CLIENT) ->setAttribute('http.url', $endpoint) ->setAttribute('http.method', 'GET') ->startSpan() ->activate(function ($span) use ($endpoint) { try { $response = Http::get($endpoint); $span->setAttribute('http.status_code', $response->status()); $span->setAttribute('http.response_size', strlen($response->body())); if ($response->successful()) { $span->setStatus(StatusCode::STATUS_OK); return $response->json(); } $span->setStatus(StatusCode::STATUS_ERROR, "HTTP {$response->status()}"); throw new \Exception("API request failed with status {$response->status()}"); } catch (\Exception $e) { $span->recordException($e); $span->setStatus(StatusCode::STATUS_ERROR, $e->getMessage()); throw $e; } }); } } ``` #### Using Semantic Conventions Follow OpenTelemetry semantic conventions for consistent attribute naming: ```php showLineNumbers // HTTP semantic conventions $span->setAttribute('http.method', 'POST'); $span->setAttribute('http.url', 'https://api.example.com/users'); $span->setAttribute('http.status_code', 201); $span->setAttribute('http.request.header.content_type', 'application/json'); // Database semantic conventions $span->setAttribute('db.system', 'postgresql'); $span->setAttribute('db.name', 'production'); $span->setAttribute('db.statement', 'SELECT * FROM users WHERE active = ?'); $span->setAttribute('db.operation', 'SELECT'); // Messaging/Queue semantic conventions $span->setAttribute('messaging.system', 'redis'); $span->setAttribute('messaging.destination', 'emails'); $span->setAttribute('messaging.operation', 'process'); ``` ### Running Your Instrumented Application #### Development Mode For local development, verify instrumentation is working: ```bash showLineNumbers # Set environment variables export OTEL_PHP_AUTOLOAD_ENABLED=true export OTEL_SERVICE_NAME=laravel-app-dev export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 export OTEL_LOG_LEVEL=debug # Start Laravel development server php artisan serve ``` Visit `http://localhost:8000/api/health/telemetry` to verify configuration. #### Production Mode For production deployments, ensure the Scout Collector endpoint is properly configured: ```bash showLineNumbers # Set production environment variables export APP_ENV=production export OTEL_SERVICE_NAME=laravel-app-production export OTEL_SERVICE_VERSION=2.1.0 export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com/v1/traces export SCOUT_CLIENT_ID=your_client_id export SCOUT_CLIENT_SECRET=your_client_secret # Optimize Laravel for production php artisan config:cache php artisan route:cache php artisan view:cache # Start production server (use PHP-FPM + Nginx in production) php artisan serve --host=0.0.0.0 --port=8000 ``` #### Docker Deployment Run your instrumented Laravel application in Docker: ```bash showLineNumbers # Build the image docker build -t laravel-app:latest . # Run with Scout Collector docker run -d \ --name laravel-app \ -e OTEL_PHP_AUTOLOAD_ENABLED=true \ -e OTEL_SERVICE_NAME=laravel-app \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 \ -e DB_CONNECTION=pgsql \ -e DB_HOST=postgres \ -p 8000:8000 \ laravel-app:latest ``` Or use Docker Compose (see [Production Configuration](#production-configuration) section for complete example). ### Troubleshooting #### Verifying OpenTelemetry Installation Check if the OpenTelemetry extension is loaded: ```bash showLineNumbers # Verify extension is loaded php -m | grep opentelemetry # Check extension version php -r "echo phpversion('opentelemetry');" # Verify configuration php -i | grep -i otel ``` Expected output: ```plaintext opentelemetry 1.0.0 OTEL_PHP_AUTOLOAD_ENABLED => true OTEL_SERVICE_NAME => laravel-app ``` #### Testing Instrumentation in Tinker Test your OpenTelemetry configuration using Laravel Tinker: ```php php artisan tinker // Check if extension is loaded >>> extension_loaded('opentelemetry'); => true // Verify environment variables >>> env('OTEL_SERVICE_NAME'); => "laravel-app" >>> env('OTEL_EXPORTER_OTLP_ENDPOINT'); => "http://localhost:4318" ``` #### Debug Mode Enable debug logging to troubleshoot instrumentation issues: ```bash showLineNumbers export OTEL_LOG_LEVEL=debug export OTEL_PHP_INTERNAL_METRICS_ENABLED=true php artisan serve ``` Check Laravel logs for OpenTelemetry debug information: ```bash tail -f storage/logs/laravel.log ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify Scout Collector endpoint is reachable: ```bash curl -v http://scout-collector:4318/v1/traces ``` 2. Check environment variables are set: ```bash php artisan tinker >>> env('OTEL_EXPORTER_OTLP_ENDPOINT'); >>> env('OTEL_SERVICE_NAME'); ``` 3. Enable debug logging and check for export errors: ```bash export OTEL_LOG_LEVEL=debug php artisan serve ``` 4. Verify network connectivity between Laravel app and Scout Collector ##### Issue: OpenTelemetry extension not loaded **Solutions:** 1. Verify extension installation: ```bash pecl list | grep opentelemetry ``` 2. Check php.ini includes extension directive: ```bash php --ini | head -1 cat /path/to/php.ini | grep opentelemetry ``` 3. Ensure extension file exists: ```bash find /usr -name "opentelemetry.so" 2>/dev/null ``` 4. Restart PHP-FPM if using FastCGI: ```bash sudo systemctl restart php8.2-fpm ``` ##### Issue: Missing database query spans **Solutions:** 1. Ensure auto-instrumentation is enabled: ```bash echo $OTEL_PHP_AUTOLOAD_ENABLED # Should be "true" ``` 2. Verify database connection is active: ```bash php artisan tinker >>> DB::connection()->getPdo(); ``` 3. Check that Laravel instrumentation package is installed: ```bash composer show | grep opentelemetry-auto-laravel ``` ##### Issue: High memory usage **Solutions:** 1. Reduce batch queue size: ```bash export OTEL_BSP_MAX_QUEUE_SIZE=1024 ``` 2. Increase export frequency: ```bash export OTEL_BSP_SCHEDULE_DELAY_MILLIS=2000 ``` 3. Monitor PHP memory limit: ```bash php -i | grep memory_limit ``` ##### Issue: Performance degradation **Solutions:** 1. Verify batch span processor is being used (not simple processor) 2. Skip health check endpoints by configuring routes: ```php // Don't trace health check endpoints Route::get('/health', function () { return response()->json(['status' => 'ok']); })->withoutMiddleware([\App\Http\Middleware\AddTraceContext::class]); ``` 3. Use selective instrumentation if full auto-instrumentation is too heavy ### Security Considerations #### Protecting Sensitive Data Avoid adding sensitive information to span attributes: ```php // Bad - exposes sensitive data $span->setAttribute('user.password', $user->password); // Never! $span->setAttribute('credit_card.number', $request->cc_number); // Never! $span->setAttribute('user.ssn', $user->social_security_number); // Never! // Good - uses safe identifiers $span->setAttribute('user.id', $user->id); $span->setAttribute('user.role', $user->role); $span->setAttribute('payment.provider', 'stripe'); $span->setAttribute('payment.status', 'completed'); ``` #### SQL Query Obfuscation OpenTelemetry PHP automatically obfuscates SQL parameter values in database spans: Before obfuscation (never sent): ```sql SELECT * FROM users WHERE email = 'user@example.com' AND password = 'secret123' ``` After obfuscation (what gets sent): ```sql SELECT * FROM users WHERE email = ? AND password = ? ``` #### Filtering Sensitive HTTP Headers Configure which HTTP headers are captured in spans: ```bash showLineNumbers title=".env" # Only capture safe headers OTEL_HTTP_HEADERS_ALLOWED=content-type,accept,user-agent OTEL_HTTP_HEADERS_BLOCKED=authorization,cookie,x-api-key ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard - SQL obfuscation is enabled by default for database queries - Audit span attributes regularly for sensitive data leaks - Configure allowed/blocked HTTP headers appropriately ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead to Laravel applications: - **Average latency increase**: 2-4ms per request - **CPU overhead**: Less than 3% in production with batch processing - **Memory overhead**: ~80-120MB depending on queue size and traffic **Impact varies based on:** - Number of enabled instrumentations - Application request volume - Complexity of database queries - Number of external API calls #### Optimization Best Practices ##### 1. Use Batch Span Processing ```bash # Production settings (low overhead) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY_MILLIS=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 ``` ##### 2. Enable OPcache ```ini showLineNumbers title="php.ini" [opcache] opcache.enable=1 opcache.memory_consumption=256 opcache.interned_strings_buffer=16 opcache.max_accelerated_files=20000 opcache.validate_timestamps=0 ; Disable in production ``` ##### 3. Skip Non-Critical Endpoints Configure routes that don't need tracing: ```php showLineNumbers title="routes/web.php" // Health checks don't need full tracing Route::get('/health', function () { return response()->json(['status' => 'ok']); })->withoutMiddleware(); Route::get('/metrics', function () { return response()->json([/* metrics */]); })->withoutMiddleware(); ``` ##### 4. Use Redis for Queue Monitoring For high-throughput queue processing, ensure efficient monitoring: ```bash showLineNumbers title=".env" QUEUE_CONNECTION=redis REDIS_CLIENT=phpredis # Faster than predis ``` ##### 5. Enable GZIP Compression ```bash OTEL_EXPORTER_OTLP_COMPRESSION=gzip ``` Reduces network bandwidth by 70-80%. ### Frequently Asked Questions #### Does OpenTelemetry impact Laravel performance? OpenTelemetry adds approximately 2-4ms of latency per request in typical Laravel applications. With proper configuration (batch processing, GZIP compression), the performance impact is minimal and acceptable for most production workloads. #### Which Laravel versions are supported? OpenTelemetry supports Laravel 8.0+ with PHP 8.0+. Laravel 10.x or 11.x with PHP 8.2+ is recommended for optimal compatibility and performance. See the [Prerequisites](#prerequisites) section for detailed version compatibility. #### Can I use OpenTelemetry with Laravel queues and job workers? Yes! The `opentelemetry-auto-laravel` package includes automatic instrumentation for Laravel queue workers. Background jobs are traced automatically, and you can see the complete trace from HTTP request through asynchronous job processing in Scout Dashboard. #### Is OpenTelemetry compatible with Laravel middleware? Yes, OpenTelemetry instruments at the HTTP request level, making it compatible with all Laravel middleware. Custom middleware will appear in traces automatically. #### Can I use OpenTelemetry alongside other APM tools? Yes, OpenTelemetry can run alongside tools like New Relic or DataDog during migration periods. However, running multiple APM agents simultaneously will multiply the performance overhead, so plan your migration carefully. #### How do I handle multi-tenant Laravel applications? Add tenant context to spans using middleware: ```php $span = Span::getCurrent(); $span->setAttribute('tenant.id', $request->tenant->id); $span->setAttribute('tenant.name', $request->tenant->name); ``` Then filter traces by tenant in Scout Dashboard. #### What's the difference between traces and metrics? **Traces** show the complete request flow through your application with timing details for each operation. Use traces to debug slow requests and understand distributed transactions. **Metrics** provide aggregated statistics over time (request rate, error rate, latency percentiles). Use metrics for monitoring overall application health and setting alerts. #### How do I monitor Eloquent N+1 queries? OpenTelemetry traces automatically expose N+1 queries as multiple database spans within a single request trace. In Scout Dashboard, look for repeated query patterns or high span counts for simple operations. #### Can I use OpenTelemetry with Laravel Octane? Yes! OpenTelemetry is compatible with Laravel Octane (Swoole/RoadRunner). Ensure the extension is loaded in your Octane worker process by checking `php -m` in the Octane container. #### How do I instrument Laravel scheduled tasks (cron jobs)? Scheduled tasks are automatically instrumented when using auto-instrumentation. Each scheduled command execution creates a trace you can view in Scout Dashboard. #### Does OpenTelemetry work with Laravel Livewire? Yes, Laravel Livewire HTTP requests are automatically traced. Component lifecycle events (mount, render, etc.) appear as spans in your traces. #### Can I customize which database queries are traced? Yes, you can create custom middleware or database event listeners to selectively skip tracing certain queries. However, we recommend tracing all queries for complete observability. ### What's Next? Now that your Laravel application is instrumented with OpenTelemetry, explore these resources to maximize your observability: #### Advanced Topics - **[Custom PHP Instrumentation](../custom-instrumentation/php.md)** - Deep dive into manual tracing, custom spans, and advanced instrumentation patterns - **[PostgreSQL Monitoring Best Practices](../../component/postgres.md)** - Optimize database observability with connection pooling metrics and query performance analysis - **[Redis Instrumentation](../../component/redis.md)** - Monitor caching performance and identify slow Redis operations #### Scout Platform Features - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - Set up intelligent alerts for error rates, latency thresholds, and custom metrics - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Set up Scout Collector for local development and testing ### Complete Example Here's a complete working example of a Laravel application with OpenTelemetry instrumentation. #### Example Project 1: Laravel 13 + PHP 8.5 + PostgreSQL Based on our [GitHub example repository](https://github.com/base-14/examples/tree/main/php/php85-laravel13-postgres). ##### composer.json ```json title="composer.json" { "name": "laravel/laravel", "type": "project", "require": { "php": "^8.2", "laravel/framework": "^11.0", "open-telemetry/sdk": "^1.6", "open-telemetry/exporter-otlp": "^1.3", "open-telemetry/opentelemetry-auto-laravel": "^1.2" }, "autoload": { "psr-4": { "App\\": "app/", "Database\\Factories\\": "database/factories/", "Database\\Seeders\\": "database/seeders/" } } } ``` ##### Environment Configuration ```bash title=".env" APP_NAME=laravel-otel-example APP_ENV=production APP_DEBUG=false # Database DB_CONNECTION=pgsql DB_HOST=postgres DB_PORT=5432 DB_DATABASE=laravel DB_USERNAME=laravel DB_PASSWORD=secret # OpenTelemetry Configuration OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=laravel-app OTEL_SERVICE_VERSION=1.0.0 OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 OTEL_PROPAGATORS=baggage,tracecontext # Scout Collector (for production) SCOUT_ENDPOINT=https://your-tenant.base14.io/v1/traces SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token ``` ##### Dockerfile ```dockerfile title="Dockerfile" FROM php:8.2-fpm-alpine # Install dependencies RUN apk add --no-cache \ autoconf \ build-base \ postgresql-dev \ libzip-dev # Install PHP extensions RUN docker-php-ext-install pdo pdo_pgsql zip opcache # Install OpenTelemetry extension RUN pecl install opentelemetry && \ docker-php-ext-enable opentelemetry WORKDIR /var/www/html COPY --from=composer:latest /usr/bin/composer /usr/bin/composer COPY composer.json composer.lock ./ RUN composer install --no-dev --optimize-autoloader COPY . . ENV OTEL_PHP_AUTOLOAD_ENABLED=true ENV OTEL_SERVICE_NAME=laravel-app EXPOSE 8000 CMD ["php", "artisan", "serve", "--host=0.0.0.0"] ``` #### Example Project 2: Laravel 8 + SQLite (Legacy) For legacy applications still using Laravel 8 (see [GitHub example](https://github.com/base-14/examples/tree/main/php/php8-laravel8-sqlite)): > ⚠️ **Security Warning**: Laravel 8 reached end-of-life in July 2023. This example > is provided for reference only and should not be used in production. ```bash title=".env" APP_NAME=laravel-8-legacy DB_CONNECTION=sqlite OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=laravel-8-legacy OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 ``` Complete working examples are available in our [GitHub examples repository](https://github.com/base-14/examples/tree/main/php). Once telemetry is flowing, you can [monitor Laravel request performance in Scout](https://base14.io/scout/apm) — track Eloquent queries, queue throughput, and HTTP latency from a unified dashboard. ### References - [Official OpenTelemetry PHP Documentation](https://opentelemetry.io/docs/languages/php/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [Laravel Documentation](https://laravel.com/docs) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development. - [PHP Custom Instrumentation](../custom-instrumentation/php.md) - Manual spans and advanced patterns. - [WordPress](./wordpress.md) - self-hosted WordPress on Apache or PHP-FPM. - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language. --- ## Litestar OpenTelemetry Instrumentation - Async API Tracing ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Implement OpenTelemetry instrumentation for Litestar applications to capture distributed traces, metrics, and structured logs from your async Python APIs. This guide shows you how to auto-instrument Litestar with the `opentelemetry-instrument` CLI wrapper and the `OpenTelemetryPlugin` shipped in `litestar.contrib.opentelemetry`, so HTTP server spans, asyncpg queries, httpx outbound calls, and SQLAlchemy operations land in your collector with no SDK boilerplate in your application code. Litestar is a modern ASGI Python framework, a close alternative to [FastAPI](./fast-api.md) with a more batteries-included feel than [Flask](./flask.md). Litestar uses its own custom ASGI router, which means the generic `opentelemetry-instrumentation-asgi` package cannot produce HTTP server spans for it on its own. The Litestar team ships a first-class plugin precisely for this case, and combining it with the standard auto-instrumentation distro gives you a complete picture: server spans from Litestar, query spans from asyncpg, client spans from httpx, ORM spans from SQLAlchemy, and trace-IDs injected onto every JSON log line. All of it driven by environment variables, all of it production-ready. Whether you are migrating from DataDog or New Relic, standing up observability for the first time on a greenfield Litestar service, or replacing a DIY logging setup with OTLP-exported telemetry, this guide walks through a working two-service example: a Litestar articles API backed by PostgreSQL (asyncpg + SQLAlchemy + Alembic) that calls a sibling Litestar notify service over httpx. You will see how a single `POST /api/articles` flows through both services under one trace ID, why `BEGIN`/`COMMIT` spans are noise worth filtering, and how to add a `articles.created` counter without writing any SDK plumbing yourself. :::tip TL;DR Add `OpenTelemetryPlugin(config=OpenTelemetryConfig())` to your Litestar `plugins` list, install `opentelemetry-distro` plus the asyncpg, httpx, and logging contrib packages, and boot uvicorn under `opentelemetry-instrument`. Set `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi` so the generic ASGI patch does not double-handle requests, and `OTEL_PYTHON_LOG_CORRELATION=true` so trace IDs land on your log records. Traces, metrics, and logs export to base14 Scout via OTLP with no changes to your route handlers. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Litestar developers**: building production async APIs with msgspec validation, advanced-alchemy repositories, and uvicorn deployments. - **DevOps engineers**: containerising Litestar services with Docker Compose or Kubernetes and wiring them into an OTel collector. - **Backend teams**: migrating from FastAPI to Litestar and looking for parity in their observability stack. - **Engineering teams**: switching off DataDog, New Relic, or AppDynamics in favour of open-source OpenTelemetry exported to base14 Scout. - **Platform engineers**: standardising tracing, metrics, and structured logging across multiple Python microservices that share a collector. ### Overview This guide demonstrates how to: - Instrument a Litestar app using `OpenTelemetryPlugin` from the official `litestar.contrib.opentelemetry` module. - Auto-instrument asyncpg, SQLAlchemy, and httpx via the `opentelemetry-instrument` CLI wrapper. - Inject trace IDs onto every Python `LogRecord` via `OTEL_PYTHON_LOG_CORRELATION=true` and surface them in JSON logs. - Add custom counters and span attributes without writing SDK setup code. - Filter out liveness probes and asyncpg transaction-lifecycle noise at the collector. - Run the full stack locally with Docker Compose against a real Postgres. - Export OTLP/HTTP to base14 Scout with OAuth2 client credentials and gzip. #### Prerequisites Before starting, ensure you have: - **Python 3.11 or later** installed (Python 3.14 recommended for best performance and free-threaded build support). - **Litestar 2.0 or later** installed in your project (2.21.1 used in the example). - **PostgreSQL 14+** if you intend to use the asyncpg + SQLAlchemy combination (Postgres 18 in the example). - **Scout Collector** configured and accessible from your application. - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development. - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment. - **Basic understanding** of OpenTelemetry concepts (traces, spans, metrics, resources, propagators). - Access to package installation via `pip`, `poetry`, or `uv`. #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | ---------------------------------------- | --------------- | ------------------- | ---------------------------------------------------------------- | | **Python** | 3.11 | 3.14 | Litestar 2.x supports 3.8+; 3.11+ recommended for asyncio perf. | | **Litestar** | 2.0 | 2.21.1+ | Earlier 1.x is the legacy "Starlite" name, schema differs. | | **OpenTelemetry SDK** | 1.30.0 | 1.41+ | Core SDK for traces, metrics, logs. | | **OpenTelemetry contrib instrumentations** | 0.50b0 | 0.62b0+ | asyncpg, httpx, SQLAlchemy, logging packages. | | **opentelemetry-distro** | 0.50b0 | 0.62b0+ | Provides the `opentelemetry-instrument` CLI wrapper. | | **asyncpg** (optional) | 0.27 | 0.31.0 | Native Postgres driver. | | **SQLAlchemy** (optional) | 2.0 | 2.0.49 | 2.x async API required for the example. | | **httpx** (optional) | 0.24 | 0.28.1 | For outbound HTTP tracing and W3C propagation. | | **uvicorn** | 0.20 | 0.30+ | ASGI server; the `opentelemetry-instrument` wrapper boots it. | #### What Gets Instrumented OpenTelemetry produces the following telemetry for the Litestar example shipped at [python/litestar-postgres](https://github.com/base-14/examples/tree/main/python/litestar-postgres): | Source | Telemetry produced | Driver | | ---------------------- | ------------------------------------------------------------------------------- | --------------------------------------------------- | | HTTP server | One server span per request (method, route, status, duration) | `litestar.contrib.opentelemetry.OpenTelemetryPlugin` | | Database (Postgres) | One client span per asyncpg statement (prepared statement text, duration) | `opentelemetry-instrumentation-asyncpg` | | ORM | One client span per SQLAlchemy operation (logical SQL, dialect) | `opentelemetry-instrumentation-sqlalchemy` | | Outbound HTTP | One client span per httpx call, with `traceparent` header injection | `opentelemetry-instrumentation-httpx` | | Logs | `otelTraceID`, `otelSpanID`, `otelTraceSampled`, `otelServiceName` on every record | `opentelemetry-instrumentation-logging` | | Custom metrics | `articles.created` counter; `notifications.received` counter | OpenTelemetry Meter API in `src/telemetry.py` | The complete working example with two services, Alembic migrations, a collector config, an end-to-end smoke script, and a verifier that proves telemetry reached Scout is at [python/litestar-postgres](https://github.com/base-14/examples/tree/main/python/litestar-postgres). Read along with this guide. ### Installation The Litestar example uses `uv` as its package manager but the OpenTelemetry packages install identically with `pip` or Poetry. Pick the tab that matches your project. ```mdx-code-block ``` ```bash uv add opentelemetry-api opentelemetry-sdk \ opentelemetry-exporter-otlp opentelemetry-distro \ opentelemetry-instrumentation \ opentelemetry-instrumentation-asgi \ opentelemetry-instrumentation-asyncpg \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging ``` ```mdx-code-block ``` ```bash pip install opentelemetry-api opentelemetry-sdk \ opentelemetry-exporter-otlp opentelemetry-distro \ opentelemetry-instrumentation \ opentelemetry-instrumentation-asgi \ opentelemetry-instrumentation-asyncpg \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging ``` ```mdx-code-block ``` ```bash poetry add opentelemetry-api opentelemetry-sdk \ opentelemetry-exporter-otlp opentelemetry-distro \ opentelemetry-instrumentation \ opentelemetry-instrumentation-asgi \ opentelemetry-instrumentation-asyncpg \ opentelemetry-instrumentation-sqlalchemy \ opentelemetry-instrumentation-httpx \ opentelemetry-instrumentation-logging ``` ```mdx-code-block ``` #### Pinned Dependencies For reproducible production builds, pin the OpenTelemetry packages alongside your Litestar project. The example uses these versions in `app/pyproject.toml`: ```toml title="app/pyproject.toml" showLineNumbers [project] name = "litestar-articles" version = "0.1.0" description = "Litestar + PostgreSQL articles API with OpenTelemetry instrumentation" requires-python = ">=3.14" dependencies = [ "litestar[standard]==2.21.1", "msgspec==0.21.1", "sqlalchemy[asyncio]==2.0.49", "asyncpg==0.31.0", "alembic==1.18.4", "advanced-alchemy==1.9.3", "httpx==0.28.1", "python-json-logger==4.1.0", # OpenTelemetry — SDK + auto-instrumentation "opentelemetry-api==1.41.0", "opentelemetry-sdk==1.41.0", "opentelemetry-exporter-otlp==1.41.0", "opentelemetry-distro==0.62b0", "opentelemetry-instrumentation==0.62b0", "opentelemetry-instrumentation-asgi==0.62b0", "opentelemetry-instrumentation-sqlalchemy==0.62b0", "opentelemetry-instrumentation-httpx==0.62b0", "opentelemetry-instrumentation-asyncpg==0.62b0", "opentelemetry-instrumentation-logging==0.62b0", ] ``` #### Why a Distro Plus Per-Library Packages `opentelemetry-distro` provides the `opentelemetry-instrument` CLI wrapper that reads `OTEL_*` environment variables, builds a `TracerProvider` and `MeterProvider`, and patches every installed instrumentation package before your application code runs. The per-library packages (`opentelemetry-instrumentation-asyncpg`, etc.) are what get picked up by the distro at boot. Install them both - the distro alone does not include the contrib instrumentations. ### Configuration Litestar instrumentation needs two pieces wired up: the `OpenTelemetryPlugin` inside your application code, and `OTEL_*` environment variables consumed by the wrapper at boot. Both are required, and the order matters - the wrapper sets the global `TracerProvider` before uvicorn imports your code, so the plugin picks up the same provider automatically. #### The OpenTelemetryPlugin Litestar uses a custom router that does not match the generic ASGI app shape, so `opentelemetry-instrumentation-asgi` cannot produce HTTP server spans for it on its own. The Litestar team ships `litestar.contrib.opentelemetry.OpenTelemetryPlugin` precisely for this: ```python title="app/src/main.py" showLineNumbers from advanced_alchemy.extensions.litestar import ( AsyncSessionConfig, SQLAlchemyAsyncConfig, SQLAlchemyPlugin, ) from litestar import Litestar from litestar.contrib.opentelemetry import OpenTelemetryConfig, OpenTelemetryPlugin from litestar.di import Provide from src.config import Settings from src.controllers.article import ArticleController from src.controllers.health import HealthController from src.logging_config import build_logging_config from src.services.notification import NotificationService def create_app(notification_service: NotificationService | None = None) -> Litestar: settings = Settings.from_env() notifier = notification_service or NotificationService(url=settings.notify_url) db_config = SQLAlchemyAsyncConfig( connection_string=settings.database_url, session_config=AsyncSessionConfig(expire_on_commit=False), create_all=False, ) # Litestar uses a custom ASGI router, so the generic # opentelemetry-instrumentation-asgi auto-patch does not produce # server spans for it. This plugin wires the same instrumentation # into Litestar's request lifecycle properly. otel_config = OpenTelemetryConfig() return Litestar( route_handlers=[HealthController, ArticleController], plugins=[ SQLAlchemyPlugin(config=db_config), OpenTelemetryPlugin(config=otel_config), ], dependencies={ "notification_service": Provide(lambda: notifier, sync_to_thread=False) }, on_shutdown=[notifier.aclose], logging_config=build_logging_config(), ) app = create_app() ``` Pair this with `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi` in your environment to make the choice explicit and avoid the generic ASGI auto-patch double-handling requests. #### Configuration Approaches Pick the approach that matches your deployment target. The example uses Docker Compose, but pure environment variables and shell-driven local dev are equally supported. ```mdx-code-block ``` Set these on your shell, your systemd unit, or your Kubernetes Pod spec. Boot uvicorn through the `opentelemetry-instrument` wrapper to install the SDK before your application code runs. ```bash export OTEL_SERVICE_NAME=litestar-postgres-app export OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 export OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf export OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.version=1.0.0 export OTEL_PYTHON_LOG_CORRELATION=true export OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi export OTEL_METRIC_EXPORT_INTERVAL=60000 export OTEL_BSP_SCHEDULE_DELAY=5000 opentelemetry-instrument uvicorn src.main:app --host 0.0.0.0 --port 8080 ``` ```mdx-code-block ``` The example bakes `opentelemetry-instrument` directly into the container `CMD`. Note the `alembic upgrade head` runs first so the schema is current before traffic arrives, and the wrapper instruments the uvicorn process that follows. ```dockerfile title="app/Dockerfile" showLineNumbers FROM python:3.14-slim AS builder COPY --from=ghcr.io/astral-sh/uv:0.6.12 /uv /usr/local/bin/uv WORKDIR /app RUN apt-get update && apt-get install -y --no-install-recommends \ gcc \ && rm -rf /var/lib/apt/lists/* COPY pyproject.toml uv.lock* ./ ENV UV_LINK_MODE=copy \ UV_COMPILE_BYTECODE=1 \ UV_PROJECT_ENVIRONMENT=/app/.venv RUN uv sync --no-dev --frozen FROM python:3.14-slim WORKDIR /app RUN apt-get update && apt-get install -y --no-install-recommends \ curl \ && rm -rf /var/lib/apt/lists/* \ && adduser --disabled-password --gecos '' --uid 1000 appuser COPY --from=builder --chown=appuser:appuser /app/.venv /app/.venv COPY --chown=appuser:appuser . . ENV PATH=/app/.venv/bin:$PATH \ PYTHONUNBUFFERED=1 \ PYTHONPATH=/app USER appuser EXPOSE 8080 HEALTHCHECK --interval=10s --timeout=5s --start-period=15s --retries=3 \ CMD curl -f http://localhost:8080/api/health || exit 1 # Run migrations then boot uvicorn under the OTel auto-instrumentation wrapper # (instruments ASGI, SQLAlchemy, httpx, asyncpg, logging). CMD ["sh", "-c", "alembic upgrade head && opentelemetry-instrument uvicorn src.main:app --host 0.0.0.0 --port 8080"] ``` ```mdx-code-block ``` Setting all `OTEL_*` variables in `compose.yml` keeps the Dockerfile generic and the configuration discoverable. The example uses this pattern for both services. ```yaml title="compose.yml" showLineNumbers services: app: build: context: ./app dockerfile: Dockerfile container_name: litestar-app env_file: - path: .env required: false ports: - "8080:8080" environment: - DATABASE_URL=postgresql+asyncpg://${DB_USERNAME:-postgres}:${DB_PASSWORD:?DB_PASSWORD is required}@postgres:5432/${DB_NAME:-articles} - NOTIFY_URL=http://notify:8081/notify - OTEL_SERVICE_NAME=litestar-postgres-app - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf - OTEL_RESOURCE_ATTRIBUTES=${OTEL_RESOURCE_ATTRIBUTES:-deployment.environment=development,environment=development,service.version=1.0.0} - OTEL_PYTHON_LOG_CORRELATION=true - OTEL_METRIC_EXPORT_INTERVAL=10000 - OTEL_BSP_SCHEDULE_DELAY=2000 # Litestar uses its own ASGI router, so we instrument it via # OpenTelemetryPlugin in code. Disable the generic ASGI auto-patch # to make the choice explicit (and avoid double-handling). - OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi depends_on: postgres: condition: service_healthy otel-collector: condition: service_started notify: condition: service_healthy networks: - app-network ``` ```mdx-code-block ``` #### Key Environment Variables | Variable | Purpose | Example value | | ------------------------------------- | -------------------------------------------------------- | --------------------------------------------------- | | `OTEL_SERVICE_NAME` | One unique value per service. | `litestar-postgres-app` | | `OTEL_EXPORTER_OTLP_ENDPOINT` | OTLP collector address. | `http://otel-collector:4318` | | `OTEL_EXPORTER_OTLP_PROTOCOL` | `http/protobuf` or `grpc`. | `http/protobuf` | | `OTEL_RESOURCE_ATTRIBUTES` | Comma-separated `k=v` resource tags. | `deployment.environment=development,service.version=1.0.0` | | `OTEL_PYTHON_LOG_CORRELATION` | Inject trace IDs onto Python LogRecords. | `true` | | `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS` | Skip auto-patching for the named entry-points. | `asgi` | | `OTEL_METRIC_EXPORT_INTERVAL` | Milliseconds between metric flushes. | `60000` (prod) / `10000` (dev) | | `OTEL_BSP_SCHEDULE_DELAY` | Milliseconds between span batch flushes. | `5000` (prod) / `2000` (dev) | ### Production Configuration The defaults that come with `opentelemetry-instrument` are tuned for correctness, not for cost. A handful of knobs make the difference between an expensive pipeline and a frugal one. #### BatchSpanProcessor Tuning The Python SDK's BatchSpanProcessor flushes spans either when the batch fills up or when `OTEL_BSP_SCHEDULE_DELAY` elapses, whichever comes first. ```bash # Faster export - useful for local dev where you want to see spans within seconds. export OTEL_BSP_SCHEDULE_DELAY=2000 export OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 # Frugal export - cuts egress bandwidth and reduces collector wakeups in production. export OTEL_BSP_SCHEDULE_DELAY=5000 export OTEL_BSP_MAX_EXPORT_BATCH_SIZE=2048 export OTEL_BSP_MAX_QUEUE_SIZE=4096 ``` `OTEL_METRIC_EXPORT_INTERVAL` does the same job for metrics. The example uses 10 s in dev so the verifier script finishes inside a minute; production defaults of 60 s are appropriate for most workloads. #### Compression and Resource Attributes OTLP/HTTP supports gzip compression. Enable it on the collector exporter (the example sets `compression: gzip`); the SDK side respects `OTEL_EXPORTER_OTLP_COMPRESSION` if you export directly without a collector. Resource attributes attach to every span, metric, and log emitted by the process. Set `service.version`, `deployment.environment`, and any other constants once via `OTEL_RESOURCE_ATTRIBUTES`: ```bash export OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.version=2.7.1,service.instance.id=$(hostname) ``` #### Collector Config The collector is where you do the bulk of the cleanup. Filter probes, drop transaction-lifecycle noise, and route to base14 Scout via OAuth2 client credentials: ```yaml title="config/otel-config.yaml" showLineNumbers extensions: oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s tls: insecure_skip_verify: true health_check: endpoint: 0.0.0.0:13133 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: limit_mib: 256 check_interval: 1s batch: timeout: 10s send_batch_size: 1024 filter/noisy: error_mode: ignore traces: span: # Drop liveness probes from both services so they do not pollute traces. # litestar-postgres-app uses /api/health, litestar-postgres-notify uses /health. - 'IsMatch(name, ".*(/api)?/health.*")' # Drop asyncpg transaction-lifecycle spans — BEGIN/COMMIT/ROLLBACK add # noise without telling you anything the INSERT/SELECT spans don't. - 'IsMatch(name, "^(BEGIN|COMMIT|ROLLBACK)( TRANSACTION)?;?$")' resource: attributes: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: detailed service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, resource, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/b14, debug] ``` `tls.insecure_skip_verify: true` is for local development against a Scout endpoint without a fully trusted certificate chain - never ship it to production. Remove it once your endpoint is publicly trusted. #### Multi-Service Distributed Tracing The example ships two Litestar services that share a single trace ID per inbound request. The article service receives `POST /api/articles`, writes to Postgres, then calls the notify service over httpx. Because `opentelemetry-instrumentation-httpx` is enabled, the `traceparent` header is injected automatically and the notify service's `OpenTelemetryPlugin` extracts it on the way in. ```text litestar-postgres-app ├── HTTP server span (POST /api/articles) │ ├── asyncpg span (INSERT INTO articles ...) │ ├── asyncpg span (SELECT ... FROM articles WHERE id = $1) │ └── httpx client span (POST http://notify:8081/notify) │ └── litestar-postgres-notify │ └── HTTP server span (POST /notify) ``` All four spans share one trace ID. Click any span in base14 Scout and you jump to the structured logs emitted by both services for that request. ### Framework-Specific Features #### Async Database Spans (asyncpg + SQLAlchemy) The example layers SQLAlchemy 2.x async over asyncpg via `advanced-alchemy`. Both packages are auto-instrumented when their respective contrib packages are installed; you get logical SQL from SQLAlchemy and the underlying prepared statements from asyncpg, both attached to the active server span. ```python title="app/src/repository.py" showLineNumbers from advanced_alchemy.repository import SQLAlchemyAsyncRepository from sqlalchemy.ext.asyncio import AsyncSession from src.models import Article class ArticleRepository(SQLAlchemyAsyncRepository[Article]): model_type = Article async def provide_article_repo(db_session: AsyncSession) -> ArticleRepository: return ArticleRepository(session=db_session) ``` A single `repo.add(article, auto_commit=True)` call produces a SQLAlchemy client span describing the insert and an asyncpg client span describing the prepared statement that hit Postgres - both as children of the inbound HTTP server span. There is nothing to wire up in the repository itself. #### Outbound HTTP and Distributed Context `opentelemetry-instrumentation-httpx` patches `httpx.AsyncClient` so every outbound call becomes a client span and gets a `traceparent` header. The example wraps a single shared client per service (pool churn would otherwise dominate the latency budget): ```python title="app/src/services/notification.py" showLineNumbers import httpx class NotificationService: """Pooled httpx wrapper. Subclassed in tests to record/fail without network.""" def __init__(self, url: str, timeout: float = 5.0) -> None: self.url = url self._client: httpx.AsyncClient | None = httpx.AsyncClient(timeout=timeout) async def send(self, *, article_id: int, title: str) -> None: assert self._client is not None, "NotificationService used after close" response = await self._client.post( self.url, json={"article_id": article_id, "title": title}, ) response.raise_for_status() async def aclose(self) -> None: if self._client is not None: await self._client.aclose() self._client = None ``` The `aclose` method is wired into Litestar's `on_shutdown` hook so the connection pool drains cleanly during graceful termination. #### Trace-Correlated Structured Logs `opentelemetry-instrumentation-logging` injects four attributes onto every Python `LogRecord` when `OTEL_PYTHON_LOG_CORRELATION=true`: ```text otelTraceID otelSpanID otelTraceSampled otelServiceName ``` Surface those keys in your formatter and you get trace-log correlation for free in base14 Scout. The example uses `python-json-logger` and Litestar's `LoggingConfig`: ```python title="app/src/logging_config.py" showLineNumbers from litestar.logging.config import LoggingConfig _FORMAT = ( "%(asctime)s %(levelname)s %(name)s %(message)s " "%(otelTraceID)s %(otelSpanID)s %(otelTraceSampled)s %(otelServiceName)s" ) def build_logging_config() -> LoggingConfig: return LoggingConfig( formatters={ "json": { "()": "pythonjsonlogger.json.JsonFormatter", "format": _FORMAT, } }, handlers={ "default": { "class": "logging.StreamHandler", "formatter": "json", "stream": "ext://sys.stdout", } }, loggers={ "uvicorn.access": { "level": "INFO", "handlers": ["default"], "propagate": False, }, "uvicorn.error": { "level": "INFO", "handlers": ["default"], "propagate": False, }, "sqlalchemy.engine": { "level": "WARNING", "handlers": ["default"], "propagate": False, }, }, root={"level": "INFO", "handlers": ["default"]}, ) ``` Returning a `LoggingConfig` object (rather than mutating the `logging` module directly) keeps Litestar from clobbering your handlers during init. #### msgspec Request and Response Bodies Litestar uses msgspec by default for request validation and response serialisation. msgspec itself does not need instrumentation - the HTTP server span emitted by `OpenTelemetryPlugin` already covers the full request lifecycle including msgspec decode/encode. If you want to break out validation time as a separate span, wrap the call manually (see Custom Instrumentation). ### Custom Instrumentation Auto-instrumentation covers HTTP, database, and outbound HTTP. Anything business-specific you add yourself, with the same OpenTelemetry API the contrib packages use under the hood. #### Adding Span Attributes from a Handler The active span inside any Litestar handler is the HTTP server span. Use the OpenTelemetry tracer API to tag it with anything you want to search by in Scout - request IDs, tenant IDs, the new row's primary key: ```python title="app/src/controllers/article.py" showLineNumbers from opentelemetry import trace from src.telemetry import articles_created class ArticleController(Controller): path = "/api/articles" dependencies = {"repo": Provide(provide_article_repo)} @post("/") async def create( self, data: ArticleCreate, repo: ArticleRepository, notification_service: NotificationService, ) -> ArticleRead: article = await repo.add( Article(title=data.title, body=data.body), auto_commit=True ) # Tag the active server span with the new ID so trace search by # `article.id` works in Scout — this is the canonical pattern for # adding business attributes to auto-instrumented spans. trace.get_current_span().set_attribute("article.id", article.id) articles_created.add(1) logger.info("article created", extra={"article_id": article.id}) try: await notification_service.send(article_id=article.id, title=article.title) except Exception as exc: logger.warning( "notification dispatch failed", extra={"article_id": article.id, "error": str(exc)}, ) return ArticleRead.from_model(article) ``` #### Custom Counters Acquire a Meter at module load time and create instruments alongside it. The `MeterProvider` is set up by `opentelemetry-instrument` before uvicorn imports your code, so the Counter binds to the real OTLP-exporting provider, never the no-op default: ```python title="app/src/telemetry.py" showLineNumbers from opentelemetry import metrics _meter = metrics.get_meter("litestar-postgres-app") articles_created = _meter.create_counter( name="articles.created", description="Number of articles successfully created", unit="1", ) ``` Bumping the counter is one line: ```python articles_created.add(1) ``` The same pattern works for histograms (`create_histogram`), up-down counters (`create_up_down_counter`), and observable gauges (`create_observable_gauge`). All of them export through the same OTLP pipeline as auto-instrumented metrics. #### Manual Spans for Business Logic For long-running internal operations that you want broken out from the parent HTTP server span, create a child span with `tracer.start_as_current_span`: ```python showLineNumbers from opentelemetry import trace tracer = trace.get_tracer("litestar-postgres-app") async def regenerate_search_index(repo: ArticleRepository) -> int: with tracer.start_as_current_span("articles.reindex") as span: items, total = await repo.list_and_count() span.set_attribute("articles.count", total) # ... call your search-index client here ... return total ``` The child span inherits the trace ID from the surrounding HTTP server span, so the reindex shows up as a nested span in the trace waterfall. #### Trace ID in Response Headers Returning the trace ID to the caller makes incident response dramatically easier - the user can paste the ID into Scout to find the exact request: ```python showLineNumbers from litestar import Request, Response, get from opentelemetry import trace @get("/api/articles/{article_id:int}") async def get_one_with_trace( request: Request, article_id: int, repo: ArticleRepository, ) -> Response[ArticleRead]: article = await repo.get_one_or_none(id=article_id) if article is None: raise NotFoundException(detail=f"Article {article_id} not found") trace_id = format(trace.get_current_span().get_span_context().trace_id, "032x") return Response( content=ArticleRead.from_model(article), headers={"X-Trace-Id": trace_id}, ) ``` ### Running Your Application The example ships a self-contained four-service stack: two Litestar services, Postgres, and an OTel collector. The Makefile wraps the common operations. #### Local Development with Docker Compose ```bash git clone https://github.com/base-14/examples.git cd examples/python/litestar-postgres cp .env.example .env # edit .env to set DB_PASSWORD; SCOUT_* vars are optional make docker-up # build + start all 4 services ./scripts/test-api.sh # CRUD smoke make docker-down ``` #### Verify Telemetry End-to-End Tail the collector to see telemetry land as it is exported: ```bash docker compose logs -f otel-collector ``` After a single `POST /api/articles` you should see: 1. **One trace ID** appearing in spans from both `litestar-postgres-app` (HTTP server, asyncpg INSERT/SELECT, httpx client) and `litestar-postgres-notify` (HTTP server). The notify service's parent span ID is the httpx client span ID - that is distributed tracing working. `BEGIN`/`COMMIT`/`ROLLBACK` transaction-lifecycle spans are dropped by the collector's `filter/noisy` processor - they add volume without insight. 2. **`articles.created`** as a cumulative monotonic Sum metric, with a value matching how many articles you have POSTed since startup. 3. **JSON log lines** in `app` and `notify` stdout containing `otelTraceID`, `otelSpanID`, `otelServiceName` - the same trace ID you saw in the spans. This is what powers the "jump from span to logs" UI flow in Scout. #### Smoke Test the API `scripts/test-api.sh` exercises the full CRUD surface and exits non-zero on the first failure, so it slots cleanly into CI: ```bash title="scripts/test-api.sh" showLineNumbers #!/usr/bin/env bash # End-to-end CRUD smoke. Assumes `make docker-up` is already running. # Exits non-zero on the first failure so it slots into CI cleanly. set -euo pipefail BASE_URL="${API_BASE_URL:-http://localhost:8080}" NOTIFY_URL="${NOTIFY_BASE_URL:-http://localhost:8081}" # 1. health checks check "GET /api/health (articles)" 200 "$(status_of "$BASE_URL/api/health")" check "GET /health (notify)" 200 "$(status_of "$NOTIFY_URL/health")" # 2. create RESP=$(curl -s -w "\n%{http_code}" -X POST "$BASE_URL/api/articles" \ -H 'Content-Type: application/json' \ -d '{"title":"smoke","body":"created by test-api.sh"}') # 3. get one check "GET /api/articles/{id}" 200 "$(status_of "$BASE_URL/api/articles/$ARTICLE_ID")" # 4. list with pagination LIST_BODY=$(curl -s "$BASE_URL/api/articles?limit=10&offset=0") # 5. update check "PUT /api/articles/{id}" 200 "$(status_of -X PUT "$BASE_URL/api/articles/$ARTICLE_ID" \ -H 'Content-Type: application/json' \ -d '{"title":"smoke-updated","body":"after PUT"}')" # 6. delete check "DELETE /api/articles/{id}" 204 "$(status_of -X DELETE "$BASE_URL/api/articles/$ARTICLE_ID")" ``` #### Running Without Docker The Litestar app itself runs anywhere uvicorn does. From the `app/` directory: ```bash uv sync export DATABASE_URL=postgresql+asyncpg://postgres:postgres@localhost:5432/articles export OTEL_SERVICE_NAME=litestar-postgres-app export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 export OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf export OTEL_PYTHON_LOG_CORRELATION=true export OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi alembic upgrade head uv run opentelemetry-instrument uvicorn src.main:app --host 0.0.0.0 --port 8080 ``` ### Troubleshooting #### No HTTP Server Spans Appear **Symptom**: asyncpg and httpx client spans show up, but you never see a parent HTTP server span - every client span is a root span. **Cause**: `OpenTelemetryPlugin` is not in the `plugins` list, so Litestar's custom router is not wired into the OTel context. The generic ASGI auto-patch alone cannot trace Litestar. **Fix**: Add the plugin to your Litestar instance: ```python from litestar.contrib.opentelemetry import OpenTelemetryConfig, OpenTelemetryPlugin app = Litestar( route_handlers=[...], plugins=[OpenTelemetryPlugin(config=OpenTelemetryConfig())], ) ``` #### Duplicate or Conflicting HTTP Spans **Symptom**: every request produces two HTTP server spans - one named after your route, one named `HTTP {method}`. **Cause**: both `OpenTelemetryPlugin` and the generic ASGI auto-patch are producing server spans. The generic patch picks up the inner ASGI app and double-handles each request. **Fix**: Disable the generic ASGI auto-patch by setting `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi` in your environment. #### Trace IDs Missing from Log Lines **Symptom**: Your JSON logs ship to Scout, but `otelTraceID` is always `"0"` or absent. **Cause**: One of three things - `OTEL_PYTHON_LOG_CORRELATION` is unset, `opentelemetry-instrumentation-logging` is not installed, or the formatter does not surface the injected fields. **Fix**: 1. Confirm the env var is set: `echo $OTEL_PYTHON_LOG_CORRELATION` should print `true`. 2. Confirm the package is installed: `pip show opentelemetry-instrumentation-logging`. 3. Confirm your formatter format string includes the keys: ```python _FORMAT = ( "%(asctime)s %(levelname)s %(name)s %(message)s " "%(otelTraceID)s %(otelSpanID)s %(otelTraceSampled)s %(otelServiceName)s" ) ``` #### Health Check Probes Polluting Traces **Symptom**: Your trace volume is dominated by `/health` and `/api/health` spans from Kubernetes liveness probes. **Cause**: probes hit your service every few seconds and produce a span every time. **Fix**: drop them at the collector with a filter processor. The example config does this: ```yaml processors: filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*(/api)?/health.*")' ``` Filtering at the collector is preferable to filtering at the SDK because it keeps your application code simple and works for every probe path consistently across services. #### asyncpg Spans Show `BEGIN` / `COMMIT` Noise **Symptom**: Every CRUD request produces three spans called `BEGIN`, `INSERT`, `COMMIT`. Your trace waterfall is double the height it needs to be. **Cause**: asyncpg emits a span for every prepared statement, including transaction-lifecycle ones. They double trace volume without revealing anything the INSERT/SELECT spans don't already. **Fix**: drop them at the collector with a filter rule: ```yaml processors: filter/noisy: traces: span: - 'IsMatch(name, "^(BEGIN|COMMIT|ROLLBACK)( TRANSACTION)?;?$")' ``` If you need them for diagnosing a transaction-isolation bug, comment the rule out temporarily - the SDK is still emitting them; they just stop landing downstream. ### Security Considerations #### Sensitive Data in Span Attributes Auto-instrumentation captures HTTP request/response headers, query parameters, and prepared statement text. Before exporting to a third-party backend, audit what is being captured: - **HTTP headers**: `Authorization`, `Cookie`, and custom auth headers may appear in `http.request.header.*` attributes. Litestar's `OpenTelemetryConfig` lets you filter them via the `server_request_hook` parameter - set sensitive header names to `[REDACTED]` before the span closes. - **Query parameters**: API tokens passed as `?api_key=...` show up in the `url.full` attribute. Strip them at the SDK or collector before export. - **SQL parameter values**: SQLAlchemy auto-instrumentation can be configured to omit bound parameters (`enable_commenter=False` and the `tracer_provider` hooks). asyncpg captures prepared-statement text but not the bound parameter values, which is normally what you want. #### PII in Custom Span Attributes When you call `set_attribute` yourself, you control what gets recorded. Avoid attaching email addresses, full names, IP addresses, or anything that identifies a user directly. Use opaque IDs (`tenant.id`, `user.id`) and look up the PII separately in your application database when needed. #### Compliance: GDPR, HIPAA, SOC 2 OpenTelemetry is a transport - what makes a deployment compliant or not is what attributes you capture, where you store them, and who can read them. For regulated workloads: - Run the collector in the same trust zone as your application, with outbound traffic restricted to your observability backend's endpoint. - Use the collector's `attributes` and `redaction` processors to strip PII before export. Don't rely on the application to get this right consistently. - Configure data retention on the backend side. base14 Scout supports per-tenant retention policies; configure them to match your compliance posture. - Encrypt OTLP in transit. The example collector exporter uses TLS (`tls.insecure_skip_verify` is for local development only - remove it in production). #### Authentication to the Collector The example uses OAuth2 client credentials between the collector and base14 Scout, with the secret materialised from environment variables, never committed to the repository: ```yaml extensions: oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} ``` Rotate `SCOUT_CLIENT_SECRET` regularly and inject it via your secret manager of choice (AWS Secrets Manager, HashiCorp Vault, Kubernetes Secrets) - never bake it into a container image. ### Performance Considerations #### Measured Overhead For the example articles API on Python 3.14 / Litestar 2.21.1, with all six contrib instrumentations enabled, the measured overhead per `POST /api/articles` is: | Metric | Without OTel | With OTel | Delta | | ------------------------------- | ------------ | --------- | --------- | | p50 latency | 12 ms | 14 ms | +2 ms | | p99 latency | 28 ms | 32 ms | +4 ms | | CPU per request | baseline | +3% | +3% | | Resident memory (steady state) | 95 MB | 145 MB | +50 MB | The bulk of the latency hit is asyncpg span construction; the SDK itself contributes well under 1 ms per request. CPU and memory grow with span batch size - the BatchSpanProcessor holds spans until the next flush. #### Batch and Buffer Tuning The defaults are fine for most workloads. Knobs that matter when you start seeing dropped spans (visible as warnings in the SDK logs): ```bash # Larger queue smooths out traffic bursts. export OTEL_BSP_MAX_QUEUE_SIZE=4096 # Larger batches reduce export-call overhead. export OTEL_BSP_MAX_EXPORT_BATCH_SIZE=2048 # Slower flush reduces collector wakeups, increases tail latency to dashboard. export OTEL_BSP_SCHEDULE_DELAY=5000 ``` The metric-side knobs are simpler: `OTEL_METRIC_EXPORT_INTERVAL` controls how often counters and histograms ship. 60 s is the OTel default; the example uses 10 s in dev so the verifier finishes quickly. #### Health Check Filtering Liveness probes from Docker, Kubernetes, or your load balancer hit your service every few seconds. Without filtering, they dominate span volume. Always filter `/health`-style paths at the collector. The example config shows the pattern - a regex against `name` in the `filter/noisy` processor. #### Connection Pooling The httpx auto-instrumentation does not change pool behaviour, but how you construct the client does. Always reuse a single `httpx.AsyncClient` across requests; constructing a new client per call destroys the keep-alive pool and adds TLS handshake latency to every outbound call. The example wraps a shared client in a service class and closes it on Litestar shutdown. #### What Auto-Instrumentation Does Not Do - It does not instrument framework-internal hooks (Litestar guards, middlewares written by you, custom dependencies). Wrap them manually with `tracer.start_as_current_span` if you need to. - It does not group asyncpg `BEGIN`/`COMMIT` spans with the surrounding request - they appear as separate child spans of the server span. Drop them at the collector if they are noise to you. - It does not propagate context across `asyncio.create_task` if the task is spawned from a synchronous frame. Use `with trace.use_span(...)` inside the task body to re-attach context. ### FAQ #### Why does Litestar need OpenTelemetryPlugin instead of just opentelemetry-instrument? Litestar uses its own ASGI router rather than the generic ASGI app pattern, so `opentelemetry-instrumentation-asgi` cannot produce HTTP server spans for it automatically. The `OpenTelemetryPlugin` from `litestar.contrib.opentelemetry` hooks into Litestar's request lifecycle directly. Set `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS=asgi` to avoid double handling. #### What is the performance overhead of OpenTelemetry on Litestar? Typical overhead is 1-3 ms added latency per HTTP request, 2-5% CPU increase, and 30-60 MB additional memory. The BatchSpanProcessor exports telemetry asynchronously, so request latency is not blocked on collector network calls. Filter health checks at the collector to keep span volume proportional to real traffic. #### Which Python and Litestar versions are supported? Python 3.11+ minimum (3.14 recommended), Litestar 2.0+ (2.21.1+ recommended), OpenTelemetry SDK 1.30+ (1.41+ recommended), and contrib instrumentations 0.50b0+ (0.62b0+ recommended). The example pins Python 3.14 and Litestar 2.21.1. #### How does asyncpg auto-instrumentation differ from SQLAlchemy instrumentation? `opentelemetry-instrumentation-asyncpg` patches the asyncpg driver, capturing every prepared statement and query as a span. `opentelemetry-instrumentation-sqlalchemy` hooks the engine, capturing logical SQL with bound parameters. Both can be enabled together when SQLAlchemy is layered over asyncpg, which is the typical Litestar setup - you get the high-level operation from SQLAlchemy and the wire-level statement from asyncpg, both attached to the same parent span. #### How do I correlate logs with traces in Litestar? Set `OTEL_PYTHON_LOG_CORRELATION=true`. The `opentelemetry-instrumentation-logging` package injects `otelTraceID`, `otelSpanID`, `otelTraceSampled`, and `otelServiceName` onto every Python `LogRecord`. Include those keys in your JSON formatter and Litestar's `LoggingConfig` surfaces them on every log line. Trace-to-log navigation in base14 Scout uses `otelTraceID` as the join key. #### Can I add custom span attributes from Litestar route handlers? Yes. Call `trace.get_current_span().set_attribute(key, value)` inside your handler. The active span is the HTTP server span produced by `OpenTelemetryPlugin`, so any attribute you set is searchable in base14 Scout per request. The example tags `article.id` on every successful create. #### Why are BEGIN and COMMIT spans missing from my traces? In the example collector config they are dropped by a `filter/noisy` processor because asyncpg emits a span per transaction-lifecycle statement. `BEGIN`, `COMMIT`, and `ROLLBACK` add volume without insight beyond what the INSERT/SELECT spans already show. Remove the filter rule to keep them if you are debugging a transaction-isolation issue. #### How does distributed tracing work between two Litestar services? `opentelemetry-instrumentation-httpx` injects W3C `traceparent` headers on outbound HTTP requests. The receiving Litestar service's `OpenTelemetryPlugin` extracts the headers and creates a child span under the same trace ID. No code changes required on either side - it works as long as both services have the plugin and the contrib package installed. #### Does OpenTelemetry support Litestar WebSockets and Server-Sent Events? `OpenTelemetryPlugin` produces a single long-lived span for WebSocket connections, covering the connection lifetime. Server-Sent Events produce a normal HTTP server span. For per-message tracing inside a WebSocket, create child spans manually with the OpenTelemetry tracer API. #### How do I add custom metrics like a counter to a Litestar handler? Call `metrics.get_meter(name)` to acquire a Meter, then `create_counter()` at module load time and call `.add(1)` inside the handler. The `MeterProvider` is initialised by `opentelemetry-instrument` before uvicorn imports your code, so the counter binds to the real OTLP-exporting provider. The example does this in `app/src/telemetry.py` for `articles.created`. #### How do I disable a specific auto-instrumentation? Use `OTEL_PYTHON_DISABLED_INSTRUMENTATIONS` with a comma-separated list of entry-point names. The example disables `asgi` so the generic ASGI patch does not double-handle Litestar requests. The full list of names is visible in `pip show opentelemetry-instrumentation-asgi` and similar packages - each contrib package registers itself under a short name. #### Can I use this guide with the legacy Starlite name? Starlite was renamed to Litestar at version 2.0. The `litestar.contrib.opentelemetry` plugin is only on the Litestar branch - on Starlite 1.x you have to use `opentelemetry-instrumentation-asgi` and accept that the spans will be coarser. Migrating to Litestar 2.x is the right answer. ### What's Next You now have working OpenTelemetry instrumentation for a Litestar service backed by asyncpg, SQLAlchemy, and httpx, with structured logs correlated to traces and a custom counter exporting alongside the auto-instrumented metrics. From here: - **Wire metric dashboards**: build Scout dashboards over `articles.created` and your auto-instrumented HTTP histograms to track p50/p99 per route. - **Add error tracking**: hook `Exception` events on the active span via `span.record_exception(exc)` from your handler error paths. - **Wrap slow internal operations**: any background task or third-party client call benefits from a manual child span - the surrounding HTTP span already gives you the context. [base14 Scout](https://base14.io) provides managed OTLP ingestion, dashboards, and alerting for OpenTelemetry data, so the same guide that gets you spans locally also gets you a production observability backend with no extra SDK configuration. ### Complete Example The full working example with two Litestar services, Postgres, the OTel collector, Alembic migrations, and end-to-end verification scripts is at [python/litestar-postgres](https://github.com/base-14/examples/tree/main/python/litestar-postgres). Layout: ```text litestar-postgres/ ├── app/ # litestar-postgres-app service │ ├── src/ │ │ ├── main.py # create_app() factory + module-level `app` │ │ ├── config.py # env-driven Settings │ │ ├── models.py # Article ORM + Base │ │ ├── repository.py # SQLAlchemyAsyncRepository[Article] │ │ ├── telemetry.py # OTel Meter + articles.created counter │ │ ├── logging_config.py # JSON formatter wired via Litestar LoggingConfig │ │ ├── controllers/ # health.py, article.py │ │ └── services/ # notification.py (httpx client) │ ├── alembic/ # async migrations │ ├── tests/ # pytest (12 tests) │ ├── pyproject.toml # uv project │ └── Dockerfile ├── notify/ # litestar-postgres-notify service │ ├── src/{main.py,logging_config.py,telemetry.py} │ ├── tests/ # pytest (2 tests) │ ├── pyproject.toml │ └── Dockerfile ├── config/otel-config.yaml # collector pipeline (debug + Scout) ├── compose.yml # 4 services ├── Makefile # sync/test/lint/format/audit/check + docker-* targets └── scripts/ ├── test-api.sh # CRUD smoke against running stack └── verify-scout.sh # end-to-end OTel pipeline verification ``` To run it: ```bash git clone https://github.com/base-14/examples.git cd examples/python/litestar-postgres cp .env.example .env # edit .env to set DB_PASSWORD; SCOUT_* vars are optional for local-only dev make docker-up ./scripts/test-api.sh make docker-down ``` The `notify` service's `main.py` shows the minimum-viable Litestar OTel setup - same plugin, same wrapper, no database: ```python title="notify/src/main.py" showLineNumbers import logging import msgspec from litestar import Controller, Litestar, get, post from litestar.contrib.opentelemetry import OpenTelemetryConfig, OpenTelemetryPlugin from src.logging_config import build_logging_config from src.telemetry import notifications_received logger = logging.getLogger(__name__) class NotifyPayload(msgspec.Struct): article_id: int title: str class HealthController(Controller): path = "/health" @get("/") async def health(self) -> dict[str, str]: return {"status": "ok", "service": "litestar-postgres-notify"} class NotifyController(Controller): path = "/notify" @post("/", status_code=200) async def notify(self, data: NotifyPayload) -> dict[str, object]: notifications_received.add(1) logger.info( "article notification received", extra={"article_id": data.article_id, "title": data.title}, ) return {"received": True, "article_id": data.article_id} app = Litestar( route_handlers=[HealthController, NotifyController], plugins=[OpenTelemetryPlugin(config=OpenTelemetryConfig())], logging_config=build_logging_config(), ) ``` ### References - [Litestar OpenTelemetry plugin documentation](https://docs.litestar.dev/2/usage/plugins/opentelemetry.html) - [OpenTelemetry Python documentation](https://opentelemetry.io/docs/languages/python/) - [opentelemetry-distro on PyPI](https://pypi.org/project/opentelemetry-distro/) - [opentelemetry-instrumentation-asyncpg on PyPI](https://pypi.org/project/opentelemetry-instrumentation-asyncpg/) - [opentelemetry-instrumentation-sqlalchemy on PyPI](https://pypi.org/project/opentelemetry-instrumentation-sqlalchemy/) - [opentelemetry-instrumentation-httpx on PyPI](https://pypi.org/project/opentelemetry-instrumentation-httpx/) - [W3C Trace Context specification](https://www.w3.org/TR/trace-context/) - [base14 Scout](https://base14.io) ### Related Guides - [Django Instrumentation](./django.md) - Batteries-included Python framework - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language - [Docker Compose Collector Setup](../../collector-setup/docker-compose-example.md) - local OTel collector for development. --- ## LlamaIndex OpenTelemetry Instrumentation - RAG & Agent Monitoring Guide ## LlamaIndex Implement OpenTelemetry instrumentation for LlamaIndex applications to enable comprehensive AI application monitoring, LLM cost tracking, and quality evaluation. This guide shows you how to instrument a LlamaIndex-powered content quality agent with custom GenAI semantic convention spans, multi-provider LLM support, structured output with self-correction, token and cost metrics, PII scrubbing, and eval-driven development with Promptfoo. LlamaIndex is a Python framework for LLM data and RAG applications, alongside [LangGraph](./langgraph.md) for agents and the TypeScript [Vercel AI SDK](./vercel-ai-sdk.md). This guide intentionally uses **custom OpenTelemetry GenAI semantic conventions** rather than OpenInference or LlamaIndex auto-instrumentation. OpenInference produces non-standard attributes (`llm.*`, `input.*`, `output.*`) that pollute telemetry with framework-specific data outside the OTel GenAI semconv. Custom instrumentation gives you full control over what gets recorded and ensures your telemetry works with any OpenTelemetry-compatible backend. Whether you're building AI agents, content analysis pipelines, RAG systems, or multi-provider LLM applications, this guide provides production-ready patterns for unified AI observability where LLM spans, token metrics, cost attribution, and evaluation scores live alongside your standard HTTP and database telemetry in a single trace. > **Note:** For general LLM observability patterns applicable to any Python > framework, see the > [LLM Observability guide](../../../guides/ai-observability/llm-observability.md). > This guide focuses specifically on LlamaIndex integration patterns. :::tip TL;DR Use custom OpenTelemetry spans with GenAI semantic conventions to instrument LlamaIndex - not OpenInference or the built-in auto-instrumentation. Wrap each LLM call in a span that records model, token counts, and cost using a pricing table, then attach a PII scrubber before recording prompts and completions. Pair this with versioned YAML prompt templates and Promptfoo evaluations for a full production observability setup. ::: ### Who This Guide Is For This documentation is designed for: - **AI/ML engineers**: building LlamaIndex-powered features and needing visibility into model performance, cost, and quality - **Backend developers**: adding AI capabilities to existing FastAPI applications and wanting unified tracing - **Platform teams**: standardizing observability across AI services and traditional microservices - **Engineering teams**: migrating from LangSmith or other proprietary AI observability tools to OpenTelemetry - **DevOps engineers**: deploying AI applications with production monitoring, cost alerting, and quality tracking ### Overview This guide demonstrates how to: - Set up unified OpenTelemetry for a LlamaIndex application (traces + metrics + logs) - Create custom LLM spans following OpenTelemetry GenAI semantic conventions - Support multiple LLM providers (OpenAI, Anthropic, Google) through a single interface - Implement structured output with JSON self-correction loops - Track token usage and calculate cost per LLM call with a pricing table - Record evaluation metrics for content quality tracking - Scrub PII from prompts and completions before recording in telemetry - Manage prompts with versioned YAML templates - Run eval-driven development with Promptfoo - Deploy with Docker Compose and the OpenTelemetry Collector ### Prerequisites Before starting, ensure you have: - **Python 3.12 or later** installed (3.14+ recommended) - **An LLM API key** from at least one provider (OpenAI, Anthropic, or Google) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Basic understanding of OpenTelemetry concepts (traces, spans, metrics) #### Compatibility Matrix | Component | Minimum Version | Recommended | | ----------------------------- | --------------- | ----------- | | Python | 3.12 | 3.14+ | | opentelemetry-sdk | 1.39.0 | 1.39+ | | opentelemetry-api | 1.39.0 | 1.39+ | | FastAPI | 0.115+ | 0.128+ | | llama-index-core | 0.14.0 | 0.14.13+ | | llama-index-llms-openai | 0.6.0 | 0.6.18+ | | llama-index-llms-anthropic | 0.10.0 | 0.10.8+ | | llama-index-llms-google-genai | 0.8.0 | 0.8.7+ | | Pydantic | 2.0 | 2.12.5+ | ### Installation ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash showLineNumbers title="Terminal" pip install \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-logging \ llama-index-core \ llama-index-llms-openai \ llama-index-llms-anthropic \ llama-index-llms-google-genai \ fastapi uvicorn pydantic-settings \ tenacity httpx pyyaml ``` ```mdx-code-block ``` ```bash showLineNumbers title="Terminal" uv add \ opentelemetry-api \ opentelemetry-sdk \ opentelemetry-exporter-otlp-proto-http \ opentelemetry-instrumentation-fastapi \ opentelemetry-instrumentation-logging \ llama-index-core \ llama-index-llms-openai \ llama-index-llms-anthropic \ llama-index-llms-google-genai \ fastapi uvicorn pydantic-settings \ tenacity httpx pyyaml ``` ```mdx-code-block ``` ### Configuration ```mdx-code-block ``` ```python showLineNumbers title="src/content_quality/telemetry.py" import atexit import logging import os from importlib.metadata import version from typing import Any from opentelemetry import _logs, metrics, trace from opentelemetry.exporter.otlp.proto.http._log_exporter import OTLPLogExporter from opentelemetry.exporter.otlp.proto.http.metric_exporter import OTLPMetricExporter from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter from opentelemetry.instrumentation.logging import LoggingInstrumentor from opentelemetry.sdk._logs import LoggerProvider, LoggingHandler from opentelemetry.sdk._logs.export import BatchLogRecordProcessor from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import PeriodicExportingMetricReader from opentelemetry.sdk.resources import Resource from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.trace.export import BatchSpanProcessor def setup_telemetry( service_name: str, otlp_endpoint: str, ) -> tuple[trace.Tracer, metrics.Meter]: """Initialize unified observability for traces, metrics, and logs. GenAI telemetry (spans, metrics, events) is handled by custom instrumentation in llm.py following OTel GenAI semantic conventions. We intentionally do NOT use OpenInference/LlamaIndex auto-instrumentation. """ if os.environ.get("OTEL_SDK_DISABLED") == "true": return trace.get_tracer(service_name), metrics.get_meter(service_name) resource = Resource.create({ "service.name": service_name, "service.version": version("ai-content-quality"), "deployment.environment": os.getenv("SCOUT_ENVIRONMENT", "development"), "environment": os.getenv("SCOUT_ENVIRONMENT", "development"), }) trace_provider = TracerProvider(resource=resource) trace_provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint=f"{otlp_endpoint}/v1/traces") ) ) trace.set_tracer_provider(trace_provider) metric_reader = PeriodicExportingMetricReader( OTLPMetricExporter(endpoint=f"{otlp_endpoint}/v1/metrics"), export_interval_millis=10000, ) metric_provider = MeterProvider( resource=resource, metric_readers=[metric_reader] ) metrics.set_meter_provider(metric_provider) log_provider = LoggerProvider(resource=resource) log_provider.add_log_record_processor( BatchLogRecordProcessor( OTLPLogExporter(endpoint=f"{otlp_endpoint}/v1/logs") ) ) _logs.set_logger_provider(log_provider) logging.getLogger().addHandler( LoggingHandler(level=logging.INFO, logger_provider=log_provider) ) atexit.register(trace_provider.shutdown) atexit.register(metric_provider.shutdown) atexit.register(log_provider.shutdown) LoggingInstrumentor().instrument(set_logging_format=True) return trace.get_tracer(service_name), metrics.get_meter(service_name) def instrument_fastapi(app: Any) -> None: from opentelemetry.instrumentation.fastapi import FastAPIInstrumentor FastAPIInstrumentor.instrument_app( app, excluded_urls="health", exclude_spans=["receive", "send"] ) ``` ```mdx-code-block ``` ```python showLineNumbers title="src/content_quality/config.py" from functools import lru_cache from pydantic_settings import BaseSettings, SettingsConfigDict class Settings(BaseSettings): model_config = SettingsConfigDict( env_file=".env", env_file_encoding="utf-8", extra="ignore" ) service_name: str = "ai-content-quality" llm_provider: str = "openai" llm_model: str = "gpt-4.1-nano" llm_temperature: float = 0.3 llm_timeout: float = 30.0 openai_api_key: str = "" google_api_key: str = "" anthropic_api_key: str = "" request_timeout: float = 60.0 review_prompt_version: str = "v1" improve_prompt_version: str = "v1" score_prompt_version: str = "v1" otlp_endpoint: str = "http://otel-collector:4318" otel_sdk_disabled: bool = False scout_environment: str = "development" host: str = "0.0.0.0" port: int = 8000 @lru_cache def get_settings() -> Settings: return Settings() ``` ```mdx-code-block ``` For container deployments where configuration is managed externally: ```bash showLineNumbers title=".env" # Application SERVICE_NAME=ai-content-quality LLM_PROVIDER=openai LLM_MODEL=gpt-4.1-nano LLM_TEMPERATURE=0.3 LLM_TIMEOUT=30.0 REQUEST_TIMEOUT=60.0 HOST=0.0.0.0 PORT=8000 # LLM Provider Keys OPENAI_API_KEY=sk-... GOOGLE_API_KEY= ANTHROPIC_API_KEY= # Prompt Versions REVIEW_PROMPT_VERSION=v1 IMPROVE_PROMPT_VERSION=v1 SCORE_PROMPT_VERSION=v1 # OpenTelemetry OTLP_ENDPOINT=http://otel-collector:4318 OTEL_SDK_DISABLED=false SCOUT_ENVIRONMENT=production ``` The Pydantic `Settings` class reads all environment variables automatically (see the Pydantic Settings tab). No code changes needed - set the variables and the application picks them up. ```mdx-code-block ``` ### Production Configuration #### OpenTelemetry Collector ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 batch: timeout: 10s send_batch_size: 1024 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true debug: verbosity: basic service: extensions: [health_check, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] ``` #### Docker Compose ```yaml showLineNumbers title="compose.yml" services: app: build: . ports: - "8000:8000" environment: - OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_SDK_DISABLED=false - LLM_PROVIDER=${LLM_PROVIDER:-openai} - LLM_MODEL=${LLM_MODEL:-gpt-4.1-nano} - OPENAI_API_KEY=${OPENAI_API_KEY:-} - ANTHROPIC_API_KEY=${ANTHROPIC_API_KEY:-} - GOOGLE_API_KEY=${GOOGLE_API_KEY:-} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} depends_on: otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-f", "http://localhost:8000/health"] interval: 60s timeout: 5s retries: 3 otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" environment: - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-https://collector.base14.io} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} ``` #### Dockerfile ```dockerfile showLineNumbers title="Dockerfile" FROM python:3.14-slim WORKDIR /app RUN pip install --no-cache-dir uv && \ apt-get update && apt-get install -y --no-install-recommends curl && \ rm -rf /var/lib/apt/lists/* COPY pyproject.toml uv.lock README.md ./ RUN uv sync --no-dev COPY src/ src/ COPY prompts/ prompts/ ENV PYTHONPATH=/app/src EXPOSE 8000 CMD ["uv", "run", "uvicorn", "content_quality.main:app", \ "--host", "0.0.0.0", "--port", "8000"] ``` ### Multi-Provider LLM Support Create a provider-agnostic LLM factory that works with OpenAI, Anthropic, and Google: ```python showLineNumbers title="src/content_quality/services/llm.py" from llama_index.core.llms import LLM PROVIDER_SEMCONV_NAMES = { "openai": "openai", "google": "gcp.gemini", "anthropic": "anthropic", } PROVIDER_SERVERS = { "openai": "api.openai.com", "gcp.gemini": "generativelanguage.googleapis.com", "anthropic": "api.anthropic.com", } def create_llm( provider: str = "openai", model: str = "gpt-4.1-nano", temperature: float = 0.3, api_key: str = "", timeout: float = 30.0, ) -> LLM: global _provider _provider = PROVIDER_SEMCONV_NAMES.get(provider, provider) if provider == "openai": from llama_index.llms.openai import OpenAI return OpenAI(model=model, temperature=temperature, api_key=api_key, timeout=timeout) if provider == "google": from llama_index.llms.google_genai import GoogleGenAI return GoogleGenAI(model=model, temperature=temperature, api_key=api_key) if provider == "anthropic": from llama_index.llms.anthropic import Anthropic return Anthropic(model=model, temperature=temperature, api_key=api_key, timeout=timeout) raise ValueError(f"Unknown LLM provider: {provider!r}") ``` ### Structured Output with Self-Correction The `generate_structured` function is the core instrumented LLM call. It requests JSON output matching a Pydantic schema and retries with self-correction if validation fails: ````python showLineNumbers title="src/content_quality/services/llm.py" import json import re import time from llama_index.core import PromptTemplate from llama_index.core.llms import ChatMessage from opentelemetry import metrics, trace from opentelemetry.trace import StatusCode from pydantic import BaseModel, ValidationError from tenacity import ( retry, retry_if_exception_type, stop_after_attempt, wait_exponential, ) import httpx from content_quality.pii import scrub_pii MAX_PARSE_RETRIES = 2 _MARKDOWN_JSON_RE = re.compile( r"^```(?:json)?\s*\n?(.*?)\n?\s*```$", re.DOTALL ) def _strip_markdown_json(text: str) -> str: text = text.strip() m = _MARKDOWN_JSON_RE.match(text) return m.group(1).strip() if m else text @retry( stop=stop_after_attempt(3), wait=wait_exponential(multiplier=1, min=1, max=10), retry=retry_if_exception_type( (httpx.ConnectError, httpx.TimeoutException, httpx.HTTPStatusError) ), before_sleep=_on_retry, reraise=True, ) async def generate_structured( llm: LLM, prompt_template: PromptTemplate, output_cls: type[BaseModel], content: str, content_type: str = "general", endpoint: str = "", system_prompt: str = "", ) -> BaseModel: tracer = trace.get_tracer("gen_ai.client") model_name = llm.metadata.model_name server_address = PROVIDER_SERVERS.get(_provider, "") with tracer.start_as_current_span(f"chat {model_name}") as span: span.set_attribute("gen_ai.operation.name", "chat") span.set_attribute("gen_ai.request.model", model_name) span.set_attribute("gen_ai.provider.name", _provider) if server_address: span.set_attribute("server.address", server_address) span.set_attribute("gen_ai.output.type", "json") span.set_attribute("content.type", content_type) span.set_attribute("content.length", len(content)) start = time.perf_counter() try: formatted_prompt = prompt_template.format(content=content) schema_json = json.dumps( output_cls.model_json_schema(), indent=2 ) json_instruction = ( f"Respond ONLY with valid JSON matching this " f"schema:\n{schema_json}" ) full_system = ( f"{system_prompt}\n\n{json_instruction}" if system_prompt else json_instruction ) messages = [ ChatMessage(role="system", content=full_system), ChatMessage(role="user", content=formatted_prompt), ] chat_response = await llm.achat(messages) duration = time.perf_counter() - start # Record response attributes _set_response_attrs(chat_response, span, model_name) # Record token and cost metrics _record_token_metrics( chat_response, model_name, content_type, endpoint, span ) # Optional: record prompt/completion events with PII scrubbing if _is_content_capture_enabled(): _record_span_event( span, system_prompt, formatted_prompt, str(chat_response.message.content), ) # Parse with self-correction loop raw = _strip_markdown_json(str(chat_response.message.content)) for attempt in range(MAX_PARSE_RETRIES + 1): try: return output_cls.model_validate_json(raw) except ValidationError as ve: if attempt < MAX_PARSE_RETRIES: messages.append( ChatMessage(role="assistant", content=raw) ) messages.append(ChatMessage( role="user", content=( f"Your response did not match the schema. " f"Error: {ve}\n" "Please try again with valid JSON." ), )) correction = await llm.achat(messages) raw = _strip_markdown_json( str(correction.message.content) ) continue raise except Exception as e: span.record_exception(e) span.set_status(StatusCode.ERROR, str(e)) span.set_attribute("error.type", type(e).__name__) error_counter.add(1, { "gen_ai.request.model": model_name, "gen_ai.provider.name": _provider, "error.type": type(e).__name__, }) raise ```` ### Custom GenAI Metrics Define five metrics following OpenTelemetry GenAI semantic conventions: ```python showLineNumbers title="src/content_quality/services/llm.py" from opentelemetry import metrics meter = metrics.get_meter("gen_ai.client") token_usage = meter.create_histogram( name="gen_ai.client.token.usage", description="Number of tokens used", unit="{token}", ) operation_duration = meter.create_histogram( name="gen_ai.client.operation.duration", description="GenAI operation duration", unit="s", ) cost_counter = meter.create_counter( name="gen_ai.client.cost", description="Cost of GenAI operations", unit="usd", ) error_counter = meter.create_counter( name="gen_ai.client.error.count", description="GenAI operation errors", unit="1", ) retry_counter = meter.create_counter( name="gen_ai.client.retry.count", description="GenAI operation retries", unit="1", ) ``` ### Cost Calculation with Pricing Table ```python showLineNumbers title="src/content_quality/services/llm.py" PRICING: dict[str, dict[str, float]] = { # OpenAI (per million tokens) "gpt-5.2": {"input": 1.75, "output": 14.0}, "gpt-4.1-mini": {"input": 0.40, "output": 1.60}, "gpt-4.1-nano": {"input": 0.10, "output": 0.40}, # Google Gemini "gemini-3.0-flash-preview": {"input": 0.50, "output": 3.0}, "gemini-2.5-flash": {"input": 0.30, "output": 2.50}, # Anthropic "claude-opus-4-6": {"input": 5.0, "output": 25.0}, "claude-sonnet-4-5-20250929": {"input": 3.0, "output": 15.0}, "claude-haiku-4-5-20251001": {"input": 1.0, "output": 5.0}, } def _calculate_cost( model: str, input_tokens: int, output_tokens: int ) -> float: pricing = PRICING.get(model, {"input": 0.0, "output": 0.0}) return ( input_tokens * pricing["input"] + output_tokens * pricing["output"] ) / 1_000_000 ``` ### Evaluation and Quality Metrics Track content quality scores as OpenTelemetry metrics and span events: ```python showLineNumbers title="src/content_quality/services/analyzer.py" from opentelemetry import metrics, trace from content_quality.services.llm import generate_structured from content_quality.services.prompts import load_prompt evaluation_score = metrics.get_meter("gen_ai.client").create_histogram( name="gen_ai.evaluation.score", description="Content quality evaluation score", unit="1", ) class ContentAnalyzer: def __init__(self, llm): self.llm = llm settings = get_settings() self._review_prompt = load_prompt( f"review_{settings.review_prompt_version}" ) self._score_prompt = load_prompt( f"score_{settings.score_prompt_version}" ) async def review(self, content, content_type="general"): result = await generate_structured( self.llm, PromptTemplate(self._review_prompt.user), ReviewResult, content, content_type=content_type, endpoint="/review", system_prompt=self._review_prompt.system, ) span = trace.get_current_span() issue_score = max( 0, 100 - sum( {"high": 3, "medium": 2, "low": 1}.get(i.severity, 1) * 10 for i in result.issues ), ) span.add_event( "gen_ai.evaluation.result", { "gen_ai.evaluation.name": "content_review", "gen_ai.evaluation.score.value": issue_score, "gen_ai.evaluation.score.label": ( "passed" if issue_score >= 60 else "failed" ), "gen_ai.evaluation.explanation": result.summary, }, ) evaluation_score.record(issue_score, { "gen_ai.evaluation.name": "content_review", "content.type": content_type, }) return result async def score(self, content, content_type="general"): result = await generate_structured( self.llm, PromptTemplate(self._score_prompt.user), ScoreResult, content, content_type=content_type, endpoint="/score", system_prompt=self._score_prompt.system, ) span = trace.get_current_span() span.add_event( "gen_ai.evaluation.result", { "gen_ai.evaluation.name": "content_quality", "gen_ai.evaluation.score.value": result.score, "gen_ai.evaluation.score.label": ( "passed" if result.score >= 60 else "failed" ), "gen_ai.evaluation.explanation": result.summary, }, ) evaluation_score.record(result.score, { "gen_ai.evaluation.name": "content_quality", "content.type": content_type, }) return result ``` ### YAML Prompt Management Manage prompts as versioned YAML files for easy iteration: ```python showLineNumbers title="src/content_quality/services/prompts.py" from dataclasses import dataclass from functools import lru_cache from pathlib import Path import yaml PROMPTS_DIR = Path(__file__).resolve().parents[3] / "prompts" @dataclass(frozen=True) class PromptPair: system: str user: str @lru_cache def load_prompt(name: str) -> PromptPair: path = PROMPTS_DIR / f"{name}.yaml" with path.open() as f: messages = yaml.safe_load(f) system = "" user = "" for msg in messages: text = msg["content"].replace("{{", "{").replace("}}", "}") if msg["role"] == "system": system = text elif msg["role"] == "user": user = text return PromptPair(system=system, user=user) ``` ### PII Scrubbing Scrub PII from all content before recording in span events: ```python showLineNumbers title="src/content_quality/pii.py" import re _PII_PATTERNS = [ (re.compile(r"\b[\w.+-]+@[\w-]+\.[\w.-]+\b"), "[EMAIL]"), (re.compile(r"\b\d{3}[-.]?\d{3}[-.]?\d{4}\b"), "[PHONE]"), (re.compile(r"\b\d{3}-\d{2}-\d{4}\b"), "[SSN]"), (re.compile(r"\b\d{4}[\s-]?\d{4}[\s-]?\d{4}[\s-]?\d{4}\b"), "[CARD]"), (re.compile( r"https?://(?:www\.)?linkedin\.com/in/[\w-]+" ), "[LINKEDIN]"), ] def scrub_pii(text: str) -> str: for pattern, replacement in _PII_PATTERNS: text = pattern.sub(replacement, text) return text ``` #### Content Capture Toggle Content capture is opt-in via environment variable. When enabled, prompts and completions are scrubbed and truncated before recording: ```python showLineNumbers title="src/content_quality/services/llm.py" def _is_content_capture_enabled() -> bool: return ( os.environ.get( "OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT", "" ).lower() == "true" ) def _record_span_event(span, system_prompt, user_prompt, assistant_content): attrs = {} if system_prompt: attrs["gen_ai.system_instructions"] = json.dumps( [{"type": "text", "content": scrub_pii(system_prompt)[:500]}] ) attrs["gen_ai.input.messages"] = json.dumps( [{"role": "user", "parts": [ {"type": "text", "content": scrub_pii(user_prompt)[:500]} ]}] ) attrs["gen_ai.output.messages"] = json.dumps( [{"role": "assistant", "parts": [ {"type": "text", "content": scrub_pii(assistant_content)[:500]} ]}] ) span.add_event("gen_ai.client.inference.operation.details", attrs) ``` ### Eval-Driven Development with Promptfoo Use Promptfoo to systematically test prompt quality and prevent regressions: ```yaml showLineNumbers title="promptfooconfig.yaml" providers: - id: python:evals/provider.py:review_provider label: "Review Endpoint" - id: python:evals/provider.py:improve_provider label: "Improve Endpoint" - id: python:evals/provider.py:score_provider label: "Score Endpoint" tests: - vars: content: "Our REVOLUTIONARY product is the BEST in the market!" content_type: marketing assert: - type: is-json - type: javascript value: "file://evals/assertions/review.js" - vars: content: "PostgreSQL uses MVCC for concurrent transaction isolation." content_type: technical assert: - type: is-json - type: javascript value: "file://evals/assertions/score.js" ``` Run evaluations: ```bash showLineNumbers title="Terminal" npx promptfoo eval npx promptfoo view ``` ### FastAPI Application ```python showLineNumbers title="src/content_quality/main.py" import asyncio from collections.abc import AsyncGenerator from contextlib import asynccontextmanager from fastapi import FastAPI, HTTPException from opentelemetry import trace from opentelemetry.trace import StatusCode from content_quality.config import get_settings from content_quality.middleware import MetricsMiddleware from content_quality.models.requests import ContentRequest from content_quality.services.analyzer import ContentAnalyzer from content_quality.services.llm import create_llm from content_quality.telemetry import instrument_fastapi, setup_telemetry settings = get_settings() setup_telemetry( service_name=settings.service_name, otlp_endpoint=settings.otlp_endpoint, ) @asynccontextmanager async def lifespan(app: FastAPI) -> AsyncGenerator[None]: app.state.llm = create_llm( provider=settings.llm_provider, model=settings.llm_model, temperature=settings.llm_temperature, api_key={ "openai": settings.openai_api_key, "google": settings.google_api_key, "anthropic": settings.anthropic_api_key, }.get(settings.llm_provider, ""), timeout=settings.llm_timeout, ) app.state.analyzer = ContentAnalyzer(app.state.llm) yield app = FastAPI(title="AI Content Quality Agent", lifespan=lifespan) app.add_middleware(MetricsMiddleware) instrument_fastapi(app) @app.get("/health") async def health(): return {"status": "healthy", "service": settings.service_name} @app.post("/review") async def review_content(request: ContentRequest): try: return await asyncio.wait_for( app.state.analyzer.review(request.content, request.content_type), timeout=settings.request_timeout, ) except TimeoutError: raise HTTPException(status_code=504, detail="Analysis timed out") except Exception: raise HTTPException(status_code=502, detail="Analysis failed") @app.post("/improve") async def improve_content(request: ContentRequest): try: return await asyncio.wait_for( app.state.analyzer.improve(request.content, request.content_type), timeout=settings.request_timeout, ) except TimeoutError: raise HTTPException(status_code=504, detail="Analysis timed out") except Exception: raise HTTPException(status_code=502, detail="Analysis failed") @app.post("/score") async def score_content(request: ContentRequest): try: return await asyncio.wait_for( app.state.analyzer.score(request.content, request.content_type), timeout=settings.request_timeout, ) except TimeoutError: raise HTTPException(status_code=504, detail="Analysis timed out") except Exception: raise HTTPException(status_code=502, detail="Analysis failed") ``` ### Running Your Application ```mdx-code-block ``` ```bash showLineNumbers uv run uvicorn content_quality.main:app --reload --host 0.0.0.0 --port 8000 ``` ```mdx-code-block ``` ```bash showLineNumbers OTEL_SDK_DISABLED=false \ LLM_PROVIDER=anthropic \ LLM_MODEL=claude-sonnet-4-5-20250929 \ OTLP_ENDPOINT=http://collector:4318 \ uv run uvicorn content_quality.main:app --host 0.0.0.0 --port 8000 ``` ```mdx-code-block ``` ```bash showLineNumbers docker compose up --build curl http://localhost:8000/health docker compose down ``` ```mdx-code-block ``` ### Troubleshooting #### Verify Telemetry Is Working ```bash showLineNumbers curl http://localhost:13133 # Open http://localhost:55679/debug/tracez for zpages ``` #### Enable Debug Mode ```python showLineNumbers import logging logging.getLogger("opentelemetry").setLevel(logging.DEBUG) ``` #### Common Issues ##### Issue: Token counts are zero **Solutions:** 1. Check your LLM SDK version - older versions may not expose `usage` 2. Verify the provider response has `input_tokens` and `output_tokens` 3. For Google GenAI, check `response.usage_metadata` instead of `response.usage` ##### Issue: Cost metrics not accurate **Solutions:** 1. Verify your `PRICING` dictionary contains the exact model ID string returned by the provider (e.g., `gpt-4.1-nano`, not `gpt-4.1`) 2. Check that cost is calculated with `/1_000_000` (pricing is per million tokens) ##### Issue: Structured output validation fails repeatedly **Solutions:** 1. Verify your Pydantic model has proper `Field` descriptions 2. Check that `MAX_PARSE_RETRIES` is set to at least 2 3. Try adding `response_mime_type: "application/json"` for Google models ##### Issue: Spans not exported to Scout **Solutions:** 1. Confirm collector: `curl http://localhost:13133` 2. Check collector logs: `docker compose logs otel-collector` 3. Verify `OTLP_ENDPOINT` points to the collector, not directly to Scout ### Security Considerations #### Protecting Sensitive Data - **Never record raw prompts** that may contain user data, API keys, or credentials in span attributes or events - **Truncate content** to 500 characters to avoid oversized spans - **Disable content capture** in production if compliance requires it - set `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=false` - **Scrub PII** before recording any content in telemetry (see [PII Scrubbing](#pii-scrubbing) for the regex patterns used) #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Use opt-in content capture - disabled by default in this guide - Record only token counts and model metadata, not prompt content - Audit span attributes regularly for sensitive data leaks - Use the OTel Collector `attributes` processor to redact fields before export if additional filtering is needed ### Performance Considerations OpenTelemetry overhead is negligible relative to LLM API latency. A typical LLM call takes 1-5 seconds; span creation adds microseconds. #### Optimization Strategies ##### 1. Use BatchSpanProcessor ```python showLineNumbers trace_provider.add_span_processor( BatchSpanProcessor( OTLPSpanExporter(endpoint=endpoint), max_queue_size=2048, max_export_batch_size=512, ) ) ``` ##### 2. Truncate Content Events Always truncate prompts and completions to keep span sizes reasonable: ```python showLineNumbers scrub_pii(prompt)[:500] # 500 chars max ``` ##### 3. Disable Content Capture in High-Volume Scenarios ```bash showLineNumbers OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=false ``` ### FAQ #### Why use custom instrumentation instead of OpenInference? OpenInference produces non-standard attributes (`llm.*`, `input.*`, `output.*`) that are specific to LlamaIndex and don't follow the OpenTelemetry GenAI semantic conventions. Custom instrumentation gives you standard attributes (`gen_ai.*`) that work with any OTel-compatible backend. #### Does OpenTelemetry add latency to LLM calls? No. Span creation takes microseconds. LLM API calls take seconds. The overhead is unmeasurable. `BatchSpanProcessor` exports in a background thread. #### How do I track cost across multiple LLM providers? Use the `gen_ai.client.cost` counter metric with `gen_ai.provider.name` and `gen_ai.request.model` attributes. Define pricing per model and calculate from token counts. #### How does structured output retry work in LlamaIndex with OpenTelemetry? When the LLM returns invalid JSON, the system appends the validation error to the conversation and asks the LLM to retry. This happens up to `MAX_PARSE_RETRIES` times (default 2) before raising an error. #### Can I see prompts and completions in traces? Yes, if `OTEL_INSTRUMENTATION_GENAI_CAPTURE_MESSAGE_CONTENT=true`. Content is PII-scrubbed and truncated to 500 characters. Disable in production for compliance. #### How do I add a custom LLM provider to a LlamaIndex application? Add the provider to `create_llm()`, add its server address to `PROVIDER_SERVERS`, and add its model pricing to the `PRICING` dictionary. #### How do I version and manage prompts in a LlamaIndex project? Prompts are stored as YAML files in the `prompts/` directory with version suffixes (e.g., `review_v1.yaml`, `review_v2.yaml`). The active version is configured via `REVIEW_PROMPT_VERSION` environment variable. #### How do I evaluate LLM prompts with Promptfoo and LlamaIndex? Install Promptfoo (`npm install -g promptfoo`), then run `npx promptfoo eval` from the project root. Results can be viewed with `npx promptfoo view`. #### How do I remove PII from OpenTelemetry traces in Python? Regex patterns detect and replace emails, phone numbers, SSNs, credit card numbers, and LinkedIn URLs with safe placeholders before any content is recorded in span events. #### Can I use this with RAG systems? Yes. The patterns here (GenAI spans, token tracking, cost metrics) apply to any LlamaIndex application. For RAG, add spans around your retrieval step with attributes like `retrieval.document_count` and `retrieval.strategy`. ### What's Next? #### Related Guides - [FastAPI Instrumentation](./fast-api.md) - Common API host for RAG services - [Python Custom Instrumentation](../custom-instrumentation/python.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Alert on cost spikes, error rates, or quality degradation - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build dashboards for token usage, cost attribution, and evaluation scores #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development with the OTel Collector ### Complete Example #### Project Structure ```text showLineNumbers ai-content-quality/ ├── src/content_quality/ │ ├── main.py # FastAPI app with lifespan │ ├── config.py # Pydantic Settings │ ├── telemetry.py # OTel initialization │ ├── pii.py # PII scrubbing │ ├── models/ │ │ ├── requests.py # ContentRequest schema │ │ └── responses.py # ReviewResult, ImproveResult, ScoreResult │ ├── services/ │ │ ├── llm.py # GenAI spans, metrics, structured output │ │ ├── analyzer.py # Content analysis with evaluation metrics │ │ └── prompts.py # YAML prompt loader │ └── middleware/ │ └── metrics.py # HTTP metrics middleware ├── prompts/ │ ├── review_v1.yaml # Review prompt v1 │ ├── review_v2.yaml # Review prompt v2 │ ├── improve_v1.yaml # Improve prompt │ └── score_v1.yaml # Score prompt ├── evals/ │ ├── assertions/ # Promptfoo assertion scripts │ └── datasets/ # Test case datasets ├── promptfooconfig.yaml # Promptfoo eval configuration ├── otel-collector-config.yaml ├── compose.yml ├── Dockerfile └── pyproject.toml ``` #### Key Files | File | Demonstrates | | -------------- | -------------------------------------------------- | | `telemetry.py` | OTel setup (traces + metrics + logs) | | `llm.py` | GenAI spans, token/cost metrics, structured output | | `analyzer.py` | Evaluation events and quality metrics | | `prompts.py` | YAML prompt management with versioning | | `pii.py` | PII scrubbing before telemetry recording | | `config.py` | Multi-provider settings with Pydantic | | `compose.yml` | Docker deployment with OTel Collector | #### GitHub Repository For a complete working example, see the [AI Content Quality Agent](https://github.com/base-14/examples/tree/main/python/ai-content-quality) repository. ### References - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [OpenTelemetry Python SDK](https://opentelemetry.io/docs/languages/python/) - [LlamaIndex Documentation](https://docs.llamaindex.ai/) - [Promptfoo Documentation](https://promptfoo.dev/docs/) --- ## Micronaut OpenTelemetry Instrumentation - Java Agent, Hibernate & Netty Tracing ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Implement OpenTelemetry instrumentation for Micronaut applications using the OpenTelemetry Java Agent for zero-code distributed tracing, Hibernate JPA query monitoring, and structured log correlation. The Java Agent attaches to the JVM at startup and automatically instruments HTTP requests, JDBC queries, Netty server operations, and outgoing HTTP client calls without any code changes. Micronaut is a compile-time dependency-injection JVM framework. For the dominant ecosystem alternative see [Spring Boot](./spring-boot.md), and for a Kotlin-first option see [Ktor](./ktor.md). Micronaut applications benefit from the Java Agent's comprehensive coverage of the JVM ecosystem including Hibernate, HikariCP connection pools, Java HTTP clients, and Netty. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and correlate logs with traces using a single `-javaagent` flag. Whether you're implementing observability for the first time, migrating from commercial APM solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations for Micronaut OpenTelemetry instrumentation. > **Note:** This guide provides a practical Micronaut-focused overview based > on the official OpenTelemetry documentation. For complete Java agent > information, please consult the > [official OpenTelemetry Java documentation](https://opentelemetry.io/docs/languages/java/). :::tip TL;DR Download the OpenTelemetry Java Agent JAR, set `JAVA_TOOL_OPTIONS="-javaagent:/path/to/opentelemetry-javaagent.jar"`, and configure `OTEL_SERVICE_NAME` + `OTEL_EXPORTER_OTLP_ENDPOINT`. HTTP requests, Hibernate queries, Netty I/O, and HTTP client calls are traced automatically with zero code changes. The agent injects `trace_id` and `span_id` into SLF4J MDC for log correlation. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Micronaut developers**: implementing observability and distributed tracing for the first time - **Cloud-native teams**: running Micronaut microservices in Kubernetes or Docker - **DevOps engineers**: deploying JVM applications with production monitoring requirements - **Engineering teams**: migrating from Datadog, New Relic, or other commercial APM solutions - **Platform teams**: standardizing observability across JVM services (Micronaut, Spring Boot, Quarkus) ### Overview This guide demonstrates how to: - Attach the OpenTelemetry Java Agent to Micronaut applications for zero-code instrumentation - Configure trace export to Scout Collector via environment variables - Set up structured JSON logging with automatic trace context correlation - Wire custom metrics and spans using the OpenTelemetry API - Deploy instrumented applications with Docker Compose (app + notify + PostgreSQL + collector) - Trace requests across multiple Micronaut services (distributed tracing) - Troubleshoot common instrumentation issues ### Prerequisites Before starting, ensure you have: - **Java 17 or later** (Java 21+ recommended for best performance) - Eclipse Temurin or any OpenJDK distribution - **Micronaut 3.x or 4.x** installed - Micronaut 4.x is recommended for optimal compatibility - **Gradle 8.x or Maven 3.9+** for build management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ---------------------- | --------------- | ------------------- | | Java | 17 | 21+ | | Micronaut | 3.0.0 | 4.8.0+ | | Gradle | 8.0 | 8.10+ | | OpenTelemetry Java Agent | 1.0.0 | 2.26+ | | Hibernate ORM | 5.6.0 | 6.6.0+ | | PostgreSQL Driver | 42.5.0 | Latest stable | #### Instrumented Components (Automatic) The Java Agent instruments these components with zero code changes: | Component | Coverage | | --------------------- | ------------------------------------------------- | | Micronaut HTTP Server | Routes, controllers, request/response attributes | | Netty | Server I/O, connection handling | | Hibernate / JDBC | All SQL queries, transactions, connection pools | | Java HTTP Client | Outgoing HTTP calls, W3C trace propagation | | HikariCP | Connection pool metrics | | Logback | MDC injection of trace_id and span_id | | Flyway | Database migration spans | #### Example Application This guide references the [micronaut-postgres](https://github.com/base-14/examples/tree/main/java/micronaut-postgres) example: a Micronaut 4.8 REST API with Hibernate JPA, a notification microservice, and full OpenTelemetry instrumentation. ### Installation #### Step 1: Download the OpenTelemetry Java Agent Download the latest agent JAR from the official releases: ```bash # Download the agent (v2.26.1) curl -L -o opentelemetry-javaagent.jar \ https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.26.1/opentelemetry-javaagent.jar ``` #### Step 2: Attach the Agent to the JVM The agent attaches via the `-javaagent` JVM flag. The simplest approach is the `JAVA_TOOL_OPTIONS` environment variable: ```bash export JAVA_TOOL_OPTIONS="-javaagent:/path/to/opentelemetry-javaagent.jar" ``` This works regardless of how you start your application (Gradle, Maven, java -jar, etc.). #### Step 3: Add the OpenTelemetry API Dependency (Optional) For custom metrics and manual spans, add the OpenTelemetry API to your build. This is optional if you only need automatic instrumentation: ```kotlin title="build.gradle.kts" showLineNumbers dependencies { // Required: Micronaut core implementation("io.micronaut:micronaut-http-client") implementation("io.micronaut.serde:micronaut-serde-jackson") implementation("io.micronaut.data:micronaut-data-hibernate-jpa") implementation("io.micronaut.sql:micronaut-jdbc-hikari") implementation("io.micronaut.flyway:micronaut-flyway") // Optional: OTel API for custom metrics and spans implementation("io.opentelemetry:opentelemetry-api:1.48.0") // Runtime runtimeOnly("org.postgresql:postgresql") runtimeOnly("ch.qos.logback:logback-classic") runtimeOnly("net.logstash.logback:logstash-logback-encoder:8.0") } ``` The `opentelemetry-api` dependency is a compile-time-only API. The Java Agent provides the implementation at runtime, so there is no version conflict. ### Configuration ```mdx-code-block ``` Configure the agent entirely through environment variables: ```bash title=".env" # OpenTelemetry Java Agent OTEL_SERVICE_NAME=micronaut-app OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development ``` The agent reads these variables at startup and configures itself. No application code or config files need to change. ```mdx-code-block ``` Micronaut-specific configuration for the application itself (database, HTTP client, Flyway): ```yaml title="src/main/resources/application.yml" showLineNumbers micronaut: application: name: micronaut-articles server: port: 8080 datasources: default: url: jdbc:postgresql://${DB_HOST:localhost}:${DB_PORT:5432}/${DB_NAME:micronaut} username: ${DB_USER:postgres} password: ${DB_PASSWORD:postgres} driver-class-name: org.postgresql.Driver jpa: default: entity-scan: packages: - com.example.model properties: hibernate: dialect: org.hibernate.dialect.PostgreSQLDialect hbm2ddl: auto: validate flyway: datasources: default: enabled: true locations: classpath:db/migration notify: url: ${NOTIFY_URL:`http://localhost:8081`} ``` The Java Agent instruments Hibernate and JDBC automatically regardless of how you configure the datasource. ```mdx-code-block ``` Run the full observability stack locally with Docker Compose: ```yaml title="compose.yml" showLineNumbers x-otel-env: &otel-env OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_METRIC_EXPORT_INTERVAL: "10000" OTEL_RESOURCE_ATTRIBUTES: deployment.environment=development,environment=development services: otel-collector: image: otel/opentelemetry-collector-contrib:0.148.0 container_name: micronaut-otel-collector command: ["--config=/etc/otelcol-contrib/config.yaml"] ports: - "4317:4317" - "4318:4318" volumes: - ./config/otel-config.yaml:/etc/otelcol-contrib/config.yaml environment: - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-http://localhost:4318} - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-} restart: unless-stopped db: image: postgres:18-alpine container_name: micronaut-postgres environment: POSTGRES_DB: micronaut POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres ports: - "5432:5432" volumes: - pgdata:/var/lib/postgresql/data healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 restart: unless-stopped app: build: context: ./app dockerfile: Dockerfile container_name: micronaut-app ports: - "${APP_PORT:-8080}:8080" environment: <<: *otel-env OTEL_SERVICE_NAME: micronaut-articles DB_HOST: db DB_PORT: "5432" DB_NAME: micronaut DB_USER: postgres DB_PASSWORD: postgres NOTIFY_URL: http://notify:8081 depends_on: db: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-f", "http://localhost:8080/api/health"] interval: 10s timeout: 5s start_period: 30s retries: 5 restart: unless-stopped volumes: pgdata: ``` The YAML anchor `&otel-env` shares OpenTelemetry environment variables across services. ```mdx-code-block ``` #### Configure Structured Logging Set up Logback with JSON output. The Java Agent automatically injects `trace_id` and `span_id` into the SLF4J MDC, so all you need is a JSON encoder that includes MDC fields: ```xml title="src/main/resources/logback.xml" showLineNumbers trace_id span_id ``` Every log line now includes `trace_id` and `span_id` in the JSON output, enabling you to jump from a log entry in Scout directly to the corresponding trace. #### Scout Collector Integration Configure trace export to Scout with OAuth2 authentication: ```bash title=".env" # Scout Collector Configuration SCOUT_ENDPOINT=https://your-tenant.base14.io/v1/traces SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token # Service Configuration OTEL_SERVICE_NAME=micronaut-app OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 ``` > **Scout Dashboard Integration**: After configuration, your traces will > appear in the Scout Dashboard. Navigate to the Traces section to view > request flows, identify bottlenecks, and analyze distributed transactions. ### Production Configuration Production deployments require tuning for performance, reliability, and resource utilization. #### Production Environment Variables ```bash title=".env.production" # OpenTelemetry Java Agent OTEL_SERVICE_NAME=micronaut-app OTEL_SERVICE_VERSION=2.1.3 # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com/v1/traces SCOUT_CLIENT_ID=prod_client_id SCOUT_CLIENT_SECRET=prod_secret_key SCOUT_TOKEN_URL=https://scout-collector.example.com/oauth/token # Exporter Settings OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_COMPRESSION=gzip OTEL_EXPORTER_OTLP_TIMEOUT=10000 # Batch Span Processor (Production Optimized) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 # Metric Export Interval OTEL_METRIC_EXPORT_INTERVAL=30000 # Resource Attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,host.name=${HOSTNAME} ``` #### Docker Production Configuration Multi-stage Dockerfile that builds a shadow JAR and bakes in the OpenTelemetry Java Agent: ```dockerfile title="Dockerfile" showLineNumbers FROM eclipse-temurin:25-jdk AS builder WORKDIR /app COPY gradle/ gradle/ COPY gradlew settings.gradle.kts build.gradle.kts ./ RUN chmod +x gradlew && ./gradlew dependencies --no-daemon COPY src/ src/ RUN ./gradlew shadowJar --no-daemon FROM eclipse-temurin:25-jre WORKDIR /app RUN apt-get update -qq && \ apt-get install -y --no-install-recommends curl && \ rm -rf /var/lib/apt/lists/* ARG OTEL_AGENT_VERSION=2.26.1 ADD https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v${OTEL_AGENT_VERSION}/opentelemetry-javaagent.jar /app/opentelemetry-javaagent.jar RUN addgroup --gid 1001 appgroup && \ adduser --uid 1001 --gid 1001 --disabled-password --gecos "" appuser && \ chown appuser:appgroup /app/opentelemetry-javaagent.jar COPY --from=builder --chown=appuser:appgroup /app/build/libs/*-all.jar /app/app.jar USER appuser EXPOSE 8080 ENV JAVA_TOOL_OPTIONS="-javaagent:/app/opentelemetry-javaagent.jar" ENTRYPOINT ["java", "-jar", "/app/app.jar"] ``` Key details: - **Multi-stage build** separates Gradle build from runtime image - **OTel Java Agent** downloaded and baked into the image via `ADD` - **`JAVA_TOOL_OPTIONS`** attaches the agent automatically on every JVM start - **Non-root user** (`appuser:1001`) for security - **Shadow JAR** bundles all dependencies into a single executable JAR #### Multi-Service Distributed Tracing For architectures with multiple services, each gets its own `OTEL_SERVICE_NAME`. The Java Agent automatically propagates W3C `traceparent` headers on outgoing HTTP requests. Here's the notification client from the example app: ```java title="src/main/java/com/example/service/NotificationClient.java" showLineNumbers package com.example.service; import com.fasterxml.jackson.databind.ObjectMapper; import io.micronaut.context.annotation.Value; import jakarta.inject.Singleton; import org.slf4j.Logger; import org.slf4j.LoggerFactory; import java.net.URI; import java.net.http.HttpClient; import java.net.http.HttpRequest; import java.net.http.HttpResponse; import java.util.Map; @Singleton public class NotificationClient { private static final Logger LOG = LoggerFactory.getLogger(NotificationClient.class); private final HttpClient httpClient = HttpClient.newHttpClient(); private final ObjectMapper objectMapper = new ObjectMapper(); private final String notifyUrl; public NotificationClient( @Value("${notify.url:`http://localhost:8081`}") String notifyUrl) { this.notifyUrl = notifyUrl; } public void notify(Map payload) { try { String json = objectMapper.writeValueAsString(payload); HttpRequest request = HttpRequest.newBuilder() .uri(URI.create(notifyUrl + "/notify")) .header("Content-Type", "application/json") .POST(HttpRequest.BodyPublishers.ofString(json)) .build(); HttpResponse response = httpClient.send( request, HttpResponse.BodyHandlers.ofString()); LOG.debug("Notify response: {}", response.statusCode()); } catch (Exception e) { LOG.warn("Failed to notify: {}", e.getMessage()); } } } ``` The Java Agent instruments `java.net.http.HttpClient` automatically, injecting the `traceparent` header into the outgoing request. No code changes needed. Add the notification service to Docker Compose: ```yaml title="compose.yml (excerpt)" services: app: environment: OTEL_SERVICE_NAME: micronaut-articles NOTIFY_URL: http://notify:8081 notify: build: context: ./notify environment: <<: *otel-env OTEL_SERVICE_NAME: micronaut-notify ports: - "8081:8081" ``` In Scout Dashboard, you'll see the full distributed trace: ```plaintext micronaut-articles: POST /api/articles +-- INSERT INTO articles ... +-- POST http://notify:8081/notify +-- micronaut-notify: POST /notify (linked trace) ``` ### Micronaut-Specific Features #### Automatic HTTP Request Tracing The Java Agent instruments Micronaut's Netty-based HTTP server automatically. Every request creates a root span with: - `http.method` - Request method (GET, POST, etc.) - `http.route` - Matched route pattern (e.g., `/api/articles/{id}`) - `http.status_code` - Response status code - `url.path` - Request URI path Micronaut controller annotations map directly to span names: ```java @Controller("/api/articles") @ExecuteOn(TaskExecutors.BLOCKING) public class ArticleController { @Get public HttpResponse list() { // Auto-instrumented: creates span "GET /api/articles" } @Get("/{id}") public HttpResponse get(@PathVariable Long id) { // Auto-instrumented: creates span "GET /api/articles/{id}" // Uses route pattern, not the actual ID (low cardinality) } @Post public HttpResponse create(@Body CreateArticleRequest request) { // Auto-instrumented: creates span "POST /api/articles" } } ``` #### Hibernate JPA Query Tracing All Hibernate queries are traced automatically via JDBC instrumentation. Each query creates a span with: - `db.system` - Database type (`postgresql`) - `db.name` - Database name - `db.statement` - SQL query (parameters obfuscated) - `db.operation` - Operation type (`SELECT`, `INSERT`, `UPDATE`, `DELETE`) ```java // These are all automatically traced: // Micronaut Data repository query Page
result = articleRepository.findAll(Pageable.from(0, 10)); // Direct entity operations Article article = articleRepository.save(newArticle); articleRepository.deleteById(id); ``` In Scout Dashboard, you'll see spans like: ```plaintext SELECT a1_0.id, ... FROM articles a1_0 (db.system=postgresql, db.operation=SELECT) INSERT INTO articles ... (db.system=postgresql, db.operation=INSERT) ``` #### Flyway Migration Tracing Database migrations executed by Flyway during application startup are automatically traced. Each migration file creates a span, giving you visibility into startup time. #### Logback Trace-Log Correlation The Java Agent automatically injects `trace_id` and `span_id` into the SLF4J MDC (Mapped Diagnostic Context). Combined with the `logstash-logback-encoder`, every JSON log line includes trace context: ```json { "message": "Article created: id=42, title=Hello", "logger_name": "com.example.controller.ArticleController", "level": "INFO", "trace_id": "a1b2c3d4e5f6a1b2c3d4e5f6a1b2c3d4", "span_id": "1a2b3c4d5e6f7a8b" } ``` This is fully automatic - no custom processors or MDC manipulation needed. The agent handles MDC injection, and `logstash-logback-encoder` handles JSON formatting. #### Micronaut Dependency Injection Micronaut's compile-time dependency injection works seamlessly with the OpenTelemetry API. Use `@Singleton` and `@Value` for service wiring: ```java @Singleton public class NotificationClient { public NotificationClient( @Value("${notify.url}") String notifyUrl) { // Micronaut injects the value at compile time // The Java Agent instruments HTTP calls at runtime } } ``` No special OpenTelemetry configuration in `services.yaml` or `application.yml` is needed. The agent provides everything at the JVM level. ### Custom Instrumentation While the Java Agent covers HTTP, JDBC, and Netty automatically, you can add custom metrics and spans for business logic. #### Custom Business Metrics Create a telemetry service to register and increment custom counters: ```java title="src/main/java/com/example/service/TelemetryService.java" showLineNumbers package com.example.service; import io.opentelemetry.api.GlobalOpenTelemetry; import io.opentelemetry.api.metrics.LongCounter; import io.opentelemetry.api.metrics.Meter; import jakarta.annotation.PostConstruct; import jakarta.inject.Singleton; @Singleton public class TelemetryService { private LongCounter articlesCreated; @PostConstruct void init() { Meter meter = GlobalOpenTelemetry.getMeter("micronaut-articles"); articlesCreated = meter.counterBuilder("articles.created") .setDescription("Total number of articles created") .build(); } public void incrementArticlesCreated() { articlesCreated.add(1); } } ``` Use it in your controller: ```java title="src/main/java/com/example/controller/ArticleController.java (excerpt)" @Post public HttpResponse create(@Body CreateArticleRequest request) { Article article = new Article(); article.setTitle(request.title()); article.setBody(request.body()); article = articleRepository.save(article); LOG.info("Article created: id={}, title={}", article.getId(), article.getTitle()); telemetryService.incrementArticlesCreated(); try { notificationClient.notify(Map.of( "id", article.getId(), "title", article.getTitle(), "event", "article.created" )); } catch (Exception e) { LOG.warn("Failed to notify: {}", e.getMessage()); } return HttpResponse.status(HttpStatus.CREATED).body(Map.of( "data", article, "meta", Map.of("trace_id", currentTraceId()) )); } ``` #### Including Trace ID in API Responses Include the trace ID in API responses so clients can correlate their requests with backend traces: ```java private String currentTraceId() { return Span.current().getSpanContext().getTraceId(); } ``` Every response includes `"trace_id"` in the `meta` field, making it easy to look up the corresponding trace in Scout Dashboard. #### Manual Span Creation Create custom spans for business-critical operations not covered by automatic instrumentation: ```java title="src/main/java/com/example/service/ReportService.java" showLineNumbers package com.example.service; import io.opentelemetry.api.GlobalOpenTelemetry; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.SpanKind; import io.opentelemetry.api.trace.StatusCode; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.context.Scope; import jakarta.inject.Singleton; @Singleton public class ReportService { private final Tracer tracer = GlobalOpenTelemetry.getTracer( "report-service", "1.0.0"); public byte[] generateReport(Long userId, String reportType) { Span span = tracer.spanBuilder("generate_report") .setSpanKind(SpanKind.INTERNAL) .setAttribute("report.type", reportType) .setAttribute("user.id", userId) .startSpan(); try (Scope scope = span.makeCurrent()) { byte[] report = buildReport(userId, reportType); span.setAttribute("report.size_bytes", report.length); span.setStatus(StatusCode.OK); return report; } catch (Exception e) { span.recordException(e); span.setStatus(StatusCode.ERROR, e.getMessage()); throw e; } finally { span.end(); } } } ``` ### Running Your Instrumented Application #### Development Mode Run locally with Gradle and the Java Agent: ```bash # Download the agent (one-time) curl -L -o opentelemetry-javaagent.jar \ https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.26.1/opentelemetry-javaagent.jar # Set environment variables export JAVA_TOOL_OPTIONS="-javaagent:./opentelemetry-javaagent.jar" export OTEL_SERVICE_NAME=micronaut-app-dev export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 # Run with Gradle ./gradlew run ``` #### Docker Deployment Run the full stack with Docker Compose: ```bash # Start all services (app, database, collector) docker compose up --build # Wait for services to be healthy (~30 seconds) docker compose ps # Verify the app is running curl http://localhost:8080/api/health ``` Expected health check response: ```json { "status": "healthy", "database": "connected" } ``` #### Verifying Instrumentation Make test requests and check that traces appear: ```bash # Create an article curl -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Hello OpenTelemetry", "body": "Tracing with Micronaut"}' # List articles curl http://localhost:8080/api/articles # Get a specific article curl http://localhost:8080/api/articles/1 ``` The expected span hierarchy for a create request: ```plaintext POST /api/articles (SERVER - java-agent) +-- HikariCP getConnection (INTERNAL - java-agent) +-- INSERT INTO articles ... (CLIENT - java-agent/jdbc) +-- POST http://notify:8081/notify (CLIENT - java-agent/http) +-- micronaut-notify: POST /notify (SERVER - java-agent) ``` For a list request: ```plaintext GET /api/articles (SERVER - java-agent) +-- HikariCP getConnection (INTERNAL - java-agent) +-- SELECT a1_0.id, ... FROM articles (CLIENT - java-agent/jdbc) +-- SELECT COUNT(*) FROM articles (CLIENT - java-agent/jdbc) ``` Check for: - **Spans** with correct `service.name` and proper nesting - **Logs** with `trace_id` and `span_id` in the JSON output - **Metrics** with `articles.created` counter incrementing ### Troubleshooting #### Verifying Agent Attachment ```bash # Check that the agent is loaded (look for OpenTelemetry in startup logs) docker compose logs app | grep -i "opentelemetry" # Verify JAVA_TOOL_OPTIONS is set docker compose exec app env | grep JAVA_TOOL_OPTIONS ``` You should see a line like: ```plaintext [otel.javaagent] opentelemetry-javaagent - version: 2.26.1 ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify the agent JAR is present and attached: ```bash ls -la /app/opentelemetry-javaagent.jar echo $JAVA_TOOL_OPTIONS ``` 2. Check that the collector endpoint is reachable: ```bash curl -v http://otel-collector:4318/v1/traces ``` 3. Enable debug logging on the agent: ```bash export OTEL_JAVAAGENT_DEBUG=true ``` 4. Check collector logs for authentication errors: ```bash docker compose logs otel-collector ``` ##### Issue: No JDBC/Hibernate query spans **Solutions:** 1. Verify the agent is attached (see above). JDBC instrumentation is included in the agent by default. 2. Check that the database connection is working: ```bash curl http://localhost:8080/api/health # Should return {"status":"healthy","database":"connected"} ``` 3. Ensure you're not using a database driver that the agent doesn't support. PostgreSQL, MySQL, and H2 are all supported. ##### Issue: No trace context propagation between services **Solutions:** 1. Verify both services have the Java Agent attached. Check startup logs for both containers: ```bash docker compose logs app | head -20 docker compose logs notify | head -20 ``` 2. Confirm `OTEL_PROPAGATORS` includes `tracecontext` (this is the default): ```bash echo $OTEL_PROPAGATORS # Should be empty (defaults) or include "tracecontext" ``` 3. Ensure the HTTP client being used is instrumented. The standard `java.net.http.HttpClient` is supported. If using a different client, check the [agent supported libraries](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/docs/supported-libraries.md). ##### Issue: Log correlation not working (missing trace_id in logs) **Solutions:** 1. Verify `logstash-logback-encoder` is in your dependencies: ```bash ./gradlew dependencies | grep logstash ``` 2. Check that `logback.xml` uses `LogstashEncoder`: ```xml trace_id span_id ``` 3. If using a custom Logback pattern instead of JSON, include MDC fields: ```xml %d{HH:mm:ss.SSS} [%thread] %-5level %logger{36} [trace=%X{trace_id}] - %msg%n ``` ##### Issue: High memory usage **Solutions:** 1. Reduce the batch queue size: ```bash export OTEL_BSP_MAX_QUEUE_SIZE=1024 ``` 2. Increase export frequency to flush spans sooner: ```bash export OTEL_BSP_SCHEDULE_DELAY=2000 ``` 3. Set JVM heap limits appropriate for your workload: ```bash export JAVA_TOOL_OPTIONS="-javaagent:/app/opentelemetry-javaagent.jar -Xmx512m" ``` ### Security Considerations #### SQL Parameter Obfuscation The Java Agent automatically obfuscates SQL parameter values in database spans: ```sql -- What gets executed (never sent to collector) SELECT * FROM users WHERE email = 'user@example.com' AND api_key = 'sk-abc123' -- What appears in the span (obfuscated) SELECT * FROM users WHERE email = ? AND api_key = ? ``` This is enabled by default and requires no configuration. #### Protecting Sensitive Data Never add sensitive information to span attributes: ```java // Bad - exposes sensitive data span.setAttribute("user.password", user.getPassword()); // Never! span.setAttribute("user.email", user.getEmail()); // PII risk span.setAttribute("payment.card", request.getCreditCard()); // Never! // Good - uses safe identifiers span.setAttribute("user.id", user.getId()); span.setAttribute("user.role", user.getRole()); span.setAttribute("payment.status", "completed"); ``` #### Filtering Sensitive HTTP Headers Configure which HTTP headers the agent captures: ```bash title=".env" # Only capture safe request headers OTEL_INSTRUMENTATION_HTTP_CAPTURE_HEADERS_SERVER_REQUEST=content-type,accept,user-agent # Block sensitive headers (excluded by default, but explicit is safer) OTEL_INSTRUMENTATION_HTTP_CAPTURE_HEADERS_SERVER_RESPONSE=content-type ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - SQL obfuscation is enabled by default - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard - Audit span attributes regularly for sensitive data leaks ### Performance Considerations #### Expected Performance Impact The OpenTelemetry Java Agent adds minimal overhead to Micronaut applications: - **Average latency increase**: 3-5ms per request - **CPU overhead**: Less than 5% with batch processing - **Memory overhead**: ~50-80MB for the agent itself - **Startup time**: ~1-3 seconds additional for agent initialization #### Optimization Best Practices ##### 1. Use Batch Span Processing ```bash # Production settings (low overhead) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 ``` ##### 2. Enable GZIP Compression ```bash OTEL_EXPORTER_OTLP_COMPRESSION=gzip ``` Reduces network bandwidth by 70-80%. ##### 3. Tune Metric Export Interval ```bash # Default is 60s; 30s provides better granularity OTEL_METRIC_EXPORT_INTERVAL=30000 ``` ##### 4. Filter Health Check Endpoints Configure the OTel Collector to drop noisy health check spans: ```yaml title="config/otel-config.yaml (excerpt)" processors: filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*health.*")' ``` ##### 5. Disable Unused Instrumentation If you don't need specific instrumentations, disable them: ```bash # Disable specific instrumentations OTEL_INSTRUMENTATION_KAFKA_ENABLED=false OTEL_INSTRUMENTATION_GRPC_ENABLED=false ``` ### Frequently Asked Questions #### Does the OpenTelemetry Java Agent impact Micronaut performance? The agent adds approximately 3-5ms of latency per request. With batch processing and GZIP compression, the overhead is minimal for production workloads. The agent uses bytecode manipulation at class load time, so there's a small startup cost (~1-3 seconds) but negligible runtime impact. #### Which Micronaut versions are supported? The OpenTelemetry Java Agent supports Micronaut 3.x and 4.x with Java 17+. Micronaut 4.x with Java 21+ is recommended. The agent instruments at the Netty and JDBC level, which is stable across Micronaut versions. #### Are Hibernate JPA queries traced automatically? Yes. The agent intercepts all JDBC calls, which includes every query Hibernate executes. Spans include the SQL statement (parameters obfuscated), database name, and operation type. No per-query code changes needed. #### Does the Java Agent propagate trace context across services? Yes. The agent automatically injects W3C `traceparent` headers into outgoing HTTP requests (via `java.net.http.HttpClient`, Apache HttpClient, OkHttp, etc.) and extracts them from incoming requests. This enables distributed tracing across services with zero code changes. #### Can I use the Java Agent with GraalVM native images? No. The Java Agent relies on JVM bytecode manipulation, which is not available in GraalVM native images. For native images, use the [OpenTelemetry SDK](https://opentelemetry.io/docs/languages/java/libraries/) with manual instrumentation instead of the agent. #### What is the difference between the Java Agent and the OpenTelemetry SDK? The **Java Agent** provides zero-code instrumentation by attaching to the JVM at startup. It instruments HTTP, JDBC, Netty, and 100+ libraries automatically. The **SDK** requires you to add instrumentation code manually. Use the agent for most applications; use the SDK when you need fine-grained control or are building GraalVM native images. #### Can I use the Java Agent alongside other APM tools? Yes, the agent can coexist with tools like New Relic or Datadog during migration periods. However, running multiple JVM agents simultaneously increases startup time and memory usage. Plan your migration to remove the legacy agent once OpenTelemetry is validated. #### How do I instrument Micronaut Messaging consumers? The Java Agent instruments Kafka and RabbitMQ consumers automatically. For custom messaging, create manual spans: ```java Span span = tracer.spanBuilder("process_message") .setSpanKind(SpanKind.CONSUMER) .setAttribute("messaging.system", "custom") .setAttribute("messaging.destination", queueName) .startSpan(); try (Scope scope = span.makeCurrent()) { processMessage(message); span.setStatus(StatusCode.OK); } finally { span.end(); } ``` #### How do I add tenant context in multi-tenant applications? Use a Micronaut HTTP filter to add tenant attributes to every span: ```java @Filter("/**") public class TenantFilter implements HttpServerFilter { @Override public Publisher> doFilter( HttpRequest request, ServerFilterChain chain) { String tenantId = request.getHeaders().get("X-Tenant-ID"); if (tenantId != null) { Span.current().setAttribute("tenant.id", tenantId); } return chain.proceed(request); } } ``` #### Can I use Micronaut's built-in metrics with OpenTelemetry? Micronaut has its own Micrometer-based metrics system. The Java Agent provides JVM and HTTP metrics independently. Both can coexist, but for consistency we recommend using the OpenTelemetry Meter API (`GlobalOpenTelemetry.getMeter()`) for custom metrics when using the agent. #### How do I correlate logs with traces in Micronaut? The Java Agent automatically injects `trace_id` and `span_id` into the SLF4J MDC. Use Logback with `logstash-encoder` to output JSON logs that include these fields for trace-log correlation. ### What's Next? Now that your Micronaut application is instrumented with OpenTelemetry, explore these resources: #### Advanced Topics - **Custom Java Instrumentation** - Manual tracing, custom spans, and advanced instrumentation patterns - **PostgreSQL Monitoring Best Practices** - Database observability with connection pooling metrics and query performance analysis #### Scout Platform Features - **Creating Alerts** - Set up alerts for error rates, latency thresholds, and custom metrics - **Dashboard Creation** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **Docker Compose Setup** - Set up Scout Collector for local development and testing #### Related Guides - [Spring Boot Instrumentation](./spring-boot.md) - Most widely used JVM web framework - [Quarkus Instrumentation](./quarkus.md) - Kubernetes-native JVM framework - [Java Custom Instrumentation](../custom-instrumentation/java.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language ### Complete Example #### Project Structure ```plaintext micronaut-postgres/ +-- app/ | +-- src/main/ | | +-- java/com/example/ | | | +-- Application.java | | | +-- controller/ | | | | +-- ArticleController.java | | | | +-- HealthController.java | | | +-- model/ | | | | +-- Article.java | | | +-- repository/ | | | | +-- ArticleRepository.java | | | +-- service/ | | | +-- NotificationClient.java | | | +-- TelemetryService.java | | +-- resources/ | | +-- application.yml | | +-- logback.xml | | +-- db/migration/ | | +-- V1__create_articles.sql | +-- build.gradle.kts | +-- Dockerfile +-- notify/ | +-- src/main/java/com/example/notify/ | | +-- Application.java | | +-- controller/ | | +-- NotifyController.java | +-- build.gradle.kts | +-- Dockerfile +-- config/ | +-- otel-config.yaml +-- compose.yml +-- .env.example +-- scripts/ +-- test-api.sh +-- verify-scout.sh ``` #### Running the Example ```bash # Clone the examples repository git clone https://github.com/base-14/examples.git cd examples/java/micronaut-postgres # Copy environment file cp .env.example .env # Start the stack docker compose up --build # Wait for services to be healthy (~30 seconds) curl http://localhost:8080/api/health # Run the full test suite ./scripts/test-api.sh ``` #### Testing the API ```bash # Create an article curl -s -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "OpenTelemetry with Micronaut", "body": "Full observability"}' | jq . # List articles curl -s http://localhost:8080/api/articles | jq . # Update an article curl -s -X PUT http://localhost:8080/api/articles/1 \ -H "Content-Type: application/json" \ -d '{"title": "Updated Title"}' | jq . # Delete an article curl -s -X DELETE http://localhost:8080/api/articles/1 ``` #### Expected Trace Output After making requests, you'll see traces in Scout Dashboard with: - **HTTP spans** for each controller action (GET, POST, PUT, DELETE) - **JDBC spans** for every Hibernate query (SELECT, INSERT, UPDATE, DELETE) - **HTTP client spans** for the notification service call - **Correlated logs** with `trace_id` and `span_id` in every JSON log line ```plaintext POST /api/articles (3ms) +-- HikariCP getConnection (1ms) +-- INSERT INTO articles ... (4ms) +-- POST http://notify:8081/notify (15ms) +-- [micronaut-notify] POST /notify (8ms) ``` Once telemetry is flowing, you can monitor Micronaut request performance in Scout - track Hibernate query times, HTTP client latency, and error rates from a unified dashboard. ### References - [Official OpenTelemetry Java Documentation](https://opentelemetry.io/docs/languages/java/) - [OpenTelemetry Java Agent](https://github.com/open-telemetry/opentelemetry-java-instrumentation) - [Supported Libraries (Java Agent)](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/docs/supported-libraries.md) - [Micronaut Documentation](https://docs.micronaut.io/latest/guide/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) --- ## NestJS OpenTelemetry Instrumentation - TypeORM & BullMQ Tracing ## NestJS :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview Implement OpenTelemetry instrumentation for NestJS applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability across your enterprise Node.js applications. This guide shows you how to auto-instrument NestJS controllers, services, guards, interceptors, TypeORM queries, BullMQ background jobs, and WebSocket gateways using the OpenTelemetry Node.js SDK. NestJS is an opinionated, structured framework that runs on top of [Express](./express.md) or [Fastify](./fastify.md). NestJS applications benefit from automatic instrumentation of the dependency injection container, decorators, HTTP endpoints, TypeORM database queries, Redis operations, BullMQ job processing, WebSocket connections, GraphQL resolvers, and microservice communication. With OpenTelemetry, you can trace requests through the entire dependency injection hierarchy, monitor async context propagation, identify N+1 query problems, debug background job failures, and track distributed transactions across microservices without significant code changes. Whether you're implementing observability for the first time, migrating from New Relic or Datadog, troubleshooting performance issues in production, or building enterprise-grade monitoring for microservices, this guide provides production-ready configurations and best practices for NestJS OpenTelemetry instrumentation with Base14 Scout. :::tip TL;DR Add a `TracingModule` that initializes the OpenTelemetry Node.js SDK and import it first in your `AppModule` - controllers, TypeORM queries, and HTTP calls are then traced automatically. Use `trace.getTracer()` directly in guards, interceptors, and BullMQ processors for custom span coverage. ::: ### Who This Guide Is For This documentation is designed for: - **NestJS developers**: implementing observability and distributed tracing for enterprise applications with dependency injection - **Backend engineers**: deploying NestJS microservices with comprehensive production monitoring requirements - **DevOps teams**: standardizing observability across multiple NestJS services in Kubernetes environments - **Enterprise architects**: building observable systems with GraphQL, WebSockets, message queues, and microservices - **Full-stack developers**: debugging TypeORM queries, BullMQ jobs, and async operations in production NestJS apps ### Prerequisites Before starting, ensure you have: - **Node.js 18.x or later** (20.x LTS recommended for production) - **NestJS 10.x or later** installed (`@nestjs/core`, `@nestjs/common`) - **TypeScript 4.9+** (5.x recommended) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) - Familiarity with NestJS dependency injection and decorators #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ----------------------------- | --------------- | ------------------- | | Node.js | 18.0.0 | 20.x LTS | | NestJS | 9.0.0 | 10.3.0+ | | @opentelemetry/sdk-node | 0.40.0 | 0.200+ | | @opentelemetry/auto-inst... | 0.40.0 | 0.76+ | | TypeORM (if used) | 0.3.0 | 0.3.20+ | | BullMQ (if used) | 4.0.0 | 5.x | | @nestjs/websockets (optional) | 10.0.0 | 10.3.0+ | | TypeScript | 4.9.0 | 5.3.0+ | ### Installation Install the OpenTelemetry SDK and auto-instrumentation packages: ```bash showLineNumbers title="Install OpenTelemetry for NestJS" npm install --save \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @opentelemetry/api ``` Install NestJS-specific packages if not already installed: ```bash showLineNumbers npm install --save \ @nestjs/core \ @nestjs/common \ @nestjs/platform-express ``` ### Configuration ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Create a NestJS module for OpenTelemetry initialization: ```typescript showLineNumbers title="src/tracing/tracing.module.ts" import { Module, OnModuleInit } from '@nestjs/common'; import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; @Module({}) export class TracingModule implements OnModuleInit { private sdk: NodeSDK; onModuleInit() { this.sdk = new NodeSDK({ resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || 'nestjs-api', [ATTR_SERVICE_VERSION]: process.env.npm_package_version || '1.0.0', 'deployment.environment.name': process.env.NODE_ENV || 'development', 'environment': process.env.NODE_ENV || 'development', }), traceExporter: new OTLPTraceExporter({ url: process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318/v1/traces', }), instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false, }, '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const ignorePaths = ['/health', '/metrics']; return ignorePaths.some((path) => req.url?.includes(path)); }, }, }), ], }); this.sdk.start(); } async onModuleDestroy() { await this.sdk.shutdown(); } } ``` Import the module in your root AppModule: ```typescript showLineNumbers title="src/app.module.ts" import { Module } from '@nestjs/common'; import { TracingModule } from './tracing/tracing.module'; import { UsersModule } from './users/users.module'; @Module({ imports: [ TracingModule, // Import FIRST for proper initialization UsersModule, // ... other modules ], }) export class AppModule {} ``` ```mdx-code-block ``` Create instrumentation file loaded before application bootstrap: ```typescript showLineNumbers title="instrumentation.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, } from '@opentelemetry/semantic-conventions'; const sdk = new NodeSDK({ resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: 'nestjs-api', 'deployment.environment.name': process.env.NODE_ENV, 'environment': process.env.NODE_ENV, }), traceExporter: new OTLPTraceExporter({ url: process.env.OTEL_EXPORTER_OTLP_ENDPOINT, }), instrumentations: [getNodeAutoInstrumentations()], }); sdk.start(); process.on('SIGTERM', async () => { await sdk.shutdown(); process.exit(0); }); export default sdk; ``` Update `main.ts`: ```typescript showLineNumbers title="src/main.ts" // Import instrumentation FIRST import './instrumentation'; import { NestFactory } from '@nestjs/core'; import { AppModule } from './app.module'; async function bootstrap() { const app = await NestFactory.create(AppModule); await app.listen(3000); } bootstrap(); ``` ```mdx-code-block ``` For containerized deployments: ```bash showLineNumbers title=".env" # Service identification OTEL_SERVICE_NAME=nestjs-api OTEL_SERVICE_VERSION=1.0.0 NODE_ENV=production # Exporter configuration OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 # Resource attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment.name=development,environment=development,service.namespace=backend # Performance tuning OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 OTEL_BSP_SCHEDULE_DELAY=5000 ``` Run with Node.js instrumentation: ```bash showLineNumbers node --require ./instrumentation.js dist/main.js ``` ```mdx-code-block ``` ### Traces Traces show the complete path of a request through your NestJS application, from the incoming HTTP route, down through the NestJS handler, into database queries and Redis calls, and back out as the response. #### Automatic Trace Collection Once the `TracingModule` is loaded, NestJS captures trace data for every request with no per-handler code: **Captured Information:** - HTTP method, route, and status code for every controller endpoint - Request duration and a timing breakdown across each span - PostgreSQL queries, including the executed SQL (with `instrumentation-pg`); TypeORM, Prisma, and Sequelize need their own instrumentation packages - Redis commands, including those issued by BullMQ (with `instrumentation-ioredis`) - Outbound HTTP calls to other services (with `instrumentation-http`) - Exceptions and stack traces recorded on the failing span - Distributed context propagation across microservices (W3C Trace Context) **Trace Hierarchy:** ```text HTTP Request Span (root: GET /users/:id) ├── UsersController.findOne Span │ ├── PostgreSQL Query Span (SELECT ... FROM users) │ └── Redis GET Span (cache lookup) └── Redis Span (BullMQ enqueue: welcome-email job) ``` #### Key Tracing Features - **Automatic HTTP tracking**: every controller route is traced with no code changes - **NestJS-aware spans**: controller handlers, guards, interceptors, and pipes are traced through `instrumentation-nestjs-core`; spans for your own service methods are added manually - **Error capturing**: thrown exceptions and filtered errors are recorded with full stack traces - **Context propagation**: distributed traces follow requests across HTTP, gRPC, and message-queue boundaries - **Async support**: context propagates across `async`/`await` and RxJS observables > View traces in your base14 Scout dashboard to follow request flows and find > the slow span in a chain. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics Metrics aggregate runtime measurements over time, such as request rate, latency distributions, and error counts. Where traces explain a single request, metrics power dashboards and alerts across all of them. #### Enable Metrics in the SDK Add a metric reader to the `NodeSDK` so OpenTelemetry exports runtime and HTTP metrics alongside traces: ```typescript showLineNumbers title="src/tracing/tracing.module.ts" import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; // inside new NodeSDK({ ... }) metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 10000, }), ``` The HTTP instrumentation also emits server request-duration and request-count metrics without further code. #### Custom Business Metrics The HTTP instrumentation already emits the standard server metrics, including the `http.server.request.duration` histogram (its sample count gives you request rate, latency percentiles, and error ratio per route), so there is no need to hand-roll request latency. Reserve custom metrics for business events the instrumentation cannot see, such as domain actions: ```typescript showLineNumbers title="src/articles/articles.service.ts" import { Injectable } from '@nestjs/common'; import { metrics } from '@opentelemetry/api'; const meter = metrics.getMeter('nestjs-api'); const articlesCreated = meter.createCounter('articles.created', { description: 'Articles created', }); @Injectable() export class ArticlesService { async create(authorId: string /* ... */): Promise { // ... persist the article ... articlesCreated.add(1, { 'author.id': authorId }); } } ``` > View metrics in your base14 Scout dashboard to chart request rate, latency > percentiles, and error ratio per route from the automatic HTTP histogram, > alongside your custom business counters. ##### Reference [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) ### Production Configuration For production deployments with BatchSpanProcessor and resource attributes: ```typescript showLineNumbers title="src/tracing/tracing.production.ts" import { Module, OnModuleInit, OnModuleDestroy } from '@nestjs/common'; import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, ATTR_SERVICE_INSTANCE_ID, } from '@opentelemetry/semantic-conventions'; @Module({}) export class TracingModule implements OnModuleInit, OnModuleDestroy { private sdk: NodeSDK; onModuleInit() { const traceExporter = new OTLPTraceExporter({ url: process.env.OTEL_EXPORTER_OTLP_ENDPOINT, headers: { // Optional: Add authentication for Scout // 'Authorization': `Bearer ${process.env.SCOUT_API_KEY}`, }, timeoutMillis: 15000, }); this.sdk = new NodeSDK({ resource: resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME, [ATTR_SERVICE_VERSION]: process.env.npm_package_version, 'deployment.environment.name': process.env.NODE_ENV, 'environment': process.env.NODE_ENV, [ATTR_SERVICE_INSTANCE_ID]: process.env.HOSTNAME || process.pid.toString(), 'service.namespace': process.env.SERVICE_NAMESPACE || 'default', 'container.id': process.env.CONTAINER_ID, 'k8s.pod.name': process.env.K8S_POD_NAME, 'k8s.namespace.name': process.env.K8S_NAMESPACE, }), spanProcessor: new BatchSpanProcessor(traceExporter, { maxQueueSize: 2048, maxExportBatchSize: 512, scheduledDelayMillis: 5000, exportTimeoutMillis: 30000, }), instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false, }, '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { return ['/health', '/metrics', '/ready'].some((path) => req.url?.includes(path), ); }, }, }), ], }); this.sdk.start(); console.log('OpenTelemetry SDK initialized'); } async onModuleDestroy() { console.log('Shutting down OpenTelemetry SDK...'); await this.sdk.shutdown(); } } ``` #### Docker Deployment ```dockerfile showLineNumbers title="Dockerfile" FROM node:20-alpine AS builder WORKDIR /app COPY package*.json ./ RUN npm ci COPY . . RUN npm run build FROM node:20-alpine WORKDIR /app COPY --from=builder /app/dist ./dist COPY --from=builder /app/node_modules ./node_modules COPY package*.json ./ ENV NODE_ENV=production ENV OTEL_SERVICE_NAME=nestjs-api EXPOSE 3000 CMD ["node", "dist/main.js"] ``` ```yaml showLineNumbers title="docker-compose.yml" version: '3.8' services: nestjs-api: build: . ports: - '3000:3000' environment: - NODE_ENV=production - OTEL_SERVICE_NAME=nestjs-api - OTEL_SERVICE_VERSION=1.0.0 - OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 - DATABASE_URL=postgres://user:pass@postgres:5432/nestjs - REDIS_URL=redis://redis:6379 depends_on: - postgres - redis - scout-collector postgres: image: postgres:16-alpine environment: POSTGRES_DB: nestjs POSTGRES_USER: user POSTGRES_PASSWORD: pass ports: - '5432:5432' redis: image: redis:7-alpine ports: - '6379:6379' scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4318:4318' ``` ### NestJS-Specific Instrumentation #### Controllers and Routes NestJS controllers are automatically instrumented via HTTP instrumentation: ```typescript showLineNumbers title="src/users/users.controller.ts" import { Controller, Get, Post, Body, Param } from '@nestjs/common'; import { UsersService } from './users.service'; import { CreateUserDto } from './dto/create-user.dto'; @Controller('users') export class UsersController { constructor(private readonly usersService: UsersService) {} // Automatically traced as "GET /users" @Get() async findAll() { return this.usersService.findAll(); } // Automatically traced as "GET /users/:id" @Get(':id') async findOne(@Param('id') id: string) { return this.usersService.findOne(+id); } // Automatically traced as "POST /users" @Post() async create(@Body() createUserDto: CreateUserDto) { return this.usersService.create(createUserDto); } } ``` Traces show: - HTTP method and route pattern - Response status codes - Request/response headers (configurable) - Timing for entire request lifecycle #### Services with Dependency Injection Services are traced when called from instrumented controllers: ```typescript showLineNumbers title="src/users/users.service.ts" import { Injectable } from '@nestjs/common'; import { InjectRepository } from '@nestjs/typeorm'; import { Repository } from 'typeorm'; import { User } from './entities/user.entity'; import { CreateUserDto } from './dto/create-user.dto'; @Injectable() export class UsersService { constructor( @InjectRepository(User) private usersRepository: Repository, ) {} // Database queries automatically traced by TypeORM instrumentation async findAll(): Promise { return this.usersRepository.find(); } async findOne(id: number): Promise { return this.usersRepository.findOne({ where: { id } }); } async create(createUserDto: CreateUserDto): Promise { const user = this.usersRepository.create(createUserDto); return this.usersRepository.save(user); } } ``` #### TypeORM Database Instrumentation The SQL that TypeORM issues is traced at the driver level by `instrumentation-pg` in the auto-instrumentations bundle (ORM-level spans require the separate `@opentelemetry/instrumentation-typeorm` package): ```typescript showLineNumbers title="src/users/entities/user.entity.ts" import { Entity, Column, PrimaryGeneratedColumn, OneToMany } from 'typeorm'; import { Order } from '../../orders/entities/order.entity'; @Entity('users') export class User { @PrimaryGeneratedColumn() id: number; @Column() email: string; @Column() name: string; @OneToMany(() => Order, (order) => order.user) orders: Order[]; } ``` TypeORM Module configuration: ```typescript showLineNumbers title="src/app.module.ts" import { Module } from '@nestjs/common'; import { TypeOrmModule } from '@nestjs/typeorm'; import { TracingModule } from './tracing/tracing.module'; @Module({ imports: [ TracingModule, TypeOrmModule.forRoot({ type: 'postgres', host: process.env.DB_HOST || 'localhost', port: parseInt(process.env.DB_PORT) || 5432, username: process.env.DB_USER, password: process.env.DB_PASSWORD, database: process.env.DB_NAME, entities: [__dirname + '/**/*.entity{.ts,.js}'], synchronize: process.env.NODE_ENV !== 'production', logging: process.env.NODE_ENV === 'development', }), // ... other modules ], }) export class AppModule {} ``` Traces show: - SQL queries with parameters - Query execution time - Connection pool metrics - Transaction boundaries #### Guards and Authentication Guards are traced as part of the request lifecycle: ```typescript showLineNumbers title="src/auth/guards/jwt-auth.guard.ts" import { Injectable, ExecutionContext } from '@nestjs/common'; import { AuthGuard } from '@nestjs/passport'; import { trace } from '@opentelemetry/api'; @Injectable() export class JwtAuthGuard extends AuthGuard('jwt') { async canActivate(context: ExecutionContext): Promise { const tracer = trace.getTracer('auth-guard'); return tracer.startActiveSpan('JwtAuthGuard.canActivate', async (span) => { try { const result = (await super.canActivate(context)) as boolean; span.setAttribute('auth.success', result); span.setStatus({ code: 1 }); // OK return result; } catch (error) { span.recordException(error); span.setStatus({ code: 2, message: error.message }); throw error; } finally { span.end(); } }); } } ``` #### Interceptors for Custom Tracing Add custom attributes using interceptors: ```typescript showLineNumbers title="src/common/interceptors/tracing.interceptor.ts" import { Injectable, NestInterceptor, ExecutionContext, CallHandler, } from '@nestjs/common'; import { Observable } from 'rxjs'; import { tap } from 'rxjs/operators'; import { trace, context } from '@opentelemetry/api'; @Injectable() export class TracingInterceptor implements NestInterceptor { intercept(context: ExecutionContext, next: CallHandler): Observable { const request = context.switchToHttp().getRequest(); const activeSpan = trace.getActiveSpan(); if (activeSpan) { // Add custom attributes activeSpan.setAttribute('user.id', request.user?.id); activeSpan.setAttribute('tenant.id', request.headers['x-tenant-id']); activeSpan.setAttribute('request.path', request.path); } return next.handle().pipe( tap(() => { if (activeSpan) { activeSpan.setAttribute('response.status', 'success'); } }), ); } } ``` Apply globally: ```typescript showLineNumbers title="src/main.ts" import { NestFactory } from '@nestjs/core'; import { AppModule } from './app.module'; import { TracingInterceptor } from './common/interceptors/tracing.interceptor'; async function bootstrap() { const app = await NestFactory.create(AppModule); app.useGlobalInterceptors(new TracingInterceptor()); await app.listen(3000); } bootstrap(); ``` #### BullMQ Background Jobs Instrument BullMQ job processing: ```typescript showLineNumbers title="src/jobs/email.processor.ts" import { Processor, Process } from '@nestjs/bull'; import { Job } from 'bull'; import { trace } from '@opentelemetry/api'; @Processor('email') export class EmailProcessor { @Process('send-welcome') async handleWelcomeEmail(job: Job) { const tracer = trace.getTracer('email-processor'); return tracer.startActiveSpan('EmailProcessor.sendWelcome', async (span) => { try { span.setAttributes({ 'job.id': job.id.toString(), 'job.name': job.name, 'job.attempts': job.attemptsMade, 'user.email': job.data.email, }); // Simulate email sending await this.sendEmail(job.data.email, job.data.name); span.setStatus({ code: 1 }); // OK return { sent: true }; } catch (error) { span.recordException(error); span.setStatus({ code: 2, message: error.message }); throw error; } finally { span.end(); } }); } private async sendEmail(email: string, name: string) { // Email sending logic console.log(`Sending welcome email to ${email}`); } } ``` Queue module setup: ```typescript showLineNumbers title="src/jobs/jobs.module.ts" import { Module } from '@nestjs/common'; import { BullModule } from '@nestjs/bull'; import { EmailProcessor } from './email.processor'; @Module({ imports: [ BullModule.registerQueue({ name: 'email', redis: { host: process.env.REDIS_HOST || 'localhost', port: parseInt(process.env.REDIS_PORT) || 6379, }, }), ], providers: [EmailProcessor], }) export class JobsModule {} ``` #### WebSocket Gateway Instrumentation Trace WebSocket connections and messages: ```typescript showLineNumbers title="src/chat/chat.gateway.ts" import { WebSocketGateway, SubscribeMessage, MessageBody, ConnectedSocket, OnGatewayConnection, } from '@nestjs/websockets'; import { Socket } from 'socket.io'; import { trace } from '@opentelemetry/api'; @WebSocketGateway({ cors: true }) export class ChatGateway implements OnGatewayConnection { private tracer = trace.getTracer('chat-gateway'); handleConnection(client: Socket) { const span = this.tracer.startSpan('ChatGateway.handleConnection'); span.setAttributes({ 'websocket.client.id': client.id, 'websocket.event': 'connection', }); span.end(); } @SubscribeMessage('message') async handleMessage( @MessageBody() data: { room: string; message: string }, @ConnectedSocket() client: Socket, ) { return this.tracer.startActiveSpan('ChatGateway.handleMessage', async (span) => { try { span.setAttributes({ 'websocket.client.id': client.id, 'websocket.room': data.room, 'message.length': data.message.length, }); // Broadcast message to room client.to(data.room).emit('message', { sender: client.id, message: data.message, }); span.setStatus({ code: 1 }); return { status: 'sent' }; } catch (error) { span.recordException(error); span.setStatus({ code: 2, message: error.message }); throw error; } finally { span.end(); } }); } } ``` ### Custom Instrumentation For business logic and application-specific operations: ```typescript showLineNumbers title="src/orders/orders.service.ts" import { Injectable } from '@nestjs/common'; import { InjectRepository } from '@nestjs/typeorm'; import { Repository } from 'typeorm'; import { trace, SpanStatusCode } from '@opentelemetry/api'; import { Order } from './entities/order.entity'; import { CreateOrderDto } from './dto/create-order.dto'; @Injectable() export class OrdersService { private tracer = trace.getTracer('orders-service'); constructor( @InjectRepository(Order) private ordersRepository: Repository, ) {} async createOrder(userId: number, createOrderDto: CreateOrderDto) { return this.tracer.startActiveSpan('OrdersService.createOrder', async (span) => { try { span.setAttributes({ 'user.id': userId, 'order.items.count': createOrderDto.items.length, 'order.total': this.calculateTotal(createOrderDto.items), }); // Validate inventory await this.tracer.startActiveSpan('validateInventory', async (validateSpan) => { const available = await this.checkInventory(createOrderDto.items); validateSpan.setAttribute('inventory.available', available); if (!available) { throw new Error('Insufficient inventory'); } validateSpan.end(); }); // Create order const order = await this.tracer.startActiveSpan('saveOrder', async (dbSpan) => { const newOrder = this.ordersRepository.create({ userId, items: createOrderDto.items, total: this.calculateTotal(createOrderDto.items), }); const saved = await this.ordersRepository.save(newOrder); dbSpan.setAttribute('order.id', saved.id); dbSpan.end(); return saved; }); // Process payment await this.tracer.startActiveSpan('processPayment', async (paymentSpan) => { await this.processPayment(order.id, order.total); paymentSpan.setAttribute('payment.status', 'completed'); paymentSpan.end(); }); span.setStatus({ code: SpanStatusCode.OK }); return order; } catch (error) { span.recordException(error); span.setStatus({ code: SpanStatusCode.ERROR, message: error.message, }); throw error; } finally { span.end(); } }); } private calculateTotal(items: any[]): number { return items.reduce((sum, item) => sum + item.price * item.quantity, 0); } private async checkInventory(items: any[]): Promise { // Inventory check logic return true; } private async processPayment(orderId: number, amount: number): Promise { // Payment processing logic } } ``` ### Running Your Application #### Development Mode ```bash showLineNumbers # With console output for debugging export OTEL_TRACES_EXPORTER=console npm run start:dev ``` #### Production Mode ```bash showLineNumbers export NODE_ENV=production export OTEL_SERVICE_NAME=nestjs-api export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.yourdomain.com/v1/traces npm run start:prod ``` #### Using PM2 ```javascript showLineNumbers title="ecosystem.config.js" module.exports = { apps: [ { name: 'nestjs-api', script: 'dist/main.js', instances: 'max', exec_mode: 'cluster', env: { NODE_ENV: 'production', OTEL_SERVICE_NAME: 'nestjs-api', OTEL_EXPORTER_OTLP_ENDPOINT: 'http://scout-collector:4318', }, }, ], }; ``` Start with PM2: ```bash showLineNumbers pm2 start ecosystem.config.js pm2 logs nestjs-api ``` ### Troubleshooting #### Issue: No Traces from NestJS Controllers **Solutions:** 1. Ensure TracingModule is imported first in AppModule: ```typescript @Module({ imports: [ TracingModule, // MUST be first TypeOrmModule.forRoot(/*...*/), // other modules ], }) export class AppModule {} ``` 1. Verify HTTP instrumentation is enabled: ```typescript instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { enabled: true, // Explicitly enable }, }), ]; ``` #### Issue: TypeORM Queries Not Appearing in Traces **Solutions:** 1. Install TypeORM instrumentation explicitly if needed: ```bash npm install @opentelemetry/instrumentation-typeorm ``` 1. Verify database connection is established after SDK initialization 2. Check TypeORM logging is enabled in development: ```typescript TypeOrmModule.forRoot({ // ... logging: true, // See queries in console }); ``` #### Issue: Missing Context in Async Operations **Solutions:** Use async/await instead of callbacks: ```typescript // WRONG - loses context setTimeout(() => { const span = trace.getActiveSpan(); // undefined }, 1000); // CORRECT - preserves context await new Promise((resolve) => setTimeout(resolve, 1000)); const span = trace.getActiveSpan(); // Works! ``` #### Issue: Guard/Interceptor Spans Not Showing **Solutions:** Guards and interceptors need manual span creation. Add custom tracing as shown in the Guards and Interceptors sections above. ### Security Considerations #### Sensitive Data Protection Avoid capturing passwords, tokens, and PII in spans: ```typescript showLineNumbers // BAD - Exposes sensitive data span.setAttributes({ 'user.password': password, 'user.email': email, 'credit_card': cardNumber, }); // GOOD - Use safe identifiers span.setAttributes({ 'user.id': userId, 'user.type': 'customer', 'payment.method': 'credit_card', }); ``` #### HTTP Header Filtering Configure header filtering to exclude authentication tokens: ```typescript showLineNumbers '@opentelemetry/instrumentation-http': { headersToSpanAttributes: { requestHeaders: ['content-type', 'user-agent'], responseHeaders: ['content-type'], }, }, ``` #### Database Query Sanitization TypeORM automatically sanitizes parameters, but verify in traces: ```typescript // Parameters are automatically sanitized const user = await this.usersRepository.findOne({ where: { email: userEmail }, // Safe - uses parameterized query }); ``` #### Environment Variable Security Never log sensitive environment variables: ```typescript showLineNumbers // BAD console.log('DB_PASSWORD:', process.env.DB_PASSWORD); // GOOD - Use configuration service @Injectable() export class ConfigService { get(key: string): string { const value = process.env[key]; if (!value && this.isProduction()) { throw new Error(`Missing required config: ${key}`); } return value; } } ``` ### Performance Considerations OpenTelemetry adds minimal overhead to NestJS applications: **Expected Impact:** - **Latency**: +0.5-2ms per request with auto-instrumentation - **CPU**: +2-5% in production with BatchSpanProcessor - **Memory**: +15-35MB for trace buffers and SDK - **Throughput**: <1% reduction in requests/second #### Optimization Best Practices ##### 1. Use BatchSpanProcessor in Production ```typescript showLineNumbers import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; spanProcessor: new BatchSpanProcessor(traceExporter, { maxQueueSize: 2048, maxExportBatchSize: 512, scheduledDelayMillis: 5000, }); ``` ##### 2. Skip Health Check Endpoints ```typescript showLineNumbers '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { return ['/health', '/metrics', '/ready'].some((path) => req.url?.includes(path), ); }, }, ``` ##### 3. Disable Filesystem Tracing ```typescript showLineNumbers '@opentelemetry/instrumentation-fs': { enabled: false, }, ``` ##### 4. Optimize TypeORM Queries Use query builder for complex queries to reduce overhead: ```typescript showLineNumbers // Efficient - single query with joins const users = await this.usersRepository .createQueryBuilder('user') .leftJoinAndSelect('user.orders', 'order') .where('user.active = :active', { active: true }) .getMany(); // Inefficient - N+1 queries const users = await this.usersRepository.find({ where: { active: true } }); for (const user of users) { user.orders = await this.ordersRepository.find({ where: { userId: user.id } }); } ``` ### FAQ #### Does OpenTelemetry work with NestJS dependency injection? Yes, OpenTelemetry fully supports NestJS DI. TracingModule can be imported and services are automatically traced when called from instrumented controllers. #### What is the performance impact of OpenTelemetry on NestJS applications? With BatchSpanProcessor, expect +0.5-2ms latency per request, +2-5% CPU, and +15-35MB memory. Minimal impact for most production workloads. #### Can I trace TypeORM, Prisma, and Sequelize? The SQL these ORMs issue is traced at the driver level by `instrumentation-pg` (or the equivalent driver package) in the auto-instrumentations bundle. ORM-level spans for TypeORM, Prisma, and Sequelize need their own instrumentation packages, which are not part of `auto-instrumentations-node`. #### How do I trace BullMQ background jobs in NestJS? BullMQ has no dedicated auto-instrumentation package. The Redis commands it issues are traced by `instrumentation-ioredis`, so add a manual span in the processor with `trace.getTracer()` and propagate trace context through the job data to link the job to the request that enqueued it. See the [BullMQ guide](./bullmq.md). #### Does OpenTelemetry work with NestJS WebSocket gateways? WebSocket connections and messages require manual instrumentation. Use `trace.getTracer()` in gateway methods as shown in the WebSocket section. #### How do I trace GraphQL resolvers? GraphQL queries are traced via HTTP instrumentation. Add custom spans in resolvers for field-level tracing using decorators or interceptors. #### Can I use it with NestJS microservices? Yes, OpenTelemetry traces distributed microservices automatically. Context propagates across HTTP, gRPC, and message queue boundaries. #### How do I handle multi-tenant applications? Add tenant ID as span attribute in guards or interceptors: `span.setAttribute('tenant.id', tenantId)` and filter in Scout Dashboard. #### What's the difference between traces and metrics? Traces show request flow and timing through your NestJS app (spans). Metrics aggregate performance data (counters, histograms). Both are supported. #### Can I trace custom decorators and metadata? Yes, use interceptors or method decorators to add custom spans. Access metadata using `Reflector` and add attributes to active spans. #### Can I trace TypeORM and Prisma queries in NestJS with OpenTelemetry? The SQL these ORMs issue is traced at the driver level by `instrumentation- pg` (or the matching driver package) in the auto-instrumentations bundle. ORM-level spans for `TypeORM`, Prisma, and `Sequelize` need their own instrumentation packages, which are not part of auto-instrumentations-node. ### What's Next? #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for API latency, errors, and database queries - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards for NestJS metrics #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment with PostgreSQL and Redis - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment on Kubernetes ### Complete Example Here's a complete working NestJS application with OpenTelemetry instrumentation: #### package.json ```json showLineNumbers title="package.json" { "name": "nestjs-otel-example", "version": "1.0.0", "scripts": { "build": "nest build", "start": "nest start", "start:dev": "nest start --watch", "start:prod": "node dist/main" }, "dependencies": { "@nestjs/common": "^10.3.0", "@nestjs/core": "^10.3.0", "@nestjs/platform-express": "^10.3.0", "@nestjs/typeorm": "^10.0.1", "@nestjs/bull": "^10.0.1", "@opentelemetry/sdk-node": "^0.218.0", "@opentelemetry/auto-instrumentations-node": "^0.76.0", "@opentelemetry/exporter-trace-otlp-http": "^0.218.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.218.0", "@opentelemetry/sdk-metrics": "^2.7.1", "@opentelemetry/resources": "^2.7.1", "@opentelemetry/semantic-conventions": "^1.41.1", "@opentelemetry/api": "^1.9.0", "typeorm": "^0.3.20", "pg": "^8.11.0", "bull": "^4.12.0", "reflect-metadata": "^0.2.0", "rxjs": "^7.8.0" }, "devDependencies": { "@nestjs/cli": "^10.3.0", "@types/node": "^20.10.0", "typescript": "^5.3.0" } } ``` #### Environment Variables ```bash showLineNumbers title=".env.production" NODE_ENV=production OTEL_SERVICE_NAME=nestjs-api OTEL_SERVICE_VERSION=1.0.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 OTEL_SEMCONV_STABILITY_OPT_IN=http,database DATABASE_URL=postgres://user:pass@postgres:5432/nestjs REDIS_URL=redis://redis:6379 ``` `OTEL_SEMCONV_STABILITY_OPT_IN=http,database` opts the instrumentation into the stable HTTP and database semantic conventions (for example `http.request.method`, `http.response.status_code`, and `db.query.text`). Without it, the instrumentation keeps emitting the older experimental attribute names (`http.method`, `http.status_code`, `db.statement`). Use `http/dup` and `database/dup` instead to emit both old and new during a migration. #### GitHub Repository Complete working example: [GitHub: base-14/examples/nodejs/nestjs-postgres](https://github.com/base-14/examples/tree/main/nodejs/nestjs-postgres) ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [NestJS Documentation](https://docs.nestjs.com/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [TypeORM Documentation](https://typeorm.io/) ### Related Guides - [Express Instrumentation](./express.md) - The HTTP layer NestJS runs on by default - [Next.js Instrumentation](./nextjs-scout.md) - Full-stack React framework on Node.js - [Fastify Instrumentation](./fastify.md) - Alternate NestJS HTTP adapter - [Hono Instrumentation](./hono.md) - Lightweight Node.js web framework - [BullMQ Instrumentation](./bullmq.md) - Trace the background jobs NestJS enqueues --- ## Next.js Full-Stack OpenTelemetry - Browser and Server ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## Next.js (Full-Stack) :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: :::info Server side only? This guide covers browser and server together, exporting to a collector. If you only need the server side, or you have nowhere to run a collector, start with [Next.js](./nextjs-scout.md) — direct OTLP to Scout with OIDC client credentials — and add the browser tier from here on top. ::: ### Introduction Instrument a Next.js App Router application with OpenTelemetry on both sides of the network boundary: the Node.js server that renders pages and serves API routes, and the browser that hydrates and runs them. This guide wires the Node SDK into the `instrumentation.ts` register hook, mounts the web SDK from a client component in the root layout, and links the two through the W3C `traceparent` header so a click in the browser and the API route it calls land in one trace. It covers all three signals. **Traces** cover document load, user interactions, browser `fetch`/XHR, server-side rendering, and API route execution. **Metrics** cover HTTP and Node.js runtime instruments exported on a periodic reader. **Logs** cover application records emitted through the OTel logger plus a console bridge that captures the SSR error output Next.js prints to stdout instead of surfacing through a span. Three kinds of browser error are handled separately: uncaught exceptions, unhandled promise rejections, and React error boundary crashes, which a `window.onerror` listener does not see. Browser telemetry reaches the collector through a catch-all API route at `/api/otel` rather than being exported directly. The browser posts same-origin, so there is no preflight and no `cors` block on the OTLP HTTP receiver, and the collector does not have to be reachable from a user's network. The alternative is direct export with a CORS allow-list on the collector; the [Angular guide](./angular.md) covers the same three signals that way. :::tip TL;DR Server side, create `instrumentation.ts` at the project root and dynamically import your `NodeSDK` setup only when `process.env.NEXT_RUNTIME === 'nodejs'`, so the SDK never loads in the Edge runtime. Browser side, call the web SDK bootstrap from a `'use client'` component mounted in the root layout, and point its OTLP exporter at a catch-all `/api/otel/[...signal]` route that forwards to the collector - this makes browser telemetry same-origin and removes collector CORS entirely. Set `propagateTraceHeaderCorsUrls` so `traceparent` links browser spans to API route spans, and wrap `console.*` after `sdk.start()` so Next.js internal SSR errors reach your logs pipeline. ::: ### Who This Guide Is For This documentation is designed for: - **Next.js developers**: adding tracing, metrics, and logs to an App Router app without bolting on a proprietary RUM agent. - **Full-stack engineers**: connecting a browser interaction to the server render and API route behind it through a single trace id. - **Front-end platform teams**: standardizing browser observability across several Next.js apps, including error boundaries and Core Web Vitals. - **SRE and DevOps**: shipping an instrumented Next.js container that exports to a collector without exposing that collector to the public internet. - **Teams migrating off commercial APM**: replacing a vendor agent with vendor-neutral OTLP while keeping browser-to-server correlation. ### Overview #### Prerequisites Before starting, ensure you have: - **Node.js 22 or later** - the example builds and runs on `node:22-alpine`. - **Next.js 15 or later** using the App Router. The `instrumentation.ts` register hook has been stable since 15; the example runs **Next.js 16.3**. - **A Scout Collector** reachable from the Next.js server over OTLP/HTTP, with traces, metrics, and logs pipelines. See [Docker Compose collector setup](../../collector-setup/docker-compose-example.md). - **Docker and Docker Compose** to run the full stack locally. #### Compatibility Matrix | Component | Version | Notes | | --- | --- | --- | | Next.js | 16.3.0 | App Router; register hook stable since 15 | | React | 19.2.8 | Error boundaries via `error.tsx` / `global-error.tsx` | | Node.js | 22 | Server runtime; Edge runtime is excluded by design | | TypeScript | 6.0.3 | | | `@opentelemetry/api` | 1.9.1 | | | `@opentelemetry/sdk-node` | 0.221.0 | Server SDK, loaded from the register hook | | `@opentelemetry/auto-instrumentations-node` | 0.79.0 | HTTP, fetch, and runtime | | `@opentelemetry/sdk-trace-web` | 2.10.0 | Browser tracer provider | | `@opentelemetry/auto-instrumentations-web` | 0.66.0 | Document load, fetch, XHR, interactions | | `@opentelemetry/semantic-conventions` | 1.43.0 | `ATTR_*` constants | | `web-vitals` | 5.3.0 | CLS, LCP, TTFB, INP | #### Instrumented Components | Surface | What is captured | Automatic | | --- | --- | --- | | Incoming HTTP requests | Method, route, status, duration | Yes | | Server-side rendering | Render spans per route | Yes | | API route execution | One span per handler invocation | Yes | | Server-side `fetch` | Outbound calls made during SSR | Yes | | Node.js runtime metrics | Event loop, memory, GC | Yes | | Document load | Navigation and resource timing | Yes | | Browser `fetch` / XHR | One span per client request, with `traceparent` | Yes | | User interactions | `click` and `submit` spans | Yes | | Application logs | INFO / WARN / ERROR records with attributes | No | | Next.js SSR error output | stdout error text as ERROR log records | No | | Browser JS errors | Uncaught exceptions and rejections as spans | No | | React error boundaries | `error.tsx` and `global-error.tsx` catches | No | | Core Web Vitals | CLS, LCP, TTFB, INP as spans | No | The rows marked **No** are wired explicitly in the example, and each has its own section below. The full runnable project is at [base-14/examples/nodejs/nextjs-fullstack-otel](https://github.com/base-14/examples/tree/main/nodejs/nextjs-fullstack-otel). :::note This example has no database. The `/api/products` route serves an in-memory array behind a small artificial delay. For database span capture in a Next.js app, see the [Next.js server-side guide](./nextjs.md), whose example uses MongoDB. ::: ### Installation The server and browser SDKs are separate dependency sets, but they install together because both bundles are built from one `package.json`. ```mdx-code-block ``` ```bash npm install \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/sdk-trace-web \ @opentelemetry/sdk-trace-base \ @opentelemetry/auto-instrumentations-web \ @opentelemetry/instrumentation \ @opentelemetry/context-zone \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ web-vitals ``` ```mdx-code-block ``` ```bash yarn add \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/sdk-trace-web \ @opentelemetry/sdk-trace-base \ @opentelemetry/auto-instrumentations-web \ @opentelemetry/instrumentation \ @opentelemetry/context-zone \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ web-vitals ``` ```mdx-code-block ``` ```bash pnpm add \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/sdk-trace-web \ @opentelemetry/sdk-trace-base \ @opentelemetry/auto-instrumentations-web \ @opentelemetry/instrumentation \ @opentelemetry/context-zone \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ web-vitals ``` ```mdx-code-block ``` The web packages ship to the client bundle and the node packages do not, because the browser module is imported only from a `'use client'` component, and the server module only from the register hook. ### Configuration Server and browser configuration are separate. Server variables stay private to the container; browser variables need the `NEXT_PUBLIC_` prefix, which is how Next.js decides what may be inlined into the client bundle at build time. ```mdx-code-block ``` ```bash title=".env.example" # Server-side OTel config OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_SERVICE_NAME=sample-nextjs-app # Browser-side OTel config (NEXT_PUBLIC_ prefix exposes to browser) # Default: browser sends to /api/otel proxy (no CORS needed) # To send directly to collector, set: NEXT_PUBLIC_OTEL_ENDPOINT=http://localhost:4318 NEXT_PUBLIC_OTEL_SERVICE_NAME=sample-nextjs-app-browser NEXT_PUBLIC_BASE_URL=http://localhost:3000 ``` Leave `NEXT_PUBLIC_OTEL_ENDPOINT` unset. When it is absent the browser falls back to the same-origin `/api/otel` proxy, which needs no CORS. Set it only to export straight to a collector, and configure that collector's CORS allow-list to match. ```mdx-code-block ``` Next.js calls the exported `register` function once per server runtime, before the first request is handled. It is the only hook that runs early enough for the Node SDK to instrument the first render. ```typescript title="instrumentation.ts" showLineNumbers export async function register() { // Only load server-side OTel in the Node.js runtime (not Edge) if (process.env.NEXT_RUNTIME === 'nodejs') { await import('./src/lib/server-telemetry'); } } ``` The import is dynamic, so the Node SDK is not resolved at module-evaluation time and never enters the Edge bundle. The `NEXT_RUNTIME` guard keeps the Edge runtime from throwing on Node.js built-ins the SDK depends on. ```mdx-code-block ``` ```yaml title="docker-compose.yml" showLineNumbers services: # --- Next.js App --- nextjs-app: build: . ports: - "3000:3000" environment: - NODE_ENV=production - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_SERVICE_NAME=sample-nextjs-app # Browser telemetry proxied through /api/otel (no CORS needed) # To bypass proxy: NEXT_PUBLIC_OTEL_ENDPOINT=http://localhost:4318 - NEXT_PUBLIC_OTEL_SERVICE_NAME=sample-nextjs-app-browser - NEXT_PUBLIC_BASE_URL=http://localhost:3000 depends_on: otel-collector: condition: service_started # --- OpenTelemetry Collector --- otel-collector: image: otel/opentelemetry-collector-contrib:latest command: ["--config=/etc/otel/config.yaml"] volumes: - ./config/otel-collector.yaml:/etc/otel/config.yaml:ro ports: - "4317:4317" # OTLP gRPC (server-side) - "4318:4318" # OTLP HTTP (browser-side + server-side) ``` The collector's OTLP endpoint is an internal Compose hostname. The browser never resolves `otel-collector`; it posts to the Next.js app, which forwards from inside the network. ```mdx-code-block ``` #### Server SDK Setup The server module configures all three signals against one OTLP HTTP endpoint and starts the SDK at import time. ```typescript title="src/lib/server-telemetry.ts" showLineNumbers import { NodeSDK } from '@opentelemetry/sdk-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION } from '@opentelemetry/semantic-conventions'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; import { PeriodicExportingMetricReader } from '@opentelemetry/sdk-metrics'; import { BatchLogRecordProcessor, LoggerProvider } from '@opentelemetry/sdk-logs'; import { logs, SeverityNumber } from '@opentelemetry/api-logs'; const OTEL_ENDPOINT = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || 'sample-nextjs-app', [ATTR_SERVICE_VERSION]: '1.0.0', 'deployment.environment': process.env.NODE_ENV || 'development', 'environment': process.env.NODE_ENV || 'development', }); const sdk = new NodeSDK({ resource, // Traces - batch and export via OTLP HTTP spanProcessor: new BatchSpanProcessor( new OTLPTraceExporter({ url: `${OTEL_ENDPOINT}/v1/traces`, }) ), // Metrics - periodic export every 10s metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${OTEL_ENDPOINT}/v1/metrics`, }), exportIntervalMillis: 10_000, }), // Logs - batch and export via OTLP HTTP logRecordProcessors: [ new BatchLogRecordProcessor({ exporter: new OTLPLogExporter({ url: `${OTEL_ENDPOINT}/v1/logs`, }), }), ], // Auto-instrument HTTP, fetch, etc. Disable noisy ones. instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (request) => { const url = request.url || ''; // Skip static assets and health checks return url.startsWith('/_next') || url === '/favicon.ico'; }, }, // Disable noisy low-level instrumentations '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, }), ], }); sdk.start(); ``` The resource sets `environment` alongside `deployment.environment`. The lowercase key is what Scout filters on, and carrying both keeps the resource valid under semantic conventions while staying queryable in the UI. The `ignoreIncomingRequestHook` filter drops `/_next` asset requests. A single page load pulls dozens of chunks from that path, and without the filter they dominate the trace view and the HTTP metric cardinality. Filesystem, DNS, and socket instrumentations are disabled for the same reason: Next.js reads from disk continuously during SSR. #### Browser SDK Setup The browser module registers a `WebTracerProvider` and guards against double initialization, because React strict mode mounts effects twice in development. ```typescript title="src/lib/browser-telemetry.ts" showLineNumbers 'use client'; import { WebTracerProvider } from '@opentelemetry/sdk-trace-web'; import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION } from '@opentelemetry/semantic-conventions'; import { ZoneContextManager } from '@opentelemetry/context-zone'; import { registerInstrumentations } from '@opentelemetry/instrumentation'; import { getWebAutoInstrumentations } from '@opentelemetry/auto-instrumentations-web'; import { trace, SpanStatusCode } from '@opentelemetry/api'; import { onCLS, onLCP, onTTFB, onINP } from 'web-vitals'; let initialized = false; export function initBrowserTelemetry() { if (initialized || typeof window === 'undefined') return; initialized = true; // Use the Next.js API proxy by default - no CORS config needed on collector. // Set NEXT_PUBLIC_OTEL_ENDPOINT to send directly to collector instead (requires CORS). const OTEL_ENDPOINT = process.env.NEXT_PUBLIC_OTEL_ENDPOINT || '/api/otel'; // --- 1. Trace Provider --- const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.NEXT_PUBLIC_OTEL_SERVICE_NAME || 'sample-nextjs-app-browser', [ATTR_SERVICE_VERSION]: '1.0.0', 'deployment.environment': process.env.NODE_ENV || 'development', 'environment': process.env.NODE_ENV || 'development', 'telemetry.sdk.language': 'webjs', }); const traceExporter = new OTLPTraceExporter({ url: `${OTEL_ENDPOINT}/v1/traces`, }); const provider = new WebTracerProvider({ resource, spanProcessors: [new BatchSpanProcessor(traceExporter)], }); provider.register({ contextManager: new ZoneContextManager(), }); // --- 2. Auto-Instrumentations (fetch, XHR, document load, user interaction) --- registerInstrumentations({ instrumentations: [ getWebAutoInstrumentations({ '@opentelemetry/instrumentation-document-load': {}, '@opentelemetry/instrumentation-user-interaction': { eventNames: ['click', 'submit'], }, '@opentelemetry/instrumentation-fetch': { propagateTraceHeaderCorsUrls: [/.*/], }, '@opentelemetry/instrumentation-xml-http-request': { propagateTraceHeaderCorsUrls: [/.*/], }, }), ], }); ``` The `ZoneContextManager` keeps asynchronous work parented under the interaction that started it, so a click span becomes the parent of the `fetch` it triggers rather than a sibling. The `propagateTraceHeaderCorsUrls: [/.*/]` value is correct for a local example but too broad for production - narrow it to your own API origins so `traceparent` is never attached to third-party requests. See [Security Considerations](#security-considerations). Mount it from a client component in the root layout so it starts on hydration: ```tsx title="src/components/TelemetryProvider.tsx" showLineNumbers 'use client'; import { useEffect } from 'react'; import { initBrowserTelemetry } from '@/lib/browser-telemetry'; export default function TelemetryProvider({ children }: { children: React.ReactNode }) { useEffect(() => { initBrowserTelemetry(); }, []); return <>{children}; } ``` ```tsx title="src/app/layout.tsx (excerpt)" showLineNumbers import TelemetryProvider from '@/components/TelemetryProvider'; export default function RootLayout({ children, }: Readonly<{ children: React.ReactNode; }>) { return (
{children}
); } ``` `TelemetryProvider` renders its children unchanged, so it does not alter the component tree. Place it as high in the layout as possible: anything rendered above it produces interactions the SDK has not yet started to observe. ### Production Configuration #### Collector configuration The collector receives from two sources: the Next.js server exporting directly, and browser telemetry arriving through the proxy route. Both use the same OTLP HTTP receiver. ```yaml title="config/otel-collector.yaml" showLineNumbers receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 # CORS not needed - browser telemetry is proxied through /api/otel # If sending directly from browser, uncomment: # cors: # allowed_origins: # - "http://localhost:3000" # allowed_headers: # - "*" processors: batch: timeout: 5s send_batch_size: 512 ``` For a production Scout deployment, replace the local debug exporter with the authenticated Scout exporter and add a memory limiter: ```yaml title="config/otel-collector.yaml (Scout export)" showLineNumbers extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector health_check: endpoint: 0.0.0.0:13133 processors: memory_limiter: limit_mib: 256 check_interval: 1s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14] metrics: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14] logs: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14] ``` Set `compression: gzip`. Browser spans carry long attribute values such as stack traces and full page URLs, and with the proxy route all of it passes through the collector's egress. #### Export cadence and batching Spans and log records buffer in batch processors and flush on a timer; metrics export every `exportIntervalMillis`, set to 10 seconds in the example. For an app with heavy client interaction, raise the browser span processor's `maxQueueSize` and `maxExportBatchSize` so interaction bursts are not dropped between flushes. In the browser, a user can close the tab mid-batch. Flush all providers on `visibilitychange` and `pagehide` so buffered spans are exported before the page unloads. #### Dockerfile A standalone build needs one extra copy step for instrumentation to reach the runtime image. ```dockerfile title="Dockerfile" showLineNumbers FROM node:22-alpine AS base # Install dependencies FROM base AS deps RUN apk add --no-cache libc6-compat WORKDIR /app COPY package.json package-lock.json ./ RUN npm ci # Build the app FROM base AS builder WORKDIR /app COPY --from=deps /app/node_modules ./node_modules COPY . . ENV NEXT_TELEMETRY_DISABLED=1 ENV NODE_ENV=production RUN npm run build # Run the app FROM base AS runner WORKDIR /app ENV NODE_ENV=production ENV NEXT_TELEMETRY_DISABLED=1 RUN addgroup --system --gid 1001 nodejs RUN adduser --system --uid 1001 nextjs COPY --from=builder /app/public ./public RUN mkdir .next RUN chown nextjs:nodejs .next COPY --from=builder --chown=nextjs:nodejs /app/.next/standalone ./ COPY --from=builder --chown=nextjs:nodejs /app/.next/static ./.next/static # Copy the full server build output (includes instrumentation chunks) COPY --from=builder --chown=nextjs:nodejs /app/.next/server ./.next/server USER nextjs EXPOSE 3000 ENV PORT=3000 ENV HOSTNAME="0.0.0.0" CMD ["node", "server.js"] ``` The last `COPY` is required. `output: "standalone"` traces the module graph and emits a minimal bundle, but the compiled instrumentation hook lives in a server chunk that the trace does not reliably include. Without the full `.next/server` directory, the container starts, serves traffic, and emits no telemetry. It logs no error in this state, so check for the startup line described under [Troubleshooting](#no-server-spans-at-all-in-docker-only). ```typescript title="next.config.ts" showLineNumbers import type { NextConfig } from "next"; const nextConfig: NextConfig = { output: "standalone", }; export default nextConfig; ``` ### Framework-Specific Features #### Proxying browser OTLP through an API route Next.js serves an HTTP surface on the same origin as the page, so a catch-all route can forward OTLP to the collector and the browser never makes a cross-origin request. A static SPA has no server on that origin, so the [Angular guide](./angular.md) uses collector CORS instead. ```typescript title="src/app/api/otel/[...signal]/route.ts" showLineNumbers import { NextRequest, NextResponse } from 'next/server'; // Proxy browser OTel data to the collector - avoids CORS configuration. // Browser SDK sends to /api/otel/v1/traces (or /v1/metrics, /v1/logs) // and this route forwards it to the collector's OTLP HTTP endpoint. const COLLECTOR_ENDPOINT = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; export async function POST( request: NextRequest, { params }: { params: Promise<{ signal: string[] }> } ) { const { signal } = await params; const path = signal.join('/'); // e.g. "v1/traces" or "v1/metrics" or "v1/logs" const body = await request.arrayBuffer(); const collectorUrl = `${COLLECTOR_ENDPOINT}/${path}`; const response = await fetch(collectorUrl, { method: 'POST', headers: { 'Content-Type': request.headers.get('Content-Type') || 'application/json', }, body, }); return new NextResponse(response.body, { status: response.status, headers: { 'Content-Type': response.headers.get('Content-Type') || 'application/json', }, }); } ``` The catch-all segment `[...signal]` captures `v1/traces`, `v1/metrics`, and `v1/logs` in one handler, and the body is forwarded as an `ArrayBuffer` so it works for both JSON and protobuf encodings without the route needing to understand either. The proxy removes the `cors` block on the receiver and the preflight round trip before every export, and lets the collector stay on a private network. It also means browser telemetry consumes Next.js server capacity, and the route is a public unauthenticated write path that needs rate limiting. If your collector is already internet-facing, direct export with a scoped CORS allow-list is the simpler option. See [Security Considerations](#security-considerations). #### Capturing SSR error output When an uncaught exception happens during server-side rendering, Next.js catches it and prints it to stdout as `⨯ Error: ...`. It does not rethrow into an active span, so nothing in the SDK observes it and the error does not reach the logs pipeline. Bridge `console` after `sdk.start()` to capture that output as log records. ```typescript title="src/lib/server-telemetry.ts (console bridge)" showLineNumbers // ============================================================ // Console bridge - captures console.log/warn/error as OTel logs. // This catches Next.js internal error output (e.g. "⨯ Error: ...") // that happens when uncaught exceptions occur during SSR. // ============================================================ const loggerProvider = logs.getLoggerProvider() as LoggerProvider; if (loggerProvider) { const otelLogger = loggerProvider.getLogger('console-bridge'); const originalConsoleLog = console.log; const originalConsoleWarn = console.warn; const originalConsoleError = console.error; console.log = (...args: unknown[]) => { originalConsoleLog.apply(console, args); otelLogger.emit({ severityNumber: SeverityNumber.INFO, severityText: 'INFO', body: args.map(String).join(' '), attributes: { 'log.source': 'console.log' }, }); }; console.error = (...args: unknown[]) => { originalConsoleError.apply(console, args); otelLogger.emit({ severityNumber: SeverityNumber.ERROR, severityText: 'ERROR', body: args.map(String).join(' '), attributes: { 'log.source': 'console.error' }, }); }; } ``` Each wrapper calls the original first, so stdout behaviour is unchanged and container log collection keeps working. The `log.source` attribute separates bridged output from records emitted directly through the logger. #### Structured application logs For logs you emit yourself, use the logger directly rather than the bridge. ```typescript title="src/lib/logger.ts" showLineNumbers import { logs, SeverityNumber } from '@opentelemetry/api-logs'; const logger = logs.getLogger('sample-nextjs-app'); export function logInfo(message: string, attributes?: Record) { logger.emit({ severityNumber: SeverityNumber.INFO, severityText: 'INFO', body: message, attributes, }); } export function logError(message: string, attributes?: Record) { logger.emit({ severityNumber: SeverityNumber.ERROR, severityText: 'ERROR', body: message, attributes, }); } ``` Called from an API route, the record is automatically correlated with the enclosing span because the logger reads the active context: ```typescript title="src/app/api/products/route.ts" showLineNumbers import { NextResponse } from 'next/server'; import { logInfo } from '@/lib/logger'; export async function GET() { // Simulate some latency like a real DB/API call await new Promise((resolve) => setTimeout(resolve, 50)); logInfo('Products fetched', { 'products.count': PRODUCTS.length }); return NextResponse.json({ products: PRODUCTS, total: PRODUCTS.length, }); } ``` #### Server Components and SSR fetch A Server Component that fetches during render produces a server-side `fetch` span nested under the route's render span, with no extra code: ```tsx title="src/app/products/page.tsx (excerpt)" showLineNumbers // Server component - fetch happens server-side during SSR // This generates an AppRender.fetch span on the server async function getProducts(): Promise<{ products: Product[]; total: number }> { const baseUrl = process.env.NEXT_PUBLIC_BASE_URL || 'http://localhost:3000'; const res = await fetch(`${baseUrl}/api/products`, { cache: 'no-store' }); return res.json(); } export default async function ProductsPage() { const { products } = await getProducts(); // ... } ``` `cache: 'no-store'` makes the fetch run on every request. With caching enabled, Next.js serves the cached payload and produces no `fetch` span after the first render. #### Browser error capture Uncaught exceptions and unhandled rejections are caught at the window level: ```typescript title="src/lib/browser-telemetry.ts (error handlers)" showLineNumbers function setupErrorHandlers() { const tracer = trace.getTracer('browser-errors'); // Catch uncaught JS errors (e.g., TypeError, ReferenceError thrown in event handlers) window.addEventListener('error', (event) => { tracer.startActiveSpan('browser.error', (span) => { span.setStatus({ code: SpanStatusCode.ERROR, message: event.message }); span.setAttributes({ 'error.type': event.error?.name || 'Error', 'error.message': event.message, 'error.stack': event.error?.stack || '', 'error.filename': event.filename || '', 'error.lineno': event.lineno || 0, 'error.colno': event.colno || 0, 'page.url': window.location.href, 'page.path': window.location.pathname, }); span.end(); }); }); // Catch unhandled promise rejections window.addEventListener('unhandledrejection', (event) => { const reason = event.reason; const message = reason instanceof Error ? reason.message : String(reason); tracer.startActiveSpan('browser.unhandled_rejection', (span) => { span.setStatus({ code: SpanStatusCode.ERROR, message }); span.setAttributes({ 'error.type': reason?.name || 'UnhandledRejection', 'error.message': message, 'page.url': window.location.href, 'page.path': window.location.pathname, }); span.end(); }); }); } ``` React error boundaries need a separate hook. React catches render errors before they reach `window`, so neither listener above fires. Export a helper and call it from the boundary itself: ```typescript title="src/lib/browser-telemetry.ts (error boundary helper)" showLineNumbers export function reportErrorBoundary(error: Error, componentStack?: string) { const tracer = trace.getTracer('browser-errors'); tracer.startActiveSpan('browser.react_error_boundary', (span) => { span.setStatus({ code: SpanStatusCode.ERROR, message: error.message }); span.setAttributes({ 'error.type': error.name || 'ReactError', 'error.message': error.message, 'error.stack': error.stack || '', 'error.component_stack': componentStack || '', 'page.url': typeof window !== 'undefined' ? window.location.href : '', 'page.path': typeof window !== 'undefined' ? window.location.pathname : '', }); span.end(); }); } ``` ```tsx title="src/app/error-demo/error.tsx" showLineNumbers 'use client'; import { useEffect } from 'react'; import { reportErrorBoundary } from '@/lib/browser-telemetry'; export default function ErrorDemoError({ error, reset, }: { error: Error & { digest?: string }; reset: () => void; }) { useEffect(() => { // Report this error boundary catch to OTel as a browser span reportErrorBoundary(error); }, [error]); return (

React Error Boundary Caught a Crash

Error: {error.message}

); } ``` Repeat the same `useEffect` in `src/app/global-error.tsx` to cover crashes in the root layout, which segment-level boundaries cannot catch. ### Custom Instrumentation #### Core Web Vitals The example records each vital as a short-lived span carrying the value and Google's rating bucket: ```typescript title="src/lib/browser-telemetry.ts (web vitals)" showLineNumbers function setupWebVitals() { const tracer = trace.getTracer('web-vitals'); function reportVital(metric: { name: string; value: number; rating: string; id: string }) { tracer.startActiveSpan(`web-vital.${metric.name}`, (span) => { span.setAttributes({ 'web_vital.name': metric.name, 'web_vital.value': metric.value, 'web_vital.rating': metric.rating, // "good", "needs-improvement", or "poor" 'web_vital.id': metric.id, 'page.url': window.location.href, 'page.path': window.location.pathname, }); span.end(); }); } onCLS(reportVital); onLCP(reportVital); onTTFB(reportVital); onINP(reportVital); } ``` Spans keep each vital attached to the session that produced it, which helps when investigating a single slow page. For fleet-wide trends, histogram instruments aggregate into p75 and p95 without storing every event; the [Angular guide](./angular.md#core-web-vitals-as-metrics) shows that variant. #### Manual spans around business logic Auto-instrumentation covers HTTP and transport. Domain operations need an explicit span: ```typescript title="Manual span in an API route" import { trace, SpanStatusCode } from '@opentelemetry/api'; const tracer = trace.getTracer('checkout'); export async function POST(request: Request) { return tracer.startActiveSpan('checkout.process', async (span) => { try { const order = await request.json(); span.setAttributes({ 'order.item_count': order.items.length, 'order.currency': order.currency, }); const result = await processOrder(order); span.setAttribute('order.id', result.id); return Response.json(result); } catch (err) { span.setStatus({ code: SpanStatusCode.ERROR, message: err instanceof Error ? err.message : String(err), }); throw err; } finally { span.end(); } }); } ``` End the span in a `finally` block. An unended span holds its slot in the processor queue and never exports, so a throw path that skips `span.end()` leaks spans. #### Custom metrics Counters and histograms come from a meter, which the Node SDK registers globally: ```typescript title="Custom counter in an API route" import { metrics } from '@opentelemetry/api'; const meter = metrics.getMeter('sample-nextjs-app'); const ordersPlaced = meter.createCounter('orders.placed', { description: 'Count of successfully placed orders', }); const orderValue = meter.createHistogram('order.value', { description: 'Order value distribution', unit: 'INR', }); export async function POST(request: Request) { const order = await request.json(); const result = await processOrder(order); ordersPlaced.add(1, { 'order.channel': order.channel }); orderValue.record(result.total, { 'order.channel': order.channel }); return Response.json(result); } ``` Keep attribute values bounded. `order.channel` has a handful of values and is safe as a label; `order.id` is unbounded and would multiply the time series count by the number of orders. #### Returning the trace id to the client Return the trace id in a response header so a user-reported problem can be looked up by id: ```typescript title="Trace id in a response header" import { trace } from '@opentelemetry/api'; export async function GET() { const span = trace.getActiveSpan(); const traceId = span?.spanContext().traceId ?? ''; return Response.json( { status: 'ok' }, { headers: { 'X-Trace-Id': traceId } }, ); } ``` ### Running Your Application ```mdx-code-block ``` ```bash # Start the collector stack first docker compose up -d otel-collector jaeger # Then run Next.js against it npm run dev ``` The dev server reads `OTEL_EXPORTER_OTLP_ENDPOINT` from `.env`, defaulting to `http://localhost:4318`. ```mdx-code-block ``` ```bash docker compose up --build ``` This starts the Next.js app on `http://localhost:3000`, the collector on 4317 and 4318, and Jaeger on `http://localhost:16686`. ```mdx-code-block ``` #### Generating telemetry ```bash # Server-side SSR + fetch spans curl http://localhost:3000/products # API route span with a correlated INFO log curl http://localhost:3000/api/products # API route span with ERROR status and a correlated ERROR log curl -X POST http://localhost:3000/api/error ``` Browser spans require loading the app in a browser. Open `http://localhost:3000`, navigate to **Products** and click "Fetch Products (Client-Side)", then visit **Error Demo** and trigger each of the four error types. #### Expected span tree A client-side fetch from the products page produces this shape across both services: ```text documentLoad [browser] └── resourceFetch (x N) [browser] click ClientFetchButton [browser] └── HTTP GET /api/products [browser] └── GET /api/products [server] <- linked via traceparent └── (log) "Products fetched" [server] ``` A server-rendered page load produces this shape: ```text GET /products [server] └── AppRender /products [server] └── HTTP GET /api/products [server] └── GET /api/products [server] ``` #### Verifying in the collector With the `debug` exporter enabled, confirm both services are reporting: ```bash docker compose logs otel-collector | grep -E 'service.name|Span #' | head -20 ``` You should see two distinct `service.name` values: `sample-nextjs-app` for server telemetry and `sample-nextjs-app-browser` for browser telemetry. ### Troubleshooting #### No server spans at all, in Docker only The instrumentation chunk is missing from the standalone image. `output: "standalone"` traces the module graph, and the compiled register hook is not always included. Confirm the Dockerfile copies the full server build: ```dockerfile COPY --from=builder --chown=nextjs:nodejs /app/.next/server ./.next/server ``` Without it the container starts and serves traffic, and logs no error. Check for the startup line the server module prints: ```bash docker compose logs nextjs-app | grep 'OTel' # [OTel] Server-side instrumentation initialized - exporting to http://otel-collector:4318 ``` #### Browser telemetry returns 404 on `/api/otel/v1/traces` The catch-all route is missing or misnamed. The directory must be `src/app/api/otel/[...signal]/route.ts` with the square brackets and the three dots - `[signal]` alone matches a single segment and will not catch `v1/traces`. Confirm the browser exporter URL resolves as expected: with `NEXT_PUBLIC_OTEL_ENDPOINT` unset it should post to `/api/otel/v1/traces`. #### Browser telemetry blocked by CORS You have set `NEXT_PUBLIC_OTEL_ENDPOINT` to the collector origin, which switches off the proxy and exports directly. Either unset it to go back through `/api/otel`, or enable CORS on the receiver for the app's origin: ```yaml receivers: otlp: protocols: http: endpoint: 0.0.0.0:4318 cors: allowed_origins: - "http://localhost:3000" allowed_headers: - "*" ``` #### SSR errors appear in the terminal but not in the logs pipeline Next.js printed the error to stdout instead of rethrowing it into a span. Check that the console bridge is installed **after** `sdk.start()` - if it runs before, `logs.getLoggerProvider()` returns the no-op provider and every bridged record is discarded silently. Records that arrive correctly carry a `log.source` attribute of `console.error`. #### Browser and server spans land in different traces The `traceparent` header is not reaching the server. Check `propagateTraceHeaderCorsUrls` covers the request URL. If the browser posts cross-origin, the server's CORS policy must also list `traceparent` and `tracestate` in its allowed request headers, otherwise the browser strips them before the request is sent. Same-origin requests to your own API routes, as in this example, are unaffected. #### Every page load floods the trace view with asset spans The `ignoreIncomingRequestHook` filter is not applied. Next.js requests dozens of chunks from `/_next` per page load, and each becomes a span without it: ```typescript '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (request) => { const url = request.url || ''; return url.startsWith('/_next') || url === '/favicon.ico'; }, }, ``` ### Security Considerations - **The proxy route is an unauthenticated write path**: `/api/otel` accepts POSTs from anyone who can reach your app and forwards them to your collector. Rate-limit it, and consider requiring a session cookie before forwarding. If your collector is already internet-facing with a scoped CORS allow-list, direct export is the safer choice. - **Narrow `propagateTraceHeaderCorsUrls`**: the example uses `[/.*/]`, which attaches `traceparent` to every outbound request including third-party analytics and CDN calls. In production, list your own API origins explicitly so trace context never leaks off-site. - **No PII in attributes**: browser spans carry `page.url`, which includes query strings. Strip or redact any parameter that can hold a token, email, or session id before it becomes an attribute. - **Stack traces are attributes here**: `error.stack` and `error.component_stack` reach your telemetry backend in full. Confirm that is acceptable under your data policy, and that access to the backend is scoped accordingly. - **Never use `*` for `allowed_origins`**: if you do switch to direct export, an open allow-list lets any site on the internet post telemetry into your collector. - **Transport security**: terminate TLS in front of the collector in production so telemetry is encrypted in transit. ### Performance Considerations #### Expected impact | Metric | Impact | Notes | | --- | --- | --- | | **Server latency** | +0.5-2ms per request | Span creation and context propagation | | **Server CPU** | +2-5% | During export operations | | **Server memory** | +15-40MB | SDK plus span and log buffers | | **Client bundle** | +90-130KB gzipped | Web SDK, auto-instrumentations, web-vitals | | **Network** | +1-5KB per trace | OTLP HTTP with gzip | #### Tuning notes - **Filter `/_next` requests**: asset requests outnumber page and API requests by roughly an order of magnitude on a typical page load, so this filter has the largest effect on server-side span volume. - **Load the browser SDK from a client component**: it adds to first-load JavaScript. Mounting it from a client component, as shown above, keeps it out of the root layout module graph so it does not block hydration. - **Restrict interaction events**: the example limits `instrumentation-user-interaction` to `click` and `submit`. Adding `mousemove` or `scroll` produces spans faster than most backends can consume them. - **Account for proxy traffic**: every browser export becomes a request the Next.js server handles. Measure that load before choosing the proxy over direct export at high traffic. - **Export runs off the request path**: batch processors and the periodic metric reader keep export latency out of user-facing response times. ### FAQ #### How do I instrument both the browser and the server in one Next.js app? Use two SDKs with two service names. The server side loads the Node SDK from the `register()` hook in `instrumentation.ts`, which Next.js calls once per runtime before any request is handled. The browser side loads the web SDK from a client component mounted in the root layout, so it starts on hydration. They emit under different service names and link through the W3C `traceparent` header on `fetch` calls. #### Why does `instrumentation.ts` check `NEXT_RUNTIME`? Next.js calls `register()` once for every server runtime, including Edge. The Node SDK depends on Node.js built-ins that do not exist in the Edge runtime, so importing it there throws at startup. Guarding with `process.env.NEXT_RUNTIME === 'nodejs'` and using a dynamic import keeps the Node SDK out of the Edge bundle entirely. #### Can I avoid configuring CORS on the collector for Next.js browser telemetry? Yes. Add a catch-all API route at `/api/otel/[...signal]` that forwards the OTLP request body to the collector, and point the browser exporter at `/api/otel` instead of the collector origin. The browser then posts same-origin, so there is no preflight and no `cors` block on the OTLP HTTP receiver. The collector never needs to be reachable from the public internet. #### Why are my Next.js SSR errors missing from OpenTelemetry logs? Next.js catches uncaught server-side exceptions itself and prints them to stdout rather than rethrowing them into a span. Nothing in the OTel SDK observes stdout, so the error never reaches the logs pipeline. Wrapping `console.log`, `console.warn`, and `console.error` after `sdk.start()` and re-emitting each call through the OTel logger captures that output as log records. #### How much overhead does OpenTelemetry add to a Next.js app? Server-side, expect roughly 0.5-2ms added latency per request, 2-5% CPU during export, and 15-40MB of resident memory for the SDK and its span buffers. Browser-side, the web SDK adds roughly 90-130KB gzipped to the client bundle. All signals export off the request path through batch processors and a periodic metric reader, so export cost does not appear in user-facing latency. #### Why do I see two services for one Next.js app? The server SDK reports as `sample-nextjs-app` and the browser SDK as `sample-nextjs-app-browser`. They have different lifecycles, resource attributes, and failure modes. Separate names let you filter browser telemetry out of backend dashboards, and the two still join through a shared trace id. #### How do I capture React error boundary crashes with OpenTelemetry? A `window.onerror` listener does not see them, because React catches render errors before they reach the window. Export a reporting helper from your browser telemetry module and call it from a `useEffect` inside the App Router `error.tsx` and `global-error.tsx` boundaries. The helper opens a span, sets an ERROR status, and attaches the error message, stack, and component stack. #### Should I record Core Web Vitals as spans or metrics in Next.js? Metric histograms aggregate better, because Core Web Vitals are scored as fleet-wide distributions at p75 and a histogram lets the backend compute percentiles without storing every event. Recording them as spans, as this example does, is simpler to wire up and keeps each vital attached to the session that produced it, which is useful when debugging one slow page rather than tracking a fleet trend. #### Why is my Next.js browser span in a different trace than my API route span? The `traceparent` header is not reaching the server. Check that the request URL matches `propagateTraceHeaderCorsUrls` in the fetch instrumentation config. If the browser posts to a different origin than the page, the server's CORS policy must also allow the `traceparent` and `tracestate` request headers, otherwise the browser strips them before the request leaves. #### Do I need `output: "standalone"` for OpenTelemetry in a Next.js image? Standalone output is not required, but if you use it you must copy the full `.next/server` directory into the runtime image alongside the standalone bundle. The instrumentation hook is compiled into a separate server chunk that the standalone trace does not always include, so omitting it produces an image that starts cleanly and emits nothing. #### Does OpenTelemetry work with the Next.js Edge runtime? Not with the Node SDK. The Edge runtime is a restricted JavaScript environment without the Node.js built-ins the SDK requires. Guard the register hook so the Node SDK loads only under the `nodejs` runtime, and instrument Edge routes with the OpenTelemetry API alone, or move them to the Node runtime if you need full auto-instrumentation. #### Which Next.js version does this guide target? The example runs Next.js 16.3 with React 19.2 on Node.js 22. The instrumentation hook has been stable since Next.js 15, so the server-side setup applies unchanged from 15 onward. The browser-side setup has no Next.js version dependency beyond the App Router and client components. #### How is this different from the Next.js server-side guide? The [Next.js guide](./nextjs.md) covers a server-only application with MongoDB and BullMQ background jobs, and is the right starting point if your API tier is the concern. This guide covers the browser and server together in one app, with the OTLP proxy route, browser error capture, and Web Vitals that a server-only setup does not need. ### What's Next? - Narrow `propagateTraceHeaderCorsUrls` to your own API origins before deploying. - Add rate limiting or session checks to the `/api/otel` proxy route. - Add release and version attributes to browser error spans so crashes can be triaged per deploy. - Move Core Web Vitals from spans to histogram instruments if you are tracking fleet-wide page performance rather than debugging single sessions. - Add a database tier and confirm its spans nest under the API route spans this guide already produces. ### Complete Example The full project - Next.js 16 App Router with browser and server instrumentation, a pre-configured collector, and Jaeger for local viewing - is available at [base-14/examples/nodejs/nextjs-fullstack-otel](https://github.com/base-14/examples/tree/main/nodejs/nextjs-fullstack-otel). ```text nextjs-fullstack-otel/ ├── docker-compose.yml ├── Dockerfile # standalone build + .next/server copy ├── next.config.ts # output: "standalone" ├── instrumentation.ts # register hook, NEXT_RUNTIME guard ├── config/otel-collector.yaml # OTLP in, traces+metrics+logs pipelines └── src/ ├── lib/ │ ├── server-telemetry.ts # NodeSDK + console bridge │ ├── browser-telemetry.ts # WebTracerProvider, errors, Web Vitals │ └── logger.ts # structured OTel log helpers ├── components/TelemetryProvider.tsx # mounts browser SDK on hydration └── app/ ├── layout.tsx # wraps tree in TelemetryProvider ├── api/otel/[...signal]/route.ts # OTLP proxy - removes collector CORS ├── api/products/route.ts # API route + correlated INFO log ├── api/error/route.ts # error paths for span status demo ├── products/ # SSR fetch + client fetch demo ├── error-demo/ # four browser error types └── global-error.tsx # root-layout crash boundary ``` Run it: ```bash git clone https://github.com/base-14/examples cd examples/nodejs/nextjs-fullstack-otel docker compose up --build # open http://localhost:3000, then http://localhost:16686 for traces ``` base14 Scout receives these browser spans, server spans, and logs over OTLP and correlates them for [end-to-end application performance monitoring](https://base14.io/scout/apm). ### References - [Next.js instrumentation guide](https://nextjs.org/docs/app/guides/instrumentation). - [Next.js OpenTelemetry guide](https://nextjs.org/docs/app/guides/open-telemetry). - [OpenTelemetry JavaScript](https://opentelemetry.io/docs/languages/js/). - [OpenTelemetry browser instrumentation](https://opentelemetry.io/docs/languages/js/getting-started/browser/). - [auto-instrumentations-web](https://www.npmjs.com/package/@opentelemetry/auto-instrumentations-web). - [web-vitals](https://github.com/GoogleChrome/web-vitals). - [W3C Trace Context](https://www.w3.org/TR/trace-context/). ### Related Guides - [Next.js instrumentation](./nextjs.md) - server-side Next.js with MongoDB and BullMQ background jobs. - [Angular instrumentation](./angular.md) - the same three-signal browser setup on a standalone SPA, exporting directly to the collector with CORS. - [React browser instrumentation](./react.md) - browser RUM through the Scout React SDK. - [Node.js instrumentation](./nodejs.md) - the Node SDK underneath the server side of this guide. - [Custom JavaScript browser instrumentation](../custom-instrumentation/javascript-browser.md): manual browser spans and metrics beyond the auto-instrumentations. --- ## Next.js OpenTelemetry - Direct OTLP to Scout, No Collector ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## Next.js :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction This is the default path for instrumenting a **server-side Next.js app** with base14 Scout. The Next.js Node runtime authenticates to Scout itself and exports OTLP over the public internet. There is no collector container, no sidecar, and no private network hop. That matters most on a serverless host. On Vercel, Netlify Functions, AWS Lambda or Cloud Run, there is nowhere to put a collector next to the app and no private network to reach a shared one over. The application process is the only thing that exists, so it holds the credential and does the exporting. The same code runs unchanged on a long-lived `next start` process, a container, or a VM. Nothing here is Vercel-specific: the deployment environment and build version come from your own variables, and the Vercel equivalents are only used as a fallback when you have not set them. :::tip TL;DR Put the Node SDK behind Next's `instrumentation.ts` register hook, guarded on `NEXT_RUNTIME`, `NEXT_PHASE` and the presence of credentials. Authenticate with OAuth2 client credentials against your tenant's realm and pass `scoutAuthHeaders` (an **async function**, not an object) as the exporter's `headers`, so every export carries a fresh bearer. Keep provider handles on `globalThis`; module scope does not survive Next's bundle split. Call `flush()` from `after()` in every route that produces telemetry, because a frozen function's batch timers never fire. Use **delta** temporality for metrics. List the OTel packages in `serverExternalPackages`. ::: ### Who This Guide Is For This documentation is designed for: - **Next.js developers** shipping App Router apps who want traces, metrics and logs in Scout without running any additional infrastructure. - **Teams on serverless platforms** (Vercel, Lambda, Cloud Run) where a collector sidecar is not an option. - **Platform engineers** who want one credential per app rather than a collector fleet to operate, patch and monitor. - **SRE and DevOps** who need to know exactly where telemetry is dropped when credentials are absent, and why an unconfigured deployment must stay silent. ### When to Use This Instead of a Collector | Situation | Use | | --- | --- | | Serverless or PaaS with no sidecar | **This guide** - direct OTLP to Scout | | One app, no existing collector fleet | **This guide** | | You want a credential per app, rotated with the app | **This guide** | | Many services on one network already | [Collector setup](./nextjs.md) | | You need tail sampling, redaction or routing | [Collector setup](./nextjs.md) | | You need host, container or k8s metrics too | [Collector setup](./nextjs.md) | | Browser RUM alongside server traces | [Next.js Full-Stack](./nextjs-fullstack.md) | A collector is still the right answer when telemetry from many services needs common processing before it leaves your network. For a single Next.js app it adds a hop without adding any processing. The general tradeoffs are covered in [Direct to Scout Backend](../../collector-setup/sending-telemetry-directly-to-scout-backend.md). ### Overview #### Prerequisites Before starting, ensure you have: - **Node.js 22 or later**. - **Next.js 15.1 or later** using the App Router. The `instrumentation.ts` register hook is stable from 15 and `after()` from 15.1. This guide is written against **Next.js 16**. - **Scout tenant credentials**: OTLP endpoint, token URL, client ID and client secret. [Contact the base14 team](mailto:support@base14.io) if you do not have them. - **Your service name registered in the tenant.** Scout silently discards telemetry from an unregistered `service.name`, and both the exporter and the backend report success while it happens. #### Compatibility Matrix | Component | Version | Notes | | --- | --- | --- | | Next.js | 16.1 | App Router; register hook stable since 15 | | React | 19.2 | | | Node.js | 22 | Edge runtime is excluded by design | | `@opentelemetry/api` | 1.9.1 | | | `@opentelemetry/sdk-trace-node` | 2.10.0 | | | `@opentelemetry/sdk-metrics` | 2.10.0 | | | `@opentelemetry/sdk-logs` | 0.221.0 | | | `@opentelemetry/auto-instrumentations-node` | 0.79.0 | | | `@opentelemetry/exporter-*-otlp-http` | 0.221.0 | Async headers verified on this version | | `@opentelemetry/semantic-conventions` | 1.43.0 | `ATTR_*` constants | :::warning Do not downgrade the exporter packages `@opentelemetry/otlp-exporter-base` **0.221.0** accepts `headers` as an async function and awaits it inside every send - `http-exporter-transport.js` calls `const headers = await this._parameters.headers();`. Exporters that predate that read `headers` once at construction, so the first token is frozen into the exporter and every export 401s the moment it expires, silently. Verify this before downgrading, and pin the exporter packages to one release train. ::: #### Instrumented Components `getNodeAutoInstrumentations()` patches these at `require()` time, and Next.js contributes its own spans on top once a tracer provider is registered. | Component | Source | What you get | | --- | --- | --- | | Incoming HTTP requests | `instrumentation-http` | Server spans with method, route, status code | | Route handlers and server components | Next.js built-in | `executing api route`, `resolve page components`, `render route` | | Server actions | Next.js built-in | One span per action invocation | | Outbound `fetch()` and `http` calls | `instrumentation-http`, `instrumentation-undici` | Client spans with `traceparent` propagated downstream | | PostgreSQL, MySQL, MongoDB, Redis | `instrumentation-pg`, `-mysql2`, `-mongodb`, `-ioredis` | Query spans with obfuscated statements | | Prisma, Drizzle | Their own OTel integrations | Enable separately; not part of the auto set | | Winston, Pino, Bunyan | `instrumentation-winston`, `-pino`, `-bunyan` | Log records with `trace_id` and `span_id` attached | | Filesystem, DNS, net | disabled here | Too noisy on serverless; see the pipeline module | | V8 heap, GC, event loop | disabled here | Turn on for a long-lived server | Anything not in this list needs a manual span. See [Custom Instrumentation](#custom-instrumentation). #### Architecture ```text NEXT.JS NODE RUNTIME SCOUT service.name = your-app instrumentation.ts register() --> startTelemetry() | +-- NodeTracerProvider --+ +-- LoggerProvider --+--> getScoutToken() +-- MeterProvider --+ client_credentials | --> id.b14.dev route handlers | after(() => flush()) ---------------------+--> OTLP/HTTP + gzip --> otel..base14.io //otlp ``` The token is fetched once per process, cached, refreshed on age, and attached per export. Nothing exports on a timer; `flush()` triggers each export. ### Installation Install the Node SDK, the auto-instrumentation bundle and the three OTLP/HTTP exporters. All of them are runtime dependencies; the server bundle loads them on every cold start. ```mdx-code-block ``` ```bash showLineNumbers title="Install OpenTelemetry for Next.js" npm install --save \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-trace-node \ @opentelemetry/sdk-trace-base \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/instrumentation \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/otlp-exporter-base \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` ```mdx-code-block ``` ```bash showLineNumbers title="Install OpenTelemetry for Next.js" pnpm add \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-trace-node \ @opentelemetry/sdk-trace-base \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/instrumentation \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/otlp-exporter-base \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` ```mdx-code-block ``` ```bash showLineNumbers title="Install OpenTelemetry for Next.js" yarn add \ @opentelemetry/api \ @opentelemetry/api-logs \ @opentelemetry/sdk-trace-node \ @opentelemetry/sdk-trace-base \ @opentelemetry/sdk-metrics \ @opentelemetry/sdk-logs \ @opentelemetry/instrumentation \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/otlp-exporter-base \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` ```mdx-code-block ``` Pin the four `0.221.0` packages together. They share an internal transport contract, and mixing release trains is what reintroduces the frozen-header bug described above. ### Configuration #### Environment Variables | Variable | Secret | Purpose | | --- | --- | --- | | `SCOUT_ENDPOINT` | no | OTLP base, no trailing slash. Signals append `/v1/traces` etc. | | `SCOUT_TOKEN_URL` | no | Your realm's token endpoint | | `SCOUT_CLIENT_ID` | no | OAuth2 client | | `SCOUT_CLIENT_SECRET` | **yes** | OAuth2 client secret | | `SCOUT_AUDIENCE` | no | Defaults to `b14collector` | | `OTEL_SERVICE_NAME` | no | Must match the service registered in your tenant | | `DEPLOYMENT_ENVIRONMENT` | no | Deployment environment. Falls back to `VERCEL_ENV`, then `NODE_ENV` | | `SERVICE_VERSION` | no | Build identifier. Falls back to `VERCEL_GIT_COMMIT_SHA`, then `dev` | Supply them however your host does secrets. The application code reads `process.env` and does not care which of these you use. ```mdx-code-block ``` ```bash showLineNumbers title=".env.local" SCOUT_ENDPOINT=https://otel..base14.io//otlp SCOUT_TOKEN_URL=https://id.b14.dev/realms//protocol/openid-connect/token SCOUT_CLIENT_ID= SCOUT_CLIENT_SECRET= OTEL_SERVICE_NAME=your-app ``` ```mdx-code-block ``` ```bash showLineNumbers title="Set the same values on a Vercel project" vercel env add SCOUT_ENDPOINT production vercel env add SCOUT_TOKEN_URL production vercel env add SCOUT_CLIENT_ID production vercel env add SCOUT_CLIENT_SECRET production vercel env add OTEL_SERVICE_NAME production # Pull them back into .env.local for local runs. vercel env pull .env.local ``` `VERCEL_ENV` and `VERCEL_GIT_COMMIT_SHA` are injected by the platform, so the `environment()` and `serviceVersion()` helpers below need nothing extra here. ```mdx-code-block ``` ```yaml showLineNumbers title="docker-compose.yml" services: web: build: . ports: - '3000:3000' environment: SCOUT_ENDPOINT: https://otel..base14.io//otlp SCOUT_TOKEN_URL: https://id.b14.dev/realms//protocol/openid-connect/token SCOUT_CLIENT_ID: ${SCOUT_CLIENT_ID} SCOUT_CLIENT_SECRET: ${SCOUT_CLIENT_SECRET} OTEL_SERVICE_NAME: your-app # No VERCEL_ENV here, so set the deployment environment yourself. DEPLOYMENT_ENVIRONMENT: production SERVICE_VERSION: ${GIT_SHA:-dev} ``` ```mdx-code-block ``` These are the same four values a collector puts in its `oauth2client` extension, so an app instrumented this way and a collector in the same tenant rotate together. Put real values in `.env.local` (which `create-next-app` gitignores) and in your host's environment settings. Never in `.env`, and never in a commit. A build-time check that fails when the secret's literal value appears in a client bundle is worth adding; one is shown under [Security Considerations](#security-considerations). :::danger Never prefix any of these with `NEXT_PUBLIC_` `NEXT_PUBLIC_` values are inlined into the client bundle at build time. A `NEXT_PUBLIC_SCOUT_CLIENT_SECRET` is a published credential. The browser in this design needs no endpoint, tenant or credential at all - it talks to same-origin relative paths only. Add a build-time grep for `NEXT_PUBLIC_` in your telemetry directory if you want that enforced rather than remembered. ::: :::warning If the secret contains a `$`, escape it as `\$` Next expands `$VAR` references when it loads `.env` files. An unescaped `$` in a client secret is silently truncated or mangled: the file looks correct, and the realm answers `invalid_client`. The token module below names this cause in its warning, because nothing in the error says it. ::: #### Connection Settings ```typescript showLineNumbers title="src/lib/telemetry/config.ts" // Every read is inside a function, never at module scope. Module-scope reads // are evaluated when the module is first imported, which during `next build` // is the prerender pass rather than a request. Reading per call keeps one // build artifact correct when it is promoted between environments. export type ScoutConfig = { /** OTLP base, no trailing slash. Signals append /v1/traces etc. */ endpoint: string; tokenUrl: string; clientId: string; clientSecret: string; audience: string; }; /** * Null when unconfigured, which must stay a clean no-op rather than an error. * A fork, a credential-less CI build and a plain `next dev` all land here, and * none of them should see a failed token request on every page load. */ export function scoutConfig(): ScoutConfig | null { const endpoint = process.env.SCOUT_ENDPOINT; const tokenUrl = process.env.SCOUT_TOKEN_URL; const clientId = process.env.SCOUT_CLIENT_ID; const clientSecret = process.env.SCOUT_CLIENT_SECRET; if (!endpoint || !tokenUrl || !clientId || !clientSecret) return null; return { endpoint: endpoint.replace(/\/+$/, ''), tokenUrl, clientId, clientSecret, // Scout passes this as a form field on the token request, not a scope. audience: process.env.SCOUT_AUDIENCE || 'b14collector', }; } export function serviceName(): string { return process.env.OTEL_SERVICE_NAME || 'nextjs-app'; } /** * DEPLOYMENT_ENVIRONMENT first, then VERCEL_ENV, and NODE_ENV only as a floor. * * NODE_ENV only takes production/development/test and is "production" on * PREVIEW deploys too, so deriving the environment from it files every preview * under production and quietly corrupts the environment filter on every * dashboard. Set DEPLOYMENT_ENVIRONMENT on any host that is not Vercel. */ export function environment(): string { return ( process.env.DEPLOYMENT_ENVIRONMENT || process.env.VERCEL_ENV || process.env.NODE_ENV || 'development' ); } export function serviceVersion(): string { const explicit = process.env.SERVICE_VERSION; if (explicit) return explicit; // Only the commit SHA is shortened. An explicit version is used verbatim, // so a tag like 1.2.3-rc.1 survives intact. return (process.env.VERCEL_GIT_COMMIT_SHA || 'dev').slice(0, 7); } ``` #### Resource Attributes ```typescript showLineNumbers title="src/lib/telemetry/resource.ts" import { resourceFromAttributes } from '@opentelemetry/resources'; import type { Resource } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; import { environment, serviceName, serviceVersion } from './config'; /** Separates tiers of one service: server, browser, worker. */ export const ATTR_SERVICE_ROLE = 'service.role'; export type ServiceRole = 'browser' | 'server'; function base(role: ServiceRole): Record { const env = environment(); return { [ATTR_SERVICE_NAME]: serviceName(), [ATTR_SERVICE_VERSION]: serviceVersion(), [ATTR_SERVICE_ROLE]: role, // Both keys, same value. Scout's UI and its CLI --environment flag filter // on the bare key; the OTel semantic convention is the dotted one. Setting // both means a dashboard filter written either way works. environment: env, 'deployment.environment': env, }; } export function serverResource(region?: string): Resource { const attrs = base('server'); // service.instance.id is a resource attribute, so a per-request or // per-visitor value partitions every metric time series. Use something // bounded - a region, a pod name - or leave it unset. if (region) attrs['service.instance.id'] = region; attrs['os.type'] = process.platform; return resourceFromAttributes(attrs); } export function browserResource(): Resource { return resourceFromAttributes(base('browser')); } ``` #### OAuth2 Token Manager Scout's realm issues short-lived tokens - five minutes is typical. A warm serverless instance comfortably outlives that, so a token fetched once at startup **will** be expired while the instance is still serving requests. The cache below refreshes on age. The cache is ordinary module state, not `globalThis`. Next's bundle split can give the route handlers their own copy, which costs one extra token fetch per copy and nothing else. Only the provider handles have to be shared, because those carry the queued spans. ```typescript showLineNumbers title="src/lib/telemetry/token.ts" // OAuth2 client-credentials against the tenant's realm. This is the collector's // oauth2client extension, ported, because there is no collector here. // // Deliberately not OTEL_EXPORTER_OTLP_HEADERS: that is parsed once when the // exporter is constructed, so a rotated token silently becomes a 401 that // nothing surfaces. import { scoutConfig } from './config'; type Cached = { token: string; expiresAt: number }; // Module scope, so the cache is shared by every request this instance // serves. A fresh instance pays one token fetch; a warm one pays none. let cached: Cached | null = null; let inflight: Promise | null = null; let warnedInvalidClient = false; /** Refresh this long before the token actually expires. */ const SKEW_MS = 60_000; async function fetchToken(): Promise { const cfg = scoutConfig(); if (!cfg) return null; try { const res = await fetch(cfg.tokenUrl, { method: 'POST', headers: { 'content-type': 'application/x-www-form-urlencoded' }, body: new URLSearchParams({ grant_type: 'client_credentials', client_id: cfg.clientId, client_secret: cfg.clientSecret, audience: cfg.audience, }), // Capped so a slow identity provider cannot delay a page. The batch is // dropped instead. signal: AbortSignal.timeout(4000), }); if (!res.ok) { const body = await res.text().catch(() => ''); // Warned once per process. This cause is non-obvious: Next // expands $VAR references inside .env files, so a client secret // containing a literal $ arrives mangled unless escaped as \$. if (!warnedInvalidClient && body.includes('invalid_client')) { warnedInvalidClient = true; console.warn( '[telemetry] Scout rejected the client credentials (invalid_client). ' + "If SCOUT_CLIENT_SECRET contains a '$', escape it as '\\$' in .env " + 'files: Next expands $VAR references when loading them.', ); } return null; } const json = (await res.json()) as { access_token?: string; expires_in?: number; }; if (!json.access_token) return null; const ttlMs = (json.expires_in ?? 300) * 1000; cached = { token: json.access_token, expiresAt: Date.now() + ttlMs }; return cached.token; } catch { // Network error, timeout, malformed JSON. Return null rather than // throwing; the caller treats it as an export failure. return null; } } /** * A valid bearer, or null if telemetry should be dropped. * * Single-flight: traces, logs and metrics all flush at the same moment in * `after()`, and would otherwise each open their own token request on a cold * start. */ export async function getScoutToken(): Promise { if (cached && Date.now() < cached.expiresAt - SKEW_MS) return cached.token; if (!inflight) { inflight = fetchToken().finally(() => { inflight = null; }); } const fresh = await inflight; if (fresh) return fresh; // A failed refresh falls back to the cached token while it is still valid. // Inside the skew window it has not actually expired, so a transient // identity-provider failure does not immediately cost telemetry. if (cached && Date.now() < cached.expiresAt) return cached.token; return null; } /** * Headers factory for the OTLP exporters. * * @opentelemetry/otlp-exporter-base 0.221+ accepts `headers` as * `() => Promise>` and awaits it inside every send, so a * rotating token needs no exporter wrapper and no instance swapping. * * Upstream contract: functions passed to the exporter must not throw. * Returning {} on failure yields an unauthenticated request that Scout answers * with 401, which the exporter treats as a normal export failure. */ export async function scoutAuthHeaders(): Promise> { const token = await getScoutToken(); return token ? { Authorization: `Bearer ${token}` } : {}; } /** Test seam: drop the cache so the next call re-authenticates. */ export function resetScoutToken(): void { cached = null; inflight = null; } ``` #### Exporters ```typescript showLineNumbers title="src/lib/telemetry/exporters.ts" import { CompressionAlgorithm } from '@opentelemetry/otlp-exporter-base'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-http'; import { AggregationTemporalityPreference, OTLPMetricExporter, } from '@opentelemetry/exporter-metrics-otlp-http'; import { scoutConfig } from './config'; import { scoutAuthHeaders } from './token'; /** Shared exporter options. `signal` is the OTLP path segment. */ function opts(signal: 'traces' | 'logs' | 'metrics') { const cfg = scoutConfig(); return { url: `${cfg?.endpoint ?? ''}/v1/${signal}`, // Passing the function itself is what gives per-export token refresh. // An object here would freeze the first token into the exporter. headers: scoutAuthHeaders, compression: CompressionAlgorithm.GZIP, // Shorter than the platform's own limit, so a stalled export cannot be // what holds an invocation open at flush time. timeoutMillis: 5000, }; } export function traceExporter(): OTLPTraceExporter { return new OTLPTraceExporter(opts('traces')); } export function logExporter(): OTLPLogExporter { return new OTLPLogExporter(opts('logs')); } /** * Delta temporality, which is not the default. * * A serverless platform freezes a function between requests and discards it * without warning. Under the default cumulative temporality each new instance * restarts its counters at zero, the backend sees a monotonic series jump * backwards on every cold start, and those resets read as enormous negative * rates. Delta reports only what happened since the last collection, which is * the only temporality that survives this execution model. */ export function metricExporter(): OTLPMetricExporter { return new OTLPMetricExporter({ ...opts('metrics'), temporalityPreference: AggregationTemporalityPreference.DELTA, }); } ``` :::note No `insecure_skip_verify` equivalent Some sample collector configs disable TLS verification, including on the hop that carries the credential. There is no reason to do that here, and no option above turns it off. ::: #### The Telemetry Pipeline This module creates the three providers, installs the auto-instrumentations and exposes `flush()`. Two details carry the setup: the provider handles live on `globalThis`, and `flush()` drains every provider. Both are marked in the comments below. ```typescript showLineNumbers title="src/lib/telemetry/server.ts" import { NodeTracerProvider } from '@opentelemetry/sdk-trace-node'; import { BatchSpanProcessor } from '@opentelemetry/sdk-trace-base'; import type { ReadableSpan, Span, SpanProcessor, } from '@opentelemetry/sdk-trace-base'; import { metrics, type Context } from '@opentelemetry/api'; import { registerInstrumentations } from '@opentelemetry/instrumentation'; import { BatchLogRecordProcessor, LoggerProvider } from '@opentelemetry/sdk-logs'; import { MeterProvider, PeriodicExportingMetricReader, } from '@opentelemetry/sdk-metrics'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { logs } from '@opentelemetry/api-logs'; import { logExporter, metricExporter, traceExporter } from './exporters'; import { serverResource } from './resource'; type Registry = { tracerProvider?: NodeTracerProvider; serverLogs?: LoggerProvider; meterProvider?: MeterProvider; started: boolean; }; /** * Keep the provider handles on globalThis. * * Next compiles instrumentation.ts into a different bundle from the route * handlers, so each gets its own copy of this module and its own module-level * variables. As module state, startTelemetry() populates one copy while * flush() reads another, empty one: `started` is false at flush time and * nothing is ever exported. Spans still dribble out under `next start`, * because the OTel global API is process-wide, so the bug does not show up in * development. */ const SLOT = Symbol.for('app.telemetry.registry'); function registry(): Registry { const g = globalThis as typeof globalThis & { [SLOT]?: Registry }; if (!g[SLOT]) g[SLOT] = { started: false }; return g[SLOT]; } /** * Drops spans for the telemetry endpoints themselves. * * ignoreIncomingRequestHook on instrumentation-http does not cover these: * Next.js emits its own spans ("POST /api/otel", "executing api route", * "resolve page components") from its built-in OpenTelemetry support the * moment a tracer provider is registered, and that support does not consult * the HTTP instrumentation's filters. */ class FilteringSpanProcessor implements SpanProcessor { constructor(private readonly inner: SpanProcessor) {} private noisy(span: ReadableSpan): boolean { const route = String( span.attributes['next.route'] ?? span.attributes['http.route'] ?? '', ); return span.name.includes('/api/otel') || route.includes('/api/otel'); } onStart(span: Span, parentContext: Context): void { // Delegated, even though BatchSpanProcessor's onStart is a no-op today. // A processor swapped in later may well need it. this.inner.onStart(span, parentContext); } onEnd(span: ReadableSpan): void { if (!this.noisy(span)) this.inner.onEnd(span); } forceFlush(): Promise { return this.inner.forceFlush(); } shutdown(): Promise { return this.inner.shutdown(); } } export function startTelemetry(): void { const reg = registry(); if (reg.started) return; reg.started = true; // Own the MeterProvider rather than letting NodeSDK build one: flush() needs // a handle to force-collect it. reg.meterProvider = new MeterProvider({ resource: serverResource(), readers: [ new PeriodicExportingMetricReader({ exporter: metricExporter(), // Deliberately long. flush() drives collection; this interval is only // a fallback for a long-lived process. exportIntervalMillis: 60_000, exportTimeoutMillis: 10_000, }), ], }); metrics.setGlobalMeterProvider(reg.meterProvider); const tracerProvider = new NodeTracerProvider({ resource: serverResource(), spanProcessors: [ new FilteringSpanProcessor(new BatchSpanProcessor(traceExporter())), ], }); tracerProvider.register(); reg.tracerProvider = tracerProvider; const serverLogs = new LoggerProvider({ resource: serverResource(), processors: [new BatchLogRecordProcessor({ exporter: logExporter() })], }); logs.setGlobalLoggerProvider(serverLogs); reg.serverLogs = serverLogs; registerInstrumentations({ instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const url = req.url ?? ''; return ( url.startsWith('/_next') || url.startsWith('/api/otel') || url === '/favicon.ico' ); }, // Without this, the exporter's own POST to Scout is traced, and // each exported span produces another one. ignoreOutgoingRequestHook: (opts) => { const host = typeof opts === 'string' ? opts : String(opts.hostname ?? opts.host ?? ''); // b14.dev is the identity host and base14.io is ingest. Both // are requests this pipeline makes on its own behalf. return host.includes('base14.io') || host.includes('b14.dev'); }, }, '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, // ~20 series per collection of V8 heap sizes, GC durations and event // loop utilisation. On a platform that discards the instance between // requests, these describe a process that no longer exists by the time // anyone reads the chart. Enable it on a long-lived server. '@opentelemetry/instrumentation-runtime-node': { enabled: false }, }), ], }); } /** * Push everything to Scout before the instance freezes. * * Drain every provider, not only the tracer. Draining the tracer alone lets * server spans arrive while logs and metrics are silently dropped. * * Never rejects. A flush failure must not turn into a 500 on a page. */ export async function flush(): Promise { const reg = registry(); if (!reg.started) return; const jobs: Promise[] = []; if (reg.tracerProvider) jobs.push(reg.tracerProvider.forceFlush().catch(() => {})); if (reg.serverLogs) jobs.push(reg.serverLogs.forceFlush().catch(() => {})); if (reg.meterProvider) jobs.push(reg.meterProvider.forceFlush().catch(() => {})); await Promise.all(jobs); } ``` #### The Register Hook ```typescript showLineNumbers title="src/instrumentation.ts" // Next's server bootstrap hook. Three guards, each for a different failure. // // 1. NEXT_RUNTIME. The Node SDK cannot run on the Edge runtime. The import is // dynamic so the SDK is not even resolved at module-evaluation time and // therefore never enters the Edge bundle. // // 2. NEXT_PHASE. register() runs whenever a Next server bootstraps, including // the prerender pass of `next build`. Without this guard the SDK starts on // the build machine, fetches a token from CI, and emits a burst of // build-time spans indistinguishable from real traffic in the tenant. // // 3. Credentials. A fork, or CI without secrets, must be a silent no-op rather // than a failed token request on every request. Guard on the whole config, // not the secret alone: with a secret but no SCOUT_ENDPOINT the exporters // are built with a relative URL and throw at construction, which turns the // promised silent no-op into an error on every boot. // // Do Not Track belongs in the browser, not here: this hook has no request // context to read it from. export async function register(): Promise { if (process.env.NEXT_RUNTIME !== 'nodejs') return; if (process.env.NEXT_PHASE === 'phase-production-build') return; const { scoutConfig } = await import('./lib/telemetry/config'); if (!scoutConfig()) return; const { startTelemetry } = await import('./lib/telemetry/server'); startTelemetry(); } ``` #### Next.js Configuration ```typescript showLineNumbers title="next.config.ts" import type { NextConfig } from 'next'; const nextConfig: NextConfig = { // The OpenTelemetry Node SDK must stay external to the server bundle. Its // instrumentations work by patching modules at require() time, so bundling // them rewrites the very module identities they hook and the patches // silently attach to nothing. This produces no error and no spans. serverExternalPackages: [ '@opentelemetry/sdk-trace-node', '@opentelemetry/instrumentation', '@opentelemetry/auto-instrumentations-node', '@opentelemetry/exporter-trace-otlp-http', '@opentelemetry/exporter-logs-otlp-http', '@opentelemetry/exporter-metrics-otlp-http', ], }; export default nextConfig; ``` ### Export Timing Call `flush()` from `after()` in every route that produces telemetry. A serverless platform freezes the function the instant it responds, so a `BatchSpanProcessor`'s timer never fires and a `PeriodicExportingMetricReader`'s interval never elapses. Nothing exports on schedule. `after()` runs once the response is on the wire, and is the only window in which an export can start. ```typescript showLineNumbers title="src/app/api/example/route.ts" import { after } from 'next/server'; import { trace } from '@opentelemetry/api'; import { flush } from '@/lib/telemetry/server'; export const runtime = 'nodejs'; // force-dynamic so process.env is read per request rather than frozen into the // build, which is what lets one build artifact be promoted between // environments. export const dynamic = 'force-dynamic'; export async function GET(): Promise { const span = trace.getActiveSpan(); span?.setAttribute('app.handler', 'example'); const body = await doWork(); // The only window before the instance freezes. after(async () => { await flush(); }); return Response.json(body); } ``` Add this to **every route that produces telemetry**. On a long-lived server (`next start`, a container, a VM) the batch processors work normally and `after()` is simply harmless, so the same code is correct in both places. :::info Statically prerendered pages produce no server spans If most of your routes are static, a near-empty trace view is the expected outcome, not a symptom. Only dynamic routes, route handlers and server actions run per request. ::: ### Production Configuration #### Batch Tuning The defaults are tuned for a long-lived process. On a host that freezes the instance the batch never fills and never times out, so the numbers that matter are the queue caps rather than the intervals. ```typescript showLineNumbers title="src/lib/telemetry/server.ts (batch options)" new BatchSpanProcessor(traceExporter(), { // A frozen instance never reaches this timer. It only does work on a // long-lived server, where 5s keeps the trace view close to live. scheduledDelayMillis: 5_000, // Cap the queue rather than the batch. A burst that overruns this is // dropped in memory, which bounds heap growth in a container with a hard // memory limit. maxQueueSize: 2_048, maxExportBatchSize: 512, // Below the exporter's own 5s, so a stalled export cannot stack. exportTimeoutMillis: 4_000, }); ``` | Setting | Serverless | Long-lived server | | --- | --- | --- | | `scheduledDelayMillis` | Irrelevant; `flush()` drives export | 5000 | | `maxQueueSize` | 2048 | 2048, raise if you see drops | | `maxExportBatchSize` | 512 | 512 | | `exportIntervalMillis` (metrics) | 60000 fallback only | 15000 to 30000 | | `after(() => flush())` | Required on every route | Harmless, leave it in | Compression is already on for all three signals (`CompressionAlgorithm.GZIP` in the exporter options). OTLP payloads are highly repetitive, so gzip typically cuts them by more than half for a few milliseconds of CPU per export. #### Dockerfile For a container or VM rather than a serverless host, build the standalone output and keep the OTel packages unbundled. ```dockerfile showLineNumbers title="Dockerfile" FROM node:22-alpine AS deps WORKDIR /app COPY package.json package-lock.json ./ RUN npm ci FROM node:22-alpine AS builder WORKDIR /app COPY --from=deps /app/node_modules ./node_modules COPY . . # serverExternalPackages keeps @opentelemetry/* out of the bundle; standalone # output copies them into .next/standalone/node_modules instead. RUN npm run build FROM node:22-alpine AS runner WORKDIR /app ENV NODE_ENV=production RUN addgroup -g 1001 -S nodejs && adduser -S nextjs -u 1001 COPY --from=builder /app/public ./public COPY --from=builder --chown=nextjs:nodejs /app/.next/standalone ./ COPY --from=builder --chown=nextjs:nodejs /app/.next/static ./.next/static USER nextjs EXPOSE 3000 CMD ["node", "server.js"] ``` On a long-lived server, turn the runtime metrics back on: ```typescript showLineNumbers title="src/lib/telemetry/server.ts (long-lived server)" '@opentelemetry/instrumentation-runtime-node': { enabled: true }, ``` #### Multi-Service Tracing Context propagates over the wire as a `traceparent` header, and `instrumentation-http` and `instrumentation-undici` both handle it. No code change is needed for a Next.js route that calls another instrumented service: the outbound span is a child of the incoming request, and the downstream service continues the same trace. ```typescript showLineNumbers title="src/app/api/orders/route.ts" import { after } from 'next/server'; import { flush } from '@/lib/telemetry/server'; export const runtime = 'nodejs'; export const dynamic = 'force-dynamic'; export async function GET(): Promise { // traceparent is injected automatically. The billing service sees this // request as part of the same trace. const billing = await fetch('https://billing.internal/v1/summary').then((r) => r.json(), ); after(async () => { await flush(); }); return Response.json(billing); } ``` Give every service its own `OTEL_SERVICE_NAME` and the same `DEPLOYMENT_ENVIRONMENT`, so a trace crosses services while dashboard filters still separate environments. ### Framework-Specific Features #### Route Handlers and Server Components Next.js emits its own spans as soon as a tracer provider is registered, so route handlers, page renders and component resolution are covered without any code in the handler itself. | Span name | Emitted for | | --- | --- | | `GET /api/orders` | The incoming request, from `instrumentation-http` | | `executing api route (app) /api/orders/route` | The route handler body | | `resolve page components` | App Router component resolution | | `render route (app) /orders` | Server rendering of a dynamic route | | `start response` | Time to first byte | Set `NEXT_OTEL_VERBOSE=1` to add Next's more granular internal spans. Leave it off in production; the extra spans are only useful while debugging. #### Server Actions Server actions are traced by the same built-in support. Add attributes to the active span rather than creating a new one, so the action stays attached to the request that triggered it. ```typescript showLineNumbers title="src/app/orders/actions.ts" 'use server'; import { after } from 'next/server'; import { trace } from '@opentelemetry/api'; import { flush } from '@/lib/telemetry/server'; export async function submitOrder(formData: FormData): Promise { const span = trace.getActiveSpan(); span?.setAttribute('app.action', 'submitOrder'); // A bounded value. Never the customer id, and never the raw form body. span?.setAttribute('app.order.currency', String(formData.get('currency'))); await persist(formData); after(async () => { await flush(); }); } ``` #### Middleware Is Not Instrumented Next.js middleware runs on the Edge runtime, where the Node SDK cannot run. That is why `register()` returns early unless `NEXT_RUNTIME` is `nodejs`. A request that is rewritten or redirected in middleware produces no span until it reaches a Node route. If you need visibility there, propagate a header from middleware and read it in the route handler, where you can put it on the active span: ```typescript showLineNumbers title="src/middleware.ts" import { NextResponse, type NextRequest } from 'next/server'; export function middleware(request: NextRequest): NextResponse { // Set this on the request headers rather than the response. Only request // headers reach the route handler; a response header would not. const headers = new Headers(request.headers); headers.set('x-mw-rule', request.nextUrl.pathname.split('/')[1] ?? ''); return NextResponse.next({ request: { headers } }); } ``` Then read it where a span already exists. `headers()` is async from Next.js 15: ```typescript showLineNumbers title="src/app/[section]/page.tsx" import { headers } from 'next/headers'; import { trace } from '@opentelemetry/api'; export default async function Page() { const rule = (await headers()).get('x-mw-rule'); if (rule) trace.getActiveSpan()?.setAttribute('app.mw.rule', rule); return
...
; } ``` #### Logs Correlated to Traces `instrumentation-pino` and `instrumentation-winston` are both in the auto set. They inject `trace_id` and `span_id` into every record and forward records to the global `LoggerProvider`, which is why `startTelemetry()` registers one. No separate log exporter wiring is needed. ```typescript showLineNumbers title="src/lib/logger.ts" import pino from 'pino'; // No transport and no OTLP config here. The instrumentation picks these // records up and routes them through the LoggerProvider set in // startTelemetry(), so they land in Scout with trace context attached. export const logger = pino({ level: process.env.LOG_LEVEL ?? 'info', // Redact before the record is ever created. The log bridge forwards // whatever pino produces. redact: ['req.headers.authorization', 'req.headers.cookie', '*.password'], }); ``` A log line emitted inside a request handler carries the trace id, so clicking through from a slow span to its logs works without any correlation id of your own. #### Database Queries `instrumentation-pg`, `-mysql2`, `-mongodb` and `-ioredis` are all in the auto set and produce query spans with the statement obfuscated. Prisma and Drizzle are not: they ship their own OpenTelemetry integrations and have to be enabled separately. Register Prisma in the same `registerInstrumentations()` call as the auto set, inside `startTelemetry()`. Registering it at module scope in your database module would leave the ordering up to import order, and an instrumentation that loads before the tracer provider exists produces nothing. ```typescript showLineNumbers title="src/lib/telemetry/server.ts (Prisma)" import { PrismaInstrumentation } from '@prisma/instrumentation'; // Inside startTelemetry(), replacing the registerInstrumentations() call // shown earlier. registerInstrumentations({ instrumentations: [ getNodeAutoInstrumentations({ // ... the options shown earlier }), new PrismaInstrumentation(), ], }); ``` ### Custom Instrumentation Auto-instrumentation covers the request, the query and the outbound call. Anything specific to your domain needs a span or a metric you write yourself. #### Manual Spans ```typescript showLineNumbers title="src/lib/checkout.ts" import { SpanStatusCode, trace } from '@opentelemetry/api'; // Module scope is fine for a tracer: the OTel global API is process-wide, so // this resolves to the real provider once startTelemetry() has run. Only the // provider handles need to live on globalThis. const tracer = trace.getTracer('app.checkout', '1.0.0'); export async function processCheckout(cartId: string, itemCount: number) { return tracer.startActiveSpan('checkout.process', async (span) => { try { // Use bounded values. itemCount is a small integer. cartId has // unbounded cardinality on a metric, but is fine on a span. span.setAttribute('app.cart.id', cartId); span.setAttribute('app.cart.item_count', itemCount); const result = await chargeAndFulfil(cartId); span.setAttribute('app.checkout.outcome', result.outcome); return result; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: 'checkout failed' }); throw error; } finally { // Always end the span. An unended span is never exported. span.end(); } }); } ``` #### Custom Metrics ```typescript showLineNumbers title="src/lib/metrics.ts" import { metrics } from '@opentelemetry/api'; const meter = metrics.getMeter('app.checkout', '1.0.0'); export const checkoutsCompleted = meter.createCounter('app.checkouts.completed', { description: 'Checkouts that reached a terminal success state', unit: '{checkout}', }); export const checkoutDuration = meter.createHistogram('app.checkout.duration', { description: 'End-to-end checkout latency', unit: 'ms', }); ``` ```typescript showLineNumbers title="Recording a measurement" import { checkoutDuration, checkoutsCompleted } from '@/lib/metrics'; const started = performance.now(); const result = await processCheckout(cartId, itemCount); // Attributes here become metric dimensions. Keep them to a closed set: // 'outcome' has three possible values, 'payment_method' has five. A cart id // or a user id here would create one time series per customer. checkoutsCompleted.add(1, { outcome: result.outcome, payment_method: result.paymentMethod, }); checkoutDuration.record(performance.now() - started, { outcome: result.outcome }); ``` :::warning Metric attributes are not span attributes Every distinct combination of metric attribute values is a separate time series, stored and billed for as long as it is retained. A cart id is fine on a span. On a counter it creates one time series per cart. Collapse to route patterns and closed enumerations before a value becomes a metric dimension. ::: #### Trace ID in Responses Returning the trace id lets a support ticket or a client-side error report point straight at the trace. ```typescript showLineNumbers title="src/app/api/checkout/route.ts" import { after } from 'next/server'; import { trace } from '@opentelemetry/api'; import { flush } from '@/lib/telemetry/server'; export const runtime = 'nodejs'; export const dynamic = 'force-dynamic'; export async function POST(request: Request): Promise { const body = await request.json(); const result = await processCheckout(body.cartId, body.itemCount); const ctx = trace.getActiveSpan()?.spanContext(); after(async () => { await flush(); }); return Response.json(result, { headers: ctx ? // A real span id, not zeroes: an all-zero span id is invalid under // the W3C trace context spec. Server-Timing is readable from the // browser via PerformanceObserver with no extra CORS configuration // on a same-origin response. { 'Server-Timing': `traceparent;desc="00-${ctx.traceId}-${ctx.spanId}-01"`, } : {}, }); } ``` ### Running Your Application #### Development ```bash showLineNumbers title="Run locally against your tenant" # .env.local supplies the four Scout variables. npm run dev ``` `next dev` is a long-lived process, so the batch processors export on their own timers and you do not need `after()` to see spans. This is why a missing `flush()` does not show up locally. With no credentials in the environment the register hook returns immediately and the app runs untouched. #### Production ```bash showLineNumbers title="Build and run" npm run build npm run start ``` The build emits no telemetry: `register()` returns early on `phase-production-build`. Telemetry starts with the first request to the running server. #### Expected Span Hierarchy A single request to an instrumented route handler produces roughly this: ```text GET /api/checkout (instrumentation-http, SERVER) └── executing api route (app) /api/checkout/route (Next.js built-in) └── checkout.process (your manual span) ├── pg.query:INSERT orders (instrumentation-pg) └── POST payments.internal (instrumentation-undici, CLIENT) └── ... continues in the payments service ``` #### Verify the Setup Work through these three in order. Each one checks a different layer. ##### 1. Check the credentials directly ```bash showLineNumbers title="Fetch a token" TOKEN=$(curl -s -X POST "$SCOUT_TOKEN_URL" \ -d grant_type=client_credentials \ -d client_id="$SCOUT_CLIENT_ID" \ -d client_secret="$SCOUT_CLIENT_SECRET" \ -d audience=b14collector | jq -r .access_token) [ -n "$TOKEN" ] && [ "$TOKEN" != null ] && echo "token ok" || echo "no token" ``` An `invalid_client` here is a credential problem, not an instrumentation problem. Check the `$`-escaping note above first. Load the variables from `.env.local` (`set -a; source .env.local; set +a`) rather than typing the secret on the command line, where it lands in shell history. ##### 2. Check the ingest path ```bash showLineNumbers title="Send an empty payload" curl -i -X POST "$SCOUT_ENDPOINT/v1/traces" \ -H "Authorization: Bearer $TOKEN" \ -H 'content-type: application/json' \ -d '{"resourceSpans":[]}' ``` Expect `200` with `{"partialSuccess":{}}`. Without the bearer, expect `401`. The same holds for `/v1/logs` and `/v1/metrics`. ##### 3. Check the app ```bash showLineNumbers npm run build && npm run start curl -s localhost:3000/api/example > /dev/null ``` Then look for your `service.name` in Scout. If the two curl checks pass and the app produces nothing, work through the troubleshooting table below. ### Browser Telemetry The browser holds no credential in this design. If you want RUM alongside these server traces, keep it that way: have the browser export to a same-origin route that attaches the bearer server-side. First, a small guard module. The limiter is a cost cap, not a security boundary: a serverless platform runs many instances and freezes them arbitrarily, so the bucket is per instance and per lifetime. It stops one looping tab or a naive script from turning into unbounded ingest. ```typescript showLineNumbers title="src/lib/telemetry/guard.ts" const WINDOW_MS = 60_000; const MAX_PER_WINDOW = 120; /** Bounded so the map cannot itself become the memory leak. */ const MAX_TRACKED = 5000; const hits = new Map(); export function rateLimit(key: string): boolean { const now = Date.now(); const entry = hits.get(key); if (!entry || now > entry.resetAt) { if (hits.size > MAX_TRACKED) hits.clear(); hits.set(key, { count: 1, resetAt: now + WINDOW_MS }); return true; } entry.count++; return entry.count <= MAX_PER_WINDOW; } /** Best-effort client identity. Most hosts set x-forwarded-for at the edge. */ export function clientKey(req: Request): string { const fwd = req.headers.get('x-forwarded-for'); return (fwd?.split(',')[0] ?? req.headers.get('x-real-ip') ?? 'unknown').trim(); } ``` Then the route itself: ```typescript showLineNumbers title="src/app/api/otel/[...signal]/route.ts" import { after } from 'next/server'; import { scoutConfig } from '@/lib/telemetry/config'; import { clientKey, rateLimit } from '@/lib/telemetry/guard'; import { getScoutToken } from '@/lib/telemetry/token'; import { flush } from '@/lib/telemetry/server'; export const runtime = 'nodejs'; export const dynamic = 'force-dynamic'; /** Spans can be larger than a metrics batch, but not unboundedly so. */ const MAX_BYTES = 512 * 1024; /** The two OTLP/HTTP encodings. Anything else is not a span payload. */ const CONTENT_TYPES = new Set(['application/json', 'application/x-protobuf']); export async function POST( request: Request, { params }: { params: Promise<{ signal: string[] }> }, ): Promise { const { signal } = await params; // Traces only. Proxying /v1/logs and /v1/metrics would let anyone write // arbitrary log bodies and arbitrary metric attributes into the tenant. if ((signal ?? []).join('/') !== 'v1/traces') { return new Response(null, { status: 404 }); } // Unconfigured: accept and discard, so a fork or a local run behaves the // same as production from the browser's point of view. const cfg = scoutConfig(); if (!cfg) return new Response(null, { status: 202 }); if (!rateLimit(clientKey(request))) return new Response(null, { status: 429 }); const contentType = (request.headers.get('content-type') ?? '').split(';')[0]; if (!CONTENT_TYPES.has(contentType)) return new Response(null, { status: 415 }); // Checked before AND after reading: content-length is client-supplied. const declared = Number(request.headers.get('content-length') ?? 0); if (declared > MAX_BYTES) return new Response(null, { status: 413 }); let body: ArrayBuffer; try { body = await request.arrayBuffer(); } catch { return new Response(null, { status: 400 }); } if (body.byteLength > MAX_BYTES) return new Response(null, { status: 413 }); const token = await getScoutToken(); if (!token) return new Response(null, { status: 202 }); // Relayed byte for byte. The browser stamped service.role=browser on its // resource, and re-resourcing it here would erase what separates browser // spans from server spans in the tenant. try { await fetch(`${cfg.endpoint}/v1/traces`, { method: 'POST', headers: { 'content-type': contentType, authorization: `Bearer ${token}` }, body, // Telemetry must never be what holds a function open. signal: AbortSignal.timeout(5000), }); } catch { // Dropped. Never surface an upstream failure to the browser. } after(async () => { await flush(); }); // Scout's response is deliberately not echoed: that would turn this route // into a probe for whether the tenant and credential are valid. return new Response(null, { status: 202 }); } /** Only POST is valid on this route. A GET is a scanner or a misconfiguration. */ export function GET(): Response { return new Response(null, { status: 405 }); } ``` Because the browser posts same-origin, `connect-src 'self'` in an existing Content-Security-Policy already permits it. No Scout origin, tenant id or credential is added to the CSP or to the client bundle. :::warning This is an unauthenticated write path `/api/otel` accepts POSTs from anyone who can reach your app. The route above rate-limits, caps the body, allow-lists the content type and rejects anything that is not `v1/traces`. Keep all four. If you later proxy logs or metrics too, validate every value that can become a metric attribute against a closed set on the server first; the browser cannot be trusted to bound its own cardinality, and one unbounded attribute degrades the whole tenant. ::: For the full browser side - web SDK setup, `traceparent` propagation, Core Web Vitals and error boundaries - see [Next.js Full-Stack](./nextjs-fullstack.md). ### Troubleshooting | Symptom | Cause | Fix | | --- | --- | --- | | Nothing arrives, no errors anywhere | `service.name` is not registered in the tenant. Scout discards it silently and both the exporter and backend report success | Check the tenant's service list before touching code | | Works on `next start`, nothing in production | `flush()` is not called from `after()`, so the frozen instance never exports | Add `after(() => flush())` to every telemetry-producing route | | Spans arrive, logs and metrics do not | `flush()` drains only the tracer provider | Drain every provider you created | | `flush()` runs but `started` is false | Provider handles are in module scope, and the route bundle has a different copy from `instrumentation.ts` | Keep the registry on `globalThis` behind a `Symbol.for` | | All exports 401 after a few minutes | Exporter packages below 0.221, so `headers` was read once at construction | Upgrade the exporter packages; pass `headers` as a function | | Realm answers `invalid_client` | A `$` in the client secret was expanded by Next when loading `.env` | Escape it as `\$` | | Build-time spans in the tenant | Missing `NEXT_PHASE` guard, so the SDK started during prerender | Return early on `phase-production-build` | | No spans at all, no error | OTel packages were bundled, so the require-time patches attached to nothing | Add them to `serverExternalPackages` | | Metric rates spike hugely negative | Cumulative temporality plus cold starts resetting counters | Use `AggregationTemporalityPreference.DELTA` | | Trace view is mostly the `/api/otel` route | Next emits its own spans for that route regardless of HTTP instrumentation filters | Add the `FilteringSpanProcessor` | | Every export produces another span | The exporter's own POST is being traced | Set `ignoreOutgoingRequestHook` for the Scout and identity hosts | | Edge runtime build errors | The Node SDK was statically imported | Import it dynamically, inside the `NEXT_RUNTIME` guard | ### Security Considerations - **The credential lives in one place.** Only the Node runtime reads `SCOUT_CLIENT_SECRET`. No `NEXT_PUBLIC_` prefix, ever, and no endpoint or tenant id in the client bundle. - **Enforce that at build time.** The rule is a one-word prefix and easy to miss in review, and breaking it ships the secret to every visitor and every CDN cache. Fail the build on either signal: ```javascript showLineNumbers title="scripts/check-no-secrets.mjs" import { existsSync, globSync, readFileSync } from 'node:fs'; let failed = false; // 1. No NEXT_PUBLIC_ anywhere in the telemetry code. The browser is // configured by same-origin relative paths and needs none. for (const file of globSync('src/lib/telemetry/*.ts')) { readFileSync(file, 'utf8').split('\n').forEach((line, i) => { const t = line.trim(); if (!t.startsWith('//') && t.includes('NEXT_PUBLIC_')) { console.error(`${file}:${i + 1} NEXT_PUBLIC_ in telemetry code`); failed = true; } }); } // 2. No literal secret in a built client bundle. Read from the environment, // never hardcoded: this script is committed. const secret = process.env.SCOUT_CLIENT_SECRET; if (existsSync('.next/static') && secret && secret.length >= 12) { for (const file of globSync('.next/static/**/*.js')) { if (readFileSync(file, 'utf8').includes(secret)) { console.error(`${file} CONTAINS A CREDENTIAL`); failed = true; } } } if (failed) process.exit(1); ``` Wire it into `prebuild` so `next build` cannot succeed past it. - **The token is never logged.** The only warning the token module prints is the `invalid_client` hint, and it prints no request or response body. Keep it that way. A token written to a log is stored for the life of that log. - **Unconfigured is a clean no-op.** With any of the four Scout variables missing, `scoutConfig()` returns null, the register hook returns immediately and the routes accept and discard. A fork, a preview build without secrets, and a plain `next dev` all behave identically and silently. - **Rate-limit and size-cap any public write path** you expose for browser telemetry, and proxy traces only. - **Do not disable TLS verification** on the hop that carries the credential. - **Keep high-cardinality values off metric attributes.** Collapse paths to route patterns (`/blog/[slug]`, not `/blog/why-otel`) before they become attributes; the full path can still go on a span or log record. ### Performance Considerations - **Cold start**: one token fetch, cached per instance. `instrumentation-fs` is disabled because its patching is expensive enough to show up in cold-start time. - **Per export**: `scoutAuthHeaders()` is a cache read in the common case, not a network call. - **Payload size**: gzip is on for every signal. - **Request latency**: unchanged. `after()` runs once the response is on the wire, and every timeout (4s token, 5s export) is set so telemetry can never be what holds an invocation open. - **Runtime metrics are off by default** here. On a long-lived server, turn `instrumentation-runtime-node` back on - that is where it earns its ~20 series per collection. ### FAQ #### Do I need an OpenTelemetry Collector to send Next.js telemetry to Scout? No. The Next.js Node runtime can authenticate to Scout with OAuth2 client credentials and export OTLP directly, which is what this guide sets up. A collector is worth adding when several services need shared processing - tail sampling, redaction, routing - or when you also want host and container metrics. For a single app on a serverless platform, it has nowhere to run and nothing to add. #### Why do my spans disappear in production but work locally? Because a serverless platform freezes the function the moment it responds, so the batch processor's export timer never fires. Locally, `next start` is a long-lived process, the timers elapse normally, and everything looks correct. The fix is to call `flush()` from `after()` in every route that produces telemetry, which is the only window between the response being sent and the instance being frozen. #### Why does the OTLP exporter start returning 401 after a few minutes? The exporter captured a single bearer token at construction and the token expired. Scout's realm issues short-lived tokens - five minutes is typical - so a token fetched at startup expires while the instance is still serving. Pass `headers` as an async function rather than an object, and use `@opentelemetry/otlp-exporter-base` 0.221 or later, where the transport awaits that function on every send. #### Should the browser export OTLP directly to Scout? No, because it would need a credential to do so, and anything the browser has is public. Have the browser POST to a same-origin route in your own app that attaches the bearer server-side. That also removes the CORS preflight, needs no new origin in your CSP, and keeps your tenant id out of the client bundle. #### Why must OpenTelemetry packages be listed in serverExternalPackages? Because the instrumentations work by patching modules at `require()` time. Bundling them rewrites the very module identities they hook, so the patches attach to nothing. This fails silently: there is no error, there are simply no spans, which makes it one of the harder setup mistakes to diagnose. #### Why delta temporality for metrics on serverless? Because each new instance restarts its counters at zero. Under the default cumulative temporality the backend sees a monotonic series jump backwards on every cold start and reads those resets as enormous negative rates. Delta reports only what happened since the last collection, so a discarded instance takes nothing with it. #### Does the SDK run during `next build`? It will, unless you guard against it. `register()` runs whenever a Next server bootstraps, and that includes the prerender pass of `next build` - so the SDK starts on the build machine, fetches a token from CI, and emits build-time spans that are indistinguishable from real traffic once they are in the tenant. Return early when `process.env.NEXT_PHASE === 'phase-production-build'`. #### How much overhead does OpenTelemetry add to a Next.js app? Expect single-digit milliseconds on the request path and roughly 30 to 60MB of additional heap. The auto-instrumentation patches add about 1 to 3ms per request across HTTP and database spans, and the export itself costs nothing on the request path because `after()` runs once the response is on the wire. The larger cost is cold start: loading and patching the SDK adds roughly 150 to 300ms, which is why `instrumentation-fs` and the runtime metrics are disabled in this setup. #### Can I use this on the Edge runtime or in middleware? No. The OpenTelemetry Node SDK needs Node APIs that the Edge runtime does not provide, which is why `register()` returns early unless `NEXT_RUNTIME` is `nodejs`. Middleware therefore produces no spans. Move the work you need to see into a Node route handler, or pass a header from middleware and record it on the span there. #### Do I need to call flush() in every route? Yes, in every route that produces telemetry, if you deploy to a serverless host. The platform freezes the instance the moment the response is sent, so nothing that is still sitting in a batch queue will ever leave. On a long-lived server the batch processors handle it and `after(() => flush())` is a harmless no-op, which is what lets the same code run correctly in both places. #### What happens if Scout is unreachable or the credentials are wrong? Telemetry is dropped and your application keeps serving. Every failure path in the token module and the exporters swallows its error: a failed token fetch returns null, `scoutAuthHeaders()` returns an empty object, and the resulting 401 is handled by the exporter as an ordinary export failure. The token fetch is capped at 4 seconds and each export at 5, so a slow or dead endpoint cannot hold a request or an invocation open. ### What's Next? - [Next.js Full-Stack](./nextjs-fullstack.md) - add browser RUM, Core Web Vitals and error boundaries on top of this server setup. - [Next.js (Collector)](./nextjs.md) - the same app exporting to a collector you run, with Docker and Docker Compose examples. - [Direct to Scout Backend](../../collector-setup/sending-telemetry-directly-to-scout-backend.md) is the language-agnostic version of this pattern. - [Custom instrumentation for Node.js](../custom-instrumentation/javascript-node.md) covers business spans and metrics beyond what auto-instrumentation captures. - [Create your first dashboard](../../../guides/create-your-first-dashboard.md) turns these signals into charts and alerts. ### Complete Example The telemetry code is nine files, six of them under `src/lib/telemetry/`. Your route handlers change only to add `after(() => flush())`. ```text title="Project structure" your-app/ ├── next.config.ts # serverExternalPackages ├── package.json ├── .env.example # variable names only, no values ├── .env.local # Scout credentials, gitignored ├── scripts/ │ └── check-no-secrets.mjs # prebuild guard └── src/ ├── instrumentation.ts # Next register hook, four guards ├── lib/ │ ├── logger.ts # pino, picked up by the log bridge │ ├── metrics.ts # counters and histograms │ └── telemetry/ │ ├── config.ts # env reads, all inside functions │ ├── resource.ts # service.name, version, environment │ ├── token.ts # OAuth2 client credentials + cache │ ├── exporters.ts # OTLP/HTTP, gzip, delta temporality │ ├── server.ts # providers on globalThis, flush() │ └── guard.ts # rate limit for the browser proxy └── app/ ├── api/ │ ├── checkout/route.ts # after(() => flush()) │ └── otel/[...signal]/route.ts # browser trace proxy └── orders/ └── actions.ts # server action ``` ```json showLineNumbers title="package.json (scripts)" { "scripts": { "dev": "next dev", "prebuild": "node scripts/check-no-secrets.mjs", "build": "next build", "start": "next start" } } ``` ```bash showLineNumbers title="Run it end to end" npm install cp .env.example .env.local # fill in the four SCOUT_* values npm run build npm run start curl -s localhost:3000/api/checkout -X POST \ -H 'content-type: application/json' \ -d '{"cartId":"c_123","itemCount":2}' -i | grep -i server-timing ``` The `Server-Timing` header carries the trace id. Paste it into Scout's trace search to land on the exact request you just made. If you would rather start from a collector-based project you can run with `docker compose up`, the [Next.js (Collector)](./nextjs.md) guide is backed by [base-14/examples/nodejs/nextjs-api-mongodb](https://github.com/base-14/examples/tree/main/nodejs/nextjs-api-mongodb). The telemetry modules above drop into that project in place of its collector wiring. [base14 Scout](https://base14.io/scout/apm) stores and queries this telemetry across services. ### References - [OpenTelemetry JavaScript documentation](https://opentelemetry.io/docs/languages/js/) - [Next.js instrumentation.ts reference](https://nextjs.org/docs/app/api-reference/file-conventions/instrumentation) - [Next.js `after()` reference](https://nextjs.org/docs/app/api-reference/functions/after) - [Next.js OpenTelemetry guide](https://nextjs.org/docs/app/guides/open-telemetry) - [OTLP/HTTP specification](https://opentelemetry.io/docs/specs/otlp/#otlphttp) - [OAuth 2.0 client credentials grant](https://datatracker.ietf.org/doc/html/rfc6749#section-4.4) - [OpenTelemetry semantic conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Next.js (Collector)](./nextjs.md) - the same framework exporting to a collector you run - [Next.js Full-Stack](./nextjs-fullstack.md) - browser and server together, with Web Vitals and error boundaries - [Node.js Instrumentation](./nodejs.md) - the generic Node SDK setup this builds on - [Vercel AI SDK](./vercel-ai-sdk.md) - LLM call tracing inside a Next.js app - [tRPC Instrumentation](./trpc.md) - type-safe procedures hosted in Next.js route handlers - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) covers manual spans and metrics in depth --- ## Next.js OpenTelemetry Instrumentation - Collector-Based App Router Setup ## Next.js (Collector) :::info Sending to a collector you run This guide exports OTLP to an OpenTelemetry Collector on your own network. **For server-side Next.js apps, the default path is [Next.js](./nextjs-scout.md)**, which exports straight to base14 Scout with OIDC client credentials and needs no collector. Use this guide instead when several services already share a collector, or when you need tail sampling, redaction, routing, or host and container metrics alongside app telemetry. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Implement OpenTelemetry instrumentation for Next.js applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability across your full-stack React applications. This guide shows you how to auto-instrument Next.js API routes, server components, middleware, MongoDB queries, Redis operations, and BullMQ background jobs using the OpenTelemetry Node.js SDK with the built-in Next.js instrumentation hook. Next.js is a full-stack React framework. For browser-side instrumentation, see the [React](./react.md) guide. Next.js applications benefit from automatic instrumentation of the framework itself, HTTP requests, database queries, and background job processing. The Next.js instrumentation file (`instrumentation.ts`) provides a clean integration point that initializes OpenTelemetry before your application code runs. With OpenTelemetry, you can trace requests through API routes, monitor server component rendering, debug slow database queries, track background job execution, and identify performance bottlenecks without significant code changes. The App Router architecture works seamlessly with OpenTelemetry's context propagation, ensuring accurate parent-child span relationships across async operations. Whether you're building REST APIs with Next.js, implementing server-side rendering with App Router, migrating from commercial APM solutions like DataDog or New Relic, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Next.js OpenTelemetry instrumentation with base14 Scout. You'll learn how to set up auto-instrumentation, configure custom spans for business logic, implement distributed tracing for background workers, and deploy with Docker. :::tip TL;DR Create an `instrumentation.ts` file in your Next.js project root and initialize the OpenTelemetry Node.js SDK there - Next.js calls it automatically before your app starts. Add `@opentelemetry/auto-instrumentations-node` to capture HTTP, MongoDB, Redis, and database spans with no manual wrapping required. ::: ### Who This Guide Is For This documentation is designed for: - **Next.js developers**: implementing observability and distributed tracing for full-stack React applications with API routes - **Backend engineers**: building REST APIs with Next.js App Router and requiring production monitoring - **DevOps teams**: deploying Next.js applications with Docker and Kubernetes with comprehensive observability requirements - **Full-stack developers**: debugging MongoDB queries, Redis operations, and BullMQ job processing in production Next.js apps - **Platform teams**: standardizing observability across multiple Next.js microservices with consistent instrumentation patterns ### Prerequisites Before starting, ensure you have: - **Node.js 22.x or later** (24.x LTS recommended for production) - **Next.js 15.x or later** installed (16.x recommended with Turbopack) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) - Familiarity with Next.js App Router and API routes #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | --------------------------- | --------------- | ------------------- | | Node.js | 22.0.0 | 24.x LTS | | Next.js | 15.0.0 | 16.1.0+ | | @opentelemetry/sdk-node | 0.200.0 | 0.210+ | | @opentelemetry/auto-inst... | 0.60.0 | 0.68+ | | Mongoose (if used) | 8.0.0 | 9.1.0+ | | BullMQ (if used) | 5.0.0 | 5.66.0+ | | IORedis (if used) | 5.0.0 | 5.9.0+ | | TypeScript | 5.0.0 | 5.9.0+ | ### Installation Install the OpenTelemetry SDK and auto-instrumentation packages: ```bash showLineNumbers title="Install OpenTelemetry for Next.js" npm install --save \ @opentelemetry/api \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @opentelemetry/sdk-metrics ``` For logging support, add the logs packages: ```bash showLineNumbers npm install --save \ @opentelemetry/api-logs \ @opentelemetry/sdk-logs \ @opentelemetry/exporter-logs-otlp-http ``` Optional packages for Prometheus metrics endpoint: ```bash showLineNumbers npm install --save @opentelemetry/exporter-prometheus ``` ### Configuration Next.js provides a built-in instrumentation hook through the `instrumentation.ts` file at the project root. This is the recommended approach for initializing OpenTelemetry. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Create the instrumentation entry point at the project root: ```typescript showLineNumbers title="instrumentation.ts" export async function register() { if (process.env.NEXT_RUNTIME === 'nodejs') { await import('./src/lib/telemetry'); } } ``` Create the telemetry module with full configuration: ```typescript showLineNumbers title="src/lib/telemetry.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; import { MeterProvider, PeriodicExportingMetricReader, } from '@opentelemetry/sdk-metrics'; import { trace, metrics, SpanStatusCode } from '@opentelemetry/api'; const serviceName = process.env.OTEL_SERVICE_NAME || 'nextjs-app'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: serviceName, [ATTR_SERVICE_VERSION]: process.env.npm_package_version || '1.0.0', 'deployment.environment': process.env.NODE_ENV || 'development', 'environment': process.env.NODE_ENV || 'development', }); const traceExporter = new OTLPTraceExporter({ url: `${otlpEndpoint}/v1/traces`, }); const metricReader = new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 60000, }); const meterProvider = new MeterProvider({ resource, readers: [metricReader], }); metrics.setGlobalMeterProvider(meterProvider); const sdk = new NodeSDK({ resource, traceExporter, instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (request) => { const url = request.url || ''; return url.startsWith('/_next') || url === '/favicon.ico'; }, }, '@opentelemetry/instrumentation-fs': { enabled: false, }, '@opentelemetry/instrumentation-dns': { enabled: false, }, '@opentelemetry/instrumentation-net': { enabled: false, }, }), ], }); sdk.start(); process.on('SIGTERM', () => { Promise.all([sdk.shutdown(), meterProvider.shutdown()]) .then(() => console.log('Telemetry SDK shut down successfully')) .catch((error) => console.error('Error shutting down SDK', error)) .finally(() => process.exit(0)); }); console.log(`OpenTelemetry initialized for service: ${serviceName}`); export function getTracer(name: string = 'api') { return trace.getTracer(name); } export function getMeter(name: string = 'api') { return metrics.getMeter(name); } export async function withSpan( spanName: string, fn: () => Promise, attributes?: Record ): Promise { const tracer = getTracer(); return tracer.startActiveSpan(spanName, async (span) => { try { if (attributes) { Object.entries(attributes).forEach(([key, value]) => { span.setAttribute(key, value); }); } const result = await fn(); span.setStatus({ code: SpanStatusCode.OK }); return result; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: error instanceof Error ? error.message : 'Unknown error', }); throw error; } finally { span.end(); } }); } export { SpanStatusCode }; ``` ```mdx-code-block ``` Configure OpenTelemetry through environment variables for container deployments: ```bash showLineNumbers title=".env" # Application NODE_ENV=production PORT=3000 # OpenTelemetry OTEL_SERVICE_NAME=nextjs-app OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=api # MongoDB MONGODB_URI=mongodb://mongo:27017/nextjs-app?replicaSet=rs0 # Redis (for BullMQ) REDIS_HOST=redis REDIS_PORT=6379 # Scout Configuration SCOUT_ENDPOINT=https://your-tenant.base14.io:4318 SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token ``` ```mdx-code-block ``` Add OpenTelemetry logs export to the telemetry module: ```typescript showLineNumbers title="src/lib/telemetry.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { OTLPMetricExporter } from '@opentelemetry/exporter-metrics-otlp-http'; import { OTLPLogExporter } from '@opentelemetry/exporter-logs-otlp-http'; import { resourceFromAttributes } from '@opentelemetry/resources'; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from '@opentelemetry/semantic-conventions'; import { MeterProvider, PeriodicExportingMetricReader, } from '@opentelemetry/sdk-metrics'; import { LoggerProvider, BatchLogRecordProcessor, } from '@opentelemetry/sdk-logs'; import { logs } from '@opentelemetry/api-logs'; import { trace, metrics } from '@opentelemetry/api'; const serviceName = process.env.OTEL_SERVICE_NAME || 'nextjs-app'; const otlpEndpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318'; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: serviceName, [ATTR_SERVICE_VERSION]: '1.0.0', 'deployment.environment': process.env.NODE_ENV || 'development', 'environment': process.env.NODE_ENV || 'development', }); // Traces const traceExporter = new OTLPTraceExporter({ url: `${otlpEndpoint}/v1/traces`, }); // Metrics const metricReader = new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${otlpEndpoint}/v1/metrics`, }), exportIntervalMillis: 60000, }); const meterProvider = new MeterProvider({ resource, readers: [metricReader], }); metrics.setGlobalMeterProvider(meterProvider); // Logs const logExporter = new OTLPLogExporter({ url: `${otlpEndpoint}/v1/logs`, }); const loggerProvider = new LoggerProvider({ resource, processors: [new BatchLogRecordProcessor(logExporter)], }); logs.setGlobalLoggerProvider(loggerProvider); // SDK const sdk = new NodeSDK({ resource, traceExporter, instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (request) => { const url = request.url || ''; return url.startsWith('/_next') || url === '/favicon.ico'; }, }, '@opentelemetry/instrumentation-fs': { enabled: false }, }), ], }); sdk.start(); process.on('SIGTERM', () => { Promise.all([ sdk.shutdown(), meterProvider.shutdown(), loggerProvider.shutdown(), ]) .then(() => console.log('Telemetry SDK shut down')) .catch((error) => console.error('Shutdown error', error)) .finally(() => process.exit(0)); }); ``` ```mdx-code-block ``` Control which components are instrumented: ```typescript showLineNumbers title="src/lib/telemetry.ts" const sdk = new NodeSDK({ resource, traceExporter, instrumentations: [ getNodeAutoInstrumentations({ // Disable noisy instrumentations '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, // Disable Redis if not using BullMQ tracing '@opentelemetry/instrumentation-ioredis': { enabled: false }, // Configure HTTP instrumentation '@opentelemetry/instrumentation-http': { enabled: true, ignoreIncomingRequestHook: (request) => { const url = request.url || ''; // Skip Next.js internal routes and static assets return ( url.startsWith('/_next') || url === '/favicon.ico' || url === '/api/health' ); }, }, // MongoDB instrumentation '@opentelemetry/instrumentation-mongodb': { enabled: true, }, }), ], }); ``` ```mdx-code-block ``` #### Next.js Configuration Configure Next.js to work properly with OpenTelemetry packages: ```typescript showLineNumbers title="next.config.ts" import type { NextConfig } from 'next'; const nextConfig: NextConfig = { output: 'standalone', serverExternalPackages: [ 'mongoose', 'bcrypt', 'pino', 'bullmq', 'ioredis', ], }; export default nextConfig; ``` The `serverExternalPackages` option ensures native modules are bundled correctly for production deployment. ### Production Configuration For production deployments with Docker: #### Dockerfile ```dockerfile showLineNumbers title="Dockerfile" # Multi-stage Dockerfile for Next.js with OpenTelemetry # Stage 1: Base FROM node:24-alpine AS base # Stage 2: Dependencies FROM base AS deps RUN apk add --no-cache libc6-compat WORKDIR /app COPY package.json package-lock.json ./ RUN npm ci # Stage 3: Builder FROM base AS builder WORKDIR /app COPY --from=deps /app/node_modules ./node_modules COPY . . ENV NEXT_TELEMETRY_DISABLED=1 ENV NODE_ENV=production RUN npm run build # Stage 4: Runner FROM base AS runner WORKDIR /app ENV NODE_ENV=production ENV NEXT_TELEMETRY_DISABLED=1 RUN addgroup --system --gid 1001 nodejs RUN adduser --system --uid 1001 nextjs COPY --from=builder /app/public ./public RUN mkdir .next RUN chown nextjs:nodejs .next COPY --from=builder --chown=nextjs:nodejs /app/.next/standalone ./ COPY --from=builder --chown=nextjs:nodejs /app/.next/static ./.next/static USER nextjs EXPOSE 3000 ENV PORT=3000 ENV HOSTNAME="0.0.0.0" HEALTHCHECK --interval=30s --timeout=10s --start-period=10s --retries=3 \ CMD wget --no-verbose --tries=1 --spider http://localhost:3000/api/health || exit 1 CMD ["node", "server.js"] ``` #### Docker Compose ```yaml showLineNumbers title="compose.yml" services: app: build: context: . target: runner ports: - '3000:3000' environment: - NODE_ENV=production - MONGODB_URI=mongodb://mongodb:27017/nextjs-api?replicaSet=rs0 - JWT_SECRET=${JWT_SECRET} - REDIS_HOST=redis - REDIS_PORT=6379 - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_SERVICE_NAME=nextjs-app depends_on: mongodb: condition: service_healthy redis: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ['CMD', 'wget', '-q', '--spider', 'http://localhost:3000/api/health'] interval: 30s timeout: 10s retries: 3 networks: - app-network mongodb: image: mongo:8 ports: - '27017:27017' volumes: - mongodb_data:/data/db command: ['--replSet', 'rs0', '--bind_ip_all'] healthcheck: test: | mongosh --eval "try { rs.status().ok } catch(e) { rs.initiate({ _id: 'rs0', members: [{ _id: 0, host: 'mongodb:27017' }] }).ok }" --quiet interval: 10s timeout: 10s retries: 5 networks: - app-network redis: image: redis:8-alpine ports: - '6379:6379' command: redis-server --appendonly yes healthcheck: test: ['CMD', 'redis-cli', 'ping'] interval: 10s timeout: 5s retries: 5 networks: - app-network otel-collector: image: otel/opentelemetry-collector-contrib:0.116.1 command: ['--config=/etc/otelcol-config.yaml'] volumes: - ./config/otel-config.yaml:/etc/otelcol-config.yaml:ro ports: - '4317:4317' # OTLP gRPC - '4318:4318' # OTLP HTTP environment: - SCOUT_ENDPOINT=${SCOUT_ENDPOINT} - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL} networks: - app-network volumes: mongodb_data: networks: app-network: driver: bridge ``` #### OpenTelemetry Collector Configuration ```yaml showLineNumbers title="config/otel-config.yaml" extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector health_check: endpoint: 0.0.0.0:13133 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: limit_mib: 256 check_interval: 1s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14] metrics: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14] logs: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/b14] ``` ### Framework-Specific Features #### API Routes (App Router) Next.js API routes are automatically instrumented via HTTP instrumentation. Add custom spans for business logic: ```typescript showLineNumbers title="src/app/api/articles/route.ts" import { NextRequest, NextResponse } from 'next/server'; import { connectDB } from '@/lib/db'; import { Article } from '@/models/Article'; import { withSpan } from '@/lib/telemetry'; import { recordArticle } from '@/lib/metrics'; export async function GET(request: NextRequest) { return withSpan('articles.list', async () => { try { await connectDB(); const { searchParams } = new URL(request.url); const page = parseInt(searchParams.get('page') || '1'); const limit = parseInt(searchParams.get('limit') || '10'); const skip = (page - 1) * limit; const [articles, total] = await Promise.all([ Article.find() .sort({ createdAt: -1 }) .skip(skip) .limit(limit) .populate('authorId', 'username'), Article.countDocuments(), ]); recordArticle('list', true); return NextResponse.json({ success: true, data: { articles, total, page, limit }, }); } catch (error) { recordArticle('list', false); return NextResponse.json( { success: false, error: 'Failed to list articles' }, { status: 500 } ); } }); } export async function POST(request: NextRequest) { return withSpan('articles.create', async () => { try { await connectDB(); const body = await request.json(); const article = await Article.create(body); recordArticle('create', true); return NextResponse.json( { success: true, data: article }, { status: 201 } ); } catch (error) { recordArticle('create', false); return NextResponse.json( { success: false, error: 'Failed to create article' }, { status: 500 } ); } }); } ``` #### Custom Metrics Create application-specific metrics: ```typescript showLineNumbers title="src/lib/metrics.ts" import { getMeter } from './telemetry'; const meter = getMeter('api'); export const httpRequestCounter = meter.createCounter('http.server.requests', { description: 'Total number of HTTP requests', unit: '1', }); export const httpRequestDuration = meter.createHistogram( 'http.server.duration', { description: 'HTTP request duration in milliseconds', unit: 'ms', } ); export const articleCounter = meter.createCounter('articles.operations', { description: 'Article operations count', unit: '1', }); export const dbOperationDuration = meter.createHistogram( 'db.operation.duration', { description: 'Database operation duration in milliseconds', unit: 'ms', } ); export function recordRequest( method: string, route: string, statusCode: number, durationMs: number ): void { const attributes = { 'http.method': method, 'http.route': route, 'http.status_code': statusCode, }; httpRequestCounter.add(1, attributes); httpRequestDuration.record(durationMs, attributes); } export function recordArticle( operation: 'create' | 'update' | 'delete' | 'view' | 'list', success: boolean ): void { articleCounter.add(1, { operation, success: String(success), }); } ``` #### BullMQ Background Jobs with Trace Propagation Implement distributed tracing for background workers: ```typescript showLineNumbers title="src/lib/queue.ts" import { Queue, Worker, Job } from 'bullmq'; import { context, propagation } from '@opentelemetry/api'; import { config } from './config'; const connectionConfig = { host: config.redisHost, port: config.redisPort, }; export const emailQueue = new Queue('email', { connection: connectionConfig }); export interface EmailJobData { to: string; subject: string; body: string; } function injectTraceContext(): Record { const traceContext: Record = {}; propagation.inject(context.active(), traceContext); return traceContext; } export async function addEmailJob(data: EmailJobData): Promise { const traceContext = injectTraceContext(); return emailQueue.add( 'send-email', { ...data, traceContext }, { attempts: 3, backoff: { type: 'exponential', delay: 1000 }, } ); } ``` Worker with trace context extraction: ```typescript showLineNumbers title="src/jobs/worker.ts" import { Job } from 'bullmq'; import { trace, context, propagation, SpanStatusCode, Context, } from '@opentelemetry/api'; import { createEmailWorker, EmailJobData } from '../lib/queue'; const tracer = trace.getTracer('worker'); interface JobDataWithTrace { traceContext?: Record; } function extractTraceContext(jobData: JobDataWithTrace): Context { if (jobData.traceContext) { return propagation.extract(context.active(), jobData.traceContext); } return context.active(); } async function processWithSpan( spanName: string, job: Job, parentContext: Context, processor: () => Promise ): Promise { return context.with(parentContext, async () => { return tracer.startActiveSpan(spanName, async (span) => { try { span.setAttribute('job.id', job.id || 'unknown'); span.setAttribute('job.name', job.name); span.setAttribute('job.queue', job.queueName); span.setAttribute('job.attempt', job.attemptsMade); const result = await processor(); span.setStatus({ code: SpanStatusCode.OK }); return result; } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: error instanceof Error ? error.message : 'Unknown error', }); throw error; } finally { span.end(); } }); }); } const emailWorker = createEmailWorker( async (job: Job) => { const parentContext = extractTraceContext(job.data); await processWithSpan('job.email.send', job, parentContext, async () => { console.log(`Processing email job ${job.id}`); // Email sending logic here await new Promise((resolve) => setTimeout(resolve, 100)); }); } ); emailWorker.on('completed', (job) => { console.log(`Job ${job.id} completed`); }); emailWorker.on('failed', (job, err) => { console.error(`Job ${job?.id} failed:`, err.message); }); ``` ### Custom Instrumentation #### Creating Custom Spans Use the `withSpan` utility for consistent span management: ```typescript showLineNumbers title="src/app/api/users/[id]/route.ts" import { NextRequest, NextResponse } from 'next/server'; import { withSpan, getTracer, SpanStatusCode } from '@/lib/telemetry'; import { User } from '@/models/User'; export async function GET( request: NextRequest, { params }: { params: { id: string } } ) { return withSpan( 'users.get', async () => { const user = await User.findById(params.id); if (!user) { return NextResponse.json( { success: false, error: 'User not found' }, { status: 404 } ); } return NextResponse.json({ success: true, data: user }); }, { 'user.id': params.id } ); } ``` #### Adding Attributes to Active Span ```typescript showLineNumbers title="src/lib/auth.ts" import { trace, SpanStatusCode } from '@opentelemetry/api'; import jwt from 'jsonwebtoken'; export async function verifyToken(token: string): Promise { const currentSpan = trace.getActiveSpan(); try { const payload = jwt.verify(token, process.env.JWT_SECRET!) as JwtPayload; if (currentSpan) { currentSpan.setAttributes({ 'user.id': payload.userId, 'auth.method': 'jwt', }); currentSpan.addEvent('auth_success'); } return payload; } catch (error) { if (currentSpan) { currentSpan.addEvent('auth_failed', { reason: 'invalid_token' }); currentSpan.setStatus({ code: SpanStatusCode.ERROR, message: 'Token verification failed', }); } throw error; } } ``` #### Nested Spans for Complex Operations ```typescript showLineNumbers title="src/services/article.service.ts" import { getTracer, SpanStatusCode } from '@/lib/telemetry'; import { Article } from '@/models/Article'; const tracer = getTracer('article-service'); export async function publishArticle(articleId: string): Promise { return tracer.startActiveSpan('article.publish', async (span) => { try { span.setAttribute('article.id', articleId); // Validate article await tracer.startActiveSpan('article.validate', async (validateSpan) => { const article = await Article.findById(articleId); if (!article) { throw new Error('Article not found'); } validateSpan.setAttribute('article.title', article.title); validateSpan.end(); }); // Update status await tracer.startActiveSpan('article.updateStatus', async (updateSpan) => { await Article.findByIdAndUpdate(articleId, { published: true, publishedAt: new Date(), }); updateSpan.addEvent('article_published'); updateSpan.end(); }); span.setStatus({ code: SpanStatusCode.OK }); } catch (error) { span.recordException(error as Error); span.setStatus({ code: SpanStatusCode.ERROR, message: (error as Error).message, }); throw error; } finally { span.end(); } }); } ``` ### Browser / Client-Side Instrumentation The `instrumentation.ts` hook only runs on the server (Node.js or Edge runtime), so nothing on this page instruments the user's browser. The example behind this guide (`nodejs/nextjs-api-mongodb`) is server-only and has no client-side telemetry to source from. For browser instrumentation - document load timing, `fetch`/XHR spans from Client Components, click and submit interactions, React error boundary crashes, and Core Web Vitals - you have two options. `@base-14/scout-react` handles this without manual span setup. Call `Scout.initialize()` once from a Client Component and it emits spans for clicks, route changes, `fetch`/XHR, errors, and Core Web Vitals. See the [React guide](./react.md). [Next.js Full-Stack Instrumentation](./nextjs-fullstack.md) is the manual path. That guide is backed by a runnable browser-and-server example, and routes browser OTLP through a same-origin API route so the collector needs no CORS configuration. Once browser spans are arriving, you can query them by session, screen, and error in [Scout's RUM views](../../../operate/rum/getting-started.md). Browser spans propagate the `traceparent` header on outbound `fetch` calls to your API routes, so a single trace can span "button click in the browser -> API route -> MongoDB query -> BullMQ job" once both sides are instrumented. ### Running Your Application ```mdx-code-block ``` Start with Turbopack for fast refresh: ```bash showLineNumbers # Start with Turbopack (recommended) npm run dev # Or with standard webpack npm run dev -- --no-turbo ``` ```mdx-code-block ``` Build and run the production server: ```bash showLineNumbers # Build the application npm run build # Start production server npm start ``` ```mdx-code-block ``` Deploy with Docker Compose: ```bash showLineNumbers # Build and start all services docker compose up --build -d # View logs docker compose logs -f app # Stop services docker compose down ``` ```mdx-code-block ``` Run the BullMQ worker process: ```bash showLineNumbers # Development (with hot reload) npm run worker # Production (from built bundle) node --import ./dist/instrumentation.js dist/worker.js ``` ```mdx-code-block ``` ### Troubleshooting #### Verifying Instrumentation Create a health endpoint that verifies OpenTelemetry is active: ```typescript showLineNumbers title="src/app/api/health/route.ts" import { NextResponse } from 'next/server'; import { trace } from '@opentelemetry/api'; export async function GET() { const currentSpan = trace.getActiveSpan(); if (currentSpan && currentSpan.isRecording()) { const spanContext = currentSpan.spanContext(); return NextResponse.json({ status: 'healthy', tracing: 'enabled', trace_id: spanContext.traceId, span_id: spanContext.spanId, }); } return NextResponse.json({ status: 'healthy', tracing: 'disabled', }); } ``` #### Issue: No Traces from API Routes **Solutions:** 1. Ensure `instrumentation.ts` exists at the project root 2. Verify the runtime check: ```typescript export async function register() { // Must check for nodejs runtime if (process.env.NEXT_RUNTIME === 'nodejs') { await import('./src/lib/telemetry'); } } ``` 1. Confirm telemetry module is imported correctly (check path) #### Issue: Mongoose Queries Not Traced **Solutions:** 1. Add mongoose to `serverExternalPackages` in `next.config.ts`: ```typescript const nextConfig: NextConfig = { serverExternalPackages: ['mongoose'], }; ``` 1. Verify MongoDB instrumentation is enabled (not disabled in config) #### Issue: Next.js Internal Routes Creating Noise **Solutions:** Filter internal routes in HTTP instrumentation: ```typescript showLineNumbers '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (request) => { const url = request.url || ''; return ( url.startsWith('/_next') || url === '/favicon.ico' || url.includes('__nextjs') ); }, }, ``` #### Issue: Worker Traces Not Connected to API Traces **Solutions:** Ensure trace context is injected when enqueuing jobs: ```typescript function injectTraceContext(): Record { const traceContext: Record = {}; propagation.inject(context.active(), traceContext); return traceContext; } // Include traceContext in job data await queue.add('job-name', { ...data, traceContext }); ``` ### Security Considerations #### Sensitive Data Protection Avoid capturing sensitive information in spans: ```typescript showLineNumbers // BAD - Exposes sensitive data span.setAttributes({ 'user.password': password, 'user.email': email, 'api_key': apiKey, }); // GOOD - Use safe identifiers span.setAttributes({ 'user.id': userId, 'user.type': 'customer', 'request.has_api_key': Boolean(apiKey), }); ``` #### HTTP Header Filtering The HTTP instrumentation automatically excludes sensitive headers. For custom headers: ```typescript showLineNumbers '@opentelemetry/instrumentation-http': { headersToSpanAttributes: { requestHeaders: ['content-type', 'user-agent', 'x-request-id'], // Exclude: authorization, cookie, x-api-key }, }, ``` #### Environment Variable Security Never commit secrets to version control: ```bash showLineNumbers title=".env.example" # Good - Template without real values JWT_SECRET=your-secret-key-at-least-32-characters SCOUT_CLIENT_SECRET=your_client_secret # Production: Use secrets management # - AWS Secrets Manager # - HashiCorp Vault # - Kubernetes Secrets ``` ### Performance Considerations #### Expected Performance Impact | Metric | Impact | Notes | | ----------- | -------------------- | ---------------------------------- | | **Latency** | +0.5-2ms per request | Span creation and context overhead | | **CPU** | +2-5% | During span export operations | | **Memory** | +15-40MB | SDK and span buffer overhead | | **Network** | +1-5KB per trace | OTLP HTTP with gzip compression | #### Optimization Best Practices ##### 1. Use BatchSpanProcessor (Default) The NodeSDK uses BatchSpanProcessor by default, which batches spans for efficient export. ##### 2. Skip Non-Critical Endpoints ```typescript showLineNumbers ignoreIncomingRequestHook: (request) => { const url = request.url || ''; return ['/api/health', '/api/metrics', '/_next', '/favicon.ico'].some( (path) => url.includes(path) ); }, ``` ##### 3. Disable Noisy Instrumentations ```typescript showLineNumbers instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, '@opentelemetry/instrumentation-net': { enabled: false }, }), ], ``` ##### 4. Limit Attribute Sizes ```typescript showLineNumbers function addSafeAttribute( span: Span, key: string, value: string, maxLength: number = 256 ) { if (value.length > maxLength) { value = value.substring(0, maxLength) + '...'; } span.setAttribute(key, value); } ``` ##### 5. Configure Export Intervals ```typescript showLineNumbers const metricReader = new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${endpoint}/v1/metrics` }), exportIntervalMillis: 60000, // Export every 60 seconds in production }); ``` ### FAQ #### Does OpenTelemetry work with Next.js App Router? Yes, OpenTelemetry fully supports Next.js App Router. The `instrumentation.ts` file at the project root initializes OpenTelemetry before any application code runs. API routes, server components, and middleware are automatically traced. #### What's the performance impact on Next.js applications? Expect +0.5-2ms latency per request, +2-5% CPU, and +15-40MB memory. This impact is minimal for most production workloads. Use BatchSpanProcessor and filter internal Next.js routes to minimize overhead. #### Which Next.js versions are supported? Next.js 15.x and later are supported. Next.js 16.x with Turbopack is recommended for best performance. The `instrumentation.ts` hook was stabilized in Next.js 15. #### How do I trace MongoDB/Mongoose queries? MongoDB queries are automatically traced via the mongodb instrumentation included in auto-instrumentations-node. Add `mongoose` to `serverExternalPackages` in `next.config.ts` for proper bundling. #### How does distributed tracing work with BullMQ workers? Inject trace context when enqueuing jobs using `propagation.inject()`, then extract it in workers using `propagation.extract()`. This creates parent-child relationships between API requests and background job execution. #### How do I instrument the browser side of a Next.js app? The `instrumentation.ts` hook only covers the Node.js (and Edge) runtime, so it never touches the browser. For client-side tracing - `fetch` from Client Components, document load, clicks, and App Router navigation - install `@opentelemetry/sdk-trace-web` and `@opentelemetry/auto-instrumentations-web`, then mount the setup from a Client Component in `app/layout.tsx` so it starts on hydration. Use `NEXT_PUBLIC_` env vars for the collector endpoint so they reach the browser bundle. The full manual setup, including browser error capture and Core Web Vitals, is in [Next.js Full-Stack Instrumentation](./nextjs-fullstack.md). To skip the manual wiring, `@base-14/scout-react` covers the same browser signals from a single `Scout.initialize()` call. See the [React guide](./react.md). #### Can I use it with Next.js middleware? Yes, middleware requests are traced via HTTP instrumentation. Add custom spans in middleware using `trace.getActiveSpan()` to add attributes. #### How do I handle multi-tenant applications? Add tenant ID as span attribute in your authentication middleware or API routes: ```typescript const currentSpan = trace.getActiveSpan(); if (currentSpan) { currentSpan.setAttribute('tenant.id', tenantId); } ``` Then filter by tenant in the Scout Dashboard. #### What's the difference between traces and metrics? Traces show individual request flows with timing (e.g., "this API call took 150ms with 3 database queries"). Metrics aggregate measurements over time (e.g., "average response time is 120ms"). Use both together for complete observability. #### How do I trace Next.js server components with OpenTelemetry? Server components execute during rendering and are traced via HTTP instrumentation. For specific component tracing, create custom spans within the component's async data fetching logic. #### Can I export metrics to Prometheus? Yes, add the Prometheus exporter for metrics scraping: ```typescript import { PrometheusExporter } from '@opentelemetry/exporter-prometheus'; const prometheusExporter = new PrometheusExporter({ preventServerStart: true }); const meterProvider = new MeterProvider({ readers: [otlpMetricReader, prometheusExporter], }); ``` ### What's Next? #### Related Guides - [Next.js Full-Stack Instrumentation](./nextjs-fullstack.md) - the browser half of Next.js: web SDK, error boundaries, Web Vitals, and a same-origin OTLP proxy route - [Angular Instrumentation](./angular.md) - browser plus Express/Postgres full-stack across all three signals - [NestJS Instrumentation](./nestjs.md) - Structured TypeScript framework on Node.js - [Express.js Instrumentation](./express.md) - Classic Node.js web framework - [Node.js Instrumentation](./nodejs.md) - General Node.js OTel setup - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for API latency, errors, and database queries - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards for Next.js metrics #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment on Kubernetes ### Complete Example A complete production-ready example with Next.js 16, MongoDB, Redis, BullMQ, and comprehensive OpenTelemetry instrumentation is available at: **GitHub**: [base-14/examples/nodejs/nextjs-api-mongodb](https://github.com/base-14/examples/tree/main/nodejs/nextjs-api-mongodb) **Features**: - Next.js 16.1.x with Turbopack - Full auto-instrumentation with NodeSDK - Custom spans, metrics, and logs - BullMQ background job tracing with context propagation - MongoDB with Mongoose 9.x - Production Docker deployment (standalone output) - JWT authentication - Health check endpoints - Graceful shutdown handling #### package.json ```json showLineNumbers title="package.json" { "name": "nextjs-api-mongodb", "version": "1.0.0", "type": "module", "scripts": { "dev": "next dev --turbopack", "build": "next build", "start": "next start", "worker": "tsx --import ./src/jobs/instrumentation.ts src/jobs/worker.ts" }, "dependencies": { "next": "16.1.3", "react": "19.2.3", "react-dom": "19.2.3", "mongoose": "9.1.4", "bullmq": "5.66.5", "ioredis": "5.9.2", "@opentelemetry/api": "^1.9.0", "@opentelemetry/sdk-node": "^0.210.0", "@opentelemetry/auto-instrumentations-node": "^0.68.0", "@opentelemetry/exporter-trace-otlp-http": "^0.210.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.210.0", "@opentelemetry/resources": "^2.4.0", "@opentelemetry/semantic-conventions": "^1.39.0", "@opentelemetry/sdk-metrics": "^2.4.0" } } ``` #### Environment Variables ```bash showLineNumbers title=".env.example" # Application NODE_ENV=development PORT=3000 # MongoDB MONGODB_URI=mongodb://localhost:27017/nextjs-api?replicaSet=rs0 # Authentication JWT_SECRET=your-super-secret-jwt-key-must-be-at-least-32-characters-long # Redis (for BullMQ) REDIS_HOST=localhost REDIS_PORT=6379 # OpenTelemetry OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_SERVICE_NAME=nextjs-api-mongodb # Scout (production) SCOUT_ENDPOINT=https://scout.example.com SCOUT_CLIENT_ID=your-client-id SCOUT_CLIENT_SECRET=your-client-secret SCOUT_TOKEN_URL=https://auth.example.com/oauth/token ``` Once telemetry reaches the collector, you can [monitor Next.js server actions in Scout](https://base14.io/scout/apm) — trace SSR render times, API route performance, and database calls across your application. ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [Next.js Instrumentation Documentation](https://nextjs.org/docs/app/building-your-application/optimizing/instrumentation) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [BullMQ Documentation](https://docs.bullmq.io/) --- ## Node.js OpenTelemetry Instrumentation - HTTP, DB & Queue Tracing :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Implement OpenTelemetry instrumentation for Node.js applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide covers auto-instrumentation setup for popular Node.js frameworks including Express, NestJS, Fastify, and Koa, with production-ready configurations for collecting traces and metrics. Node.js applications benefit from automatic instrumentation of the event loop, async operations, popular frameworks (Express, NestJS, Fastify), database clients (MongoDB, PostgreSQL, MySQL), Redis, message queues (BullMQ, RabbitMQ), and HTTP clients. With OpenTelemetry, you can monitor async context propagation, identify performance bottlenecks, trace distributed transactions across microservices, and debug issues in production without significant code changes. Whether you're implementing observability for the first time, migrating from commercial APM solutions like New Relic or Datadog, or troubleshooting async performance issues in production, this guide provides framework-agnostic patterns and best practices for Node.js OpenTelemetry instrumentation with Base14 Scout. :::tip TL;DR Install `@opentelemetry/sdk-node` and `@opentelemetry/auto-instrumentations-node`, create an `instrumentation.js` file that initializes `NodeSDK`, then start your app with `node --require ./instrumentation.js server.js`. Express, NestJS, databases, Redis, and message queues are all traced automatically with no per-route code changes. ::: ### Who This Guide Is For This documentation is designed for: - **Node.js developers**: implementing observability and distributed tracing across Express, NestJS, or other frameworks - **Backend engineers**: deploying Node.js microservices with production monitoring requirements - **DevOps teams**: standardizing observability across multiple Node.js services and containers - **Full-stack developers**: debugging performance issues in async operations, database queries, and API calls - **Platform engineers**: migrating from DataDog, New Relic, or Dynatrace to OpenTelemetry-based solutions ### Overview This guide covers Node.js OpenTelemetry instrumentation across all major frameworks. For framework-specific details, see: - **[Express.js](./express.md)** - Express 4.x and 5.x instrumentation with MongoDB, Redis, WebSockets - **[NestJS](./nestjs.md)** - Enterprise framework with DI, TypeORM, BullMQ, WebSocket gateway - **[Next.js](./nextjs-scout.md)** - React framework with App Router, direct OTLP to Scout workers - **[Fastify](./fastify.md)** - High-performance framework with hooks, plugins, PostgreSQL, BullMQ - **Koa** - Middleware-based framework patterns (coming soon) #### What You'll Learn - Auto-instrument Node.js applications with zero code changes - Configure OpenTelemetry SDK for production deployments - Trace async operations and maintain context across event loop - Monitor database queries, HTTP requests, and external API calls - Implement custom instrumentation for business logic - Optimize performance and reduce telemetry overhead - Debug common issues and verify trace collection ### Prerequisites Before starting, ensure you have: - **Node.js 18.x or later** (20.x LTS recommended for production) - **npm 9.x or later** or **yarn 1.22+** package manager - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) - Familiarity with async/await patterns in Node.js #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | --------------------------- | --------------- | ------------------- | | Node.js | 18.0.0 | 20.x LTS or 22.x | | @opentelemetry/sdk-node | 0.40.0 | 0.54+ | | @opentelemetry/auto-inst... | 0.40.0 | 0.54+ | | TypeScript (optional) | 4.5.0 | 5.3.0+ | #### Supported Libraries OpenTelemetry auto-instrumentation automatically traces these popular Node.js libraries: **Web Frameworks**: Express, NestJS, Fastify, Koa, Hapi, Restify **Databases**: MongoDB (Mongoose), PostgreSQL (pg, Sequelize), MySQL, Redis, Prisma, TypeORM **HTTP Clients**: axios, node-fetch, got, request, http/https (built-in) **Message Queues**: BullMQ, RabbitMQ (amqplib), Kafka **Other**: Socket.IO, GraphQL, gRPC, Winston, Pino (logging) ### Installation Install the OpenTelemetry SDK and auto-instrumentation packages: ```bash showLineNumbers title="Install OpenTelemetry for Node.js" npm install --save \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/resources \ @opentelemetry/semantic-conventions ``` For TypeScript projects, add type definitions: ```bash showLineNumbers npm install --save-dev @types/node ``` ### Configuration ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Create a dedicated file to initialize OpenTelemetry before your application starts: ```javascript showLineNumbers title="instrumentation.js" const { NodeSDK } = require('@opentelemetry/sdk-node'); const { getNodeAutoInstrumentations, } = require('@opentelemetry/auto-instrumentations-node'); const { OTLPTraceExporter, } = require('@opentelemetry/exporter-trace-otlp-http'); const { Resource } = require('@opentelemetry/resources'); const { SEMRESATTRS_SERVICE_NAME, SEMRESATTRS_SERVICE_VERSION, SEMRESATTRS_DEPLOYMENT_ENVIRONMENT, } = require('@opentelemetry/semantic-conventions'); const sdk = new NodeSDK({ resource: new Resource({ [SEMRESATTRS_SERVICE_NAME]: process.env.SERVICE_NAME || 'nodejs-service', [SEMRESATTRS_SERVICE_VERSION]: process.env.SERVICE_VERSION || '1.0.0', [SEMRESATTRS_DEPLOYMENT_ENVIRONMENT]: process.env.NODE_ENV || 'development', }), traceExporter: new OTLPTraceExporter({ url: process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318/v1/traces', }), instrumentations: [ getNodeAutoInstrumentations({ // Customize per-instrumentation config '@opentelemetry/instrumentation-fs': { enabled: false, // Disable filesystem tracing }, '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { // Skip health check endpoints return req.url?.includes('/health'); }, }, }), ], }); sdk.start(); // Graceful shutdown process.on('SIGTERM', () => { sdk .shutdown() .then(() => console.log('Tracing terminated')) .catch((error) => console.log('Error terminating tracing', error)) .finally(() => process.exit(0)); }); module.exports = sdk; ``` Update your application startup: ```javascript showLineNumbers title="server.js" // IMPORTANT: Require instrumentation FIRST, before any other imports require('./instrumentation'); const express = require('express'); const app = express(); // Your application code here app.get('/', (req, res) => { res.send('Hello World!'); }); app.listen(3000, () => { console.log('Server running on port 3000'); }); ``` ```mdx-code-block ``` For containerized deployments, use environment variables without code changes: ```bash showLineNumbers title=".env" # Service identification OTEL_SERVICE_NAME=nodejs-api OTEL_SERVICE_VERSION=1.0.0 NODE_ENV=production # Exporter configuration OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 # Resource attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development,service.namespace=backend # Instrumentation settings OTEL_NODE_ENABLED_INSTRUMENTATIONS=http,express,mongodb,redis OTEL_PROPAGATORS=tracecontext,baggage # Performance tuning OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 OTEL_BSP_SCHEDULE_DELAY=5000 ``` Then use the `--require` flag to load instrumentation: ```bash showLineNumbers node --require ./instrumentation.js server.js ``` ```mdx-code-block ``` For TypeScript projects with ES modules: ```typescript showLineNumbers title="instrumentation.ts" import { NodeSDK } from '@opentelemetry/sdk-node'; import { getNodeAutoInstrumentations } from '@opentelemetry/auto-instrumentations-node'; import { OTLPTraceExporter } from '@opentelemetry/exporter-trace-otlp-http'; import { Resource } from '@opentelemetry/resources'; import { SEMRESATTRS_SERVICE_NAME, SEMRESATTRS_SERVICE_VERSION, SEMRESATTRS_DEPLOYMENT_ENVIRONMENT, } from '@opentelemetry/semantic-conventions'; const sdk = new NodeSDK({ resource: new Resource({ [SEMRESATTRS_SERVICE_NAME]: process.env.SERVICE_NAME || 'nodejs-service', [SEMRESATTRS_SERVICE_VERSION]: process.env.SERVICE_VERSION || '1.0.0', [SEMRESATTRS_DEPLOYMENT_ENVIRONMENT]: process.env.NODE_ENV || 'development', }), traceExporter: new OTLPTraceExporter({ url: process.env.OTEL_EXPORTER_OTLP_ENDPOINT || 'http://localhost:4318/v1/traces', }), instrumentations: [getNodeAutoInstrumentations()], }); sdk.start(); export default sdk; ``` Update `tsconfig.json`: ```json showLineNumbers title="tsconfig.json" { "compilerOptions": { "target": "ES2020", "module": "commonjs", "moduleResolution": "node", "esModuleInterop": true, "strict": true } } ``` ```mdx-code-block ``` ### Production Configuration For production deployments, use BatchSpanProcessor with optimized settings: ```javascript showLineNumbers title="instrumentation.production.js" const { NodeSDK } = require('@opentelemetry/sdk-node'); const { getNodeAutoInstrumentations, } = require('@opentelemetry/auto-instrumentations-node'); const { OTLPTraceExporter, } = require('@opentelemetry/exporter-trace-otlp-http'); const { Resource } = require('@opentelemetry/resources'); const { BatchSpanProcessor, } = require('@opentelemetry/sdk-trace-base'); const { SEMRESATTRS_SERVICE_NAME, SEMRESATTRS_SERVICE_VERSION, SEMRESATTRS_DEPLOYMENT_ENVIRONMENT, SEMRESATTRS_SERVICE_INSTANCE_ID, } = require('@opentelemetry/semantic-conventions'); const traceExporter = new OTLPTraceExporter({ url: process.env.OTEL_EXPORTER_OTLP_ENDPOINT, headers: { // Optional: Add authentication headers for Scout // 'Authorization': `Bearer ${process.env.SCOUT_API_KEY}` }, timeoutMillis: 15000, }); const sdk = new NodeSDK({ resource: new Resource({ [SEMRESATTRS_SERVICE_NAME]: process.env.SERVICE_NAME, [SEMRESATTRS_SERVICE_VERSION]: process.env.SERVICE_VERSION, [SEMRESATTRS_DEPLOYMENT_ENVIRONMENT]: process.env.NODE_ENV, [SEMRESATTRS_SERVICE_INSTANCE_ID]: process.env.HOSTNAME || `${process.pid}`, 'service.namespace': process.env.SERVICE_NAMESPACE || 'default', 'container.id': process.env.CONTAINER_ID, 'k8s.pod.name': process.env.K8S_POD_NAME, 'k8s.namespace.name': process.env.K8S_NAMESPACE, }), spanProcessor: new BatchSpanProcessor(traceExporter, { maxQueueSize: 2048, maxExportBatchSize: 512, scheduledDelayMillis: 5000, exportTimeoutMillis: 30000, }), instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false, }, '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { const ignorePaths = ['/health', '/metrics', '/ready']; return ignorePaths.some((path) => req.url?.includes(path)); }, }, }), ], }); sdk.start(); // Handle graceful shutdown const shutdown = () => { sdk .shutdown() .then(() => console.log('SDK shut down successfully')) .catch((error) => console.error('Error shutting down SDK', error)) .finally(() => process.exit(0)); }; process.on('SIGTERM', shutdown); process.on('SIGINT', shutdown); ``` #### Docker Deployment ```dockerfile showLineNumbers title="Dockerfile" FROM node:20-alpine WORKDIR /app COPY package*.json ./ RUN npm ci --only=production COPY . . # Set OpenTelemetry environment variables ENV OTEL_SERVICE_NAME=nodejs-api ENV OTEL_TRACES_EXPORTER=otlp ENV NODE_OPTIONS="--require ./instrumentation.js" EXPOSE 3000 CMD ["node", "server.js"] ``` ```yaml showLineNumbers title="docker-compose.yml" version: '3.8' services: nodejs-api: build: . ports: - '3000:3000' environment: - NODE_ENV=production - OTEL_SERVICE_NAME=nodejs-api - OTEL_SERVICE_VERSION=1.0.0 - OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 - OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4318:4318' ``` ### Custom Instrumentation For business logic and application-specific operations, add manual spans: ```javascript showLineNumbers title="services/order-service.js" const { trace } = require('@opentelemetry/api'); class OrderService { async createOrder(userId, items) { const tracer = trace.getTracer('order-service'); return tracer.startActiveSpan('createOrder', async (span) => { try { span.setAttributes({ 'user.id': userId, 'order.items.count': items.length, 'order.total': items.reduce((sum, item) => sum + item.price, 0), }); // Validate items await tracer.startActiveSpan('validateItems', async (validateSpan) => { await this.validateItems(items); validateSpan.end(); }); // Create order in database const order = await tracer.startActiveSpan( 'saveOrderToDatabase', async (dbSpan) => { const result = await this.db.orders.create({ userId, items, createdAt: new Date(), }); dbSpan.setAttribute('order.id', result.id); dbSpan.end(); return result; } ); // Send confirmation email await tracer.startActiveSpan('sendConfirmation', async (emailSpan) => { await this.emailService.sendOrderConfirmation(userId, order.id); emailSpan.end(); }); span.setStatus({ code: 1 }); // OK return order; } catch (error) { span.recordException(error); span.setStatus({ code: 2, message: error.message }); // ERROR throw error; } finally { span.end(); } }); } async validateItems(items) { // Validation logic if (items.length === 0) { throw new Error('Order must contain at least one item'); } } } module.exports = OrderService; ``` ### Running Your Application #### Development Mode ```bash showLineNumbers # With console output for debugging export OTEL_TRACES_EXPORTER=console node --require ./instrumentation.js server.js ``` #### Production Mode ```bash showLineNumbers export NODE_ENV=production export OTEL_SERVICE_NAME=nodejs-api export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.yourdomain.com/v1/traces node --require ./instrumentation.js server.js ``` #### Using PM2 ```javascript showLineNumbers title="ecosystem.config.js" module.exports = { apps: [ { name: 'nodejs-api', script: 'server.js', node_args: '--require ./instrumentation.js', instances: 'max', exec_mode: 'cluster', env: { NODE_ENV: 'production', OTEL_SERVICE_NAME: 'nodejs-api', OTEL_EXPORTER_OTLP_ENDPOINT: 'http://scout-collector:4318', }, }, ], }; ``` ### Troubleshooting #### Issue: No Traces Appearing in Scout Dashboard **Solutions:** 1. Verify collector connectivity: ```javascript showLineNumbers const { OTLPTraceExporter } = require('@opentelemetry/exporter-trace-otlp-http'); const exporter = new OTLPTraceExporter({ url: 'http://localhost:4318/v1/traces', }); // Send test span exporter .export([{ name: 'test-span' }], (result) => { console.log('Export result:', result); }) .catch(console.error); ``` 1. Enable debug logging: ```bash export OTEL_LOG_LEVEL=debug node --require ./instrumentation.js server.js ``` 1. Check if instrumentation loads before application: ```javascript // WRONG - instrumentation loaded too late const express = require('express'); require('./instrumentation'); // CORRECT - instrumentation loaded first require('./instrumentation'); const express = require('express'); ``` #### Issue: Missing Async Context in Traces **Solutions:** Ensure async operations use `async/await` or properly propagate context: ```javascript showLineNumbers const { context, trace } = require('@opentelemetry/api'); // WRONG - loses context async function processData() { setTimeout(() => { // This runs in different async context const span = trace.getActiveSpan(); // undefined! }, 1000); } // CORRECT - preserve context async function processData() { const activeContext = context.active(); setTimeout(() => { context.with(activeContext, () => { const span = trace.getActiveSpan(); // Works! }); }, 1000); } ``` #### Issue: High Memory Usage **Solutions:** 1. Reduce batch size and queue limits: ```javascript spanProcessor: new BatchSpanProcessor(traceExporter, { maxQueueSize: 1024, // Reduced from 2048 maxExportBatchSize: 256, // Reduced from 512 }), ``` 1. Disable unnecessary instrumentations: ```javascript instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, }), ]; ``` #### Issue: TypeScript Compilation Errors **Solutions:** Install type definitions: ```bash npm install --save-dev \ @types/node \ @types/express ``` ### Performance Considerations OpenTelemetry instrumentation adds minimal overhead to Node.js applications: **Expected Impact:** - **Latency**: +0.5-2ms per request (automatic instrumentation) - **CPU**: +2-5% in production with BatchSpanProcessor - **Memory**: +10-30MB for trace buffers and SDK - **Event Loop**: Minimal impact with proper batching #### Optimization Best Practices ##### 1. Use BatchSpanProcessor in Production ```javascript showLineNumbers const { BatchSpanProcessor } = require('@opentelemetry/sdk-trace-base'); spanProcessor: new BatchSpanProcessor(traceExporter, { maxQueueSize: 2048, scheduledDelayMillis: 5000, // Export every 5 seconds }); ``` ##### 2. Skip Health Check and Metrics Endpoints ```javascript showLineNumbers instrumentations: [ getNodeAutoInstrumentations({ '@opentelemetry/instrumentation-http': { ignoreIncomingRequestHook: (req) => { return ['/health', '/metrics', '/ready'].some((path) => req.url?.includes(path) ); }, }, }), ]; ``` ##### 3. Disable Filesystem and DNS Tracing ```javascript showLineNumbers '@opentelemetry/instrumentation-fs': { enabled: false }, '@opentelemetry/instrumentation-dns': { enabled: false }, ``` ### Security Considerations #### Sensitive Data in Spans Avoid capturing sensitive information in span attributes: ```javascript showLineNumbers // BAD - Exposes sensitive data span.setAttributes({ 'user.password': userPassword, 'credit_card.number': ccNumber, }); // GOOD - Use safe identifiers span.setAttributes({ 'user.id': userId, 'payment.method': 'credit_card', 'payment.last4': last4Digits, }); ``` #### HTTP Header Filtering Configure header filtering for sensitive authentication tokens: ```javascript showLineNumbers '@opentelemetry/instrumentation-http': { headersToSpanAttributes: { requestHeaders: ['content-type', 'user-agent'], responseHeaders: ['content-type'], }, }, ``` ### What's Next? #### Related Frameworks - **[Hono Instrumentation](./hono.md)** - edge/middleware, PostgreSQL, BullMQ - **[tRPC Instrumentation](./trpc.md)** - type-safe procedures, Prisma, PostgreSQL - **[Elysia Instrumentation](./elysia.md)** - Bun runtime, middleware, structured logging #### Framework-Specific Guides - **[Express.js Instrumentation](./express.md)** - Detailed Express 4.x/5.x setup with MongoDB, Redis, and WebSockets - **[NestJS Instrumentation](./nestjs.md)** - Enterprise DI framework with TypeORM and BullMQ - **[Fastify Instrumentation](./fastify.md)** - High-performance framework patterns #### Advanced Topics - [Custom JavaScript Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [Celery Background Jobs](./celery.md) - Distributed task tracing #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for latency and errors - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment ### FAQ #### Does OpenTelemetry work with TypeScript? Yes, OpenTelemetry fully supports TypeScript with official type definitions. Install `@types/node` and use `.ts` instrumentation files. #### What's the performance impact on Node.js applications? With BatchSpanProcessor, expect +0.5-2ms latency per request, +2-5% CPU, and +10-30MB memory. Impact is minimal for most production workloads. #### Can I use OpenTelemetry with Express, NestJS, and Fastify? Yes, auto-instrumentation supports all major Node.js frameworks including Express, NestJS, Fastify, Koa, and Hapi automatically. #### How do I trace async operations in Node.js with OpenTelemetry? OpenTelemetry automatically propagates context through async/await. For callbacks, manually propagate context using `context.with()`. #### Does auto-instrumentation support Mongoose, TypeORM, and Prisma? Yes, auto-instrumentation includes MongoDB (Mongoose), PostgreSQL (pg, Sequelize, TypeORM), MySQL, and Prisma ORM. #### Can I trace BullMQ and RabbitMQ jobs? Yes, auto-instrumentation includes BullMQ, RabbitMQ (amqplib), and other message queue libraries. #### How do I handle multi-tenant applications? Add tenant identifiers as span attributes: `span.setAttribute('tenant.id', tenantId)` and filter in Scout Dashboard. #### What's the difference between traces and metrics? Traces show request flow and timing (spans), while metrics aggregate performance data (counters, histograms). Both are supported by OpenTelemetry. ### Complete Example This guide provides framework-agnostic Node.js instrumentation patterns. For complete working examples with full application code, see the framework-specific guides: #### Express.js ```bash showLineNumbers title="Quick Start" git clone https://github.com/base-14/examples.git cd examples/nodejs/express-typescript-mongodb npm install docker-compose up -d # Run with tracing node --require ./instrumentation.js server.js ``` See **[Express.js Instrumentation](./express.md)** for the complete guide with MongoDB, Redis, WebSockets, and BullMQ integration. #### NestJS ```bash showLineNumbers title="Quick Start" git clone https://github.com/base-14/examples.git cd examples/nodejs/nestjs-postgres npm install docker-compose up -d npm run start:prod ``` See **[NestJS Instrumentation](./nestjs.md)** for enterprise patterns with TypeORM, BullMQ, and WebSocket gateway tracing. :::tip Complete Examples Repository All Node.js examples with Docker Compose, Kubernetes manifests, and production configurations are available at: **[https://github.com/base-14/examples/tree/main/nodejs](https://github.com/base-14/examples/tree/main/nodejs)** ::: Once instrumented, you can [monitor Node.js services with Scout APM](https://base14.io/scout/apm) — track event loop latency, async operation traces, and HTTP handler performance across your applications. ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [Node.js Examples Repository](https://github.com/base-14/examples/tree/main/nodejs) ### Related Guides - [Angular Instrumentation](./angular.md) - browser front-end over a Node.js API, emitting all three signals - [Express.js Instrumentation](./express.md) - Express-specific auto-instrumentation - [Custom Node.js Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual instrumentation patterns - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development with collector - [Kubernetes Deployment](../../collector-setup/kubernetes-helm-setup.md) - Production Kubernetes setup --- ## Quarkus OpenTelemetry Instrumentation - Native Image & REST Tracing :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Quarkus is a Kubernetes-native Java framework optimized for GraalVM and HotSpot, designed for cloud-native applications with supersonic startup times and incredibly low memory footprint. Unlike traditional Java frameworks, Quarkus provides **built-in OpenTelemetry support** through its extension ecosystem, making instrumentation significantly simpler than manual configuration. Quarkus is a Kubernetes-native JVM framework that competes with [Spring Boot](./spring-boot.md). [Micronaut](./micronaut.md) and [Ktor](./ktor.md) are other JVM options. This guide demonstrates how to instrument Quarkus applications with OpenTelemetry for comprehensive distributed tracing, metrics collection, and application performance monitoring. We'll cover both JVM mode and native image compilation scenarios, leveraging Quarkus's extension-based approach for zero-code auto-instrumentation of REST endpoints, database queries, and business logic. Quarkus's native compilation with GraalVM creates standalone executables with sub-second startup times, making it ideal for serverless deployments and microservices architectures. We'll explore how to maintain full observability in both development and production modes while taking advantage of Quarkus's unique performance characteristics. The example application includes JWT authentication, PostgreSQL integration with Hibernate ORM with Panache, and RESTful API endpoints—all automatically instrumented through Quarkus extensions. :::tip TL;DR Add the `quarkus-opentelemetry` extension via `./mvnw quarkus:add-extension`, then set `quarkus.otel.exporter.otlp.endpoint` in `application.properties`. REST endpoints, Hibernate Panache queries, and reactive Mutiny pipelines are traced automatically - no Java agent needed, and native GraalVM images are fully supported. ::: ### Who This Guide Is For This guide is designed for: - **Java Backend Developers** building microservices with Quarkus and needing production-grade observability without extensive configuration - **DevOps Engineers** deploying Quarkus native images to Kubernetes and requiring lightweight tracing with minimal memory overhead - **Platform Engineers** standardizing on Quarkus for cloud-native applications and seeking built-in OpenTelemetry integration - **Technical Leads** evaluating Quarkus versus Spring Boot and comparing instrumentation approaches with native compilation - **Site Reliability Engineers** optimizing application performance in containerized environments and monitoring sub-second startup times ### Overview This guide covers Quarkus OpenTelemetry instrumentation using the official Quarkus OpenTelemetry extension. The approach differs significantly from traditional Java frameworks by leveraging Quarkus's build-time optimization and extension ecosystem. #### What You'll Learn - Installing and configuring the Quarkus OpenTelemetry extension for automatic instrumentation - Understanding Quarkus's built-in OTEL support versus manual SDK configuration - Instrumenting REST endpoints, Hibernate queries, and business logic with zero code changes - Configuring native image compilation while maintaining full tracing capabilities - Setting up dev mode with live reload and automatic trace collection - Implementing custom spans and attributes using CDI and interceptors - Optimizing telemetry for supersonic startup and minimal memory footprint - Deploying instrumented native images to Docker and Kubernetes - Troubleshooting GraalVM reflection issues with tracing libraries #### Prerequisites **System Requirements:** - **Java:** 21+ (LTS recommended, 17+ supported) - **Quarkus:** 3.15+ (built-in OpenTelemetry support) - **GraalVM:** 21+ for native compilation (optional but recommended) - **Maven or Gradle:** Build tool for dependency management - **Docker:** For containerized deployments and native builds **Supported Quarkus Versions:** | Quarkus Version | Java Version | OpenTelemetry Extension | Native Image | Status | | --------------- | ------------ | ----------------------- | ------------ | ----------- | | 3.17+ | 21+ | 3.0+ | ✅ Full | Recommended | | 3.15-3.16 | 17+ | 3.0+ | ✅ Full | Supported | | 3.8-3.14 | 17+ | 2.0+ | ⚠️ Limited | Legacy | | 3.0-3.7 | 17+ | 1.x | ⚠️ Limited | EOL | | 2.x | 11+ | Not supported | ❌ None | EOL | **Instrumented Components:** Quarkus OpenTelemetry extension automatically instruments: - ✅ **REST Endpoints** - JAX-RS resources via RESTEasy Reactive - ✅ **Database Queries** - Hibernate ORM, Panache, and JDBC connections - ✅ **HTTP Clients** - REST Client and Vert.x HTTP client calls - ✅ **Messaging** - Kafka, AMQP, and reactive messaging streams - ✅ **CDI Beans** - Application-scoped and request-scoped beans - ✅ **Security** - JWT authentication and OIDC flows - ✅ **Reactive Streams** - Mutiny and SmallRye Reactive operators :::info Example Application This guide references the [quarkus-postgres example](https://github.com/base-14/examples/tree/main/java/quarkus-postgres) featuring: - **Framework**: Quarkus 3.17+ with RESTEasy Reactive - **Database**: PostgreSQL 18 with Hibernate ORM with Panache - **Authentication**: JWT bearer tokens with SmallRye JWT - **Architecture**: Supersonic startup (<50ms native), resource-oriented REST API - **Deployment**: Docker multi-stage builds and Kubernetes manifests ::: ### Installation & Setup Quarkus uses an **extension-based architecture** where OpenTelemetry support is added through the official `quarkus-opentelemetry` extension. This approach provides automatic instrumentation without requiring manual SDK initialization. import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; **Maven** Add the OpenTelemetry extension to your `pom.xml`: ```xml title="pom.xml" showLineNumbers io.quarkus quarkus-opentelemetry io.opentelemetry opentelemetry-exporter-otlp io.quarkus quarkus-jdbc-postgresql io.quarkus quarkus-hibernate-orm-panache ``` Install dependencies: ```bash ./mvnw clean install ``` **Gradle (Kotlin DSL)** Add the OpenTelemetry extension to `build.gradle.kts`: ```kotlin title="build.gradle.kts" showLineNumbers dependencies { // Quarkus OpenTelemetry Extension implementation("io.quarkus:quarkus-opentelemetry") // OTLP Exporter implementation("io.opentelemetry:opentelemetry-exporter-otlp") // Optional: Additional instrumentation implementation("io.quarkus:quarkus-jdbc-postgresql") implementation("io.quarkus:quarkus-hibernate-orm-panache") } ``` Install dependencies: ```bash ./gradlew build ``` **Quarkus CLI (Recommended)** Use the Quarkus CLI to add the extension: ```bash title="Terminal" showLineNumbers # Install Quarkus CLI (if not already installed) curl -Ls https://sh.jbang.dev | bash -s - trust add https://repo1.maven.org/maven2/io/quarkus/quarkus-cli/ curl -Ls https://sh.jbang.dev | bash -s - app install --fresh --force quarkus@quarkusio # Add OpenTelemetry extension to existing project quarkus extension add opentelemetry # Or create new project with extension quarkus create app com.example:my-app \ --extension=opentelemetry,resteasy-reactive-jackson,hibernate-orm-panache,jdbc-postgresql ``` This automatically updates `pom.xml` or `build.gradle.kts` with the correct dependencies. **Code.Quarkus.io Generator** Generate a new project with OpenTelemetry pre-configured: 1. Visit [code.quarkus.io](https://code.quarkus.io) 2. Select **Extensions**: - OpenTelemetry - RESTEasy Reactive - Hibernate ORM with Panache - JDBC Driver - PostgreSQL 3. Click **Generate your application** 4. Extract and run: ```bash cd my-quarkus-app ./mvnw quarkus:dev ``` :::tip Quarkus Dev Mode Quarkus's dev mode (`./mvnw quarkus:dev`) provides **live reload** with automatic trace collection. Changes to code are instantly reflected without restarting the application, making it ideal for iterative development with observability. ::: ### Configuration Quarkus OpenTelemetry configuration uses the standard `application.properties` file (or `application.yml`). Unlike Spring Boot, Quarkus performs build-time optimization, so many configurations are locked in during compilation. #### Basic Configuration ```properties title="src/main/resources/application.properties" showLineNumbers # Service identification quarkus.application.name=quarkus-order-service quarkus.application.version=1.0.0 # OpenTelemetry exporter configuration quarkus.otel.exporter.otlp.endpoint=http://localhost:4317 quarkus.otel.exporter.otlp.protocol=grpc quarkus.otel.traces.exporter=otlp # Service resource attributes quarkus.otel.resource.attributes=service.name=quarkus-order-service,service.version=1.0.0,deployment.environment=development,environment=development # Sampling (always-on for dev, probabilistic for production) quarkus.otel.traces.sampler=always_on # Database query tracing quarkus.datasource.jdbc.telemetry=true # Enable all instrumentation quarkus.otel.instrument.rest-client=true quarkus.otel.instrument.messaging=true quarkus.otel.instrument.security=true ``` #### Environment Variable Configuration Quarkus supports environment variable overrides using the standard naming convention: ```bash title="Terminal" showLineNumbers export QUARKUS_OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 export QUARKUS_OTEL_EXPORTER_OTLP_HEADERS=authorization=Bearer%20YOUR_API_KEY export QUARKUS_OTEL_TRACES_SAMPLER=traceidratio export QUARKUS_OTEL_TRACES_SAMPLER_ARG=0.1 export QUARKUS_DATASOURCE_JDBC_TELEMETRY=true ./mvnw quarkus:dev ``` #### Docker Compose Configuration ```yaml title="docker-compose.yml" showLineNumbers version: '3.9' services: quarkus-app: build: context: . dockerfile: src/main/docker/Dockerfile.jvm ports: - '8080:8080' environment: QUARKUS_OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4317 QUARKUS_OTEL_RESOURCE_ATTRIBUTES: >- service.name=quarkus-order-service, service.version=1.0.0, deployment.environment=docker, environment=docker QUARKUS_DATASOURCE_JDBC_URL: jdbc:postgresql://postgres:5432/orders QUARKUS_DATASOURCE_USERNAME: quarkus QUARKUS_DATASOURCE_PASSWORD: quarkus123 QUARKUS_DATASOURCE_JDBC_TELEMETRY: 'true' depends_on: - postgres - scout-collector postgres: image: postgres:18-alpine environment: POSTGRES_DB: orders POSTGRES_USER: quarkus POSTGRES_PASSWORD: quarkus123 volumes: - postgres_data:/var/lib/postgresql/data scout-collector: image: otel/opentelemetry-collector-contrib:latest command: ['--config=/etc/otel-collector-config.yaml'] volumes: - ./otel-collector-config.yaml:/etc/otel-collector-config.yaml ports: - '4317:4317' # OTLP gRPC volumes: postgres_data: ``` #### Profile-Based Configuration Quarkus uses **build profiles** for environment-specific configurations: ```properties title="src/main/resources/application.properties" showLineNumbers # Default configuration (dev mode) quarkus.otel.exporter.otlp.endpoint=http://localhost:4317 quarkus.otel.traces.sampler=always_on # Production profile %prod.quarkus.otel.exporter.otlp.endpoint=https://scout.base14.io:4317 %prod.quarkus.otel.exporter.otlp.headers=authorization=Bearer ${SCOUT_API_KEY} %prod.quarkus.otel.traces.sampler=traceidratio %prod.quarkus.otel.traces.sampler.arg=0.1 # Test profile (disable tracing) %test.quarkus.otel.sdk.disabled=true ``` Run with production profile: ```bash ./mvnw clean package -Dquarkus.profile=prod java -jar target/quarkus-app/quarkus-run.jar ``` :::info Scout Integration When using [Base14 Scout](https://base14.io/scout), configure the OTLP endpoint to point to your Scout Collector. Scout provides managed OpenTelemetry infrastructure optimized for Quarkus native images with minimal overhead. ::: ### Production Configuration Production deployments require optimized sampling, batch processing, and native image compilation for minimal resource usage. #### Optimized Application Properties ```properties title="src/main/resources/application.properties" showLineNumbers # Production profile configuration %prod.quarkus.application.name=quarkus-order-service %prod.quarkus.application.version=${APP_VERSION:1.0.0} # Scout Collector endpoint (production) %prod.quarkus.otel.exporter.otlp.endpoint=https://scout.base14.io:4317 %prod.quarkus.otel.exporter.otlp.headers=authorization=Bearer ${SCOUT_API_KEY} %prod.quarkus.otel.exporter.otlp.protocol=grpc %prod.quarkus.otel.exporter.otlp.timeout=10s # Sampling strategy (10% of traces) %prod.quarkus.otel.traces.sampler=traceidratio %prod.quarkus.otel.traces.sampler.arg=0.1 # Resource attributes %prod.quarkus.otel.resource.attributes=\ service.name=quarkus-order-service,\ service.version=${APP_VERSION:1.0.0},\ deployment.environment=demo,\ environment=demo,\ cloud.provider=aws,\ cloud.region=${AWS_REGION:us-east-1},\ k8s.cluster.name=${K8S_CLUSTER:production},\ k8s.namespace.name=${K8S_NAMESPACE:default},\ k8s.pod.name=${HOSTNAME} # Batch span processor (production optimization) %prod.quarkus.otel.bsp.schedule.delay=5000 %prod.quarkus.otel.bsp.max.queue.size=2048 %prod.quarkus.otel.bsp.max.export.batch.size=512 %prod.quarkus.otel.bsp.export.timeout=30s # Database telemetry %prod.quarkus.datasource.jdbc.telemetry=true # Disable dev-mode features %prod.quarkus.log.console.enable=true %prod.quarkus.log.console.json=true %prod.quarkus.log.level=INFO ``` #### Native Image Compilation Quarkus native images with GraalVM provide subsecond startup and minimal memory footprint while maintaining full tracing capabilities: ```bash title="Terminal" showLineNumbers # Build native executable with tracing support ./mvnw clean package -Pnative \ -Dquarkus.native.container-build=true \ -Dquarkus.native.builder-image=quay.io/quarkus/ubi-quarkus-mandrel-builder-image:jdk-21 # Test native executable ./target/quarkus-order-service-1.0.0-runner # Check startup time (should be <50ms) time ./target/quarkus-order-service-1.0.0-runner ``` #### Docker Multi-Stage Build (Native) ```dockerfile title="src/main/docker/Dockerfile.multistage" showLineNumbers ## Stage 1: Build native executable FROM quay.io/quarkus/ubi-quarkus-mandrel-builder-image:jdk-21 AS build COPY --chown=quarkus:quarkus . /code WORKDIR /code USER quarkus RUN ./mvnw clean package -Pnative -DskipTests \ -Dquarkus.native.container-build=true ## Stage 2: Create runtime image FROM quay.io/quarkus/quarkus-micro-image:2.0 WORKDIR /work/ COPY --from=build /code/target/*-runner /work/application # Set ownership RUN chown 1001 /work \ && chmod "g+rwX" /work \ && chown 1001:root /work # Expose port EXPOSE 8080 USER 1001 # Environment variables for OpenTelemetry ENV QUARKUS_OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4317 ENV QUARKUS_OTEL_TRACES_SAMPLER=traceidratio ENV QUARKUS_OTEL_TRACES_SAMPLER_ARG=0.1 ENTRYPOINT ["./application", "-Dquarkus.http.host=0.0.0.0"] ``` Build and run: ```bash docker build -f src/main/docker/Dockerfile.multistage -t quarkus-order-service:native . docker run -p 8080:8080 \ -e QUARKUS_OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 \ -e SCOUT_API_KEY=your_api_key \ quarkus-order-service:native ``` #### Kubernetes Deployment ```yaml title="k8s/deployment.yaml" showLineNumbers apiVersion: apps/v1 kind: Deployment metadata: name: quarkus-order-service labels: app: quarkus-order-service spec: replicas: 3 selector: matchLabels: app: quarkus-order-service template: metadata: labels: app: quarkus-order-service spec: containers: - name: quarkus-app image: quarkus-order-service:native ports: - containerPort: 8080 name: http env: - name: QUARKUS_OTEL_EXPORTER_OTLP_ENDPOINT value: 'http://scout-collector:4317' - name: SCOUT_API_KEY valueFrom: secretKeyRef: name: scout-credentials key: api-key - name: QUARKUS_OTEL_RESOURCE_ATTRIBUTES value: >- service.name=quarkus-order-service, service.version=1.0.0, deployment.environment=demo, environment=demo, k8s.cluster.name=production, k8s.namespace.name=$(K8S_NAMESPACE), k8s.pod.name=$(K8S_POD_NAME) - name: K8S_NAMESPACE valueFrom: fieldRef: fieldPath: metadata.namespace - name: K8S_POD_NAME valueFrom: fieldRef: fieldPath: metadata.name - name: QUARKUS_DATASOURCE_JDBC_URL value: jdbc:postgresql://postgres:5432/orders - name: QUARKUS_DATASOURCE_USERNAME valueFrom: secretKeyRef: name: postgres-credentials key: username - name: QUARKUS_DATASOURCE_PASSWORD valueFrom: secretKeyRef: name: postgres-credentials key: password - name: QUARKUS_DATASOURCE_JDBC_TELEMETRY value: 'true' resources: requests: memory: '128Mi' cpu: '100m' limits: memory: '256Mi' cpu: '500m' livenessProbe: httpGet: path: /q/health/live port: 8080 initialDelaySeconds: 5 periodSeconds: 10 readinessProbe: httpGet: path: /q/health/ready port: 8080 initialDelaySeconds: 5 periodSeconds: 10 --- apiVersion: v1 kind: Service metadata: name: quarkus-order-service spec: selector: app: quarkus-order-service ports: - protocol: TCP port: 80 targetPort: 8080 type: ClusterIP ``` #### Native Image Performance Metrics Expected performance characteristics with native compilation: | Metric | JVM Mode | Native Mode | Improvement | | -------------------- | -------- | ----------- | ----------- | | **Startup Time** | 2-3s | 30-50ms | 60x faster | | **Memory (RSS)** | 300-400M | 50-80M | 5x smaller | | **Image Size** | 200-300M | 50-70M | 4x smaller | | **First Request** | 500ms | 20ms | 25x faster | | **Tracing Overhead** | <2% | <1% | Negligible | ### Quarkus-Specific Features Quarkus provides automatic instrumentation for common frameworks and libraries through its extension ecosystem. No manual span creation is required for standard operations. #### REST Endpoint Auto-Instrumentation All JAX-RS resources are automatically instrumented: ```java title="src/main/java/com/example/OrderResource.java" showLineNumbers package com.example; import io.quarkus.security.Authenticated; import jakarta.inject.Inject; import jakarta.transaction.Transactional; import jakarta.ws.rs.*; import jakarta.ws.rs.core.MediaType; import jakarta.ws.rs.core.Response; import org.eclipse.microprofile.jwt.JsonWebToken; import java.util.List; @Path("/api/orders") @Produces(MediaType.APPLICATION_JSON) @Consumes(MediaType.APPLICATION_JSON) public class OrderResource { @Inject OrderService orderService; @Inject JsonWebToken jwt; // Automatically creates span: "GET /api/orders" @GET public List getAllOrders() { return orderService.findAll(); } // Span includes path parameter: "GET /api/orders/{id}" @GET @Path("/{id}") public Order getOrder(@PathParam("id") Long id) { Order order = orderService.findById(id); if (order == null) { throw new NotFoundException("Order not found"); } return order; } // Span includes authentication context @POST @Authenticated @Transactional public Response createOrder(Order order) { // JWT claims are automatically added to span attributes String userId = jwt.getClaim("sub"); order.setUserId(userId); Order created = orderService.create(order); return Response.status(Response.Status.CREATED).entity(created).build(); } // Exception information is captured in span @DELETE @Path("/{id}") @Authenticated @Transactional public Response deleteOrder(@PathParam("id") Long id) { orderService.delete(id); return Response.noContent().build(); } } ``` #### Hibernate ORM with Panache Instrumentation Database queries are automatically traced with full SQL visibility: ```java title="src/main/java/com/example/Order.java" showLineNumbers package com.example; import io.quarkus.hibernate.orm.panache.PanacheEntity; import jakarta.persistence.*; import java.math.BigDecimal; import java.time.LocalDateTime; @Entity @Table(name = "orders") public class Order extends PanacheEntity { @Column(nullable = false) public String userId; @Column(nullable = false) public String productName; @Column(nullable = false) public BigDecimal amount; @Column(nullable = false) public String status; @Column(name = "created_at", nullable = false) public LocalDateTime createdAt; // Automatically traced: "SELECT o FROM Order o WHERE o.userId = ?1" public static List findByUserId(String userId) { return find("userId", userId).list(); } // Automatically traced with query parameters public static List findByStatus(String status) { return list("status = ?1 ORDER BY createdAt DESC", status); } // Automatically traced with pagination public static List findRecent(int limit) { return find("ORDER BY createdAt DESC").page(0, limit).list(); } } ``` ```java title="src/main/java/com/example/OrderService.java" showLineNumbers package com.example; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.StatusCode; import io.opentelemetry.instrumentation.annotations.WithSpan; import jakarta.enterprise.context.ApplicationScoped; import jakarta.transaction.Transactional; import java.time.LocalDateTime; import java.util.List; @ApplicationScoped public class OrderService { // Database queries are automatically traced public List findAll() { return Order.listAll(); } public Order findById(Long id) { return Order.findById(id); } @Transactional public Order create(Order order) { order.createdAt = LocalDateTime.now(); order.status = "pending"; order.persist(); // Automatically traced INSERT query return order; } @Transactional public void delete(Long id) { Order order = Order.findById(id); if (order != null) { order.delete(); // Automatically traced DELETE query } } // Find orders by user with automatic tracing public List findByUser(String userId) { return Order.findByUserId(userId); } } ``` #### CDI Bean Instrumentation with @WithSpan For business logic that requires custom instrumentation, use the `@WithSpan` annotation: ```java title="src/main/java/com/example/PaymentService.java" showLineNumbers package com.example; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.StatusCode; import io.opentelemetry.instrumentation.annotations.SpanAttribute; import io.opentelemetry.instrumentation.annotations.WithSpan; import jakarta.enterprise.context.ApplicationScoped; import jakarta.inject.Inject; import java.math.BigDecimal; @ApplicationScoped public class PaymentService { @Inject ExternalPaymentGateway paymentGateway; // Creates custom span: "PaymentService.processPayment" @WithSpan("process_payment") public PaymentResult processPayment( @SpanAttribute("order.id") Long orderId, @SpanAttribute("payment.amount") BigDecimal amount, @SpanAttribute("user.id") String userId ) { Span currentSpan = Span.current(); try { // Add custom attributes currentSpan.setAttribute("payment.gateway", "stripe"); currentSpan.setAttribute("payment.currency", "USD"); // External API call (instrumented automatically) PaymentResult result = paymentGateway.charge(amount, userId); currentSpan.setAttribute("payment.transaction_id", result.getTransactionId()); currentSpan.setStatus(StatusCode.OK); return result; } catch (PaymentException e) { currentSpan.setStatus(StatusCode.ERROR, "Payment failed"); currentSpan.recordException(e); throw e; } } @WithSpan("validate_payment") public boolean validatePaymentMethod( @SpanAttribute("user.id") String userId, @SpanAttribute("payment.method") String method ) { // Validation logic automatically traced return paymentGateway.validateMethod(userId, method); } } ``` #### Reactive Streams with Mutiny Quarkus's reactive programming model (Mutiny) is automatically instrumented: ```java title="src/main/java/com/example/ReactiveOrderResource.java" showLineNumbers package com.example; import io.smallrye.mutiny.Uni; import jakarta.inject.Inject; import jakarta.ws.rs.*; import jakarta.ws.rs.core.MediaType; import java.util.List; @Path("/api/reactive/orders") @Produces(MediaType.APPLICATION_JSON) public class ReactiveOrderResource { @Inject ReactiveOrderService orderService; // Reactive chain is automatically traced @GET public Uni> getAllOrders() { return orderService.findAll(); } @POST public Uni createOrder(Order order) { return orderService.create(order) .onItem().transform(created -> { Span.current().setAttribute("order.id", created.id); return created; }); } } ``` ### Custom Instrumentation While Quarkus provides extensive auto-instrumentation, custom spans are needed for specific business logic or external integrations. #### Manual Span Creation with Tracer ```java title="src/main/java/com/example/InventoryService.java" showLineNumbers package com.example; import io.opentelemetry.api.GlobalOpenTelemetry; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.SpanKind; import io.opentelemetry.api.trace.StatusCode; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.context.Context; import io.opentelemetry.context.Scope; import jakarta.enterprise.context.ApplicationScoped; @ApplicationScoped public class InventoryService { private final Tracer tracer = GlobalOpenTelemetry.getTracer("inventory-service"); public boolean checkInventory(String productId, int quantity) { // Create custom span Span span = tracer.spanBuilder("check_inventory") .setSpanKind(SpanKind.INTERNAL) .setAttribute("product.id", productId) .setAttribute("inventory.requested_quantity", quantity) .startSpan(); try (Scope scope = span.makeCurrent()) { // Simulate inventory check int available = queryAvailableStock(productId); span.setAttribute("inventory.available_quantity", available); boolean inStock = available >= quantity; span.setAttribute("inventory.in_stock", inStock); if (inStock) { span.setStatus(StatusCode.OK); } else { span.setStatus(StatusCode.ERROR, "Insufficient stock"); } return inStock; } catch (Exception e) { span.setStatus(StatusCode.ERROR, e.getMessage()); span.recordException(e); throw e; } finally { span.end(); } } private int queryAvailableStock(String productId) { // Database query (automatically traced by Hibernate) return InventoryItem.find("productId", productId) .firstResult() .map(item -> ((InventoryItem) item).quantity) .orElse(0); } } ``` #### CDI Interceptor for Automatic Tracing Create a custom interceptor to trace all methods in specific beans: ```java title="src/main/java/com/example/Traced.java" showLineNumbers package com.example; import jakarta.interceptor.InterceptorBinding; import java.lang.annotation.ElementType; import java.lang.annotation.Retention; import java.lang.annotation.RetentionPolicy; import java.lang.annotation.Target; @InterceptorBinding @Target({ElementType.TYPE, ElementType.METHOD}) @Retention(RetentionPolicy.RUNTIME) public @interface Traced { } ``` ```java title="src/main/java/com/example/TracingInterceptor.java" showLineNumbers package com.example; import io.opentelemetry.api.GlobalOpenTelemetry; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.context.Scope; import jakarta.interceptor.AroundInvoke; import jakarta.interceptor.Interceptor; import jakarta.interceptor.InvocationContext; @Traced @Interceptor public class TracingInterceptor { private final Tracer tracer = GlobalOpenTelemetry.getTracer("custom-interceptor"); @AroundInvoke public Object trace(InvocationContext context) throws Exception { String className = context.getTarget().getClass().getSimpleName(); String methodName = context.getMethod().getName(); String spanName = className + "." + methodName; Span span = tracer.spanBuilder(spanName).startSpan(); try (Scope scope = span.makeCurrent()) { // Add method parameters as attributes Object[] params = context.getParameters(); for (int i = 0; i < params.length; i++) { span.setAttribute("param." + i, String.valueOf(params[i])); } return context.proceed(); } catch (Exception e) { span.recordException(e); throw e; } finally { span.end(); } } } ``` Use the interceptor: ```java title="src/main/java/com/example/NotificationService.java" showLineNumbers package com.example; import jakarta.enterprise.context.ApplicationScoped; @ApplicationScoped @Traced // All methods will be automatically traced public class NotificationService { public void sendOrderConfirmation(String email, Long orderId) { // This method is automatically traced by interceptor // Span name: "NotificationService.sendOrderConfirmation" System.out.println("Sending confirmation to " + email); } public void sendShippingNotification(String email, String trackingNumber) { // Also automatically traced System.out.println("Sending shipping notification"); } } ``` #### Context Propagation in Async Operations ```java title="src/main/java/com/example/AsyncOrderProcessor.java" showLineNumbers package com.example; import io.opentelemetry.api.trace.Span; import io.opentelemetry.context.Context; import io.smallrye.mutiny.Uni; import jakarta.enterprise.context.ApplicationScoped; import jakarta.inject.Inject; import java.util.concurrent.CompletableFuture; import java.util.concurrent.ExecutorService; import java.util.concurrent.Executors; @ApplicationScoped public class AsyncOrderProcessor { @Inject PaymentService paymentService; @Inject InventoryService inventoryService; private final ExecutorService executor = Executors.newFixedThreadPool(10); public CompletableFuture processOrderAsync(Order order) { // Capture current trace context Context currentContext = Context.current(); Span parentSpan = Span.current(); return CompletableFuture.supplyAsync(() -> { // Restore context in new thread try (var scope = currentContext.makeCurrent()) { parentSpan.setAttribute("async.processing", true); // Check inventory (traced in current context) boolean inStock = inventoryService.checkInventory( order.productName, 1 ); if (!inStock) { throw new RuntimeException("Out of stock"); } // Process payment (traced in current context) paymentService.processPayment( order.id, order.amount, order.userId ); order.status = "completed"; return order; } }, executor); } } ``` ### Running Your Application Quarkus provides multiple run modes optimized for different stages of development and deployment. #### Development Mode (Live Reload) ```bash title="Terminal" showLineNumbers # Start dev mode with live reload ./mvnw quarkus:dev # Dev mode features: # - Automatic recompilation on code changes # - Live reload without restart # - Dev UI at http://localhost:8080/q/dev # - Continuous testing with 'r' key # - Always-on sampling for all traces # Access application curl http://localhost:8080/api/orders # View Dev UI (includes OpenTelemetry info) open http://localhost:8080/q/dev ``` #### JVM Mode (Production) ```bash title="Terminal" showLineNumbers # Build JVM package ./mvnw clean package # Run with production profile java -Dquarkus.profile=prod \ -Dquarkus.otel.exporter.otlp.endpoint=https://scout.base14.io:4317 \ -Dquarkus.otel.exporter.otlp.headers=authorization=Bearer\ YOUR_API_KEY \ -jar target/quarkus-app/quarkus-run.jar ``` #### Native Mode (Supersonic Startup) ```bash title="Terminal" showLineNumbers # Build native executable ./mvnw clean package -Pnative \ -Dquarkus.native.container-build=true # Run native executable ./target/quarkus-order-service-1.0.0-runner # Expected output: # __ ____ __ _____ ___ __ ____ ______ # --/ __ \/ / / / _ | / _ \/ //_/ / / / __/ # -/ /_/ / /_/ / __ |/ , _/ ,< / /_/ /\ \ # --\___\_\____/_/ |_/_/|_/_/|_|\____/___/ # INFO [io.quarkus] (main) quarkus-order-service 1.0.0 native (powered by Quarkus 3.17.0) started in 0.045s # Memory footprint ps aux | grep quarkus-order-service # Expected: ~60MB RSS ``` #### Docker Deployment ```bash title="Terminal" showLineNumbers # Build Docker image (JVM mode) docker build -f src/main/docker/Dockerfile.jvm -t quarkus-app:jvm . # Build Docker image (Native mode) docker build -f src/main/docker/Dockerfile.multistage -t quarkus-app:native . # Run container with tracing docker run -p 8080:8080 \ -e QUARKUS_OTEL_EXPORTER_OTLP_ENDPOINT=https://scout.base14.io:4317 \ -e SCOUT_API_KEY=your_api_key \ -e QUARKUS_DATASOURCE_JDBC_URL=jdbc:postgresql://host.docker.internal:5432/orders \ -e QUARKUS_DATASOURCE_USERNAME=postgres \ -e QUARKUS_DATASOURCE_PASSWORD=postgres123 \ quarkus-app:native # Compare startup times time docker run -p 8081:8080 quarkus-app:jvm # ~2-3s time docker run -p 8082:8080 quarkus-app:native # ~0.05s (60x faster) ``` #### Kubernetes Deployment ```bash title="Terminal" showLineNumbers # Deploy to Kubernetes kubectl apply -f k8s/deployment.yaml # Check pod startup time kubectl logs -f deployment/quarkus-order-service # Expected for native image: # INFO [io.quarkus] (main) quarkus-order-service 1.0.0 native started in 0.042s # Check memory usage kubectl top pod -l app=quarkus-order-service # Expected for native image: # NAME CPU(cores) MEMORY(bytes) # quarkus-order-service-7d9f8b4c5-abc12 5m 62Mi # Test endpoint kubectl port-forward deployment/quarkus-order-service 8080:8080 curl http://localhost:8080/api/orders ``` ### Troubleshooting #### Issue 1: Native Image Build Fails with Reflection Errors **Symptoms:** ```text Error: Classes that should be initialized at run time got initialized during image building: io.opentelemetry.sdk.trace.SdkTracerProvider was unintentionally initialized at build time. ``` **Solution:** Configure GraalVM reflection for OpenTelemetry classes: ```json title="src/main/resources/reflection-config.json" showLineNumbers [ { "name": "io.opentelemetry.sdk.trace.SdkTracerProvider", "allDeclaredConstructors": true, "allPublicConstructors": true, "allDeclaredMethods": true, "allPublicMethods": true }, { "name": "io.opentelemetry.sdk.trace.export.BatchSpanProcessor", "allDeclaredConstructors": true, "allDeclaredMethods": true } ] ``` Add to `application.properties`: ```properties quarkus.native.additional-build-args=\ -H:ReflectionConfigurationFiles=reflection-config.json,\ --initialize-at-run-time=io.opentelemetry ``` #### Issue 2: No Traces Generated in Dev Mode **Symptoms:** Application starts successfully but no traces appear in collector. **Diagnosis:** ```bash # Check if OpenTelemetry extension is active ./mvnw quarkus:info | grep opentelemetry # Verify endpoint configuration curl http://localhost:8080/q/dev ``` **Solution:** Ensure extension is properly installed and configured: ```properties title="application.properties" showLineNumbers # Enable OpenTelemetry explicitly quarkus.otel.enabled=true quarkus.otel.sdk.disabled=false # Verify exporter configuration quarkus.otel.exporter.otlp.endpoint=http://localhost:4317 quarkus.otel.traces.exporter=otlp # Enable debug logging quarkus.log.category."io.opentelemetry".level=DEBUG ``` #### Issue 3: Database Queries Not Traced **Symptoms:** REST endpoints create spans but SQL queries are missing. **Solution:** Enable JDBC telemetry explicitly: ```properties title="application.properties" showLineNumbers # Enable database telemetry quarkus.datasource.jdbc.telemetry=true # For Hibernate, ensure logging is enabled (helps debugging) quarkus.hibernate-orm.log.sql=true quarkus.hibernate-orm.log.bind-parameters=true ``` Verify Hibernate instrumentation is active: ```java // In your service class import io.opentelemetry.api.trace.Span; public List findAll() { Span currentSpan = Span.current(); System.out.println("Current span: " + currentSpan.getSpanContext().getSpanId()); return Order.listAll(); // Should create child span for SQL query } ``` #### Issue 4: Native Image Startup Fails with OTLP Connection Error **Symptoms:** ```text Failed to export spans. The request could not be executed. Full error message: Failed to connect to scout.base14.io/192.168.1.1:4317 ``` **Solution:** The native image tries to connect immediately at startup. Use delayed initialization: ```properties title="application.properties" showLineNumbers # Delay span export to allow network initialization %prod.quarkus.otel.bsp.schedule.delay=5000 # Increase connection timeout %prod.quarkus.otel.exporter.otlp.timeout=30s # Add retry configuration %prod.quarkus.otel.exporter.otlp.retry.enabled=true %prod.quarkus.otel.exporter.otlp.retry.max.attempts=5 ``` #### Issue 5: High Memory Usage with Tracing **Symptoms:** Native image memory usage is higher than expected (>200MB instead of <100MB). **Solution:** Optimize batch span processor settings: ```properties title="application.properties" showLineNumbers # Reduce batch queue size %prod.quarkus.otel.bsp.max.queue.size=1024 %prod.quarkus.otel.bsp.max.export.batch.size=256 # Export more frequently %prod.quarkus.otel.bsp.schedule.delay=3000 # Use sampling to reduce volume %prod.quarkus.otel.traces.sampler=traceidratio %prod.quarkus.otel.traces.sampler.arg=0.1 ``` ### Security Considerations #### PII Data Masking Quarkus applications often handle sensitive data. Implement attribute filtering to prevent PII exposure: ```java title="src/main/java/com/example/SensitiveDataFilter.java" showLineNumbers package com.example; import io.opentelemetry.sdk.trace.SpanProcessor; import io.opentelemetry.sdk.trace.data.SpanData; import io.opentelemetry.context.Context; import jakarta.enterprise.context.ApplicationScoped; import jakarta.enterprise.inject.Produces; import java.util.regex.Pattern; @ApplicationScoped public class TelemetryConfig { private static final Pattern EMAIL_PATTERN = Pattern.compile( "[a-zA-Z0-9._%+-]+@[a-zA-Z0-9.-]+\\.[a-zA-Z]{2,}" ); private static final Pattern CREDIT_CARD_PATTERN = Pattern.compile( "\\b\\d{4}[\\s-]?\\d{4}[\\s-]?\\d{4}[\\s-]?\\d{4}\\b" ); @Produces public SpanProcessor piiMaskingProcessor() { return new SpanProcessor() { @Override public void onStart(Context parentContext, io.opentelemetry.sdk.trace.ReadWriteSpan span) { // Mask PII in span name String spanName = span.getName(); spanName = EMAIL_PATTERN.matcher(spanName).replaceAll("***@***.***"); spanName = CREDIT_CARD_PATTERN.matcher(spanName).replaceAll("****-****-****-****"); span.updateName(spanName); } @Override public boolean isStartRequired() { return true; } @Override public void onEnd(SpanData span) { // No action needed } @Override public boolean isEndRequired() { return false; } }; } } ``` #### SQL Query Obfuscation Database queries may contain sensitive values. Configure Hibernate to use parameterized queries: ```properties title="application.properties" showLineNumbers # Never log SQL parameter values in production %prod.quarkus.hibernate-orm.log.sql=false %prod.quarkus.hibernate-orm.log.bind-parameters=false # Use prepared statements to prevent SQL injection quarkus.datasource.jdbc.detect-statement-leaks=true ``` Implement custom attribute filter: ```java title="src/main/java/com/example/SqlSanitizer.java" showLineNumbers package com.example; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.context.Context; import jakarta.enterprise.context.ApplicationScoped; import jakarta.inject.Inject; @ApplicationScoped public class SecureQueryService { @Inject Tracer tracer; public void executeQuery(String sql, Object... params) { Span span = tracer.spanBuilder("database.query") .setAttribute("db.system", "postgresql") .setAttribute("db.operation", extractOperation(sql)) .setAttribute("db.sql.table", extractTable(sql)) // DO NOT add actual SQL or parameters .startSpan(); try (var scope = span.makeCurrent()) { // Execute query } finally { span.end(); } } private String extractOperation(String sql) { return sql.trim().split("\\s+")[0].toUpperCase(); } private String extractTable(String sql) { // Extract table name without exposing query details if (sql.contains("FROM")) { return sql.split("FROM")[1].trim().split("\\s+")[0]; } return "unknown"; } } ``` #### Authentication Token Redaction Prevent JWT tokens from being logged in traces: ```java title="src/main/java/com/example/AuthHeaderFilter.java" showLineNumbers package com.example; import io.opentelemetry.api.trace.Span; import jakarta.ws.rs.container.ContainerRequestContext; import jakarta.ws.rs.container.ContainerRequestFilter; import jakarta.ws.rs.ext.Provider; @Provider public class AuthHeaderFilter implements ContainerRequestFilter { @Override public void filter(ContainerRequestContext requestContext) { String authHeader = requestContext.getHeaderString("Authorization"); if (authHeader != null && authHeader.startsWith("Bearer ")) { Span currentSpan = Span.current(); // Only log that auth is present, not the token itself currentSpan.setAttribute("http.auth.present", true); currentSpan.setAttribute("http.auth.type", "Bearer"); // DO NOT: currentSpan.setAttribute("http.auth.token", authHeader); } } } ``` #### Compliance (GDPR, HIPAA) For regulated industries, implement comprehensive data governance: ```properties title="application.properties" showLineNumbers # Disable automatic attribute collection for user data %prod.quarkus.otel.traces.suppress-application-uris=/api/users/*,/api/health/* # Limit span attribute size to prevent large data exposure %prod.quarkus.otel.attribute.value.length.limit=256 %prod.quarkus.otel.attribute.count.limit=32 # Disable exporting to prevent data leaving infrastructure (optional) # %prod.quarkus.otel.traces.exporter=none ``` ### Performance Considerations #### Tracing Overhead Metrics Measured performance impact of OpenTelemetry on Quarkus native images: | Configuration | Latency (p50) | Latency (p99) | Throughput | Memory | | ------------------- | ------------- | ------------- | ---------- | ------- | | **No Tracing** | 5ms | 15ms | 15,000 rps | 60MB | | **Tracing (100%)** | 5.1ms (+2%) | 16ms (+6%) | 14,500 rps | 75MB | | **Tracing (10%)** | 5.0ms (<1%)| 15.2ms (+1%) | 14,900 rps | 65MB | | **Tracing (JVM)** | 12ms | 35ms | 8,000 rps | 350MB | **Key Findings:** - Native image tracing overhead: <1% with sampling - JVM mode overhead: 5-10% higher than native - Memory impact: +15MB for 100% sampling, +5MB for 10% sampling - Startup time: no measurable difference (<1ms) #### Optimization Strategies ##### 1. Optimize Batch Span Processor ```properties title="application.properties" showLineNumbers # Export every 5 seconds instead of default 5s %prod.quarkus.otel.bsp.schedule.delay=5000 # Reduce batch size to lower memory usage %prod.quarkus.otel.bsp.max.export.batch.size=256 # Limit queue size to prevent memory growth %prod.quarkus.otel.bsp.max.queue.size=1024 # Set export timeout %prod.quarkus.otel.bsp.export.timeout=10s ``` ##### 2. Disable Instrumentation for High-Volume Endpoints ```properties title="application.properties" showLineNumbers # Skip tracing for health checks and metrics %prod.quarkus.otel.traces.suppress-application-uris=/q/health/*,/q/metrics,/favicon.ico ``` ##### 3. Use Native Image for Maximum Performance Native compilation provides: - **60x faster startup** (3s → 50ms) - **5x lower memory** (350MB → 70MB) - **25% lower latency** (p99: 35ms → 15ms) - **<1% tracing overhead** vs 5-10% in JVM mode Build native image: ```bash ./mvnw clean package -Pnative \ -Dquarkus.native.container-build=true \ -Dquarkus.native.builder-image=quay.io/quarkus/ubi-quarkus-mandrel-builder-image:jdk-21 ``` ##### 4. Limit Span Attributes ```properties title="application.properties" showLineNumbers # Limit attribute value length (prevent large payloads) %prod.quarkus.otel.attribute.value.length.limit=512 # Limit number of attributes per span %prod.quarkus.otel.attribute.count.limit=64 # Limit number of events per span %prod.quarkus.otel.span.event.count.limit=32 ``` ### FAQ #### Does Quarkus require manual OpenTelemetry SDK initialization? **No.** Unlike Spring Boot or Express.js, Quarkus handles OpenTelemetry initialization automatically through the `quarkus-opentelemetry` extension. You only need to add the dependency and configure `application.properties`—no Java code required for basic instrumentation. #### Can I use Quarkus native images with OpenTelemetry? **Yes.** Quarkus fully supports OpenTelemetry in native images compiled with GraalVM. The extension handles all necessary reflection configuration and build-time initialization automatically. Native images provide subsecond startup and minimal memory footprint while maintaining full tracing capabilities. #### How do I instrument reactive code with Mutiny? **Automatically.** Quarkus's reactive programming model (Mutiny) is automatically instrumented by the OpenTelemetry extension. Context propagation across `Uni` and `Multi` chains works out of the box without manual configuration. #### What's the difference between Quarkus and Spring Boot OpenTelemetry setup? **Quarkus is simpler.** Quarkus uses extension-based configuration with zero Java code, while Spring Boot requires programmatic SDK initialization in a `@Configuration` class. Quarkus also provides built-in dev mode with live reload and automatic tracing, whereas Spring Boot requires DevTools or manual restarts. #### How do I add custom spans in Quarkus? Annotate the method with `@WithSpan`, and mark any parameters you want recorded with `@SpanAttribute`. Quarkus creates and closes the span for you: ```java import io.opentelemetry.instrumentation.annotations.WithSpan; import io.opentelemetry.instrumentation.annotations.SpanAttribute; @WithSpan("custom_operation") public void doSomething(@SpanAttribute("user.id") String userId) { // Automatically creates span } ``` Alternatively, inject `Tracer` and create spans manually: ```java import io.opentelemetry.api.GlobalOpenTelemetry; import io.opentelemetry.api.trace.Tracer; private final Tracer tracer = GlobalOpenTelemetry.getTracer("my-service"); ``` #### Can I disable OpenTelemetry in tests? Yes. Set `%test.quarkus.otel.sdk.disabled=true` to turn the SDK off for the whole test profile: ```properties title="application.properties" showLineNumbers # Disable OpenTelemetry in test profile %test.quarkus.otel.sdk.disabled=true ``` Or in test classes: ```java @QuarkusTest @TestProfile(NoTelemetryProfile.class) public class OrderServiceTest { // Tests run without tracing } ``` #### How do I trace Hibernate queries with Panache? **Automatically.** Enable JDBC telemetry: ```properties quarkus.datasource.jdbc.telemetry=true ``` All Panache methods (`findAll()`, `find()`, `persist()`, etc.) will automatically create child spans with SQL query details. #### What's the performance overhead of tracing in native images? **<1% with sampling.** Native images with 10% sampling add approximately 0.1ms to p50 latency and 15MB to memory usage. This is significantly lower than JVM mode (5-10% overhead) due to build-time optimizations. #### Can I use Quarkus OpenTelemetry with Kafka? **Yes.** Add the Kafka extension and enable messaging instrumentation: ```xml io.quarkus quarkus-smallrye-reactive-messaging-kafka ``` ```properties quarkus.otel.instrument.messaging=true ``` Kafka producers and consumers are automatically traced with message headers for context propagation. #### How do I send traces to Base14 Scout? Point `quarkus.otel.exporter.otlp.endpoint` at your Scout endpoint on port 4317 and pass your API key as a bearer token in the OTLP headers: ```properties title="application.properties" showLineNumbers %prod.quarkus.otel.exporter.otlp.endpoint=https://scout.base14.io:4317 %prod.quarkus.otel.exporter.otlp.headers=authorization=Bearer ${SCOUT_API_KEY} %prod.quarkus.otel.traces.exporter=otlp ``` Set the API key as an environment variable: ```bash export SCOUT_API_KEY=your_api_key ./target/quarkus-order-service-1.0.0-runner ``` #### Can I use OpenTelemetry metrics with Quarkus? Yes. Set `quarkus.otel.metrics.exporter=otlp` and the same extension exports metrics alongside traces: ```properties quarkus.otel.metrics.exporter=otlp ``` However, Quarkus also provides Micrometer integration which may be more mature for production use: ```xml io.quarkus quarkus-micrometer-registry-prometheus ``` #### How do I trace gRPC services in Quarkus? **Automatically.** Add the gRPC extension: ```xml io.quarkus quarkus-grpc ``` gRPC services and clients are automatically instrumented with full context propagation. ### What's Next Now that you have Quarkus instrumented with OpenTelemetry, explore advanced observability patterns: #### Advanced Tracing Topics - **[Custom Instrumentation for Java](/instrument/apps/custom-instrumentation/java)** \- Deep dive into manual span creation, context propagation, and baggage - **Distributed Tracing Best Practices** \- Sampling strategies, cardinality limits, and performance optimization - **[All framework guides](/instrument/apps/auto-instrumentation/)** \- Auto-instrumentation overview for every language #### Scout Platform Features - **[Base14 Scout Dashboard](https://base14.io/scout)** - Visualize Quarkus traces with native image performance metrics - **Service Map Visualization** - Understand microservice dependencies and latency bottlenecks - **Alert Configuration** - Set up SLO-based alerts for Quarkus services #### Deployment & Operations - **Kubernetes Instrumentation** - Monitor Quarkus pods with cluster-level observability - **Docker Instrumentation** - Trace containerized Quarkus applications - **AWS ECS/Fargate Deployment** - Deploy instrumented native images to serverless containers ### Complete Example Here's a complete Quarkus application with OpenTelemetry instrumentation, including REST endpoints, database access, authentication, and custom business logic. #### Project Structure ```text quarkus-order-service/ ├── src/main/ │ ├── java/com/example/ │ │ ├── Order.java │ │ ├── OrderResource.java │ │ ├── OrderService.java │ │ ├── PaymentService.java │ │ └── TracingInterceptor.java │ ├── resources/ │ │ ├── application.properties │ │ └── import.sql │ └── docker/ │ ├── Dockerfile.jvm │ └── Dockerfile.multistage ├── pom.xml └── docker-compose.yml ``` #### Complete Application Configuration ```properties title="src/main/resources/application.properties" showLineNumbers # Application metadata quarkus.application.name=quarkus-order-service quarkus.application.version=1.0.0 # HTTP configuration quarkus.http.port=8080 quarkus.http.cors=true # Database configuration quarkus.datasource.db-kind=postgresql quarkus.datasource.username=quarkus quarkus.datasource.password=quarkus123 quarkus.datasource.jdbc.url=jdbc:postgresql://localhost:5432/orders quarkus.datasource.jdbc.telemetry=true # Hibernate ORM quarkus.hibernate-orm.database.generation=drop-and-create quarkus.hibernate-orm.log.sql=true # OpenTelemetry - Development quarkus.otel.enabled=true quarkus.otel.exporter.otlp.endpoint=http://localhost:4317 quarkus.otel.exporter.otlp.protocol=grpc quarkus.otel.traces.exporter=otlp quarkus.otel.traces.sampler=always_on quarkus.otel.resource.attributes=service.name=quarkus-order-service,service.version=1.0.0,deployment.environment=development,environment=development # OpenTelemetry - Production %prod.quarkus.otel.exporter.otlp.endpoint=https://scout.base14.io:4317 %prod.quarkus.otel.exporter.otlp.headers=authorization=Bearer ${SCOUT_API_KEY} %prod.quarkus.otel.traces.sampler=traceidratio %prod.quarkus.otel.traces.sampler.arg=0.1 %prod.quarkus.otel.bsp.schedule.delay=5000 %prod.quarkus.otel.bsp.max.export.batch.size=512 # Security (JWT) mp.jwt.verify.publickey.location=https://your-auth-server.com/.well-known/jwks.json mp.jwt.verify.issuer=https://your-auth-server.com # Logging quarkus.log.console.format=%d{HH:mm:ss} %-5p traceId=%X{traceId}, spanId=%X{spanId} [%c{2.}] (%t) %s%e%n quarkus.log.level=INFO quarkus.log.category."io.opentelemetry".level=DEBUG ``` #### Running the Example ```bash title="Terminal" showLineNumbers # Clone the examples repository git clone https://github.com/base-14/examples.git cd examples/java/quarkus-postgres # Start dependencies (PostgreSQL, Scout Collector) docker-compose up -d postgres scout-collector # Run in dev mode ./mvnw quarkus:dev # Test endpoints (in another terminal) # Create order curl -X POST http://localhost:8080/api/orders \ -H "Content-Type: application/json" \ -d '{"productName":"Widget","amount":99.99,"userId":"user123"}' # Get all orders curl http://localhost:8080/api/orders # View traces in Scout Dashboard open https://scout.base14.io # Build native image ./mvnw clean package -Pnative -Dquarkus.native.container-build=true # Run native executable ./target/quarkus-order-service-1.0.0-runner ``` #### Expected Trace Output When you create an order via `POST /api/orders`, you should see a trace with this structure: ```text POST /api/orders (200ms) ├── PaymentService.processPayment (150ms) │ ├── validate_payment_method (20ms) │ └── external_payment_gateway_call (120ms) ├── SELECT FROM orders WHERE userId = ? (10ms) ├── INSERT INTO orders (...) (15ms) └── NotificationService.sendOrderConfirmation (5ms) ``` #### View Traces in Scout After running requests, view your traces in the Base14 Scout dashboard: 1. Navigate to [https://scout.base14.io](https://scout.base14.io) 2. Select the **quarkus-order-service** service 3. Explore trace timelines, database queries, and performance metrics 4. Set up alerts for latency thresholds or error rates :::tip Complete Example Repository The full example application with Docker Compose, Kubernetes manifests, and native image build scripts is available at: **[https://github.com/base-14/examples/tree/main/java/quarkus-postgres](https://github.com/base-14/examples/tree/main/java/quarkus-postgres)** This includes production-ready configurations for AWS ECS, Kubernetes, and Docker Swarm deployments. ::: ### References #### Official Documentation - **[Quarkus OpenTelemetry Extension](https://quarkus.io/guides/opentelemetry)** \- Official Quarkus OpenTelemetry guide - **[OpenTelemetry Java SDK](https://opentelemetry.io/docs/languages/java/)** \- Core OpenTelemetry Java documentation - **[GraalVM Native Image](https://www.graalvm.org/latest/reference-manual/native-image/)** \- Native compilation reference - **[Quarkus Configuration Reference](https://quarkus.io/guides/config-reference)** \- All configuration properties #### Related Guides - **[Spring Boot Instrumentation](/instrument/apps/auto-instrumentation/spring-boot)** \- Compare with traditional Spring Boot setup - **[Java Custom Instrumentation](/instrument/apps/custom-instrumentation/java)** \- Advanced manual instrumentation patterns - **[Go Instrumentation](/instrument/apps/auto-instrumentation/go)** \- Another compiled language with low overhead - **Kubernetes Deployment** \- Deploy instrumented Quarkus to Kubernetes #### Tools & Resources - **[Base14 Scout](https://base14.io/scout)** \- Managed OpenTelemetry platform for Quarkus - **[OpenTelemetry Demo](https://github.com/open-telemetry/opentelemetry-demo)** \- Reference microservices architecture - **[Quarkus CLI](https://quarkus.io/guides/cli-tooling)** \- Command-line tool for project management --- ## Rails Legacy OpenTelemetry Instrumentation - Rails 5 & 6 Setup Guide ## Ruby on Rails (Legacy) > This guide covers Ruby 3.0 (EOL: March 2024), Ruby 2.7 (EOL: March 2023), > Rails 6.1 (EOL: April 2024), and Rails 5.2 (EOL: June 2022) This guide covers OpenTelemetry instrumentation for legacy Rails applications running on end-of-life Ruby or Rails versions. The latest OTel Ruby gems now require Ruby >= 3.3, so users on older versions need pinned gem versions. While instrumentation works, these versions are no longer officially maintained or tested. This guide covers older Ruby on Rails versions. For current Rails, see the [main Rails guide](./rails.md). > ⚠️ **Production Warning**: Legacy versions have known limitations, security > vulnerabilities, and reduced performance. We strongly recommend upgrading to > supported versions. See [Migration Path](#migration-path) below. :::tip TL;DR For Ruby 3.0 and Rails 6.1, pin every OTel gem to its last compatible release and use `use_all()` with `BatchSpanProcessor`. For Ruby 2.7, skip the all-in-one gem, use individual instrumentation gems with older pinned versions, and switch to `SimpleSpanProcessor` to avoid threading issues. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Supported Legacy Versions This guide covers: - **Ruby 3.0** (EOL: March 2024) with **Rails 6.1** (EOL: April 2024) - **Ruby 2.7** (EOL: March 2023) - **Rails 5.2** (Maintenance ended: June 2022) - **Rails 6.0** with Ruby 2.7 **Not covered**: Ruby 2.6 or earlier, Rails 5.1 or earlier (no OpenTelemetry support) ### Ruby 3.0 / Rails 6.1 Ruby 3.0 reached EOL in March 2024 and Rails 6.1 in April 2024. Many production apps still run this combination. The latest OTel Ruby gems require Ruby >= 3.3, so you must pin gem versions to the last compatible releases. #### Why Pinned Versions? Starting in late 2024, the `opentelemetry-sdk` gem and its dependencies began raising their Ruby floor; current releases require Ruby >= 3.3. Running `bundle update` on a Ruby 3.0 app will pull incompatible versions and fail. The configuration below pins every OTel gem to its last Ruby 3.0–compatible release. #### Known Limitations - **Gem version ceiling**: OTel gems are pinned - no new features or bug fixes from upstream - **Logger 1.4.3 pin**: newer `logger` versions break `ActiveSupport::LoggerThreadSafeLevel` in Rails 6.1 - **Bundler 2.3.27**: required in Docker to handle default gem replacement correctly - **Bootsnap incompatible**: latest bootsnap (1.23.0+) does not support Ruby 3.0 #### Working Configuration ##### Gemfile Pin OTel gems to the last Ruby 3.0–compatible versions: ```ruby showLineNumbers title="Gemfile" source "https://rubygems.org" ruby "~> 3.0.0" gem "rails", "~> 6.1.0" gem "mysql2", "~> 0.5" gem "puma", "~> 5.0" gem "logger", "1.4.3" # OpenTelemetry - pinned to last Ruby 3.0 compatible versions gem "opentelemetry-api", "1.4.0" gem "opentelemetry-sdk", "1.7.0" gem "opentelemetry-exporter-otlp", "0.29.1" gem "opentelemetry-instrumentation-rails", "0.34.1" gem "opentelemetry-instrumentation-mysql2", "0.28.0" ``` > Swap `mysql2` for `pg` or `sqlite3` as needed. The OTel core gem versions stay > the same. ##### Initializer `use_all()` auto-instruments Rack, ActionPack, ActiveRecord, ActiveSupport, and your database adapter. The OTLP exporter reads its endpoint from environment variables, so no hardcoded URLs are needed: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require "opentelemetry/sdk" require "opentelemetry/exporter/otlp" OpenTelemetry::SDK.configure do |c| c.use_all() end ``` Unlike Ruby 2.7, Ruby 3.0 works fine with `BatchSpanProcessor` (the SDK default), so there is no need to switch to `SimpleSpanProcessor`. ##### Custom Spans Wrap business logic in custom spans for richer traces: ```ruby showLineNumbers title="app/controllers/items_controller.rb" class ItemsController < ApplicationController def create permitted = item_params tracer = OpenTelemetry.tracer_provider.tracer("items-controller") item = nil tracer.in_span("item.create", attributes: { "item.title" => permitted[:title] }) do |span| item = Item.create!(permitted) span.set_attribute("item.id", item.id) end render json: item, status: :created end private def item_params params.require(:item).permit(:title, :description) end end ``` Auto-instrumented DB calls nest under the custom span automatically: ```text HTTP POST /api/items └── item.create (custom span) ├── Item query (ActiveRecord auto) ├── select (MySQL2 auto) ├── begin (MySQL2 auto) ├── insert (MySQL2 auto) └── commit (MySQL2 auto) ``` ##### Error Handling and Log Correlation Record exceptions on the current span and inject trace context into logs so you can jump from a log line straight to the trace: ```ruby showLineNumbers title="app/controllers/application_controller.rb" class ApplicationController < ActionController::API rescue_from ActiveRecord::RecordNotFound, with: :handle_not_found private def handle_not_found(exception) span = OpenTelemetry::Trace.current_span span.record_exception(exception) span.status = OpenTelemetry::Trace::Status.error(exception.message) trace_id = span.context.hex_trace_id span_id = span.context.hex_span_id Rails.logger.error( "[trace_id=#{trace_id} span_id=#{span_id}] " \ "#{exception.class}: #{exception.message}" ) render json: { error: "Not found", trace_id: trace_id }, status: :not_found end end ``` #### Docker Setup ##### Dockerfile Pin bundler to 2.3.27 and skip bootsnap: ```docker showLineNumbers title="Dockerfile" ARG RUBY_VERSION=3.0 FROM docker.io/library/ruby:$RUBY_VERSION-slim WORKDIR /rails RUN apt-get update -qq && \ apt-get install --no-install-recommends -y \ build-essential default-libmysqlclient-dev \ curl git libyaml-dev pkg-config && \ rm -rf /var/lib/apt/lists /var/cache/apt/archives ENV RAILS_ENV="development" \ BUNDLE_PATH="/usr/local/bundle" RUN gem update --system 3.3.27 && gem install bundler -v 2.3.27 COPY Gemfile ./ RUN bundle install COPY . . EXPOSE 3000 CMD ["bin/rails", "server", "-b", "0.0.0.0"] ``` ##### Docker Compose The app, database, and OTel Collector run together. The key environment variables for telemetry are `OTEL_SERVICE_NAME` and `OTEL_EXPORTER_OTLP_ENDPOINT`: ```yaml showLineNumbers title="compose.yml" services: app: build: . environment: OTEL_SERVICE_NAME: ruby30-rails61-app OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf DATABASE_HOST: mysql depends_on: mysql: condition: service_healthy otel-collector: condition: service_started ports: - "3000:3000" otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 ports: - "4317:4317" - "4318:4318" mysql: image: mysql:8.0 environment: MYSQL_ROOT_PASSWORD: rootpassword MYSQL_DATABASE: rails_otel_dev healthcheck: test: ["CMD", "mysqladmin", "ping", "-h", "localhost", "-prootpassword"] interval: 5s timeout: 5s retries: 10 ``` A complete working example is available at [ruby30-rails61-mysql](https://github.com/base-14/examples/tree/main/ruby/ruby30-rails61-mysql). #### Ruby 3.0 Troubleshooting ##### Issue: `logger` gem conflicts on Rails 6.1 **Cause**: Newer `logger` versions remove methods that Rails 6.1's `ActiveSupport::LoggerThreadSafeLevel` depends on. **Solution**: Pin `logger` to `1.4.3` in your Gemfile (shown in the configuration above). ##### Issue: Bundler fails to replace default gems **Cause**: The system bundler in the Ruby 3.0 Docker image doesn't handle default gem replacement correctly. **Solution**: Upgrade bundler to 2.3.27 before `bundle install`: ```bash gem update --system 3.3.27 && gem install bundler -v 2.3.27 ``` ##### Issue: Bootsnap crashes on startup **Cause**: Bootsnap 1.23.0+ requires Ruby 3.1. **Solution**: Remove bootsnap from your Gemfile. Rails 6.1 runs fine without it — cold boot adds roughly 1–2 seconds. ##### Issue: No traces appearing **Cause**: OTel gems may have been updated past the Ruby 3.0 ceiling. **Solution**: Verify pinned versions match the table in [Compatibility Matrix](#compatibility-matrix) and run: ```bash bundle exec ruby -e "require 'opentelemetry/sdk'; puts OpenTelemetry::SDK::VERSION" # Expected: 1.7.0 ``` ### Ruby 2.7 Support #### Known Limitations - **Performance overhead**: 5-10ms per request (vs 1-3ms on Ruby 3.x) - **Threading issues**: BatchSpanProcessor may cause thread leaks - **Instrumentation gaps**: Some newer gems don't support Ruby 2.7 - **Security**: No security patches since March 2023 #### Working Configuration ##### Gemfile Lock to compatible OpenTelemetry versions: ```ruby showLineNumbers title="Gemfile" source 'https://rubygems.org' gem 'rails', '~> 6.1.0' # or your Rails version # OpenTelemetry - use older versions compatible with Ruby 2.7 gem 'opentelemetry-sdk', '~> 1.1.0' gem 'opentelemetry-exporter-otlp', '~> 0.21.0' # Use specific instrumentation gems instead of -all gem 'opentelemetry-instrumentation-rails', '~> 0.28.0' gem 'opentelemetry-instrumentation-action_pack', '~> 0.9.0' gem 'opentelemetry-instrumentation-active_record', '~> 0.6.0' gem 'opentelemetry-instrumentation-rack', '~> 0.23.0' # Optional: background jobs gem 'opentelemetry-instrumentation-sidekiq', '~> 0.25.0' # Optional: HTTP clients gem 'opentelemetry-instrumentation-net_http', '~> 0.22.0' ``` ##### Configuration Use SimpleSpanProcessor to avoid thread issues: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app-ruby27') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') # Use SimpleSpanProcessor to avoid Ruby 2.7 threading issues c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318') ) ) ) # Enable only core instrumentations c.use 'OpenTelemetry::Instrumentation::Rails' c.use 'OpenTelemetry::Instrumentation::ActionPack' c.use 'OpenTelemetry::Instrumentation::ActiveRecord' c.use 'OpenTelemetry::Instrumentation::Rack' # Optional: enable if you use Sidekiq # c.use 'OpenTelemetry::Instrumentation::Sidekiq' end TRACER = OpenTelemetry.tracer_provider.tracer('rails-app', '1.0.0') ``` #### Ruby 2.7 Troubleshooting ##### Issue: Thread deadlocks or memory leaks **Cause**: BatchSpanProcessor has known issues with Ruby 2.7's GVL **Solution**: Use SimpleSpanProcessor (shown in config above) **Trade-off**: Higher network overhead, but stable ##### Issue: Missing instrumentation for newer gems **Cause**: Newer instrumentation gems require Ruby 3.0+ **Solution**: Manually instrument using custom spans: ```ruby showLineNumbers title="app/controllers/application_controller.rb" class ApplicationController < ActionController::Base around_action :trace_request private def trace_request tracer = OpenTelemetry.tracer_provider.tracer('rails-app') tracer.in_span("#{controller_name}##{action_name}", kind: :server) do |span| span.set_attribute('http.method', request.method) span.set_attribute('http.route', "#{controller_name}##{action_name}") yield span.set_attribute('http.status_code', response.status) end end end ``` ### Rails 5.2 Support #### Known Limitations - **ActiveRecord**: May miss queries in some edge cases - **ActionCable**: Not instrumented - **ActiveJob**: Unreliable instrumentation - **Minitest**: No test instrumentation - **Compatibility**: Requires specific gem versions #### Working Configuration ##### Gemfile ```ruby showLineNumbers title="Gemfile" source 'https://rubygems.org' gem 'rails', '~> 5.2.8' # OpenTelemetry - lock to Rails 5.2 compatible versions gem 'opentelemetry-sdk', '~> 1.2.0' gem 'opentelemetry-exporter-otlp', '~> 0.25.0' # Rails 5.2 requires manual instrumentation selection gem 'opentelemetry-instrumentation-rack', '~> 0.23.0' gem 'opentelemetry-instrumentation-active_record', '~> 0.5.0' # Note: opentelemetry-instrumentation-rails doesn't fully support Rails 5.2 # Use Rack instrumentation instead ``` ##### Configuration Initialize before Rails application boots: ```ruby showLineNumbers title="config/application.rb" require_relative 'boot' require 'rails/all' # Initialize OpenTelemetry before Rails boots require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails52-app') c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318') ) ) ) # Only enable instrumentations that work with Rails 5.2 c.use 'OpenTelemetry::Instrumentation::Rack' c.use 'OpenTelemetry::Instrumentation::ActiveRecord' end Bundler.require(*Rails.groups) module YourApp class Application < Rails::Application config.load_defaults 5.2 # ... end end ``` #### Rails 5.2 Troubleshooting ##### Issue: Missing request traces **Cause**: Rails 5.2 doesn't have full Rails instrumentation support **Solution**: Use Rack instrumentation + manual controller tracing: ```ruby showLineNumbers title="app/controllers/application_controller.rb" class ApplicationController < ActionController::Base before_action :start_trace after_action :end_trace private def start_trace @tracer = OpenTelemetry.tracer_provider.tracer('rails-app') @current_span = @tracer.start_span( "#{controller_name}##{action_name}", kind: :server, attributes: { 'http.method' => request.method, 'http.url' => request.original_url, 'http.route' => "#{controller_name}##{action_name}" } ) OpenTelemetry::Trace.current_span = @current_span end def end_trace if @current_span @current_span.set_attribute('http.status_code', response.status) @current_span.finish end end end ``` ##### Issue: ActiveRecord queries not appearing **Cause**: ActiveRecord instrumentation version mismatch **Solution**: Verify gem version and test: ```bash showLineNumbers bundle exec rails console # Test ActiveRecord instrumentation require 'opentelemetry/sdk' tracer = OpenTelemetry.tracer_provider.tracer('test') tracer.in_span('test_query') do User.first end ``` If queries still missing, use manual instrumentation: ```ruby showLineNumbers title="app/models/concerns/traced_queries.rb" module TracedQueries extend ActiveSupport::Concern included do around_save :trace_save around_destroy :trace_destroy end private def trace_save tracer = OpenTelemetry.tracer_provider.tracer('active_record') tracer.in_span("#{self.class.name}.save", kind: :client) do |span| span.set_attribute('db.operation', 'save') span.set_attribute('db.table', self.class.table_name) yield end end def trace_destroy tracer = OpenTelemetry.tracer_provider.tracer('active_record') tracer.in_span("#{self.class.name}.destroy", kind: :client) do |span| span.set_attribute('db.operation', 'destroy') span.set_attribute('db.table', self.class.table_name) yield end end end # Include in your models class User < ApplicationRecord include TracedQueries end ``` ### Compatibility Matrix | Ruby Version | Rails Version | OpenTelemetry SDK | Status | Notes | | ------------ | ------------- | ----------------- | ---------- | ------------------------------------------ | | 3.0 | 6.1 | 1.7.0 (pinned) | ⚠️ Works | [Pinned gems required](#ruby-30--rails-61) | | 2.7 | 6.1 | 1.3.x | ⚠️ Works | Use SimpleSpanProcessor | | 2.7 | 6.0 | 1.3.x | ⚠️ Works | Use SimpleSpanProcessor | | 2.7 | 5.2 | 1.2.x | ⚠️ Limited | Manual instrumentation needed | | 3.0 | 5.2 | 1.2.x | ⚠️ Limited | Manual instrumentation needed | ### Feature Support Comparison | Feature | Ruby 3.1+ | Ruby 3.0 (pinned) | Ruby 2.7 | Rails 5.2 | | -------------------- | -------------- | ----------------- | ------------------ | ------------------ | | HTTP request tracing | ✅ Automatic | ✅ Automatic | ✅ Automatic | ⚠️ Manual | | ActiveRecord queries | ✅ Full | ✅ Full | ✅ Full | ⚠️ Partial | | `use_all()` | ✅ Latest gems | ✅ Pinned gems | ❌ Individual gems | ❌ Individual gems | | Background jobs | ✅ Sidekiq, DJ | ✅ Sidekiq, DJ | ✅ Sidekiq, DJ | ❌ No support | | ActionCable | ✅ Automatic | ✅ Automatic | ✅ Automatic | ❌ No support | | Custom spans | ✅ Full API | ✅ Full API | ✅ Full API | ✅ Full API | | BatchSpanProcessor | ✅ Recommended | ✅ Works | ❌ Unstable | ❌ Unstable | | Performance overhead | 1–3ms | 1–3ms | 5–10ms | 3–8ms | ### Migration Path #### Recommended Upgrade Order **Priority 1: Ruby Upgrade** (Biggest impact) ```text Ruby 2.7 → Ruby 3.0 → Ruby 3.1 → Ruby 3.2+ ``` **Key milestone - Ruby 3.1**: This is where you can drop pinned OTel gem versions and use the latest releases (including `opentelemetry-instrumentation-all`). **Benefits of upgrading past 3.0:** - Latest OTel gems with new features and bug fixes - Security patches - Stable BatchSpanProcessor (already works on 3.0) - All instrumentation gems supported without version pins **Rails compatibility:** - Rails 6.1 supports Ruby 3.0+ - Rails 7.0 requires Ruby 2.7+, supports Ruby 3.x - Rails 7.1 requires Ruby 2.7+, supports Ruby 3.x **Priority 2: Rails Upgrade** (After Ruby is upgraded) ```text Rails 5.2 → Rails 6.1 (LTS) → Rails 7.1 (Current LTS) ``` **Benefits:** - Better ActiveRecord instrumentation - ActionCable support - ActiveJob tracing - Future-proof #### Incremental Migration Strategy ##### Step 1: Upgrade Ruby to 3.0 (if on 2.7) ```bash rbenv install 3.0.7 rbenv local 3.0.7 bundle install bundle exec rspec ``` At this point you can switch from `SimpleSpanProcessor` to `BatchSpanProcessor` and use `use_all()` with pinned gems (see [Ruby 3.0 / Rails 6.1](#ruby-30--rails-61) above). ##### Step 2: Upgrade Ruby to 3.1+ (1–2 weeks) ```bash rbenv install 3.1.4 rbenv local 3.1.4 bundle install bundle exec rspec # Deploy to staging, monitor for 1 week ``` ##### Step 3: Update OpenTelemetry ```ruby # After Ruby 3.1 upgrade, remove version pins and use latest gem 'opentelemetry-sdk' gem 'opentelemetry-exporter-otlp' gem 'opentelemetry-instrumentation-all' ``` ##### Step 4: Switch to BatchSpanProcessor If you were on Ruby 2.7 with `SimpleSpanProcessor`, you can now safely switch to `BatchSpanProcessor` (already the default when using `use_all()` without explicit processor config): ```ruby c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT') ) ) ) ``` ##### Step 5: Upgrade Rails (2–4 weeks) ```bash # Follow Rails upgrade guides # Test thoroughly at each minor version Rails 5.2 → 6.0 → 6.1 → 7.0 → 7.1 ``` ### Production Deployment Recommendations #### For Ruby 2.7 Production Apps **If you must run Ruby 2.7 in production:** 1. **Use SimpleSpanProcessor** (avoid BatchSpanProcessor) 2. **Monitor memory usage** closely 3. **Plan Ruby upgrade** within 3-6 months 4. **Disable non-critical instrumentations** ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app-ruby27' c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT') ) ) ) # Only enable critical instrumentations c.use 'OpenTelemetry::Instrumentation::Rails' c.use 'OpenTelemetry::Instrumentation::ActiveRecord' end ``` #### For Rails 5.2 Production Apps **If you must run Rails 5.2 in production:** 1. **Test thoroughly in staging** (many edge cases) 2. **Implement manual instrumentation** for critical paths 3. **Monitor for missing traces** 4. **Plan Rails upgrade** to 6.1 LTS within 6 months 5. **Use health check endpoint** to verify instrumentation ```ruby showLineNumbers title="config/routes.rb" Rails.application.routes.draw do get '/health/telemetry', to: 'health#telemetry' end ``` ```ruby showLineNumbers title="app/controllers/health_controller.rb" class HealthController < ApplicationController def telemetry tracer = OpenTelemetry.tracer_provider.tracer('health_check') tracer.in_span('telemetry_health_check') do |span| span.set_attribute('rails.version', Rails.version) span.set_attribute('ruby.version', RUBY_VERSION) render json: { status: 'ok', rails_version: Rails.version, ruby_version: RUBY_VERSION, opentelemetry: { sdk_version: OpenTelemetry::SDK::VERSION, instrumented: instrumentation_status } } end end private def instrumentation_status { rack: defined?(OpenTelemetry::Instrumentation::Rack), active_record: defined?(OpenTelemetry::Instrumentation::ActiveRecord) } end end ``` ### FAQ #### Can I use the all-in-one instrumentation gem on Ruby 2.7 or 3.0? No. The `opentelemetry-instrumentation-all` meta-gem pulls the latest versions of its dependencies, and those now require Ruby 3.3 or later. On either runtime the install fails or resolves to gems that break at runtime. Install individual instrumentation gems with pinned versions instead. #### Will my legacy Rails app slow down with OpenTelemetry? Expect roughly 5-10ms of added latency per request on Ruby 2.7, against 1-3ms on Ruby 3.x. The gap comes from the older runtime, not from the SDK configuration. #### Is Rails 5.2 instrumentation production-ready? No. Rails 5.2 support is limited and untested. Upgrade to Rails 6.1 or later before relying on this instrumentation in production. #### Can I run Ruby 2.7 with Rails 7.1? Yes. Rails 7.1 requires Ruby 2.7.0 or newer, so the combination is supported. Rails 7.2 is the release that raises the floor to Ruby 3.1, so upgrade the Ruby runtime before going past 7.1. ### Getting Help #### Community Resources - **OpenTelemetry Ruby GitHub**: [Report issues](https://github.com/open-telemetry/opentelemetry-ruby/issues) - **Ruby Upgrade Guides**: [Rails upgrade guides](https://guides.rubyonrails.org/upgrading_ruby_on_rails.html) - **base14 Scout**: For help with legacy versions, [contact the base14 team](mailto:support@base14.io) ### Related Guides - [Ruby Custom Instrumentation](../custom-instrumentation/ruby.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development setup --- ## Rails OpenTelemetry Instrumentation - ActiveRecord & Sidekiq Tracing ## Ruby on Rails Implement OpenTelemetry instrumentation for Ruby on Rails applications to enable comprehensive application performance monitoring (APM), distributed tracing, and observability. This guide shows you how to auto-instrument your Rails application to collect traces and metrics from HTTP requests, database queries, background jobs, and custom business logic using the OpenTelemetry Ruby SDK. This guide covers modern Ruby on Rails. For older Rails versions, see the [legacy Rails guide](./rails-legacy.md). Rails applications benefit from automatic instrumentation of popular frameworks and libraries including ActiveRecord, ActionPack, ActionView, Redis, Sidekiq, and dozens of commonly used gems. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and identify database bottlenecks without significant code changes. Whether you're implementing observability for the first time, migrating from commercial APM solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Rails OpenTelemetry instrumentation. :::tip TL;DR Add `opentelemetry-sdk` and `opentelemetry-instrumentation-all` to your Gemfile, then call `OpenTelemetry::SDK.configure` with `use_all` in a Rails initializer - this automatically instruments ActiveRecord, ActionPack, Redis, Sidekiq, and most popular gems. Set `OTEL_SERVICE_NAME` and `OTEL_EXPORTER_OTLP_ENDPOINT` as environment variables, and configure the OTLP exporter to point at your Scout collector with no additional code changes. ::: > **Note:** This guide provides a practical Rails-focused overview based on the official OpenTelemetry documentation. For complete Ruby language information, please consult the [official OpenTelemetry Ruby documentation](https://opentelemetry.io/docs/languages/ruby/instrumentation). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Rails developers:** implementing observability and distributed tracing for the first time - **DevOps engineers:** deploying Rails applications with production monitoring requirements - **Engineering teams:** migrating from DataDog, New Relic, or other commercial APM solutions - **Developers:** debugging performance issues, slow database queries, or N+1 problems in Rails applications - **Platform teams:** standardizing observability across multiple Rails services ### Overview This comprehensive guide demonstrates how to: - Install and configure OpenTelemetry SDK for Rails applications - Set up automatic instrumentation for HTTP requests, database queries, and popular gems - Configure production-ready telemetry export to Scout Collector - Implement custom instrumentation for business-critical operations - Collect and analyze traces, metrics, and performance data - Deploy instrumented Rails applications to development, staging, and production environments - Troubleshoot common instrumentation issues and optimize performance - Secure sensitive data in telemetry exports ### Prerequisites > 📦 **Using older versions?** If you're on Ruby 3.0, Ruby 2.7, > Rails 6.1, Rails 5.x, or other legacy versions, see our > [Legacy Rails Instrumentation Guide](./rails-legacy.md) for > version-specific configurations and known limitations. Before starting, ensure you have: - **Ruby 3.1 or later** (CRuby), **JRuby 9.3.2.0+**, or **TruffleRuby 22.1+** - Ruby 3.0 requires pinned gem versions - see the [Legacy Guide](./rails-legacy.md#ruby-30--rails-61) - JRuby users should use the latest stable release - **Rails 6.0 or later** installed - Rails 7.0+ is recommended for optimal OpenTelemetry support - Rails 6.x is supported but may require additional configuration - **Bundler 2.0+** for dependency management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Production deployments should use a dedicated Scout Collector instance - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | |-----------|----------------|---------------------| | Ruby (CRuby) | 3.1.0 | 3.2.0+ | | JRuby | 9.3.2.0 | 9.4.0+ | | TruffleRuby | 22.1.0 | Latest stable | | Rails | 6.0.0 | 7.1.0+ | | Bundler | 2.0.0 | 2.4.0+ | ### Required Packages Install the following necessary packages by `gem install` or add it to `Gemfile` and run `bundle install`. ```ruby showLineNumbers gem 'opentelemetry-sdk' gem 'opentelemetry-exporter-otlp' gem 'opentelemetry-instrumentation-all' ``` ### Configuration OpenTelemetry Rails instrumentation can be configured using multiple approaches depending on your deployment requirements and preferences. Choose the method that best fits your application architecture. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The recommended approach is to create a dedicated OpenTelemetry initializer. This provides the most flexibility and keeps configuration separate from your application bootstrap. ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318') ) ) ) c.use_all end TRACER = OpenTelemetry.tracer_provider.tracer('rails-app', '1.0.0') ``` This configuration automatically instruments all supported Rails components and gems including: - **Rails Core**: ActionPack, ActionView, ActiveRecord, ActiveJob, ActionMailer - **HTTP Clients**: Net::HTTP, Faraday, HTTPClient, RestClient - **Databases**: PostgreSQL, MySQL, SQLite, MongoDB - **Caching**: Redis, Memcached - **Background Jobs**: Sidekiq, DelayedJob, Resque - **Web Servers**: Rack, Puma, Unicorn ```mdx-code-block ``` For applications using `config/environment.rb` for initialization, you can configure OpenTelemetry before Rails boots: ```ruby showLineNumbers title="config/environment.rb" require_relative 'application' require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.use_all end Rails.application.initialize! ``` This approach ensures OpenTelemetry is configured before any application code runs, which can be useful for capturing early initialization events. ```mdx-code-block ``` For containerized deployments or environments where configuration is managed externally, you can rely entirely on environment variables: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.use_all end ``` With this minimal configuration, use environment variables to control behavior: ```bash showLineNumbers export OTEL_SERVICE_NAME=rails-app export OTEL_SERVICE_VERSION=1.0.0 export OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 export OTEL_TRACES_EXPORTER=otlp export OTEL_METRICS_EXPORTER=otlp export OTEL_LOGS_LEVEL=info ``` ```mdx-code-block ``` If you want to enable only specific instrumentations or disable certain gems, use selective configuration: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' # Enable specific instrumentations only c.use 'OpenTelemetry::Instrumentation::Rails' c.use 'OpenTelemetry::Instrumentation::ActionPack' c.use 'OpenTelemetry::Instrumentation::ActiveRecord' c.use 'OpenTelemetry::Instrumentation::Redis' c.use 'OpenTelemetry::Instrumentation::Sidekiq' end ``` To use all instrumentations except specific ones: ```ruby showLineNumbers OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' # Use all but disable specific instrumentations c.use_all({ 'OpenTelemetry::Instrumentation::ActionCable' => { enabled: false }, 'OpenTelemetry::Instrumentation::MongoDB' => { enabled: false } }) end ``` ```mdx-code-block ``` #### Configuring Instrumentation Options Many instrumentations support additional configuration options: ```ruby showLineNumbers OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' c.use_all({ 'OpenTelemetry::Instrumentation::ActiveRecord' => { enabled: true, enable_statement_obfuscation: true, # Sanitize SQL in spans db_statement_limit: 2000 # Limit SQL length in attributes }, 'OpenTelemetry::Instrumentation::Redis' => { enabled: true, db_statement_limit: 500 }, 'OpenTelemetry::Instrumentation::Rack' => { enabled: true, untraced_endpoints: ['/health', '/metrics'] # Skip health checks } }) end ``` #### Scout Collector Integration When using Scout Collector, configure your Rails application to send telemetry data to the Scout Collector endpoint: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') # Scout Collector endpoint scout_endpoint = ENV.fetch('SCOUT_COLLECTOR_ENDPOINT', 'http://localhost:4318') c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: scout_endpoint, headers: { 'x-scout-api-key' => ENV['SCOUT_API_KEY'] }.compact ) ) ) c.use_all end ``` > **Scout Dashboard Integration**: After configuration, your traces will appear in the Scout Dashboard. Navigate to the Traces section to view request flows, identify performance bottlenecks, and analyze distributed transactions across your Rails services. ### Production Configuration Production deployments require additional configuration for optimal performance, reliability, and resource utilization. This section covers production-specific settings and best practices. #### Batch Span Processor (Recommended for Production) The `BatchSpanProcessor` is recommended for production environments as it reduces network overhead by batching span exports: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') # Configure batch span processor for production c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT') ), max_queue_size: 2048, # Maximum spans in queue schedule_delay: 5000, # Export every 5 seconds exporter_timeout: 30000, # 30 second timeout max_export_batch_size: 512 # Export up to 512 spans at once ) ) c.use_all end ``` **Benefits of BatchSpanProcessor:** - Reduces network requests by up to 95% - Lower CPU overhead compared to SimpleSpanProcessor - Prevents network saturation during traffic spikes - Configurable batching for optimal throughput #### Resource Attributes Add rich context to all telemetry data with resource attributes: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') # Add resource attributes for production context c.resource = OpenTelemetry::SDK::Resources::Resource.create({ 'deployment.environment' => Rails.env, 'environment' => Rails.env, 'service.namespace' => ENV.fetch('SERVICE_NAMESPACE', 'production'), 'service.instance.id' => Socket.gethostname, 'host.name' => Socket.gethostname, 'host.type' => ENV.fetch('HOST_TYPE', 'container'), 'cloud.provider' => ENV.fetch('CLOUD_PROVIDER', 'aws'), 'cloud.region' => ENV.fetch('AWS_REGION', 'us-east-1'), 'k8s.pod.name' => ENV['K8S_POD_NAME'], 'k8s.namespace.name' => ENV['K8S_NAMESPACE'] }.compact) c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT') ) ) ) c.use_all end ``` These attributes help you: - Filter traces by environment, region, or instance - Correlate issues with specific deployments - Analyze performance across different infrastructure - Debug production incidents faster #### Environment-Based Configuration Use environment variables to manage configuration across deployments: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| # Service identification c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') # Resource attributes c.resource = OpenTelemetry::SDK::Resources::Resource.create({ 'deployment.environment' => Rails.env, 'environment' => Rails.env, 'service.instance.id' => Socket.gethostname }) # Span processor selection based on environment exporter = OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318'), compression: ENV.fetch('OTEL_EXPORTER_OTLP_COMPRESSION', 'gzip'), timeout: ENV.fetch('OTEL_EXPORTER_OTLP_TIMEOUT', '10').to_i ) if Rails.env.production? # Use batch processor for production c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( exporter, max_queue_size: ENV.fetch('OTEL_BSP_MAX_QUEUE_SIZE', '2048').to_i, schedule_delay: ENV.fetch('OTEL_BSP_SCHEDULE_DELAY', '5000').to_i, max_export_batch_size: ENV.fetch('OTEL_BSP_MAX_EXPORT_BATCH_SIZE', '512').to_i ) ) else # Use simple processor for development (immediate export) c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new(exporter) ) end c.use_all end ``` #### Production Environment Variables Create a production environment configuration file: ```bash showLineNumbers title=".env.production" # Service Configuration OTEL_SERVICE_NAME=rails-app APP_VERSION=2.1.3 SERVICE_NAMESPACE=production # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4318 SCOUT_API_KEY=your-scout-api-key # Batch Processor Settings OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 # Exporter Settings OTEL_EXPORTER_OTLP_COMPRESSION=gzip OTEL_EXPORTER_OTLP_TIMEOUT=30 # Infrastructure Context CLOUD_PROVIDER=aws AWS_REGION=us-east-1 HOST_TYPE=container ``` #### Docker Production Configuration For containerized Rails applications, configure OpenTelemetry in your Docker setup: ```docker showLineNumbers title="Dockerfile" FROM ruby:3.2-alpine WORKDIR /app # Install dependencies COPY Gemfile Gemfile.lock ./ RUN bundle install --without development test # Copy application code COPY . . # Set production environment ENV RAILS_ENV=production ENV OTEL_SERVICE_NAME=rails-app ENV OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 # Precompile assets RUN bundle exec rails assets:precompile EXPOSE 3000 CMD ["bundle", "exec", "rails", "server", "-b", "0.0.0.0"] ``` ```yaml showLineNumbers title="docker-compose.yml" version: '3.8' services: rails-app: build: . environment: OTEL_SERVICE_NAME: rails-app APP_VERSION: ${APP_VERSION:-1.0.0} OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4318 DATABASE_URL: postgres://user:pass@postgres:5432/rails_production depends_on: - postgres - scout-collector ports: - "3000:3000" scout-collector: image: base14/scout-collector:latest ports: - "4318:4318" postgres: image: postgres:15-alpine environment: POSTGRES_PASSWORD: password ``` ### Metrics In addition to traces, OpenTelemetry can collect metrics from your Rails application to monitor resource utilization, request rates, error counts, and custom business metrics. #### Automatic HTTP Metrics The Rails instrumentation automatically collects HTTP-related metrics when you configure the metrics exporter: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' require 'opentelemetry/instrumentation/all' OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' # Configure trace export c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318') ) ) ) # Enable all instrumentations including metrics c.use_all end ``` **Automatic metrics include:** - `http.server.duration` - HTTP request duration histogram - `http.server.active_requests` - Currently active requests - `http.server.request.size` - HTTP request body size - `http.server.response.size` - HTTP response body size #### Custom Business Metrics Create custom metrics to track business-specific events and KPIs: ```ruby showLineNumbers title="app/services/order_service.rb" class OrderService def initialize @meter = OpenTelemetry.meter_provider.meter('order-service', '1.0.0') # Create custom metrics @orders_created = @meter.create_counter( 'orders.created', unit: 'orders', description: 'Total number of orders created' ) @order_value = @meter.create_histogram( 'orders.value', unit: 'USD', description: 'Distribution of order values' ) @active_orders = @meter.create_up_down_counter( 'orders.active', unit: 'orders', description: 'Currently active orders' ) end def create_order(params) order = Order.create!(params) # Increment orders created counter @orders_created.add(1, attributes: { 'order.type' => order.order_type, 'user.tier' => order.user.tier }) # Record order value @order_value.record(order.total_amount, attributes: { 'order.type' => order.order_type }) # Increment active orders @active_orders.add(1) order rescue => e @orders_created.add(1, attributes: { 'order.status' => 'failed', 'error.type' => e.class.name }) raise end end ``` #### Viewing Metrics in Scout Dashboard After configuring metrics export, navigate to the Scout Dashboard to: - View HTTP request rate and latency percentiles (p50, p95, p99) - Monitor error rates and status code distributions - Track custom business metrics in real-time - Create alerts based on metric thresholds - Build custom dashboards combining metrics and traces ### ActiveRecord Database Monitoring OpenTelemetry automatically instruments ActiveRecord to provide comprehensive database query monitoring and performance insights. #### Automatic Query Tracing Once configured, all ActiveRecord queries are automatically traced with detailed information: ```ruby # This query is automatically instrumented users = User.where(active: true).includes(:posts).limit(10) # The trace will show: # - SQL query statement # - Database name and operation # - Query duration # - Connection pool metrics ``` #### Configuring ActiveRecord Instrumentation Fine-tune ActiveRecord instrumentation for security and performance: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' c.use_all({ 'OpenTelemetry::Instrumentation::ActiveRecord' => { enabled: true, # Obfuscate SQL parameter values for security enable_statement_obfuscation: true, # Limit SQL statement length in spans db_statement_limit: 2000, # Include SQL comments in traces enable_sql_obfuscation: false } }) c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT') ) ) ) end ``` **ActiveRecord span attributes include:** - `db.system` - Database type (postgresql, mysql, sqlite) - `db.name` - Database name - `db.statement` - SQL query - `db.operation` - Operation type (SELECT, INSERT, UPDATE, DELETE) - `db.sql.table` - Table name - `db.connection.pool.name` - Connection pool identifier #### Detecting N+1 Queries Use OpenTelemetry traces to identify and fix N+1 query problems: ```ruby # Bad: N+1 query pattern (visible in traces as multiple DB spans) posts = Post.limit(10) posts.each do |post| puts post.author.name # Triggers 10 additional queries end # Good: Optimized with eager loading (single query in trace) posts = Post.includes(:author).limit(10) posts.each do |post| puts post.author.name # No additional queries end ``` In Scout Dashboard, N+1 queries will appear as: - Multiple identical database spans within a single request trace - High span count for simple operations - Repeated query patterns with different parameters #### Custom Database Spans Add custom instrumentation for complex database operations: ```ruby showLineNumbers title="app/services/report_generator.rb" class ReportGenerator def initialize @tracer = OpenTelemetry.tracer_provider.tracer('report-generator', '1.0.0') end def generate_monthly_report(month) @tracer.in_span('generate_monthly_report', attributes: { 'report.month' => month }, kind: :internal) do |span| @tracer.in_span('aggregate_sales_data') do sales_data = aggregate_sales(month) span.add_event('Sales data aggregated', attributes: { 'sales.total' => sales_data.sum, 'sales.count' => sales_data.count }) end @tracer.in_span('generate_charts') do charts = generate_charts(month) span.add_event('Charts generated', attributes: { 'charts.count' => charts.length }) end span.set_status(OpenTelemetry::Trace::Status.ok) span.add_attributes({ 'report.generated_at' => Time.current.iso8601 }) end end end ``` ### Custom Manual Instrumentation While automatic instrumentation covers most Rails components, you can add custom instrumentation for business logic, external API calls, or performance-critical code paths. #### Creating Custom Spans for Business Logic Instrument important business operations in controllers and services: ```ruby showLineNumbers title="app/controllers/orders_controller.rb" class OrdersController < ApplicationController before_action :set_tracer def create @tracer.in_span('create_order', attributes: { 'user.id' => current_user.id, 'order.items_count' => params[:items].length }, kind: :server) do |span| span.add_event('Validating order data') @order = Order.new(order_params) if @order.save span.add_event('Order saved successfully', attributes: { 'order.id' => @order.id, 'order.total' => @order.total_amount }) @tracer.in_span('process_payment') do |payment_span| payment_result = PaymentService.charge(current_user, @order.total_amount) payment_span.add_attributes({ 'payment.provider' => payment_result.provider, 'payment.status' => payment_result.status }) end @tracer.in_span('send_confirmation_email') do OrderMailer.confirmation(@order).deliver_later end span.set_status(OpenTelemetry::Trace::Status.ok) render json: @order, status: :created else span.add_event('Order validation failed', attributes: { 'validation.errors' => @order.errors.full_messages }) span.set_status( OpenTelemetry::Trace::Status.error("Validation failed: #{@order.errors.full_messages.join(', ')}") ) render json: @order.errors, status: :unprocessable_entity end end end private def set_tracer @tracer = OpenTelemetry.tracer_provider.tracer('orders-controller', '1.0.0') end def order_params params.require(:order).permit(:items, :shipping_address, :payment_method) end end ``` #### Adding Attributes to Current Spans Enrich existing spans with additional context: ```ruby showLineNumbers title="app/controllers/application_controller.rb" class ApplicationController < ActionController::Base before_action :add_user_context_to_trace private def add_user_context_to_trace return unless current_user # Get the current span current_span = OpenTelemetry::Trace.current_span # Add user context attributes current_span.add_attributes({ 'user.id' => current_user.id, 'user.email' => current_user.email, 'user.tier' => current_user.subscription_tier, 'user.authenticated' => true }) end end ``` #### Exception Handling and Error Tracking Capture exceptions in custom spans: ```ruby showLineNumbers title="app/services/external_api_client.rb" class ExternalApiClient def initialize @tracer = OpenTelemetry.tracer_provider.tracer('external-api-client', '1.0.0') end def fetch_data(endpoint) @tracer.in_span('external_api_call', attributes: { 'http.url' => endpoint, 'http.method' => 'GET' }, kind: :client) do |span| begin response = HTTP.get(endpoint) span.add_attributes({ 'http.status_code' => response.code, 'http.response_size' => response.body.length }) if response.code == 200 span.set_status(OpenTelemetry::Trace::Status.ok) JSON.parse(response.body) else span.set_status( OpenTelemetry::Trace::Status.error("HTTP #{response.code}") ) raise "API request failed with status #{response.code}" end rescue => e span.record_exception(e) span.set_status( OpenTelemetry::Trace::Status.error("Exception: #{e.message}") ) raise end end end end ``` #### Using Semantic Conventions Follow OpenTelemetry semantic conventions for consistent attribute naming: ```ruby showLineNumbers # HTTP semantic conventions span.add_attributes({ 'http.method' => 'POST', 'http.url' => 'https://api.example.com/users', 'http.status_code' => 201, 'http.request.header.content_type' => 'application/json' }) # Database semantic conventions span.add_attributes({ 'db.system' => 'postgresql', 'db.name' => 'production', 'db.statement' => 'SELECT * FROM users WHERE active = true', 'db.operation' => 'SELECT' }) # Messaging semantic conventions span.add_attributes({ 'messaging.system' => 'sidekiq', 'messaging.destination' => 'orders_queue', 'messaging.operation' => 'process' }) ``` ### Running Your Instrumented Application #### Development Mode For local development, use console output to verify instrumentation: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app-dev' if Rails.env.development? # Use console exporter for debugging require 'opentelemetry/exporter/otlp' c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new( OpenTelemetry::SDK::Trace::Export::ConsoleSpanExporter.new ) ) end c.use_all end ``` Start your Rails server: ```bash bundle exec rails server ``` You'll see span output in the console for each request: ``` ruby #, attributes={"http.method"=>"GET", "http.target"=>"/users", "http.status_code"=>200}> ``` #### Production Mode For production deployments, ensure the Scout Collector endpoint is properly configured: ```bash # Set environment variables export OTEL_SERVICE_NAME=rails-app-production export APP_VERSION=2.1.0 export OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com:4318 export SCOUT_API_KEY=your-scout-api-key export RAILS_ENV=production # Start Rails server bundle exec puma -C config/puma.rb ``` #### Docker Deployment Run your instrumented Rails application in Docker: ```bash # Build the image docker build -t rails-app:latest . # Run with Scout Collector docker run -d \ --name rails-app \ -e OTEL_SERVICE_NAME=rails-app \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 \ -e DATABASE_URL=postgres://user:pass@db:5432/production \ -p 3000:3000 \ rails-app:latest ``` Or use Docker Compose (see [Production Configuration](#production-configuration) section for complete example). ### Troubleshooting #### Verifying OpenTelemetry Installation Test your OpenTelemetry configuration in the Rails console: ```ruby # Start Rails console bundle exec rails console # Create a test span tracer = OpenTelemetry.tracer_provider.tracer('test') tracer.in_span('test_span') do |span| span.add_attributes({'test' => 'value'}) puts "OpenTelemetry is working!" puts "Tracer provider: #{OpenTelemetry.tracer_provider.class}" puts "Active span: #{span.name}" end # Check instrumented libraries OpenTelemetry.instrumentation_registry.each do |instrumentation| puts "#{instrumentation.name}: #{instrumentation.installed? ? 'INSTALLED' : 'NOT INSTALLED'}" end ``` Expected output: ``` ruby OpenTelemetry is working! Tracer provider: OpenTelemetry::SDK::Trace::TracerProvider Active span: test_span OpenTelemetry::Instrumentation::ActionPack: INSTALLED OpenTelemetry::Instrumentation::ActiveRecord: INSTALLED OpenTelemetry::Instrumentation::Rails: INSTALLED ``` #### Health Check Endpoint Create a health check endpoint to verify telemetry export: ```ruby showLineNumbers title="config/routes.rb" Rails.application.routes.draw do get '/health', to: 'health#check' get '/health/telemetry', to: 'health#telemetry' end ``` ```ruby showLineNumbers title="app/controllers/health_controller.rb" class HealthController < ApplicationController def check render json: { status: 'ok', timestamp: Time.current, environment: Rails.env } end def telemetry tracer = OpenTelemetry.tracer_provider.tracer('health_check') tracer.in_span('telemetry_health_check') do |span| span.add_attributes({ 'service.name' => ENV.fetch('OTEL_SERVICE_NAME', 'rails-app'), 'service.version' => ENV.fetch('APP_VERSION', '1.0.0'), 'rails.environment' => Rails.env, 'ruby.version' => RUBY_VERSION }) render json: { status: 'ok', telemetry: { tracer_provider: OpenTelemetry.tracer_provider.class.name, instrumented_gems: instrumented_gems_list } } end end private def instrumented_gems_list OpenTelemetry.instrumentation_registry.map do |i| { name: i.name, installed: i.installed? } end end end ``` Test the endpoint: ```bash curl http://localhost:3000/health/telemetry ``` #### Debug Mode Enable debug logging to troubleshoot instrumentation issues: ```bash export OTEL_LOG_LEVEL=debug bundle exec rails server ``` Or configure in the initializer: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' # Enable debug logging OpenTelemetry.logger.level = Logger::DEBUG if Rails.env.development? OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' c.use_all end ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify Scout Collector endpoint is reachable: ```bash curl -v http://scout-collector:4318/v1/traces ``` 2. Check environment variables: ```bash echo $OTEL_EXPORTER_OTLP_ENDPOINT echo $OTEL_SERVICE_NAME ``` 3. Enable debug logging and check for export errors 4. Verify network connectivity between Rails app and Scout Collector ##### Issue: Missing database query spans **Solutions:** 1. Ensure `opentelemetry-instrumentation-active_record` is installed 2. Verify ActiveRecord instrumentation is enabled: ```ruby OpenTelemetry.instrumentation_registry.lookup('OpenTelemetry::Instrumentation::ActiveRecord').installed? ``` 3. Check that `c.use_all` or specific ActiveRecord instrumentation is configured ##### Issue: High memory usage **Solutions:** 1. Use `BatchSpanProcessor` instead of `SimpleSpanProcessor` 2. Reduce `max_queue_size` in BatchSpanProcessor configuration 3. Limit span attribute sizes with `db_statement_limit` ##### Issue: Performance degradation **Solutions:** 1. Use `enable_statement_obfuscation` to reduce attribute processing 2. Skip health check endpoints with `untraced_endpoints` 3. Verify BatchSpanProcessor is configured (not SimpleSpanProcessor) ### Security Considerations #### Protecting Sensitive Data Avoid adding sensitive information to span attributes: ```ruby # Bad - exposes sensitive data span.add_attributes({ 'user.password' => user.password, # Never include passwords! 'credit_card.number' => params[:cc_number], # Never include payment data! 'user.ssn' => user.social_security_number # Never include PII! }) # Good - uses safe identifiers span.add_attributes({ 'user.id' => user.id, 'user.role' => user.role, 'payment.provider' => 'stripe', 'payment.status' => 'completed' }) ``` #### Sanitizing SQL Statements Enable SQL obfuscation to remove sensitive parameter values: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' c.use_all({ 'OpenTelemetry::Instrumentation::ActiveRecord' => { enabled: true, # Obfuscate SQL parameters enable_statement_obfuscation: true, # Limit SQL statement length db_statement_limit: 2000 } }) end ``` Before obfuscation: ```sql SELECT * FROM users WHERE email = 'user@example.com' AND password = 'secret123' ``` After obfuscation: ```sql SELECT * FROM users WHERE email = ? AND password = ? ``` #### Filtering Sensitive HTTP Headers Avoid capturing sensitive HTTP headers: ```ruby showLineNumbers title="config/initializers/opentelemetry.rb" OpenTelemetry::SDK.configure do |c| c.service_name = 'rails-app' c.use_all({ 'OpenTelemetry::Instrumentation::Rack' => { enabled: true, # Don't capture these headers untraced_endpoints: ['/health', '/metrics'], # Additional security configuration allowed_request_headers: ['content-type', 'accept'], allowed_response_headers: ['content-type'] } }) end ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - Implement data retention policies in Scout Dashboard - Configure SQL obfuscation for all database queries - Audit span attributes regularly for sensitive data leaks ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead to Rails applications: - **Average latency increase**: 1-3ms per request - **CPU overhead**: Less than 2% in production with BatchSpanProcessor - **Memory overhead**: ~50-100MB depending on queue size and traffic **Impact varies based on:** - Number of enabled instrumentations - Span processor type (Batch vs Simple) - Application request volume - Complexity of database queries #### Optimization Best Practices ##### 1. Use BatchSpanProcessor in Production ```ruby # Good - batches exports, low overhead c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new(exporter) ) # Bad - exports every span immediately, high overhead c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new(exporter) ) ``` ##### 2. Skip Non-Critical Endpoints ```ruby c.use_all({ 'OpenTelemetry::Instrumentation::Rack' => { untraced_endpoints: ['/health', '/metrics', '/favicon.ico'] } }) ``` ##### 3. Conditional Span Recording ```ruby span = OpenTelemetry::Trace.current_span # Only add expensive attributes if span is being recorded if span.recording? span.add_attributes(expensive_computation()) end ``` ##### 4. Limit Attribute Sizes ```ruby c.use_all({ 'OpenTelemetry::Instrumentation::ActiveRecord' => { db_statement_limit: 2000 # Truncate long SQL statements } }) ``` ### Frequently Asked Questions #### What is the performance impact of OpenTelemetry on Rails apps? With `BatchSpanProcessor`, expect roughly 1-3ms per request, a small CPU increase, and 10-30MB of additional memory. Sampling reduces it further in high-traffic apps. #### Which Rails versions are supported? OpenTelemetry supports Rails 6.0+ with Ruby 3.1+ (latest gems). Ruby 3.0 requires pinned gem versions - see the [Legacy Guide](./rails-legacy.md#ruby-30--rails-61). Rails 7.0+ with Ruby 3.1+ is recommended for optimal compatibility and performance. See the [Prerequisites](#prerequisites) section for detailed version compatibility. #### Can I use OpenTelemetry with Sidekiq or other background job processors? Yes! The `opentelemetry-instrumentation-all` gem includes automatic instrumentation for Sidekiq, DelayedJob, and Resque. Background jobs are traced automatically, and you can see the complete trace from HTTP request through asynchronous job processing in Scout Dashboard. #### Is OpenTelemetry compatible with Rack middleware? Yes, OpenTelemetry instruments at the Rack level, making it compatible with all Rack-based frameworks and middleware. Custom Rack middleware will appear in traces automatically. #### Can I use OpenTelemetry alongside other APM tools? Yes, OpenTelemetry can run alongside tools like New Relic or DataDog during migration periods. However, running multiple APM agents simultaneously will multiply the performance overhead, so plan your migration carefully. #### How do I handle multi-tenant Rails applications? Add tenant context to spans using attributes: ```ruby current_span.add_attributes({ 'tenant.id' => current_tenant.id, 'tenant.name' => current_tenant.name }) ``` Then filter traces by tenant in Scout Dashboard. #### What's the difference between traces and metrics? **Traces** show the complete request flow through your application with timing details for each operation. Use traces to debug slow requests and understand distributed transactions. **Metrics** provide aggregated statistics over time (request rate, error rate, latency percentiles). Use metrics for monitoring overall application health and setting alerts. #### How do I monitor N+1 database queries? OpenTelemetry traces automatically expose N+1 queries as multiple database spans within a single request trace. In Scout Dashboard, look for repeated query patterns or high span counts for simple operations. #### Can I customize which gems are instrumented? Yes! Use selective instrumentation instead of `c.use_all`: ```ruby c.use 'OpenTelemetry::Instrumentation::Rails' c.use 'OpenTelemetry::Instrumentation::ActiveRecord' c.use 'OpenTelemetry::Instrumentation::Redis' ``` Or disable specific instrumentations: ```ruby c.use_all({ 'OpenTelemetry::Instrumentation::MongoDB' => { enabled: false } }) ``` #### Can OpenTelemetry detect N+1 queries in Rails? Yes. OpenTelemetry traces each ActiveRecord query as a separate span. An N+1 query shows up in base14 Scout as many sequential database spans under a single parent span. ### What's Next? Now that your Rails application is instrumented with OpenTelemetry, explore these resources to maximize your observability: #### Advanced Topics - **[Custom Ruby Instrumentation](../custom-instrumentation/ruby.md)** - Deep dive into manual tracing, custom spans, and advanced instrumentation patterns - **[PostgreSQL Monitoring Best Practices](../../component/postgres.md)** - Optimize database observability with connection pooling metrics and query performance analysis - **[Redis Instrumentation](../../component/redis.md)** - Monitor caching performance and identify slow Redis operations #### Scout Platform Features - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - Set up intelligent alerts for error rates, latency thresholds, and custom metrics - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Set up Scout Collector for local development and testing ### Complete Example Here's a complete working example of a Rails 7 application with OpenTelemetry instrumentation: #### Gemfile ```ruby title="Gemfile" source 'https://rubygems.org' ruby '3.2.0' gem 'rails', '~> 7.1.0' gem 'pg', '~> 1.5' gem 'puma', '~> 6.0' # OpenTelemetry gems gem 'opentelemetry-sdk' gem 'opentelemetry-exporter-otlp' gem 'opentelemetry-instrumentation-all' group :development, :test do gem 'debug' gem 'rspec-rails' end ``` #### OpenTelemetry Initializer ```ruby title="config/initializers/opentelemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| # Service identification c.service_name = ENV.fetch('OTEL_SERVICE_NAME', 'rails-app') c.service_version = ENV.fetch('APP_VERSION', '1.0.0') # Resource attributes c.resource = OpenTelemetry::SDK::Resources::Resource.create({ 'deployment.environment' => Rails.env, 'environment' => Rails.env, 'service.instance.id' => Socket.gethostname }) # Configure exporter exporter = OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318') ) # Use batch processor for production, simple for development if Rails.env.production? c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new(exporter) ) else c.add_span_processor( OpenTelemetry::SDK::Trace::Export::SimpleSpanProcessor.new(exporter) ) end # Enable all instrumentations c.use_all end # Create global tracer TRACER = OpenTelemetry.tracer_provider.tracer('rails-app', '1.0.0') ``` #### Instrumented Controller ```ruby title="app/controllers/api/v1/orders_controller.rb" module Api module V1 class OrdersController < ApplicationController before_action :set_tracer def create @tracer.in_span('create_order') do |span| span.add_attributes({ 'user.id' => current_user.id, 'order.items_count' => order_params[:items].length }) @order = Order.create!(order_params) span.add_event('Order created', attributes: { 'order.id' => @order.id, 'order.total' => @order.total_amount }) render json: @order, status: :created end rescue => e OpenTelemetry::Trace.current_span.record_exception(e) render json: { error: e.message }, status: :unprocessable_entity end private def set_tracer @tracer = OpenTelemetry.tracer_provider.tracer('api', '1.0.0') end def order_params params.require(:order).permit(:items, :total_amount) end end end end ``` #### Environment Variables ```bash title=".env.production" OTEL_SERVICE_NAME=rails-app-production APP_VERSION=1.0.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 RAILS_ENV=production DATABASE_URL=postgres://user:pass@db:5432/production ``` This complete example is available in our [GitHub examples repository](https://github.com/base-14/examples/tree/main/ruby/rails8-sqlite). ### References [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Ruby Custom Instrumentation](../custom-instrumentation/ruby.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language --- ## React OpenTelemetry Instrumentation - Browser Tracing & Web Vitals ## React (web) `@base-14/scout-react` ships **zero-config Real User Monitoring** for React web apps. One npm install, one `Scout.initialize()` call, and every click, route change, fetch request, error, Core Web Vital, long task, and lifecycle transition is captured as an OpenTelemetry span / metric / log and exported via OTLP to your Scout endpoint. :::tip TL;DR `npm install @base-14/scout-react`, call `Scout.initialize({ serviceName, endpoint, headers })` once on app boot from the browser, optionally wrap your root with `ScoutErrorBoundary`. No manual `Scout.track(...)` calls needed — the SDK auto-instruments the entire browser-RUM surface. ::: :::info Mobile (React Native)? The same SDK package targets React Native. See the [React Native + React Web instrumentation guide](../../mobile/react-native.md) for the full reference including native crash capture, ANR detection, session-context persistence, and Expo integration. ::: :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What you get | Capability | Signal | How it's captured | |---|---|---| | Route / page navigation | `screen_view` ROOT span with `view.id`, `view.loading_type`, `view.referrer`, `screen_load` span with `screen.load_time` | History API + `popstate` listener | | Click tracking | `user_interaction` span (`type=click`, target selector, x/y, composed-path) | Capture-phase `click` listener | | Frustration signals | `user_interaction.action.frustration.type` (`rage_click` / `dead_click` / `error_click`) | DOM mutation observer + error correlation | | Fetch / XHR | `http.request` span with method / `url.full` / `http.response.status_code` / `http.duration_ms` / phase breakdown (DNS / connect / SSL / TTFB / download / redirect) / `network.protocol.name` / GraphQL operation parse / third-party provider classification (Stripe / CloudFront / Google Fonts / …) | Global `fetch` + `XMLHttpRequest` wrap + `PerformanceResourceTiming` | | Errors | `error` span with `error.id`, `error.type`, `error.message`, `error.stack_trace`, `error.fingerprint`, `error.causes_json`, `breadcrumbs` | `window.onerror` + `unhandledrejection` + `ErrorBoundary` | | `app_crash` (catch-all) | Emitted on next launch if the previous session didn't exit cleanly (`pagehide` never fired) | Session marker in `localStorage` | | Core Web Vitals | `web_vital` spans for LCP / INP / CLS / FCP / TTFB plus sub-parts (input_delay, processing_duration, presentation_delay for INP; load_delay, load_time, render_delay for LCP; layout-shift rects for CLS) | `web-vitals` library | | Long tasks | `long_task` span with `long_task.duration`, blocking_duration, render_start, style_and_layout_start, first_ui_event_timestamp, `scripts_json` | `PerformanceObserver('longtask')` + `long-animation-frame` (Chrome 123+) | | Frozen frames | `frozen_frame` span (≥ 700 ms blocks) | Same `PerformanceObserver` | | Scroll depth | `display.scroll.max_depth`, `max_scroll_height`, `max_scroll_height_time_ms` on `screen_view` | `window.scroll` listener with rAF coalescing | | CSP violations | `error` span with `error.csp.violated_directive`, `blocked_uri`, `disposition` | `securitypolicyviolation` event listener | | Page lifecycle | `app_paused` / `app_resumed` spans + `view.page_states_json` + `view.in_foreground_periods_json` | `visibilitychange` + `freeze` / `resume` events | | Background flush | All batched signals force-flushed on `visibilitychange=hidden` / `pagehide` | OTel `BatchSpanProcessor.forceFlush()` | | Resource attributes | `service.name`, `service.version`, `app.bundle_id`, `os.name`, `device.locale`, `network.connection.type`, `viewport.width/height`, `screen.pixel_ratio`, `a11y.*` (~20 accessibility flags) | Collected at init | | Identity + session attrs | `user.id` + `user.*` (from `setUser`), `account.id` (from `setAccount`), `feature_flag.*` (from `setFeatureFlag`), arbitrary session bag (from `setSessionAttributes`) | In-memory; merged into every span via `commonAttributes()` | | Retry with jitter | Exponential backoff with full jitter on 5xx / 408 / 429 / network errors; configurable max retries | `wrapWithRetry` exporter wrapper | | Offline buffer | Retry-exhausted batches persisted to `localStorage`; replayed on `Scout.initialize()` + `visibilitychange=visible` + `online` events | Per-signal FIFO item caps | ### Prerequisites - React 18 or 19 - A Scout collector / RUM ingest endpoint reachable from the browser ### Install ```bash npm install @base-14/scout-react ``` ### Initialize `Scout.initialize()` must run only in the browser. For pure CSR (Create React App, Vite without SSR), import it from your client entry. For any SSR setup (Next.js, Remix, Astro, Docusaurus, etc.), gate it with `useEffect` or a `typeof window !== 'undefined'` check so it doesn't run during SSR build time when `window` / `document` / `localStorage` are absent. #### Pure CSR (Vite, CRA) ```tsx title="src/main.tsx" import Scout from '@base-14/scout-react'; import { ScoutErrorBoundary } from '@base-14/scout-react/react'; import { BrowserRouter } from 'react-router-dom'; import { createRoot } from 'react-dom/client'; import App from './App'; await Scout.initialize({ serviceName: 'my-web-app', endpoint: 'https://rum.example.com//otlp', secure: true, headers: { Authorization: `Bearer ${import.meta.env.VITE_SCOUT_TOKEN}` }, }); createRoot(document.getElementById('root')!).render( , ); ``` #### SSR-aware (Next.js, Remix, Docusaurus, etc.) Run `Scout.initialize()` inside `useEffect` (which only fires on the client), or guard a top-level module with a `typeof window` check: ```tsx title="components/ScoutBootstrap.tsx (Next.js client component)" 'use client'; import { useEffect } from 'react'; import Scout from '@base-14/scout-react'; let initialized = false; export function ScoutBootstrap() { useEffect(() => { if (initialized) return; initialized = true; void Scout.initialize({ serviceName: 'my-web-app', endpoint: 'https://rum.example.com//otlp', secure: true, headers: { Authorization: `Bearer ${process.env.NEXT_PUBLIC_SCOUT_TOKEN}` }, }); }, []); return null; } ``` Render `` once at the root of your app. The `!initialized` flag is a belt-and-braces idempotency check — bundler HMR sometimes re-evaluates top-level modules. ### Identity + session attributes Once `Scout.initialize()` resolves you can attach identity and arbitrary session-scoped attributes. Every subsequent span, metric, and log carries them automatically until you change or clear them. ```ts // End-user identity → user.id + user. on every span Scout.setUser('user-123', { email: 'jane@example.com', plan: 'pro', }); // B2B tenant → account.id + account.name Scout.setAccount('acme-corp', 'Acme Corp'); // Session-scoped attribute bag (tenant id, build flavor, A/B cohort) Scout.setSessionAttributes({ 'tenant.id': 'acme', 'tenant.plan': 'enterprise', 'build.flavor': 'production', }); // Feature flags — attached to every error span emitted while flags are active Scout.setFeatureFlag('new-checkout', true); Scout.setFeatureFlag('checkout-variant', 'B'); // Manual breadcrumbs (rolling 100-entry trail attached to every crash / error) Scout.addBreadcrumb('checkout', 'added item to cart'); // Logs — go to the OTel log pipeline with active trace context Scout.logInfo('app booted'); Scout.logError('payment failed', { 'order.id': 'ord-42' }); // Manual error report (handled errors) try { /* … */ } catch (err) { Scout.reportError(err, { handled: true }); } ``` On sign-out, clear identity / account / flags: ```ts async function signOut() { await api.signOut(); Scout.clearUser(); Scout.clearAccount(); Scout.clearFeatureFlags(); Scout.clearSessionAttributes(); } ``` ### Filtering / PII redaction Pass a `beforeSend` callback that runs on every span / metric / log before export. Return `null` to drop, or mutate the attributes object to redact: ```ts Scout.initialize({ // … beforeSend: (event) => { if (String(event['url.full'] ?? '').includes('/health')) return null; delete event['user.email']; return event; }, }); ``` The callback sees per-span attributes only; resource attributes (e.g. `service.name`, `os.name`, `device.*`) aren't in the event payload. ### CORS The browser SDK exports via OTLP-HTTP. If your collector is on a different origin you'll need to allow CORS: ```yaml title="collector config" receivers: otlp: protocols: http: endpoint: 0.0.0.0:4318 cors: allowed_origins: - "https://my-web-app.example.com" ``` ### Auto-instrumentation toggles Every auto-instrumentation can be turned off independently — see the [React Native + React Web reference](../../mobile/react-native.md#auto-instrumentation-toggles) for the complete list (`enableErrorTracking`, `enableWebVitals`, `enableNetworkTracking`, `enableLongTaskDetection`, `enableAutoTapTracking`, `captureConsole`, etc.). All default to `true` except `captureConsole`. ### Sampling `sessionSampleRate` defaults to `1` (1% of sessions) to bound telemetry volume in production. Error / crash / ANR / UI-hang spans bypass this gate (controlled by `alwaysCaptureErrors`, default `true`) so failures are always captured regardless of sampling. Below `100`, full sessions are dropped (never partial) so traces stay coherent. For development bump it to `100`: ```ts Scout.initialize({ // … sessionSampleRate: 100, }); ``` ### Full reference For the complete configuration surface (transport, batching, retry, offline buffer, thresholds, resource attrs, every `enable*` toggle, native crash setup, ANR detection, troubleshooting, FAQ), see the [React Native + React Web instrumentation guide](../../mobile/react-native.md). The same package and the same APIs apply across React Native and React web — only the entry import (`@base-14/scout-react` vs `@base-14/scout-react/native`) and the runtime-specific captures differ. ### FAQ #### How do I add Real User Monitoring to a React web app with base14 Scout? Install `@base-14/scout-react`, call `Scout.initialize()` once on app boot from the browser, and wrap your root with `ScoutErrorBoundary`. Routes, clicks, fetch and XHR calls, errors, Core Web Vitals, and lifecycle events are then captured automatically and exported as OTLP traces, metrics, and logs to your Scout endpoint. #### What does scout-react capture without manual instrumentation? Clicks, route navigations, fetch and XHR requests, JavaScript errors, unhandled rejections, Core Web Vitals (LCP, INP, CLS, FCP, TTFB), long tasks, frozen frames, scroll depth, CSP violations, page lifecycle transitions, and frustration signals such as rage clicks, dead clicks, and error clicks. These arrive as OpenTelemetry spans, metrics, and logs. #### Does scout-react work with React Router, Next.js, Remix, or Docusaurus? Yes. The route tracker subscribes to the History API, which every SPA router uses. For SSR setups such as Next.js, Remix, Astro, and Docusaurus, initialize Scout inside a `useEffect` or guard it with a `typeof window` check so it runs only in the browser, never during SSR. #### How do I scrub PII before telemetry leaves the browser? Pass a `beforeSend` callback to `Scout.initialize()`. It runs on every span, metric, and log before export. Return `null` to drop the event, or mutate the attributes object to redact specific fields such as `user.email` or query-string tokens. ### What's next - [Configure your collector](../../collector-setup/docker-compose-example.md) to receive OTLP-HTTP on `:4318` - [React Native + React Web instrumentation reference](../../mobile/react-native.md) - [Custom JavaScript browser instrumentation](../custom-instrumentation/javascript-browser.md) for manual span / metric / log emission - [Query your RUM data in Scout](../../../operate/rum/getting-started.md) once sessions, errors, and Core Web Vitals are flowing ### References - Package: [`@base-14/scout-react`](https://www.npmjs.com/package/@base-14/scout-react) - Repository: [github.com/base-14/scout-react](https://github.com/base-14/scout-react) - OpenTelemetry JS SDK: [opentelemetry-js](https://github.com/open-telemetry/opentelemetry-js) - Web Vitals: [github.com/GoogleChrome/web-vitals](https://github.com/GoogleChrome/web-vitals) --- ## Slim Framework OpenTelemetry Instrumentation - Complete APM Setup Guide ## Slim Framework Implement OpenTelemetry instrumentation for Slim Framework applications to enable distributed tracing, metrics, and log correlation. This guide covers both Slim 4 (with fully automatic HTTP span instrumentation via `opentelemetry-auto-slim`) and Slim 3 (with a manual `TelemetryMiddleware`). The ~70% of setup that is identical between versions - environment variables, shutdown handlers, metrics, MongoDB auto-instrumentation, Docker deployment - is shared throughout. Slim is a PHP micro-framework, a lighter alternative to the full-featured [Laravel](./laravel.md) and [Symfony](./symfony.md). Slim applications benefit from the OpenTelemetry PHP ecosystem: automatic MongoDB query tracing, Monolog log-trace correlation, and business metric counters - all with minimal application code. Whether you are building a new API on Slim 4 or maintaining a legacy Slim 3 service, this guide provides production-ready configurations for PHP-FPM deployments with base14 Scout. :::tip TL;DR Install the `opentelemetry` and `mongodb` PECL extensions, then set `OTEL_PHP_AUTOLOAD_ENABLED=true` - this single env var activates the `opentelemetry-auto-slim` package, which automatically instruments every Slim 4 route with no middleware code. For Slim 3, add a `TelemetryMiddleware` manually since `opentelemetry-auto-slim` only supports Slim 4+. Register a shutdown handler in both cases to ensure PHP-FPM workers flush telemetry before recycling. ::: > **Note:** This guide provides a practical Slim-focused overview based on the > official OpenTelemetry documentation. For complete PHP language information, > please consult the > [official OpenTelemetry PHP documentation](https://opentelemetry.io/docs/languages/php/). :::warning Slim 3 End-of-Life Slim 3 is **EOL** and produces deprecation warnings on PHP 8.4. The `opentelemetry-auto-slim` package only supports Slim 4+, so HTTP spans must be created manually. If you are starting a new project, use Slim 4. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Prerequisites #### Compatibility Matrix | Component | Slim 4 | Slim 3 | | ------------------------- | ---------------------- | ----------------------------------------- | | PHP | 8.1+ (8.4 recommended) | 8.0–8.4 (deprecation warnings suppressed) | | Slim | ^4.15 | ~3.12 | | `opentelemetry-auto-slim` | ^1.3 | Not supported | | HTTP span creation | Automatic | Manual (`TelemetryMiddleware`) | | MongoDB auto-spans | ^0.2 | ^0.2 | | OTel SDK | ^1.13 | ^1.13 | | Composer | 2.0+ | 2.0+ | You also need: - **Scout Collector** configured and accessible - see [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - **Build tools** for compiling the OpenTelemetry PHP extension (gcc, make, autoconf) ### Installation #### Step 1: Install PHP Extensions ##### Ubuntu 24.04 LTS Install PHP 8.4, the build toolchain, and PECL in one shot: ```bash showLineNumbers sudo apt-get update sudo apt-get install -y php8.4-cli php8.4-dev php8.4-fpm php8.4-mbstring \ php8.4-zip php8.4-curl gcc make autoconf pkg-config libssl-dev ``` If your system ships an older PHP, add the [Ondrej PPA](https://launchpad.net/~ondrej/+archive/ubuntu/php) first: ```bash showLineNumbers sudo add-apt-repository ppa:ondrej/php sudo apt-get update ``` Then install the extensions: ```bash showLineNumbers sudo pecl install opentelemetry mongodb ``` ##### Other Platforms ```bash showLineNumbers # macOS (Homebrew) brew install php@8.4 autoconf pkg-config pecl install opentelemetry mongodb # Alpine Linux (Docker) - see Dockerfile section below apk add --no-cache autoconf build-base pecl install opentelemetry mongodb ``` ##### All Platforms Install Composer 2 if you haven't already: ```bash showLineNumbers php -r "copy('https://getcomposer.org/installer', 'composer-setup.php');" php composer-setup.php --install-dir=/usr/local/bin --filename=composer ``` ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Enable them in your `php.ini`: ```ini showLineNumbers title="php.ini" extension=opentelemetry extension=mongodb ``` ```mdx-code-block ``` Enable them in your `php.ini` and suppress Slim 3 deprecation warnings: ```ini showLineNumbers title="php.ini" extension=opentelemetry extension=mongodb ; Slim 3 triggers deprecation warnings on PHP 8.4 error_reporting = E_ALL & ~E_DEPRECATED & ~E_NOTICE ``` ```mdx-code-block ``` Verify the extensions are loaded: ```bash showLineNumbers php -m | grep -E "opentelemetry|mongodb" ``` #### Step 2: Install Composer Packages ```mdx-code-block ``` ```bash showLineNumbers composer require \ slim/slim:^4.15 \ slim/psr7:^1.8 \ php-di/php-di:^7.1 \ open-telemetry/sdk:^1.13 \ open-telemetry/exporter-otlp:^1.4 \ open-telemetry/opentelemetry-auto-slim:^1.3 \ open-telemetry/opentelemetry-auto-mongodb:^0.2 \ open-telemetry/opentelemetry-logger-monolog:^1.1 \ php-http/guzzle7-adapter:^1.1 \ guzzlehttp/psr7:^2.8 ``` ```mdx-code-block ``` ```bash showLineNumbers composer require \ slim/slim:~3.12 \ mongodb/mongodb:^2.0 \ monolog/monolog:^3.7 \ open-telemetry/sdk:^1.13 \ open-telemetry/exporter-otlp:^1.4 \ open-telemetry/opentelemetry-auto-mongodb:^0.2 \ open-telemetry/opentelemetry-logger-monolog:^1.1 \ php-http/guzzle7-adapter:^1.0 \ guzzlehttp/psr7:^2.7 ``` Note: `opentelemetry-auto-slim` is **not included** because it only supports Slim 4+. HTTP spans are created manually via `TelemetryMiddleware` (see [HTTP Request Tracing](#http-request-tracing)). ```mdx-code-block ``` **What each package does:** | Package | Purpose | | ------------------------------ | -------------------------------------------------------------- | | `open-telemetry/sdk` | Core OTel PHP SDK (creates spans, manages context) | | `open-telemetry/exporter-otlp` | Sends telemetry over OTLP protocol | | `opentelemetry-auto-slim` | Auto-instruments every Slim 4 route (Slim 4 only) | | `opentelemetry-auto-mongodb` | Auto-creates spans for all MongoDB driver operations | | `opentelemetry-logger-monolog` | Bridges Monolog to OTel logs with automatic `traceId`/`spanId` | | `guzzle7-adapter` + `psr7` | HTTP transport for the OTLP exporter | | `slim/psr7` + `php-di/php-di` | PSR-7 implementation and DI container (Slim 4 only) | ### Environment Variables OTel auto-configures via environment. Set these before your app starts (in your shell, `.env`, or process manager): ```bash showLineNumbers title=".env" OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=my-slim-app OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_RESOURCE_ATTRIBUTES=deployment.environment.name=development,environment=development ``` `OTEL_PHP_AUTOLOAD_ENABLED=true` is the key switch. It tells the SDK to automatically discover and activate the auto-instrumentation packages (like `opentelemetry-auto-slim` and `opentelemetry-auto-mongodb`). Without it, the packages sit idle. Scout's UI filters on the lowercase `environment` key, so emit it alongside the OTel-native `deployment.environment.name`. The legacy `deployment.environment` is still accepted for backward compatibility. #### Scout Collector Integration When using Scout Collector, configure your application to send telemetry data with OAuth2 authentication: ```bash showLineNumbers title=".env" # Scout Collector Configuration OTEL_EXPORTER_OTLP_ENDPOINT=https://your-tenant.base14.io/v1/traces SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token ``` > **Scout Dashboard Integration**: After configuration, your traces will appear > in the Scout Dashboard. Navigate to the Traces section to view request flows, > identify performance bottlenecks, and analyze distributed transactions. ### Bootstrap ```mdx-code-block ``` Slim 4 requires a PSR-11 container (PHP-DI) and explicit PSR-7 implementation (`slim/psr7`): ```php showLineNumbers title="public/index.php" safeLoad(); require __DIR__ . '/../src/telemetry.php'; $builder = new ContainerBuilder(); $builder->addDefinitions(__DIR__ . '/../src/dependencies.php'); $container = $builder->build(); AppFactory::setContainer($container); $app = AppFactory::create(); $app->addBodyParsingMiddleware(); $app->addRoutingMiddleware(); require __DIR__ . '/../src/routes.php'; $displayErrors = ($_ENV['APP_DEBUG'] ?? 'false') === 'true'; $errorMiddleware = $app->addErrorMiddleware($displayErrors, true, true); $errorMiddleware->setDefaultErrorHandler(function ( ServerRequestInterface $request, \Throwable $exception, bool $displayErrorDetails, bool $logErrors, bool $logErrorDetails, ) use ($app) { // Record exception on the auto-instrumented span $span = Span::getCurrent(); $span->recordException($exception); $span->setStatus(StatusCode::STATUS_ERROR, $exception->getMessage()); $logger = $app->getContainer()->get(LoggerInterface::class); $logger->error('Unhandled exception', [ 'exception' => $exception, 'uri' => (string) $request->getUri(), 'method' => $request->getMethod(), ]); $statusCode = 500; if ($exception instanceof \Slim\Exception\HttpException) { $statusCode = $exception->getCode(); } $response = $app->getResponseFactory()->createResponse($statusCode); $response->getBody()->write(json_encode([ 'error' => $displayErrorDetails ? $exception->getMessage() : 'Internal server error', ])); return $response->withHeader('Content-Type', 'application/json'); }); $app->run(); ``` The three lines that record exceptions on spans (`Span::getCurrent()`, `recordException`, `setStatus`) are the only OTel API calls in the entire entry point. ```mdx-code-block ``` The `determineRouteBeforeAppMiddleware` setting is required so the `TelemetryMiddleware` can read the matched route pattern for span names: ```php showLineNumbers title="public/index.php" safeLoad(); require __DIR__ . '/../src/telemetry.php'; $app = new \Slim\App([ 'settings' => [ 'displayErrorDetails' => ($_ENV['APP_DEBUG'] ?? 'false') === 'true', 'addContentLengthHeader' => false, 'determineRouteBeforeAppMiddleware' => true, ], ]); require __DIR__ . '/../src/dependencies.php'; require __DIR__ . '/../src/middleware.php'; require __DIR__ . '/../src/routes.php'; $container = $app->getContainer(); $container['errorHandler'] = function ($c) { return function ($request, $response, $exception) use ($c) { $span = Span::getCurrent(); $span->recordException($exception); $span->setStatus(StatusCode::STATUS_ERROR, $exception->getMessage()); $c['logger']->error('Unhandled exception', [ 'exception' => $exception, 'uri' => (string) $request->getUri(), 'method' => $request->getMethod(), ]); $statusCode = 500; if (method_exists($exception, 'getCode') && $exception->getCode() >= 400 && $exception->getCode() < 600) { $statusCode = $exception->getCode(); } return $response->withJson([ 'error' => ($c['settings']['displayErrorDetails'] ?? false) ? $exception->getMessage() : 'Internal server error', ], $statusCode); }; }; $app->run(); ``` ```mdx-code-block ``` ### Shutdown Handler PHP-FPM workers can exit before the SDK flushes its buffer. Register a shutdown handler to force-flush all providers on process exit. Create `src/Telemetry/Shutdown.php`: ```php showLineNumbers title="src/Telemetry/Shutdown.php" forceFlush(); } $mp = Globals::meterProvider(); if (method_exists($mp, 'forceFlush')) { $mp->forceFlush(); } $lp = Globals::loggerProvider(); if (method_exists($lp, 'forceFlush')) { $lp->forceFlush(); } } catch (\Throwable $e) { // swallow - nothing useful to do during shutdown } } } ``` Bootstrap it early in `src/telemetry.php`: ```php showLineNumbers title="src/telemetry.php" ``` With `opentelemetry-auto-slim` installed and `OTEL_PHP_AUTOLOAD_ENABLED=true`, every Slim 4 request automatically gets: - Root **SERVER** span named `{METHOD} {route_pattern}` (e.g. `GET /api/articles/{id}`) - Controller-level **INTERNAL** span (e.g. `ArticleController::create`) - Semantic convention attributes (`http.request.method`, `http.route`, `http.response.status_code`) - HTTP server metrics (request duration, count) No manual `TelemetryMiddleware` is needed. Do not create duplicate HTTP metrics or span attributes in your application code. ```mdx-code-block ``` Since `opentelemetry-auto-slim` doesn't support Slim 3, create a `TelemetryMiddleware` that produces the root SERVER span: ```php showLineNumbers title="src/Middleware/TelemetryMiddleware.php" getTracer('slim-app'); $method = $request->getMethod(); $path = (string) $request->getUri()->getPath(); $span = $tracer->spanBuilder("$method $path") ->setSpanKind(SpanKind::KIND_SERVER) ->startSpan(); $scope = $span->activate(); $span->setAttribute('http.method', $method); $span->setAttribute('http.url', (string) $request->getUri()); $span->setAttribute('http.target', $path); $span->setAttribute('http.scheme', $request->getUri()->getScheme() ?: 'http'); try { $response = $next($request, $response); // After route matching, update span name to low-cardinality pattern $route = $request->getAttribute('route'); if ($route instanceof \Slim\Route) { $pattern = $route->getPattern(); $span->updateName("$method $pattern"); $span->setAttribute('http.route', $pattern); } $span->setAttribute('http.status_code', $response->getStatusCode()); return $response; } catch (\Exception $e) { $span->recordException($e); $span->setStatus( StatusCode::STATUS_ERROR, $e->getMessage()); throw $e; } finally { $scope->detach(); $span->end(); } } } ``` Key details: - **Scope activation** (`$span->activate()`) makes this span current so MongoDB auto-spans and logs inherit the trace context - Span name updates from `/api/articles/abc123` to `/api/articles/{id}` after route matching (low cardinality) - `determineRouteBeforeAppMiddleware: true` in your Slim 3 settings is **required** for the route pattern to be available inside middleware - Do **not** set `STATUS_OK` on success - leave as UNSET per OTel conventions - Do **not** set `STATUS_ERROR` for 4xx responses - only for exceptions Register it in `src/middleware.php`: ```php showLineNumbers title="src/middleware.php" $app->add(new \App\Middleware\TelemetryMiddleware()); ``` Because Slim 3 uses LIFO middleware ordering, `TelemetryMiddleware` should be added **last** so it executes **first** (outermost wrapper). ```mdx-code-block ``` ### Structured Logging Wire Monolog with both a stderr handler and the OTel log handler. The OTel handler automatically attaches `traceId` and `spanId` to every log record - no manual trace context injection needed. ```mdx-code-block ``` Register in your PHP-DI definitions file: ```php showLineNumbers title="src/dependencies.php" use Monolog\Handler\StreamHandler; use Monolog\Logger; use OpenTelemetry\API\Globals; use OpenTelemetry\Contrib\Logs\Monolog\Handler as OtelLogHandler; use Psr\Log\LoggerInterface; return [ LoggerInterface::class => function () { $logger = new Logger('slim-app'); $logger->pushHandler(new StreamHandler('php://stderr', Logger::DEBUG)); try { $loggerProvider = Globals::loggerProvider(); $logger->pushHandler(new OtelLogHandler($loggerProvider, Logger::DEBUG)); } catch (\Throwable $e) { // OTel logger not available, continue with stderr only } return $logger; }, ]; ``` ```mdx-code-block ``` Register on the Pimple container: ```php showLineNumbers title="src/dependencies.php" use Monolog\Handler\StreamHandler; use Monolog\Logger; use OpenTelemetry\API\Globals; use OpenTelemetry\Contrib\Logs\Monolog\Handler as OtelLogHandler; $container['logger'] = function () { $logger = new Logger('slim-app'); $logger->pushHandler(new StreamHandler('php://stderr', Logger::DEBUG)); try { $loggerProvider = Globals::loggerProvider(); $logger->pushHandler(new OtelLogHandler($loggerProvider, Logger::DEBUG)); } catch (\Throwable $e) { // OTel logger not available, continue with stderr only } return $logger; }; ``` ```mdx-code-block ``` ### Business Metrics Create counters with an `app.` namespace prefix. Do not add a `.total` suffix to counter names - the metric type already implies it. Use attributes for differentiation instead of separate counters: ```php showLineNumbers title="src/Telemetry/Metrics.php" getMeter('slim-app') ->createCounter($name, '', $desc); } public static function authLoginSuccess(): void { self::getCounter('app.user.logins', 'User login attempts') ->add(1, ['result' => 'success']); } public static function authLoginFailed(): void { self::getCounter('app.user.logins', 'User login attempts') ->add(1, ['result' => 'failure']); } public static function articleCreated(): void { self::getCounter('app.article.creates', 'Articles created') ->add(1); } } ``` Call these from your controllers as one-liners: ```php Metrics::authLoginSuccess(); Metrics::articleCreated(); ``` No span wrapping or trace context management needed. The counters flow through the `OTEL_METRICS_EXPORTER=otlp` pipeline independently. ### Controllers With auto-instrumentation (Slim 4) or `TelemetryMiddleware` (Slim 3) handling traces, your controllers stay focused on business logic. The only OTel touchpoint is the `Metrics::*` one-liner calls. ```mdx-code-block ``` ```php showLineNumbers title="src/Controllers/ArticleController.php" use App\Repositories\ArticleRepository; use App\Telemetry\Metrics; use Psr\Log\LoggerInterface; class ArticleController { private ArticleRepository $articleRepository; private LoggerInterface $logger; public function __construct( ArticleRepository $articleRepository, LoggerInterface $logger ) { $this->articleRepository = $articleRepository; $this->logger = $logger; } public function create($request, $response) { $data = $request->getParsedBody(); $user = $request->getAttribute('user'); if (empty($data['title']) || empty($data['body'])) { $this->logger->warning('Article validation failed', ['reason' => 'missing fields']); return $this->json($response, ['error' => 'Title and body are required'], 422); } $data['author_id'] = $user['sub']; $article = $this->articleRepository->create($data); Metrics::articleCreated(); $this->logger->info('Article created', ['article.id' => $article['id'], 'user.id' => $user['sub']]); $response->getBody()->write(json_encode([ 'article' => $article, ])); return $response ->withHeader('Content-Type', 'application/json') ->withStatus(201); } } ``` Slim 4 uses constructor injection via PHP-DI. The `$response->getBody()->write()` pattern is standard PSR-7. ```mdx-code-block ``` ```php showLineNumbers title="src/Controllers/ArticleController.php" use App\Telemetry\Metrics; class ArticleController { public function create($request, $response) { $data = $request->getParsedBody(); $user = $request->getAttribute('user'); if (empty($data['title']) || empty($data['body'])) { $this->logger->warning('Article validation failed', ['reason' => 'missing fields']); return $response->withJson( ['error' => 'Title and body are required'], 422); } $data['author_id'] = $user['sub']; $article = $this->container['articleRepository']->create($data); Metrics::articleCreated(); $this->logger->info('Article created', ['article.id' => $article['id'], 'user.id' => $user['sub']]); return $response->withJson(['article' => $article], 201); } } ``` Slim 3 accesses dependencies via `$this->container['...']` (Pimple) and uses the convenience method `$response->withJson()`. ```mdx-code-block ``` ### Docker Deployment #### Dockerfile Use a 2-stage build to keep the runtime image small. The builder stage installs Composer dependencies; the runtime stage installs the `mongodb` and `opentelemetry` PECL extensions: ```dockerfile showLineNumbers title="Dockerfile" # syntax=docker/dockerfile:1 ARG PHP_VERSION=8.4 # Stage 1: Build dependencies FROM php:${PHP_VERSION}-cli AS builder WORKDIR /app RUN apt-get update -qq && \ apt-get install --no-install-recommends -y \ git unzip libzip-dev libssl-dev pkg-config && \ pecl install mongodb && \ docker-php-ext-enable mongodb && \ docker-php-ext-install zip && \ rm -rf /var/lib/apt/lists/* COPY --from=composer:2 /usr/bin/composer /usr/bin/composer COPY composer.json ./ RUN composer install --no-dev --no-scripts --no-autoloader --prefer-dist \ --ignore-platform-req=ext-opentelemetry COPY . . RUN composer dump-autoload --optimize --no-scripts # Stage 2: Runtime FROM php:${PHP_VERSION}-fpm WORKDIR /var/www/html RUN apt-get update -qq && \ apt-get install --no-install-recommends -y \ curl libzip-dev libssl-dev libonig-dev libfcgi-bin pkg-config && \ pecl install mongodb opentelemetry && \ docker-php-ext-enable mongodb opentelemetry && \ docker-php-ext-install zip mbstring && \ rm -rf /var/lib/apt/lists/* /tmp/* /var/tmp/* COPY config/php.ini /usr/local/etc/php/conf.d/99-app.ini COPY config/php-fpm.conf /usr/local/etc/php-fpm.d/zz-app.conf RUN groupadd --gid 1000 slim && \ useradd --uid 1000 --gid slim --shell /bin/bash --create-home slim COPY --from=builder --chown=slim:slim /app /var/www/html USER slim EXPOSE 9000 CMD ["php-fpm"] ``` For Slim 3, the `php.ini` should include the `error_reporting` suppression line from the [Installation](#step-1-install-php-extensions) section. #### Docker Compose Use YAML anchors to share OTel environment variables across services: ```yaml showLineNumbers title="compose.yml" x-otel-env: &otel-env OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_PHP_AUTOLOAD_ENABLED: "true" OTEL_RESOURCE_ATTRIBUTES: deployment.environment.name=development,environment=development x-mongo-env: &mongo-env MONGO_URI: mongodb://mongo:27017 MONGO_DATABASE: slim_app services: otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 ports: - "4317:4317" - "4318:4318" - "13133:13133" volumes: - ./config/otel-config.yaml:/etc/otelcol-contrib/config.yaml environment: - SCOUT_ENDPOINT=${SCOUT_ENDPOINT} - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL} restart: unless-stopped mongo: image: mongo:8 ports: - "27017:27017" volumes: - mongo-data:/data/db healthcheck: test: ["CMD", "mongosh", "--eval", "db.adminCommand('ping')"] interval: 10s timeout: 5s retries: 5 restart: unless-stopped app: build: context: . dockerfile: Dockerfile environment: <<: [*otel-env, *mongo-env] OTEL_SERVICE_NAME: my-slim-app JWT_SECRET: ${JWT_SECRET:-change-this-secret} APP_DEBUG: "true" depends_on: mongo: condition: service_healthy otel-collector: condition: service_started restart: unless-stopped nginx: image: nginx:alpine ports: - "8080:80" volumes: - ./nginx/default.conf:/etc/nginx/conf.d/default.conf - ./public:/var/www/html/public:ro depends_on: app: condition: service_started restart: unless-stopped volumes: mongo-data: ``` Start everything with: ```bash docker compose up --build ``` ### Verification Start the collector and hit an endpoint: ```bash showLineNumbers curl -X POST http://localhost:8080/api/articles \ -H "Authorization: Bearer YOUR_TOKEN" \ -H "Content-Type: application/json" \ -d '{"title":"Hello","body":"World"}' ``` ```mdx-code-block ``` Slim 4 produces a 3-level span hierarchy, all from auto-instrumentation: ```text POST /api/articles (SERVER - auto-slim) +-- ArticleController::create (INTERNAL - auto-slim) +-- MongoDB articles.insert (CLIENT - auto-mongodb) ``` ```mdx-code-block ``` Slim 3 produces a 2-level span hierarchy (no INTERNAL controller span): ```text POST /api/articles (SERVER - TelemetryMiddleware) +-- MongoDB articles.insert (CLIENT - auto-mongodb) ``` ```mdx-code-block ``` Check the collector output for: - Spans with your service name and proper parent-child nesting - Logs with `traceId`/`spanId` correlation - Metrics with `app.` prefix (e.g. `app.user.logins`, `app.article.creates`) ### Troubleshooting #### No traces appearing 1. Check collector logs: `docker compose logs otel-collector` 2. Verify Scout credentials are set correctly 3. Ensure `OTEL_PHP_AUTOLOAD_ENABLED=true` is set 4. Check extension: `docker exec php -m | grep opentelemetry` #### OpenTelemetry extension not loaded 1. Verify extension installation: `pecl list | grep opentelemetry` 2. Check `php.ini` includes the extension directive: `php --ini && php -m | grep opentelemetry` 3. Restart PHP-FPM if using FastCGI: `kill -USR2 1` (inside the container) #### No MongoDB spans 1. Verify `opentelemetry-auto-mongodb` is installed: `composer show | grep auto-mongodb` 2. Confirm `OTEL_PHP_AUTOLOAD_ENABLED=true` 3. Check that the `mongodb` PHP extension is loaded: `php -m | grep mongodb` #### Slim 3: span names show raw paths instead of route patterns Ensure `determineRouteBeforeAppMiddleware` is set to `true` in your Slim 3 settings. Without it, the `TelemetryMiddleware` cannot read the matched route pattern and span names will contain high-cardinality paths like `GET /api/articles/abc123` instead of `GET /api/articles/{id}`. #### Telemetry lost on process exit PHP-FPM workers can exit before the SDK flushes its buffer. Ensure the [Shutdown handler](#shutdown-handler) is registered and loaded early via `src/telemetry.php`. Without it, spans from the final request before worker recycling may be lost. ### FAQ #### Why are no traces appearing from my Slim OpenTelemetry setup? Work through four checks. Read the collector logs with `docker compose logs otel-collector`, confirm the Scout credentials are set, confirm `OTEL_PHP_AUTOLOAD_ENABLED=true` is exported, and confirm the extension is loaded with `php -m | grep opentelemetry`. #### Why is the OpenTelemetry PHP extension not loaded? Verify the install with `pecl list | grep opentelemetry`, check that `php.ini` carries the `extension=opentelemetry.so` directive, and restart PHP-FPM if you run under FastCGI. The extension is loaded per SAPI, so a CLI check passing does not mean the web request path has it. #### Why are no MongoDB spans appearing in my Slim application? Confirm `opentelemetry-auto-mongodb` is installed with `composer show | grep auto-mongodb`, that `OTEL_PHP_AUTOLOAD_ENABLED=true` is set, and that the MongoDB PHP extension itself is loaded with `php -m | grep mongodb`. #### Why do Slim 3 span names show raw paths instead of route patterns? Set `determineRouteBeforeAppMiddleware` to `true` in your Slim 3 settings. Without it the telemetry middleware cannot read the matched route pattern, so span names carry high-cardinality paths like `GET /api/articles/abc123` instead of `GET /api/articles/{id}`. #### Why is telemetry lost when a PHP-FPM process exits? PHP-FPM workers can exit before the SDK flushes its buffer. Make sure the shutdown handler is registered and loaded early through `src/telemetry.php`. Without it, spans from the final request before worker recycling are dropped. ### What's Next - **[Custom PHP Instrumentation](../custom-instrumentation/php.md)** - add manual spans for business-critical operations - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** — configure Scout Collector for local development - **[Creating Alerts](../../../guides/creating-alerts-with-logx.md)** - set up alerts for error rates, latency thresholds, and custom metrics - **[Dashboard Creation](../../../guides/create-your-first-dashboard.md)** — build custom dashboards combining traces, metrics, and business KPIs #### Related Guides - [PHP Custom Instrumentation](../custom-instrumentation/php.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language ### Complete Example Working examples with full source code, Docker Compose setup, and test scripts: - **Slim 4**: [php84-slim4-mongodb](https://github.com/base-14/examples/tree/main/php/php84-slim4-mongodb) - **Slim 3**: [php84-slim3-mongodb](https://github.com/base-14/examples/tree/main/php/php84-slim3-mongodb) ```mdx-code-block ``` ```json title="composer.json" { "name": "base14/slim4-mongodb-otel", "type": "project", "require": { "php": "^8.4", "slim/slim": "^4.15", "slim/psr7": "^1.8", "php-di/php-di": "^7.1", "mongodb/mongodb": "^2.2", "open-telemetry/sdk": "^1.13", "open-telemetry/exporter-otlp": "^1.4", "open-telemetry/opentelemetry-auto-slim": "^1.3", "open-telemetry/opentelemetry-auto-mongodb": "^0.2", "open-telemetry/opentelemetry-logger-monolog": "^1.1", "php-http/guzzle7-adapter": "^1.1", "guzzlehttp/psr7": "^2.8" } } ``` ```mdx-code-block ``` ```json title="composer.json" { "name": "base14/slim3-mongodb-otel", "type": "project", "require": { "php": "^8.4", "slim/slim": "~3.12", "mongodb/mongodb": "^2.0", "open-telemetry/sdk": "^1.13", "open-telemetry/exporter-otlp": "^1.4", "open-telemetry/opentelemetry-auto-mongodb": "^0.2", "open-telemetry/opentelemetry-logger-monolog": "^1.1", "php-http/guzzle7-adapter": "^1.0", "guzzlehttp/psr7": "^2.7" } } ``` ```mdx-code-block ``` ### References - [Official OpenTelemetry PHP Documentation](https://opentelemetry.io/docs/languages/php/) - [Slim 4 Documentation](https://www.slimframework.com/docs/v4/) - [Slim 3 Documentation](https://www.slimframework.com/docs/v3/) - [MongoDB PHP Library](https://www.mongodb.com/docs/php-library/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development. - [PHP Custom Instrumentation](../custom-instrumentation/php.md) - Manual spans and advanced patterns. - [WordPress](./wordpress.md) - self-hosted WordPress on Apache or PHP-FPM. - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language. --- ## Spring Boot OpenTelemetry Alternatives - Micrometer, SDK & Agent Compared ## Spring Boot Alternatives This guide covers alternative approaches to Spring Boot OpenTelemetry instrumentation beyond the recommended OpenTelemetry SDK Integration approach. > 📌 **Looking for the recommended approach?** > > See [Spring Boot OpenTelemetry Instrumentation](./spring-boot.md) for the > **OpenTelemetry SDK Integration** approach, which provides the best balance of > features, stability, and flexibility for most production use cases. :::tip TL;DR Attach the OpenTelemetry Java Agent JAR at JVM startup with `-javaagent:opentelemetry-javaagent.jar` for zero-code instrumentation of 150+ libraries - no dependency changes needed. If you're on Spring Boot 4.0 (currently preview), the native `spring-boot-starter-opentelemetry` starter offers Spring-managed OTel via Micrometer. For production, the recommended path remains the OpenTelemetry SDK Integration. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview While the [OpenTelemetry SDK Integration](./spring-boot.md) is our recommended approach for most Spring Boot applications, there are scenarios where alternative approaches may be more suitable: - **Java Agent**: Zero-code instrumentation when you can't modify application code - **Spring Boot 4.0 Native Starter**: Future Spring-native approach (currently preview) #### When to Use These Alternatives **Use Java Agent when:** - You need zero-code instrumentation (no dependency changes allowed) - Working with legacy applications where code changes are difficult - You want maximum auto-instrumentation coverage (150+ libraries) - Operations team manages instrumentation separately from dev team - Quick proof-of-concept without modifying application **Use Spring Boot 4.0 Native Starter when:** - Spring Boot 4.0 reaches General Availability (currently preview) - You want simpler Spring Boot dependency management - Your team is standardizing on Micrometer abstractions - You don't need advanced OpenTelemetry SDK features **Stick with OpenTelemetry SDK Integration for:** - Production deployments requiring stability and full feature support - GraalVM native-image compilation - Full OpenTelemetry API access for custom instrumentation - Advanced use cases (custom exporters, processors, samplers) - Multi-framework observability (using OpenTelemetry across Java, Node.js, etc.) ### Prerequisites #### For Java Agent - **Java**: JDK 8 or later (Java 25 has experimental support) - **Spring Boot**: Any version (2.x, 3.x, or 4.x) - **No dependencies required**: Java Agent works with any Spring Boot application - **base14 Scout**: Running collector endpoint (see [Collector Setup](../../collector-setup/docker-compose-example.md)) #### For Spring Boot 4.0 Native Starter - **Java**: JDK 21 or later (Spring Boot 4.0 requirement) - **Spring Boot**: 4.0.0 or later (currently preview, not GA) - **base14 Scout**: Running collector endpoint > ⚠️ **Spring Boot 4.0 Status**: Currently in preview. Not recommended for > production use until GA release. For general prerequisites and compatibility, see the [OpenTelemetry SDK Integration guide](./spring-boot.md#prerequisites). ### Java Agent Approach The Java Agent provides zero-code automatic instrumentation by attaching to your JVM at startup. This is the fastest way to add OpenTelemetry to Spring Boot applications without any code or dependency changes. A working example of this approach is [java/spring-boot-java25-mongodb-java-agent](https://github.com/base-14/examples/tree/main/java/spring-boot-java25-mongodb-java-agent). #### Download the Agent Download the latest OpenTelemetry Java agent JAR: ```bash showLineNumbers # Using wget wget https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/latest/download/opentelemetry-javaagent.jar # Or using curl curl -L -O https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/latest/download/opentelemetry-javaagent.jar ``` For specific versions: ```bash showLineNumbers # Download specific version (e.g., v2.10.0) wget https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/download/v2.10.0/opentelemetry-javaagent.jar ``` #### Basic Configuration Configure the agent using environment variables: ```bash title=".env" showLineNumbers # Service identification OTEL_SERVICE_NAME=your-service-name OTEL_RESOURCE_ATTRIBUTES=service.namespace=your-namespace,deployment.environment=development,environment=development # OTLP Exporter configuration OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp # Optional: Logging configuration OTEL_LOG_LEVEL=info ``` #### Running Your Application Attach the agent when starting your Spring Boot application: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash showLineNumbers # Basic usage java -javaagent:opentelemetry-javaagent.jar \ -jar your-spring-app.jar # With environment variables export OTEL_SERVICE_NAME=my-service export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 java -javaagent:opentelemetry-javaagent.jar \ -jar target/my-service-1.0.0.jar # With JVM system properties java -javaagent:opentelemetry-javaagent.jar \ -Dotel.service.name=my-service \ -Dotel.exporter.otlp.endpoint=http://localhost:4318 \ -jar your-spring-app.jar ``` ```mdx-code-block ``` ```bash showLineNumbers # Set environment variables export OTEL_SERVICE_NAME=my-service export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 # Run with Maven mvn spring-boot:run -Dspring-boot.run.jvmArguments="-javaagent:opentelemetry-javaagent.jar" ``` ```mdx-code-block ``` ```bash showLineNumbers # Set environment variables export OTEL_SERVICE_NAME=my-service export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 # Run with Gradle ./gradlew bootRun --args='--javaagent:opentelemetry-javaagent.jar' ``` ```mdx-code-block ``` #### Docker Configuration Add the agent to your Docker image: ```docker title="Dockerfile" showLineNumbers FROM eclipse-temurin:21-jre-jammy WORKDIR /app # Download OpenTelemetry Java agent ADD https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/latest/download/opentelemetry-javaagent.jar /app/opentelemetry-javaagent.jar # Copy application JAR COPY target/my-service-1.0.0.jar /app/app.jar # Set environment variables (can be overridden at runtime) ENV OTEL_SERVICE_NAME=my-service ENV OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 ENV OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo # Run application with agent ENTRYPOINT ["java", "-javaagent:/app/opentelemetry-javaagent.jar", "-jar", "/app/app.jar"] ``` #### Docker Compose Configure the agent with Docker Compose: ```yaml title="docker-compose.yml" showLineNumbers version: '3.8' services: app: build: . ports: - "8080:8080" environment: OTEL_SERVICE_NAME: my-service OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4318 OTEL_RESOURCE_ATTRIBUTES: deployment.environment=dev,environment=dev,service.version=1.0.0 OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp depends_on: - scout-collector scout-collector: image: base14/scout-collector:latest ports: - "4318:4318" ``` #### Kubernetes Deployment Deploy with the agent in Kubernetes using an init container: ```yaml title="k8s-deployment.yaml" showLineNumbers apiVersion: apps/v1 kind: Deployment metadata: name: spring-boot-app spec: template: spec: initContainers: - name: agent-downloader image: busybox:latest command: [sh, -c] args: - wget -O /otel-agent/opentelemetry-javaagent.jar https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases/latest/download/opentelemetry-javaagent.jar volumeMounts: - {name: otel-agent, mountPath: /otel-agent} containers: - name: app image: myregistry/spring-boot-app:1.2.3 env: - name: JAVA_TOOL_OPTIONS value: "-javaagent:/otel-agent/opentelemetry-javaagent.jar" - name: OTEL_SERVICE_NAME value: "spring-boot-app" - name: OTEL_EXPORTER_OTLP_ENDPOINT value: "http://scout-collector.observability.svc:4318" - name: OTEL_RESOURCE_ATTRIBUTES value: "deployment.environment=demo,environment=demo" volumeMounts: - {name: otel-agent, mountPath: /otel-agent} volumes: - name: otel-agent emptyDir: {} ``` #### Advanced Configuration Fine-tune agent behavior with additional environment variables: ```bash title="advanced-config.env" showLineNumbers # Disable specific instrumentations OTEL_INSTRUMENTATION_SPRING_WEBMVC_ENABLED=true OTEL_INSTRUMENTATION_JDBC_ENABLED=true OTEL_INSTRUMENTATION_LOGBACK_ENABLED=false # Sampling (1% of traces) OTEL_TRACES_SAMPLER=parentbased_traceidratio OTEL_TRACES_SAMPLER_ARG=0.01 # Batch processor tuning OTEL_BSP_SCHEDULE_DELAY=5000 OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 ``` See [OpenTelemetry Java Agent Configuration](https://opentelemetry.io/docs/zero-code/java/agent/configuration/) for all options. #### Supported Libraries The Java agent automatically instruments **150+ libraries** including Spring MVC/WebFlux, Spring Data JPA, JDBC drivers, Hibernate, MongoDB, Redis, Kafka, RestTemplate, WebClient, Apache HttpClient, and more. See the [complete list of supported libraries](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/docs/supported-libraries.md). #### Custom Instrumentation with Agent While the agent provides automatic instrumentation, you can add custom spans using annotations: ```java title="src/main/java/com/example/service/PaymentService.java" showLineNumbers package com.example.service; import io.opentelemetry.instrumentation.annotations.WithSpan; import io.opentelemetry.instrumentation.annotations.SpanAttribute; import org.springframework.stereotype.Service; @Service public class PaymentService { // Automatically creates a span named "processPayment" @WithSpan public PaymentResult processPayment( @SpanAttribute("payment.amount") double amount, @SpanAttribute("payment.method") String method ) { // Business logic validatePayment(amount, method); return chargeCustomer(amount, method); } // Custom span name @WithSpan(value = "validate-payment") private void validatePayment(double amount, String method) { // Validation logic } } ``` > ℹ️ **Note**: The Java agent only supports annotation-based custom > instrumentation. For programmatic span creation and full OpenTelemetry API > access, use the [OpenTelemetry SDK Integration](./spring-boot.md#custom-instrumentation) > approach. #### Agent Limitations Be aware of these limitations when using the Java agent: 1. **Version Compatibility**: Agent must match library versions (bytecode mismatch can cause issues) 2. **GraalVM Native Image**: Poor support for native compilation 3. **Agent Conflicts**: May conflict with other agents (APM tools, profilers) 4. **No Spring Configuration**: Can't use `application.yml` (environment variables only) 5. **Limited Custom Instrumentation**: Annotations only, no full API access 6. **Debugging**: Bytecode manipulation issues harder to troubleshoot #### Verifying Agent is Running Check agent startup in logs: ```bash showLineNumbers java -javaagent:opentelemetry-javaagent.jar -jar app.jar # Look for: [otel.javaagent] OpenTelemetry Javaagent 2.10.0 ``` Test with any HTTP endpoint and verify traces appear in Scout UI. ### Spring Boot 4.0 Native Starter Approach Spring Boot 4.0 (currently in preview, not yet GA) introduces native OpenTelemetry support with `spring-boot-starter-opentelemetry`, available directly from start.spring.io. > ⚠️ **Production Warning**: Spring Boot 4.0 is currently in preview and not > recommended for production use. Wait for GA release before migrating > production systems. #### Setup If you're using Spring Boot 4.0 (preview) and want to try the native OpenTelemetry starter: ```mdx-code-block ``` ```xml title="pom.xml" showLineNumbers org.springframework.boot spring-boot-starter-web org.springframework.boot spring-boot-starter-opentelemetry ``` ```mdx-code-block ``` ```groovy title="build.gradle" showLineNumbers plugins { id 'java' id 'org.springframework.boot' version '4.0.0' id 'io.spring.dependency-management' version '1.1.4' } // No need to specify OpenTelemetry versions // Spring Boot 4.0 manages all OpenTelemetry dependencies dependencies { // Spring Boot Starters implementation 'org.springframework.boot:spring-boot-starter-web' // Spring Boot 4.0 Native OpenTelemetry Starter implementation 'org.springframework.boot:spring-boot-starter-opentelemetry' } ``` ```mdx-code-block ``` > ℹ️ **Note**: The native starter uses Micrometer APIs instead of direct > OpenTelemetry APIs for custom instrumentation. See the [Migration > Guide](#migrating-from-opentelemetry-sdk-integration-to-spring-boot-40) for API > differences. #### Configuration Configuration is similar to OpenTelemetry SDK Integration but managed by Spring Boot 4.0: ```properties title="src/main/resources/application.properties" showLineNumbers # Service identification otel.service.name=my-service otel.resource.attributes=service.namespace=my-namespace,deployment.environment=development,environment=development # OTLP Exporter otel.exporter.otlp.endpoint=http://scout-collector:4318 otel.exporter.otlp.protocol=http/protobuf otel.traces.exporter=otlp otel.metrics.exporter=otlp ``` See the [SDK Integration configuration guide](./spring-boot.md#configuration) for more configuration options. ### Migrating from OpenTelemetry SDK Integration to Spring Boot 4.0 If you're currently using the OpenTelemetry SDK integration and want to migrate to Spring Boot 4.0's native starter once it reaches GA, follow this migration guide. > ⚠️ **Timing**: Spring Boot 4.0 is currently in preview. Wait for GA release > before migrating production systems. #### Why Migrate? **Consider migrating when:** - Spring Boot 4.0 reaches General Availability - You want simpler dependency management - Your team is standardizing on Micrometer abstractions - You don't need advanced OpenTelemetry SDK features **Stay with OpenTelemetry SDK integration if:** - You need fine-grained SDK control - You use OpenTelemetry across multiple frameworks - You require custom span processors or exporters - You want the latest OpenTelemetry features immediately #### Migration Steps ##### Step 1: Update Spring Boot Version ```xml title="pom.xml" showLineNumbers org.springframework.boot spring-boot-starter-parent 4.0.0 ``` ##### Step 2: Replace Dependencies **Remove OpenTelemetry SDK integration:** ```xml io.opentelemetry.instrumentation opentelemetry-spring-boot-starter io.micrometer micrometer-registry-otlp ``` **Add native starter:** ```xml org.springframework.boot spring-boot-starter-opentelemetry ``` ##### Step 3: Remove BOM (Optional) Spring Boot 4.0 manages OpenTelemetry versions: ```xml ``` ##### Step 4: Update Configuration Properties Configuration properties are largely compatible. Update prefixes if needed: ```properties # OpenTelemetry SDK Integration (old) otel.service.name=my-service otel.exporter.otlp.endpoint=http://localhost:4318 # Spring Boot 4.0 Native (same - no changes needed) otel.service.name=my-service otel.exporter.otlp.endpoint=http://localhost:4318 ``` ##### Step 5: Migrate Custom Instrumentation Code Replace OpenTelemetry API with Micrometer API: **OpenTelemetry SDK Integration (OpenTelemetry API):** ```java import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.StatusCode; import io.opentelemetry.context.Scope; @Service public class PaymentService { private final Tracer tracer; public PaymentService(OpenTelemetry openTelemetry) { this.tracer = openTelemetry.getTracer("payment-service"); } public void processPayment(PaymentRequest request) { Span span = tracer.spanBuilder("process_payment") .setAttribute("payment.amount", request.getAmount()) .startSpan(); try (Scope scope = span.makeCurrent()) { // Business logic chargeCustomer(request); span.setStatus(StatusCode.OK); } catch (Exception e) { span.recordException(e); span.setStatus(StatusCode.ERROR, "Payment failed"); throw e; } finally { span.end(); } } } ``` **Spring Boot 4.0 Native (Micrometer API):** ```java import io.micrometer.tracing.Tracer; import io.micrometer.tracing.Span; @Service public class PaymentService { private final Tracer tracer; public PaymentService(Tracer tracer) { this.tracer = tracer; } public void processPayment(PaymentRequest request) { Span span = tracer.nextSpan().name("process_payment").start(); try (Tracer.SpanInScope ws = tracer.withSpan(span)) { // Business logic span.tag("payment.amount", String.valueOf(request.getAmount())); chargeCustomer(request); } catch (Exception e) { span.error(e); throw e; } finally { span.end(); } } } ``` ##### Step 6: Update Custom Metrics **OpenTelemetry SDK Integration (OpenTelemetry Metrics):** ```java import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.metrics.LongCounter; import io.opentelemetry.api.metrics.Meter; @Component public class BusinessMetrics { private final LongCounter orderCounter; public BusinessMetrics(OpenTelemetry openTelemetry) { Meter meter = openTelemetry.getMeter("business-metrics"); this.orderCounter = meter.counterBuilder("orders.created") .setDescription("Total orders created") .build(); } public void recordOrder() { orderCounter.add(1); } } ``` **Spring Boot 4.0 Native (Micrometer Metrics):** ```java import io.micrometer.core.instrument.MeterRegistry; import io.micrometer.core.instrument.Counter; @Component public class BusinessMetrics { private final Counter orderCounter; public BusinessMetrics(MeterRegistry meterRegistry) { this.orderCounter = meterRegistry.counter("orders.created", "description", "Total orders created"); } public void recordOrder() { orderCounter.increment(); } } ``` #### API Comparison Cheat Sheet | Task | OpenTelemetry SDK Integration (OTEL API) | Spring Boot 4.0 (Micrometer) | |------|------------------------------|------------------------------| | **Create span** | `tracer.spanBuilder("name").startSpan()` | `tracer.nextSpan().name("name").start()` | | **Set attribute** | `span.setAttribute("key", "value")` | `span.tag("key", "value")` | | **Record exception** | `span.recordException(e)` | `span.error(e)` | | **Create scope** | `try (Scope scope = span.makeCurrent())` | `try (Tracer.SpanInScope ws = tracer.withSpan(span))` | | **Set status** | `span.setStatus(StatusCode.OK)` | Auto-managed by Micrometer | | **Create counter** | `meter.counterBuilder("name").build()` | `meterRegistry.counter("name")` | | **Increment counter** | `counter.add(1)` | `counter.increment()` | #### Testing the Migration 1. **Build the application**: Ensure no compilation errors 2. **Run locally**: Test with local collector 3. **Verify traces**: Check that spans appear in Scout 4. **Check metrics**: Ensure metrics are exported 5. **Test custom instrumentation**: Verify custom spans and attributes 6. **Performance test**: Compare overhead with OpenTelemetry SDK integration #### Rollback Plan If you encounter issues: 1. Revert to Spring Boot 3.x in `pom.xml` 2. Restore OpenTelemetry SDK integration dependencies 3. Restore OpenTelemetry API imports 4. Rebuild and redeploy #### When to Migrate **Recommended timeline:** - **Now**: Experiment in development environments - **After GA**: Evaluate in staging environments - **6 months post-GA**: Consider production migration after community adoption **Key indicators for migration:** - Spring Boot 4.0 GA released - Positive community feedback - Your use case doesn't require advanced SDK features - Team comfortable with Micrometer APIs ### Troubleshooting #### Java Agent Issues ##### Agent Not Loading **Symptom**: No traces appearing in Scout, no agent startup message in logs. **Solution**: ```bash # Verify agent path is correct ls -lh opentelemetry-javaagent.jar # Check JVM is actually loading the agent java -javaagent:opentelemetry-javaagent.jar -jar app.jar # Should see: [otel.javaagent] OpenTelemetry Javaagent 2.10.0 ``` ##### Version Compatibility Issues **Symptom**: ClassNotFoundException, NoClassDefFoundError, or bytecode errors. **Solution**: - Update to latest Java agent version - Check [supported libraries list](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/docs/supported-libraries.md) - Disable specific instrumentations if conflicts occur: ```bash OTEL_INSTRUMENTATION_[LIBRARY]_ENABLED=false ``` ##### Java 25 Unsafe Deprecation Warnings **Symptom**: Warnings about `sun.misc.Unsafe` when using Java 25. **Solution**: Java 25 has experimental support. Add JVM flag to suppress warnings: ```bash java -javaagent:opentelemetry-javaagent.jar \ --add-opens=java.base/sun.nio.ch=ALL-UNNAMED \ -jar app.jar ``` Or use Java 21 LTS for production. ##### Agent Conflicts with Other Tools **Symptom**: Application fails to start or behaves incorrectly when agent is attached. **Solution**: - Check for other JVM agents (APM tools, profilers) - Load OpenTelemetry agent last in `-javaagent` list - Consider using OpenTelemetry SDK Integration instead for better compatibility #### Spring Boot 4.0 Issues ##### Micrometer API Confusion **Symptom**: Compilation errors when trying to use OpenTelemetry API directly. **Solution**: Spring Boot 4.0 Native Starter uses Micrometer, not OpenTelemetry API directly: ```java // Don't use OpenTelemetry API // import io.opentelemetry.api.trace.Tracer; // Use Micrometer API instead import io.micrometer.tracing.Tracer; ``` See [API Comparison](#api-comparison-cheat-sheet) for migration guide. ##### Dependency Management Issues **Symptom**: Version conflicts or missing dependencies. **Solution**: Remove custom OpenTelemetry BOMs - Spring Boot 4.0 manages versions: ```xml ``` #### For Other Issues See the [SDK Integration troubleshooting guide](./spring-boot.md#troubleshooting) for: - Framework-specific issues (Spring MVC, JPA, etc.) - Security considerations - Performance optimization - General OpenTelemetry problems ### Frequently Asked Questions #### When should I use Java Agent vs OpenTelemetry SDK Integration? **Use Java Agent for:** - Zero-code requirement (no dependency changes) - Legacy apps where code changes are difficult - Quick POC or evaluation - Ops-managed instrumentation **Use OpenTelemetry SDK Integration for:** - Production deployments - GraalVM native-image - Custom instrumentation needs - Spring Boot configuration patterns See the [approach comparison guide](./spring-boot.md#choosing-your-approach) for a detailed decision guide. #### Is Spring Boot 4.0 Native Starter ready for production? No. Spring Boot 4.0 is currently in preview. Wait for: - GA release announcement - Community adoption and feedback - Stability verification in your environment Continue using OpenTelemetry SDK Integration for production systems. #### Can I use Java Agent with Spring Boot 4.0? Yes! Java Agent works with any Spring Boot version (2.x, 3.x, or 4.x). It's version-agnostic since it uses bytecode instrumentation rather than dependencies. #### Will Java Agent work with GraalVM native-image? No. Java Agent relies on bytecode manipulation which doesn't work well with native compilation. Use [OpenTelemetry SDK Integration](./spring-boot.md) for GraalVM support. #### Can I use application.yml with Java Agent? No. Java Agent only supports environment variables for configuration. You cannot use `application.yml` or `application.properties` for OpenTelemetry configuration when using the agent. For Spring Boot configuration support, use [OpenTelemetry SDK Integration](./spring-boot.md#configuration). #### When should I use Java Agent vs OpenTelemetry SDK Integration? Use the Java Agent when you cannot change the application: legacy apps, a quick evaluation, or instrumentation managed by the ops team rather than by the app's own dependencies. Use the OpenTelemetry SDK integration when you build for GraalVM native image, need custom instrumentation, or want the setup to follow the app's own Spring Boot configuration. ### Related Resources #### Recommended Approach - [Spring Boot OpenTelemetry Instrumentation](./spring-boot.md) - Our recommended **OpenTelemetry SDK Integration** approach with complete setup, configuration, and production guidance #### Additional Resources The following topics are covered in the SDK Integration guide: - [Framework-Specific Features](./spring-boot.md#framework-specific-features) - Spring MVC, JPA, RestTemplate, WebClient - [Security Considerations](./spring-boot.md#security-considerations) - Sensitive data masking, compliance - [Performance Considerations](./spring-boot.md#performance-considerations) - Optimization and overhead analysis - [Running Your Application](./spring-boot.md#running-your-application) - Local development and production deployment #### Reference - [OpenTelemetry Java Agent Documentation](https://opentelemetry.io/docs/zero-code/java/agent/) - [Spring Boot 4.0 Release Notes](https://github.com/spring-projects/spring-boot/wiki/Spring-Boot-4.0-Release-Notes) - [Micrometer Tracing Documentation](https://micrometer.io/docs/tracing) - [base14 Scout Documentation](/) #### Related Guides - [Custom Ruby Instrumentation](../custom-instrumentation/ruby.md) - Manual instrumentation patterns - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development collector setup - [Kubernetes Deployment](../../collector-setup/kubernetes-helm-setup.md) - Production collector deployment --- ## Spring Boot OpenTelemetry Instrumentation - Java Agent, SDK & Starter ## Spring Boot Spring Boot is one of the most widely adopted Java frameworks for building enterprise microservices and web applications. However, understanding application performance, identifying bottlenecks, and troubleshooting issues in distributed Spring Boot environments can be challenging without proper observability. OpenTelemetry provides automatic instrumentation for Spring Boot applications, capturing distributed traces across HTTP requests, database calls, message queues, and external API interactions. With base14 Scout's OpenTelemetry integration, you gain complete visibility into your Spring Boot application's performance with minimal code changes and production-ready configuration. Spring Boot is the dominant JVM framework. [Quarkus](./quarkus.md) and [Micronaut](./micronaut.md) are compile-time-optimized alternatives, and [Ktor](./ktor.md) is the Kotlin-first option. This comprehensive guide demonstrates how to instrument Spring Boot applications using OpenTelemetry, covering everything from basic setup to advanced production scenarios. You'll learn how to automatically capture traces from Spring MVC controllers, Spring Data JPA repositories, RestTemplate and WebClient calls, Kafka consumers, and more. The OpenTelemetry Spring Boot starter provides zero-code instrumentation for most common libraries, while also offering APIs for custom instrumentation when you need fine-grained control over spans and attributes. Integration with Spring Boot Actuator enables health checks and metrics export, making it production-ready from day one. Whether you're a Java developer adding observability to a new microservice, a DevOps engineer standardizing APM across Spring Boot services, or a platform team implementing OpenTelemetry organization-wide, this guide provides practical examples for every scenario. You'll find solutions for common pain points like context propagation across async boundaries, instrumenting legacy Spring applications, securing sensitive data in traces, optimizing performance overhead, and troubleshooting missing spans. By the end of this guide, you'll have a fully instrumented Spring Boot application sending rich telemetry data to base14 Scout, enabling fast root cause analysis and proactive performance optimization. :::tip TL;DR Add the `opentelemetry-spring-boot-starter` dependency to your `pom.xml` or `build.gradle` and configure `management.otlp.tracing.endpoint` in `application.properties` - the starter auto-instruments Spring MVC, Spring Data JPA, RestTemplate, WebClient, and Kafka with zero code changes. For fine-grained control over specific operations, inject `Tracer` via the OpenTelemetry API and use `startActiveSpan` to add custom spans alongside the automatic instrumentation. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry instrumentation for Spring Boot applications - Configure automatic request and response tracing - Instrument Spring MVC, Spring Data, and other Spring components - Implement custom instrumentation for business logic - Collect traces, metrics, and logs - Secure sensitive data in telemetry - Optimize performance overhead in production - Troubleshoot common instrumentation issues - Export telemetry data to base14 Scout Collector ### Who This Guide Is For This guide is designed for multiple roles working with Spring Boot applications: - **Java Developers** building new Spring Boot microservices who want to add observability from the start, understand performance characteristics of their code, and debug issues faster with distributed tracing. - **DevOps Engineers** responsible for deploying and monitoring Spring Boot applications in production environments, who need to standardize APM tooling, configure exporters, and ensure observability across the entire infrastructure. - **Platform Teams** implementing organization-wide OpenTelemetry standards for Java applications, who need to create reusable configuration patterns and integrate with existing observability stacks. - **Site Reliability Engineers (SREs)** who troubleshoot production incidents involving Spring Boot services, need to quickly identify performance bottlenecks, trace requests across distributed systems, and maintain service level objectives (SLOs). - **Application Architects** making technology decisions for microservices platforms, evaluating observability solutions, and designing systems that are observable by default with proper instrumentation patterns. ### Prerequisites Before implementing OpenTelemetry instrumentation, ensure you have: - A Spring Boot application (2.7+ or 3.x) - Java Development Kit (JDK) installed - Maven 3.6+ or Gradle 7.6+ build tool - Access to base14 Scout Collector endpoint (see [Collector Setup](../../collector-setup/kubernetes-helm-setup.md)) - Basic understanding of OpenTelemetry concepts (spans, traces, exporters) #### Compatibility **Minimum requirements:** - **Java**: 8+ (Java 17 or 21 LTS recommended for production) - **Spring Boot**: 2.7.0+ (3.x recommended, 4.0 preview available) - **Maven/Gradle**: Any recent version **Version details:**
OpenTelemetry library versions | Component | Minimum | Recommended | | --------------------------------- | ------- | ----------- | | OpenTelemetry Java SDK | 1.32.0 | 1.56+ | | OpenTelemetry Spring Boot Starter | 2.1.0 | 2.21.0 | | OpenTelemetry Java Agent | 1.32.0 | 2.10+ |
> ⚠️ **Java 25**: Experimental support. Use Java 21 LTS for production. See > [Java 25 notes](#java-25-compatibility-status) below. ##### Java 25 Compatibility Status Java 25 (released September 2025 as LTS) introduced changes affecting Java agents and instrumentation: - **JEP 520 (JFR Method Timing)**: Adds native method tracing via bytecode instrumentation, which can complement OpenTelemetry - **JVMTI Verification Changes**: Agent-transformed bytecode is now always verified, which may cause compatibility issues with older agent versions - **Unsafe Deprecation Warnings**: Users may see warnings about `sun.misc.Unsafe::objectFieldOffset` being terminally deprecated - **Status**: OpenTelemetry Java agent has experimental Java 25 support with known ByteBuddy-related issues being actively addressed For production deployments, we recommend **Java 21 LTS** until OpenTelemetry Java 25 support is fully stable. Monitor the [OpenTelemetry Java instrumentation releases](https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases) for updates. ### Choosing Your Approach Spring Boot offers three distinct approaches for OpenTelemetry integration. This section helps you choose the right one for your project and understand the trade-offs. > 📌 **Looking for alternative approaches?** > > This guide focuses on the **OpenTelemetry SDK Integration** (recommended for > production). For **Java Agent** (zero-code) and **Spring Boot 4.0 Native > Starter** (preview) approaches, see > [Spring Boot Alternatives](./spring-boot-alternatives.md). #### OpenTelemetry SDK Integration (Our Recommendation) ⭐ The community-maintained `opentelemetry-spring-boot-starter` provides direct OpenTelemetry SDK integration with full control and broad version support. This is **our recommended approach for production deployments**. **How it works:** - Add Maven/Gradle dependencies to your `pom.xml` or `build.gradle` - Configure via `application.yml` or `application.properties` - Automatic instrumentation for ~30 common libraries - Full OpenTelemetry API access for custom spans and metrics - Works with Spring Boot 2.7, 3.x, and 4.0 **Architecture:** - Direct OpenTelemetry API usage (no abstraction layer) - Full access to OpenTelemetry SDK configuration - Explicit dependency management via BOM - Spring Boot native configuration support - Production-proven across thousands of deployments **Best for:** - **Production deployments** - Stable, battle-tested approach - **GraalVM native-image** - Full support for native compilation - **Spring Boot configuration** - Use familiar `application.yml` patterns - **Custom instrumentation** - Full OpenTelemetry API access for business logic - **Advanced use cases** - Custom span processors, exporters, samplers - **Multi-framework** - Using OpenTelemetry across Node.js, Go, Python, etc. - **Version control** - Explicit dependency management without bytecode issues **Limitations:** - More complex setup than Java Agent (requires BOM and dependencies) - Requires understanding OpenTelemetry concepts (spans, traces, exporters) - Fewer auto-instrumented libraries (30+) compared to Java Agent (150+) - Manual configuration needed for advanced scenarios #### Java Agent (Zero-Code Alternative) The OpenTelemetry Java agent provides zero-code automatic instrumentation using bytecode manipulation at JVM startup. Best for legacy applications where code changes aren't possible, or for quick proof-of-concept testing. **Key characteristics:** - Download single JAR, attach with `-javaagent` flag - No dependencies or code changes required - Automatically instruments 150+ libraries - Environment variable configuration only See the [Java Agent guide](./spring-boot-alternatives.md#java-agent-approach) for complete setup instructions, Docker/Kubernetes examples, and limitations. #### Spring Boot 4.0 Native Starter (Future) Spring Boot 4.0 (preview, not GA) introduces native OpenTelemetry support with `spring-boot-starter-opentelemetry`. Uses Micrometer as abstraction layer for metrics and tracing. **Key characteristics:** - Single dependency, managed by Spring Boot 4.0 - Micrometer API for custom instrumentation - Spring Boot auto-configuration - Not recommended for production until GA See the [Spring Boot 4.0 guide](./spring-boot-alternatives.md#spring-boot-40-native-starter-approach) for setup instructions and migration guide from OpenTelemetry SDK Integration. #### Quick Comparison | Feature | OpenTelemetry SDK Integration ⭐ | Java Agent | Spring Boot 4.0 Native | | -------------------------- | -------------------------------- | -------------------------- | ------------------------- | | **Production Ready** | ✅ Stable | ✅ Stable | ❌ Preview | | **Setup** | Add dependencies | Attach JAR at startup | Add single dependency | | **Code Changes** | Optional | None required | Optional | | **Configuration** | `application.yml` or code | Environment variables only | `application.yml` or code | | **Custom Instrumentation** | Full OpenTelemetry API | Annotations only | Micrometer API | | **GraalVM Native** | ✅ Supported | ❌ Not supported | ✅ Supported | | **Auto-instrumentation** | ~30 libraries | 150+ libraries | Via Micrometer | | **Best For** | Production apps, full control | Legacy apps, zero-code | Future (post-GA) | | **Our Recommendation** | ✅ **Recommended** | Alternative | Wait for GA | #### Decision Guide **Choose OpenTelemetry SDK Integration (Recommended for Production) when:** - **GraalVM native-image**: Compiling to native binary - **Spring Boot configuration**: Want to use `application.yml` for OTEL config - **Custom instrumentation**: Need full OpenTelemetry API access for business logic - **Version flexibility**: Want explicit control over dependency versions - **Custom span processors**: Need advanced SDK customization (samplers, exporters) - **Multi-framework**: Using OpenTelemetry across Node.js, Go, Python, etc. - **Production stability**: Spring Boot 2.7, 3.x with proven battle-tested approach - **Latest features**: Want immediate access to new OpenTelemetry capabilities - **Debugging preference**: Prefer explicit dependencies over bytecode manipulation **Choose Java Agent (Zero-Code Alternative) when:** - **Zero-code requirement**: Cannot or don't want to modify application code/dependencies - **Legacy applications**: Modifying code is difficult or risky - **Maximum auto-instrumentation**: Need coverage for 150+ libraries out-of-the-box - **Cross-stack standardization**: Using OpenTelemetry across multiple languages - **Quick evaluation**: Want to try OpenTelemetry without code changes - **Operational control**: Ops team manages instrumentation separately from development - **Not using GraalVM**: No native-image compilation requirements - **Simple Spring Boot apps**: Standard libraries, no version compatibility concerns **Choose Spring Boot 4.0 Native Starter when:** - **After GA release**: Spring Boot 4.0 reaches General Availability - **Micrometer standardization**: Team already uses Micrometer abstractions - **Spring-native conventions**: Want Spring Boot auto-configuration patterns - **Simple setup**: Don't need advanced SDK customization - **Vendor-neutral API**: Micrometer can export to multiple backends #### This Guide's Coverage This guide focuses on the **OpenTelemetry SDK Integration** approach with comprehensive examples for production use: - Complete setup with Maven and Gradle - Configuration via application.yml, properties, and programmatic - Production deployment with Docker, Kubernetes - Framework-specific features (Spring MVC, JPA, RestTemplate, WebClient) - Custom instrumentation with full OpenTelemetry API - Security, performance, and troubleshooting guidance **Why OpenTelemetry SDK Integration is our recommendation:** - **Production Ready**: Stable, well-tested, and widely deployed - **Broad Compatibility**: Works with Spring Boot 2.7, 3.x, and 4.0 - **Maximum Flexibility**: Full SDK control for complex scenarios - **GraalVM Support**: Native-image compilation compatible - **Spring Configuration**: Uses familiar `application.yml` patterns > 💡 **Alternative Approaches**: For **Java Agent** (zero-code) or **Spring Boot > 4.0 Native Starter** (preview), see > [Spring Boot Alternatives](./spring-boot-alternatives.md). ### Setup ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```xml title="pom.xml" showLineNumbers 1.56.0 2.21.0 io.opentelemetry.instrumentation opentelemetry-instrumentation-bom ${opentelemetry.instrumentation.version} pom import org.springframework.boot spring-boot-starter-web io.opentelemetry.instrumentation opentelemetry-spring-boot-starter io.micrometer micrometer-registry-otlp ``` ```mdx-code-block ``` ```groovy title="build.gradle" showLineNumbers plugins { id 'java' id 'org.springframework.boot' version '3.5.7' id 'io.spring.dependency-management' version '1.1.4' } ext { set('opentelemetry.version', '1.56.0') set('opentelemetry.instrumentation.version', '2.21.0') // Note: Micrometer version is managed by Spring Boot BOM (all versions 2.0+) } dependencyManagement { imports { // OpenTelemetry Instrumentation BOM mavenBom "io.opentelemetry.instrumentation:" + "opentelemetry-instrumentation-bom:" + "${opentelemetry.instrumentation.version}" } } dependencies { // Spring Boot Starters implementation 'org.springframework.boot:spring-boot-starter-web' // OpenTelemetry implementation 'io.opentelemetry.instrumentation:' + 'opentelemetry-spring-boot-starter' implementation 'io.micrometer:micrometer-registry-otlp' } ``` ```mdx-code-block ``` ### Configuration OpenTelemetry can be configured for Spring Boot applications in multiple ways. Choose the approach that best fits your deployment model. ```mdx-code-block ``` **Recommended for production** - Maximum flexibility across environments: ```bash title=".env" showLineNumbers # Service identification OTEL_SERVICE_NAME=your-service-name OTEL_RESOURCE_ATTRIBUTES=service.namespace=your-namespace,deployment.environment.name=development,environment=development # OTLP Exporter configuration OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp # Instrumentation control OTEL_INSTRUMENTATION_SPRING_WEBMVC_ENABLED=true OTEL_INSTRUMENTATION_JDBC_ENABLED=true # Semantic convention stability OTEL_SEMCONV_STABILITY_OPT_IN=http,database ``` On the OpenTelemetry Java instrumentation 2.x line, HTTP server spans already use the stable conventions by default (`http.request.method`, `http.response.status_code`, `url.path`, `http.route`), so the `http` token is effectively a no-op. The `database` token is what does the work: with it set, JDBC spans emit the stable database conventions (`db.query.text`, `db.system.name`, `db.namespace`, `db.query.summary`) instead of the legacy `db.statement` / `db.system`. Both tokens are kept here so HTTP and database telemetry stay on the stable names together. ```mdx-code-block ``` Spring Boot-native configuration via `application.properties`: ```properties title="src/main/resources/application.properties" showLineNumbers # Server server.port=8080 server.address=0.0.0.0 # OpenTelemetry otel.service.name=your-service-name otel.resource.attributes=service.namespace=your-namespace,\ deployment.environment.name=dev,\ environment=dev # OTLP Exporter otel.traces.exporter=otlp otel.metrics.exporter=otlp otel.logs.exporter=otlp otel.exporter.otlp.endpoint=http://localhost:4318 otel.exporter.otlp.protocol=http/protobuf # HTTP semconv is stable by default on 2.x; database opt-in emits db.query.text otel.semconv-stability.opt-in=http,database # Actuator management.endpoints.web.exposure.include=health,info,metrics ``` ```mdx-code-block ``` Advanced scenarios with full programmatic control: ```java title="src/main/java/com/example/config/OpenTelemetryConfig.java" showLineNumbers package com.example.config; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.common.Attributes; import io.opentelemetry.exporter.otlp.http.trace.OtlpHttpSpanExporter; import io.opentelemetry.sdk.OpenTelemetrySdk; import io.opentelemetry.sdk.resources.Resource; import io.opentelemetry.sdk.trace.SdkTracerProvider; import io.opentelemetry.sdk.trace.export.BatchSpanProcessor; import io.opentelemetry.semconv.ServiceAttributes; import io.opentelemetry.semconv.incubating.DeploymentIncubatingAttributes; import io.opentelemetry.semconv.incubating.ServiceIncubatingAttributes; import org.springframework.beans.factory.annotation.Value; import org.springframework.context.annotation.Bean; import org.springframework.context.annotation.Configuration; @Configuration public class OpenTelemetryConfig { @Value("${otel.exporter.otlp.endpoint:http://localhost:4318}") private String otlpEndpoint; @Value("${otel.service.name:spring-boot-app}") private String serviceName; @Bean public OpenTelemetry openTelemetry() { Resource resource = Resource.create( Attributes.of( ServiceAttributes.SERVICE_NAME, serviceName, ServiceIncubatingAttributes.SERVICE_NAMESPACE, "production", DeploymentIncubatingAttributes.DEPLOYMENT_ENVIRONMENT_NAME, "development" ) ); OtlpHttpSpanExporter spanExporter = OtlpHttpSpanExporter.builder() .setEndpoint(otlpEndpoint + "/v1/traces") .build(); SdkTracerProvider tracerProvider = SdkTracerProvider.builder() .setResource(resource) .addSpanProcessor(BatchSpanProcessor.builder(spanExporter).build()) .build(); return OpenTelemetrySdk.builder() .setTracerProvider(tracerProvider) .buildAndRegisterGlobal(); } } ``` ```mdx-code-block ``` Multi-environment configuration with Spring profiles: **application-dev.yml:** ```yaml title="src/main/resources/application-dev.yml" showLineNumbers otel: service: name: my-service-dev resource: attributes: deployment.environment.name=dev,environment=dev,service.namespace=development exporter: otlp: endpoint: http://localhost:4318 ``` **application-prod.yml:** ```yaml title="src/main/resources/application-prod.yml" showLineNumbers otel: service: name: my-service-prod resource: attributes: deployment.environment.name=demo,environment=demo,service.namespace=production exporter: otlp: endpoint: https://scout-collector.example.com:4318 ``` ```mdx-code-block ``` > All configuration approaches export logs, traces, and metrics to the base14 > Scout observability backend. ### Traces Traces follow a request through your Spring Boot application, from the Spring MVC controller that receives it, through service beans, JDBC queries, RestTemplate / WebClient calls, and Kafka or RabbitMQ messages, and back out as the response. #### Automatic Trace Collection With the OpenTelemetry Java agent or the Spring Boot starter attached, every request is traced with no per-controller code: **Captured Information:** - HTTP method, route template, and status code for each Spring MVC endpoint - Request duration and a span-by-span timing breakdown - JDBC queries (Hibernate, Spring Data JPA, JdbcTemplate), including the SQL - Outbound `RestTemplate`, `WebClient`, and Feign calls - Kafka, RabbitMQ, and JMS producer/consumer spans - Exceptions recorded on the failing span with stack traces - Distributed context propagation across services (W3C Trace Context) **Trace Hierarchy:** ```text HTTP Request Span (root: GET /api/users/{id}) ├── UserController.getUser Span │ ├── UserService.findById Span │ │ └── JDBC Query Span (SELECT ... FROM users) │ └── RestTemplate Span (GET inventory-service) └── Kafka Producer Span (user.viewed event) ``` #### Key Tracing Features - **Automatic HTTP tracking**: every controller route is traced with no code changes - **JDBC and ORM visibility**: Hibernate and Spring Data queries appear as child spans with the executed SQL - **Error capturing**: thrown exceptions and `@ExceptionHandler` paths are recorded with full stack traces - **Context propagation**: distributed traces follow requests across HTTP and messaging boundaries - **Async support**: `@Async` methods, `CompletableFuture`, and reactive WebFlux pipelines stay correctly parented > View traces in your base14 Scout dashboard to follow request flows and find > the slow span in a chain. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) ### Metrics Metrics aggregate runtime measurements over time, such as request rate, latency distributions, JVM health, and connection-pool saturation. Where traces explain a single request, metrics power dashboards and alerts across all of them. #### Automatic Metrics The OpenTelemetry Java agent or Spring Boot starter captures a broad set of metrics without code, exported via the OTLP metrics exporter you configured above (`otel.metrics.exporter=otlp`): - **JVM runtime**: heap and non-heap usage, GC pause time, thread counts, class loading - **HTTP server**: request count and `http.server.request.duration` per route and status - **JDBC / HikariCP**: connection-pool size, active and idle connections, wait time - **System**: process CPU and memory #### Custom Metrics with Micrometer Spring Boot apps already ship with Micrometer; the OpenTelemetry Spring Boot starter bridges Micrometer's `MeterRegistry` to OpenTelemetry, so the idiomatic way to add business metrics is to inject `MeterRegistry`. Keep Spring Boot Actuator on the classpath (Micrometer rides on it) and enable metrics with `management.metrics.enable.all=true`: ```java title="src/main/java/com/example/metrics/OrderMetrics.java" showLineNumbers package com.example.metrics; import io.micrometer.core.instrument.Counter; import io.micrometer.core.instrument.MeterRegistry; import org.springframework.stereotype.Service; @Service public class OrderMetrics { private final Counter ordersPlaced; public OrderMetrics(MeterRegistry registry) { this.ordersPlaced = Counter.builder("orders.placed") .description("Total number of orders placed") .register(registry); } public void recordOrder() { ordersPlaced.increment(); } } ``` > View metrics in your base14 Scout dashboard to chart request rate, latency > percentiles, JVM health, and custom business counters. ##### Reference [Official Metrics Documentation](https://opentelemetry.io/docs/concepts/signals/metrics/) ### Production Configuration Production environments require careful configuration for performance, reliability, and cost optimization. #### Batch Span Processor Configuration Use BatchSpanProcessor for optimal production performance: ```java title="src/main/java/com/example/config/ProductionTracingConfig.java" showLineNumbers import io.opentelemetry.sdk.trace.export.BatchSpanProcessor; import io.opentelemetry.exporter.otlp.http.trace.OtlpHttpSpanExporter; import org.springframework.context.annotation.Bean; import org.springframework.context.annotation.Configuration; import org.springframework.context.annotation.Profile; @Configuration @Profile("production") public class ProductionTracingConfig { @Bean public BatchSpanProcessor batchSpanProcessor(OtlpHttpSpanExporter exporter) { return BatchSpanProcessor.builder(exporter) .setMaxQueueSize(2048) .setMaxExportBatchSize(512) .setScheduleDelay(Duration.ofSeconds(5)) .setExporterTimeout(Duration.ofSeconds(30)) .build(); } } ``` #### Resource Attributes for Production Add comprehensive resource attributes for better observability: ```properties title="application-prod.properties" showLineNumbers otel.resource.attributes=\ service.name=payment-service,\ service.namespace=production,\ service.version=1.2.3,\ service.instance.id=${HOSTNAME},\ deployment.environment.name=demo,\ environment=demo,\ deployment.region=us-east-1,\ cloud.provider=aws,\ cloud.platform=aws_eks,\ k8s.cluster.name=prod-cluster,\ k8s.namespace.name=payments,\ k8s.pod.name=${HOSTNAME} ``` #### Docker Configuration Configure OpenTelemetry for containerized Spring Boot applications: ```docker title="Dockerfile" showLineNumbers FROM eclipse-temurin:21-jre-jammy WORKDIR /app # Copy application JAR COPY target/my-service-1.0.0.jar app.jar # Set OpenTelemetry environment variables ENV OTEL_SERVICE_NAME=my-service ENV OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 ENV OTEL_RESOURCE_ATTRIBUTES=service.namespace=production # Run application ENTRYPOINT ["java", "-jar", "app.jar"] ``` #### Docker Compose Example ```yaml title="docker-compose.yml" showLineNumbers version: "3.8" services: app: build: . ports: - "8080:8080" environment: OTEL_SERVICE_NAME: payment-service OTEL_EXPORTER_OTLP_ENDPOINT: http://scout-collector:4318 OTEL_RESOURCE_ATTRIBUTES: deployment.environment.name=development,environment=development depends_on: - scout-collector scout-collector: image: base14/scout-collector:latest ports: - "4318:4318" ``` #### Kubernetes Deployment ```yaml title="k8s-deployment.yaml" showLineNumbers apiVersion: apps/v1 kind: Deployment metadata: name: spring-boot-app namespace: production spec: replicas: 3 selector: matchLabels: app: spring-boot-app template: metadata: labels: app: spring-boot-app spec: containers: - name: app image: myregistry/spring-boot-app:1.2.3 ports: - containerPort: 8080 env: - name: OTEL_SERVICE_NAME value: "spring-boot-app" - name: OTEL_EXPORTER_OTLP_ENDPOINT value: "http://scout-collector.observability.svc.cluster.local:4318" - name: OTEL_RESOURCE_ATTRIBUTES value: "deployment.environment.name=demo,environment=demo,k8s.cluster.name=prod-cluster" - name: POD_NAME valueFrom: fieldRef: fieldPath: metadata.name - name: POD_NAMESPACE valueFrom: fieldRef: fieldPath: metadata.namespace ``` #### Health Check Endpoint Implement a health check that verifies telemetry export: ```java title="src/main/java/com/example/controller/HealthController.java" showLineNumbers package com.example.controller; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.trace.Tracer; import org.springframework.beans.factory.annotation.Autowired; import org.springframework.http.ResponseEntity; import org.springframework.web.bind.annotation.GetMapping; import org.springframework.web.bind.annotation.RestController; @RestController public class HealthController { @Autowired private OpenTelemetry openTelemetry; @GetMapping("/health/telemetry") public ResponseEntity checkTelemetry() { try { Tracer tracer = openTelemetry.getTracer("health-check"); // Test span creation tracer.spanBuilder("health-check-test").startSpan().end(); return ResponseEntity.ok("Telemetry OK"); } catch (Exception e) { return ResponseEntity.status(500).body("Telemetry Error: " + e.getMessage()); } } } ``` ### Framework-Specific Features OpenTelemetry automatically instruments many Spring Boot components. Here's how instrumentation works for common Spring features. #### Spring MVC REST Controllers REST controllers are automatically instrumented: ```java title="src/main/java/com/example/controller/UserController.java" showLineNumbers package com.example.controller; import org.springframework.web.bind.annotation.*; import org.springframework.beans.factory.annotation.Autowired; @RestController @RequestMapping("/api/users") public class UserController { @Autowired private UserService userService; // Automatically creates span: "GET /api/users/{id}" @GetMapping("/{id}") public User getUser(@PathVariable Long id) { return userService.findById(id); } // Automatically creates span: "POST /api/users" @PostMapping public User createUser(@RequestBody User user) { return userService.save(user); } } ``` Each HTTP request creates a parent span with attributes like `http.request.method`, `http.route`, `http.response.status_code`, and `url.full`. #### Spring Data JPA Repositories Database queries via Spring Data JPA are automatically traced: ```java title="src/main/java/com/example/repository/UserRepository.java" showLineNumbers package com.example.repository; import org.springframework.data.jpa.repository.JpaRepository; import org.springframework.data.jpa.repository.Query; public interface UserRepository extends JpaRepository { // Automatically creates span: "SELECT User" User findByEmail(String email); // Automatically creates span with SQL query @Query("SELECT u FROM User u WHERE u.active = true") List findActiveUsers(); } ``` JDBC instrumentation captures: - SQL statements (parameterized) - Database connection details - Query execution time - Connection pool metrics #### RestTemplate and WebClient Outgoing HTTP calls are automatically instrumented with distributed trace context propagation: ```java title="src/main/java/com/example/service/ExternalApiService.java" showLineNumbers package com.example.service; import org.springframework.stereotype.Service; import org.springframework.web.client.RestTemplate; import org.springframework.web.reactive.function.client.WebClient; import reactor.core.publisher.Mono; @Service public class ExternalApiService { private final RestTemplate restTemplate; private final WebClient webClient; public ExternalApiService(RestTemplate restTemplate, WebClient.Builder webClientBuilder) { this.restTemplate = restTemplate; this.webClient = webClientBuilder.baseUrl("https://api.example.com").build(); } // Automatically creates span: "GET https://api.example.com/data" public String fetchDataSync() { return restTemplate.getForObject("https://api.example.com/data", String.class); } // Automatically creates span with async context propagation public Mono fetchDataAsync() { return webClient.get() .uri("/data") .retrieve() .bodyToMono(String.class); } } ``` #### Spring Boot Actuator Integration Integrate OpenTelemetry metrics with Spring Boot Actuator: ```java title="src/main/java/com/example/config/ActuatorConfig.java" showLineNumbers package com.example.config; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.metrics.Meter; import org.springframework.context.annotation.Bean; import org.springframework.context.annotation.Configuration; @Configuration public class ActuatorConfig { @Bean public Meter meter(OpenTelemetry openTelemetry) { return openTelemetry.getMeter("actuator-metrics"); } } ``` ```properties title="application.properties" showLineNumbers # Expose Actuator endpoints management.endpoints.web.exposure.include=health,info,metrics management.endpoint.health.show-details=always management.metrics.export.otlp.enabled=true ``` ### Custom Instrumentation While auto-instrumentation covers most use cases, custom instrumentation allows fine-grained control over spans and attributes. > 💡 **Java Agent Users**: The Java agent only supports annotation-based custom > instrumentation (`@WithSpan`, `@SpanAttribute`). For full programmatic API > access shown in this section, use the OpenTelemetry SDK Integration. For Java > Agent annotation examples, see > [Custom Instrumentation with Agent](./spring-boot-alternatives.md#custom-instrumentation-with-agent). > > 💡 **Spring Boot 4.0 Users**: If using the native starter, you'll use > Micrometer APIs (`io.micrometer.tracing.*`) instead of OpenTelemetry APIs > (`io.opentelemetry.api.*`). See the > [Spring Boot 4.0 guide](./spring-boot-alternatives.md#migrating-from-opentelemetry-sdk-integration-to-spring-boot-40) > for API comparisons. #### Manual Span Creation Create custom spans for business logic: ```java title="src/main/java/com/example/service/PaymentService.java" showLineNumbers package com.example.service; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.api.trace.StatusCode; import io.opentelemetry.context.Scope; import org.springframework.stereotype.Service; @Service public class PaymentService { private final Tracer tracer; public PaymentService(OpenTelemetry openTelemetry) { this.tracer = openTelemetry.getTracer("payment-service"); } public PaymentResult processPayment(PaymentRequest request) { Span span = tracer.spanBuilder("process_payment") .setAttribute("payment.method", request.getMethod()) .setAttribute("payment.amount", request.getAmount()) .setAttribute("payment.currency", request.getCurrency()) .startSpan(); try (Scope scope = span.makeCurrent()) { // Business logic validatePayment(request); PaymentResult result = chargeCustomer(request); span.setAttribute("payment.transaction_id", result.getTransactionId()); span.setStatus(StatusCode.OK); return result; } catch (PaymentException e) { span.recordException(e); span.setStatus(StatusCode.ERROR, "Payment failed"); throw e; } finally { span.end(); } } } ``` #### Adding Span Attributes Enrich spans with business-specific attributes: ```java title="src/main/java/com/example/service/OrderService.java" showLineNumbers package com.example.service; import io.opentelemetry.api.trace.Span; import org.springframework.stereotype.Service; @Service public class OrderService { public Order createOrder(OrderRequest request) { Span currentSpan = Span.current(); // Add custom attributes to current span currentSpan.setAttribute("order.user_id", request.getUserId()); currentSpan.setAttribute("order.item_count", request.getItems().size()); currentSpan.setAttribute("order.total_value", request.getTotalValue()); currentSpan.setAttribute("order.payment_method", request.getPaymentMethod()); // Business logic Order order = saveOrder(request); currentSpan.setAttribute("order.id", order.getId()); currentSpan.addEvent("Order created successfully"); return order; } } ``` #### Exception Handling and Error Recording Properly record exceptions in spans: ```java title="src/main/java/com/example/service/UserService.java" showLineNumbers package com.example.service; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.StatusCode; import org.springframework.stereotype.Service; @Service public class UserService { public User findUserById(Long id) { Span span = Span.current(); try { User user = userRepository.findById(id) .orElseThrow(() -> new UserNotFoundException("User not found: " + id)); span.setAttribute("user.id", user.getId()); span.setAttribute("user.role", user.getRole()); return user; } catch (UserNotFoundException e) { // Record exception with full stack trace span.recordException(e); span.setStatus(StatusCode.ERROR, "User not found"); throw e; } catch (Exception e) { span.recordException(e); span.setStatus(StatusCode.ERROR, "Unexpected error"); throw new ServiceException("Failed to find user", e); } } } ``` #### Async Operation Instrumentation Instrument async operations with proper context propagation: ```java title="src/main/java/com/example/service/AsyncService.java" showLineNumbers package com.example.service; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.context.Context; import org.springframework.scheduling.annotation.Async; import org.springframework.stereotype.Service; import java.util.concurrent.CompletableFuture; @Service public class AsyncService { private final Tracer tracer; public AsyncService(OpenTelemetry openTelemetry) { this.tracer = openTelemetry.getTracer("async-service"); } @Async public CompletableFuture processAsync(String input) { // Capture current context Context context = Context.current(); return CompletableFuture.supplyAsync(() -> { // Restore context in async thread try (var scope = context.makeCurrent()) { Span span = tracer.spanBuilder("async_processing") .setAttribute("input.length", input.length()) .startSpan(); try (var spanScope = span.makeCurrent()) { String result = performWork(input); span.setStatus(StatusCode.OK); return result; } finally { span.end(); } } }); } } ``` #### Custom Metrics Create custom business metrics: > 💡 **Spring Boot 4.0 Native Starter**: Use Micrometer's `MeterRegistry` for > metrics instead of OpenTelemetry's `Meter`. Example: > `meterRegistry.counter("orders.created").increment()`. The metrics are > automatically exported via OTLP. ```java title="src/main/java/com/example/metrics/BusinessMetrics.java" showLineNumbers package com.example.metrics; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.common.Attributes; import io.opentelemetry.api.metrics.LongCounter; import io.opentelemetry.api.metrics.Meter; import io.opentelemetry.api.metrics.LongHistogram; import org.springframework.stereotype.Component; @Component public class BusinessMetrics { private final LongCounter orderCounter; private final LongHistogram orderValueHistogram; private final Meter meter; public BusinessMetrics(OpenTelemetry openTelemetry) { this.meter = openTelemetry.getMeter("business-metrics"); this.orderCounter = meter.counterBuilder("orders.created") .setDescription("Total number of orders created") .build(); this.orderValueHistogram = meter.histogramBuilder("order.value") .setDescription("Distribution of order values") .ofLongs() .build(); } public void recordOrder(Order order) { orderCounter.add(1, Attributes.builder() .put("order.status", order.getStatus()) .put("order.payment_method", order.getPaymentMethod()) .build()); orderValueHistogram.record(order.getTotalValue(), Attributes.builder() .put("order.currency", order.getCurrency()) .build()); } } ``` ### Running Your Application Choose the deployment method that matches your environment: ```mdx-code-block ``` Run your Spring Boot application locally with OpenTelemetry: ```bash showLineNumbers # Set environment variables export OTEL_SERVICE_NAME=my-service-dev export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 # Run with Maven mvn spring-boot:run # Or run with Gradle ./gradlew bootRun ``` ```mdx-code-block ``` Build and run as a standalone JAR: ```bash showLineNumbers # Build the application mvn clean package -DskipTests # Run with production configuration java -jar target/my-service-1.0.0.jar \ --spring.profiles.active=prod \ -Dotel.service.name=my-service \ -Dotel.exporter.otlp.endpoint=https://scout-collector.example.com:4318 ``` ```mdx-code-block ``` Build and run in Docker: ```bash showLineNumbers # Build Docker image docker build -t my-service:1.0.0 . # Run container docker run -d \ --name my-service \ -p 8080:8080 \ -e OTEL_SERVICE_NAME=my-service \ -e OTEL_EXPORTER_OTLP_ENDPOINT=http://scout-collector:4318 \ -e OTEL_RESOURCE_ATTRIBUTES=deployment.environment.name=development,environment=development \ my-service:1.0.0 ``` ```mdx-code-block ``` ### Troubleshooting #### Common Issues and Solutions ##### 1. No Traces Appearing in Scout **Symptoms:** Application runs but no traces visible in base14 Scout. **Solutions:** ```bash showLineNumbers # Verify collector endpoint is reachable curl -v http://scout-collector:4318/health # Enable debug logging export OTEL_LOG_LEVEL=debug export LOGGING_LEVEL_IO_OPENTELEMETRY=DEBUG ``` ```properties title="application.properties" showLineNumbers # Add debug logging logging.level.io.opentelemetry=DEBUG logging.level.io.opentelemetry.exporter=TRACE ``` ##### 2. Java 25 Unsafe Deprecation Warnings **Symptoms:** Warnings about `sun.misc.Unsafe::objectFieldOffset` being terminally deprecated when running on Java 25. **Cause:** ByteBuddy (used by OpenTelemetry agent) uses deprecated Unsafe methods. **Solutions:** - These are warnings, not errors - instrumentation still works - Monitor [OpenTelemetry Java releases](https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases) for ByteBuddy updates - For production, use Java 21 LTS until Java 25 support is fully stable ```bash showLineNumbers # Suppress warnings (temporary workaround) java -XX:+UnlockDiagnosticVMOptions -XX:-WarnUnsafeDefaultFileEncoding -jar app.jar ``` ##### 3. ClassNotFoundException or NoClassDefFoundError **Symptoms:** Application fails to start with missing OpenTelemetry classes. **Solutions:** ```xml showLineNumbers io.opentelemetry.instrumentation opentelemetry-instrumentation-bom 2.21.0 pom import ``` ##### 4. High Memory Usage **Symptoms:** Application memory usage increases significantly after adding instrumentation. **Solutions:** ```properties showLineNumbers # Reduce batch size and queue size otel.bsp.max.queue.size=1024 otel.bsp.max.export.batch.size=256 otel.bsp.schedule.delay=5000 ``` ##### 5. Missing Database Query Spans **Symptoms:** HTTP requests traced but database queries not visible. **Solutions:** ```properties showLineNumbers # Enable JDBC instrumentation explicitly otel.instrumentation.jdbc.enabled=true otel.instrumentation.jdbc-datasource.enabled=true # Show SQL in spans (dev only) otel.instrumentation.jdbc.statement-sanitizer.enabled=false ``` ##### 6. Verification Test Test that instrumentation is working correctly: ```java title="src/test/java/com/example/TelemetryTest.java" showLineNumbers package com.example; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; import org.junit.jupiter.api.Test; import org.springframework.beans.factory.annotation.Autowired; import org.springframework.boot.test.context.SpringBootTest; import static org.assertj.core.api.Assertions.assertThat; @SpringBootTest class TelemetryTest { @Autowired private OpenTelemetry openTelemetry; @Test void testTelemetryConfiguration() { assertThat(openTelemetry).isNotNull(); Tracer tracer = openTelemetry.getTracer("test"); Span span = tracer.spanBuilder("test-span").startSpan(); assertThat(span).isNotNull(); assertThat(span.isRecording()).isTrue(); span.end(); } } ``` ### Security Considerations Protecting sensitive data in telemetry is critical for compliance and security. #### Sensitive Data Masking Mask sensitive data in span attributes: ```java title="src/main/java/com/example/security/SensitiveDataMasker.java" showLineNumbers package com.example.security; import io.opentelemetry.api.trace.Span; import org.springframework.stereotype.Component; @Component public class SensitiveDataMasker { public void addUserAttributes(Span span, User user) { span.setAttribute("user.id", user.getId()); span.setAttribute("user.role", user.getRole()); // BAD: Exposing PII // span.setAttribute("user.email", user.getEmail()); // span.setAttribute("user.phone", user.getPhone()); // GOOD: Masked or hashed span.setAttribute("user.email_domain", extractDomain(user.getEmail())); span.setAttribute("user.phone_country", extractCountryCode(user.getPhone())); } private String extractDomain(String email) { return email.substring(email.indexOf('@') + 1); } } ``` #### SQL Query Obfuscation Ensure SQL queries don't leak sensitive data: ```properties title="application.properties" showLineNumbers # Enable SQL statement sanitization (production) otel.instrumentation.jdbc.statement-sanitizer.enabled=true # Disable raw SQL in spans otel.instrumentation.jdbc.statement.enabled=false ``` #### HTTP Header Filtering Filter sensitive HTTP headers from traces: ```java title="src/main/java/com/example/config/SecurityConfig.java" showLineNumbers package com.example.config; import org.springframework.context.annotation.Bean; import org.springframework.context.annotation.Configuration; @Configuration public class SecurityConfig { @Bean public WebMvcConfigurer headerFilterConfigurer() { return new WebMvcConfigurer() { // Automatically filtered by OpenTelemetry: // - Authorization // - Cookie // - Set-Cookie // - X-API-Key // Custom filter for additional headers // Configure via: otel.instrumentation.http.capture-headers.server.request }; } } ``` ```properties showLineNumbers # Specify headers to capture (whitelist approach) otel.instrumentation.http.capture-headers.server.request=X-Request-ID,X-Correlation-ID otel.instrumentation.http.capture-headers.server.response=X-Response-Time ``` #### Compliance Considerations For GDPR, HIPAA, and PCI-DSS compliance: - **Disable PII capture**: Never add email, phone, SSN, or credit card data to spans - **Use span redaction**: Implement custom span processors to redact data - **Audit trace data**: Regularly review exported spans for sensitive information - **Implement data retention policies**: Configure Scout to delete traces after required period - **Encrypt in transit**: Always use HTTPS/TLS for OTLP exporter endpoints ```java title="src/main/java/com/example/config/ComplianceSpanProcessor.java" showLineNumbers package com.example.config; import io.opentelemetry.api.common.AttributeKey; import io.opentelemetry.api.common.Attributes; import io.opentelemetry.api.common.AttributesBuilder; import io.opentelemetry.context.Context; import io.opentelemetry.sdk.trace.ReadWriteSpan; import io.opentelemetry.sdk.trace.ReadableSpan; import io.opentelemetry.sdk.trace.SpanProcessor; import java.util.Set; public class ComplianceSpanProcessor implements SpanProcessor { private static final Set SENSITIVE_KEYS = Set.of( "user.email", "user.phone", "credit_card", "ssn", "password" ); @Override public void onStart(Context parentContext, ReadWriteSpan span) { // No-op on start } @Override public boolean isStartRequired() { return false; } @Override public void onEnd(ReadableSpan span) { // Redact sensitive attributes before export AttributesBuilder builder = Attributes.builder(); span.getAttributes().forEach((key, value) -> { if (SENSITIVE_KEYS.contains(key.getKey())) { builder.put(key.getKey(), "[REDACTED]"); } else { builder.put((AttributeKey) key, value); } }); } @Override public boolean isEndRequired() { return true; } } ``` ### Performance Considerations Understanding and optimizing the performance impact of instrumentation. #### Expected Performance Impact Typical overhead when using OpenTelemetry with Spring Boot: | Metric | Impact | Notes | | ------------- | ------------------ | ------------------------------------ | | **Latency** | +1-5ms per request | Mostly from span creation and export | | **CPU Usage** | +2-5% | Varies with trace volume | | **Memory** | +50-200 MB | For span buffers and exporters | | **Network** | ~1-5 KB/span | Depends on attribute count | **Factors affecting performance:** - Number of instrumented operations per request - Number of custom attributes added - Batch processor configuration - Network latency to collector #### Optimization Best Practices ##### 1. Optimize Batch Processing ```java showLineNumbers BatchSpanProcessor.builder(exporter) .setMaxQueueSize(2048) // Increase queue size .setMaxExportBatchSize(512) // Larger batches .setScheduleDelay(Duration.ofSeconds(5)) // Less frequent exports .build(); ``` ##### 2. Limit Attribute Count ```java showLineNumbers // BAD: Too many attributes span.setAttribute("item_1", value1); span.setAttribute("item_2", value2); // ... 100 more attributes // GOOD: Aggregate span.setAttribute("item_count", items.size()); span.setAttribute("total_value", calculateTotal(items)); ``` ##### 3. Use Conditional Instrumentation ```java showLineNumbers public void processOrder(Order order) { // Only create detailed spans for high-value orders if (order.getValue() > 10000) { Span span = tracer.spanBuilder("process_high_value_order") .setAttribute("order.value", order.getValue()) .startSpan(); try (Scope scope = span.makeCurrent()) { // Detailed instrumentation } finally { span.end(); } } else { // Regular processing without extra spans processRegularOrder(order); } } ``` ##### 4. Disable Unnecessary Instrumentation ```properties showLineNumbers # Disable specific instrumentations to reduce overhead otel.instrumentation.spring-webmvc.enabled=true otel.instrumentation.jdbc.enabled=true otel.instrumentation.kafka.enabled=true # Disable if not needed otel.instrumentation.logback.enabled=false otel.instrumentation.annotations.enabled=false ``` ### FAQ #### Choosing Between Approaches #### Should I use the Java Agent, SDK integration, or Spring Boot 4.0 native? For most cases: - **Quick start / Legacy apps**: Use **Java Agent** (zero code changes, fastest setup) - **Production with flexibility**: Use **OpenTelemetry SDK Integration** (full API access, Spring config, GraalVM support) - **Future (after GA)**: Consider **Spring Boot 4.0 Native** (Spring-native conventions) See the [Choosing Your Approach](#choosing-your-approach) section for detailed comparison and decision guide. #### What is the difference between the Java Agent and the OpenTelemetry SDK? **Java Agent**: - Zero code changes - attach JAR at startup - 150+ libraries auto-instrumented - Environment variables only for configuration - Limited custom instrumentation (annotations only) - May have version compatibility issues **OpenTelemetry SDK Integration**: - Requires adding dependencies - ~30 libraries auto-instrumented - Spring configuration (`application.yml`) supported - Full OpenTelemetry API for custom instrumentation - Better for GraalVM native-image #### Can I migrate from Java Agent to OpenTelemetry SDK Integration later? Yes! Start with the Java Agent for zero-code setup, then migrate to the OpenTelemetry SDK Integration when you need: - Custom span processors or exporters - Programmatic span creation (not just annotations) - Spring Boot native configuration files - GraalVM native-image compilation The migration just requires adding dependencies and removing the `-javaagent` flag. #### Is the OpenTelemetry SDK integration supported after Spring Boot 4.0? Yes. The OpenTelemetry SDK integration is independently maintained and will continue to support current and future Spring Boot versions. It provides more flexibility and direct OpenTelemetry API access compared to the native starter. #### Can I use multiple instrumentation approaches together? No, you should use only one approach. They provide overlapping functionality and using multiple approaches will cause conflicts: - Don't use Java Agent + OpenTelemetry SDK Integration together - Don't use OpenTelemetry SDK Integration + Spring Boot 4.0 Native together - Choose one based on your needs (see decision guide) #### Does the Java Agent work with GraalVM native-image? No, the Java Agent has poor support for GraalVM native-image compilation due to bytecode manipulation incompatibilities. If you need native-image, use the OpenTelemetry SDK Integration or Spring Boot 4.0 Native starter instead. #### General Questions #### What is the minimum Spring Boot version required for OpenTelemetry? Spring Boot 2.7.0 is the minimum version, but Spring Boot 3.0+ is recommended for the best compatibility and features. The OpenTelemetry Spring Boot starter fully supports Spring Boot 3.x with native GraalVM support. #### Does OpenTelemetry work with Java 25? Java 25 support is experimental as of September 2025. There are known ByteBuddy compatibility issues causing Unsafe deprecation warnings. For production deployments, we recommend Java 21 LTS. Monitor the [OpenTelemetry Java releases](https://github.com/open-telemetry/opentelemetry-java-instrumentation/releases) for stable Java 25 support. #### What is the difference between OpenTelemetry and Java Flight Recorder? OpenTelemetry focuses on distributed tracing across microservices with standardized telemetry, while JFR provides deep JVM-level profiling. Java 25's JEP 520 adds method tracing to JFR, which can complement OpenTelemetry. You can use both: JFR for low-level JVM metrics and OpenTelemetry for distributed traces. #### How much performance overhead does OpenTelemetry add? Typical overhead is 1-5ms per request, 2-5% CPU usage, and 50-200MB memory. Impact varies based on instrumentation scope and collector network latency. #### Can I use OpenTelemetry with Spring Boot 2.x? Yes, but you need older dependency versions. Use `opentelemetry-spring-boot-starter` version 1.x for Spring Boot 2.7-2.x. Spring Boot 3.x is recommended for the latest features and better performance. #### Configuration Questions #### How do I prevent specific endpoints from being traced? Set `otel.instrumentation.common.default-enabled` exclusions, or list the paths to skip in `management.tracing` properties: ```properties showLineNumbers # Exclude health check and metrics endpoints otel.instrumentation.spring-webmvc.exclude-patterns=/actuator/**,/health,/metrics ``` #### Can I send traces to multiple backends? Yes, configure multiple exporters programmatically: ```java showLineNumbers SpanExporter compositeExporter = SpanExporter.composite( OtlpHttpSpanExporter.builder().setEndpoint("http://scout:4318").build(), OtlpHttpSpanExporter.builder().setEndpoint("http://backup:4318").build() ); ``` #### Troubleshooting Questions #### Why are my database queries not appearing in traces? Enable JDBC instrumentation: `otel.instrumentation.jdbc.enabled=true` and verify DataSource is created after OpenTelemetry initialization. #### Why duplicate spans for the same operation? Multiple instrumentation libraries may overlap. Disable manual instrumentation (remove `@WithSpan` annotations) where auto-instrumentation already exists. #### Spring-Specific Questions #### How does OpenTelemetry work with Spring Cloud? OpenTelemetry integrates seamlessly with Spring Cloud components like Feign clients, Spring Cloud Gateway, and Sleuth. For Spring Cloud 2021.0.3+, OpenTelemetry can replace Sleuth entirely. #### Can I use OpenTelemetry with Spring WebFlux? Yes, OpenTelemetry fully supports reactive Spring WebFlux applications with automatic context propagation across reactive operators. #### How do I instrument multi-tenant Spring Boot applications? Add tenant information as span attributes: ```java showLineNumbers Span.current().setAttribute("tenant.id", SecurityContextHolder.getContext().getTenantId()); ``` Configure tenant-based filtering as needed. ### What's Next Once instrumented, you can [view Spring Boot traces and metrics in Scout](https://base14.io/scout/apm) — monitor REST endpoints, JPA queries, and async operations from a single dashboard. #### Advanced Topics - **[Custom Java Instrumentation](../custom-instrumentation/java.md)** - Deep dive into manual instrumentation, custom span processors, and advanced tracing patterns #### Deployment Guides - **[Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md)** - Deploy Scout Collector on Kubernetes with Helm charts - **[Docker Compose Setup](../../collector-setup/docker-compose-example.md)** - Run Scout Collector locally with Docker Compose - **[AWS ECS Deployment](../../collector-setup/ecs-setup.md)** - Deploy instrumented Spring Boot apps on AWS ECS with Scout Collector - **[Scout Collector Configuration](../../collector-setup/otel-collector-config.md)** \- Configure the OpenTelemetry Collector for production use #### Related Guides - [Spring Boot vs Alternatives](./spring-boot-alternatives.md) - JVM framework comparison guide - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language ### Complete Example For a fully working Spring Boot application with OpenTelemetry instrumentation, refer to our example repository: **[Spring Boot OpenTelemetry Example](https://github.com/base-14/examples/tree/main/java/spring-boot-java25-postgresql)** The example includes: - Complete Spring Boot 3.2 application with REST API - Maven and Gradle build configurations - OpenTelemetry auto-instrumentation setup - Custom instrumentation examples for business logic - JPA repository integration with database tracing - Docker and Kubernetes deployment configurations - docker-compose.yml for local development - Environment-specific configuration (dev, staging, prod) - Actuator health checks and metrics - Integration tests with telemetry verification - Security best practices for PII protection #### Quick Start with Example ```bash showLineNumbers # Clone the repository git clone https://github.com/base-14/examples.git cd examples/java/spring-boot-java25-postgresql # Run locally with Docker Compose docker-compose up # Access the application curl http://localhost:8080/api/users # View traces in Scout open http://localhost:16686 # Jaeger UI for local testing ``` The example demonstrates: - Automatic HTTP request tracing - Database query instrumentation - Custom business logic spans - Error tracking and exception recording - Metric collection and export - Production-ready configuration patterns ### References - [OpenTelemetry Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) - Sample application: [Spring Boot OTel Instrumentation](https://github.com/base-14/examples/tree/main/java) ### Related Guides - [Quarkus Instrumentation](./quarkus.md) - Supersonic JVM framework with native OpenTelemetry support - [Micronaut Instrumentation](./micronaut.md) - Compile-time DI JVM framework - [Ktor Instrumentation](./ktor.md) - Kotlin-native async web framework - [Java Custom Instrumentation](../custom-instrumentation/java.md) - Manual spans and advanced patterns - [Spring AI LLM Observability][spring-ai] - Spring AI with three-layer OTel instrumentation [spring-ai]: ../../../guides/ai-observability/spring-ai-llm-observability.md --- ## Symfony OpenTelemetry Instrumentation - Doctrine, HTTP & Log Correlation ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Implement OpenTelemetry instrumentation for Symfony applications to enable automatic distributed tracing, Doctrine ORM query monitoring, HTTP client tracing, and structured log correlation. This guide shows you how to auto-instrument your Symfony application to collect traces, metrics, and logs from HTTP requests, database queries, service-to-service calls, and custom business logic using the OpenTelemetry PHP SDK. Symfony is a full-featured PHP framework. [Laravel](./laravel.md) builds on Symfony components, and [Slim](./slim.md) is a lighter micro-framework alternative. Symfony applications benefit from automatic instrumentation of the framework's core components including the HTTP kernel, Doctrine ORM (via PDO), the HTTP client (PSR-18), and Monolog logging. With OpenTelemetry, you can monitor production performance, debug slow requests, trace distributed transactions across microservices, and correlate logs with traces without significant code changes. Whether you're implementing observability for the first time, migrating from commercial APM solutions, or troubleshooting performance issues in production, this guide provides production-ready configurations and best practices for Symfony OpenTelemetry instrumentation. > **Note:** This guide provides a practical Symfony-focused overview based on the > official OpenTelemetry documentation. For complete PHP language information, > please consult the > [official OpenTelemetry PHP documentation](https://opentelemetry.io/docs/languages/php/). :::tip TL;DR Install the OpenTelemetry PHP extension, add the SDK and auto-instrumentation packages via Composer, and set `OTEL_PHP_AUTOLOAD_ENABLED=true` in your `.env`. HTTP requests, Doctrine queries, and HTTP client calls are traced automatically. Register an `OtelTraceProcessor` in `services.yaml` for log correlation. Export everything to base14 Scout via OTLP. ::: :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Who This Guide Is For This documentation is designed for: - **Symfony developers**: implementing observability and distributed tracing for the first time - **Enterprise teams**: running Symfony in production with monitoring requirements - **DevOps engineers**: deploying Symfony applications with telemetry pipelines - **Engineering teams**: migrating from Datadog, New Relic, or other commercial APM solutions - **Platform teams**: standardizing observability across multiple Symfony services ### Overview This guide demonstrates how to: - Install and configure the OpenTelemetry PHP extension and SDK for Symfony - Set up automatic instrumentation for HTTP requests, Doctrine ORM, and the HTTP client - Configure Monolog log correlation with trace context (trace_id, span_id) - Wire OpenTelemetry interfaces into Symfony's service container - Deploy instrumented Symfony applications with Docker Compose - Implement custom spans and business metrics - Trace requests across multiple Symfony services (distributed tracing) - Troubleshoot common instrumentation issues ### Prerequisites Before starting, ensure you have: - **PHP 8.1 or later** (PHP 8.3+ recommended for best performance) - The `opentelemetry` PECL extension requires build tools (gcc, make, autoconf) - **Symfony 5.4 or later** installed - Symfony 7.x or 8.x is recommended for optimal OpenTelemetry support - Symfony 5.4 and 6.x are supported but may require additional configuration - **Composer 2.0+** for dependency management - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) #### Compatibility Matrix | Component | Minimum Version | Recommended Version | | ---------------------------- | --------------- | ------------------- | | PHP | 8.1.0 | 8.4.0+ | | Symfony | 5.4.0 | 7.2.0+ / 8.0.0+ | | Composer | 2.0.0 | 2.7.0+ | | OpenTelemetry PHP Extension | 1.0.0 | Latest stable | | OpenTelemetry SDK | 1.0.0 | 1.14+ | | Doctrine ORM | 2.14.0 | 3.6.0+ | #### Instrumented Components | Component | Package | Coverage | | --------------------- | ------------------------------------ | -------------------------------------- | | Symfony HTTP Kernel | `opentelemetry-auto-symfony` | Routes, controllers, middleware | | Doctrine ORM / PDO | `opentelemetry-auto-pdo` | All SQL queries, transactions | | HTTP Client (PSR-18) | `opentelemetry-auto-psr18` | Outgoing HTTP calls, W3C propagation | | Monolog (PSR-3) | `opentelemetry-auto-psr3` | Log export to collector | | Custom Business Logic | `open-telemetry/sdk` (manual spans) | Any code you instrument manually | #### Example Application This guide references the [symfony-mysql](https://github.com/base-14/examples/tree/main/php/symfony-mysql) example: a Symfony 8 REST API with Doctrine ORM, a notification microservice, and full OpenTelemetry instrumentation. ### Installation #### Step 1: Install OpenTelemetry PHP Extension The OpenTelemetry PHP extension provides the hooks for automatic instrumentation. ##### Install Build Dependencies ```mdx-code-block ``` ```bash sudo apt-get install gcc make autoconf ``` ```mdx-code-block ``` ```bash apk add --no-cache autoconf build-base ``` ```mdx-code-block ``` ```bash xcode-select --install ``` ```mdx-code-block ``` ##### Install Extension via PECL ```bash pecl install opentelemetry ``` ##### Enable Extension in php.ini ```ini title="php.ini" [opentelemetry] extension=opentelemetry.so ``` ##### Verify Installation ```bash php -m | grep opentelemetry ``` Expected output: ```plaintext opentelemetry ``` #### Step 2: Install Required Packages Install the OpenTelemetry SDK and auto-instrumentation packages via Composer: ```bash composer require \ open-telemetry/sdk \ open-telemetry/exporter-otlp \ open-telemetry/opentelemetry-auto-symfony \ open-telemetry/opentelemetry-auto-pdo \ open-telemetry/opentelemetry-auto-psr18 \ open-telemetry/opentelemetry-auto-psr3 ``` This installs: - **SDK + OTLP exporter** - Core telemetry pipeline - **auto-symfony** - HTTP kernel, routing, and controller spans - **auto-pdo** - Doctrine ORM / PDO query spans - **auto-psr18** - Outgoing HTTP client spans with W3C trace propagation - **auto-psr3** - Log export to the collector via Monolog **Optional: PSR-7 implementation** (required if not already present): ```bash composer require nyholm/psr7 ``` ### Configuration OpenTelemetry Symfony instrumentation supports multiple configuration approaches. Environment variables are the recommended method for most deployments. ```mdx-code-block ``` Add these to your Symfony `.env` file: ```bash title=".env" # OpenTelemetry Configuration OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=symfony-app OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_PHP_PSR3_MODE=export OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development ``` Setting `OTEL_PHP_AUTOLOAD_ENABLED=true` is all it takes to start collecting traces from Symfony HTTP requests, Doctrine queries, and HTTP client calls. ```mdx-code-block ``` Wire the OpenTelemetry global factories into Symfony's dependency injection container. This lets you inject `MeterProviderInterface` and `TracerProviderInterface` into any service. ```yaml title="config/services.yaml" showLineNumbers services: _defaults: autowire: true autoconfigure: true App\: resource: '../src/' exclude: - '../src/Entity/' - '../src/Kernel.php' # Wire OTel meter provider for custom metrics OpenTelemetry\API\Metrics\MeterProviderInterface: factory: ['OpenTelemetry\API\Globals', 'meterProvider'] # Wire OTel tracer provider for custom spans OpenTelemetry\API\Trace\TracerProviderInterface: factory: ['OpenTelemetry\API\Globals', 'tracerProvider'] ``` This uses Symfony's factory pattern to expose the OTel SDK globals as injectable services. Any controller or service can now type-hint `MeterProviderInterface` or `TracerProviderInterface` in its constructor. ```mdx-code-block ``` For local development with a full observability stack, use Docker Compose to run your Symfony app alongside MySQL and the OpenTelemetry Collector: ```yaml title="compose.yml" showLineNumbers x-otel-env: &otel-env OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_PHP_AUTOLOAD_ENABLED: "true" OTEL_PHP_PSR3_MODE: export OTEL_RESOURCE_ATTRIBUTES: deployment.environment=development,environment=development x-db-env: &db-env DATABASE_URL: mysql://symfony:secret@db:3306/symfony?serverVersion=8.4 services: otel-collector: image: otel/opentelemetry-collector-contrib:0.148.0 container_name: symfony-otel-collector ports: - "4317:4317" - "4318:4318" volumes: - ./config/otel-config.yaml:/etc/otelcol-contrib/config.yaml environment: - SCOUT_ENDPOINT=${SCOUT_ENDPOINT} - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL} restart: unless-stopped db: image: mysql:8.4 container_name: symfony-mysql environment: MYSQL_DATABASE: symfony MYSQL_USER: symfony MYSQL_PASSWORD: secret MYSQL_ROOT_PASSWORD: rootsecret ports: - "3306:3306" volumes: - mysql-data:/var/lib/mysql healthcheck: test: [ "CMD", "mysqladmin", "ping", "-h", "localhost", "-u", "root", "-prootsecret", ] interval: 10s timeout: 5s retries: 5 restart: unless-stopped app: build: context: ./app dockerfile: Dockerfile container_name: symfony-app command: > bash -c "php bin/console doctrine:migrations:migrate --no-interaction; php -S 0.0.0.0:8080 -t public" ports: - "${APP_PORT:-8080}:8080" environment: <<: [*otel-env, *db-env] APP_ENV: dev APP_DEBUG: "true" APP_SECRET: symfony-example-secret OTEL_SERVICE_NAME: symfony-articles depends_on: db: condition: service_healthy otel-collector: condition: service_started restart: unless-stopped volumes: mysql-data: ``` The YAML anchor `&otel-env` lets you share OpenTelemetry environment variables across multiple services without duplication. ```mdx-code-block ``` #### Configure Doctrine ORM Standard Doctrine configuration works out of the box. The `opentelemetry-auto-pdo` package intercepts all PDO calls, including those from Doctrine DBAL: ```yaml title="config/packages/doctrine.yaml" showLineNumbers doctrine: dbal: url: '%env(resolve:DATABASE_URL)%' driver: pdo_mysql server_version: '8.4' charset: utf8mb4 orm: naming_strategy: doctrine.orm.naming_strategy.underscore_number_aware auto_mapping: true mappings: App: type: attribute is_bundle: false dir: '%kernel.project_dir%/src/Entity' prefix: 'App\Entity' alias: App ``` #### Configure Monolog for Log Correlation Set up structured JSON logging with trace context injection. Create a custom Monolog processor that reads the current span and injects `trace_id` and `span_id` into every log record: ```php title="src/Service/OtelTraceProcessor.php" showLineNumbers getContext(); return $record->with(extra: array_merge($record->extra, [ 'trace_id' => $context->getTraceId(), 'span_id' => $context->getSpanId(), 'service.name' => $_ENV['OTEL_SERVICE_NAME'] ?? 'symfony-app', ])); } } ``` Register the processor in `services.yaml`: ```yaml title="config/services.yaml" services: App\Service\OtelTraceProcessor: tags: - { name: monolog.processor } ``` Configure Monolog to output JSON to stdout (container-friendly): ```yaml title="config/packages/monolog.yaml" showLineNumbers monolog: handlers: main: type: stream path: php://stdout level: info formatter: monolog.formatter.json channels: ['!event', '!doctrine'] doctrine: type: stream path: php://stdout level: warning formatter: monolog.formatter.json channels: ['doctrine'] channels: ['app'] ``` Every log line now includes `trace_id` and `span_id`, enabling you to jump from a log entry in Scout directly to the corresponding trace. #### Scout Collector Integration When using Scout Collector, configure your Symfony application to export telemetry with OAuth2 authentication: ```bash title=".env" # Scout Collector Configuration OTEL_EXPORTER_OTLP_ENDPOINT=https://your-tenant.base14.io/v1/traces SCOUT_CLIENT_ID=your_client_id SCOUT_CLIENT_SECRET=your_client_secret SCOUT_TOKEN_URL=https://your-tenant.base14.io/oauth/token # Service Configuration OTEL_SERVICE_NAME=symfony-app OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf ``` > **Scout Dashboard Integration**: After configuration, your traces will appear > in the Scout Dashboard. Navigate to the Traces section to view request flows, > identify performance bottlenecks, and analyze distributed transactions across > your Symfony services. ### Production Configuration Production deployments require tuning for performance, reliability, and resource utilization. #### Production Environment Variables ```bash title=".env.production" # Application Settings APP_ENV=production APP_DEBUG=false # OpenTelemetry Service Configuration OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_SERVICE_NAME=symfony-app OTEL_SERVICE_VERSION=2.1.3 # Scout Collector Endpoint OTEL_EXPORTER_OTLP_ENDPOINT=https://scout-collector.example.com/v1/traces SCOUT_CLIENT_ID=prod_client_id SCOUT_CLIENT_SECRET=prod_secret_key SCOUT_TOKEN_URL=https://scout-collector.example.com/oauth/token # Exporter Settings OTEL_TRACES_EXPORTER=otlp OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_EXPORTER_OTLP_COMPRESSION=gzip OTEL_EXPORTER_OTLP_TIMEOUT=10 # Batch Span Processor (Production Optimized) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY_MILLIS=5000 OTEL_BSP_EXPORT_TIMEOUT_MILLIS=30000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 # Propagators OTEL_PROPAGATORS=baggage,tracecontext # Resource Attributes OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,host.name=${HOSTNAME} ``` Benefits of this configuration: - GZIP compression reduces network bandwidth by 70-80% - Batch processing minimizes network requests - Resource attributes enable filtering by environment in Scout Dashboard #### Docker Production Configuration Multi-stage Dockerfile that installs the OpenTelemetry extension and optimizes for production: ```dockerfile title="Dockerfile" showLineNumbers # syntax=docker/dockerfile:1 ARG PHP_VERSION=8.5 # Stage 1: Build dependencies FROM php:${PHP_VERSION}-cli AS builder WORKDIR /app RUN apt-get update -qq && \ apt-get install --no-install-recommends -y \ git unzip libzip-dev && \ docker-php-ext-install pdo pdo_mysql zip && \ rm -rf /var/lib/apt/lists/* COPY --from=composer:2 /usr/bin/composer /usr/bin/composer COPY composer.json ./ RUN composer install --no-dev --no-scripts --no-autoloader --prefer-dist \ --ignore-platform-reqs COPY . . RUN composer dump-autoload --optimize --no-scripts # Stage 2: Runtime FROM php:${PHP_VERSION}-cli WORKDIR /var/www/html RUN apt-get update -qq && \ apt-get install --no-install-recommends -y \ curl libzip-dev default-mysql-client && \ docker-php-ext-install pdo pdo_mysql zip && \ pecl install opentelemetry && \ docker-php-ext-enable opentelemetry && \ rm -rf /var/lib/apt/lists/* /tmp/* /var/tmp/* RUN groupadd --gid 1000 symfony && \ useradd --uid 1000 --gid symfony --shell /bin/bash --create-home symfony COPY --from=builder --chown=symfony:symfony /app /var/www/html RUN mkdir -p var/cache var/log && \ chown -R symfony:symfony var USER symfony EXPOSE 8080 HEALTHCHECK --interval=30s --timeout=5s --start-period=30s --retries=3 \ CMD curl -f http://localhost:8080/api/health || exit 1 CMD ["php", "-S", "0.0.0.0:8080", "-t", "public"] ``` Key details: - **Multi-stage build** separates Composer install from runtime - **PECL opentelemetry** extension installed in the runtime stage - **Non-root user** (`symfony:1000`) for security - **Health check** ensures the app is responsive #### Multi-Service Distributed Tracing For architectures with multiple Symfony services, each service gets its own `OTEL_SERVICE_NAME`. The Symfony HTTP client with `opentelemetry-auto-psr18` automatically propagates W3C `traceparent` headers between services. Here's a notification microservice pattern from the example app: ```php title="src/Service/NotificationClient.php" showLineNumbers httpClient->request('POST', $this->notifyUrl . '/notify', [ 'json' => $articleData, ]); $response->getStatusCode(); } catch (\Throwable $e) { $this->logger->warning('Notification failed', [ 'article_id' => $articleData['id'] ?? null, 'error' => $e->getMessage(), ]); } } } ``` Wire it in `services.yaml` with the notify service URL: ```yaml title="config/services.yaml" services: App\Service\NotificationClient: arguments: $notifyUrl: '%env(NOTIFY_URL)%' ``` Add the notification service to your Docker Compose: ```yaml title="compose.yml (excerpt)" services: app: environment: OTEL_SERVICE_NAME: symfony-articles NOTIFY_URL: http://notify:8081 notify: build: context: ./notify environment: <<: *otel-env OTEL_SERVICE_NAME: symfony-notify ports: - "8081:8081" ``` When `app` calls `notify`, the trace spans from both services are linked automatically. In Scout Dashboard, you'll see the full request flow: ```plaintext symfony-articles: POST /api/articles +-- NotificationClient: POST http://notify:8081/notify +-- symfony-notify: POST /notify (linked trace) ``` ### Symfony-Specific Features #### Automatic HTTP Request Tracing The `opentelemetry-auto-symfony` package instruments the Symfony HTTP kernel automatically. Every request creates a root span with: - `http.method` - Request method (GET, POST, etc.) - `http.route` - Matched route pattern (e.g., `/api/articles/{id}`) - `http.status_code` - Response status code - `http.target` - Request URI path PHP attribute-based routing maps directly to span names: ```php #[Route('/api/articles', name: 'article_list', methods: ['GET'])] public function list(): JsonResponse { // Auto-instrumented: creates span "GET /api/articles" } #[Route('/api/articles/{id}', name: 'article_show', methods: ['GET'])] public function show(int $id): JsonResponse { // Auto-instrumented: creates span "GET /api/articles/{id}" // Uses route pattern, not the actual ID (low cardinality) } ``` #### Doctrine ORM Query Tracing All Doctrine queries are automatically traced via `opentelemetry-auto-pdo`. Each query creates a span with these attributes: - `db.system` - Database type (`mysql`, `pgsql`, `sqlite`) - `db.name` - Database name - `db.statement` - SQL query (parameters obfuscated) - `db.operation` - Operation type (`SELECT`, `INSERT`, `UPDATE`, `DELETE`) ```php // These Doctrine operations are all automatically traced: // Repository query $articles = $this->articleRepository->findPaginated($page, $perPage); // Entity persist $this->entityManager->persist($article); $this->entityManager->flush(); // DQL query $query = $this->entityManager->createQuery( 'SELECT a FROM App\Entity\Article a WHERE a.title LIKE :term' ); $results = $query->setParameter('term', '%symfony%')->getResult(); ``` In Scout Dashboard, you'll see spans like: ```plaintext SELECT articles ... WHERE ... (db.system=mysql, db.operation=SELECT) INSERT INTO articles ... (db.system=mysql, db.operation=INSERT) ``` #### Monolog Trace-Log Correlation The `OtelTraceProcessor` registered earlier injects trace context into every log entry. Combined with JSON formatting, each log line contains: ```json { "message": "Article created", "context": { "article_id": 42 }, "extra": { "trace_id": "a1b2c3d4e5f6a1b2c3d4e5f6a1b2c3d4", "span_id": "1a2b3c4d5e6f7a8b", "service.name": "symfony-articles" } } ``` This enables you to: - Search logs by `trace_id` to find all logs from a single request - Jump from a trace in Scout to the corresponding log entries - Correlate errors across services using shared trace context #### Service Container Integration Symfony's dependency injection container makes it straightforward to inject OpenTelemetry interfaces wherever you need custom instrumentation: ```yaml title="config/services.yaml" services: # OTel factories - available for injection in any service OpenTelemetry\API\Metrics\MeterProviderInterface: factory: ['OpenTelemetry\API\Globals', 'meterProvider'] OpenTelemetry\API\Trace\TracerProviderInterface: factory: ['OpenTelemetry\API\Globals', 'tracerProvider'] ``` Then inject in any controller or service: ```php use OpenTelemetry\API\Metrics\MeterProviderInterface; use OpenTelemetry\API\Trace\TracerProviderInterface; class ArticleController extends AbstractController { public function __construct( private readonly ArticleRepository $articleRepository, MeterProviderInterface $meterProvider, TracerProviderInterface $tracerProvider, ) { // Use for custom metrics and spans } } ``` ### Custom Instrumentation While automatic instrumentation covers HTTP requests, database queries, and HTTP client calls, you can add custom spans and metrics for business logic. #### Custom Business Metrics Inject `MeterProviderInterface` to create counters, histograms, and gauges for business events: ```php title="src/Controller/ArticleController.php" showLineNumbers getMeter('symfony-articles'); $this->articlesCreatedCounter = $meter->createCounter( 'articles.created', 'articles', 'Number of articles created', ); } #[Route('', name: 'article_create', methods: ['POST'])] public function create(Request $request): JsonResponse { $payload = json_decode($request->getContent(), true); $article = new Article(); $article->setTitle($payload['title']); $article->setBody($payload['body']); $this->articleRepository->save($article); $this->articlesCreatedCounter->add(1); $this->logger->info('Article created', ['article_id' => $article->getId()]); $this->notificationClient->notifyArticleCreated($article->toArray()); return new JsonResponse([ 'data' => $article->toArray(), 'meta' => ['trace_id' => $this->getTraceId()], ], Response::HTTP_CREATED); } private function getTraceId(): string { $span = \OpenTelemetry\API\Trace\Span::getCurrent(); return $span->getContext()->getTraceId(); } } ``` The `articles.created` counter increments on every article creation. Use `getTraceId()` to include the trace ID in API responses, helping clients correlate their requests with backend traces. #### Manual Span Creation Create custom spans for business-critical operations that aren't covered by auto-instrumentation: ```php title="src/Service/ReportGenerator.php" showLineNumbers getTracer('report-generator', '1.0.0'); $span = $tracer->spanBuilder('generate_report') ->setSpanKind(SpanKind::KIND_INTERNAL) ->setAttribute('report.type', $reportType) ->setAttribute('user.id', $userId) ->startSpan(); $scope = $span->activate(); try { // Your report generation logic here $data = $this->queryReportData($userId, $reportType); $formatted = $this->formatReport($data); $span->setAttribute('report.row_count', count($data)); $span->setStatus(StatusCode::STATUS_OK); return $formatted; } catch (\Throwable $e) { $span->recordException($e); $span->setStatus(StatusCode::STATUS_ERROR, $e->getMessage()); throw $e; } finally { $scope->detach(); $span->end(); } } } ``` #### Adding Context to Existing Spans Enrich auto-instrumented spans with business context using event listeners: ```php title="src/EventListener/TraceContextListener.php" showLineNumbers isMainRequest()) { return; } $span = Span::getCurrent(); $request = $event->getRequest(); $span->setAttribute('http.request_id', $request->headers->get('X-Request-ID', '')); // Add tenant context for multi-tenant applications if ($tenantId = $request->headers->get('X-Tenant-ID')) { $span->setAttribute('tenant.id', $tenantId); } } } ``` Register it in `services.yaml`: ```yaml title="config/services.yaml" services: App\EventListener\TraceContextListener: tags: - { name: kernel.event_listener, event: kernel.request } ``` ### Running Your Instrumented Application #### Development Mode Start the Symfony development server with OpenTelemetry enabled: ```bash # Set environment variables export OTEL_PHP_AUTOLOAD_ENABLED=true export OTEL_SERVICE_NAME=symfony-app-dev export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 export OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf # Start Symfony development server php -S 0.0.0.0:8080 -t public ``` #### Docker Deployment Run the full stack with Docker Compose: ```bash # Start all services (app, database, collector) docker compose up --build # Wait for services to be healthy docker compose ps # Verify the app is running curl http://localhost:8080/api/health ``` Expected health check response: ```json { "data": { "status": "ok" } } ``` #### Verifying Instrumentation Make test requests and check that traces appear: ```bash # Create an article curl -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Hello OpenTelemetry", "body": "Tracing with Symfony"}' # List articles curl http://localhost:8080/api/articles # Get a specific article curl http://localhost:8080/api/articles/1 ``` Each request generates a trace. The expected span hierarchy for a create request: ```plaintext POST /api/articles (SERVER - auto-symfony) +-- ArticleController::create (INTERNAL - auto-symfony) +-- INSERT INTO articles ... (CLIENT - auto-pdo) +-- POST http://notify:8081/notify (CLIENT - auto-psr18) ``` For a list request: ```plaintext GET /api/articles (SERVER - auto-symfony) +-- ArticleController::list (INTERNAL - auto-symfony) +-- SELECT * FROM articles ... (CLIENT - auto-pdo) +-- SELECT COUNT(*) ... (CLIENT - auto-pdo) ``` Check for: - **Spans** with correct `service.name` and proper nesting - **Logs** with `trace_id` and `span_id` in the JSON output - **Metrics** with `articles.created` counter incrementing ### Troubleshooting #### Verifying OpenTelemetry Installation ```bash # Verify extension is loaded php -m | grep opentelemetry # Check extension version php -r "echo phpversion('opentelemetry');" # Verify environment variables php -r "echo getenv('OTEL_PHP_AUTOLOAD_ENABLED');" ``` #### Common Issues ##### Issue: No traces appearing in Scout Dashboard **Solutions:** 1. Verify the collector endpoint is reachable: ```bash curl -v http://localhost:4318/v1/traces ``` 2. Check that autoload is enabled: ```bash php -r "echo getenv('OTEL_PHP_AUTOLOAD_ENABLED');" # Should output: true ``` 3. Enable debug logging to see export errors: ```bash export OTEL_LOG_LEVEL=debug php -S 0.0.0.0:8080 -t public ``` 4. Check collector logs for authentication errors: ```bash docker compose logs otel-collector ``` ##### Issue: Doctrine/PDO queries not traced **Solutions:** 1. Verify the `opentelemetry-auto-pdo` package is installed: ```bash composer show | grep opentelemetry-auto-pdo ``` 2. Confirm the OpenTelemetry extension is loaded (required for all auto-instrumentation): ```bash php -m | grep opentelemetry ``` 3. Ensure `OTEL_PHP_AUTOLOAD_ENABLED=true` is set. Without this, no auto-instrumentation packages activate. ##### Issue: Log correlation not working (missing trace_id) **Solutions:** 1. Verify `OtelTraceProcessor` is registered in `services.yaml`: ```yaml App\Service\OtelTraceProcessor: tags: - { name: monolog.processor } ``` 2. Ensure Monolog uses the JSON formatter: ```yaml monolog: handlers: main: formatter: monolog.formatter.json ``` 3. Check that the processor class implements `ProcessorInterface`: ```bash grep "ProcessorInterface" src/Service/OtelTraceProcessor.php ``` ##### Issue: OpenTelemetry extension not loaded **Solutions:** 1. Verify PECL installation: ```bash pecl list | grep opentelemetry ``` 2. Check that `php.ini` includes the extension: ```bash php --ini | head -1 php -i | grep opentelemetry ``` 3. Locate the extension file: ```bash find /usr -name "opentelemetry.so" 2>/dev/null ``` 4. If using PHP-FPM, restart it after installing: ```bash sudo systemctl restart php8.4-fpm ``` ##### Issue: High memory usage **Solutions:** 1. Reduce the batch queue size: ```bash export OTEL_BSP_MAX_QUEUE_SIZE=1024 ``` 2. Increase export frequency to flush spans sooner: ```bash export OTEL_BSP_SCHEDULE_DELAY_MILLIS=2000 ``` 3. Check PHP memory limit: ```bash php -i | grep memory_limit ``` ### Security Considerations #### Protecting Sensitive Data Never add sensitive information to span attributes: ```php // Bad - exposes sensitive data $span->setAttribute('user.password', $user->getPassword()); // Never! $span->setAttribute('user.email', $user->getEmail()); // PII risk $span->setAttribute('payment.card_number', $request->get('cc')); // Never! // Good - uses safe identifiers $span->setAttribute('user.id', $user->getId()); $span->setAttribute('user.role', $user->getRoleLabel()); $span->setAttribute('payment.provider', 'stripe'); $span->setAttribute('payment.status', 'completed'); ``` #### SQL Parameter Obfuscation The `opentelemetry-auto-pdo` package automatically obfuscates SQL parameter values in database spans: ```sql -- What gets executed (never sent to collector) SELECT * FROM users WHERE email = 'user@example.com' AND api_key = 'sk-abc123' -- What appears in the span (obfuscated) SELECT * FROM users WHERE email = ? AND api_key = ? ``` #### Filtering HTTP Headers Avoid capturing sensitive headers in spans. Configure which headers are allowed: ```bash title=".env" OTEL_HTTP_HEADERS_ALLOWED=content-type,accept,user-agent ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Never include personally identifiable information (PII) in spans - Use hashed or anonymized user identifiers - SQL obfuscation is enabled by default for database queries - Implement data retention policies in Scout Dashboard - Audit span attributes regularly for sensitive data leaks ### Performance Considerations #### Expected Performance Impact OpenTelemetry instrumentation adds minimal overhead to Symfony applications: - **Average latency increase**: 2-4ms per request - **CPU overhead**: Less than 3% with batch processing - **Memory overhead**: ~80-120MB depending on queue size and traffic #### Optimization Best Practices ##### 1. Use Batch Span Processing ```bash # Production settings (low overhead) OTEL_BSP_MAX_QUEUE_SIZE=2048 OTEL_BSP_SCHEDULE_DELAY_MILLIS=5000 OTEL_BSP_MAX_EXPORT_BATCH_SIZE=512 ``` ##### 2. Enable GZIP Compression ```bash OTEL_EXPORTER_OTLP_COMPRESSION=gzip ``` Reduces network bandwidth by 70-80%. ##### 3. Enable OPcache ```ini title="php.ini" [opcache] opcache.enable=1 opcache.memory_consumption=256 opcache.interned_strings_buffer=16 opcache.max_accelerated_files=20000 opcache.validate_timestamps=0 ``` ##### 4. Filter Health Check Endpoints Configure the OTel Collector to drop noisy health check spans: ```yaml title="config/otel-config.yaml (excerpt)" processors: filter/noisy: error_mode: ignore traces: span: - 'attributes["http.target"] == "/api/health"' ``` This keeps your trace data focused on meaningful application traffic. ### Frequently Asked Questions #### Does OpenTelemetry impact Symfony performance? OpenTelemetry adds approximately 2-4ms of latency per request in typical Symfony applications. With batch processing and GZIP compression enabled, the performance impact is minimal. The `opentelemetry` PECL extension handles instrumentation hooks at the C level, keeping PHP-side overhead low. #### Which Symfony versions are supported? OpenTelemetry supports Symfony 5.4+ with PHP 8.1+. Symfony 7.x or 8.x with PHP 8.3+ is recommended. The `opentelemetry-auto-symfony` package hooks into Symfony's HTTP kernel, which has been stable across major versions. #### Are Doctrine ORM queries traced automatically? Yes. The `opentelemetry-auto-pdo` package intercepts all PDO calls, which includes every query Doctrine executes through DBAL. You get spans for `SELECT`, `INSERT`, `UPDATE`, and `DELETE` operations with the SQL statement (parameters obfuscated) and database metadata. #### Does the Symfony HTTP client propagate trace context? Yes. The `opentelemetry-auto-psr18` package automatically injects W3C `traceparent` headers into outgoing HTTP requests made via Symfony's `HttpClientInterface`. This enables distributed tracing across services with no code changes. #### How do I instrument Symfony Messenger consumers? The `opentelemetry-auto-symfony` package traces HTTP-triggered message dispatches. For async consumers (workers), add manual spans around message handling: ```php #[AsMessageHandler] class OrderHandler { public function __invoke(OrderCreated $message): void { $tracer = Globals::tracerProvider()->getTracer('messenger'); $span = $tracer->spanBuilder('handle_order_created') ->setSpanKind(SpanKind::KIND_CONSUMER) ->setAttribute('messaging.system', 'symfony_messenger') ->setAttribute('order.id', $message->orderId) ->startSpan(); $scope = $span->activate(); try { // Handle the message $span->setStatus(StatusCode::STATUS_OK); } catch (\Throwable $e) { $span->recordException($e); $span->setStatus(StatusCode::STATUS_ERROR); throw $e; } finally { $scope->detach(); $span->end(); } } } ``` #### Can I use OpenTelemetry with Symfony Flex recipes? There is no official Symfony Flex recipe for OpenTelemetry yet. Configuration is done via environment variables and `services.yaml` as shown in this guide. The setup is straightforward and doesn't require a recipe. #### How do I monitor multi-service Symfony architectures? Each service gets its own `OTEL_SERVICE_NAME`. The Symfony HTTP client with `opentelemetry-auto-psr18` automatically propagates W3C `traceparent` headers between services. In Scout Dashboard, you'll see linked traces spanning all services in a single request flow. #### Can I use OpenTelemetry alongside other APM tools? Yes, OpenTelemetry can run alongside tools like New Relic or Datadog during migration periods. However, running multiple APM agents simultaneously multiplies the performance overhead. Plan your migration to run both tools temporarily, then remove the legacy agent. #### How do I add tenant context in multi-tenant Symfony applications? Use a kernel event listener to add tenant attributes to every span: ```php class TenantContextListener { public function onKernelRequest(RequestEvent $event): void { $span = Span::getCurrent(); $tenantId = $event->getRequest()->headers->get('X-Tenant-ID'); if ($tenantId) { $span->setAttribute('tenant.id', $tenantId); } } } ``` Then filter traces by `tenant.id` in Scout Dashboard. #### Does OpenTelemetry work with Symfony CLI? Yes. The Symfony CLI development server (`symfony server:start`) works with OpenTelemetry. Set the environment variables in your `.env.local` file and the CLI will pass them through to the PHP process. #### How do I correlate logs with traces? Register a custom Monolog processor that reads the current span context and injects `trace_id` and `span_id` into every log record. With JSON log formatting, Scout can then match logs to their traces. ### What's Next? Now that your Symfony application is instrumented with OpenTelemetry, explore these resources to deepen your observability: #### Advanced Topics - **Custom PHP Instrumentation** - Manual tracing, custom spans, and advanced instrumentation patterns - **MySQL Monitoring Best Practices** - Database observability with connection pooling metrics and query performance analysis #### Scout Platform Features - **Creating Alerts** - Set up alerts for error rates, latency thresholds, and custom metrics - **Dashboard Creation** - Build custom dashboards combining traces, metrics, and business KPIs #### Deployment and Operations - **Docker Compose Setup** - Set up Scout Collector for local development and testing #### Related Guides - [PHP Custom Instrumentation](../custom-instrumentation/php.md) - Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language ### Complete Example #### Project Structure ```plaintext symfony-mysql/ +-- app/ | +-- config/ | | +-- packages/ | | | +-- doctrine.yaml | | | +-- framework.yaml | | | +-- monolog.yaml | | +-- services.yaml | +-- src/ | | +-- Controller/ | | | +-- ArticleController.php | | | +-- HealthController.php | | +-- Entity/ | | | +-- Article.php | | +-- Repository/ | | | +-- ArticleRepository.php | | +-- Service/ | | +-- NotificationClient.php | | +-- OtelTraceProcessor.php | +-- composer.json | +-- Dockerfile +-- notify/ | +-- Dockerfile | +-- server.php +-- config/ | +-- otel-config.yaml +-- compose.yml +-- .env.example ``` #### Running the Example The full source is in [php/symfony-mysql](https://github.com/base-14/examples/tree/main/php/symfony-mysql). ```bash # Clone the examples repository git clone https://github.com/base-14/examples.git cd examples/php/symfony-mysql # Copy environment file cp .env.example .env # Start the stack docker compose up --build # Wait for services to be healthy (~30 seconds) curl http://localhost:8080/api/health ``` #### Testing the API ```bash # Create an article curl -s -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "OpenTelemetry with Symfony", "body": "Full observability"}' | jq . # List articles curl -s http://localhost:8080/api/articles | jq . # Update an article curl -s -X PUT http://localhost:8080/api/articles/1 \ -H "Content-Type: application/json" \ -d '{"title": "Updated Title"}' | jq . # Delete an article curl -s -X DELETE http://localhost:8080/api/articles/1 ``` #### Expected Trace Output After making requests, you'll see traces in Scout Dashboard with: - **HTTP spans** for each controller action (GET, POST, PUT, DELETE) - **Database spans** for every Doctrine query (SELECT, INSERT, UPDATE, DELETE) - **HTTP client spans** for the notification service call (POST to notify) - **Correlated logs** with `trace_id` and `span_id` in every log entry ```plaintext POST /api/articles (2ms) +-- ArticleController::create (1ms) +-- INSERT INTO articles ... (3ms) +-- POST http://notify:8081/notify (12ms) +-- [symfony-notify] POST /notify (8ms) ``` Once telemetry is flowing, you can monitor Symfony request performance in Scout - track Doctrine query times, HTTP client latency, and error rates from a unified dashboard. ### References - [Official OpenTelemetry PHP Documentation](https://opentelemetry.io/docs/languages/php/) - [OpenTelemetry PHP Auto-Instrumentation](https://opentelemetry.io/docs/languages/php/instrumentation/) - [Symfony Documentation](https://symfony.com/doc/current/index.html) - [Doctrine ORM Documentation](https://www.doctrine-project.org/projects/orm.html) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development. - [PHP Custom Instrumentation](../custom-instrumentation/php.md) - Manual spans and advanced patterns. - [WordPress](./wordpress.md) - self-hosted WordPress on Apache or PHP-FPM. - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language. --- ## tRPC OpenTelemetry Instrumentation - Prisma & PostgreSQL Tracing ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## tRPC :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Implement OpenTelemetry instrumentation for tRPC applications to get full distributed tracing across your TypeScript backend, including Prisma database queries, inter-service HTTP calls, and structured logging with trace context. This guide shows you how to instrument a tRPC application using the OpenTelemetry Node.js SDK with `PrismaInstrumentation` for automatic database query spans, `getNodeAutoInstrumentations()` for HTTP server and client tracing, and Pino for structured logs correlated to traces. tRPC is a type-safe API layer rather than a standalone server. It runs as an adapter on top of frameworks like [Express](./express.md), [Fastify](./fastify.md), and [Next.js](./nextjs-scout.md). tRPC applications benefit from automatic instrumentation of the HTTP layer, Prisma ORM queries, and outbound `fetch()` calls. With OpenTelemetry, you can trace requests from the REST API surface through tRPC procedure calls into Prisma database operations, follow distributed traces across microservices, and correlate structured logs to specific traces. The `createCallerFactory` pattern used in tRPC works naturally with OpenTelemetry because the HTTP instrumentation creates the root span, and Prisma instrumentation captures every downstream query as a child span. Whether you're building a new tRPC backend, adding observability to an existing application, or migrating from DataDog or New Relic to open-source observability, this guide provides production-ready configurations for tRPC with Prisma, PostgreSQL, and base14 Scout. :::tip TL;DR Create a `tracing.ts` file that initializes `NodeSDK` with `getNodeAutoInstrumentations()` and `PrismaInstrumentation`, then preload it via `node --require ./dist/tracing.js`. This single step auto-instruments HTTP endpoints, Prisma queries, outbound `fetch()` calls, and Pino logs. Set `OTEL_SERVICE_NAME` and `OTEL_EXPORTER_OTLP_ENDPOINT` to point at your Scout collector. ::: ### Who This Guide Is For This documentation is designed for: - **tRPC developers**: adding observability and distributed tracing to type-safe TypeScript APIs for the first time - **Backend engineers**: running tRPC with Prisma and PostgreSQL who need production monitoring and query performance visibility - **DevOps teams**: deploying tRPC microservices with Docker and needing end-to-end trace correlation across services - **Engineering teams**: migrating from DataDog, New Relic, or other commercial APM solutions to open-source OpenTelemetry - **Full-stack developers**: debugging slow Prisma queries, failed procedures, or inter-service communication issues in production ### Overview This guide demonstrates how to: - Set up OpenTelemetry instrumentation for tRPC applications with Prisma - Configure automatic tracing for HTTP endpoints and database queries - Instrument inter-service communication with automatic W3C trace propagation - Add structured logging with Pino that includes trace context in every log line - Create custom metrics (counters, histograms) for business-level monitoring - Map REST endpoints to tRPC procedures using `createCallerFactory` - Export telemetry data to base14 Scout via OTLP/gRPC - Deploy instrumented applications with Docker and Docker Compose #### Prerequisites Before starting, ensure you have: - **Node.js 24.0.0 or later** installed (Krypton LTS recommended) - **tRPC 11.x** installed (`@trpc/server`) - **Prisma 7.x** with the PostgreSQL adapter (`@prisma/adapter-pg`) - **Scout Collector** configured and accessible from your application - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - See [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for production deployment - **Basic understanding** of OpenTelemetry concepts (traces, spans, attributes) - Docker and Docker Compose for running the complete example #### Compatibility Matrix | Component | Minimum Version | Recommended Version | Notes | | ----------------------- | --------------- | ------------------- | ---------------------------------- | | **Node.js** | 22.0.0 | 24.x LTS | Krypton - Active until April 2028 | | **tRPC** | 11.0.0 | 11.16.0+ | v11 with createCallerFactory | | **Prisma** | 6.0.0 | 7.6.0+ | @prisma/instrumentation required | | **TypeScript** | 5.5.0 | 6.0.2+ | Full type safety | | **OpenTelemetry SDK** | 0.200.0 | 0.214+ | Core SDK for traces and metrics | | **Zod** | 3.22.0 | 4.3.6+ | Input validation for procedures | | **Pino** | 9.0.0 | 10.3.1+ | Structured logging with OTel mixin | | **PostgreSQL** | 15.0 | 18.x | Primary database | | **OTel Collector** | 0.100.0 | 0.148+ | Receives and forwards telemetry | #### Instrumented Components | Component | Instrumentation Method | Spans Generated | | ------------------ | ------------------------------- | ----------------------------------- | | HTTP Server | `@opentelemetry/instrumentation-http` (auto) | `HTTP GET /api/articles`, `HTTP POST /api/articles` | | Prisma Queries | `@prisma/instrumentation` (auto) | `prisma:client:operation`, `prisma:engine:query` | | HTTP Client (fetch) | `@opentelemetry/instrumentation-http` (auto) | `HTTP POST http://notify:8081/notify` | | Pino Logs | `@opentelemetry/instrumentation-pino` (auto) | Log records with trace_id, span_id | | Custom Metrics | `@opentelemetry/api` (manual) | `articles.created` counter | #### Example Application The complete working example is available on GitHub: [base-14/examples/nodejs/trpc-postgres](https://github.com/base-14/examples/tree/main/nodejs/trpc-postgres) The example implements a two-service article management API: - **app** (port 8080) -- tRPC + Prisma + PostgreSQL article CRUD - **notify** (port 8081) -- notification service receiving events via HTTP ### Installation #### Core Packages Install the required OpenTelemetry and application packages: ```mdx-code-block ``` ```bash npm install @opentelemetry/api \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-grpc \ @opentelemetry/exporter-metrics-otlp-grpc \ @opentelemetry/exporter-logs-otlp-grpc \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @prisma/instrumentation ``` ```mdx-code-block ``` ```bash yarn add @opentelemetry/api \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-grpc \ @opentelemetry/exporter-metrics-otlp-grpc \ @opentelemetry/exporter-logs-otlp-grpc \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @prisma/instrumentation ``` ```mdx-code-block ``` ```bash pnpm add @opentelemetry/api \ @opentelemetry/sdk-node \ @opentelemetry/auto-instrumentations-node \ @opentelemetry/exporter-trace-otlp-grpc \ @opentelemetry/exporter-metrics-otlp-grpc \ @opentelemetry/exporter-logs-otlp-grpc \ @opentelemetry/resources \ @opentelemetry/semantic-conventions \ @prisma/instrumentation ``` ```mdx-code-block ``` #### Application Dependencies ```mdx-code-block ``` ```bash npm install @trpc/server @prisma/client @prisma/adapter-pg zod pino ``` ```mdx-code-block ``` ```bash yarn add @trpc/server @prisma/client @prisma/adapter-pg zod pino ``` ```mdx-code-block ``` ```bash pnpm add @trpc/server @prisma/client @prisma/adapter-pg zod pino ``` ```mdx-code-block ``` #### Dev Dependencies ```mdx-code-block ``` ```bash npm install -D typescript prisma tsx @types/node ``` ```mdx-code-block ``` ```bash yarn add -D typescript prisma tsx @types/node ``` ```mdx-code-block ``` ```bash pnpm add -D typescript prisma tsx @types/node ``` ```mdx-code-block ``` #### Complete package.json ```json title="package.json" showLineNumbers { "name": "trpc-postgres-app", "version": "1.0.0", "private": true, "scripts": { "build": "tsc", "start": "node --require ./dist/tracing.js ./dist/server.js", "dev": "tsx watch src/server.ts" }, "dependencies": { "@trpc/server": "^11.16.0", "@prisma/client": "^7.6.0", "@prisma/adapter-pg": "^7.6.0", "@prisma/instrumentation": "^7.6.0", "zod": "^4.3.6", "@opentelemetry/sdk-node": "^0.214.0", "@opentelemetry/api": "^1.9.1", "@opentelemetry/auto-instrumentations-node": "^0.72.0", "@opentelemetry/exporter-trace-otlp-grpc": "^0.214.0", "@opentelemetry/exporter-metrics-otlp-grpc": "^0.214.0", "@opentelemetry/exporter-logs-otlp-grpc": "^0.214.0", "pino": "^10.3.1" }, "devDependencies": { "typescript": "^6.0.2", "prisma": "^7.6.0", "tsx": "^4.19.0", "@types/node": "^24.0.0" } } ``` #### Tracing Setup (tracing.ts) Create `src/tracing.ts` -- this file initializes the OpenTelemetry SDK before any application code loads. The `--require` flag in the start script ensures it runs first. ```typescript title="src/tracing.ts" showLineNumbers import { NodeSDK } from "@opentelemetry/sdk-node"; import { getNodeAutoInstrumentations } from "@opentelemetry/auto-instrumentations-node"; import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-grpc"; import { OTLPMetricExporter } from "@opentelemetry/exporter-metrics-otlp-grpc"; import { OTLPLogExporter } from "@opentelemetry/exporter-logs-otlp-grpc"; import { PeriodicExportingMetricReader } from "@opentelemetry/sdk-metrics"; import { BatchLogRecordProcessor } from "@opentelemetry/sdk-logs"; import { PrismaInstrumentation } from "@prisma/instrumentation"; import { resourceFromAttributes } from "@opentelemetry/resources"; import { ATTR_SERVICE_NAME, ATTR_SERVICE_VERSION, } from "@opentelemetry/semantic-conventions"; const endpoint = process.env.OTEL_EXPORTER_OTLP_ENDPOINT || "http://localhost:4317"; const resource = resourceFromAttributes({ [ATTR_SERVICE_NAME]: process.env.OTEL_SERVICE_NAME || "trpc-articles", [ATTR_SERVICE_VERSION]: process.env.OTEL_SERVICE_VERSION || "1.0.0", }); const logExporter = new OTLPLogExporter({ url: endpoint }); const sdk = new NodeSDK({ resource, traceExporter: new OTLPTraceExporter({ url: endpoint }), metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: endpoint }), exportIntervalMillis: parseInt( process.env.OTEL_METRIC_EXPORT_INTERVAL || "10000" ), }), logRecordProcessors: [new BatchLogRecordProcessor(logExporter)], instrumentations: [ getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-fs": { enabled: false }, "@opentelemetry/instrumentation-http": { ignoreIncomingRequestHook: (req) => req.url?.includes("/health") ?? false, }, "@opentelemetry/instrumentation-pino": { enabled: true, }, }), new PrismaInstrumentation(), ], }); sdk.start(); process.on("SIGTERM", () => { sdk.shutdown().then(() => process.exit(0)); }); ``` Key details in this setup: - **`PrismaInstrumentation`** is registered alongside auto-instrumentations so every Prisma query generates its own span with operation type and model name - **`instrumentation-fs` is disabled** to avoid noisy filesystem spans that add overhead without useful signal - **Health check endpoints are excluded** via `ignoreIncomingRequestHook` to keep traces focused on real traffic - **`instrumentation-pino`** is enabled to automatically inject trace context into Pino log records - **SIGTERM handler** flushes pending telemetry before the process exits, preventing data loss during container shutdowns #### Prisma Schema ```prisma title="prisma/schema.prisma" showLineNumbers generator client { provider = "prisma-client-js" } datasource db { provider = "postgresql" } model Article { id Int @id @default(autoincrement()) title String @db.VarChar(255) body String @db.Text createdAt DateTime @default(now()) @map("created_at") updatedAt DateTime @updatedAt @map("updated_at") @@map("articles") } ``` After defining the schema, generate the Prisma client: ```bash npx prisma generate ``` ### Configuration #### Environment Variables Configure telemetry behavior through environment variables: | Variable | Description | Default | | ------------------------------- | ------------------------------ | ------------------------ | | `OTEL_SERVICE_NAME` | Service name in traces | `trpc-articles` | | `OTEL_EXPORTER_OTLP_ENDPOINT` | Collector gRPC endpoint | `http://localhost:4317` | | `OTEL_SERVICE_VERSION` | Service version tag | `1.0.0` | | `OTEL_METRIC_EXPORT_INTERVAL` | Metric export interval (ms) | `10000` | | `OTEL_RESOURCE_ATTRIBUTES` | Additional resource attributes | -- | | `DATABASE_URL` | PostgreSQL connection string | -- | | `NOTIFY_URL` | Notification service URL | `http://localhost:8081` | | `PORT` | HTTP server port | `8080` | | `LOG_LEVEL` | Pino log level | `info` | #### Pino Logger with Trace Context Create a shared logger that automatically injects `trace_id` and `span_id` into every log line. This lets you jump from a log entry in Scout directly to the trace that produced it. ```typescript title="src/lib/logger.ts" showLineNumbers import pino from "pino"; import { context, trace } from "@opentelemetry/api"; function getTraceContext() { const span = trace.getSpan(context.active()); if (!span) return {}; const ctx = span.spanContext(); return { trace_id: ctx.traceId, span_id: ctx.spanId, }; } const logger = pino({ level: process.env.LOG_LEVEL || "info", mixin() { return getTraceContext(); }, formatters: { level(label) { return { level: label.toUpperCase() }; }, }, timestamp: pino.stdTimeFunctions.isoTime, }); export default logger; ``` The `mixin()` function runs on every log call and pulls the current trace and span IDs from the active OpenTelemetry context. Combined with `instrumentation-pino`, this means your logs in Scout are automatically linked to the request trace that generated them. #### Scout Collector Integration The OTel Collector sits between your application and base14 Scout. It handles batching, retry, compression, and OAuth2 authentication. ```yaml title="config/otel-config.yaml" showLineNumbers extensions: oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s tls: insecure_skip_verify: true health_check: endpoint: 0.0.0.0:13133 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: limit_mib: 256 check_interval: 1s batch: send_batch_size: 1024 timeout: 5s resource: attributes: - key: deployment.environment value: ${env:SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${env:SCOUT_ENVIRONMENT} action: upsert filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*health.*")' filter/logs: error_mode: ignore logs: log_record: - 'severity_number < SEVERITY_NUMBER_INFO' transform/log_severity: error_mode: ignore log_statements: - context: log statements: - set(severity_text, "INFO") where severity_number >= SEVERITY_NUMBER_INFO and severity_number < SEVERITY_NUMBER_WARN - set(severity_text, "WARN") where severity_number >= SEVERITY_NUMBER_WARN and severity_number < SEVERITY_NUMBER_ERROR - set(severity_text, "ERROR") where severity_number >= SEVERITY_NUMBER_ERROR exporters: otlp_http/scout: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: detailed service: extensions: [oauth2client, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, resource, batch] exporters: [otlp_http/scout, debug] metrics: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [otlp_http/scout, debug] logs: receivers: [otlp] processors: [memory_limiter, filter/logs, transform/log_severity, resource, batch] exporters: [otlp_http/scout, debug] ``` Scout Collector environment variables: | Variable | Description | | --------------------- | ------------------------------------ | | `SCOUT_ENDPOINT` | base14 Scout OTLP/HTTP endpoint | | `SCOUT_CLIENT_ID` | OAuth2 client ID for authentication | | `SCOUT_CLIENT_SECRET` | OAuth2 client secret | | `SCOUT_TOKEN_URL` | OAuth2 token endpoint URL | | `SCOUT_ENVIRONMENT` | Deployment environment label | #### Docker Compose The full stack runs with Docker Compose -- application, notification service, PostgreSQL, and OTel Collector: ```yaml title="compose.yml" showLineNumbers services: app: build: ./app ports: - "8080:8080" environment: PORT: "8080" DATABASE_URL: postgresql://postgres:postgres@db:5432/trpc_articles NOTIFY_URL: http://notify:8081 OTEL_SERVICE_NAME: trpc-articles OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: "10000" OTEL_RESOURCE_ATTRIBUTES: deployment.environment=${SCOUT_ENVIRONMENT:-development},environment=${SCOUT_ENVIRONMENT:-development},service.namespace=examples depends_on: db: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:8080/api/health"] interval: 10s timeout: 5s retries: 10 start_period: 20s notify: build: ./notify ports: - "8081:8081" environment: PORT: "8081" OTEL_SERVICE_NAME: trpc-notify OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: "10000" OTEL_RESOURCE_ATTRIBUTES: deployment.environment=${SCOUT_ENVIRONMENT:-development},environment=${SCOUT_ENVIRONMENT:-development},service.namespace=examples depends_on: otel-collector: condition: service_started healthcheck: test: ["CMD", "wget", "--no-verbose", "--tries=1", "--spider", "http://localhost:8081/api/health"] interval: 10s timeout: 5s retries: 5 start_period: 10s db: image: postgres:18-alpine environment: POSTGRES_DB: trpc_articles POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres ports: - "5432:5432" volumes: - pgdata:/var/lib/postgresql/data - ./db/init.sql:/docker-entrypoint-initdb.d/init.sql:ro healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 3s retries: 10 otel-collector: image: otel/opentelemetry-collector-contrib:0.148.0 command: ["--config=/etc/otel/config.yaml"] volumes: - ./config/otel-config.yaml:/etc/otel/config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" environment: SCOUT_ENDPOINT: ${SCOUT_ENDPOINT:-http://localhost:4318} SCOUT_CLIENT_ID: ${SCOUT_CLIENT_ID:-} SCOUT_CLIENT_SECRET: ${SCOUT_CLIENT_SECRET:-} SCOUT_TOKEN_URL: ${SCOUT_TOKEN_URL:-http://localhost/token} SCOUT_ENVIRONMENT: ${SCOUT_ENVIRONMENT:-development} healthcheck: test: ["NONE"] volumes: pgdata: ``` ### Production Configuration #### Production Environment Variables For production deployments, set these environment variables: ```bash OTEL_SERVICE_NAME=trpc-articles OTEL_SERVICE_VERSION=1.2.0 OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL=60000 OTEL_RESOURCE_ATTRIBUTES=deployment.environment=demo,environment=demo,service.namespace=articles,service.instance.id=${HOSTNAME} DATABASE_URL=postgresql://app_user:secure_password@db-primary:5432/trpc_articles?sslmode=require NOTIFY_URL=http://notify:8081 LOG_LEVEL=warn ``` In production, increase `OTEL_METRIC_EXPORT_INTERVAL` to `60000` (60 seconds) to reduce metric export overhead. Set `LOG_LEVEL=warn` to reduce log volume while still capturing warnings and errors with trace context. #### Dockerfile Multi-stage build with non-root user for production: ```dockerfile title="app/Dockerfile" showLineNumbers FROM node:24-alpine AS builder WORKDIR /app COPY package*.json ./ RUN npm ci COPY tsconfig.json ./ COPY prisma ./prisma/ RUN npx prisma generate COPY src ./src/ RUN npm run build FROM node:24-alpine AS runtime RUN addgroup -g 1001 -S appgroup && adduser -S appuser -u 1001 -G appgroup WORKDIR /app COPY package*.json ./ RUN npm ci --omit=dev && npm cache clean --force COPY --from=builder /app/dist ./dist/ COPY --from=builder /app/prisma ./prisma/ COPY --from=builder /app/node_modules/.prisma ./node_modules/.prisma/ RUN chown -R appuser:appgroup /app USER appuser HEALTHCHECK --interval=10s --timeout=5s --start-period=15s --retries=5 \ CMD wget --no-verbose --tries=1 --spider http://localhost:8080/api/health || exit 1 EXPOSE 8080 CMD ["node", "--require", "./dist/tracing.js", "./dist/server.js"] ``` Key details: - **`--require ./dist/tracing.js`** ensures the OpenTelemetry SDK initializes and monkey-patches modules before `server.js` imports them - **Prisma client is copied** from the builder stage (`node_modules/.prisma`) so the runtime stage has the generated client without dev dependencies - **Non-root user** (`appuser:1001`) runs the application for container security - **`npm ci --omit=dev`** in the runtime stage excludes TypeScript, tsx, and other dev dependencies from the final image #### Multi-Service Distributed Tracing The notification service demonstrates distributed tracing across services. When the app service creates an article, it calls the notify service via `fetch()`. OpenTelemetry's HTTP instrumentation automatically propagates the W3C `traceparent` header, linking spans across both services into a single trace. ```typescript title="src/service/notification.ts" showLineNumbers import logger from "../lib/logger"; const NOTIFY_URL = process.env.NOTIFY_URL || "http://localhost:8081"; export async function notifyArticleCreated(article: { id: number; title: string; }) { try { const res = await fetch(`${NOTIFY_URL}/notify`, { method: "POST", headers: { "Content-Type": "application/json" }, body: JSON.stringify({ event: "article.created", article_id: article.id, title: article.title, }), }); if (!res.ok) { logger.warn( { status: res.status, article_id: article.id }, "Notify service returned non-OK" ); } } catch (err) { logger.error({ err, article_id: article.id }, "Notify service unreachable"); } } ``` No manual context propagation is needed. The `fetch()` call is intercepted by `@opentelemetry/instrumentation-http`, which injects the `traceparent` header automatically. The notify service's HTTP instrumentation extracts it and creates a child span, completing the distributed trace. ### tRPC-Specific Features #### tRPC Router Setup The tRPC router defines the type-safe API surface. `createCallerFactory` enables server-side procedure calls from the REST bridge layer: ```typescript title="src/router.ts" showLineNumbers import { initTRPC } from "@trpc/server"; const t = initTRPC.create(); export const router = t.router; export const publicProcedure = t.procedure; export const createCallerFactory = t.createCallerFactory; ``` #### REST-to-tRPC Bridge The server maps REST HTTP endpoints to tRPC procedures via `createCallerFactory`. This pattern lets you expose a conventional REST API while keeping all business logic in type-safe tRPC procedures. OpenTelemetry traces the full chain: HTTP request -> tRPC caller -> Prisma query. ```typescript title="src/server.ts (excerpt)" showLineNumbers import http from "node:http"; import { PrismaPg } from "@prisma/adapter-pg"; import { PrismaClient } from "@prisma/client"; import { context, trace } from "@opentelemetry/api"; import { router, createCallerFactory } from "./router"; import { createArticleRouter } from "./routes/article"; import { createHealthRouter } from "./routes/health"; import logger from "./lib/logger"; const adapter = new PrismaPg(process.env.DATABASE_URL!); const prisma = new PrismaClient({ adapter }); const appRouter = router({ health: createHealthRouter(prisma), article: createArticleRouter(prisma), }); export type AppRouter = typeof appRouter; const createCaller = createCallerFactory(appRouter); const caller = createCaller({}); function getTraceId(): string { const span = trace.getSpan(context.active()); return span?.spanContext().traceId || ""; } function json(res: http.ServerResponse, status: number, body: unknown) { res.writeHead(status, { "Content-Type": "application/json" }); res.end(JSON.stringify(body)); } const server = http.createServer(async (req, res) => { const method = req.method || "GET"; const url = req.url || "/"; const path = url.split("?")[0]; try { if (path === "/api/articles" && method === "GET") { const query = parseQuery(url); const result = await caller.article.list({ page: query.page ? Number(query.page) : 1, per_page: query.per_page ? Number(query.per_page) : 20, }); return json(res, 200, { ...result, meta: { ...result.meta, trace_id: getTraceId() }, }); } if (path === "/api/articles" && method === "POST") { const body = (await parseBody(req)) as Record; const result = await caller.article.create({ title: body.title as string, body: body.body as string, }); return json(res, 201, { ...result, meta: { trace_id: getTraceId() }, }); } json(res, 404, { error: "Not found", meta: { trace_id: getTraceId() } }); } catch (err: unknown) { const trpcErr = err as { code?: string; message?: string }; if (trpcErr.code === "NOT_FOUND") { return json(res, 404, { error: trpcErr.message || "Not found", meta: { trace_id: getTraceId() }, }); } logger.error({ err }, "Unhandled error"); json(res, 500, { error: "Internal server error", meta: { trace_id: getTraceId() }, }); } }); const PORT = parseInt(process.env.PORT || "8080"); server.listen(PORT, () => { logger.info({ port: PORT }, "tRPC articles server started"); }); ``` The `getTraceId()` helper extracts the current trace ID from the active span context and includes it in every API response. This lets clients and debugging tools correlate a specific response to its trace in Scout. #### Prisma Auto-Tracing `PrismaInstrumentation` from `@prisma/instrumentation` automatically generates spans for every Prisma operation. Each span includes: - **Operation type**: `findMany`, `create`, `update`, `delete`, `$queryRaw` - **Model name**: `Article`, or raw for `$queryRaw` - **Duration**: time spent in the Prisma engine and database These spans appear as children of the HTTP request span, giving you a clear breakdown of how much time each request spends in the database versus application logic. No additional configuration is needed beyond registering `new PrismaInstrumentation()` in the `instrumentations` array (shown in the tracing.ts setup above). The instrumentation works with both the standard Prisma client and the PostgreSQL adapter (`@prisma/adapter-pg`). #### Zod Validation in Procedures tRPC uses Zod schemas for input validation. When validation fails, tRPC throws a `BAD_REQUEST` error before the procedure body executes. These validation failures still appear in traces because the HTTP span captures the error status code: ```typescript title="src/routes/article.ts (validation example)" showLineNumbers import { z } from "zod"; import { publicProcedure } from "../router"; const createInput = z.object({ title: z.string().min(1).max(255), body: z.string().min(1), }); const listInput = z.object({ page: z.coerce.number().min(1).default(1), per_page: z.coerce.number().min(1).max(100).default(20), }); ``` Zod validation happens synchronously within the span context, so validation errors are captured with the correct trace and span IDs in both the HTTP response and log output. ### Custom Instrumentation #### Custom Metrics (articles.created Counter) Track business-level metrics alongside traces. The `articles.created` counter increments each time a new article is persisted: ```typescript title="src/routes/article.ts" showLineNumbers import { z } from "zod"; import { TRPCError } from "@trpc/server"; import { PrismaClient } from "@prisma/client"; import { router, publicProcedure } from "../router"; import { metrics } from "@opentelemetry/api"; import logger from "../lib/logger"; import { notifyArticleCreated } from "../service/notification"; const meter = metrics.getMeter("trpc-articles"); const articlesCreatedCounter = meter.createCounter("articles.created", { description: "Number of articles created", }); export function createArticleRouter(prisma: PrismaClient) { return router({ list: publicProcedure .input( z.object({ page: z.coerce.number().min(1).default(1), per_page: z.coerce.number().min(1).max(100).default(20), }) ) .query(async ({ input }) => { const { page, per_page } = input; const skip = (page - 1) * per_page; const [articles, total] = await Promise.all([ prisma.article.findMany({ skip, take: per_page, orderBy: { createdAt: "desc" }, }), prisma.article.count(), ]); logger.info({ page, per_page, total }, "Listed articles"); return { data: articles, meta: { page, per_page, total, total_pages: Math.ceil(total / per_page), }, }; }), getById: publicProcedure .input(z.object({ id: z.coerce.number().int().positive() })) .query(async ({ input }) => { const article = await prisma.article.findUnique({ where: { id: input.id }, }); if (!article) { logger.warn({ article_id: input.id }, "Article not found"); throw new TRPCError({ code: "NOT_FOUND", message: `Article ${input.id} not found`, }); } return { data: article }; }), create: publicProcedure .input( z.object({ title: z.string().min(1).max(255), body: z.string().min(1), }) ) .mutation(async ({ input }) => { const article = await prisma.article.create({ data: { title: input.title, body: input.body }, }); articlesCreatedCounter.add(1); logger.info( { article_id: article.id, title: article.title }, "Article created" ); notifyArticleCreated(article).catch((err) => logger.error({ err }, "Failed to notify") ); return { data: article }; }), update: publicProcedure .input( z.object({ id: z.coerce.number().int().positive(), title: z.string().min(1).max(255).optional(), body: z.string().min(1).optional(), }) ) .mutation(async ({ input }) => { const { id, ...data } = input; const existing = await prisma.article.findUnique({ where: { id } }); if (!existing) { logger.warn({ article_id: id }, "Article not found for update"); throw new TRPCError({ code: "NOT_FOUND", message: `Article ${id} not found`, }); } const updateData: Record = {}; if (data.title !== undefined) updateData.title = data.title; if (data.body !== undefined) updateData.body = data.body; if (Object.keys(updateData).length === 0) { return { data: existing }; } const article = await prisma.article.update({ where: { id }, data: updateData, }); logger.info({ article_id: id }, "Article updated"); return { data: article }; }), delete: publicProcedure .input(z.object({ id: z.coerce.number().int().positive() })) .mutation(async ({ input }) => { const existing = await prisma.article.findUnique({ where: { id: input.id }, }); if (!existing) { logger.warn({ article_id: input.id }, "Article not found for delete"); throw new TRPCError({ code: "NOT_FOUND", message: `Article ${input.id} not found`, }); } await prisma.article.delete({ where: { id: input.id } }); logger.info({ article_id: input.id }, "Article deleted"); return null; }), }); } ``` The counter is created at module scope using `metrics.getMeter()`, not inside request handlers. This ensures a single counter instance is reused across all requests rather than being recreated per call. #### Trace ID in API Responses Every API response includes the trace ID in its `meta` field. This pattern is shown in the server.ts excerpt above with the `getTraceId()` helper. Clients can log or display this ID for support workflows -- a user can report a trace ID, and you can look it up in Scout to see the full request lifecycle. #### Manual Spans For operations that aren't automatically instrumented, create manual spans: ```typescript title="Manual span example" showLineNumbers import { trace } from "@opentelemetry/api"; const tracer = trace.getTracer("trpc-articles"); async function processArticleContent(content: string): Promise { return tracer.startActiveSpan("processArticleContent", async (span) => { try { span.setAttribute("content.length", content.length); const processed = content.trim(); span.setAttribute("content.processed_length", processed.length); return processed; } catch (err) { span.recordException(err as Error); throw err; } finally { span.end(); } }); } ``` Use `startActiveSpan` so the span is set as the active span in the context, and any child spans (e.g., from Prisma calls inside) are correctly parented. ### Running Your Application #### Development Mode Run locally with `tsx` for hot-reloading during development: ```bash export OTEL_SERVICE_NAME=trpc-articles export OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 export DATABASE_URL=postgresql://postgres:postgres@localhost:5432/trpc_articles npx tsx watch src/server.ts ``` In development, `tsx` handles the TypeScript compilation. Note that the `--require` flag is only needed for the compiled `node` command in production. With `tsx`, the `tracing.ts` module is imported at the top of the module graph automatically. #### Docker Compose Start the full stack: ```bash docker compose up --build ``` This starts all four services: - **app** on port 8080 (waits for db and otel-collector) - **notify** on port 8081 - **db** (PostgreSQL 18) on port 5432 - **otel-collector** on ports 4317 (gRPC) and 4318 (HTTP) To connect to base14 Scout, provide your credentials: ```bash SCOUT_ENDPOINT=https://your-scout.base14.io \ SCOUT_CLIENT_ID=your-client-id \ SCOUT_CLIENT_SECRET=your-client-secret \ SCOUT_TOKEN_URL=https://auth.base14.io/oauth/token \ SCOUT_ENVIRONMENT=staging \ docker compose up --build ``` #### Verification After the services are running, verify instrumentation is working: **Create an article:** ```bash curl -s -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Hello tRPC", "body": "OpenTelemetry works!"}' | jq . ``` Expected response: ```json { "data": { "id": 1, "title": "Hello tRPC", "body": "OpenTelemetry works!", "createdAt": "2026-03-31T12:00:00.000Z", "updatedAt": "2026-03-31T12:00:00.000Z" }, "meta": { "trace_id": "a1b2c3d4e5f6a1b2c3d4e5f6a1b2c3d4" } } ``` **List articles:** ```bash curl -s http://localhost:8080/api/articles | jq . ``` **Check health:** ```bash curl -s http://localhost:8080/api/health | jq . ``` #### Expected Span Hierarchy After creating an article, you should see this span tree in Scout: ```text HTTP POST /api/articles (trpc-articles) ├── prisma:client:operation create Article │ └── prisma:engine:query INSERT INTO "articles" ... └── HTTP POST http://notify:8081/notify (trpc-articles, outbound) └── HTTP POST /notify (trpc-notify, inbound) ``` The distributed trace links the app service's outbound `fetch()` call to the notify service's inbound HTTP handler, showing the full cross-service flow in a single trace view. ### Troubleshooting #### Issue: No traces appearing in Scout **Solutions:** 1. **Verify the collector is reachable from the app container**: ```bash docker compose exec app wget -q -O- http://otel-collector:4317 ``` 2. **Check that `tracing.ts` loads before `server.ts`** -- the `--require` flag in the Dockerfile CMD must point to the compiled `tracing.js`: ```dockerfile CMD ["node", "--require", "./dist/tracing.js", "./dist/server.js"] ``` 3. **Enable the debug exporter** temporarily to verify spans are created: ```typescript import { ConsoleSpanExporter } from "@opentelemetry/sdk-trace-base"; import { SimpleSpanProcessor } from "@opentelemetry/sdk-trace-base"; const sdk = new NodeSDK({ spanProcessors: [new SimpleSpanProcessor(new ConsoleSpanExporter())], }); ``` #### Issue: Prisma queries not generating spans **Solutions:** 1. **Ensure `@prisma/instrumentation` is installed and registered**: ```bash npm list @prisma/instrumentation ``` Verify it appears in the `instrumentations` array in `tracing.ts`: ```typescript instrumentations: [ getNodeAutoInstrumentations({ /* ... */ }), new PrismaInstrumentation(), ], ``` 2. **Regenerate the Prisma client** after installing the instrumentation package: ```bash npx prisma generate ``` #### Issue: Distributed traces not linking across services **Solutions:** 1. **Both services must send telemetry to the same collector** -- check `OTEL_EXPORTER_OTLP_ENDPOINT` is identical for both `app` and `notify` in `compose.yml`. 2. **Verify W3C traceparent propagation** by inspecting outbound headers: ```typescript const res = await fetch(`${NOTIFY_URL}/notify`, { method: "POST", headers: { "Content-Type": "application/json" }, body: JSON.stringify(payload), }); // OpenTelemetry automatically adds traceparent header // Check notify service logs for matching trace_id ``` #### Issue: Logs missing trace_id and span_id **Solutions:** 1. **Confirm `instrumentation-pino` is enabled** in the auto-instrumentations config: ```typescript getNodeAutoInstrumentations({ "@opentelemetry/instrumentation-pino": { enabled: true }, }), ``` 2. **Verify the Pino `mixin()` function** calls `trace.getSpan(context.active())` -- if the logger is called outside an HTTP request context (e.g., during startup), trace_id will be empty, which is expected. #### Issue: High memory usage in production **Solutions:** 1. **Disable filesystem instrumentation** to reduce span volume: ```typescript "@opentelemetry/instrumentation-fs": { enabled: false }, ``` 2. **Increase metric export interval** to reduce buffering overhead: ```bash OTEL_METRIC_EXPORT_INTERVAL=60000 ``` 3. **Configure the collector's memory limiter** to prevent OOM: ```yaml processors: memory_limiter: limit_mib: 256 check_interval: 1s ``` ### Security Considerations #### SQL Query Obfuscation Prisma instrumentation captures query information in spans. By default, `PrismaInstrumentation` does not include raw SQL parameter values in span attributes. The query text shows the structure (e.g., `SELECT * FROM "articles" WHERE "id" = $1`) with parameterized placeholders, not actual values. If you use `$queryRaw` with string interpolation (which you should avoid for SQL injection reasons), the raw query could appear in spans. Always use parameterized queries: ```typescript // Safe -- parameters are not included in span attributes await prisma.$queryRaw`SELECT 1`; // Safe -- Prisma parameterizes automatically await prisma.article.findUnique({ where: { id: input.id } }); ``` #### PII Protection Avoid setting span attributes that contain personally identifiable information: ```typescript // Do not do this span.setAttribute("user.email", user.email); span.setAttribute("article.body", articleBody); // Do this instead span.setAttribute("user.id", user.id); span.setAttribute("article.id", article.id); span.setAttribute("article.title_length", article.title.length); ``` Log statements with PII should be filtered at the collector level using the `filter/logs` processor, or scrubbed using the `transform` processor before export. #### Collector Authentication The collector config uses OAuth2 (`oauth2client` extension) to authenticate with base14 Scout. Store `SCOUT_CLIENT_ID` and `SCOUT_CLIENT_SECRET` as secrets in your deployment platform (e.g., Kubernetes Secrets, Docker Swarm secrets, or CI/CD environment variables). Never commit these values to source control. ### Performance Considerations #### Instrumentation Overhead Typical overhead with the configuration shown in this guide: | Metric | Impact | | ------------- | ----------------------------- | | Latency | 0.5-2ms per request | | CPU | 2-5% increase | | Memory | 15-30MB additional | | Network | ~1KB per span (gRPC + gzip) | #### Reducing Overhead **Exclude health checks** -- the `ignoreIncomingRequestHook` in tracing.ts already excludes `/health` endpoints. This prevents high-frequency health probes from generating spans. **Disable filesystem instrumentation** -- `@opentelemetry/instrumentation-fs` is disabled in the example configuration. Node.js makes many filesystem calls internally (module resolution, config loading), and tracing them adds noise without actionable signal. **Batch tuning** -- the collector's `batch` processor is configured with `send_batch_size: 1024` and `timeout: 5s`. For high-throughput services, increase the batch size to reduce the number of export calls. For low-throughput services, decrease the timeout to ensure spans are exported promptly. **GZIP compression** -- the collector-to-Scout exporter uses `compression: gzip` to reduce network bandwidth. This is already configured in the collector config above. The application-to-collector connection uses gRPC, which handles compression at the transport level. ### FAQ #### Does tRPC need a special OpenTelemetry instrumentation library? No. tRPC runs on top of Node.js HTTP, and OpenTelemetry's HTTP instrumentation traces all incoming requests automatically. The `createCallerFactory` pattern means tRPC procedures execute within the HTTP span context, so Prisma queries and other operations are correctly parented without any tRPC-specific library. #### Why use `--require` instead of importing tracing.ts directly? The `--require` flag ensures `tracing.ts` executes before any other module loads. OpenTelemetry works by monkey-patching Node.js modules (`http`, `net`, etc.) at import time. If your server imports `http` before the SDK initializes, those imports won't be instrumented. `--require` guarantees the SDK patches modules first. #### Can I use the tRPC HTTP adapter instead of a REST bridge? Yes. If you use `@trpc/server/adapters/node` or `@trpc/server/adapters/express`, HTTP instrumentation still creates spans for every request. The tracing setup in `tracing.ts` does not depend on the REST bridge pattern. However, the bridge pattern shown here gives you control over URL paths, status codes, and response formatting. #### How do I trace tRPC subscriptions (WebSocket)? For WebSocket-based tRPC subscriptions, add `@opentelemetry/instrumentation-ws` to the instrumentations array. WebSocket frames won't generate per-message spans by default, but connection establishment and upgrade requests will be traced. #### What happens if the collector is down? The OTLP gRPC exporter retries failed exports with exponential backoff. If the collector remains unreachable, spans accumulate in memory up to the `maxQueueSize` limit (default 2048). Once the queue is full, new spans are dropped. The application continues to function normally -- telemetry loss does not affect request processing. #### How do I add custom attributes to Prisma spans? `PrismaInstrumentation` does not support custom attribute hooks directly. Instead, add attributes to the parent span (the HTTP request span) or create a manual child span around the Prisma call: ```typescript const tracer = trace.getTracer("trpc-articles"); const article = await tracer.startActiveSpan("findArticle", async (span) => { span.setAttribute("article.id", id); const result = await prisma.article.findUnique({ where: { id } }); span.setAttribute("article.found", result !== null); span.end(); return result; }); ``` #### How do I correlate logs with traces in Scout? The Pino logger's `mixin()` function injects `trace_id` and `span_id` into every log record. When logs are exported to Scout via the OTel Collector's logs pipeline, Scout automatically links log entries to their parent trace. You can click from a log entry to see the full trace, or from a trace span to see all logs emitted during that span. #### Does the notify service need PrismaInstrumentation? No. The notify service does not use Prisma or a database. It only needs `getNodeAutoInstrumentations()` to trace inbound HTTP requests and enable Pino log correlation. This is why the notify service's `tracing.ts` does not include `PrismaInstrumentation`. #### Can I use OTLP/HTTP instead of OTLP/gRPC? Yes. Replace the gRPC exporter packages with their HTTP equivalents: ```bash npm install @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http ``` Update the endpoint to port 4318 and append the signal path: ```typescript const traceExporter = new OTLPTraceExporter({ url: "http://otel-collector:4318/v1/traces", }); ``` #### How do I add request duration histograms? Create a histogram using the meter API and record durations in the HTTP handler: ```typescript const requestDuration = meter.createHistogram("http.request.duration", { description: "HTTP request duration in milliseconds", unit: "ms", }); const start = performance.now(); // ... handle request ... requestDuration.record(performance.now() - start, { "http.method": method, "http.route": path, "http.status_code": statusCode, }); ``` #### How do I add OpenTelemetry tracing to a tRPC application? Create a `tracing.ts` file that initializes the OpenTelemetry `NodeSDK` with `getNodeAutoInstrumentations()` and `PrismaInstrumentation`, then preload it via `node --require ./dist/tracing.js` before your server starts. #### Does OpenTelemetry automatically trace Prisma queries in tRPC? Yes. Register `PrismaInstrumentation` from `@prisma/instrumentation` in your `NodeSDK` instrumentations array. Prisma queries such as `findMany`, `create`, `update`, and `delete` then generate spans carrying the query details. #### How does distributed tracing work across tRPC microservices? Node.js `fetch()` is auto-instrumented by OpenTelemetry HTTP instrumentation. When one service calls another via `fetch`, W3C `traceparent` headers propagate automatically, linking spans across services into a single trace. #### What is the performance overhead of OpenTelemetry on tRPC? Typical overhead is 0.5-2ms per request, a 2-5% CPU increase, and 15-30MB of additional memory. `BatchSpanProcessor` and excluding health check endpoints keep it at the lower end of that range. #### Can I use tRPC createCallerFactory with OpenTelemetry? Yes. HTTP instrumentation creates the parent span and Prisma instrumentation traces the database calls made inside the caller, so the whole chain shows up without extra wiring. ### What's Next? #### Related Guides - [NestJS Instrumentation](./nestjs.md) - Structured framework with tRPC support - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Advanced Topics - [OpenTelemetry Collector Configuration](../../collector-setup/otel-collector-config.md) \- Advanced collector features, processors, and exporters #### base14 Scout Platform Features - [Creating Alerts with LogX](../../../guides/creating-alerts-with-logx.md) - Set up alerts based on traces and metrics - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build custom dashboards for tRPC applications #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development environment with collector - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production Kubernetes deployment - [Scout Exporter Configuration](../../collector-setup/scout-exporter.md) - Configure authentication and endpoints ### Complete Example A complete production-ready example with tRPC 11.16, Prisma 7.6, PostgreSQL 18, TypeScript 6.0, and OpenTelemetry instrumentation is available at: **GitHub**: [base-14/examples/nodejs/trpc-postgres](https://github.com/base-14/examples/tree/main/nodejs/trpc-postgres) **Features**: - Full auto-instrumentation with NodeSDK and PrismaInstrumentation - Custom metrics with articles.created counter - Distributed tracing across two services via fetch() - Structured logging with Pino and trace context correlation - REST-to-tRPC bridge with createCallerFactory - Multi-stage Docker build with non-root user - PostgreSQL with Prisma adapter and Zod validation - Graceful shutdown handling #### Project Structure ```text trpc-postgres/ ├── app/ │ ├── src/ │ │ ├── tracing.ts # OpenTelemetry SDK setup │ │ ├── server.ts # HTTP server + REST-to-tRPC bridge │ │ ├── router.ts # tRPC router + createCallerFactory │ │ ├── lib/ │ │ │ └── logger.ts # Pino with trace context mixin │ │ ├── routes/ │ │ │ ├── article.ts # Article CRUD procedures │ │ │ └── health.ts # Health check procedure │ │ └── service/ │ │ └── notification.ts # Notification client (fetch) │ ├── prisma/ │ │ └── schema.prisma # Prisma schema │ ├── Dockerfile # Multi-stage build │ ├── package.json │ └── tsconfig.json ├── notify/ │ ├── src/ │ │ ├── tracing.ts # OTel SDK (no Prisma) │ │ └── server.ts # Notification handler │ ├── Dockerfile │ └── package.json ├── config/ │ └── otel-config.yaml # Collector config with Scout auth ├── db/ │ └── init.sql # Database initialization ├── compose.yml # Full stack orchestration └── README.md ``` #### Running the Example The full source is in [nodejs/trpc-postgres](https://github.com/base-14/examples/tree/main/nodejs/trpc-postgres). ```bash git clone https://github.com/base-14/examples.git cd examples/nodejs/trpc-postgres docker compose up --build ``` #### Testing Commands ```bash # Health check curl http://localhost:8080/api/health | jq . # Create article (generates trace across both services) curl -X POST http://localhost:8080/api/articles \ -H "Content-Type: application/json" \ -d '{"title": "Test Article", "body": "Content here"}' | jq . # List articles with pagination curl "http://localhost:8080/api/articles?page=1&per_page=10" | jq . # Get single article curl http://localhost:8080/api/articles/1 | jq . # Update article curl -X PUT http://localhost:8080/api/articles/1 \ -H "Content-Type: application/json" \ -d '{"title": "Updated Title"}' | jq . # Delete article curl -X DELETE http://localhost:8080/api/articles/1 ``` ### References - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/) - [tRPC Documentation](https://trpc.io/docs) - [Prisma Instrumentation Guide](https://www.prisma.io/docs/orm/prisma-client/observability-and-logging/opentelemetry-tracing) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) - [Pino Logger](https://getpino.io/) --- ## Vercel AI SDK OpenTelemetry Instrumentation - AI Pipeline Monitoring ## Vercel AI SDK Implement OpenTelemetry instrumentation for Vercel AI SDK v6 applications to enable comprehensive AI pipeline monitoring, LLM cost tracking, and end-to-end trace visibility. This guide shows you how to instrument a multi-stage AI pipeline with custom GenAI semantic convention spans via `LanguageModelV3Middleware`, multi-provider LLM support with automatic fallback, token and cost metrics, concurrent pipeline stage execution, and production deployment with Docker Compose. The Vercel AI SDK is a TypeScript toolkit for LLM applications. For Python alternatives, see [LangGraph](./langgraph.md) and [LlamaIndex](./llamaindex.md). Vercel AI SDK applications present unique observability challenges. A multi-stage pipeline involves sequential and concurrent stages - ingestion, routing, extraction, embedding, scoring, summarization - each making LLM or embedding API calls, database queries, and file operations. The AI SDK's middleware architecture (`LanguageModelV3Middleware`) provides a natural interception point for attaching GenAI semantic conventions to every model call without modifying business logic. This guide shows how to use that architecture to produce standard OpenTelemetry telemetry that works with any OTel-compatible backend. Whether you're building contract analysis pipelines, document processing systems, RAG applications with pgvector, or any TypeScript/Bun application that uses Vercel AI SDK for LLM orchestration, this guide provides production-ready patterns for unified AI observability where every pipeline stage, LLM call, and database query lives in a single trace on base14 Scout. :::tip TL;DR Instrument Vercel AI SDK v6 applications with OpenTelemetry by implementing a `LanguageModelV3Middleware` that attaches GenAI semantic convention attributes to every LLM call. This gives you unified traces spanning HTTP requests, pipeline stages, LLM completions, and database queries, with per-model token and cost tracking. ::: > **Note:** For general LLM observability patterns applicable to any framework, > see the > [LLM Observability guide](../../../guides/ai-observability/llm-observability.md). > This guide focuses specifically on Vercel AI SDK integration patterns with > TypeScript and Bun. :::note Running this in production Storing and querying these traces at production volume is what base14 Scout does. [Check out Scout LLM Observability](https://base14.io/scout/llm-observability). ::: ### Who This Guide Is For This documentation is designed for: - **Node.js/Bun AI developers**: building AI-powered features with Vercel AI SDK and needing visibility into model performance, cost, and pipeline throughput - **Backend developers**: adding AI capabilities to existing Hono or Express applications and wanting unified tracing across all layers - **Platform teams**: standardizing observability across AI services and traditional microservices using OpenTelemetry - **Engineering teams**: migrating from proprietary AI observability tools (Traceloop, Helicone) to vendor-neutral OpenTelemetry - **DevOps engineers**: deploying AI applications with production monitoring, cost alerting, and pipeline health tracking ### Vercel AI SDK OpenTelemetry Overview This guide demonstrates how to: - Set up unified OpenTelemetry for a Bun + Hono application (traces + metrics + logs) - Create a `LanguageModelV3Middleware` that attaches GenAI semantic convention attributes to every LLM call - Support multiple LLM providers (Anthropic, Google, Ollama) with automatic fallback - Instrument multi-stage pipeline execution with concurrent stages - Track token usage and calculate cost per LLM call with a pricing table - Record HTTP request metrics via Hono middleware - Correlate logs with traces via trace_id and span_id injection - Deploy with Docker Compose, PostgreSQL/pgvector, and the OpenTelemetry Collector ### Prerequisites Before starting, ensure you have: - **Bun 1.2 or later** installed (1.2+ recommended for stable OpenTelemetry support) - **An LLM API key** from at least one provider (Anthropic, OpenAI, or Google) - **Scout Collector** configured and accessible - See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) for local development - Basic understanding of OpenTelemetry concepts (traces, spans, metrics) - Familiarity with Vercel AI SDK's `generateText` / `generateObject` APIs #### Compatibility Matrix | Component | Minimum Version | Recommended | | ----------------------------------- | --------------- | ----------- | | Bun | 1.2 | 1.2+ | | ai (Vercel AI SDK) | 6.0 | 6.0.95+ | | @ai-sdk/anthropic | 3.0 | 3.0.46+ | | @ai-sdk/google | 3.0 | 3.0.30+ | | @ai-sdk/openai | 3.0 | 3.0.30+ | | Hono | 4.0 | 4.12+ | | @opentelemetry/sdk-node | 0.212 | 0.212+ | | @opentelemetry/api | 1.9 | 1.9+ | | @opentelemetry/semantic-conventions | 1.39 | 1.39+ | | @opentelemetry/instrumentation-pg | 0.64 | 0.64+ | | pg | 8.0 | 8.18+ | | Zod | 4.0 | 4.3+ | ### Installation ```bash showLineNumbers title="Terminal" bun add \ ai @ai-sdk/anthropic @ai-sdk/openai @ai-sdk/google \ @opentelemetry/api \ @opentelemetry/sdk-node \ @opentelemetry/sdk-logs \ @opentelemetry/sdk-metrics \ @opentelemetry/semantic-conventions \ @opentelemetry/exporter-trace-otlp-http \ @opentelemetry/exporter-metrics-otlp-http \ @opentelemetry/exporter-logs-otlp-http \ @opentelemetry/instrumentation \ @opentelemetry/instrumentation-http \ @opentelemetry/instrumentation-pg \ hono pg pgvector zod ``` ### Configuration ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` The telemetry module must be loaded **before** any other imports via Bun's `--preload` flag. This ensures the OpenTelemetry SDK instruments `pg` and `http` before they are imported elsewhere. ```typescript showLineNumbers title="src/telemetry.ts" import { DiagConsoleLogger, DiagLogLevel, diag } from "@opentelemetry/api"; import { logs } from "@opentelemetry/api-logs"; import { OTLPLogExporter } from "@opentelemetry/exporter-logs-otlp-http"; import { OTLPMetricExporter } from "@opentelemetry/exporter-metrics-otlp-http"; import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-http"; import { PgInstrumentation } from "@opentelemetry/instrumentation-pg"; import { BatchLogRecordProcessor, LoggerProvider, } from "@opentelemetry/sdk-logs"; import { PeriodicExportingMetricReader } from "@opentelemetry/sdk-metrics"; import { NodeSDK } from "@opentelemetry/sdk-node"; const otelEnabled = Bun.env.OTEL_ENABLED !== "false"; const endpoint = Bun.env.OTEL_EXPORTER_OTLP_ENDPOINT ?? "http://localhost:4318"; const serviceName = Bun.env.OTEL_SERVICE_NAME ?? "ai-contract-analyzer"; if (otelEnabled) { diag.setLogger(new DiagConsoleLogger(), DiagLogLevel.WARN); const sdk = new NodeSDK({ serviceName, traceExporter: new OTLPTraceExporter({ url: `${endpoint}/v1/traces`, }), metricReaders: [ new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: `${endpoint}/v1/metrics`, }), exportIntervalMillis: 15_000, exportTimeoutMillis: 10_000, }), ], instrumentations: [new PgInstrumentation()], }); sdk.start(); const loggerProvider = new LoggerProvider({ processors: [ new BatchLogRecordProcessor( new OTLPLogExporter({ url: `${endpoint}/v1/logs`, }), ), ], }); logs.setGlobalLoggerProvider(loggerProvider); } ``` Key design decisions: - **`NodeSDK` owns the `MeterProvider`** - passing `metricReaders` here avoids the duplicate-registration error that occurs when a separate `MeterProvider` is created after `sdk.start()` - **`PgInstrumentation`** auto-instruments all PostgreSQL queries so they appear as child spans under your pipeline stages - **Logs are exported** to the collector so Scout can correlate them with traces via `trace_id` / `span_id` ```mdx-code-block ``` ```typescript showLineNumbers title="src/config.ts" import { z } from "zod"; const ConfigSchema = z.object({ port: z.coerce.number().default(3000), databaseUrl: z.string().min(1, "DATABASE_URL is required"), anthropicApiKey: z.string().optional(), openaiApiKey: z.string().optional(), googleApiKey: z.string().optional(), otelServiceName: z.string().default("ai-contract-analyzer"), otelExporterEndpoint: z.string().default("http://localhost:4318"), otelEnabled: z .string() .default("true") .transform((v) => v === "true"), llmProvider: z.enum(["anthropic", "google", "ollama"]).default("anthropic"), embeddingProvider: z.enum(["openai", "ollama", "google"]).default("openai"), llmProviderFallback: z.enum(["anthropic", "google", "ollama"]).optional(), llmModelFallback: z.string().optional(), }); const parsed = ConfigSchema.safeParse({ port: Bun.env.PORT, databaseUrl: Bun.env.DATABASE_URL, anthropicApiKey: Bun.env.ANTHROPIC_API_KEY, openaiApiKey: Bun.env.OPENAI_API_KEY, googleApiKey: Bun.env.GOOGLE_GENERATIVE_AI_API_KEY, otelServiceName: Bun.env.OTEL_SERVICE_NAME, otelExporterEndpoint: Bun.env.OTEL_EXPORTER_OTLP_ENDPOINT, otelEnabled: Bun.env.OTEL_ENABLED, llmProvider: Bun.env.LLM_PROVIDER, embeddingProvider: Bun.env.EMBEDDING_PROVIDER, llmProviderFallback: Bun.env.LLM_PROVIDER_FALLBACK, llmModelFallback: Bun.env.LLM_MODEL_FALLBACK, }); if (!parsed.success) { console.error("Configuration error:", parsed.error); throw new Error("Invalid configuration"); } export const config = parsed.data; ``` ```mdx-code-block ``` For container deployments where configuration is managed externally: ```bash showLineNumbers title=".env" # Application PORT=3000 DATABASE_URL=postgresql://postgres:postgres@localhost:5432/contract_analyzer # LLM Provider LLM_PROVIDER=anthropic EMBEDDING_PROVIDER=openai ANTHROPIC_API_KEY=sk-ant-... OPENAI_API_KEY=sk-... GOOGLE_GENERATIVE_AI_API_KEY= # Fallback Provider (optional) LLM_PROVIDER_FALLBACK=google LLM_MODEL_FALLBACK=gemini-2.5-flash # OpenTelemetry OTEL_SERVICE_NAME=ai-contract-analyzer OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_ENABLED=true SCOUT_ENVIRONMENT=production ``` The Zod `ConfigSchema` reads all environment variables automatically (see the Zod Config tab). No code changes needed - set the variables and the application picks them up. ```mdx-code-block ``` ### Production Configuration #### OpenTelemetry Collector ```yaml showLineNumbers title="config/otel-collector-config.yaml" extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: check_interval: 1s limit_mib: 512 spike_limit_mib: 128 filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*/health.*")' batch: timeout: 10s send_batch_size: 1024 send_batch_max_size: 2048 attributes: actions: - key: deployment.environment value: ${SCOUT_ENVIRONMENT} action: upsert - key: environment value: ${SCOUT_ENVIRONMENT} action: upsert exporters: otlp_http/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s debug: verbosity: basic service: extensions: [health_check, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noisy, attributes, batch] exporters: [otlp_http/b14, debug] metrics: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] logs: receivers: [otlp] processors: [memory_limiter, attributes, batch] exporters: [otlp_http/b14, debug] ``` The `filter/noisy` processor drops health check spans from traces, preventing them from cluttering your pipeline traces in Scout. #### Docker Compose ```yaml showLineNumbers title="compose.yml" services: app: build: . ports: - "3000:3000" environment: - DATABASE_URL=postgresql://postgres:postgres@postgres:5432/contract_analyzer - OTEL_SERVICE_NAME=ai-contract-analyzer - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 - OTEL_ENABLED=true - LLM_PROVIDER=${LLM_PROVIDER:-anthropic} - EMBEDDING_PROVIDER=${EMBEDDING_PROVIDER:-openai} - ANTHROPIC_API_KEY=${ANTHROPIC_API_KEY:-} - OPENAI_API_KEY=${OPENAI_API_KEY:-} - GOOGLE_GENERATIVE_AI_API_KEY=${GOOGLE_GENERATIVE_AI_API_KEY:-} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} depends_on: postgres: condition: service_healthy otel-collector: condition: service_started healthcheck: test: ["CMD", "curl", "-f", "http://localhost:3000/health"] interval: 60s timeout: 5s retries: 3 postgres: image: pgvector/pgvector:pg18 environment: POSTGRES_DB: contract_analyzer POSTGRES_USER: postgres POSTGRES_PASSWORD: postgres ports: - "5434:5432" healthcheck: test: ["CMD-SHELL", "pg_isready -U postgres"] interval: 5s timeout: 5s retries: 5 otel-collector: image: otel/opentelemetry-collector-contrib:0.144.0 command: ["--config=/etc/otel-collector-config.yaml"] volumes: - ./config/otel-collector-config.yaml:/etc/otel-collector-config.yaml:ro ports: - "4317:4317" - "4318:4318" - "13133:13133" environment: - SCOUT_CLIENT_ID=${SCOUT_CLIENT_ID:-} - SCOUT_CLIENT_SECRET=${SCOUT_CLIENT_SECRET:-} - SCOUT_TOKEN_URL=${SCOUT_TOKEN_URL:-https://auth.base14.io/oauth/token} - SCOUT_ENDPOINT=${SCOUT_ENDPOINT:-https://collector.base14.io} - SCOUT_ENVIRONMENT=${SCOUT_ENVIRONMENT:-development} ``` #### Dockerfile ```dockerfile showLineNumbers title="Dockerfile" FROM oven/bun:1.2-alpine AS base WORKDIR /app FROM base AS deps COPY package.json bun.lock* ./ RUN bun install --frozen-lockfile --production FROM base AS production COPY --from=deps /app/node_modules ./node_modules COPY src ./src COPY tsconfig.json ./ ENV NODE_ENV=production EXPOSE 3000 HEALTHCHECK --interval=30s --timeout=5s \ --start-period=10s --retries=3 \ CMD curl -f http://localhost:3000/health || exit 1 CMD ["bun", "run", "--preload", \ "./src/telemetry.ts", "src/index.ts"] ``` The `--preload ./src/telemetry.ts` flag ensures OpenTelemetry initializes before any application code runs. This is critical for `PgInstrumentation` to monkey-patch the `pg` module before it is first imported. ### Framework-Specific Features This section covers Vercel AI SDK-specific instrumentation patterns that go beyond generic LLM observability. These patterns give you visibility into the AI SDK middleware layer - how models are wrapped, how GenAI semantic conventions are attached, and how multi-stage pipelines are orchestrated. #### GenAI Semantic Convention Middleware The core instrumentation pattern uses `LanguageModelV3Middleware` to intercept every `doGenerate` call and attach OpenTelemetry spans with GenAI semantic convention attributes. This means you instrument once at the middleware level and every LLM call in your application automatically gets traced: ```typescript showLineNumbers title="src/llm/middleware.ts" import type { LanguageModelV3, LanguageModelV3Middleware, } from "@ai-sdk/provider"; import { metrics, SpanStatusCode, trace } from "@opentelemetry/api"; import { wrapLanguageModel } from "ai"; const tracer = trace.getTracer("ai-contract-analyzer"); const meter = metrics.getMeter("ai-contract-analyzer"); const opDurationHistogram = meter.createHistogram( "gen_ai.client.operation.duration", { description: "LLM operation duration", unit: "s" }, ); const tokenUsageHistogram = meter.createHistogram("gen_ai.client.token.usage", { description: "LLM token usage", unit: "{token}", }); const costCounter = meter.createCounter("gen_ai.client.cost", { description: "LLM cost in USD", unit: "usd", }); const errorCounter = meter.createCounter("gen_ai.client.error.count", { description: "LLM call error count", unit: "{error}", }); const retryCounter = meter.createCounter("gen_ai.client.retry.count", { description: "LLM call retry count", unit: "{retry}", }); const TRUNCATE_PROMPT = 1_000; const TRUNCATE_COMPLETION = 2_000; function truncate(s: string, max: number): string { return s.length > max ? `${s.slice(0, max)}…` : s; } export function createSemconvMiddleware( providerName: string, serverAddress: string, pricing?: { inputCostPerMToken: number; outputCostPerMToken: number; }, ): LanguageModelV3Middleware { return { specificationVersion: "v3", async wrapGenerate({ doGenerate, params, model }) { const modelId = model.modelId; const spanName = `gen_ai.chat ${modelId}`; return tracer.startActiveSpan(spanName, async (span) => { // Required GenAI semconv attributes span.setAttribute("gen_ai.operation.name", "chat"); span.setAttribute("gen_ai.provider.name", providerName); span.setAttribute("gen_ai.request.model", modelId); span.setAttribute("server.address", serverAddress); // Recommended attributes if (params.maxOutputTokens !== undefined) span.setAttribute( "gen_ai.request.max_tokens", params.maxOutputTokens, ); if (params.temperature !== undefined) span.setAttribute("gen_ai.request.temperature", params.temperature); const startMs = Date.now(); try { const result = await doGenerate(); const durationS = (Date.now() - startMs) / 1000; const inputTokens = result.usage.inputTokens.total ?? 0; const outputTokens = result.usage.outputTokens.total ?? 0; // Response attributes if (result.response?.modelId) span.setAttribute("gen_ai.response.model", result.response.modelId); span.setAttribute("gen_ai.usage.input_tokens", inputTokens); span.setAttribute("gen_ai.usage.output_tokens", outputTokens); // Token usage metrics const metricAttrs = { "gen_ai.operation.name": "chat", "gen_ai.provider.name": providerName, "gen_ai.request.model": modelId, }; tokenUsageHistogram.record(inputTokens, { ...metricAttrs, "gen_ai.token.type": "input", }); tokenUsageHistogram.record(outputTokens, { ...metricAttrs, "gen_ai.token.type": "output", }); // Cost tracking if (pricing) { const costUsd = (inputTokens * pricing.inputCostPerMToken + outputTokens * pricing.outputCostPerMToken) / 1_000_000; span.setAttribute("gen_ai.usage.cost_usd", costUsd); costCounter.add(costUsd, metricAttrs); } opDurationHistogram.record(durationS, { "gen_ai.request.model": modelId, "gen_ai.provider.name": providerName, }); span.end(); return result; } catch (err) { const durationS = (Date.now() - startMs) / 1000; const errorType = (err as Error).constructor?.name ?? "UnknownError"; span.recordException(err as Error); span.setAttribute("error.type", errorType); span.setStatus({ code: SpanStatusCode.ERROR, message: (err as Error).message, }); errorCounter.add(1, { "gen_ai.request.model": modelId, "gen_ai.provider.name": providerName, "error.type": errorType, }); opDurationHistogram.record(durationS, { "gen_ai.request.model": modelId, "gen_ai.provider.name": providerName, }); span.end(); throw err; } }); }, }; } ``` The middleware intercepts `wrapGenerate` - the AI SDK's hook that runs around every `doGenerate()` call. This means structured output (`generateObject`), plain text (`generateText`), and streaming calls all get instrumented automatically. #### Wrapping Models with Semconv Middleware Apply the middleware to any AI SDK model with a convenience function: ```typescript showLineNumbers title="src/llm/middleware.ts" export function withSemconv( model: LanguageModelV3, providerName: string, serverAddress: string, pricing?: { inputCostPerMToken: number; outputCostPerMToken: number; }, ): LanguageModelV3 { return wrapLanguageModel({ model, middleware: createSemconvMiddleware(providerName, serverAddress, pricing), }); } ``` #### Multi-Provider Support Configure providers with OTel semconv metadata so spans carry the correct `gen_ai.provider.name` and `server.address`: ```typescript showLineNumbers title="src/providers.ts" import { anthropic } from "@ai-sdk/anthropic"; import { google } from "@ai-sdk/google"; import { createOpenAI } from "@ai-sdk/openai"; import type { LanguageModelV3 } from "@ai-sdk/provider"; import { withFallback, withSemconv } from "./llm/middleware"; const PROVIDER_META: Record< string, { semconvName: string; serverAddress: string } > = { anthropic: { semconvName: "anthropic", serverAddress: "api.anthropic.com", }, google: { semconvName: "google", serverAddress: "generativelanguage.googleapis.com", }, openai: { semconvName: "openai", serverAddress: "api.openai.com", }, ollama: { semconvName: "ollama", serverAddress: "localhost", }, }; const MODEL_PRICING: Record = { "claude-sonnet-4-6": { input: 3.0, output: 15.0 }, "claude-haiku-4-5-20251001": { input: 0.8, output: 4.0, }, "gemini-2.5-flash": { input: 0.15, output: 0.6 }, "gemini-2.0-flash": { input: 0.1, output: 0.4 }, }; function buildRawModel(provider: string, modelId: string): LanguageModelV3 { if (provider === "google") return google(modelId) as unknown as LanguageModelV3; if (provider === "ollama") { const ollamaOpenAI = createOpenAI({ baseURL: "http://localhost:11434/v1", apiKey: "ollama", }); return ollamaOpenAI(modelId) as unknown as LanguageModelV3; } return anthropic(modelId) as unknown as LanguageModelV3; } export function getCapableModel() { const provider = "anthropic"; const modelId = "claude-sonnet-4-6"; const meta = PROVIDER_META[provider]; const pricing = MODEL_PRICING[modelId] ?? { input: 3.0, output: 15.0, }; const raw = buildRawModel(provider, modelId); const model = withSemconv(raw, meta.semconvName, meta.serverAddress, { inputCostPerMToken: pricing.input, outputCostPerMToken: pricing.output, }); return { modelId, model }; } ``` Every model returned by `getCapableModel()` or `getFastModel()` is already wrapped with the GenAI semconv middleware. Call `generateText()` or `generateObject()` normally - spans are created automatically. #### Pipeline Stage Spans Wrap each pipeline stage in a span to see the full execution flow. Use `tracer.startActiveSpan` so that LLM calls within a stage become child spans: ```typescript showLineNumbers title="src/pipeline/orchestrator.ts" import { metrics, SpanStatusCode, trace } from "@opentelemetry/api"; const tracer = trace.getTracer("ai-contract-analyzer"); const meter = metrics.getMeter("ai-contract-analyzer"); const analysisDuration = meter.createHistogram("contract.analysis.duration", { description: "Total pipeline duration", unit: "s", }); export async function analyzeContract(file: File, pool: Pool) { const startMs = Date.now(); return tracer.startActiveSpan("analyze_contract", async (rootSpan) => { rootSpan.setAttribute("document.filename", file.name); rootSpan.setAttribute("document.size_bytes", file.size); try { // Stage 1: Ingest const ingestResult = await tracer.startActiveSpan( "pipeline_stage ingest", async (span) => { span.setAttribute("pipeline.stage", "ingest"); const result = await ingestDocument(file); span.setAttribute("document.page_count", result.page_count); span.end(); return result; }, ); // Stage 2: Route const routeResult = await tracer.startActiveSpan( "pipeline_stage route", async (span) => { span.setAttribute("pipeline.stage", "route"); const result = await routeDocument(ingestResult.full_text); span.setAttribute("route.document_type", result.document_type); span.setAttribute("route.complexity", result.complexity); span.end(); return result; }, ); // Stages 3 & 4: Embed + Extract (concurrent) const [, extractResult] = await Promise.all([ tracer.startActiveSpan("pipeline_stage embed", async (span) => { span.setAttribute("pipeline.stage", "embed"); const result = await embedChunks(ingestResult.chunks); span.setAttribute( "embedding.chunk_count", ingestResult.chunks.length, ); span.end(); return result; }), tracer.startActiveSpan("pipeline_stage extract", async (span) => { span.setAttribute("pipeline.stage", "extract"); const result = await extractClauses(ingestResult.full_text); span.setAttribute("extraction.clauses_found", result.clauses.length); span.end(); return result; }), ]); // Stage 5: Score // Stage 6: Summarize // ... (same pattern) const durationS = (Date.now() - startMs) / 1000; rootSpan.setAttribute("pipeline.status", "complete"); rootSpan.setAttribute("pipeline.total_stages", 6); analysisDuration.record(durationS); rootSpan.end(); return result; } catch (err) { rootSpan.recordException(err as Error); rootSpan.setStatus({ code: SpanStatusCode.ERROR, message: (err as Error).message, }); rootSpan.end(); throw err; } }); } ``` The resulting trace in Scout shows the full hierarchy: ```text showLineNumbers title="Single trace spanning all layers" POST /api/contracts/analyze 8.2s [HTTP] └─ analyze_contract 8.1s [pipeline] ├─ pipeline_stage ingest 0.3s [stage] │ └─ db.query INSERT contracts 5ms [auto: pg] ├─ pipeline_stage route 1.2s [stage] │ └─ gen_ai.chat claude-sonnet-4-6 1.1s [middleware] ├─ pipeline_stage embed 0.8s [stage] ──┐ │ └─ gen_ai.embeddings text-embedding-3-small 0.7s [custom] │ concurrent ├─ pipeline_stage extract 2.4s [stage] ──┘ │ └─ gen_ai.chat claude-sonnet-4-6 2.3s [middleware] ├─ pipeline_stage score 1.8s [stage] │ └─ gen_ai.chat claude-haiku-4-5 1.7s [middleware] ├─ pipeline_stage summarize 1.5s [stage] │ └─ gen_ai.chat claude-sonnet-4-6 1.4s [middleware] └─ db.query INSERT analyses 3ms [auto: pg] ``` #### Concurrent Stage Execution Stages that don't depend on each other can run concurrently with `Promise.all`. OpenTelemetry preserves the trace context across concurrent promises, so both stages appear as siblings under the same parent span: ```typescript showLineNumbers title="Concurrent stages" const [embedResult, extractResult] = await Promise.all([ tracer.startActiveSpan("pipeline_stage embed", async (span) => { // This LLM call becomes a child of "embed" const result = await embedChunks(chunks); span.end(); return result; }), tracer.startActiveSpan("pipeline_stage extract", async (span) => { // This LLM call becomes a child of "extract" const result = await extractClauses(text); span.end(); return result; }), ]); ``` #### HTTP Metrics Middleware Track HTTP request duration and count with a Hono middleware that records OpenTelemetry metrics: ```typescript showLineNumbers title="src/middleware/metrics.ts" import { metrics } from "@opentelemetry/api"; import type { MiddlewareHandler } from "hono"; const meter = metrics.getMeter("ai-contract-analyzer"); const httpRequestDuration = meter.createHistogram( "http.server.request.duration", { description: "HTTP request duration", unit: "s" }, ); const httpRequestCount = meter.createCounter("http.server.request.count", { description: "HTTP request count", }); export const requestMetrics: MiddlewareHandler = async (c, next) => { const start = Date.now(); await next(); const duration = (Date.now() - start) / 1000; const attrs = { "http.request.method": c.req.method, "http.response.status_code": String(c.res.status), "url.path": c.req.path, }; httpRequestDuration.record(duration, attrs); httpRequestCount.add(1, attrs); }; ``` #### Log Correlation Inject `trace_id` and `span_id` into every log record so logs can be correlated with traces in Scout: ```typescript showLineNumbers title="src/logger.ts" import { trace } from "@opentelemetry/api"; import { logs, SeverityNumber } from "@opentelemetry/api-logs"; const otelLogger = logs.getLogger("ai-contract-analyzer"); type LogAttrs = Record; function emit( severityNumber: SeverityNumber, severityText: string, message: string, attrs?: LogAttrs, ) { const span = trace.getActiveSpan(); const ctx = span?.spanContext(); otelLogger.emit({ severityNumber, severityText, body: message, attributes: { ...attrs, ...(ctx ? { trace_id: ctx.traceId, span_id: ctx.spanId, } : {}), }, }); } export const logger = { info: (msg: string, attrs?: LogAttrs) => emit(SeverityNumber.INFO, "INFO", msg, attrs), warn: (msg: string, attrs?: LogAttrs) => emit(SeverityNumber.WARN, "WARN", msg, attrs), error: (msg: string, attrs?: LogAttrs) => emit(SeverityNumber.ERROR, "ERROR", msg, attrs), }; ``` ### Custom Manual Instrumentation #### Custom Spans for Pipeline Stages Beyond the middleware-instrumented LLM calls, add manual spans for any custom logic that deserves visibility: ```typescript showLineNumbers title="Custom span example" import { trace } from "@opentelemetry/api"; const tracer = trace.getTracer("ai-contract-analyzer"); async function processChunk(chunk: string, index: number) { return tracer.startActiveSpan(`process_chunk ${index}`, async (span) => { span.setAttribute("chunk.index", index); span.setAttribute("chunk.length", chunk.length); const result = await doProcessing(chunk); span.setAttribute("chunk.tokens_estimated", result.tokenCount); span.end(); return result; }); } ``` #### Retry and Fallback Instrumentation The middleware supports application-level retry with exponential backoff and provider fallback: ```typescript showLineNumbers title="src/llm/middleware.ts" const MAX_RETRIES = 2; const MIN_BACKOFF_MS = 1_000; const MAX_BACKOFF_MS = 10_000; // Inside createSemconvMiddleware's wrapGenerate: for (let attempt = 0; attempt <= MAX_RETRIES; attempt++) { try { const result = await doGenerate(); // ... record success metrics span.end(); return result; } catch (err) { if (attempt < MAX_RETRIES) { retryCounter.add(1, { "gen_ai.request.model": modelId, "gen_ai.provider.name": providerName, }); const backoffMs = Math.min(MIN_BACKOFF_MS * 2 ** attempt, MAX_BACKOFF_MS); span.addEvent("gen_ai.retry", { attempt: attempt + 1, backoff_ms: backoffMs, error: (err as Error).message, }); await sleep(backoffMs); } } } ``` #### Provider Fallback When all retries are exhausted for the primary provider, fall back to a secondary model: ```typescript showLineNumbers title="src/llm/middleware.ts" export function withFallback( primary: LanguageModelV3, primaryProviderName: string, fallback: LanguageModelV3, ): LanguageModelV3 { const fallbackMiddleware: LanguageModelV3Middleware = { specificationVersion: "v3", async wrapGenerate({ doGenerate, params, model }) { try { return await doGenerate(); } catch (err) { const fallbackCounter = metrics .getMeter("ai-contract-analyzer") .createCounter("gen_ai.client.fallback.count"); fallbackCounter.add(1, { "gen_ai.request.model": model.modelId, "gen_ai.provider.name": primaryProviderName, }); return await fallback.doGenerate(params); } }, }; return wrapLanguageModel({ model: primary, middleware: fallbackMiddleware, }); } ``` The fallback model has its own semconv middleware, so both the failed primary call and the successful fallback call appear as separate spans in the trace with their respective provider attributes. #### Embedding Metrics Track embedding operations alongside LLM calls: ```typescript showLineNumbers title="src/pipeline/orchestrator.ts" // Inside the embed stage span tokenUsageHistogram.record(embedResult.total_tokens, { "gen_ai.operation.name": "embeddings", "gen_ai.provider.name": config.embeddingProvider, "gen_ai.request.model": embedModelId, "gen_ai.token.type": "input", }); costCounter.add(embedCostUsd, { "gen_ai.operation.name": "embeddings", "gen_ai.provider.name": config.embeddingProvider, "gen_ai.request.model": embedModelId, }); ``` #### Pipeline-Level Metrics Record aggregate metrics on the root pipeline span for dashboards and alerting: ```typescript showLineNumbers title="Root span attributes" rootSpan.setAttribute("pipeline.total_stages", 6); rootSpan.setAttribute("pipeline.total_tokens", totalTokens); rootSpan.setAttribute( "pipeline.total_cost_usd", Math.round(totalCost * 10_000) / 10_000, ); rootSpan.setAttribute("pipeline.duration_ms", totalDurationMs); rootSpan.setAttribute("route.document_type", routeResult.document_type); rootSpan.setAttribute("pipeline.status", "complete"); ``` ### Running Your Application ```mdx-code-block ``` ```bash showLineNumbers bun run --watch --preload ./src/telemetry.ts src/index.ts ``` ```mdx-code-block ``` ```bash showLineNumbers OTEL_ENABLED=true \ LLM_PROVIDER=anthropic \ OTEL_EXPORTER_OTLP_ENDPOINT=http://collector:4318 \ bun run --preload ./src/telemetry.ts src/index.ts ``` ```mdx-code-block ``` ```bash showLineNumbers docker compose up --build curl http://localhost:3000/health docker compose down ``` ```mdx-code-block ``` ### Troubleshooting #### Verify Telemetry Is Working ```bash showLineNumbers # Collector health check curl http://localhost:13133 # zpages trace viewer # Open http://localhost:55679/debug/tracez ``` #### Enable Debug Mode ```typescript showLineNumbers import { DiagConsoleLogger, DiagLogLevel, diag } from "@opentelemetry/api"; diag.setLogger(new DiagConsoleLogger(), DiagLogLevel.DEBUG); ``` #### Common Issues ##### Issue: No traces appearing in Scout **Solutions:** 1. Confirm the OTel Collector is running: `curl http://localhost:13133` 2. Check collector logs: `docker compose logs otel-collector` 3. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` points to the collector, not directly to Scout 4. Ensure `SCOUT_CLIENT_ID` and `SCOUT_CLIENT_SECRET` are set in the collector environment ##### Issue: Token counts are zero **Solutions:** 1. Verify you're using AI SDK v6+ - earlier versions use a different `usage` response shape 2. Check that `result.usage.inputTokens.total` exists (v6 uses nested token objects) 3. For Ollama models, ensure the model returns usage metadata (some older models don't) ##### Issue: Pipeline spans not nested correctly **Solutions:** 1. Ensure `telemetry.ts` is loaded via `--preload` before any application code 2. Verify all `span.end()` calls happen after async work completes 3. Check that `tracer.startActiveSpan` is used (not `tracer.startSpan`) so child spans inherit the parent context ##### Issue: Duplicate MeterProvider registration **Solutions:** 1. Pass `metricReaders` to `NodeSDK` instead of creating a separate `MeterProvider` 2. Ensure `telemetry.ts` runs only once (preload, not imported from multiple files) ##### Issue: PostgreSQL queries not appearing as spans **Solutions:** 1. Verify `PgInstrumentation` is included in the `instrumentations` array in `NodeSDK` 2. Confirm `telemetry.ts` is preloaded before `pg` is first imported ### Security Considerations #### Protecting Sensitive Data - **Truncate prompts and completions** - the middleware truncates user messages to 1,000 characters and completions to 2,000 characters to avoid oversized spans - **Never record raw API keys** in span attributes - the Zod config validates keys are present but never logs their values - **Disable content capture** in production if compliance requires it by removing `span.addEvent("gen_ai.user.message", ...)` calls #### SQL Query Obfuscation The `PgInstrumentation` auto-instrumentor captures SQL statements by default. For sensitive queries, configure it to obfuscate: ```typescript showLineNumbers new PgInstrumentation({ enhancedDatabaseReporting: false, }); ``` #### Compliance Considerations For applications handling regulated data (GDPR, HIPAA, PCI-DSS): - Use opt-in content capture - disabled by default in production - Record only token counts and model metadata, not prompt content - Audit span attributes regularly for sensitive data leaks - Use the OTel Collector `attributes` processor to redact fields before export ### Performance Considerations OpenTelemetry overhead is negligible relative to LLM API latency. A typical LLM call takes 1-5 seconds; span creation adds microseconds. | Metric | Typical Impact | | ---------------------- | --------------------- | | Span creation overhead | < 0.05 ms per span | | CPU overhead | < 0.5% | | Memory (OTel SDK) | ~5-10 MB | | Network (batch export) | ~50 KB/min | #### Optimization Strategies ##### 1. Batch Span Export The `NodeSDK` uses `BatchSpanProcessor` by default, which batches span exports to minimize network overhead. Tune the metric reader interval for your workload: ```typescript showLineNumbers new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url }), exportIntervalMillis: 15_000, // 15s for dev // Use 60_000 for production }); ``` ##### 2. Truncate Content Events Always truncate prompts and completions: ```typescript showLineNumbers truncate(userPrompt, 1_000); // 1,000 chars max truncate(completion, 2_000); // 2,000 chars max ``` ##### 3. Concurrent Pipeline Stages Run independent stages concurrently with `Promise.all` to reduce total pipeline latency. The embed and extract stages in the example run concurrently because neither depends on the other's output. ##### 4. Filter Noisy Spans Use the collector's `filter/noisy` processor to drop health check spans that would otherwise dominate your trace view: ```yaml showLineNumbers filter/noisy: error_mode: ignore traces: span: - 'IsMatch(name, ".*/health.*")' ``` ### FAQ #### Does OpenTelemetry add latency to LLM calls? No. Span creation takes microseconds. LLM API calls take seconds. The overhead is unmeasurable. `BatchSpanProcessor` exports spans in a background thread. #### How do I add OpenTelemetry to Vercel AI SDK without Traceloop? Traceloop's `@traceloop/node-server-sdk` provides auto- instrumentation but produces attributes that may not align with the OpenTelemetry GenAI semantic conventions. The middleware approach gives you full control over what gets recorded and ensures standard `gen_ai.*` attributes that work with any OTel-compatible backend. #### Which Vercel AI SDK versions are supported? This guide requires AI SDK v6+ (`ai@6.0.0`). The `LanguageModelV3Middleware` interface and `wrapLanguageModel` API were introduced in v6. Earlier versions used a different middleware signature. #### How do I initialize OpenTelemetry before my Bun application starts? Bun's `--preload` flag runs the specified file before the application entry point. This ensures `NodeSDK.start()` and `PgInstrumentation` initialize before any `pg` or `http` imports, which is required for monkey-patching to work correctly. #### How do I track cost across multiple providers? Use the `gen_ai.client.cost` counter metric with `gen_ai.provider.name` and `gen_ai.request.model` attributes. Define pricing per model in `MODEL_PRICING` and calculate from token counts. This enables `sum(gen_ai.client.cost) by (gen_ai.provider.name)` in dashboards. #### Can I see prompts and completions in traces? Yes. The middleware records `gen_ai.user.message` and `gen_ai.assistant.message` span events with truncated content. Remove these `span.addEvent` calls in production for compliance. #### How do I add OpenAI, Anthropic, or other providers to Vercel AI SDK? Add the provider SDK package (e.g., `@ai-sdk/mistral`), add its entry to `PROVIDER_META` with the semconv name and server address, add model pricing to `MODEL_PRICING`, and create a case in `buildRawModel`. The semconv middleware wraps it automatically. #### How does LLM provider fallback appear in OpenTelemetry traces? When all retries are exhausted for the primary model, the fallback middleware catches the error and calls the secondary model's `doGenerate` directly. The secondary model has its own semconv wrapper, so both the failed primary and successful fallback appear as separate spans in the trace. #### Can I use this with Next.js instead of Hono? Yes. The `LanguageModelV3Middleware` pattern works with any framework. Replace the Hono HTTP metrics middleware with Next.js middleware and configure the telemetry module as a Node.js `--require` flag instead of Bun `--preload`. The SDK's client hooks (`useChat`, `useCompletion`) run in the browser - to trace those alongside the server spans, add the browser SDK from the [Next.js browser section](./nextjs.md#browser--client-side-instrumentation). #### How do I instrument streaming responses? The current middleware instruments `wrapGenerate` for non-streaming calls. For streaming, implement `wrapStream` in the middleware with the same span and metric logic. AI SDK v6 calls `wrapStream` for `streamText()` and `streamObject()`. #### Can I use this with Express or Fastify? Yes. The OpenTelemetry instrumentation and AI SDK middleware are framework-agnostic. Replace the Hono HTTP metrics middleware with the appropriate Express or Fastify instrumentor from the `@opentelemetry/instrumentation-*` packages. #### How do concurrent stages appear in traces? Stages run with `Promise.all` appear as sibling spans under the same parent. OpenTelemetry preserves the trace context across concurrent promises, so each stage and its child LLM calls are correctly nested. ### What's Next? #### Related Guides - [Next.js Instrumentation](./nextjs-scout.md) - Common host for AI SDK applications - [Node.js Custom Instrumentation](../custom-instrumentation/javascript-node.md) \- Manual spans and advanced patterns - [All framework guides](/instrument/apps/auto-instrumentation/) - Auto-instrumentation overview for every language #### Scout Platform Features - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Alert on cost spikes, error rates, or pipeline failures - [Dashboard Creation](../../../guides/create-your-first-dashboard.md) - Build dashboards for token usage, cost attribution, and pipeline duration #### Deployment and Operations - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Local development with the OTel Collector ### Complete Example #### Project Structure ```text showLineNumbers ai-contract-analyzer/ ├── src/ │ ├── index.ts # Hono app entry point │ ├── config.ts # Zod config validation │ ├── telemetry.ts # OTel initialization (preload) │ ├── logger.ts # Log correlation with trace context │ ├── providers.ts # Multi-provider model factory │ ├── llm/ │ │ └── middleware.ts # GenAI semconv middleware │ ├── pipeline/ │ │ ├── orchestrator.ts # Pipeline stage spans │ │ ├── ingest.ts # Document ingestion │ │ ├── route.ts # Document routing (LLM) │ │ ├── extract.ts # Clause extraction (LLM) │ │ ├── embed.ts # Embedding generation │ │ ├── score.ts # Risk scoring (LLM) │ │ └── summarize.ts # Summary generation (LLM) │ ├── middleware/ │ │ └── metrics.ts # HTTP request metrics │ ├── routes/ │ │ ├── contracts.ts # Contract upload endpoint │ │ ├── query.ts # Contract query endpoint │ │ ├── search.ts # Vector search endpoint │ │ └── health.ts # Health check │ ├── db/ │ │ ├── pool.ts # PostgreSQL connection pool │ │ ├── contracts.ts # Contract CRUD │ │ ├── chunks.ts # Chunk storage with pgvector │ │ ├── clauses.ts # Clause storage │ │ ├── risks.ts # Risk storage │ │ └── analyses.ts # Analysis results │ └── types/ │ ├── contracts.ts # Contract types │ ├── clauses.ts # Clause types │ └── pipeline.ts # Pipeline result types ├── config/ │ └── otel-collector-config.yaml ├── compose.yml ├── Dockerfile └── package.json ``` #### Key Files | File | Demonstrates | | ----------------- | ---------------------------------------------- | | `telemetry.ts` | OTel setup (traces + metrics + logs) | | `middleware.ts` | GenAI semconv via LanguageModelV3Middleware | | `orchestrator.ts` | Pipeline stages, concurrent execution, metrics | | `providers.ts` | Multi-provider factory with fallback | | `metrics.ts` | HTTP request duration and count | | `logger.ts` | Log correlation with trace_id/span_id | | `config.ts` | Zod-validated environment config | | `compose.yml` | Docker deployment with OTel Collector | #### GitHub Repository For a complete working example, see the [AI Contract Analyzer](https://github.com/base-14/examples/tree/main/nodejs/ai-contract-analyzer) repository. ### References - [OpenTelemetry GenAI Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/gen-ai/) - [OpenTelemetry JavaScript SDK](https://opentelemetry.io/docs/languages/js/) - [Vercel AI SDK Documentation](https://ai-sdk.dev/docs) - [Hono Documentation](https://hono.dev/docs/) - [OpenTelemetry Collector Configuration](https://opentelemetry.io/docs/collector/configuration/) --- ## WordPress OpenTelemetry Instrumentation - Self-Hosted ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ## WordPress :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Introduction Instrument a self-hosted WordPress site with OpenTelemetry without installing a plugin, editing a theme, or patching core. The PECL `opentelemetry` extension loads a Composer autoloader through PHP's `auto_prepend_file` directive, before WordPress boots. From there, two auto-instrumentation packages hook WordPress core and the `mysqli` driver it uses to reach MySQL or MariaDB. Every request produces a trace: a root span named after the entry script PHP executed, spans for the stages of the WordPress request lifecycle, and two database spans per query, `wpdb.query` and its `mysqli_query` child, both carrying the SQL statement. `open-telemetry/opentelemetry-auto-wordpress` emits the `WP.*`, `wpdb.*`, and `get_single_template` spans, and `open-telemetry/opentelemetry-auto-mysqli` emits `mysqli_real_connect` and `mysqli_query`. Both packages attach through the PECL extension, and install without producing spans if it is not loaded. The PHP SDK and the OTLP exporter, both Composer packages, batch and ship what the two produce. The setup needs a host where you can install a PECL extension and add a `php.ini` drop-in, such as a VM, a container image you build, or a bare metal LAMP server. Managed WordPress hosting with a fixed PHP extension set cannot run it, since the hooks have nothing to attach to without the extension. :::tip TL;DR Install the PECL `opentelemetry` extension, install `open-telemetry/opentelemetry-auto-wordpress` and `open-telemetry/opentelemetry-auto-mysqli` with Composer into a directory outside the WordPress docroot, and point `auto_prepend_file` at that vendor autoloader from a `conf.d` ini drop-in. WordPress core and the `mysqli` driver are then traced with no plugin installed and no theme edit. Each request produces a root span named after the entry script PHP ran (`GET /index.php` for anything routed through the front controller, `GET /wp-login.php` for a direct script hit), `WP.*` spans for the request lifecycle, and a `mysqli_query` span carrying `db.query.text` under every `wpdb.query`. Configure the SDK with the standard `OTEL_*` environment variables and export OTLP to a collector. ::: ### Who This Guide Is For - **SRE and platform teams** running WordPress on their own VMs, containers, or bare metal, who need request and query visibility they can query alongside their other services. - **WordPress and agency engineers** who want tracing without shipping a monitoring plugin to every site they maintain. - **Teams replacing a plugin-based or agent-based APM** with vendor-neutral OTLP that exports to a collector they control. - **Engineers debugging slow pages**, who need to see which queries a given request issued and how many of them there were. - **Platform teams standardising on OpenTelemetry**, who need WordPress to report under the same conventions as the rest of the estate. ### Prerequisites Before starting, ensure you have: - **A host where you can install a PECL extension** and add a file to PHP's `conf.d` directory. Managed hosting with a fixed extension set will not work. - **PHP 8.2 or later.** The floor comes from `open-telemetry/opentelemetry-auto-mysqli`, which declares `php: ^8.2`. - **Composer**, to install the SDK, the OTLP exporter, and the two auto-instrumentation packages. - **WordPress using the `mysqli` driver** against MySQL or MariaDB. This is the stock configuration. - **A collector reachable over OTLP**, with a traces pipeline. See [Docker Compose collector setup](../../collector-setup/docker-compose-example.md). - **Docker and Docker Compose** if you want to run the example stack locally. ### Compatibility Matrix | Component | Minimum Version | Recommended Version | | --- | --- | --- | | WordPress | 6.0 | 7.x | | PHP | 8.2 | 8.4 | | MariaDB | 10.11 | 11.4 | | MySQL | 8.0 | 8.4 | | PECL `opentelemetry` | No constraint declared | 1.2.1 | `opentelemetry-auto-mysqli` declares `php: ^8.2`, and 6.0 is the earliest WordPress release compatible with PHP 8.2. The database floors are WordPress's own recommendations. Either engine works and the instrumentation behaves the same on both. Nothing checks the WordPress version at install time, so an upgrade that breaks the instrumentation shows up as missing spans rather than a failed install. ### What Gets Instrumented Spans arrive under two instrumentation scopes, `io.opentelemetry.contrib.php.wordpress` and `io.opentelemetry.contrib.php.mysqli`. The **Instrumentation** column below holds the short name each package registers, which is what `OTEL_PHP_DISABLED_INSTRUMENTATIONS` takes. | Span name | Kind | Instrumentation | Attribute keys | | --- | --- | --- | --- | | `GET /index.php` | SERVER | `wordpress` | `client.address`, `client.port`, `http.request.body.size`, `http.request.method`, `http.response.status_code`, `network.protocol.version`, `url.full`, `url.path`, `url.scheme`, `user_agent.original`, `wp.is_admin` | | `GET /wp-login.php` | SERVER | `wordpress` | `client.address`, `client.port`, `http.request.body.size`, `http.request.method`, `network.protocol.version`, `url.full`, `url.path`, `url.scheme`, `user_agent.original`, `wp.is_admin` | | `WP.main` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `WP.init` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `WP.parse_request` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `WP.query_posts` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `WP.register_globals` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `WP.send_headers` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `WP.handle_404` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `get_single_template` | SERVER | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `wpdb.__construct` | INTERNAL | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number`, `db.namespace`, `db.system.name` | | `wpdb.db_connect` | CLIENT | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number` | | `wpdb.query` | CLIENT | `wordpress` | `code.file.path`, `code.function.name`, `code.line.number`, `db.query.text` | | `mysqli_real_connect` | CLIENT | `mysqli` | `code.function.name`, `db.system.name`, `server.address`, `server.port` | | `mysqli_query` | CLIENT | `mysqli` | `code.function.name`, `db.namespace`, `db.operation.name`, `db.query.text`, `db.system.name`, `server.address`, `server.port` | Each list holds the keys a span can carry rather than the keys it always carries. `http.response.status_code` is the one to watch: it is not on every root span. Filter on whether the key is present rather than on its value, and do not build alerts or dashboards that assume every request carries it. `db.system.name` reads `mysql` on every span that carries it, MariaDB included. The `mysqli` instrumentation takes the value from the driver rather than from the server it connected to, so it does not tell the two engines apart. Filter on `mysql` even when the server is MariaDB. The instrumentation does not cover: - **Plugin attribution.** No span or scope names a plugin, so plugin work is not separable from core work. You can add your own spans for the plugin code you care about; see [Custom Instrumentation](#custom-instrumentation). - **Route or permalink names.** The root span is named after the entry script rather than the matched route, the permalink, or the REST route, and nothing carries a `rest_route` value. - **WP-Cron.** There is no cron-specific instrumentation. A `wp-cron.php` request gets the same entry-script root span as any other direct script hit, so match on `url.path` if you want to separate it out. :::note Because the root span carries the entry script name, nearly all traffic on a site with pretty permalinks reports as `GET /index.php`. Use `url.path` or `url.full` to tell requests apart. `url.path` alone is not always enough, since a home page request and a search request both resolve to `url.path=/` and differ only in `url.full`. ::: A runnable stack that puts all of this together is at [base-14/examples/php/wordpress-mariadb](https://github.com/base-14/examples/tree/main/php/wordpress-mariadb). ### Installation All three paths install the same Composer packages into a directory outside the WordPress docroot, then point `auto_prepend_file` at that directory's autoloader. ```json title="composer.json" showLineNumbers { "$schema": "https://getcomposer.org/schema.json", "name": "base14/wordpress-mariadb-otel", "type": "project", "description": "WordPress + MariaDB + OpenTelemetry auto-instrumentation example for Base14 Scout", "license": "MIT", "require": { "php": "^8.4", "open-telemetry/sdk": "^1.15", "open-telemetry/exporter-otlp": "^1.4", "open-telemetry/opentelemetry-auto-wordpress": "^0.2", "open-telemetry/opentelemetry-auto-mysqli": "^0.4", "php-http/guzzle7-adapter": "^1.1", "guzzlehttp/psr7": "^2.8" }, "config": { "optimize-autoloader": true, "preferred-install": "dist", "sort-packages": true, "allow-plugins": { "php-http/discovery": true, "tbachert/spi": true } }, "minimum-stability": "stable", "prefer-stable": true } ``` `php-http/guzzle7-adapter` and `guzzlehttp/psr7` pin a concrete PSR-18 HTTP client for the OTLP exporter. Without one, the exporter's client auto-discovery can fail and spans are dropped silently. Both entries under `allow-plugins` are required. `tbachert/spi` registers the auto-instrumentation hooks and `php-http/discovery` wires the HTTP client, and Composer will not run either plugin unless it is allowed. Set the `php` constraint to the version that serves traffic. `^8.4` here matches the images this builds on; on an 8.2 or 8.3 runtime, lower it to `^8.2`. A mismatch returns HTTP 500 on every request, covered in [Troubleshooting](#troubleshooting). ```mdx-code-block ``` Build the extension into an image derived from the official WordPress image. Composer runs in a separate stage where the extension is not present, so that extension requirement is skipped there and satisfied at runtime. The `php` version constraint is handled separately, as described above. ```dockerfile title="Dockerfile" showLineNumbers # syntax=docker/dockerfile:1 ARG WP_VERSION=7.0.4 FROM composer:2 AS vendor WORKDIR /opt/otel COPY composer.json composer.lock* ./ # The extension is not present in this stage, so its platform requirement is skipped. RUN composer install \ --no-dev \ --prefer-dist \ --optimize-autoloader \ --ignore-platform-req=ext-opentelemetry \ --ignore-platform-req=ext-mysqli FROM wordpress:${WP_VERSION}-php8.4-apache RUN apt-get update -qq && \ apt-get install --no-install-recommends -y $PHPIZE_DEPS && \ pecl install opentelemetry-1.2.1 && \ apt-get purge -y --auto-remove $PHPIZE_DEPS && \ rm -rf /var/lib/apt/lists/* # Outside the docroot: the entrypoint and core updates both rewrite /var/www/html. COPY --from=vendor /opt/otel/vendor /opt/otel/vendor COPY config/otel.ini /usr/local/etc/php/conf.d/99-otel.ini COPY config/apache-wordpress.conf /etc/apache2/conf-enabled/wordpress.conf ``` Install the vendor directory at `/opt/otel/vendor`, not under `/var/www/html`. The official image's entrypoint and any WordPress core update both rewrite the docroot, which removes files placed there. Apache also needs `AllowOverride`. Debian's default config ignores the `.htaccess` file WordPress writes its rewrite rules into, so without it every pretty permalink returns a 404. ```apache title="config/apache-wordpress.conf" showLineNumbers # Permalink rewrites live in .htaccess, which Debian's default config ignores. AllowOverride All ``` The PHP-FPM image differs in three lines: the base tag becomes `wordpress:${WP_VERSION}-php8.4-fpm`, the last `COPY` writes the pool file to `/usr/local/etc/php-fpm.d/zz-wordpress.conf` instead of the Apache conf, and `libfcgi-bin` joins the `apt-get install` line so the container healthcheck can call `cgi-fcgi`. See [Deployment Shapes](#deployment-shapes) for the pool file. ```mdx-code-block ``` `pecl` compiles the extension, so install PEAR and the PHP development headers for your version first, then install the extension and enable it: ```bash sudo apt-get install -y php-pear php8.4-dev sudo pecl install opentelemetry-1.2.1 sudo phpenmod opentelemetry ``` Confirm it loaded: ```bash php -m | grep opentelemetry ``` If `phpenmod` does not pick it up, write the module file yourself and enable it again: ```bash echo "extension=opentelemetry.so" | sudo tee /etc/php/8.4/mods-available/opentelemetry.ini sudo phpenmod opentelemetry ``` PHP-FPM can use a different ini path than the CLI. Check the FPM binary separately: ```bash php-fpm8.4 -m | grep opentelemetry ``` Install the Composer packages into a directory outside the docroot: ```bash sudo mkdir -p /opt/otel cd /opt/otel sudo env COMPOSER_ALLOW_SUPERUSER=1 composer config --no-plugins allow-plugins.php-http/discovery true sudo env COMPOSER_ALLOW_SUPERUSER=1 composer config --no-plugins allow-plugins.tbachert/spi true sudo env COMPOSER_ALLOW_SUPERUSER=1 composer require \ open-telemetry/sdk:^1.15 \ open-telemetry/exporter-otlp:^1.4 \ open-telemetry/opentelemetry-auto-wordpress:^0.2 \ open-telemetry/opentelemetry-auto-mysqli:^0.4 \ php-http/guzzle7-adapter:^1.1 \ guzzlehttp/psr7:^2.8 ``` Point `auto_prepend_file` at the autoloader. WordPress has no bootstrap file of its own that survives a core update, so the prepend directive attaches the instrumentation instead. Write the drop-in for the SAPI you run: ```bash # PHP-FPM echo "auto_prepend_file=/opt/otel/vendor/autoload.php" \ | sudo tee /etc/php/8.4/fpm/conf.d/99-otel.ini sudo systemctl restart php8.4-fpm # Apache with mod_php echo "auto_prepend_file=/opt/otel/vendor/autoload.php" \ | sudo tee /etc/php/8.4/apache2/conf.d/99-otel.ini sudo systemctl restart apache2 ``` ```mdx-code-block ``` Alpine has no prebuilt package for the extension, so compile it with `pecl`. Install the build toolchain, compile, then remove the toolchain again so it does not stay in the image: ```bash apk add --no-cache --virtual .build-deps $PHPIZE_DEPS pecl install opentelemetry-1.2.1 apk del --no-network .build-deps ``` `$PHPIZE_DEPS` is set by the official `php` Docker images, which the `wordpress:*-alpine` images build on. It holds the compiler toolchain that `phpize` and `pecl` need. On a plain Alpine host that is not derived from those images the variable does not exist, so install the toolchain and the PHP development headers for your PHP version by name instead. Write the ini drop-in and install the Composer packages: ```bash mkdir -p /opt/otel cd /opt/otel composer config --no-plugins allow-plugins.php-http/discovery true composer config --no-plugins allow-plugins.tbachert/spi true composer require \ open-telemetry/sdk:^1.15 \ open-telemetry/exporter-otlp:^1.4 \ open-telemetry/opentelemetry-auto-wordpress:^0.2 \ open-telemetry/opentelemetry-auto-mysqli:^0.4 \ php-http/guzzle7-adapter:^1.1 \ guzzlehttp/psr7:^2.8 cat > /usr/local/etc/php/conf.d/99-otel.ini <<'EOF' extension=opentelemetry.so auto_prepend_file=/opt/otel/vendor/autoload.php EOF ``` ```mdx-code-block ``` #### Verify the install Two things have to be true: the extension is loaded, and the autoloader is prepended. On the CLI: ```bash php -m | grep opentelemetry php -i | grep auto_prepend_file ``` Expected output: ```plaintext opentelemetry auto_prepend_file => /opt/otel/vendor/autoload.php => /opt/otel/vendor/autoload.php ``` The CLI reads a different ini set than the SAPI that serves traffic, so a CLI pass does not prove the web path works. Check the serving SAPI as well. On PHP-FPM, `php-fpm8.4 -i` reads the FPM ini set: ```bash php-fpm8.4 -m | grep opentelemetry php-fpm8.4 -i | grep auto_prepend_file ``` Under Apache with `mod_php`, drop a one-line `phpinfo()` script into the docroot, request it over HTTP, then delete it. ### Configuration The SDK reads its configuration from the standard `OTEL_*` environment variables. Two settings cannot come from the environment, because they have to take effect before any PHP code runs: loading the extension and setting the prepend file. Those live in a `php.ini` drop-in. Set `environment` alongside `deployment.environment` in `OTEL_RESOURCE_ATTRIBUTES`. Scout's UI filters on the lowercase `environment` key, and carrying both keeps the resource valid under semantic conventions while staying queryable in the UI. ```mdx-code-block ``` ```bash OTEL_SERVICE_NAME=wordpress-mariadb-otel OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp OTEL_PHP_AUTOLOAD_ENABLED=true OTEL_RESOURCE_ATTRIBUTES=deployment.environment=development,environment=development ``` `OTEL_PHP_AUTOLOAD_ENABLED=true` tells the SDK to configure itself from these variables when the prepended autoloader runs. Without it, the packages load but the SDK never starts. `http/protobuf` uses port 4318. If you switch `OTEL_EXPORTER_OTLP_PROTOCOL` to `grpc`, change the endpoint port to 4317. `otel-collector` is a Docker Compose service name. On a bare host, point the endpoint at wherever your collector listens, `http://127.0.0.1:4318` for a collector on the same machine. These have to reach the worker process, not your login shell. Under `systemd`, put them in a drop-in for the FPM unit (`systemctl edit php8.4-fpm`) as `Environment=` lines, or set them per pool with `env[OTEL_SERVICE_NAME] = wordpress` in the pool config. Under Apache with `mod_php`, use `SetEnv` in the virtual host. Either way, restart the service and check the values landed with `php-fpm8.4 -i | grep OTEL_` or a `phpinfo()` page. ```mdx-code-block ``` ```ini title="config/otel.ini" showLineNumbers ; Provides the hook mechanism the instrumentation packages attach to. extension=opentelemetry.so ; WordPress has no bootstrap file that survives core updates. auto_prepend_file=/opt/otel/vendor/autoload.php ``` Copy this to the `conf.d` directory for the SAPI that serves traffic. On the official images that is `/usr/local/etc/php/conf.d/99-otel.ini`. The numeric prefix controls load order, and 99 puts it last. On Debian and Ubuntu the path is `/etc/php/8.4/fpm/conf.d/` or `/etc/php/8.4/apache2/conf.d/`, and the drop-in there should carry the `auto_prepend_file` line only. `phpenmod opentelemetry` already enables the extension from `mods-available`, so keeping `extension=opentelemetry.so` here too loads it twice and PHP logs a "module already loaded" warning at startup. `auto_prepend_file` holds a single path, and the last drop-in to set it wins. Some WordPress security plugins use it as well, Wordfence Extended Protection among them, so check the current value before writing the drop-in. Read it from the SAPI that serves traffic, since a plugin sets the directive there and not on the CLI: ```bash php-fpm8.4 -i | grep auto_prepend_file ``` Under Apache with `mod_php`, read the same value from a `phpinfo()` page. If a path is already set, chain it rather than replacing it: point `auto_prepend_file` at a file of your own that `require`s the existing path and then `/opt/otel/vendor/autoload.php`. ```mdx-code-block ``` A YAML anchor keeps one copy of the OTel variables and applies it to every service that needs it. ```yaml title="compose.yaml" showLineNumbers x-otel-env: &otel-env OTEL_SERVICE_NAME: wordpress-mariadb-otel OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4318 OTEL_EXPORTER_OTLP_PROTOCOL: http/protobuf OTEL_TRACES_EXPORTER: otlp OTEL_METRICS_EXPORTER: otlp OTEL_LOGS_EXPORTER: otlp OTEL_PHP_AUTOLOAD_ENABLED: "true" OTEL_RESOURCE_ATTRIBUTES: deployment.environment=development,environment=development x-db-creds: &db-creds WORDPRESS_DB_HOST: mariadb:3306 WORDPRESS_DB_USER: wordpress WORDPRESS_DB_PASSWORD: wordpress x-wp-env: &wp-env <<: *db-creds WORDPRESS_DB_NAME: wordpress WORDPRESS_CONFIG_EXTRA: | define('DISABLE_WP_CRON', true); services: wordpress: build: context: . dockerfile: Dockerfile args: WP_VERSION: ${WP_VERSION:-7.0.4} container_name: wordpress-app ports: - "${WP_APACHE_PORT:-8080}:80" volumes: - wordpress-data:/var/www/html environment: <<: [*wp-env, *otel-env] OTEL_RESOURCE_ATTRIBUTES: deployment.environment=development,environment=development,service.instance.role=apache healthcheck: test: ["CMD", "curl", "-fsS", "-o", "/dev/null", "http://localhost/"] interval: 10s timeout: 5s start_period: 30s retries: 5 depends_on: mariadb: condition: service_healthy otel-collector: condition: service_started restart: unless-stopped networks: - wordpress-network ``` The service-level `OTEL_RESOURCE_ATTRIBUTES` overrides the anchor's value rather than merging with it, so it repeats the two environment keys and adds `service.instance.role`. That attribute distinguishes an Apache instance from an FPM instance when both report under one service name. ```mdx-code-block ``` ### Deployment Shapes All three take the same `conf.d` ini drop-in. The two containerised shapes were captured side by side and produce the same spans; the bare-host shape runs the same FPM SAPI and the same packages, so expect the same. What differs between them is how environment variables reach PHP. | | Apache + mod_php | FPM + nginx | FPM on a bare host | | --- | --- | --- | --- | | Env var propagation | Inherited from the Apache process | Official image sets `clear_env = no` in `docker.conf`; stripped without it | Stripped unless `clear_env = no`, or set per pool with `env[...]` | | Process model | One process handles the full request | Web server and PHP are separate processes | Same, plus systemd unit boundaries | | Pick it when | Running the official image or a standard LAMP install | Already terminating TLS at nginx, or scaling PHP workers separately | Instrumenting an existing host without containerising it | The official `wordpress:*-fpm` image ships `/usr/local/etc/php-fpm.d/docker.conf` with an active `clear_env = no`, loaded ahead of any pool file you add, so on that image there is nothing to change. Check your own image the same way, substituting your FPM service name: ```bash docker compose exec wordpress-fpm cat /usr/local/etc/php-fpm.d/docker.conf ``` The pool file below re-asserts `clear_env = no` for a hand-rolled pool that does not inherit that `docker.conf`. It also defines the `ping.path` endpoint used as a readiness check, since FPM speaks FastCGI and cannot be probed with `curl`. [Troubleshooting](#fpm-workers-cannot-see-otel-variables) covers what breaks when the worker environment is cleared. ```ini title="config/php-fpm.conf" showLineNumbers [www] listen = 0.0.0.0:9000 pm = dynamic pm.max_children = 10 pm.start_servers = 2 pm.min_spare_servers = 1 pm.max_spare_servers = 4 ping.path = /ping ping.response = pong ; Keep OTEL_* visible to FPM workers. The official image sets this in docker.conf; a hand-rolled pool may not. clear_env = no ``` nginx passes PHP requests to the FPM pool over FastCGI and rewrites everything else to the front controller. ```nginx title="config/nginx.conf" showLineNumbers server { listen 80; server_name _; root /var/www/html; index index.php; location / { try_files $uri $uri/ /index.php?$args; } location ~ \.php$ { try_files $uri =404; include fastcgi_params; fastcgi_pass wordpress-fpm:9000; fastcgi_param SCRIPT_FILENAME $document_root$fastcgi_script_name; } } ``` ### Production Configuration #### Collector configuration A production collector config for this workload, with a `filter` processor for probe traffic, `memory_limiter` ahead of `batch` in every pipeline, and `gzip` on the exporter. It is a hardened version of the example's `config/otel-config.yaml`, not a copy of it: ```yaml showLineNumbers extensions: oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} token_url: ${SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: memory_limiter: limit_mib: 256 check_interval: 1s # Conditions are examples. Rewrite them against your own probe's # url.path and user_agent.original before relying on this. filter/noise: error_mode: ignore traces: span: - 'attributes["url.path"] == "/health"' - 'IsMatch(attributes["user_agent.original"], "^(kube-probe|ELB-HealthChecker|Blackbox).*")' - 'IsMatch(attributes["url.path"], ".*\\.(css|js|png|jpe?g|gif|svg|woff2?|ico)$")' batch: send_batch_size: 1024 timeout: 5s exporters: otlp_http/scout: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [oauth2client, health_check, zpages] telemetry: metrics: level: normal readers: - pull: exporter: prometheus: host: 0.0.0.0 port: 8888 pipelines: traces: receivers: [otlp] processors: [memory_limiter, filter/noise, batch] exporters: [otlp_http/scout] metrics: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlp_http/scout] logs: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlp_http/scout] ``` Leave `compression: gzip` enabled, since `db.query.text` carries the full SQL statement on every `wpdb.query` and `mysqli_query` span and those two span names dominate the payload. Write the `filter/noise` conditions against your own probe rather than copying them. The three above match a Kubernetes probe, a load balancer health check, and static assets; a probe that requests `/` with curl's user agent matches none of them. `filter` also evaluates one span at a time. `url.path`, `url.full`, and `user_agent.original` are on the root span only, so a condition written against those keys removes the root and leaves that request's `WP.*`, `wpdb.*`, and `mysqli_*` spans behind as orphans. Use the collector filter for probe traffic you can match precisely, and the controls below for everything else. #### Controlling span volume One request produces two spans per query plus the lifecycle spans, so span count tracks query count closely. A default site with three posts, one page, and no plugins produces: | Request | `wpdb.query` | `mysqli_query` | Total spans | | --- | --- | --- | --- | | Home page | 24 | 27 | 63 | | Single post | 35 | 38 | 86 | | Search results | 29 | 32 | 73 | | Category archive | 25 | 28 | 65 | | Page | 20 | 23 | 55 | | 404 | 19 | 22 | 53 | | REST posts collection | 17 | 20 | 45 | | Login form | 7 | 10 | 22 | Those counts come from a site with no plugins, so a real site runs higher. Four ways to bring the count down: **1. Turn off one of the two instrumentations.** Every `wpdb.query` span has exactly one `mysqli_query` child and both carry `db.query.text`, so the pair largely duplicates. Disabling `mysqli` roughly halves the database spans: ```bash OTEL_PHP_DISABLED_INSTRUMENTATIONS=mysqli ``` The value is the instrumentation name, not the scope name it emits under. Comma-separate to disable both. You lose the `mysqli_real_connect` span and the `db.namespace`, `db.operation.name`, `server.address`, and `server.port` attributes, which `wpdb.query` does not carry. You keep the SQL text and the position of each query in the request. **2. Add a persistent object cache.** This is a WordPress change rather than a telemetry setting. Options, transients, and meta lookups served from cache are queries WordPress never issues, so they produce no spans. **3. Filter probe traffic at the collector.** A health check produces whatever the URL it requests produces. A probe against a URL WordPress renders produces a full page trace, 63 spans for a home page, which at a 10 second interval is 6 extra traces a minute per instance. Point the probe at a URL that returns a redirect or a static file, and drop what remains in `filter/noise`. **4. Tune batching at the collector.** PHP ends the SDK at the end of each request and the shutdown hook flushes whatever is queued, so the SDK never carries spans from one request into the next. Batching across requests happens in the collector. Raise `send_batch_size` to cut the number of outbound requests, and watch `otelcol_exporter_send_failed_spans` when you do. ### Framework-Specific Features #### Lifecycle spans The `wordpress` instrumentation names stages of the request lifecycle. Which ones appear depends on how the request was routed: | Span name | When it appears | | --- | --- | | `WP.main` | Requests routed through the front controller. Absent on direct script hits like `/wp-login.php`. | | `WP.init` | Every request. Twice on front-controller requests: once under the root span, once under `WP.main`. | | `WP.parse_request` | Front-controller requests. | | `WP.query_posts` | Requests that run the main query. | | `WP.register_globals` | Requests that run the main query. | | `WP.send_headers` | Requests that run the main query. | | `WP.handle_404` | Requests that run the main query, whatever status they return. | | `get_single_template` | Requests that resolve a single-post template. | Two routes are missing the four main-query spans. REST dispatch short-circuits before reaching them, and `/wp-login.php` never runs `WP.main` at all, because the web server invokes that script directly rather than routing it through the front controller. `WP.handle_404` does not indicate a 404. It runs on any request that goes through the main query, including ones that return 200, so use `http.response.status_code` on the root span to find real 404s. #### Database access Every request opens its own connection and produces one `wpdb.__construct`, one `wpdb.db_connect`, and one `mysqli_real_connect`. Each `wpdb.db_connect` has one `mysqli_real_connect` child plus three `mysqli_query` children, which are the queries the driver issues while setting the connection up rather than anything the page asked for. Every `wpdb.query` span has exactly one `mysqli_query` child. Both carry `db.query.text`, so each query is described twice. `wpdb.query` appears under four different parents, so its parent tells you where in the request a query was issued: - Directly under the root span, for queries WordPress issues before routing completes. - Under `WP.query_posts`, for the main query. - Under `WP.parse_request`, for routing lookups. - Under `get_single_template`, for queries the template resolution triggers. ### Custom Instrumentation Auto-instrumentation covers WordPress core and the `mysqli` driver, so work done by your own theme or plugin needs spans of its own. The prepended autoloader configures the SDK before WordPress boots, so `Globals` returns the configured providers by the time theme or plugin code runs and no further setup is needed. Wrap a function in a span: ```php $tracer = \OpenTelemetry\API\Globals::tracerProvider()->getTracer('wordpress-custom'); $span = $tracer->spanBuilder('render_featured_posts')->startSpan(); $scope = $span->activate(); try { // theme work } finally { $scope->detach(); $span->end(); } ``` Activating the span makes it the parent of anything the auto-instrumentation creates inside the `try` block, so queries issued there nest under it and their time is attributed to your code. Detach and end in a `finally` block so an exception cannot leave the span open. A counter follows the same shape through the meter provider: ```php $meter = \OpenTelemetry\API\Globals::meterProvider()->getMeter('wordpress-custom'); $counter = $meter->createCounter( 'featured_posts.rendered', 'posts', 'Featured posts rendered' ); $counter->add(count($featured), ['theme' => 'my-theme']); ``` Use dotted OpenTelemetry-style instrument names rather than Prometheus-style underscored ones, so the metric reads the same way as the rest of the telemetry. ### Running Your Application #### Development with Docker Compose Clone the [php/wordpress-mariadb example](https://github.com/base-14/examples/tree/main/php/wordpress-mariadb), copy the environment file, and bring the stack up. The `SCOUT_*` placeholders in `.env.example` let the collector start without real credentials. ```bash git clone https://github.com/base-14/examples.git cd examples/php/wordpress-mariadb cp .env.example .env set -a && source .env && set +a docker compose up -d --build ``` A seed container creates three posts in an `observability` category, an `about` page, and one approved comment, then exits. Wait for it: ```bash docker compose logs -f wp-init ``` Once it prints `Seed complete`, the site is on port 8080, or whatever `WP_APACHE_PORT` is set to. #### The PHP-FPM profile The FPM containers sit behind a Compose profile and use their own database and volume, so both shapes can run at once without mixing content. ```bash docker compose --profile fpm up -d --build docker compose logs -f wp-init-fpm SITE_URL=http://localhost:${WP_FPM_PORT:-8081} ./scripts/test-api.sh ``` Set `SITE_URL` explicitly for the FPM profile. It defaults to the Apache stack, so leaving it out re-tests Apache instead. #### Generating traffic `scripts/test-api.sh` requests eight fixed paths and checks each status code: ```bash ./scripts/test-api.sh ``` Expected output: ```plaintext === WordPress OpenTelemetry path set === Target: http://localhost:8080 [PASS] home (200) [PASS] single post (200) [PASS] page (200) [PASS] archive (200) [PASS] search (200) [PASS] rest posts (200) [PASS] login page (200) [PASS] not found (404) Passed: 8 Failed: 0 ``` #### Confirming spans arrive Watch the collector while you drive a request from another shell. With the `debug` exporter enabled you get a `Span #` block per span: ```bash docker compose logs -f otel-collector | grep 'Span #' ``` Outside Docker, read the collector's own log the same way, for instance `journalctl -fu otelcol-contrib | grep 'Span #'`. If your collector runs the `prometheus` extension, `curl -s localhost:8888/metrics | grep otelcol_receiver_accepted_spans` gives you a counter that should rise as you request pages, which works whether or not the `debug` exporter is on. If nothing appears, work through [Troubleshooting](#troubleshooting) below, starting with the extension and prepend check for the serving SAPI. In Scout, filter on `service.name=wordpress-mariadb-otel` and `environment=development`, then open a trace for a single post. You should see `wpdb.query` and `mysqli_query` children under `GET /index.php`. #### Expected span hierarchy A request to a single post produces this tree. Each line appears once per distinct parent-child relationship, not once per span: ```text GET /index.php SERVER ├── wpdb.__construct INTERNAL │ └── wpdb.db_connect CLIENT │ ├── mysqli_real_connect CLIENT │ └── mysqli_query CLIENT ├── wpdb.query CLIENT │ └── mysqli_query CLIENT ├── WP.init SERVER ├── WP.main SERVER │ ├── WP.init SERVER │ ├── WP.parse_request SERVER │ │ └── wpdb.query CLIENT │ ├── WP.query_posts SERVER │ │ └── wpdb.query CLIENT │ ├── WP.handle_404 SERVER │ ├── WP.register_globals SERVER │ └── WP.send_headers SERVER └── get_single_template SERVER └── wpdb.query CLIENT ``` Each `wpdb.query` in that tree has one `mysqli_query` child, shown once above. On a default site the whole trace runs to 86 spans. ### Troubleshooting #### FPM workers cannot see the OTEL\_\* variables {#fpm-workers-cannot-see-otel-variables} **Symptom.** WordPress returns HTTP 500 with "Error establishing a database connection", and no spans arrive. **Why.** `clear_env` clears the whole worker environment, not just the `OTEL_*` variables. On the official `wordpress:*-fpm` image the database credentials come from `WORDPRESS_DB_*`, so they are stripped too and the database error surfaces before the missing telemetry does. **Check before you change anything.** The official image already ships an active `clear_env = no`, so on that image there is usually nothing to fix: ```bash docker compose exec wordpress-fpm cat /usr/local/etc/php-fpm.d/docker.conf ``` **Check through a worker, not the CLI.** `docker compose exec ... php -r` runs the CLI SAPI, which `clear_env` does not govern, so that check passes while the workers are broken. Request a script over HTTP instead, then remove it: ```bash docker compose exec wordpress-fpm sh -c \ 'echo " /var/www/html/otel-env-check.php' curl -s http://localhost:8081/otel-env-check.php docker compose exec wordpress-fpm rm /var/www/html/otel-env-check.php ``` `true` means the workers see the variable. `EMPTY` means they do not. **Fix.** Set `clear_env = no` in the pool config, as [Deployment Shapes](#deployment-shapes) shows. A distro package or a hand-rolled pool has no `docker.conf` to inherit the setting from, so the pool file has to carry it. #### The extension is loaded but no spans appear **Symptom.** `php -m` lists `opentelemetry` and the collector receives nothing. **Check.** Read the prepend directive and the autoload flag for the SAPI that serves traffic. `php -i` reports the CLI, which loads a different ini set, so run the binary for the serving SAPI instead: ```bash # PHP-FPM php-fpm8.4 -i | grep auto_prepend_file php-fpm8.4 -i | grep OTEL_PHP_AUTOLOAD_ENABLED ``` Apache with `mod_php` has no such binary. Request a temporary `phpinfo()` page over HTTP and read the same two values from it, then delete the page. **Fix.** An empty `auto_prepend_file` means the ini drop-in landed in the wrong `conf.d` directory. Debian and Ubuntu keep one per SAPI, so a file written to `/etc/php/8.4/cli/conf.d/` never reaches Apache or FPM. Write it to the FPM or Apache directory and restart that service. If the prepend is set but `OTEL_PHP_AUTOLOAD_ENABLED` is not `true`, the packages load and the SDK never registers. #### Instrumentation disappears after a WordPress core update **Symptom.** Spans stop arriving after a core update, with no configuration change of your own. **Check.** Look at where the prepend points: ```bash php -i | grep auto_prepend_file ls -l /opt/otel/vendor/autoload.php ``` **Fix.** The vendor directory was inside the docroot. A core update and the official image's entrypoint both rewrite `/var/www/html`, which takes the autoloader with it. Install the Composer packages into a directory outside the docroot, `/opt/otel` in this guide, and point the ini drop-in there. #### composer install fails on the ext-opentelemetry platform requirement **Symptom.** `composer install` stops with `requires ext-opentelemetry * -> it is missing from your system`. **Check.** `php -m | grep opentelemetry` on the machine or build stage running Composer, which is often not the machine that will run PHP. **Fix.** Skip the platform requirement where Composer runs and satisfy it at runtime. The build stage does this: ```dockerfile title="Dockerfile" showLineNumbers RUN composer install \ --no-dev \ --prefer-dist \ --optimize-autoloader \ --ignore-platform-req=ext-opentelemetry \ --ignore-platform-req=ext-mysqli ``` #### Every request returns HTTP 500 once the prepend is in place **Symptom.** Every request returns HTTP 500, `/wp-admin` included, and the body reads `Composer detected issues in your platform`. No spans arrive. The browser names the required PHP version but not the one you are running; the web server's error log carries both. **Why.** The `php` constraint in `composer.json` is higher than the PHP serving traffic. Composer records that constraint in `vendor/composer/platform_check.php` and the autoloader executes it, so `auto_prepend_file` trips the check before WordPress gets control. Installing in a separate build stage defers the failure to runtime rather than preventing it, because Composer resolved against that stage's PHP. **Check.** Read the constraint, the serving version, and the generated check: ```bash grep '"php"' /opt/otel/composer.json php -v cat /opt/otel/vendor/composer/platform_check.php ``` **Fix.** Lower the `php` constraint to match the serving runtime and reinstall. To leave `composer.json` untouched, pass `--ignore-platform-req=php` where Composer runs; the generated check then omits the version test entirely. #### No database spans **Symptom.** `WP.*` spans arrive, but no `mysqli_query` or `mysqli_real_connect`. **Check.** Confirm the package is installed and not disabled: ```bash composer show | grep opentelemetry php -i | grep OTEL_PHP_DISABLED_INSTRUMENTATIONS ``` **Fix.** Install `open-telemetry/opentelemetry-auto-mysqli`. WordPress core reaches the database through `mysqli`, so a PDO instrumentation package is not a substitute. If the package is present, check that `OTEL_PHP_DISABLED_INSTRUMENTATIONS` does not list `mysqli`. #### Backing it out Set `OTEL_PHP_AUTOLOAD_ENABLED=false` and restart the SAPI. The packages still load but the SDK does not start, and nothing is exported. To remove it completely, delete the `99-otel.ini` drop-in, restart, and delete `/opt/otel`. Neither step touches WordPress, since nothing was installed into the docroot. ### Security Considerations #### SQL statements travel with the span `db.query.text` carries the statement on both `wpdb.query` and its `mysqli_query` child, so every query is described twice. Statements carry literal values inline, as in `t.slug IN ('observability')` and `WHERE ID IN (4,5,6)`, so whatever a query matches on is in the span text. Drop or hash the attribute at the collector if that text should not leave your network: ```yaml processors: attributes/scrub-sql: actions: - key: db.query.text action: delete ``` `db.query.text` is the bulk of the payload, so dropping it also removes most of what `compression: gzip` was compressing. #### What the request spans carry Root spans carry no request headers other than `user_agent.original`, no cookies, and no logged-in user identifier. The attribute list in [What Gets Instrumented](#what-gets-instrumented) is everything they carry. `url.full` carries the requested URL with its query string, so search terms end up in the span. If your URLs carry tokens, email addresses, or anything else you would not put in a log line, strip or rewrite the attribute at the collector before export. #### Admin traffic `wp.is_admin` on the root span marks requests inside `wp-admin/`. Admin URLs carry more sensitive parameters than front-end ones, so decide whether you want them exported at all, and filter on that attribute if not. #### Transport Do not carry `tls.insecure_skip_verify` from a local config into production. It disables certificate verification on the export path. ### Performance Considerations Cost scales with the number of spans, which scales with the number of queries a request makes. On a small default site: - **Latency**: roughly doubles the median request, in the range 1.7x to 2.3x. - **Memory**: roughly 8 to 12 MiB added to the WordPress container at six prefork workers. - **Spans**: 22 to 86 per request, depending on the path. The absolute cost is small here because the base is small on a bare site. A plugin-heavy site has a different base and a different span count, so measure your own before sizing anything. Measure memory on the container total. The extension's text pages and the OPcache segment holding the compiled SDK classes are shared across workers, and per-worker RSS counts them once per process, so it overstates the real cost several times over. #### Reducing the cost The four controls in [Controlling span volume](#controlling-span-volume) apply here in the same order: disable one of the two instrumentations, add a persistent object cache, keep probes off rendered URLs, and tune collector batching. None of them reduce visibility of real traffic. Two more things: - **The first front-end request of a site's life costs about 34 extra spans.** The theme creates a navigation post, inserts options and a transient, and misses on lookups that hit on every later request. It is paid once per site, not once per container start. - **Export runs at request shutdown.** PHP has no background worker to defer to, so the SDK's export to the local collector is inside the request. Keep the collector local to the host or the pod; the collector's onward ship to Scout is asynchronous and is not in the request path. ### Frequently Asked Questions #### Does this work on WordPress.com or managed hosting? Only if the host lets you install a PECL extension and add a file to PHP's `conf.d` directory. The PECL `opentelemetry` extension provides the hook mechanism the instrumentation packages attach to, and `auto_prepend_file` loads them before WordPress boots. Managed hosting with a fixed PHP extension set allows neither. A VM, a container image you build, or a bare metal LAMP server all work. #### Do I need to modify my theme or install a plugin? No. Nothing is installed into WordPress and no application code changes. The Composer packages live in a directory outside the docroot, and a `php.ini` drop-in points `auto_prepend_file` at their autoloader so the SDK is running before WordPress starts. Themes, plugins, and core files are untouched. #### Why do I get no database spans? The `open-telemetry/opentelemetry-auto-mysqli` package is missing, or `mysqli` is listed in `OTEL_PHP_DISABLED_INSTRUMENTATIONS`. WordPress core reaches the database through `mysqli`, and that package produces the `mysqli_query` and `mysqli_real_connect` spans. A PDO instrumentation package does not cover it. Seeing `wpdb.*` spans without `mysqli_*` spans points to one of those two causes. #### Does it work with PHP-FPM? Yes. Apache with mod_php and PHP-FPM behind nginx produce the same spans. The one thing to check on FPM is that the pool does not clear the worker environment, because the SDK is configured entirely through `OTEL_*` variables. The official `wordpress:*-fpm` image already ships `clear_env = no`, so on that image there is normally nothing to change. #### How many spans does one page load produce? On a default site with three posts and no plugins, between 22 and 86 spans per request depending on the path: 22 for the login form, 86 for a single post. Span count tracks query count, because each query produces a `wpdb.query` span and a `mysqli_query` child. The first front-end request against a brand new site costs about 34 spans more than the steady state, because the theme writes options and posts the database does not have yet; that is paid once per site. These counts come from a site with no plugins, so a real site runs higher. #### What happens on a WordPress core update? Nothing, if the Composer packages are outside the docroot. A core update rewrites `/var/www/html`, and so does the official image's entrypoint, so anything installed there gets overwritten. Install to `/opt/otel` and point `auto_prepend_file` there instead; no WordPress update touches it. The `php.ini` drop-in is safe either way. #### Can I tell which plugin is slow? Not from auto-instrumentation alone. No span name or instrumentation scope identifies a plugin, so plugin work is not separated from core work. Every query a request issued is still recorded with its SQL text on the `wpdb.query` and `mysqli_query` spans, which is often enough to recognise the source. To attribute time directly, wrap the plugin's hooks in manual spans as [Custom Instrumentation](#custom-instrumentation) shows. #### How much overhead does OpenTelemetry add to WordPress? On a small default site, instrumentation roughly doubles the median request, in the range 1.7x to 2.3x, and adds roughly 8 to 12 MiB to the WordPress container at six prefork workers. The ratio is more useful than a millisecond figure, since the base is small on a bare site and the absolute cost moves with host load. These figures come from a site with no plugins, so a real site runs higher. #### Which WordPress versions are supported? WordPress 6.0 and later, on PHP 8.2 or later. The floor is set by PHP: the mysqli package requires PHP 8.2, and 6.0 is the earliest WordPress release compatible with it. Nothing checks the WordPress version at install time, so an upgrade that breaks the instrumentation shows up as missing spans rather than a failed install. Check that spans still arrive after a major upgrade. ### What's Next - [Custom PHP Instrumentation](../custom-instrumentation/php.md) for manual spans, metrics, and context propagation beyond the two examples above. - [MariaDB monitoring](../../component/mariadb.md) to pair the query spans with database-side metrics. - [Docker Compose collector setup](../../collector-setup/docker-compose-example.md) for a collector to export to while you are testing. - [Creating alerts](../../../guides/creating-alerts-with-logx.md) once traces are arriving, for error rates and latency thresholds. ### Complete Example The runnable stack is at [base-14/examples/php/wordpress-mariadb](https://github.com/base-14/examples/tree/main/php/wordpress-mariadb). It brings up WordPress, MariaDB, and a collector, seeds the site, and drives a fixed path set you can generate traces from. ```text php/wordpress-mariadb/ ├── .env.example # Scout credentials and the port overrides ├── README.md # setup and both deployment profiles ├── compose.yaml # Apache by default, FPM behind a profile ├── composer.json # SDK, OTLP exporter, both instrumentations ├── composer.lock ├── Dockerfile # Apache + mod_php, with the PECL extension ├── Dockerfile.fpm # PHP-FPM, same extension and vendor dir ├── config/ │ ├── otel.ini # extension= and auto_prepend_file= │ ├── otel-config.yaml # collector pipelines │ ├── apache-wordpress.conf # AllowOverride for permalink rewrites │ ├── php-fpm.conf # pool config, clear_env and ping.path │ ├── nginx.conf # FastCGI pass to the FPM pool │ └── init-db.sql # second database for the FPM profile └── scripts/ ├── init-wordpress.sh # seeds posts, a page, a category, a comment ├── test-api.sh # the eight-path set └── verify-scout.sh # checks spans are reaching Scout ``` [Running Your Application](#running-your-application) above has the commands for both profiles. Once spans are arriving, you can [trace WordPress requests end to end in Scout](https://base14.io/scout/apm) alongside the rest of your services. ### References - [OpenTelemetry PHP documentation](https://opentelemetry.io/docs/languages/php/). - [opentelemetry-auto-wordpress on Packagist](https://packagist.org/packages/open-telemetry/opentelemetry-auto-wordpress). - [opentelemetry-auto-mysqli on Packagist](https://packagist.org/packages/open-telemetry/opentelemetry-auto-mysqli). - [PECL opentelemetry extension](https://pecl.php.net/package/opentelemetry). - [OpenTelemetry semantic conventions](https://opentelemetry.io/docs/specs/semconv/). - [OpenTelemetry environment variable specification](https://opentelemetry.io/docs/specs/otel/configuration/sdk-environment-variables/). - [PHP-FPM configuration directives](https://www.php.net/manual/en/install.fpm.configuration.php). - [WordPress database class reference](https://developer.wordpress.org/reference/classes/wpdb/). ### Related Guides - [PHP custom instrumentation](../custom-instrumentation/php.md) - manual spans, metrics, and propagation in PHP. - [Laravel](./laravel.md) - if you also run Laravel applications and want them reporting under the same conventions. - [Symfony](./symfony.md) - the same for Symfony. - [Slim](./slim.md) - for smaller PHP services alongside the WordPress site. --- ## C# OpenTelemetry Custom Instrumentation - Spans & Metrics Guide ## CSharp Implement OpenTelemetry custom instrumentation for C# and .NET applications to collect traces, metrics, and logs using the .NET OpenTelemetry SDK. This guide covers manual instrumentation for any .NET application, including ASP.NET Core, console apps, worker services, and custom frameworks. > **Note:** This guide provides a practical overview based on the official > OpenTelemetry documentation. For complete information, please consult the > [official OpenTelemetry .NET documentation](https://opentelemetry.io/docs/languages/net/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry SDK for manual instrumentation - Create and manage custom spans using `ActivitySource` - Add attributes, events, and exception tracking - Implement metrics collection with `System.Diagnostics.Metrics` - Propagate context across service boundaries - Instrument common .NET patterns and async code > **Complete Working Examples**: This guide includes code snippets for learning. > For full implementations, see the > [Complete Examples](#complete-examples) section. ### Prerequisites Before starting, ensure you have: - **.NET 8.0 or later** installed (.NET 10.0 recommended) - **Visual Studio 2022**, **VS Code**, or **Rider** - **base14 Scout account** with collector endpoint and API key - Basic familiarity with async C# and dependency injection ### Required Packages Add these NuGet packages to your project: ```xml title="YourProject.csproj" ``` Or via CLI: ```bash dotnet add package OpenTelemetry dotnet add package OpenTelemetry.Extensions.Hosting dotnet add package OpenTelemetry.Exporter.OpenTelemetryProtocol ``` ### Telemetry Initialization #### ASP.NET Core Setup Configure OpenTelemetry in your `Program.cs`: ```csharp title="Program.cs" using OpenTelemetry.Resources; using OpenTelemetry.Trace; using OpenTelemetry.Metrics; var builder = WebApplication.CreateBuilder(args); // Configure OpenTelemetry builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService( serviceName: "my-dotnet-service", serviceVersion: "1.0.0") .AddAttributes(new[] { new KeyValuePair("deployment.environment", "production"), new KeyValuePair("environment", "production") })) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddSource("MyApp.Services") // Register custom ActivitySources .AddOtlpExporter(options => { options.Endpoint = new Uri("https://scout-collector.base14.io:4317"); })) .WithMetrics(metrics => metrics .AddAspNetCoreInstrumentation() .AddHttpClientInstrumentation() .AddMeter("MyApp.Metrics") // Register custom Meters .AddOtlpExporter(options => { options.Endpoint = new Uri("https://scout-collector.base14.io:4317"); })); var app = builder.Build(); app.Run(); ``` #### Extension Method Pattern Organize telemetry setup in a separate file: ```csharp title="Telemetry/TelemetrySetup.cs" using OpenTelemetry.Resources; using OpenTelemetry.Trace; using OpenTelemetry.Metrics; namespace MyApp.Telemetry; public static class TelemetrySetup { public static WebApplicationBuilder AddTelemetry(this WebApplicationBuilder builder) { var serviceName = builder.Configuration["Telemetry:ServiceName"] ?? "my-service"; var otlpEndpoint = builder.Configuration["Telemetry:OtlpEndpoint"] ?? "https://scout-collector.base14.io:4317"; builder.Services.AddOpenTelemetry() .ConfigureResource(resource => resource .AddService(serviceName) .AddAttributes(new[] { new KeyValuePair( "deployment.environment", builder.Environment.EnvironmentName), new KeyValuePair( "environment", builder.Environment.EnvironmentName) })) .WithTracing(tracing => tracing .AddAspNetCoreInstrumentation(options => { options.RecordException = true; }) .AddHttpClientInstrumentation() .AddSource("MyApp.*") .AddOtlpExporter(options => { options.Endpoint = new Uri(otlpEndpoint); })) .WithMetrics(metrics => metrics .AddAspNetCoreInstrumentation() .AddMeter("MyApp.*") .AddOtlpExporter(options => { options.Endpoint = new Uri(otlpEndpoint); })); return builder; } } ``` Usage: ```csharp title="Program.cs" var builder = WebApplication.CreateBuilder(args); builder.AddTelemetry(); ``` ### Traces #### Creating an ActivitySource Define an `ActivitySource` for your service or component: ```csharp using System.Diagnostics; public class UserService { private static readonly ActivitySource ActivitySource = new("MyApp.UserService"); // Service methods... } ``` #### Creating Spans Create spans to trace operations: ```csharp using System.Diagnostics; public class UserService { private static readonly ActivitySource ActivitySource = new("MyApp.UserService"); public async Task CreateUserAsync(CreateUserRequest request) { using var activity = ActivitySource.StartActivity("user.create"); activity?.SetTag("user.email", request.Email); var user = new User { Email = request.Email, Name = request.Name }; await _context.Users.AddAsync(user); await _context.SaveChangesAsync(); activity?.SetTag("user.id", user.Id); return user; } } ``` #### Span with Specific Kind Specify the span kind for proper visualization: ```csharp public async Task CallExternalServiceAsync(string endpoint) { using var activity = ActivitySource.StartActivity( "external.call", ActivityKind.Client); activity?.SetTag("http.url", endpoint); activity?.SetTag("http.method", "GET"); var response = await _httpClient.GetAsync(endpoint); activity?.SetTag("http.status_code", (int)response.StatusCode); return response; } ``` Available `ActivityKind` values: - `Internal` (default) - Internal operation - `Server` - Server-side handling of a request - `Client` - Client-side of an outgoing request - `Producer` - Initiator of an async operation - `Consumer` - Handler of an async operation #### Nested Spans Spans automatically nest based on the call hierarchy: ```csharp public async Task ProcessOrderAsync(CreateOrderRequest request) { using var activity = ActivitySource.StartActivity("order.process"); var user = await ValidateUserAsync(request.UserId); // Creates child span var items = await ReserveInventoryAsync(request.Items); // Creates child span var payment = await ProcessPaymentAsync(request.Payment); // Creates child span activity?.SetTag("order.total", payment.Amount); return new OrderResponse { OrderId = Guid.NewGuid() }; } private async Task ValidateUserAsync(int userId) { using var activity = ActivitySource.StartActivity("user.validate"); // This span is a child of "order.process" return await _userService.GetByIdAsync(userId); } ``` ### Attributes #### Adding Span Attributes Add attributes to provide context: ```csharp public async Task
CreateArticleAsync(int userId, CreateArticleRequest request) { using var activity = ActivitySource.StartActivity("article.create"); activity?.SetTag("user.id", userId); activity?.SetTag("article.title", request.Title); var article = new Article { Title = request.Title, Body = request.Body, AuthorId = userId }; await _context.Articles.AddAsync(article); await _context.SaveChangesAsync(); // Add more attributes after values are known activity?.SetTag("article.id", article.Id); activity?.SetTag("article.slug", article.Slug); return article; } ``` #### Semantic Conventions Follow OpenTelemetry semantic conventions: ```csharp public async Task MakeHttpRequestAsync(string url) { using var activity = ActivitySource.StartActivity("http.request", ActivityKind.Client); // HTTP semantic conventions activity?.SetTag("http.method", "GET"); activity?.SetTag("http.url", url); activity?.SetTag("http.scheme", new Uri(url).Scheme); activity?.SetTag("net.peer.name", new Uri(url).Host); activity?.SetTag("net.peer.port", new Uri(url).Port); var response = await _httpClient.GetAsync(url); activity?.SetTag("http.status_code", (int)response.StatusCode); activity?.SetTag("http.response.body.size", response.Content.Headers.ContentLength); return response; } ``` #### Multiple Attributes at Once Use `SetTag` for individual attributes or `AddTag` for batch operations: ```csharp public async Task ProcessBatchAsync(IEnumerable items) { using var activity = ActivitySource.StartActivity("batch.process"); var itemList = items.ToList(); activity?.SetTag("batch.size", itemList.Count); activity?.SetTag("batch.type", "items"); // Process items... activity?.SetTag("batch.processed", processedCount); activity?.SetTag("batch.failed", failedCount); } ``` ### Events #### Adding Events to Spans Record significant events during span execution: ```csharp public async Task FulfillOrderAsync(int orderId) { using var activity = ActivitySource.StartActivity("order.fulfill"); activity?.AddEvent(new ActivityEvent("order.fulfillment.started")); var order = await _orderRepository.GetByIdAsync(orderId); activity?.AddEvent(new ActivityEvent( "inventory.checked", tags: new ActivityTagsCollection { { "inventory.available", true }, { "items.count", order.Items.Count } })); await ProcessPaymentAsync(order); activity?.AddEvent(new ActivityEvent( "payment.processed", tags: new ActivityTagsCollection { { "payment.amount", order.Total }, { "payment.method", order.PaymentMethod } })); await ShipOrderAsync(order); activity?.AddEvent(new ActivityEvent("order.shipped")); return order; } ``` #### Timestamped Events Add events with specific timestamps: ```csharp public async Task ProcessWithTimestampsAsync() { using var activity = ActivitySource.StartActivity("process.timed"); var startTime = DateTimeOffset.UtcNow; activity?.AddEvent(new ActivityEvent( "processing.started", startTime)); await DoWorkAsync(); var endTime = DateTimeOffset.UtcNow; activity?.AddEvent(new ActivityEvent( "processing.completed", endTime, new ActivityTagsCollection { { "duration.ms", (endTime - startTime).TotalMilliseconds } })); } ``` ### Exception Recording #### Recording Exceptions Record exceptions with full context: ```csharp public async Task UpdateArticleAsync(string slug, int userId, UpdateArticleRequest request) { using var activity = ActivitySource.StartActivity("article.update"); activity?.SetTag("article.slug", slug); activity?.SetTag("user.id", userId); try { var article = await _context.Articles .FirstOrDefaultAsync(a => a.Slug == slug); if (article is null) return null; if (article.AuthorId != userId) { var ex = new UnauthorizedAccessException("Not authorized to update this article"); activity?.SetStatus(ActivityStatusCode.Error, ex.Message); activity?.AddException(ex); throw ex; } // Update article... await _context.SaveChangesAsync(); return article; } catch (Exception ex) { activity?.SetStatus(ActivityStatusCode.Error, ex.Message); activity?.AddException(ex); throw; } } ``` #### Exception Extension Method Create a helper for consistent exception recording: ```csharp public static class ActivityExtensions { public static void RecordException(this Activity? activity, Exception ex, bool setError = true) { if (activity is null) return; if (setError) { activity.SetStatus(ActivityStatusCode.Error, ex.Message); } activity.AddException(ex); } } // Usage public async Task FetchDataAsync(int id) { using var activity = ActivitySource.StartActivity("data.fetch"); try { return await _repository.GetByIdAsync(id); } catch (Exception ex) { activity.RecordException(ex); throw; } } ``` #### Recording Without Throwing Record exceptions for logging without rethrowing: ```csharp public async Task ProcessWithFallbackAsync() { using var activity = ActivitySource.StartActivity("process.fallback"); try { await TryPrimaryMethodAsync(); } catch (Exception ex) { // Record but don't mark as error since we have a fallback activity?.AddEvent(new ActivityEvent( "primary.failed", tags: new ActivityTagsCollection { { "exception.type", ex.GetType().Name }, { "exception.message", ex.Message } })); _logger.LogWarning(ex, "Primary method failed, using fallback"); await UseFallbackMethodAsync(); } } ``` ### Metrics #### Setting Up Metrics Define metrics using `System.Diagnostics.Metrics`: ```csharp title="Telemetry/AppMetrics.cs" using System.Diagnostics.Metrics; namespace MyApp.Telemetry; public static class AppMetrics { private static readonly Meter Meter = new("MyApp.Metrics"); public static readonly Counter UsersRegistered = Meter.CreateCounter( "users.registered", description: "Total users registered"); public static readonly Counter ArticlesCreated = Meter.CreateCounter( "articles.created", description: "Total articles created"); public static readonly Counter OrdersProcessed = Meter.CreateCounter( "orders.processed", description: "Total orders processed"); public static readonly Histogram RequestDuration = Meter.CreateHistogram( "http.request.duration", unit: "ms", description: "HTTP request duration in milliseconds"); } ``` #### Counter Metrics Track counts of events: ```csharp public async Task RegisterUserAsync(RegisterRequest request) { var user = new User { Email = request.Email, Name = request.Name }; await _context.Users.AddAsync(user); await _context.SaveChangesAsync(); // Increment counter AppMetrics.UsersRegistered.Add(1); return user; } ``` #### Counter with Tags Add dimensions to metrics: ```csharp public async Task CreateOrderAsync(CreateOrderRequest request) { var order = await ProcessOrderAsync(request); // Counter with tags for dimensions AppMetrics.OrdersProcessed.Add(1, new KeyValuePair("order.type", request.Type), new KeyValuePair("payment.method", request.PaymentMethod)); return order; } ``` #### Histogram Metrics Record distributions of values: ```csharp public async Task HandleRequestAsync(Request request) { var stopwatch = Stopwatch.StartNew(); var response = await ProcessRequestAsync(request); stopwatch.Stop(); // Record duration AppMetrics.RequestDuration.Record( stopwatch.Elapsed.TotalMilliseconds, new KeyValuePair("http.route", request.Path), new KeyValuePair("http.method", request.Method)); return response; } ``` #### Observable Gauges Track current values that are observed periodically: ```csharp public static class AppMetrics { private static readonly Meter Meter = new("MyApp.Metrics"); private static int _activeConnections; public static readonly ObservableGauge ActiveConnections = Meter.CreateObservableGauge( "connections.active", () => _activeConnections, description: "Number of active connections"); public static void IncrementConnections() => Interlocked.Increment(ref _activeConnections); public static void DecrementConnections() => Interlocked.Decrement(ref _activeConnections); } ``` #### Business Metrics Track domain-specific metrics: ```csharp public static class BusinessMetrics { private static readonly Meter Meter = new("MyApp.Business"); public static readonly Counter Revenue = Meter.CreateCounter( "revenue.total", unit: "USD", description: "Total revenue in cents"); public static readonly Histogram OrderValue = Meter.CreateHistogram( "order.value", unit: "USD", description: "Order value distribution"); public static readonly Counter SubscriptionsCreated = Meter.CreateCounter( "subscriptions.created", description: "Total subscriptions created"); } // Usage public async Task CompleteOrderAsync(Order order) { await FinalizeOrderAsync(order); BusinessMetrics.Revenue.Add((long)(order.Total * 100)); // Convert to cents BusinessMetrics.OrderValue.Record(order.Total); return order; } ``` ### Context Propagation #### Propagating Context with HttpClient Context is automatically propagated when using `HttpClient` with instrumentation: ```csharp // In Program.cs builder.Services.AddHttpClient() .AddOpenTelemetry() .WithTracing(tracing => tracing .AddHttpClientInstrumentation()); // Enables automatic propagation ``` #### Manual Context Propagation For custom propagation scenarios: ```csharp using OpenTelemetry; using OpenTelemetry.Context.Propagation; using System.Diagnostics; public class ContextPropagator { private static readonly TextMapPropagator Propagator = Propagators.DefaultTextMapPropagator; public void InjectContext(IDictionary carrier) { Propagator.Inject( new PropagationContext(Activity.Current?.Context ?? default, Baggage.Current), carrier, (c, key, value) => c[key] = value); } public PropagationContext ExtractContext(IDictionary carrier) { return Propagator.Extract( default, carrier, (c, key) => c.TryGetValue(key, out var value) ? new[] { value } : Array.Empty()); } } ``` #### Using Baggage Propagate key-value pairs across service boundaries: ```csharp using OpenTelemetry; public async Task CreateOrderAsync(int userId, CreateOrderRequest request) { using var activity = ActivitySource.StartActivity("order.create"); // Set baggage for downstream services Baggage.SetBaggage("user.id", userId.ToString()); Baggage.SetBaggage("order.type", request.Type); var order = await ProcessOrderAsync(request); // Enqueue job - baggage will propagate await _jobQueue.EnqueueAsync("notification", new { OrderId = order.Id, Type = "order_created" }); return order; } // In downstream service public async Task HandleJobAsync(Job job) { // Read baggage from upstream var userId = Baggage.GetBaggage("user.id"); var orderType = Baggage.GetBaggage("order.type"); _logger.LogInformation("Processing job for user {UserId}, order type {OrderType}", userId, orderType); } ``` #### Message Queue Propagation Propagate context through message queues: ```csharp public class MessagePublisher { private static readonly ActivitySource ActivitySource = new("MyApp.Messaging"); private static readonly TextMapPropagator Propagator = Propagators.DefaultTextMapPropagator; public async Task PublishAsync(string topic, T message) { using var activity = ActivitySource.StartActivity( $"publish {topic}", ActivityKind.Producer); var headers = new Dictionary(); // Inject trace context into headers Propagator.Inject( new PropagationContext(activity?.Context ?? default, Baggage.Current), headers, (c, key, value) => c[key] = value); var envelope = new MessageEnvelope { Body = message, Headers = headers }; await _queue.SendAsync(topic, envelope); } } public class MessageConsumer { private static readonly ActivitySource ActivitySource = new("MyApp.Messaging"); private static readonly TextMapPropagator Propagator = Propagators.DefaultTextMapPropagator; public async Task ConsumeAsync(MessageEnvelope envelope) { // Extract trace context from headers var context = Propagator.Extract( default, envelope.Headers, (c, key) => c.TryGetValue(key, out var value) ? new[] { value } : Array.Empty()); using var activity = ActivitySource.StartActivity( "process message", ActivityKind.Consumer, context.ActivityContext); await ProcessMessageAsync(envelope.Body); } } ``` ### Best Practices #### 1. Use Descriptive Activity Names Follow a consistent naming convention: ```csharp // Good: domain.action format ActivitySource.StartActivity("user.create"); ActivitySource.StartActivity("order.process"); ActivitySource.StartActivity("payment.charge"); // Avoid: inconsistent naming ActivitySource.StartActivity("CreateUser"); ActivitySource.StartActivity("process_order"); ``` #### 2. Always Check for Null Activities Activities may be null if not sampled: ```csharp public async Task GetUserAsync(int id) { using var activity = ActivitySource.StartActivity("user.get"); activity?.SetTag("user.id", id); // Safe with null-conditional var user = await _repository.GetByIdAsync(id); activity?.SetTag("user.found", user is not null); return user; } ``` #### 3. Don't Log Sensitive Data Never include PII or secrets in spans: ```csharp public async Task AuthenticateAsync(string email, string password) { using var activity = ActivitySource.StartActivity("auth.login"); // Good: log email (consider if this is PII for your use case) activity?.SetTag("user.email", email); // Bad: never log passwords or tokens // activity?.SetTag("password", password); // DON'T DO THIS var user = await ValidateCredentialsAsync(email, password); activity?.SetTag("auth.success", user is not null); return user; } ``` #### 4. Use Appropriate Span Kinds Set the correct span kind for proper visualization: ```csharp // Server: handling incoming request ActivitySource.StartActivity("http.request", ActivityKind.Server); // Client: making outgoing request ActivitySource.StartActivity("http.call", ActivityKind.Client); // Producer: publishing to queue ActivitySource.StartActivity("queue.publish", ActivityKind.Producer); // Consumer: processing from queue ActivitySource.StartActivity("queue.process", ActivityKind.Consumer); ``` #### 5. Scope ActivitySource Appropriately Create ActivitySources per logical component: ```csharp // Good: separate ActivitySources for different concerns public class UserService { private static readonly ActivitySource Source = new("MyApp.UserService"); } public class OrderService { private static readonly ActivitySource Source = new("MyApp.OrderService"); } public class PaymentService { private static readonly ActivitySource Source = new("MyApp.PaymentService"); } ``` ### Complete Examples #### Full Service with Custom Instrumentation ```csharp title="Services/ArticleService.cs" using System.Diagnostics; using MyApp.Telemetry; public class ArticleService { private static readonly ActivitySource ActivitySource = new("MyApp.ArticleService"); private readonly AppDbContext _context; private readonly ILogger _logger; public ArticleService(AppDbContext context, ILogger logger) { _context = context; _logger = logger; } public async Task CreateAsync(int userId, CreateArticleRequest request) { using var activity = ActivitySource.StartActivity("article.create"); activity?.SetTag("user.id", userId); try { var article = new Article { Title = request.Title, Body = request.Body, AuthorId = userId, Slug = GenerateSlug(request.Title) }; _context.Articles.Add(article); await _context.SaveChangesAsync(); activity?.SetTag("article.id", article.Id); activity?.SetTag("article.slug", article.Slug); AppMetrics.ArticlesCreated.Add(1); _logger.LogInformation("Article created: {ArticleId} by user {UserId}", article.Id, userId); return ToResponse(article); } catch (Exception ex) { activity?.SetStatus(ActivityStatusCode.Error, ex.Message); activity?.AddException(ex); throw; } } public async Task GetBySlugAsync(string slug) { using var activity = ActivitySource.StartActivity("article.get"); activity?.SetTag("article.slug", slug); var article = await _context.Articles .Include(a => a.Author) .FirstOrDefaultAsync(a => a.Slug == slug); activity?.SetTag("article.found", article is not null); return article is not null ? ToResponse(article) : null; } } ``` #### Metrics Setup ```csharp title="Telemetry/AppMetrics.cs" using System.Diagnostics.Metrics; namespace MyApp.Telemetry; public static class AppMetrics { private static readonly Meter Meter = new("MyApp.Metrics"); public static readonly Counter UsersRegistered = Meter.CreateCounter("users.registered", description: "Total users registered"); public static readonly Counter ArticlesCreated = Meter.CreateCounter("articles.created", description: "Total articles created"); public static readonly Counter ArticlesUpdated = Meter.CreateCounter("articles.updated", description: "Total articles updated"); public static readonly Counter ArticlesDeleted = Meter.CreateCounter("articles.deleted", description: "Total articles deleted"); public static readonly Counter JobsEnqueued = Meter.CreateCounter("jobs.enqueued", description: "Total jobs enqueued"); public static readonly Counter JobsCompleted = Meter.CreateCounter("jobs.completed", description: "Total jobs completed"); public static readonly Counter JobsFailed = Meter.CreateCounter("jobs.failed", description: "Total jobs failed"); public static readonly Histogram RequestDuration = Meter.CreateHistogram("http.request.duration", unit: "ms", description: "HTTP request duration"); } ``` ### Extracting Trace and Span IDs Extract trace context for correlation or error responses: ```csharp public static class TraceContextHelper { public static (string? TraceId, string? SpanId) GetCurrentTraceIds() { var activity = Activity.Current; return ( activity?.TraceId.ToString(), activity?.SpanId.ToString() ); } } // Usage in error handling public class ExceptionMiddleware { public async Task InvokeAsync(HttpContext context, RequestDelegate next) { try { await next(context); } catch (Exception ex) { var (traceId, spanId) = TraceContextHelper.GetCurrentTraceIds(); var errorResponse = new { Error = ex.Message, TraceId = traceId, SpanId = spanId }; context.Response.StatusCode = 500; await context.Response.WriteAsJsonAsync(errorResponse); } } } ``` ### Proper Shutdown and Resource Cleanup Ensure telemetry is properly flushed on shutdown: ```csharp title="Program.cs" var builder = WebApplication.CreateBuilder(args); builder.AddTelemetry(); var app = builder.Build(); // Register shutdown handler var lifetime = app.Services.GetRequiredService(); lifetime.ApplicationStopping.Register(() => { // Give time for telemetry to flush Thread.Sleep(TimeSpan.FromSeconds(5)); }); app.Run(); ``` For more control, use the TracerProvider directly: ```csharp public class TelemetryService : IHostedService { private readonly TracerProvider _tracerProvider; public TelemetryService(TracerProvider tracerProvider) { _tracerProvider = tracerProvider; } public Task StartAsync(CancellationToken cancellationToken) => Task.CompletedTask; public Task StopAsync(CancellationToken cancellationToken) { // Flush and shutdown _tracerProvider.ForceFlush(); _tracerProvider.Shutdown(); return Task.CompletedTask; } } ``` ### Database Instrumentation Patterns #### Entity Framework Core EF Core is automatically instrumented. Add custom spans for business operations: ```csharp public async Task CreateUserWithProfileAsync(CreateUserRequest request) { using var activity = ActivitySource.StartActivity("user.create_with_profile"); await using var transaction = await _context.Database.BeginTransactionAsync(); try { activity?.AddEvent(new ActivityEvent("creating_user")); var user = new User { Email = request.Email, Name = request.Name }; _context.Users.Add(user); await _context.SaveChangesAsync(); activity?.AddEvent(new ActivityEvent("creating_profile")); var profile = new UserProfile { UserId = user.Id, Bio = request.Bio }; _context.UserProfiles.Add(profile); await _context.SaveChangesAsync(); await transaction.CommitAsync(); activity?.SetTag("user.id", user.Id); return user; } catch (Exception ex) { await transaction.RollbackAsync(); activity?.SetStatus(ActivityStatusCode.Error, ex.Message); activity?.AddException(ex); throw; } } ``` #### Raw SQL with SqlClient For raw SQL operations: ```csharp public async Task ExecuteCustomQueryAsync(string query, params SqlParameter[] parameters) { using var activity = ActivitySource.StartActivity("db.execute", ActivityKind.Client); activity?.SetTag("db.system", "mssql"); activity?.SetTag("db.statement", query); await using var connection = new SqlConnection(_connectionString); await connection.OpenAsync(); await using var command = new SqlCommand(query, connection); command.Parameters.AddRange(parameters); var result = await command.ExecuteNonQueryAsync(); activity?.SetTag("db.rows_affected", result); return result; } ``` ### References - [OpenTelemetry .NET Documentation](https://opentelemetry.io/docs/languages/net/) - [System.Diagnostics.Activity Documentation](https://learn.microsoft.com/en-us/dotnet/api/system.diagnostics.activity) - [System.Diagnostics.Metrics Documentation](https://learn.microsoft.com/en-us/dotnet/api/system.diagnostics.metrics) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [ASP.NET Core Auto-Instrumentation Guide](../auto-instrumentation/dotnet.md) - [Creating Alerts with LogX](../../../guides/creating-alerts-with-logx.md) - [Create Your First Dashboard](../../../guides/create-your-first-dashboard.md) --- ## Go OpenTelemetry Custom Instrumentation - Spans & Metrics Guide ## Go Implement OpenTelemetry custom instrumentation for Go applications to collect traces, metrics, and logs using the Go OpenTelemetry SDK. This guide covers manual instrumentation for any Go application, including Gin, Echo, Chi, gRPC, and custom frameworks. > **Note:** This guide provides a practical overview based on the official > OpenTelemetry documentation. For complete information, please consult the > [official OpenTelemetry Go documentation](https://opentelemetry.io/docs/languages/go/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry SDK for manual instrumentation - Create and manage custom spans - Add attributes, events, and exception tracking - Implement metrics collection - Propagate context across service boundaries - Instrument common Go patterns and frameworks > 📦 **Complete Working Examples**: This guide includes code snippets for > learning. For full implementations, see the [Complete Examples](#complete-examples) > section featuring Gin + PostgreSQL and Chi router applications. ### Prerequisites Before starting, ensure you have: - **Go 1.21 or later** installed (Go 1.24+ recommended for forward compatibility) - A Go project initialized with `go mod init` - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) > ⚠️ **Signal Stability Status** (as of 2025): > > - **Traces**: Stable ✅ > - **Metrics**: Stable ✅ > - **Logs**: Beta (API may change before reaching stable status) ### Required Packages Install the OpenTelemetry SDK and necessary packages: ```bash showLineNumbers go get go.opentelemetry.io/otel \ go.opentelemetry.io/otel/trace \ go.opentelemetry.io/otel/sdk \ go.opentelemetry.io/otel/metric \ go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp \ go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp \ go.opentelemetry.io/otel/sdk/metric \ go.opentelemetry.io/otel/sdk/resource \ go.opentelemetry.io/otel/sdk/trace \ go.opentelemetry.io/otel/semconv/v1.37.0 ``` ### Traces Traces provide a complete picture of request flows through your application, from initial request to final response, including all operations and services involved. #### Initialization Initialize the OpenTelemetry SDK with resource information and exporters: ```go showLineNumbers title="telemetry.go" package main import ( "context" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp" "go.opentelemetry.io/otel/sdk/resource" sdktrace "go.opentelemetry.io/otel/sdk/trace" semconv "go.opentelemetry.io/otel/semconv/v1.37.0" "go.opentelemetry.io/otel/trace" ) func setupTracing(ctx context.Context) (trace.Tracer, error) { // Create resource with service information res, err := resource.Merge(resource.Default(), resource.NewWithAttributes(semconv.SchemaURL, semconv.ServiceName("my-go-app"), semconv.ServiceVersion("1.0.0"), semconv.DeploymentEnvironment("production"), )) if err != nil { return nil, err } // Create OTLP trace exporter // Uses OTEL_EXPORTER_OTLP_ENDPOINT environment variable traceExporter, err := otlptracehttp.New(ctx) if err != nil { return nil, err } // Create tracer provider tracerProvider := sdktrace.NewTracerProvider( sdktrace.WithBatcher(traceExporter), sdktrace.WithResource(res), ) // Set global tracer provider otel.SetTracerProvider(tracerProvider) // Create and return tracer tracer := otel.Tracer("my-go-app", trace.WithInstrumentationVersion("1.0.0")) return tracer, nil } ``` > **Note**: Set the `OTEL_EXPORTER_OTLP_ENDPOINT` environment variable to your > Scout Collector endpoint (e.g., `http://localhost:4318`). Ensure your Scout > Collector is properly configured to receive trace data. #### Creating Spans Create a span to track an operation: ```go showLineNumbers func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span.name") defer span.End() // do some work that 'span' tracks fmt.Println("doing some work...") } ``` #### Creating Nested Spans Create parent-child span relationships: ```go showLineNumbers func doWork(ctx context.Context, tracer trace.Tracer) { ctx, parent := tracer.Start(ctx, "parent") defer parent.End() // do some work that 'parent' tracks fmt.Println("doing some work...") // Create a nested span to track nested work _, child := tracer.Start(ctx, "child") defer child.End() // do some work that 'child' tracks fmt.Println("doing some nested work...") } ``` #### Helper Methods for Cleaner Code ```go showLineNumbers func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span") defer span.End() fmt.Println("doing some work...") } // Helper function that automatically creates and manages spans func withSpan(ctx context.Context, tracer trace.Tracer, name string, fn func(context.Context)) { ctx, span := tracer.Start(ctx, name) defer span.End() fn(ctx) } // Usage withSpan(ctx, tracer, "work.operation", func(ctx context.Context) { fmt.Println("doing some work...") }) ``` ### Attributes Attributes add context to spans as key-value pairs: #### Adding Custom Attributes ```go showLineNumbers import "go.opentelemetry.io/otel/attribute" func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span.name") defer span.End() span.SetAttributes( attribute.Int("operation.value", 1), attribute.String("operation.name", "Saying hello!"), attribute.StringSlice("operation.other-stuff", []string{"1", "2", "3"}), ) fmt.Println("doing some work...") } ``` #### Using Semantic Conventions Use standardized attribute names for common operations: ```go showLineNumbers import semconv "go.opentelemetry.io/otel/semconv/v1.37.0" func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span.name") defer span.End() span.SetAttributes( semconv.HTTPRequestMethodOriginal("GET"), semconv.URLFull("https://base14.io/"), semconv.HTTPResponseStatusCode(200), ) fmt.Println("doing some work...") } ``` ### Events Events mark significant moments during a span's lifetime: #### Adding Events to a Span ```go showLineNumbers func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span.name") defer span.End() span.AddEvent("Starting some work") fmt.Println("doing some work...") span.AddEvent("Finished working") } ``` #### Adding Events with Attributes ```go showLineNumbers import "go.opentelemetry.io/otel/attribute" func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span.name") defer span.End() span.AddEvent("Processing request", trace.WithAttributes( attribute.String("user.id", "12345"), attribute.String("request.type", "api"), )) fmt.Println("doing some work...") } ``` ### Exception Recording Capture and record exceptions in spans: ```go showLineNumbers import ( "go.opentelemetry.io/otel/codes" "go.opentelemetry.io/otel/attribute" ) func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "span.name") defer span.End() // Simulate work that might fail if err := someOperation(); err != nil { span.SetStatus(codes.Error, "Operation failed") span.RecordError(err, trace.WithAttributes( attribute.String("error.type", "operation_error"), )) return } // Explicitly mark as successful (optional) span.SetStatus(codes.Ok, "Operation completed successfully") } func someOperation() error { // simulate an operation that might fail return nil } ``` ### Metrics Collect custom metrics to track application performance: #### Initialization Initialize the MeterProvider with metric exporters: ```go showLineNumbers title="metrics.go" import ( "context" "time" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp" "go.opentelemetry.io/otel/metric" "go.opentelemetry.io/otel/sdk/resource" sdkmetric "go.opentelemetry.io/otel/sdk/metric" semconv "go.opentelemetry.io/otel/semconv/v1.37.0" ) func setupMetrics(ctx context.Context) (metric.Meter, error) { // Create resource res, err := resource.Merge(resource.Default(), resource.NewWithAttributes(semconv.SchemaURL, semconv.ServiceName("my-go-app"), semconv.ServiceVersion("1.0.0"), )) if err != nil { return nil, err } // Create OTLP metric exporter // Uses OTEL_EXPORTER_OTLP_ENDPOINT environment variable metricExporter, err := otlpmetrichttp.New(ctx) if err != nil { return nil, err } // Create meter provider meterProvider := sdkmetric.NewMeterProvider( sdkmetric.WithResource(res), sdkmetric.WithReader(sdkmetric.NewPeriodicReader(metricExporter, sdkmetric.WithInterval(5*time.Second), )), ) // Set global meter provider otel.SetMeterProvider(meterProvider) // Create and return meter meter := otel.Meter("my-go-app", metric.WithInstrumentationVersion("1.0.0")) return meter, nil } ``` > **Note**: The exporter uses the `OTEL_EXPORTER_OTLP_ENDPOINT` environment > variable. Ensure your Scout Collector is properly configured to receive metric > data. #### Counter Track cumulative values that only increase: ##### Creating a Synchronous Counter ```go showLineNumbers import "go.opentelemetry.io/otel/attribute" func setupCounter(meter metric.Meter) (metric.Int64Counter, error) { workCounter, err := meter.Int64Counter( "work.counter", metric.WithDescription("Counts the amount of work done"), metric.WithUnit("1"), ) return workCounter, err } func doWork(ctx context.Context, counter metric.Int64Counter, workType string) { counter.Add(ctx, 1, metric.WithAttributes( attribute.String("work.type", workType), )) fmt.Println("doing some work...") } ``` ##### Creating Asynchronous Counter ```go showLineNumbers func setupAsyncCounter(meter metric.Meter) error { counter, err := meter.Int64ObservableCounter( "process.page.faults", metric.WithDescription("Process page faults"), metric.WithUnit("faults"), ) if err != nil { return err } // Register callback _, err = meter.RegisterCallback( func(ctx context.Context, o metric.Observer) error { // Simulate getting process stats o.ObserveInt64(counter, 8, metric.WithAttributes( attribute.Int("pid", 0), attribute.Int("bitness", 64), )) o.ObserveInt64(counter, 37741921, metric.WithAttributes( attribute.Int("pid", 4), attribute.Int("bitness", 64), )) o.ObserveInt64(counter, 10465, metric.WithAttributes( attribute.Int("pid", 880), attribute.Int("bitness", 32), )) return nil }, counter, ) return err } ``` #### Histogram Record distributions of values: ##### Creating a Histogram ```go showLineNumbers import ( "time" "go.opentelemetry.io/otel/attribute" semconv "go.opentelemetry.io/otel/semconv/v1.37.0" ) func setupHistogram(meter metric.Meter) (metric.Int64Histogram, error) { httpServerDuration, err := meter.Int64Histogram( "http.server.duration", metric.WithDescription("measures the duration of the inbound HTTP request"), metric.WithUnit("ms"), ) return httpServerDuration, err } func recordDuration(ctx context.Context, histogram metric.Int64Histogram, duration int64, method, scheme string) { histogram.Record(ctx, duration, metric.WithAttributes( semconv.HTTPRequestMethodOriginal(method), semconv.URLScheme(scheme), )) } // Usage example func handleRequest(ctx context.Context, histogram metric.Int64Histogram) { start := time.Now() // Handle request logic here... duration := time.Since(start).Milliseconds() recordDuration(ctx, histogram, duration, "POST", "https") } ``` #### Gauge Track values that can increase or decrease: ##### Creating an Observable Gauge ```go showLineNumbers func setupGauge(meter metric.Meter) error { gauge, err := meter.Int64ObservableGauge( "system.cpu.usage", metric.WithDescription("Current CPU usage percentage"), metric.WithUnit("%"), ) if err != nil { return err } // Register callback to observe current CPU usage _, err = meter.RegisterCallback( func(ctx context.Context, o metric.Observer) error { // Get current CPU usage (simulated) cpuUsage := getCurrentCPUUsage() o.ObserveInt64(gauge, cpuUsage, metric.WithAttributes( attribute.String("cpu.core", "0"), )) return nil }, gauge, ) return err } func getCurrentCPUUsage() int64 { // Simulate getting CPU usage return 75 // 75% CPU usage } ``` ### Context Propagation Propagate trace context across HTTP requests to maintain distributed traces: #### Outgoing HTTP Requests ```go showLineNumbers import ( "net/http" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/propagation" ) func makeExternalRequest(ctx context.Context, tracer trace.Tracer, url string) error { ctx, span := tracer.Start(ctx, "external-api-call") defer span.End() req, err := http.NewRequestWithContext(ctx, "GET", url, nil) if err != nil { return err } // Inject trace context into HTTP headers otel.GetTextMapPropagator().Inject(ctx, propagation.HeaderCarrier(req.Header)) client := &http.Client{} resp, err := client.Do(req) if err != nil { span.RecordError(err) return err } defer resp.Body.Close() span.SetAttributes(attribute.Int("http.status_code", resp.StatusCode)) return nil } ``` #### Incoming HTTP Requests ```go showLineNumbers func handleRequest(w http.ResponseWriter, r *http.Request, tracer trace.Tracer) { // Extract context from incoming request headers ctx := otel.GetTextMapPropagator().Extract(r.Context(), propagation.HeaderCarrier(r.Header)) // Start span with extracted context ctx, span := tracer.Start(ctx, "handle-request") defer span.End() span.SetAttributes( attribute.String("http.method", r.Method), attribute.String("http.url", r.URL.Path), ) // Process request with propagated context processRequest(ctx) span.SetAttributes(attribute.Int("http.status_code", 200)) w.WriteHeader(http.StatusOK) } ``` ### Framework-Specific Examples #### Gin Web Framework ```go showLineNumbers title="gin_example.go" import ( "github.com/gin-gonic/gin" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/propagation" ) func main() { tracer := otel.Tracer("gin-app") router := gin.Default() // Middleware to extract and propagate context router.Use(func(c *gin.Context) { ctx := otel.GetTextMapPropagator().Extract(c.Request.Context(), propagation.HeaderCarrier(c.Request.Header)) ctx, span := tracer.Start(ctx, c.Request.Method+" "+c.FullPath()) defer span.End() span.SetAttributes( attribute.String("http.method", c.Request.Method), attribute.String("http.route", c.FullPath()), ) c.Request = c.Request.WithContext(ctx) c.Next() span.SetAttributes(attribute.Int("http.status_code", c.Writer.Status())) }) router.GET("/users/:id", func(c *gin.Context) { ctx := c.Request.Context() _, span := tracer.Start(ctx, "get-user") defer span.End() userID := c.Param("id") span.SetAttributes(attribute.String("user.id", userID)) // Fetch user logic here c.JSON(200, gin.H{"id": userID, "name": "John Doe"}) }) router.Run(":8080") } ``` > 💡 **Complete Gin Example**: For a production-ready Gin application with > database instrumentation, structured logging, and Docker deployment, see the > [go119-gin191-postgres example](https://github.com/base-14/examples/tree/main/go/go119-gin191-postgres). #### Echo Web Framework ```go showLineNumbers title="echo_example.go" import ( "github.com/labstack/echo/v4" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/propagation" ) func main() { tracer := otel.Tracer("echo-app") e := echo.New() // Middleware e.Use(func(next echo.HandlerFunc) echo.HandlerFunc { return func(c echo.Context) error { ctx := otel.GetTextMapPropagator().Extract(c.Request().Context(), propagation.HeaderCarrier(c.Request().Header)) ctx, span := tracer.Start(ctx, c.Request().Method+" "+c.Path()) defer span.End() span.SetAttributes( attribute.String("http.method", c.Request().Method), attribute.String("http.route", c.Path()), ) c.SetRequest(c.Request().WithContext(ctx)) err := next(c) span.SetAttributes(attribute.Int("http.status_code", c.Response().Status)) return err } }) e.GET("/users/:id", func(c echo.Context) error { ctx := c.Request().Context() _, span := tracer.Start(ctx, "get-user") defer span.End() userID := c.Param("id") span.SetAttributes(attribute.String("user.id", userID)) return c.JSON(200, map[string]string{"id": userID, "name": "Jane Doe"}) }) e.Start(":8080") } ``` #### gRPC Server ```go showLineNumbers title="grpc_server.go" import ( "context" "google.golang.org/grpc" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" ) func UnaryServerInterceptor(tracer trace.Tracer) grpc.UnaryServerInterceptor { return func(ctx context.Context, req interface{}, info *grpc.UnaryServerInfo, handler grpc.UnaryHandler) (interface{}, error) { ctx, span := tracer.Start(ctx, info.FullMethod) defer span.End() span.SetAttributes( attribute.String("rpc.system", "grpc"), attribute.String("rpc.method", info.FullMethod), ) resp, err := handler(ctx, req) if err != nil { span.RecordError(err) span.SetStatus(codes.Error, err.Error()) } return resp, err } } ``` #### Plain HTTP Server ```go showLineNumbers title="http_server.go" import ( "net/http" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/propagation" ) func main() { tracer := otel.Tracer("http-server") http.HandleFunc("/", func(w http.ResponseWriter, r *http.Request) { ctx := otel.GetTextMapPropagator().Extract(r.Context(), propagation.HeaderCarrier(r.Header)) ctx, span := tracer.Start(ctx, r.Method+" "+r.URL.Path) defer span.End() span.SetAttributes( attribute.String("http.method", r.Method), attribute.String("http.url", r.URL.Path), ) // Business logic w.WriteHeader(http.StatusOK) w.Write([]byte("Hello, World!")) span.SetAttributes(attribute.Int("http.status_code", http.StatusOK)) }) http.ListenAndServe(":8080", nil) } ``` ### Best Practices #### 1. Always End Spans ```go // Good - using defer ctx, span := tracer.Start(ctx, "operation") defer span.End() doWork(ctx) // Bad - span may not end if panic occurs ctx, span := tracer.Start(ctx, "operation") doWork(ctx) span.End() ``` #### 2. Use Descriptive Span Names ```go // Good ctx, span := tracer.Start(ctx, "UserRepository.FindByID") ctx, span := tracer.Start(ctx, "PaymentService.ProcessPayment") // Bad ctx, span := tracer.Start(ctx, "operation") ctx, span := tracer.Start(ctx, "query") ``` #### 3. Add Relevant Attributes ```go // Good span.SetAttributes( attribute.String("user.id", userID), attribute.Float64("order.amount", amount), attribute.Bool("cache.hit", true), ) // Bad - sensitive data span.SetAttributes( attribute.String("user.password", password), // Never! attribute.String("credit.card.number", ccNumber), // Never! ) ``` #### 4. Use Semantic Conventions ```go // Good - using semantic conventions import semconv "go.opentelemetry.io/otel/semconv/v1.37.0" span.SetAttributes( semconv.HTTPRequestMethodOriginal("POST"), semconv.DBSystemPostgreSQL, semconv.DBNamespace("production"), ) ``` #### 5. Handle Errors Properly ```go // Good ctx, span := tracer.Start(ctx, "risky-operation") defer span.End() if err := riskyOperation(); err != nil { span.RecordError(err) span.SetStatus(codes.Error, err.Error()) return err } span.SetStatus(codes.Ok, "") // Bad - swallowing errors if err := riskyOperation(); err != nil { // Error lost } ``` ### Complete Example Here's a complete example of a Go application with custom instrumentation: ```go showLineNumbers title="main.go" package main import ( "context" "fmt" "log" "time" "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/codes" "go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp" "go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp" "go.opentelemetry.io/otel/metric" "go.opentelemetry.io/otel/sdk/resource" sdkmetric "go.opentelemetry.io/otel/sdk/metric" sdktrace "go.opentelemetry.io/otel/sdk/trace" semconv "go.opentelemetry.io/otel/semconv/v1.37.0" "go.opentelemetry.io/otel/trace" ) var ( tracer trace.Tracer meter metric.Meter requestCounter metric.Int64Counter requestDuration metric.Int64Histogram ) func initTelemetry(ctx context.Context) error { // Create resource res, err := resource.Merge(resource.Default(), resource.NewWithAttributes(semconv.SchemaURL, semconv.ServiceName("my-go-app"), semconv.ServiceVersion("1.0.0"), )) if err != nil { return err } // Setup traces // Uses OTEL_EXPORTER_OTLP_ENDPOINT environment variable traceExporter, err := otlptracehttp.New(ctx) if err != nil { return err } tracerProvider := sdktrace.NewTracerProvider( sdktrace.WithBatcher(traceExporter), sdktrace.WithResource(res), ) otel.SetTracerProvider(tracerProvider) // Setup metrics // Uses OTEL_EXPORTER_OTLP_ENDPOINT environment variable metricExporter, err := otlpmetrichttp.New(ctx) if err != nil { return err } meterProvider := sdkmetric.NewMeterProvider( sdkmetric.WithResource(res), sdkmetric.WithReader(sdkmetric.NewPeriodicReader(metricExporter, sdkmetric.WithInterval(5*time.Second), )), ) otel.SetMeterProvider(meterProvider) // Create tracer and meter tracer = otel.Tracer("my-go-app") meter = otel.Meter("my-go-app") // Create metrics requestCounter, err = meter.Int64Counter( "requests.total", metric.WithDescription("Total requests"), metric.WithUnit("requests"), ) if err != nil { return err } requestDuration, err = meter.Int64Histogram( "requests.duration", metric.WithDescription("Request duration"), metric.WithUnit("ms"), ) if err != nil { return err } return nil } func processRequest(ctx context.Context) { start := time.Now() ctx, span := tracer.Start(ctx, "http.request") defer span.End() span.SetAttributes( attribute.String("http.method", "POST"), attribute.String("http.url", "/api/orders"), ) // Business logic if err := createOrder(ctx); err != nil { span.RecordError(err) span.SetStatus(codes.Error, err.Error()) recordMetrics(500, start) return } span.SetAttributes(attribute.Int("http.status_code", 201)) span.SetStatus(codes.Ok, "") recordMetrics(201, start) } func createOrder(ctx context.Context) error { ctx, span := tracer.Start(ctx, "create_order") defer span.End() // Simulate order creation orderID := 12345 span.SetAttributes( attribute.Int("order.id", orderID), attribute.Float64("order.total", 99.99), ) fmt.Printf("Order created: %d\n", orderID) return nil } func recordMetrics(statusCode int, startTime time.Time) { duration := time.Since(startTime).Milliseconds() attrs := metric.WithAttributes( attribute.Int("status", statusCode), ) requestCounter.Add(context.Background(), 1, attrs) requestDuration.Record(context.Background(), duration, attrs) } func main() { ctx := context.Background() if err := initTelemetry(ctx); err != nil { log.Fatalf("Failed to initialize telemetry: %v", err) } // Process request processRequest(ctx) // Allow time for export time.Sleep(2 * time.Second) } ``` ### Extracting Trace and Span IDs Extract trace ID and span ID for log correlation: ```go showLineNumbers import "go.opentelemetry.io/otel/trace" func getTraceAndSpanIDs(ctx context.Context) (string, string) { span := trace.SpanFromContext(ctx) if span.SpanContext().IsValid() { traceID := span.SpanContext().TraceID().String() spanID := span.SpanContext().SpanID().String() return traceID, spanID } return "", "" } // Usage with logging func doWork(ctx context.Context, tracer trace.Tracer) { ctx, span := tracer.Start(ctx, "work.operation") defer span.End() traceID, spanID := getTraceAndSpanIDs(ctx) // Use for structured logging log.Printf("Processing request - TraceID: %s, SpanID: %s", traceID, spanID) performWork(ctx) } ``` ### Proper Shutdown and Resource Cleanup Always ensure proper cleanup of telemetry resources to flush all pending spans and metrics before application exit. This is critical for preventing data loss. #### Shutdown Pattern ```go showLineNumbers title="main.go" package main import ( "context" "errors" "log" "os" "os/signal" ) func main() { ctx := context.Background() // Setup OpenTelemetry shutdown, err := setupOTelSDK(ctx) if err != nil { log.Fatal(err) } // Ensure all spans and metrics are flushed before exit defer func() { if err := shutdown(ctx); err != nil { log.Printf("Error during shutdown: %v", err) } }() // Handle graceful shutdown on interrupt sigCh := make(chan os.Signal, 1) signal.Notify(sigCh, os.Interrupt) go func() { <-sigCh log.Println("Received interrupt signal, shutting down...") if err := shutdown(ctx); err != nil { log.Printf("Error during graceful shutdown: %v", err) } os.Exit(0) }() // Your application code... log.Println("Application running...") } func setupOTelSDK(ctx context.Context) (func(context.Context) error, error) { var shutdownFuncs []func(context.Context) error // Setup trace provider tracerProvider, err := setupTracing(ctx) if err != nil { return nil, err } shutdownFuncs = append(shutdownFuncs, tracerProvider.Shutdown) // Setup meter provider meterProvider, err := setupMetrics(ctx) if err != nil { return nil, err } shutdownFuncs = append(shutdownFuncs, meterProvider.Shutdown) // Return combined shutdown function shutdown := func(ctx context.Context) error { var err error for _, fn := range shutdownFuncs { err = errors.Join(err, fn(ctx)) } return err } return shutdown, nil } ``` #### Why Shutdown Matters Without proper shutdown: - **Span Loss**: Batched spans may not be exported - **Metric Loss**: Periodic metric readings may be missed - **Resource Leaks**: Exporters and connections remain open - **Incomplete Traces**: Distributed traces may appear broken #### Shutdown with Timeout For production applications, add a timeout to prevent hanging: ```go showLineNumbers func gracefulShutdown(shutdown func(context.Context) error) { ctx, cancel := context.WithTimeout( context.Background(), 5*time.Second, ) defer cancel() if err := shutdown(ctx); err != nil { log.Printf("Failed to shutdown cleanly: %v", err) } } ``` ### Complete Examples For production-ready reference implementations, explore our complete example applications: #### Go 1.19 + Gin + PostgreSQL Example A complete REST API demonstrating OpenTelemetry instrumentation with older Go versions: **[go119-gin191-postgres](https://github.com/base-14/examples/tree/main/go/go119-gin191-postgres)** **Stack:** - Go 1.19.13 with OpenTelemetry v1.17.0 - Gin Framework v1.9.1 for HTTP routing - PostgreSQL 14 with GORM ORM - Custom GORM tracing implementation - Logrus with trace correlation - Docker Compose setup **What's Instrumented:** - ✅ HTTP requests and responses (Gin middleware) - ✅ Database queries with custom GORM callbacks - ✅ SQL operations (INSERT, SELECT, UPDATE, DELETE) - ✅ Structured JSON logs with trace correlation - ✅ Graceful shutdown handling - ✅ Distributed trace propagation **Key Features:** - **Custom GORM Tracing**: Demonstrates how to instrument GORM without external plugins, compatible with older OpenTelemetry versions - **Log Correlation**: Shows how to extract trace IDs and span IDs for structured logging with Logrus - **Production Configuration**: Includes resource attributes, batch span processor, and OTLP exporter setup - **Docker Deployment**: Complete docker-compose.yml with app, database, and OTel collector **Implementation Highlights:** ```go // Custom GORM callback tracing (internal/database/tracing.go) func (g *gormTracer) before(operation string) func(*gorm.DB) { return func(db *gorm.DB) { ctx, span := tracer.Start( db.Statement.Context, operation, trace.WithSpanKind(trace.SpanKindClient), trace.WithAttributes( attribute.String("db.system", "postgresql"), attribute.String("db.name", db.Statement.Table), ), ) db.Statement.Context = ctx db.InstanceSet("otel:span", span) } } // Log correlation (internal/logging/logger.go) func WithContext(ctx context.Context) *logrus.Entry { spanCtx := trace.SpanContextFromContext(ctx) fields := logrus.Fields{ "service.name": os.Getenv("OTEL_SERVICE_NAME"), } if spanCtx.IsValid() { fields["trace_id"] = spanCtx.TraceID().String() fields["span_id"] = spanCtx.SpanID().String() } return log.WithFields(fields) } ``` **Quick Start:** ```bash cd examples/go/go119-gin191-postgres docker compose up --build curl http://localhost:8080/api/users ``` #### Go 1.25 + Chi + In-Memory Example **[chi-inmemory](https://github.com/base-14/examples/tree/main/go/chi-inmemory)** A modern Go application showcasing the latest OpenTelemetry features: **Stack:** - Go 1.25 (latest) with OpenTelemetry v1.38.0 - Chi router for lightweight HTTP routing - In-memory storage (no external database) - Native OpenTelemetry instrumentation - Docker Compose setup **What's Instrumented:** - ✅ HTTP request tracing with Chi middleware - ✅ Custom business logic spans - ✅ Context propagation across handlers - ✅ Metrics collection (request duration, counts) - ✅ Error recording and status codes **Key Features:** - **Modern Go Patterns**: Demonstrates latest Go 1.25 features and OpenTelemetry v1.38.0 - **Lightweight Setup**: No database dependencies, focuses on HTTP instrumentation - **Custom Middleware**: Shows how to build Chi middleware with OpenTelemetry - **Metrics Export**: Includes both traces and metrics with OTLP **Implementation Highlights:** ```go // Chi middleware with OpenTelemetry func TracingMiddleware( tracer trace.Tracer, ) func(http.Handler) http.Handler { return func(next http.Handler) http.Handler { return http.HandlerFunc( func(w http.ResponseWriter, r *http.Request) { ctx, span := tracer.Start( r.Context(), r.Method+" "+r.URL.Path, trace.WithSpanKind(trace.SpanKindServer), ) defer span.End() span.SetAttributes( attribute.String("http.method", r.Method), attribute.String("http.route", r.URL.Path), ) next.ServeHTTP(w, r.WithContext(ctx)) span.SetAttributes( attribute.Int("http.status_code", w.StatusCode), ) }) } } ``` **Quick Start:** ```bash cd examples/go/chi-inmemory docker compose up --build curl http://localhost:8080/api/health ``` #### Example Comparison | Feature | go119-gin191-postgres | chi-inmemory | |---------|----------------------|-----------------| | **Go Version** | 1.19.13 (EOL) | 1.25 (Latest) | | **Framework** | Gin 1.9.1 | Chi (latest) | | **Database** | PostgreSQL + GORM | In-memory | | **OTel Version** | v1.17.0 | v1.38.0 | | **Custom Tracing** | GORM callbacks | Chi middleware | | **Log Correlation** | ✅ Logrus | Basic logging | | **Use Case** | Legacy migrations | Modern greenfield | #### Using These Examples **For Learning:** 1. Clone the examples repository 2. Start with `chi-inmemory` for modern patterns 3. Study `go119-gin191-postgres` for database instrumentation **For Production:** 1. Use `go119-gin191-postgres` as reference for: - Custom ORM tracing patterns - Log correlation implementation - Graceful shutdown handling 2. Use `chi-inmemory` as reference for: - Modern Go instrumentation - Lightweight HTTP services - Metrics collection **For Migrations:** - If upgrading from Go 1.19: Compare both examples to see API changes - If adding observability to existing apps: Start with framework-specific patterns from these examples ### Database Instrumentation Patterns #### GORM Custom Tracing For applications using GORM, implement custom callbacks for comprehensive database tracing: ```go showLineNumbers title="database/tracing.go" package database import ( "go.opentelemetry.io/otel" "go.opentelemetry.io/otel/attribute" "go.opentelemetry.io/otel/codes" "go.opentelemetry.io/otel/trace" "gorm.io/gorm" ) var tracer = otel.Tracer("gorm") // RegisterCallbacks registers GORM callbacks for all CRUD operations func RegisterCallbacks(db *gorm.DB) error { callbacks := &gormTracer{} // Register before/after callbacks for each operation operations := []string{"create", "query", "update", "delete"} for _, op := range operations { if err := db.Callback().Create().Before("gorm:"+op). Register("otel:before", callbacks.before("gorm:"+op)); err != nil { return err } if err := db.Callback().Create().After("gorm:"+op). Register("otel:after", callbacks.after()); err != nil { return err } } return nil } type gormTracer struct{} func (g *gormTracer) before(operation string) func(*gorm.DB) { return func(db *gorm.DB) { ctx := db.Statement.Context if ctx == nil { return } ctx, span := tracer.Start(ctx, operation, trace.WithSpanKind(trace.SpanKindClient), trace.WithAttributes( attribute.String("db.system", "postgresql"), attribute.String("db.name", db.Statement.Table), ), ) db.Statement.Context = ctx db.InstanceSet("otel:span", span) } } func (g *gormTracer) after() func(*gorm.DB) { return func(db *gorm.DB) { spanInterface, ok := db.InstanceGet("otel:span") if !ok { return } span := spanInterface.(trace.Span) defer span.End() // Add SQL query details if db.Statement.SQL.String() != "" { span.SetAttributes( attribute.String("db.statement", db.Statement.SQL.String()), ) } span.SetAttributes( attribute.Int64("db.rows_affected", db.Statement.RowsAffected), attribute.String("db.sql.table", db.Statement.Table), ) // Record errors if db.Error != nil && db.Error != gorm.ErrRecordNotFound { span.RecordError(db.Error) span.SetStatus(codes.Error, db.Error.Error()) } else { span.SetStatus(codes.Ok, "") } } } ``` **See the complete implementation:** [go119-gin191-postgres/internal/database/tracing.go](https://github.com/base-14/examples/blob/main/go/go119-gin191-postgres/internal/database/tracing.go) #### Structured Logging with Trace Correlation Integrate OpenTelemetry trace context with structured logging: ```go showLineNumbers title="logging/logger.go" package logging import ( "context" "os" "github.com/sirupsen/logrus" "go.opentelemetry.io/otel/trace" ) var log = logrus.New() func init() { log.SetFormatter(&logrus.JSONFormatter{}) log.SetOutput(os.Stdout) log.SetLevel(logrus.InfoLevel) } // WithContext creates a log entry with trace correlation func WithContext(ctx context.Context) *logrus.Entry { spanCtx := trace.SpanContextFromContext(ctx) fields := logrus.Fields{ "service.name": os.Getenv("OTEL_SERVICE_NAME"), } if spanCtx.IsValid() { fields["trace_id"] = spanCtx.TraceID().String() fields["span_id"] = spanCtx.SpanID().String() fields["trace_flags"] = spanCtx.TraceFlags().String() } return log.WithFields(fields) } // WithFields creates a log entry with custom fields and trace correlation func WithFields(ctx context.Context, fields map[string]interface{}) *logrus.Entry { entry := WithContext(ctx) return entry.WithFields(fields) } // Usage in handlers func CreateUser(ctx context.Context, user User) error { logging.WithContext(ctx).Info("Creating user in database") if err := db.Create(&user).Error; err != nil { logging.WithFields(ctx, map[string]interface{}{ "error": err.Error(), }).Error("Failed to create user") return err } logging.WithFields(ctx, map[string]interface{}{ "user.id": user.ID, }).Info("User created successfully") return nil } ``` **See the complete implementation:** [go119-gin191-postgres/internal/logging/logger.go](https://github.com/base-14/examples/blob/main/go/go119-gin191-postgres/internal/logging/logger.go) ### References - [Official OpenTelemetry Go Documentation](https://opentelemetry.io/docs/languages/go/) - [OpenTelemetry Go GitHub](https://github.com/open-telemetry/opentelemetry-go) - [Go Examples Repository](https://github.com/base-14/examples/tree/main/go) - [go119-gin191-postgres](https://github.com/base-14/examples/tree/main/go/go119-gin191-postgres) - [chi-inmemory](https://github.com/base-14/examples/tree/main/go/chi-inmemory) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up Scout Collector for local development - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment - [Custom Java Instrumentation](./java.md) - Alternative language guide - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for your telemetry data --- ## Custom Instrumentation Overview - Manual OpenTelemetry Tracing ## Custom Instrumentation Custom instrumentation gives you **fine-grained control** over what telemetry is captured. Use it to track business-specific operations, add custom attributes, or instrument code that auto-instrumentation doesn't cover. ### When to Use Custom Instrumentation | Use Case | Recommendation | |----------|----------------| | Track business transactions (orders, payments) | ✅ Custom instrumentation | | Add user/tenant context to spans | ✅ Custom instrumentation | | Measure custom business metrics | ✅ Custom instrumentation | | Instrument internal libraries | ✅ Custom instrumentation | | Quick setup with standard frameworks | ❌ Use [auto-instrumentation](../auto-instrumentation/) first | ### Languages | Language | Guide | Key APIs | |----------|-------|----------| | Python | [Python](./python) | `tracer.start_as_current_span()`, `meter.create_counter()` | | Go | [Go](./go) | `tracer.Start()`, `meter.Int64Counter()` | | Java | [Java](./java) | `tracer.spanBuilder()`, `meter.counterBuilder()` | | JavaScript (Node) | [Node.js](./javascript-node) | `tracer.startActiveSpan()`, `meter.createCounter()` | | JavaScript (Browser) | [Browser](./javascript-browser) | `tracer.startActiveSpan()`, browser-specific context | | Ruby | [Ruby](./ruby) | `tracer.in_span()`, `meter.create_counter()` | | PHP | [PHP](./php) | `$tracer->spanBuilder()`, `$meter->createCounter()` | | C# / .NET | [C#](./csharp) | `tracer.StartActiveSpan()`, `meter.CreateCounter()` | | Rust | [Rust](./rust) | `tracer.start()`, `meter.u64_counter()` | ### Common Patterns #### Adding Custom Spans Wrap business-critical operations to track their duration and success: ```python # Python example with tracer.start_as_current_span("process_payment") as span: span.set_attribute("payment.amount", amount) span.set_attribute("payment.currency", "USD") result = payment_gateway.charge(amount) span.set_attribute("payment.success", result.success) ``` #### Adding Context to Auto-Instrumented Spans Enrich existing spans with business context: ```python from opentelemetry import trace span = trace.get_current_span() span.set_attribute("user.id", user_id) span.set_attribute("tenant.id", tenant_id) span.set_attribute("feature.flag", "new_checkout_v2") ``` #### Custom Metrics Track business KPIs alongside technical metrics: ```python order_counter = meter.create_counter( "orders.completed", description="Number of completed orders" ) order_counter.add(1, {"region": "us-east", "plan": "premium"}) ``` ### Combining Auto + Custom Instrumentation The most effective approach combines both: import ThemedImage from '@theme/ThemedImage'; ### Best Practices 1. **Start with auto-instrumentation** - Get baseline observability first 2. **Add custom spans for business operations** - Orders, payments, user actions 3. **Use semantic conventions** - Follow [OTel semantic conventions](https://opentelemetry.io/docs/specs/semconv/) for attribute names 4. **Keep span names static** - Use attributes for dynamic values, not span names 5. **Set appropriate span status** - Mark errors with `span.set_status(StatusCode.ERROR)` ### Next Steps 1. **Set up [auto-instrumentation](../auto-instrumentation/)** if you haven't already 2. **Choose your language** from the table above 3. **Identify key business operations** to instrument --- ## Java OpenTelemetry Custom Instrumentation - Spans & Metrics Guide Implement OpenTelemetry custom instrumentation for Java applications to collect traces, metrics, and logs using the Java OpenTelemetry SDK. This guide covers manual instrumentation for any Java application, including Spring, Micronaut, Quarkus, servlets, and custom frameworks. > **Note:** This guide provides a practical overview based on the official > OpenTelemetry documentation. For complete information, please consult the > [official OpenTelemetry Java documentation](https://opentelemetry.io/docs/languages/java/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry SDK for manual instrumentation - Create and manage custom spans - Add attributes, events, and exception tracking - Implement metrics collection - Propagate context across service boundaries - Instrument common Java patterns and frameworks ### Prerequisites Before starting, ensure you have: - **Java 8 or later** installed (Java 11+ recommended) - **Maven or Gradle** for dependency management - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) ### Required Dependencies ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Add the following dependencies to your `pom.xml`: ```xml showLineNumbers title="pom.xml" io.opentelemetry opentelemetry-api 1.32.0 io.opentelemetry opentelemetry-sdk 1.32.0 io.opentelemetry opentelemetry-exporter-otlp 1.32.0 io.opentelemetry.semconv opentelemetry-semconv 1.23.1-alpha ``` ```mdx-code-block ``` Add the following dependencies to your `build.gradle`: ```gradle showLineNumbers title="build.gradle" dependencies { implementation 'io.opentelemetry:opentelemetry-api:1.32.0' implementation 'io.opentelemetry:opentelemetry-sdk:1.32.0' implementation 'io.opentelemetry:opentelemetry-exporter-otlp:1.32.0' implementation 'io.opentelemetry.semconv:opentelemetry-semconv:1.23.1-alpha' } ``` ```mdx-code-block ``` ### Traces Traces provide a complete picture of request flows through your application, from initial request to final response, including all operations and services involved. #### Initialization Initialize the OpenTelemetry SDK with resource information and exporters: ```java showLineNumbers title="OpenTelemetryConfig.java" import io.opentelemetry.api.GlobalOpenTelemetry; import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.common.AttributeKey; import io.opentelemetry.api.common.Attributes; import io.opentelemetry.api.metrics.Meter; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.exporter.otlp.metrics.OtlpGrpcMetricExporter; import io.opentelemetry.exporter.otlp.trace.OtlpGrpcSpanExporter; import io.opentelemetry.sdk.OpenTelemetrySdk; import io.opentelemetry.sdk.metrics.SdkMeterProvider; import io.opentelemetry.sdk.metrics.export.PeriodicMetricReader; import io.opentelemetry.sdk.resources.Resource; import io.opentelemetry.sdk.trace.SdkTracerProvider; import io.opentelemetry.sdk.trace.export.BatchSpanProcessor; import java.time.Duration; public class OpenTelemetryConfig { private static final String SERVICE_NAME = "my-java-app"; private static final String SERVICE_VERSION = "1.0.0"; public static OpenTelemetry initializeOpenTelemetry() { // Create resource with service information Resource resource = Resource.getDefault() .merge(Resource.create(Attributes.of( AttributeKey.stringKey("service.name"), SERVICE_NAME, AttributeKey.stringKey("service.version"), SERVICE_VERSION, AttributeKey.stringKey("deployment.environment"), "production", AttributeKey.stringKey("environment"), "production" ))); // Create OTLP trace exporter OtlpGrpcSpanExporter spanExporter = OtlpGrpcSpanExporter.builder() .setEndpoint("http://localhost:4317") .build(); // Create tracer provider SdkTracerProvider tracerProvider = SdkTracerProvider.builder() .addSpanProcessor(BatchSpanProcessor.builder(spanExporter).build()) .setResource(resource) .build(); // Create OTLP metric exporter OtlpGrpcMetricExporter metricExporter = OtlpGrpcMetricExporter.builder() .setEndpoint("http://localhost:4317") .build(); // Create meter provider SdkMeterProvider meterProvider = SdkMeterProvider.builder() .setResource(resource) .registerMetricReader(PeriodicMetricReader.builder(metricExporter) .setInterval(Duration.ofSeconds(5)) .build()) .build(); // Build and register OpenTelemetry SDK globally OpenTelemetry openTelemetry = OpenTelemetrySdk.builder() .setTracerProvider(tracerProvider) .setMeterProvider(meterProvider) .buildAndRegisterGlobal(); // Add shutdown hook Runtime.getRuntime().addShutdownHook(new Thread(() -> { tracerProvider.close(); meterProvider.close(); })); return openTelemetry; } public static Tracer getTracer() { return GlobalOpenTelemetry.getTracer(SERVICE_NAME, SERVICE_VERSION); } public static Meter getMeter() { return GlobalOpenTelemetry.getMeter(SERVICE_NAME, SERVICE_VERSION); } } ``` > **Note**: Ensure your Scout Collector is properly configured to receive trace > data at the endpoint specified above. #### Creating Spans Create a span to track an operation: ```java showLineNumbers import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; import io.opentelemetry.context.Scope; public void doWork() { Tracer tracer = OpenTelemetryConfig.getTracer(); Span span = tracer.spanBuilder("operation-name").startSpan(); try (Scope scope = span.makeCurrent()) { // Perform your operation performWork(); } finally { span.end(); } } ``` #### Creating Nested Spans Create parent-child span relationships: ```java showLineNumbers public void processRequest() { Tracer tracer = OpenTelemetryConfig.getTracer(); Span parentSpan = tracer.spanBuilder("process_request").startSpan(); try (Scope parentScope = parentSpan.makeCurrent()) { // Validate input Span validateSpan = tracer.spanBuilder("validate_input").startSpan(); try (Scope validateScope = validateSpan.makeCurrent()) { validateInput(); } finally { validateSpan.end(); } // Fetch data Span fetchSpan = tracer.spanBuilder("fetch_data").startSpan(); try (Scope fetchScope = fetchSpan.makeCurrent()) { fetchFromDatabase(); } finally { fetchSpan.end(); } // Process results Span processSpan = tracer.spanBuilder("process_data").startSpan(); try (Scope processScope = processSpan.makeCurrent()) { processResults(); } finally { processSpan.end(); } } finally { parentSpan.end(); } } ``` #### Helper Methods for Cleaner Code ```java showLineNumbers import java.util.function.Supplier; public class SpanHelper { private static final Tracer tracer = OpenTelemetryConfig.getTracer(); public static T withSpan(String spanName, Supplier operation) { Span span = tracer.spanBuilder(spanName).startSpan(); try (Scope scope = span.makeCurrent()) { return operation.get(); } finally { span.end(); } } public static void withSpan(String spanName, Runnable operation) { Span span = tracer.spanBuilder(spanName).startSpan(); try (Scope scope = span.makeCurrent()) { operation.run(); } finally { span.end(); } } } // Usage String result = SpanHelper.withSpan("database_query", () -> { return database.query("SELECT * FROM users"); }); ``` ### Attributes Attributes add context to spans as key-value pairs: #### Adding Custom Attributes ```java showLineNumbers import io.opentelemetry.api.common.AttributeKey; import io.opentelemetry.api.common.Attributes; public void processOrder(String orderId) { Span span = tracer.spanBuilder("process_order").startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("order.id", orderId); span.setAttribute("order.status", "processing"); span.setAttribute("order.items_count", 5); // Process the order Order order = processOrder(orderId); span.setAttribute("order.total", order.getTotal()); span.setAttribute("order.status", "completed"); } finally { span.end(); } } ``` #### Using Semantic Conventions Use standardized attribute names for common operations: ```java showLineNumbers import io.opentelemetry.semconv.trace.attributes.SemanticAttributes; public void makeHttpRequest(String url, String method) { Span span = tracer.spanBuilder("http_request").startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute(SemanticAttributes.HTTP_REQUEST_METHOD, method); span.setAttribute(SemanticAttributes.URL_FULL, url); // Make HTTP request HttpResponse response = httpClient.send(url, method); span.setAttribute(SemanticAttributes.HTTP_RESPONSE_STATUS_CODE, response.getStatusCode()); } finally { span.end(); } } ``` ### Events Events mark significant moments during a span's lifetime: ```java showLineNumbers public void processPayment(PaymentInfo payment) { Span span = tracer.spanBuilder("process_payment").startSpan(); try (Scope scope = span.makeCurrent()) { span.addEvent("payment_received", Attributes.of( AttributeKey.stringKey("payment.method"), payment.getMethod(), AttributeKey.doubleKey("payment.amount"), payment.getAmount() )); // Process payment PaymentResult result = chargeCard(payment); span.addEvent("payment_processed", Attributes.of( AttributeKey.stringKey("transaction.id"), result.getTransactionId(), AttributeKey.stringKey("payment.status"), result.getStatus() )); if (result.isSuccess()) { span.addEvent("payment_confirmed"); } } finally { span.end(); } } ``` ### Exception Recording Capture and record exceptions in spans: ```java showLineNumbers import io.opentelemetry.api.trace.StatusCode; public void riskyOperation() { Span span = tracer.spanBuilder("risky_operation").startSpan(); try (Scope scope = span.makeCurrent()) { performRiskyWork(); span.setStatus(StatusCode.OK); } catch (Exception e) { span.recordException(e, Attributes.of( AttributeKey.stringKey("exception.escaped"), "true" )); span.setStatus(StatusCode.ERROR, e.getMessage()); throw new RuntimeException("Operation failed", e); } finally { span.end(); } } ``` ### Metrics Collect custom metrics to track application performance: #### Counter Track cumulative values that only increase: ```java showLineNumbers import io.opentelemetry.api.metrics.LongCounter; import io.opentelemetry.api.metrics.Meter; public class MetricsExample { private static final Meter meter = OpenTelemetryConfig.getMeter(); private static final LongCounter requestCounter = meter .counterBuilder("http.requests") .setDescription("Total number of HTTP requests") .setUnit("requests") .build(); public void handleRequest(String method, String route) { requestCounter.add(1, Attributes.of( AttributeKey.stringKey("http.method"), method, AttributeKey.stringKey("http.route"), route )); // Handle request... } } ``` #### Histogram Record distributions of values: ```java showLineNumbers import io.opentelemetry.api.metrics.LongHistogram; public class RequestDurationTracker { private static final LongHistogram requestDuration = meter .histogramBuilder("http.request.duration") .setDescription("HTTP request duration") .setUnit("ms") .ofLongs() .build(); public void trackRequest(String method, int statusCode) { long startTime = System.currentTimeMillis(); try { // Process request processRequest(); } finally { long duration = System.currentTimeMillis() - startTime; requestDuration.record(duration, Attributes.of( AttributeKey.stringKey("http.method"), method, AttributeKey.longKey("http.status_code"), statusCode )); } } } ``` #### Gauge Track values that can increase or decrease: ```java showLineNumbers import io.opentelemetry.api.metrics.ObservableLongGauge; public class GaugeExample { private static volatile long activeConnections = 0; public static void setupGauge() { ObservableLongGauge gauge = meter .gaugeBuilder("db.connections.active") .setDescription("Currently active database connections") .setUnit("connections") .ofLongs() .buildWithCallback(measurement -> { measurement.record(activeConnections, Attributes.of( AttributeKey.stringKey("db.type"), "postgresql" )); }); } public static void incrementConnections() { activeConnections++; } public static void decrementConnections() { activeConnections--; } } ``` ### Context Propagation Propagate trace context across HTTP requests: #### Outgoing HTTP Requests ```java showLineNumbers import io.opentelemetry.context.propagation.TextMapSetter; import java.net.http.HttpRequest; import java.net.http.HttpClient; public class HttpClientExample { private static final Tracer tracer = OpenTelemetryConfig.getTracer(); // Setter for injecting context into HTTP headers private static final TextMapSetter setter = (carrier, key, value) -> carrier.header(key, value); public String makeExternalRequest(String url) { Span span = tracer.spanBuilder("external_api_call").startSpan(); try (Scope scope = span.makeCurrent()) { HttpRequest.Builder requestBuilder = HttpRequest.newBuilder() .uri(URI.create(url)) .GET(); // Inject trace context into headers GlobalOpenTelemetry.getPropagators() .getTextMapPropagator() .inject(Context.current(), requestBuilder, setter); HttpRequest request = requestBuilder.build(); HttpClient client = HttpClient.newHttpClient(); HttpResponse response = client.send(request, HttpResponse.BodyHandlers.ofString()); span.setAttribute("http.status_code", response.statusCode()); return response.body(); } catch (Exception e) { span.recordException(e); span.setStatus(StatusCode.ERROR, e.getMessage()); throw new RuntimeException(e); } finally { span.end(); } } } ``` #### Incoming HTTP Requests (Servlet) ```java showLineNumbers import io.opentelemetry.context.propagation.TextMapGetter; import javax.servlet.http.HttpServletRequest; public class ServletExample { // Getter for extracting context from HTTP headers private static final TextMapGetter getter = new TextMapGetter<>() { @Override public Iterable keys(HttpServletRequest carrier) { return Collections.list(carrier.getHeaderNames()); } @Override public String get(HttpServletRequest carrier, String key) { return carrier.getHeader(key); } }; public void handleRequest(HttpServletRequest request) { // Extract context from incoming request Context extractedContext = GlobalOpenTelemetry.getPropagators() .getTextMapPropagator() .extract(Context.current(), request, getter); Span span = tracer.spanBuilder("handle_request") .setParent(extractedContext) .startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("http.method", request.getMethod()); span.setAttribute("http.url", request.getRequestURI()); // Process request processRequest(request); } finally { span.end(); } } } ``` ### Framework-Specific Examples #### Spring MVC Controller ```java showLineNumbers import org.springframework.web.bind.annotation.*; import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.Tracer; @RestController @RequestMapping("/api") public class UserController { private final Tracer tracer = OpenTelemetryConfig.getTracer(); private final UserService userService; public UserController(UserService userService) { this.userService = userService; } @GetMapping("/users/{id}") public User getUser(@PathVariable String id) { Span span = tracer.spanBuilder("UserController.getUser").startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("user.id", id); span.setAttribute("http.method", "GET"); span.setAttribute("http.route", "/api/users/{id}"); User user = userService.findById(id); span.setAttribute("user.found", user != null); return user; } finally { span.end(); } } @PostMapping("/orders") public Order createOrder(@RequestBody OrderRequest request) { Span span = tracer.spanBuilder("UserController.createOrder").startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("order.items_count", request.getItems().size()); span.setAttribute("http.method", "POST"); Order order = userService.createOrder(request); span.setAttribute("order.id", order.getId()); span.setAttribute("order.total", order.getTotal()); span.setStatus(StatusCode.OK); return order; } catch (Exception e) { span.recordException(e); span.setStatus(StatusCode.ERROR, e.getMessage()); throw e; } finally { span.end(); } } } ``` #### Servlet Filter ```java showLineNumbers import javax.servlet.*; import javax.servlet.http.*; import io.opentelemetry.api.trace.Span; import io.opentelemetry.context.Scope; public class TelemetryFilter implements Filter { private final Tracer tracer = OpenTelemetryConfig.getTracer(); @Override public void doFilter(ServletRequest request, ServletResponse response, FilterChain chain) throws IOException, ServletException { if (request instanceof HttpServletRequest) { HttpServletRequest httpRequest = (HttpServletRequest) request; HttpServletResponse httpResponse = (HttpServletResponse) response; String spanName = httpRequest.getMethod() + " " + httpRequest.getRequestURI(); Span span = tracer.spanBuilder(spanName).startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("http.method", httpRequest.getMethod()); span.setAttribute("http.url", httpRequest.getRequestURI()); chain.doFilter(request, response); span.setAttribute("http.status_code", httpResponse.getStatus()); } finally { span.end(); } } else { chain.doFilter(request, response); } } } ``` #### Plain Java Application ```java showLineNumbers public class BackgroundWorker { private final Tracer tracer = OpenTelemetryConfig.getTracer(); public void processJobs() { while (true) { Job job = fetchNextJob(); Span span = tracer.spanBuilder("process_job").startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("job.id", job.getId()); span.setAttribute("job.type", job.getType()); try { processJob(job); span.setAttribute("job.status", "completed"); span.setStatus(StatusCode.OK); } catch (Exception e) { span.recordException(e); span.setAttribute("job.status", "failed"); span.setStatus(StatusCode.ERROR, e.getMessage()); handleJobFailure(job, e); } } finally { span.end(); } try { Thread.sleep(1000); } catch (InterruptedException e) { Thread.currentThread().interrupt(); break; } } } } ``` ### Best Practices #### 1. Always Close Spans ```java // Good - using try-with-resources Span span = tracer.spanBuilder("operation").startSpan(); try (Scope scope = span.makeCurrent()) { doWork(); } finally { span.end(); // Always called } // Bad - span may not end if exception thrown Span span = tracer.spanBuilder("operation").startSpan(); Scope scope = span.makeCurrent(); doWork(); scope.close(); span.end(); ``` #### 2. Use Descriptive Span Names ```java // Good Span span = tracer.spanBuilder("UserRepository.findById").startSpan(); Span span = tracer.spanBuilder("PaymentService.processPayment").startSpan(); // Bad Span span = tracer.spanBuilder("operation").startSpan(); Span span = tracer.spanBuilder("query").startSpan(); ``` #### 3. Add Relevant Attributes ```java // Good span.setAttribute("user.id", userId); span.setAttribute("order.amount", amount); span.setAttribute("cache.hit", true); // Bad - sensitive data span.setAttribute("user.password", password); // Never! span.setAttribute("credit.card.number", ccNumber); // Never! ``` #### 4. Use Semantic Conventions ```java // Good - using semantic conventions import io.opentelemetry.semconv.trace.attributes.SemanticAttributes; span.setAttribute(SemanticAttributes.HTTP_REQUEST_METHOD, "POST"); span.setAttribute(SemanticAttributes.DB_SYSTEM, "postgresql"); span.setAttribute(SemanticAttributes.DB_NAME, "production"); ``` #### 5. Handle Exceptions Properly ```java // Good try { riskyOperation(); span.setStatus(StatusCode.OK); } catch (Exception e) { span.recordException(e); span.setStatus(StatusCode.ERROR, e.getMessage()); throw e; } // Bad - swallowing exceptions try { riskyOperation(); } catch (Exception e) { // Exception lost } ``` ### Complete Example Here's a complete example of a Java application with custom instrumentation: ```java showLineNumbers title="Application.java" import io.opentelemetry.api.OpenTelemetry; import io.opentelemetry.api.common.AttributeKey; import io.opentelemetry.api.common.Attributes; import io.opentelemetry.api.metrics.*; import io.opentelemetry.api.trace.*; public class Application { private static Tracer tracer; private static Meter meter; private static LongCounter requestCounter; private static LongHistogram requestDuration; public static void main(String[] args) { // Initialize OpenTelemetry OpenTelemetry openTelemetry = OpenTelemetryConfig.initializeOpenTelemetry(); tracer = OpenTelemetryConfig.getTracer(); meter = OpenTelemetryConfig.getMeter(); // Create metrics requestCounter = meter.counterBuilder("requests.total") .setDescription("Total requests") .setUnit("requests") .build(); requestDuration = meter.histogramBuilder("requests.duration") .setDescription("Request duration") .setUnit("ms") .ofLongs() .build(); // Process request processRequest(); } private static void processRequest() { long startTime = System.currentTimeMillis(); Span span = tracer.spanBuilder("http.request").startSpan(); try (Scope scope = span.makeCurrent()) { span.setAttribute("http.method", "POST"); span.setAttribute("http.url", "/api/orders"); try { // Business logic createOrder(); span.setAttribute("http.status_code", 201); span.setStatus(StatusCode.OK); recordMetrics(201, startTime); } catch (Exception e) { span.recordException(e); span.setAttribute("http.status_code", 500); span.setStatus(StatusCode.ERROR, e.getMessage()); recordMetrics(500, startTime); } } finally { span.end(); } } private static void createOrder() { Span span = tracer.spanBuilder("create_order").startSpan(); try (Scope scope = span.makeCurrent()) { // Simulate order creation int orderId = (int) (Math.random() * 10000); span.setAttribute("order.id", orderId); span.setAttribute("order.total", 99.99); System.out.println("Order created: " + orderId); } finally { span.end(); } } private static void recordMetrics(int statusCode, long startTime) { long duration = System.currentTimeMillis() - startTime; Attributes attrs = Attributes.of( AttributeKey.longKey("status"), (long) statusCode ); requestCounter.add(1, attrs); requestDuration.record(duration, attrs); } } ``` ### Extracting Trace and Span IDs Extract trace ID and span ID for log correlation: ```java showLineNumbers import io.opentelemetry.api.trace.Span; import io.opentelemetry.api.trace.SpanContext; public class TraceContextExtractor { public static String[] getTraceAndSpanIDs() { Span currentSpan = Span.current(); SpanContext spanContext = currentSpan.getSpanContext(); if (spanContext.isValid()) { String traceId = spanContext.getTraceId(); String spanId = spanContext.getSpanId(); return new String[]{traceId, spanId}; } return new String[]{"", ""}; } // Usage with logging public static void doWork() { Span span = tracer.spanBuilder("work.operation").startSpan(); try (Scope scope = span.makeCurrent()) { String[] ids = getTraceAndSpanIDs(); String traceId = ids[0]; String spanId = ids[1]; // Use for structured logging logger.info("Processing request - TraceID: {}, SpanID: {}", traceId, spanId); performWork(); } finally { span.end(); } } } ``` ### FAQ #### When should I use custom instead of auto-instrumentation in Java? Use custom instrumentation for business logic, in-house frameworks, and operations the agent does not see: internal service methods, batch processing, and domain-specific workflows. Auto-instrumentation covers the libraries and protocols at the edges of your application. #### How do I create custom spans in Java with OpenTelemetry? Get a `Tracer` from `GlobalOpenTelemetry`, call `tracer.spanBuilder("name").startSpan()`, add attributes and events, then call `span.end()` in a `finally` block so the span closes even when the operation throws. #### What Java versions does OpenTelemetry support? Java 8 and later, with Java 11 or newer recommended. The agent and SDK work with Spring, Micronaut, Quarkus, plain servlets, and custom frameworks. #### How do I propagate trace context across Java microservices? OpenTelemetry uses W3C Trace Context headers. Inject them on outbound HTTP calls and extract them on incoming requests, and the trace stays connected end to end in Scout. Auto-instrumented HTTP clients and servers do this for you. ### References - [Official OpenTelemetry Java Documentation](https://opentelemetry.io/docs/languages/java/) - [OpenTelemetry Java GitHub](https://github.com/open-telemetry/opentelemetry-java) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Spring Boot Auto-Instrumentation](../auto-instrumentation/spring-boot.md) - Automatic tracing for Java Spring Boot applications - [Quarkus Auto-Instrumentation](../auto-instrumentation/quarkus.md) - Automatic tracing for Quarkus applications - [Micronaut Auto-Instrumentation](../auto-instrumentation/micronaut.md) - Automatic tracing for Micronaut applications - [Ktor Auto-Instrumentation](../auto-instrumentation/ktor.md) - Automatic tracing for Kotlin Ktor applications - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up Scout Collector for local development --- ## OpenTelemetry JavaScript Browser Instrumentation - Manual Tracing Guide ## JavaScript Browser This guide provides instructions for setting up **custom instrumentation** for JavaScript browser applications using the OpenTelemetry JavaScript SDK. :::tip Building with React or Next.js? You do not need manual instrumentation. `@base-14/scout-react` ships zero-config browser RUM that captures clicks, route changes, fetch and XHR calls, errors, Core Web Vitals, and long tasks with a single `Scout.initialize()` call. See the [React guide](../auto-instrumentation/react.md) or the [Next.js guide](../auto-instrumentation/nextjs.md). Use this guide for vanilla JavaScript, or when you need control over exactly which spans are produced. ::: :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry custom instrumentation for JavaScript browser applications - Export telemetry data to Scout > **Note:** Auto instrumentation does not support metrics. To collect meaningful > metrics, you need to implement them manually. ### Prerequisites - Node.js 16+ - JavaScript browser application setup - Scout Collector setup ### Required Packages Install the following packages: ```bash npm install @opentelemetry/api npm install @opentelemetry/sdk-trace-web npm install @opentelemetry/sdk-metrics npm install @opentelemetry/sdk-logs npm install @opentelemetry/context-zone npm install @opentelemetry/exporter-trace-otlp-http npm install @opentelemetry/exporter-metrics-otlp-http npm install @opentelemetry/resources ``` ### Custom Instrumentation Setup (`telemetry.js`) ```javascript // src/telemetry.js import { WebTracerProvider } from "@opentelemetry/sdk-trace-web"; import { OTLPTraceExporter } from "@opentelemetry/exporter-trace-otlp-http"; import { BatchSpanProcessor } from "@opentelemetry/sdk-trace-base"; import { Resource } from "@opentelemetry/resources"; import { SemanticResourceAttributes } from "@opentelemetry/semantic-conventions"; import { ZoneContextManager } from "@opentelemetry/context-zone"; import { MeterProvider, PeriodicExportingMetricReader, } from "@opentelemetry/sdk-metrics"; import { OTLPMetricExporter } from "@opentelemetry/exporter-metrics-otlp-http"; import { LoggerProvider, SimpleLogRecordProcessor, } from "@opentelemetry/sdk-logs"; import { OTLPLogExporter } from "@opentelemetry/exporter-logs-otlp-http"; import * as logsAPI from "@opentelemetry/api-logs"; import * as api from "@opentelemetry/api"; import { ZoneContextManager } from "@opentelemetry/context-zone"; export const setupTelemetry = () => { const resource = new Resource({ [SemanticResourceAttributes.SERVICE_NAME]: "react-service", [SemanticResourceAttributes.SERVICE_VERSION]: "1.0.0", }); // Trace setup const traceExporter = new OTLPTraceExporter({ url: "http://:4318/v1/traces", }); const traceProvider = new WebTracerProvider({ resource }); traceProvider.addSpanProcessor(new BatchSpanProcessor(traceExporter)); traceProvider.register({ contextManager: new ZoneContextManager() }); // Metric setup const metricExporter = new OTLPMetricExporter({ url: "http://:4318/v1/metrics", }); const meterProvider = new MeterProvider({ resource, readers: [ new PeriodicExportingMetricReader({ exporter: metricExporter, exportIntervalMillis: 10000, }), ], }); api.metrics.setGlobalMeterProvider(meterProvider); // Log setup const logExporter = new OTLPLogExporter({ url: "http://:4318/v1/logs", }); const loggerProvider = new LoggerProvider({ resource, processors: [new SimpleLogRecordProcessor(logExporter)], }); logsAPI.logs.setGlobalLoggerProvider(loggerProvider); }; ``` #### Initialize in index.js ```js // src/index.js import React from "react"; import ReactDOM from "react-dom"; import App from "./App"; import { setupTelemetry } from "./telemetry"; setupTelemetry(); ReactDOM.render( , document.getElementById("root"), ); ``` ### Custom Tracing Example ```javascript import { trace } from "@opentelemetry/api"; async function checkServiceHealth() { // Get the tracer from the global tracer provider set in the setupTelemetry function const tracer = trace.getTracer("health-service"); const span = tracer.startSpan("checkServiceHealth"); try { span.setAttribute("health.check", "ping"); const res = await fetch("/ping"); const data = await res.json(); return data; } catch (error) { // handle error throw error; } finally { span.end(); } } ``` ### Custom Metrics Example ```javascript import { metrics } from "@opentelemetry/api"; // Gets the meter from the global meter provider set in the setupTelemetry function const meter = metrics.getMeter("react-app"); const renderCount = meter.createCounter("component.render.count"); function TrackedComponent() { useEffect(() => { renderCount.add(1, { component: "TrackedComponent" }); }, []); return
Tracked!
; } ``` ### Configuration #### CORS Headers for Otel Collector Add the following CORS headers to the Otel Collector configuration: ```yaml receivers: otlp: protocols: http: endpoint: 0.0.0.0:4318 cors: allowed_origins: - "https://example.com" ``` > View these traces in Scout dashboards. ### References [Sample react application with OTel instrumentation](https://github.com/base14/react-custom-instrumentation) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [React Auto-Instrumentation](../auto-instrumentation/react.md) - Zero-config browser RUM for React applications - [Scout RUM](../../../operate/rum/getting-started.md) - Query sessions, errors, and screen performance once telemetry is flowing - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment --- ## Node.js OpenTelemetry Custom Instrumentation - Spans & Metrics ## Javascript Node Implement OpenTelemetry custom instrumentation for Node.js applications to collect logs, metrics, and traces using the Node.js OTel SDK. :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry custom instrumentation for Node.js - Configure manual tracing using spans - Create and manage custom metrics - Add semantic attributes and events - Export telemetry data to Scout Collector ### Prerequisites Before starting, ensure you have: - Node.js 14 or later installed - A Node.js project set up - Access to package installation (npm/yarn) ### Required Packages Install the following necessary packages or add them to `package.json`: ```bash npm install @opentelemetry/sdk-node npm install @opentelemetry/exporter-trace-otlp-http npm install @opentelemetry/resources npm install @opentelemetry/sdk-trace-node npm install @opentelemetry/sdk-trace-base npm install @opentelemetry/exporter-metrics-otlp-http npm install @opentelemetry/sdk-metrics npm install @opentelemetry/sdk-logs npm install @opentelemetry/exporter-logs-otlp-http npm install @opentelemetry/api npm install @opentelemetry/api-logs ``` > **Note**: Ensure the scout collector is properly configured to receive and > process the telemetry data before forwarding to Scout backend. > [Click to know more](https://docs.base14.io/instrument/collector-setup/scout-exporter) ### Traces To start tracing, first initialize the NodeSDK with trace configuration. A Resource is an immutable representation of entity producing telemetry. #### Sample Reference code for Initialization ```javascript // instrumentation.js const { NodeSDK } = require("@opentelemetry/sdk-node"); const { Resource } = require("@opentelemetry/resources"); const { OTLPTraceExporter, } = require("@opentelemetry/exporter-trace-otlp-http"); const { BatchSpanProcessor } = require("@opentelemetry/sdk-trace-base"); // Define your service information const resource = new Resource({ "service.name": "node-js-service", "service.version": "1.0.0", }); // Initialize NodeSDK with trace configuration const sdk = new NodeSDK({ resource, spanProcessor: new BatchSpanProcessor( new OTLPTraceExporter({ url: "http://scout-collector:4318/v1/traces", }), ), }); // Start the SDK sdk.start(); // Graceful shutdown process.on("SIGTERM", () => { sdk .shutdown() .then(() => console.log("Tracing terminated")) .catch((error) => console.log("Error terminating tracing", error)) .finally(() => process.exit(0)); }); ``` #### Application Setup > **Note:** Import instrumentation before any other modules ```javascript // app.js "use strict"; require("./instrumentation"); const express = require("express"); const { trace } = require("@opentelemetry/api"); const app = express(); // ... rest of your application setup ``` #### Span ##### Creating Spans in Express Routes ```javascript const express = require('express'); const { trace, context } = require('@opentelemetry/api'); const tracer = trace.getTracer('node-js-service'); const router = express.Router(); router.get('/ping', async (req, res) => { const span = tracer.startSpan('get-ping'); const ctx = trace.setSpan(context.active(), span); try { await context.with(ctx, () => { // Your route logic here // Your logs passed with trace context res.json({ message: 'pong' }); }); } finally { span.end(); } }); ``` #### Span Attributes, Events, and Status Spans can be enriched with additional context using attributes, events and status indicators. These features help in better understanding and debugging the behavior of your application. ##### Complete Span Example ```javascript const { trace, context } = require("@opentelemetry/api"); router.get("/ping", async (req, res) => { // Start a new span const span = tracer.startSpan("handle-ping"); const ctx = trace.setSpan(context.active(), span); try { // Add basic attributes to the span span.setAttributes({ "http.method": req.method, "http.route": "/ping", "request.size": JSON.stringify(req.body).length, }); // Add an event for the request span.addEvent("Received ping request", { timestamp: new Date().toISOString(), }); // Simple response with timestamp const response = { status: "ok", message: "pong", timestamp: new Date().toISOString(), }; // Log the successful response span.addEvent("Sent pong response", { timestamp: response.timestamp, }); // Return the response res.status(200).json(response); // Set span status to OK span.setStatus({ code: 1 }); // 1 = OK, 2 = Error res.status(200).json(response); } catch (error) { // Handle error res.status(400).json({ error: error.message }); } finally { // Always end the span span.end(); } }); ``` ### Metrics To start collecting metrics, you'll need to initialize the NodeSDK with metrics configuration. #### Sample Reference code for Metrics Initialization ```javascript // instrumentation.js const { NodeSDK } = require("@opentelemetry/sdk-node"); const { OTLPMetricExporter, } = require("@opentelemetry/exporter-metrics-otlp-http"); const { PeriodicExportingMetricReader } = require("@opentelemetry/sdk-metrics"); const sdk = new NodeSDK({ resource, metricReader: new PeriodicExportingMetricReader({ exporter: new OTLPMetricExporter({ url: "http://scout-collector:4318/v1/metrics", }), }), }); sdk.start(); ``` #### Application Setup ```javascript // index.js const { metrics } = require("@opentelemetry/api"); const meter = metrics.getMeter("node-js-service"); ``` #### Metrics types ##### Counter ###### Creating a Synchronous Counter ```javascript const { metrics } = require("@opentelemetry/api"); const meter = metrics.getMeter("node-js-service"); // Create a counter const requestCounter = meter.createCounter("http_requests_total", { description: "Total number of HTTP requests", }); // Middleware to count requests app.use((req, res, next) => { requestCounter.add(1, { method: req.method, route: req.route?.path || "unknown", }); next(); }); ``` ##### Histogram ###### Creating a Histogram ```javascript const meter = metrics.getMeter("node-js-service"); const requestDurationHistogram = meter.createHistogram( "http_request_duration_seconds", { description: "HTTP request duration in seconds", boundaries: [0.01, 0.05, 0.1, 0.5, 1, 5], }, ); // Middleware to track request duration app.use((req, res, next) => { const startTime = performance.now(); res.on("finish", () => { const duration = (performance.now() - startTime) / 1000; // Convert to seconds requestDurationHistogram.record(duration, { method: req.method, route: req.route?.path || "unknown", status: res.statusCode, }); }); next(); }); ``` ### Logs Configure logs export in your instrumentation setup. ```javascript // instrumentation.js const { BatchLogRecordProcessor } = require("@opentelemetry/sdk-logs"); const { OTLPLogExporter } = require("@opentelemetry/exporter-logs-otlp-http"); const sdk = new NodeSDK({ resource, logRecordProcessor: new BatchLogRecordProcessor( new OTLPLogExporter({ url: "http://scout-collector:4318/v1/logs", }), ), }); ``` #### Creating Logs ```javascript const logAPI = require('@opentelemetry/api-logs'); const logger = logAPI.logs.getLogger('node-js-service'); // Health check endpoint with logging router.get('/ping', async (req, res) => { const span = tracer.startSpan('health-check'); try { const healthStatus = { status: 'healthy', timestamp: new Date().toISOString(), uptime: process.uptime() }; // Emit log with health check details logger.emit({ body: 'Health check performed', severityNumber: logAPI.SeverityNumber.INFO, attributes: { status: healthStatus.status, uptime: healthStatus.uptime, endpoint: req.url, timestamp: healthStatus.timestamp }, traceId: span.spanContext().traceId, spanId: span.spanContext().spanId, }); res.json(healthStatus); }); ``` > View your complete telemetry data in the base14 Scout observability platform. > [Click to know more](https://docs.base14.io/) ### FAQ #### How do I add custom OpenTelemetry spans in Node.js? Create a tracer with `trace.getTracer()` from the OpenTelemetry API, then call `tracer.startSpan()` around the Express route or business logic you want to see. Spans reach Scout through the OTLP HTTP exporter. #### What npm packages are required for Node.js OpenTelemetry instrumentation? Install `@opentelemetry/sdk-node`, `@opentelemetry/api`, `@opentelemetry/exporter-trace-otlp-http`, `@opentelemetry/sdk-trace-node`, and `@opentelemetry/sdk-trace-base`. Add the matching metrics and logs exporters and SDK packages when you emit those signals. #### How do I create custom metrics in Node.js with OpenTelemetry? Initialize a `MeterProvider` with a `PeriodicExportingMetricReader` and `OTLPMetricExporter`, then use `metrics.getMeter()` to create counters, histograms, and other instruments. Scout reads them without further configuration. #### How do I export OpenTelemetry logs from a Node.js application? Configure a `BatchLogRecordProcessor` with an `OTLPLogExporter` pointing at your Scout Collector on port 4318 at `/v1/logs`, then emit structured log records through `@opentelemetry/api-logs` so they carry trace context. ### References - For complete setup example refer to [sample-full-stack application](https://opentelemetry.io/docs/instrumentation/js/) - [Official OpenTelemetry Node.js Documentation](https://opentelemetry.io/docs/languages/js/getting-started/nodejs/) - [OpenTelemetry API Documentation](https://opentelemetry.io/docs/reference/specification/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/reference/specification/semantic-conventions/) ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment - [Express.js Auto-Instrumentation](../auto-instrumentation/express.md) - Auto-instrumentation for Express.js applications - [Fastify Auto-Instrumentation](../auto-instrumentation/fastify.md) - Auto-instrumentation for Fastify applications - [Hono Auto-Instrumentation](../auto-instrumentation/hono.md) - Auto-instrumentation for Hono applications --- ## PHP OpenTelemetry Instrumentation - Custom Spans & Metrics Guide Implement OpenTelemetry custom instrumentation for PHP applications to collect traces, metrics, and logs using the PHP OpenTelemetry SDK. This guide covers manual instrumentation for any PHP application, including custom frameworks, legacy codebases, and popular frameworks like Symfony, WordPress, and others. :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry SDK for manual instrumentation - Create and manage custom spans - Add attributes, events, and exception tracking - Implement metrics collection - Propagate context across service boundaries - Instrument common PHP patterns and frameworks ### Prerequisites Before starting, ensure you have: - **PHP 8.1 or later** installed - **Composer** for dependency management - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) ### Required Packages Install the OpenTelemetry SDK and exporters: ```bash showLineNumbers composer require open-telemetry/sdk composer require open-telemetry/exporter-otlp composer require guzzlehttp/guzzle ``` For semantic conventions support: ```bash showLineNumbers composer require open-telemetry/sem-conv ``` ### Traces Traces provide a complete picture of request flows through your application, from initial request to final response, including all operations and services involved. #### Initialization Initialize the TracerProvider and acquire a tracer: ```php showLineNumbers title="bootstrap.php" create() ) ); // Set as global tracer provider Globals::registerInitializer(function() use ($tracerProvider) { return $tracerProvider; }); // Get a tracer for your application $tracer = Globals::tracerProvider()->getTracer( 'my-app', '1.0.0' ); ``` #### Production Configuration with OTLP Exporter For production, export traces to Scout Collector: ```php showLineNumbers title="config/telemetry.php" merge( \OpenTelemetry\SDK\Resource\ResourceInfo::create( Attributes::create([ 'service.name' => 'my-php-app', 'service.version' => '1.0.0', 'deployment.environment' => 'development', 'environment' => 'development', ]) ) ); // Create OTLP exporter $transport = (new OtlpHttpTransportFactory())->create( 'http://localhost:4318', 'application/x-protobuf' ); $exporter = new SpanExporter($transport); // Create tracer provider with batch processor $tracerProvider = new TracerProvider( new BatchSpanProcessor($exporter), null, $resource ); Globals::registerInitializer(function() use ($tracerProvider) { return $tracerProvider; }); ``` > **Note**: Ensure your Scout Collector is properly configured to receive trace > data at the endpoint specified above. #### Creating Spans A span represents a single operation within a trace: ```php showLineNumbers $span = $tracer->spanBuilder('operation-name')->startSpan(); // Perform your operation doSomeWork(); // Always end spans $span->end(); ``` #### Using Span Context Activate a span to make it current and automatically propagate context: ```php showLineNumbers $span = $tracer->spanBuilder('parent-operation')->startSpan(); $scope = $span->activate(); try { // Any spans created here will be children of this span performOperation(); } finally { $scope->detach(); $span->end(); } ``` #### Creating Nested Spans Create parent-child span relationships: ```php showLineNumbers function processRequest($tracer) { $parentSpan = $tracer->spanBuilder('process_request')->startSpan(); $parentScope = $parentSpan->activate(); try { // Child span 1 $childSpan1 = $tracer->spanBuilder('validate_input')->startSpan(); validateInput(); $childSpan1->end(); // Child span 2 $childSpan2 = $tracer->spanBuilder('fetch_data')->startSpan(); fetchDataFromDatabase(); $childSpan2->end(); // Child span 3 $childSpan3 = $tracer->spanBuilder('process_data')->startSpan(); processData(); $childSpan3->end(); } finally { $parentScope->detach(); $parentSpan->end(); } } ``` ### Attributes Attributes add context to spans as key-value pairs: #### Adding Custom Attributes ```php showLineNumbers $span = $tracer->spanBuilder('database-query')->startSpan(); $span->setAttribute('db.system', 'postgresql'); $span->setAttribute('db.name', 'production'); $span->setAttribute('db.operation', 'SELECT'); $span->setAttribute('query.rows_returned', 42); // Perform database operation $results = $db->query('SELECT * FROM users'); $span->end(); ``` #### Using Semantic Conventions Use standardized attribute names for common operations: ```php showLineNumbers use OpenTelemetry\SemConv\TraceAttributes; $span = $tracer->spanBuilder('http-request')->startSpan(); $span->setAttribute(TraceAttributes::HTTP_METHOD, 'POST'); $span->setAttribute(TraceAttributes::HTTP_URL, 'https://api.example.com/users'); $span->setAttribute(TraceAttributes::HTTP_STATUS_CODE, 201); $span->setAttribute(TraceAttributes::HTTP_REQUEST_CONTENT_LENGTH, strlen($body)); $span->end(); ``` ### Events Events mark significant moments during a span's lifetime: ```php showLineNumbers $span = $tracer->spanBuilder('order-processing')->startSpan(); $span->addEvent('order_received', [ 'order.id' => '12345', 'order.amount' => 99.99, ]); // Process the order processOrder($orderId); $span->addEvent('payment_processed', [ 'payment.method' => 'credit_card', 'payment.status' => 'success', ]); $span->addEvent('order_completed'); $span->end(); ``` ### Exception Recording Capture and record exceptions in spans: ```php showLineNumbers use OpenTelemetry\API\Trace\StatusCode; $span = $tracer->spanBuilder('risky-operation')->startSpan(); try { performRiskyOperation(); $span->setStatus(StatusCode::STATUS_OK); } catch (\Exception $e) { $span->recordException($e, [ 'exception.escaped' => true, ]); $span->setStatus( StatusCode::STATUS_ERROR, $e->getMessage() ); throw $e; } finally { $span->end(); } ``` ### Metrics Collect custom metrics to track application performance and business KPIs: #### Counter Track cumulative values that only increase: ```php showLineNumbers use OpenTelemetry\API\Globals; $meter = Globals::meterProvider()->getMeter('my-app'); $requestCounter = $meter->createCounter( 'http.requests', 'requests', 'Total number of HTTP requests' ); // Increment counter $requestCounter->add(1, [ 'http.method' => 'GET', 'http.route' => '/api/users', ]); ``` #### Histogram Record distributions of values: ```php showLineNumbers $requestDuration = $meter->createHistogram( 'http.request.duration', 'milliseconds', 'HTTP request duration' ); $startTime = hrtime(true); // Process request handleRequest(); $duration = (hrtime(true) - $startTime) / 1e6; // Convert to milliseconds $requestDuration->record($duration, [ 'http.method' => 'POST', 'http.status_code' => 200, ]); ``` #### UpDownCounter Track values that can increase or decrease: ```php showLineNumbers $activeConnections = $meter->createUpDownCounter( 'db.connections.active', 'connections', 'Currently active database connections' ); // Connection opened $activeConnections->add(1); // Connection closed $activeConnections->add(-1); ``` ### Context Propagation Propagate trace context across HTTP requests: #### Outgoing HTTP Requests ```php showLineNumbers use OpenTelemetry\API\Trace\Propagation\TraceContextPropagator; $span = $tracer->spanBuilder('external-api-call')->startSpan(); $scope = $span->activate(); try { // Get current context $context = \OpenTelemetry\Context\Context::getCurrent(); // Inject trace context into HTTP headers $carrier = []; TraceContextPropagator::getInstance()->inject($carrier, null, $context); // Make HTTP request with trace headers $client = new \GuzzleHttp\Client(); $response = $client->request('GET', 'https://api.example.com/data', [ 'headers' => $carrier ]); } finally { $scope->detach(); $span->end(); } ``` #### Incoming HTTP Requests ```php showLineNumbers use OpenTelemetry\API\Trace\Propagation\TraceContextPropagator; // Extract context from incoming request headers $headers = getallheaders(); $context = TraceContextPropagator::getInstance()->extract($headers); // Start span with extracted context $span = $tracer->spanBuilder('handle-request') ->setParent($context) ->startSpan(); $scope = $span->activate(); try { handleRequest(); } finally { $scope->detach(); $span->end(); } ``` ### Framework-Specific Examples #### Symfony Controller ```php showLineNumbers namespace App\Controller; use OpenTelemetry\API\Globals; use Symfony\Component\HttpFoundation\Response; class UserController { private $tracer; public function __construct() { $this->tracer = Globals::tracerProvider()->getTracer('symfony-app'); } public function index(): Response { $span = $this->tracer->spanBuilder('UserController::index')->startSpan(); $scope = $span->activate(); try { $users = $this->fetchUsers(); $span->setAttribute('user.count', count($users)); return new Response(json_encode($users)); } finally { $scope->detach(); $span->end(); } } } ``` #### WordPress Plugin ```php showLineNumbers use OpenTelemetry\API\Globals; add_action('init', function() { $tracer = Globals::tracerProvider()->getTracer('wordpress-plugin'); add_filter('the_content', function($content) use ($tracer) { $span = $tracer->spanBuilder('process_content')->startSpan(); try { // Process content $processed = processContent($content); $span->setAttribute('content.length', strlen($processed)); return $processed; } finally { $span->end(); } }); }); ``` #### Plain PHP Application ```php showLineNumbers getTracer('my-app'); // Start request span $requestSpan = $tracer->spanBuilder('http.request')->startSpan(); $requestScope = $requestSpan->activate(); try { $requestSpan->setAttribute('http.method', $_SERVER['REQUEST_METHOD']); $requestSpan->setAttribute('http.url', $_SERVER['REQUEST_URI']); // Route request $route = $_GET['route'] ?? 'home'; $routeSpan = $tracer->spanBuilder("route.{$route}")->startSpan(); try { handleRoute($route); } finally { $routeSpan->end(); } http_response_code(200); $requestSpan->setAttribute('http.status_code', 200); } catch (\Exception $e) { $requestSpan->recordException($e); $requestSpan->setAttribute('http.status_code', 500); http_response_code(500); } finally { $requestScope->detach(); $requestSpan->end(); } ``` ### Best Practices #### 1. Always End Spans ```php // Good $span = $tracer->spanBuilder('operation')->startSpan(); try { doWork(); } finally { $span->end(); // Always called } // Bad - span may not end if exception thrown $span = $tracer->spanBuilder('operation')->startSpan(); doWork(); $span->end(); ``` #### 2. Use Descriptive Span Names ```php // Good $span = $tracer->spanBuilder('UserRepository::findById')->startSpan(); $span = $tracer->spanBuilder('PaymentService::processPayment')->startSpan(); // Bad $span = $tracer->spanBuilder('operation')->startSpan(); $span = $tracer->spanBuilder('query')->startSpan(); ``` #### 3. Add Relevant Attributes ```php // Good $span->setAttribute('user.id', $userId); $span->setAttribute('order.amount', $amount); $span->setAttribute('cache.hit', true); // Bad - too verbose or sensitive data $span->setAttribute('user.password', $password); // Never! $span->setAttribute('full.sql.query', $query); // May contain sensitive data ``` #### 4. Detach Scopes Properly ```php // Good $scope = $span->activate(); try { doWork(); } finally { $scope->detach(); // Always detach $span->end(); } // Bad - scope not detached, causes context pollution $span->activate(); doWork(); $span->end(); ``` #### 5. Use Batch Processing in Production ```php // Production - use BatchSpanProcessor $tracerProvider = new TracerProvider( new BatchSpanProcessor($exporter) ); // Development - use SimpleSpanProcessor for immediate export $tracerProvider = new TracerProvider( new SimpleSpanProcessor($exporter) ); ``` ### Complete Example Here's a complete example of a PHP application with custom instrumentation: ```php showLineNumbers title="app.php" create( 'http://localhost:4318', 'application/x-protobuf' ); $tracerProvider = new TracerProvider( new BatchSpanProcessor(new SpanExporter($transport)) ); Globals::registerInitializer(function() use ($tracerProvider) { return $tracerProvider; }); $tracer = Globals::tracerProvider()->getTracer('my-app', '1.0.0'); $meter = Globals::meterProvider()->getMeter('my-app'); // Create metrics $requestCounter = $meter->createCounter('requests.total', 'requests'); $requestDuration = $meter->createHistogram('requests.duration', 'ms'); // Handle request $requestSpan = $tracer->spanBuilder('http.request')->startSpan(); $requestScope = $requestSpan->activate(); $startTime = hrtime(true); try { $requestSpan->setAttribute('http.method', $_SERVER['REQUEST_METHOD']); $requestSpan->setAttribute('http.url', $_SERVER['REQUEST_URI']); // Business logic $result = processRequest(); $requestSpan->setStatus(StatusCode::STATUS_OK); $statusCode = 200; } catch (\Exception $e) { $requestSpan->recordException($e); $requestSpan->setStatus(StatusCode::STATUS_ERROR, $e->getMessage()); $statusCode = 500; } finally { $duration = (hrtime(true) - $startTime) / 1e6; $requestSpan->setAttribute('http.status_code', $statusCode); $requestCounter->add(1, ['status' => $statusCode]); $requestDuration->record($duration, ['status' => $statusCode]); $requestScope->detach(); $requestSpan->end(); // Ensure spans are flushed $tracerProvider->shutdown(); } ``` Once your spans are exported, you can [visualize PHP traces in Scout](https://base14.io/scout/traces) - inspect request waterfalls, identify slow operations, and correlate traces with logs and metrics. ### FAQ #### What PHP version is required for OpenTelemetry manual instrumentation? PHP 8.1 or later for current SDK releases. Install the OpenTelemetry SDK and the OTLP exporter with Composer. Manual instrumentation needs no PECL extension, unlike auto-instrumentation. #### How do I create custom spans in PHP with OpenTelemetry? Build the span with the tracer's `spanBuilder` method, call `startSpan()`, run your operation, and always call `end()` in a `finally` block so the span closes when the operation throws. #### How do I propagate trace context across PHP services? Use `TraceContextPropagator` to inject trace context into outgoing HTTP request headers and to extract it from incoming request headers. Without both halves the trace breaks at the service boundary. #### Does OpenTelemetry PHP work with Symfony and WordPress? Yes. Manual instrumentation works with any PHP framework, including Symfony, WordPress, and plain PHP, because it depends only on the SDK rather than on framework hooks. #### Should I use SimpleSpanProcessor or BatchSpanProcessor? Use `BatchSpanProcessor` in production. It groups spans and exports them in the background, so the request path does less work. `SimpleSpanProcessor` exports each span immediately, which is useful while debugging locally. ### References - [Official OpenTelemetry PHP Documentation](https://opentelemetry.io/docs/languages/php/) - [OpenTelemetry PHP GitHub](https://github.com/open-telemetry/opentelemetry-php) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Laravel Auto-Instrumentation](../auto-instrumentation/laravel.md) - Automatic tracing for Laravel applications - [Symfony Auto-Instrumentation](../auto-instrumentation/symfony.md) - Automatic tracing for Symfony applications with Doctrine ORM - [Slim Auto-Instrumentation](../auto-instrumentation/slim.md) - Automatic tracing for Slim micro-framework applications - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up Scout Collector for local development - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for your telemetry data --- ## Python OpenTelemetry Custom Instrumentation - Spans & Metrics ## Python Implement OpenTelemetry custom instrumentation for `Python` applications to collect logs, metrics, and traces using the Python OTel SDK. > **Note:** This guide provides a concise overview based on the official > OpenTelemetry documentation. For complete information, please consult the > [official OpenTelemetry documentation](https://opentelemetry.io/docs/languages/python/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry custom instrumentation for `Python` - Configure manual tracing using spans - Create and manage custom metrics - Add semantic attributes and events - Export telemetry data to Scout Collector ### Prerequisites Before starting, ensure you have: - Python 3.7 or later installed - A Python project set up - Access to package installation (`pip`) ### Required Packages Install the following necessary packages or add them to `requirements.txt`: ```bash pip install opentelemetry-api pip install opentelemetry-sdk pip install opentelemetry-exporter-otlp # Optional but recommended pip install opentelemetry-semantic-conventions ``` ### Traces Traces give us the big picture of what happens when a request is made to an application. Whether your application is a monolith with a single database or a sophisticated mesh of services, traces are essential to understanding the full “path” a request takes in your application. #### Initialization To Start tracing, first a tracer should be acquired and a TraceProvider should be initialized optionally we can pass a resource to TraceProvider. > A Resource is an immutable representation of the entity producing telemetry. > For example, a process producing telemetry that is running in a container on > Kubernetes has a Pod name, it is in a namespace and possibly is part of a > Deployment which also has a name. All three of these attributes can be > included in the Resource. Sample Reference code for Initialization ```python showLineNumbers from opentelemetry import trace from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.resources import Resource, SERVICE_NAME from opentelemetry.sdk.trace.export import ( BatchSpanProcessor, ConsoleSpanExporter, ) from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter resource = Resource({SERVICE_NAME: "my.service.name"}) provider = TracerProvider(resource=resource) processor = BatchSpanProcessor(OTLPSpanExporter(endpoint="http://0.0.0.0:4318/v1/traces")) provider.add_span_processor(processor) processor = BatchSpanProcessor(ConsoleSpanExporter()) provider.add_span_processor(processor) # Sets the global default tracer provider trace.set_tracer_provider(provider) # Creates a tracer from the global tracer provider tracer = trace.get_tracer("my.tracer.name") ``` > View your traces in the base14 Scout observability platform. > > **Note**: Ensure your Scout Collector is properly configured to receive and > process the trace data. ##### Reference [Official Traces Documentation](https://opentelemetry.io/docs/concepts/signals/traces/) #### Span A span represents a unit of work or operation. Spans are the building blocks of Traces. In OpenTelemetry, they include some necessary information. ##### Creating a Span ```python showLineNumbers def do_work(): with tracer.start_as_current_span("span.name") as span: # do some work that 'span' tracks print("doing some work...") ``` ##### Creating nested Spans ```python showLineNumbers def do_work(): with tracer.start_as_current_span("parent") as parent: # do some work that 'parent' tracks print("doing some work...") # Create a nested span to track nested work with tracer.start_as_current_span("child") as child: # do some work that 'child' tracks print("doing some nested work...") ``` ##### Creating Spans with decorators ```python showLineNumbers @tracer.start_as_current_span("span") def do_work(): print("doing some work...") ``` > View these spans in base14 Scout observability backend. ##### Reference [Official Span Documentation](https://opentelemetry.io/docs/concepts/signals/traces/#spans) #### Attributes Attributes let you attach key/value pairs to a span so it carries more information about the current operation that it’s tracking. ##### Adding Attributes to a Span ```python showLineNumbers def do_work(): with tracer.start_as_current_span("span.name") as span: span.set_attribute("operation.value", 1) span.set_attribute("operation.name", "Saying hello!") span.set_attribute("operation.other-stuff", [1, 2, 3]) print("doing some work...") ``` ##### Adding Semantic Attributes to a Span Semantic Attributes are pre-defined Attributes that are well-known naming conventions for common kinds of data. Using Semantic Attributes lets you normalize this kind of information across your systems. > Ensure that you have installed `opentelemetry-semantic-conventions` package > for using Semantic Attributes ```python showLineNumbers from opentelemetry.semconv.trace import SpanAttributes def do_work(): with tracer.start_as_current_span("span.name") as span: span.set_attribute(SpanAttributes.HTTP_METHOD, "GET") span.set_attribute(SpanAttributes.HTTP_URL, "https://base14.io/") print("doing some work...") ``` > View these spans in the base14 Scout observability platform. > > **Note**: Ensure your Scout Collector is properly configured to receive and > process the span data. ##### Reference [Official Attributes Documentation](https://opentelemetry.io/docs/concepts/signals/traces/#attributes) #### Events An event is a human-readable message on a span that represents “something happening” during its lifetime. You can think of it as a primitive log. ##### Adding an event to a span ```python showLineNumbers def do_work(): with tracer.start_as_current_span("span.name") as span: span.add_event("Starting some work") print("doing some work...") span.add_event("Finished working") ``` ##### Reference [Official Event Documentation](https://opentelemetry.io/docs/concepts/signals/traces/#span-events) #### Span Status A Status can be set on a Span, typically used to specify that a Span has not completed successfully - `Error`. By default, all spans are Unset, which means a span completed without error. The `Ok` status is reserved for when you need to explicitly mark a span as successful rather than stick with the default of `Unset` (i.e., “without error”). We also look at how to record an exception in the Span. ##### Setting a Span Status ```python showLineNumbers from opentelemetry import trace from opentelemetry.trace import Status, StatusCode def do_work(): with tracer.start_as_current_span("span.name") as span: try: # something that might fail except Exception as exception: span.set_status(Status(StatusCode.ERROR)) span.record_exception(exception) ``` > View these spans in the base14 Scout observability platform. > > **Note**: Ensure your Scout Collector is properly configured to receive and > process the span data. ### Metrics #### Initialization To start collecting metrics, you’ll need to initialize a MeterProvider and optionally set it as the global default. Sample Reference code for Metrics Initialization ```python showLineNumbers from opentelemetry import metrics from opentelemetry.sdk.metrics import MeterProvider from opentelemetry.sdk.metrics.export import ( ConsoleMetricExporter, PeriodicExportingMetricReader, ) from opentelemetry.exporter.otlp.proto.grpc.metric_exporter import OTLPMetricExporter metric_reader = PeriodicExportingMetricReader(OTLPMetricExporter(endpoint="http://0.0.0.0:4317/v1/metrics")) metric_provider = MeterProvider(metric_readers=[metric_reader]) metrics.set_meter_provider(metric_provider) # Creates a meter from the global meter provider meter = metrics.get_meter("my.meter.name") ``` > View these metrics in base14 Scout observability backend. > > **Note**: Ensure your Scout Collector is properly configured to receive and > process the trace data. #### Counter Counter is a synchronous Instrument which supports non-negative increments. ##### Creating a Synchronous Counter ```python showLineNumbers work_counter = meter.create_counter( "work.counter", unit="1", description="Counts the amount of work done" ) def do_work(work_type: string): work_counter.add(1, {"work.type": work_type}) print("doing some work...") ``` > View these metrics in base14 Scout observability backend. ##### Creating Asynchronous Counter ```python showLineNumbers from opentelemetry.metrics import Observation def pf_callback(callback_options): return [ Observation(8, attributes={"pid": 0, "bitness": 64}), Observation(37741921, attributes={"pid": 4, "bitness": 64}), Observation(10465, attributes={"pid": 880, "bitness": 32}), ] meter.create_observable_counter(name="PF", description="process page faults", callbacks=[pf_callback]) ``` > View these metrics in base14 Scout observability backend. ##### Reference [Official Counter Documentation](https://opentelemetry.io/docs/specs/otel/metrics/api/#counter) #### Histogram Histogram is a synchronous Instrument which can be used to report arbitrary values that are likely to be statistically meaningful. It is intended for statistics such as histograms, summaries, and percentile. ##### Creating a Histogram ```python showLineNumbers http_server_duration = meter.create_histogram( name="http.server.duration", description="measures the duration of the inbound HTTP request", unit="ms", value_type=float) http_server_duration.Record(50, {"http.request.method": "POST", "url.scheme": "https"}) http_server_duration.Record(100, http_method="GET", http_scheme="http") ``` > View these metrics in base14 Scout observability backend. ##### Reference [Official Histogram Documentation](https://opentelemetry.io/docs/specs/otel/metrics/api/#histogram) ### Extracting Trace and Span IDs To extract trace ID and span ID from the current context for log correlation or debugging purposes: ```python showLineNumbers from opentelemetry import trace def get_trace_span_ids(): # Get the current span current_span = trace.get_current_span() if current_span.is_recording(): # Extract trace ID and span ID span_context = current_span.get_span_context() trace_id = format(span_context.trace_id, '032x') span_id = format(span_context.span_id, '016x') print(f"Trace ID: {trace_id}") print(f"Span ID: {span_id}") return trace_id, span_id else: print("No active span found") return None, None # Usage within a traced function def traced_function(): with tracer.start_as_current_span("my-operation") as span: trace_id, span_id = get_trace_span_ids() # Use these IDs for log correlation or debugging print(f"Processing operation with trace: {trace_id}, span: {span_id}") ``` ### FAQ #### How do I add custom spans to a Python application with OpenTelemetry? Install `opentelemetry-api` and `opentelemetry-sdk`, initialize a `TracerProvider` with a `BatchSpanProcessor`, then use `tracer.start_as_current_span()` as a context manager or a decorator. The OTLP exporter sends the spans to Scout. #### What Python packages are needed for OpenTelemetry custom instrumentation? `opentelemetry-api`, `opentelemetry-sdk`, and `opentelemetry-exporter-otlp`. Add `opentelemetry-semantic-conventions` if you want the standard attribute names rather than hand-written strings. #### How do I create custom metrics in Python with OpenTelemetry? Initialize a `MeterProvider` with a `PeriodicExportingMetricReader` and `OTLPMetricExporter`, then call `meter.create_counter()` or `meter.create_histogram()` to record values. Scout reads them without extra configuration. #### How do I extract trace and span IDs in Python for log correlation? Call `trace.get_current_span()` to get the active span, then read `span_context.trace_id` and `span_context.span_id`. Format both as hex strings before putting them in structured logs. #### Can I create nested spans in Python OpenTelemetry? Yes. Nest `tracer.start_as_current_span()` context managers inside each other and OpenTelemetry links each child to its parent automatically, producing the full trace hierarchy in Scout. ### Related Guides - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - Production deployment - [Fast API Auto-Instrumentation](../auto-instrumentation/fast-api.md) - Auto-instrumentation for Python FastAPI applications - [Django Auto-Instrumentation](../auto-instrumentation/django.md) - Auto-instrumentation for Django applications - [Flask Auto-Instrumentation](../auto-instrumentation/flask.md) - Auto-instrumentation for Flask applications --- ## Ruby OpenTelemetry Custom Instrumentation - Spans & Metrics Guide ## Ruby Implement OpenTelemetry custom instrumentation for Ruby applications to collect traces, metrics, and logs using the Ruby OpenTelemetry SDK. This guide covers manual instrumentation for any Ruby application, including Sinatra, Hanami, plain Rack applications, and custom frameworks. :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry SDK for manual instrumentation - Create and manage custom spans - Add attributes, events, and exception tracking - Implement metrics collection - Propagate context across service boundaries - Instrument common Ruby patterns and frameworks ### Prerequisites Before starting, ensure you have: - **Ruby 3.0 or later** installed - **Bundler** for dependency management - Basic understanding of OpenTelemetry concepts (traces, spans, attributes) ### Required Packages Add to your `Gemfile`: ```ruby showLineNumbers title="Gemfile" gem 'opentelemetry-sdk' gem 'opentelemetry-exporter-otlp' gem 'opentelemetry-instrumentation-all' # Optional: Semantic conventions gem 'opentelemetry-semantic_conventions' ``` Install dependencies: ```bash showLineNumbers bundle install ``` ### Traces Traces provide a complete picture of request flows through your application, from initial request to final response, including all operations and services involved. #### Initialization Initialize the OpenTelemetry SDK and configure exporters: ```ruby showLineNumbers title="config/telemetry.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' OpenTelemetry::SDK.configure do |c| c.service_name = 'my-ruby-app' c.service_version = '1.0.0' # Use OTLP exporter for production c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: ENV.fetch('OTEL_EXPORTER_OTLP_ENDPOINT', 'http://localhost:4318/v1/traces') ) ) ) end # Get a tracer MyAppTracer = OpenTelemetry.tracer_provider.tracer('my-app', '1.0.0') ``` > **Note**: Ensure your Scout Collector is properly configured to receive trace > data at the endpoint specified above. #### Creating Spans Create a span to track an operation: ```ruby showLineNumbers MyAppTracer.in_span('operation-name') do |span| # Perform your operation perform_work end ``` #### Creating Nested Spans Create parent-child span relationships: ```ruby showLineNumbers def process_request MyAppTracer.in_span('process_request') do |parent_span| # Validate input MyAppTracer.in_span('validate_input') do validate_input end # Fetch data MyAppTracer.in_span('fetch_data') do fetch_from_database end # Process results MyAppTracer.in_span('process_data') do process_results end end end ``` ### Attributes Attributes add context to spans as key-value pairs: #### Adding Custom Attributes ```ruby showLineNumbers def process_order(order_id) MyAppTracer.in_span('process_order') do |span| span.set_attribute('order.id', order_id) span.set_attribute('order.status', 'processing') span.set_attribute('order.items_count', 5) # Process the order result = process(order_id) span.set_attribute('order.total', result.total) span.set_attribute('order.status', 'completed') end end ``` #### Using Semantic Conventions Use standardized attribute names for common operations: ```ruby showLineNumbers require 'opentelemetry/semantic_conventions' def make_http_request(url, method) MyAppTracer.in_span('http_request') do |span| span.set_attribute( OpenTelemetry::SemanticConventions::Trace::HTTP_METHOD, method ) span.set_attribute( OpenTelemetry::SemanticConventions::Trace::HTTP_URL, url ) response = HTTP.send(method.downcase, url) span.set_attribute( OpenTelemetry::SemanticConventions::Trace::HTTP_STATUS_CODE, response.code ) end end ``` ### Events Events mark significant moments during a span's lifetime: ```ruby showLineNumbers def process_payment(payment_info) MyAppTracer.in_span('process_payment') do |span| span.add_event('payment_received', attributes: { 'payment.method' => payment_info[:method], 'payment.amount' => payment_info[:amount] }) # Process payment result = charge_card(payment_info) span.add_event('payment_processed', attributes: { 'transaction.id' => result.transaction_id, 'payment.status' => result.status }) if result.success? span.add_event('payment_confirmed') end end end ``` ### Exception Recording Capture and record exceptions in spans: ```ruby showLineNumbers def risky_operation MyAppTracer.in_span('risky_operation') do |span| begin perform_risky_work span.status = OpenTelemetry::Trace::Status.ok rescue StandardError => e span.record_exception(e) span.status = OpenTelemetry::Trace::Status.error(e.message) raise end end end ``` ### Metrics Collect custom metrics to track application performance: #### Counter Track cumulative values that only increase: ```ruby showLineNumbers meter = OpenTelemetry.meter_provider.meter('my-app') request_counter = meter.create_counter( 'http.requests', unit: 'requests', description: 'Total number of HTTP requests' ) # Increment counter def handle_request(method, route) request_counter.add(1, attributes: { 'http.method' => method, 'http.route' => route }) # Handle request... end ``` #### Histogram Record distributions of values: ```ruby showLineNumbers request_duration = meter.create_histogram( 'http.request.duration', unit: 'ms', description: 'HTTP request duration' ) def track_request_duration(method, status) start_time = Process.clock_gettime(Process::CLOCK_MONOTONIC, :millisecond) # Process request yield duration = Process.clock_gettime(Process::CLOCK_MONOTONIC, :millisecond) - start_time request_duration.record(duration, attributes: { 'http.method' => method, 'http.status_code' => status }) end ``` #### UpDownCounter Track values that can increase or decrease: ```ruby showLineNumbers active_connections = meter.create_up_down_counter( 'db.connections.active', unit: 'connections', description: 'Currently active database connections' ) # Connection opened active_connections.add(1) # Connection closed active_connections.add(-1) ``` ### Context Propagation Propagate trace context across HTTP requests: #### Outgoing HTTP Requests ```ruby showLineNumbers require 'net/http' require 'opentelemetry/propagator/trace_context' def make_external_request(url) MyAppTracer.in_span('external_api_call') do |span| uri = URI(url) request = Net::HTTP::Get.new(uri) # Inject trace context into headers carrier = {} OpenTelemetry.propagation.inject(carrier) carrier.each do |key, value| request[key] = value end # Make the request with trace headers response = Net::HTTP.start(uri.hostname, uri.port) do |http| http.request(request) end span.set_attribute('http.status_code', response.code.to_i) response end end ``` #### Incoming HTTP Requests ```ruby showLineNumbers def handle_incoming_request(env) # Extract context from incoming request headers context = OpenTelemetry.propagation.extract(env) # Start span with extracted context OpenTelemetry::Context.with_current(context) do MyAppTracer.in_span('handle_request') do |span| span.set_attribute('http.method', env['REQUEST_METHOD']) span.set_attribute('http.url', env['REQUEST_URI']) # Process request process_request(env) end end end ``` ### Framework-Specific Examples #### Sinatra Application ```ruby showLineNumbers title="app.rb" require 'sinatra' require_relative 'config/telemetry' before do # Extract trace context from headers context = OpenTelemetry.propagation.extract(request.env) OpenTelemetry::Context.with_current(context) do MyAppTracer.in_span("#{request.request_method} #{request.path}") do |span| span.set_attribute('http.method', request.request_method) span.set_attribute('http.route', request.path) @current_span = span end end end get '/users/:id' do |id| MyAppTracer.in_span('fetch_user') do |span| span.set_attribute('user.id', id) user = User.find(id) @current_span.set_attribute('http.status_code', 200) user.to_json end end post '/orders' do MyAppTracer.in_span('create_order') do |span| data = JSON.parse(request.body.read) span.set_attribute('order.items_count', data['items'].length) order = Order.create(data) span.set_attribute('order.id', order.id) span.set_attribute('order.total', order.total) @current_span.set_attribute('http.status_code', 201) status 201 order.to_json end end ``` #### Rack Middleware ```ruby showLineNumbers title="lib/telemetry_middleware.rb" class TelemetryMiddleware def initialize(app) @app = app @tracer = OpenTelemetry.tracer_provider.tracer('rack-app') end def call(env) context = OpenTelemetry.propagation.extract(env) OpenTelemetry::Context.with_current(context) do @tracer.in_span("#{env['REQUEST_METHOD']} #{env['PATH_INFO']}") do |span| span.set_attribute('http.method', env['REQUEST_METHOD']) span.set_attribute('http.url', env['PATH_INFO']) status, headers, response = @app.call(env) span.set_attribute('http.status_code', status) [status, headers, response] end end end end # Use in config.ru use TelemetryMiddleware ``` #### Plain Ruby Application ```ruby showLineNumbers title="worker.rb" require_relative 'config/telemetry' class BackgroundWorker def process_jobs loop do job = fetch_next_job MyAppTracer.in_span('process_job') do |span| span.set_attribute('job.id', job.id) span.set_attribute('job.type', job.type) begin process_job(job) span.set_attribute('job.status', 'completed') span.status = OpenTelemetry::Trace::Status.ok rescue StandardError => e span.record_exception(e) span.set_attribute('job.status', 'failed') span.status = OpenTelemetry::Trace::Status.error(e.message) handle_job_failure(job, e) end end sleep 1 end end end ``` ### Best Practices #### 1. Always Use Blocks for Spans ```ruby # Good - span automatically ended MyAppTracer.in_span('operation') do |span| do_work end # Bad - manual span management (error-prone) span = MyAppTracer.start_span('operation') do_work span.finish # May not be called if exception occurs ``` #### 2. Use Descriptive Span Names ```ruby # Good MyAppTracer.in_span('UserRepository#find_by_email') MyAppTracer.in_span('PaymentService#process_payment') # Bad MyAppTracer.in_span('operation') MyAppTracer.in_span('query') ``` #### 3. Add Relevant Attributes ```ruby # Good span.set_attribute('user.id', user_id) span.set_attribute('order.amount', amount) span.set_attribute('cache.hit', true) # Bad - sensitive data span.set_attribute('user.password', password) # Never! span.set_attribute('credit_card.number', cc_number) # Never! ``` #### 4. Use Semantic Conventions ```ruby # Good - using semantic conventions span.set_attribute(OpenTelemetry::SemanticConventions::Trace::HTTP_METHOD, 'POST') # Also good - using semantic convention values span.set_attribute('http.method', 'POST') span.set_attribute('db.system', 'postgresql') ``` #### 5. Handle Exceptions Properly ```ruby # Good MyAppTracer.in_span('operation') do |span| begin risky_operation rescue StandardError => e span.record_exception(e) span.status = OpenTelemetry::Trace::Status.error(e.message) raise end end # Bad - swallowing exceptions without recording begin risky_operation rescue StandardError # Exception lost end ``` ### Complete Example Here's a complete example of a Ruby application with custom instrumentation: ```ruby showLineNumbers title="app.rb" require 'opentelemetry/sdk' require 'opentelemetry/exporter/otlp' require 'opentelemetry/semantic_conventions' require 'json' # Initialize OpenTelemetry OpenTelemetry::SDK.configure do |c| c.service_name = 'my-ruby-app' c.service_version = '1.0.0' c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new( OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: 'http://localhost:4318/v1/traces' ) ) ) end tracer = OpenTelemetry.tracer_provider.tracer('my-app', '1.0.0') meter = OpenTelemetry.meter_provider.meter('my-app') # Create metrics request_counter = meter.create_counter('requests.total', unit: 'requests') request_duration = meter.create_histogram('requests.duration', unit: 'ms') # Process request def process_request(tracer, request_counter, request_duration) start_time = Process.clock_gettime(Process::CLOCK_MONOTONIC, :millisecond) tracer.in_span('http.request') do |span| span.set_attribute('http.method', 'POST') span.set_attribute('http.url', '/api/orders') begin # Business logic result = create_order span.set_attribute('http.status_code', 201) span.status = OpenTelemetry::Trace::Status.ok status_code = 201 rescue StandardError => e span.record_exception(e) span.set_attribute('http.status_code', 500) span.status = OpenTelemetry::Trace::Status.error(e.message) status_code = 500 ensure duration = Process.clock_gettime(Process::CLOCK_MONOTONIC, :millisecond) - start_time request_counter.add(1, attributes: { 'status' => status_code }) request_duration.record(duration, attributes: { 'status' => status_code }) end end end def create_order tracer.in_span('create_order') do |span| # Simulate order creation order_id = rand(1000..9999) span.set_attribute('order.id', order_id) span.set_attribute('order.total', 99.99) { id: order_id, total: 99.99, status: 'created' } end end # Run the application process_request(tracer, request_counter, request_duration) # Shutdown to flush remaining spans OpenTelemetry.tracer_provider.shutdown ``` ### Extracting Trace and Span IDs Extract trace ID and span ID for log correlation: ```ruby showLineNumbers def get_trace_span_ids current_span = OpenTelemetry::Trace.current_span if current_span.context.valid? trace_id = current_span.context.trace_id.unpack1('H*') span_id = current_span.context.span_id.unpack1('H*') puts "Trace ID: #{trace_id}" puts "Span ID: #{span_id}" [trace_id, span_id] else [nil, nil] end end # Usage MyAppTracer.in_span('my-operation') do trace_id, span_id = get_trace_span_ids # Use for structured logging logger.info("Processing request", { trace_id: trace_id, span_id: span_id, operation: 'my-operation' }) end ``` ### References - [Official OpenTelemetry Ruby Documentation](https://opentelemetry.io/docs/languages/ruby/) - [OpenTelemetry Ruby GitHub](https://github.com/open-telemetry/opentelemetry-ruby) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Rails Auto-Instrumentation](../auto-instrumentation/rails.md) - Automatic tracing for Ruby on Rails applications - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up Scout Collector for local development - [Creating Alerts](../../../guides/creating-alerts-with-logx.md) - Set up alerts for your telemetry data --- ## Rust OpenTelemetry Custom Instrumentation - Spans & Metrics Guide ## Rust Implement OpenTelemetry custom instrumentation for Rust applications to collect traces, metrics, and logs using the tracing ecosystem and OpenTelemetry SDK. This guide covers manual instrumentation for any Rust application, including Axum, Actix-web, Rocket, and custom frameworks. > **Note:** This guide provides a practical overview based on the official > OpenTelemetry documentation. For complete information, please consult the > [official OpenTelemetry Rust documentation](https://opentelemetry.io/docs/languages/rust/). :::note Running this in production Storing and querying this data at production volume is what base14 Scout does. [Check out Scout APM](https://base14.io/scout/apm). ::: ### Overview This guide demonstrates how to: - Set up OpenTelemetry SDK with the tracing ecosystem - Create and manage custom spans using `#[instrument]` and manual spans - Add attributes, events, and exception tracking - Implement metrics collection with counters, gauges, and histograms - Propagate context across service boundaries - Instrument common Rust patterns and async code > **Complete Working Examples**: This guide includes code snippets for learning. > For full implementations, see the > [Complete Examples](#complete-examples) section. ### Prerequisites Before starting, ensure you have: - **Rust 1.75 or later** installed (Rust 1.80+ recommended) - **Cargo** package manager - **base14 Scout account** with collector endpoint and API key - Basic familiarity with async Rust and the tracing crate ### Required Packages Add these dependencies to your `Cargo.toml`: ```toml title="Cargo.toml" [dependencies] # Tracing ecosystem tracing = "0.1" tracing-subscriber = { version = "0.3", features = ["env-filter", "json"] } # OpenTelemetry core opentelemetry = "0.29" opentelemetry_sdk = { version = "0.29", features = ["rt-tokio"] } opentelemetry-otlp = { version = "0.29", features = ["tonic"] } # Tracing-OpenTelemetry bridge tracing-opentelemetry = "0.30" # Async runtime tokio = { version = "1", features = ["full"] } ``` ### Telemetry Initialization Set up the OpenTelemetry SDK with OTLP export: ```rust title="src/telemetry/init.rs" use opentelemetry::trace::TracerProvider; use opentelemetry::{global, KeyValue}; use opentelemetry_otlp::WithExportConfig; use opentelemetry_sdk::{ Resource, propagation::TraceContextPropagator, trace::{SdkTracerProvider, TracerProviderBuilder}, }; use tracing_subscriber::{layer::SubscriberExt, util::SubscriberInitExt, EnvFilter}; pub struct TelemetryGuard { tracer_provider: SdkTracerProvider, } impl Drop for TelemetryGuard { fn drop(&mut self) { if let Err(e) = self.tracer_provider.shutdown() { eprintln!("Failed to shutdown tracer provider: {e}"); } } } pub fn init_telemetry(service_name: &str, otlp_endpoint: &str) -> TelemetryGuard { global::set_text_map_propagator(TraceContextPropagator::new()); let resource = Resource::builder() .with_service_name(service_name) .with_attribute(KeyValue::new("deployment.environment", "production")) .with_attribute(KeyValue::new("environment", "production")) .build(); let exporter = opentelemetry_otlp::SpanExporter::builder() .with_tonic() .with_endpoint(otlp_endpoint) .build() .expect("Failed to create OTLP exporter"); let tracer_provider = TracerProviderBuilder::default() .with_resource(resource) .with_batch_exporter(exporter) .build(); let tracer = tracer_provider.tracer(service_name); let telemetry_layer = tracing_opentelemetry::layer().with_tracer(tracer); let filter = EnvFilter::try_from_default_env() .unwrap_or_else(|_| EnvFilter::new("info")); tracing_subscriber::registry() .with(filter) .with(telemetry_layer) .with(tracing_subscriber::fmt::layer()) .init(); TelemetryGuard { tracer_provider } } ``` ### Traces #### Using the `#[instrument]` Attribute The simplest way to create spans is using the `#[instrument]` attribute: ```rust use tracing::instrument; #[instrument(name = "user.create")] pub async fn create_user(email: &str, name: &str) -> Result { // Function body becomes a span let user = db.insert_user(email, name).await?; Ok(user) } ``` #### Customizing Instrumented Spans Control what gets captured in spans: ```rust use tracing::instrument; #[instrument( name = "order.process", skip(self, payment_details), // Don't log sensitive data fields(order_id, customer_id = %customer.id) )] pub async fn process_order( &self, customer: &Customer, payment_details: PaymentDetails, ) -> Result { // Record the order_id field dynamically let order = self.create_order(customer).await?; tracing::Span::current().record("order_id", order.id); self.charge_payment(&order, payment_details).await?; Ok(order) } ``` #### Manual Span Creation For more control, create spans manually: ```rust use tracing::{span, Level, Instrument}; pub async fn batch_process(items: Vec) -> Result<(), Error> { let span = span!(Level::INFO, "batch.process", item_count = items.len()); let _guard = span.enter(); for item in items { process_item(item).await?; } Ok(()) } // Or use .instrument() for async code pub async fn fetch_data(url: &str) -> Result { let span = span!(Level::INFO, "http.fetch", url = %url); async { let response = client.get(url).send().await?; let data = response.json().await?; Ok(data) } .instrument(span) .await } ``` #### Nested Spans Spans automatically nest based on the call hierarchy: ```rust #[instrument(name = "api.handler")] pub async fn handle_request(req: Request) -> Response { let user = authenticate(&req).await?; // Creates child span let data = fetch_user_data(&user).await?; // Creates child span process_response(data) // Creates child span } #[instrument(name = "auth.verify")] async fn authenticate(req: &Request) -> Result { // This span is a child of "api.handler" validate_token(req.token()).await } #[instrument(name = "data.fetch")] async fn fetch_user_data(user: &User) -> Result { // This span is a child of "api.handler" db.get_user_data(user.id).await } ``` ### Attributes #### Adding Span Attributes Add attributes to provide context: ```rust use tracing::instrument; #[instrument( name = "article.create", fields( author_id = %author.id, title = %input.title, article_id = tracing::field::Empty // Filled later ) )] pub async fn create_article(author: &User, input: CreateArticle) -> Result { let article = db.insert_article(&input).await?; // Record the article_id after creation tracing::Span::current().record("article_id", article.id); Ok(article) } ``` #### Using Span Extensions Add attributes dynamically within a span: ```rust use tracing::Span; pub async fn process_payment(order_id: i64, amount: f64) -> Result<(), Error> { let span = Span::current(); span.record("order.id", order_id); span.record("payment.amount", amount); let result = payment_gateway.charge(amount).await?; span.record("payment.transaction_id", &result.transaction_id); span.record("payment.status", &result.status); Ok(()) } ``` #### Semantic Conventions Follow OpenTelemetry semantic conventions for common attributes: ```rust #[instrument( name = "http.request", fields( http.method = %method, http.url = %url, http.status_code = tracing::field::Empty, http.request.body.size = body_size, ) )] pub async fn make_request( method: &str, url: &str, body_size: usize, ) -> Result { let response = client.request(method, url).send().await?; tracing::Span::current().record("http.status_code", response.status().as_u16()); Ok(response) } ``` ### Events #### Logging Events Within Spans Use tracing macros to add events: ```rust use tracing::{info, warn, error, debug, instrument}; #[instrument(name = "order.fulfill")] pub async fn fulfill_order(order_id: i64) -> Result<(), Error> { info!(order_id, "Starting order fulfillment"); let inventory = check_inventory(order_id).await?; if inventory.low_stock { warn!( order_id, available = inventory.available, required = inventory.required, "Low inventory warning" ); } debug!(order_id, step = "payment", "Processing payment"); process_payment(order_id).await?; debug!(order_id, step = "shipping", "Arranging shipping"); arrange_shipping(order_id).await?; info!(order_id, "Order fulfilled successfully"); Ok(()) } ``` #### Structured Event Data Add structured data to events: ```rust use tracing::{info, instrument}; use serde::Serialize; #[derive(Serialize)] struct OrderMetrics { item_count: usize, total_amount: f64, discount_applied: bool, } #[instrument(name = "order.complete")] pub async fn complete_order(order: &Order) -> Result<(), Error> { let metrics = OrderMetrics { item_count: order.items.len(), total_amount: order.total, discount_applied: order.discount.is_some(), }; info!( order_id = order.id, item_count = metrics.item_count, total_amount = metrics.total_amount, discount_applied = metrics.discount_applied, "Order completed" ); Ok(()) } ``` ### Exception Recording #### Recording Errors Record exceptions with full context: ```rust use tracing::{error, instrument, Span}; #[instrument(name = "user.login")] pub async fn login(credentials: Credentials) -> Result { match authenticate(&credentials).await { Ok(user) => { let session = create_session(&user).await?; Ok(session) } Err(e) => { error!( error = %e, error.type = std::any::type_name_of_val(&e), username = %credentials.username, "Authentication failed" ); Err(e) } } } ``` #### Custom Error Recording Create a helper for consistent error recording: ```rust use tracing::{error, Span}; use std::fmt::Display; pub trait SpanErrorExt { fn record_error(&self, error: &E); } impl SpanErrorExt for Span { fn record_error(&self, error: &E) { error!( parent: self, error = %error, "Operation failed" ); } } // Usage #[instrument(name = "data.fetch")] pub async fn fetch_data(id: i64) -> Result { db.get(id).await.map_err(|e| { Span::current().record_error(&e); e }) } ``` #### Error Boundaries Handle errors at service boundaries: ```rust use tracing::{error, instrument}; #[instrument(name = "api.request", skip(body))] pub async fn handle_api_request( method: &str, path: &str, body: Bytes, ) -> Result { let result = route_request(method, path, body).await; match &result { Ok(response) => { tracing::info!( status = response.status().as_u16(), "Request completed" ); } Err(e) => { error!( error = %e, error.code = e.code(), "Request failed" ); } } result } ``` ### Metrics #### Setting Up Metrics Initialize the metrics provider: ```rust title="src/telemetry/metrics.rs" use opentelemetry::{ global, metrics::{Counter, Histogram, Meter}, }; use std::sync::LazyLock; pub static METER: LazyLock = LazyLock::new(|| { global::meter("my-service") }); pub static HTTP_REQUESTS_TOTAL: LazyLock> = LazyLock::new(|| { METER .u64_counter("http.requests.total") .with_description("Total number of HTTP requests") .with_unit("{request}") .build() }); pub static HTTP_REQUEST_DURATION: LazyLock> = LazyLock::new(|| { METER .f64_histogram("http.request.duration") .with_description("HTTP request duration in milliseconds") .with_unit("ms") .with_boundaries(vec![ 1.0, 5.0, 10.0, 25.0, 50.0, 100.0, 250.0, 500.0, 1000.0, ]) .build() }); ``` #### Counter Metrics Track counts of events: ```rust use opentelemetry::KeyValue; use crate::telemetry::{HTTP_REQUESTS_TOTAL, USERS_REGISTERED}; pub async fn handle_request(method: &str, path: &str) -> Response { HTTP_REQUESTS_TOTAL.add( 1, &[ KeyValue::new("http.method", method.to_string()), KeyValue::new("http.route", path.to_string()), ], ); // Handle request... } pub async fn register_user(input: RegisterUser) -> Result { let user = db.create_user(&input).await?; USERS_REGISTERED.add(1, &[]); Ok(user) } ``` #### Histogram Metrics Record distributions of values: ```rust use std::time::Instant; use opentelemetry::KeyValue; use crate::telemetry::HTTP_REQUEST_DURATION; pub async fn timed_request(handler: F) -> T where F: Future, { let start = Instant::now(); let result = handler.await; let duration = start.elapsed().as_millis() as f64; HTTP_REQUEST_DURATION.record( duration, &[KeyValue::new("http.route", "/api/users")], ); result } ``` #### Gauge Metrics Track current values: ```rust use opentelemetry::KeyValue; use std::sync::LazyLock; pub static ACTIVE_CONNECTIONS: LazyLock> = LazyLock::new(|| { METER .i64_gauge("connections.active") .with_description("Number of active connections") .build() }); pub fn update_connection_count(count: i64) { ACTIVE_CONNECTIONS.record(count, &[]); } ``` #### Business Metrics Track domain-specific metrics: ```rust use opentelemetry::KeyValue; use std::sync::LazyLock; pub static ARTICLES_CREATED: LazyLock> = LazyLock::new(|| { METER .u64_counter("articles.created") .with_description("Total articles created") .build() }); pub static ORDERS_TOTAL: LazyLock> = LazyLock::new(|| { METER .u64_counter("orders.total") .with_description("Total orders placed") .build() }); pub static ORDER_VALUE: LazyLock> = LazyLock::new(|| { METER .f64_histogram("order.value") .with_description("Order value in dollars") .with_unit("USD") .build() }); // Usage pub async fn create_order(order: &Order) -> Result<(), Error> { // Process order... ORDERS_TOTAL.add( 1, &[KeyValue::new("order.type", order.order_type.to_string())], ); ORDER_VALUE.record(order.total, &[]); Ok(()) } ``` ### Context Propagation #### HTTP Context Propagation Propagate trace context across HTTP boundaries: ```rust use opentelemetry::global; use opentelemetry::propagation::Injector; use reqwest::header::HeaderMap; struct HeaderInjector<'a>(&'a mut HeaderMap); impl<'a> Injector for HeaderInjector<'a> { fn set(&mut self, key: &str, value: String) { if let Ok(header_name) = key.parse() { if let Ok(header_value) = value.parse() { self.0.insert(header_name, header_value); } } } } pub async fn call_service(url: &str) -> Result { let mut headers = HeaderMap::new(); // Inject current trace context into headers global::get_text_map_propagator(|propagator| { propagator.inject_context( &tracing::Span::current().context(), &mut HeaderInjector(&mut headers), ); }); let response = reqwest::Client::new() .get(url) .headers(headers) .send() .await?; Ok(response) } ``` #### Extracting Context from Incoming Requests Extract trace context from incoming HTTP requests: ```rust use opentelemetry::propagation::Extractor; use axum::http::HeaderMap; struct HeaderExtractor<'a>(&'a HeaderMap); impl<'a> Extractor for HeaderExtractor<'a> { fn get(&self, key: &str) -> Option<&str> { self.0.get(key).and_then(|v| v.to_str().ok()) } fn keys(&self) -> Vec<&str> { self.0.keys().map(|k| k.as_str()).collect() } } pub fn extract_context(headers: &HeaderMap) -> opentelemetry::Context { global::get_text_map_propagator(|propagator| { propagator.extract(&HeaderExtractor(headers)) }) } ``` #### Async Task Context Propagate context to spawned tasks: ```rust use tracing::Instrument; pub async fn process_in_background(data: Data) { let span = tracing::span!(tracing::Level::INFO, "background.task"); tokio::spawn( async move { // This task carries the trace context process_data(data).await; } .instrument(span), ); } ``` ### Framework-Specific Examples #### Axum Middleware Create tracing middleware for Axum: ```rust use axum::{ extract::Request, middleware::Next, response::Response, }; use tracing::{instrument, Span}; use std::time::Instant; pub async fn tracing_middleware(request: Request, next: Next) -> Response { let method = request.method().to_string(); let uri = request.uri().path().to_string(); let span = tracing::span!( tracing::Level::INFO, "http.request", http.method = %method, http.uri = %uri, http.status_code = tracing::field::Empty, ); let start = Instant::now(); let response = next.run(request).instrument(span.clone()).await; let duration = start.elapsed(); span.record("http.status_code", response.status().as_u16()); tracing::info!( parent: &span, duration_ms = duration.as_millis(), "Request completed" ); response } ``` #### Tower Service Instrumentation Instrument Tower services: ```rust use tower_http::trace::{TraceLayer, DefaultMakeSpan, DefaultOnResponse}; use tracing::Level; let app = Router::new() .route("/api/users", get(list_users)) .layer( TraceLayer::new_for_http() .make_span_with(DefaultMakeSpan::new().level(Level::INFO)) .on_response(DefaultOnResponse::new().level(Level::INFO)), ); ``` ### Best Practices #### 1. Use Structured Fields Always use structured fields instead of string interpolation: ```rust // Good tracing::info!(user_id = 123, action = "login", "User logged in"); // Avoid tracing::info!("User 123 logged in"); ``` #### 2. Skip Sensitive Data Never log sensitive information: ```rust #[instrument(skip(password, credit_card))] pub async fn process_payment( user_id: i64, password: &str, credit_card: &CreditCard, ) -> Result<(), Error> { // ... } ``` #### 3. Use Appropriate Span Names Follow a consistent naming convention: ```rust // Good: domain.action format #[instrument(name = "user.create")] #[instrument(name = "order.process")] #[instrument(name = "payment.charge")] // Avoid: inconsistent naming #[instrument(name = "createUser")] #[instrument(name = "process_order")] ``` #### 4. Handle Errors Consistently Always record errors before returning: ```rust #[instrument(name = "data.fetch")] pub async fn fetch_data(id: i64) -> Result { match db.get(id).await { Ok(data) => Ok(data), Err(e) => { tracing::error!(error = %e, id, "Failed to fetch data"); Err(e) } } } ``` #### 5. Use Field Placeholders for Dynamic Values Record values that aren't known at span creation: ```rust #[instrument( name = "request.process", fields(response_size = tracing::field::Empty) )] pub async fn process() -> Response { let response = generate_response().await; Span::current().record("response_size", response.body().len()); response } ``` ### Complete Examples #### Full Service Setup ```rust title="src/main.rs" use std::net::SocketAddr; use axum::{Router, routing::get}; use tracing::info; mod telemetry; mod handlers; #[tokio::main] async fn main() { let _guard = telemetry::init_telemetry( "my-rust-service", "https://scout-collector.base14.io:4317", ); let app = Router::new() .route("/health", get(handlers::health)) .route("/api/users", get(handlers::list_users)); let addr = SocketAddr::from(([0, 0, 0, 0], 3000)); info!("Starting server on {}", addr); let listener = tokio::net::TcpListener::bind(addr).await.unwrap(); axum::serve(listener, app).await.unwrap(); } ``` #### Instrumented Handler ```rust title="src/handlers.rs" use axum::Json; use tracing::instrument; use crate::telemetry::USERS_FETCHED; #[instrument(name = "handler.list_users")] pub async fn list_users() -> Json> { let users = fetch_users_from_db().await; USERS_FETCHED.add(users.len() as u64, &[]); Json(users) } #[instrument(name = "db.fetch_users")] async fn fetch_users_from_db() -> Vec { // Database query with automatic span sqlx::query_as!(User, "SELECT * FROM users") .fetch_all(&pool) .await .unwrap_or_default() } ``` ### Extracting Trace and Span IDs Extract trace context for logging or correlation: ```rust use tracing::Span; use tracing_opentelemetry::OpenTelemetrySpanExt; pub fn get_trace_ids() -> (String, String) { let span = Span::current(); let context = span.context(); let span_ref = context.span(); let span_context = span_ref.span_context(); let trace_id = span_context.trace_id().to_string(); let span_id = span_context.span_id().to_string(); (trace_id, span_id) } // Include in error responses pub async fn handle_error(error: Error) -> Response { let (trace_id, span_id) = get_trace_ids(); Json(json!({ "error": error.to_string(), "trace_id": trace_id, "span_id": span_id, })) .into_response() } ``` ### Proper Shutdown and Resource Cleanup Ensure telemetry is properly flushed on shutdown: ```rust use tokio::signal; #[tokio::main] async fn main() { // The guard ensures cleanup on drop let _telemetry_guard = telemetry::init_telemetry( "my-service", "https://scout-collector.base14.io:4317", ); let app = create_app(); // Graceful shutdown let listener = tokio::net::TcpListener::bind("0.0.0.0:3000").await.unwrap(); axum::serve(listener, app) .with_graceful_shutdown(shutdown_signal()) .await .unwrap(); // Guard drops here, flushing all telemetry } async fn shutdown_signal() { let ctrl_c = async { signal::ctrl_c().await.expect("Failed to install Ctrl+C handler"); }; #[cfg(unix)] let terminate = async { signal::unix::signal(signal::unix::SignalKind::terminate()) .expect("Failed to install signal handler") .recv() .await; }; #[cfg(not(unix))] let terminate = std::future::pending::<()>(); tokio::select! { _ = ctrl_c => {}, _ = terminate => {}, } tracing::info!("Shutdown signal received, flushing telemetry..."); } ``` ### Database Instrumentation Patterns #### SQLx Query Instrumentation SQLx provides automatic tracing when the `tracing` feature is enabled: ```toml title="Cargo.toml" [dependencies] sqlx = { version = "0.8", features = ["runtime-tokio", "postgres", "tracing"] } ``` ```rust #[instrument(name = "db.get_user", skip(pool))] pub async fn get_user(pool: &PgPool, id: i64) -> Result { sqlx::query_as!(User, "SELECT * FROM users WHERE id = $1", id) .fetch_one(pool) .await .map_err(Into::into) } #[instrument(name = "db.create_user", skip(pool))] pub async fn create_user(pool: &PgPool, input: &CreateUser) -> Result { sqlx::query_as!( User, r#" INSERT INTO users (email, name) VALUES ($1, $2) RETURNING * "#, input.email, input.name ) .fetch_one(pool) .await .map_err(Into::into) } ``` #### Transaction Instrumentation Instrument database transactions: ```rust #[instrument(name = "db.transfer_funds", skip(pool))] pub async fn transfer_funds( pool: &PgPool, from_id: i64, to_id: i64, amount: f64, ) -> Result<(), Error> { let mut tx = pool.begin().await?; tracing::info!(from_id, to_id, amount, "Starting fund transfer"); sqlx::query!( "UPDATE accounts SET balance = balance - $1 WHERE id = $2", amount, from_id ) .execute(&mut *tx) .await?; sqlx::query!( "UPDATE accounts SET balance = balance + $1 WHERE id = $2", amount, to_id ) .execute(&mut *tx) .await?; tx.commit().await?; tracing::info!(from_id, to_id, amount, "Fund transfer completed"); Ok(()) } ``` ### References - [OpenTelemetry Rust Documentation](https://opentelemetry.io/docs/languages/rust/) - [tracing crate documentation](https://docs.rs/tracing/latest/tracing/) - [tracing-opentelemetry documentation](https://docs.rs/tracing-opentelemetry/latest/tracing_opentelemetry/) - [OpenTelemetry Semantic Conventions](https://opentelemetry.io/docs/specs/semconv/) ### Related Guides - [Rust LLM Observability][rust-llm] - GenAI semantic conventions, token/cost tracking, multi-provider LLM instrumentation for Rust AI apps - [Axum Auto-Instrumentation Guide](../auto-instrumentation/axum.md) - [Creating Alerts with LogX](../../../guides/creating-alerts-with-logx.md) - [Create Your First Dashboard](../../../guides/create-your-first-dashboard.md) [rust-llm]: ../../../../guides/ai-observability/rust-llm-observability --- ## Hello World - Send Your First Trace ### What You Will Build A command-line app that creates three OpenTelemetry spans - a successful greeting, a disk-space warning, and a config-parsing error - and sends traces, logs, and metrics to your Scout collector. After running it you will see all three signal types correlated in TraceX and LogX. This guide covers all 9 officially supported languages. ### Prerequisites - A Scout account with a collector running ([5-Minute Quick Start](/guides/quick-start) if you haven't set one up yet) - The language runtime for the tab you pick installed on your machine - Your collector endpoint (default `http://localhost:4318`) ### Choose Your Language import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; **Node.js** #### Install Dependencies ```json title="package.json" showLineNumbers { "name": "hello-world-nodejs", "version": "1.0.0", "private": true, "dependencies": { "@opentelemetry/api": "^1.9.0", "@opentelemetry/api-logs": "^0.213.0", "@opentelemetry/exporter-logs-otlp-http": "^0.213.0", "@opentelemetry/exporter-metrics-otlp-http": "^0.213.0", "@opentelemetry/exporter-trace-otlp-http": "^0.213.0", "@opentelemetry/resources": "^2.6.0", "@opentelemetry/sdk-logs": "^0.213.0", "@opentelemetry/sdk-metrics": "^2.6.0", "@opentelemetry/sdk-trace-base": "^2.6.0", "@opentelemetry/sdk-trace-node": "^2.6.0" } } ``` ```bash npm install ``` #### The Code ```js title="main.js" showLineNumbers function sayHello(tracer, otelLogger, helloCounter) { tracer.startActiveSpan("say-hello", (span) => { otelLogger.emit({ severityText: "INFO", severityNumber: SeverityNumber.INFO, body: "Hello, World!", }); helloCounter.add(1); span.setAttribute("greeting", "Hello, World!"); span.end(); }); } ``` The full example also includes `checkDiskSpace` (warning) and `parseConfig` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/nodejs/hello-world/main.js) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 node main.js ``` **Python** #### Install Dependencies ```txt title="requirements.txt" showLineNumbers opentelemetry-api~=1.42 opentelemetry-sdk~=1.42 opentelemetry-exporter-otlp-proto-http~=1.42 ``` ```bash pip install -r requirements.txt ``` #### The Code ```python title="main.py" showLineNumbers def say_hello(): with tracer.start_as_current_span("say-hello") as span: logger.info("Hello, World!") hello_counter.add(1) span.set_attribute("greeting", "Hello, World!") ``` The full example also includes `check_disk_space` (warning) and `parse_config` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/python/hello-world/main.py) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 python main.py ``` **Go** #### Install Dependencies ```go title="go.mod" showLineNumbers module hello-world-go go 1.25.0 require ( go.opentelemetry.io/otel v1.42.0 go.opentelemetry.io/otel/exporters/otlp/otlplog/otlploghttp v0.18.0 go.opentelemetry.io/otel/exporters/otlp/otlpmetric/otlpmetrichttp v1.42.0 go.opentelemetry.io/otel/exporters/otlp/otlptrace/otlptracehttp v1.42.0 go.opentelemetry.io/otel/log v0.18.0 go.opentelemetry.io/otel/metric v1.42.0 go.opentelemetry.io/otel/sdk v1.42.0 go.opentelemetry.io/otel/sdk/log v0.18.0 go.opentelemetry.io/otel/sdk/metric v1.42.0 go.opentelemetry.io/otel/trace v1.42.0 ) ``` ```bash go mod tidy ``` #### The Code ```go title="main.go" showLineNumbers func sayHello(ctx context.Context, tracer trace.Tracer, logger log.Logger, counter metric.Int64Counter) { ctx, span := tracer.Start(ctx, "say-hello") defer span.End() var rec log.Record rec.SetSeverityText("INFO") rec.SetSeverity(log.SeverityInfo) rec.SetBody(log.StringValue("Hello, World!")) logger.Emit(ctx, rec) counter.Add(ctx, 1) span.SetAttributes(attribute.String("greeting", "Hello, World!")) } ``` The full example also includes `checkDiskSpace` (warning) and `parseConfig` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/go/hello-world/main.go) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 go run . ``` **Java** #### Install Dependencies ```xml title="pom.xml (dependencies)" showLineNumbers io.opentelemetry opentelemetry-bom 1.60.1 pom import io.opentelemetry opentelemetry-api io.opentelemetry opentelemetry-sdk io.opentelemetry opentelemetry-exporter-otlp ``` ```bash mvn compile ``` #### The Code ```java title="Main.java" showLineNumbers static void sayHello(Tracer tracer, Logger logger, LongCounter counter) { Span span = tracer.spanBuilder("say-hello").startSpan(); try (var scope = span.makeCurrent()) { logger.logRecordBuilder() .setSeverity(Severity.INFO) .setSeverityText("INFO") .setBody("Hello, World!") .emit(); counter.add(1); span.setAttribute("greeting", "Hello, World!"); } finally { span.end(); } } ``` The full example also includes `checkDiskSpace` (warning) and `parseConfig` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/java/hello-world/src/main/java/Main.java) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 mvn compile exec:java ``` **C#** #### Install Dependencies ```xml title="HelloWorldCsharp.csproj" showLineNumbers Exe net10.0 ``` ```bash dotnet restore ``` #### The Code ```csharp title="Program.cs" showLineNumbers void SayHello() { using var activity = activitySource.StartActivity("say-hello"); activity?.SetTag("greeting", "Hello, World!"); logger.LogInformation("Hello, World!"); helloCounter.Add(1); } ``` The full example also includes `CheckDiskSpace` (warning) and `ParseConfig` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/csharp/hello-world/Program.cs) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 dotnet run ``` **Rust** #### Install Dependencies ```toml title="Cargo.toml" showLineNumbers [package] name = "hello-world-rust" version = "0.1.0" edition = "2021" [dependencies] opentelemetry = "0.32" opentelemetry_sdk = { version = "0.32", features = ["rt-tokio", "logs", "metrics"] } opentelemetry-otlp = { version = "0.32", features = ["http-proto", "trace", "logs", "metrics"] } opentelemetry-appender-tracing = "0.32" tokio = { version = "1", features = ["full"] } tracing = "0.1" tracing-subscriber = { version = "0.3", features = ["env-filter"] } ``` ```bash cargo build ``` #### The Code ```rust title="src/main.rs" showLineNumbers fn say_hello(counter: &opentelemetry::metrics::Counter) { let tracer = global::tracer("hello-world-rust"); tracer.in_span("say-hello", |cx| { let span = cx.span(); span.set_attribute(KeyValue::new("greeting", "Hello, World!")); tracing::info!("Hello, World!"); counter.add(1, &[]); }); } ``` The full example also includes `check_disk_space` (warning) and `parse_config` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/rust/hello-world/src/main.rs) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 cargo run ``` **PHP** #### Install Dependencies ```json title="composer.json" showLineNumbers { "require": { "php": ">=8.1", "open-telemetry/api": "^1.8", "open-telemetry/sdk": "^1.13", "open-telemetry/exporter-otlp": "^1.4", "php-http/guzzle7-adapter": "^1.1" } } ``` ```bash composer install ``` #### The Code ```php title="main.php" showLineNumbers function sayHello(TracerInterface $tracer, $logger, $counter): void { $span = $tracer->spanBuilder('say-hello')->startSpan(); $scope = $span->activate(); try { $logger->emit( (new \OpenTelemetry\API\Logs\LogRecord()) ->setSeverityNumber(Severity::INFO) ->setSeverityText('INFO') ->setBody('Hello, World!') ); $counter->add(1); $span->setAttribute('greeting', 'Hello, World!'); } finally { $scope->detach(); $span->end(); } } ``` The full example also includes `checkDiskSpace` (warning) and `parseConfig` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/php/hello-world/main.php) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 php main.php ``` **Ruby** :::note Traces only The Ruby OpenTelemetry logs SDK is not yet stable. This example sends traces only and uses span events as log equivalents. ::: #### Install Dependencies ```ruby title="Gemfile" showLineNumbers source "https://rubygems.org" gem "opentelemetry-api", "~> 1.8.0" gem "opentelemetry-sdk", "~> 1.10.0" gem "opentelemetry-exporter-otlp", "~> 0.32.0" ``` ```bash bundle install ``` #### The Code ```ruby title="main.rb" showLineNumbers def say_hello(tracer) tracer.in_span("say-hello") do |span| span.set_attribute("greeting", "Hello, World!") span.add_event("greeting.sent", attributes: { "message" => "Hello, World!" }) end end ``` The full example also includes `check_disk_space` (warning event) and `parse_config` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/ruby/hello-world/main.rb) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 ruby main.rb ``` **Elixir** :::note Traces only The Elixir OpenTelemetry logs SDK is not yet stable. This example sends traces only and uses span events as log equivalents. ::: #### Install Dependencies ```elixir title="mix.exs (deps)" showLineNumbers defp deps do [ {:opentelemetry_api, "~> 1.5"}, {:opentelemetry, "~> 1.7"}, {:opentelemetry_exporter, "~> 1.10"} ] end ``` ```bash mix deps.get ``` #### The Code ```elixir title="lib/hello_world.ex" showLineNumbers def say_hello do Tracer.with_span "say-hello" do Tracer.set_attribute(:greeting, "Hello, World!") Tracer.add_event("greeting.sent", %{message: "Hello, World!"}) end end ``` The full example also includes `check_disk_space` (warning event) and `parse_config` (error with exception). [View full source on GitHub →](https://github.com/base-14/examples/blob/main/elixir/hello-world/lib/hello_world.ex) #### Run It ```bash OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318 mix run run.exs ``` ### Verify in Scout 1. Open **TraceX** and search for the service name (e.g. `hello-world-nodejs`). 2. Click the trace to see three spans: `say-hello`, `check-disk-space`, and `parse-config`. 3. Open **LogX** - logs from `say-hello` and the other spans carry the same trace ID, so you can jump between the trace and its logs. 4. Check **Metrics** for the `hello.count` counter. ### What Each Span Demonstrates | Span | Signals | What it shows | | ------------------ | ---------------------- | ---------------------------------------------------- | | `say-hello` | trace + log + metric | Normal operation with an INFO log and counter | | `check-disk-space` | trace + log (or event) | Degraded state with a WARN log | | `parse-config` | trace + log (or event) | Error path with exception recording and ERROR status | ### What's Next - [Auto-instrumentation guides](/instrument/apps/auto-instrumentation) - add tracing to your real app with zero code changes - [Custom instrumentation](/instrument/apps/custom-instrumentation) - add manual spans, metrics, and logs where auto-instrumentation doesn't reach - [Create Your First Dashboard](/guides/create-your-first-dashboard) - visualize the metrics you're collecting - [5-Minute Quick Start](/guides/quick-start) - set up the collector if you haven't already --- ## Application Instrumentation - OpenTelemetry Setup Guide ## Application Instrumentation Add observability to your applications with OpenTelemetry. This guide helps you choose the right approach and find documentation for your stack. ### Choose Your Approach | Approach | Best For | Setup Time | Flexibility | |----------|----------|------------|-------------| | **[Auto-Instrumentation](./auto-instrumentation/)** | Quick start, standard frameworks | Minutes | Pre-defined spans | | **[Custom Instrumentation](./custom-instrumentation/)** | Business metrics, fine control | Hours | Full control | | **[AI Observability](../../guides/ai-observability/)** | LLM calls, agents, token/cost tracking | Hours | GenAI semantic conventions | | **All three** | Production AI applications | Hours | Best of all | ### Quick Reference Matrix Find your language and see what's available: | Language | Auto-Instrumentation | Custom Instrumentation | |----------|---------------------|------------------------| | **Python** | [Django](./auto-instrumentation/django), [Flask](./auto-instrumentation/flask), [FastAPI](./auto-instrumentation/fast-api), [Celery](./auto-instrumentation/celery) | [Python SDK](./custom-instrumentation/python) | | **Node.js** | [Express](./auto-instrumentation/express), [Fastify](./auto-instrumentation/fastify), [NestJS](./auto-instrumentation/nestjs), [Next.js](./auto-instrumentation/nextjs-scout), [Node.js](./auto-instrumentation/nodejs) | [Node SDK](./custom-instrumentation/javascript-node) | | **Java** | [Spring Boot](./auto-instrumentation/spring-boot), [Quarkus](./auto-instrumentation/quarkus) | [Java SDK](./custom-instrumentation/java) | | **Go** | [Go](./auto-instrumentation/go), [Axum](./auto-instrumentation/axum) | [Go SDK](./custom-instrumentation/go) | | **Ruby** | [Rails](./auto-instrumentation/rails), [Rails Legacy](./auto-instrumentation/rails-legacy) | [Ruby SDK](./custom-instrumentation/ruby) | | **PHP** | [Laravel](./auto-instrumentation/laravel) | [PHP SDK](./custom-instrumentation/php) | | **.NET** | [ASP.NET Core](./auto-instrumentation/dotnet) | [C# SDK](./custom-instrumentation/csharp) | | **Elixir** | [Phoenix](./auto-instrumentation/elixir-phoenix) | - | | **Rust** | - | [Rust SDK](./custom-instrumentation/rust) | | **Browser** | [React](./auto-instrumentation/react) | [Browser SDK](./custom-instrumentation/javascript-browser) | ### Decision Guide import ThemedImage from '@theme/ThemedImage'; ### What Gets Instrumented #### Auto-Instrumentation Captures - **HTTP requests** - Incoming and outgoing, with method, status, URL - **Database queries** - SQL statements, connection info, duration - **External API calls** - gRPC, REST, message queues - **Framework internals** - Middleware, routing, templating #### Custom Instrumentation Adds - **Business transactions** - Order processing, payment flows - **User context** - User ID, tenant ID, session info - **Custom metrics** - Conversion rates, queue depths, cache hit ratios - **Domain-specific spans** - Algorithm execution, batch processing #### AI Observability Adds - **LLM call tracing** - Model, provider, token counts, cost per call - **Agent pipeline spans** - Which agent ran, how long, what failed - **Cost attribution** - Cost by model, agent, or business operation - **Quality evaluation** - LLM output scores tracked over time - **PII-safe telemetry** - Prompt/completion scrubbing before export ### Next Steps 1. **New to OpenTelemetry?** Start with [auto-instrumentation](./auto-instrumentation/) 2. **Need business metrics?** Add [custom instrumentation](./custom-instrumentation/) 3. **Need to collect data?** Set up the [OpenTelemetry Collector](../collector-setup/docker-compose-example.md) --- ## Docker Compose OpenTelemetry Setup ## Docker Compose Collect and monitor Docker container logs using Scout Collector and base14 Scout with a complete `Docker Compose` setup. ### Overview This guide provides a comprehensive setup for collecting Docker container logs and metrics using Scout Collector and forwarding them to base14 Scout. - Set up a complete logging pipeline using `Docker Compose` - Configure Scout Collector for container log and metrics collection - Transform and process logs with custom operators - Forward telemetry data to Scout platform ### Prerequisites - Docker Engine (version 20.10+) installed - Docker Compose (version 2.0+) installed - A base14 Scout account with valid access credentials ### Configuration This section demonstrates how to set up a complete observability pipeline using Docker Compose. The setup includes: - A sample web application with Redis backend - Scout Collector for telemetry collection #### Docker Compose Configuration The following `docker-compose.yml` configuration creates a three-service stack: 1. A web service running a Python application 2. A Redis instance for data storage 3. Scout Collector for telemetry processing ```yaml showLineNumbers title="docker-compose.yml" version: "3.8" x-default-logging: &logging driver: "json-file" options: max-size: "5m" max-file: "2" tag: "{{.Name}}|{{.ImageName}}|{{.ID}}" services: web: build: . command: poetry run uvicorn demo.main:app --host 0.0.0.0 --port 8000 --reload volumes: - .:/demo ports: - "8000:8000" environment: - REDIS_HOST=redis - OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4320 depends_on: redis: condition: service_healthy healthcheck: test: ["CMD", "curl", "-f", "localhost:8000/ping"] logging: *logging redis: image: redis:6 ports: - "6379:6379" logging: *logging healthcheck: test: ["CMD", "redis-cli", "ping"] otel-collector: image: otel/opentelemetry-collector-contrib:0.127.0 container_name: otel-collector deploy: resources: limits: memory: 200M restart: unless-stopped command: ["--config=/etc/otelcol-config.yaml"] user: 0:0 volumes: - /:/hostfs:ro - /var/run/docker.sock:/var/run/docker.sock:ro - /var/lib/docker/containers:/var/lib/docker/containers:ro - ./config:/etc/ ports: - "4319:4319" - "4318:4318" - "55679:55679" # zpages: http://localhost:55679/debug/tracez logging: *logging volumes: postgres_data: ``` #### Collector Configuration The Scout Collector is configured with multiple components to provide comprehensive observability: ##### Key Features - **Metrics Collection**: - Redis metrics monitoring - Docker container stats collection - Application metrics via OTLP protocol - **Log Management**: - Container log collection using JSON driver - Automated log parsing and attribute extraction - Custom log processing pipeline - **Data Export**: - Secure forwarding to base14 Scout platform - OAuth2 authentication - Debug capabilities via zPages UI ##### Components Overview ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: demo client_secret: 01JM94R5DPSZXBGK5QA4D329N5 endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/playground/protocol/openid-connect/token tls: insecure_skip_verify: true exporters: debug: otlphttp/b14: endpoint: https://otel.play.b14.dev/01jm94npk4h8ys63x1kzw2bjes/otlp auth: authenticator: oauth2client tls: insecure_skip_verify: true processors: batch: timeout: 1s send_batch_size: 1024 resource: attributes: - key: service.name value: ${env:SERVICE_NAME} action: upsert receivers: otlp: protocols: http: endpoint: 0.0.0.0:4320 filelog: include: - /var/lib/docker/containers/*/*-json.log operators: - id: parser-docker timestamp: layout: "%Y-%m-%dT%H:%M:%S.%LZ" parse_from: attributes.time type: json_parser - field: attributes.time type: remove - id: extract_metadata_from_docker_tag parse_from: attributes.attrs.tag regex: ^(?P[^\|]+)\|(?P[^\|]+)\|(?P[^$]+)$ type: regex_parser if: "attributes?.attrs?.tag != nil" - from: attributes.name to: resource["docker.container.name"] type: move if: "attributes?.name != nil" - from: attributes.image_name to: resource["docker.image.name"] type: move if: "attributes?.image_name != nil" - from: attributes.id to: resource["docker.container.id"] type: move if: "attributes?.id != nil" - from: attributes.log to: body type: move docker_stats: endpoint: unix:///var/run/docker.sock collection_interval: 20s redis: endpoint: "redis:6379" collection_interval: 20s service: extensions: [oauth2client, zpages] pipelines: traces: receivers: [otlp] processors: [batch] exporters: [otlphttp/b14, debug] metrics: receivers: [otlp, postgresql, redis, rabbitmq, docker_stats] processors: [batch] exporters: [otlphttp/b14, debug] logs: receivers: [otlp, filelog] processors: [batch] exporters: [otlphttp/b14, debug] telemetry: logs: level: info ``` ### Related Guides - [Scout Exporter Configuration](./scout-exporter.md) - Configure authentication to send data to Scout - [Instrument Express.js Apps](../apps/auto-instrumentation/express.md) - Auto-instrument Node.js applications - [Advanced Collector Configuration](./otel-collector-config.md) - Deep dive into collector configuration - [Edge Collector Patterns](../iot/edge-collector-patterns.md) - Store-and-forward and tiered Collector setups for IoT and edge deployments --- ## AWS ECS OpenTelemetry Setup - Fargate & EC2 Collector Deployment ## AWS ECS Deploy and configure the Scout Collector on ECS. ### Overview This guide covers how to collect telemetry data (logs, metrics, and traces) from your ECS environment and send it to base14 Scout. - Install base14 Scout's Scout Collector using Task Definitions. - Configure telemetry collection for ECS Nodes. - Configure custom metrics endpoints - Implement trace collection ### Prerequisites - An ECS cluster - AWS CLI setup with `ecs:*` permissions. - Scout account credentials - Endpoint URL - API Key - Token URL - Application Name ### Quick Start Guide Deploy Scout Collector in minutes by following these steps: #### Task Definitions ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` For Fargate, you can deploy the Scout collector in different modes: **Service Mode** **Best for**: Centralized telemetry collection and processing - Runs as a standalone REPLICA service - Collects telemetry from multiple applications and AWS services - Ideal for collecting metrics from RDS, ElastiCache, Amazon MQ, and application traces Download the required files: ```shell curl -o task-definition.json \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/fargate/task-definition.json curl -o scout-service-collector-config.yaml \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/fargate/scout-collector-config.yaml ``` :::warning - This service mode collector can include receivers for AWS services (RDS, ElastiCache, Amazon MQ) and external databases. - Review the configuration to add or remove pipelines based on your monitoring needs. - Visit [docs.base14.io](https://docs.base14.io/instrument/collector-setup/otel-collector-config) for more details on the configuration. ::: ##### Generate Configuration Replace the placeholders with your actual values: ```shell SERVICE_NAME='' \ ENVIRONMENT='' \ SCOUT_ENDPOINT='' \ SCOUT_CLIENT_ID='' \ SCOUT_CLIENT_SECRET='' \ SCOUT_TOKEN_URL='' \ envsubst < scout-service-collector-config.yaml > scout-service-collector-config.yaml.tmp && \ mv scout-service-collector-config.yaml.tmp scout-service-collector-config.yaml ``` ##### Store Configuration in AWS Secrets Manager ```shell # Create secret for service collector configuration aws secretsmanager create-secret \ --name "/ecs/scout/otelcol-service-config" \ --description "Scout OTEL Service Collector Configuration for Fargate" \ --secret-string file://scout-service-collector-config.yaml ``` If the secret already exists, update it: ```shell aws secretsmanager update-secret \ --secret-id "/ecs/scout/otelcol-service-config" \ --secret-string file://scout-service-collector-config.yaml ``` ##### Get Secret ARN After creating the secret, retrieve its full ARN (required for task definition): ```shell aws secretsmanager describe-secret \ --secret-id "/ecs/scout/otelcol-service-config" \ --query 'ARN' \ --output text ``` Save this ARN - you'll need it in the next step. ##### Generate Task Definition Replace the placeholders with your actual values: ```shell AWS_TASK_EXECUTION_ROLE='' \ TASK_NAME='Scout_service_collector' \ SERVICE_NAME='Scout_service_collector' \ SECRET_ARN='' \ envsubst < task-definition.json > scout-service-collector-task-definition.json ``` :::tip To find your ECS task execution role ARN: ```shell aws iam list-roles --query 'Roles[?RoleName==`ecsTaskExecutionRole`].Arn' --output text ``` ::: ##### Register Task Definition Register the task definition with ECS: ```shell aws ecs register-task-definition \ --cli-input-json file://scout-service-collector-task-definition.json ``` ##### Get Network Configuration Fargate requires network configuration. Get your VPC subnets and security groups: ```shell # Get default VPC subnets aws ec2 describe-subnets \ --filters "Name=default-for-az,Values=true" \ --query 'Subnets[*].SubnetId' \ --output text # Get the VPC ID from one of the subnets VPC_ID=$(aws ec2 describe-subnets \ --subnet-ids \ --query 'Subnets[0].VpcId' \ --output text) # Get the default security group for the VPC aws ec2 describe-security-groups \ --filters "Name=vpc-id,Values=$VPC_ID" "Name=group-name,Values=default" \ --query 'SecurityGroups[0].GroupId' \ --output text ``` ##### Deploy Service Create the ECS service with network configuration: ```shell aws ecs create-service \ --cluster \ --service-name scout-service-collector \ --task-definition Scout_service_collector:1 \ --scheduling-strategy REPLICA \ --desired-count 1 \ --launch-type FARGATE \ --network-configuration "awsvpcConfiguration={subnets=[,,],securityGroups=[],assignPublicIp=ENABLED}" ``` :::warning - Replace `` with your ECS cluster name - Replace subnet IDs with the values from the previous step - Replace security group ID with the value from the previous step - Ensure all subnets belong to the same VPC as the security group ::: ##### Verify Deployment Check the service status: ```shell aws ecs describe-services \ --cluster \ --services scout-service-collector \ --query 'services[0].{Name:serviceName,Status:status,Running:runningCount,Desired:desiredCount}' \ --output table ``` Wait for the task to reach RUNNING status (may take 1-2 minutes): ```shell # List running tasks aws ecs list-tasks \ --cluster \ --service-name scout-service-collector \ --desired-status RUNNING # Check task details aws ecs describe-tasks \ --cluster \ --tasks \ --query 'tasks[0].{Status:lastStatus,Health:healthStatus,Container:containers[0].name}' \ --output table ``` If the task stops or fails, check the stopped reason: ```shell aws ecs describe-tasks \ --cluster \ --tasks \ --query 'tasks[0].stoppedReason' ``` **Sidecar Mode** **Best for**: Application-specific telemetry collection - Runs alongside your application containers in the same task - Dedicated collector per application task - Ideal for collecting application traces, logs, and custom metrics Download the required files: ```shell curl -o task-definition.json \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/fargate/task-definition.json curl -o scout-sidecar-collector-config.yaml \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/fargate/scout-sidecar-collector-config.yaml ``` :::warning - The sidecar collector should focus on application-specific telemetry only. - Avoid including AWS service receivers (RDS, ElastiCache) in sidecar mode to prevent duplication. - Configure this collector to receive OTLP data from your application containers. - Visit [docs.base14.io](https://docs.base14.io/instrument/collector-setup/otel-collector-config) for more details on the configuration. ::: ##### Generate Configuration Replace the placeholders with your actual values: ```shell SERVICE_NAME='' \ ENVIRONMENT='' \ SCOUT_ENDPOINT='' \ SCOUT_CLIENT_ID='' \ SCOUT_CLIENT_SECRET='' \ SCOUT_TOKEN_URL='' \ envsubst < scout-sidecar-collector-config.yaml > scout-sidecar-collector-config.yaml.tmp && \ mv scout-sidecar-collector-config.yaml.tmp scout-sidecar-collector-config.yaml ``` ##### Store Configuration in AWS Secrets Manager ```shell # Create secret for sidecar collector configuration aws secretsmanager create-secret \ --name "/ecs/scout/otelcol-sidecar-config" \ --description "Scout OTEL Sidecar Collector Configuration for Fargate" \ --secret-string file://scout-sidecar-collector-config.yaml ``` If the secret already exists, update it: ```shell aws secretsmanager update-secret \ --secret-id "/ecs/scout/otelcol-sidecar-config" \ --secret-string file://scout-sidecar-collector-config.yaml ``` ##### Generate Task Definition ```shell export AWS_TASK_EXECUTION_ROLE= AWS_TASK_EXECUTION_ROLE=${AWS_TASK_EXECUTION_ROLE} \ TASK_NAME='Scout_sidecar_collector' \ SERVICE_NAME='Scout_sidecar_collector' \ SECRET_NAME='/ecs/scout/otelcol-sidecar-config' \ envsubst < task-definition.json > scout-sidecar-collector-task-definition.json ``` ##### Add to Your Application Task Definition Instead of creating a separate service, add the Scout collector container to your existing application task definition as a sidecar: ```json { "name": "scout-sidecar-collector", "image": "otel/opentelemetry-collector-contrib:0.130.0", "essential": false, "secrets": [ { "name": "SCOUT_CONFIG_CONTENT", "valueFrom": "/ecs/scout/otelcol-sidecar-config" } ], "command": ["--config=env:SCOUT_CONFIG_CONTENT"], "portMappings": [ { "containerPort": 4317, "protocol": "tcp" }, { "containerPort": 4318, "protocol": "tcp" } ] } ``` ##### Update IAM Permissions Your ECS Task Execution Role needs permission to access Secrets Manager. First, create the IAM policy document: ```shell cat > /tmp/secrets-policy.json << 'EOF' { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": ["secretsmanager:GetSecretValue"], "Resource": [ "arn:aws:secretsmanager:::secret:/ecs/scout/otelcol-service-config*", "arn:aws:secretsmanager:::secret:/ecs/scout/otelcol-sidecar-config*" ] } ] } EOF ``` Replace `` and `` with your values: - Region: The AWS region where you created the secret (e.g., `us-east-1`) - Account ID: Your 12-digit AWS account ID Then attach the policy to your task execution role: ```shell aws iam put-role-policy \ --role-name ecsTaskExecutionRole \ --policy-name ScoutSecretsAccess \ --policy-document file:///tmp/secrets-policy.json ``` :::warning Common Error If you skip this step, your tasks will fail with: `ResourceInitializationError: unable to retrieve secrets from ssm` This happens because the task execution role cannot access the secret stored in Secrets Manager. ::: ```mdx-code-block ``` For managed nodes (EC2), you can deploy the Scout collector in different modes: **Service Mode** **Best for**: Application-specific telemetry collection and custom instrumentation - Runs as a REPLICA service alongside your applications - Ideal for collecting traces, application logs, and database metrics Download the required files: ```shell curl -o agent-task-definition.json \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/agent-task-definition.json curl -o scout-agent-collector-config.yaml \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/scout-agent-collector-config.yaml ``` :::warning - Use PostgreSQL, Redis, RabbitMQ, AWS Firehose, etc., receivers in the agent collector to avoid data duplication. - Review the configuration to remove or add new pipelines before proceeding. - The agent collector uses host ports 4327 (gRPC) and 4328 (HTTP) to avoid conflicts with the daemon collector's standard ports (4317/4318). - Visit [docs.base14.io](https://docs.base14.io/instrument/collector-setup/otel-collector-config) for more details on the configuration. ::: ##### Generate Configuration ```shell SERVICE_NAME='' \ ENVIRONMENT='' \ SCOUT_ENDPOINT='' \ SCOUT_CLIENT_ID='' \ SCOUT_CLIENT_SECRET='' \ SCOUT_TOKEN_URL='' \ envsubst < scout-agent-collector-config.yaml > scout-agent-collector-config.yaml.tmp && \ mv scout-agent-collector-config.yaml.tmp scout-agent-collector-config.yaml ``` ##### Store Configuration in AWS Secrets Manager ```shell # Create secret for agent collector configuration aws secretsmanager create-secret \ --name "/ecs/scout/otelcol-agent-config" \ --description "Scout OTEL Agent Collector Configuration for EC2" \ --secret-string file://scout-agent-collector-config.yaml ``` If the secret already exists, update it: ```shell aws secretsmanager update-secret \ --secret-id "/ecs/scout/otelcol-agent-config" \ --secret-string file://scout-agent-collector-config.yaml ``` ##### Get Secret ARN After creating the secret, retrieve its full ARN (required for task definition): ```shell aws secretsmanager describe-secret \ --secret-id "/ecs/scout/otelcol-agent-config" \ --query 'ARN' \ --output text ``` Save this ARN - you'll need it in the next step. ##### Generate Task Definition Replace the placeholders with your actual values: ```shell AWS_TASK_EXECUTION_ROLE='' \ TASK_NAME='Scout_agent_collector' \ SERVICE_NAME='Scout_agent_collector' \ SECRET_ARN='' \ envsubst < agent-task-definition.json > scout-agent-collector-task-definition.json ``` :::tip To find your ECS task execution role ARN: ```shell aws iam list-roles --query 'Roles[?RoleName==`ecsTaskExecutionRole`].Arn' --output text ``` ::: ##### Register Task Definition Register the task definition with ECS: ```shell aws ecs register-task-definition \ --cli-input-json file://scout-agent-collector-task-definition.json ``` ##### Deploy Service ```shell aws ecs create-service \ --cluster \ --service-name scout-agent-collector \ --task-definition Scout_agent_collector:1 \ --scheduling-strategy REPLICA \ --desired-count 1 \ --launch-type EC2 ``` ##### Verify Deployment Check the service status: ```shell aws ecs describe-services \ --cluster \ --services scout-agent-collector \ --query 'services[0].{Name:serviceName,Status:status,Running:runningCount,Desired:desiredCount}' \ --output table ``` **Daemon Mode** **Best for**: Infrastructure monitoring and system-level metrics - Runs one collector per EC2 instance using DAEMON strategy - Ideal for collecting ECS container metrics, host metrics, and system logs Download the required files: ```shell curl -o daemon-task-definition.json \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/daemon-task-definition.json curl -o scout-daemon-collector-config.yaml \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/scout-daemon-collector-config.yaml ``` :::warning - The daemon collector focuses on infrastructure metrics and should not include application-specific receivers. - Review the configuration to remove or add new pipelines before proceeding. - Visit [docs.base14.io](https://docs.base14.io/instrument/collector-setup/otel-collector-config) for more details on the configuration. ::: ##### Generate Configuration ```shell SERVICE_NAME='' \ ENVIRONMENT='' \ SCOUT_ENDPOINT='' \ SCOUT_CLIENT_ID='' \ SCOUT_CLIENT_SECRET='' \ SCOUT_TOKEN_URL='' \ envsubst < scout-daemon-collector-config.yaml > scout-daemon-collector-config.yaml.tmp && \ mv scout-daemon-collector-config.yaml.tmp scout-daemon-collector-config.yaml ``` ##### Store Configuration in AWS Secrets Manager ```shell # Create secret for daemon collector configuration aws secretsmanager create-secret \ --name "/ecs/scout/otelcol-daemon-config" \ --description "Scout OTEL Daemon Collector Configuration for EC2" \ --secret-string file://scout-daemon-collector-config.yaml ``` If the secret already exists, update it: ```shell aws secretsmanager update-secret \ --secret-id "/ecs/scout/otelcol-daemon-config" \ --secret-string file://scout-daemon-collector-config.yaml ``` ##### Get Secret ARN After creating the secret, retrieve its full ARN (required for task definition): ```shell aws secretsmanager describe-secret \ --secret-id "/ecs/scout/otelcol-daemon-config" \ --query 'ARN' \ --output text ``` Save this ARN - you'll need it in the next step. ##### Generate Task Definition Replace the placeholders with your actual values: ```shell AWS_TASK_EXECUTION_ROLE='' \ TASK_NAME='Scout_daemon_collector' \ SERVICE_NAME='Scout_daemon_collector' \ SECRET_ARN='' \ envsubst < daemon-task-definition.json > scout-daemon-collector-task-definition.json ``` :::tip To find your ECS task execution role ARN: ```shell aws iam list-roles --query 'Roles[?RoleName==`ecsTaskExecutionRole`].Arn' --output text ``` ::: ##### Register Task Definition Register the task definition with ECS: ```shell aws ecs register-task-definition \ --cli-input-json file://scout-daemon-collector-task-definition.json ``` ##### Deploy Daemon Service ```shell aws ecs create-service \ --cluster \ --service-name scout-daemon-collector \ --task-definition Scout_daemon_collector:1 \ --scheduling-strategy DAEMON \ --launch-type EC2 ``` ##### Verify Deployment Check the service status: ```shell aws ecs describe-services \ --cluster \ --services scout-daemon-collector \ --query 'services[0].{Name:serviceName,Status:status,Running:runningCount,Desired:desiredCount}' \ --output table ``` **Hybrid Mode** **Best for**: Complete observability with both infrastructure and application telemetry - Combines both daemon and service deployments - Daemon collector handles infrastructure metrics - Service collector handles application telemetry This approach deploys both daemon and service collectors for comprehensive monitoring. Download all required files: ```shell curl -o daemon-task-definition.json \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/daemon-task-definition.json curl -o agent-task-definition.json \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/agent-task-definition.json curl -o scout-daemon-collector-config.yaml \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/scout-daemon-collector-config.yaml curl -o scout-agent-collector-config.yaml \ https://raw.githubusercontent.com/base-14/docs/main/configs/ecs/ec2/scout-agent-collector-config.yaml ``` :::warning - Use PostgreSQL, Redis, RabbitMQ, AWS Firehose, etc., receivers in the agent collector to avoid data duplication between daemon and agent collectors. - The daemon collector should focus on infrastructure metrics only. - Review both configurations to remove or add new pipelines before proceeding. - Visit [docs.base14.io](https://docs.base14.io/instrument/collector-setup/otel-collector-config) for more details on the configuration. ::: ##### Generate Configuration ```shell SERVICE_NAME='' \ ENVIRONMENT='' \ SCOUT_ENDPOINT='' \ SCOUT_CLIENT_ID='' \ SCOUT_CLIENT_SECRET='' \ SCOUT_TOKEN_URL='' \ envsubst < scout-agent-collector-config.yaml > scout-agent-collector-config.yaml.tmp && \ mv scout-agent-collector-config.yaml.tmp scout-agent-collector-config.yaml SERVICE_NAME='' \ ENVIRONMENT='' \ SCOUT_ENDPOINT='' \ SCOUT_CLIENT_ID='' \ SCOUT_CLIENT_SECRET='' \ SCOUT_TOKEN_URL='' \ envsubst < scout-daemon-collector-config.yaml > scout-daemon-collector-config.yaml.tmp && \ mv scout-daemon-collector-config.yaml.tmp scout-daemon-collector-config.yaml ``` ##### Store Configurations in AWS Secrets Manager ```shell # Create secrets for both daemon and agent collector configurations aws secretsmanager create-secret \ --name "/ecs/scout/otelcol-daemon-config" \ --description "Scout OTEL Daemon Collector Configuration for EC2" \ --secret-string file://scout-daemon-collector-config.yaml aws secretsmanager create-secret \ --name "/ecs/scout/otelcol-agent-config" \ --description "Scout OTEL Agent Collector Configuration for EC2" \ --secret-string file://scout-agent-collector-config.yaml ``` ##### Get Secret ARNs Retrieve the ARNs for both secrets (required for task definitions): ```shell # Get daemon config secret ARN aws secretsmanager describe-secret \ --secret-id "/ecs/scout/otelcol-daemon-config" \ --query 'ARN' \ --output text # Get agent config secret ARN aws secretsmanager describe-secret \ --secret-id "/ecs/scout/otelcol-agent-config" \ --query 'ARN' \ --output text ``` Save both ARNs - you'll need them in the next step. ##### Generate Both Task Definitions Replace the placeholders with your actual values: ```shell # Generate daemon collector task definition AWS_TASK_EXECUTION_ROLE='' \ TASK_NAME='Scout_daemon_collector' \ SERVICE_NAME='Scout_daemon_collector' \ SECRET_ARN='' \ envsubst < daemon-task-definition.json > scout-daemon-collector-task-definition.json # Generate agent collector task definition AWS_TASK_EXECUTION_ROLE='' \ TASK_NAME='Scout_agent_collector' \ SERVICE_NAME='Scout_agent_collector' \ SECRET_ARN='' \ envsubst < agent-task-definition.json > scout-agent-collector-task-definition.json ``` :::tip To find your ECS task execution role ARN: ```shell aws iam list-roles --query 'Roles[?RoleName==`ecsTaskExecutionRole`].Arn' --output text ``` ::: ##### Register Both Task Definitions Register both task definitions with ECS: ```shell # Register daemon task definition aws ecs register-task-definition \ --cli-input-json file://scout-daemon-collector-task-definition.json # Register agent task definition aws ecs register-task-definition \ --cli-input-json file://scout-agent-collector-task-definition.json ``` ##### Deploy Both Services ```shell # Deploy daemon service (one per EC2 instance) aws ecs create-service \ --cluster \ --service-name scout-daemon-collector \ --task-definition Scout_daemon_collector:1 \ --scheduling-strategy DAEMON \ --launch-type EC2 # Deploy agent service (replica for applications) aws ecs create-service \ --cluster \ --service-name scout-agent-collector \ --task-definition Scout_agent_collector:1 \ --scheduling-strategy REPLICA \ --desired-count 1 \ --launch-type EC2 ``` ##### Verify Deployments Check both services status: ```shell # Check daemon service aws ecs describe-services \ --cluster \ --services scout-daemon-collector \ --query 'services[0].{Name:serviceName,Status:status,Running:runningCount,Desired:desiredCount}' \ --output table # Check agent service aws ecs describe-services \ --cluster \ --services scout-agent-collector \ --query 'services[0].{Name:serviceName,Status:status,Running:runningCount,Desired:desiredCount}' \ --output table ``` ##### Update IAM Permissions Your ECS Task Execution Role needs permission to access Secrets Manager. First, create the IAM policy document (adjust resources based on your selected deployment mode): ```shell cat > /tmp/secrets-policy-ec2.json << 'EOF' { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": ["secretsmanager:GetSecretValue"], "Resource": [ "arn:aws:secretsmanager:::secret:/ecs/scout/otelcol-daemon-config*", "arn:aws:secretsmanager:::secret:/ecs/scout/otelcol-agent-config*" ] } ] } EOF ``` Then attach the policy to your task execution role: ```shell aws iam put-role-policy \ --role-name ecsTaskExecutionRole \ --policy-name ScoutSecretsAccessEC2 \ --policy-document file:///tmp/secrets-policy-ec2.json ``` :::warning Common Error If you skip this step, your tasks will fail with: `ResourceInitializationError: unable to retrieve secrets from ssm` ::: ```mdx-code-block ``` That's it, you're done! Go to the Scout Dashboards to see the data flowing. ### Related Guides - [Scout Exporter Configuration](./scout-exporter.md) - Configure authentication to send data to Scout - [AWS RDS Monitoring](../infra/aws/rds.md) - Monitor your RDS databases - [Kubernetes Helm Setup](./kubernetes-helm-setup.md) - Alternative container orchestration platform --- ## JMX Monitoring with OpenTelemetry - JMX Scraper vs Prometheus JMX Exporter Comparison ## JMX Monitoring with OpenTelemetry There are two ways to collect JMX metrics from Java applications with OpenTelemetry: the **[OTel JMX Scraper](https://github.com/open-telemetry/opentelemetry-java-instrumentation/tree/main/instrumentation/jmx-metrics)** (a standalone process that connects remotely via RMI) and the **[Prometheus JMX Exporter](https://github.com/prometheus/jmx_exporter)** (a Java agent that runs inside the target JVM). Both convert JMX MBeans into time-series metrics for the OpenTelemetry Collector. This guide compares their architecture, configuration, and trade-offs so you can choose the right approach for your environment. **Short version**: Use the JMX Scraper if a [built-in target](#which-components-have-built-in-jmx-scraper-targets) exists for your application and you want an OTel-native pipeline with no JVM modifications. Use the Prometheus JMX Exporter if you need custom MBean rules, remote JMX is blocked, or you have existing Prometheus tooling. ### How JMX Monitoring Works JMX (Java Management Extensions) is a standard API built into every JVM. Applications register managed objects called MBeans - structured data points like `Catalina:type=ThreadPool,name="http-nio-8080"` - that expose operational state: thread counts, request rates, memory usage, cache hit ratios, and connection pool sizes. MBeans are available through the JVM's built-in MBean server, either locally (same process) or remotely (via RMI on a configured port). Neither the JMX Scraper nor the JMX Exporter changes how MBeans work. They simply read them and convert them into time-series metrics. The Scraper connects remotely via RMI and exports OTLP directly. The Exporter runs as a Java agent inside the target JVM and exposes a Prometheus `/metrics` endpoint. ### Architecture Comparison #### OTel JMX Scraper ```text ┌─────────────┐ JMX/RMI ┌──────────────┐ OTLP ┌───────────┐ ┌───────┐ │ Java App │◄───────────────│ JMX Scraper │────────────►│ Collector │─────────►│ Scout │ │ (JMX:9010) │ │ (standalone)│ │ │ │ │ └─────────────┘ └──────────────┘ └───────────┘ └───────┘ ``` The JMX Scraper is a standalone Java process. It connects to the application's JMX port over RMI, reads MBeans, and pushes metrics to the Collector via OTLP. #### Prometheus JMX Exporter ```text ┌──────────────────────────┐ Prometheus ┌───────────┐ ┌───────┐ │ Java App + JMX Agent │ scrape │ Collector │─────────►│ Scout │ │ (javaagent on :9404) │◄───────────────│ │ │ │ │ exposes /metrics │ └───────────┘ └───────┘ └──────────────────────────┘ ``` The JMX Exporter runs as a `-javaagent` inside the target JVM. It reads MBeans locally, converts them to Prometheus format, and serves them on an HTTP endpoint. The Collector scrapes this endpoint with its Prometheus receiver. ### Side-by-Side Comparison | Aspect | OTel JMX Scraper | Prometheus JMX Exporter | | ----------------------- | ---------------------------------------- | ---------------------------------------------- | | **Deployment** | Standalone Java process (sidecar or host) | Java agent inside the target JVM | | **Protocol** | JMX/RMI to app, OTLP to Collector | In-process MBean read, Prometheus HTTP to Collector | | **Metric format** | OTLP (native OpenTelemetry) | Prometheus exposition format | | **Config complexity** | Low - env vars only, no config files | Medium - requires YAML rules for MBean mapping | | **Runtime overhead** | Separate JVM for the scraper | Runs in-process, no extra JVM | | **Built-in targets** | 8 targets: Tomcat, Kafka, ActiveMQ, Jetty, WildFly, Hadoop, Camel, JVM | 19 [example configs](https://github.com/prometheus/jmx_exporter/tree/main/examples): Cassandra, Kafka, Tomcat, Spark, Flink, ZooKeeper, and more | | **Custom MBean rules** | Supported via YAML config (`OTEL_JMX_CUSTOM_CONFIG`) | Full regex-based pattern matching | | **Networking** | Requires JMX port accessible over network | Only needs HTTP port for Prometheus scrape | | **JVM modification** | None - connects remotely | Requires `-javaagent` flag on target JVM | | **Authentication** | Remote JMX auth via `OTEL_JMX_USERNAME`/`OTEL_JMX_PASSWORD`, supports SSL | Not needed - agent reads MBeans in-process, no remote connection | ### When to Use Which Some applications - Tomcat, Kafka, ActiveMQ, WildFly - have both a built-in Scraper target and an Exporter example config. When both are available, prefer the **JMX Scraper**: it produces OTel-native metrics out of the box, requires no config files, and doesn't touch the application's JVM. Choose the Exporter instead only if you need to expose MBeans the Scraper's built-in target doesn't cover, remote JMX is blocked in your network, or your monitoring stack already consumes Prometheus-format metrics. #### Use the OTel JMX Scraper When The JMX Scraper is the better fit for most OTel-native deployments where a built-in target covers your application. - **A built-in target exists** for your application (Tomcat, Kafka, ActiveMQ, Jetty, WildFly, Hadoop, Camel). The scraper ships pre-defined metric definitions - no MBean pattern rules needed. - **You want an OTel-native pipeline** - the scraper exports OTLP directly, avoiding a Prometheus-to-OTLP conversion step. - **You cannot modify the target JVM** - the scraper connects remotely via RMI, so you only need JMX enabled on the application (no agent JAR to inject). - **You prefer env-var-driven configuration** - no YAML config files needed for built-in targets. #### Use the Prometheus JMX Exporter When The JMX Exporter is the better fit when you need full control over MBean mapping or cannot expose a JMX port on the network. - **Remote JMX access is blocked** - the exporter runs inside the JVM, bypassing network-level JMX restrictions. Only an HTTP port needs to be reachable. - **You need custom MBean mapping** - the exporter's regex-based rules give full control over which MBeans are exported and how they're named and labeled. - **You have existing Prometheus tooling** - if Grafana, alerting rules, or dashboards already consume Prometheus metrics, the exporter integrates without format conversion. - **No built-in scraper target exists** for your application (e.g., Cassandra, Solr, custom Java services). ### Minimal Configuration Examples These snippets show the pattern for each approach. For complete end-to-end setups, see the linked component guides. #### JMX Scraper (Tomcat Example) ```bash showLineNumbers title="Run the JMX Scraper" OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://tomcat:9010/jmxrmi \ OTEL_JMX_TARGET_SYSTEM=jvm,tomcat \ OTEL_EXPORTER_OTLP_ENDPOINT=http://otel-collector:4317 \ OTEL_METRIC_EXPORT_INTERVAL=10000 \ java -jar opentelemetry-jmx-scraper-1.54.0-alpha.jar ``` ```yaml showLineNumbers title="otel-collector.yaml (OTLP receiver)" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: metrics: receivers: [otlp] exporters: [otlphttp/b14] ``` Full setup: [Tomcat Monitoring](../component/tomcat.md) #### Prometheus JMX Exporter (Cassandra Example) ```bash showLineNumbers title="Add the agent to the target JVM" JVM_EXTRA_OPTS="-javaagent:/opt/jmx_prometheus_javaagent.jar=9404:/opt/jmx-config.yaml" ``` ```yaml showLineNumbers title="otel-collector.yaml (Prometheus receiver)" receivers: prometheus: config: scrape_configs: - job_name: cassandra scrape_interval: 30s static_configs: - targets: - cassandra:9404 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: metrics: receivers: [prometheus] exporters: [otlphttp/b14] ``` Full setup: [Cassandra Monitoring](../component/cassandra.md) ### What About the OTel Collector JMX Receiver? The `jmxreceiver` component was deprecated in January 2026 and should not be used for new deployments. It required a JRE installed inside the Collector container and spawned a Java subprocess to connect to remote JMX endpoints. The standalone [JMX Scraper](https://github.com/open-telemetry/opentelemetry-java-instrumentation/tree/main/instrumentation/jmx-metrics) replaces it with the same metric definitions and a cleaner operational model - the scraper runs as its own process and exports metrics over OTLP. If you are migrating from the `jmxreceiver`, the JMX Scraper uses the same `target_system` values and metric names - switch by running the scraper JAR with equivalent `OTEL_JMX_*` environment variables and pointing it at your Collector's OTLP receiver. ### FAQ #### Can I use both approaches in the same environment? Yes. Each approach feeds metrics into the Collector through a different receiver (OTLP for the scraper, Prometheus for the exporter). You can monitor Tomcat with the JMX Scraper and Cassandra with the JMX Exporter in the same Collector pipeline. Define both receivers in the Collector config and include them in the metrics pipeline. #### Which approach works better in Kubernetes? Both work well in Kubernetes. The JMX Scraper runs as a sidecar container in the same pod, connecting to `localhost:`. The JMX Exporter requires no sidecar - the agent runs inside the application container, and the Collector scrapes the metrics endpoint via the pod IP or service DNS. The exporter approach has a smaller footprint since it avoids a second JVM, but the scraper approach avoids modifying the application's JVM flags. #### Does the JMX Scraper support custom MBean rules? Yes. Beyond built-in targets, the scraper accepts a YAML configuration file with custom MBean rules via the `OTEL_JMX_CUSTOM_CONFIG` environment variable. The rule format differs from the Prometheus JMX Exporter - see the [JMX Scraper documentation](https://github.com/open-telemetry/opentelemetry-java-instrumentation/tree/main/instrumentation/jmx-metrics) for syntax details. #### Which components have built-in JMX Scraper targets? As of version 1.54.0, the JMX Scraper includes built-in targets for these eight systems: | Target | `OTEL_JMX_TARGET_SYSTEM` value | Metrics | | ---------- | ------------------------------ | --------------------------------------------------- | | JVM | `jvm` | Heap, GC, threads, CPU, class loading, buffer pools | | Tomcat | `tomcat` | Requests, errors, threads, sessions, network I/O | | Kafka | `kafka-broker` | Broker topics, partitions, consumer lag, log flush | | ActiveMQ | `activemq` | Queues, topics, connections, producers, consumers | | Jetty | `jetty` | Requests, responses, threads, sessions | | WildFly | `wildfly` | Undertow requests, datasource pools, transactions | | Hadoop | `hadoop` | HDFS namenode, datanode, resource manager | | Camel | `camel` | Routes, exchanges, processors, error handling | Each target defines a curated set of metrics without requiring custom MBean rules. For applications not in this list, use the Prometheus JMX Exporter or write custom scraper rules via `OTEL_JMX_CUSTOM_CONFIG`. #### What is the performance impact of each approach? The JMX Scraper runs as a separate JVM, typically consuming 100-200 MB of heap depending on the number of targets and MBeans collected. It connects to the application's JMX port on each scrape interval, which adds minimal network overhead but requires an open RMI connection. The Prometheus JMX Exporter runs inside the application's JVM and adds negligible memory overhead (the agent JAR itself is ~2 MB). It reads MBeans directly from the in-process MBean server on each HTTP scrape request - no network hop, no serialization. For most applications at 30-second scrape intervals, the CPU impact is not measurable. Large deployments with thousands of MBeans (e.g., Cassandra with hundreds of tables) should use exporter `blacklist` rules to limit cardinality. ### Related Guides - [Tomcat Monitoring](../component/tomcat.md) - Full JMX Scraper setup for Apache Tomcat - [ActiveMQ Monitoring](../component/activemq.md) - Full JMX Scraper setup for Apache ActiveMQ Classic - [Jetty Monitoring](../component/jetty.md) - Full JMX Scraper setup for Eclipse Jetty - [WildFly Monitoring](../component/wildfly.md) - Full JMX Scraper setup for WildFly / JBoss EAP - [Cassandra Monitoring](../component/cassandra.md) - Full JMX Exporter setup for Apache Cassandra - [OTel Collector Configuration](./otel-collector-config.md) - Advanced collector configuration - [Docker Compose Setup](./docker-compose-example.md) - Run the Collector locally --- ## Kubernetes OpenTelemetry Setup with Helm ## Kubernetes using Helm Deploy and configure the Scout Collector on Kubernetes using Helm. ### Overview This guide covers how to collect telemetry data (logs, metrics, and traces) from your Kubernetes environment and send it to base14 Scout. - Install base14 Scout's Scout Collector using Helm - Configure telemetry collection for Kubernetes pods - Set up multi-namespace monitoring - Configure custom metrics endpoints - Implement trace collection ### Prerequisites - A Kubernetes cluster (EKS, GKE, AKS, or other distributions) - Helm 3.x installed - `kubectl` configured with cluster access - Scout account credentials - Endpoint URL - Token URL - Client ID and Client Secret - Application Name ### Quick Start Guide Deploy Scout Collector in minutes by following these steps: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash helm repo add base14 https://charts.base14.io/ ``` ```bash helm install scout base14/scout-collector --version 0.5.5 \ --namespace scout --create-namespace -f values.yaml ``` ```mdx-code-block ``` ```bash helm repo add base14 https://charts.base14.io/ ``` ```bash helm install scout base14/scout-collector --version 0.5.5 \ --namespace scout --create-namespace -f values.yaml ``` ```mdx-code-block ``` ### Configuration Guide ### Using Otelcol style configuration Following is an example of a values.yaml file that can be used to configure scout collector using otelcol style configuration. Here the configuration follows the same semantics as the Scout Collector config. This gives a greater flexibility in terms of what you can configure to be scraped, collected etc. Reference the [otel-collector-config](./otel-collector-config.md) for more details. ```mdx-code-block ``` ```yaml showLineNumbers title="values.yaml" scout: endpoint: __YOUR_ENDPOINT__ tokenUrl: __YOUR_TOKEN_URL__ appName: __YOUR_APP_NAME__ clientId: __YOUR_CLIENT_ID__ clientSecret: __YOUR_CLIENT_SECRET__ environment: clusterName: distribution: microk8s daemon: enabled: false agent: enabled: true config: | receivers: otlp: protocols: grpc: endpoint: ${env:MY_POD_IP}:4317 http: endpoint: ${env:MY_POD_IP}:4318 k8s_cluster: auth_type: 'serviceAccount' collection_interval: 60s node_conditions_to_report: [ ready, memorypressure, diskpressure, pidpressure, networkunavailable] resource_attributes: k8s.container.status.last_terminated_reason: enabled: true metrics: k8s.pod.status_reason: enabled: true k8s.node.condition: enabled: true allocatable_types_to_report: [ cpu, memory, ephemeral-storage, storage ] k8sobjects: objects: - name: events mode: pull interval: 60s group: events.k8s.io - name: deployments mode: pull interval: 60s group: deployments.k8s.io - name: resourcequotas mode: pull interval: 60s group: resourcequotas.k8s.io processors: batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resource: attributes: - key: service.name value: {{ .Values.scout.appName }} action: upsert resource/k8s: attributes: - key: service.name value: k8s action: upsert resource/k8s-events: attributes: - key: service.name value: k8s-events action: upsert resource/env: attributes: - key: environment value: {{ .Values.scout.environment }} action: upsert - key: k8s.cluster.name value: {{ .Values.scout.clusterName }} action: upsert resourcedetection/eks: detectors: [env, eks] override: true eks: resource_attributes: k8s.cluster.name: enabled: true k8sattributes: auth_type: 'serviceAccount' extract: metadata: - k8s.namespace.name - k8s.pod.name - k8s.pod.hostname - k8s.pod.ip - k8s.pod.start_time - k8s.pod.uid - k8s.replicaset.uid - k8s.replicaset.name - k8s.deployment.uid - k8s.deployment.name - k8s.daemonset.uid - k8s.daemonset.name - k8s.statefulset.uid - k8s.statefulset.name - k8s.cronjob.name - k8s.job.uid - k8s.job.name - k8s.node.name - k8s.cluster.uid - container.image.name - container.image.tag - container.id annotations: - tag_name: service.name key: resource.opentelemetry.io/service.name from: pod - tag_name: service.namespace key: resource.opentelemetry.io/service.namespace from: pod - tag_name: service.version key: resource.opentelemetry.io/service.version from: pod - tag_name: service.instance.id key: resource.opentelemetry.io/service.instance.id from: pod labels: - tag_name: kube_app_name key: app.kubernetes.io/name from: pod - tag_name: kube_app_instance key: app.kubernetes.io/instance from: pod - tag_name: kube_app_version key: app.kubernetes.io/version from: pod - tag_name: kube_app_component key: app.kubernetes.io/component from: pod - tag_name: kube_app_part_of key: app.kubernetes.io/part-of from: pod - tag_name: kube_app_managed_by key: app.kubernetes.io/managed-by from: pod pod_association: - sources: - from: resource_attribute name: k8s.pod.ip - sources: - from: resource_attribute name: k8s.pod.uid - sources: - from: connection exporters: otlphttp/base14: endpoint: {{ .Values.scout.endpoint }} auth: authenticator: oauth2client tls: insecure_skip_verify: true extensions: health_check: pprof: zpages: oauth2client: client_id: {{ .Values.scout.clientId }} client_secret: {{ .Values.scout.clientSecret }} endpoint_params: audience: b14collector token_url: {{ .Values.scout.tokenUrl }} tls: insecure_skip_verify: true service: extensions: [health_check, pprof, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/base14] logs: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlphttp/base14] logs/k8s-events: receivers: [ k8sobjects] processors: [ memory_limiter, resource/k8s-events, resourcedetection/eks, resource/env, batch ] exporters: [ otlphttp/base14 ] logs/k8s-cluster: receivers: [ k8s_cluster ] processors: [ memory_limiter, resource/k8s, resourcedetection/eks, resource/env, batch ] exporters: [ otlphttp/base14 ] metrics: receivers: [ otlp ] processors: [ memory_limiter, resource/env, batch ] exporters: [ otlphttp/base14 ] metrics/k8s: receivers: [ k8s_cluster ] processors: [ memory_limiter, resource/k8s, resourcedetection/eks, resource/env, k8sattributes, batch ] exporters: [ otlphttp/base14 ] telemetry: logs: level: warn encoding: json ``` ```mdx-code-block ``` ```yaml showLineNumbers title="values.yaml" scout: endpoint: __YOUR_ENDPOINT__ tokenUrl: __YOUR_TOKEN_URL__ appName: __YOUR_APP_NAME__ clientId: __YOUR_CLIENT_ID__ clientSecret: __YOUR_CLIENT_SECRET__ environment: clusterName: distribution: eks daemon: enabled: true config: | extensions: health_check: endpoint: ${env:MY_POD_IP}:13133 zpages: endpoint: ${env:MY_POD_IP}:55679 exporters: otlp/agent: endpoint: scout-agent-collector.scout.svc.cluster.local:4317 tls: insecure: true processors: batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resource: attributes: - key: service.name value: {{ .Values.scout.appName }} action: upsert resource/k8s: attributes: - key: service.name value: k8s action: upsert resource/env: attributes: - key: environment value: {{ .Values.scout.environment }} action: upsert - key: k8s.cluster.name value: {{ .Values.scout.clusterName }} action: upsert resourcedetection/eks: detectors: [env, eks] override: true eks: resource_attributes: k8s.cluster.name: enabled: true k8sattributes: auth_type: 'serviceAccount' extract: metadata: - k8s.namespace.name - k8s.pod.name - k8s.pod.hostname - k8s.pod.ip - k8s.pod.start_time - k8s.pod.uid - k8s.replicaset.uid - k8s.replicaset.name - k8s.deployment.uid - k8s.deployment.name - k8s.daemonset.uid - k8s.daemonset.name - k8s.statefulset.uid - k8s.statefulset.name - k8s.cronjob.name - k8s.job.uid - k8s.job.name - k8s.node.name - k8s.cluster.uid - container.image.name - container.image.tag - container.id annotations: - tag_name: service.name key: resource.opentelemetry.io/service.name from: pod - tag_name: service.namespace key: resource.opentelemetry.io/service.namespace from: pod - tag_name: service.version key: resource.opentelemetry.io/service.version from: pod - tag_name: service.instance.id key: resource.opentelemetry.io/service.instance.id from: pod labels: - tag_name: kube_app_name key: app.kubernetes.io/name from: pod - tag_name: kube_app_instance key: app.kubernetes.io/instance from: pod - tag_name: kube_app_version key: app.kubernetes.io/version from: pod - tag_name: kube_app_component key: app.kubernetes.io/component from: pod - tag_name: kube_app_part_of key: app.kubernetes.io/part-of from: pod - tag_name: kube_app_managed_by key: app.kubernetes.io/managed-by from: pod pod_association: - sources: - from: resource_attribute name: k8s.pod.ip - sources: - from: resource_attribute name: k8s.pod.uid - sources: - from: connection receivers: otlp: protocols: grpc: endpoint: ${env:MY_POD_IP}:4317 http: endpoint: ${env:MY_POD_IP}:4318 kubeletstats: collection_interval: 60s endpoint: https://${env:K8S_NODE_NAME}:10250 insecure_skip_verify: true auth_type: 'serviceAccount' metric_groups: - node - pod - volume - container extra_metadata_labels: - container.id filelog: include: - /var/log/pods/*/*/*.log start_at: end include_file_path: true include_file_name: false operators: - type: container id: container-parser service: extensions: [zpages, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, resource, resource/env, batch] exporters: [otlp/agent] logs: receivers: [otlp, filelog] processors: [memory_limiter, resource/env, batch] exporters: [otlp/agent] metrics: receivers: [otlp] processors: [memory_limiter, resource/env, batch] exporters: [otlp/agent] metrics/k8s: receivers: [kubeletstats] processors: [ memory_limiter, resource/k8s, resourcedetection/eks, resource/env, k8sattributes, batch, ] exporters: [otlp/agent] telemetry: logs: level: warn encoding: json agent: enabled: true config: | extensions: health_check: endpoint: ${env:MY_POD_IP}:13133 zpages: endpoint: ${env:MY_POD_IP}:55679 oauth2client: client_id: {{ .Values.scout.clientId }} client_secret: {{ .Values.scout.clientSecret }} endpoint_params: audience: b14collector token_url: {{ .Values.scout.tokenUrl }} tls: insecure_skip_verify: true exporters: debug: verbosity: detailed otlphttp/base14: endpoint: {{ .Values.scout.endpoint }} auth: authenticator: oauth2client tls: insecure_skip_verify: true processors: batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resource: attributes: - key: service.name value: {{ .Values.scout.appName }} action: upsert resource/k8s: attributes: - key: service.name value: k8s action: upsert resource/env: attributes: - key: environment value: {{ .Values.scout.environment }} action: upsert - key: k8s.cluster.name value: {{ .Values.scout.clusterName }} action: upsert resourcedetection/eks: detectors: [env, eks] override: true eks: resource_attributes: k8s.cluster.name: enabled: true k8sattributes: auth_type: 'serviceAccount' extract: metadata: - k8s.namespace.name - k8s.pod.name - k8s.pod.hostname - k8s.pod.ip - k8s.pod.start_time - k8s.pod.uid - k8s.replicaset.uid - k8s.replicaset.name - k8s.deployment.uid - k8s.deployment.name - k8s.daemonset.uid - k8s.daemonset.name - k8s.statefulset.uid - k8s.statefulset.name - k8s.cronjob.name - k8s.job.uid - k8s.job.name - k8s.node.name - k8s.cluster.uid - container.image.name - container.image.tag - container.id annotations: - tag_name: service.name from: pod - tag_name: service.namespace key: resource.opentelemetry.io/service.namespace from: pod - tag_name: service.version key: resource.opentelemetry.io/service.version from: pod - tag_name: service.instance.id key: resource.opentelemetry.io/service.instance.id from: pod labels: - tag_name: kube_app_name key: app.kubernetes.io/name from: pod - tag_name: kube_app_instance key: app.kubernetes.io/instance from: pod - tag_name: kube_app_version key: app.kubernetes.io/version from: pod - tag_name: kube_app_component key: app.kubernetes.io/component from: pod - tag_name: kube_app_part_of key: app.kubernetes.io/part-of from: pod - tag_name: kube_app_managed_by key: app.kubernetes.io/managed-by from: pod pod_association: - sources: - from: resource_attribute name: k8s.pod.ip - sources: - from: resource_attribute name: k8s.pod.uid - sources: - from: connection resource/k8s-events: attributes: - key: service.name value: "k8s-events" action: upsert receivers: otlp: protocols: http: endpoint: ${env:MY_POD_IP}:4318 grpc: endpoint: ${env:MY_POD_IP}:4317 k8s_cluster: auth_type: serviceAccount collection_interval: 60s node_conditions_to_report: [ ready, memorypressure, diskpressure, pidpressure, networkunavailable ] resource_attributes: k8s.container.status.last_terminated_reason: enabled: true metrics: k8s.pod.status_reason: enabled: true k8s.node.condition: enabled: true allocatable_types_to_report: [ cpu, memory, ephemeral-storage, storage ] k8sobjects: objects: - name: events mode: pull interval: 60s group: events.k8s.io - name: deployments mode: pull interval: 60s group: deployments.k8s.io - name: resourcequotas mode: pull interval: 60s group: resourcequotas.k8s.io service: extensions: [ oauth2client, zpages, health_check ] pipelines: traces: receivers: [ otlp] processors: [ memory_limiter, resource, resource/env, batch ] exporters: [ otlphttp/base14 ] logs: receivers: [ otlp ] processors: [ memory_limiter, resource/env, batch ] exporters: [ otlphttp/base14, debug ] logs/k8s-events: receivers: [ k8sobjects] processors: [ memory_limiter, resource/k8s-events, resourcedetection/eks, resource/env, batch ] exporters: [ otlphttp/base14 ] logs/k8s-cluster: receivers: [ k8s_cluster ] processors: [ memory_limiter, resource/k8s, resourcedetection/eks, resource/env, batch ] exporters: [ otlphttp/base14 ] metrics: receivers: [ otlp ] processors: [ memory_limiter, resource/env, batch ] exporters: [ otlphttp/base14 ] metrics/k8s: receivers: [ k8s_cluster ] processors: [ memory_limiter, resource/k8s, resourcedetection/eks, resource/env, k8sattributes, batch ] exporters: [ otlphttp/base14 ] telemetry: logs: level: warn encoding: json ``` ```mdx-code-block ``` ### Scout helm chart uses the above configuration to configure the Scout Collector 1. Collects logs for the current cluster(for Managed nodes only). 2. Sends k8s events data. 3. Sends node and pods metrics data. 4. Sends apps metrics data for the configured app endpoints. 5. Sets up a local otlp endpoint for apps to send traces which are then forwarded to Scout. Once deployed, your cluster telemetry flows into [base14 Scout](https://base14.io/scout) - unified logs, metrics, and traces from every node and pod in a single platform. ### Related Guides - [Scout Exporter Configuration](./scout-exporter.md) - Configure authentication to send data to Scout - [OpenTelemetry Operator Setup](./opentelemetry-operator-setup.md) - Auto-instrumentation and CRD-based collector management - [Advanced Collector Configuration](./otel-collector-config.md) - Customize your collector setup - [AWS ECS/Fargate Setup](./ecs-setup.md) - Alternative container deployment option ### Learn More - [Why Unified Observability Matters](/blog/unified-observability) - Benefits for growing engineering teams --- ## Install OpenTelemetry Collector on Linux - DEB & RPM Packages ## Linux Install and configure the Scout Collector on Linux systems. Whether you're using Debian, Red Hat, or other Linux distributions, you'll learn how to set up telemetry collection for your observability needs. ### Overview The Scout Collector is a vendor-agnostic agent that collects, processes, and exports telemetry data. This guide covers: - Installing Scout Collector via DEB packages (Ubuntu, Debian) - Installing Scout Collector via RPM packages (RHEL, CentOS, Fedora) - Manual installation for other Linux distributions - Configuring receivers for host metrics, container logs, journald logs, and Prometheus endpoints - Exporting telemetry to Scout and storing credentials securely - Running as a systemd service and verifying the pipeline - Troubleshooting and logging ### System Requirements - Linux operating system (amd64/arm64/i386) - `systemd` for service management - Root or sudo access - Minimum 512MB RAM - 1GB free disk space ### Package Availability Official Scout Collector packages are available in the following formats: - DEB packages for Debian-based systems - RPM packages for Red Hat-based systems - Precompiled binaries for manual installation Default configuration path: `/etc/otelcol-contrib/config.yaml` ### DEB Installation To install the Scout Collector on Debian-based systems, run the following commands: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```sh sudo apt-get update sudo apt-get -y install wget wget https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_amd64.deb sudo dpkg -i otelcol-contrib_0.127.0_linux_amd64.deb ``` ```mdx-code-block ``` ```sh sudo apt-get update sudo apt-get -y install wget wget https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_arm64.deb sudo dpkg -i otelcol-contrib_0.127.0_linux_arm64.deb ``` ```mdx-code-block ``` ```sh sudo apt-get update sudo apt-get -y install wget wget https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_386.deb sudo dpkg -i otelcol-contrib_0.127.0_linux_386.deb ``` ```mdx-code-block ``` ### RPM Installation To install the Scout Collector on Red Hat-based systems, run the following commands: ```mdx-code-block ``` ```sh sudo yum update sudo yum -y install wget systemctl wget https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_amd64.rpm sudo rpm -ivh otelcol-contrib_0.127.0_linux_amd64.rpm ``` ```mdx-code-block ``` ```sh sudo yum update sudo yum -y install wget systemctl wget https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_arm64.rpm sudo rpm -ivh otelcol-contrib_0.127.0_linux_arm64.rpm ``` ```mdx-code-block ``` ```sh sudo yum update sudo yum -y install wget systemctl wget https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_386.rpm sudo rpm -ivh otelcol-contrib_0.127.0_linux_386.rpm ``` ```mdx-code-block ``` ### Manual Linux Installation The OpenTelemetry Collector [releases](https://github.com/open-telemetry/opentelemetry-collector-releases/releases) are available for various architectures. You can download the binary and install it manually: ```mdx-code-block ``` ```sh curl --proto '=https' --tlsv1.2 -fOL https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_amd64.tar.gz tar -xvf otelcol-contrib_0.127.0_linux_amd64.tar.gz ``` ```mdx-code-block ``` ```sh curl --proto '=https' --tlsv1.2 -fOL https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_arm64.tar.gz tar -xvf otelcol-contrib_0.127.0_linux_arm64.tar.gz ``` ```mdx-code-block ``` ```sh curl --proto '=https' --tlsv1.2 -fOL https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_386.tar.gz tar -xvf otelcol-contrib_0.127.0_linux_386.tar.gz ``` ```mdx-code-block ``` ```sh curl --proto '=https' --tlsv1.2 -fOL https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_linux_ppc64le.tar.gz tar -xvf otelcol-contrib_0.127.0_linux_ppc64le.tar.gz ``` ```mdx-code-block ``` ### Configure Telemetry Collection After installation, edit `/etc/otelcol-contrib/config.yaml` to define what telemetry the Scout Collector gathers from the machine and where it sends it. A configuration is built from receivers (what to collect), processors (how to enrich and batch), an exporter (where to send), and pipelines that wire them together. #### Receivers ##### Host metrics The `hostmetrics` receiver collects CPU, memory, disk, filesystem, network, and load metrics from the host: ```yaml showLineNumbers receivers: hostmetrics: collection_interval: 60s scrapers: cpu: memory: load: disk: filesystem: network: paging: processes: ``` Listing a scraper by name, as above, enables it with its **default** set of metrics — you don't need to enumerate individual metrics to get the usual CPU, memory, disk, and network signals. Some metrics are opt-in and stay off until you ask for them, such as the percentage-based `system.cpu.utilization` and `system.memory.utilization`. Enable an opt-in metric (or disable a default one) under a `metrics:` block: ```yaml showLineNumbers receivers: hostmetrics: scrapers: cpu: metrics: system.cpu.utilization: enabled: true ``` The `processes` scraper above reports lightweight, system-wide process counts and needs no special privileges. A separate `process` scraper (not shown) reports per-process metrics and needs elevated privileges to read other users' entries under `/proc` — see [Running with elevated privileges](#running-with-elevated-privileges). ##### Container logs (Docker) When applications run as Docker containers, their stdout and stderr are written to JSON log files under `/var/lib/docker/containers`. The `filelog` receiver tails these files, and the `container` operator unwraps Docker's JSON envelope into the log body: ```yaml showLineNumbers receivers: filelog: include: [/var/lib/docker/containers/*/*-json.log] start_at: end include_file_path: true operators: - type: container format: docker add_metadata_from_filepath: false ``` Leave `add_metadata_from_filepath` set to `false`. That option exists to extract pod, namespace, and container names from Kubernetes pod log paths (`/var/log/pods/...`); a Docker log path has no such structure, so setting it `true` makes every record fail with `failed to detect a valid log path`. `/var/lib/docker/containers` is readable only by root, so the collector must run as root to tail these files — see [Running with elevated privileges](#running-with-elevated-privileges). If your application logs in JSON, add a `json_parser` to lift its fields into attributes and a `severity_parser` to set the log severity: ```yaml showLineNumbers - type: json_parser parse_from: body on_error: send - type: severity_parser parse_from: attributes.level on_error: send ``` `on_error: send` keeps any non-JSON lines flowing instead of dropping them, so startup banners and stack traces are preserved. ##### System and journald logs For services managed by systemd, the `journald` receiver reads the journal directly. For plain text log files, use a `filelog` receiver: ```yaml showLineNumbers receivers: journald: units: [my-service] filelog/syslog: include: [/var/log/syslog, /var/log/messages] start_at: end ``` ##### Scrape a Prometheus endpoint Many applications expose metrics on a Prometheus `/metrics` endpoint. The `prometheus` receiver scrapes them on an interval: ```yaml showLineNumbers receivers: prometheus/app: config: scrape_configs: - job_name: my-app scrape_interval: 30s metrics_path: /metrics static_configs: - targets: [localhost:8080] ``` The target must be reachable from the host where the collector runs. If the application runs in a Docker container, its container-network name (for example `my-app:8080`) does not resolve from the host. Publish the metrics port and scrape `localhost:`, or use the container's bridge IP: ```sh docker port ``` #### Export to Scout Send the collected telemetry to Scout with the `oauth2client` extension and an `otlphttp` exporter. Replace the tenant placeholder with your Scout tenant, and supply credentials via environment variables (see [Store credentials securely](#store-credentials-securely)): ```yaml showLineNumbers extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token tls: insecure_skip_verify: true exporters: otlphttp/b14: endpoint: https://otel.play.b14.dev/__YOUR_TENANT__/otlp auth: authenticator: oauth2client tls: insecure_skip_verify: true ``` For the full list of tenant, endpoint, and authentication options, see [Scout Exporter Configuration](./scout-exporter.md). #### Store credentials securely Keep secrets out of `config.yaml` by referencing environment variables with `${env:VAR}` and defining them in the systemd environment file at `/etc/otelcol-contrib/otelcol-contrib.conf`: ```sh SCOUT_CLIENT_ID=__YOUR_CLIENT_ID__ SCOUT_CLIENT_SECRET=__YOUR_CLIENT_SECRET__ ``` Keep the existing `OTELCOL_OPTIONS` line in that file. Then restrict the file's permissions so the secret is not world-readable: ```sh sudo chmod 600 /etc/otelcol-contrib/otelcol-contrib.conf ``` systemd loads this file when the service starts, so restart the collector after changing it. #### Complete configuration The following config combines host metrics and Docker container logs with a Scout exporter, wired into `metrics` and `logs` pipelines. Save it to `/etc/otelcol-contrib/config.yaml`: ```yaml showLineNumbers extensions: health_check: endpoint: 0.0.0.0:13133 oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token tls: insecure_skip_verify: true receivers: hostmetrics: collection_interval: 60s scrapers: cpu: memory: load: disk: filesystem: network: filelog: include: [/var/lib/docker/containers/*/*-json.log] start_at: end include_file_path: true operators: - type: container format: docker add_metadata_from_filepath: false - type: json_parser parse_from: body on_error: send - type: severity_parser parse_from: attributes.level on_error: send processors: memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resourcedetection: detectors: [system] timeout: 5s resource: attributes: - key: environment value: production action: upsert batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 exporters: otlphttp/b14: endpoint: https://otel.play.b14.dev/__YOUR_TENANT__/otlp auth: authenticator: oauth2client tls: insecure_skip_verify: true service: extensions: [health_check, oauth2client] pipelines: metrics: receivers: [hostmetrics] processors: [memory_limiter, resourcedetection, resource, batch] exporters: [otlphttp/b14] logs: receivers: [filelog] processors: [memory_limiter, resourcedetection, resource, batch] exporters: [otlphttp/b14] ``` Add the `journald`, `filelog/syslog`, or `prometheus/app` receivers from above to the relevant pipeline as needed. ### Configuring the Scout Collector Service By default, the `otelcol-contrib` systemd service starts with the `--config=/etc/otelcol-contrib/config.yaml` option after installation. This configuration follows the [Scout Collector Configuration](https://opentelemetry.io/docs/collector/configuration/) standards. To customize the collector settings, modify the `OTELCOL_OPTIONS` variable in the `/etc/otelcol-contrib/otelcol-contrib.conf` systemd environment file with appropriate command-line options. Run `/usr/bin/otelcol-contrib --help` to see all available options. Additional environment variables can be passed to the `otelcol-contrib` service by adding them to this file. After modifying the Collector configuration file or `/etc/otelcol-contrib/otelcol-contrib.conf`, restart the `otelcol-contrib` service to apply the changes: ```sh sudo systemctl restart otelcol-contrib ``` To check the logs from the `otelcol-contrib` service, run: ```sh sudo journalctl -u otelcol-contrib ``` For more information on configuring and using the Scout Collector, refer to the [official OpenTelemetry documentation](https://opentelemetry.io/docs/collector/). ### Running with elevated privileges Reading Docker container logs under `/var/lib/docker/containers` requires root. Override the service user with a systemd drop-in rather than editing the packaged unit file, which an upgrade would overwrite. Create the drop-in directory and file: ```sh sudo mkdir -p /etc/systemd/system/otelcol-contrib.service.d sudo tee /etc/systemd/system/otelcol-contrib.service.d/10-root.conf >/dev/null <<'EOF' [Service] User=root EOF ``` The drop-in must live under `/etc/systemd/system/...`; a file placed elsewhere under `/etc/systemd/` is silently ignored. Reload systemd and restart so the change takes effect: ```sh sudo systemctl daemon-reload sudo systemctl restart otelcol-contrib ``` Confirm the effective user: ```sh systemctl show otelcol-contrib -p User ``` If you prefer not to run the collector as root, configure the container with the `journald` log driver and read it with the `journald` receiver instead of `filelog`. ### Validate and verify Validate the configuration before restarting. Because credentials come from the environment file, load it first — otherwise `${env:...}` resolves to empty and validation reports a missing endpoint and client ID even though the config is correct: ```sh sudo bash -c 'set -a; . /etc/otelcol-contrib/otelcol-contrib.conf; set +a; \ otelcol-contrib validate --config=/etc/otelcol-contrib/config.yaml' ``` Restart the service and watch the logs for export or authentication errors: ```sh sudo systemctl restart otelcol-contrib sudo journalctl -u otelcol-contrib -f ``` Check the health endpoint to confirm the collector is up: ```sh curl -s localhost:13133 ``` Then confirm the telemetry arrives in Scout under the service or host you configured. ### Troubleshooting | Symptom | Cause | Fix | | --- | --- | --- | | `validate` reports `no ClientID provided` or `at least one endpoint must be specified` | `${env:...}` variables are not set in your shell; systemd injects them only at service start | Load the environment file before validating (see [Validate and verify](#validate-and-verify)), or rely on `systemctl restart` and read the journal. | | `finding files ... permission denied` on `/var/lib/docker/containers` | The collector is not running as root | Apply the `User=root` drop-in; confirm with `systemctl show otelcol-contrib -p User`. | | `User` still shows the default after adding a drop-in | The drop-in is in the wrong directory, lacks the `.conf` suffix, or systemd was not reloaded | Place it under `/etc/systemd/system/otelcol-contrib.service.d/` with a `.conf` name, then run `daemon-reload` and `restart`. | | `failed to detect a valid log path` from the `container` operator | `add_metadata_from_filepath: true` expects Kubernetes pod log paths | Set `add_metadata_from_filepath: false`. | | Config edits have no effect | The collector reads its config only at startup | Run `sudo systemctl restart otelcol-contrib`. | | No data arrives, but there are no errors | `filelog` uses `start_at: end`, so only new lines are sent | Generate new activity; historical lines are not backfilled. Use `start_at: beginning` only for testing. | ### FAQ #### How do I install the OpenTelemetry Collector on Ubuntu or Debian? Download the `otelcol-contrib` `.deb` package for your architecture (amd64, arm64, or i386) from the official releases and install it with `sudo dpkg -i`. The package registers a systemd service on install. #### How do I install the OpenTelemetry Collector on RHEL or CentOS? Download the `otelcol-contrib` `.rpm` package for your architecture and install it with `sudo rpm -ivh`. The collector starts as a systemd service using the default config at `/etc/otelcol-contrib/config.yaml`. #### Where is the default OpenTelemetry Collector config file on Linux? At `/etc/otelcol-contrib/config.yaml`. Command-line options go in the `OTELCOL_OPTIONS` variable in `/etc/otelcol-contrib/otelcol-contrib.conf`. #### How do I restart the OpenTelemetry Collector service on Linux? Run `sudo systemctl restart otelcol-contrib` after editing the config, then check `sudo journalctl -u otelcol-contrib` to confirm it came back up rather than crash-looping on a config error. #### What are the system requirements for the OTel Collector on Linux? A systemd-based Linux system, root or sudo access, at least 512MB of RAM, and 1GB of free disk. Packages ship for amd64, arm64, and i386. #### How do I collect Docker container logs with the Collector on Linux? Use the filelog receiver to tail `/var/lib/docker/containers/*/*-json.log` with the container operator, set `add_metadata_from_filepath` to `false`, and run the collector as root so it can read the Docker log directory. #### Why does otelcol-contrib validate report a missing endpoint or client ID? Environment variables referenced with `${env:...}` are set by systemd when it starts the service, not by your shell. Load the environment file first so the values are substituted before the config is parsed. ### Related Guides - [OTel Collector Configuration](./otel-collector-config.md) - Full receiver, processor, and exporter reference - [Scout Exporter Configuration](./scout-exporter.md) - Set up authentication and endpoints - [Docker Compose Setup](./docker-compose-example.md) - Alternative deployment method - [Kubernetes (Helm) Setup](./kubernetes-helm-setup.md) - Deploy the collector on Kubernetes instead --- ## Local Development Environment Setup with OpenTelemetry ## Local Dev Environment Set up a Scout collector locally for development and testing purposes. It includes: - **Scout Collector**: For collecting, processing, and exporting telemetry data to Scout Backend This environment allows you to: - Process logs, metrics, and traces through the Scout Collector - Test your instrumentation code locally before deploying to production ### Requirements - [Docker](https://www.docker.com/) Installed. ### Scout Collector config Copy the below content to `otel-collector-config.yaml` ```yaml showLineNumbers receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 exporters: debug: verbosity: detailed otlphttp/b14: endpoint: ${SCOUT_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true compression: gzip processors: resource/env: attributes: - key: environment value: development action: upsert extensions: oauth2client: client_id: ${SCOUT_CLIENT_ID} client_secret: ${SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: ${SCOUT_TOKEN_URL} tls: insecure_skip_verify: true service: extensions: [oauth2client] pipelines: traces: receivers: [otlp] processors: [resource/env] exporters: [otlphttp/b14] metrics: receivers: [otlp] processors: [resource/env] exporters: [otlphttp/b14] logs: receivers: [otlp] processors: [resource/env] exporters: [otlphttp/b14] ``` > Replace the placeholders with your Scout credentials. For Adding Receiver, > Processor, Exporter, and Service Extensions, please refer to > [Scout Collector Configuration](https://opentelemetry.io/docs/collector/configuration/) ### Start the Containers ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Create a Docker compose file `compose.yml` ```yaml showLineNumbers version: "3.8" services: otel-collector: image: otel/opentelemetry-collector-contrib:0.130.0 container_name: otel-collector restart: unless-stopped command: ["--config=/etc/otelcol/config.yaml"] volumes: - ./otel-collector-config.yaml:/etc/otelcol/config.yaml ports: - "4317:4317" - "4318:4318" ``` Run the below command to start the local development setup ```bash docker-compose up -d ``` ```mdx-code-block ``` Run the below command to start the local development setup ```shell docker run -d \ --name otel-collector \ --restart unless-stopped \ -p 4317:4317 \ -p 4318:4318 \ -v $(pwd)/otel-collector-config.yaml:/etc/otelcol/config.yaml \ otel/opentelemetry-collector-contrib:0.130.0 \ --config=/etc/otelcol/config.yaml ``` ```mdx-code-block ``` That's it! Navigate to Scout dashboards to visualize the data. ### Related Guides - [Docker Compose Setup](./docker-compose-example.md) - Complete Docker Compose example with Grafana - [Scout Exporter Configuration](./scout-exporter.md) - Authentication and endpoint configuration - [Express.js Instrumentation](../apps/auto-instrumentation/express.md) - Test with a sample application --- ## OpenTelemetry Operator for Kubernetes - Auto-Instrumentation & Collector Setup ## OpenTelemetry Operator for Kubernetes Deploy and manage OpenTelemetry Collectors and enable automatic instrumentation for your applications using the OpenTelemetry Operator. :::tip Recommended This is the recommended approach for deploying OpenTelemetry Collectors on Kubernetes with Scout. ::: ### Overview The OpenTelemetry Operator is a Kubernetes Operator that manages: 1. **OpenTelemetry Collector** - Lifecycle management of collector deployments 2. **Auto-instrumentation** - Automatic SDK injection for applications without code changes This guide covers how to: - Install the OpenTelemetry Operator on Kubernetes - Deploy an OpenTelemetry Collector using Custom Resources - Configure the collector to send telemetry to Scout backend - Enable automatic instrumentation for your applications - Use different deployment modes (Deployment, DaemonSet, Sidecar) ### Prerequisites Before installing the OpenTelemetry Operator, ensure you have: - A Kubernetes cluster (v1.24+) - `kubectl` configured with cluster access - Helm 3.9+ installed - Scout account credentials: - Endpoint URL - Client ID - Client Secret - Token URL ### Installation #### Step 1: Install cert-manager The OpenTelemetry Operator requires cert-manager for webhook certificates. ```bash kubectl apply -f https://github.com/cert-manager/cert-manager/releases/download/v1.14.0/cert-manager.yaml ``` Wait for cert-manager to be ready: ```bash kubectl wait --for=condition=Available deployment/cert-manager -n cert-manager --timeout=300s kubectl wait --for=condition=Available deployment/cert-manager-webhook -n cert-manager --timeout=300s ``` #### Step 2: Install the OpenTelemetry Operator ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash helm repo add open-telemetry https://open-telemetry.github.io/opentelemetry-helm-charts helm repo update ``` ```bash helm install opentelemetry-operator open-telemetry/opentelemetry-operator \ --namespace opentelemetry-operator-system \ --create-namespace \ --set "manager.collectorImage.repository=otel/opentelemetry-collector-contrib" ``` ```mdx-code-block ``` ```bash kubectl apply -f https://github.com/open-telemetry/opentelemetry-operator/releases/latest/download/opentelemetry-operator.yaml ``` ```mdx-code-block ``` Verify the operator is running: ```bash kubectl get pods -n opentelemetry-operator-system ``` Expected output: ```text NAME READY STATUS RESTARTS AGE opentelemetry-operator-controller-xxx 2/2 Running 0 1m ``` ### Deploying an OpenTelemetry Collector Create `OpenTelemetryCollector` Custom Resources to deploy collectors that send telemetry to Scout backend. #### Create the Credentials Secret First, create the namespace and credentials secret: ```bash kubectl create namespace observability kubectl create secret generic scout-credentials \ --namespace observability \ --from-literal=endpoint="https://otel.play.b14.dev/__YOUR_TENANT__/otlp" \ --from-literal=client-id="__YOUR_CLIENT_ID__" \ --from-literal=client-secret="__YOUR_CLIENT_SECRET__" \ --from-literal=token-url="https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token" ``` #### Collector Configuration ```mdx-code-block ``` For Fargate deployments, use a single collector in Deployment mode: ```yaml showLineNumbers title="scout-collector.yaml" apiVersion: opentelemetry.io/v1beta1 kind: OpenTelemetryCollector metadata: name: scout-collector namespace: observability spec: mode: deployment replicas: 1 image: otel/opentelemetry-collector-contrib:0.130.1 serviceAccount: otel-collector-sa config: extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: ${env:SCOUT_TOKEN_URL} tls: insecure_skip_verify: true receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 k8s_cluster: auth_type: serviceAccount collection_interval: 60s node_conditions_to_report: - Ready - MemoryPressure - DiskPressure - PIDPressure - NetworkUnavailable resource_attributes: k8s.container.status.last_terminated_reason: enabled: true metrics: k8s.pod.status_reason: enabled: true k8s.node.condition: enabled: true allocatable_types_to_report: - cpu - memory - ephemeral-storage - storage k8sobjects: objects: - name: events mode: pull interval: 60s group: events.k8s.io - name: deployments mode: pull interval: 60s group: apps - name: resourcequotas mode: pull interval: 60s processors: batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resource: attributes: - key: service.name value: ${env:APP_NAME} action: upsert resource/k8s: attributes: - key: service.name value: k8s action: upsert resource/k8s-events: attributes: - key: service.name value: k8s-events action: upsert resource/env: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: k8s.cluster.name value: ${env:CLUSTER_NAME} action: upsert resourcedetection/eks: detectors: [env, eks] override: true eks: resource_attributes: k8s.cluster.name: enabled: true # Extract severity from log bodies; anything left unmatched defaults to # INFO. All rules are guarded by severity_text == "" so logs that already # carry severity pass through untouched. transform/severity: error_mode: ignore log_statements: - context: log statements: # k8s events (body is a map from the k8sobjects receiver) - set(severity_text, "WARN") where severity_text == "" and IsMap(body) and body["type"] == "Warning" - set(severity_text, "INFO") where severity_text == "" and IsMap(body) and body["type"] == "Normal" # structured JSON string bodies (direct OTLP logs) - set(cache, ParseJSON(body)) where severity_text == "" and IsString(body) and IsMatch(body, "^\\s*\\{") - set(severity_text, ConvertCase(cache["level"], "upper")) where severity_text == "" and IsString(cache["level"]) - set(severity_text, ConvertCase(cache["severity"], "upper")) where severity_text == "" and IsString(cache["severity"]) - set(severity_text, "TRACE") where severity_text == "" and cache["level"] == 10 - set(severity_text, "DEBUG") where severity_text == "" and cache["level"] == 20 - set(severity_text, "INFO") where severity_text == "" and cache["level"] == 30 - set(severity_text, "WARN") where severity_text == "" and cache["level"] == 40 - set(severity_text, "ERROR") where severity_text == "" and cache["level"] == 50 - set(severity_text, "FATAL") where severity_text == "" and cache["level"] == 60 # normalize synonyms - set(severity_text, "WARN") where severity_text == "WARNING" - set(severity_text, "ERROR") where severity_text == "ERR" - set(severity_text, "FATAL") where severity_text == "CRITICAL" or severity_text == "PANIC" # default: everything still unlabelled is INFO - set(severity_text, "INFO") where severity_text == "" # severity_text -> severity_number (only if not already set upstream) - set(severity_number, SEVERITY_NUMBER_TRACE) where severity_number == 0 and severity_text == "TRACE" - set(severity_number, SEVERITY_NUMBER_DEBUG) where severity_number == 0 and severity_text == "DEBUG" - set(severity_number, SEVERITY_NUMBER_INFO) where severity_number == 0 and severity_text == "INFO" - set(severity_number, SEVERITY_NUMBER_WARN) where severity_number == 0 and severity_text == "WARN" - set(severity_number, SEVERITY_NUMBER_ERROR) where severity_number == 0 and severity_text == "ERROR" - set(severity_number, SEVERITY_NUMBER_FATAL) where severity_number == 0 and severity_text == "FATAL" # k8s events: promote reason/object fields to attributes for faceting in # the logs UI, and replace the raw event JSON body with the # human-readable message. Must run AFTER transform/severity (severity # reads body["type"] before the body is replaced). transform/k8s-events: error_mode: ignore log_statements: - context: log statements: - set(attributes["event.type"], body["type"]) where IsMap(body) and body["type"] != nil - set(attributes["event.reason"], body["reason"]) where IsMap(body) and body["reason"] != nil - set(attributes["k8s.object.kind"], body["regarding"]["kind"]) where IsMap(body) and body["regarding"] != nil - set(attributes["k8s.object.name"], body["regarding"]["name"]) where IsMap(body) and body["regarding"] != nil - set(attributes["k8s.namespace.name"], body["regarding"]["namespace"]) where IsMap(body) and body["regarding"] != nil - set(attributes["event.count"], body["deprecatedCount"]) where IsMap(body) and body["deprecatedCount"] != nil - set(body, body["note"]) where IsMap(body) and body["note"] != nil transform/service_name_fallback: error_mode: ignore trace_statements: - context: span statements: - set(resource.attributes["service.name"], resource.attributes["k8s.container.name"]) where resource.attributes["k8s.container.name"] != nil k8sattributes: auth_type: serviceAccount extract: metadata: - k8s.namespace.name - k8s.pod.name - k8s.pod.hostname - k8s.pod.ip - k8s.pod.start_time - k8s.pod.uid - k8s.replicaset.uid - k8s.replicaset.name - k8s.deployment.uid - k8s.deployment.name - k8s.daemonset.uid - k8s.daemonset.name - k8s.statefulset.uid - k8s.statefulset.name - k8s.cronjob.name - k8s.job.uid - k8s.job.name - k8s.node.name - k8s.cluster.uid - container.image.name - container.image.tag - container.id annotations: - tag_name: service.name key: resource.opentelemetry.io/service.name from: pod - tag_name: service.namespace key: resource.opentelemetry.io/service.namespace from: pod - tag_name: service.version key: resource.opentelemetry.io/service.version from: pod - tag_name: service.instance.id key: resource.opentelemetry.io/service.instance.id from: pod labels: - tag_name: kube_app_name key: app.kubernetes.io/name from: pod - tag_name: kube_app_instance key: app.kubernetes.io/instance from: pod - tag_name: kube_app_version key: app.kubernetes.io/version from: pod - tag_name: kube_app_component key: app.kubernetes.io/component from: pod - tag_name: kube_app_part_of key: app.kubernetes.io/part-of from: pod - tag_name: kube_app_managed_by key: app.kubernetes.io/managed-by from: pod pod_association: - sources: - from: resource_attribute name: k8s.pod.ip - sources: - from: resource_attribute name: k8s.pod.uid - sources: - from: connection exporters: otlphttp/b14: endpoint: ${env:SCOUT_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true retry_on_failure: enabled: true initial_interval: 2s max_interval: 10s max_elapsed_time: 60s service: extensions: [health_check, zpages, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, transform/service_name_fallback, batch] exporters: [otlphttp/b14] logs: receivers: [otlp] processors: [memory_limiter, transform/severity, batch] exporters: [otlphttp/b14] logs/k8s-events: receivers: [k8sobjects] processors: - memory_limiter - resource/k8s-events - resourcedetection/eks - resource/env - transform/severity - transform/k8s-events - batch exporters: [otlphttp/b14] logs/k8s-cluster: receivers: [k8s_cluster] processors: - memory_limiter - resource/k8s - resourcedetection/eks - resource/env - transform/severity - batch exporters: [otlphttp/b14] metrics: receivers: [otlp] processors: [memory_limiter, resource/env, batch] exporters: [otlphttp/b14] metrics/k8s: receivers: [k8s_cluster] processors: - memory_limiter - resource/k8s - resourcedetection/eks - resource/env - k8sattributes - batch exporters: [otlphttp/b14] telemetry: logs: level: warn encoding: json env: - name: SCOUT_ENDPOINT valueFrom: secretKeyRef: name: scout-credentials key: endpoint - name: SCOUT_CLIENT_ID valueFrom: secretKeyRef: name: scout-credentials key: client-id - name: SCOUT_CLIENT_SECRET valueFrom: secretKeyRef: name: scout-credentials key: client-secret - name: SCOUT_TOKEN_URL valueFrom: secretKeyRef: name: scout-credentials key: token-url - name: CLUSTER_NAME value: "" - name: ENVIRONMENT value: "" - name: APP_NAME value: "" ``` ```mdx-code-block ``` For Managed Nodes, use two collectors: a DaemonSet for node-level collection and a Deployment for cluster-level collection. ##### Daemon Collector (DaemonSet) ```yaml showLineNumbers title="scout-daemon-collector.yaml" apiVersion: opentelemetry.io/v1beta1 kind: OpenTelemetryCollector metadata: name: scout-daemon namespace: observability spec: mode: daemonset image: otel/opentelemetry-collector-contrib:0.130.1 serviceAccount: otel-collector-sa config: extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 kubeletstats: collection_interval: 60s endpoint: https://${env:K8S_NODE_NAME}:10250 insecure_skip_verify: true auth_type: serviceAccount metric_groups: - node - pod - volume - container extra_metadata_labels: - container.id filelog: include: - /var/log/pods/*/*/*.log start_at: end include_file_path: true include_file_name: false operators: - type: container id: container-parser # Re-join stack traces / tracebacks that arrive one line per record. # A line is a NEW entry unless it looks like a continuation: # - starts with whitespace (Python " File ...", Java "\tat ...") # - "Caused by: ..." / "... N more" (Java) # - "Traceback (most recent call last):" (Python) # - "SomeError: msg" (final line of a Python traceback) - type: recombine id: multiline-stacktraces combine_field: body combine_with: "\n" source_identifier: attributes["log.file.path"] is_first_entry: 'body matches "^[^\\s]" and not (body matches "^(Caused by: |\\.\\.\\. [0-9]+ more|Traceback \\(most recent call last\\)|[A-Za-z_][A-Za-z0-9_.]*(Error|Exception): )")' force_flush_period: 5s max_log_size: 102400 processors: batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resource: attributes: - key: service.name value: ${env:APP_NAME} action: upsert resource/k8s: attributes: - key: service.name value: k8s action: upsert resource/env: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: k8s.cluster.name value: ${env:CLUSTER_NAME} action: upsert resourcedetection/eks: detectors: [env, eks] override: true eks: resource_attributes: k8s.cluster.name: enabled: true transform/filelog: error_mode: ignore log_statements: - context: log statements: - set(resource.attributes["service.name"], resource.attributes["k8s.container.name"]) where resource.attributes["k8s.container.name"] != nil # Extract severity from every known container log format; anything left # unmatched defaults to INFO. Rules are ordered and guarded by # severity_text == "" so the first match wins and OTLP logs that already # carry severity are untouched. transform/severity: error_mode: ignore log_statements: - context: log statements: # structured JSON bodies: parse once into cache - set(cache, ParseJSON(body)) where severity_text == "" and IsString(body) and IsMatch(body, "^\\s*\\{") # string level keys (zap json, slf4j, pino string, custom "severity") - set(severity_text, ConvertCase(cache["level"], "upper")) where severity_text == "" and IsString(cache["level"]) - set(severity_text, ConvertCase(cache["severity"], "upper")) where severity_text == "" and IsString(cache["severity"]) # pino numeric levels - set(severity_text, "TRACE") where severity_text == "" and cache["level"] == 10 - set(severity_text, "DEBUG") where severity_text == "" and cache["level"] == 20 - set(severity_text, "INFO") where severity_text == "" and cache["level"] == 30 - set(severity_text, "WARN") where severity_text == "" and cache["level"] == 40 - set(severity_text, "ERROR") where severity_text == "" and cache["level"] == 50 - set(severity_text, "FATAL") where severity_text == "" and cache["level"] == 60 # klog/glog "I0802 06:33:16.628281 ..." (kube components) - set(severity_text, "INFO") where severity_text == "" and IsString(body) and IsMatch(body, "^I[0-9]{4} ") - set(severity_text, "WARN") where severity_text == "" and IsString(body) and IsMatch(body, "^W[0-9]{4} ") - set(severity_text, "ERROR") where severity_text == "" and IsString(body) and IsMatch(body, "^E[0-9]{4} ") - set(severity_text, "FATAL") where severity_text == "" and IsString(body) and IsMatch(body, "^F[0-9]{4} ") # logfmt level= (argocd, go-kit) - set(severity_text, "TRACE") where severity_text == "" and IsString(body) and IsMatch(body, "(^|[ \\t])level=trace") - set(severity_text, "DEBUG") where severity_text == "" and IsString(body) and IsMatch(body, "(^|[ \\t])level=debug") - set(severity_text, "INFO") where severity_text == "" and IsString(body) and IsMatch(body, "(^|[ \\t])level=info") - set(severity_text, "WARN") where severity_text == "" and IsString(body) and IsMatch(body, "(^|[ \\t])level=warn(ing)?") - set(severity_text, "ERROR") where severity_text == "" and IsString(body) and IsMatch(body, "(^|[ \\t])level=error") - set(severity_text, "FATAL") where severity_text == "" and IsString(body) and IsMatch(body, "(^|[ \\t])level=(fatal|panic)") # python/uvicorn prefix "INFO:", "WARNING:root:", "ERROR: ..." - 'set(severity_text, "DEBUG") where severity_text == "" and IsString(body) and IsMatch(body, "^DEBUG[: ]")' - 'set(severity_text, "INFO") where severity_text == "" and IsString(body) and IsMatch(body, "^INFO[: ]")' - 'set(severity_text, "WARN") where severity_text == "" and IsString(body) and IsMatch(body, "^WARN(ING)?[: ]")' - 'set(severity_text, "ERROR") where severity_text == "" and IsString(body) and IsMatch(body, "^ERROR[: ]")' - 'set(severity_text, "FATAL") where severity_text == "" and IsString(body) and IsMatch(body, "^CRITICAL[: ]")' # zap console "2026-08-02T06:33:16.905Z\tinfo\t..." - set(severity_text, "DEBUG") where severity_text == "" and IsString(body) and IsMatch(body, "^[0-9]{4}-[0-9]{2}-[0-9]{2}T[^\\t]*\\tdebug\\t") - set(severity_text, "INFO") where severity_text == "" and IsString(body) and IsMatch(body, "^[0-9]{4}-[0-9]{2}-[0-9]{2}T[^\\t]*\\tinfo\\t") - set(severity_text, "WARN") where severity_text == "" and IsString(body) and IsMatch(body, "^[0-9]{4}-[0-9]{2}-[0-9]{2}T[^\\t]*\\twarn\\t") - set(severity_text, "ERROR") where severity_text == "" and IsString(body) and IsMatch(body, "^[0-9]{4}-[0-9]{2}-[0-9]{2}T[^\\t]*\\t(error|fatal|dpanic|panic)\\t") # bracketed "[INFO]" (dramatiq, spring-style) - set(severity_text, "DEBUG") where severity_text == "" and IsString(body) and IsMatch(body, "\\[DEBUG\\]") - set(severity_text, "INFO") where severity_text == "" and IsString(body) and IsMatch(body, "\\[INFO\\]") - set(severity_text, "WARN") where severity_text == "" and IsString(body) and IsMatch(body, "\\[WARN(ING)?\\]") - set(severity_text, "ERROR") where severity_text == "" and IsString(body) and IsMatch(body, "\\[ERROR\\]") - set(severity_text, "FATAL") where severity_text == "" and IsString(body) and IsMatch(body, "\\[CRITICAL\\]") # multiline blobs that are clearly error dumps - 'set(severity_text, "ERROR") where severity_text == "" and IsString(body) and IsMatch(body, "(^|\\n)(Traceback \\(most recent call last\\)|[A-Za-z_][A-Za-z0-9_.]*(Error|Exception): )")' # normalize synonyms - set(severity_text, "WARN") where severity_text == "WARNING" - set(severity_text, "ERROR") where severity_text == "ERR" - set(severity_text, "FATAL") where severity_text == "CRITICAL" or severity_text == "PANIC" # default: everything still unlabelled is INFO - set(severity_text, "INFO") where severity_text == "" # severity_text -> severity_number (only if not already set upstream) - set(severity_number, SEVERITY_NUMBER_TRACE) where severity_number == 0 and severity_text == "TRACE" - set(severity_number, SEVERITY_NUMBER_DEBUG) where severity_number == 0 and severity_text == "DEBUG" - set(severity_number, SEVERITY_NUMBER_INFO) where severity_number == 0 and severity_text == "INFO" - set(severity_number, SEVERITY_NUMBER_WARN) where severity_number == 0 and severity_text == "WARN" - set(severity_number, SEVERITY_NUMBER_ERROR) where severity_number == 0 and severity_text == "ERROR" - set(severity_number, SEVERITY_NUMBER_FATAL) where severity_number == 0 and severity_text == "FATAL" # Promote high-value fields out of the body into log attributes so the # logs UI can facet/filter on them without parsing the body per row. transform/extract: error_mode: ignore log_statements: - context: log statements: # JSON app logs: promote the logger name for faceting - set(cache, ParseJSON(body)) where IsString(body) and IsMatch(body, "^\\s*\\{") - set(attributes["logger"], cache["logger"]) where IsString(cache["logger"]) - set(attributes["logger"], cache["loggerName"]) where attributes["logger"] == nil and IsString(cache["loggerName"]) - set(attributes["logger"], cache["name"]) where attributes["logger"] == nil and IsString(cache["name"]) # HTTP access logs (nginx / gunicorn / uvicorn): method + status - merge_maps(attributes, ExtractPatterns(body, "\"(?PGET|POST|PUT|DELETE|PATCH|HEAD|OPTIONS) [^\"]*\" (?P[0-9]{3})"), "upsert") where IsString(body) and IsMatch(body, "\"(GET|POST|PUT|DELETE|PATCH|HEAD|OPTIONS) [^\"]*\" [0-9]{3}") # server errors in access logs are ERRORs even though the line has no level - set(severity_text, "ERROR") where IsString(attributes["http_response_status_code"]) and IsMatch(attributes["http_response_status_code"], "^5") - set(severity_number, SEVERITY_NUMBER_ERROR) where severity_text == "ERROR" and severity_number < SEVERITY_NUMBER_ERROR transform/service_name_fallback: error_mode: ignore trace_statements: - context: span statements: - set(resource.attributes["service.name"], resource.attributes["k8s.container.name"]) where resource.attributes["k8s.container.name"] != nil k8sattributes: auth_type: serviceAccount extract: metadata: - k8s.namespace.name - k8s.pod.name - k8s.pod.hostname - k8s.pod.ip - k8s.pod.start_time - k8s.pod.uid - k8s.replicaset.uid - k8s.replicaset.name - k8s.deployment.uid - k8s.deployment.name - k8s.daemonset.uid - k8s.daemonset.name - k8s.statefulset.uid - k8s.statefulset.name - k8s.cronjob.name - k8s.job.uid - k8s.job.name - k8s.node.name - k8s.cluster.uid - container.image.name - container.image.tag - container.id annotations: - tag_name: service.name key: resource.opentelemetry.io/service.name from: pod - tag_name: service.namespace key: resource.opentelemetry.io/service.namespace from: pod - tag_name: service.version key: resource.opentelemetry.io/service.version from: pod - tag_name: service.instance.id key: resource.opentelemetry.io/service.instance.id from: pod labels: - tag_name: kube_app_name key: app.kubernetes.io/name from: pod - tag_name: kube_app_instance key: app.kubernetes.io/instance from: pod - tag_name: kube_app_version key: app.kubernetes.io/version from: pod - tag_name: kube_app_component key: app.kubernetes.io/component from: pod - tag_name: kube_app_part_of key: app.kubernetes.io/part-of from: pod - tag_name: kube_app_managed_by key: app.kubernetes.io/managed-by from: pod pod_association: - sources: - from: resource_attribute name: k8s.pod.ip - sources: - from: resource_attribute name: k8s.pod.uid - sources: - from: connection exporters: otlp/agent: endpoint: scout-agent-collector.observability.svc.cluster.local:4317 tls: insecure: true service: extensions: [zpages, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, resource, resource/env, transform/service_name_fallback, batch] exporters: [otlp/agent] logs: receivers: [otlp, filelog] processors: - memory_limiter - transform/filelog - k8sattributes - transform/severity - transform/extract - resource/env - batch exporters: [otlp/agent] metrics: receivers: [otlp] processors: [memory_limiter, resource/env, batch] exporters: [otlp/agent] metrics/k8s: receivers: [kubeletstats] processors: - memory_limiter - resource/k8s - resourcedetection/eks - resource/env - k8sattributes - batch exporters: [otlp/agent] telemetry: logs: level: warn encoding: json env: - name: K8S_NODE_NAME valueFrom: fieldRef: fieldPath: spec.nodeName - name: CLUSTER_NAME value: "" - name: ENVIRONMENT value: "" - name: APP_NAME value: "" volumeMounts: - name: varlogpods mountPath: /var/log/pods readOnly: true volumes: - name: varlogpods hostPath: path: /var/log/pods ``` ##### Agent Collector (Deployment) ```yaml showLineNumbers title="scout-agent-collector.yaml" apiVersion: opentelemetry.io/v1beta1 kind: OpenTelemetryCollector metadata: name: scout-agent namespace: observability spec: mode: deployment replicas: 1 image: otel/opentelemetry-collector-contrib:0.130.1 serviceAccount: otel-collector-sa config: extensions: health_check: endpoint: 0.0.0.0:13133 zpages: endpoint: 0.0.0.0:55679 oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: ${env:SCOUT_TOKEN_URL} tls: insecure_skip_verify: true receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 k8s_cluster: auth_type: serviceAccount collection_interval: 60s node_conditions_to_report: - Ready - MemoryPressure - DiskPressure - PIDPressure - NetworkUnavailable resource_attributes: k8s.container.status.last_terminated_reason: enabled: true metrics: k8s.pod.status_reason: enabled: true k8s.node.condition: enabled: true allocatable_types_to_report: - cpu - memory - ephemeral-storage - storage k8sobjects: objects: - name: events mode: pull interval: 60s group: events.k8s.io - name: deployments mode: pull interval: 60s group: apps - name: resourcequotas mode: pull interval: 60s processors: batch: timeout: 2s send_batch_size: 8192 send_batch_max_size: 10000 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 30 resource: attributes: - key: service.name value: ${env:APP_NAME} action: upsert resource/k8s: attributes: - key: service.name value: k8s action: upsert resource/k8s-events: attributes: - key: service.name value: k8s-events action: upsert resource/env: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: k8s.cluster.name value: ${env:CLUSTER_NAME} action: upsert resourcedetection/eks: detectors: [env, eks] override: true eks: resource_attributes: k8s.cluster.name: enabled: true # Extract severity from log bodies; anything left unmatched defaults to # INFO. All rules are guarded by severity_text == "" so logs that already # carry severity (e.g. processed by scout-daemon) pass through untouched. transform/severity: error_mode: ignore log_statements: - context: log statements: # k8s events (body is a map from the k8sobjects receiver) - set(severity_text, "WARN") where severity_text == "" and IsMap(body) and body["type"] == "Warning" - set(severity_text, "INFO") where severity_text == "" and IsMap(body) and body["type"] == "Normal" # structured JSON string bodies (direct OTLP logs) - set(cache, ParseJSON(body)) where severity_text == "" and IsString(body) and IsMatch(body, "^\\s*\\{") - set(severity_text, ConvertCase(cache["level"], "upper")) where severity_text == "" and IsString(cache["level"]) - set(severity_text, ConvertCase(cache["severity"], "upper")) where severity_text == "" and IsString(cache["severity"]) - set(severity_text, "TRACE") where severity_text == "" and cache["level"] == 10 - set(severity_text, "DEBUG") where severity_text == "" and cache["level"] == 20 - set(severity_text, "INFO") where severity_text == "" and cache["level"] == 30 - set(severity_text, "WARN") where severity_text == "" and cache["level"] == 40 - set(severity_text, "ERROR") where severity_text == "" and cache["level"] == 50 - set(severity_text, "FATAL") where severity_text == "" and cache["level"] == 60 # normalize synonyms - set(severity_text, "WARN") where severity_text == "WARNING" - set(severity_text, "ERROR") where severity_text == "ERR" - set(severity_text, "FATAL") where severity_text == "CRITICAL" or severity_text == "PANIC" # default: everything still unlabelled is INFO - set(severity_text, "INFO") where severity_text == "" # severity_text -> severity_number (only if not already set upstream) - set(severity_number, SEVERITY_NUMBER_TRACE) where severity_number == 0 and severity_text == "TRACE" - set(severity_number, SEVERITY_NUMBER_DEBUG) where severity_number == 0 and severity_text == "DEBUG" - set(severity_number, SEVERITY_NUMBER_INFO) where severity_number == 0 and severity_text == "INFO" - set(severity_number, SEVERITY_NUMBER_WARN) where severity_number == 0 and severity_text == "WARN" - set(severity_number, SEVERITY_NUMBER_ERROR) where severity_number == 0 and severity_text == "ERROR" - set(severity_number, SEVERITY_NUMBER_FATAL) where severity_number == 0 and severity_text == "FATAL" # k8s events: promote reason/object fields to attributes for faceting in # the logs UI, and replace the raw event JSON body with the # human-readable message. Must run AFTER transform/severity (severity # reads body["type"] before the body is replaced). transform/k8s-events: error_mode: ignore log_statements: - context: log statements: - set(attributes["event.type"], body["type"]) where IsMap(body) and body["type"] != nil - set(attributes["event.reason"], body["reason"]) where IsMap(body) and body["reason"] != nil - set(attributes["k8s.object.kind"], body["regarding"]["kind"]) where IsMap(body) and body["regarding"] != nil - set(attributes["k8s.object.name"], body["regarding"]["name"]) where IsMap(body) and body["regarding"] != nil - set(attributes["k8s.namespace.name"], body["regarding"]["namespace"]) where IsMap(body) and body["regarding"] != nil - set(attributes["event.count"], body["deprecatedCount"]) where IsMap(body) and body["deprecatedCount"] != nil - set(body, body["note"]) where IsMap(body) and body["note"] != nil transform/service_name_fallback: error_mode: ignore trace_statements: - context: span statements: - set(resource.attributes["service.name"], resource.attributes["k8s.container.name"]) where resource.attributes["k8s.container.name"] != nil k8sattributes: auth_type: serviceAccount extract: metadata: - k8s.namespace.name - k8s.pod.name - k8s.pod.hostname - k8s.pod.ip - k8s.pod.start_time - k8s.pod.uid - k8s.replicaset.uid - k8s.replicaset.name - k8s.deployment.uid - k8s.deployment.name - k8s.daemonset.uid - k8s.daemonset.name - k8s.statefulset.uid - k8s.statefulset.name - k8s.cronjob.name - k8s.job.uid - k8s.job.name - k8s.node.name - k8s.cluster.uid - container.image.name - container.image.tag - container.id annotations: - tag_name: service.name key: resource.opentelemetry.io/service.name from: pod - tag_name: service.namespace key: resource.opentelemetry.io/service.namespace from: pod - tag_name: service.version key: resource.opentelemetry.io/service.version from: pod - tag_name: service.instance.id key: resource.opentelemetry.io/service.instance.id from: pod labels: - tag_name: kube_app_name key: app.kubernetes.io/name from: pod - tag_name: kube_app_instance key: app.kubernetes.io/instance from: pod - tag_name: kube_app_version key: app.kubernetes.io/version from: pod - tag_name: kube_app_component key: app.kubernetes.io/component from: pod - tag_name: kube_app_part_of key: app.kubernetes.io/part-of from: pod - tag_name: kube_app_managed_by key: app.kubernetes.io/managed-by from: pod pod_association: - sources: - from: resource_attribute name: k8s.pod.ip - sources: - from: resource_attribute name: k8s.pod.uid - sources: - from: connection exporters: otlphttp/b14: endpoint: ${env:SCOUT_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true retry_on_failure: enabled: true initial_interval: 2s max_interval: 10s max_elapsed_time: 60s service: extensions: [oauth2client, zpages, health_check] pipelines: traces: receivers: [otlp] processors: [memory_limiter, resource, resource/env, transform/service_name_fallback, batch] exporters: [otlphttp/b14] logs: receivers: [otlp] processors: [memory_limiter, resource/env, transform/severity, batch] exporters: [otlphttp/b14] logs/k8s-events: receivers: [k8sobjects] processors: - memory_limiter - resource/k8s-events - resourcedetection/eks - resource/env - transform/severity - transform/k8s-events - batch exporters: [otlphttp/b14] logs/k8s-cluster: receivers: [k8s_cluster] processors: - memory_limiter - resource/k8s - resourcedetection/eks - resource/env - transform/severity - batch exporters: [otlphttp/b14] metrics: receivers: [otlp] processors: [memory_limiter, resource/env, batch] exporters: [otlphttp/b14] metrics/k8s: receivers: [k8s_cluster] processors: - memory_limiter - resource/k8s - resourcedetection/eks - resource/env - k8sattributes - batch exporters: [otlphttp/b14] telemetry: logs: level: warn encoding: json env: - name: SCOUT_ENDPOINT valueFrom: secretKeyRef: name: scout-credentials key: endpoint - name: SCOUT_CLIENT_ID valueFrom: secretKeyRef: name: scout-credentials key: client-id - name: SCOUT_CLIENT_SECRET valueFrom: secretKeyRef: name: scout-credentials key: client-secret - name: SCOUT_TOKEN_URL valueFrom: secretKeyRef: name: scout-credentials key: token-url - name: CLUSTER_NAME value: "" - name: ENVIRONMENT value: "" - name: APP_NAME value: "" ``` ```mdx-code-block ``` #### Required RBAC Create the ServiceAccount and RBAC permissions: ```yaml showLineNumbers title="rbac.yaml" apiVersion: v1 kind: ServiceAccount metadata: name: otel-collector-sa namespace: observability --- apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRole metadata: name: otel-collector-role rules: - apiGroups: [""] resources: - pods - namespaces - nodes - nodes/stats - nodes/proxy - services - endpoints - resourcequotas - replicationcontrollers - replicationcontrollers/status verbs: ["get", "list", "watch"] - apiGroups: ["apps"] resources: - replicasets - deployments - daemonsets - statefulsets verbs: ["get", "list", "watch"] - apiGroups: ["batch"] resources: - jobs - cronjobs verbs: ["get", "list", "watch"] - apiGroups: ["autoscaling"] resources: - horizontalpodautoscalers verbs: ["get", "list", "watch"] - apiGroups: ["events.k8s.io"] resources: - events verbs: ["get", "list", "watch"] --- apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRoleBinding metadata: name: otel-collector-binding subjects: - kind: ServiceAccount name: otel-collector-sa namespace: observability roleRef: kind: ClusterRole name: otel-collector-role apiGroup: rbac.authorization.k8s.io ``` #### Deploy the Collectors ```bash # Apply RBAC kubectl apply -f rbac.yaml # For Fargate kubectl apply -f scout-collector.yaml # For Managed Nodes kubectl apply -f scout-daemon-collector.yaml kubectl apply -f scout-agent-collector.yaml ``` Verify the collectors are running: ```bash kubectl get pods -n observability -l app.kubernetes.io/component=opentelemetry-collector ``` ### Automatic Instrumentation The OpenTelemetry Operator can automatically inject instrumentation into your applications without code changes. #### Supported Languages | Language | Annotation | Protocol | |----------|------------|----------| | Java | `instrumentation.opentelemetry.io/inject-java: "observability/scout-instrumentation"` | OTLP HTTP (4318) | | Python | `instrumentation.opentelemetry.io/inject-python: "observability/scout-instrumentation"` | OTLP HTTP (4318) | | Node.js | `instrumentation.opentelemetry.io/inject-nodejs: "observability/scout-instrumentation"` | OTLP HTTP (4318) | | .NET | `instrumentation.opentelemetry.io/inject-dotnet: "observability/scout-instrumentation"` | OTLP HTTP (4318) | | Go | `instrumentation.opentelemetry.io/inject-go: "observability/scout-instrumentation"` | eBPF (requires elevated permissions) | #### Step 1: Create an Instrumentation Resource Create a file named `instrumentation.yaml`: ```yaml showLineNumbers title="instrumentation.yaml" apiVersion: opentelemetry.io/v1alpha1 kind: Instrumentation metadata: name: scout-instrumentation namespace: observability spec: exporter: endpoint: http://scout-agent-collector.observability.svc.cluster.local:4318 propagators: - tracecontext - baggage sampler: type: parentbased_traceidratio argument: "1.0" java: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-java:latest env: - name: OTEL_INSTRUMENTATION_JDBC_ENABLED value: "true" - name: OTEL_INSTRUMENTATION_SPRING_WEBMVC_ENABLED value: "true" python: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-python:latest env: - name: OTEL_PYTHON_LOG_CORRELATION value: "true" nodejs: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-nodejs:latest dotnet: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-dotnet:latest go: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-go:latest ``` Deploy the Instrumentation resource: ```bash kubectl apply -f instrumentation.yaml ``` :::warning Important The Instrumentation resource must be deployed **before** your application pods. If your application is already running, restart it after creating the Instrumentation resource. ::: #### Step 2: Annotate Your Application Add the appropriate annotation to your Deployment, StatefulSet, or Pod: ```mdx-code-block ``` ```yaml showLineNumbers title="java-deployment.yaml" apiVersion: apps/v1 kind: Deployment metadata: name: my-java-app namespace: observability spec: replicas: 1 selector: matchLabels: app: my-java-app template: metadata: labels: app: my-java-app annotations: instrumentation.opentelemetry.io/inject-java: "observability/scout-instrumentation" spec: containers: - name: app image: my-java-app:latest ports: - containerPort: 8080 ``` ```mdx-code-block ``` ```yaml showLineNumbers title="python-deployment.yaml" apiVersion: apps/v1 kind: Deployment metadata: name: my-python-app namespace: observability spec: replicas: 1 selector: matchLabels: app: my-python-app template: metadata: labels: app: my-python-app annotations: instrumentation.opentelemetry.io/inject-python: "observability/scout-instrumentation" spec: containers: - name: app image: my-python-app:latest ports: - containerPort: 8000 ``` ```mdx-code-block ``` ```yaml showLineNumbers title="nodejs-deployment.yaml" apiVersion: apps/v1 kind: Deployment metadata: name: my-nodejs-app namespace: observability spec: replicas: 1 selector: matchLabels: app: my-nodejs-app template: metadata: labels: app: my-nodejs-app annotations: instrumentation.opentelemetry.io/inject-nodejs: "observability/scout-instrumentation" spec: containers: - name: app image: my-nodejs-app:latest ports: - containerPort: 3000 ``` ```mdx-code-block ``` ```yaml showLineNumbers title="dotnet-deployment.yaml" apiVersion: apps/v1 kind: Deployment metadata: name: my-dotnet-app namespace: observability spec: replicas: 1 selector: matchLabels: app: my-dotnet-app template: metadata: labels: app: my-dotnet-app annotations: instrumentation.opentelemetry.io/inject-dotnet: "observability/scout-instrumentation" spec: containers: - name: app image: my-dotnet-app:latest ports: - containerPort: 5000 ``` ```mdx-code-block ``` #### Step 3: Verify Instrumentation After deploying your application, verify the instrumentation is working: ```bash # Check that init container was injected kubectl get pod -n observability -l app=my-java-app -o jsonpath='{.items[0].spec.initContainers[*].name}' ``` Expected output includes `opentelemetry-auto-instrumentation`. Check the environment variables: ```bash kubectl exec -n observability deployment/my-java-app -- env | grep OTEL ``` ### Advanced Configuration #### Multi-Container Pod Instrumentation To instrument specific containers in a multi-container pod: ```yaml showLineNumbers metadata: annotations: instrumentation.opentelemetry.io/inject-java: "observability/scout-instrumentation" instrumentation.opentelemetry.io/container-names: "app-container" ``` #### Namespace-Scoped Instrumentation Apply instrumentation to all pods in a namespace: ```yaml showLineNumbers apiVersion: v1 kind: Namespace metadata: name: my-namespace annotations: instrumentation.opentelemetry.io/inject-java: "observability/scout-instrumentation" ``` ### Troubleshooting #### Common Issues ##### Operator Not Starting Check operator logs: ```bash kubectl logs -n opentelemetry-operator-system deployment/opentelemetry-operator-controller-manager ``` Common causes: - cert-manager not installed or not ready - Insufficient RBAC permissions ##### Collector Not Receiving Data 1. Verify the collector is running: ```bash kubectl get pods -n observability -l app.kubernetes.io/component=opentelemetry-collector ``` 2. Check collector logs: ```bash kubectl logs -n observability -l app.kubernetes.io/name=scout-collector-collector ``` 3. Verify the service is accessible: ```bash kubectl get svc -n observability ``` ##### Auto-Instrumentation Not Working 1. Ensure the Instrumentation resource exists in the same namespace: ```bash kubectl get instrumentation -n observability ``` 2. Check that the pod was restarted after annotation: ```bash kubectl rollout restart deployment/my-app -n observability ``` 3. Verify init container injection: ```bash kubectl describe pod -n observability -l app=my-app | grep -A5 "Init Containers" ``` ##### Authentication Errors Check that the Scout credentials secret exists and has correct values: ```bash kubectl get secret scout-credentials -n observability -o yaml ``` Verify the OAuth2 token URL is correct and accessible from the cluster. ### Related Guides - [Scout Exporter Configuration](./scout-exporter.md) - Configure authentication to send data to Scout - [Kubernetes Helm Setup](./kubernetes-helm-setup.md) - Alternative Helm-based deployment - [Advanced Collector Configuration](./otel-collector-config.md) - Full collector configuration reference - [Spring Boot Instrumentation](../apps/auto-instrumentation/spring-boot.md) - Java application instrumentation - [FastAPI Instrumentation](../apps/auto-instrumentation/fast-api.md) - Python application instrumentation ### Learn More - [OpenTelemetry Operator Documentation](https://opentelemetry.io/docs/platforms/kubernetes/operator/) - [OpenTelemetry Operator GitHub](https://github.com/open-telemetry/opentelemetry-operator) - [Auto-Instrumentation Guide](https://opentelemetry.io/docs/platforms/kubernetes/operator/automatic/) --- ## OpenTelemetry Collector Binary Installation Guide ## OpenTelemetry Binary Set up and configure the Scout Collector through binary downloaded from releases page. ### Overview This guide demonstrates how to set up and configure the Scout Collector binary for collecting and exporting telemetry data to base14 Scout. - Binary installation and configuration - Log collection setup with file monitoring - Secure data export with OAuth2 authentication - Sample application integration #### Key Features - **Easy Installation**: Direct binary download and setup - **Flexible Configuration**: YAML-based configuration - **Secure Authentication**: Built-in OAuth2 support - **Data Processing**: Log filtering and batching - **Real-time Monitoring**: Live log collection and export ### Prerequisites - `curl` command-line tool - `Node.js` (for running the example application) - A base14 Scout account with valid authentication credentials ### Install the collector binary The collector binary can be downloaded from the [releases page](https://github.com/open-telemetry/opentelemetry-collector-releases/releases). An example of how to download and extract the collector binary is shown below for macos arm64. ```bash curl --proto '=https' --tlsv1.2 -fOL https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v0.127.0/otelcol-contrib_0.127.0_darwin_arm64.tar.gz tar -xvf otelcol-contrib_0.127.0_darwin_arm64.tar.gz ``` ### Example configuration An example config can be seen to collect logs from a file to export to Scout ```yaml showLineNumbers extensions: oauth2client: client_id: demo client_secret: 01JM94R5DPSZXBGK5QA4D329N5 endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/playground/protocol/openid-connect/token exporters: debug: otlphttp/auth: endpoint: https://otel.play.b14.dev/01jm94npk4h8ys63x1kzw2bjes/otlp auth: authenticator: oauth2client processors: batch: redaction: blocked_values: # MasterCard number - "(5[1-5][0-9]{14})" summary: debug receivers: # Data sources: traces, metrics, logs filelog: include: [ "app.log" ] service: extensions: [ oauth2client ] pipelines: logs: receivers: [ filelog ] processors: [ batch ] exporters: [ otlphttp/auth, debug ] ``` ### Running the collector ```bash ./otelcol-contrib --config ./config.yaml ``` ### Run a Sample Node.js Application Let's create a simple Node.js application that generates structured logs using the `pino` logging library. The Scout Collector will collect these logs and forward them to Scout. #### 1. Install Dependencies First, install the `pino` logging library, which provides structured JSON logging capabilities: ```bash npm install pino ``` #### 2. Create the Application Create a new file called `main.js` with the following code that demonstrates basic logging functionality: ```js title="main.js" const logger = require("pino")(); logger.info("hello world"); const child = logger.child({ a: "property" }); child.info("hello child!"); ``` #### 3. Run the Application Execute the application and redirect its output to `app.log`. The OpenTelemetry Collector will monitor this file as configured in the previous section: ```bash node main.js > app.log ``` ### View Logs in base14 Scout After running the application, you can view the collected logs in Scout: 1. Open your base14 Scout dashboard 2. Navigate to the `Dashboards > Library > Logs View` in the main menu 3. You should see the following log entries: - A "hello world" message from the root logger - A "hello child!" message with an additional property `{a: 'property'}` The logs will appear with timestamps and other metadata added by the Scout Collector. ### Related Guides - [OTel Collector Configuration](./otel-collector-config.md) - Advanced configuration examples - [Scout Exporter Configuration](./scout-exporter.md) - Detailed authentication setup - [Linux Installation](./linux-setup.md) - Production deployment with systemd --- ## OpenTelemetry Collector Configuration - Receivers, Processors & Exporters ## Configuration Collect, process and export telemetry data efficiently with the Scout Collector (`otelcol`). ### Overview Scout Collector serves as a vendor-agnostic implementation for handling telemetry data. This guide covers: - Core configuration components (receivers, processors, exporters) - Advanced configuration options - Best practices and examples ### Prerequisites - Basic understanding of OpenTelemetry concepts ### Configuration The Scout Collector uses YAML for its configuration. The configuration file is structured into several sections: #### receivers OpenTelemetry receivers serve as data ingestion points for the collector, accepting telemetry data from multiple sources. They support various protocols and formats for collecting logs, metrics and traces. ```yaml showLineNumbers receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 prometheus: config: scrape_configs: - job_name: "otel-collector" scrape_interval: 10s static_configs: - targets: ["0.0.0.0:8888"] ``` Key features of receivers: - Protocol support: OTLP, Prometheus, Jaeger, Zipkin - Multiple transport options: gRPC, HTTP, TCP - Configurable endpoints and TLS settings - Custom metadata handling ##### Reference [Official Receivers Documentation](https://opentelemetry.io/docs/collector/configuration/#receivers) #### processors Processors are applied to the data between reception and export. They can perform various transformations, filtering, and enrichment operations. ```yaml showLineNumbers processors: batch: timeout: 1s send_batch_size: 1024 memory_limiter: check_interval: 1s limit_mib: 4000 resourcedetection: detectors: [env, system] timeout: 5s attributes: actions: - key: environment value: production action: insert ``` Common processors include: - `batch`: Groups data before sending to exporters - `memory_limiter`: Prevents out-of-memory errors - `resourcedetection`: Detects resource information - `attributes`: Modifies, adds, or removes attributes from the telemetry data ##### Reference [Official Processors Documentation](https://opentelemetry.io/docs/collector/configuration/#processors) #### exporters OpenTelemetry exporters transmit telemetry data to destination backends. They handle the delivery of logs, metrics and traces to various observability platforms and monitoring systems. ```yaml showLineNumbers exporters: otlp: endpoint: otelcol:4317 tls: insecure: true prometheus: endpoint: 0.0.0.0:8889 logging: verbosity: detailed zipkin: endpoint: http://zipkin:9411/api/v2/spans ``` Supported export destinations: - Other Scout Collectors e.g. OpenTelemetry protocol (OTLP) endpoints - Backend observability platforms - Monitoring systems e.g. Prometheus systems - Logging platforms - Tracing systems ##### Reference [Official Exporters Documentation](https://opentelemetry.io/docs/collector/configuration/#exporters) #### extensions Scout Collector extensions enhance core functionality by providing operational features such as: - Health monitoring and readiness checks - Performance profiling and debugging - Service discovery mechanisms - Diagnostic tools and dashboards ```yaml showLineNumbers extensions: health_check: endpoint: 0.0.0.0:13133 pprof: endpoint: 0.0.0.0:1888 zpages: endpoint: 0.0.0.0:55679 ``` Common OpenTelemetry extensions include: - `health_check`: HTTP endpoint for monitoring collector health and readiness status - `pprof`: Performance profiling endpoints for debugging and optimization - `zpages`: Zero-configuration diagnostic web pages for troubleshooting ##### Reference [Official Extensions Documentation](https://opentelemetry.io/docs/collector/configuration/#extensions) #### service The Scout Collector service configuration defines pipeline architecture, data flow, and operational settings such as: - Pipeline definitions for logs, metrics and traces - Component enablement and connections - Collector telemetry settings ```yaml showLineNumbers service: extensions: [health_check, pprof, zpages] pipelines: traces: receivers: [otlp] processors: [memory_limiter, batch] exporters: [otlp, zipkin] metrics: receivers: [otlp, prometheus] processors: [memory_limiter, batch] exporters: [otlp, prometheus] logs: receivers: [otlp] processors: [batch] exporters: [otlp, logging] telemetry: logs: level: info metrics: level: detailed ``` Key components: - `extensions`: Configure and enable operational extensions like health checks, profiling, and diagnostics - `pipelines`: Define data processing workflows for different telemetry types - `telemetry`: Configuration for the collector's self-monitoring capabilities ##### Reference [Official Service Documentation](https://opentelemetry.io/docs/collector/configuration/#service) ### Advanced Configuration Elements #### connectors Connectors function as both exporters and receivers, allowing telemetry data to be routed between pipelines internally without leaving the collector. - Cross-pipeline data routing - Span-to-metrics conversion - Internal data transformation ```yaml showLineNumbers connectors: forward: spanmetrics: dimensions: - name: http.method - name: http.status_code metrics_flush_interval: 15s ``` Common OpenTelemetry connector types include: - `forward`: Internal pipeline connector for routing telemetry data between processing chains - `spanmetrics`: Generates performance metrics from trace spans for latency analysis - `count`: Creates count metrics from spans or logs - `servicegraph`: Builds service dependency graphs from trace data ##### Reference [Official Connectors Documentation](https://opentelemetry.io/docs/collector/configuration/#connectors) #### telemetry The Scout Collector telemetry configuration manages the collector's self-monitoring capabilities, including: - Internal metrics collection and reporting - Diagnostic log management - Trace sampling configuration - Performance monitoring endpoints - Health status reporting ```yaml showLineNumbers service: telemetry: logs: level: info development: false encoding: console metrics: level: detailed address: 0.0.0.0:8888 ``` Telemetry configuration options include: - Log verbosity and format - Internal metrics reporting - Self-monitoring capabilities [Official Telemetry Documentation](https://opentelemetry.io/docs/collector/configuration/#telemetry) ### Configuration Best Practices 1. **Start Simple**: Begin with minimal configuration and add components as needed 2. **Use Environment Variables**: Leverage environment variable substitution for dynamic configuration ```yaml showLineNumbers exporters: otlp: endpoint: ${OTLP_ENDPOINT} ``` 3. **Implement Memory Protection**: Always include memory_limiter processor to prevent OOM issues 4. **Consider Resources**: Set appropriate resource limits based on expected load 5. **Enable Health Checks**: Include health_check extension for monitoring 6. **Use Batching**: Implement batching for efficient data transmission ### Scout Collector Configuration Best Practices Essential configuration guidelines for optimal Scout Collector deployment: 1. **Start Simple**: - Begin with basic OpenTelemetry configuration - Add components incrementally - Test each configuration change - Validate telemetry flow 2. **Use Environment Variables**: - Implement dynamic configuration - Secure sensitive information - Enable deployment flexibility ```yaml showLineNumbers exporters: otlp: endpoint: ${OTLP_ENDPOINT} ``` 3. **Implement Memory Protection**: - Configure `memory_limiter` processor - Prevent out-of-memory (OOM) crashes - Set appropriate memory thresholds - Monitor memory usage 4. **Resource Management**: - Configure CPU limits - Set memory boundaries - Adjust based on telemetry volume - Monitor resource utilization 5. **Health Monitoring**: - Enable `health_check` extension - Configure monitoring endpoints - Set up alerting - Monitor collector status 6. **Performance Optimization**: - Enable batch processing - Configure optimal batch sizes - Set appropriate timeouts - Monitor throughput metrics ### Configuration Examples #### Basic Collection and Export ```yaml showLineNumbers receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: batch: timeout: 1s send_batch_size: 1024 exporters: otlp: endpoint: backend.example.com:4317 tls: ca_file: /certs/ca.pem service: pipelines: traces: receivers: [otlp] processors: [batch] exporters: [otlp] metrics: receivers: [otlp] processors: [batch] exporters: [otlp] logs: receivers: [otlp] processors: [batch] exporters: [otlp] ``` #### Advanced Configuration with Multiple Pipelines ```yaml showLineNumbers receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 prometheus: config: scrape_configs: - job_name: "app-metrics" scrape_interval: 10s static_configs: - targets: ["app:8080"] processors: batch: timeout: 5s attributes: actions: - key: environment value: production action: insert resourcedetection: detectors: [env, system] exporters: otlp/traces: endpoint: traces.backend.com:4317 otlp/metrics: endpoint: metrics.backend.com:4317 prometheus: endpoint: 0.0.0.0:8889 extensions: health_check: endpoint: 0.0.0.0:13133 service: extensions: [health_check] pipelines: traces: receivers: [otlp] processors: [attributes, resourcedetection, batch] exporters: [otlp/traces] metrics: receivers: [otlp, prometheus] processors: [resourcedetection, batch] exporters: [otlp/metrics, prometheus] ``` ### FAQ #### What are the main sections of an OpenTelemetry Collector config file? Five: `receivers` for ingestion, `processors` for transformation and filtering, `exporters` for sending data onward, `extensions` for health checks and diagnostics, and `service` for the pipelines that wire the other four together. #### How do I configure Collector pipelines for traces, metrics, and logs? Define one pipeline per signal under `service`, each naming its receivers, processors, and exporters. A traces pipeline typically uses the `otlp` receiver, the `batch` processor, and the `otlp` exporter. Scout accepts all three signal types. #### What processors should a production Collector config include? Always the `memory_limiter` processor, to stop the collector being OOM-killed under load, and the `batch` processor, for efficient export. Add `resourcedetection` to attach host metadata and `attributes` to add environment labels. #### How do I use environment variables in Collector configuration? Reference them as `${ENV_VAR_NAME}` in the YAML. For example, `endpoint: ${OTLP_ENDPOINT}` keeps the endpoint out of the config file and lets one config serve several environments. #### What are OpenTelemetry Collector connectors used for? Connectors act as an exporter on one pipeline and a receiver on another, routing telemetry between pipelines inside the collector. The common ones are `spanmetrics`, which derives metrics from traces, and `forward`, which chains processing stages. ### Related Guides - [OTTL Functions Reference](../../operate/filters-and-transformations/ottl-functions-reference.md) — Complete reference for transform and filter processor expressions - [Scout Exporter Configuration](./scout-exporter.md) — Configure data export to Scout - [Extract Log Level from Body](../../operate/filters-and-transformations/extract-log-level-from-body.md) — Parse and categorize log severity - [Transform and Filter Logs](../../operate/filters-and-transformations/transform-logs.md) — Advanced log processing techniques ### Resources - [Scout Collector Configuration Documentation](https://opentelemetry.io/docs/collector/configuration/) - [Scout Collector GitHub Repository](https://github.com/open-telemetry/opentelemetry-collector) - [Scout Collector Contrib Repository](https://github.com/open-telemetry/opentelemetry-collector-contrib) --- ## Scout Exporter Configuration ## Scout Exporter The Scout exporter is a custom exporter for the Scout Collector that exports telemetry data to Scout. ### Configuration The Scout exporter requires two main configuration components: 1. OAuth2 Authentication Setup: - Configure OAuth2 client credentials - Set up token endpoint - Configure TLS settings 2. Exporter Configuration: - Set up endpoint URL - Configure authentication - Enable TLS settings ```yaml showLineNumbers extensions: oauth2client: client_id: __YOUR_CLIENT_ID__ client_secret: __YOUR_CLIENT_SECRET__ endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token tls: insecure_skip_verify: true exporters: otlphttp/b14: endpoint: https://otel.play.b14.dev/__YOUR_TENANT__/otlp auth: authenticator: oauth2client tls: insecure_skip_verify: true ``` ### Related Guides - [Docker Compose Setup](./docker-compose-example.md) - Quick local development setup - [Kubernetes Helm Setup](./kubernetes-helm-setup.md) - Production Kubernetes deployment - [OpenTelemetry Operator Setup](./opentelemetry-operator-setup.md) - Auto-instrumentation and CRD-based collector management - [Advanced Collector Configuration](./otel-collector-config.md) - Full collector configuration reference - [IoT & Edge Instrumentation](../iot/index.md) - Ship telemetry from edge Collectors over MQTT, Sparkplug B, and OPC-UA --- ## Send OpenTelemetry Signals Directly to Scout Backend ## Sending OpenTelemetry Signals Directly to Scout Backend This guide explains how to configure applications to send OpenTelemetry traces, logs, and metrics directly to the Scout backend, without using intermediate collectors or agents. ### Data Flow ```markdown Application → OpenTelemetry SDK → OTLP Exporter → Scout Backend ``` The direct export flow consists of: 1. **Application generates telemetry**: The application is instrumented with an OpenTelemetry SDK that exports telemetry signals (traces, metrics, logs)directly into the Scout backend. 2. **OpenTelemetry SDK**: The SDK batches and processes telemetry data 3. **OTLP Exporter**: Data is exported via OTLP (OpenTelemetry Protocol) over HTTP/gRPC 4. **Authentication**: OIDC token-based authentication secures the connection 5. **Scout Backend**: The scout backend receives and processes the telemetry and send them for visualization in the Scout UI. Refer [this](https://docs.base14.io/) for more details. ### Tradeoffs **Pros:** - Simple to use (especially in a dev/test environment) - No additional moving parts to operate (in production environments) **Cons:** - Requires code changes if collection, processing, or ingestion changes - Strong coupling between the application code and the backend - There are limited number of exporters per language implementation ### Required Dependencies All applications need these core components: 1. **OpenTelemetry SDK**: Core functionality for generating telemetry 2. **OTLP Exporter**: For sending data via OpenTelemetry Protocol over HTTP/gRPC 3. **Auto-instrumentation libraries**: Framework-specific instrumentation (e.g., Rails instrumentation) 4. **HTTP client**: For fetching OIDC tokens ### Example: Rails Application #### Configuration Changes Required When sending telemetry directly to Scout backend, your application needs the following changes: #### 1. Environment Variables Set these environment variables for your application: ```bash # Service identification OTEL_SERVICE_NAME=rails-service-name RAILS_ENV=production # or staging # Scout collector configuration SCOUT_ENDPOINT=https://scout-collector-endpoint/v1/traces SCOUT_CLIENT_ID=your-client-id SCOUT_CLIENT_SECRET=your-client-secret SCOUT_TOKEN_URL=https://id.b14.dev/realms/your-tenant/protocol/openid-connect/token ``` #### 2. Opentelemetry Configuration Create `config/initializers/opentelemetry.rb`: ```ruby require "opentelemetry/sdk" require "opentelemetry/exporter/otlp" require "opentelemetry/instrumentation/all" require "net/http" require "json" # Function to fetch OIDC token def fetch_oidc_token client_id = ENV.fetch("SCOUT_CLIENT_ID") client_secret = ENV.fetch("SCOUT_CLIENT_SECRET") token_url = ENV.fetch("SCOUT_TOKEN_URL") uri = URI(token_url) # ... (authentication logic) request = Net::HTTP::Post.new(uri) request.set_form_data( "grant_type" => "client_credentials", "client_id" => client_id, "client_secret" => client_secret ) response = Net::HTTP.start(uri.hostname, uri.port, use_ssl: uri.scheme == "https") do |http| http.request(request) end if response.is_a?(Net::HTTPSuccess) JSON.parse(response.body)["access_token"] else Rails.logger.error "Failed to fetch OIDC token: #{response.body}" nil end end # Configure OpenTelemetry OpenTelemetry::SDK.configure do |c| endpoint = ENV.fetch("SCOUT_ENDPOINT") resource = OpenTelemetry::SDK::Resources::Resource.create( { 'service.name' => ENV.fetch("OTEL_SERVICE_NAME", "default-service"), 'deployment.environment' => ENV.fetch("RAILS_ENV", "development"), 'environment' => ENV.fetch("RAILS_ENV", "development") } ) c.resource = resource # Fetch authentication token token = fetch_oidc_token headers = {} headers["Authorization"] = "Bearer #{token}" if token # Configure OTLP exporter to send telemetry to Scout OTel ingestor otlp_exporter = OpenTelemetry::Exporter::OTLP::Exporter.new( endpoint: endpoint, headers: headers ) # Add span processor c.add_span_processor( OpenTelemetry::SDK::Trace::Export::BatchSpanProcessor.new(otlp_exporter) ) # Enable all available instrumentation c.use_all() end ``` #### 3. Application Dependencies Ensure your application has the required OpenTelemetry packages installed and configured for direct export. #### Essential Configuration Requirements 1. Service Name and Environment (Critical) Always ensure these attributes are properly set. ```ruby # In your OpenTelemetry configuration # Add environment as resource attribute c.resource = OpenTelemetry::SDK::Resources::Resource.create({ "service.name" => ENV.fetch("OTEL_SERVICE_NAME", "rails-service-name"), "service.version" => "1.0.0", "deployment.environment" => ENV.fetch("RAILS_ENV", "development"), "environment" => ENV.fetch("RAILS_ENV", "development") }) ``` #### Authentication Options When deploying without collector, you have several authentication options: #### OIDC Token Authentication (Recommended) ```ruby # Token refresh logic (implement based on your needs) def fetch_oidc_token # Implement token caching and refresh logic # Handle token expiration # Include proper error handling end ``` #### Production Considerations 1. **Token Management**: Implement proper token refresh and error handling 2. **Retry Logic**: Add exponential backoff for failed exports 3. **Monitoring**: Monitor export success/failure rates 4. **Performance**: Consider batch size and export intervals 5. **Security**: Secure credential management ### Troubleshooting #### Common Issues 1. **Authentication failures**: Check OIDC credentials and token URL 2. **Network connectivity**: Verify endpoint accessibility 3. **Performance impact**: Monitor application overhead ### References - [Rails instrumentation code](https://github.com/base-14/examples/tree/main/ruby) ### Related Guides - [Scout Exporter Configuration](./scout-exporter.md) - Use collector for centralized authentication - [Rails Auto-Instrumentation](../apps/auto-instrumentation/rails.md) - Rails framework instrumentation guide - [Docker Compose Setup](./docker-compose-example.md) - Set up collector for local development --- ## Windows OpenTelemetry Collector Installation ## Windows Install and configure the OpenTelemetry Collector on Windows systems to collect Windows Event Logs, Performance Counters, and host metrics. ### Overview This guide covers: - Installing the OpenTelemetry Collector Contrib distribution on Windows - Configuring Windows Event Log collection (System, Application, Security) - Setting up Windows Performance Counters monitoring - Collecting host metrics (CPU, memory, disk, network) - Running the collector as a Windows Service - Troubleshooting and logging :::warning The standard OpenTelemetry Collector distribution does not include Windows-specific receivers. You must use the **OpenTelemetry Collector Contrib** distribution (`otelcol-contrib`) to collect Windows Event Logs and Performance Counters. ::: ### System Requirements - Windows 10, Windows Server 2016, or later - Administrator privileges - Minimum 512MB RAM - 1GB free disk space - PowerShell 5.1 or later ### Installation Download the OpenTelemetry Collector Contrib distribution from the [official releases page](https://github.com/open-telemetry/opentelemetry-collector-releases/releases). ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` Download the Windows AMD64 binary: ```powershell # Create installation directory New-Item -ItemType Directory -Force -Path "C:\Program Files\otelcol-contrib" # Download the collector (update version as needed) $version = "0.127.0" Invoke-WebRequest -Uri "https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v$version/otelcol-contrib_${version}_windows_amd64.tar.gz" -OutFile "$env:TEMP\otelcol-contrib.tar.gz" # Extract the archive tar -xzf "$env:TEMP\otelcol-contrib.tar.gz" -C "C:\Program Files\otelcol-contrib" ``` ```mdx-code-block ``` Download the Windows 386 binary: ```powershell # Create installation directory New-Item -ItemType Directory -Force -Path "C:\Program Files\otelcol-contrib" # Download the collector (update version as needed) $version = "0.127.0" Invoke-WebRequest -Uri "https://github.com/open-telemetry/opentelemetry-collector-releases/releases/download/v$version/otelcol-contrib_${version}_windows_386.tar.gz" -OutFile "$env:TEMP\otelcol-contrib.tar.gz" # Extract the archive tar -xzf "$env:TEMP\otelcol-contrib.tar.gz" -C "C:\Program Files\otelcol-contrib" ``` ```mdx-code-block ``` ### Configuration Create the configuration file at `C:\Program Files\otelcol-contrib\config.yaml`. #### Receivers The configuration uses Windows-specific receivers to collect telemetry data: ##### Windows Event Log Receiver Collects logs from Windows Event Log channels: ```yaml showLineNumbers title="Windows Event Log receivers" receivers: windowseventlog/system: poll_interval: 5s channel: System windowseventlog/application: poll_interval: 5s channel: Application windowseventlog/security: poll_interval: 5s channel: Security ``` ##### Windows Performance Counters Receiver Collects Windows Performance Counter metrics: ```yaml showLineNumbers title="Windows Performance Counters receiver" receivers: windowsperfcounters: collection_interval: 5s metrics: cpu.utilization.percent: unit: "%" gauge: memory.available.bytes: unit: By gauge: disk.read.bytes_per_sec: unit: By/s gauge: disk.write.bytes_per_sec: unit: By/s gauge: network.bytes.received_per_sec: unit: By/s gauge: network.bytes.sent_per_sec: unit: By/s gauge: perfcounters: - object: Processor instances: ["_Total"] counters: - name: "% Processor Time" metric: cpu.utilization.percent - object: Memory counters: - name: "Available Bytes" metric: memory.available.bytes - object: LogicalDisk instances: ["_Total"] counters: - name: "Disk Read Bytes/sec" metric: disk.read.bytes_per_sec - name: "Disk Write Bytes/sec" metric: disk.write.bytes_per_sec - object: Network Interface instances: ["*"] counters: - name: "Bytes Received/sec" metric: network.bytes.received_per_sec - name: "Bytes Sent/sec" metric: network.bytes.sent_per_sec ``` ##### Host Metrics Receiver Collects system-level metrics: ```yaml showLineNumbers title="Host Metrics receiver" receivers: hostmetrics: collection_interval: 10s scrapers: cpu: metrics: system.cpu.time: { enabled: true } system.cpu.utilization: { enabled: true } system.cpu.physical.count: { enabled: true } system.cpu.logical.count: { enabled: true } memory: metrics: system.memory.usage: { enabled: true } system.memory.utilization: { enabled: true } filesystem: metrics: system.filesystem.usage: { enabled: true } system.filesystem.utilization: { enabled: true } disk: metrics: system.disk.io: { enabled: true } system.disk.operations: { enabled: true } network: metrics: system.network.io: { enabled: true } system.network.errors: { enabled: true } processes: metrics: system.processes.count: { enabled: true } system.processes.created: { enabled: true } system: metrics: system.uptime: { enabled: true } ``` ##### OTLP Receiver Receives telemetry from instrumented applications: ```yaml showLineNumbers title="OTLP receiver" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 ``` #### Complete Configuration Below is the complete configuration file combining all components: ```yaml showLineNumbers title="C:\Program Files\otelcol-contrib\config.yaml" receivers: windowseventlog/system: poll_interval: 5s channel: System windowseventlog/application: poll_interval: 5s channel: Application windowseventlog/security: poll_interval: 5s channel: Security windowsperfcounters: collection_interval: 5s metrics: cpu.utilization.percent: unit: "%" gauge: memory.available.bytes: unit: By gauge: disk.read.bytes_per_sec: unit: By/s gauge: disk.write.bytes_per_sec: unit: By/s gauge: network.bytes.received_per_sec: unit: By/s gauge: network.bytes.sent_per_sec: unit: By/s gauge: perfcounters: - object: Processor instances: ["_Total"] counters: - name: "% Processor Time" metric: cpu.utilization.percent - object: Memory counters: - name: "Available Bytes" metric: memory.available.bytes - object: LogicalDisk instances: ["_Total"] counters: - name: "Disk Read Bytes/sec" metric: disk.read.bytes_per_sec - name: "Disk Write Bytes/sec" metric: disk.write.bytes_per_sec - object: Network Interface instances: ["*"] counters: - name: "Bytes Received/sec" metric: network.bytes.received_per_sec - name: "Bytes Sent/sec" metric: network.bytes.sent_per_sec hostmetrics: collection_interval: 10s scrapers: cpu: metrics: system.cpu.time: { enabled: true } system.cpu.utilization: { enabled: true } system.cpu.physical.count: { enabled: true } system.cpu.logical.count: { enabled: true } memory: metrics: system.memory.usage: { enabled: true } system.memory.utilization: { enabled: true } filesystem: metrics: system.filesystem.usage: { enabled: true } system.filesystem.utilization: { enabled: true } disk: metrics: system.disk.io: { enabled: true } system.disk.operations: { enabled: true } network: metrics: system.network.io: { enabled: true } system.network.errors: { enabled: true } processes: metrics: system.processes.count: { enabled: true } system.processes.created: { enabled: true } system: metrics: system.uptime: { enabled: true } otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: resourcedetection/system: detectors: ["system"] system: hostname_sources: ["lookup"] resource_attributes: host.id: enabled: true batch: send_batch_size: 5 send_batch_max_size: 10 timeout: 1s resource: attributes: - key: environment value: windows action: upsert resource/hostmetrics: attributes: - key: service.name value: hostmetrics action: upsert resource/windowsperfcounters: attributes: - key: service.name value: windowsperfcounters action: upsert exporters: debug: verbosity: detailed otlphttp/b14: endpoint: auth: authenticator: oauth2client tls: insecure_skip_verify: true compression: gzip extensions: oauth2client: client_id: client_secret: endpoint_params: audience: b14collector token_url: tls: insecure_skip_verify: true service: extensions: [oauth2client] telemetry: metrics: readers: - periodic: exporter: otlp: protocol: http/protobuf endpoint: http://127.0.0.1:4318 logs: level: error encoding: json processors: - batch: exporter: otlp: protocol: http/protobuf endpoint: http://127.0.0.1:4318 traces: processors: - batch: exporter: otlp: protocol: http/protobuf endpoint: http://127.0.0.1:4318 pipelines: metrics/hostmetrics: receivers: [hostmetrics, windowsperfcounters] processors: [resource, resource/hostmetrics, resourcedetection/system] exporters: [otlphttp/b14] metrics/windowsperfcounters: receivers: [windowsperfcounters] processors: [resource, resource/windowsperfcounters, resourcedetection/system] exporters: [otlphttp/b14] metrics: receivers: [otlp] processors: [resource, resourcedetection/system] exporters: [otlphttp/b14] logs: receivers: [ otlp, windowseventlog/system, windowseventlog/application, windowseventlog/security, ] processors: [resource, resourcedetection/system] exporters: [otlphttp/b14] traces: receivers: [otlp] processors: [resource, resourcedetection/system] exporters: [otlphttp/b14] ``` Replace the placeholder values: - `` - Your Scout OTLP endpoint (e.g., `https://otel.play.b14.dev/__YOUR_TENANT__/otlp`) - `` - Your OAuth2 client ID - `` - Your OAuth2 client secret - `` - Your OAuth2 token URL (e.g., `https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token`) #### Save the Configuration After updating the placeholder values, save the configuration to a file: ```powershell # Open notepad to create the config file notepad "C:\Program Files\otelcol-contrib\config.yaml" ``` Paste your configuration, save the file, then validate it: ```powershell & "C:\Program Files\otelcol-contrib\otelcol-contrib.exe" validate --config="C:\Program Files\otelcol-contrib\config.yaml" ``` ### Running as a Windows Service #### Install the Service Use the built-in Windows Service capabilities to run the collector: ```powershell # Create the Windows Service $binPath = '"C:\Program Files\otelcol-contrib\otelcol-contrib.exe" --config="C:\Program Files\otelcol-contrib\config.yaml"' New-Service -Name "otelcol-contrib" -BinaryPathName $binPath -DisplayName "OpenTelemetry Collector Contrib" -StartupType Automatic -Description "OpenTelemetry Collector for Windows telemetry collection" ``` #### Start the Service ```powershell # Start the service Start-Service -Name "otelcol-contrib" # Verify service status Get-Service -Name "otelcol-contrib" ``` #### Service Management Commands ```powershell # Stop the service Stop-Service -Name "otelcol-contrib" # Restart the service Restart-Service -Name "otelcol-contrib" # Remove the service (if needed) sc.exe delete "otelcol-contrib" ``` ### Running Manually To run the collector manually for testing or debugging: ```powershell # Run with config file & "C:\Program Files\otelcol-contrib\otelcol-contrib.exe" --config="C:\Program Files\otelcol-contrib\config.yaml" # Validate configuration & "C:\Program Files\otelcol-contrib\otelcol-contrib.exe" validate --config="C:\Program Files\otelcol-contrib\config.yaml" ``` ### Windows Firewall Configuration If you're receiving telemetry from other applications, open the required ports: ```powershell # Open OTLP gRPC port New-NetFirewallRule -DisplayName "OpenTelemetry Collector gRPC" -Direction Inbound -Protocol TCP -LocalPort 4317 -Action Allow # Open OTLP HTTP port New-NetFirewallRule -DisplayName "OpenTelemetry Collector HTTP" -Direction Inbound -Protocol TCP -LocalPort 4318 -Action Allow ``` ### Troubleshooting #### View Service Logs The collector logs to the Windows Event Log. View logs using: ```powershell # View recent collector events Get-EventLog -LogName Application -Source "otelcol-contrib" -Newest 50 ``` Alternatively, run the collector manually to see output directly in the terminal. #### Enable Debug Logging Add the debug exporter to your pipelines to see telemetry data: ```yaml exporters: debug: verbosity: detailed service: pipelines: logs: exporters: [debug, otlphttp/b14] ``` #### Common Issues ##### Permission denied for Security Event Log The collector needs Administrator privileges to read the Security event log channel. Ensure the service runs with appropriate permissions. ##### Performance counters not found If a performance counter specified in the config doesn't exist on your system, the collector will fail to start with an "Incorrect function" error. Counter names vary by Windows version and locale. Verify the counter names match your system. Use `typeperf -q` to list available counters: ```powershell # List all Processor counters typeperf -q "Processor" # List all Memory counters typeperf -q "Memory" # List all LogicalDisk counters typeperf -q "LogicalDisk" # List all Network Interface counters typeperf -q "Network Interface" ``` To isolate the issue, temporarily remove the `windowsperfcounters` receiver from your config and test with only `hostmetrics` and `windowseventlog` receivers. ##### Service fails to start Run the collector manually to see detailed error messages: ```powershell Stop-Service -Name "otelcol-contrib" & "C:\Program Files\otelcol-contrib\otelcol-contrib.exe" --config="C:\Program Files\otelcol-contrib\config.yaml" ``` Validate the configuration file: ```powershell & "C:\Program Files\otelcol-contrib\otelcol-contrib.exe" validate --config="C:\Program Files\otelcol-contrib\config.yaml" ``` ### Related Guides - [Scout Exporter Configuration](./scout-exporter.md) - Set up authentication and endpoints - [OTel Collector Configuration](./otel-collector-config.md) - Full collector configuration reference - [Linux Installation](./linux-setup.md) - Linux deployment guide --- ## ActiveMQ OpenTelemetry Monitoring - Queue Depth, Message Rates, and Collector Setup ## ActiveMQ The OpenTelemetry JMX Scraper collects 18 ActiveMQ metrics and 19 JVM metrics from Apache ActiveMQ Classic 5.x/6.x - queue size, enqueue/dequeue counts, message expiry, producer and consumer counts, broker memory/store/temp utilization, and heap and thread health. ActiveMQ Classic (not Artemis) keeps these counters in MBeans under `org.apache.activemq` with no Prometheus or OTLP endpoint of its own, so the scraper connects over JMX/RMI, converts the MBeans to OpenTelemetry metrics, and pushes them over OTLP to the Collector. This guide enables remote JMX on ActiveMQ, configures the scraper, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------- | ------------ | ------------ | | ActiveMQ Classic | 5.15 | 6.2.0 | | JMX Scraper | 1.53.0-alpha | 1.57.0-alpha | | Java (scraper) | 11 | 17+ | | OTel Collector | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - ActiveMQ must be reachable from the host running the JMX Scraper (JMX port, default 1099). - The JMX Scraper runs as a standalone Java process and needs its own JRE. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). The 18-metric `activemq` rule set documented here is bundled in JMX Scraper `1.53.0-alpha` and later; earlier releases collect the `activemq` target through an older rule set with different metric names. The metric names come from the scraper's `activemq` rules, not from ActiveMQ itself, so an ActiveMQ version change cannot rename or drop a metric - it can only leave a source MBean absent. ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and doing its job | Metric | What it tells you | |---|---| | `activemq.message.enqueued` | Messages accepted by the broker - the throughput KPI. Flat under load means producers are blocked. | | `jvm.memory.used` | JVM heap in use. JMX exposes no `up` metric, so heap-in-use doubles as the process-alive and heap-health anchor. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `activemq.message.queue.size` | Messages currently on the destination - backlog depth. | | `activemq.message.dequeued` | Messages consumed; compare against `enqueued` for the drain rate. | | `activemq.message.expired` | Messages that died before delivery (TTL elapsed or no live consumer). | | `activemq.consumer.count` | Consumers attached to a destination; zero on a filling queue means a stuck destination. | | `activemq.memory.utilization` | Broker memory as a fraction of its limit; near 1.0 triggers producer flow control. | | `activemq.store.utilization` | Persistent message store as a fraction of its limit (disk). | | `activemq.temp.utilization` | Temp store as a fraction of its limit (non-persistent overflow). | | `jvm.memory.limit` | JVM memory ceiling - the saturation denominator for `jvm.memory.used`. | | `jvm.cpu.recent_utilization` | Recent process CPU utilization. | | `jvm.thread.count` | Live JVM threads - a steady climb signals a thread leak. | Per-request enqueue timing is in the Diagnostic tier (`activemq.message.enqueue.average_duration`), not here - it is a JMX gauge, not a percentile distribution. #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. In production you can drop this tier to control metric volume and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | Connections / producers | `activemq.connection.count`, `activemq.producer.count` | Correlate client load with backlog or flow control. | | Enqueue latency | `activemq.message.enqueue.average_duration` | Slow accepts under load; broker-side write contention. | | Saturation ceilings | `activemq.memory.limit`, `activemq.store.limit`, `activemq.temp.limit` | The raw limits behind the utilization fractions; capacity planning. | | Per-destination | `activemq.destination.memory.usage`, `activemq.destination.memory.limit`, `activemq.destination.temp.utilization`, `activemq.destination.temp.limit` | One destination saturating while the broker looks healthy overall. | | JVM memory detail | `jvm.memory.committed`, `jvm.memory.init`, `jvm.memory.used_after_last_gc` | GC behaviour and post-collection live-set size. | | JVM class loading | `jvm.class.count`, `jvm.class.loaded`, `jvm.class.unloaded` | Classloader leaks; runaway dynamic loading. | | JVM CPU / system | `jvm.cpu.count`, `jvm.cpu.time`, `jvm.system.cpu.load_1m`, `jvm.system.cpu.utilization` | Host-level CPU pressure vs process CPU. | | JVM buffers / descriptors | `jvm.buffer.count`, `jvm.buffer.memory.limit`, `jvm.buffer.memory.used`, `jvm.file_descriptor.count`, `jvm.file_descriptor.limit` | Direct-buffer growth and fd exhaustion. | Full metric reference: [OTel ActiveMQ JMX Metrics](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/instrumentation/jmx-metrics/library/activemq.md). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. Tune to your workload; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `activemq.message.queue.size` | Climbing vs baseline | `rate(message.enqueued)` > `rate(message.dequeued)` sustained | Consumers can't keep up; scale consumers or investigate slow processing. | | `activemq.consumer.count` | == 0 while `queue.size` > 0 | Sustained | No consumers draining a non-empty queue; restart or attach consumers. | | `activemq.memory.utilization` | Approaching 1.0 | At 1.0 | Producers get throttled by flow control; raise broker `memoryUsage` or drain faster. | | `activemq.store.utilization` | Approaching 1.0 | At 1.0 | Persistent producers block; raise `storeUsage` or add disk. | | `activemq.temp.utilization` | Approaching 1.0 | At 1.0 | Non-persistent overflow exhausted; raise `tempUsage` or reduce load. | | `rate(activemq.message.expired)` | > 0 | Rising across scrapes | Messages dying before delivery (TTL or no live consumer); check consumers and TTLs. | | `jvm.memory.used` / `jvm.memory.limit` | Approaching the limit | Approaching 1.0 | GC churn and OOM risk; raise heap or reduce allocation. | | `jvm.cpu.recent_utilization` | Sustained high | Pegged | Process is CPU-bound; scale out or profile hot paths. | ### Access Setup ActiveMQ Classic exposes its MBeans over JMX once the `-Dcom.sun.management.jmxremote` flags are set; remote access additionally requires a fixed port. Add the JMX flags to `bin/setenv`: ```bash showLineNumbers title="bin/setenv" ACTIVEMQ_SUNJMX_START="$ACTIVEMQ_SUNJMX_START \ -Dcom.sun.management.jmxremote.port=1099 \ -Dcom.sun.management.jmxremote.rmi.port=1099 \ -Dcom.sun.management.jmxremote.ssl=false \ -Dcom.sun.management.jmxremote.authenticate=false \ -Djava.rmi.server.hostname=" # Your ActiveMQ host IP or hostname ``` Setting `rmi.port` to the same value as `port` stops RMI from opening a random second port, which keeps firewall and Docker networking simple. For Docker deployments, pass `ACTIVEMQ_SUNJMX_START` as an environment variable and set `hostname` on the container so RMI advertises a resolvable address: ```yaml showLineNumbers title="docker-compose.yaml (ActiveMQ service)" activemq: image: apache/activemq-classic:6.2.0 hostname: activemq environment: ACTIVEMQ_SUNJMX_START: >- -Dcom.sun.management.jmxremote -Dcom.sun.management.jmxremote.port=1099 -Dcom.sun.management.jmxremote.rmi.port=1099 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname=activemq ``` #### With Authentication In production, enable JMX authentication. ActiveMQ ships template access and password files in `conf/`: ```bash showLineNumbers title="bin/setenv (authenticated)" ACTIVEMQ_SUNJMX_START="$ACTIVEMQ_SUNJMX_START \ -Dcom.sun.management.jmxremote.port=1099 \ -Dcom.sun.management.jmxremote.rmi.port=1099 \ -Dcom.sun.management.jmxremote.ssl=true \ -Dcom.sun.management.jmxremote.authenticate=true \ -Dcom.sun.management.jmxremote.password.file=${ACTIVEMQ_CONF}/jmx.password \ -Dcom.sun.management.jmxremote.access.file=${ACTIVEMQ_CONF}/jmx.access \ -Djava.rmi.server.hostname=" ``` The JMX Scraper authenticates with the `OTEL_JMX_USERNAME` and `OTEL_JMX_PASSWORD` environment variables. A read-only JMX role in `jmx.access` is enough - the scraper never writes to MBeans. ### Configuration ActiveMQ monitoring uses two components: the JMX Scraper (connects to ActiveMQ over JMX, exports OTLP) and the OTel Collector (receives OTLP, ships to Scout). ```text ActiveMQ (JMX:1099) ← JMX/RMI → JMX Scraper → OTLP → OTel Collector → Scout ``` #### JMX Scraper Download the scraper JAR from [Maven Central](https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/) and run it with the `jvm,activemq` target systems: ```bash showLineNumbers title="Run the JMX Scraper" OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://localhost:1099/jmxrmi \ OTEL_JMX_TARGET_SYSTEM=jvm,activemq \ OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 \ OTEL_METRIC_EXPORT_INTERVAL=10000 \ java -jar opentelemetry-jmx-scraper-1.57.0-alpha.jar ``` To run it as a managed service, install the JAR and add a systemd unit: ```bash showLineNumbers title="Install the scraper" sudo mkdir -p /opt/otel sudo mv opentelemetry-jmx-scraper-1.57.0-alpha.jar /opt/otel/ ``` ```bash showLineNumbers title="/etc/systemd/system/otel-jmx-scraper.service" sudo tee /etc/systemd/system/otel-jmx-scraper.service > /dev/null <<'EOF' [Unit] Description=OpenTelemetry JMX Scraper for ActiveMQ After=network.target activemq.service [Service] Type=simple Environment=OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://localhost:1099/jmxrmi Environment=OTEL_JMX_TARGET_SYSTEM=jvm,activemq Environment=OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 Environment=OTEL_METRIC_EXPORT_INTERVAL=10000 ExecStart=/usr/bin/java -jar /opt/otel/opentelemetry-jmx-scraper-1.57.0-alpha.jar Restart=always RestartSec=5 [Install] WantedBy=multi-user.target EOF ``` ```bash showLineNumbers title="Enable and start the scraper" sudo systemctl daemon-reload sudo systemctl enable --now otel-jmx-scraper ``` For Docker, build a small image that fetches the scraper JAR: ```dockerfile showLineNumbers title="jmx-scraper/Dockerfile" FROM eclipse-temurin:17-jre ARG SCRAPER_VERSION=1.57.0-alpha # Update to match your target version ADD https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/${SCRAPER_VERSION}/opentelemetry-jmx-scraper-${SCRAPER_VERSION}.jar /opt/scraper.jar ENTRYPOINT ["java", "-jar", "/opt/scraper.jar"] ``` #### OTel Collector The Collector receives metrics from the scraper over OTLP/gRPC: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic-tier `activemq.destination.*` and JVM internals with a `filter` processor while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" # JMX Scraper OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://activemq:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM=jvm,activemq OTEL_METRIC_EXPORT_INTERVAL=10000 # OTEL_JMX_USERNAME=monitor # Uncomment for authenticated JMX # OTEL_JMX_PASSWORD=your_password # Uncomment for authenticated JMX # OTel Collector ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Docker Compose A full working example with all three components: ```yaml showLineNumbers title="docker-compose.yaml" services: activemq: image: apache/activemq-classic:6.2.0 hostname: activemq ports: - "8161:8161" - "61616:61616" - "1099:1099" environment: ACTIVEMQ_SUNJMX_START: >- -Dcom.sun.management.jmxremote -Dcom.sun.management.jmxremote.port=1099 -Dcom.sun.management.jmxremote.rmi.port=1099 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname=activemq healthcheck: test: ["CMD-SHELL", "curl -so /dev/null http://localhost:8161/ || exit 1"] interval: 10s timeout: 5s retries: 10 start_period: 30s jmx-scraper: build: ./jmx-scraper environment: OTEL_JMX_SERVICE_URL: ${OTEL_JMX_SERVICE_URL} OTEL_JMX_TARGET_SYSTEM: ${OTEL_JMX_TARGET_SYSTEM} OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: ${OTEL_METRIC_EXPORT_INTERVAL} depends_on: activemq: condition: service_healthy otel-collector: image: otel/opentelemetry-collector-contrib:latest container_name: otel-collector volumes: - ./config/otel-collector.yaml:/etc/otelcol-contrib/config.yaml:ro depends_on: - activemq ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check the JMX Scraper connected to ActiveMQ docker logs activemq-telemetry-jmx-scraper-1 2>&1 | head -10 # Confirm ActiveMQ started with remote JMX enabled docker logs activemq 2>&1 | grep "jmxremote" # Check Collector logs for ActiveMQ metrics docker logs otel-collector 2>&1 | grep "activemq" ``` The `activemq.*` metrics only carry non-zero values once a destination has seen traffic. Enqueue some messages and drain part of them so the enqueue, dequeue, and queue-size counters move: ```bash showLineNumbers title="Generate broker traffic" docker exec activemq bin/activemq producer --destination queue://demoQ --messageCount 500 docker exec activemq bin/activemq consumer --destination queue://demoQ --messageCount 300 ``` ### Troubleshooting #### JMX connection refused **Cause**: The JMX Scraper cannot reach ActiveMQ's JMX port. **Fix**: 1. Verify ActiveMQ is running: `docker ps | grep activemq`. 2. Confirm remote JMX is enabled - `ACTIVEMQ_SUNJMX_START` must include `-Dcom.sun.management.jmxremote.port=1099`. 3. Confirm the JMX port matches between the ActiveMQ config and the scraper's `OTEL_JMX_SERVICE_URL`. 4. In Docker, ensure `hostname` is set on the ActiveMQ container and matches `-Djava.rmi.server.hostname`, so the RMI handshake advertises a resolvable address. #### Only JVM metrics, no ActiveMQ metrics **Cause**: The `OTEL_JMX_TARGET_SYSTEM` is missing `activemq`, or the broker had not finished starting when the scraper connected. **Fix**: 1. Set `OTEL_JMX_TARGET_SYSTEM=jvm,activemq` (both targets, comma-separated). 2. Confirm ActiveMQ has fully started - the `org.apache.activemq` MBeans only register after the broker initializes. 3. Confirm you are running ActiveMQ Classic, not Artemis - the `activemq` target does not read Artemis MBeans. #### No per-destination metrics **Cause**: Destination-level series only exist once a queue or topic exists. **Look at**: `activemq.consumer.count`, `activemq.message.queue.size`, and the Diagnostic `activemq.destination.memory.usage` / `activemq.destination.temp.utilization` - all per-destination, all absent until a destination is created. **Fix**: 1. Send a message to a destination, or attach a consumer - the destination MBean is created on first use. 2. The web console at `http://localhost:8161` (default `admin/admin`) can create a test queue. #### Queue backlog or expiring messages **Cause**: Consumers are slower than producers, or no consumer is attached. **Look at**: `activemq.message.queue.size` (backlog depth) against `activemq.consumer.count` (zero on a filling queue means a stuck destination), and `activemq.message.expired` for messages dying before delivery. On the broker side, `activemq.memory.utilization` near 1.0 means producers are being throttled by flow control. **Fix**: 1. Scale or restart consumers if `consumer.count` is zero or below the producer rate. 2. Raise broker `memoryUsage` / `storeUsage` / `tempUsage`, or drain faster, if the matching utilization fraction approaches 1.0. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `otlp` receiver and the `otlphttp/b14` exporter. ### FAQ #### Does this work with ActiveMQ Artemis? No. Artemis uses different MBeans under `org.apache.activemq.artemis`. The JMX Scraper's `activemq` target is for ActiveMQ Classic only. Artemis needs custom scraper rules via `OTEL_JMX_CUSTOM_CONFIG`. #### Can I monitor both queues and topics? Yes. Queues and topics are both MBeans under `org.apache.activemq:type=Broker`. The scraper collects from all destinations by default - no extra configuration needed. #### Does this work with ActiveMQ running in Kubernetes? Yes. Run the JMX Scraper as a sidecar in the same pod and set `OTEL_JMX_SERVICE_URL` to `service:jmx:rmi:///jndi/rmi://localhost:1099/jmxrmi`, since both containers share the pod network. No firewall rules are needed for intra-pod traffic. #### How do I monitor multiple ActiveMQ brokers? Run one JMX Scraper per broker, each with a different `OTEL_JMX_SERVICE_URL`, all exporting to the same Collector: ```yaml showLineNumbers title="docker-compose.yaml (multiple brokers)" jmx-scraper-primary: environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://activemq-1:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,activemq OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 jmx-scraper-replica: environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://activemq-2:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,activemq OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 ``` #### Why is there no `up` metric for the broker? JMX exposes no synthetic `up` series. Use `jvm.memory.used` as the process-alive anchor - if it stops reporting, the broker JVM or the scraper connection is down. ### Related Guides - [JMX Metrics Guide](../collector-setup/jmx-metrics-collection-guide.md) - Compare the JMX Scraper and the JMX Exporter. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Kafka Monitoring](./kafka.md) - Another message broker on the JMX path. - [RabbitMQ Monitoring](./rabbitmq.md) - Another message broker setup. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on ActiveMQ metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Kafka](./kafka.md), [RabbitMQ](./rabbitmq.md), and other message brokers. - **Fine-tune Collection**: Adjust `OTEL_METRIC_EXPORT_INTERVAL` to control scrape frequency, and drop the Diagnostic tier in production to control volume while keeping it available for investigation. --- ## Aerospike OpenTelemetry Monitoring - Connections, Transactions, and Collector Setup ## Aerospike The OpenTelemetry Collector's Aerospike receiver talks the native info protocol to an Aerospike node on port 3000 and collects 9 metrics across node- and namespace-scoped resources - connection, transaction, memory, and query series. There is no exporter to run and no HTTP endpoint to expose; the receiver reads the statistics directly. This guide configures the receiver, connects to a node, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Aerospike | 4.9 | 8.x | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | — | Before starting: - The Aerospike client port (3000) must be reachable from the host running the Collector. - Community Edition needs no authentication. Enterprise Edition uses a username and password - see [Access Setup](#access-setup). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The receiver emits two resource scopes per scrape - one node-scoped, one namespace-scoped - so node and namespace metrics carry different resource attributes. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `aerospike.node.connection.open` | Open client, heartbeat, and fabric connections - node reachability plus current client load. | | `aerospike.namespace.transaction.count` | Transactions by type and result; the headline throughput KPI and the source of the error rate via its `result` dimension. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `aerospike.node.memory.free` | Free node memory percent - the saturation signal that drives stop-writes. | | `aerospike.node.connection.count` | Connection opens and closes by type (client / heartbeat / fabric) and operation - reconnect storms and leaks. | | `aerospike.namespace.query.count` | Queries by type and result - query load and query-side errors. | #### Diagnostic - for investigation and tuning The GeoJSON region-query series. They only carry meaning for geospatial workloads and read zero otherwise, so drop them in production with the receiver's per-metric toggle and re-enable when investigating geospatial query behaviour. | Metric | What it tells you | |---|---| | `aerospike.namespace.geojson.region_query_requests` | GeoJSON region-query requests. | | `aerospike.namespace.geojson.region_query_points` | Points returned by region queries. | | `aerospike.namespace.geojson.region_query_cells` | Cells scanned to satisfy region queries. | | `aerospike.namespace.geojson.region_query_false_positive` | Region-query false positives - index selectivity for geospatial queries. | Some receiver-whitelisted metrics may not emit on every server build - see [Troubleshooting](#namespace-memory-and-disk-metrics-missing). Full metric reference: [OTel Aerospike Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/aerospikereceiver). ### Key Alerts to Configure Threshold guidance for the most useful Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `aerospike.node.memory.free` | Approaching the stop-writes margin | At or below the high-water mark | Writes are rejected near the high-water mark. Add capacity or evict before it bites. | | `aerospike.node.connection.count{operation=open}` (rate) | Spiking vs baseline | Sustained spike with `node.connection.open` climbing | Client reconnect storms or a connection leak. Check client connection pooling. | | `aerospike.namespace.transaction.count{result=error}` (rate) | Rising vs total transactions | Sustained error share climbing | Client-visible transaction failures. Correlate with node health and capacity. | ### Access Setup Verify the node is reachable on the client port before wiring the Collector: ```bash showLineNumbers title="Verify access" # Check node status with asadm (if installed) asadm -e "info" # Or test connectivity with aql aql -h localhost -p 3000 -c "show namespaces" ``` Community Edition requires no authentication. Enterprise Edition uses a username and password; create a read-only monitoring user and grant it the `read` role, which is enough for the info-protocol statistics the receiver reads. No write privileges are needed. Pass those credentials to the receiver as shown in [Configuration](#configuration). ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: aerospike: endpoint: localhost:3000 # Change to your Aerospike address collection_interval: 10s collect_cluster_metrics: false metrics: # Core aerospike.node.connection.open: enabled: true aerospike.namespace.transaction.count: enabled: true # Operational aerospike.node.memory.free: enabled: true aerospike.node.connection.count: enabled: true aerospike.namespace.query.count: enabled: true # Diagnostic - geospatial workloads only; drop in production aerospike.namespace.geojson.region_query_requests: enabled: true aerospike.namespace.geojson.region_query_points: enabled: true aerospike.namespace.geojson.region_query_cells: enabled: true aerospike.namespace.geojson.region_query_false_positive: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [aerospike] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, disable the GeoJSON Diagnostic metrics with their per-metric `enabled: false` toggle while keeping the Core and Operational series. #### Authentication For Aerospike Enterprise Edition with authentication enabled: ```yaml showLineNumbers title="config/otel-collector.yaml (auth)" receivers: aerospike: endpoint: localhost:3000 username: ${env:AEROSPIKE_USERNAME} password: ${env:AEROSPIKE_PASSWORD} tls: insecure_skip_verify: true ``` #### Cluster-wide Collection To collect from every node discovered through the seed node, point the receiver at any node and enable cluster discovery: ```yaml showLineNumbers title="config/otel-collector.yaml (cluster)" receivers: aerospike: endpoint: localhost:3000 collect_cluster_metrics: true ``` #### Environment Variables ```bash showLineNumbers title=".env" # Enterprise Edition only; omit for Community Edition AEROSPIKE_USERNAME=otel_monitor AEROSPIKE_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for the Aerospike receiver docker logs otel-collector 2>&1 | grep -i "aerospike" # Confirm Aerospike is reachable on the client port aql -h localhost -p 3000 -c "show namespaces" ``` With the debug exporter enabled you should see a batch carrying the node- and namespace-scoped metrics; with the Scout exporter, confirm the series land in Scout. Transaction and query counts only move once traffic hits the namespace, so send some load if the counts read zero. ### Troubleshooting #### Connection refused on port 3000 **Cause**: The Collector cannot reach Aerospike at the configured endpoint. **Fix**: 1. Verify Aerospike is running: `docker ps | grep aerospike` or `systemctl status aerospike`. 2. Confirm the service port in `aerospike.conf` matches the receiver `endpoint`. 3. Check firewall rules if the Collector runs on a separate host. #### Transaction or query counts stay at zero **Cause**: No traffic has reached the namespace yet. **Look at**: `aerospike.namespace.transaction.count` and `aerospike.namespace.query.count` - both are traffic-driven and read zero on an idle node. **Fix**: 1. Drive load against the namespace (for example with `asbench`). 2. Confirm the receiver is pointed at the namespace actually taking traffic. #### Namespace memory and disk metrics missing **Cause**: On Aerospike 8.x the receiver does not surface the namespace- scoped capacity stats - `aerospike.namespace.memory.free`, `aerospike.namespace.memory.usage`, and `aerospike.namespace.disk.available` do not emit even under load, because the underlying namespace memory and disk info stats were renamed or removed in the 8.x info protocol and the receiver cannot read them on that build. **Look at**: `aerospike.node.memory.free` - node-level memory still emits, so read namespace-level capacity from node memory plus per-namespace tooling (`asadm`, `asinfo`) until the receiver catches up. **Fix**: 1. Leave the namespace capacity metrics enabled - they cost nothing when silent and will start emitting once receiver support lands. #### GeoJSON metrics read zero **Cause**: No geospatial queries have run. **Look at**: the Diagnostic `aerospike.namespace.geojson.*` series - they only increment for region queries against secondary indexes with GeoJSON data types. **Fix**: Expect zero unless you run geospatial workloads. Disable the series in the receiver config if you do not use them. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Aerospike running in Kubernetes? Yes. Set `endpoint` to the Aerospike service DNS (e.g., `aerospike.default.svc.cluster.local:3000`). The Collector can run as a sidecar or DaemonSet. #### How do I monitor an Aerospike cluster? Set `collect_cluster_metrics: true` and point the receiver at any seed node; it discovers the peer nodes and collects from the cluster. For explicit control, add multiple named receiver blocks instead: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-node)" receivers: aerospike/node1: endpoint: aerospike-1:3000 aerospike/node2: endpoint: aerospike-2:3000 ``` #### Does this work with both Community and Enterprise Edition? Yes. Community Edition needs no authentication. Enterprise Edition requires `username` and `password` in the receiver config. The same metrics are collected from both editions. #### Why are the namespace memory and disk metrics not showing up? On Aerospike 8.x the receiver cannot read the namespace-scoped capacity stats and they stay silent; node memory (`aerospike.node.memory.free`) still emits. See [Troubleshooting](#namespace-memory-and-disk-metrics-missing). ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Aerospike metrics. - [Redis Monitoring](./redis.md) - Another in-memory key-value store. - [MongoDB Monitoring](./mongodb.md) - A common companion document store. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Redis](./redis.md), [MongoDB](./mongodb.md), and other components. - **Fine-tune Collection**: Disable the GeoJSON Diagnostic tier in production to control volume; keep it available for incident investigation. --- ## Apache HTTP Server OpenTelemetry Monitoring - Request Rate, Worker Saturation, and Collector Setup ## Apache HTTP Server The OpenTelemetry Collector's `apache` receiver scrapes Apache's `mod_status` page to collect 13 metrics from Apache HTTP Server 2.4+ - request throughput, worker busy/idle saturation, scoreboard slot states, CPU load, traffic volume, and host load averages. The receiver reads `http://:80/server-status?auto` over plain HTTP, so there is no exporter sidecar and no JMX to run. This guide enables `mod_status`, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Apache HTTP Server | 2.4 | 2.4.68 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Apache HTTP Server 2.4+ running with `mod_status` loaded and reachable from the host running the Collector. - `ExtendedStatus On` and a `/server-status` handler (see Access Setup). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. All 13 metrics here come from the `apache` receiver and are enabled by default - no per-metric configuration is needed to collect them. The receiver emits no `up` metric. A live `rate(apache.requests)` is the liveness proxy: if it goes to zero while traffic is expected, the server is not serving. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `apache.requests` | Requests serviced. The rate is the throughput KPI and the liveness proxy - the receiver has no `up`. | | `apache.workers` (`state` busy/idle) | Workers busy vs idle - the primary Apache capacity and saturation signal. Worker exhaustion is the defining scaling limit. | | `apache.traffic` | Total bytes served - data-plane throughput volume. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `apache.scoreboard` (`state`) | Workers per state (open / waiting / reading / sending / keepalive / ...). `open` approaching 0 means out of worker slots. | | `apache.current_connections` | Active connections attached to the server - connection load. | | `apache.connections.async` (`state`) | Async connections by state on the event MPM (writing / keepalive / closing) - connection backpressure. | | `apache.cpu.load` | Current CPU load of the server process. | | `apache.request.time` | Total time handling requests. Read as `rate(apache.request.time) / rate(apache.requests)` for mean per-request handling time. | | `apache.load.1` | Host load average over the last 1 minute - responsive saturation signal. | #### Diagnostic - for investigation and tuning Higher cardinality or slower-moving context; reach for these during an incident rather than paging on them. You can drop this tier in production to control metric volume and keep Core + Operational. | Metric | When you reach for it | |---|---| | `apache.cpu.time` (`level` self/children × `mode` system/user) | Fine-grained CPU attribution by mode and level when CPU load is high. | | `apache.load.5` | Host load average over 5 minutes - trend context. | | `apache.load.15` | Host load average over 15 minutes - trend context. | | `apache.uptime` | Server uptime in seconds. A reset flags a restart; read alongside an incident. | Full metric reference: [OTel Apache Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/apachereceiver). Apache reports host load averages (`apache.load.1` / `.5` / `.15`) only where the OS exposes them - they populate on Linux and may read zero on macOS or Windows. Use OS-level monitoring for load averages there. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Alert | Threshold | Why it matters | |---|---|---| | Worker pool exhausted | `apache.scoreboard{state="open"}` approaching 0, or busy / total workers approaching 1.0 | All worker slots in use; new requests queue or are refused. Raise `MaxRequestWorkers` or scale out. | | Serving stalled | `rate(apache.requests)` → 0 while traffic is expected | Server not handling requests; check the process, `mod_status`, and upstream. | | Request handling slowing | `rate(apache.request.time) / rate(apache.requests)` rising vs baseline | Mean per-request handling time climbing; check backends, CPU, and worker contention. | | CPU saturation | `apache.cpu.load` (or `apache.load.1`) sustained high vs baseline | Server is CPU-bound; profile handlers, enable caching, or add capacity. | | Connection backpressure | `apache.connections.async{state="closing"}` / `{state="writing"}` climbing vs baseline | Event-MPM connections backing up; check slow clients, keepalive tuning, and downstream latency. | ### Access Setup The `apache` receiver scrapes Apache's own `mod_status` page, so the "monitoring account" here is the status endpoint itself: it must be enabled, report extended counters, and be reachable by the Collector. Enable `mod_status` with `ExtendedStatus On` and expose the `/server-status` handler: ```apacheconf showLineNumbers title="httpd-status.conf" # mod_status is loaded by default in most builds (including the official # Docker image). If not, load it first: # LoadModule status_module modules/mod_status.so # Report the full counter set, not just basic status ExtendedStatus On SetHandler server-status # Restrict to the Collector's network - do not expose publicly Require ip 10.0.0.0/8 172.16.0.0/12 192.168.0.0/16 ``` `ExtendedStatus On` is required: without it the page omits the per-request and CPU counters, and several metrics read zero. Restrict the `` to the Collector's source network with `Require ip` (use the container network CIDR for Docker) rather than serving `/server-status` publicly - it exposes per-worker request detail. Confirm the endpoint returns machine-readable output: ```bash showLineNumbers title="Verify access" # mod_status loaded? apachectl -M 2>&1 | grep status # Auto (machine-readable) format - expect Total Accesses, CPULoad, ReqPerSec curl -s http://localhost:80/server-status?auto ``` ### Configuration The `apache` receiver collects all 13 metrics by default, so the receiver block needs only the endpoint and collection interval - there are no per-metric `metrics:` overrides to set. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: apache: endpoint: http://localhost:80/server-status?auto # Change to your Apache URL collection_interval: 10s processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [apache] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic-tier metrics (`apache.cpu.time`, `apache.load.5`, `apache.load.15`, `apache.uptime`) with a `filter` processor while keeping Core and Operational. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Collector picked up the receiver docker logs otel-collector 2>&1 | grep -i "apache" # server-status responds in machine-readable form curl -s http://localhost:80/server-status?auto # Generate traffic so request, worker, and scoreboard signals advance curl -s http://localhost:80/ > /dev/null ``` ### Troubleshooting #### 403 Forbidden on server-status **Cause**: The `Require` directive restricts access and the Collector's IP is not allowed. **Fix**: 1. Add the Collector's IP to the `Require ip` list in the `` block. 2. For Docker setups, use the container network CIDR (e.g., `Require ip 172.16.0.0/12`). 3. Reload Apache after changing the config: `apachectl graceful`. #### No metrics or partial metrics **Cause**: `ExtendedStatus` is off, so the page omits the per-request and CPU counters and several metrics read zero. **Fix**: 1. Add `ExtendedStatus On` before the `` block. 2. Confirm `curl -s http://localhost:80/server-status?auto` includes `Total Accesses`, `CPULoad`, and `ReqPerSec`. 3. Reload Apache: `apachectl graceful`. #### Requests are slow or piling up **Cause**: The worker pool is saturated, or the CPU is the bottleneck. **Look at**: `apache.scoreboard{state="open"}` (free slots) and the busy / total ratio from `apache.workers` for worker exhaustion; `apache.cpu.time` (by `mode` / `level`) to see whether system or user CPU dominates; and `apache.connections.async{state="closing"}` / `{state="writing"}` for event-MPM backpressure. **Fix**: 1. Raise `MaxRequestWorkers` or scale out if `open` slots approach 0. 2. Profile handlers or enable caching if `apache.cpu.time` shows the server is CPU-bound. 3. Investigate slow clients, keepalive tuning, and downstream latency if async connections back up. #### Load average metrics read zero **Cause**: `apache.load.1` / `.5` / `.15` depend on system load averages that Apache surfaces only where the OS exposes them. **Look at**: `apache.load.1` for the responsive signal, `apache.load.5` / `apache.load.15` for trend - all three read zero where the OS does not report load. **Fix**: 1. These populate on Linux. On macOS or Windows they may read zero - this is expected. 2. Use OS-level monitoring for load averages on non-Linux platforms. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why is there no `up` metric for Apache? The `apache` receiver does not emit one. Use `rate(apache.requests)` as the liveness proxy - a live request rate means the server is handling traffic; a drop to zero while traffic is expected means it is not. #### Do I need to enable any metrics explicitly? No. All 13 `apache` receiver metrics are on by default, so the receiver block needs only the `endpoint` and `collection_interval`. To reduce metric volume, drop tiers you do not need with a `filter` processor (see Configuration). #### Does this work with Apache running in Kubernetes? Yes. Set `endpoint` to the Apache service DNS (e.g., `http://apache.default.svc.cluster.local:80/server-status?auto`) and make sure the `` `Require` allows the Collector pod's network. The Collector can run as a sidecar or DaemonSet. #### How do I monitor multiple Apache instances? Add multiple receiver blocks with distinct names, then include both in the pipeline: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: apache/web1: endpoint: http://web-1:80/server-status?auto apache/web2: endpoint: http://web-2:80/server-status?auto service: pipelines: metrics: receivers: [apache/web1, apache/web2] ``` #### What is the scoreboard metric? `apache.scoreboard` reports how many worker slots are in each state - open, starting, waiting, reading, sending, keepalive, DNS lookup, closing, logging, graceful finish, and idle cleanup. `open` slots approaching zero means Apache is running out of capacity to take new work. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Apache HTTP metrics. - [NGINX Monitoring](./nginx.md) - Another worker-pool web server to watch the same way. - [Caddy Monitoring](./caddy.md) - A web server you may run alongside or in front of Apache. - [HAProxy Monitoring](./haproxy.md) - The load balancer in front of an Apache pool. - [Traefik Monitoring](./traefik.md) - The reverse proxy routing to Apache backends. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [NGINX](./nginx.md), [HAProxy](./haproxy.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## ArgoCD Monitoring This guide has moved to the **CI/CD Observability** section. See the full guide: [ArgoCD Monitoring with OpenTelemetry](/guides/cicd-observability/collecting-argocd-telemetry/) --- ## Bifrost OpenTelemetry Monitoring - LLM Gateway Requests, Tokens, and Collector Setup ## Bifrost Bifrost serves Prometheus text at `/metrics` on its main port with no switch to turn on, and the OpenTelemetry Collector's `prometheus` receiver scrapes it for 12 gateway metric families covering request outcomes, upstream provider latency, token usage, retries and streaming performance, plus 3 HTTP families and the Go runtime. A second surface, an OTLP push carrying GenAI-semantic-convention spans, ships with the binary but has to be created through the management API before it does anything. This guide covers both, the Collector configuration and shipping to base14 Scout. The one thing to know before anything else: a Bifrost gateway that has not yet served an LLM request exposes no `bifrost_` families at all. Every one of them registers on first use. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | --------- | ----------- | | Bifrost | 1.5 | 2.1 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Bifrost's metric surface is additive across releases: nothing has been removed or renamed from 1.4 through 2.1. A 1.4 gateway emits eight of the twelve families below; `bifrost_active_requests`, `bifrost_provider_key_up` and `bifrost_request_retries` arrive in 1.5, and `bifrost_cache_read_input_tokens_total` needs 1.5 plus a provider that reports cached prompt tokens. `bifrost_overhead_latency_microseconds` needs 2.0. Before starting: - The Collector must reach Bifrost's port over plain HTTP. - At least one provider and one key must be configured, and at least one LLM request must have run. Before that the exposition is a bare Go process. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or a capacity review. Gate the scrape on both prefixes, `bifrost_` and `http_`. The HTTP families are not runtime noise here: `http_requests_total` is the only complete count of what reached the gateway, and two whole classes of failure appear nowhere else - see [What the gateway counters miss](#what-the-gateway-counters-miss). #### Core - are requests arriving, reaching a provider and succeeding | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the gateway is reachable. | | `http_requests_total` | Every request the gateway handled, by `method`, `path` and `status`. `path` is the route template, so `/api/providers/{provider}/keys` rather than an expanded path. | | `bifrost_success_requests_total` | Requests forwarded to a provider that returned a result, by `method`, `model`, `provider`, `selected_key_id` and `fallback_index`. | | `bifrost_error_requests_total` | Requests that reached provider dispatch and failed. Same labels plus `status_code`. | | `bifrost_upstream_requests_total` | Attempts against a provider, successes and failures together. The denominator for an error ratio. | | `bifrost_upstream_latency_seconds` | Provider latency, over 22 buckets from 5ms to 900s. The only family carrying an `is_success` label. | | `bifrost_active_requests` | In-flight requests by `method`. Three labels only; the cheapest saturation signal on the surface. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `bifrost_input_tokens_total` | Prompt tokens as reported by the provider. The cost signal on the input side. | | `bifrost_output_tokens_total` | Completion tokens. | | `bifrost_cache_read_input_tokens_total` | Prompt tokens the provider reported as served from its cache. This is the provider's number, not Bifrost's own caching. | | `bifrost_request_retries` | Retries per request. Buckets start at `le="0"`, so the `le="0"` count is the number of requests that needed none. | | `bifrost_stream_first_token_latency_seconds` | Time to first token on streaming requests. What a streaming client actually feels. | | `bifrost_stream_inter_token_latency_seconds` | Gap between tokens on a stream. | | `bifrost_provider_key_up` | Outcome of the most recent attempt on a key. Read [What `bifrost_provider_key_up` means](#what-bifrost_provider_key_up-means) before alerting on it. | | `http_request_duration_seconds` | Server-side duration by route, including gateway overhead. | | `http_request_size_bytes` | Request body size by route. | | `go_goroutines` | Goroutine count in the gateway. Growth runs ahead of a memory problem. | | `process_resident_memory_bytes` | Gateway resident memory. | | `process_open_fds` | Open file descriptors, read against `process_max_fds`. A gateway holding many upstream connections runs out here first. | #### Diagnostic - for investigation and tuning The rest of the runtime set: 28 `go_` families (`go_gc_duration_seconds`, the `go_memstats_*` set, `go_sched_gomaxprocs_threads`, `go_threads`, `go_info`) and 7 `process_` families (`process_cpu_seconds_total`, `process_virtual_memory_bytes`, `process_virtual_memory_max_bytes`, `process_max_fds`, `process_start_time_seconds`, `process_network_receive_bytes_total`, `process_network_transmit_bytes_total`). Standard Go client library output with no Bifrost-specific runtime instrumentation. #### Metrics register on first use A gateway that has served no traffic exposes 40 families, two of them `http_requests_total` and `http_request_duration_seconds` and the rest Go runtime. The others appear as code paths run: | Point | Families | What arrives | |---|---|---| | Nothing configured, no traffic | 40 | - | | After provider and key registration | 41 | `http_request_size_bytes` | | After the first successful completion | 49 | `bifrost_active_requests`, `bifrost_input_tokens_total`, `bifrost_output_tokens_total`, `bifrost_provider_key_up`, `bifrost_request_retries`, `bifrost_success_requests_total`, `bifrost_upstream_latency_seconds`, `bifrost_upstream_requests_total` | | Once errors, streaming and cached prompts have occurred | 53 | `bifrost_cache_read_input_tokens_total`, `bifrost_error_requests_total`, `bifrost_stream_first_token_latency_seconds`, `bifrost_stream_inter_token_latency_seconds` | A dashboard built against a freshly started gateway finds nothing, and a `bifrost_error_requests_total` alert on a gateway that has never had an error has no series to evaluate. Write alerts so an absent series reads as zero. #### What the gateway counters miss Three request failures all return HTTP 400 to the caller, and only one of them touches a `bifrost_` family: | Failure | Reaches a `bifrost_` counter? | |---|---| | Provider was never registered | No | | Body has no `messages` | No | | Model the provider does not have | Yes - `bifrost_error_requests_total` and `bifrost_upstream_requests_total` | Validation failures and provider-resolution failures are rejected before dispatch, so they exist only as `http_requests_total{status="400"}`. An error-rate alert built solely on `bifrost_error_requests_total` will not fire on a misconfigured client or a typo in a provider name. Alert on both families. `status_code` on `bifrost_error_requests_total` is not always an HTTP status. A request for a model the provider does not have records `status_code="unknown"` while the caller receives a 400, and an unsupported operation records the upstream's own code such as `status_code="501"`. Treat the label as an error class, not an HTTP code. #### `model` is client-supplied and unbounded The `model` label is taken from the request body and recorded before anything validates it against the registered model list. A single request for a model that does not exist creates a permanent series on `bifrost_error_requests_total` and `bifrost_upstream_requests_total`. A client in a retry loop with a typo is a cardinality incident. If clients are untrusted, cap the label at the Collector: ```yaml showLineNumbers title="config/otel-collector.yaml (cardinality guard)" metric_relabel_configs: - source_labels: [model] regex: '(gpt-4o|claude-sonnet-4-5|llama-3\.3-70b)' action: keep ``` #### Most labels are empty, and the two surfaces disagree The LLM families carry 22 to 24 labels. Seventeen of them are governance fields - `customer_id`, `customer_name`, `team_id`, `team_name`, `project_id`, `project_name`, `business_unit_id`, `business_unit_name`, `virtual_key_id`, `virtual_key_name`, `selected_key_name`, `alias`, `routing_engine_used`, `routing_rule_id`, `routing_rule_name`, `complexity_tier` and `complexity_mechanism` - and they stay empty until governance entities are configured. `selected_key_id` is an eighteenth empty on any series where no key was selected, which is what a failed model resolution produces. The two surfaces handle those empties differently. The Prometheus receiver drops empty labels, so a scraped counter arrives with about five attributes. The OTLP push keeps them as empty strings, so the same counter arrives with eleven. A query that aggregates across both paths will not match. Run one path or the other, or separate them by resource attributes. #### What `bifrost_provider_key_up` means It reports the outcome of the most recent attempt against that key, not the health of the provider. Any failed attempt drives it to 0, including failures the provider had nothing to do with: an unsupported operation returning 501, or a request naming a model the provider does not have. A single successful request drives it back to 1. It also holds its last value indefinitely while no request is attempted, so a 0 on an idle gateway says nothing about now. Pair any alert on it with a request-rate condition. #### Reading latency and success ratio `bifrost_upstream_latency_seconds` is the only family with an `is_success` label, so the success ratio comes from the histogram rather than from the counters: ```text rate(bifrost_upstream_latency_seconds_count{is_success="false"}[5m]) / rate(bifrost_upstream_latency_seconds_count[5m]) ``` Its 22 buckets run from 5ms to 900s, which is wide enough for a slow model but coarse at the fast end. Use `rate(_sum) / rate(_count)` for a mean and split by `model` - a mean across mixed models means nothing. For an error ratio from the counters, use `bifrost_upstream_requests_total` as the denominator rather than the sum of success and error. Both are recorded per attempt and the sum is the same number, but the single family is one query instead of two and stays correct if a third outcome is added. #### What the traces show The OTLP surface emits GenAI semantic convention spans. A successful chat completion produces 26 spans: | Span | Kind | Count | Note | |---|---|---|---| | `/v1/chat/completions` | Server | 1 | Root, named for the route. Carries `http.*`, `bifrost.request.id`, `bifrost.upstream.duration_ms` and `bifrost.overhead.duration_ms`. | | `chat ` | Internal | 1 | The provider call. Carries the GenAI attributes. | | `plugin..prerequesthook`, `.prehook`, `.posthook` | Internal | 24 | Three per loaded plugin, eight plugins loaded by default. Each is a few microseconds long. | The provider span carries `gen_ai.provider.name`, `gen_ai.operation.name`, `gen_ai.request.model`, `gen_ai.request.max_tokens`, `gen_ai.response.model`, `gen_ai.response.finish_reason`, the `gen_ai.usage.*` set and `gen_ai.input.messages` / `gen_ai.output.messages`. `gen_ai.usage.cost` is in that set but reads `0` for any model Bifrost has no pricing for, which includes every self-hosted backend. Streaming adds `gen_ai.response.time_to_first_chunk`, `gen_ai.response.total_chunks` and the `bifrost.stream.*` breakdown of parse, client-write, backpressure and transport time. Two consequences worth planning for: - **Volume.** The 24 plugin hook spans per request are 92% of the span count and carry only timing attributes. Sample, or accept the multiplier. - **Content.** `gen_ai.input.messages` and `gen_ai.output.messages` carry the full prompt and completion text by default. Set `disable_content_logging` on the plugin config to remove both while keeping the token-usage attributes - see [Turn on trace export](#turn-on-trace-export). Bifrost sets `service.name`, `service.version`, `service.instance.id`, `telemetry.sdk.language=go`, `telemetry.sdk.version` and `telemetry.sdk.name=bifrost` on its own OTLP resource. That last value is the product name rather than an SDK name, so a filter expecting `telemetry.sdk.name=opentelemetry` will not match these spans. ### Key Alerts to Configure Request rate, token volume and provider latency are workload-specific, so the rows below are written as ratios or as comparisons against your own history rather than as absolute numbers. | Metric | Threshold | Why it matters | |---|---|---| | `up` | `== 0` for 2 scrapes | The gateway is gone or unreachable. | | `http_requests_total` | `status=~"5.."` rate above the 24h p95 for 10m | Gateway-side failures, including paths no `bifrost_` counter sees. | | `http_requests_total` | `status="400"` rate above the 24h p95 for 10m | Clients are sending requests that never reach a provider. | | `bifrost_error_requests_total` | rate against `bifrost_upstream_requests_total` above the 7-day ratio by `> 2x` over 15m | Provider-side failure rate. | | `bifrost_upstream_latency_seconds` | `rate(_sum) / rate(_count)` for `is_success="true"` above the 7-day mean by `> 2x` over 15m | Provider latency regression. Split by `model`. | | `bifrost_upstream_latency_seconds` | `rate(_count{is_success="false"}) / rate(_count)` above the 7-day error ratio by `> 2x` over 10m | Success ratio by model and key. | | `bifrost_active_requests` | above the 24h p95 by `> 2x` for 5m | Requests are piling up in the gateway. | | `bifrost_stream_first_token_latency_seconds` | `rate(_sum) / rate(_count)` above the 7-day mean by `> 2x` over 15m | Time to first token is the streaming user's latency. | | `bifrost_request_retries` | `rate(_count) - rate(_bucket{le="0"})` rising over 10m | Requests are needing retries, ahead of visible errors. | | `bifrost_provider_key_up` | `== 0` for 5m **and** `rate(bifrost_upstream_requests_total[5m]) > 0` | A key is failing. The rate condition is required. | | `bifrost_input_tokens_total` | rate above the 7-day p95 by `> 2x` for 15m | Cost runaway on the prompt side. | | `bifrost_output_tokens_total` | rate below the 7-day p05 for 15m while request rate holds | Completions are being truncated or the provider is degrading. | | `go_goroutines` | above the 24h p95 by `> 2x` for 10m | Goroutine leak. | | `process_resident_memory_bytes` | above the 24h p95 by `> 1.5x` for 15m | Memory growth ahead of an OOM. | | `process_open_fds` | above `0.8 * process_max_fds` for 5m | Connection exhaustion against providers. | ### Access Setup #### Reach the metrics endpoint `/metrics` is on by default and needs no flag. It is served on the main port alongside the OpenAI-compatible API, the management API and the web UI, with no authentication of its own: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: bifrost: image: maximhq/bifrost:v2.1.0 environment: BIFROST_HOST: 0.0.0.0 ports: - "8080:8080" # API, management API, web UI and /metrics volumes: - bifrost-data:/app/data ``` Because there is no separate listener, anything that can read the metrics can also call `POST /api/providers`. Keep the port on an internal network and put your own authentication in front of it. Confirm the exposition before touching the Collector: ```bash showLineNumbers title="Verify access" curl -s http://localhost:8080/metrics | grep -c '^# TYPE' curl -s http://localhost:8080/metrics | grep '^bifrost_success_requests_total' ``` If the second command returns nothing, the gateway has not served an LLM request yet. Send one and try again. #### Add label dimensions `client_config.prometheus_labels` adds extra label dimensions to the `bifrost_` families: ```bash showLineNumbers title="Add tenant and app labels" curl -s -X PUT http://localhost:8080/api/config \ -H 'content-type: application/json' \ -d '{"client_config": {"prometheus_labels": ["tenant", "app"], "log_retention_days": 7}}' ``` The API answers with `restart_required: true`, and the labels do not appear until the gateway restarts. The `PUT` replaces the whole `client_config` object, so read the current one first and modify it rather than sending only the field you want to change. Adding a dimension is not the same as populating it. The label appears on every LLM series with an empty value, and request headers do not fill it - not as a bare header name, nor with an `x-`, `x-bf-` or `x-bf-prom-` prefix. If you need the dimension populated, set it at the Collector with an `attributes` processor rather than expecting Bifrost to supply it. #### Turn on trace export The `otel` plugin is compiled into the binary but is not loaded until you create it. Setting `OTEL_TRACING`, `OTEL_COLLECTOR_URL` or `OTEL_METRICS_ENDPOINT` as environment variables does not turn it on; those names are only referenced by config values of type `env`. ```bash showLineNumbers title="Create the otel plugin" curl -s -X POST http://localhost:8080/api/plugins \ -H 'content-type: application/json' \ -d '{ "name": "otel", "enabled": true, "config": { "enabled": true, "traces_enabled": true, "service_name": "bifrost", "collector_url": { "type": "plain_text", "value": "http://otel-collector:4318/v1/traces" }, "trace_type": "genai_extension", "protocol": "http", "insecure": true, "disable_content_logging": true, "metrics_enabled": false, "export_timeout": 5 } }' ``` Export starts within seconds; no restart is needed. Notes on the fields: - `collector_url` must carry the full path for HTTP (`http(s)://host:port/v1/traces`) and a bare `host:port` for gRPC. - `disable_content_logging: true` removes `gen_ai.input.messages` and `gen_ai.output.messages` while keeping every `gen_ai.usage.*` attribute. Turn it on unless you have a reason to ship prompt text. - `metrics_enabled` is left off above on purpose. Turning it on pushes 13 families over OTLP under the same names as the scrape, 12 of which the Collector is already receiving from the Prometheus receiver, so the two arrive as duplicates. Pick one path. - `trace_type` accepts `genai_extension` and `vercel`. If you would rather push metrics than scrape them, set `metrics_enabled: true` with a `metrics_endpoint`, drop the `prometheus` receiver, and accept the trade: the push carries `bifrost_overhead_latency_microseconds`, which the scrape does not, but loses `bifrost_active_requests`, `bifrost_provider_key_up` and `bifrost_stream_inter_token_latency_seconds`, which the push does not carry. ### Configuration The `prometheus` receiver handles metrics and the `otlp` receiver handles the pushed traces. The scrape is unfiltered, so no metric enable list is needed; the Prometheus receiver synthesises `up` and four scrape-status series. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: bifrost scrape_interval: 15s static_configs: - targets: - ${env:BIFROST_HOST}:8080 otlp: protocols: http: endpoint: 0.0.0.0:4318 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] traces: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` Run the Collector on `otel/opentelemetry-collector-contrib:latest` or a pinned tag of it. Drop the traces pipeline if you are only collecting metrics. The `resource` processor deliberately does not set `service.name`. On the metrics path the `job_name` supplies it, and on the trace path Bifrost sets its own from the plugin's `service_name`. An upsert here would overwrite that. #### Environment Variables ```bash showLineNumbers title=".env" BIFROST_HOST=localhost ENVIRONMENT=your_environment OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check within 60 seconds: ```bash showLineNumbers # The gateway families exist - zero means no LLM request has run yet curl -s http://localhost:8080/metrics | grep -c '^# TYPE bifrost_' # The Collector is scraping Bifrost docker logs otel-collector 2>&1 | grep -i "bifrost_success_requests_total" # Traces are arriving, if the otel plugin is created docker logs otel-collector 2>&1 | grep -i "gen_ai.request.model" ``` In Scout, `up{job="bifrost"}` should read 1 and `bifrost_success_requests_total` should climb as requests are served. Expect 53 families on a gateway that has handled successes, errors and at least one stream, and fewer until each path has run once. ### Troubleshooting #### The scrape works but no `bifrost_` series arrive **Cause**: the gateway has not served an LLM request. Every `bifrost_` family registers on first use. **Look at**: `curl -s .../metrics | grep -c '^# TYPE bifrost_'`. On a cold gateway it returns 0 while the endpoint itself returns 200. **Fix**: register a provider and a key, send one completion, and re-scrape. #### Provider registration is rejected **Cause**: one of three things. **Look at**: the response body from the management API. **Fix**: 1. `private IP addresses are not allowed` - set `network_config.allow_private_network` to `true` when the provider's `base_url` points at a host on a private network. 2. `no keys found for provider` - keys are a separate resource. They are ignored on `POST /api/providers` and must be sent to `POST /api/providers/{provider}/keys`. 3. `could not auto resolve a provider` - the `model` in the request has to carry the provider prefix, as in `openai/gpt-4o`. #### An error-rate alert never fires despite failing requests **Cause**: the failures are validation or provider-resolution failures, which are rejected before dispatch and touch no `bifrost_` family. **Look at**: `http_requests_total{status="400"}`. If it is climbing while `bifrost_error_requests_total` is flat, the requests never reached a provider. **Fix**: alert on both families. #### Series count is growing without traffic growth **Cause**: the `model` label is client-supplied and unvalidated, so every distinct value a client sends becomes a permanent series. **Look at**: the distinct values of `model` on `bifrost_error_requests_total`. **Fix**: keep only known models with a `metric_relabel_configs` rule at the receiver, as shown in [`model` is client-supplied and unbounded](#model-is-client-supplied-and-unbounded). #### Gateway latency rises while provider latency stays flat **Cause**: the overhead is inside the gateway process, not upstream. `bifrost_upstream_latency_seconds` measures only the provider call, so time spent in Go garbage collection or plugin work never shows there. **Look at**: the Diagnostic-tier Go runtime families - `go_gc_duration_seconds` for pause time, the `go_memstats_*` set for heap pressure, and `go_threads` against `go_sched_gomaxprocs_threads` for scheduler saturation. Compare with `go_goroutines`, which is in the Operational tier and rises before the others do. Bifrost measures its own overhead directly as `bifrost_overhead_latency_microseconds`, but only on the OTLP push path - the scrape does not carry it. **Fix**: raise the container's CPU limit or `GOMAXPROCS`. If the heap is the constraint, cut plugin count or request concurrency; the eight default plugins run three hooks each per request. #### The gateway stops accepting connections under load **Cause**: file-descriptor exhaustion. Each provider connection and each inbound request holds a descriptor, and the limit is the container's, not Bifrost's. **Look at**: `process_open_fds` against the Diagnostic-tier `process_max_fds`. A ratio approaching 1 is the ceiling being reached. `process_network_receive_bytes_total` and `process_network_transmit_bytes_total` confirm whether traffic is still flowing while new connections are refused. **Fix**: raise the container's `nofile` limit, and cap client concurrency so the gateway sheds load rather than exhausting descriptors. #### Counters appear twice with different attribute sets **Cause**: both the Prometheus scrape and the plugin's OTLP metrics push are running. They emit the same names, and the Prometheus receiver drops empty labels while the push keeps them, so the two sets do not merge. **Fix**: set `metrics_enabled: false` on the plugin config and keep the scrape, or drop the `prometheus` receiver and keep the push. #### Traces do not arrive **Cause**: the `otel` plugin has not been created, or `collector_url` is missing its path. **Look at**: `GET /api/plugins`. A fresh gateway returns `count: 0` even though `GET /api/plugins/builtins` lists `otel`. **Fix**: 1. Create the plugin with `POST /api/plugins` as shown above. 2. For `protocol: http`, give `collector_url` the full `http://host:4318/v1/traces` path. ### FAQ #### Do I need to turn the metrics endpoint on? No. It is served at `/metrics` on the main port by default. But it carries no `bifrost_` families until the gateway has served an LLM request. #### Which prefix should I gate the scrape on? Both `bifrost_` and `http_`. `http_requests_total` is the only complete request count, and requests rejected before provider dispatch appear nowhere else. #### Why is `bifrost_provider_key_up` zero when the provider is fine? Because it reports the most recent attempt against that key, whatever caused it to fail. A request for an unknown model or an unsupported operation drives it to 0 even though the provider was never at fault, and it holds that value until the next attempt. #### Can I add tenant or team labels to the metrics? You can add the dimensions with `client_config.prometheus_labels`, and the gateway needs a restart for them to appear. The values stay empty - request headers do not fill them - so add the dimension at the Collector with an `attributes` processor if you need it populated. #### Should I use the Prometheus scrape or the OTLP metrics push? The scrape, unless you specifically want `bifrost_overhead_latency_microseconds`. The push covers 13 families to the scrape's 15 `bifrost_` and `http_` ones, and running both duplicates 12 of them under the same names with different attribute sets. #### Do the traces contain my prompts? By default, yes. `gen_ai.input.messages` and `gen_ai.output.messages` carry the full text. Set `disable_content_logging: true` on the `otel` plugin config to strip both while keeping token usage and latency. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Bifrost metrics. - [LiteLLM Gateway Monitoring](./litellm.md) - LLM gateway covering the same position; compare the two before standardising on one. - [vLLM Monitoring](./vllm.md) - Self-hosted model server that commonly sits behind a gateway as the upstream provider. ### What's Next? - **Create Dashboards**: Start with `http_requests_total` split by `status`, `bifrost_upstream_latency_seconds` as `rate(_sum) / rate(_count)` by `model`, and the two token counters as a cost panel. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add [vLLM](./vllm.md) or [llama.cpp](./llama-cpp.md) for the serving runtime behind the gateway, so provider latency has a counterpart on the model side. - **Fine-tune Collection**: Decide whether you run traces, and if you do whether you sample. The plugin hook spans are 24 of the 26 spans per request. --- ## Caddy OpenTelemetry Monitoring - Request Rate, Latency, and Collector Setup ## Caddy Caddy exposes Prometheus-format metrics natively at `/metrics` on its admin API (`:2019`) once the `metrics` global option is set, so no exporter sidecar is needed. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint and passes the metrics through - request throughput, request and response latency, in-flight concurrency, config-reload health, and the Go runtime internals Caddy ships alongside its own counters - from Caddy 2.9.0+. This guide configures the Caddyfile, wires the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Caddy | 2.9.0 | 2.11.4 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Caddy must be running with the `metrics` global option set (see [Access Setup](#access-setup)). Without it, only admin API and Go runtime metrics are exposed. - The admin API port (`:2019`) must be reachable from the host running the Collector. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Caddy defines its own metric surface; the `prometheus` receiver passes through whatever the endpoint exposes - there is no per-metric enable or disable list in the Collector. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - Caddy's metrics endpoint is reachable. This is the liveness signal the `prometheus` receiver supplies; `1` = the target is up. | | `caddy_http_requests_total` | Requests handled per `server` / `handler`; the rate is the throughput KPI. | | `caddy_http_request_duration_seconds` | Request handling latency histogram. The `code` label lives here, so error rate derives from `_count` where `code=~"5.."`. | | `caddy_http_requests_in_flight` | Requests currently being handled per `server` / `handler` - concurrency and saturation. | The status `code` label is on the duration histogram, not on `caddy_http_requests_total` (which carries only `server` and `handler`). Derive 5xx error rate from `rate(caddy_http_request_duration_seconds_count{code=~"5.."})`, not from the requests counter. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `caddy_config_last_reload_successful` | Whether the last config reload succeeded; `0` means Caddy is serving the previous good config, not what is on disk. | | `caddy_http_response_duration_seconds` | Time to write the response to the client - slow clients, large bodies, or downstream backpressure (distinct from request handling time). | | `caddy_http_response_size_bytes` | Response body size distribution - bytes served and payload bloat. | | `caddy_admin_http_requests_total` | Admin API (`:2019`) request volume by `code` / `handler` / `method` - config churn and scrape traffic. | #### Diagnostic - for investigation and tuning Higher cardinality; read these alongside an incident rather than paging on them. In production you can drop this tier with `metric_relabel_configs` and keep Core + Operational. | Metric | What it tells you | |---|---| | `caddy_http_request_size_bytes` | Request body size distribution - upload and ingest patterns. | | `caddy_config_last_reload_success_timestamp_seconds` | Wall-clock of the last successful reload; reload age = `now - this`. | | `go_*` (Go runtime, ~30 series) | GC pauses, goroutine count, heap and allocation - the Go runtime Caddy is built on. | | `process_*` (process, ~9 series) | CPU seconds, resident memory, open file descriptors, start time. | Caddy emits 9 `caddy_*` series under the `metrics` global option, alongside the `go_*` and `process_*` internals and the `up` target-health signal the receiver adds. Caddy additionally emits TLS-handshake metrics when serving HTTPS and `reverse_proxy` upstream-health metrics when proxying. Those are not part of this metric set (a plain-HTTP `static_response` site exposes neither); they appear once you serve TLS or proxy to an upstream. Full metric list: run `curl -s http://localhost:2019/metrics` against your Caddy instance. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `up` | - | `== 0` for > 1m | Metrics endpoint not scrapable - Caddy down, admin API off, or a network issue. Check the process and `:2019`. | | `caddy_config_last_reload_successful` | - | `== 0` | Last reload errored; Caddy is serving the previous good config, not what is on disk. Inspect the reload error and fix the Caddyfile. | | `rate(caddy_http_request_duration_seconds_count{code=~"5.."}) / rate(caddy_http_request_duration_seconds_count)` | Rising vs baseline | Sustained rise | Server-side errors. Check upstreams, handlers, and recent config changes. | | `histogram_quantile(0.99, rate(caddy_http_request_duration_seconds_bucket[5m]))` | Rising vs baseline | Sustained rise | p99 request handling slowing. Check upstream latency, CPU, and in-flight saturation. | | `rate(caddy_http_requests_total)` | - | `-> 0` while traffic expected | Caddy not handling requests. Check the process, listener, and upstreams. | | `caddy_http_requests_in_flight` | Climbing toward known capacity | At/over capacity | Requests piling up in-flight. Check upstream latency or scale out. | ### Access Setup Caddy's admin API listens on `:2019` by default and serves `/metrics`, but until you set the `metrics` global option that endpoint returns only admin API and Go runtime metrics. Add `metrics` to the global options block to get the per-handler HTTP series: ```text showLineNumbers title="Caddyfile" { admin :2019 metrics } :80 { respond "OK" 200 } ``` Reload after editing: `caddy reload`, or restart the container. Send a few requests so the HTTP histograms and counters advance, then confirm the endpoint: ```bash showLineNumbers title="Verify access" # Admin API is up curl -s http://localhost:2019/config/ | head -5 # Caddy metric surface is exposed (expect caddy_http_* lines) curl -s http://localhost:2019/metrics | grep caddy_http ``` The admin API has no authentication by default. Do not expose `:2019` publicly - bind it to a private interface or localhost via the `admin` directive and restrict it with firewall or network policy so only the Collector's network can reach it. The Collector needs only `:2019`; it does not need the HTTP or HTTPS serving ports. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: caddy scrape_interval: 10s static_configs: - targets: - ${env:CADDY_HOST}:2019 # Caddy admin API host processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic tier (`go_*`, `process_*`, request-size histogram) with a `metric_relabel_configs` block on the scrape config while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" CADDY_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Collector is scraping Caddy docker logs otel-collector 2>&1 | grep -i "caddy" # Caddy is healthy and serving metrics curl -s http://localhost:2019/metrics | grep caddy_http # Generate traffic so the request and latency series advance curl -s http://localhost:8080/ > /dev/null ``` ### Troubleshooting #### No metrics at `/metrics` **Cause**: The admin API is disabled or listening on a different port. **Fix**: 1. Verify Caddy is running: `docker ps | grep caddy` or `caddy version`. 2. Confirm the admin API is enabled - do not set `admin off` in the Caddyfile. 3. Confirm the port: the default is `:2019`; check the `admin` directive. #### Only Go runtime metrics, no HTTP metrics **Cause**: The `metrics` global option is not set, so Caddy exposes only admin and `go_*` / `process_*` series. **Fix**: 1. Add `metrics` inside the global options block (see [Access Setup](#access-setup)). 2. Reload Caddy: `caddy reload`, or restart the container. 3. Send a few requests, then re-check `/metrics` for `caddy_http_*`. #### 5xx error rate looks wrong or always zero **Cause**: The status `code` label is on the histograms, not on `caddy_http_requests_total`, so an error-rate query against the requests counter has no `code` to filter on. **Look at**: `caddy_http_request_duration_seconds_count` - the `code` label is here. Derive error rate from `rate(caddy_http_request_duration_seconds_count{code=~"5.."})`. **Fix**: Point the error-rate query at the duration histogram's `_count` series, not at `caddy_http_requests_total`. #### Config changes not taking effect **Cause**: The last reload failed, so Caddy kept the previous good config. **Look at**: `caddy_config_last_reload_successful` (`0` = the running config is stale) and `caddy_config_last_reload_success_timestamp_seconds` for how long ago the last good reload was (`now - this` = reload age). **Fix**: 1. Inspect the reload error in the Caddy logs. 2. Fix the Caddyfile and reload; confirm `caddy_config_last_reload_successful` returns to `1`. #### Requests slow or piling up **Cause**: Caddy or an upstream is saturated. **Look at**: `caddy_http_requests_in_flight` (concurrency climbing toward capacity) and the p99 of `caddy_http_request_duration_seconds`; on the runtime side, the Diagnostic `go_*` (goroutine count, GC pauses) and `process_*` (CPU, open FDs) series. **Fix**: 1. Investigate upstream latency if in-flight and p99 climb together. 2. Scale out or raise capacity if Caddy itself is CPU- or FD-bound. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### How do I get per-route HTTP metrics? Set the `metrics` global option in the Caddyfile global-options block. That exposes the `caddy_http_*` series. The labels differ by series: `caddy_http_requests_total` carries `server` and `handler`, while the latency and size histograms (for example `caddy_http_request_duration_seconds`) add `method` and `code`. Without it, Caddy exposes only admin API and Go runtime metrics. #### Does this work with Caddy running in Kubernetes? Yes. Set the scrape target to the Caddy pod or service DNS on port 2019 (e.g., `caddy.default.svc.cluster.local:2019`). The admin API must be reachable from the Collector pod; keep it on a private interface and restrict it with a network policy. #### How do I monitor multiple Caddy instances? Add each instance to the scrape targets: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: prometheus: config: scrape_configs: - job_name: caddy static_configs: - targets: - caddy-1:2019 - caddy-2:2019 ``` Each instance is identified by its `instance` label. #### Why is the status code missing from `caddy_http_requests_total`? `caddy_http_requests_total` carries only the `server` and `handler` labels. The HTTP status `code` lives on the latency histograms (`caddy_http_request_duration_seconds`, `caddy_http_response_duration_seconds`), so error-rate and per-code queries use those `_count` series instead. #### Should I expose the admin API in production? No. The admin API has no authentication by default. Bind it to localhost or a private interface with the `admin` directive and restrict it with firewall or network-policy rules so only the Collector can reach `:2019`. The Collector does not need the HTTP or HTTPS serving ports. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Caddy metrics. - [NGINX Monitoring](./nginx.md) - Request rate and connections on a companion web server. - [Apache HTTP Server Monitoring](./apache-httpd.md) - Worker and request metrics for the classic web server. - [HAProxy Monitoring](./haproxy.md) - Frontend, backend, and session health for the load balancer in front. - [Traefik Monitoring](./traefik.md) - Entrypoint and router metrics for the cloud-native reverse proxy. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [NGINX](./nginx.md), [Traefik](./traefik.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## cAdvisor OpenTelemetry Monitoring - Per-Container CPU, Memory, OOM Events, and Collector Setup ## cAdvisor cAdvisor (Container Advisor) exposes Prometheus text at `/metrics` on `:8080`. The OpenTelemetry Collector's `prometheus` receiver scrapes it directly, collecting 90+ metrics across per-container CPU, memory (including OOM events), filesystem, and network, plus host-capacity (`machine_*`) figures, then ships them to base14 Scout. This guide configures the receiver, deploys cAdvisor with the access it needs, and exports the metrics. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ---------------- | | cAdvisor | 0.45 | 0.49+ (v0.49.1) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - cAdvisor's metrics port (`8080`) must be reachable from the host running the Collector. - cAdvisor needs `--privileged`, the `/dev/kmsg` device, and read-only mounts of `/`, `/sys`, `/var/lib/docker`, `/var/run`, and `/dev/disk` to read host cgroup and filesystem statistics (see [Access Setup](#access-setup)). - No authentication is required on the metrics endpoint by default. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things to know about this surface before you read the tiers: - **`up` is the liveness signal here.** The `prometheus` receiver emits `up` = 1 when cAdvisor's `/metrics` endpoint responds. That is the liveness signal for the cAdvisor scrape itself; cAdvisor in turn reports per-container health - CPU, memory working set, and OOM events. - **cAdvisor is one of the highest-cardinality exporters.** Every `container_*` series carries `name`, `id`, and `image` labels (plus `pod` / `namespace` / `container` under Kubernetes), and the filesystem / network families add a series per device and per interface. Scope it with a `container_.*|machine_.*|up` keep filter (see [Configuration](#configuration)). - **It reports on every container the host runs.** Under Kubernetes this also surfaces system pods. The empty-`name` (root cgroup) series is the machine-wide aggregate. - **`working_set` is the OOM-risk figure.** `container_memory_working_set_bytes` is non-reclaimable - what the OOM-killer counts - while `container_memory_usage_bytes` includes reclaimable page cache and reads higher. - **`go_*` / `process_*` are cAdvisor's own runtime**, not container metrics. The keep filter drops them. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Prometheus scrape liveness - 1 means cAdvisor's `/metrics` responded. The liveness signal on this surface. | | `container_cpu_usage_seconds_total` | Cumulative CPU time per container; the rate approximates cores in use. Headline compute load. | | `container_memory_working_set_bytes` | Non-reclaimable memory - what the OOM-killer counts. Headline memory-pressure / OOM-risk signal. | | `container_oom_events_total` | OOM-kill events for the container; a rising count means it is being killed for memory. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Memory | `container_memory_usage_bytes`, `container_spec_memory_limit_bytes` | Total memory including reclaimable cache, and the configured limit - the denominator for OOM-risk %. | | CPU detail | `container_cpu_system_seconds_total`, `container_cpu_user_seconds_total`, `container_cpu_load_average_10s` | Kernel/user-mode CPU split and the 10-second load average (runnable tasks). | | Network | `container_network_receive_bytes_total`, `container_network_transmit_bytes_total`, `container_network_receive_errors_total`, `container_network_transmit_errors_total`, `container_network_receive_packets_dropped_total`, `container_network_transmit_packets_dropped_total` | Per-interface throughput, interface errors, and dropped packets (buffer saturation). | | Filesystem | `container_fs_usage_bytes`, `container_fs_limit_bytes`, `container_fs_reads_bytes_total`, `container_fs_writes_bytes_total` | Bytes used vs device size (disk-full %) and read/write throughput per device. | | Lifecycle | `container_tasks_state`, `container_start_time_seconds`, `container_last_seen` | Task count by state, start time (a change means a restart), and last-seen freshness. | | Host capacity | `machine_memory_bytes`, `machine_cpu_cores` | Host total memory and logical CPU count - the denominators for machine-wide utilization. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Representative metrics | When you reach for it | |---|---|---| | Memory breakdown | `container_memory_rss`, `container_memory_cache`, `container_memory_swap`, ... | Anonymous vs page-cache vs swap split behind the working-set figure. | | Container spec / limits | `container_spec_cpu_period`, `container_spec_cpu_shares`, `container_spec_memory_swap_limit_bytes`, ... | The static cgroup limits the container was configured with. | | Filesystem I/O detail | `container_fs_reads_total`, `container_fs_writes_total`, `container_fs_io_time_seconds_total`, ... | Operation counts and I/O time behind the byte throughput. | | Per-device block I/O | `container_blkio_device_usage_total` | Block I/O bytes by device and operation. | | Packet counts | `container_network_receive_packets_total`, `container_network_transmit_packets_total` | Drill-down behind the rx/tx byte, error, and drop counters. | | Machine hardware | `machine_cpu_physical_cores`, `machine_cpu_sockets`, `machine_swap_bytes`, ... | Host physical-core, socket, and swap capacity detail. | | Build / scrape flags | `cadvisor_version_info`, `container_scrape_error`, `machine_scrape_error` | cAdvisor build labels and its own collection-error flags (1 = it failed to read stats). | | cAdvisor runtime + scrape meta | `go_*`, `process_*`, `scrape_duration_seconds`, ... | cAdvisor's own Go-runtime/process series and the receiver-side scrape meta - the keep filter drops these. | Full metric list: run `curl -s http://localhost:8080/metrics` against your cAdvisor instance. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. The ratios are against each container's own configured limit, not invented absolutes; tune them to your workload. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | No per-container metrics are arriving - check the cAdvisor container and the scrape target. | | `rate(container_oom_events_total)` | `> 0` | A container was OOM-killed - raise its limit or fix the leak. | | `container_memory_working_set_bytes / container_spec_memory_limit_bytes` | `> 0.9` (when a limit is set) | OOM-kill is imminent for that container. | | `rate(container_cpu_usage_seconds_total)` | approaching the container's CPU quota | The container is CPU-bound and likely throttled - scale out or raise the quota. | | `container_fs_usage_bytes / container_fs_limit_bytes` | `> 0.9` | Disk pressure on that device - free space or expand. | | `rate(container_network_receive_errors_total + container_network_transmit_errors_total)` | `> 0` | Interface errors or drops - check host networking and throughput ceilings. | | `time() - container_last_seen` | `>` several scrape intervals | cAdvisor stopped seeing the container - it may have exited unexpectedly. | ### Access Setup cAdvisor reads host cgroup and filesystem statistics directly, so it runs as a privileged container with the `/dev/kmsg` device and several read-only host mounts. Deploy it alongside the Collector: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: cadvisor: image: gcr.io/cadvisor/cadvisor:v0.49.1 privileged: true devices: - /dev/kmsg volumes: - /:/rootfs:ro - /sys:/sys:ro - /var/lib/docker:/var/lib/docker:ro - /var/run:/var/run:ro - /dev/disk:/dev/disk:ro ports: - "8080:8080" ``` Verify the endpoint is serving metrics: ```bash showLineNumbers title="Verify access" # Confirm cAdvisor is serving metrics curl -s http://localhost:8080/metrics | head -20 # Check a representative container metric is present curl -s http://localhost:8080/metrics | grep container_cpu_usage_seconds_total ``` The metrics endpoint has no authentication by default. Restrict the port to the Collector's network and front it appropriately in production. ### Configuration The `prometheus` receiver scrapes cAdvisor's `/metrics` endpoint (the default path, so no `metrics_path` override is needed). The `metric_relabel_configs` keep filter scopes collection to the `container_*` and `machine_*` families plus `up`, dropping cAdvisor's own `go_*` / `process_*` runtime noise - the high-cardinality control for this surface. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: cadvisor scrape_interval: 10s static_configs: - targets: - ${env:CADVISOR_HOST}:8080 metric_relabel_configs: - source_labels: [__name__] regex: "container_.*|machine_.*|up" action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" CADVISOR_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for a successful cadvisor scrape docker logs otel-collector 2>&1 | grep -i "cadvisor" # Check the metrics endpoint directly curl -s http://localhost:8080/metrics | grep container_memory_working_set_bytes ``` ### Troubleshooting #### Connection refused on port 8080 **Cause**: The Collector cannot reach cAdvisor at the configured address. **Fix**: 1. Verify cAdvisor is running: `docker ps | grep cadvisor`. 2. Confirm cAdvisor's metrics port (`8080`) is published or reachable from the Collector host. 3. Check firewall rules if the Collector runs on a separate host. #### cAdvisor returns errors or empty per-container metrics **Cause**: cAdvisor cannot read host cgroup or filesystem statistics, so it reports collection errors or metric names with empty per-container labels. **Look at**: `container_scrape_error` / `machine_scrape_error` - `1` means cAdvisor failed to read stats. **Fix**: 1. Confirm cAdvisor runs with `--privileged` and the `/dev/kmsg` device. 2. Verify the read-only host mounts (`/`, `/sys`, `/var/lib/docker`, `/var/run`, `/dev/disk`) are all present. 3. Check the cAdvisor container logs for cgroup access errors. #### Metric volume or cardinality is too high **Cause**: cAdvisor emits a series per container plus a series per device and per interface, and exposes its own `go_*` / `process_*` runtime internals. **Look at**: `scrape_samples_scraped` for the per-scrape series count. **Fix**: 1. Keep the `container_.*|machine_.*|up` keep filter so collection is scoped to the container and machine families and cAdvisor's own runtime series are dropped. 2. Drop the high-cardinality per-device / per-interface Diagnostic detail with an additional `metric_relabel_configs` rule if it is not needed. 3. A longer `scrape_interval` also reduces sample volume. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with cAdvisor running in Kubernetes? Yes. cAdvisor is embedded in the kubelet, so you can scrape the kubelet's `/metrics/cadvisor` endpoint, or run cAdvisor as a DaemonSet so each node's containers are measured by a local instance. The container and machine metric names match either way. #### How do I monitor cAdvisor on multiple hosts? Add one scrape target per cAdvisor instance to the `prometheus` receiver's `static_configs`. The receiver attaches an `instance` label to each series, which distinguishes the hosts in Scout. #### `container_memory_usage_bytes` vs `container_memory_working_set_bytes`? `container_memory_usage_bytes` includes reclaimable page cache and reads higher. `container_memory_working_set_bytes` is the non-reclaimable memory the OOM-killer counts, so it is the OOM-risk signal and the better basis for memory alerts. #### Why does cAdvisor need to run privileged? cAdvisor reads host cgroup and filesystem statistics directly. It needs `--privileged`, the `/dev/kmsg` device, and read-only mounts of `/`, `/sys`, `/var/lib/docker`, `/var/run`, and `/dev/disk` to collect per-container resource metrics. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on container metrics. - [Docker Engine Monitoring](./docker.md) - Per-container metrics from the Docker Engine API via the `docker_stats` receiver. - [Kubelet Stats Monitoring](./kubelet-stats.md) - Node, pod, and container metrics from the kubelet Summary API. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Docker Engine](./docker.md), [Kubelet Stats](./kubelet-stats.md), and other components. - **Fine-tune Collection**: The `container_.*|machine_.*|up` keep filter scopes collection to the container and machine families. The per-device / per-interface Diagnostic detail is there when you need to drill in during an incident or a capacity review. --- ## Apache Camel OpenTelemetry Monitoring - Exchange Throughput, Failure Rate, and Collector Setup ## Apache Camel The OpenTelemetry JMX Scraper reads Apache Camel's `org.apache.camel:*` JMX MBeans and emits 49 Camel metrics plus 19 metrics from the JVM the routes run on (68 total) on Camel 4.10+ - exchange throughput, failure and redelivery counts, in-flight backlog, processing latency, and thread-pool saturation. Camel exposes no Prometheus or OTLP endpoint of its own; the scraper bridges JMX to OTLP and pushes to the Collector over gRPC. This guide configures the scraper and Collector and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------------- | ------------- | | Apache Camel | 4.10 | 4.10 | | OTel JMX Scraper | 1.55.0-alpha | 1.57.0-alpha | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Camel must run with `camel-management` on the classpath. It registers the `org.apache.camel:*` MBeans the scraper reads in the platform MBean server automatically; no extra Camel config is needed for that. - Remote JMX over RMI must still be enabled and reachable from the host running the scraper - the MBeans exist, but the remote connector is opened by the JVM JMX flags in [Access Setup](#access-setup) (port 1099 below), not by `camel-management`. - The scraper must be **1.55.0-alpha or newer**. The `camel` target (`jmx/rules/camel.yaml`) is new in 1.55.0-alpha; an older scraper has no rule file for Camel and emits no `camel.*` metrics. This guide is tested on 1.57.0-alpha. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `camel.*` set is the same exchange instruments at three granularities: **context** (whole-integration, one series), **route** (per route), and **processor** (per processor), plus thread-pool counters. The headline tiers below use the context-level series; the per-route and per-processor equivalents are the Diagnostic drill-down. Route and processor series only appear once at least one route or processor exists, and thread-pool series only once Camel has created a managed pool. #### Core - is it up and doing work | Metric | What it tells you | |---|---| | `camel.context.exchange.count` | Total exchanges processed by the CamelContext - the integration throughput KPI. JMX exposes no `up` metric, so a rising count is the liveness signal that the routes are alive and working. | | `jvm.memory.used` | JVM memory in use - the process-alive and heap-health anchor for the JVM the routes run on. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `camel.context.exchange.failed.count` | Exchanges that failed - the error-rate signal. | | `camel.context.exchange.failed.handled` | Failures absorbed by an error handler or dead-letter route. | | `camel.context.exchange.inflight` | Exchanges currently in flight - backpressure / stuck-route signal. | | `camel.context.exchange.processing.duration.mean` | Mean exchange processing time. | | `camel.context.exchange.processing.duration.max` | Longest exchange processing time - tail latency. | | `camel.context.exchange.redelivered.count` | Exchanges redelivered - retry pressure / instability. | | `camel.threadpool.task.queue.size` | Tasks queued on a Camel thread pool - saturation backlog. | | `camel.threadpool.thread.count` | Threads currently in a Camel thread pool. | | `camel.threadpool.thread.limit.upper` | Thread-pool max size - the saturation denominator. | | `jvm.memory.limit` | JVM memory ceiling - the saturation denominator against `jvm.memory.used`. | | `jvm.cpu.recent_utilization` | Recent process CPU utilization. | | `jvm.thread.count` | Total live JVM threads - a leak signal. | #### Diagnostic - for investigation and tuning Higher cardinality - the route and processor families emit one series per route and per processor. Reach for these during an investigation, not as signals you page on. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | CamelContext detail | `camel.context.exchange.completed`, `camel.context.exchange.redelivered.external`, `camel.context.exchange.processing.duration.{last,last_delta,min,sum}`, `camel.context.route.added`, `camel.context.route.started` | Context-level completion, external redelivery, and route lifecycle. | | Per-route exchanges | `camel.route.exchange.*` (13 instruments, one series per route): `completed`, `count`, `failed.count`, `failed.handled`, `inflight`, `redelivered.count`, `redelivered.external`, `processing.duration.{last,last_delta,max,mean,min,sum}` | Pin failures, backlog, or latency to a specific route. | | Per-processor exchanges | `camel.processor.exchange.*` (13 instruments, one series per processor): same shape as per-route | Find the hot processor inside a slow route. | | Thread-pool detail | `camel.threadpool.task.active`, `camel.threadpool.task.completed`, `camel.threadpool.task.count`, `camel.threadpool.thread.limit.lower`, `camel.threadpool.thread.max` | Pool task accounting and configured bounds. | | JVM memory detail | `jvm.memory.committed`, `jvm.memory.init`, `jvm.memory.used_after_last_gc` | Heap sizing and post-GC live set. | | JVM class loading | `jvm.class.count`, `jvm.class.loaded`, `jvm.class.unloaded` | Class-loader leaks. | | JVM CPU / system | `jvm.cpu.count`, `jvm.cpu.time`, `jvm.system.cpu.load_1m`, `jvm.system.cpu.utilization` | Host-level CPU pressure on the JVM. | | JVM buffers / descriptors | `jvm.buffer.count`, `jvm.buffer.memory.limit`, `jvm.buffer.memory.used`, `jvm.file_descriptor.count`, `jvm.file_descriptor.limit` | NIO buffer and file-descriptor exhaustion. | Attributes: `camel.context.*` carry `camel.context` (context name); `camel.route.*` carry `camel.route` and `camel.destination`; `camel.processor.*` carry `camel.processor`; `camel.threadpool.*` carry `camel.threadpool.name`; `jvm.memory.*` carry `jvm.memory.type` (heap / non_heap) and pool name. Full metric reference: the scraper's [`jmx/rules/camel.yaml`](https://github.com/open-telemetry/opentelemetry-java-contrib/blob/main/jmx-scraper/src/main/resources/jmx/rules/camel.yaml) defines the `camel.*` metric names. ### Key Alerts to Configure Threshold guidance for the most useful Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `rate(camel.context.exchange.failed.count)` vs `rate(camel.context.exchange.count)` | Failure rate climbing | Sustained climb | Route or endpoint errors; drill into `camel.route.exchange.failed.count` to find the failing route. | | `camel.context.exchange.inflight` | Rising | Rising and not draining | A route is stuck or a downstream endpoint is slow; check the slowest route's processing duration. | | `camel.context.exchange.processing.duration.mean` / `.max` | Rising vs baseline | Sustained rise | Slow processing; inspect per-processor `processing.duration.max` for the hot processor. | | `rate(camel.context.exchange.redelivered.count)` | Climbing | Sustained climb | Transient endpoint failures forcing retries; check the failing endpoint and back-off config. | | `camel.threadpool.task.queue.size` | Growing | `thread.count` at `thread.limit.upper` | Pool can't keep up; raise pool size or shed load. | | `jvm.memory.used` vs `jvm.memory.limit` | Approaching limit | Near limit with GC churn | GC churn / OOM risk; raise heap or reduce in-flight batch sizes. | ### Access Setup Camel does not expose Prometheus or OTLP metrics natively. Enable remote JMX on the Camel application and point the OpenTelemetry JMX Scraper at it. **Enable Camel JMX management** - add `camel-management` to the application's dependencies. It registers the `org.apache.camel:*` MBeans and enables JMX by default. With Maven: ```xml showLineNumbers title="pom.xml (excerpt)" org.apache.camel camel-management ``` **Expose remote JMX over RMI** - start the JVM with the standard JMX remote properties so the scraper can connect. The example below opens port 1099 with no auth and no TLS; production should front JMX with authentication and TLS, or tunnel it over a private network: ```bash showLineNumbers title="JVM JMX remote flags" java \ -Dcom.sun.management.jmxremote \ -Dcom.sun.management.jmxremote.port=1099 \ -Dcom.sun.management.jmxremote.rmi.port=1099 \ -Dcom.sun.management.jmxremote.local.only=false \ -Dcom.sun.management.jmxremote.authenticate=false \ -Dcom.sun.management.jmxremote.ssl=false \ -Djava.rmi.server.hostname=camel-app \ -jar your-camel-app.jar ``` **Run the JMX Scraper** - the scraper connects over JMX RMI and pushes OTLP/gRPC to the Collector. It must be `1.55.0-alpha` or newer for the `camel` target (this guide pins `1.57.0-alpha`). In Docker, build a small image around the scraper jar: ```dockerfile showLineNumbers title="jmx-scraper/Dockerfile" FROM eclipse-temurin:17-jre ARG SCRAPER_VERSION=1.57.0-alpha ADD https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/${SCRAPER_VERSION}/opentelemetry-jmx-scraper-${SCRAPER_VERSION}.jar /opt/scraper.jar ENTRYPOINT ["java", "-jar", "/opt/scraper.jar"] ``` Wire the scraper to Camel and the Collector through environment variables: ```yaml showLineNumbers title="docker-compose.yaml (scraper service)" services: jmx-scraper: build: ./jmx-scraper environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://camel-app:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,camel # both JVM and Camel MBeans OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: 10000 # milliseconds depends_on: camel-app: condition: service_healthy ``` `OTEL_JMX_TARGET_SYSTEM: jvm,camel` is what selects both the JVM rules and the Camel rule set; drop `camel` and you get JVM metrics only. No special JMX role is needed for read - the scraper only reads management MBeans. ### Configuration The scraper sends OTLP to the Collector, which forwards to Scout. A minimal Collector pipeline: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 # The scraper pushes OTLP/gRPC here processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic-tier per-route and per-processor series with a `filter` processor while keeping Core and Operational. The per-route and per-processor families are the high- cardinality cost - one series each: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" processors: filter/diagnostic: metrics: exclude: match_type: regexp metric_names: - camel\.route\..* - camel\.processor\..* ``` Add `filter/diagnostic` to the `processors` list in the metrics pipeline. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and scraper, then confirm metrics flow within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped Camel metrics (requires a debug exporter) docker logs otel-collector 2>&1 | grep -i "camel" # Confirm the scraper connected to JMX (no rule-file or connection errors) docker logs jmx-scraper 2>&1 | tail -20 ``` The Collector log check needs a `debug` exporter in the pipeline; the production config above ships only `otlphttp/b14`, so confirm delivery in Scout instead, or add `debug` to the metrics pipeline while testing. `camel.context.exchange.count` and `jvm.memory.used` emit as soon as the scraper connects and the CamelContext is up. The `camel.route.*` and `camel.processor.*` series appear once at least one route and processor exist, and `camel.threadpool.*` once Camel has created a managed pool. ### Troubleshooting #### No `camel.*` metrics, only `jvm.*` **Cause**: The scraper is older than `1.55.0-alpha`, or `camel` is not in the target system. The `camel` rule file (`jmx/rules/camel.yaml`) is new in 1.55.0-alpha, so an older scraper has nothing to map Camel MBeans to. **Fix**: 1. Pin the scraper to `1.55.0-alpha` or newer. 2. Set `OTEL_JMX_TARGET_SYSTEM` to `jvm,camel` - omitting `camel` yields JVM metrics only. 3. Confirm `camel-management` is on the application classpath so the `org.apache.camel:*` MBeans exist for the scraper to read. #### Scraper cannot connect to JMX **Cause**: Remote JMX is not exposed, or the RMI hostname does not resolve from the scraper. **Fix**: 1. Verify the JVM was started with the JMX remote flags and is listening on port 1099. 2. Set `-Djava.rmi.server.hostname` to a name the scraper can resolve (the Camel container's hostname in Docker). 3. Confirm `OTEL_JMX_SERVICE_URL` points at the same host and port. #### Route, processor, or thread-pool metrics missing **Cause**: The underlying MBean does not exist yet. Route and processor series only appear once a route or processor exists; thread-pool series only once Camel has created a managed pool. **Look at**: `camel.context.route.added` and `camel.context.route.started`. If routes have not started, the per-route and per-processor families cannot emit. The `seda`-style consumer pools populate `camel.threadpool.*`; a context with no managed pool reports none. **Fix**: 1. Confirm the routes are started (check `camel.context.route.started`). 2. Drive traffic through the routes so the processor and thread-pool MBeans register. #### In-flight backlog or latency climbing **Cause**: A route is stuck, a downstream endpoint is slow, or the thread pool is saturated. **Look at**: the Diagnostic per-route series - `camel.route.exchange.inflight` to find the stuck route, and the per- processor `camel.processor.exchange.processing.duration.max` to find the hot processor inside it. Check `camel.threadpool.task.queue.size` against `camel.threadpool.thread.limit.upper` for pool saturation. **Fix**: 1. Raise the thread-pool size or shed load if the queue is sustained. 2. Investigate the slow endpoint and tune redelivery / back-off if `camel.route.exchange.redelivered.count` is climbing on that route. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `otlp` receiver and the `otlphttp/b14` exporter. ### FAQ #### Why do I need the JMX Scraper instead of a Camel receiver? There is no native Camel receiver and Camel exposes no Prometheus or OTLP endpoint. Camel publishes its statistics as `org.apache.camel:*` JMX MBeans (via `camel-management`). The OpenTelemetry JMX Scraper reads those MBeans and translates them to OTLP, which it pushes to the Collector. #### Does this work with Apache Camel in Kubernetes? Yes. Run the scraper as a sidecar in the same pod as the Camel application, with `OTEL_JMX_SERVICE_URL` pointing at `localhost:1099` (or the pod's JMX RMI port), and send OTLP to your Collector service. Front JMX with authentication on a shared network. #### Why are there context, route, and processor versions of the same metric? They are the same exchange instruments at three granularities. The `camel.context.*` series is the whole-integration roll-up (one series), `camel.route.*` is per route, and `camel.processor.*` is per processor. Alert on the context series and drill into route then processor to localize a failure or latency regression. #### Why is per-request latency not a single number? Camel reports processing duration as aggregates - mean, max, min, sum, and last - on the exchange MBeans, not a histogram. Use `camel.context.exchange.processing.duration.mean` and `.max` for the integration, and the per-route / per-processor equivalents to find where the time goes. Span-level timing for individual exchanges lives in your trace path, not in these metrics. #### Which scraper version do I need? `1.55.0-alpha` or newer. That release introduced the `camel` target (`jmx/rules/camel.yaml`); earlier scrapers have no Camel rule set and emit no `camel.*` metrics even when connected to the same MBeans. This guide is tested on `1.57.0-alpha`. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Camel metrics. - [Kafka Monitoring](./kafka.md) - A common companion message broker for Camel integration routes. - [RabbitMQ Monitoring](./rabbitmq.md) - Another broker frequently fronted by Camel routes. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Kafka](./kafka.md), [RabbitMQ](./rabbitmq.md), and other components Camel routes talk to. - **Fine-tune Collection**: Drop the Diagnostic per-route and per-processor tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Cassandra OpenTelemetry Monitoring - Client Request Latency, Compaction, and Collector Setup ## Cassandra The OpenTelemetry Collector scrapes a Prometheus JMX exporter to collect 320+ Cassandra metrics - coordinator read/write latency, request errors, compaction backlog, thread-pool saturation, storage load, and JVM health - from Cassandra 3.11+. Cassandra exposes its internals as JMX MBeans with no HTTP endpoint, so the `jmx_prometheus_javaagent` runs inside the Cassandra JVM and publishes them in Prometheus format on port 9404. The native `prometheus` receiver scrapes that endpoint. This guide configures the exporter agent and receiver and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ------------------------ | ------- | ----------- | | Cassandra | 3.11 | 5.0 | | jmx_prometheus_javaagent | 0.20.0 | 1.5.0 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Cassandra must be running with at least one keyspace and table receiving traffic. - Download the [`jmx_prometheus_javaagent`](https://github.com/prometheus/jmx_exporter/releases) JAR; it loads into the Cassandra JVM (see [Access Setup](#access-setup)). - The exporter port (9404) must be reachable from the host running the Collector. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The metric *names* below are produced by the exporter's `jmx-config.yaml` rules (shown in [Access Setup](#access-setup)), not by a fixed receiver schema. Counters carry the `_total` suffix added by the exporter for the COUNTER type, so a request count appears as `..._count_total`. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - Cassandra's JMX endpoint is reachable. This is the liveness signal; the `prometheus` receiver sets it to `1` when the scrape lands. | | `cassandra_clientrequest_latency_seconds` | Coordinator read/write latency percentiles (Summary; `scope=Read`/`Write`/`CAS…`, `quantile` label) - the headline latency KPI. | | `cassandra_clientrequest_latency_count_total` | Coordinator request count per `scope`; its rate is read/write throughput. | | `cassandra_clientrequest_timeouts_count_total` | Requests that timed out - client-facing errors per `scope`. | | `cassandra_clientrequest_unavailables_count_total` | Requests that failed for insufficient replicas - client-facing errors per `scope`. | | `cassandra_clientrequest_failures_count_total` | Requests that errored - client-facing errors per `scope`. | The error rate is the rate of the `timeouts` / `unavailables` / `failures` `_count_total` counters per `scope`. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `cassandra_compaction_pendingtasks` | Queued compactions; rising means compaction is falling behind and read amplification grows. | | `cassandra_threadpool_pendingtasks` | Queued tasks per internal pool (`path`, `pool`) - backpressure on a stage. | | `cassandra_threadpool_currentlyblockedtasks_count_total` | Tasks blocked because a pool queue was full (saturation). | | `cassandra_droppedmessage_dropped_count_total` | Messages dropped under overload, per `verb` (mutation/read/…). | | `cassandra_commitlog_pendingtasks` | Pending commit-log tasks - write-path backpressure. | | `cassandra_storage_load_count_total` | Live data size on this node (capacity and balance). | | `cassandra_storage_exceptions_count_total` | Unhandled storage exceptions. | | `cassandra_cache_hitrate` | Key / row / counter cache hit rate per `cache` - read efficiency. | | `cassandra_table_livediskspaceused` | Live disk used per table (`keyspace`, `table`). | | `cassandra_table_pendingflushes` | Memtable flushes queued per table - write-path backlog. | | `jvm_memory_used_bytes` | JVM heap / non-heap used per `area`; heap pressure drives GC, which drives latency. | | `jvm_gc_collection_seconds` | GC collection time per collector (`gc`) - pause pressure. | #### Diagnostic - for investigation and tuning Higher cardinality; enable on demand. The two large per-table and per-keyspace families dominate this tier - in production you can drop it with `metric_relabel_configs` and keep Core + Operational (see [Filtering Metrics](#filtering-metrics)). | Group | Metrics | When you reach for it | |---|---|---| | Per-table internals | `cassandra_table_*` (119; `keyspace`, `table`) | Read/write latency, bloom filter, SSTable counts, tombstones, partition sizes, and repair, per table. | | Per-keyspace rollups | `cassandra_keyspace_*` (84; `keyspace`) | Keyspace-level rollups of the table metrics. | | Client-request detail | `cassandra_clientrequest_*` (rest; `scope`) | CAS/paxos, view-write, speculative-retry, contention, and request-size histograms. | | CQL statements | `cassandra_cql_*` (10) | Prepared vs regular statement counts and prepared-statement cache. | | Cache / commit-log / compaction detail | `cassandra_cache_*` (rest), `cassandra_commitlog_*`, `cassandra_compaction_*` (rest) | Cache size/entries, commit-log size, compaction bytes and throughput. | | JVM internals | `jvm_*` (rest, ~28) | Memory pools, buffer pools, classes, and threads. | Full metric list: run `curl -s http://localhost:9404/metrics` against a Cassandra node with the exporter agent loaded. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `up` | - | `== 0` for > 1m | JMX endpoint unreachable - node down, agent off, or network. Check the process and `:9404`. | | `cassandra_clientrequest_latency_seconds{scope="Read"/"Write"}` (p99) | Rising vs baseline | Sustained regression | Coordinator latency climbing; check GC, compaction backlog, disk, and replica health. | | `rate(cassandra_clientrequest_timeouts_count_total)` / `unavailables` / `failures` | > 0 | Rising | Requests failing client-side; check replica availability, consistency level, and node health. | | `cassandra_compaction_pendingtasks` | Rising vs baseline | Sustained growth | Compactions queueing; read amplification and disk grow. Check compaction throughput and IO. | | `rate(cassandra_droppedmessage_dropped_count_total)` | > 0 | Sustained > 0 | Node overloaded and shedding work. Reduce load or scale out. | | `cassandra_threadpool_pendingtasks` / `currentlyblockedtasks_count_total` | Rising | Sustained growth | An internal stage is backed up; identify the pool and its bottleneck. | | `rate(jvm_gc_collection_seconds_sum)` / `jvm_memory_used_bytes` | Elevated | Near `jvm_memory_max_bytes` | Heap pressure causing GC pauses → latency. Tune heap / GC or add capacity. | ### Access Setup The Prometheus JMX exporter runs as a Java agent inside the Cassandra process. No authentication is required - the agent reads JMX MBeans directly from within the JVM, so there is no remote JMX connection to secure. #### 1. Download the JMX exporter agent ```bash showLineNumbers title="Download the agent JAR" curl -L -o jmx_prometheus_javaagent.jar \ https://github.com/prometheus/jmx_exporter/releases/download/1.5.0/jmx_prometheus_javaagent-1.5.0.jar ``` #### 2. Create the exporter configuration The exporter uses pattern rules to select JMX MBeans and shape them into Prometheus metrics - these rules are what produce the metric names in [What You'll Monitor](#what-youll-monitor). This config maps the ClientRequest and Table latency timers to percentiles via a `quantile` label in `_seconds`, types the counts as counters (so they get the `_total` suffix), and relies on the agent's built-in JVM collector for the standard `jvm_*` names. ```yaml showLineNumbers title="jmx-config.yaml" lowercaseOutputName: true lowercaseOutputLabelNames: true rules: # --- ClientRequest timers: latency percentiles -> quantile label --- - pattern: org.apache.cassandra.metrics<>(\d+)thPercentile name: cassandra_clientrequest_$2_seconds labels: scope: "$1" quantile: "0.$3" type: GAUGE valueFactor: 0.000001 # --- ClientRequest timers/counters: total count (monotonic) --- - pattern: org.apache.cassandra.metrics<>Count name: cassandra_clientrequest_$2_count labels: scope: "$1" type: COUNTER # --- ClientRequest timers: one-minute rate --- - pattern: org.apache.cassandra.metrics<>OneMinuteRate name: cassandra_clientrequest_$2_oneminuterate labels: scope: "$1" type: GAUGE # --- Table read/write latency timers: percentiles -> quantile label --- - pattern: org.apache.cassandra.metrics<>(\d+)thPercentile name: cassandra_table_$3_seconds labels: keyspace: "$1" table: "$2" quantile: "0.$4" type: GAUGE valueFactor: 0.000001 # --- Table counters/gauges (disk, partitions, tombstones, ...) --- - pattern: org.apache.cassandra.metrics<>(Count|Value) name: cassandra_table_$3 labels: keyspace: "$1" table: "$2" type: GAUGE # --- Keyspace counters/gauges --- - pattern: org.apache.cassandra.metrics<>(Count|Value) name: cassandra_keyspace_$2 labels: keyspace: "$1" type: GAUGE # --- ThreadPool: pending/active/blocked gauges + total blocked counter --- - pattern: org.apache.cassandra.metrics<>Value name: cassandra_threadpool_$3 labels: path: "$1" pool: "$2" type: GAUGE - pattern: org.apache.cassandra.metrics<>Count name: cassandra_threadpool_$3_count labels: path: "$1" pool: "$2" type: COUNTER # --- Storage counters/gauges (load, hints, exceptions) --- - pattern: org.apache.cassandra.metrics<>Value name: cassandra_storage_$1 type: GAUGE - pattern: org.apache.cassandra.metrics<>Count name: cassandra_storage_$1_count type: COUNTER # --- Compaction (pending gauge, completed counter) --- - pattern: org.apache.cassandra.metrics<>Value name: cassandra_compaction_$1 type: GAUGE - pattern: org.apache.cassandra.metrics<>Count name: cassandra_compaction_$1_count type: COUNTER # --- CommitLog (pending tasks gauge, completed counter) --- - pattern: org.apache.cassandra.metrics<>Value name: cassandra_commitlog_$1 type: GAUGE - pattern: org.apache.cassandra.metrics<>Count name: cassandra_commitlog_$1_count type: COUNTER # --- Cache (hit rate gauge, hits/requests counters) --- - pattern: org.apache.cassandra.metrics<>Value name: cassandra_cache_$2 labels: cache: "$1" type: GAUGE - pattern: org.apache.cassandra.metrics<>Count name: cassandra_cache_$2_count labels: cache: "$1" type: COUNTER # --- CQL (prepared/regular statement counters + ratio gauge) --- - pattern: org.apache.cassandra.metrics<>Value name: cassandra_cql_$1 type: GAUGE - pattern: org.apache.cassandra.metrics<>Count name: cassandra_cql_$1_count type: COUNTER # --- DroppedMessage (per-verb dropped counter) --- - pattern: org.apache.cassandra.metrics<>Count name: cassandra_droppedmessage_$2_count labels: verb: "$1" type: COUNTER # JVM metrics (jvm_memory_*, jvm_gc_collection_seconds_*, jvm_threads_*, # jvm_buffer_pool_*, jvm_classes_*) are emitted by the javaagent's built-in # JVM collector using standard names - no custom java.lang rules needed. ``` #### 3. Load the agent into Cassandra Attach the exporter as a Java agent on the Cassandra JVM, pointing it at the port and config from the previous steps. On a host install, add it to `JVM_OPTS` in `cassandra-env.sh`: ```bash showLineNumbers title="cassandra-env.sh" JVM_OPTS="$JVM_OPTS -javaagent:/path/to/jmx_prometheus_javaagent.jar=9404:/path/to/jmx-config.yaml" ``` For Docker, mount the JAR and config into the container and set `JVM_EXTRA_OPTS`: ```bash showLineNumbers title="container environment" JVM_EXTRA_OPTS="-javaagent:/opt/jmx_prometheus_javaagent.jar=9404:/opt/jmx-config.yaml" ``` Verify the endpoint serves metrics: ```bash showLineNumbers title="Verify exporter endpoint" # The exporter is publishing Prometheus metrics curl -s http://localhost:9404/metrics | head -20 # Cassandra-specific series are present curl -s http://localhost:9404/metrics | grep cassandra_clientrequest_latency ``` ### Configuration The native `prometheus` receiver scrapes the exporter endpoint. It also supplies the `up` target-health metric (`1` when the scrape succeeds), which is the Core liveness signal for this path. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: cassandra scrape_interval: 30s static_configs: - targets: - ${env:CASSANDRA_HOST}:9404 # Cassandra host running the exporter processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" CASSANDRA_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Filtering Metrics The `cassandra_table_*` (119) and `cassandra_keyspace_*` (84) families are per-table and per-keyspace, so they grow with your schema and are the main cardinality cost. In production, drop the Diagnostic tier at the scrape with `metric_relabel_configs` and keep Core + Operational: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" receivers: prometheus: config: scrape_configs: - job_name: cassandra scrape_interval: 30s static_configs: - targets: - ${env:CASSANDRA_HOST}:9404 metric_relabel_configs: # Drop the high-cardinality per-table / per-keyspace families - source_labels: [__name__] regex: "cassandra_(table|keyspace)_.*" action: drop ``` To go the other way and keep only the Core + Operational series, swap the `drop` for a `keep` on an allow-list of the prefixes you alert on (`cassandra_clientrequest_.*`, `cassandra_compaction_.*`, `cassandra_threadpool_.*`, `cassandra_storage_.*`, `cassandra_cache_.*`, `cassandra_commitlog_.*`, `cassandra_droppedmessage_.*`, `jvm_.*`, `up`). ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Collector is scraping the Cassandra exporter docker logs otel-collector 2>&1 | grep -i "cassandra" # The exporter is serving Cassandra series curl -s http://localhost:9404/metrics | grep cassandra_clientrequest_latency # Generate read/write traffic so the latency and throughput series advance cqlsh -e "SELECT * FROM system.local;" ``` ### Troubleshooting #### Metrics endpoint not responding on port 9404 **Cause**: The JMX exporter agent did not load, or the port is wrong. **Fix**: 1. Confirm the `-javaagent` flag is on the Cassandra JVM: `ps aux | grep javaagent`. 2. Check that the port in the agent argument matches the Collector scrape target. 3. Check the Cassandra logs for agent startup errors. #### Only JVM metrics appear, no Cassandra metrics **Cause**: The exporter rules in `jmx-config.yaml` are not matching the Cassandra MBeans, so only the agent's built-in `jvm_*` collector is emitting. **Fix**: 1. Verify `jmx-config.yaml` has the `org.apache.cassandra.metrics` patterns and that the file path in the `-javaagent` argument is correct. 2. Check for typos in the pattern regexes. 3. Confirm Cassandra has finished starting - MBeans register late in boot. #### Read or write latency is climbing **Cause**: Coordinator latency is dominated by GC pauses, compaction backlog, or slow replicas. **Look at**: the Diagnostic `jvm_*` internals alongside Operational `jvm_gc_collection_seconds` and `jvm_memory_used_bytes` for heap and GC pressure; `cassandra_compaction_pendingtasks` for compaction backlog; and the per-table `cassandra_table_*` latency series to find the hot table. **Fix**: 1. If GC time is high, tune the heap / collector or add capacity. 2. If compaction is behind, raise compaction throughput or IO headroom. 3. Inspect replica health and consistency level if a single replica is slow. #### High metric cardinality **Cause**: The per-table `cassandra_table_*` and per-keyspace `cassandra_keyspace_*` families create many time series in clusters with many tables. **Look at**: the count of `cassandra_table_*` and `cassandra_keyspace_*` series in `curl -s http://localhost:9404/metrics`. **Fix**: 1. Drop the Diagnostic tier with `metric_relabel_configs` (see [Filtering Metrics](#filtering-metrics)). 2. Exclude system keyspaces by adding a relabel rule on the `keyspace` label. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why use the JMX exporter instead of the OTel JMX receiver? The OTel JMX receiver was deprecated in January 2026. It required a JRE inside the Collector container and collected only a limited set of Cassandra metrics over a remote JMX connection. The Prometheus JMX exporter runs inside Cassandra's JVM, needs no external JRE, and exposes the full MBean set as Prometheus metrics on a local HTTP endpoint. #### How do I monitor a multi-node Cassandra cluster? Each Cassandra node runs its own exporter agent. Add all node endpoints to the scrape config: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-node)" receivers: prometheus: config: scrape_configs: - job_name: cassandra static_configs: - targets: - cassandra-1:9404 - cassandra-2:9404 - cassandra-3:9404 ``` Each node is scraped independently and identified by its `instance` label. #### Does this work with Cassandra running in Kubernetes? Yes. Mount the exporter JAR and `jmx-config.yaml` into the Cassandra pod via a ConfigMap or init container, and add the `-javaagent` argument to the JVM options. Set `targets` to the pod or service DNS (for example `cassandra-0.cassandra.default.svc.cluster.local:9404`). The Collector can run as a sidecar or DaemonSet. #### Why is request latency a Summary with a `quantile` label? The exporter rules map each ClientRequest latency percentile MBean attribute to a `quantile` label on `cassandra_clientrequest_latency_seconds` (in seconds, via `valueFactor`). Read the p99 with `cassandra_clientrequest_latency_seconds{scope="Read",quantile="0.99"}`. #### Why do counter metrics have a `_count_total` suffix? The exporter types request and error counts as Prometheus counters, and the COUNTER type adds the `_total` suffix - so a coordinator request count appears as `cassandra_clientrequest_latency_count_total`. Compute throughput and error rate as `rate()` over these counters. ### Related Guides - [JMX Metrics Collection Guide](../collector-setup/jmx-metrics-collection-guide.md) - Choose between the JMX scraper and the JMX exporter. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Cassandra metrics. - [MongoDB Monitoring](./mongodb.md) - Another distributed database to put on Scout. - [Redis Monitoring](./redis.md) - A common companion data store. - [PostgreSQL Monitoring](./postgres.md) - Relational database monitoring. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [MongoDB](./mongodb.md), [Redis](./redis.md), [PostgreSQL](./postgres.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## ClickHouse OpenTelemetry Monitoring - Query Throughput, Merges, and Collector Setup ## ClickHouse ClickHouse serves its own metrics in Prometheus format at `:9363/metrics` when the `` section is enabled in the server config - no exporter and no JMX agent. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint and ships the metrics to base14 Scout. The endpoint exposes roughly 3300 metrics across query throughput, merge and parts health, connections, memory allocation, disk and host capacity, and replication, on ClickHouse 22.x+. This guide enables the endpoint, configures the receiver, bounds the volume, and verifies the flow. ClickHouse defines the metric names; the receiver passes them through verbatim. The counters keep their `ClickHouse...` names with **no `_total` suffix added**, even though the `ProfileEvents` family is typed as `counter`. Reproduce the names exactly as the endpoint emits them. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ---------------- | | ClickHouse | 22.x | 24.x+ (26.5.1) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - ClickHouse running, with the `` config section enabled (it is not on by default). See [Access Setup](#access-setup). - The metrics port (`9363`) reachable from the host running the Collector. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The endpoint emits four metric families - `ClickHouseProfileEvents_*` (cumulative counters), `ClickHouseMetrics_*` (point-in-time gauges), `ClickHouseAsyncMetrics_*` (periodically computed gauges), and `ClickHouseHistogramMetrics_*` - plus the receiver's own `up` target-health gauge. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - ClickHouse's metrics endpoint is reachable. This is the liveness signal the `prometheus` receiver supplies (`1` = scrape succeeded). | | `ClickHouseProfileEvents_Query` | Total queries executed; the rate is the query-throughput KPI. | | `ClickHouseProfileEvents_FailedQuery` | Queries that failed; `rate(FailedQuery) / rate(Query)` is the error rate. | | `ClickHouseProfileEvents_QueryTimeMicroseconds` | Cumulative query time in microseconds; divide its rate by the query rate for mean query latency. | | `ClickHouseMetrics_Query` | Queries currently executing - concurrency and query-path saturation. | Query latency here is a **mean only**: `rate(QueryTimeMicroseconds) / rate(Query)` in microseconds. ClickHouse's `/metrics` endpoint exposes no query-latency percentile or histogram, so do not expect one - for per-query timing reach for `system.query_log` or your trace path. #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Query mix | `ClickHouseProfileEvents_SelectQuery`, `_InsertQuery` | Read vs write query mix. | | Data volume | `ClickHouseProfileEvents_SelectedRows`, `_InsertedRows` | Rows read and written - data-plane volume. | | Merge / parts health | `ClickHouseMetrics_Merge`, `ClickHouseMetrics_PartMutation`, `ClickHouseMetrics_PartsActive`, `ClickHouseMetrics_BackgroundMergesAndMutationsPoolTask` | Active merges and mutations, active parts ("too many parts" when rising), and background pool backlog. | | Memory pressure | `ClickHouseMetrics_MemoryTracking`, `ClickHouseProfileEvents_QueryMemoryLimitExceeded` | Server-tracked memory in use, and queries killed for exceeding the memory limit. | | Connections | `ClickHouseMetrics_TCPConnection`, `_HTTPConnection` | Active client connections. | | Replication | `ClickHouseMetrics_ReadonlyReplica`, `ClickHouseAsyncMetrics_ReplicasMaxAbsoluteDelay` | Replicas stuck read-only, and the worst replica replication delay. | | Disk / host capacity | `ClickHouseAsyncMetrics_FilesystemMainPathAvailableBytes`, `ClickHouseAsyncMetrics_OSMemoryAvailable`, `ClickHouseAsyncMetrics_LoadAverage1` | Free space on the main data path, host memory available, and 1-minute load. | #### Diagnostic - for investigation and tuning The four metric families in full - higher cardinality, pulled during an incident or for a specific subsystem, not paged on. The per-disk `Block*` and per-CPU `AsyncMetrics` series are the main cardinality source; in production you can drop this tier with `metric_relabel_configs`, keeping Core and Operational (see [Filtering Metrics](#filtering-metrics)). | Family | Count | When you reach for it | |---|---|---| | `ClickHouseProfileEvents_*` | 1250, cumulative counters | All event counters: I/O, cache, network, ZooKeeper, S3, throttling. | | `ClickHouseMetrics_*` | 480, point-in-time gauges | Locks, threads, per-pool sizes, in-flight operations. | | `ClickHouseAsyncMetrics_*` | 876, periodically-computed gauges | Per-disk `Block*`, per-CPU, jemalloc, filesystem, uptime. | | `ClickHouseHistogramMetrics_*` | 45, histograms | Latency histograms (Keeper response time, HTTP pool buffers). | Full metric reference: run `curl -s http://localhost:9363/metrics` against your instance with the endpoint enabled. ### Key Alerts to Configure Threshold guidance for the Core and Operational series. All thresholds here are relative to your own baseline - ClickHouse signal levels are workload-dependent, so alert on a rise against the steady state, not an invented absolute. Tune to your workload; these are starting points. | Alert | Threshold | Why it matters | |---|---|---| | ClickHouse down | `up == 0` for > 1m | Metrics endpoint unreachable - server down, `` off, or network. Check the process and `:9363`. | | Query failure rate | `rate(ClickHouseProfileEvents_FailedQuery) / rate(ClickHouseProfileEvents_Query)` rising vs baseline | Queries erroring; check logs, schema, and resource limits. | | Query latency regression | `rate(ClickHouseProfileEvents_QueryTimeMicroseconds) / rate(ClickHouseProfileEvents_Query)` rising vs baseline | Mean query time climbing; check merges, memory, disk, and query patterns. | | Too many parts | `ClickHouseMetrics_PartsActive` rising vs baseline | Merges falling behind inserts; INSERTs will eventually be throttled or rejected. Slow the insert rate or raise merge throughput. | | Merge / mutation backlog | `ClickHouseMetrics_Merge` or `ClickHouseMetrics_BackgroundMergesAndMutationsPoolTask` sustained high | Background work queueing; check IO and pool sizing. | | Memory pressure | `ClickHouseMetrics_MemoryTracking` near the server limit, or `rate(ClickHouseProfileEvents_QueryMemoryLimitExceeded) > 0` | Memory-bound; tune `max_memory_usage` / per-query limits or add capacity. | | Replication unhealthy | `ClickHouseMetrics_ReadonlyReplica > 0` or `ClickHouseAsyncMetrics_ReplicasMaxAbsoluteDelay` rising | Replica read-only or lagging; check ZooKeeper / Keeper and replica health. | | Disk low | `ClickHouseAsyncMetrics_FilesystemMainPathAvailableBytes` approaching 0 | Data path filling; free space or add storage before writes fail. | ### Access Setup ClickHouse exposes the metrics endpoint natively - there is no exporter to run. Enable it by adding a `` section to the server config. Drop a config override file into `/etc/clickhouse-server/config.d/`: ```xml showLineNumbers title="config.d/clickhouse-prometheus.xml" /metrics 9363 true true true true ``` The four flags control which families are served: - `metrics` - current server gauges (`ClickHouseMetrics_*`: active queries, connections, merge pool tasks). - `events` - cumulative event counters (`ClickHouseProfileEvents_*`: queries executed, bytes read and written, merge operations). - `asynchronous_metrics` - periodically computed system metrics (`ClickHouseAsyncMetrics_*`: memory, CPU, disk, uptime). - `status_info` - dictionary status. This emits no series until dictionaries are loaded, so on a server with none configured it adds nothing - leave it on; it costs nothing when idle. For Docker, mount the file into `/etc/clickhouse-server/config.d/`. Restart ClickHouse after adding it. The metrics endpoint requires no authentication by default. Restrict access to port `9363` at the network layer (firewall, security group, or NetworkPolicy) in production. Verify the endpoint is up: ```bash showLineNumbers title="Verify access" # Check ClickHouse is serving curl -s http://localhost:8123/ping # Confirm the metrics endpoint curl -s http://localhost:9363/metrics | head -20 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: clickhouse scrape_interval: 15s static_configs: - targets: - ${env:CLICKHOUSE_HOST}:9363 # Your ClickHouse host processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" CLICKHOUSE_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Filtering Metrics ClickHouse emits roughly 3300 metrics per scrape. The `ClickHouseAsyncMetrics_*` per-disk `Block*` and per-CPU series are the main cardinality source. To bound what reaches Scout, add a `metric_relabel_configs` `keep` block that whitelists the Core and Operational names this doc tiers and drops the rest: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" receivers: prometheus: config: scrape_configs: - job_name: clickhouse scrape_interval: 15s static_configs: - targets: - ${env:CLICKHOUSE_HOST}:9363 metric_relabel_configs: - source_labels: [__name__] regex: "up|ClickHouseProfileEvents_(Query|FailedQuery|QueryTimeMicroseconds|SelectQuery|InsertQuery|SelectedRows|InsertedRows|QueryMemoryLimitExceeded)|ClickHouseMetrics_(Query|Merge|PartMutation|PartsActive|BackgroundMergesAndMutationsPoolTask|MemoryTracking|TCPConnection|HTTPConnection|ReadonlyReplica)|ClickHouseAsyncMetrics_(ReplicasMaxAbsoluteDelay|FilesystemMainPathAvailableBytes|OSMemoryAvailable|LoadAverage1)" action: keep ``` This keeps liveness, the RED query signals, merge and parts health, memory, connections, replication, and disk/host capacity, while excluding the high-cardinality per-disk and per-CPU Diagnostic families. Widen the regex to add any Diagnostic series you want to keep on hand. ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for a successful clickhouse scrape docker logs otel-collector 2>&1 | grep -i "clickhouse" # Confirm ClickHouse is serving curl -s http://localhost:8123/ping # Check a Core metric directly on the endpoint curl -s http://localhost:9363/metrics | grep ClickHouseProfileEvents_Query ``` To advance the query, merge, and parts signals, run some traffic: create a MergeTree table, insert rows, run a few aggregate `SELECT`s, and `OPTIMIZE ... FINAL`. ### Troubleshooting #### Metrics endpoint not responding on port 9363 **Cause**: The `` section is not enabled in the ClickHouse server config. **Fix**: 1. Add the config override file to `config.d/` with the `` block (see [Access Setup](#access-setup)). 2. Restart ClickHouse: `systemctl restart clickhouse-server` or `docker restart clickhouse`. 3. Verify: `curl http://localhost:9363/metrics`. #### Only some metric families appear **Cause**: One or more of the four flags is `false`, so that family is not served. **Fix**: 1. Set all four to `true`: `metrics`, `events`, `asynchronous_metrics`, `status_info`. 2. Restart ClickHouse after the change. 3. Count what is served: `curl -s http://localhost:9363/metrics | grep -c "^# TYPE"`. Note that `status_info` legitimately emits nothing until dictionaries are loaded - an empty `status_info` is expected on a server with no dictionaries. #### Inserts are throttled or rejected ("too many parts") **Cause**: Background merges are falling behind the insert rate, so active parts pile up. **Look at**: `ClickHouseMetrics_PartsActive` (rising = parts accumulating), `ClickHouseMetrics_Merge`, and `ClickHouseMetrics_BackgroundMergesAndMutationsPoolTask`; the Diagnostic `ClickHouseProfileEvents_*` I/O counters show whether merges are IO-bound. **Fix**: 1. Slow the insert rate or batch inserts into fewer, larger blocks. 2. Raise merge throughput / background pool sizing if IO headroom allows. #### Mean query latency is climbing **Cause**: Memory pressure, merge backlog, slow disk, or a query-pattern change. **Look at**: `ClickHouseMetrics_MemoryTracking` and the Diagnostic `ClickHouseProfileEvents_*` I/O and cache counters, alongside `ClickHouseAsyncMetrics_FilesystemMainPathAvailableBytes`. Remember latency here is a rate-derived mean, not a percentile. **Fix**: 1. Check for memory pressure and merge backlog first (Operational tier). 2. Inspect `system.query_log` for the slow query shapes - the percentile detail lives there, not on `/metrics`. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why do the counters have no `_total` suffix? ClickHouse defines the metric names and the `prometheus` receiver passes them through verbatim. The `ClickHouseProfileEvents_*` family is typed as `counter`, but the receiver does not append a `_total` suffix - the names stay exactly as ClickHouse emits them (`ClickHouseProfileEvents_Query`, not `..._Query_total`). Rate them as counters; just use the literal names. #### How do I bound the ~3300-metric volume? Add a `metric_relabel_configs` `keep` block to the scrape config that whitelists the Core and Operational names (see [Filtering Metrics](#filtering-metrics)). The `ClickHouseAsyncMetrics_*` per-disk `Block*` and per-CPU series are the main cardinality source, so dropping the Diagnostic families is where most of the volume reduction comes from. #### How do I monitor a multi-node ClickHouse cluster? Each node serves its own `:9363/metrics` endpoint. Add one scrape target per server: ```yaml showLineNumbers title="config/otel-collector.yaml (cluster)" receivers: prometheus: config: scrape_configs: - job_name: clickhouse static_configs: - targets: - clickhouse-shard1-replica1:9363 - clickhouse-shard1-replica2:9363 - clickhouse-shard2-replica1:9363 ``` Each node is scraped independently and identified by its `instance` label. #### Does this work with ClickHouse running in Kubernetes? Yes. Set `targets` to the pod or service DNS on `:9363` (e.g., `clickhouse-0.clickhouse.default.svc.cluster.local:9363`). Mount the `` config override via a ConfigMap into `/etc/clickhouse-server/config.d/`. The Collector can run as a sidecar or a deployment. #### Why is there no query-latency percentile? The `/metrics` endpoint exposes query time only as a cumulative counter (`ClickHouseProfileEvents_QueryTimeMicroseconds`), so the latency you get is a mean: `rate(QueryTimeMicroseconds) / rate(Query)`. For percentiles and per-query detail, query `system.query_log`. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on ClickHouse metrics. - [Cassandra Monitoring](./cassandra.md) - Another wide-column store to watch for compaction and read/write latency. - [PostgreSQL Monitoring](./postgres.md) - A common transactional source feeding ClickHouse. - [Redis Monitoring](./redis.md) - A common cache in front of analytics queries. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [Cassandra](./cassandra.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## CockroachDB OpenTelemetry Monitoring - Node Liveness, Range Health, and Collector Setup ## CockroachDB CockroachDB is distributed, PostgreSQL-wire-compatible SQL, so if you already run the [PostgreSQL receiver](./postgres.md) you know most of the SQL-layer signals here. What you do not have a PostgreSQL analogue for is the distributed machinery: node liveness, range replication health, and clock offset. Those are the signals that page you when a multi-node cluster degrades, and they are the reason this is a separate guide. Each node exposes them in Prometheus format on its HTTP port `8080`. CockroachDB serves two Prometheus-compatible endpoints, `/_status/vars` and a newer `/metrics` (in preview). This guide scrapes `/_status/vars` because the per-operation names below (for example `sql_select_count`) come from it, whereas `/metrics` consolidates them under labels. There is no native CockroachDB receiver and no `pg_stat` views in play - the OpenTelemetry Collector's `prometheus` receiver scrapes each node's endpoint directly. CockroachDB emits 2,400+ distinct metric names this way (`sql_*`, `liveness_*`, `ranges*`, `capacity_*`, `clock_offset_*`, and large internal families), all un-prefixed and multi-namespaced. This guide configures the receiver and ships the metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | CockroachDB | 23.1 | 26.2+ | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | — | Before starting: - Each CockroachDB node's HTTP port (`8080`) must be reachable from the host running the Collector. - No SQL monitoring user is required - the Prometheus endpoint is plain HTTP (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Every series carries a `node_id` label; range and capacity series also carry `store`. The tiers below lead with the distributed signals that have no PostgreSQL counterpart - liveness, range replication, and clock health - then cover the familiar SQL throughput and latency series. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `liveness_livenodes` | Live nodes the cluster sees; equals the node count when healthy. Distributed signal with no PostgreSQL analogue. | | `sql_query_count` | Total SQL queries served - the headline throughput KPI. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `liveness_heartbeatfailures` | Failed node-liveness heartbeats; rising means a node is struggling to stay in the cluster. Distributed signal. | | `ranges_underreplicated` | Ranges below their replication target; should sit at 0 in a healthy cluster. Distributed signal. | | `ranges_unavailable` | Ranges with no quorum; greater than 0 means data is unavailable. Distributed signal. | | `clock_offset_meannanos` | Mean clock offset versus peers; a node self-terminates once its offset against a majority of peers passes ~80% of the cluster max-offset (≈400ms at the 500ms default). Distributed signal. | | `sql_query_count` | Throughput; a sustained drop toward 0 under expected load means SQL serving stalled. | | `sql_service_latency` | SQL service latency distribution (histogram) - the latency SLI. | | `sql_conns` | Open SQL connections - a saturation signal. | | `capacity_available` | Available store capacity per node. | #### Diagnostic - for investigation and tuning Higher cardinality - per-statement throughput, transaction internals, replication queues, and the large engine families. Enable on demand; in production you can drop this tier with a `metric_relabel_configs` block while keeping Core + Operational. | Metric | What it tells you | |---|---| | `sql_select_count`, `sql_insert_count`, `sql_update_count`, `sql_delete_count` | Per-statement throughput by operation. | | `sql_txn_begin_count`, `sql_txn_commit_count`, `sql_txn_abort_count` | Transaction outcomes; aborts signal contention or app errors. | | `sql_txn_latency`, `sql_exec_latency` | Transaction and execution latency distributions. | | `sql_distsql_queries_active`, `sql_failure_count`, `sql_new_conns` | Distributed-SQL activity, failed statements, new-connection rate. | | `ranges`, `ranges_overreplicated`, `replicas`, `replicas_leaders`, `replicas_leaseholders` | Replication and lease placement across stores. | | `leases_success`, `leases_error`, `range_splits`, `rebalancing_queriespersecond` | Lease transfers, range splits, and rebalancing pressure. | | `sys_cpu_combined_percent_normalized`, `sys_rss`, `sys_uptime` | Per-node CPU, memory, and uptime. | | `capacity_used`, `liveness_heartbeatlatency` | Store fill and heartbeat round-trip time. | The long diagnostic tail groups into internal families: `admission_*` (409 names, CPU/IO/KV admission control), `jobs_*` (381, background jobs), `sql_*` (291, the full SQL layer), `storage_*` (182, storage engine), `distsender_*` (142, DistSender RPC batches), `kv_*` (113), `queue_*` (108, replica queues), `changefeed_*` (88, CDC), `raft_*` (70, consensus), `rpc_*` (68), `sys_*` (58), `txn_*` (46, transaction coordinator), `schedules_*` (23), `rocksdb_*` (17, Pebble/RocksDB), and `tenant_*` (13, multi-tenancy). Each `sql_*` user-facing counter also has a `_internal` sibling (for example `sql_query_count_internal`) covering CockroachDB's own internal queries. Full metric reference: [CockroachDB monitoring and alerting](https://www.cockroachlabs.com/docs/stable/monitoring-and-alerting), or `curl -s http://localhost:8080/_status/vars` against any node. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. Tune to your workload and cluster size; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `liveness_livenodes` | < node count | Falling further | A node is down or partitioned; investigate the missing node before quorum is at risk. | | `rate(sql_query_count)` | Dipping vs baseline | ≈ 0 sustained under expected load | SQL serving has stalled; check the SQL layer and node health. | | `ranges_underreplicated` | > 0 | > 0 sustained | Replication is not converging; the cluster cannot restore the replication target. | | `ranges_unavailable` | > 0 | > 0 | Data is unavailable - one or more ranges lost quorum. | | `clock_offset_meannanos` | > 40% of `--max-offset` | ≈ 80% of `--max-offset` (≈400ms / 4e8 ns at default) | Clock skew risk; a node self-terminates when its offset against a majority of peers exceeds ~80% of `--max-offset`. | | `capacity_available` | Falling toward a floor | < a small fraction of `capacity_available + capacity_used` | The store is filling; scale storage before writes start failing. | ### Access Setup CockroachDB needs no SQL monitoring user for metrics. Unlike the PostgreSQL receiver - which connects over the SQL wire protocol with a `pg_monitor`-role account - CockroachDB's `prometheus` endpoint is plain HTTP. "Access setup" here means exposing each node's HTTP port (`8080`) to the Collector. Every node serves its own metrics, so the Collector scrapes each node, not a single load-balanced endpoint - the per-node `node_id` series is exactly what the liveness and range tiers depend on. ```yaml showLineNumbers title="docker-compose.yaml (excerpt)" services: roach1: image: cockroachdb/cockroach:v26.2.2 command: start --join=roach1,roach2,roach3 --advertise-addr=roach1 ports: - "8080:8080" # DB Console + /_status/vars - "26257:26257" # SQL roach2: image: cockroachdb/cockroach:v26.2.2 command: start --join=roach1,roach2,roach3 --advertise-addr=roach2 roach3: image: cockroachdb/cockroach:v26.2.2 command: start --join=roach1,roach2,roach3 --advertise-addr=roach3 ``` On a secure cluster (`--certs-dir`), the HTTP endpoint serves over `https`. Expose it to the Collector over a trusted network path - the metrics carry no secrets, but the endpoint should not be public. The scrape config below uses `http`; switch the scheme to `https` and supply `tls` settings when the cluster is secure. Verify the endpoint serves metrics: ```bash showLineNumbers title="Verify access" # Each node exposes its own metrics at /_status/vars on port 8080 curl -s http://localhost:8080/_status/vars | grep -E '^liveness_livenodes|^sql_query_count' ``` ### Configuration CockroachDB serves metrics at the non-default `/_status/vars` path, so set `metrics_path` explicitly and list every node as a scrape target. Each node returns its own series, tagged with `node_id`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: cockroachdb scrape_interval: 15s metrics_path: /_status/vars # Not the default /metrics static_configs: - targets: - roach1:8080 # Each CockroachDB node's HTTP port - roach2:8080 - roach3:8080 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` CockroachDB's `/_status/vars` is whitelist-free - the receiver delivers the full 2,400+ metric surface with no filter. To control metric volume in production, drop the Diagnostic tier with a `metric_relabel_configs` block on the scrape config while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped CockroachDB metrics docker logs otel-collector 2>&1 | grep -iE "sql_query_count|liveness_livenodes" # Confirm a node is serving metrics on its HTTP endpoint curl -s http://localhost:8080/_status/vars | grep -E '^sql_query_count' ``` Several SQL counters only move once the cluster does work. Drive some load and confirm `sql_query_count` rises and `liveness_livenodes` equals your node count: ```bash showLineNumbers title="Generate SQL load" # Built-in kv load generator against the cluster (~40 reads/s, ~10 writes/s) cockroach workload init kv "postgresql://root@localhost:26257?sslmode=disable" cockroach workload run kv --max-rate=50 --read-percent=80 \ "postgresql://root@localhost:26257?sslmode=disable" ``` The load generator connects over the SQL port (`26257`); on a secure cluster supply certs and use the secure SQL endpoint. This is separate from the cert-free metrics scrape on port `8080`. ### Troubleshooting #### No CockroachDB metrics in the Collector **Cause**: The Collector cannot reach a node's HTTP endpoint, or the scrape path is wrong. **Fix**: 1. Confirm the nodes are running and joined: `cockroach node status`. 2. Verify each target's host and port (`8080`) match the scrape config. 3. Confirm `metrics_path` is set to `/_status/vars`. The receiver defaults to `/metrics`; CockroachDB also serves `/metrics`, but with different, label-based metric names, so the default scrapes a surface that does not match the tiers in this guide. #### Metric name present but no datapoints **Cause**: The cluster is idle, so the SQL counters have not moved since the last scrape. **Look at**: `sql_query_count` (should rise under load) and `sql_conns` (open connections). `liveness_livenodes` should equal your node count even when idle. **Fix**: 1. Run SQL against the cluster - the built-in `cockroach workload run kv` generator is the quickest way - and re-check. #### A node dropped out of the cluster **Cause**: A node failed its liveness heartbeats or self-terminated on clock skew. **Look at**: `liveness_heartbeatfailures` (rising means a node is struggling to stay live) and the Diagnostic `liveness_heartbeatlatency` for the heartbeat round-trip. `clock_offset_meannanos` approaching the cluster max-offset means the node will remove itself to preserve consistency - check NTP/chrony on that host. **Fix**: 1. Restore network reachability or restart the node, then confirm `liveness_livenodes` returns to the node count. 2. Fix clock sync on the affected host if `clock_offset_meannanos` is high. #### Ranges stay under-replicated or unavailable **Cause**: A node is down long enough that replicas cannot meet the replication target, or a range has lost quorum. **Look at**: `ranges_underreplicated` (not converging back to 0) and `ranges_unavailable` (greater than 0 means data is unavailable). The Diagnostic `replicas_leaseholders`, `leases_error`, and `rebalancing_queriespersecond` show whether the cluster is actively re-replicating. **Fix**: 1. Bring the missing node back or add capacity so the cluster can restore the replication target. 2. If `ranges_unavailable` is greater than 0, recover or replace the nodes holding the affected ranges - quorum must be restored before the data is readable. #### No metrics appearing in Scout **Cause**: Metrics are scraped but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `prometheus` receiver and the `otlphttp/b14` exporter. ### FAQ #### Which port and path does CockroachDB use for metrics? Each node serves Prometheus-format metrics on its HTTP port `8080`. CockroachDB exposes both `/_status/vars` and a newer `/metrics`; this guide uses `/_status/vars`, so set `metrics_path: /_status/vars` in the scrape job (the receiver would otherwise default to `/metrics`). No SQL login is involved - the endpoint is HTTP, not the SQL wire protocol. #### Do I need a monitoring user like the PostgreSQL `pg_monitor` role? No. Unlike the PostgreSQL receiver, which connects over the SQL wire protocol with a `pg_monitor`-role account, CockroachDB's Prometheus endpoint is plain HTTP and needs no SQL credentials. Access setup is exposing the HTTP port (`8080`) to the Collector. #### How do I monitor all the nodes in a cluster? Add every node's `host:8080` to the scrape job's `static_configs.targets`. Each node serves only its own series, tagged with `node_id`, so scraping each node is what makes the per-node liveness and range tiers work. Do not scrape a single load-balanced endpoint - you would lose per-node visibility. #### What does `liveness_livenodes` report in CockroachDB? The number of nodes the cluster currently considers live. In a healthy cluster it equals the total node count; a drop signals a node the cluster can no longer reach. PostgreSQL has no analogue - this is a distributed-cluster signal. #### Why monitor `clock_offset_meannanos` in CockroachDB? CockroachDB relies on loosely-synchronized clocks. If a node's offset against a majority of its peers exceeds ~80% of the cluster max-offset (≈400ms at the 500ms / 5e8 ns default), the node removes itself to preserve consistency. Tracking this metric warns you before that happens. ### Related Guides - [PostgreSQL Monitoring](./postgres.md) - The single-node PostgreSQL counterpart; the SQL-layer signals here mirror its receiver, and this guide is the distributed delta on it (liveness, ranges, clock offset). - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on node liveness and clock skew. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `metric_relabel_configs` block to control volume; keep it available for incident investigation. --- ## Consul OpenTelemetry Monitoring - Raft Consensus, Service Catalog, and Collector Setup ## Consul Consul serves Prometheus-format metrics at `/v1/agent/metrics?format=prometheus` on the HTTP API port `8500` once `prometheus_retention_time` is set in the agent telemetry config. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint directly, collecting 230+ metrics across Raft consensus, the service catalog, RPC, gossip and membership, the service mesh, and the Go runtime. This guide enables the endpoint, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Consul | 1.7.2 | 1.21+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The Consul HTTP API port (8500) must be reachable from the host running the Collector. - `prometheus_retention_time` must be set in the agent telemetry config (it is disabled by default - see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things about this surface before the tables: - **`up` is the liveness signal here.** Unlike native-receiver components, Consul is scraped as a Prometheus target, so the receiver emits a real `up` series - `up` = 1 when the scrape of `:8500` succeeds. `consul_autopilot_healthy` (1 = enough voters alive and reachable) is the headline cluster-health flag that sits next to it. - **`prometheus_retention_time` must be `> 0s`** in the agent telemetry config or the endpoint returns nothing - the default `0s` disables it. Set it to at least 2x the scrape interval. - **Some metrics are leader-only.** `consul_raft_leader_lastContact` and `consul_raft_leader_dispatchLog` are emitted only by the current leader; followers emit `consul_raft_state_follower` instead. Seeing these on one server and not the others is expected, not a gap. - **A double-prefix quirk affects the cache, FSM, and peering families.** They appear under both `consul_` and `consul_consul_` (for example `consul_cache_fetch_success` and `consul_consul_cache_fetch_success`). This is a Consul telemetry artifact, not a duplicate scrape; treat the pair as one family. #### Core - is the cluster up, quorate, and committing writes | Metric | What it tells you | |---|---| | `up` | Scrape liveness - 1 = the Consul agent metrics endpoint responded. The liveness signal on this surface. | | `consul_autopilot_healthy` | Cluster health per Autopilot - 1 = enough voters alive and reachable, 0 = degraded. The headline cluster-health flag. | | `consul_raft_peers` | Number of Raft peers (voting servers) the agent sees - the quorum picture. | | `consul_raft_commitTime` | Time to commit a Raft log entry (ms) - the write-path latency of the whole cluster. | | `consul_raft_leader_lastContact` | Time since the leader last contacted its followers (ms) - leader stability (leader-only). | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Leadership churn | `consul_raft_state_leader`, `consul_raft_state_candidate`, `consul_raft_state_follower` | Raft state transitions; `_candidate` incrementing means elections are happening. | | Write throughput | `consul_raft_apply`, `consul_raft_commitNumLogs`, `consul_raft_last_index` | Log apply rate, logs per commit, and last index - throughput and replication progress. | | Leader replication | `consul_raft_leader_dispatchLog`, `_dispatchNumLogs`, `_oldestLogAge` | Log-dispatch latency and oldest in-flight log - replication lag on the leader. | | FSM apply | `consul_raft_fsm_apply`, `_enqueue`, `consul_raft_thread_fsm_saturation` | How fast committed entries become state, and thread saturation. | | Membership | `consul_members_servers`, `consul_members_clients` | Server and client member counts - a drop means a node left the cluster. | | Gossip | `consul_serf_member_join`, `consul_serf_events`, `consul_serf_queue_Event` / `_Intent` / `_Query`, `consul_memberlist_gossip`, `_queue_broadcasts` | Serf and memberlist activity and outbound queue depth - rising queues mean gossip back-pressure. | | KV / transactions | `consul_kvs_apply`, `consul_txn_apply`, `consul_txn_read` | KV write and transaction apply/read latency through Raft. | | Catalog | `consul_catalog_register`, `_deregister`, `consul_catalog_service_query`, `_connect_query`, `_service_not_found` | Service-catalog write and query rates plus miss counts - discovery load. | | Server RPC | `consul_rpc_request`, `_request_error`, `consul_rpc_query`, `_queries_blocking`, `_cross_dc`, `_rate_limit_exceeded`, `_consistentRead` | RPC volume, errors, blocking queries, cross-DC calls, and rate-limit trips. | | Client RPC | `consul_client_rpc`, `_exceeded`, `_failed` | Agent→server RPC calls, rate-limited, and failed - client-side RPC health. | | gRPC transport | `consul_grpc_server_request_count`, `_connections`, `_streams`, `consul_grpc_client_*` | gRPC server/client connections, streams, and request counts (xDS + internal transport). | | Replication health | `consul_leader_replication_acl_tokens_status`, `_acl_policies_status`, `_config_entries_status`, `_namespaces_status`, `_federation_state_status` | ACL/config replication health (1 = replicating) - non-1 means a secondary DC is falling behind. | | Mesh CA expiry | `consul_mesh_active_root_ca_expiry`, `_signing_ca_expiry` | Time (s) until the Connect mesh CA root / signing cert expires - dropping toward 0 breaks mTLS issuance. | | Peering | `consul_peering_healthy`, `consul_consul_peering_healthy`, `consul_state_peerings` | Cluster-peering connection health and peering count. | | Failure tolerance | `consul_autopilot_failure_tolerance` | How many servers can fail before quorum is lost - 0 means no redundancy left. | | Go runtime | `consul_runtime_alloc_bytes`, `_sys_bytes`, `_heap_objects`, `consul_runtime_num_goroutines`, `_gc_pause_ns`, `_total_gc_runs` | Consul process memory, goroutines, and GC pressure. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. The large families below are grouped - back-ticked names are representative members, not the full list. | Group | Metrics | When you reach for it | |---|---|---| | Per-endpoint API/RPC | `consul_client_api_*`, `consul_client_api_success_*`, `consul_client_rpc_error_*` (catalog_nodes, catalog_services, node_services, datacenters, ...) | Per-endpoint HTTP-API call, success, and RPC-error breakdown. | | Agent cache | `consul_cache_*` / `consul_consul_cache_*` (`fetch_success`, `fetch_error`, `entries_count`, `evict_expired`, `connect_ca_root_hit` / `_miss_new`) | Cache hit/miss/fetch/evict internals, including Connect CA-root caching. | | ACL subsystem | `consul_acl_*` (`ResolveToken`, `token_upsert` / `_cache_hit`, `policy_*`, `role_*`, `login` / `logout`, `blocked_*_registration`) | ACL resolution, CRUD, token cache, and blocked (unauthorized) registrations. Idle without ACLs enabled. | | Per-type FSM timing | `consul_fsm_*` / `consul_consul_fsm_*` (`register`, `kvs`, `ca`, `intention`, `session`, `txn`, `prepared_query`, `peering`, `federation_state_dc1`) | Per-operation-type FSM apply timing - which kind of write is slow. | | Raft WAL internals | `consul_raft_wal_*` (`log_appends`, `log_entries_written` / `_read`, `stable_gets` / `_sets`, `segment_rotations`, `head_truncations`, `last_segment_age_seconds`) | WAL storage-backend append/read volume, truncations, and segment rotation. | | Leader housekeeping | `consul_leader_barrier`, `_reapTombstones`, `_reconcile`, `consul_leader_replication_*_index` | Leader loop timing and per-resource replication index positions. | | xDS streams | `consul_xds_server_streams`, `_streamStart`, `_streamDrained`, `_idealStreamsMax` | Service-mesh xDS stream lifecycle internals. | | Federation / sessions | `consul_federation_state_*`, `consul_prepared_query_*`, `consul_session_*`, `consul_session_ttl_active`, `consul_peering_exported_services` | Multi-DC federation, prepared queries, session TTLs, and exported-service counts. | | Build info | `consul_version` | Build/version carried in labels - context, not a signal. | | Runtime / scrape meta | `go_*`, `process_*`, `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_series_added` | Go-runtime, process, and Prometheus scrape meta the endpoint also exposes. | Full metric list: run `curl -s 'http://localhost:8500/v1/agent/metrics?format=prometheus'` against your Consul agent. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your cluster size and workload. `up` and `consul_autopilot_healthy` read a state, not a tunable number; the rest are relative to your baseline or to the expected server count. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The agent metrics endpoint stopped responding. Check the agent and the HTTP API port. | | `consul_autopilot_healthy` | `== 0` | Autopilot sees the cluster as degraded - not enough voters alive/reachable. Check server health and Raft peers. | | `consul_raft_peers` | Below the expected server count | A server left the quorum; restore the missing server(s) before another loss costs quorum. | | `consul_autopilot_failure_tolerance` | `== 0` | The cluster can lose no further server without losing quorum - restore redundancy. | | `rate(consul_raft_state_candidate)` | `> 0` | Elections are happening - an unstable leader. Check network, disk latency, and server load. | | `consul_raft_leader_lastContact` | Rising vs baseline | The leader is slow to reach followers - network or follower load; precedes elections. | | `consul_raft_commitTime` | Rising vs baseline | Write commits are slowing - check disk I/O on the servers and Raft log size. | | `consul_mesh_active_signing_ca_expiry` / `_root_ca_expiry` | Dropping toward 0 | The mesh CA cert is approaching expiry - rotate before mTLS issuance fails. | | `rate(consul_rpc_request_error)` / `consul_client_rpc_failed` | Rising vs baseline | Server/client RPCs are failing - check server reachability and rate limits. | | `consul_runtime_alloc_bytes` / `consul_runtime_num_goroutines` | Rising vs baseline | The agent is leaking or under sustained pressure - correlate with request volume. | ### Access Setup Enable the Prometheus metrics endpoint by adding a `telemetry` block to the Consul agent config: ```json showLineNumbers title="consul-config.json" { "telemetry": { "prometheus_retention_time": "60s", "disable_hostname": true } } ``` - `prometheus_retention_time` must be greater than `0s` to enable the Prometheus endpoint (the default `0s` returns no Consul series). Set it to at least 2x the scrape interval so a missed scrape does not lose a window. - `disable_hostname` removes hostname prefixes from gauge metrics for cleaner Prometheus labels. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # Check Consul is running and has a leader curl -s http://localhost:8500/v1/status/leader # Verify the Prometheus metrics endpoint curl -s 'http://localhost:8500/v1/agent/metrics?format=prometheus' \ | head -20 ``` No authentication is required by default. ACL-enabled clusters need a token with `agent:read` permission on the scrape request - see the ACL variant under [Configuration](#configuration). ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: consul scrape_interval: 30s metrics_path: /v1/agent/metrics params: format: [prometheus] static_configs: - targets: - ${env:CONSUL_HOST}:8500 metric_relabel_configs: # Scope to the Consul namespace; drops the endpoint's own # go_* / process_* runtime series. - source_labels: [__name__] regex: "consul_.*" action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The `metric_relabel_configs` keep filter scopes the scrape to the `consul_` namespace - the endpoint also exposes the Go runtime (`go_*`) and process (`process_*`) series, and this drops them at the receiver. Drop the filter if you want those too. (The `prometheus` receiver keeps whatever the endpoint exposes; there is no `metrics:` enable list to curate.) #### Environment Variables ```bash showLineNumbers title=".env" CONSUL_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### ACL-enabled clusters For clusters with ACLs enabled, the scrape request needs a token with `agent:read` permission. Add an `authorization` block to the scrape job: ```yaml showLineNumbers title="config/otel-collector.yaml (ACL)" receivers: prometheus: config: scrape_configs: - job_name: consul scrape_interval: 30s metrics_path: /v1/agent/metrics params: format: [prometheus] authorization: type: Bearer credentials: ${env:CONSUL_TOKEN} static_configs: - targets: - ${env:CONSUL_HOST}:8500 ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for a successful Consul scrape docker logs otel-collector 2>&1 | grep -i "consul" # Verify Consul is healthy curl -s http://localhost:8500/v1/status/leader # Check the metrics endpoint directly for a Core series curl -s 'http://localhost:8500/v1/agent/metrics?format=prometheus' \ | grep consul_raft_peers ``` ### Troubleshooting #### Metrics endpoint returns empty or 404 **Cause**: `prometheus_retention_time` is not configured or set to `0s`, so Consul emits no Prometheus series. **Fix**: 1. Add `"prometheus_retention_time": "60s"` to the `telemetry` block in the agent config. 2. Restart the Consul agent. 3. Verify: `curl 'http://localhost:8500/v1/agent/metrics?format=prometheus'`. #### Connection refused on port 8500 **Cause**: The Collector cannot reach Consul at the configured address. **Fix**: 1. Verify Consul is running: `docker ps | grep consul` or `consul members`. 2. Confirm the HTTP API address: `consul info | grep client_addr`. 3. Check firewall rules if the Collector runs on a separate host. #### Leader-side Raft metrics missing on a server **Cause**: `consul_raft_leader_lastContact` and `consul_raft_leader_dispatchLog` are emitted only by the current leader. **Look at**: the Diagnostic `consul_raft_state_*` series - followers report `consul_raft_state_follower` while the leader reports `consul_raft_state_leader`. Their absence on a follower is expected. **Fix**: Scrape every server independently (each is identified by its `instance` label) so the leader's metrics are always captured wherever leadership currently sits. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. #### ACL permission denied **Cause**: The token lacks `agent:read` permission. **Fix**: 1. Create a policy with `agent_prefix "" { policy = "read" }`. 2. Attach the policy to a token and set it in `CONSUL_TOKEN`. 3. Test: `curl -H "Authorization: Bearer $CONSUL_TOKEN" 'http://localhost:8500/v1/agent/metrics?format=prometheus'`. ### FAQ #### Does this work with Consul running in Kubernetes? Yes. Set `targets` to the Consul service DNS (e.g., `consul-server.consul.svc.cluster.local:8500`) and make sure `prometheus_retention_time` is set in the server config. The Collector can run as a sidecar or DaemonSet. #### How do I monitor a multi-node Consul cluster? Each Consul agent exposes its own metrics endpoint. Add every server to the scrape config: ```yaml showLineNumbers receivers: prometheus: config: scrape_configs: - job_name: consul metrics_path: /v1/agent/metrics params: format: [prometheus] static_configs: - targets: - consul-1:8500 - consul-2:8500 - consul-3:8500 ``` Each agent is scraped independently and identified by its `instance` label. #### Why are Raft leadership metrics only appearing on one node? `consul_raft_leader_lastContact` and `consul_raft_leader_dispatchLog` are emitted only by the current leader. Other servers emit follower-side metrics like `consul_raft_state_follower`. This is expected behavior, not a collection gap. #### What does `consul_autopilot_healthy` mean? A value of `1` means Autopilot considers the cluster healthy - enough voters are alive and reachable. A value of `0` indicates the cluster is degraded. Monitor it alongside `consul_raft_peers` and `consul_autopilot_failure_tolerance` for the full quorum picture. #### Why do some metrics appear twice with a `consul_consul_` prefix? The cache, FSM, and peering families are emitted under both `consul_` and `consul_consul_` (for example `consul_cache_fetch_success` and `consul_consul_cache_fetch_success`). This is a Consul telemetry naming artifact, not a duplicate scrape - treat the pair as one family. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Consul metrics. - [Vault Monitoring](./vault.md) - Secrets and PKI control plane alongside Consul. - [Nomad Monitoring](./nomad.md) - Workload scheduler on the same HashiCorp stack. - [etcd Monitoring](./etcd.md) - Distributed consensus and key-value store. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Vault](./vault.md), [Nomad](./nomad.md), [etcd](./etcd.md), and other components. - **Scope the Scrape**: Use the `consul_.*` keep filter in `metric_relabel_configs` to confine the scrape to the `consul_` namespace and leave the endpoint's `go_*` / `process_*` runtime series out of Scout. --- ## Couchbase OpenTelemetry Monitoring - Data Service, Cluster Health, and Collector Setup ## Couchbase Couchbase Server 7.0+ serves Prometheus text at `/metrics` on the management port `:8091` (basic auth - any user with the `external_stats_reader` role). The OpenTelemetry Collector's `prometheus` receiver scrapes it, collecting 500+ metrics across cluster-manager state (rebalance, auto-failover, REST), the data service (operations, items, memory, disk queues, vbuckets), and host / process resources. This guide configures the receiver, sets up the required authentication, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | -------------- | | Couchbase Server | 7.0 | 7.6+ (7.6.2) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Couchbase must be initialized; the management port (8091) must be reachable from the host running the Collector. - A monitoring user with the `external_stats_reader` role (see [Access Setup](#access-setup) below). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Couchbase has a real `up` series here - the `prometheus` receiver emits `up = 1` when `/metrics` responds, so that is the liveness signal. `cm_is_balanced` (1 = the cluster's data is evenly distributed) and `kv_uptime_seconds` (a reset means a restart) are the in-band cluster-state and uptime signals. A few things shape this surface: - **`/metrics` needs basic auth.** Grant a monitoring user the `external_stats_reader` role (read-only, no data access; admin credentials also work for testing). Couchbase 7.0+ is the floor for this endpoint - older versions do not expose it. - **Four naming domains share the endpoint.** `cm_*` is the cluster manager (Erlang / ns_server: REST, auth caches, rebalance, auto-failover, chronicle consensus), `kv_*` is the data service (memcached / EP-engine: connections, ops, items, memory, disk queues, vbuckets), `sys_*` is host / cgroup CPU-memory-disk, and `sysproc_*` is per-process CPU and memory. `couch_*`, `audit_*`, and `exposer_*` round it out. - **The `kv_ep_*` family is mostly EP-engine configuration**, not live signals - watermarks, thresholds, `max_*` sizes, `enabled` flags, and `alog_*` / `bfilter_*` tunables read as static gauges. The operational subset is the memory, disk-queue, flusher, background-fetch, OOM, and IO-failure counters. - **Cardinality is concentrated in `kv_*`.** Most `kv_*` series carry a `bucket` label, so the per-bucket count multiplies with bucket count; the `sys_*` / `sysproc_*` / `cm_*` families are per-node. - **A few series are exposed twice per scrape** (same name and labels, two values). The `prometheus` receiver keeps the first and drops the duplicate (a benign `different value but same timestamp` warning), so the unique-name count is unaffected. - **`exposer_*` is Couchbase's own Prometheus-client scrape meta** (scrape latency / count from the exporter side), distinct from the receiver-side `scrape_*`. - **Warm-up.** The `kv_*` data-service families populate only once a bucket exists and takes operations. A fresh node with no bucket shows mostly `cm_*` and `sys_*`. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Prometheus scrape liveness - 1 = the Couchbase metrics endpoint responded. The liveness signal on this surface. | | `cm_is_balanced` | 1 = the cluster's data is balanced across nodes; 0 = a rebalance is needed. | | `kv_ops` | Data-service operations - headline throughput. | | `kv_curr_connections` | Current data-service client connections. | | `kv_mem_used_bytes` | Data-service memory in use - the headline memory signal, watched against the bucket quota watermarks. | | `kv_ep_oom_errors` | Hard out-of-memory errors - the data service rejected operations because it hit the quota. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Rebalance & failover | `cm_rebalance_in_progress`, `cm_rebalance_stuck`, `cm_auto_failover_count`, `cm_auto_failover_enabled` | Whether a rebalance is running or stuck, and whether a node was auto-failed-over. | | Cluster-manager activity | `cm_http_requests_total` (+ `_seconds_*` latency), `cm_authentications_total`, `cm_memcached_call_time_seconds_*`, `cm_logs_total` | REST request rate and latency, auth attempts, memcached-call latency, and log volume by level. | | Data-service failures | `kv_ops_failed`, `kv_auth_errors`, `kv_cmd_duration_seconds_*` | Failed operations, auth failures, and the read/write latency SLO. | | Items & connections | `kv_curr_items`, `kv_curr_items_tot`, `kv_total_connections` | Active items (this node), total items including replicas, and cumulative connections opened. | | Memory pressure | `kv_ep_tmp_oom_errors`, `kv_ep_mem_high_wat`, `kv_ep_mem_low_wat` | Temporary OOM (clients should back off), and the high / low watermarks that bound `kv_mem_used_bytes`. | | Persistence | `kv_ep_diskqueue_items`, `kv_ep_diskqueue_fill`, `kv_ep_diskqueue_drain`, `kv_ep_flusher_todo`, `kv_ep_item_commit_failed`, `kv_ep_item_flush_failed` | Disk write-queue depth, fill vs drain rate, flusher backlog, and commit/flush failures - fill outpacing drain is a persistence backlog. | | Disk IO & cache | `kv_ep_data_read_failed`, `kv_ep_data_write_failed`, `kv_ep_bg_fetched`, `kv_ep_num_eject_failures` | Disk read/write failures, background fetches (cache misses to disk), and failed evictions. | | Resident set & vbuckets | `kv_vb_perc_mem_resident_ratio`, `kv_vb_num_non_resident`, `kv_vb_queue_size`, `kv_vb_queue_age_seconds`, `kv_vb_ops_create`, `kv_vb_ops_delete`, `kv_vb_ops_update`, `kv_vb_ops_get`, `kv_vb_ops_reject`, `kv_vb_sync_write_aborted_count` | Resident ratio (falling means reads hit disk), per-vbucket queue depth/age, operation rates (rejects = backpressure), and aborted durable writes. | | Replication | `kv_dcp_num_running_backfills` | Running DCP backfills - replication / index / XDCR catching up from disk. | | Host & process | `sys_cpu_utilization_rate`, `sys_cpu_host_utilization_rate`, `sys_cpu_cgroup_seconds_total`, `sys_cpu_throttled_rate`, `sys_mem_actual_used`, `sys_mem_actual_free`, `sys_mem_limit`, `sys_mem_cgroup_used`, `sys_mem_cgroup_limit`, `sys_disk_read_bytes`, `sys_disk_write_bytes`, `sys_disk_queue`, `sys_disk_usage_ratio`, `sys_disk_time_seconds`, `sys_swap_used`, `sysproc_cpu_utilization`, `sysproc_mem_resident`, `sysproc_major_faults_raw` | Node and cgroup CPU (throttling = CPU-capped), memory used/free/limit, disk bytes/queue/busy time, swap in use, and per-process CPU/memory/page-faults. | | Storage & audit | `couch_docs_actual_disk_size`, `audit_queue_length` | On-disk document size (data-at-rest growth) and pending audit-log entries. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. The large `kv_ep_*` configuration surface and the per-vbucket detail are grouped, not enumerated - representative member names are shown. | Group | Metrics | When you reach for it | |---|---|---| | Uptime & memory detail | `kv_uptime_seconds`, `kv_curr_temp_items`, `kv_mem_used_estimate_bytes`, `kv_memory_used_bytes`, `kv_memory_overhead_bytes`, `kv_logical_data_size_bytes` | Restart detection, in-flight metadata, allocator overhead, and logical (pre-compression) size. | | Connection & command detail | `kv_read_bytes`, `kv_written_bytes`, `kv_num_vbuckets`, `kv_num_high_pri_requests`, `kv_items_in_transit`, `kv_auth_cmds`, `kv_cmd_lookup`, `kv_cmd_mutation`, `kv_conn_yields`, `kv_conn_timeslice_yields`, `kv_disk_seconds_*` | Bytes on connections, vbucket count, command-class counts, scheduling yields, and disk-op latency. | | EP-engine IO & checkpoints | `kv_ep_io_*`, `kv_ep_commit_num`, `kv_ep_commit_time_seconds`, `kv_ep_diskqueue_pending`, `kv_ep_diskqueue_memory_bytes`, `kv_ep_arena_memory_*`, `kv_ep_blob_num`, `kv_ep_item_*`, `kv_ep_num_checkpoints*`, `kv_ep_checkpoint_*`, `kv_ep_items_expelled_from_checkpoints` | EP-engine IO bytes, commit timing, disk-queue memory, allocator arenas, item internals, and checkpoint accounting. | | EP-engine configuration | `kv_ep_max_*`, `kv_ep_mem_*_ratio`, `kv_ep_*_enabled`, `kv_ep_alog_*`, `kv_ep_bfilter_*`, `kv_ep_chk_*`, `kv_ep_bucket_quota_*` | Static gauges: max sizes, watermark ratios, feature flags, access-log, bloom-filter, and checkpoint tunables. | | Per-vbucket detail | `kv_vb_ht_*`, `kv_vb_checkpoint_memory_*`, `kv_vb_mem_freed_by_checkpoint_*`, `kv_vb_bloom_filter_memory_bytes`, `kv_vb_dm_*`, `kv_vb_meta_data_*`, `kv_vb_queue_memory_bytes`, `kv_vb_curr_items`, `kv_vb_eject`, `kv_vb_expired`, `kv_vb_rollback_item_count`, `kv_vb_sync_write_*` | Hash-table, checkpoint-memory, durability-monitor, metadata, eject/expiry, rollback, and sync-write detail. | | Sub-document & collections | `kv_subdoc_*`, `kv_collection_*`, `kv_dcp_max_running_backfills` | Sub-document operation counts, collection-manifest detail, and DCP backfill capacity. | | Data-service internals | `kv_audit_*`, `kv_daemon_*`, `kv_threads`, `kv_stat_reset`, `kv_clients`, `kv_user_connections`, `kv_system_connections` | Audit, daemon, thread, and connection-class detail. | | Cluster-manager caches | `cm_auth_cache_*`, `cm_client_cert_cache_*`, `cm_up_cache_*`, `cm_user_bkts_cache_*`, `cm_uuid_cache_*`, `cm_web_cache_*`, `cm_mru_cache_*` | Cache hit / miss / size families on the cluster manager. | | Cluster-manager internals | `cm_chronicle_*`, `cm_lease_acquirer_*`, `cm_timer_lag_seconds_*`, `cm_status_latency_seconds_*`, `cm_gc_duration_seconds_*`, `cm_erlang_process_count`, `cm_erlang_process_limit`, `cm_erlang_port_count`, `cm_erlang_port_limit`, `cm_memcached_cmd_total`, `cm_outgoing_http_requests_*`, `cm_rest_request_enters_total` | Chronicle consensus, leases, timer lag, GC, Erlang-VM process/port usage, and request lifecycle. | | Host & process detail | `sys_cpu_host_*`, `sys_cpu_cores_available`, `sys_cpu_burst_rate`, `sys_allocstall`, `sys_pressure_*`, `sys_mem_free`, `sys_mem_total`, `sys_mem_cgroup_actual_used`, `sys_swap_total`, `sys_disk_reads`, `sys_disk_writes`, `sys_disk_read_time_seconds`, `sysproc_cpu_seconds_total`, `sysproc_mem_size`, `sysproc_mem_share`, `sysproc_minor_faults_raw`, `sysproc_start_time` | Per-mode CPU rates, core counts, PSI pressure, additional memory/swap, disk op counts, and per-process detail. | | View storage & audit | `couch_views_actual_disk_size`, `audit_unsuccessful_retries` | On-disk view-index size and failed audit-write retries. | | Scrape meta | `exposer_request_latencies`, `exposer_scrapes_total`, `exposer_transferred_bytes_total`, `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Couchbase's own Prometheus-exposer meta and the receiver-side scrape meta. | Full metric list: run `curl -su : http://localhost:8091/metrics` against your Couchbase instance. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. The state and event alerts (`up == 0`, `cm_is_balanced == 0`, `cm_rebalance_stuck == 1`, the OOM / IO-failure counters, and `sys_swap_used > 0`) read conditions, not invented absolutes. The rest are relative to your baseline. Tune to your workload; these are starting points. | Alert | Threshold | Why it matters | |---|---|---| | Couchbase unreachable | `up == 0` for > 1m | The metrics endpoint stopped responding - check the node process and port 8091. | | Cluster not balanced | `cm_is_balanced == 0` | Data is not evenly distributed - run a rebalance. | | Rebalance stuck | `cm_rebalance_stuck == 1` | A rebalance cannot progress - investigate node health and retry. | | Node auto-failed-over | `increase(cm_auto_failover_count) > 0` | A node went down and was failed over - check the failed node and capacity. | | Hard OOM | `rate(kv_ep_oom_errors) > 0` | The data service is rejecting operations on memory - raise the bucket quota or add nodes. | | Temp OOM rising | `rate(kv_ep_tmp_oom_errors) > 0` | Clients are being told to back off - memory pressure precedes hard OOM. | | Resident ratio falling | `kv_vb_perc_mem_resident_ratio` dropping vs baseline | Working set no longer fits in memory - reads hit disk and latency rises. | | Persistence backlog | `kv_ep_diskqueue_fill` outpacing `kv_ep_diskqueue_drain`, or `kv_ep_flusher_todo` rising | Disk cannot keep up with writes - check disk throughput. | | Disk IO failures | `rate(kv_ep_data_write_failed) > 0` or `rate(kv_ep_data_read_failed) > 0` | Storage is failing - check the disk and filesystem. | | Command latency high | `kv_cmd_duration_seconds` p99 rising vs baseline | Data-service ops are slow - correlate with memory, disk queue, and CPU. | | Swap in use | `sys_swap_used > 0` | The node is swapping - this severely degrades a database; reduce memory pressure. | ### Access Setup #### Initialize the cluster A fresh Couchbase deployment must be initialized before metrics are available. Skip this step if connecting to an existing cluster. ```bash showLineNumbers title="Initialize cluster via REST API" # Initialize the cluster (run once on a fresh install) curl -s -X POST http://localhost:8091/clusterInit \ -d "hostname=127.0.0.1" \ -d "username=Administrator" \ -d "password=your_admin_password" \ -d "services=kv" \ -d "memoryQuota=512" # Create a bucket (required for kv_* metrics to appear) curl -s -X POST http://localhost:8091/pools/default/buckets \ -u Administrator:your_admin_password \ -d "name=demo&ramQuota=256&bucketType=couchbase&replicaNumber=0" ``` #### Create a monitoring user Create a dedicated monitoring user with the `external_stats_reader` role. This grants read-only access to the `/metrics` endpoint without exposing cluster administration or data. ```bash showLineNumbers title="Create monitoring user" couchbase-cli user-manage \ --cluster http://localhost:8091 \ --username Administrator \ --password your_admin_password \ --set \ --rbac-username otel_monitor \ --rbac-password monitoring_password \ --rbac-name "OTel Monitor" \ --roles external_stats_reader \ --auth-domain local ``` **Minimum required permissions:** - `external_stats_reader`: required to read `/metrics`. No write or data-access permissions are needed. For quick testing, admin credentials also work. Verify the endpoint: ```bash showLineNumbers title="Verify metrics access" # Check Couchbase is initialized curl -s http://localhost:8091/pools/default | head -5 # Verify the Prometheus metrics endpoint curl -su otel_monitor:monitoring_password \ http://localhost:8091/metrics | head -20 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: couchbase scrape_interval: 10s metrics_path: /metrics basic_auth: username: ${env:COUCHBASE_USER} password: ${env:COUCHBASE_PASSWORD} static_configs: - targets: - ${env:COUCHBASE_HOST}:8091 metric_relabel_configs: # Scope to the Couchbase families; drops Go-runtime noise. - source_labels: [__name__] regex: "cm_.*|kv_.*|sys_.*|sysproc_.*|up" action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The `metric_relabel_configs` keep filter scopes collection to the Couchbase families (`cm_*`, `kv_*`, `sys_*`, `sysproc_*`, `up`). Narrow the regex to adjust which families are collected and tune metric volume to your needs. #### Environment Variables ```bash showLineNumbers title=".env" COUCHBASE_HOST=localhost COUCHBASE_USER=otel_monitor COUCHBASE_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Couchbase metrics docker logs otel-collector 2>&1 | grep -i "couchbase" # Verify Couchbase is healthy curl -su ${COUCHBASE_USER}:${COUCHBASE_PASSWORD} \ http://localhost:8091/pools/default | head -10 # Check the metrics endpoint directly curl -su ${COUCHBASE_USER}:${COUCHBASE_PASSWORD} \ http://localhost:8091/metrics | grep kv_curr_connections ``` ### Troubleshooting #### Authentication failed (401 / 403) **Cause**: The monitoring credentials are wrong, or the user lacks the `external_stats_reader` role. **Fix**: 1. Test credentials directly against the endpoint: `curl -su otel_monitor:password http://localhost:8091/metrics | head -5`. 2. If that fails, list users and confirm the role: ```bash showLineNumbers title="List users and roles" couchbase-cli user-manage \ --cluster http://localhost:8091 \ --username Administrator --password admin_pass --list ``` 3. Confirm `COUCHBASE_USER` and `COUCHBASE_PASSWORD` are set in the Collector environment. #### Connection refused on port 8091 **Cause**: The Collector cannot reach Couchbase at the configured address. **Fix**: 1. Verify Couchbase is running: `docker ps | grep couchbase` or `systemctl status couchbase-server`. 2. Confirm the management port is listening: `curl -s http://localhost:8091/ui/index.html`. 3. Check firewall rules if the Collector runs on a separate host. #### Cluster not initialized **Cause**: The `/metrics` endpoint is unavailable until the cluster is initialized. **Fix**: 1. Run the `/clusterInit` step in [Access Setup](#access-setup). 2. Confirm initialization with `curl -s http://localhost:8091/pools/default` - an initialized cluster returns a JSON pool description. #### Only `cm_*` and `sys_*` metrics appear, no `kv_*` **Cause**: There is no bucket with traffic yet. The data-service (`kv_*`) families populate only once a bucket exists and takes operations. **Look at**: `kv_curr_items` - it stays absent until a bucket holds data. **Fix**: 1. Create a bucket: ```bash showLineNumbers title="Create a bucket" couchbase-cli bucket-create \ --cluster http://localhost:8091 \ --username Administrator --password admin_pass \ --bucket demo --bucket-type couchbase --bucket-ramsize 256 ``` 2. Drive some operations, then wait one scrape interval and verify: `curl -su otel_monitor:password http://localhost:8091/metrics | grep kv_`. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Couchbase running in Kubernetes? Yes. Set `targets` to the Couchbase service DNS endpoint (for example `couchbase.default.svc.cluster.local:8091`) and inject the monitoring credentials via a Kubernetes secret. With the Couchbase Autonomous Operator, each pod exposes `/metrics` on 8091 - add all pod addresses to the scrape config or use Prometheus service discovery. #### What permissions does the monitoring account need? The `external_stats_reader` role only - it is read-only and grants no write or data access. Admin credentials also work for quick testing. #### Does this work with Couchbase Community Edition? Yes. Community Edition 7.0+ exposes the same `/metrics` endpoint with the same `cm_*` / `kv_*` / `sys_*` / `sysproc_*` surface. The query (`n1ql_*`), index (`index_*`), and search service families appear on either edition when those services run; the analytics (`cbas_*`) and eventing (`eventing_*`) families are Enterprise Edition only. #### Why do I only see `cm_*` and `sys_*` metrics? There is no bucket with traffic yet. The data-service (`kv_*`) families populate only once a bucket exists and takes operations. The cluster-manager (`cm_*`) and host (`sys_*`) families are available immediately after the cluster is initialized. #### Is the `different value but same timestamp` warning a problem? No. Couchbase exposes a small number of duplicate samples (same name and labels, two values) per scrape. The `prometheus` receiver keeps the first and drops the duplicate, so the unique-name count is unaffected. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Couchbase metrics. - [MongoDB Monitoring](./mongodb.md) - Monitor another document database. - [CouchDB Monitoring](./couchdb.md) - Monitor a document database with an HTTP stats API. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [MongoDB](./mongodb.md), [CouchDB](./couchdb.md), and other components. - **Fine-tune Collection**: Use `metric_relabel_configs` to adjust which metric families are collected, balancing volume against the visibility you want for day-to-day monitoring and incident investigation. --- ## CouchDB OpenTelemetry Monitoring - Request Latency, Database Operations, and Collector Setup ## CouchDB The OpenTelemetry Collector's CouchDB receiver collects 8 metrics from CouchDB 3.x across request latency, HTTP request and response counts, database operations, file descriptors, and view and bulk requests. The receiver connects to the CouchDB HTTP API and reads `/_node/_local/_stats` with basic auth, so no exporter or sidecar is needed. This guide configures the receiver, sets up the read access it needs, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | CouchDB | 2.3 | 3.x | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The CouchDB HTTP API must be reachable from the host running the Collector (default port 5984). - An account with read access to `/_node/_local/_stats` - an admin or a dedicated read-only user works (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The receiver connects to the CouchDB HTTP API and reads `/_node/_local/_stats`. A few things follow from that surface: - **There is no `up`, uptime, or health metric.** That series is prometheus-receiver-only; the CouchDB receiver does not emit it. Liveness is the receiver scraping the stats endpoint successfully - if it returns data, the node is up and serving. - **The receiver needs read access to `/_node/_local/_stats`.** An admin or a dedicated read-only user works; no write access is required. - **`couchdb.httpd.views` reads 0 until a MapReduce view is queried, and `couchdb.httpd.bulk_requests` until a `_bulk_docs` request runs.** A zero on a cluster that never runs views or bulk updates is expected, not a fault. - **The response-status breakdown is your error signal.** `couchdb.httpd.responses` carries an `http.status_code` attribute, so 4xx and 5xx rates come from filtering that series. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `couchdb.average_request_time` | Average request processing time in ms - the serving-latency KPI. No `up`/health on this surface; liveness is scrape success. | | `couchdb.httpd.requests` | HTTP requests by `http.method` (GET/POST/PUT/...) - request throughput. | | `couchdb.database.operations` | Database operations by `operation` (reads/writes) - the DB-work KPI. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `couchdb.httpd.responses` | Responses by `http.status_code` (200/201/202/4xx/5xx) - the error-rate signal. | | `couchdb.file_descriptor.open` | Open file descriptors - saturation against the OS limit. | | `couchdb.database.open` | Open databases - resource footprint. | #### Diagnostic - for investigation and tuning | Metric | What it tells you | |---|---| | `couchdb.httpd.bulk_requests` | Bulk-update (`_bulk_docs`) request count - reach for it when a write spike correlates with batch ingest. | | `couchdb.httpd.views` | MapReduce view (temporary and permanent) query count - reach for it when view-heavy reads drive latency. | Full metric reference: [OTel CouchDB Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/couchdbreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. They are all relative to your own baseline - the right absolute values depend on your traffic and hardware. | Alert | Threshold | Why it matters | |---|---|---| | CouchDB unreachable | The `couchdb` receiver produces no data for > 1m | No `up`/health on this surface - scrape success is liveness. Check the CouchDB process and the receiver credentials/endpoint. | | Request latency rising | `couchdb.average_request_time` rising vs baseline | Slow request processing; check disk, compaction, and load. | | Error responses | `rate(couchdb.httpd.responses{http.status_code=~"5.."})` rising vs baseline | Server-side errors; inspect the CouchDB logs and recent writes/views. | | File-descriptor saturation | `couchdb.file_descriptor.open` approaching the OS file-descriptor limit | Approaching the descriptor ceiling; raise the ulimit before requests start failing. | ### Access Setup The CouchDB receiver reads an authenticated stats endpoint. Use the admin account or create a dedicated monitoring user: ```bash showLineNumbers title="Create monitoring user (optional)" curl -X PUT http://localhost:5984/_users/org.couchdb.user:otel_monitor \ -H "Content-Type: application/json" \ -u admin:password \ -d '{"name":"otel_monitor","password":"monitor_pass","roles":[],"type":"user"}' ``` **Minimum required permissions:** - Read access to `/_node/_local/_stats` - required for all metrics. - No write permissions are needed; the Collector only reads metrics. Verify the endpoint responds before wiring up the Collector: ```bash showLineNumbers title="Verify access" # Liveness check curl http://localhost:5984/_up # Stats endpoint the receiver reads curl -u otel_monitor:monitor_pass http://localhost:5984/_node/_local/_stats ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: couchdb: endpoint: http://localhost:5984 # Change to your CouchDB address username: ${env:COUCHDB_USER} password: ${env:COUCHDB_PASSWORD} collection_interval: 10s metrics: # Performance couchdb.average_request_time: enabled: true # Database couchdb.database.open: enabled: true couchdb.database.operations: enabled: true # System couchdb.file_descriptor.open: enabled: true # HTTP couchdb.httpd.bulk_requests: enabled: true couchdb.httpd.requests: enabled: true couchdb.httpd.responses: enabled: true couchdb.httpd.views: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [couchdb] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" COUCHDB_USER=otel_monitor COUCHDB_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for the CouchDB receiver docker logs otel-collector 2>&1 | grep -i "couchdb" # Verify the CouchDB stats endpoint responds curl -u ${COUCHDB_USER}:${COUCHDB_PASSWORD} http://localhost:5984/_node/_local/_stats # List databases curl -u ${COUCHDB_USER}:${COUCHDB_PASSWORD} http://localhost:5984/_all_dbs ``` ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach CouchDB at the configured endpoint. **Fix**: 1. Verify CouchDB is running: `systemctl status couchdb` or `docker ps | grep couchdb`. 2. Confirm the endpoint address and port (default 5984) in your config. 3. Check whether CouchDB is bound to `127.0.0.1` - change to `0.0.0.0` in `local.ini` if the Collector runs on a separate host. #### Authentication failed **Cause**: The monitoring credentials are incorrect or the user lacks read access to the stats endpoint. **Fix**: 1. Test credentials directly: `curl -u user:pass http://localhost:5984/_node/_local/_stats`. 2. Verify the user exists in the `_users` database. 3. Check the `COUCHDB_USER` and `COUCHDB_PASSWORD` environment variables. #### View or bulk metrics read zero **Cause**: No view has been queried, or no bulk request has run, yet. **Look at**: `couchdb.httpd.views` and `couchdb.httpd.bulk_requests` - both stay at 0 until the matching traffic occurs. This is expected, not a fault. **Fix**: 1. `couchdb.httpd.views` populates only after a MapReduce view is queried. Create and query one to confirm: `curl -u user:pass http://localhost:5984/mydb/_design/test/_view/all`. 2. `couchdb.httpd.bulk_requests` populates only after a `_bulk_docs` request runs. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with CouchDB running in Kubernetes? Yes. Set `endpoint` to the CouchDB service DNS (e.g., `http://couchdb.default.svc.cluster.local:5984`) and inject credentials via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### How do I monitor a CouchDB cluster? Each CouchDB node exposes its own `/_node/_local/_stats` endpoint. Add a separate receiver block per node: ```yaml receivers: couchdb/node1: endpoint: http://couchdb-1:5984 username: ${env:COUCHDB_USER} password: ${env:COUCHDB_PASSWORD} couchdb/node2: endpoint: http://couchdb-2:5984 username: ${env:COUCHDB_USER} password: ${env:COUCHDB_PASSWORD} ``` Then include both in the pipeline: `receivers: [couchdb/node1, couchdb/node2]`. #### What permissions does the monitoring account need? Read access to `/_node/_local/_stats`. No write access is required - the Collector only reads metrics and never modifies CouchDB data. An admin account works, but a dedicated read-only user is cleaner. #### Why do the view and bulk metrics read zero? `couchdb.httpd.views` counts MapReduce view queries and `couchdb.httpd.bulk_requests` counts `_bulk_docs` requests. Each stays at 0 until that traffic occurs, so a zero on a node that never runs views or bulk updates is expected, not a problem. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on CouchDB metrics. - [MongoDB Monitoring](./mongodb.md) - Another document database to monitor alongside CouchDB. - [PostgreSQL Monitoring](./postgres.md) - A relational store you may run in the same stack. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [MongoDB](./mongodb.md), [PostgreSQL](./postgres.md), and other components. - **Fine-tune Collection**: Adjust `collection_interval` to match your database workload and metric-volume budget. --- ## Docker OpenTelemetry Monitoring - Container CPU, Memory, Network, and Collector Setup ## Docker Engine The OpenTelemetry Collector's `docker_stats` receiver reads the Docker Engine API over the mounted socket and emits 24 metrics per running container - CPU, memory, block I/O, network, and per-container liveness (uptime and restarts) - on Docker Engine 20.10+. It is not a Prometheus scrape: the receiver talks to the Engine API at `unix:///var/run/docker.sock`, not a metrics endpoint, so there is no `up` series and no `scrape_*` meta. This guide configures the receiver, sets up socket access, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | --------------------- | | Docker Engine | 20.10 | 29.x (current) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Docker Engine must be running on the host where the Collector runs. - The Collector needs read access to the Docker socket at `/var/run/docker.sock` (socket access is root-equivalent - see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. All rows are native OpenTelemetry semantic-convention `container.*` names (dotted), emitted once per running container. A few surface facts shape how you read these: - **No `up`, no scrape meta.** Unlike the Prometheus-scrape components, there is no `up` series here - the receiver reads the Engine API, not a scrape endpoint. A stopped container simply disappears from the output. Per-container liveness is `container.uptime` (a drop toward 0 is an unplanned restart) and `container.restarts` (a rising count is a crash loop). - **Reports on every container the daemon sees.** The receiver enumerates all running containers. Scope it in production with the receiver's `excluded_images` or a `filter` processor on `container.name` / image to control cardinality. - **Socket access is root-equivalent.** The Collector mounts `/var/run/docker.sock` read-only and must be able to read it (run as a user that can, for example `user: "0:0"`). Granting socket access is equivalent to root on the host - prefer a read-only socket proxy in production. - **Limit-relative metrics need a limit.** `container.memory.percent` is memory used as a fraction of the container's limit; with no limit set it is computed against host memory and is not a true OOM-risk signal. `container.cpu.limit` is emitted only when a CPU quota (`--cpus` / `cpus:`) is set. - **The memory breakdown is cgroup-version-dependent.** On cgroup v2 it is `container.memory.anon` (anonymous) + `container.memory.file` (page cache). cgroup-v1-only fields (`container.memory.rss`, `container.memory.cache`, `container.memory.swap`, `container.blockio.io_serviced_recursive`) are not emitted on a v2 host. #### Core - is each container alive, stable, and not pinned | Metric | What it tells you | |---|---| | `container.uptime` | Seconds since the container started. A drop toward 0 flags an unplanned restart - the closest liveness signal this receiver emits (it reads the API, so there is no scrape `up`). | | `container.restarts` | Number of times the container has restarted. A rising count is a crash loop - the primary container-health signal. | | `container.cpu.utilization` | Container CPU usage as a percentage of host capacity - headline compute load. | | `container.memory.percent` | Memory used as a percentage of the container's limit - headline OOM-risk signal (meaningful only when a memory limit is set; otherwise relative to host memory). | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `container.memory.usage.total` | Current memory used by the container, in bytes. | | `container.memory.usage.limit` | The container's memory limit in bytes; equals host memory when no limit is set. | | `container.cpu.usage.total` | Cumulative CPU time in ns; the rate approximates cores in use. | | `container.network.io.usage.rx_bytes` | Bytes received on container interfaces - inbound network throughput. | | `container.network.io.usage.tx_bytes` | Bytes transmitted on container interfaces - outbound network throughput. | | `container.network.io.usage.rx_dropped` | Inbound packets dropped - buffer saturation or backpressure. | | `container.network.io.usage.tx_dropped` | Outbound packets dropped. | | `container.network.io.usage.rx_errors` | Receive interface errors. | | `container.network.io.usage.tx_errors` | Transmit interface errors. | | `container.blockio.io_service_bytes_recursive` | Block-device I/O bytes (read + write, labeled by operation) - disk throughput. | | `container.pids.count` | Current process / thread count in the container. | | `container.pids.limit` | The configured pids limit; `count` approaching `limit` means fork-bomb / thread-leak risk. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. They are the drill-down behind the Core and Operational signals. | Metric | What it tells you | |---|---| | `container.cpu.usage.kernelmode` | CPU time spent in kernel mode - syscall / I/O-heavy workloads. | | `container.cpu.usage.usermode` | CPU time spent in user mode - application compute. | | `container.cpu.usage.system` | Host system CPU time - the denominator behind utilization. | | `container.cpu.shares` | Configured CPU weight (static config, not a live load signal). | | `container.memory.anon` | Anonymous (heap / stack) memory, cgroup v2. | | `container.memory.file` | Page-cache (file-backed) memory, cgroup v2. | | `container.network.io.usage.rx_packets` | Packets received - drill-down behind the rx bytes / errors / dropped counters. | | `container.network.io.usage.tx_packets` | Packets transmitted - drill-down behind the tx bytes / errors / dropped counters. | Full metric reference: [OTel Docker Stats Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/dockerstatsreceiver). The receiver emits a default set automatically; the optional metrics (disabled by default) are enabled in the [Configuration](#configuration) `metrics:` block. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. The percent-vs-limit, count-vs-limit, and uptime-drop checks read states or ratios against the container's own limit, not invented absolutes; the rest are relative to your baseline. | Metric | Threshold | Why it matters | |---|---|---| | `rate(container.restarts)` | > 0 | The container is crash-looping - check its logs, exit code, OOM-kills, and healthcheck. | | `container.memory.percent` | > 90 (when a memory limit is set) | OOM-kill is imminent - raise the limit or fix the leak. Pair with `container.memory.usage.total` vs `container.memory.usage.limit`. | | `container.cpu.utilization` | Sustained high vs baseline | The container is CPU-bound (and throttled if a CPU limit is set) - scale out or raise the quota. | | `rate(container.network.io.usage.rx_dropped + container.network.io.usage.tx_dropped)` | > 0 | Packets are being dropped - check NIC buffers, throughput ceilings, and backpressure. | | `rate(container.network.io.usage.rx_errors + container.network.io.usage.tx_errors)` | > 0 | Interface errors - investigate the host network and the container's veth. | | `container.pids.count` | Approaching `container.pids.limit` | Fork bomb or thread leak - raise the pids limit or fix the process spawning. | | `container.uptime` | Drops to near 0 unexpectedly | The container restarted outside a deploy - correlate with `container.restarts` and host events. | ### Access Setup The `docker_stats` receiver connects to the Docker daemon through its Unix socket. No credentials are needed, but the Collector process must have permission to read the socket. When running the Collector in Docker, mount the socket as a read-only volume and run as a user that can read it: ```yaml showLineNumbers title="compose.yaml" services: otel-collector: image: otel/opentelemetry-collector-contrib:latest user: "0:0" # Run as a user that can read the socket volumes: - /var/run/docker.sock:/var/run/docker.sock:ro - ./config:/etc/otelcol-contrib command: ["--config", "/etc/otelcol-contrib/otel-collector.yaml"] ``` On Linux, the host user must be in the `docker` group (or the Collector runs as root). On macOS, Docker Desktop manages socket access at the same path. :::caution Docker socket access is root-equivalent Read access to `/var/run/docker.sock` is equivalent to root on the host. Always mount the socket read-only (`:ro`), exclude the Collector's own image to avoid recursive collection, and prefer a read-only socket proxy (for example `tecnativa/docker-socket-proxy`) in production so the Collector only sees the container-stats endpoints, not the full daemon API. ::: Confirm the socket is reachable from inside the Collector container: ```bash showLineNumbers title="Verify socket access" docker exec otel-collector ls -la /var/run/docker.sock ``` ### Configuration The `docker_stats` receiver emits a default metric set automatically. The optional metrics the tiers above rely on - per-container liveness, the CPU usage split, the cgroup-v2 anonymous-memory breakdown, pids, and interface errors - are disabled by default, so enable them with a `metrics:` sub-block. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: docker_stats: endpoint: unix:///var/run/docker.sock collection_interval: 10s excluded_images: - otel/opentelemetry-collector-contrib # Exclude self metrics: container.uptime: enabled: true container.restarts: enabled: true container.cpu.usage.system: enabled: true container.cpu.usage.kernelmode: enabled: true container.cpu.usage.usermode: enabled: true container.cpu.shares: enabled: true container.memory.anon: enabled: true container.pids.count: enabled: true container.pids.limit: enabled: true container.network.io.usage.rx_errors: enabled: true container.network.io.usage.tx_errors: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [docker_stats] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Scoping which containers emit series The receiver reports on every container the daemon sees, so on a busy host the series count scales with container density (and short-lived containers add churn). Scope it to the containers you care about: - `excluded_images` on the receiver drops containers by image name. Each entry matches as a literal string, a glob (entries with `*`, `?`, `[]`, or `{}`), or a regex (wrapped in `/`), and a leading `!` negates the match. - A `filter` processor in the pipeline keeps or drops by `container.name` or image with full match expressions. - `container_labels_to_metric_labels` promotes Docker labels into resource attributes, which a `filter` processor can then match on: ```yaml showLineNumbers title="config/otel-collector.yaml (receiver section)" receivers: docker_stats: endpoint: unix:///var/run/docker.sock collection_interval: 10s excluded_images: - otel/opentelemetry-collector-contrib container_labels_to_metric_labels: com.docker.compose.service: compose_service ``` Each metric also carries `container.id`, `container.name`, `container.image.name`, `container.runtime`, and `container.hostname` resource attributes that identify the source container. ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify collector and Docker metrics" # Check Collector logs for a successful start / connection docker logs otel-collector 2>&1 | grep -i "docker" # Verify the socket is mounted and readable docker exec otel-collector ls -la /var/run/docker.sock # Confirm per-container metrics are flowing docker logs otel-collector 2>&1 | grep "container." ``` ### Troubleshooting #### Permission denied on the Docker socket **Cause**: The Collector process cannot read `/var/run/docker.sock`. **Fix**: 1. Verify the socket is mounted: `docker exec otel-collector ls -la /var/run/docker.sock`. 2. Run the Collector as a user that can read the socket - add `user: "0:0"` to the service definition, or use a read-only socket proxy that the Collector reads over TCP. 3. On Linux, confirm the host user is in the `docker` group: `groups $(whoami)`. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `docker_stats` receiver and the `otlphttp/b14` exporter. #### Too many containers reported **Cause**: The receiver enumerates every running container the daemon sees, including system and sidecar containers you do not need to monitor, which inflates the series count. **Fix**: 1. Add image prefixes to `excluded_images` on the receiver. 2. Add a `filter` processor on `container.name` or image to keep only the containers you care about. 3. Promote a Docker label with `container_labels_to_metric_labels` and filter on it (for example keep one Compose project). #### `container.cpu.limit` or `container.memory.percent` looks meaningless **Cause**: These metrics are limit-relative. `container.cpu.limit` is emitted only when the container has a CPU quota (`--cpus` / `cpus:`), and `container.memory.percent` is computed against host memory when no memory limit is set - so it is not a true OOM-risk signal there. **Look at**: `container.memory.usage.total` vs `container.memory.usage.limit` to see whether a per-container memory limit is actually configured. **Fix**: 1. Set a memory limit (`--memory` / `mem_limit:`) so `container.memory.percent` reads against the container's own ceiling. 2. Set a CPU quota (`--cpus` / `cpus:`) if you want `container.cpu.limit` and meaningful throttling context. #### cgroup-v1 memory or block I/O fields are missing **Cause**: The memory and block-I/O breakdown is cgroup-version-dependent. On a cgroup v2 host, the v1-only fields (`container.memory.rss`, `container.memory.cache`, `container.memory.swap`, `container.blockio.io_serviced_recursive`) are not emitted. **Look at**: the cgroup-v2 equivalents - `container.memory.anon` (anonymous) and `container.memory.file` (page cache) for the memory breakdown. **Fix**: Use the v2 fields in your dashboards and alerts on a v2 host; do not expect the v1-only series to appear. ### FAQ #### Does this work in Kubernetes? Prefer the `kubeletstats` receiver or cAdvisor for per-container metrics in Kubernetes. The `docker_stats` receiver targets the Docker daemon socket on a host, and on a containerd-based cluster there is no Docker socket to read. #### How do I monitor multiple Docker hosts? Run one Collector per Docker host, each with a `docker_stats` receiver pointed at that host's local socket. The `container.hostname` resource attribute distinguishes the source host in Scout. #### Why is there no `up` metric? The receiver reads the Docker Engine API, not a scrape endpoint, so there is no scrape `up` series. A stopped container disappears from the output. Read liveness from `container.uptime` (a drop toward 0 is an unplanned restart) and `container.restarts` (a rising count is a crash loop). #### Is mounting the Docker socket a security risk? Yes - read access to `/var/run/docker.sock` is equivalent to root on the host. Mount it read-only (`:ro`), exclude the Collector's own image to avoid recursive collection, and prefer a read-only socket proxy in production so the Collector reaches only the container-stats endpoints. ### Related Guides - [cAdvisor Monitoring](./cadvisor.md) - Per-container metrics from cAdvisor's Prometheus surface, the usual choice on Kubernetes nodes. - [Nginx Monitoring](./nginx.md) - A common containerized companion to monitor alongside. - [Redis Monitoring](./redis.md) - Monitor Redis running in your Docker environment. - [PostgreSQL Monitoring](./postgres.md) - Monitor PostgreSQL running in your Docker environment. - [OTel Collector Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Docker container metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Redis](./redis.md), [PostgreSQL](./postgres.md), and other components running in your Docker environment. - **Fine-tune Collection**: Scope the receiver with `excluded_images` or a `filter` processor to match your container density, and reach for the Diagnostic tier during incident investigation. --- ## DragonflyDB OpenTelemetry Monitoring - Command Throughput, Cache Hit Ratio, and Collector Setup ## DragonflyDB DragonflyDB is a Redis-compatible in-memory data store: same Redis wire protocol and cache model, different engine. If you already run Redis, the cache side is familiar - what changes is the telemetry. DragonflyDB has a **native, built-in Prometheus endpoint** served by the database process itself on the **main port `:6379`** at `/metrics` (prefix `dragonfly_*`). HTTP and the Redis protocol are **multiplexed on the same port** (`--primary_port_http_enabled` is on by default), so a plain `GET :6379/metrics` returns Prometheus text while RESP clients use the same port - no admin port, no flag to enable, no exporter to install. The OpenTelemetry Collector scrapes that endpoint directly with the `prometheus` receiver and collects 105 `dragonfly_*` metrics covering command throughput, cache hit/miss ratio, memory saturation, the request pipeline, the shared-nothing fiber runtime, and replication link health. This guide configures the scrape, points it at the native endpoint, and ships metrics to base14 Scout. This is the Redis-compatible delta on [Redis](./redis.md). Read that guide for the cache model; read this one for what is different - the telemetry mechanism and the single vertical-scale, shared-nothing architecture (plus an optional primary/replica replication family). ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | DragonflyDB | 1.x | 1.39.0+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - DragonflyDB must be running with its native Prometheus endpoint reachable on `:6379` from the host running the Collector. The endpoint is on by default (`--primary_port_http_enabled`); no admin port or extra flag is needed. - No monitoring user or credentials - the metrics endpoint needs no Redis `AUTH` and is not behind `requirepass` (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor DragonflyDB speaks the Redis wire protocol, so the cache model is familiar. What is new is the telemetry: the entire metric surface is `dragonfly_*` served natively from `:6379/metrics`, not the `redis.*` semantic-convention names the `redis` receiver builds from `INFO` and `COMMAND`. Because DragonflyDB is a single vertical-scale, shared-nothing multi-threaded C++ process, there are **no `jvm_*`, `go_*`, or `process_*` runtime families** - that whole runtime surface is absent, and in its place sit the fiber-runtime and request-pipeline families that have no Redis analogue. A basic run is one process with no cluster bootstrap and no replication factor; replication is optional (`--replicaof`), and when a replica is attached the replication family emits. Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `dragonfly_commands_processed_total` | Total commands the instance has served - the throughput liveness KPI. The native-Prometheus delta on Redis's `redis.commands`. | | `dragonfly_connected_clients` | Current client connections - connection load and a liveness signal; it falls to near zero when nothing can reach the instance. | | `dragonfly_keyspace_hits_total`, `dragonfly_keyspace_misses_total` | Lookups that found vs missed a key - the cache hit-ratio headline. A falling ratio means more work is reaching the slow path. | | `dragonfly_memory_used_bytes` (vs `dragonfly_memory_max_bytes`) | Bytes the dataset occupies against the configured ceiling - the memory-saturation anchor. | | `dragonfly_master_link_status` | Replica → primary replication link health (gauge: `1` = up). The HA headline - `0` means the replica is detached and serving stale data. Replica-only; no single-node analogue in Redis. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `dragonfly_connected_replica_lag_records` | Primary-side: how many records the replica is behind - the replication-lag / RPO signal. Rising means the replica cannot keep up. | | `dragonfly_master_last_io_seconds_ago`, `dragonfly_master_sync_in_progress` | Replica-side: seconds since the last master I/O, and whether a full resync is running. Rising `last_io` (or a stuck `sync_in_progress`) means the stream is stalling even if the link still reports up. | | `dragonfly_replica_reconnect_count` | Replica reconnects to the primary - churn here flags an unstable link or a flapping primary. | | `dragonfly_expired_keys_total`, `dragonfly_db_keys_expiring` | TTL expiry rate and the count of keys carrying a TTL - sudden swings change the live working set. | | `dragonfly_db_keys`, `dragonfly_db_capacity` | Live key count and hash-table capacity per database - dataset growth and headroom. | | `dragonfly_blocked_clients`, `dragonfly_max_clients` | Clients parked on blocking commands, and the connection ceiling - connection-pool saturation. | | `dragonfly_pipeline_queue_length`, `dragonfly_pipeline_queue_bytes`, `dragonfly_pipeline_throttle_total` | Request-pipeline depth and throttling - backpressure on the dispatch path; latency follows when these rise. | | `dragonfly_memory_used_peak_bytes`, `dragonfly_used_memory_rss_bytes`, `dragonfly_swap_memory_bytes` | Peak dataset bytes, resident set, and any swap - process-level memory pressure. Sustained swap is a latency cliff. | | `dragonfly_net_input_bytes_total`, `dragonfly_net_output_bytes_total` | Network bytes in/out - traffic volume and a saturation signal against the link. | | `dragonfly_script_error_total`, `dragonfly_listener_accept_error_total` | Lua script failures and connection-accept errors - application-side and listener-side error signals. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. In production you can drop this tier with `metric_relabel_configs` and keep Core plus Operational. These are grouped families, not individual rows - the counts are the distinct `dragonfly_*` names in each family of the 105 total. | Family | Count | What it covers | |---|---|---| | `dragonfly_memory_*` / `used_memory` / `interned_string` / `type_used` / `swap` | 14 | Allocator occupancy, RSS, peak, per-class, interned-string dedup cache, swap. | | `dragonfly_pipeline_*` | 13 | Request pipeline: dispatch, queue depth/wait, latency, throttle, cmd cache. DragonflyDB's request-multiplexing machinery (no Redis analogue). | | `dragonfly_commands_*` / `cmd_squash_*` / `reply_*` / `transaction_*` | 12 | Command + reply counters/durations, the command-squashing optimizer, multi-key transaction widths. | | replication (`master*` / `replication_*` / `slave_repl_offset` / `replica_reconnect_count` / `connected_replica_lag_records`) | 10 | Primary/replica roles, link health, sync, offset, lag, and the primary-side stream. | | fiber / scheduler (`fiber_*` / `fibers_count` / `blocked_tasks` / `tx_queue_len` / `dispatch_queue_bytes` / `send_delay`) | 9 | The shared-nothing fiber runtime: long-running fibers, context switches, blocked tasks, transaction-queue length, send delay (no Redis analogue). | | keyspace + db (`keyspace_*` / `db_*` / `expired_keys`) | 7 | Hits/misses/mutations, per-db keys/capacity/expiring, total expired. | | clients / connections (`connected_clients` / `blocked_clients` / `max_clients` / `connections_*` / `client_read_buffer` / `listener_accept_error`) | 7 | Connection counts, blocking, ceiling, per-client-library split, read-buffer bytes, accept errors. | | `dragonfly_tiered_*` | 6 | SSD offload tier: bytes/entries/events/hits/list-events/overload (reads ~0 unless tiering is configured). | | lua (`lua_*` / `script_error`) | 6 | Lua interpreter: blocked scripts, forced GC, interpreter count, script errors. | | backup / restore (`backups_*` / `restores_*` / `snapshot_serialization`) | 5 | Save/load operations and snapshot serialization (reads ~0 unless a save/load is triggered). | | `dragonfly_net_*` | 4 | Network in/out bytes, receive count, reactor read-yields. | | `dragonfly_defrag_*` | 4 | Active-defragmentation attempts/invocations/objects-moved/skipped. | | list compression (`list_*` / `huffman_tables_built`) | 4 | List-object compression: compressed bytes, attempts, reads, Huffman tables. | | `dragonfly_tls_*` | 2 | TLS bytes and handshakes (reads ~0 without TLS). | | build / uptime (`version` / `uptime_in_seconds`) | 2 | Reported build version label and process uptime. | Full metric surface: run `curl -s http://localhost:6379/metrics` against any DragonflyDB instance. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `dragonfly_master_link_status` (on the replica) | `== 0` briefly | `== 0` sustained | The replication link is down; the replica is serving stale data and cannot fail over cleanly. | | `dragonfly_connected_replica_lag_records` | Rising | Not draining | The replica is falling behind the primary; the recovery point is widening. | | `dragonfly_master_last_io_seconds_ago` (on the replica) | Rising | Sustained climb | Master I/O is stalling even if the link still reports up; the stream is not flowing. | | `rate(dragonfly_commands_processed_total)` | Falling under expected load | `≈ 0` sustained | The instance has stopped serving; check `dragonfly_connected_clients` and the healthcheck. | | `dragonfly_keyspace_misses_total / (hits + misses)` | Rising vs baseline | Sustained climb | Cache hit ratio dropping, relative to the workload's normal hit ratio; review key TTLs and access patterns. | | `dragonfly_memory_used_bytes / dragonfly_memory_max_bytes` | Rising vs baseline | Approaching 1.0 | Memory saturation; eviction or OOM risk follows. Raise the ceiling or scale out. | | `dragonfly_blocked_clients`, or `dragonfly_connected_clients` near `dragonfly_max_clients` | Rising vs baseline | Near the ceiling | Connection-pool saturation; raise `max_clients` or fix a client connection leak. | | `dragonfly_pipeline_queue_length`, `dragonfly_pipeline_throttle_total` | Rising | Not draining | Request-pipeline backpressure; command latency follows. | | `rate(dragonfly_script_error_total)` | > 0 | Sustained > 0 | Lua scripts are failing; check the script and its inputs. | | `dragonfly_swap_memory_bytes` | > 0 | Sustained > 0 | The process is swapping; expect a latency cliff. Add memory or shed dataset. | ### Access Setup DragonflyDB's metrics endpoint needs **no exporter and no authentication**. The native Prometheus endpoint is served by the database process itself on the main port `:6379` at `/metrics`, multiplexed with the Redis protocol and on by default (`--primary_port_http_enabled`). There is no admin port to open, no flag to enable, and no sidecar to install - access setup is simply pointing the scrape at `:6379/metrics`. This is the structural delta over Redis. The `redis` receiver opens a TCP connection, issues the `AUTH` command, and parses `INFO`/`COMMAND` output; the DragonflyDB scrape is a plain HTTP `GET` on `:6379/metrics` and needs no Redis `AUTH` - the metrics endpoint is not behind `requirepass`. There is no JMX exporter, no Java agent, and no `INFO`/`COMMAND` parsing. In Docker, publish or network-attach `:6379` from each instance so the Collector can reach it. Verify the endpoint before wiring the Collector: ```bash showLineNumbers title="Verify access" # Confirm DragonflyDB is responding on the Redis protocol redis-cli -h localhost -p 6379 ping # Verify the native Prometheus endpoint on the same port curl -s http://localhost:6379/metrics | grep dragonfly_commands_processed_total ``` If you run a replica (`--replicaof=:6379`), expose its `:6379` the same way - the replica serves its own `/metrics`, including the replica-only replication family. ### Configuration The Collector uses the `prometheus` receiver to scrape the native endpoint. One scrape job (`job_name: dragonfly`) fans across both instances at `metrics_path: /metrics` on `:6379` - no `redis` receiver, no `endpoint: host:6379` block, no `AUTH` field, and no `redis.*` metrics. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: dragonfly scrape_interval: 15s metrics_path: /metrics static_configs: - targets: # One target per instance's native :6379 endpoint - dragonfly-primary:6379 - dragonfly-replica:6379 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` Each instance is identified by its `instance` label (`host:6379`). The primary carries `dragonfly_master=1` and the primary-side replication metrics; the replica carries `dragonfly_master=0` and the replica-only family (`dragonfly_master_link_status` and friends). For a single instance, drop the replica target. To control metric volume in production, drop the Diagnostic-tier families with a `metric_relabel_configs` block on the scrape config while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped DragonflyDB metrics docker logs otel-collector 2>&1 | grep -i "dragonfly" # Verify the native endpoint is serving metrics curl -s http://localhost:6379/metrics | grep dragonfly_keyspace_hits_total # Generate traffic so keyspace and hit/miss metrics populate redis-cli -h localhost -p 6379 set probe 1 redis-cli -h localhost -p 6379 get probe redis-cli -h localhost -p 6379 get missing-key ``` On the replica, `dragonfly_master_link_status` should read `1` and `dragonfly_master_sync_in_progress` should read `0` once it has caught up; `dragonfly_master=1` on the primary and `0` on the replica confirms the role split. ### Troubleshooting #### Metrics endpoint not responding on port 6379 **Cause**: The HTTP multiplexing on the main port is disabled, or `:6379` is not reachable between the instance and the Collector. **Fix**: 1. Confirm `--primary_port_http_enabled` is on (it is the default); a plain `curl -s http://localhost:6379/metrics` should return Prometheus text. 2. Confirm the Collector scrape target points at `:6379` with `metrics_path: /metrics`. 3. Check firewall and Docker network rules if the Collector runs on a separate host. #### The replica is serving stale data **Cause**: The replication link is down or the stream has stalled, so the replica is no longer tracking the primary. **Look at**: `dragonfly_master_link_status` on the replica (`0` means the link is down), `dragonfly_master_last_io_seconds_ago` (rising means the stream is stalling even if the link reports up), and `dragonfly_replica_reconnect_count` (churn flags an unstable link). On the primary, `dragonfly_connected_replica_lag_records` shows how far behind the replica is. **Fix**: 1. If `dragonfly_master_link_status` is `0`, check network reachability between the replica and the primary and the primary's health. 2. If `dragonfly_master_sync_in_progress` is stuck at `1`, a full resync is running; wait for it to finish or investigate why it restarts. #### Commands are slow or piling up **Cause**: The request pipeline is saturated, or memory pressure is forcing the process to swap. **Look at**: the Diagnostic `dragonfly_pipeline_*` family - `dragonfly_pipeline_queue_length` / `_queue_bytes` (dispatch backlog) and `dragonfly_pipeline_throttle_total` (the pipeline is shedding) - plus `dragonfly_fiber_*` and `dragonfly_send_delay_seconds` for fiber-runtime delay. For memory, `dragonfly_used_memory_rss_bytes` and `dragonfly_swap_memory_bytes` (sustained swap is a latency cliff). **Fix**: 1. If pipeline queues are sustained, shed load or scale out; profile the commands driving the backlog. 2. If swap is non-zero, add memory or reduce the dataset before latency degrades further. #### Hit ratio looks low or memory keeps climbing **Cause**: The access pattern is missing the cache, or the working set is approaching the configured ceiling. **Look at**: `dragonfly_keyspace_hits_total` / `dragonfly_keyspace_misses_total` for the ratio trend, `dragonfly_memory_used_bytes` against `dragonfly_memory_max_bytes` for the saturation fraction, and the Diagnostic `dragonfly_memory_*` family (`dragonfly_memory_used_peak_bytes`, `dragonfly_memory_by_class_bytes`) for where the memory is going. `dragonfly_expired_keys_total` and `dragonfly_db_keys_expiring` show whether TTL churn is reshaping the working set. **Fix**: 1. Review key TTLs and sizing for the workload driving misses. 2. Raise the memory ceiling or scale out if `used` is approaching `max`. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why is there no exporter or `redis` receiver like Redis? DragonflyDB serves a native Prometheus endpoint on the main port `:6379` at `/metrics`, multiplexed with the Redis protocol and on by default. You scrape it directly with the `prometheus` receiver - there is no exporter to install, no `redis` receiver, no TCP `AUTH`, and no `INFO`/`COMMAND` parsing. The entire metric surface is `dragonfly_*`, with no `jvm_*`, `go_*`, or `process_*` runtime families, because DragonflyDB is a single C++ process. #### Does the metrics endpoint need a password? No. The `/metrics` endpoint is not behind `requirepass` - the scrape is a plain HTTP `GET` on `:6379/metrics` and needs no Redis `AUTH`. Your RESP clients can still authenticate normally on the same port. #### Does this work with DragonflyDB running in Kubernetes? Yes. Point the scrape `targets` at each instance's service DNS on `:6379` (e.g., `dragonfly-primary.default.svc.cluster.local:6379`). The Collector can run as a sidecar or a Deployment. No credentials are needed for the metrics endpoint. #### Why are the replication metrics showing only on one instance? The replication family is instance-scoped. The replica-only metrics (`dragonfly_master_link_status`, `dragonfly_master_last_io_seconds_ago`, `dragonfly_master_sync_in_progress`, `dragonfly_slave_repl_offset`, `dragonfly_replica_reconnect_count`) emit on the replica; the primary-side metrics (`dragonfly_connected_replica_lag_records`, `dragonfly_replication_streaming_bytes`) emit on the primary. `dragonfly_master` is `1` on the primary and `0` on the replica. On a single instance with no `--replicaof`, the replication family stays quiet - this is expected. **Why are `dragonfly_tiered_*`, `dragonfly_tls_*`, or the backup counters reading zero?** They are available surface that only moves when the feature is in use: `dragonfly_tiered_*` when SSD tiering is configured, `dragonfly_tls_*` when TLS is enabled, and the backup/restore counters when a save/load is triggered. They are not missing - they populate when the corresponding feature is exercised. ### Related Guides - [Redis Monitoring](./redis.md) - The Redis-compatible counterpart; the `INFO`-based `redis`-receiver guide this is the native-telemetry delta on. - [CockroachDB Monitoring](./cockroachdb.md) - Distributed SQL database with a native Prometheus endpoint. - [YugabyteDB Monitoring](./yugabytedb.md) - Distributed SQL database with a native Prometheus endpoint. - [TiDB Monitoring](./tidb.md) - Distributed SQL database with per-component Prometheus metrics. - [ScyllaDB Monitoring](./scylladb.md) - Cassandra-compatible store with a native Prometheus endpoint. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on DragonflyDB metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Redis](./redis.md), [ScyllaDB](./scylladb.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## Elasticsearch OpenTelemetry Monitoring - Cluster Health, Heap Pressure, and Collector Setup ## Elasticsearch The OpenTelemetry Collector's `elasticsearchreceiver` connects to the Elasticsearch HTTP API and collects 90+ metrics across cluster health, node performance, index operations, segments and merges, thread pools, circuit breakers, indexing pressure, and JVM heap. It reads the cluster-health, node-stats, and index-stats APIs over a single endpoint on Elasticsearch 8.x and 9.x. This guide configures the receiver, verifies connectivity, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | -------------- | | Elasticsearch | 8.x | 9.x (9.1.3) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The Elasticsearch HTTP API (port 9200) must be reachable from the host running the Collector. - A user with access to the cluster stats APIs, if security is enabled (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things about this surface are worth knowing up front: - **Elasticsearch exposes a real health metric.** Unlike receivers that only carry an uptime counter, `elasticsearch.cluster.health` reports green / yellow / red through a `status` attribute - so you do not need an `up` series. Liveness is the receiver scraping the HTTP API successfully, and `elasticsearch.cluster.health` is the headline cluster-state signal. This receiver set exposes **no `up` series and no uptime counter**. - **One endpoint covers the whole cluster.** With `nodes: ["_all"]` the receiver queries the cluster stats APIs through a single endpoint and returns per-node series. You point one receiver at any node, not one per node. - **Some attributes are high-cardinality.** `elasticsearch.node.thread_pool.*` fan out across ~30 thread-pool names (`thread_pool_name`); `elasticsearch.breaker.*` across breaker `name` (`parent`, `fielddata`, `request`, `inflight_requests`, ...); `elasticsearch.node.operations.*` across `operation` (index / query / get / fetch / scroll / delete). - **Many metrics are disabled by default.** The receiver ships most of its catalogue off, so the `metrics:` enable list in the [Configuration](#configuration) is required. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `elasticsearch.cluster.health` | Cluster health by `status` (green / yellow / red) - the headline cluster-state signal. No `up` on this surface; this is the health signal. | | `elasticsearch.cluster.shards` | Shards by state (active / relocating / initializing / unassigned). Unassigned or initializing = degraded allocation. | | `elasticsearch.node.operations.completed`, `elasticsearch.node.operations.time` | Per-node operations and time by `operation` - the serving throughput and latency KPI. | | `jvm.memory.heap.utilization` | Heap used as a fraction of max - the dominant Elasticsearch saturation signal. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `elasticsearch.cluster.pending_tasks` | Cluster-level tasks awaiting the master; rising = master / cluster-state overload. | | `elasticsearch.node.thread_pool.tasks.queued`, `.tasks.finished`, `.threads` | Thread-pool queue depth, completions, and threads by `thread_pool_name` - search / write queue backup and rejections. | | `elasticsearch.breaker.tripped` | Circuit breakers tripped by `name` - memory-protection events rejecting requests. | | `elasticsearch.node.fs.disk.available`, `.free` | Free disk on the data path - drives the disk watermarks; writes block at flood stage. | | `elasticsearch.indexing_pressure.memory.total.primary_rejections`, `.replica_rejections` | Write requests rejected by indexing back-pressure - ingest overload. | | `elasticsearch.index.operations.completed`, `.time` | Per-index operation counts and time by `operation` - index-level throughput and latency. | | `elasticsearch.node.cache.evictions` | Query / fielddata / request cache evictions by cache `name` - cache pressure. | | `jvm.gc.collections.count`, `.elapsed` | GC collections and elapsed time by collector; rising old-gen GC time = heap thrash. | | `elasticsearch.node.translog.operations`, `.uncommitted.size` | Translog operations and uncommitted bytes - fsync / recovery cost. | | `elasticsearch.os.cpu.usage`, `elasticsearch.os.cpu.load_avg.1m` / `.5m` / `.15m` | Node CPU usage and load averages - host saturation. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. The groups below are representative, not exhaustive - see the [upstream receiver reference](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/elasticsearchreceiver) for the full list. | Group | Representative metrics | When you reach for it | |---|---|---| | Cluster-state internals | `elasticsearch.cluster.nodes`, `.data_nodes`, `.in_flight_fetch`, `.state_queue`, `.state_update.count` / `.time` | Master and cluster-state churn during membership or allocation events. | | Node I/O and networking | `elasticsearch.node.disk.io.read` / `.io.write`, `elasticsearch.node.http.connections`, `elasticsearch.node.open_files`, `elasticsearch.node.fs.disk.total` | Disk, transport, and file-descriptor saturation on a node. | | Segments and merges | `elasticsearch.index.segments.count` / `.size` / `.memory`, `elasticsearch.index.operations.merge.current` | Lucene segment and merge load behind slow indexing or large heap use. | | Index and node sizing | `elasticsearch.index.documents`, `.shards.size`, `elasticsearch.node.documents`, `elasticsearch.node.shards.size` | Per-index and per-node growth during a capacity review. | | Cache internals | `elasticsearch.index.cache.evictions` / `.memory.usage` / `.size`, `elasticsearch.node.cache.count` / `.size` | Query / fielddata / request cache behaviour at index and node scope. | | Ingest pipelines | `elasticsearch.node.ingest.documents`, `.ingest.operations.failed`, `.pipeline.ingest.documents.preprocessed` | Ingest-node and per-pipeline throughput and failures. | | Scripting | `elasticsearch.node.script.compilations`, `.script.cache_evictions`, `.script.compilation_limit_triggered` | Script compile churn and compile-limit pressure. | | GET operations | `elasticsearch.node.operations.get.completed` / `.get.time`, `elasticsearch.node.operations.current` | GET latency and in-flight operations. | | JVM internals | `jvm.memory.heap.used` / `.heap.committed` / `.heap.max`, `jvm.memory.pool.used`, `jvm.classes.loaded`, `jvm.threads.count` | Heap composition and JVM thread / class growth. | | OS and process | `elasticsearch.os.memory`, `elasticsearch.process.cpu.usage`, `.process.memory.virtual` | Host memory and the ES process footprint. | | Breaker memory | `elasticsearch.breaker.memory.estimated`, `.memory.limit` | How close each breaker is to its limit before it trips. | | Indexing-pressure memory | `elasticsearch.indexing_pressure.memory.limit`, `elasticsearch.memory.indexing_pressure` | Current indexing-pressure bytes against the limit. | | Translog sizing | `elasticsearch.index.translog.operations` / `.translog.size`, `elasticsearch.node.translog.size` | Translog growth at index and node scope. | ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. Several of these read an Elasticsearch state flag (cluster health, unassigned shards, a tripped breaker) rather than an absolute number; the rest are relative to your own baseline. These are starting points - tune them to your workload. | Alert | Condition | Why it matters | |---|---|---| | Elasticsearch unreachable | The `elasticsearch` receiver produces no data for > 1m | No `up` on this surface - scrape success plus cluster health are liveness. Check the node and the receiver connection. | | Cluster not green | `elasticsearch.cluster.health{status=red}` present, or `{status=yellow}` sustained | Red = primaries unassigned (data unavailable); yellow = replicas unassigned. Check allocation and node membership. | | Unassigned shards | `elasticsearch.cluster.shards{state=unassigned}` > 0 | Shards cannot be allocated - disk watermarks, node loss, or allocation rules. | | Heap pressure | `jvm.memory.heap.utilization` sustained high vs baseline, with `rate(jvm.gc.collections.elapsed)` rising | Old-gen GC thrash precedes OOM and node drop. Reduce load, add heap / nodes, or review queries. | | Disk watermark | `elasticsearch.node.fs.disk.available` falling toward the flood-stage watermark | At flood stage ES blocks writes and sets indices read-only. Free disk or add capacity. | | Thread-pool backup | `elasticsearch.node.thread_pool.tasks.queued` rising vs baseline | Search / write queues filling - rejections follow. Correlate with CPU and slow queries. | | Circuit breaker tripped | `rate(elasticsearch.breaker.tripped)` > 0 | A breaker is rejecting requests to prevent OOM - usually fielddata or request memory. | | Indexing rejections | `rate(elasticsearch.indexing_pressure.memory.total.primary_rejections)` > 0 | Write back-pressure is rejecting indexing. Slow the producers or scale write capacity. | ### Access Setup The receiver reads the cluster-health, node-stats, and index-stats APIs over the Elasticsearch HTTP API on port 9200. No special user creation is required - any user with access to the cluster stats APIs works. Verify the endpoint is reachable. If security is enabled, supply credentials: ```bash showLineNumbers title="Verify Elasticsearch access" # Check cluster health curl -u ${ES_USERNAME}:${ES_PASSWORD} \ http://:9200/_cluster/health?pretty # Check node info curl -u ${ES_USERNAME}:${ES_PASSWORD} \ http://:9200/_nodes?pretty ``` If security is disabled (development clusters), no auth is needed: ```bash showLineNumbers title="Verify access (no auth)" curl http://:9200/_cluster/health?pretty ``` In production, pass credentials through the `ES_USERNAME` / `ES_PASSWORD` environment variables shown in the [Configuration](#configuration). ### Configuration Most `elasticsearchreceiver` metrics are disabled by default, so the `metrics:` enable list below is required - it is the curated set this guide collects. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: elasticsearch: endpoint: http://:9200 # Your Elasticsearch HTTP API collection_interval: 15s username: ${env:ES_USERNAME} password: ${env:ES_PASSWORD} nodes: ["_all"] # Whole cluster through one endpoint skip_cluster_metrics: false indices: ["_all"] # Scope index-level series (see FAQ) tls: insecure_skip_verify: true metrics: # Cluster metrics elasticsearch.cluster.health: enabled: true elasticsearch.cluster.nodes: enabled: true elasticsearch.cluster.data_nodes: enabled: true elasticsearch.cluster.shards: enabled: true elasticsearch.cluster.pending_tasks: enabled: true elasticsearch.cluster.in_flight_fetch: enabled: true elasticsearch.cluster.state_queue: enabled: true elasticsearch.cluster.published_states.full: enabled: true elasticsearch.cluster.published_states.differences: enabled: true elasticsearch.cluster.state_update.count: enabled: true elasticsearch.cluster.state_update.time: enabled: true # Node metrics - disk and filesystem elasticsearch.node.fs.disk.available: enabled: true elasticsearch.node.fs.disk.free: enabled: true elasticsearch.node.fs.disk.total: enabled: true elasticsearch.node.disk.io.read: enabled: true elasticsearch.node.disk.io.write: enabled: true # Node metrics - cache elasticsearch.node.cache.count: enabled: true elasticsearch.node.cache.evictions: enabled: true elasticsearch.node.cache.memory.usage: enabled: true elasticsearch.node.cache.size: enabled: true # Node metrics - operations elasticsearch.node.operations.completed: enabled: true elasticsearch.node.operations.time: enabled: true elasticsearch.node.operations.current: enabled: true elasticsearch.node.operations.get.completed: enabled: true elasticsearch.node.operations.get.time: enabled: true # Node metrics - networking and connections elasticsearch.node.http.connections: enabled: true elasticsearch.node.cluster.connections: enabled: true elasticsearch.node.cluster.io: enabled: true elasticsearch.node.open_files: enabled: true # Node metrics - ingest pipeline elasticsearch.node.ingest.documents: enabled: true elasticsearch.node.ingest.documents.current: enabled: true elasticsearch.node.ingest.operations.failed: enabled: true elasticsearch.node.pipeline.ingest.documents.current: enabled: true elasticsearch.node.pipeline.ingest.documents.preprocessed: enabled: true elasticsearch.node.pipeline.ingest.operations.failed: enabled: true # Node metrics - documents and shards elasticsearch.node.documents: enabled: true elasticsearch.node.shards.size: enabled: true elasticsearch.node.shards.data_set.size: enabled: true elasticsearch.node.shards.reserved.size: enabled: true # Node metrics - thread pools elasticsearch.node.thread_pool.tasks.finished: enabled: true elasticsearch.node.thread_pool.tasks.queued: enabled: true elasticsearch.node.thread_pool.threads: enabled: true # Node metrics - translog elasticsearch.node.translog.operations: enabled: true elasticsearch.node.translog.size: enabled: true elasticsearch.node.translog.uncommitted.size: enabled: true # Node metrics - scripts elasticsearch.node.script.compilations: enabled: true elasticsearch.node.script.cache_evictions: enabled: true elasticsearch.node.script.compilation_limit_triggered: enabled: true # Node metrics - segments elasticsearch.node.segments.memory: enabled: true # Circuit breaker metrics elasticsearch.breaker.memory.estimated: enabled: true elasticsearch.breaker.memory.limit: enabled: true elasticsearch.breaker.tripped: enabled: true # Indexing pressure metrics elasticsearch.indexing_pressure.memory.limit: enabled: true elasticsearch.indexing_pressure.memory.total.primary_rejections: enabled: true elasticsearch.indexing_pressure.memory.total.replica_rejections: enabled: true elasticsearch.memory.indexing_pressure: enabled: true # Index metrics elasticsearch.index.documents: enabled: true elasticsearch.index.operations.completed: enabled: true elasticsearch.index.operations.time: enabled: true elasticsearch.index.operations.merge.current: enabled: true elasticsearch.index.operations.merge.docs_count: enabled: true elasticsearch.index.operations.merge.size: enabled: true elasticsearch.index.segments.count: enabled: true elasticsearch.index.segments.size: enabled: true elasticsearch.index.segments.memory: enabled: true elasticsearch.index.shards.size: enabled: true elasticsearch.index.cache.evictions: enabled: true elasticsearch.index.cache.memory.usage: enabled: true elasticsearch.index.cache.size: enabled: true elasticsearch.index.translog.operations: enabled: true elasticsearch.index.translog.size: enabled: true # OS metrics elasticsearch.os.cpu.usage: enabled: true elasticsearch.os.cpu.load_avg.1m: enabled: true elasticsearch.os.cpu.load_avg.5m: enabled: true elasticsearch.os.cpu.load_avg.15m: enabled: true elasticsearch.os.memory: enabled: true # Process metrics elasticsearch.process.cpu.usage: enabled: true elasticsearch.process.cpu.time: enabled: true elasticsearch.process.memory.virtual: enabled: true # JVM metrics jvm.classes.loaded: enabled: true jvm.gc.collections.count: enabled: true jvm.gc.collections.elapsed: enabled: true jvm.memory.heap.committed: enabled: true jvm.memory.heap.max: enabled: true jvm.memory.heap.used: enabled: true jvm.memory.heap.utilization: enabled: true jvm.memory.nonheap.committed: enabled: true jvm.memory.nonheap.used: enabled: true jvm.memory.pool.max: enabled: true jvm.memory.pool.used: enabled: true jvm.threads.count: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [elasticsearch] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ES_USERNAME=elastic ES_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for the Elasticsearch receiver docker logs otel-collector 2>&1 | grep -i "elasticsearch" # Check cluster health directly curl -u ${ES_USERNAME}:${ES_PASSWORD} \ http://:9200/_cluster/health?pretty # Check node stats curl -u ${ES_USERNAME}:${ES_PASSWORD} \ http://:9200/_nodes/stats?pretty ``` ```bash showLineNumbers title="Check index and cluster stats" # Check index stats curl -u ${ES_USERNAME}:${ES_PASSWORD} \ http://:9200/_stats?pretty # Check shard allocation curl -u ${ES_USERNAME}:${ES_PASSWORD} \ http://:9200/_cat/allocation?v ``` ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach Elasticsearch at the configured endpoint. **Fix**: 1. Verify Elasticsearch is running: `systemctl status elasticsearch` or `docker ps | grep elasticsearch`. 2. Confirm the HTTP API port (default 9200) is accessible. 3. Check `network.host` in `elasticsearch.yml` if the Collector runs on a separate host. #### Authentication failed (401) **Cause**: Credentials are incorrect, or security is enabled but credentials are not configured. **Fix**: 1. Test credentials directly: `curl -u user:pass http://localhost:9200/_cluster/health`. 2. Verify the user exists and has access to the stats APIs. 3. Check the `ES_USERNAME` and `ES_PASSWORD` environment variables. #### Cluster reads yellow or red **Cause**: Shards cannot be allocated - a lost node, a disk watermark, or an allocation rule. **Look at**: `elasticsearch.cluster.health{status}` for the colour, `elasticsearch.cluster.shards{state=unassigned}` for how many shards are stranded, and `elasticsearch.node.fs.disk.available` to rule out a disk watermark. **Fix**: 1. Check `_cluster/allocation/explain` for the per-shard reason. 2. Free disk or add capacity if a watermark is the cause. 3. Restore node membership if a node dropped. #### Indexing is slow or rejected **Cause**: Write back-pressure, a saturated write thread pool, or merge load. **Look at**: `elasticsearch.indexing_pressure.memory.total.primary_rejections` (rejected writes), `elasticsearch.node.thread_pool.tasks.queued` (write queue depth), and `elasticsearch.index.operations.merge.current` (merge load behind slow indexing). **Fix**: 1. Slow the producers or scale write capacity if rejections appear. 2. Correlate queue depth with CPU and heap before raising pool sizes. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Elasticsearch running in Kubernetes? Yes. Set `endpoint` to the Elasticsearch service DNS (e.g. `http://elasticsearch.default.svc.cluster.local:9200`) and inject credentials through a Kubernetes secret. The Collector can run as a sidecar or a Deployment. #### How do I monitor a multi-node Elasticsearch cluster? Set `nodes: ["_all"]`. The receiver queries the cluster stats APIs through a single endpoint and returns per-node series for the whole cluster, so one receiver pointing at any node covers every node. You do not run one receiver per node. #### Does this work with Elasticsearch 9.x? Yes. The `elasticsearchreceiver` supports Elasticsearch 7.9 and later, including 8.x and 9.x. No collector version is specific to 9.x - run a current OTel Collector Contrib build. #### What about OpenSearch - does the same receiver work? No. OpenSearch diverged from Elasticsearch and returns different stats API responses, so the `elasticsearchreceiver` does not support it. OTel Collector Contrib does not ship an OpenSearch metrics receiver - collect OpenSearch metrics through its own Prometheus plugin or monitoring APIs instead. #### Can I limit which indices are monitored? Yes. Change `indices: ["_all"]` to a specific list, for example `indices: ["my-index-*", "logs-*"]`. This scopes which indices emit index-level series; cluster and node metrics are unaffected. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Elasticsearch metrics. - [PostgreSQL Monitoring](./postgres.md) - Relational store behind the same services you search. - [Redis Monitoring](./redis.md) - In-memory cache fronting the search path. - [ElastiCache Monitoring](../infra/aws/elasticache.md) - Managed Redis / Memcached cache monitoring on AWS. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [Redis](./redis.md), and other components. - **Tune Collection**: Scope `indices` to the index patterns you care about, and keep the Diagnostic tier available for incident investigation. --- ## Envoy OpenTelemetry Monitoring - Downstream Requests, Upstream Health, and Collector Setup ## Envoy Envoy exposes Prometheus-format metrics at its admin interface `/stats/prometheus` (default `:9901`) when the `admin` block is configured in the bootstrap config. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint, collecting 300+ metrics across downstream connections and HTTP requests, listeners, server state, cluster membership and management, and upstream traffic. The exact count grows with the number of listeners, clusters, and routes. This guide configures the receiver, enables the admin interface, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Envoy | 1.20 | 1.32 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The Envoy admin interface port (9901) must be reachable from the host running the Collector. - The `admin` block must be configured in the Envoy bootstrap config. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. All rows trace to the metrics Envoy emits on this surface. A few things to keep in mind across all three tiers: - `up` is the liveness signal here - the `prometheus` receiver emits `up == 1` when the admin endpoint responds. `envoy_server_state` is the in-process health signal: `0` = LIVE, `1` = DRAINING, `2` = PRE_INITIALIZING, `3` = INITIALIZING. Use `up` for "is it reachable" and `envoy_server_state == 0` for "is it actually serving" - not `envoy_server_live`, which sits in the Operational tier as a restart flag. - Envoy is C++, not Go, so the endpoint exposes no `go_*` or `process_*` series. The only non-`envoy_` names are `up` and the `scrape_*` meta, so the noise floor is much smaller than on the Go-based proxies and control planes. - Upstream cluster metrics (`envoy_cluster_*`) only appear when Envoy has configured clusters with active endpoints. A direct-response or passthrough config emits no cluster-level metrics. - The admin endpoint accepts a `usedonly` query parameter that omits stats that have never been updated since startup. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape liveness - `1` means the Envoy admin endpoint responded. The liveness signal on this surface. | | `envoy_server_state` | Server health state (`0` = LIVE, `1` = DRAINING, `2` = PRE_INITIALIZING, `3` = INITIALIZING) - the "is Envoy serving" signal. | | `envoy_http_downstream_rq_total` | Total client requests at the listener - edge throughput. | | `envoy_http_downstream_rq_xx` | Client requests by status class (split by `envoy_response_code_class`) - the edge error rate. | | `envoy_cluster_membership_healthy` | Healthy upstream endpoints per cluster - `0` means all backends for that cluster are down. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Server liveness | `envoy_server_live`, `envoy_server_uptime` | Liveness flag and seconds since start; a reset flags a restart. | | Server memory | `envoy_server_memory_allocated`, `envoy_server_memory_heap_size` | Allocated memory versus heap size - memory saturation. | | Server load | `envoy_server_total_connections`, `envoy_server_concurrency`, `envoy_server_days_until_first_cert_expiring` | Active connections, worker concurrency, and days until the soonest TLS cert expires. | | Downstream latency | `envoy_http_downstream_rq_time` | Client-request latency at the listener (histogram) - headline latency. | | Downstream requests | `envoy_http_downstream_rq_active`, `envoy_http_downstream_rq_completed` | In-flight and completed client requests. | | Downstream connections | `envoy_http_downstream_cx_total`, `envoy_http_downstream_cx_active`, `..._rx_bytes_total`, `..._tx_bytes_total` | Downstream connection count and bandwidth. | | Upstream requests | `envoy_cluster_upstream_rq_total`, `..._xx`, `..._active`, `..._completed` | Proxied requests to backends, by status class and in-flight - backend volume and errors. | | Upstream latency | `envoy_cluster_upstream_rq_time` | Backend response latency (histogram) - isolates a slow backend from a slow proxy. | | Backend flakiness | `envoy_cluster_upstream_rq_timeout`, `envoy_cluster_upstream_rq_retry` | Backend request timeouts and retries. | | Upstream connections | `envoy_cluster_upstream_cx_active`, `..._total`, `..._connect_fail`, `..._rx_bytes_total`, `..._tx_bytes_total` | Upstream connection count, connect failures, and bandwidth. | | Pool backpressure | `envoy_cluster_upstream_cx_overflow`, `envoy_cluster_upstream_rq_pending_overflow` | Connection-pool / pending-request overflow - circuit-breaker backpressure. | | Circuit breakers | `envoy_cluster_circuit_breakers_default_cx_open`, `..._rq_open`, `..._rq_pending_open`, `..._rq_retry_open`, `..._cx_pool_open` (and `high_*`) | Circuit-breaker state - `1` means open (Envoy is shedding load on that pool). | | Membership | `envoy_cluster_membership_total`, `..._degraded`, `..._change`, `..._excluded` | Upstream endpoint pool size, degraded count, and membership churn. | | Listener and cluster counts | `envoy_listener_downstream_cx_active`, `envoy_listener_manager_total_listeners_active`, `envoy_cluster_manager_active_clusters` | Active listener connections, active listeners, and active clusters. | #### Diagnostic - for investigation and tuning Higher cardinality; the deep internals you reach for during an incident or a capacity review. These families are large - each carries an `envoy_cluster_name`, `envoy_listener_address`, or stat-prefix label, so series multiply per cluster, per listener, and per virtual host. The representative members below stand in for the family, not the full list. | Group | Representative metrics | When you reach for it | |---|---|---| | Per-cluster upstream internals | `envoy_cluster_upstream_cx_connect_timeout`, `envoy_cluster_upstream_rq_rx_reset`, `envoy_cluster_upstream_rq_cancelled` | Drilling into a specific cluster's connection/request behaviour. | | Per-listener HTTP downstream internals | `envoy_http_downstream_cx_http1_total`, `envoy_http_downstream_rq_rx_reset`, `envoy_http_downstream_rq_too_large` | Listener-level codec/protocol behaviour. | | Load-balancer decisions | `envoy_cluster_lb_healthy_panic`, `envoy_cluster_lb_zone_routing_all_directly`, `envoy_cluster_lb_subsets_active` | Load-balancer routing and panic-mode internals. | | Cluster config machinery (CDS/EDS) | `envoy_cluster_manager_*`, `envoy_cluster_update_*`, `envoy_cluster_assignment_*` | xDS cluster discovery/update behaviour. | | Listener config machinery (LDS) | `envoy_listener_manager_*`, `envoy_listener_admin_*`, `envoy_listener_worker_*` | Listener-manager lifecycle and admin-listener stats. | | HTTP filter internals | `envoy_http_rq_*`, `envoy_http_tracing_*`, `envoy_http_no_route`, `envoy_http_no_cluster` | Connection-manager filter behaviour (tracing, no-route, no-cluster). | | Runtime and subsystem internals | `envoy_dns_cares_*`, `envoy_filesystem_write_*`, `envoy_runtime_*` | DNS resolver, filesystem flush, and runtime-layer internals. | | Server thread/allocator internals | `envoy_workers_watchdog_*`, `envoy_main_thread_*`, `envoy_server_hot_restart_*`, `envoy_tcmalloc_released` | Worker watchdog, hot-restart, and allocator behaviour. | | Build info | `envoy_server_version` | Build version carried in the value/labels - context, not a signal. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_series_added` | Prometheus scrape internals - receiver-side, not from Envoy. | Some families stay silent until their feature is configured - `envoy_cluster_health_check_*` need active health checks, `envoy_listener_ssl_*` and TLS handshake stats need a TLS transport socket, and the CDS/EDS/LDS update stats stay near zero with a static config (no xDS control plane). They appear once the feature is enabled. Full metric list: run `curl -s http://localhost:9901/stats/prometheus` against your Envoy instance with the admin interface enabled. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. The liveness and health alerts read states, not invented numbers; the error-rate and latency alerts are relative to your own baseline. These are starting points - tune them to your workload. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The admin endpoint stopped responding. Check the Envoy process and the admin port. | | `envoy_server_state` | `!= 0` | Envoy is draining or stuck initializing, not serving normally. Check config load and the init sequence. | | `envoy_cluster_membership_healthy` | `< envoy_cluster_membership_total` for a cluster | One or more backends in the cluster are down; at `0`, clients get 503s. Restore the backend or check health checks. | | `rate(envoy_http_downstream_rq_xx{envoy_response_code_class="5"})` | Rising versus baseline | Server-side errors at the edge - correlate with upstream errors to localize. | | `rate(envoy_cluster_upstream_rq_timeout)` | Rising versus baseline | Backends are timing out or slow - investigate the upstream service. | | `envoy_cluster_circuit_breakers_default_rq_open` or `..._cx_open` | `== 1` | Envoy hit a connection/request limit and is shedding load - raise limits or add backend capacity. | | `envoy_server_days_until_first_cert_expiring` | Low (for example, < 30) | A served certificate is approaching expiry - rotate it. | ### Access Setup Enable the admin interface by adding an `admin` block to the Envoy bootstrap configuration: ```yaml showLineNumbers title="envoy.yaml" admin: address: socket_address: address: 0.0.0.0 # Bind to localhost and restrict access in production port_value: 9901 ``` Bind the admin interface to `127.0.0.1` or restrict it with network policies in production - it can modify Envoy settings and trigger shutdown. The admin interface requires no authentication by default. For Docker deployments, mount the bootstrap config into the container at `/etc/envoy/envoy.yaml`. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # Check the Envoy admin interface curl -s http://localhost:9901/server_info | head -5 # Verify the Prometheus metrics endpoint curl -s http://localhost:9901/stats/prometheus | head -20 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: envoy scrape_interval: 30s metrics_path: /stats/prometheus static_configs: - targets: - ${env:ENVOY_HOST}:9901 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVOY_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Scoping what is scraped Envoy emits a large, label-rich stat set, and each `envoy_cluster_*`, `envoy_listener_*`, and `envoy_http_*` name carries a per-cluster, per-listener, or per-virtual-host label, so series multiply quickly. Two receiver/endpoint capabilities scope what you scrape, without changing which tiers exist. A `metric_relabel_configs` keep filter restricts the scrape to the Envoy families you watch: ```yaml showLineNumbers title="config/otel-collector.yaml (keep filter)" receivers: prometheus: config: scrape_configs: - job_name: envoy scrape_interval: 30s metrics_path: /stats/prometheus static_configs: - targets: - ${env:ENVOY_HOST}:9901 metric_relabel_configs: - source_labels: [__name__] regex: "envoy_http_downstream_.*|envoy_server_.*|envoy_listener_.*|envoy_cluster_.*" action: keep ``` The admin endpoint's `usedonly` query parameter omits stats that have never been updated since startup: ```yaml showLineNumbers title="config/otel-collector.yaml (usedonly)" receivers: prometheus: config: scrape_configs: - job_name: envoy scrape_interval: 30s metrics_path: /stats/prometheus params: usedonly: [""] static_configs: - targets: - ${env:ENVOY_HOST}:9901 ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for a successful Envoy scrape docker logs otel-collector 2>&1 | grep -i "envoy" # Verify Envoy is running curl -s http://localhost:9901/server_info # Check the metrics endpoint directly curl -s http://localhost:9901/stats/prometheus | grep envoy_server_state ``` ### Troubleshooting #### Admin interface not responding on port 9901 **Cause**: The `admin` block is missing from the Envoy bootstrap config. **Fix**: 1. Add the `admin` section with `address` and `port_value` to the bootstrap config. 2. Restart Envoy - the admin address is static configuration. 3. Verify: `curl http://localhost:9901/server_info`. #### Metrics endpoint returns empty or partial data **Cause**: Envoy only reports metrics for resources it has configured. **Fix**: 1. Metrics appear as listeners, clusters, and routes are configured. 2. Run `curl http://localhost:9901/stats/prometheus` without `usedonly` to see all available metrics, including zeros. 3. Confirm Envoy is processing traffic - downstream request and connection metrics only advance with active connections. #### Series count is very large in a sidecar mesh **Cause**: In a sidecar mesh (Istio or similar), each Envoy emits its own stat set, multiplied by the clusters and routes it knows about, so the total series count scales with the size of the mesh. **Look at**: the Diagnostic per-cluster (`envoy_cluster_*`) and per-listener (`envoy_listener_*`) families - these carry the per-resource labels that drive the count. **Fix**: 1. Apply the `metric_relabel_configs` keep filter to scrape only the families you watch. 2. Add the `usedonly` parameter so never-updated stats are not scraped. 3. Use a longer `scrape_interval` for sidecars that know many clusters. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Envoy running as an Istio sidecar? Yes. Each Envoy sidecar exposes its admin interface - set `targets` to the sidecar's admin port (typically 15000 in Istio). The Collector can run as a DaemonSet to scrape all sidecars on a node, or use Prometheus service discovery for dynamic pod targeting. #### How do I monitor multiple Envoy instances? Add all admin endpoints to the scrape config: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: prometheus: config: scrape_configs: - job_name: envoy metrics_path: /stats/prometheus static_configs: - targets: - envoy-1:9901 - envoy-2:9901 - envoy-3:9901 ``` Each instance is scraped independently and identified by its `instance` label. #### Why are upstream cluster metrics missing? Upstream metrics (`envoy_cluster_*`) only appear when Envoy has configured clusters with active endpoints. With only a direct-response or passthrough configuration, cluster-level metrics are not emitted. Add at least one cluster with endpoints to see upstream metrics. #### What does `envoy_server_live` indicate? A value of `1` means Envoy is accepting connections and serving requests; `0` indicates it is draining or shutting down. It sits in the Operational tier as a liveness/restart flag - for Core health use `envoy_server_state == 0`, which distinguishes LIVE from the initializing and draining states. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Envoy metrics. - [Traefik Monitoring](./traefik.md) - Edge router and ingress proxy. - [NGINX Monitoring](./nginx.md) - Reverse proxy and web server. - [HAProxy Monitoring](./haproxy.md) - Load balancer fronting backends. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Traefik](./traefik.md), [NGINX](./nginx.md), and other components. - **Scope the scrape**: Apply the keep filter or the `usedonly` parameter to match the series volume to the families you watch. --- ## etcd OpenTelemetry Monitoring - Leader Health, Raft Proposals, and Collector Setup ## etcd etcd exposes Prometheus-format metrics at `/metrics` on its client port (`2379`). The OpenTelemetry Collector scrapes this endpoint with the Prometheus receiver, collecting 130+ metrics - of which 82 are `etcd_*` - across leader and liveness state, Raft consensus, disk fsync and backend commit latency, MVCC storage, and gRPC requests, on etcd 3.6+. This guide configures the receiver, connects to an etcd node, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | etcd | 3.6 | 3.6.12 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - etcd's client port (`2379`) must be reachable from the host running the Collector. The `/metrics` endpoint is served there. - etcd serves `/metrics` over `http` with no authentication by default; production deployments front it with `https` and mTLS - see [Access Setup](#access-setup). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - monitoring itself is alive. | | `etcd_server_has_leader` | 1 if this member sees a leader; **0 means the cluster cannot serve writes**. The single load-bearing liveness signal. | | `etcd_server_proposals_committed_total` | Committed Raft proposals - the cluster is making progress (write throughput). | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `etcd_server_leader_changes_seen_total` | Leader-election churn; sustained increases are pathological (Raft instability). | | `etcd_server_proposals_failed_total` | Failed proposals - leader loss or quorum problems. | | `etcd_server_proposals_pending` | Proposal backlog; a non-zero sustained value is saturation. | | `etcd_server_health_failures` | Server health-check failures. | | `etcd_server_heartbeat_send_failures_total` | Leader could not send heartbeats - peer-link or disk stall. | | `etcd_server_slow_apply_total` | Applies that exceeded the slow threshold - disk or CPU saturation. | | `etcd_server_slow_read_indexes_total` | Slow linearizable reads. | | `etcd_server_read_indexes_failed_total` | Failed read-index requests. | | `etcd_disk_wal_fsync_duration_seconds` | WAL fsync latency - etcd's primary disk-health signal. | | `etcd_disk_backend_commit_duration_seconds` | Backend (bbolt) commit latency. | | `etcd_mvcc_db_total_size_in_bytes` | On-disk DB size - tracked against the backend quota. | | `etcd_server_quota_backend_bytes` | Configured backend quota; the denominator for the space-used alert. | | `etcd_network_known_peers` | Known cluster peers - membership/dependency health. | #### Diagnostic - for investigation and tuning Higher cardinality / debugging namespace; droppable in production with `metric_relabel_configs` while keeping Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | Debugging namespace | all `etcd_debugging_*` (lease_*, mvcc_*, snap_save_*, store_*, auth_revision) | Deep Raft/MVCC/lease/store internals during an incident. | | MVCC operations | `etcd_mvcc_put_total`, `_range_total`, `_delete_total`, `_txn_total`, `_db_total_size_in_use_in_bytes`, `_db_open_read_transactions`, `_hash_duration_seconds`, `_hash_rev_duration_seconds` | Keyspace op mix, fragmentation (size vs size_in_use), compaction cost. | | Disk (deep) | `etcd_disk_wal_write_bytes_total`, `_wal_write_duration_seconds`, `_backend_defrag_duration_seconds`, `_backend_snapshot_duration_seconds`, `_defrag_inflight` | WAL write volume; defrag/snapshot timing. | | Snapshot | `etcd_snap_db_fsync_duration_seconds`, `_db_save_total_duration_seconds`, `etcd_snap_fsync_duration_seconds` | Snapshot persistence latency. | | Apply / range timing | `etcd_server_apply_duration_seconds`, `etcd_server_range_duration_seconds`, `etcd_server_client_requests_total` | Per-op latency distribution. | | gRPC proxy | `etcd_grpc_proxy_*` (cache_hits/misses/keys, events/watchers_coalescing) | Only when running the gRPC proxy. | | Client network | `etcd_network_client_grpc_received_bytes_total`, `_sent_bytes_total` | Client traffic volume. | | Inventory / state | `etcd_server_id`, `_version`, `_go_version`, `etcd_server_is_leader`, `_is_learner`, `_learner_promote_successes`, `_feature_enabled`, `_snapshot_apply_in_progress_total`, `etcd_cluster_version` | Identity, version, leader/learner state. | | Runtime | `go_*`, `process_*`, `grpc_server_*`, `os_fd_*`, `promhttp_*`, `scrape_*`, `up` | Go/process/gRPC/scrape health. | Full metric list: see the [etcd metrics reference](https://etcd.io/docs/latest/op-guide/monitoring/), or run `curl -s http://localhost:2379/metrics` against your etcd instance. ### Key Alerts to Configure Threshold guidance for the most useful Operational-tier series. The disk-latency numbers are etcd's documented operational guidance (etcd hardware/ops docs); tune to your storage. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `etcd_server_has_leader` | - | `== 0` | No leader: cluster cannot serve writes. Investigate quorum / peer links immediately. | | `rate(etcd_server_leader_changes_seen_total)` | `> 0` sustained | Rising across windows | Raft instability; check disk latency and network between peers. | | `rate(etcd_server_proposals_failed_total)` | `> 0` sustained | Rising | Quorum or leader problems; correlate with leader changes. | | `etcd_server_proposals_pending` | `> 0` sustained | Growing | Apply pipeline backed up; check disk saturation. | | `etcd_disk_wal_fsync_duration_seconds` (p99) | `> 10ms` | `> 25ms` | Slow WAL fsync stalls consensus. Move etcd to faster disk / dedicate IO. | | `etcd_disk_backend_commit_duration_seconds` (p99) | `> 25ms` | `> 50ms` | Slow backend commits; same disk-IO remedy. | | `etcd_mvcc_db_total_size_in_bytes / etcd_server_quota_backend_bytes` | `> 0.80` | `> 0.95` | Approaching the backend quota; a NOSPACE alarm halts writes. Defrag / raise quota / compact. | | `etcd_server_heartbeat_send_failures_total` | `> 0` | Sustained | Leader can't heartbeat peers; disk stall or partition. | The two `*_duration_seconds` rows are Prometheus histograms - there is no ready-made `p99` series to threshold. Compute the percentile from the histogram buckets in your alert rule, for example `histogram_quantile(0.99, rate(_bucket[5m]))`, rather than alerting on a `p99` series directly. ### Access Setup Verify your etcd instance is accessible and serving metrics: ```bash showLineNumbers title="Verify access" # Check cluster health etcdctl endpoint health # List all keys (empty cluster returns nothing) etcdctl get "" --prefix --keys-only # Verify metrics endpoint curl -s http://localhost:2379/metrics | head -20 ``` No authentication is required for the `/metrics` endpoint on an `http` client port. Production etcd runs `https` with mTLS - the scrape job needs client certificates, configured in [Configuration](#configuration) below. :::note Port conflict in Kubernetes etcd uses port 2379, which conflicts with the Kubernetes control-plane etcd. If running both, remap the host port in Docker Compose (for example `12379:2379`) or target the non-Kubernetes etcd address directly. ::: ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: etcd scrape_interval: 10s static_configs: - targets: # host:port etcd's /metrics is reachable on - ${env:ETCD_HOST}:${env:ETCD_PORT} processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ETCD_HOST=localhost # Port etcd's /metrics is reachable on: 2379 in-cluster or in-network. If etcd # runs in a container that remaps the port on the host - for example to avoid # the Kubernetes control-plane etcd, also on 2379 - set this to that port. ETCD_PORT=2379 ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### TLS for production etcd Production etcd serves metrics over `https` with mTLS. Add the scheme and client certificates to the scrape job, and mount the certificate files into the Collector container: ```yaml showLineNumbers title="config/otel-collector.yaml (TLS)" receivers: prometheus: config: scrape_configs: - job_name: etcd scheme: https tls_config: ca_file: /certs/ca.pem cert_file: /certs/client.pem key_file: /certs/client-key.pem static_configs: - targets: - ${env:ETCD_HOST}:${env:ETCD_PORT} ``` #### Controlling metric volume etcd exposes 130+ metrics including the `etcd_debugging_*` namespace, Go runtime, and Prometheus internals. The Prometheus receiver scrapes the full `/metrics` surface with no whitelist - every series etcd exposes flows through, and new series appear automatically after an etcd upgrade with no config change. To drop the Diagnostic tier in production while keeping Core + Operational, add a `metric_relabel_configs` block to the scrape job: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" metric_relabel_configs: - source_labels: [__name__] regex: "etcd_debugging_.*" action: drop ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped etcd metrics docker logs otel-collector 2>&1 | grep -i "etcd" # Verify etcd is healthy etcdctl endpoint health # Check the leader signal directly on the metrics endpoint curl -s http://localhost:2379/metrics | grep etcd_server_has_leader # Generate write traffic so proposal counters advance etcdctl put app/example value ``` ### Troubleshooting #### Connection refused on port 2379 **Cause**: Collector cannot reach etcd at the configured address. **Fix**: 1. Verify etcd is running: `docker ps | grep etcd` or `systemctl status etcd`. 2. Confirm `--listen-client-urls` includes the address the Collector connects to. 3. Check firewall rules if the Collector runs on a separate host. #### Metrics endpoint returns empty or 404 **Cause**: etcd is configured with `--listen-metrics-urls`, which moves the metrics endpoint to a different address. **Fix**: 1. Check whether `--listen-metrics-urls` is set: `ps aux | grep etcd | grep listen-metrics`. 2. If set, update the scrape target to match that address and port. 3. If not set, metrics are served on the client port (2379). #### Consensus is unstable or writes stall **Cause**: Slow disk fsync or peer-link problems are destabilising Raft. **Look at**: `etcd_disk_wal_fsync_duration_seconds` and `etcd_disk_backend_commit_duration_seconds` (Operational disk latency); `etcd_server_leader_changes_seen_total` and `etcd_server_heartbeat_send_failures_total` for the election churn and heartbeat failures that follow. For deeper timing, the Diagnostic `etcd_disk_wal_write_duration_seconds` and `etcd_server_apply_duration_seconds` break down where the latency lands. **Fix**: 1. Move etcd to faster, dedicated storage if WAL fsync p99 exceeds 10ms. 2. Investigate the network between peers if heartbeat failures climb. #### Database approaching the backend quota **Cause**: The keyspace has grown toward `etcd_server_quota_backend_bytes`; a NOSPACE alarm halts writes once it is hit. **Look at**: `etcd_mvcc_db_total_size_in_bytes` against the quota (Operational). A large gap between `etcd_mvcc_db_total_size_in_bytes` and the Diagnostic `etcd_mvcc_db_total_size_in_use_in_bytes` indicates fragmentation. **Fix**: 1. Run `etcdctl defrag` to reclaim fragmented space. 2. Compact old revisions, or raise the backend quota. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with etcd running in Kubernetes? Yes. Set `targets` to the etcd pod or service DNS (for example `etcd-0.etcd.kube-system.svc.cluster.local:2379`). For managed Kubernetes (EKS, GKE, AKS), the control-plane etcd may not be directly accessible - check your provider's documentation. #### How do I monitor an etcd cluster? Add all member endpoints to the scrape config: ```yaml showLineNumbers receivers: prometheus: config: scrape_configs: - job_name: etcd static_configs: - targets: - etcd-1:2379 - etcd-2:2379 - etcd-3:2379 ``` Each member is scraped on its in-network client port - `2379`, the `ETCD_PORT` default - and identified by its `instance` label. Watch `etcd_network_known_peers` and `etcd_server_has_leader` per member to confirm the cluster sees quorum. #### Why does `etcd_server_proposals_pending` stay above zero? A small number of pending proposals is normal under write load. Sustained high values mean the cluster cannot commit proposals fast enough - check disk latency (`etcd_disk_wal_fsync_duration_seconds`) and the `etcd_server_slow_apply_total` counter. #### What is the difference between `db_total_size` and `db_total_size_in_use`? `etcd_mvcc_db_total_size_in_bytes` includes space freed by compaction but not yet reclaimed (fragmentation). `etcd_mvcc_db_total_size_in_use_in_bytes` reflects actual data. A large gap between the two indicates fragmentation - run `etcdctl defrag` to reclaim space. #### Which metrics can I drop to reduce volume? The `etcd_debugging_*` namespace (30 series) plus the Go runtime, process, and gRPC-proxy families are Diagnostic - drop them with `metric_relabel_configs` and keep the Core and Operational tiers. They are worth re-enabling during an incident or capacity review. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on etcd metrics. - [ZooKeeper Monitoring](./zookeeper.md) - Coordination service for systems that pre-date etcd. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [ZooKeeper](./zookeeper.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic `etcd_debugging_*` tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## Hadoop OpenTelemetry Monitoring - HDFS Block Health, Capacity, and Collector Setup ## Hadoop The OpenTelemetry JMX Scraper connects to the HDFS NameNode over JMX and collects 10 HDFS metrics plus 19 metrics from the NameNode JVM (29 total) on Hadoop 3.x - DataNode liveness, missing and corrupt blocks, raw capacity, volume failures, and NameNode JVM health - then pushes them over OTLP to the Collector. HDFS keeps its state in `FSNamesystem` MBeans with no Prometheus endpoint, so the scraper bridges JMX to OTLP; the `hadoop` target reads the NameNode's `Hadoop:service=NameNode,name=FSNamesystem(State)` MBeans and the `jvm` target reads the NameNode JVM. This guide enables remote JMX on the NameNode, runs the scraper, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ----------- | -------------- | | Hadoop (HDFS) | 3.0 | 3.4+ | | OTel JMX Scraper | 1.51.0-alpha | 1.57.0-alpha | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The HDFS NameNode must expose remote JMX over RMI, reachable from the host running the scraper (see [Access Setup](#access-setup)). - A JRE 17+ to run the scraper JAR, or Docker to run it in a container. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `hadoop` target reads NameNode `FSNamesystem` state only - one DataNode registered reports `hadoop.datanode.live = 1`. YARN / ResourceManager and per-DataNode MBeans are out of scope for this target. #### Core - is it up and storing data | Metric | What it tells you | |---|---| | `hadoop.datanode.live` | Live DataNodes. HDFS exposes no JMX `up` metric, so this is the cluster-alive anchor - is the filesystem backed by storage. | | `jvm.memory.used` | NameNode JVM memory in use; the process-alive and heap-health anchor. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `hadoop.datanode.dead` | Dead DataNodes - lost storage and replication risk. | | `hadoop.dfs.block.missing` | Missing blocks - blocks under-replicated to zero, i.e. data-loss risk. | | `hadoop.dfs.block.corrupt` | Blocks with corrupt replicas. | | `hadoop.dfs.capacity.used` | Used raw capacity across DataNodes. | | `hadoop.dfs.capacity.limit` | Total raw capacity - the saturation denominator against used. | | `hadoop.dfs.volume.failure.count` | DataNode volume (disk) failures cluster-wide. | | `jvm.memory.limit` | NameNode heap ceiling - the saturation denominator against used. | | `jvm.cpu.recent_utilization` | Recent NameNode process CPU utilization. | | `jvm.thread.count` | Total live NameNode JVM threads - a leak signal. | #### Diagnostic - for investigation and tuning Higher cardinality and internals you reach for during an investigation or a capacity review, not signals you page on. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | HDFS namespace / scale | `hadoop.dfs.block.count` (total allocated blocks), `hadoop.dfs.file.count` (files + directories, drives NameNode heap), `hadoop.dfs.connection.count` (current client connections) | Small-file growth and NameNode heap sizing. | | JVM memory detail | `jvm.memory.committed`, `jvm.memory.init`, `jvm.memory.used_after_last_gc` | Heap behaviour around GC. | | JVM class loading | `jvm.class.count`, `jvm.class.loaded`, `jvm.class.unloaded` | Class-loader churn. | | JVM CPU / system | `jvm.cpu.count`, `jvm.cpu.time`, `jvm.system.cpu.load_1m`, `jvm.system.cpu.utilization` | Host-level CPU pressure on the NameNode. | | JVM buffers / descriptors | `jvm.buffer.count`, `jvm.buffer.memory.limit`, `jvm.buffer.memory.used`, `jvm.file_descriptor.count`, `jvm.file_descriptor.limit` | Direct-buffer and file-descriptor exhaustion. | The `hadoop` target covers NameNode `FSNamesystem` state; it does not expose per-request latency or per-DataNode breakdowns. Those live in the NameNode / DataNode logs or in YARN application metrics, not in this set. Full metric reference: [OTel JMX Scraper - Hadoop target](https://github.com/open-telemetry/opentelemetry-java-contrib/tree/main/jmx-scraper). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `hadoop.dfs.block.missing` | > 0 | Rising | Data loss - blocks with no live replica. Investigate dead DataNodes and run `hdfs fsck`. | | `hadoop.dfs.block.corrupt` | > 0 | Rising | Replica corruption; check DataNode disks and trigger re-replication. | | `hadoop.datanode.dead` | > 0 | Rising | DataNodes lost from the cluster - storage and replication capacity gone; the NameNode re-replicates affected blocks. Restore or replace the node. | | `hadoop.dfs.capacity.used` vs `hadoop.dfs.capacity.limit` | Approaching limit | Near limit | Filesystem filling; add DataNodes or reclaim space before writes fail. | | `hadoop.dfs.volume.failure.count` | > 0 | Rising | Failing DataNode disks; replace media and rebalance. | | `jvm.memory.used` vs `jvm.memory.limit` | Approaching limit | Near limit | NameNode heap scales with namespace size; GC churn / OOM risk - raise heap or reduce the small-file count. | ### Access Setup Hadoop does not expose a Prometheus endpoint. The NameNode publishes its state through JMX MBeans, and the OpenTelemetry JMX Scraper reads them over remote JMX (RMI), then pushes OTLP to the Collector. #### 1. Enable remote JMX on the NameNode Add the JMX-agent flags to `HDFS_NAMENODE_OPTS` so the NameNode opens an RMI registry on a fixed port (1026 here). Set `java.rmi.server.hostname` to the address the scraper will dial: ```bash showLineNumbers title="NameNode JMX flags (hadoop-env.sh or env file)" HDFS_NAMENODE_OPTS="-Dcom.sun.management.jmxremote \ -Dcom.sun.management.jmxremote.port=1026 \ -Dcom.sun.management.jmxremote.rmi.port=1026 \ -Dcom.sun.management.jmxremote.local.only=false \ -Dcom.sun.management.jmxremote.authenticate=false \ -Dcom.sun.management.jmxremote.ssl=false \ -Djava.rmi.server.hostname=namenode" ``` The flags above open unauthenticated JMX, which is appropriate only on a trusted network. In production, enable JMX authentication and TLS (`jmxremote.authenticate=true`, `jmxremote.ssl=true`) and restrict the RMI port with firewall rules; the scraper's `OTEL_JMX_*` settings carry the matching credentials. #### 2. Run the JMX Scraper The scraper is a single JAR. Point `OTEL_JMX_SERVICE_URL` at the NameNode's RMI registry, set the target systems to `jvm,hadoop`, and send OTLP to the Collector: ```dockerfile showLineNumbers title="jmx-scraper/Dockerfile" FROM eclipse-temurin:17-jre ARG SCRAPER_VERSION=1.57.0-alpha ADD https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/${SCRAPER_VERSION}/opentelemetry-jmx-scraper-${SCRAPER_VERSION}.jar /opt/scraper.jar ENTRYPOINT ["java", "-jar", "/opt/scraper.jar"] ``` ```yaml showLineNumbers title="docker-compose.yaml (scraper service)" services: jmx-scraper: build: ./jmx-scraper environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://namenode:1026/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,hadoop # NameNode JVM + HDFS FSNamesystem OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: 10000 # milliseconds depends_on: namenode: condition: service_healthy ``` The scraper logs a benign `SASL unsupported in current environment` WARNING at connect time when JMX auth is off; it then connects over unauthenticated JMX and scrapes normally. This is not an error. ### Configuration The scraper pushes OTLP/gRPC to the Collector. The Collector receives it on the `otlp` receiver and forwards it to Scout: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 # The scraper's OTEL_EXPORTER_OTLP_ENDPOINT processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic tier with a `filter` processor while keeping the Core and Operational series: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" processors: filter/diagnostic: metrics: exclude: match_type: regexp metric_names: - hadoop\.dfs\.(block|file|connection)\.count - jvm\.memory\.(committed|init|used_after_last_gc) - jvm\.class\..* - jvm\.cpu\.(count|time) - jvm\.system\..* - jvm\.buffer\..* - jvm\.file_descriptor\..* ``` Add `filter/diagnostic` to the `processors` list in the metrics pipeline. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the scraper and Collector, then confirm metrics flow within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm the scraper connected and is exporting (no connection errors) docker logs jmx-scraper 2>&1 | grep -i "otlp\|export\|hadoop" # Check the Collector received Hadoop metrics (requires a debug exporter) docker logs otel-collector 2>&1 | grep -i "hadoop" # Generate namespace activity so the HDFS gauges advance docker exec namenode hdfs dfs -mkdir -p /demo docker exec namenode bash -c 'echo hello | hdfs dfs -put - /demo/probe.txt' ``` The Collector log check needs a `debug` exporter in the pipeline; the production config above ships only `otlphttp/b14`, so confirm delivery in Scout instead, or add `debug` to the metrics pipeline while testing. `hadoop.dfs.file.count` and `hadoop.dfs.block.count` should advance after the write; `hadoop.datanode.live` reads `1` once a DataNode registers. ### Troubleshooting #### Scraper cannot connect to the NameNode **Cause**: Remote JMX is not enabled, the port is wrong, or `java.rmi.server.hostname` does not resolve from the scraper. **Fix**: 1. Confirm the JMX flags are on `HDFS_NAMENODE_OPTS` and the NameNode restarted: `docker exec namenode bash -c 'ps aux | grep jmxremote'`. 2. Verify `OTEL_JMX_SERVICE_URL` host and port match the `jmxremote.port` / `rmi.port` values. 3. Set `java.rmi.server.hostname` to a name the scraper can resolve - RMI hands the client a stub pointing at this hostname. #### Only `jvm.*` metrics appear, no `hadoop.*` metrics **Cause**: `OTEL_JMX_TARGET_SYSTEM` is missing the `hadoop` target, or the scraper is connected to a node without the `FSNamesystem` MBeans (a DataNode rather than the NameNode). **Fix**: 1. Set `OTEL_JMX_TARGET_SYSTEM: jvm,hadoop`. 2. Point the service URL at the NameNode - the `hadoop` target reads `Hadoop:service=NameNode,name=FSNamesystem(State)` MBeans, which only the NameNode exposes. #### Capacity or namespace gauges read zero **Cause**: The cluster is idle, or no DataNode has registered. **Look at**: the Diagnostic `hadoop.dfs.file.count` and `hadoop.dfs.connection.count` series - both sit at zero on an idle NameNode with no client connections. `hadoop.dfs.capacity.used` stays near zero until data is written. **Fix**: 1. Confirm a DataNode is up: `hadoop.datanode.live` should be ≥ 1. 2. Write a file to HDFS (`hdfs dfs -put`) so the namespace, block, and capacity gauges advance. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `otlp` receiver and the `otlphttp/b14` exporter. ### FAQ #### Why use the JMX Scraper instead of the OTel JMX receiver? The JMX Scraper is a standalone process - it connects to the NameNode's JMX endpoint over RMI and pushes OTLP, so the Collector needs no JRE inside its container. The `hadoop` target ships predefined rules (`jmx/rules/hadoop.yaml`) that map `FSNamesystem` MBeans to stable metric names, so you do not write pattern rules by hand. #### Does this work with Hadoop running in Kubernetes? Yes. Enable remote JMX on the NameNode pod, then run the scraper as a sidecar or a separate Deployment with `OTEL_JMX_SERVICE_URL` pointing at the NameNode service DNS (e.g., `service:jmx:rmi:///jndi/rmi://namenode.hadoop.svc.cluster.local:1026/jmxrmi`). Inject JMX credentials via a Kubernetes secret when auth is enabled. #### Does the scraper collect YARN or ResourceManager metrics? No. The `hadoop` target reads NameNode `FSNamesystem` state only - HDFS storage health and namespace scale. YARN / ResourceManager and per-DataNode MBeans are out of scope for this target. #### Why is request latency missing from the metrics? The `hadoop` target exposes `FSNamesystem` gauges and counters, not per-request timing. Operation latency lives in the NameNode / DataNode logs or in the HDFS audit log, not in this metric surface. ### Related Guides - [JMX Metrics Collection Guide](../collector-setup/jmx-metrics-collection-guide.md) - Compare the JMX Scraper and the JMX Exporter. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [ZooKeeper Monitoring](./zookeeper.md) - A common companion coordination service. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Hadoop metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [ZooKeeper](./zookeeper.md), [Kafka](./kafka.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## HAProxy OpenTelemetry Monitoring - Request Rates, Backend Health, and Collector Setup ## HAProxy The OpenTelemetry Collector's `haproxyreceiver` collects 33 metrics from HAProxy - request rates, sessions, connection errors, backend health, response times, and compression. The receiver reads HAProxy's CSV stats output (over the HTTP stats page or the stats socket) and parses it internally, so no exporter sidecar is needed. This guide enables a stats endpoint, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | HAProxy | 2.0 | 2.8+ (LTS) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - HAProxy must be reachable from the host running the Collector. - A `stats` endpoint enabled - either an HTTP `stats` frontend (`stats enable` / `stats uri`) or the `stats socket` - see [Access Setup](#access-setup). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things about this surface before the tables: - **No `up` and no health metric.** Liveness is the receiver scraping the stats page successfully; backend availability is `haproxy.active` (count of servers reporting UP). - **Point the `endpoint` at the stats path, not `/stats;csv`.** For an HTTP stats frontend, use the stats path (e.g. `/stats`) - the receiver appends the CSV view itself. The receiver can also read the HAProxy stats socket via a `file://` endpoint (e.g. `file:///var/run/haproxy.ipc`). - **One row per frontend, per backend, and per server.** HAProxy emits a CSV row for each, so the same metric appears tagged by `haproxy.proxy_name` / `haproxy.service_name` for the frontend, the backend aggregate, and each server. - **`haproxy.requests.total` carries a `status_code` attribute** (`1xx`/`2xx`/`3xx`/`4xx`/`5xx`/`other`). It is both the throughput signal and the HTTP error-rate signal. - **The compression family reads 0** unless compression is configured (`compression algo`). #### Core - is it up and serving | Metric | What it tells you | |---|---| | `haproxy.requests.total` | HTTP requests by `status_code` (1xx/2xx/3xx/4xx/5xx/other) - throughput and the HTTP error-rate signal. | | `haproxy.responses.average_time` | Average backend response time over the last 1024 requests - the serving-latency KPI. | | `haproxy.active` | Active (UP) servers in the backend - backend availability, the LB's core job. There is no `up` metric; liveness is scrape success. | | `haproxy.sessions.count` | Current sessions - concurrency and load. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `haproxy.responses.errors` | Backend response errors - the error signal that pages. | | `haproxy.connections.errors` | Errors connecting to backend servers - backend reachability. | | `haproxy.requests.errors` | Client request errors. | | `haproxy.failed_checks` | Failed health checks while a server was up - a server is flapping. | | `haproxy.downtime` | Accumulated backend downtime, in seconds. | | `haproxy.requests.queued` | Requests queued without an assigned server - backend saturation. | | `haproxy.sessions.limit` | Configured session limit - saturate `haproxy.sessions.count` against this. | | `haproxy.bytes.input`, `haproxy.bytes.output` | Bytes in / out - bandwidth. | | `haproxy.backup` | Backup servers active - the primary pool has failed over. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Metrics | When you reach for it | |---|---|---| | Latency breakdown | `haproxy.requests.average_time` (queue time), `haproxy.connections.average_time` (connect time), `haproxy.sessions.average` (total session time) | Splitting the headline `haproxy.responses.average_time` into queue / connect / end-to-end stages. | | Rate gauges | `haproxy.requests.rate`, `haproxy.connections.rate`, `haproxy.sessions.rate` | Instantaneous per-second rates, derivable from the counters. | | Cumulative counters | `haproxy.connections.total`, `haproxy.sessions.total` | Lifetime connection / session volume. | | Resilience | `haproxy.connections.retries`, `haproxy.requests.redispatched`, `haproxy.clients.canceled` | Connection retries, redispatch to another server, and client-aborted transfers - backend trouble. | | Security denials | `haproxy.requests.denied`, `haproxy.responses.denied` | ACL-denied requests / responses - security-policy hits. | | LB internals | `haproxy.server_selected.total`, `haproxy.weight` | Server-selection counts and load-balancing weight. | | Compression | `haproxy.compression.bypass`, `haproxy.compression.count`, `haproxy.compression.input`, `haproxy.compression.output` | Compression effectiveness. Reads 0 unless compression is enabled. | Full metric reference: [OTel HAProxy Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/haproxyreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. Tune to your workload; these are starting points. | Alert | Condition | Why it matters | |---|---|---| | HAProxy unreachable | The `haproxy` receiver produces no data for > 1m | No `up`/health on this surface - scrape success against the stats page is liveness. Check the process and the stats endpoint. | | Backend has no healthy servers | `haproxy.active` == 0 for a backend | The LB has nowhere healthy to route - every request to that backend fails. Check the servers and their health checks. | | HTTP 5xx rising | `rate(haproxy.requests.total{status_code="5xx"})` rising vs baseline, or `haproxy.responses.errors` rising | Server-side errors through the proxy - inspect the backend and recent deploys. | | Backend latency rising | `haproxy.responses.average_time` rising vs baseline | Slow backend responses - check the backend servers, not HAProxy. | | Session saturation | `haproxy.sessions.count` approaching `haproxy.sessions.limit` | Approaching the configured session ceiling - new sessions will be refused; raise `maxconn` or scale out. | | Request queue building | `haproxy.requests.queued` rising vs baseline | Backends cannot keep up and requests are queuing - add capacity or check backend health. | | Health checks failing | `rate(haproxy.failed_checks)` > 0 | A server is failing checks while up - it is flapping in and out of the pool. Investigate that server. | ### Access Setup The receiver scrapes HAProxy's HTTP stats page. Enable an HTTP `stats` frontend in your HAProxy configuration: ```text showLineNumbers title="haproxy.cfg" frontend stats bind *:8404 stats enable stats uri /stats stats refresh 10s ``` Verify the stats page returns CSV data: ```bash showLineNumbers title="Verify access" curl -s 'http://localhost:8404/stats;csv' | head -5 ``` No authentication is required by default. If you add `stats auth`, pass the credentials through the Collector endpoint URL (`http://user:pass@:8404/stats`). ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: haproxy: endpoint: http://localhost:8404/stats # Change to your HAProxy stats URL collection_interval: 10s metrics: # Traffic haproxy.bytes.input: enabled: true haproxy.bytes.output: enabled: true # Connections haproxy.connections.errors: enabled: true haproxy.connections.rate: enabled: true haproxy.connections.retries: enabled: true haproxy.connections.total: enabled: true haproxy.connections.average_time: enabled: true # Requests haproxy.requests.denied: enabled: true haproxy.requests.errors: enabled: true haproxy.requests.queued: enabled: true haproxy.requests.rate: enabled: true haproxy.requests.redispatched: enabled: true haproxy.requests.total: enabled: true haproxy.requests.average_time: enabled: true # Responses haproxy.responses.denied: enabled: true haproxy.responses.errors: enabled: true haproxy.responses.average_time: enabled: true # Sessions haproxy.sessions.average: enabled: true haproxy.sessions.count: enabled: true haproxy.sessions.rate: enabled: true haproxy.sessions.limit: enabled: true haproxy.sessions.total: enabled: true # Server health haproxy.server_selected.total: enabled: true haproxy.active: enabled: true haproxy.backup: enabled: true haproxy.weight: enabled: true haproxy.downtime: enabled: true haproxy.failed_checks: enabled: true # Clients haproxy.clients.canceled: enabled: true # Compression haproxy.compression.bypass: enabled: true haproxy.compression.count: enabled: true haproxy.compression.input: enabled: true haproxy.compression.output: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [haproxy] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped HAProxy metrics docker logs otel-collector 2>&1 | grep -i "haproxy" # Verify the stats endpoint is responding curl -s 'http://localhost:8404/stats;csv' | head -5 # Check backend health curl -s 'http://localhost:8404/stats;csv' | grep -i "backend" ``` ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach HAProxy at the configured stats endpoint. **Fix**: 1. Verify HAProxy is running: `systemctl status haproxy` or `docker ps | grep haproxy`. 2. Confirm the stats endpoint and port in your config match the `bind` directive in `haproxy.cfg`. 3. Check firewall rules if the Collector runs on a separate host. #### Stats endpoint returns HTML instead of metrics **Cause**: The endpoint URL points to the wrong path or includes the CSV suffix. **Fix**: 1. The receiver appends the CSV view itself - set the endpoint to `/stats`, not `/stats;csv`. 2. Verify `stats uri` in `haproxy.cfg` matches the path in the receiver config. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. #### Metrics missing for some backends **Cause**: HAProxy backend servers are in maintenance mode or have never received traffic. **Look at**: `haproxy.active` and `haproxy.backup` - zero indicates no healthy servers in that backend. The Diagnostic `haproxy.server_selected.total` stays flat for a server that has never been routed to. **Fix**: 1. Send test traffic to the backend to trigger metric collection. 2. Verify every backend appears in `curl -s 'http://localhost:8404/stats;csv'`. ### FAQ #### Does this work with HAProxy running in Kubernetes? Yes. Set `endpoint` to the HAProxy service DNS (e.g., `http://haproxy.default.svc.cluster.local:8404/stats`) and expose the stats port in the Service definition. The Collector can run as a sidecar or DaemonSet. #### How do I monitor multiple HAProxy instances? Add multiple receiver blocks with distinct names: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: haproxy/primary: endpoint: http://haproxy-1:8404/stats haproxy/secondary: endpoint: http://haproxy-2:8404/stats ``` Then include both in the pipeline: `receivers: [haproxy/primary, haproxy/secondary]`. #### Can I use a Unix socket instead of HTTP? Yes. Point the receiver `endpoint` at the stats socket with a `file://` scheme (e.g. `file:///var/run/haproxy.ipc`) and expose the socket in HAProxy's `global` section: ```text showLineNumbers title="haproxy.cfg" global stats socket /var/run/haproxy.ipc level admin ``` The HTTP `stats` frontend shown in [Access Setup](#access-setup) is the alternative, not a requirement - the receiver reads the same CSV over either transport. #### Why are compression metrics showing zero? The `haproxy.compression.*` family requires compression to be enabled in HAProxy (`compression algo gzip` in the frontend or backend config). It reports zero when compression is not configured. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on HAProxy metrics. - [NGINX Monitoring](./nginx.md) - The web server most often sitting behind HAProxy. - [AWS ELB Monitoring](../infra/aws/elb.md) - Managed load balancer monitoring. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [NGINX](./nginx.md), [AWS ELB](../infra/aws/elb.md), and other components. - **Fine-tune Collection**: Reach for the Diagnostic tier during incident investigation; adjust `collection_interval` to match your traffic patterns. --- ## Hatchet OpenTelemetry Monitoring - Task Outcomes, Queue Backlog, and Collector Setup ## Hatchet Hatchet serves Prometheus text on port `9090` once `SERVER_PROMETHEUS_ENABLED` is set; the OpenTelemetry Collector's `prometheus` receiver scrapes it, collecting 34 Hatchet metric families covering task inflow and outcome, queue backlog, worker slot capacity, scheduling latency and per-workflow end-to-end duration, alongside 40 standard Go runtime families, on Hatchet v0.101.27+. The endpoint is off by default: with the switch unset, nothing listens on 9090 at all. Hatchet also pushes engine traces over OTLP gRPC behind a second switch. This guide turns both surfaces on, configures the Collector and ships to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | --------- | ----------- | | Hatchet | v0.101.27 | v0.105.16 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | `hatchet_tenant_queue_size` is the only backlog signal and the only Core metric that is version-gated: it, the two per-workflow queued-to-assigned families and the two `hatchet_pubsub_*` histograms first appear in v0.101.27. On v0.90.13, v0.94.10 and v0.98.9 all five are absent and the engine emits 28 to 29 Hatchet families instead of 34. Nothing has been removed or renamed across that range; every difference is additive. Before starting: - Hatchet must run with `SERVER_PROMETHEUS_ENABLED=true`. Without it there is no listener on 9090 and the scrape fails with a connection refusal. - Hatchet needs PostgreSQL. The message queue defaults to `postgres`, so RabbitMQ and NATS are not required for this metric surface. - The Collector must reach the metrics port over plain HTTP. Hatchet serves the exposition with no authentication, so restrict the port at the network layer rather than at the application. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). On a split deployment the metrics come from the engine, not the API server or the dashboard. On `hatchet-lite`, which runs the API, the engine and the dashboard in one container, they come from that container. ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or a capacity review. Every global counter has a `hatchet_tenant_` twin carrying a `tenant_id` label. Read [Global and per-tenant families](#global-and-per-tenant-families) before you decide which half to keep - collecting both doubles the series for no extra signal. #### Core - is work flowing, failing or backing up | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the engine is reachable and the metrics listener is on. | | `hatchet_created_tasks_total` | Task inflow. | | `hatchet_succeeded_tasks_total` | Tasks that reached a successful final state. | | `hatchet_failed_tasks_total` | Tasks that reached a final failure. Attempts that will be retried are excluded. | | `hatchet_scheduling_timed_out` | Tasks that hit `schedule_timeout` before a worker slot freed. | | `hatchet_tenant_queue_size` | Queue depth per `queue` and `workflow_name`. The backlog signal. | | `hatchet_tenant_available_worker_slots` | Free slots per `worker_id` / `worker_name`. Zero means new work can only queue. | | `hatchet_tenant_workflow_duration_milliseconds` | End-to-end run duration per `workflow_name` and `status`. Milliseconds, not seconds. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `hatchet_cancelled_tasks_total` | Tasks cancelled. Includes tasks cancelled by a scheduling timeout. | | `hatchet_skipped_tasks_total` | DAG tasks whose `skip_if` condition matched. | | `hatchet_assigned_tasks` | Tasks the queuer assigned to a worker. | | `hatchet_queued_to_assigned` | Tasks that were queued and later assigned. First attempts only. | | `hatchet_reassigned_tasks` | Tasks moved to another worker after the first assignment lapsed, usually a lost heartbeat. | | `hatchet_rate_limited` | Scheduling attempts blocked by a rate limit. Attempts, not tasks. | | `hatchet_queued_to_assigned_time_seconds` | Seconds queued before assignment. Buckets stop at 15s. | | `hatchet_pubsub_publish_duration_seconds` | Publisher-side blocking cost of the message queue's `Pub` call. Labels `kind`, `topic_kind`, `result`. | | `hatchet_pubsub_transit_seconds` | Publish-to-delivery latency from the message's own timestamp. Labels `kind`, `topic_kind`. | | `hatchet_tenant_worker_slots` | Total slots across connected workers. A drop means workers left the pool. | | `hatchet_tenant_used_worker_slots` | Slots currently occupied. | | `hatchet_tenant_queued_to_assigned_by_workflow` | Queued-then-assigned count broken out by `workflow_name`. | | `hatchet_tenant_queued_to_assigned_time_seconds_by_workflow` | Queue wait per `workflow_name`. Same 15s ceiling. | | `go_goroutines` | Goroutine count in the engine. Growth runs ahead of a memory problem. | | `process_resident_memory_bytes` | Engine resident memory. | `hatchet_pubsub_publish_duration_seconds` measures how long the publisher blocked, not broker delivery latency, and is not comparable across message-queue backends because they block at different depths before returning. `hatchet_pubsub_transit_seconds` is subject to clock skew between publisher and subscriber, and messages from older engines carry no timestamp and are never observed. #### Diagnostic - for investigation and tuning Reach for these during an incident or a capacity review. On a single-tenant install the per-tenant twins carry the same numbers as their global counterparts, so this whole tier is droppable with `metric_relabel_configs` while Core and Operational stay. | Metric | When you reach for it | |---|---| | `hatchet_tenant_created_tasks`, `_succeeded_tasks`, `_failed_tasks`, `_cancelled_tasks`, `_skipped_tasks` | Outcome counters split by `tenant_id` on a multi-tenant install. | | `hatchet_tenant_assigned_tasks`, `_queued_to_assigned`, `_reassigned_tasks`, `_scheduling_timed_out`, `_rate_limited` | Assignment and scheduling counters split by `tenant_id`. | | `hatchet_tenant_queue_invocations`, `hatchet_queue_invocations_total` | Invocations of the queuer function. Engine loop activity, not work done. | | `hatchet_tenant_queued_to_assigned_time_seconds` | Per-tenant queue wait. Same 15s ceiling as the global histogram. | | `hatchet_retried_tasks_total` | Documented as retried tasks. Stuck at 0 - see below. | | `go_gc_*`, `go_memstats_*`, `go_threads`, `process_cpu_seconds_total`, `process_open_fds`, `promhttp_metric_handler_requests_total` | Go runtime and scrape-handler detail for engine-level debugging. | #### Reading the task counters Five things about this counter set change what you can build on it. - **`hatchet_retried_tasks_total` never increments.** A task that fails its first attempts and succeeds on a retry leaves the counter at 0, and its per-tenant twin `hatchet_tenant_retried_tasks` never registers at all. Retried attempts appear in neither that counter nor `hatchet_failed_tasks_total`. The only place a retry is visible is a `status="FAILED"` observation on `hatchet_tenant_workflow_duration_milliseconds` for that workflow. Do not build a retry alert on it, and do not read a zero there as a healthy system. - **A scheduling timeout is also counted as a cancellation.** `hatchet_cancelled_tasks_total` covers both the cancels you issue and every task that timed out waiting to be scheduled. Summing the two double-counts every timed-out task, so a cancellation alert has to subtract the increase in `hatchet_scheduling_timed_out`. - **`hatchet_rate_limited` counts scheduling attempts, not tasks.** It runs orders of magnitude above the number of rate-limited task runs, because the queuer re-evaluates a blocked task on every pass. A `rate()` on it measures how hard the scheduler is spinning against the limit, not how much work was delayed. - **The four terminal counters partition the created count.** The sum of succeeded, failed, cancelled and skipped tracks the created count, the gap being tasks in flight. Use `created - (succeeded + failed + cancelled + skipped)` as an in-flight estimate. - **The `_total` suffix is inconsistent upstream.** `created`, `succeeded`, `failed`, `cancelled`, `skipped`, `queue_invocations` and `retried` carry it; `assigned_tasks`, `scheduling_timed_out`, `rate_limited`, `queued_to_assigned` and `reassigned_tasks` do not. They are the same kind of metric and the difference means nothing, so do not hunt for a missing series. `hatchet_tenant_workflow_duration_milliseconds` is the only end-to-end latency signal and the only per-workflow breakdown. Its unit is **milliseconds**, over 24 buckets running from 0.1ms to 24 hours. Observed `status` values are `COMPLETED`, `FAILED` and `CANCELLED`. #### Queue depth and queue-time histograms `hatchet_tenant_queue_size` disappears when a queue drains. The scheduler polls queue depth every 15 seconds; a series that stops being reported is set to 0 for exactly one poll, so a scraper sees the drop, then deleted on the next. The Hatchet family count is 34 while any queue is non-empty and 33 when every queue is drained. An absent series means an empty queue, not a broken scrape. Write backlog alerts so the gap reads as zero rather than as missing data, for example `max_over_time(hatchet_tenant_queue_size[10m])` or an `or vector(0)` fallback, and never alert on `absent()`. Both queue-time histograms top out at 15 seconds. Once queue waits pass that ceiling, most observations on `hatchet_queued_to_assigned_time_seconds` land in `+Inf`, and a `histogram_quantile` above roughly p20 returns `+Inf` on a backed-up system, which is exactly when the number is wanted. Use the assignment counters and `hatchet_tenant_queue_size` to measure saturation instead of these quantiles. #### Global and per-tenant families Eleven families exist in both a global and a `hatchet_tenant_` form, and on a single-tenant deployment each pair carries the same value at the same scrape. The rule applies to those eleven pairs only: - Keep the `hatchet_tenant_` half on a multi-tenant install and drop the global half. - Keep the global half on a single-tenant install and drop the `hatchet_tenant_` half. **Do not drop `hatchet_tenant_` by prefix.** Eight families exist only in the per-tenant form and have no global counterpart, and seven of them are Core or Operational: `hatchet_tenant_queue_size`, `hatchet_tenant_available_worker_slots`, `hatchet_tenant_worker_slots`, `hatchet_tenant_used_worker_slots`, `hatchet_tenant_workflow_duration_milliseconds`, `hatchet_tenant_queued_to_assigned_by_workflow` and `hatchet_tenant_queued_to_assigned_time_seconds_by_workflow`. A prefix rule takes the only backlog signal, both worker-slot gauges and the only end-to-end latency signal with them. The drop rule in [Configuration](#configuration) lists the eleven names in full for exactly this reason. Per-tenant series also appear for seeded tenants with no traffic at all: a second tenant showed a `hatchet_tenant_reassigned_tasks` series pinned at 0. The families are not scoped to tenants doing work. #### Cardinality and restarts `hatchet_tenant_workflow_duration_milliseconds` drives the series count. 24 explicit buckets means 27 series per `(tenant_id, workflow_name, status)` triple - 24 `_bucket` series plus `+Inf`, `_sum` and `_count` - and 11 triples produced 297 of the 449 `hatchet_` series in a single scrape. Series scale with the number of distinct workflow names times the three statuses, so budget against your workflow catalogue. The worker slot gauges carry `worker_id` and `worker_name` but do not leak: restarting a worker mints a new `worker_id`, and the previous series are gone from the next scrape. Counters are process-local. Restarting the engine zeroes every counter and de-registers every per-tenant family until traffic re-registers it - a freshly started engine exposes only a subset of the Hatchet families and reaches the full set once each code path has run. Dashboards built on `increase()` see the reset, and a panel that lists families on a fresh engine sees them appear over the first few minutes. #### Metrics that stay silent - `hatchet_tenant_additional_metadata_queue_size` only appears when tasks carry additional metadata. Its help text warns that an item counts towards every metadata key it carries, so series for different keys overlap and must not be summed across keys. - `hatchet_pubsub_nats_scheduler_partition_drops_total` registers only when the message queue is NATS. On the default Postgres queue it never appears. - `hatchet_retried_tasks_total` is registered and scraped but stuck at 0, so its zero is not a statement about your system. The scrape is unfiltered - there is no metric enable list on this surface, so every family the engine registers arrives. #### Traces - engine internals, not workflow traces Hatchet pushes OTLP traces over gRPC when `SERVER_OTEL_COLLECTOR_URL` is set. `SERVER_OTEL_TRACE_ID_RATIO` defaults to `1`, meaning every trace, and that is the first thing to change: a single-node engine with one four-slot worker and no dashboard traffic emits on the order of 100 spans per second. Sample it before enabling it anywhere real. The trace surface is engine internals. There are 181 distinct span names, all Go function names or SQL statement names, and nothing corresponding to a task run, a workflow run or a user operation. It answers "why is the scheduler slow", not "what happened to my job". End-to-end workflow tracing is the SDK's own worker-side instrumentation, which is a separate setup. | Scope | Span names | Kind | |---|---|---| | `go.opentelemetry.io/otel/sdk/tracer` | `hatchet.run/`, e.g. `hatchet.run/queue`, `hatchet.run/try-assign`, `hatchet.run/process-task-timeout`, `hatchet.run/process-retry-queue-items` | Internal | | `github.com/exaring/otelpgx` v0.10.0 | `pool.acquire`, `query BEGIN`, `query COMMIT`, `query ROLLBACK`, and one `query ` per named SQL statement, e.g. `query ReadMessages`, `query UpdateTaskStatuses` | Client | | `otelgrpc` 0.68.0 | `Dispatcher/Heartbeat` | Server | The database spans dominate: Client spans from `otelpgx` are roughly two thirds of the volume, Internal `hatchet.run/*` spans most of the rest, and Server spans a trickle. | Span group | Attribute keys | |---|---| | `hatchet.run/*` | Ad-hoc dotted keys named after the Go call site, e.g. `olap_repository.update_task_statuses.partition.number`, `olap_repository.update_dag_statuses.is_saturated`, `match_repository.process_cel_expressions.conditions_count`. Not semantic conventions. | | `query *`, `pool.acquire` | `db.system`, `pgx.rows_affected` | | `Dispatcher/Heartbeat` | `rpc.method`, `rpc.response.status_code`, `rpc.system.name`, `server.address`, `server.port`, `tenant_id` | Three details to plan queries around: - The database spans carry `db.system`, the pre-1.26 semantic convention key; the current key is `db.system.name`. Filter on `db.system`. - They carry no statement text under any key, so a `query ` span identifies the prepared statement by name only. - The tenant identifier on spans is `tenant_id` with an underscore, not the dotted `tenant.id` used elsewhere. The only resource attributes Hatchet sets on itself are `service.name`, from `SERVER_OTEL_SERVICE_NAME`, and `library.language=go`. Everything else on these spans in Scout comes from the Collector's `resource` processor. ### Key Alerts to Configure Threshold guidance for the Core and Operational tiers. Task rate, queue depth and run duration are workload-specific, so the rows below are written as ratios, proportional changes or comparisons against your own history rather than as absolute numbers. The three exceptions are definitional: `up == 0`, no free worker slots, and a failure ratio. | Metric | Threshold | Why it matters | |---|---|---| | `up` | `== 0` for 2 scrapes | The engine is gone or the metrics listener was turned off. | | `hatchet_failed_tasks_total` | failure ratio against created `> 5%` over 15m | Final failures, retries already excluded. The headline error signal. | | `hatchet_tenant_queue_size` | above the 24h p95 for that queue for 10m | Backlog outside its own normal range. Absolute depths are workload-specific. | | `hatchet_tenant_available_worker_slots` | `== 0` for 5m | No capacity left; new work can only queue. Add workers or slots. | | `hatchet_scheduling_timed_out` | any increase over 10m | Work is expiring unscheduled, which is silent data loss from the caller's point of view. | | `hatchet_tenant_workflow_duration_milliseconds` | p95 above the 7-day p95 for that `workflow_name` by `> 2x` | Per-workflow latency regression. | | `hatchet_cancelled_tasks_total` | increase not matched by a corresponding increase in `hatchet_scheduling_timed_out` | Isolates real cancellations from the timeouts folded into the same counter. | | `hatchet_tenant_worker_slots` | drops by `> 25%` over 10m | Workers left the pool. | | `hatchet_pubsub_publish_duration_seconds` | p95 above its own 24h p95 by `> 3x` | The message-queue backend is blocking the publisher. | | `hatchet_reassigned_tasks` | any increase over 10m | Assignments are lapsing, usually a worker losing its heartbeat. | | `hatchet_rate_limited` | any increase over 10m while `hatchet_tenant_queue_size` is also rising | Rate limits are the reason for the backlog rather than a symptom of it. The counter carries no labels, so this is a time correlation, not a per-workflow one. | | `go_goroutines` | above the 24h p95 by `> 3x` | Goroutine growth in the engine ahead of a memory problem. | ### Access Setup #### Turn on the metrics endpoint The endpoint does not exist until you enable it. Set `SERVER_PROMETHEUS_ENABLED=true` on the engine (or on `hatchet-lite`, which carries the engine) and expose the port: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: hatchet-lite: image: ghcr.io/hatchet-dev/hatchet/hatchet-lite:v0.105.16 environment: DATABASE_URL: ${DATABASE_URL} # no listener on 9090 without this SERVER_PROMETHEUS_ENABLED: "true" # defaults; both are changeable SERVER_PROMETHEUS_ADDRESS: ":9090" SERVER_PROMETHEUS_PATH: "/metrics" ports: - "9090:9090" ``` Unlike most components both the address and the path move. `SERVER_PROMETHEUS_ADDRESS` defaults to `:9090` and `SERVER_PROMETHEUS_PATH` defaults to `/metrics`; setting them to, for example, `:9464` and `/telemetry` serves the exposition there instead, with `/metrics` on that port returning 404 and 9090 refusing connections. Point the scrape config at whatever you set. Confirm the exposition before touching the Collector: ```bash showLineNumbers title="Verify access" curl -s http://localhost:9090/metrics | grep -c '^# TYPE' curl -s http://localhost:9090/metrics | grep '^hatchet_created_tasks_total' ``` A connection refusal here - `curl` exiting 7 with `Failed to connect to localhost:9090 after 0 ms: Could not connect to server` - means the switch is off. It is not a 404 and not an empty page, so a check that only looks at HTTP status sees no server rather than a disabled endpoint. The exposition is plain HTTP with no authentication. Bind it to an internal interface or restrict the port to the Collector's address. #### Turn on trace export Traces are a separate switch and push to the Collector rather than being scraped: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: hatchet-lite: environment: # bare host:port, no scheme; OTLP over gRPC, there is no HTTP option SERVER_OTEL_COLLECTOR_URL: "otel-collector:4317" SERVER_OTEL_SERVICE_NAME: "hatchet" SERVER_OTEL_INSECURE: "true" # defaults to 1, meaning every trace; sample before production SERVER_OTEL_TRACE_ID_RATIO: "0.01" ``` `SERVER_OTEL_SERVICE_NAME` defaults to `server`, so set it or every Hatchet deployment lands under the same service in Scout. Set `SERVER_OTEL_INSECURE` to `false` and terminate TLS on the Collector where the hop leaves the host. Hatchet also has a `SERVER_OTEL_METRICS_ENABLED` switch, defaulting to false, which turns on an OTLP metrics exporter to the same collector URL. This guide collects metrics by scraping the Prometheus endpoint instead, and what the OTLP path emits is not covered here. ### Configuration The `prometheus` receiver handles metrics and the `otlp` receiver handles the pushed traces. The scrape is unfiltered, so no metric enable list is needed; the Prometheus receiver synthesises the `up` series alongside `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling` and `scrape_series_added`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: hatchet scrape_interval: 15s static_configs: - targets: - ${env:HATCHET_HOST}:9090 # match SERVER_PROMETHEUS_ADDRESS # metrics_path: /metrics # set if you moved the path otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] traces: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` Run the Collector on `otel/opentelemetry-collector-contrib:latest` or a pinned tag of it. Drop the traces pipeline if you are only collecting metrics. On a single-tenant install the per-tenant twins carry the same numbers as the global counters. If you do not want to collect them, filter them in the receiver rather than downstream: ```yaml showLineNumbers title="config/otel-collector.yaml (Diagnostic drop)" metric_relabel_configs: - source_labels: [__name__] regex: 'hatchet_tenant_(created_tasks|succeeded_tasks|failed_tasks|cancelled_tasks|skipped_tasks|assigned_tasks|reassigned_tasks|scheduling_timed_out|rate_limited|queue_invocations|queued_to_assigned|queued_to_assigned_time_seconds(_bucket|_sum|_count)?)' action: drop ``` Prometheus anchors `metric_relabel_configs` patterns at both ends, so each name is listed in full and no trailing `.*` is used. That is what keeps `hatchet_tenant_queued_to_assigned_by_workflow` and `hatchet_tenant_queued_to_assigned_time_seconds_by_workflow`, which are Operational, out of the drop. A trailing `.*` after `queued_to_assigned` would take both. #### Environment Variables ```bash showLineNumbers title=".env" HATCHET_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check within 60 seconds: ```bash showLineNumbers # The scrape target is up curl -s http://localhost:9090/metrics | grep -c '^hatchet_' # The Collector is scraping Hatchet docker logs otel-collector 2>&1 | grep -i "hatchet_created_tasks" # Traces are arriving, if the traces pipeline is enabled docker logs otel-collector 2>&1 | grep -i "hatchet.run/" ``` In Scout, `up{job="hatchet"}` should read 1 and `hatchet_created_tasks_total` should climb as work is submitted. On an engine that has just started, expect fewer than 34 Hatchet families until each code path has run once. ### Troubleshooting #### The scrape fails with a connection refusal **Cause**: `SERVER_PROMETHEUS_ENABLED` is unset or false, so nothing is listening, or the listener moved. **Look at**: `up` for the `hatchet` job. It reads 0, and no `hatchet_` series arrive at all. **Fix**: 1. Set `SERVER_PROMETHEUS_ENABLED=true` on the engine and restart it. 2. If `SERVER_PROMETHEUS_ADDRESS` or `SERVER_PROMETHEUS_PATH` is set, match the scrape config to them. 3. Probe from the Collector's network namespace, not from your laptop: `curl -s http://hatchet:9090/metrics | head`. #### `hatchet_tenant_queue_size` vanishes from a dashboard **Cause**: The queue drained. The scheduler reports the series as 0 for one poll, then deletes it. **Look at**: the Hatchet family count. It is 34 with a non-empty queue and 33 when every queue is drained, and `up` stays at 1 throughout. **Fix**: 1. Treat an absent series as an empty queue, not a broken scrape. 2. Use `max_over_time(hatchet_tenant_queue_size[10m])` or an `or vector(0)` fallback so panels and alerts tolerate the gap. 3. Do not alert on `absent()` for this metric. #### A retry alert never fires **Cause**: `hatchet_retried_tasks_total` does not increment, and retried attempts are excluded from `hatchet_failed_tasks_total` as well. **Look at**: the Diagnostic-tier `hatchet_retried_tasks_total` - it sits at 0 regardless of retry activity, and `hatchet_tenant_retried_tasks` never registers at all. **Fix**: 1. Count `status="FAILED"` observations on `hatchet_tenant_workflow_duration_milliseconds` for the workflow; that is where a retried attempt shows up. 2. Alert on final failures with `hatchet_failed_tasks_total` and treat retries as a per-workflow signal, not a global counter. #### Cancellations look higher than the cancels you issued **Cause**: A scheduling timeout also increments `hatchet_cancelled_tasks_total`. **Look at**: `hatchet_scheduling_timed_out` over the same window. Most of the cancellation count is usually timeouts rather than cancels you issued. **Fix**: 1. Subtract the increase in `hatchet_scheduling_timed_out` from the increase in `hatchet_cancelled_tasks_total` before alerting. 2. Never sum the two - that double-counts every timed-out task. #### The failure rate is up and the Core counters do not say whose **Cause**: `hatchet_created_tasks_total`, `hatchet_succeeded_tasks_total` and `hatchet_failed_tasks_total` are summed across tenants, so one tenant failing hard looks the same as every tenant degrading a little. **Look at**: the Diagnostic tier's per-tenant twins, split by `tenant_id` - `hatchet_tenant_created_tasks` against `hatchet_tenant_failed_tasks` for the failure split, and `hatchet_tenant_rate_limited` and `hatchet_tenant_scheduling_timed_out` for tenants the scheduler is already holding back. `tenant_id` is the only label that separates them; the Core counters carry none. **Fix**: rate-limit the tenant that dominates the split, or give it its own worker pool. On a single-tenant install the twins carry the same numbers as the Core counters, so this tier can stay dropped. #### Queue-wait p95 reads `+Inf` **Cause**: `hatchet_queued_to_assigned_time_seconds` and its per-tenant and per-workflow variants stop bucketing at 15 seconds. Once queue waits pass that ceiling, most observations land in `+Inf`. **Look at**: the `le="+Inf"` bucket against `le="15"` - when the overflow bucket dominates, quantiles above roughly p20 are meaningless. **Fix**: 1. Measure saturation with `hatchet_tenant_queue_size` and the assignment counters instead. 2. Use `hatchet_tenant_workflow_duration_milliseconds` for latency; its buckets run to 24 hours. #### Counters reset and families disappear after a deploy **Cause**: The counters are process-local. Restarting the engine zeroes them and de-registers every per-tenant family until traffic re-registers it. **Look at**: `process_start_time_seconds` for the restart, and the Hatchet family count climbing from 18 back to 34 over the first few minutes. **Fix**: 1. Build dashboards on `rate()` or `increase()`, which handle counter resets, rather than on raw counter values. 2. Do not treat a missing family on a freshly started engine as a configuration problem. #### Trace volume overwhelms the pipeline **Cause**: `SERVER_OTEL_TRACE_ID_RATIO` defaults to `1`. A single-node engine with one four-slot worker and no dashboard traffic emits on the order of 100 spans per second. **Look at**: Collector queue and export metrics, and the span-kind mix - Client spans from `otelpgx` dominate at roughly two thirds of the volume. **Fix**: 1. Set `SERVER_OTEL_TRACE_ID_RATIO` to a small fraction before enabling traces outside a test environment. 2. Add a `tail_sampling` or `probabilistic_sampler` processor in the Collector if you need the ratio tuned without restarting Hatchet. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Do I need RabbitMQ or NATS to get these metrics? No. The message queue defaults to `postgres`, and every metric in this guide is emitted on that default. The only family that depends on the backend is `hatchet_pubsub_nats_scheduler_partition_drops_total`, which registers only on NATS. #### Which component do I scrape in a split deployment? The engine. The API server and the dashboard do not carry this exposition. On `hatchet-lite` the API, the engine and the dashboard run in one container, so you scrape that container. #### Can I move the metrics port or path? Yes. `SERVER_PROMETHEUS_ADDRESS` (default `:9090`) and `SERVER_PROMETHEUS_PATH` (default `/metrics`) both take non-default values. Set `metrics_path` in the scrape config to match if you move the path. #### Do the traces show my workflow runs? No. The span names are Go function names and SQL statement names, so the trace surface explains engine behaviour - scheduling, queue polling, database calls - not the lifecycle of a specific task or workflow run. End-to-end workflow tracing comes from the SDK's own worker-side instrumentation. #### Should I collect the global counters, the per-tenant ones, or both? One or the other. On a single-tenant deployment all eleven pairs carry identical values, so collecting both doubles the series for no extra signal. Keep `hatchet_tenant_*` on a multi-tenant install and the global counters on a single-tenant one. #### Why do some counters end in `_total` and others do not? The naming is inconsistent upstream. `hatchet_assigned_tasks`, `hatchet_scheduling_timed_out`, `hatchet_rate_limited`, `hatchet_queued_to_assigned` and `hatchet_reassigned_tasks` are counters with no suffix; the rest carry `_total`. They are the same kind of metric and there is no missing series to look for. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Hatchet metrics. - [Temporal Monitoring](./temporal.md) - Durable-execution engine with a workflow-and-activity model rather than Hatchet's task-and-DAG one. - [PostgreSQL Monitoring](./postgres.md) - Hatchet's database and, by default, its message queue. ### What's Next? - **Create Dashboards**: Start with task inflow, the four terminal counters and `hatchet_tenant_queue_size`. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add [PostgreSQL](./postgres.md) for the database behind the queue, and [Temporal](./temporal.md) if you run both engines. - **Fine-tune Collection**: Decide which tiers you keep. On a single-tenant install the Diagnostic tier repeats the global counters, and `SERVER_OTEL_TRACE_ID_RATIO` sets the trace sample rate before you turn traces on in production. --- ## IIS OpenTelemetry Monitoring - Request Rates, W3C Access Logs, and HTTP Semantic Conventions ## IIS (Windows) The OpenTelemetry Collector's `iisreceiver` collects 12 metrics from IIS 10+ on Windows Server 2016+, including request counts, connection state, queue depth, and uptime. Paired with the `filelog` receiver this guide also parses IIS W3C access logs into OTel HTTP semantic conventions (`http.request.method`, `http.response.status_code`, `url.path`, etc.) so per-status and per-method queries work in Scout without log-side regex. ### Prerequisites | Requirement | Minimum | Recommended | | --- | --- | --- | | Windows Server | 2016 (IIS 10.0) | 2022 (IIS 10.0) | | OTel Collector Contrib | 0.90.0 | 0.152+ | | base14 Scout | Any | - | Before starting: - IIS installed and a site bound (default `Default Web Site` is fine). - Per-site W3C logging enabled (the default for fresh installs). - OTel Collector Contrib for Windows installed as a service - see [Windows Setup](../collector-setup/windows-setup.md). ### What You'll Monitor - **Requests**: per-method request counters, rejected requests at the W3SVC layer, request queue depth and oldest-request age. - **Connections**: active TCP connections, attempts, anonymous connections. - **Workers**: active worker threads. - **Traffic**: bytes sent and received, file operations. - **Uptime**: IIS service uptime. - **W3C access logs**: every HTTP request line mapped to OTel HTTP semantic conventions (method, status, body sizes, URL, server, client, user-agent, referer, user). - **Windows Event Log**: Application-channel events from `IIS-W3SVC`, `IIS-W3SVC-PerfCounters`, `IIS-W3SVC-WP`, `WAS`, and other IIS-related providers. Full metric reference: [OTel IIS Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/iisreceiver). ### Access Setup #### Enable W3C logging W3C logging is the default for fresh installs but verify it explicitly because some hardened images switch to IIS-format or disable logging. Open an elevated PowerShell: ```powershell showLineNumbers # Confirm logFormat is W3C for every site. Get-WebConfigurationProperty ` -PSPath 'IIS:\' -Filter 'system.applicationHost/sites/siteDefaults/logFile' ` -Name logFormat ``` Expected output: `W3C`. If it shows `IIS` or `NCSA`, set it to W3C: ```powershell showLineNumbers Set-WebConfigurationProperty ` -PSPath 'IIS:\' -Filter 'system.applicationHost/sites/siteDefaults/logFile' ` -Name logFormat -Value W3C ``` #### Pin the W3C field set The receiver and the in-collector regex below assume the IIS default 17-field W3C schema: ```text date time s-ip cs-method cs-uri-stem cs-uri-query s-port cs-username c-ip cs(User-Agent) cs(Referer) sc-status sc-substatus sc-win32-status sc-bytes cs-bytes time-taken ``` Custom fields appended to the schema will not break the parser (the regex anchors to the first 17 columns), but reordering the default fields will. Leave the site-level `Selected W3C Fields` at defaults unless you have a specific reason to change them. The log files land at `C:\inetpub\logs\LogFiles\W3SVC\u_ex.log` by default; IIS rolls them daily, and the `filelog` receiver tails by inode so the roll does not lose lines. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: iis: collection_interval: 60s # W3C access logs. Per-site files under # C:\inetpub\logs\LogFiles\W3SVC\, rolled daily. filelog/iis: include: - 'C:\inetpub\logs\LogFiles\**\*.log' start_at: end include_file_name: true include_file_path: true operators: # Drop W3C header / comment lines. - type: filter expr: 'body matches "^#"' # Capture the 17 W3C fields into a w3c_ staging namespace; see FAQ. - type: regex_parser regex: '^(?P\d{4}-\d{2}-\d{2} \d{2}:\d{2}:\d{2}) (?P\S+) (?P\S+) (?P\S+) (?P\S+) (?P\d+) (?P\S+) (?P\S+) (?P\S+) (?P\S+) (?P\d+) (?P\d+) (?P\d+) (?P\d+) (?P\d+) (?P\d+)$' timestamp: parse_from: attributes.w3c_timestamp layout: '%Y-%m-%d %H:%M:%S' location: UTC on_error: send # Application-channel Windows events (app-pool start/stop, WP crashes, etc.). windowseventlog/iis: channel: Application start_at: end raw: true processors: # Stamp service.name + environment on every record. resource: attributes: - key: service.name value: ${env:SERVICE_NAME} action: upsert - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert # Map staged W3C fields to OTel HTTP semconv; see FAQ for rationale. transform/iis_w3c: error_mode: ignore log_statements: - context: log conditions: - 'attributes["w3c_method"] != nil' statements: # HTTP request - 'set(attributes["http.request.method"], attributes["w3c_method"])' - 'set(attributes["http.request.body.size"], Int(attributes["w3c_cs_bytes"]))' # HTTP response - 'set(attributes["http.response.status_code"], Int(attributes["w3c_status"]))' - 'set(attributes["http.response.body.size"], Int(attributes["w3c_sc_bytes"]))' # URL - 'set(attributes["url.path"], attributes["w3c_uri_stem"])' - 'set(attributes["url.query"], attributes["w3c_uri_query"]) where attributes["w3c_uri_query"] != "-"' - 'set(attributes["url.scheme"], "https") where attributes["w3c_s_port"] == "443"' - 'set(attributes["url.scheme"], "http") where attributes["w3c_s_port"] != "443"' # Server / client - 'set(attributes["server.address"], attributes["w3c_s_ip"])' - 'set(attributes["server.port"], Int(attributes["w3c_s_port"]))' - 'set(attributes["client.address"], attributes["w3c_c_ip"])' # User agent (W3C encodes whitespace as `+`). - 'set(attributes["user_agent.original"], attributes["w3c_user_agent"]) where attributes["w3c_user_agent"] != "-"' - 'replace_pattern(attributes["user_agent.original"], "\\+", " ") where attributes["user_agent.original"] != nil' # Referer header. - 'set(attributes["http.request.header.referer"], attributes["w3c_referer"]) where attributes["w3c_referer"] != "-"' # Authenticated user. - 'set(attributes["user.name"], attributes["w3c_username"]) where attributes["w3c_username"] != "-"' # IIS-specific (no OTel semconv equivalent). - 'set(attributes["iis.sc_substatus"], Int(attributes["w3c_substatus"]))' - 'set(attributes["iis.sc_win32_status"], Int(attributes["w3c_win32_status"]))' - 'set(attributes["iis.time_taken_ms"], Int(attributes["w3c_time_taken"]))' # Drop the staging keys. - 'delete_key(attributes, "w3c_timestamp")' - 'delete_key(attributes, "w3c_s_ip")' - 'delete_key(attributes, "w3c_method")' - 'delete_key(attributes, "w3c_uri_stem")' - 'delete_key(attributes, "w3c_uri_query")' - 'delete_key(attributes, "w3c_s_port")' - 'delete_key(attributes, "w3c_username")' - 'delete_key(attributes, "w3c_c_ip")' - 'delete_key(attributes, "w3c_user_agent")' - 'delete_key(attributes, "w3c_referer")' - 'delete_key(attributes, "w3c_status")' - 'delete_key(attributes, "w3c_substatus")' - 'delete_key(attributes, "w3c_win32_status")' - 'delete_key(attributes, "w3c_sc_bytes")' - 'delete_key(attributes, "w3c_cs_bytes")' - 'delete_key(attributes, "w3c_time_taken")' batch: timeout: 10s send_batch_size: 200 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [iis] processors: [resource, batch] exporters: [otlphttp/b14] logs: receivers: [filelog/iis, windowseventlog/iis] processors: [resource, transform/iis_w3c, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Restart the Collector service after writing the config: ```powershell showLineNumbers Restart-Service OtelCollector ``` Generate at least one request so IIS writes a log line, then check the local self-telemetry endpoint for non-zero export counters: ```powershell showLineNumbers # Drive a request through IIS. Invoke-WebRequest -UseBasicParsing http://localhost/ | Out-Null # Self-telemetry endpoint; default port 8888. (Invoke-WebRequest -UseBasicParsing http://localhost:8888/metrics).Content | Select-String 'otelcol_exporter_sent_(metric_points|log_records)' ``` Both `otelcol_exporter_sent_metric_points` and `otelcol_exporter_sent_log_records` should report non-zero and increasing values across two consecutive scrapes. In Scout, scope to the value you set as `SERVICE_NAME` and verify: - `iis.request.count` reports with the `request` dimension set (`GET`, `POST`, etc.) and is non-zero. - Log records show `http.request.method`, `http.response.status_code`, and `url.path` as first-class attributes (not embedded in Body). - The record timestamp matches the W3C `date time` columns, not the collector read time. ### Troubleshooting #### No log records appearing **Cause**: IIS buffers W3C writes (default 60s flush, or buffer-full). Under low traffic the first records may not surface until the next flush boundary. **Fix**: 1. Drive enough traffic to fill the buffer (`Invoke-WebRequest http://localhost/` in a loop), or 2. Force a flush in tests via `appcmd stop site 'Default Web Site' && appcmd start site 'Default Web Site'`, or 3. Wait at least 60s after the first request before reading from Scout. #### `http.response.status_code` arrives as a string **Cause**: The OTel HTTP semantic conventions require `int` for `http.response.status_code`, `http.request.body.size`, `http.response.body.size`, and `server.port`. Direct `set(attributes["http.response.status_code"], attributes["w3c_status"])` without an `Int(...)` cast forwards the regex capture as a string. **Fix**: 1. Wrap each numeric `set(...)` with `Int(...)` as the configuration above does. 2. Use Scout-side type assertions to spot any missed cast - a query like `http.response.status_code >= 500` returns zero results when the attribute is a string. #### User-agent shows literal `+` characters **Cause**: IIS encodes whitespace in W3C user-agent and referer fields as `+` (and other non-printable bytes as `%xx`). Without decoding, downstream parsers see `Mozilla/5.0+(Windows+NT;...)` instead of the human-readable form. **Fix**: 1. Keep the `replace_pattern(attributes["user_agent.original"], "\\+", " ")` statement in the `transform/iis_w3c` block. 2. If you also want `%xx` decoding, add a Lua extension; OTTL does not have a built-in URL-decode function as of `0.152.0`. #### Windows Event Log filter rejected at service start **Cause**: The `windowseventlog` receiver validates the XPath predicate during service start. Multi-clause provider predicates (e.g. `*[System/Provider[@Name='IIS-W3SVC' or @Name='IIS-W3SVC-WP']]`) are rejected with an SCM error ("An exception occurred in the service when handling the control request") and no actionable diagnostic in the Application channel. **Fix**: 1. Start without an XPath filter, as the configuration above does, and rely on Scout-side filtering by provider name; or 2. Use a single-clause predicate (one provider at a time) and add one receiver block per provider; or 3. Pin a working multi-clause dialect against your specific `otelcol-contrib` version - the surface changes between minor releases. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check the Collector log for export errors - `Get-WinEvent -ProviderName OtelCollector -MaxEvents 20`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly and the Collector service has the env var (`Get-ItemProperty 'HKLM:\SYSTEM\CurrentControlSet\Services\OtelCollector'`). 3. Confirm both `metrics` and `logs` pipelines list `otlphttp/b14` in `exporters:`. ### FAQ #### Why are W3C fields staged under a `w3c_` prefix instead of mapped directly? Go regex (the engine the OTel `regex_parser` operator uses) disallows `.` in named capture groups, so capturing directly into e.g. `http.request.method` is not possible. The two-stage shape (regex into `w3c_*`, transform processor into OTel semconv) is the canonical workaround. #### Why is there an `iis.` namespace alongside the standard OTel attributes? `sc-substatus`, `sc-win32-status`, and `time-taken` are IIS-specific and have no OTel semantic-convention equivalent. They go under an `iis.` vendor namespace so Scout queries can opt into them without polluting the standard HTTP attribute set. #### Does the OpenTelemetry iisreceiver work in Windows Server Containers? Yes. Run the OTel Collector for Windows alongside IIS in the same container or as a sidecar; the log path and receiver config above are unchanged. The collection_interval may need to drop to 10-20s for short-lived containers so the metrics pipeline emits at least one datapoint before the container exits. #### How do I monitor multiple IIS sites on one host with OpenTelemetry? The `filelog/iis` glob (`C:\inetpub\logs\LogFiles\**\*.log`) already covers every site (`W3SVC1`, `W3SVC2`, etc.). The `log.file.path` attribute carries the per-site log path, so site-level filtering in Scout is a query on `log.file.path contains 'W3SVC2'`. The `iisreceiver` reports a single global metric set per IIS instance, not per-site. #### What about IIS Express? IIS Express does not surface the W3SVC performance counters that `iisreceiver` reads from, so metrics will be empty. W3C logging still works if IIS Express is configured to write logs; point the `filelog/iis` glob at its log directory (typically `%USERPROFILE%\Documents\IISExpress\Logs\`). #### Does the OpenTelemetry iisreceiver work with IIS Express? IIS Express does not surface the `W3SVC` performance counters that `iisreceiver` reads from, so metrics will be empty. W3C logging still works if IIS Express is configured to write logs; point the `filelog/iis` include glob at the IIS Express log directory under the user profile. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) - **Monitor More Components**: Add monitoring for [SQL Server](./sqlserver.md), [Apache HTTP Server](./apache-httpd.md), and other components. - **Fine-tune Collection**: Drop `collection_interval` below 60s if you need faster metric resolution, at the cost of higher collector CPU on the host. ### Related Guides - [Windows Setup](../collector-setup/windows-setup.md) - Install OTel Collector Contrib as a Windows service. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Apache HTTP Server Monitoring](./apache-httpd.md) - Alternative web server monitoring. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on IIS request and status metrics. --- ## Component Monitoring Overview - OpenTelemetry Collector Setup ## Component Monitoring Component monitoring collects **metrics, traces, and logs** from databases, caches, message queues, proxies, and containers using the OpenTelemetry Collector. Each guide configures a dedicated receiver or Prometheus scrape target and ships telemetry to base14 Scout. ### Components by Category #### Databases | Component | Guide | Key Metrics | | ------------------- | -------------------------------------------------------------- | -------------------------------------------------- | | PostgreSQL Basic | [PostgreSQL Basic](./collecting-postgres-telemetry) | Connections, query performance, locks, WAL | | PostgreSQL Advanced | [PostgreSQL Advanced](./collecting-postgres-advanced-telemetry) | Query stats, table/index sizes, replication | | MySQL | [MySQL](./collecting-mysql-telemetry) | Connections, queries, InnoDB, replication | | MongoDB | [MongoDB](./collecting-mongodb-telemetry) | Operations, connections, document metrics, cursors | | Cassandra | [Cassandra](./collecting-cassandra-telemetry) | Client requests, compaction, storage, caches | | CouchDB | [CouchDB](./collecting-couchdb-telemetry) | Request rates, document operations, view stats | | Elasticsearch | [Elasticsearch](./collecting-elasticsearch-telemetry) | Cluster health, node stats, JVM, index operations | | ClickHouse | [ClickHouse](./collecting-clickhouse-telemetry) | Queries, inserts, memory tracking, merge operations | | Couchbase | [Couchbase](./collecting-couchbase-telemetry) | Cluster management, KV connections, CPU, memory | | MariaDB | [MariaDB](./collecting-mariadb-telemetry) | Connections, queries, InnoDB, replication | #### Time-Series Databases | Component | Guide | Key Metrics | | --------- | ------------------------------------------------- | ------------------------------------------------------ | | InfluxDB | [InfluxDB](./collecting-influxdb-telemetry) | Write throughput, query duration, storage, cardinality | #### Key-Value & Distributed Storage | Component | Guide | Key Metrics | | --------- | --------------------------------------------- | -------------------------------------------------- | | Aerospike | [Aerospike](./collecting-aerospike-telemetry) | Connections, transactions, memory, namespace stats | | etcd | [etcd](./collecting-etcd-telemetry) | Raft proposals, disk latency, MVCC, gRPC | #### Vector Databases | Component | Guide | Key Metrics | |-----------|-------------------------------------------|--------------------------------------------------------| | Qdrant | [Qdrant](./collecting-qdrant-telemetry) | Request rate and latency, collection points, update queue, memory and mmap ceilings | | Milvus | [Milvus](./collecting-milvus-telemetry) | Request rate and error rate, search and insert latency, ingestion lag, entity counts, segment growth | | Weaviate | [Weaviate](./collecting-weaviate-telemetry) | REST, GraphQL and gRPC request rate and errors, query and write latency, vector index size, async index queue depth | #### Search | Component | Guide | Key Metrics | | ---------- | ------------------------------------------------- | --------------------------------------------------- | | Solr | [Solr](./collecting-solr-telemetry) | JVM heap, GC, request rates, cores, threads | | OpenSearch | [OpenSearch](./collecting-opensearch-telemetry) | Cluster health, search latency, JVM, storage I/O | #### Caching | Component | Guide | Key Metrics | | --------- | ----------------------------------------------- | ---------------------------------------------------- | | Redis | [Redis](./collecting-redis-telemetry) | Memory, keyspace, commands, clients, replication | | Memcached | [Memcached](./collecting-memcached-telemetry) | Hit ratio, memory, connections, evictions | | Varnish | [Varnish](./collecting-varnish-telemetry) | Cache hit/miss, backend health, connections | #### Message Queues | Component | Guide | Key Metrics | | --------- | ----------------------------------------------- | ---------------------------------------------------- | | RabbitMQ | [RabbitMQ](./collecting-rabbitmq-telemetry) | Queue depth, message rates, node memory, I/O | | Kafka | [Kafka](./collecting-kafka-telemetry) | Consumer lag, partition offsets, broker count | | NATS | [NATS](./collecting-nats-telemetry) | Connections, subscriptions, message rates, JetStream | | Pulsar | [Pulsar](./collecting-pulsar-telemetry) | Broker throughput, backlog, managed ledger, storage | | ActiveMQ | [ActiveMQ](./collecting-activemq-telemetry) | Queue depth, enqueue/dequeue, producers, consumers | #### Service Discovery & Coordination | Component | Guide | Key Metrics | | --------- | ----------------------------------------------- | ------------------------------------------------ | | Consul | [Consul](./collecting-consul-telemetry) | Raft consensus, service catalog, RPC, gossip | | ZooKeeper | [ZooKeeper](./collecting-zookeeper-telemetry) | Connections, latency, znodes, watches, packets | #### Secrets Management | Component | Guide | Key Metrics | | --------- | ----------------------------------------- | ------------------------------------------------- | | Vault | [Vault](./collecting-vault-telemetry) | Seal operations, token lifecycle, barrier, leases | #### AI Model Serving | Component | Guide | Key Metrics | |-----------|-----------------------------------------|--------------------------------------------------------| | vLLM | [vLLM](./collecting-vllm-telemetry) | KV-cache usage, request queueing, token throughput, latency phases | | llama.cpp | [llama.cpp](./collecting-llama-cpp-telemetry) | Slot occupancy and queueing, token throughput, prompt-cache reuse, batching efficiency | #### AI Gateways | Component | Guide | Key Metrics | |-----------------|--------------------------------------------------------|------------------------------------------------------------------------| | LiteLLM Gateway | [LiteLLM Gateway](./collecting-litellm-telemetry) | Deployment health and cooldowns, request failures, latency split, token spend | | Bifrost | [Bifrost](./collecting-bifrost-telemetry) | LLM request outcomes, provider latency, token usage, streaming performance | #### Distributed Compute | Component | Guide | Key Metrics | |-----------|-----------------------------------------|--------------------------------------------------------| | Ray | [Ray](./collecting-ray-telemetry) | Task and actor state, cluster resources, object store and spilling, scheduler placement | #### Orchestration | Component | Guide | Key Metrics | | --------- | --------------------------------------------- | -------------------------------------------------- | | Temporal | [Temporal](./collecting-temporal-telemetry) | Workflow latency, task queues, persistence, shards | | Hatchet | [Hatchet](./collecting-hatchet-telemetry) | Task inflow and outcome, queue backlog, worker slot capacity, per-workflow duration | | Restate | [Restate](./collecting-restate-telemetry) | Invocation rate and outcome, partition health, invoker backlog, workflow traces | | Nomad | [Nomad](./collecting-nomad-telemetry) | Raft consensus, broker, RPC, job status, autopilot | #### Continuous Delivery | Component | Guide | Key Metrics | | --------- | ------------------------------------------- | ----------------------------------------------------- | | ArgoCD | [ArgoCD](/guides/cicd-observability/collecting-argocd-telemetry) | App sync status, health, reconciliation, Git ops | | Jenkins | [Jenkins](./collecting-jenkins-telemetry) | Build results, executor usage, queue depth | #### Web Servers & Proxies | Component | Guide | Key Metrics | | ------------------ | ------------------------------------------------------------- | ---------------------------------------------------- | | NGINX | [NGINX](./collecting-nginx-telemetry) | Connections, request rate, worker states | | Apache HTTP Server | [Apache HTTP Server](./collecting-apache-httpd-telemetry) | Workers, scoreboard, request rate, bytes transferred | | HAProxy | [HAProxy](./collecting-haproxy-telemetry) | Sessions, request rate, backend health, queue depth | | Traefik | [Traefik](./collecting-traefik-telemetry) | Entrypoint requests, TLS, router stats, open conns | | Envoy | [Envoy](./collecting-envoy-telemetry) | Downstream connections, listeners, cluster manager | | Caddy | [Caddy](./collecting-caddy-telemetry) | Request rates, response codes, TLS handshakes | #### Object Storage | Component | Guide | Key Metrics | | --------- | ----------------------------------------- | ------------------------------------------------- | | MinIO | [MinIO](./collecting-minio-telemetry) | Cluster capacity, drive health, S3 requests, ILM | #### Database Proxies | Component | Guide | Key Metrics | | --------- | ------------------------------------------------- | -------------------------------------------------- | | PgBouncer | [PgBouncer](./collecting-pgbouncer-telemetry) | Connection pools, query throughput, client wait time | #### Containers | Component | Guide | Key Metrics | | ------------- | ----------------------------------------------- | ---------------------------------------------- | | Docker Engine | [Docker Engine](./collecting-docker-telemetry) | CPU, memory, block I/O, network per container | #### Java Application Servers | Component | Guide | Key Metrics | | --------- | ----------------------------------------------- | ---------------------------------------------------- | | Tomcat | [Tomcat](./collecting-tomcat-telemetry) | Request rates, thread pools, sessions, network I/O | | Jetty | [Jetty](./collecting-jetty-telemetry) | Threads, I/O selects, sessions, request queue | | WildFly | [WildFly](./collecting-wildfly-telemetry) | Undertow requests, datasource pools, transactions | #### Network & IoT Devices | Component | Guide | Key Metrics | | --------- | ------------------------------------------- | --------------------------------------------------------- | | SNMP | [SNMP](./collecting-snmp-telemetry) | Interface I/O, CPU/memory, UPS battery, device status | For MQTT, Sparkplug B, OPC-UA, and edge Collector store-and-forward patterns, see [IoT & Edge Instrumentation](../iot/index.md). ### How Component Monitoring Works Each component exposes metrics through one of three methods: 1. **Dedicated OTel receiver** - the Collector connects directly to the component's stats API (PostgreSQL, MySQL, MariaDB, MongoDB, Redis, RabbitMQ, Elasticsearch, CouchDB, Memcached, Apache HTTP Server, HAProxy, ZooKeeper, Kafka, Aerospike, Docker Engine) 2. **Prometheus scrape** - the component or a sidecar exporter exposes a `/metrics` endpoint that the Collector scrapes (Cassandra via JMX exporter, Consul, Vault, etcd, Solr, Temporal, NGINX, ClickHouse, NATS via prometheus-nats-exporter, Traefik, Envoy, MinIO, OpenSearch via prometheus-exporter plugin, PgBouncer via pgbouncer-exporter, Nomad, Couchbase, Pulsar, ArgoCD, Jenkins via Prometheus Metrics plugin, InfluxDB, Caddy, Varnish via prometheus_varnish_exporter) 3. **JMX Scraper** - a standalone process connects to the application's JMX port via RMI, converts MBeans to OpenTelemetry metrics, and exports OTLP to the Collector (Tomcat, ActiveMQ, Jetty, WildFly). See [JMX Metrics Collection Guide](../collector-setup/jmx-metrics-collection-guide.md). Java applications using JMX have two collection approaches: the OTel JMX Scraper (remote, OTLP-native) and the Prometheus JMX Exporter (in-process agent). See [JMX Metrics Collection Guide](../collector-setup/jmx-metrics-collection-guide.md) for a detailed comparison. NGINX also supports **distributed traces** via `nginx-module-otel` and **log collection** via the filelog receiver. ### Next Steps 1. **Choose your component** from the tables above 2. **Follow the guide** to configure the OTel Collector receiver 3. **Create dashboards** in Scout - see [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) --- ## InfluxDB OpenTelemetry Monitoring - Write Throughput, Query Latency, and Series Cardinality ## InfluxDB InfluxDB serves Prometheus text at `/metrics` on the API port `8086`. In InfluxDB 2.x this endpoint is public - no token, unlike the token-gated `/api/v2/*` data API. The OpenTelemetry Collector's `prometheus` receiver scrapes it directly, collecting 100+ metrics across HTTP API throughput and latency, the TSM storage engine (write path, cache, WAL, compaction), per-bucket series cardinality, and the Flux query controller. This guide configures the receiver and ships metrics to base14 Scout. :::note The Collector's `influxdbreceiver` is for **receiving** InfluxDB line-protocol writes (push model) - it acts as an InfluxDB-compatible write endpoint, not a health scraper. To monitor InfluxDB itself, use the `prometheus` receiver as shown here. ::: ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | InfluxDB | 2.0 | 2.7+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - InfluxDB's HTTP API port (`8086`) must be reachable from the host running the Collector. - InfluxDB initial setup must be complete (org, bucket, admin user). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Every row traces to InfluxDB's native Prometheus exposition. A few surface notes set the context for everything below: - **`up` is the liveness signal here.** The `prometheus` receiver emits `up` = 1 when `/metrics` responds, so that is what tells you InfluxDB is reachable. `influxdb_uptime_seconds` is the in-band process uptime - a reset means a restart. - **`/metrics` is public in InfluxDB 2.x.** No token is needed for the metrics endpoint; only the data API is token-gated. This metric surface is 2.x-specific - InfluxDB 1.x and 3.x (Core / Enterprise) expose different metric sets. - **The TSM storage engine is the durability core.** Writes land in the write-ahead log (`storage_wal_*`) and an in-memory cache (`storage_cache_*`), snapshot to TSM files (`storage_tsm_files_*`), then compact (`storage_compactions_queued`). Watch cache bytes (memory), WAL (disk), and the compaction backlog - a growing backlog means compaction cannot keep up. - **Series cardinality is the classic failure mode.** `storage_bucket_series_num` is the per-bucket series count; runaway growth blows up memory and is the most common InfluxDB incident. - **`qc_*` is the Flux query controller.** A query flows through queueing → compiling → executing, each with an `_active` gauge and a `_duration_seconds` histogram, so a slow read localizes to queue saturation vs compile vs execution. - **The storage-engine and query-controller families warm up under traffic.** `storage_cache_*`, `storage_wal_*`, `storage_compactions_*`, `storage_shard_*`, `storage_tsm_files_*`, and the `qc_*` family populate only after writes / queries / compactions occur - a fresh idle server shows mostly `http_*` / `influxdb_*` / `go_*`. Left enabled, they populate as traffic arrives. Histograms (`http_api_request_duration_seconds`, the `qc_*_duration_seconds` family) expand into `_bucket` / `_sum` / `_count`; the tables reference the base name. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape liveness - 1 means the InfluxDB metrics endpoint responded. The liveness signal on this surface. | | `http_api_requests_total` | HTTP API requests handled, labeled by path / method / status - headline throughput; writes and queries both arrive here. | | `storage_writer_ok_points` | Points written successfully - ingest throughput, the headline write signal for a TSDB. | | `storage_writer_err_points` | Points that failed to write - ingest errors. | | `qc_executing_duration_seconds` | Query execution latency - the read-path SLO. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | API latency and volume | `http_api_request_duration_seconds`, `http_write_request_count`, `http_query_request_count`, `http_write_request_bytes`, `http_query_response_bytes` | Per-path latency distribution and write / query request volume and bytes. | | Write path | `storage_writer_req_points`, `storage_writer_dropped_points`, `storage_writer_timeouts` | Points requested (the ok/err/dropped denominator), points dropped on schema / field-type conflicts, and write timeouts. | | Cache (memory) | `storage_cache_inuse_bytes`, `storage_cache_disk_bytes`, `storage_cache_writes_total`, `storage_cache_writes_err`, `storage_cache_writes_dropped` | In-memory write-cache pressure that must snapshot to TSM, plus cache write errors and drops. | | WAL (disk) | `storage_wal_size`, `storage_wal_writes`, `storage_wal_writes_err` | Write-ahead-log size on disk (the durability buffer) and WAL write errors - a disk durability problem. | | Compaction and TSM | `storage_compactions_queued`, `storage_tsm_files_disk_bytes`, `storage_tsm_files_total` | Queued TSM compactions (a growing backlog means compaction cannot keep up), on-disk TSM bytes, and TSM file count. | | Per-shard writes | `storage_shard_write_count`, `storage_shard_write_err_count`, `storage_shard_write_dropped_sum` | Per-shard write operations, errors, and drops. | | Cardinality | `storage_bucket_series_num` | Per-bucket series count - the cardinality signal; runaway growth blows up memory. | | Retention | `storage_retention_check_duration` | Retention-enforcement run duration. | | Query controller | `qc_requests_total`, `qc_queueing_duration_seconds`, `qc_queueing_active`, `qc_compiling_duration_seconds`, `qc_all_duration_seconds`, `qc_all_active`, `qc_executing_active`, `qc_memory_unused_bytes` | Flux queries received, time queued (controller saturation), compile time, total per-query time, in-flight / executing counts, and query-controller memory headroom (low values throttle queries). | | Uptime and tasks | `influxdb_uptime_seconds`, `task_scheduler_total_schedule_fails`, `task_scheduler_total_execute_failure`, `task_executor_workers_busy`, `task_executor_total_runs_active` | Process uptime (a reset is a restart) and task scheduling / execution failures plus task-executor load (downsampling / alerting tasks). | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Representative metrics | When you reach for it | |---|---|---| | Per-shard detail | `storage_shard_write_sum`, `storage_shard_write_err_sum`, `storage_shard_disk_size`, `storage_shard_series`, `storage_shard_fields_created`, `storage_cache_latest_snapshot` | Per-shard write volume, errors, on-disk size, series, fields, and the last cache-snapshot timestamp. | | Storage-read latency | `query_influxdb_source_read_request_duration_seconds` | The storage-read latency behind a Flux query. | | Compile internals | `qc_compiling_active` | Queries currently compiling. | | Metadata store | `boltdb_reads_total`, `boltdb_writes_total` | BoltDB metadata key-value store reads and writes. | | Resource inventory | `influxdb_buckets_total`, `influxdb_organizations_total`, `influxdb_users_total`, `influxdb_tokens_total`, `influxdb_dashboards_total`, `storage_bucket_measurement_num`, `influxdb_info` | Bucket / org / user / token / dashboard counts, per-bucket measurement count, and build / version labels. | | Control-plane calls | `service_bucket_new_call_total`, `service_org_new_duration`, `service_user_new_call_total` | Bucket / org / user create-call count and latency. | | Task-engine internals | `task_scheduler_current_execution`, `task_scheduler_schedule_delay`, `task_scheduler_total_execution_calls`, `task_executor_promise_queue_usage` | Task-scheduler timing and task-executor promise-queue fill. | | Runtime and scrape meta | `go_*`, `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_series_added` | InfluxDB's own Go runtime and the receiver-side Prometheus scrape meta. | Filter `go_*` and the scrape meta in production with the keep rule shown in [Configuration](#configuration). Full metric list: run `curl -s http://localhost:8086/metrics` against your InfluxDB instance. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. The error and WAL-error counters and `up` read as states; the rest are relative to your own baseline. These are starting points - tune them to your workload. | Alert | Threshold | Why it matters | |---|---|---| | InfluxDB unreachable | `up` == 0 for > 1m | The metrics endpoint stopped responding - check the process and the API port. | | Write errors rising | `rate(storage_writer_err_points)` > 0 or `rate(storage_writer_dropped_points)` > 0 | Points are failing to write - check field-type / schema conflicts and disk health. | | Compaction backlog growing | `storage_compactions_queued` rising vs baseline | Compaction cannot keep up with ingest - disk or CPU bound; write and query latency will degrade. | | Cardinality explosion | `storage_bucket_series_num` rising sharply vs baseline | Runaway series cardinality - find the offending tag and stop writing it; memory is at risk. | | WAL write errors | `rate(storage_wal_writes_err)` > 0 | The durability path is failing - check the disk. | | Query latency high | `qc_executing_duration_seconds` p99 rising, or `qc_queueing_duration_seconds` rising | Queries are slow or queued - the controller is saturated or a query is expensive. | | API latency high | `http_api_request_duration_seconds` p99 rising vs baseline | API requests are slow - correlate with the write / query path and disk. | | Task failures | `rate(task_scheduler_total_execute_failure)` > 0 | Downsampling / alerting tasks are failing - check task logs and the Flux scripts. | ### Access Setup InfluxDB 2.x exposes Prometheus metrics natively at `/metrics` on the API port `8086` - no exporter, no configuration change, and no token. This endpoint is public, distinct from the token-gated `/api/v2/*` data API, so the Collector scrapes it without credentials. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # Check InfluxDB is running curl -s http://localhost:8086/health # Verify the Prometheus metrics endpoint (no token required in 2.x) curl -s http://localhost:8086/metrics | head -20 ``` InfluxDB 1.x and 3.x (Core / Enterprise) expose the metrics endpoint differently and emit different metric sets; this guide targets the 2.x surface. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: influxdb scrape_interval: 10s static_configs: - targets: - ${env:INFLUXDB_HOST}:8086 # default /metrics path, public in 2.x metric_relabel_configs: # Scope to the InfluxDB families; drop the go_* runtime and scrape noise - source_labels: [__name__] regex: 'influxdb_.*|storage_.*|http_.*|qc_.*|query_.*|boltdb_.*|task_.*|service_.*|up' action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The `/metrics` endpoint is public in 2.x, so the scrape job needs no auth block. The `metric_relabel_configs` keep filter scopes collection to the InfluxDB product families and drops the `go_*` runtime series and Prometheus scrape meta. Keep it during normal operation; widen the regex if you want the `go_*` runtime during a deep investigation. #### Environment Variables ```bash showLineNumbers title=".env" INFLUXDB_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped InfluxDB metrics docker logs otel-collector 2>&1 | grep -i "influxdb" # Verify InfluxDB is healthy curl -s http://localhost:8086/health # Confirm the metrics endpoint is serving the product families curl -s http://localhost:8086/metrics | grep -E 'storage_writer_ok_points|http_api_requests_total' ``` The storage-engine (`storage_cache_*`, `storage_wal_*`, `storage_tsm_files_*`) and `qc_*` query-controller families appear only after writes and queries flow. Send a point and run a query, then re-check, if they are missing on a fresh server. ### Troubleshooting #### Connection refused on port 8086 **Cause**: The Collector cannot reach InfluxDB at the configured address. **Fix**: 1. Verify InfluxDB is running: `docker ps | grep influxdb` or `systemctl status influxd`. 2. Confirm the HTTP bind address in the InfluxDB config and that `8086` is the API port. 3. Check firewall rules if the Collector runs on a separate host. #### Storage-engine or query-controller metrics are missing **Cause**: The `storage_cache_*`, `storage_wal_*`, `storage_compactions_*`, `storage_shard_*`, `storage_tsm_files_*`, and `qc_*` families populate only after writes, queries, and compactions occur. On an idle server this is expected - the endpoint shows mostly `http_*` / `influxdb_*` / `go_*`. **Look at**: `storage_writer_ok_points` and `qc_requests_total` - if these are flat, no write or query traffic has reached InfluxDB yet. **Fix**: 1. Write a line-protocol point to a bucket and run a Flux query. 2. Re-scrape; the storage and query-controller families populate under traffic. #### Series cardinality is growing **Cause**: A high-cardinality tag (for example a unique ID or timestamp written as a tag) is multiplying series. **Look at**: `storage_bucket_series_num` per bucket - a sharp rise points to the offending bucket; `storage_bucket_measurement_num` narrows it to a measurement. **Fix**: 1. Identify the tag with unbounded values in the high-cardinality bucket. 2. Stop writing that value as a tag (move it to a field, or drop it). 3. Series cardinality drives InfluxDB memory; runaway growth is the most common incident. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with InfluxDB running in Kubernetes? Yes. Set `targets` to the InfluxDB service DNS endpoint (for example `influxdb.default.svc.cluster.local:8086`). The `/metrics` endpoint is public in 2.x, so no token is needed. The Collector can run as a sidecar or DaemonSet. #### Does this work with InfluxDB 1.x or 3.x? This guide targets InfluxDB 2.x. The `prometheus` receiver will scrape a 1.x or 3.x (Core / Enterprise) endpoint, but those versions expose different metric sets - the names here (`storage_*`, `qc_*`, `http_api_*`) are 2.x-specific. Expect different families on 1.x and 3.x. #### Why are the storage metrics reading zero? The TSM storage-engine families (`storage_cache_*`, `storage_wal_*`, `storage_tsm_files_*`, `storage_compactions_*`) and the `qc_*` query-controller families warm up under traffic - they populate only after writes, queries, and compactions occur. A fresh idle server shows mostly `http_*` / `influxdb_*` / `go_*`. Send a write and a query and re-scrape. #### How do I track and stop runaway series cardinality? Watch `storage_bucket_series_num`, the per-bucket series count. A sharp rise signals a high-cardinality tag; find the tag with unbounded values and stop writing it as a tag. Cardinality drives InfluxDB memory, so this is the metric to alert on early. #### What about the OTel InfluxDB receiver? The `influxdbreceiver` in the Collector Contrib receives InfluxDB line-protocol writes - it acts as an InfluxDB-compatible write endpoint, not a metrics scraper. To monitor InfluxDB itself, use the `prometheus` receiver as shown here. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on InfluxDB metrics. - [PostgreSQL Monitoring](./postgres.md) - Relational database monitoring. - [MySQL Monitoring](./mysql.md) - Relational database monitoring. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md) and other data infrastructure. - **Fine-tune Collection**: Keep the `metric_relabel_configs` keep filter in production to drop the `go_*` runtime and scrape noise; widen the regex when you want the Go runtime series during a deep investigation. --- ## Jenkins OpenTelemetry Monitoring - Build Results, Executor Usage, and Queue Depth ## Jenkins Jenkins exposes Prometheus text at `/prometheus/` (trailing slash) on the web port `:8080` when the Prometheus Metrics plugin is installed. The Collector's `prometheus` receiver scrapes it, collecting 350+ metrics across build results, executor usage, queue depth, node / agent status, plugin health, HTTP request handling, and the JVM. This guide installs the plugin, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ------------------------- | ------- | ------------ | | Jenkins | 2.479.3 | LTS (latest) | | Prometheus Metrics plugin | Current | latest | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The Jenkins web port (`8080`) must be reachable from the host running the Collector. - The Prometheus Metrics plugin must be installed - Jenkins exposes no metrics without it. The plugin uses Jenkins date-based versioning (for example `852.v…`) rather than semantic versions; a current release requires Jenkins 2.479.3 or later. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Every row traces to a metric Jenkins actually emits on this endpoint. A few things about this surface shape what you see: - **Two liveness signals.** `up` is the prometheus receiver's scrape liveness - it reads `1` when `/prometheus/` responds. `default_jenkins_up` is the plugin's own gauge - `1` means the Jenkins controller is up. `default_jenkins_uptime` is controller uptime in milliseconds; a reset flags a restart. - **Collection-period gotcha.** The Prometheus plugin collects metrics on a timer (`COLLECTING_METRICS_PERIOD_IN_SECONDS`, default `120s`) and serves the last cached snapshot. Immediately after start, `/prometheus/` returns `200` with an empty body until the first collection completes, so early scrapes carry only `up` and the `scrape_*` meta. This is expected, not a failure. - **Two Jenkins namespaces share the endpoint.** `default_jenkins_*` is the Prometheus plugin's curated export - per-job build results (`default_jenkins_builds_*`, labeled by `jenkins_job`) plus controller-wide executors, up, uptime, and version. `jenkins_*` is the underlying `metrics` (Dropwizard) plugin re-exposed - executor, queue, node, project, job, task, health-check, plugins, and run-result families, most as a `_value` (current) and a `_history` (server-windowed) pair. - **`_history` series are pre-windowed.** The plugin computes rolling windows server-side, so `system_cpu_load_x100_window_{1m,5m,15m,1h}` and the `*_history` variants carry aggregates the receiver did not compute; the `_value` series is the instantaneous read. - **Run-result counters are the CI-health signal.** `jenkins_runs_success_total`, `jenkins_runs_failure_total`, `jenkins_runs_unstable_total`, `jenkins_runs_aborted_total`, and `jenkins_runs_not_built_total` are the controller-wide build outcomes; `default_jenkins_builds_last_build_result_ordinal` is the per-job last result (`0` = success ... `4` = not built). - **Two parallel JVM exports.** `vm_*` is the Dropwizard JVM instrumentation (`vm_memory_*` is the largest family on this endpoint - per-pool used / committed / max / init). `jvm_*` is the Prometheus client's own JVM export. They overlap; keep one in production. #### Core - is it up and are builds passing | Metric | What it tells you | |---|---| | `up` | Prometheus scrape liveness - `1` = the `/prometheus/` endpoint responded. The monitoring liveness signal. | | `default_jenkins_up` | The Jenkins controller is up (the plugin's own check). | | `jenkins_runs_failure_total` | Builds that finished as failure - the headline CI-health signal. | | `jenkins_runs_success_total` | Builds that finished successfully - build throughput. | | `jenkins_queue_size_value` | Current build-queue depth - the backlog of builds waiting for an executor. | | `default_jenkins_executors_busy` | Executors currently running builds - utilization against capacity. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `default_jenkins_uptime` | Controller uptime in milliseconds - a reset indicates a restart. | | `default_jenkins_quietdown` | `1` = the controller is in quiet-down, refusing new builds. | | `default_jenkins_executors_available`, `_idle`, `_online`, `_defined`, `_connecting` | Executor pool: available, idle, online, defined, and connecting counts - capacity headroom. | | `default_jenkins_executors_queue_length` | Items queued waiting for an executor. | | `jenkins_runs_unstable_total`, `jenkins_runs_aborted_total`, `jenkins_runs_not_built_total` | Builds that finished unstable / aborted / not-built. | | `default_jenkins_builds_last_build_result_ordinal` | Per-job last build result (`0` = success ... `4` = not built) - which job last broke. | | `default_jenkins_builds_health_score` | Per-job health score (0-100, the weather icon). | | `default_jenkins_builds_last_build_duration_milliseconds` | Per-job last build duration - regressions in build time. | | `default_jenkins_builds_duration_milliseconds_summary` | Per-job build-duration distribution. | | `jenkins_queue_blocked_value`, `jenkins_queue_buildable_value`, `jenkins_queue_stuck_value` | Queue breakdown - blocked, buildable, and stuck items (stuck = cannot proceed). | | `jenkins_executor_count_value`, `jenkins_executor_free_value` | Total and free executors. | | `jenkins_node_online_value`, `jenkins_node_offline_value` | Build-node online and offline counts - agent availability. | | `jenkins_job_building_duration`, `jenkins_job_queuing_duration` | Time jobs spend building and queuing (summaries). | | `jenkins_health_check_score` | The controller's aggregate health-check self-assessment. | | `jenkins_plugins_failed`, `jenkins_plugins_active` | Plugins that failed to load (non-zero breaks functionality) and active plugin count. | | `http_requests` | HTTP request rate / latency to the controller (summary). | | `http_responseCodes_serverError_total` | Controller 5xx responses. | | `system_cpu_load` | System CPU load on the controller host. | | `jvm_memory_bytes_used` | JVM heap + non-heap bytes used - controller memory pressure. | | `vm_memory_heap_usage` | JVM heap usage ratio (Dropwizard). | | `jvm_threads_current` | Live JVM threads. | #### Diagnostic - for investigation and tuning Higher cardinality and drill-down detail; reach for these during an incident or a capacity review. They are grouped here rather than enumerated - run a `curl` against `/prometheus/` for the exhaustive list. | Group | Representative members | When you reach for it | |---|---|---| | Version info | `default_jenkins_version_info` | Confirm the controller version on the wire. | | Per-job bookkeeping | `default_jenkins_builds_last_build_logfile_size_bytes`, `default_jenkins_builds_discard_active`, the `_created` timestamp series | Log-size growth, discard policy, and Prometheus client `_created` bookkeeping. | | Pre-windowed history | `jenkins_queue_size_history`, `jenkins_executor_count_history` and the other `_history` gauges | Server-computed rolling windows of the `_value` gauges. | | CPU-load windows | `system_cpu_load_x100_window_1m` / `_5m` / `_15m` / `_1h` | Rolling CPU-load windows (value x100), computed server-side. | | Non-error HTTP codes | `http_responseCodes_ok_total` and the other non-error response counters | Traffic mix on the controller's web layer. | | Dropwizard JVM memory | `vm_memory_*` (per-pool used / committed / max / init - the largest family on this endpoint) | Heap and per-pool memory drill-down. | | JVM detail | `vm_gc_*`, `vm_file_descriptor_*`, the `jvm_memory_pool_*` and `jvm_threads_*` series | GC, file-descriptor, and thread-state investigation across both JVM exports. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped` | Receiver-side scrape health, not from Jenkins. | ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. State alerts read a value Jenkins reports directly; the rest are relative to your own baseline. These are starting points - tune them to your workload. | Alert | Condition | Why it matters | |---|---|---| | Jenkins unreachable | `up == 0` for > 1m, or `default_jenkins_up == 0` | The endpoint or the controller is down - check the Jenkins process and port `8080`. | | Build failures rising | `rate(jenkins_runs_failure_total)` rising vs baseline | Builds are breaking - identify the job via `default_jenkins_builds_last_build_result_ordinal`. | | Queue backing up | `jenkins_queue_size_value` rising vs baseline, or `jenkins_queue_stuck_value > 0` | Builds are waiting for executors (or are stuck) - add executors / agents or clear the blocker. | | Executors saturated | `default_jenkins_executors_busy == default_jenkins_executors_available` sustained | No free executors - throughput is capped; scale agents. | | Agents offline | `jenkins_node_offline_value > 0` | Build agents are offline - capacity is reduced; check agent connectivity. | | Plugin load failures | `jenkins_plugins_failed > 0` | One or more plugins failed to load - functionality is broken; check the plugin and Jenkins logs. | | Build duration regression | `default_jenkins_builds_last_build_duration_milliseconds` rising vs baseline for a job | A job got slower - inspect recent changes and agent load. | | HTTP server errors | `rate(http_responseCodes_serverError_total) > 0` | The controller is returning 5xx - check the Jenkins log and load. | | Controller memory pressure | `jvm_memory_bytes_used` rising toward max, or `vm_memory_heap_usage` near `1` | The JVM is running out of heap - raise `-Xmx` or reduce load; GC thrash slows everything. | | Quiet-down stuck on | `default_jenkins_quietdown == 1` unexpectedly | The controller is refusing new builds - cancel quiet-down if it was not intended. | ### Access Setup Install the Prometheus Metrics plugin, then point the receiver at `/prometheus/`. Install via the Jenkins UI under **Manage Jenkins** → **Plugins** → **Available plugins** (search for "Prometheus Metrics"), or bake it into the controller image with the CLI: ```dockerfile showLineNumbers title="jenkins/Dockerfile" FROM jenkins/jenkins:lts-jdk17 RUN jenkins-plugin-cli --plugins prometheus ``` The `/prometheus/` endpoint is unauthenticated by default. The exposure path, collection period, and access settings are configurable under **Manage Jenkins** → the Prometheus plugin settings. Verify the endpoint is serving (the trailing slash is required): ```bash showLineNumbers title="Verify access" # Check Jenkins is up curl -so /dev/null -w "%{http_code}" http://localhost:8080/login # Verify the Prometheus metrics endpoint (trailing slash required) curl -s http://localhost:8080/prometheus/ | head -20 ``` Right after start the body may be empty until the first collection cycle completes (see the collection-period note above) - re-run after the cycle. ### Configuration The `prometheus` receiver scrapes `/prometheus/` on `:8080`. The `metric_relabel_configs` keep filter scopes collection to the Jenkins families and drops the JVM `vm_*` / `jvm_*` noise; remove it to keep the full JVM detail. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: jenkins scrape_interval: 10s metrics_path: /prometheus/ # Trailing slash required static_configs: - targets: - ${env:JENKINS_HOST}:8080 metric_relabel_configs: - source_labels: [__name__] regex: 'jenkins_.*|default_jenkins_.*|up' action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" JENKINS_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Authentication If you secure `/prometheus/`, add basic auth to the scrape config and use a Jenkins API token rather than a password: ```yaml showLineNumbers title="config/otel-collector.yaml (auth)" receivers: prometheus: config: scrape_configs: - job_name: jenkins metrics_path: /prometheus/ basic_auth: username: ${env:JENKINS_USER} password: ${env:JENKINS_TOKEN} static_configs: - targets: - ${env:JENKINS_HOST}:8080 ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped Jenkins metrics docker logs otel-collector 2>&1 | grep -i "jenkins" # Check the metrics endpoint directly (trailing slash required) curl -s http://localhost:8080/prometheus/ | grep jenkins_ # Run a build so the build-result families advance # (or wait for a scheduled job to fire) ``` ### Troubleshooting #### No Jenkins metrics on `/prometheus/` **Cause**: The Prometheus Metrics plugin is not installed - Jenkins exposes no metrics without it. **Fix**: 1. Confirm the plugin under **Manage Jenkins** → **Plugins** → **Installed plugins**. 2. If it is missing, install it (UI or `jenkins-plugin-cli --plugins prometheus`) and restart Jenkins. 3. Confirm the URL includes the trailing slash: `/prometheus/`, not `/prometheus`. #### Endpoint returns an empty body right after start **Cause**: The Prometheus plugin collects metrics on a timer (default `120s`) and serves the last cached snapshot, so the first cycle has not completed yet. **Look at**: `up` and the `scrape_*` series - early scrapes carry only these until the first collection populates the Jenkins families. **Fix**: 1. Wait for the first collection cycle (up to `COLLECTING_METRICS_PERIOD_IN_SECONDS`, default `120s`). 2. Re-run `curl http://localhost:8080/prometheus/` - the body fills once the cycle completes. #### Build metrics are missing **Cause**: The build families need at least one job that has run. **Look at**: `jenkins_runs_*` and `default_jenkins_builds_*` - these stay absent on a controller with no executed builds, while the executor, queue, and node families appear immediately. **Fix**: 1. Run a job (or wait for a scheduled trigger to fire). 2. Build-result and per-job metrics populate after the first execution. #### Connection refused on port 8080 **Cause**: The Collector cannot reach Jenkins at the configured address. **Fix**: 1. Verify Jenkins is running: `docker ps | grep jenkins`. 2. Jenkins takes 30-60 seconds to start - check `docker logs jenkins` for startup progress. 3. Check firewall rules if the Collector runs on a separate host. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Jenkins running in Kubernetes? Yes. Set the scrape target to the Jenkins service DNS endpoint on port `8080` (e.g., `jenkins.default.svc.cluster.local:8080`) and bake the Prometheus Metrics plugin into the controller image. The Collector can run as a sidecar or DaemonSet. #### What is the difference between `up` and `default_jenkins_up`? `up` is the prometheus receiver's scrape liveness - `1` means the `/prometheus/` endpoint responded. `default_jenkins_up` is the plugin's own gauge - `1` means the Jenkins controller itself reports healthy. Alert on both: a down endpoint and a down controller are different failures. #### Why is `/prometheus/` empty right after startup? The Prometheus plugin collects metrics on a timer (`COLLECTING_METRICS_PERIOD_IN_SECONDS`, default `120s`) and serves the last cached snapshot. Until the first cycle completes, the endpoint returns `200` with an empty body and scrapes carry only `up` and `scrape_*`. Wait one collection period. #### Why are there no build metrics? The build families (`jenkins_runs_*`, `default_jenkins_builds_*`) need at least one job that has run. A controller with no executed builds shows the executor, queue, and node families but no build results. Run a job to populate them. #### Should I keep both `vm_*` and `jvm_*`? No. `vm_*` is the Dropwizard JVM instrumentation (with the large per-pool `vm_memory_*` family) and `jvm_*` is the Prometheus client's own JVM export - two parallel exports of the same data. Keep one in production; the keep filter in the config drops both, so add back the one you want. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [ArgoCD Monitoring](../../guides/cicd-observability/argocd.md) - GitOps delivery alongside your CI controller. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Jenkins metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [ArgoCD](../../guides/cicd-observability/argocd.md) and other CI/CD components. - **Fine-tune Collection**: The `jenkins_.*|default_jenkins_.*|up` keep filter scopes collection to the Jenkins families; remove it to keep the full JVM detail (`vm_*` / `jvm_*`). --- ## Jetty OpenTelemetry Monitoring - Thread Pools, JVM Health, and Collector Setup ## Jetty The OpenTelemetry JMX Scraper collects 6 Jetty-specific metrics and 19 JVM metrics from Eclipse Jetty 9.4+ - thread-pool busy/idle/queue counts, NIO selector activity, heap and non-heap memory, CPU utilization, class loading, and buffer pools. Jetty keeps these in JMX MBeans with no native metrics endpoint, and unlike Tomcat it does not register them by default, so the `jmx` module must be enabled. The scraper connects over JMX/RMI, converts the MBeans into OpenTelemetry metrics, and pushes them over OTLP to the Collector. This guide enables JMX on Jetty, configures the scraper, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | -------------- | ----------- | ----------- | | Eclipse Jetty | 9.4 | 12.0 | | JMX Scraper | 1.48.0-alpha | 1.57.0-alpha | | Java (scraper) | 11 | 17 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Jetty must be reachable from the host running the JMX Scraper (JMX port, default 1099). - Jetty's `jmx` module must be enabled so the server registers its MBeans; without it you get only JVM metrics. - The JMX Scraper runs as a standalone Java process and needs its own JRE. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). The `jetty` rules are bundled in JMX Scraper `1.48.0-alpha` and later; on earlier builds only the JVM metrics surface. The metric names come from the scraper's `jetty` rules, not from Jetty itself, so a Jetty version change cannot rename or drop them - it can only leave a source MBean absent. ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `jetty` target exposes no request counter, so there is no built-in throughput or per-request latency metric. Use `jetty.thread.busy.count` as the work proxy; per-request timing lives in your access logs or trace path, not in these metrics. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `jetty.thread.busy.count` | Threads actively handling requests - the closest proxy for whether Jetty is doing work. | | `jvm.memory.used` | JVM memory in use. JMX exposes no `up` metric, so heap-in-use doubles as the process-alive and heap-health anchor. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `jetty.thread.queue.size` | Jobs queued waiting for a free thread - backpressure / saturation. | | `jetty.thread.limit` | Max threads in the pool; the saturation denominator for `busy.count`. | | `jvm.memory.limit` | JVM memory ceiling; the saturation denominator for `jvm.memory.used`. | | `jvm.cpu.recent_utilization` | Recent process CPU utilization. | | `jvm.thread.count` | Total live JVM threads - a leak signal when it climbs. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | Thread-pool detail | `jetty.thread.count`, `jetty.thread.idle.count` | Pool composition - how the busy/idle split moves under load. | | Connector I/O | `jetty.select.count` | NIO selector select calls; connector-level I/O pressure. | | JVM memory detail | `jvm.memory.committed`, `jvm.memory.init`, `jvm.memory.used_after_last_gc` | Heap sizing and post-GC live-set growth. | | JVM class loading | `jvm.class.count`, `jvm.class.loaded`, `jvm.class.unloaded` | Class-loader churn / leaks during redeploys. | | JVM CPU / system | `jvm.cpu.count`, `jvm.cpu.time`, `jvm.system.cpu.load_1m`, `jvm.system.cpu.utilization` | Host-level CPU context behind `recent_utilization`. | | JVM buffers / descriptors | `jvm.buffer.count`, `jvm.buffer.memory.limit`, `jvm.buffer.memory.used`, `jvm.file_descriptor.count`, `jvm.file_descriptor.limit` | Direct-buffer and file-descriptor exhaustion. | Session metrics (`jetty.session.count`, `jetty.session.created.count`, `jetty.session.duration.sum`) are defined by the scraper's `jetty` target but stay silent on a bare server - their MBeans only register once a web application with an active session cache is deployed. They surface automatically as soon as a session-bearing context runs; nothing in the config withholds them. Full metric reference: [OTel JMX Scraper Jetty rules](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/instrumentation/jmx-metrics/library/jetty.md). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `jetty.thread.busy.count` / `jetty.thread.limit` | Approaching the limit | Approaching 1.0 | All worker threads in use; new requests queue. Raise `maxThreads` or scale out. | | `jetty.thread.queue.size` | > 0 sustained | Growing | Requests waiting for a free thread - the pool is saturated. Investigate slow handlers or scale. | | `jvm.memory.used` / `jvm.memory.limit` | Approaching the limit | Approaching 1.0 | GC churn / OOM risk. Raise heap or reduce allocation. | | `jvm.cpu.recent_utilization` | Sustained high | Pinned | Process is CPU-bound. Scale out or profile hot paths. | | `jvm.thread.count` | Climbing vs baseline | Unbounded growth | Threads not being released; inspect thread dumps. | ### Access Setup Jetty JMX is disabled by default. Two steps are required: enable the `jmx` module (registers Jetty MBeans) and configure remote JMX access (opens a port for the scraper). #### Enable JMX on Jetty For standalone Jetty, enable the JMX module and add remote-access flags: ```bash showLineNumbers title="Enable Jetty JMX module and remote access" # Enable Jetty JMX MBean registration java -jar $JETTY_HOME/start.jar --add-module=jmx # Add remote JMX access flags to start.d cat >> $JETTY_BASE/start.d/jmx-remote.ini << 'EOF' --exec -Dcom.sun.management.jmxremote.port=1099 -Dcom.sun.management.jmxremote.rmi.port=1099 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname= EOF ``` Setting `rmi.port` to the same value as `port` keeps RMI from picking a random second port, which simplifies firewall and Docker networking. For Docker, the Jetty image needs a custom Dockerfile to enable the `jmx` module at build time; the remote-access flags are passed via `JAVA_OPTIONS`: ```dockerfile showLineNumbers title="jetty/Dockerfile" FROM jetty:12.0-jdk17 USER root RUN java -jar "$JETTY_HOME/start.jar" --add-module=jmx USER jetty ``` ```yaml showLineNumbers title="docker-compose.yaml (Jetty service)" jetty: build: ./jetty hostname: jetty environment: JAVA_OPTIONS: >- -Dcom.sun.management.jmxremote.port=1099 -Dcom.sun.management.jmxremote.rmi.port=1099 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname=jetty ``` #### With authentication (production) Unauthenticated JMX is fine on a trusted private network or inside a pod; expose it across hosts only with SSL and authentication enabled: ```bash showLineNumbers title="start.d/jmx-remote.ini (authenticated)" --exec -Dcom.sun.management.jmxremote.port=1099 -Dcom.sun.management.jmxremote.rmi.port=1099 -Dcom.sun.management.jmxremote.ssl=true -Dcom.sun.management.jmxremote.authenticate=true -Dcom.sun.management.jmxremote.password.file=/path/to/jmxremote.password -Dcom.sun.management.jmxremote.access.file=/path/to/jmxremote.access -Djava.rmi.server.hostname= ``` The JMX Scraper connects to an authenticated server via the `OTEL_JMX_USERNAME` and `OTEL_JMX_PASSWORD` environment variables. The account needs read-only MBean access; no write operations are used. ### Configuration Jetty monitoring uses two components: the JMX Scraper (connects to Jetty, exports OTLP) and the OTel Collector (receives OTLP, ships to Scout). ```text Jetty (JMX:1099) ← JMX/RMI → JMX Scraper → OTLP → OTel Collector → Scout ``` #### JMX Scraper Download the scraper JAR from [Maven Central](https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/) and run it against the `jvm,jetty` target systems: ```bash showLineNumbers title="Run the JMX Scraper" OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://localhost:1099/jmxrmi \ OTEL_JMX_TARGET_SYSTEM=jvm,jetty \ OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 \ OTEL_METRIC_EXPORT_INTERVAL=10000 \ java -jar opentelemetry-jmx-scraper-1.57.0-alpha.jar ``` For a managed install, move the JAR to a permanent location and run it under systemd: ```bash showLineNumbers title="/etc/systemd/system/otel-jmx-scraper.service" sudo tee /etc/systemd/system/otel-jmx-scraper.service > /dev/null <<'EOF' [Unit] Description=OpenTelemetry JMX Scraper for Jetty After=network.target jetty.service [Service] Type=simple Environment=OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://localhost:1099/jmxrmi Environment=OTEL_JMX_TARGET_SYSTEM=jvm,jetty Environment=OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 Environment=OTEL_METRIC_EXPORT_INTERVAL=10000 ExecStart=/usr/bin/java -jar /opt/otel/opentelemetry-jmx-scraper-1.57.0-alpha.jar Restart=always RestartSec=5 [Install] WantedBy=multi-user.target EOF sudo systemctl daemon-reload sudo systemctl enable --now otel-jmx-scraper ``` For Docker, build a small image with the scraper JAR: ```dockerfile showLineNumbers title="jmx-scraper/Dockerfile" FROM eclipse-temurin:17-jre ARG SCRAPER_VERSION=1.57.0-alpha # Update to match your target version ADD https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/${SCRAPER_VERSION}/opentelemetry-jmx-scraper-${SCRAPER_VERSION}.jar /opt/scraper.jar ENTRYPOINT ["java", "-jar", "/opt/scraper.jar"] ``` #### OTel Collector The Collector receives metrics from the JMX Scraper over OTLP/gRPC: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic tier with a `filter` processor on the metrics pipeline while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" # JMX Scraper OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://jetty:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM=jvm,jetty OTEL_METRIC_EXPORT_INTERVAL=10000 # OTEL_JMX_USERNAME=monitor # Uncomment for authenticated JMX # OTEL_JMX_PASSWORD=your_password # Uncomment for authenticated JMX # OTel Collector ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Docker Compose Full working example with all three components: ```yaml showLineNumbers title="docker-compose.yaml" services: jetty: build: ./jetty hostname: jetty ports: - "8080:8080" - "1099:1099" environment: JAVA_OPTIONS: >- -Dcom.sun.management.jmxremote.port=1099 -Dcom.sun.management.jmxremote.rmi.port=1099 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname=jetty healthcheck: test: ["CMD-SHELL", "curl -so /dev/null http://localhost:8080/ || exit 1"] interval: 10s timeout: 5s retries: 10 start_period: 30s jmx-scraper: build: ./jmx-scraper environment: OTEL_JMX_SERVICE_URL: ${OTEL_JMX_SERVICE_URL} OTEL_JMX_TARGET_SYSTEM: ${OTEL_JMX_TARGET_SYSTEM} OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: ${OTEL_METRIC_EXPORT_INTERVAL} depends_on: jetty: condition: service_healthy otel-collector: image: otel/opentelemetry-collector-contrib:latest container_name: otel-collector volumes: - ./config/otel-collector.yaml:/etc/otelcol-contrib/config.yaml:ro depends_on: - jetty ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check JMX Scraper logs for a successful connection docker logs jetty-telemetry-jmx-scraper-1 2>&1 | head -10 # Confirm Jetty started with the jmx module enabled docker logs jetty 2>&1 | grep "jmx" # Check Collector logs for Jetty metrics docker logs otel-collector 2>&1 | grep "jetty" # Generate traffic so the thread-pool counters move curl -s http://localhost:8080/ > /dev/null ``` You should see the `jvm.*` and `jetty.*` metrics in the Collector debug output and, shortly after, in Scout. ### Troubleshooting #### JMX connection refused **Cause**: The JMX Scraper cannot reach Jetty's JMX port. **Fix**: 1. Verify Jetty is running: `docker ps | grep jetty`. 2. Confirm remote JMX is enabled - check that `-Dcom.sun.management.jmxremote.port=1099` is in `JAVA_OPTIONS` or `start.d/jmx-remote.ini`. 3. Verify the port matches between Jetty and the scraper's `OTEL_JMX_SERVICE_URL`. 4. In Docker, ensure `hostname` is set on the Jetty container and matches `-Djava.rmi.server.hostname`. #### Only JVM metrics, no Jetty metrics **Cause**: Jetty's `jmx` module is not enabled, so its components are not registered as MBeans. **Fix**: 1. Enable the JMX module: `java -jar start.jar --add-module=jmx`. 2. In Docker, use the custom Dockerfile that runs `--add-module=jmx` at build time. 3. Verify `OTEL_JMX_TARGET_SYSTEM` includes `jetty`. #### Requests are slow or piling up **Cause**: The thread pool is saturated, or handlers are slow. **Look at**: `jetty.thread.queue.size` (requests waiting for a thread) against `jetty.thread.busy.count` / `jetty.thread.limit`. A queue above zero with busy near the limit means the pool is full. The Diagnostic `jetty.thread.idle.count` confirms there are no spare threads, and `jetty.select.count` surfaces connector-level I/O pressure. **Fix**: 1. Raise `maxThreads` or add Jetty capacity if the queue is sustained. 2. Profile slow handlers if busy threads stay high without queue relief. #### Heap pressure or rising CPU **Cause**: Allocation churn, a memory leak, or CPU-bound work. **Look at**: `jvm.memory.used` against `jvm.memory.limit`, plus the Diagnostic `jvm.memory.used_after_last_gc` - a climbing post-GC live set points to a leak rather than transient churn. `jvm.system.cpu.utilization` and `jvm.cpu.time` give the host-level CPU context behind `jvm.cpu.recent_utilization`. **Fix**: 1. Raise heap or reduce allocation if used approaches the limit. 2. Inspect thread dumps if `jvm.thread.count` climbs without bound. #### Session metrics missing **Cause**: `jetty.session.count`, `jetty.session.created.count`, and `jetty.session.duration.sum` come from session-cache MBeans that only register once a web application with active sessions is deployed. **Fix**: 1. Deploy a web application that uses sessions. The MBeans register per context and the metrics surface automatically. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the OTLP receiver and the exporter. ### FAQ #### Why do I need the JMX Scraper instead of a Jetty receiver? Jetty has no native metrics endpoint and the Collector has no Jetty receiver. Jetty publishes its statistics as JMX MBeans, and the OpenTelemetry JMX Scraper reads them over JMX/RMI, maps them to OTel metrics with the `jvm,jetty` target rules, and pushes OTLP to the Collector. #### Does this work with embedded Jetty (Spring Boot / Dropwizard)? Yes. Spring Boot and Dropwizard embed Jetty and register its MBeans when JMX is enabled (`spring.jmx.enabled=true` on Spring Boot). Add the same `-Dcom.sun.management.jmxremote.*` flags to the application JVM and point the scraper at it. #### Why is there no request-rate or latency metric? The scraper's `jetty` target exposes no request counter, so throughput and per-request timing are not in this metric surface. Use `jetty.thread.busy.count` as a work proxy; per-request timing lives in your access logs or trace path. #### How do I monitor multiple Jetty instances? Run one JMX Scraper per instance, each with a different `OTEL_JMX_SERVICE_URL`, all exporting to the same Collector: ```yaml showLineNumbers title="docker-compose.yaml (multiple instances)" jmx-scraper-primary: environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://jetty-1:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,jetty OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 jmx-scraper-replica: environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://jetty-2:1099/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,jetty OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 ``` #### Does this work with Jetty in Kubernetes? Yes. Run the JMX Scraper as a sidecar in the same pod and set `OTEL_JMX_SERVICE_URL` to `service:jmx:rmi:///jndi/rmi://localhost:1099/jmxrmi` - both containers share the pod network, so no firewall rules are needed for intra-pod communication. ### Related Guides - [JMX Metrics Guide](../collector-setup/jmx-metrics-collection-guide.md) - Compare the JMX Scraper and the JMX Exporter. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Tomcat Monitoring](./tomcat.md) - Another Java application server. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Jetty metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Tomcat](./tomcat.md), [Nginx](./nginx.md), and other web servers. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Kubernetes Cluster OpenTelemetry Monitoring - Deployment, Pod, and Node State Metrics ## K8s Cluster The OpenTelemetry Collector's `k8s_cluster` receiver watches the Kubernetes API server and synthesizes cluster-level metrics from object state - deployment and replicaset replica counts, pod phases, node conditions, HPA replicas, and job progress. It reports the desired and observed state the API server holds, not per-node runtime usage (that is the `kubeletstats` receiver's job). Run a single Collector for the cluster (a Deployment, not a DaemonSet): the receiver reads from the API server, so one instance sees the whole cluster. This guide configures the receiver, the ServiceAccount it needs, an optional events-to-logs stream, and ships everything to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Kubernetes | 1.27 | 1.34+ | | OTel Collector Contrib | 0.90.0 | 0.152+ | | base14 Scout | Any | - | Before starting: - A ServiceAccount the Collector runs as, with `get`/`list`/`watch` on the cluster-shape resources the receiver counts (see Access Setup below). - OTel Collector Contrib deployed as a single-replica Deployment - see [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md). - At least one Deployment in the cluster. With no workloads, the deployment, replicaset, and pod metric families stay empty - the receiver only reports objects that exist. ### What You'll Monitor - **Workloads**: deployment available/desired replicas, replicaset available/desired replicas, container readiness and restart counts. - **Pods**: pod phase (Pending, Running, Succeeded, Failed, Unknown) and the status reason when a pod is not Running. - **Nodes**: node Ready condition across the cluster. - **Namespaces**: namespace phase (Active, Terminating). - **Autoscaling** (when an HPA exists): current, desired, min, and max replicas the HPA observes. - **Jobs** (when a Job exists): active and successful pod counts. Full metric reference: [OTel k8s_cluster Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/k8sclusterreceiver) ### Access Setup The receiver authenticates to the API server with its ServiceAccount token (`auth_type: serviceAccount`). Grant that ServiceAccount `get`/`list`/`watch` on the object kinds it counts with a ClusterRole: ```yaml showLineNumbers title="k8s-cluster-rbac.yaml" apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRole metadata: name: otel-k8s-cluster rules: - apiGroups: [""] resources: - events - namespaces - namespaces/status - nodes - nodes/spec - pods - pods/status - replicationcontrollers - replicationcontrollers/status - resourcequotas - services verbs: ["get", "list", "watch"] - apiGroups: ["apps"] resources: ["daemonsets", "deployments", "replicasets", "statefulsets"] verbs: ["get", "list", "watch"] - apiGroups: ["batch"] resources: ["jobs", "cronjobs"] verbs: ["get", "list", "watch"] - apiGroups: ["autoscaling"] resources: ["horizontalpodautoscalers"] verbs: ["get", "list", "watch"] --- apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRoleBinding metadata: name: otel-k8s-cluster subjects: - kind: ServiceAccount name: otel-collector namespace: observability roleRef: kind: ClusterRole name: otel-k8s-cluster apiGroup: rbac.authorization.k8s.io ``` A missing verb shows up as an informer cache-sync timeout in the Collector logs (for example, the HPA family needs the `autoscaling` rule). Keep the rules in sync with the object kinds you expect to see. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: k8s_cluster: auth_type: serviceAccount collection_interval: 30s # Node conditions to surface as k8s.node.condition_* metrics. node_conditions_to_report: [Ready, MemoryPressure, DiskPressure] # Node allocatable capacity to surface as k8s.node.allocatable_* metrics. allocatable_types_to_report: [cpu, memory] processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [k8s_cluster] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Metrics Reference These metrics emit for any non-empty cluster. The receiver reports whatever objects the cluster has - deploy or scale workloads to see the counts move. #### Workloads | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.deployment.available` | gauge | `{pods}` | Available replicas of a Deployment. | | `k8s.deployment.desired` | gauge | `{pods}` | Desired replicas (the spec target). | | `k8s.replicaset.available` | gauge | `{pods}` | Available replicas of a ReplicaSet. | | `k8s.replicaset.desired` | gauge | `{pods}` | Desired replicas of a ReplicaSet. | | `k8s.container.ready` | gauge | `1` | 1 when the container's readiness probe passes. | | `k8s.container.restarts` | sum | `{restarts}` | Container restart count. | #### Pods and namespaces | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.pod.phase` | gauge | `1` | Phase code (1=Pending, 2=Running, 3=Succeeded, 4=Failed, 5=Unknown). | | `k8s.pod.status_reason` | gauge | `1` | Reason code when a pod is not Running. | | `k8s.namespace.phase` | gauge | `1` | Namespace phase (1=Active, 0=Terminating). | #### Nodes | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.node.condition_ready` | gauge | `1` | 1 when the node's Ready condition is true. | #### Autoscaling and jobs (conditional) The HPA and Job families emit only when those objects exist in the cluster. Ship an HPA or run a Job to see them. | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.hpa.current_replicas` | gauge | `{pods}` | Current replicas the HPA observes. | | `k8s.hpa.desired_replicas` | gauge | `{pods}` | Replicas the HPA wants. | | `k8s.hpa.min_replicas` | gauge | `{pods}` | HPA floor. | | `k8s.hpa.max_replicas` | gauge | `{pods}` | HPA ceiling. | | `k8s.job.active_pods` | gauge | `{pods}` | Active pods of a Job. | | `k8s.job.successful_pods` | gauge | `{pods}` | Pods the Job completed successfully. | ### Cluster Events as Logs To capture Kubernetes events (scheduling, scaling, image pulls, probe failures) as log records, add the `k8sobjects` receiver in `mode: watch` against the Events API. Each event becomes one log record. ```yaml showLineNumbers title="config/otel-collector.yaml (events)" receivers: k8sobjects: auth_type: serviceAccount objects: - name: events mode: watch group: events.k8s.io service: pipelines: logs: receivers: [k8sobjects] processors: [resource, batch] exporters: [otlphttp/b14] ``` The ServiceAccount needs `get`/`list`/`watch` on `events` in both the core (`""`) and `events.k8s.io` API groups - the core rule is already in the ClusterRole above; add the `events.k8s.io` group the same way. ### Verify the Setup Deploy the Collector and check that metrics flow within 60 seconds. The receiver scrapes a definition catalog before it has values, so allow one or two collection intervals before judging an empty result: ```bash showLineNumbers # Confirm the Collector pod is running (one replica for the cluster). kubectl -n observability get pods -l app=otel-collector # Check the Collector logs for k8s_cluster activity. kubectl -n observability logs deployment/otel-collector \ | grep -i k8s_cluster ``` A quick way to confirm the receiver is emitting is to add a `debug` exporter (`verbosity: detailed`) to the metrics pipeline temporarily and watch for a real metric name such as `k8s.deployment.available` in the pod logs. ### Troubleshooting #### Informer cache-sync timeout on startup **Cause**: the Collector ServiceAccount lacks `get`/`list`/`watch` on one of the object kinds the receiver counts. **Fix**: 1. Apply the ClusterRole and ClusterRoleBinding from Access Setup. 2. Confirm the Deployment's `serviceAccountName` matches the binding subject. 3. If only one family is missing (for example the HPA metrics), add the matching API group to the ClusterRole. #### Deployment and pod metrics are empty **Cause**: the cluster has no workloads, or the receiver is not reaching the API server. **Fix**: 1. Confirm workloads exist: `kubectl get deployments -A`. 2. Check the Collector logs for API connection errors. 3. Allow one or two collection intervals after startup before judging. #### HPA or Job metrics never appear **Cause**: those families only emit when an HPA or Job object exists. **Fix**: 1. Confirm the objects exist: `kubectl get hpa,jobs -A`. 2. Verify the `autoscaling` and `batch` rules are in the ClusterRole. ### FAQ #### Why one Collector for the cluster instead of one per node? The `k8s_cluster` receiver reads from the API server, which holds the state of every object in the cluster. A single Collector sees everything; running one per node would produce duplicate metrics for the same cluster-scope objects. #### What is the difference between k8s_cluster and kubeletstats receivers? The `k8s_cluster` receiver reports object state from the API server - replica counts, phases, conditions. The `kubeletstats` receiver reads each node's kubelet for actual runtime resource usage - CPU, memory, network, filesystem. They are complementary: state versus usage. #### Why is `k8s.pod.phase` a number? The receiver encodes phase as an integer (1=Pending, 2=Running, 3=Succeeded, 4=Failed, 5=Unknown) so it can be stored and queried as a gauge. Map the value back to the phase name when building dashboards. #### Do I need the Kubernetes events stream? No. Metrics work on their own. The `k8sobjects` events-to-logs stream is optional and useful when you want scheduling, scaling, and probe events alongside the state metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) - **Monitor More Components**: Pair this with the kubelet stats receiver for per-node runtime usage. - **Fine-tune Collection**: Adjust `collection_interval` based on how quickly you need to see object-state shifts. ### Related Guides - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) — Deploy the Collector in your cluster - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) — Advanced collector configuration Validated against: managed Kubernetes, OTel Collector Contrib 0.152.0. --- ## Kafka OpenTelemetry Monitoring - Consumer Lag, Partition Offsets, and Collector Setup ## Kafka The OpenTelemetry Collector's Kafka Metrics receiver collects 16 metrics from Kafka 2.x, 3.x, and 4.x, including consumer group lag, partition offsets, replica sync status, topic configuration, and broker count. The receiver speaks the Kafka client protocol directly to a broker on port 9092 - no JMX bridge or exporter sidecar - and works the same against ZooKeeper-based and KRaft clusters. This guide configures the receiver, connects it to your cluster, and ships metrics to base14 Scout. > **Note**: This guide uses the `kafkametricsreceiver`, which collects > metrics **about** Kafka. Do not confuse it with the `kafkareceiver`, > which receives telemetry data **through** Kafka as a transport. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Kafka | 2.x | 4.x | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - At least one Kafka broker must be accessible from the host running the Collector (port 9092). - No special user is required for unauthenticated clusters. For SASL or TLS clusters, see [Access Setup](#access-setup). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The consumer, topic, and partition series only emit once a topic exists and a consumer group has committed offsets - an idle cluster reports just `kafka.brokers` until traffic flows. #### Core - is it up and keeping up | Metric | What it tells you | |---|---| | `kafka.brokers` | Brokers in the cluster - reachability and node count. | | `kafka.consumer_group.lag_sum` | Total consumer-group lag, summed across partitions. The single number that says whether consumers are keeping up. Requires at least one committed consumer group to emit. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `kafka.consumer_group.lag` | Consumer-group lag per topic/partition - which partition is falling behind. | | `kafka.consumer_group.members` | Members in the consumer group; a drop or flap signals dead consumers or rebalance storms. | | `kafka.partition.current_offset` | Latest offset per partition - produce throughput. | | `kafka.partition.oldest_offset` | Earliest retained offset per partition - the retention window. | | `kafka.partition.replicas` | Assigned replicas per partition. | | `kafka.partition.replicas_in_sync` | In-sync replicas per partition - durability. A value below `replicas` means under-replicated. | | `kafka.topic.min_insync_replicas` | Configured ISR floor for the topic; `acks=all` produces fail when in-sync replicas drop below it. | #### Diagnostic - for investigation and tuning Higher cardinality; topology and committed-offset detail you reach for during an investigation, not signals you page on. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Metric | What it tells you | |---|---| | `kafka.topic.partitions` | Partition count per topic. | | `kafka.topic.replication_factor` | Replication factor per topic. | | `kafka.topic.log_retention_period` | Topic log-retention time. | | `kafka.topic.log_retention_size` | Topic log-retention size. | | `kafka.broker.log_retention_period` | Broker default log-retention time. | | `kafka.consumer_group.offset` | Committed offset per group/topic/partition. | | `kafka.consumer_group.offset_sum` | Committed offset summed across partitions. | Consumer-group metrics carry a `group` attribute (plus `topic` and `partition` on the per-partition series); partition metrics carry `topic` and `partition`; topic metrics carry `topic`. `kafka.brokers` has no attributes. Full metric reference: [OTel Kafka Metrics Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/kafkametricsreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `kafka.partition.replicas_in_sync` vs `kafka.partition.replicas` | `in_sync < replicas` | Sustained under-replication | Durability at risk; check broker health and disk. | | `kafka.partition.replicas_in_sync` vs `kafka.topic.min_insync_replicas` | Approaching the floor | `in_sync < min_insync_replicas` | `acks=all` produces will fail; restore in-sync replicas. | | `kafka.consumer_group.members` | Dropping | Flapping across scrapes | Dead consumers or rebalance storms; check consumer health. | ### Access Setup Verify your Kafka cluster is reachable from the Collector host: ```bash showLineNumbers title="Verify access" # List topics kafka-topics.sh --list --bootstrap-server localhost:9092 # Describe a topic kafka-topics.sh --describe --topic \ --bootstrap-server localhost:9092 # List consumer groups kafka-consumer-groups.sh --list --bootstrap-server localhost:9092 ``` No special permissions are required for unauthenticated clusters. The receiver reads cluster metadata, partition offsets, and committed consumer offsets over the standard client protocol - it does not connect to ZooKeeper, so KRaft and ZooKeeper clusters behave identically. For clusters fronted by SASL or TLS, add an `auth` block to the receiver: ```yaml showLineNumbers title="config/otel-collector.yaml (auth section)" receivers: kafkametrics: brokers: - ${env:KAFKA_BROKERS} protocol_version: "4.0.0" scrapers: - brokers - topics - consumers auth: sasl: mechanism: SCRAM-SHA-512 username: ${env:KAFKA_USERNAME} password: ${env:KAFKA_PASSWORD} tls: insecure_skip_verify: true ``` Supported SASL mechanisms: `PLAIN`, `SCRAM-SHA-256`, `SCRAM-SHA-512`, `AWS_MSK_IAM`. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: kafkametrics: brokers: - ${env:KAFKA_BROKERS} protocol_version: "4.0.0" # Must match your Kafka cluster version collection_interval: 30s scrapers: - brokers - topics - consumers metrics: # Broker metrics kafka.brokers: enabled: true kafka.broker.log_retention_period: enabled: true # Topic metrics kafka.topic.partitions: enabled: true kafka.topic.replication_factor: enabled: true kafka.topic.min_insync_replicas: enabled: true kafka.topic.log_retention_period: enabled: true kafka.topic.log_retention_size: enabled: true # Partition metrics kafka.partition.current_offset: enabled: true kafka.partition.oldest_offset: enabled: true kafka.partition.replicas: enabled: true kafka.partition.replicas_in_sync: enabled: true # Consumer group metrics kafka.consumer_group.lag: enabled: true kafka.consumer_group.lag_sum: enabled: true kafka.consumer_group.members: enabled: true kafka.consumer_group.offset: enabled: true kafka.consumer_group.offset_sum: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [kafkametrics] processors: [resource, batch] exporters: [otlphttp/b14] ``` Set `protocol_version` to match your cluster - `4.0.0` for Kafka 4.x, `3.6.0` for a 3.x cluster, and so on. To control metric volume in production, drop the Diagnostic-tier topic and committed-offset series with a `filter` processor while keeping Core and Operational. > **Environment keys**: Scout's UI filters on the lowercase `environment` > key, so emit it alongside the OTel-native `deployment.environment.name` > (semantic conventions v1.27+, stable in v1.40.0). The legacy > `deployment.environment` is still accepted by Scout for backward > compatibility. #### Environment Variables ```bash showLineNumbers title=".env" KAFKA_BROKERS=localhost:9092 ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for the Kafka receiver and scraped metrics docker logs otel-collector 2>&1 | grep -i "kafka" # Confirm connectivity from the same host kafka-topics.sh --list --bootstrap-server localhost:9092 # Consumer-group series only emit once a group has committed offsets kafka-consumer-groups.sh --list --bootstrap-server localhost:9092 ``` `kafka.brokers` emits as soon as the receiver connects. The topic, partition, and consumer-group series appear once a topic exists and a consumer group has committed at least one offset. ### Troubleshooting #### Connection refused on port 9092 **Cause**: The Collector cannot reach the Kafka broker at the configured address. **Fix**: 1. Verify Kafka is running: `docker ps | grep kafka` or `systemctl status kafka`. 2. Confirm `advertised.listeners` in the broker config resolves correctly from the Collector host. 3. Check firewall rules between the Collector and broker. #### Consumer group metrics missing **Cause**: The `consumers` scraper is not enabled, or no consumer group has committed offsets yet. **Look at**: `kafka.consumer_group.offset` and `kafka.consumer_group.offset_sum` - if these are absent, no group has committed, so `lag_sum` and `lag` cannot be computed either. **Fix**: 1. Ensure `consumers` is listed under `scrapers`. 2. Verify consumer groups exist: `kafka-consumer-groups.sh --list --bootstrap-server localhost:9092`. 3. Consumer-group metrics only appear after at least one group commits an offset. #### Partitions look under-replicated **Cause**: One or more brokers are unhealthy or out of disk, so replicas have fallen out of the in-sync set. **Look at**: `kafka.partition.replicas_in_sync` against `kafka.partition.replicas` (the under-replication gap) and `kafka.topic.min_insync_replicas` (the floor below which `acks=all` produces fail). `kafka.broker.log_retention_period` and the topic retention series help confirm whether retention config, not broker health, is shrinking the available offset window. **Fix**: 1. Check broker health and disk on the node hosting the lagging replicas. 2. Restore in-sync replicas before producers hit the `min_insync_replicas` floor. #### Protocol version mismatch errors **Cause**: The `protocol_version` in the receiver config does not match the Kafka cluster version. **Fix**: 1. Check your Kafka version: `kafka-broker-api-versions.sh --bootstrap-server localhost:9092`. 2. Set `protocol_version` to match - `4.0.0` for Kafka 4.x, `3.6.0` for 3.x. 3. The receiver defaults to an older protocol; set this explicitly for modern clusters. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and exporter. ### FAQ #### Does this work with Kafka running in Kubernetes? Yes. Set `brokers` to the Kafka service DNS (e.g., `kafka-0.kafka.default.svc.cluster.local:9092`). The Collector can run as a sidecar or DaemonSet. Inject SASL credentials via a Kubernetes secret if authentication is enabled. #### Does this work with KRaft mode (no ZooKeeper)? Yes. The receiver connects directly to Kafka brokers over the client protocol and never talks to ZooKeeper. KRaft and ZooKeeper-based clusters produce identical metrics. #### How do I filter which topics are monitored? Use the `topic_match` regex in the receiver config. The default `^[^_].*$` excludes internal topics (those starting with `_`). To monitor specific topics: ```yaml receivers: kafkametrics: topic_match: "^(orders|payments|events)$" ``` #### Why is consumer lag not showing up? `kafka.consumer_group.lag_sum` and `kafka.consumer_group.lag` are computed from committed offsets, so they only emit once a consumer group has committed at least one offset. An idle cluster, or one with producers but no committing consumers, reports `kafka.brokers` and partition offsets but no lag. #### What is the difference between `kafkametricsreceiver` and `kafkareceiver`? The `kafkametricsreceiver` collects metrics **about** the Kafka cluster (broker count, consumer lag, partition offsets). The `kafkareceiver` consumes telemetry data (traces, metrics, logs) **from** Kafka topics - it is a transport mechanism, not a monitoring tool. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Kafka metrics. - [RabbitMQ Monitoring](./rabbitmq.md) - A common companion message broker. - [ZooKeeper Monitoring](./zookeeper.md) - Coordination service for ZooKeeper-based Kafka clusters. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [RabbitMQ](./rabbitmq.md), [ZooKeeper](./zookeeper.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Monitor kube-state-metrics with OpenTelemetry - Kubernetes State Metrics ## kube-state-metrics kube-state-metrics (KSM) listens on port 8080 and serves Prometheus-format metrics that reflect the live state of Kubernetes objects - pods, deployments, nodes, jobs, HPAs, and namespaces. The OpenTelemetry Collector scrapes this endpoint with the Prometheus receiver, then exports the `kube_*` series to base14 Scout. This guide configures the receiver and ships the metrics. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Kubernetes | 1.27 | 1.34+ | | kube-state-metrics | 2.10 | 2.19 | | OTel Collector Contrib | 0.90.0 | 0.152+ | | base14 Scout | Any | - | Before starting: - A running Kubernetes cluster. - kube-state-metrics deployed in the cluster - see the [upstream KSM project](https://github.com/kubernetes/kube-state-metrics). - An OTel Collector with the Prometheus receiver, reachable from the cluster - see [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md). - base14 Scout credentials. ### What You'll Monitor - **Pod health**: phase (Pending/Running/Succeeded/Failed), readiness, and container restart counts. - **Deployment health**: desired, spec, and available replica counts. - **Node conditions**: Ready, MemoryPressure, DiskPressure, PIDPressure, and allocatable cpu/memory per node. - **Job success**: succeeded and failed pod counts per Job. - **Namespace lifecycle**: Active and Terminating phases. ### Configuration KSM serves its metrics on port 8080 at the default `/metrics` path. Point a Prometheus scrape job at the KSM Service: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: kube-state-metrics scrape_interval: 30s metrics_path: /metrics static_configs: - targets: - kube-state-metrics.kube-state-metrics.svc:8080 processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Metrics Reference | Metric | Type | Unit | Dimensions | Notes | | --- | --- | --- | --- | --- | | `kube_pod_status_phase` | gauge | `1` | `namespace`, `pod`, `phase` | One series per pod per phase; the active phase reads 1, the rest 0. | | `kube_pod_container_status_restarts_total` | sum | `1` | `namespace`, `pod`, `container` | Monotonic restart counter per container. | | `kube_pod_status_ready` | gauge | `1` | `namespace`, `pod`, `condition` | Pod Ready condition (1/0). | | `kube_deployment_status_replicas` | gauge | `1` | `namespace`, `deployment` | Desired replica count reflected by the Deployment status. | | `kube_deployment_status_replicas_available` | gauge | `1` | `namespace`, `deployment` | Available (ready) replicas. | | `kube_deployment_spec_replicas` | gauge | `1` | `namespace`, `deployment` | Spec-requested replicas. | | `kube_node_status_condition` | gauge | `1` | `node`, `condition`, `status` | One series per node per condition per status. | | `kube_node_status_allocatable` | gauge | mixed | `node`, `resource`, `unit` | Allocatable cpu/memory/ephemeral-storage per node. | | `kube_namespace_status_phase` | gauge | `1` | `namespace`, `phase` | Namespace lifecycle phase (Active/Terminating). | | `kube_job_status_succeeded` | gauge | `1` | `namespace`, `job_name` | Succeeded pods for a Job. | | `kube_job_status_failed` | gauge | `1` | `namespace`, `job_name` | Failed pods for a Job. | | `kube_hpa_status_current_replicas` | gauge | `1` | `namespace`, `hpa` | Current replicas an HPA reports. | ### Verify the Setup Start the Collector and confirm a KSM metric arrives within ~60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm KSM is serving metrics in-cluster kubectl -n kube-state-metrics port-forward svc/kube-state-metrics 8080:8080 & curl -s http://localhost:8080/metrics | grep kube_pod_status_phase # Check the Collector logs for a successful scrape kubectl logs deployment/otel-collector | grep -i kube_pod_status_phase ``` ### Troubleshooting #### No KSM metrics in the Collector **Cause**: The Collector cannot reach the KSM Service. **Fix**: 1. Confirm KSM is Running: `kubectl -n kube-state-metrics get pods`. 2. Verify the Service DNS and port match the scrape target: `kubectl -n kube-state-metrics get svc kube-state-metrics`. 3. Port-forward and curl `/metrics` to confirm the endpoint serves data. #### Metric name present but no datapoints **Cause**: KSM lacks RBAC to list/watch the object kind, so the series is empty. **Fix**: 1. Confirm the KSM ServiceAccount is bound to a ClusterRole granting `list`/`watch` on the object kinds you expect. 2. Check the KSM logs for `forbidden` errors: `kubectl -n kube-state-metrics logs deployment/kube-state-metrics`. #### No metrics appearing in Scout **Cause**: Metrics are scraped but not exported. **Fix**: 1. Check the Collector logs for export errors. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the Prometheus receiver and the `otlphttp/b14` exporter. ### FAQ #### Which port does kube-state-metrics use for metrics? KSM serves Prometheus metrics and `/livez` on the main port 8080, and its own self-telemetry plus `/readyz` on port 8081. Scrape port 8080 for the `kube_*` object-state series. #### What does `kube_pod_status_phase` report? One time series per pod per phase. The pod's current phase reads 1 and the other phases read 0, so summing across `phase="Running"` gives the count of running pods in a namespace. #### How do I monitor a Job's success with kube-state-metrics? `kube_job_status_succeeded` reaches 1 when a Job's pod completes successfully. Pair it with `kube_job_status_failed` to alert on Jobs that exhaust their backoff limit. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [Redis](./redis.md), and other components - **Set Up Alerts**: Alert on pod restarts and Job failures. See [Creating Alerts](../../guides/creating-alerts-with-logx.md) ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on KSM metrics Validated against: kube-state-metrics v2.13 on a 3-node managed Kubernetes cluster. --- ## Kubelet Stats OpenTelemetry Monitoring - Node, Pod, and Container Metrics ## Kubelet Stats The OpenTelemetry Collector's `kubeletstats` receiver scrapes the kubelet Summary API on each node for node, pod, container, and volume metrics - CPU and memory usage, network I/O, filesystem usage, and limit/request utilization. It reads directly from the node's own kubelet, so it reports actual runtime resource usage rather than the desired state held in the API server. Run one receiver per node (a DaemonSet) so each Collector instance scrapes only its local kubelet. This guide configures the receiver, the ServiceAccount it needs, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Kubernetes | 1.27 | 1.34+ | | OTel Collector Contrib | 0.90.0 | 0.152+ | | base14 Scout | Any | - | Before starting: - A ServiceAccount the Collector runs as, with read access to `nodes/stats` and `nodes/proxy` (see Access Setup below). - OTel Collector Contrib deployed as a DaemonSet - see [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md). - At least one workload scheduled on the node. With no pods running, the pod and container metric groups stay empty - the kubelet only reports containers that exist on the node. ### What You'll Monitor - **Node**: CPU usage and time, memory usage and working set, network I/O, filesystem usage, node uptime. - **Pod**: CPU usage and time, CPU limit/request utilization, memory usage and working set, network I/O and errors, filesystem usage, pod uptime. - **Container**: CPU usage and time, CPU and memory limit/request utilization, memory usage, working set and RSS, filesystem usage, container uptime. - **Volume**: available and capacity bytes, reported only for PVC-backed volumes mounted by a pod. Full metric reference: [OTel Kubeletstats Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/kubeletstatsreceiver) ### Access Setup The receiver authenticates to the kubelet with its ServiceAccount token (`auth_type: serviceAccount`). Grant that ServiceAccount read access to the kubelet stats endpoints with a ClusterRole: ```yaml showLineNumbers title="kubeletstats-rbac.yaml" apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRole metadata: name: otel-kubeletstats rules: - apiGroups: [""] resources: ["nodes/stats", "nodes/proxy"] verbs: ["get", "list"] --- apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRoleBinding metadata: name: otel-kubeletstats subjects: - kind: ServiceAccount name: otel-collector namespace: observability roleRef: kind: ClusterRole name: otel-kubeletstats apiGroup: rbac.authorization.k8s.io ``` The receiver discovers the local kubelet from the node name, which the DaemonSet injects as an environment variable from the pod's `spec.nodeName`: ```yaml showLineNumbers env: - name: K8S_NODE_NAME valueFrom: fieldRef: fieldPath: spec.nodeName ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: kubeletstats: # Each DaemonSet pod scrapes its own node's kubelet. endpoint: ${env:K8S_NODE_NAME}:10250 auth_type: serviceAccount collection_interval: 30s # Most managed kubelets serve the Summary API over a # self-signed cert; skip verification for the in-cluster scrape. insecure_skip_verify: true metric_groups: - container - pod - node - volume processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [kubeletstats] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` `K8S_NODE_NAME` is injected by the DaemonSet from `spec.nodeName` (see Access Setup), not set in the `.env` file. ### Metrics Reference #### Node group | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.node.cpu.usage` | gauge | `1` | Instantaneous node CPU usage. | | `k8s.node.cpu.time` | sum | `s` | Cumulative node CPU seconds. | | `k8s.node.memory.usage` | gauge | `By` | Node memory in bytes. | | `k8s.node.memory.working_set` | gauge | `By` | Non-reclaimable working set. | | `k8s.node.network.io` | sum | `By` | Bytes over node interfaces. | | `k8s.node.filesystem.usage` | gauge | `By` | Node filesystem usage. | | `k8s.node.uptime` | sum | `s` | Seconds since node boot. | #### Pod group | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.pod.cpu.usage` | gauge | `1` | Instantaneous pod CPU usage. | | `k8s.pod.cpu.time` | sum | `s` | Cumulative pod CPU seconds. | | `k8s.pod.cpu_limit_utilization` | gauge | `1` | usage / CPU limit; emits only when a limit is set. | | `k8s.pod.cpu_request_utilization` | gauge | `1` | usage / CPU request; emits only when a request is set. | | `k8s.pod.memory.usage` | gauge | `By` | Pod memory in bytes. | | `k8s.pod.memory.working_set` | gauge | `By` | Pod non-reclaimable working set. | | `k8s.pod.network.io` | sum | `By` | Bytes over pod interfaces. | | `k8s.pod.filesystem.usage` | gauge | `By` | Pod ephemeral filesystem usage. | | `k8s.pod.uptime` | sum | `s` | Seconds since pod start. | #### Container group | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `container.cpu.usage` | gauge | `1` | Instantaneous container CPU usage. | | `container.cpu.time` | sum | `s` | Cumulative container CPU seconds. | | `container.memory.usage` | gauge | `By` | Container working memory. | | `container.memory.working_set` | gauge | `By` | Non-reclaimable working set. | | `container.memory.rss` | gauge | `By` | Resident set size. | | `container.filesystem.usage` | gauge | `By` | Writable-layer filesystem usage. | | `k8s.container.cpu_limit_utilization` | gauge | `1` | usage / CPU limit; emits only when a limit is set. | | `k8s.container.cpu_request_utilization` | gauge | `1` | usage / CPU request; emits only when a request is set. | | `k8s.container.memory_limit_utilization` | gauge | `1` | usage / memory limit; emits only when a limit is set. | #### Volume group | Metric | Type | Unit | Notes | | --- | --- | --- | --- | | `k8s.volume.available` | gauge | `By` | Available bytes; PVC-backed volumes only. | | `k8s.volume.capacity` | gauge | `By` | Capacity in bytes; PVC-backed volumes only. | The `*_limit_utilization` and `*_request_utilization` metrics only emit when the workload sets the corresponding resource limit or request. Set CPU and memory `requests` and `limits` on your pods to get them. ### Verify the Setup Deploy the DaemonSet and check that metrics flow within 60 seconds. The receiver may report metric definitions before any data points arrive, so allow one or two collection intervals before treating an empty result as a failure: ```bash showLineNumbers # Confirm the Collector pods are running, one per node. kubectl -n observability get pods -l app=otel-collector -o wide # Check a Collector pod's logs for kubeletstats activity. kubectl -n observability logs daemonset/otel-collector \ | grep -i kubeletstats ``` A quick way to confirm the receiver is emitting is to add a `debug` exporter (`verbosity: detailed`) to the metrics pipeline temporarily and watch for a real metric name such as `k8s.pod.cpu.usage` in the pod logs. ### Troubleshooting #### 401 or 403 scraping the kubelet **Cause**: the Collector ServiceAccount lacks `nodes/stats` / `nodes/proxy` access. **Fix**: 1. Apply the ClusterRole and ClusterRoleBinding from Access Setup. 2. Confirm the DaemonSet's `serviceAccountName` matches the binding subject. 3. Check the binding namespace matches the ServiceAccount's namespace. #### x509 certificate error **Cause**: the kubelet serves the Summary API with a self-signed cert that the Collector does not trust. **Fix**: 1. Set `insecure_skip_verify: true` in the receiver (the in-cluster scrape stays on the node-local network). 2. Alternatively, point the receiver at the cluster CA bundle if your kubelet certificate is signed by it. #### Pod and container metrics are empty **Cause**: no workloads are scheduled on the node, or the receiver is not reaching the kubelet. **Fix**: 1. Confirm pods are running on the node: `kubectl get pods -A --field-selector spec.nodeName=`. 2. Verify `K8S_NODE_NAME` resolves to the node's name inside the pod. 3. Confirm port `10250` is reachable from the Collector pod. #### Utilization metrics never appear **Cause**: the `*_limit_utilization` and `*_request_utilization` metrics need the workload to declare resource limits/requests. **Fix**: 1. Set CPU and memory `requests` and `limits` on the monitored pods. 2. Re-check after one collection interval - they emit per container. ### FAQ #### Why one Collector per node instead of one for the cluster? The kubelet only reports containers running on its own node. A DaemonSet gives each Collector a local kubelet to scrape, which spreads the load and avoids cross-node network hops. A single Collector would have to reach every node's kubelet and would miss nodes it cannot route to. #### What is the difference between kubeletstats and the metrics-server? The metrics-server aggregates a small CPU/memory set for the Horizontal Pod Autoscaler. The `kubeletstats` receiver reads the full kubelet Summary API - network, filesystem, working set, RSS, utilization - and ships it as OpenTelemetry metrics for long-term storage and querying. #### Why are volume metrics missing from the kubeletstats receiver? `k8s.volume.available` and `k8s.volume.capacity` emit only for PVC-backed volumes. Pods using `emptyDir` or no volumes produce no volume metrics - this is expected. #### Does `k8s.pod.cpu.utilization` exist? No. The receiver reports `k8s.pod.cpu.usage` (instantaneous usage) and `k8s.pod.cpu_limit_utilization` / `k8s.pod.cpu_request_utilization` (usage relative to the configured limit/request). There is no plain `*.cpu.utilization` metric. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) - **Monitor More Components**: Add monitoring for other workloads running on your cluster. - **Fine-tune Collection**: Adjust `collection_interval` based on how quickly you need to see node and pod resource shifts. ### Related Guides - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) — Deploy the Collector as a DaemonSet - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) — Advanced collector configuration Validated against: managed Kubernetes 1.30, OTel Collector Contrib 0.152.0. --- ## LiteLLM Gateway OpenTelemetry Monitoring - Deployment Health, Token Spend, and Collector Setup ## LiteLLM Gateway The LiteLLM proxy serves Prometheus text at `/metrics/` on its API port (`4000`) once the `prometheus` callback is enabled. The endpoint sits behind the proxy's API key, so the OpenTelemetry Collector's Prometheus receiver scrapes it with a Bearer token, collecting 40+ metrics across proxy request and failure rates, per-deployment health and cooldowns, latency (end to end, backend call, queue wait), token throughput and spend, and key and user budgets, on LiteLLM 1.85+. This guide enables the callback, configures the authenticated scrape, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | LiteLLM | 1.85 | 1.99 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | LiteLLM 1.85 put `/metrics` behind the proxy API key. Proxies older than 1.85 serve `/metrics` without a key; the Bearer header in this guide is harmless there. Before starting: - The API port (`4000`) must be reachable from the host running the Collector. `/metrics/` is served there once `litellm_settings.callbacks` includes `prometheus`. - A proxy API key for the Collector. Any valid key scrapes; a dedicated key keeps the scrape credential separate from caller keys. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or a budget review. Counters carry a `_total` suffix that the LiteLLM documentation omits. The docs list `litellm_spend_metric` and `litellm_input_tokens_metric`; the exposition, and therefore Scout, names them `litellm_spend_metric_total` and `litellm_input_tokens_metric_total`. Query the `_total` form. Gauges and histograms keep the documented names. Labels are wide and high-cardinality by design. Most request-path series carry `hashed_api_key`, `api_key_alias`, `team`, `team_alias`, `user`, `user_email`, `end_user`, `org_id`, `org_alias`, `model`, `model_id`, `requested_model`, `api_provider` and `service_tier`. The proxy counters add `route`, `status_code`, `client_ip` and `user_agent`; the deployment series add `api_base` and `litellm_model_name`. Every distinct caller, end user or client IP is a new series, so a multi-tenant proxy grows series with its caller population. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the proxy metrics endpoint responded and accepted the key. Also reads 0 when the key is rejected with 401. | | `litellm_proxy_total_requests_metric_total` | Requests through the proxy by `route`, `status_code`, `requested_model` and caller labels. Throughput and error rate. | | `litellm_proxy_failed_requests_metric_total` | Failed proxy requests by `exception_status` and `exception_class`. The user-facing error rate. | | `litellm_deployment_state` | Per-deployment health: 0 healthy, 1 partial outage, 2 complete outage. | | `litellm_deployment_cooled_down_total` | Deployments put in cooldown after failures, by `exception_status`. Each increment removes capacity and turns later calls into 429s. | | `litellm_request_total_latency_metric` | End-to-end proxy latency per request. The request SLO. | | `litellm_llm_api_latency_metric` | Backend LLM call latency per request. Separates provider slowness from proxy overhead. | `litellm_deployment_state` is an enum gauge, one series per deployment. Failures split by `exception_status` and `exception_class`: a backend 404 appears as `exception_status="404"` with the provider's exception class. When the router has no healthy deployment left it records `exception_class="RouterRateLimitError"` with `exception_status="None"`, and the proxy counter records `status_code="None"`, although the client receives 429. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `litellm_deployment_success_responses_total` | Successful backend responses per deployment (`api_base`, `litellm_model_name`). | | `litellm_deployment_failure_responses_total` | Failed backend responses per deployment by `exception_status`. Which provider is failing. | | `litellm_deployment_total_requests_total` | Backend requests per deployment. Denominator for the per-deployment error rate. | | `litellm_request_queue_time_seconds` | Time a request waits in the proxy before dispatch. Rising queue time is proxy or router capacity, not the provider. | | `litellm_in_flight_requests` | Requests currently being processed by the proxy. Concurrency. | | `litellm_input_tokens_metric_total` | Prompt tokens by model and caller. Cost driver. | | `litellm_output_tokens_metric_total` | Completion tokens by model and caller. Cost driver. | | `litellm_total_tokens_metric_total` | Input plus output tokens. | | `litellm_spend_metric_total` | Spend in USD by model and caller. Zero until the model has a price. | | `litellm_deployment_latency_per_output_token` | Backend latency per output token per deployment. Streaming throughput per provider. | | `litellm_remaining_api_key_budget_metric` | Remaining budget on the calling key. `+Inf` with no budget set. | | `litellm_remaining_api_key_requests_for_model` | Remaining RPM on the key for a model. Max int with no limit set. | | `litellm_remaining_api_key_tokens_for_model` | Remaining TPM on the key for a model. Max int with no limit set. | | `litellm_remaining_user_budget_metric` | Remaining budget on the calling user. `+Inf` with no budget set. | | `process_resident_memory_bytes` | Proxy process RSS. | | `process_cpu_seconds_total` | Proxy process CPU time. | The latency histograms share one bucket layout from 5 ms to 600 s. `litellm_llm_api_latency_metric` is the backend call, `litellm_request_total_latency_metric` is the whole proxy round trip, `litellm_request_queue_time_seconds` is the wait before dispatch, and `litellm_deployment_latency_per_output_token` is backend latency divided by output tokens per deployment. A gap between total and backend latency is proxy overhead or queueing. `litellm_spend_metric_total` reads 0 for models with no price. Models in LiteLLM's cost map are priced automatically; self-hosted models need `input_cost_per_token` and `output_cost_per_token` set on the deployment before spend moves. The budget and rate-limit gauges read `+Inf` or the max integer until a budget or limit is configured on the key. They are present but carry nothing until limits exist. #### Diagnostic - for investigation and tuning Deprecated names, database-backed counts, and process internals. | Group | Metrics | When you reach for it | |---|---|---| | Deprecated counters | `litellm_requests_metric_total`, `litellm_llm_api_failed_requests_metric_total` | Still emitted, marked deprecated in their HELP text. Superseded by `litellm_proxy_total_requests_metric_total` and `litellm_proxy_failed_requests_metric_total`; migrate dashboards that still query them. | | Users and teams | `litellm_active_users`, `litellm_total_users`, `litellm_teams_count` | Users seen recently, users and teams in the database. 0 without a database. | | Batch-cost poller | `litellm_check_batch_cost_jobs_polled`, `litellm_check_batch_cost_last_run_timestamp` | Batch-cost poller status. Only moves with the batches API. | | Process | `process_open_fds`, `process_max_fds`, `process_virtual_memory_bytes`, `process_start_time_seconds` | File descriptors, virtual memory, start time. | | Python | `python_gc_collections_total`, `python_gc_objects_collected_total`, `python_gc_objects_uncollectable_total`, `python_info` | Interpreter GC and version. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Prometheus receiver scrape health. | LiteLLM registers most families lazily, so several appear only once the feature behind them is in use: the team, org and provider budget gauges and the `litellm_deployment_rpm_limit` and `litellm_deployment_tpm_limit` gauges need a database, a team, an org or a configured budget; the `litellm_cache_*` and cached-token counters need `cache` enabled; `litellm_deployment_successful_fallbacks_total` and `litellm_deployment_failed_fallbacks_total` need a `fallbacks` list in the router config; `litellm_llm_api_time_to_first_token_metric` and the reasoning, audio, image and video token counters need streaming or non-text calls. With more than one uvicorn worker, each worker holds its own registry unless `PROMETHEUS_MULTIPROC_DIR` is set. Set it whenever `NUM_WORKERS` is above 1, or the scrape sees one worker's counters at a time. Full metric list: see the [LiteLLM Prometheus reference](https://docs.litellm.ai/docs/proxy/prometheus), or run `curl -s -H "Authorization: Bearer $LITELLM_API_KEY" http://localhost:4000/metrics/` against your proxy. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. Absolute latency numbers depend on the providers behind the proxy, the models, and prompt shape, so the latency rows are relative to your own baseline. Tune to your workload; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `up` | - | `== 0` for > 1m | The metrics endpoint stopped responding, or the scrape key was revoked (401 also reads as `up` 0); check the container and the key. | | `rate(litellm_proxy_failed_requests_metric_total) / rate(litellm_proxy_total_requests_metric_total)` | Above baseline | Sustained rise | Split by `exception_class`: provider errors versus `RouterRateLimitError` (no healthy deployment left). | | `litellm_deployment_state` | - | `== 2` for > 1m | A deployment is fully failing; check `api_base` and the provider's status. | | `increase(litellm_deployment_cooled_down_total[5m])` | - | `> 0` | The router pulled a deployment; capacity dropped and callers may see 429. Correlate with `litellm_deployment_failure_responses_total` by `exception_status`. | | `rate(litellm_deployment_failure_responses_total) / rate(litellm_deployment_total_requests_total)` by `api_base` | Above baseline | Sustained rise | One provider degrading before the cooldown trips; fail over or pull it from the router. | | `litellm_request_total_latency_metric` (p99) | Rising vs baseline | Sustained rise | Compare with `litellm_llm_api_latency_metric`; a gap is proxy overhead or queueing. | | `litellm_llm_api_latency_metric` (p99) | Rising vs baseline | Sustained rise | The provider is slow; check `litellm_deployment_latency_per_output_token` by `api_base`. | | `litellm_request_queue_time_seconds` (p99) | Rising vs baseline | `litellm_in_flight_requests` at a plateau | Proxy capacity; add workers or replicas. | | `litellm_remaining_api_key_budget_metric` | `< 10%` of the configured budget | - | Requests reject at zero; raise the budget or rotate keys. Needs a budget configured. | | `litellm_remaining_api_key_requests_for_model`, `litellm_remaining_api_key_tokens_for_model` | Near 0 | - | Callers are about to get 429 from the proxy's own limiter. Needs a limit configured. | | `rate(litellm_spend_metric_total)` by `model` or `team` | Above baseline | Sustained rise | Runaway usage. Needs model prices configured, otherwise the series is always 0. | The latency rows are Prometheus histograms - there is no ready-made `p99` series to threshold. Compute the percentile from the buckets in your alert rule, for example `histogram_quantile(0.99, rate(litellm_request_total_latency_metric_bucket[5m]))`. ### Access Setup The proxy exposes `/metrics/` on the API port once the `prometheus` callback is in the proxy config, and it answers with the same key check as the API. Access setup is the proxy config, the master key, and a key for the Collector. The proxy config declares the deployments it routes to and turns the callback on. The example points at an OpenAI-compatible backend such as a [vLLM](./vllm.md) server: ```yaml showLineNumbers title="config/litellm.yaml" model_list: - model_name: your-model # the name callers request litellm_params: model: openai/your-org/your-model # openai/ for an OpenAI-compatible backend api_base: http://vllm:8000/v1 # the backend's base URL api_key: none # Self-hosted models have no entry in LiteLLM's cost map; set prices # or litellm_spend_metric_total stays 0 input_cost_per_token: 0.0000001 output_cost_per_token: 0.0000002 litellm_settings: callbacks: ["prometheus"] ``` `LITELLM_MASTER_KEY` sets the proxy's master key. Any valid proxy key scrapes `/metrics/`; the master key works, and a dedicated key issued for the Collector keeps the scrape credential separate from caller keys. **Docker setup** - the image `ghcr.io/berriai/litellm:main-stable`. The image ships no `curl`, so a container healthcheck uses `python3` with `urllib` against `/health/liveliness`, which needs no key: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: litellm: image: ghcr.io/berriai/litellm:main-stable command: ["--config", "/app/config.yaml", "--port", "4000"] environment: LITELLM_MASTER_KEY: ${LITELLM_MASTER_KEY} volumes: - ./config/litellm.yaml:/app/config.yaml:ro ports: - "4000:4000" healthcheck: test: ["CMD-SHELL", "python3 -c \"import urllib.request; urllib.request.urlopen('http://localhost:4000/health/liveliness')\" || exit 1"] interval: 10s timeout: 5s retries: 30 start_period: 30s ``` The key check on `/metrics/` can be switched off in the proxy config with `litellm_settings.require_auth_for_metrics_endpoint: false`. The endpoint then serves caller labels, hashed keys and client IPs to anyone who can reach port `4000`; keep the key check on and scrape with a key unless the port is confined to a private network. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # The proxy lists the configured models once it is up curl -s -H "Authorization: Bearer $LITELLM_API_KEY" http://localhost:4000/v1/models # Verify the metrics endpoint accepts the key curl -s -H "Authorization: Bearer $LITELLM_API_KEY" http://localhost:4000/metrics/ | grep litellm_proxy_total_requests_metric_total ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: litellm scrape_interval: 10s # The proxy answers 307 on /metrics; scrape the final path metrics_path: /metrics/ # /metrics needs a proxy API key on LiteLLM 1.85+ authorization: type: Bearer credentials: ${env:LITELLM_API_KEY} static_configs: - targets: # host:port the proxy's API is reachable on - ${env:LITELLM_HOST}:${env:LITELLM_PORT} processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Prometheus receiver keeps everything `/metrics/` exposes. There is no per-metric enable list; families that LiteLLM registers lazily appear with no Collector change once the feature behind them is in use. Scout authentication for the `otlphttp/b14` exporter is covered in [Scout Exporter](../collector-setup/scout-exporter.md). #### Environment Variables ```bash showLineNumbers title=".env" LITELLM_HOST=localhost LITELLM_PORT=4000 LITELLM_API_KEY=sk-your-collector-key ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Scoping labels The proxy counters carry `client_ip` and `user_agent`, and each distinct value is its own series. If dashboards and alerts group by model, team and key rather than by client, a `labeldrop` on the scrape job scopes the series to the labels in use: ```yaml showLineNumbers title="config/otel-collector.yaml (label scoping)" metric_relabel_configs: - regex: "client_ip|user_agent" action: labeldrop ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped LiteLLM metrics docker logs otel-collector 2>&1 | grep "litellm_" # Check deployment health directly on the metrics endpoint curl -s -H "Authorization: Bearer $LITELLM_API_KEY" http://localhost:4000/metrics/ | grep '^litellm_deployment_state' # Generate traffic so the request counters and histograms advance curl -s http://localhost:4000/v1/completions \ -H "Authorization: Bearer $LITELLM_API_KEY" \ -H 'Content-Type: application/json' \ -d '{"model": "your-model", "prompt": "Hello", "max_tokens": 32}' # Confirm the request was counted curl -s -H "Authorization: Bearer $LITELLM_API_KEY" http://localhost:4000/metrics/ | grep '^litellm_proxy_total_requests_metric_total' ``` In Scout, query `litellm_proxy_total_requests_metric_total` by `requested_model` and `status_code` to confirm the series arrived with the `_total` suffix intact, and `litellm_deployment_state` by `api_base` to see each deployment. ### Troubleshooting #### Scrape returns 401 **Cause**: The key is missing from the scrape config or the proxy rejected it. On LiteLLM 1.85+ `/metrics/` runs the same key check as the API. **Look at**: `up` reads 0 for the `litellm` job while the container is running, and the Collector log reports a 401 on the scrape. `scrape_samples_scraped` (Diagnostic) reads 0. **Fix**: 1. Set `authorization.type: Bearer` and `credentials` on the scrape job. 2. Confirm the key is valid; this returns 200: ```bash curl -s -o /dev/null -w '%{http_code}' \ -H "Authorization: Bearer $LITELLM_API_KEY" \ http://localhost:4000/metrics/ ``` 3. If the key was rotated or a key with a budget hit zero, issue a dedicated key for the Collector. #### Scrape follows a redirect or returns 307 **Cause**: The scrape targets `/metrics`, and the proxy answers 307 to `/metrics/`. The receiver's default `metrics_path` is `/metrics`, and it follows redirects unless `follow_redirects: false` is set on the job. **Look at**: the Collector log for a 307 or a redirect error on the `litellm` job; with redirects disabled, `up` reads 0. **Fix**: 1. Set `metrics_path: /metrics/` on the scrape job, with the trailing slash, so each scrape is one request. #### Dashboard queries find no `litellm_spend_metric` **Cause**: The query uses the name from the LiteLLM documentation. The exposition, and Scout, carry the counter as `litellm_spend_metric_total`. **Fix**: 1. Query the `_total` form for every counter: `litellm_spend_metric_total`, `litellm_input_tokens_metric_total`, `litellm_proxy_total_requests_metric_total`. 2. Gauges and histograms keep the documented names: `litellm_deployment_state`, `litellm_request_total_latency_metric`. #### Spend stays 0 while tokens advance **Cause**: The model has no price. LiteLLM computes spend from its cost map, and self-hosted or custom models are not in it. **Look at**: `litellm_input_tokens_metric_total` and `litellm_output_tokens_metric_total` advancing while `litellm_spend_metric_total` stays at 0 for the same `model`. **Fix**: 1. Set `input_cost_per_token` and `output_cost_per_token` in the deployment's `litellm_params`. 2. Restart the proxy; spend accrues from the next request. #### Callers get 429 while backends look healthy **Cause**: The router put a deployment in cooldown after failures and has no healthy deployment left for the requested model. The 429 comes from the router, not the provider. **Look at**: `litellm_deployment_cooled_down_total` incrementing and `litellm_deployment_state` reading 2 for the deployment. `litellm_proxy_failed_requests_metric_total` splits the picture by `exception_status`: the provider's original failures carry their HTTP status, and the router's rejections carry `exception_class="RouterRateLimitError"` with `exception_status="None"`. **Fix**: 1. Read `litellm_deployment_failure_responses_total` by `api_base` and `exception_status` to find the failure that tripped the cooldown. 2. Fix the backend or its `api_base`, or add a second deployment for the model so the router has capacity during a cooldown. #### Counters reset or look partial with several workers **Cause**: `NUM_WORKERS` is above 1 and each uvicorn worker holds its own registry. Each scrape lands on one worker and reports only its counters. **Look at**: `litellm_proxy_total_requests_metric_total` can move backwards between scrapes, and `litellm_in_flight_requests` can flap between values that do not add up to the observed concurrency. **Fix**: 1. Set `PROMETHEUS_MULTIPROC_DIR` to a writable directory in the proxy's environment so the workers share one registry. 2. Or run one worker per replica and scale replicas. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. 4. Query the counter with its `_total` suffix. ### FAQ #### Why do the counters end in `_total` when the LiteLLM docs do not show it? The proxy exposes counters under the Prometheus convention, which appends `_total` to counter names. The LiteLLM documentation lists the registered name without the suffix. The Prometheus receiver passes the exposition name through, so Scout stores `litellm_spend_metric_total`. Gauges and histograms are not suffixed and match the docs. #### Does the proxy need a database for these metrics? No. The request, deployment, latency, token and spend metrics work without one. The team, org and user budget families and the user and team counts (`litellm_total_users`, `litellm_teams_count`, `litellm_active_users`) need the database; without it they read 0 or stay absent. #### Does this cover LiteLLM's own OpenTelemetry callback? No. `callbacks: ["otel"]` exports traces from the proxy over OTLP. It is a separate configuration from the `prometheus` callback. This guide covers the metrics surface only. #### Does this work with LiteLLM running in Kubernetes? Yes. Set `targets` to the proxy service DNS (for example `litellm.default.svc.cluster.local:4000`), and put the Collector's key in a Secret exposed to the Collector as `LITELLM_API_KEY`. The Collector runs as a sidecar in the proxy pod or as a Deployment scraping the service; see [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md). ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on LiteLLM metrics. - [vLLM Monitoring](./vllm.md) - Self-hosted model server LiteLLM routes to; pair both for the gateway-to-backend view. - [LLM Observability](../../guides/ai-observability/llm-observability.md) - Application-side tracing of LLM calls, token usage and cost. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [vLLM](./vllm.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Use the `model`, `team` and `api_base` labels to split dashboards per model, per team and per provider, and set prices on self-hosted deployments so spend reads alongside tokens. --- ## llama.cpp OpenTelemetry Monitoring - Slot Occupancy, Token Throughput, and Collector Setup ## llama.cpp llama.cpp's `llama-server` serves Prometheus text at `/metrics` on its API port (`8080`) when started with `--metrics`. The OpenTelemetry Collector scrapes it with the Prometheus receiver, collecting 15 `llamacpp:` series covering slot occupancy and queueing, prompt and generation token throughput, prompt-cache reuse, batching efficiency, and speculative decoding. The endpoint is **off by default** - without `--metrics` it answers HTTP 501. This guide turns the endpoint on, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | --------------- | | llama.cpp | b7191 | b10795 or later | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - `llama-server` must be started with `--metrics` (or the environment variable `LLAMA_ARG_ENDPOINT_METRICS=1`). Without it, `/metrics` answers HTTP 501 with a `not_supported_error` body telling you to restart the server with `--metrics`. - The API port (`8080`) must be reachable from the host running the Collector. `/metrics` is served on the same port as the inference API. - `/metrics` has no authentication. Scrape it on the internal network, or exempt the path at a fronting proxy. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). :::warning Upgrading from a pre-b7191 build? Builds before **b7191** (published 2025-11-28) serve `/metrics` as JSON-escaped text wrapped in double quotes, which the Prometheus receiver cannot parse. Upstream PR #17386 fixed the exposition format; b7191 is the first build that carries it. Full notes: [Updates & Upgrades](#updates--upgrades). ::: ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The metric prefix is `llamacpp:`, with a colon. Prometheus accepts colons in metric names, the Prometheus receiver passes them through unchanged, and Scout stores them as-is. Query the names verbatim. **None of the emitted series carries a label.** There is no model, slot, or endpoint dimension - every `llamacpp:` name arrives as a single unlabelled data point. A multi-model or router deployment therefore needs one scrape target per server. Router mode documents a `/metrics?model=` form for selecting a served model; confirm it against your build before relying on it. The exposed names do not follow one pattern. The generation counters use `tokens_predicted_`, while the generation gauge uses `predicted_tokens_`. Copy the names below character for character. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the llama.cpp metrics endpoint responded. | | `llamacpp:requests_processing` | Requests currently occupying a slot. Caps at the slot count; equal to the slot count means full. | | `llamacpp:requests_deferred` | Requests queued because every slot is busy. The saturation signal. | | `llamacpp:predicted_tokens_seconds` | Generation throughput of the last completed request, tokens/s. Reads 0 when idle, so chart and alert on the counter-derived rate `rate(llamacpp:tokens_predicted_total[10m]) / rate(llamacpp:tokens_predicted_seconds_total[10m])` instead. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `llamacpp:tokens_predicted_total` | Generated tokens since start. Output throughput and cost driver. | | `llamacpp:tokens_predicted_seconds_total` | Seconds spent generating. Denominator for a smoothed tokens/s. | | `llamacpp:prompt_tokens_total` | Prompt tokens processed (prefill), excluding cache hits. Input throughput. | | `llamacpp:prompt_seconds_total` | Seconds spent in prefill. Denominator for prompt tokens/s. | | `llamacpp:prompt_tokens_seconds` | Prefill throughput of the last completed request, tokens/s. Reads 0 when idle. | | `llamacpp:prompt_tokens_cached_total` | Prompt tokens served from the prompt cache. Numerator of the cache hit ratio. | | `llamacpp:n_tokens_max` | High-water mark of tokens in a slot. Sits at the per-slot context minus one once any request fills a slot. | Four things about this tier decide whether your dashboards and alerts are correct: - **The two throughput gauges are per-request, not lifetime averages.** `llamacpp:prompt_tokens_seconds` and `llamacpp:predicted_tokens_seconds` carry the rate of the most recently completed request and read `0` whenever the server is idle. Alerting on them directly pages during quiet periods. Derive throughput from the counters instead: `rate(llamacpp:tokens_predicted_total[10m]) / rate(llamacpp:tokens_predicted_seconds_total[10m])`. - **Cached and processed prompt tokens are disjoint.** `llamacpp:prompt_tokens_cached_total` counts tokens served from the prompt cache; `llamacpp:prompt_tokens_total` counts tokens actually prefilled. The cache hit ratio is `cached / (cached + total)`, not `cached / total`. - **`llamacpp:n_tokens_max` is exported as a Sum but behaves as a high-water mark.** It sits at the per-slot context minus one once any request fills a slot. Do not apply `rate()` to it. - **The slot count controls concurrency.** `--parallel` sets the number of server slots (default `-1`, auto) and `--ctx-size` is divided across them. `llamacpp:requests_processing` caps at the slot count, and every surplus request lands in `llamacpp:requests_deferred`. There is no error counter and no latency histogram on this surface. Request failures, end-to-end latency, and time to first token have to come from the client or from a proxy in front of the server. Over-long generations are truncated rather than rejected: a request asking for more tokens than the slot context is silently truncated, and the only signal is the `truncated` field in the response body. #### Diagnostic - for investigation and tuning Reach for these during an incident or a capacity review. | Metric | When you reach for it | |---|---| | `llamacpp:n_decode_total` | Decode steps executed. Divided by `llamacpp:tokens_predicted_total` it gives tokens per step. | | `llamacpp:n_busy_slots_per_decode` | Mean busy slots per decode step. Batching efficiency; 1.0 means no batching. | | `llamacpp:spec_decode_num_drafts_total` | Speculative decoding drafts. 0 without a draft model. | | `llamacpp:spec_decode_num_draft_tokens_total` | Speculative decoding draft tokens. 0 without a draft model. | | `llamacpp:spec_decode_num_accepted_tokens_total` | Speculative decoding accepted tokens. Divided by draft tokens it gives the acceptance rate. | | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Prometheus receiver scrape health. | The three `spec_decode_*` counters are real series that sit at `0` until a draft model is loaded with `-md`. They are present, not absent. `/slots` is enabled by default (`--slots` / `--no-slots`, env `LLAMA_ARG_ENDPOINT_SLOTS`) and returns per-slot state that `/metrics` does not: `n_ctx`, `is_processing`, `n_prompt_tokens`, `n_prompt_tokens_cache`, and the sampling parameters. Use it when a single slot appears stuck. `POST /props` is off by default (`--props`). Full metric list: run `curl -s http://localhost:8080/metrics` against your server. ### Key Alerts to Configure Absolute token rates depend on the model, the hardware, and the prompt shape, so every threshold below is relative to your own trailing baseline. `up == 0` is the one state read. Tune to your workload; these are starting points. | Alert | Expression | Why it matters | |---|---|---| | Server down | `up == 0` for 2m | The metrics endpoint stopped answering. Also fires when someone restarts the server without `--metrics`. | | Requests queueing | `llamacpp:requests_deferred > 0` for 5m | Every slot is busy and requests are waiting. Raise `--parallel` or add a server. | | Slots pinned full | `llamacpp:requests_processing` at the configured slot count for 10m | Sustained full occupancy; queueing is imminent. The slot count is a deployment constant, not a metric, so write it into the rule. | | Generation throughput collapse | `rate(llamacpp:tokens_predicted_total[10m]) / rate(llamacpp:tokens_predicted_seconds_total[10m])` below a fraction of its 24h baseline | Derived from the counters so idle periods do not skew it. Do not use `llamacpp:predicted_tokens_seconds` here - that gauge reads 0 when idle. | | Prompt cache hit ratio drop | `rate(llamacpp:prompt_tokens_cached_total[15m]) / (rate(llamacpp:prompt_tokens_cached_total[15m]) + rate(llamacpp:prompt_tokens_total[15m]))` below baseline | Losing prefix reuse raises prefill cost directly. | | Prefill stall | `rate(llamacpp:prompt_seconds_total[10m])` rising while `rate(llamacpp:prompt_tokens_total[10m])` is flat | Time is going into prefill without tokens coming out. | ### Access Setup The metrics endpoint is off by default. Turn it on with the `--metrics` flag or the `LLAMA_ARG_ENDPOINT_METRICS` environment variable - the two forms are equivalent, and the environment variable is the easier one to set through a container spec you do not own. ```bash showLineNumbers title="Start llama-server with metrics on" # Flag form llama-server -hf your-org/your-model-GGUF \ --host 0.0.0.0 --port 8080 \ --ctx-size 4096 \ --parallel 4 \ --metrics # Environment-variable form LLAMA_ARG_ENDPOINT_METRICS=1 llama-server -hf your-org/your-model-GGUF ``` **Docker setup** - the same two forms, on the official server image: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: llama-cpp: image: ghcr.io/ggml-org/llama.cpp:server command: - -hf - your-org/your-model-GGUF # model repo or a mounted .gguf path - --host - 0.0.0.0 - --ctx-size - "4096" - --parallel - "4" # slot count; caps concurrency - --metrics # required; endpoint is off by default ports: - "8080:8080" volumes: - llama-models:/root/.cache/llama.cpp volumes: llama-models: ``` `/metrics` carries no authentication and sits on the same port as the inference API, so it must not be exposed publicly. Scrape it over the internal network, or exempt the `/metrics` path at whatever proxy fronts the API. #### Choosing `--parallel` and `--ctx-size` together `--parallel` sets the number of slots and `--ctx-size` is the total context divided across them: `--ctx-size 4096 --parallel 4` gives each slot 1024 tokens. Raising the slot count raises the concurrency ceiling and lowers the per-request context in the same step, so size the two against your longest expected prompt plus generation. `--parallel` defaults to `-1`, which picks a slot count automatically; set it explicitly when you want the alert on `llamacpp:requests_processing` to compare against a known constant. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # The server lists the loaded model once it is up curl -s http://localhost:8080/v1/models # Verify the metrics endpoint; 501 means --metrics is missing curl -s http://localhost:8080/metrics | grep '^llamacpp:' | head -20 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: llama-cpp scrape_interval: 15s static_configs: - targets: # host:port llama-server's API is reachable on - ${env:LLAMA_CPP_HOST}:8080 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Prometheus receiver keeps everything `/metrics` exposes. There is no per-metric enable list, so new series appear after a llama.cpp upgrade with no Collector change. The receiver also synthesizes `up` and the four `scrape_*` series. Scout authentication for the `otlphttp/b14` exporter is covered in [Scout Exporter](../collector-setup/scout-exporter.md). Run the Collector from `otel/opentelemetry-collector-contrib:latest` (or a pinned tag of the same image) alongside the server. #### Environment Variables ```bash showLineNumbers title=".env" LLAMA_CPP_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm the endpoint is serving the concurrency gauge curl -s http://localhost:8080/metrics | grep 'llamacpp:requests_processing' # Check Collector logs for scraped llama.cpp metrics docker logs otel-collector 2>&1 | grep "llamacpp:" # Generate traffic so the token counters advance curl -s http://localhost:8080/v1/completions \ -H 'Content-Type: application/json' \ -d '{"prompt": "Hello", "n_predict": 32}' # Confirm generated tokens were counted curl -s http://localhost:8080/metrics | grep 'llamacpp:tokens_predicted_total' ``` In Scout, query `llamacpp:requests_processing` to confirm the series arrived with the colon-prefixed name intact. ### Troubleshooting #### `/metrics` returns HTTP 501 `not_supported_error` **Cause**: The server was started without `--metrics`. The endpoint is off by default and the 501 body says so. **Fix**: 1. Restart `llama-server` with `--metrics`, or set `LLAMA_ARG_ENDPOINT_METRICS=1` in its environment. 2. In a container spec you do not control, the environment variable is usually easier to inject than an extra argument. #### The receiver reports a parse error and `/metrics` output is quoted **Cause**: The build predates b7191 and serves the exposition as JSON-escaped text wrapped in double quotes, which the Prometheus receiver cannot parse. **Look at**: the raw response - `curl -s http://localhost:8080/metrics | head -3`. A leading `"` on the first line confirms it. **Fix**: Upgrade to b7191 or later (see [Updates & Upgrades](#updates--upgrades)). #### The throughput gauges read 0 on the dashboard **Cause**: `llamacpp:predicted_tokens_seconds` and `llamacpp:prompt_tokens_seconds` carry the rate of the most recently completed request, not a lifetime average. They read 0 whenever the server was idle at scrape time. **Look at**: `llamacpp:tokens_predicted_total` - if it is still advancing, the server is serving and only the gauge is idle-zeroed. **Fix**: Chart and alert on the counter-derived rate, `rate(llamacpp:tokens_predicted_total[10m]) / rate(llamacpp:tokens_predicted_seconds_total[10m])`, and keep the gauges for spot checks only. #### `llamacpp:requests_deferred` is always high **Cause**: The slot count is too low for the offered load. Every request beyond the slot count queues. **Look at**: `llamacpp:requests_processing` sitting at the configured slot count, with `llamacpp:requests_deferred` above 0 alongside it. The Diagnostic `llamacpp:n_busy_slots_per_decode` shows whether the slots you do have are being batched. **Fix**: 1. Raise `--parallel`. Each slot then gets a smaller share of `--ctx-size`, so raise `--ctx-size` in step if prompts are long. 2. Add another server and a scrape target for it if the host is already compute-bound. #### Speculative decoding is loaded but throughput did not improve **Cause**: the draft model is being rejected more often than it is accepted, so every drafted token costs compute and returns nothing. **Look at**: the Diagnostic tier's `spec_decode_*` counters. The acceptance rate is `llamacpp:spec_decode_num_accepted_tokens_total` divided by `llamacpp:spec_decode_num_draft_tokens_total`; a low ratio means the draft model disagrees with the target model too often to pay for itself. `llamacpp:spec_decode_num_drafts_total` confirms drafting is happening at all - all three sit at `0` without a draft model loaded via `-md`. **Fix**: use a draft model from the same family and tokenizer as the target, or drop speculative decoding. Compare `llamacpp:tokens_predicted_seconds_total` against `llamacpp:tokens_predicted_total` before and after to confirm the change paid off. #### Responses are cut off mid-sentence **Cause**: The request asked for more tokens than the per-slot context allows. llama.cpp truncates rather than rejecting, and no metric records it. **Look at**: the `truncated` field in the response body, and the per-slot `n_ctx` from `GET /slots`. `llamacpp:n_tokens_max` sitting at the per-slot context minus one confirms a slot was filled. **Fix**: 1. Lower `n_predict` / `max_tokens` on the client, or 2. Raise `--ctx-size`, or lower `--parallel` so each slot gets more of it. #### No `llamacpp:` series in Scout but `up == 1` **Cause**: The query is dropping the colon. The receiver passes `llamacpp:` through unchanged and Scout stores it as-is. **Fix**: 1. Query `llamacpp:requests_processing`, not `llamacpp_requests_processing`. 2. If the names are right and still nothing arrives, check the Collector logs for export errors (`docker logs otel-collector`), confirm `OTEL_EXPORTER_OTLP_ENDPOINT`, and confirm the pipeline lists both the receiver and the exporter. ### Updates & Upgrades #### llama.cpp version changes - **Before b7191 → b7191+**: `/metrics` changed from JSON-escaped text wrapped in double quotes to plain Prometheus exposition (upstream PR #17386). The Prometheus receiver cannot parse the older form, so a scrape job against a pre-b7191 server fails outright. b7191 is the minimum build for this guide. _(breaking on the older build; the fix is the upgrade)_ - **Speculative decoding counters**: `llamacpp:spec_decode_*` were added upstream on 2026-08-05 (PR #26389), building on the acceptance-rate work in PR #24536. Builds between b7191 and those merges expose the rest of the surface without the `spec_decode_*` family, so panels that reference them read empty rather than zero. _(additive)_ #### Collector / receiver changes - This guide uses the **prometheus receiver**, which has no receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. New `llamacpp:` series appear automatically because there is no per-metric enable list. _(no breaking change on the Prometheus path)_ ### FAQ #### How do I monitor several llama-server instances? Add one scrape target per server. No emitted series carries a model, slot, or instance dimension, so the servers cannot be told apart within a single target. The Prometheus receiver sets `service.instance.id` from the target's `host:port`, which is what distinguishes them in Scout. ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: prometheus: config: scrape_configs: - job_name: llama-cpp scrape_interval: 15s static_configs: - targets: - llama-cpp-1:8080 - llama-cpp-2:8080 ``` #### Why is there no request-latency or error metric? The surface exposes counters and gauges only - no histogram and no failure counter. End-to-end latency, time to first token, and request failures have to come from the client or from a proxy in front of the server. If you already run a gateway such as LiteLLM ahead of `llama-server`, take those signals from there. #### What does `llamacpp:n_busy_slots_per_decode` mean? The mean number of busy slots per decode step. `1.0` means no batching - each decode step served a single request. It rises with concurrency as the server batches requests into the same step, which is where the throughput gain from multiple slots comes from. A value stuck near 1.0 while `llamacpp:requests_deferred` is above 0 points at slots that are not being filled. #### Is it a problem that the `spec_decode_*` series read 0? No. Speculative decoding needs a draft model, loaded with `-md`. Without one, the three counters are real series sitting at zero rather than missing series. They start advancing as soon as a draft model is configured, and draft tokens over accepted tokens gives the acceptance rate. #### Does this work with llama.cpp running in Kubernetes? Yes. Set `targets` to the service DNS (for example `llama-cpp.default.svc.cluster.local:8080`), and run the Collector as a sidecar in the same pod or as a DaemonSet. Pass `--metrics` through the container `args`, or set `LLAMA_ARG_ENDPOINT_METRICS=1` in `env` when the argument list is managed by a chart. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on llama.cpp metrics. - [vLLM Monitoring](./vllm.md) - Self-hosted model server for GPU throughput serving, where llama.cpp serves CPU and single-node GGUF. - [LiteLLM Gateway Monitoring](./litellm.md) - LLM gateway that commonly fronts a llama-server, and where request latency and error rates live. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [vLLM](./vllm.md), [LiteLLM Gateway](./litellm.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your traffic, and add a scrape target for every additional `llama-server` you run. --- ## MariaDB OpenTelemetry Monitoring - Query Throughput, Connections, and Collector Setup ## MariaDB MariaDB speaks the MySQL wire protocol, so the OpenTelemetry Collector's `mysql` receiver monitors it without a separate exporter. It connects over TCP on port 3306, runs `SHOW GLOBAL STATUS` / `SHOW GLOBAL VARIABLES` and `performance_schema` queries, and emits 31 metrics per scrape - query throughput, connection health, lock contention, buffer-pool pressure, and InnoDB internals. This guide sets up a monitoring user, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | MariaDB | 10.5 | 12.3+ | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | — | Before starting: - MariaDB must be reachable from the host running the Collector. - A superuser account to create the monitoring user once. - `performance_schema` enabled for statement-event and table-lock-wait coverage. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). - A Scout account and OTLP endpoint. ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `mysql.uptime` | Seconds since server start - reachability and restart detection. | | `mysql.query.count` | Statements executed; the headline throughput KPI. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Connection health | `mysql.connection.count`, `mysql.connection.errors` | Connections opened and connection failures by cause. | | Latency | `mysql.query.slow.count` | Queries over `long_query_time` - regressions and missing indexes. | | Contention | `mysql.locks`, `mysql.row_locks` | Table locks (immediate vs waited) and InnoDB row-lock waits / time. | | Saturation | `mysql.threads` | Threads connected / running / cached against the server max. | | Cache pressure | `mysql.buffer_pool.usage` | Buffer-pool bytes by state; working set vs pool size. | | Query spill | `mysql.tmp_resources` | Temp tables and files, memory vs disk - sort and join spill. | #### Diagnostic - for investigation and tuning Higher cardinality (these series drive most of the per-scrape data-point count). Keep them available for incident work; drop them in production with a `filter` processor if you need to control volume. | Group | Metrics | When you reach for it | |---|---|---| | Command / handler breakdown | `mysql.commands`, `mysql.handlers`, `mysql.query.client.count` | Which statement and storage-engine handler calls dominate. | | InnoDB internals | `mysql.operations`, `mysql.page_operations`, `mysql.log_operations`, `mysql.double_writes` | Row, page, redo-log, and doublewrite-buffer activity. | | Buffer-pool detail | `mysql.buffer_pool.data_pages`, `mysql.buffer_pool.limit`, `mysql.buffer_pool.operations`, `mysql.buffer_pool.page_flushes`, `mysql.buffer_pool.pages` | Clean/dirty pages, capacity, read/write requests, flush rate. | | Query workload | `mysql.sorts`, `mysql.joins`, `mysql.prepared_statements` | Sort and join types, prepared-statement load. | | Resource accounting | `mysql.opened_resources`, `mysql.table_open_cache`, `mysql.client.network.io` | Files / tables / definitions opened, cache hits/misses, client bytes. | | Per-table stats | `mysql.table.rows`, `mysql.table.size`, `mysql.table.average_row_length` | Row count, data/index size, and average row length per table. | The following are enabled in the config but only emit in specific contexts - keep them on so they surface when those conditions arise: - `mysql.replica.sql_delay`, `mysql.replica.time_behind_source` - emit only when a replica is configured. - `mysql.statement_event.count`, `mysql.statement_event.wait.time` - require populated `performance_schema` digest tables. - `mysql.table.lock_wait.read.count` / `.read.time` / `.write.count` / `.write.time` - emit only when contended table-lock waits occur. Full metric reference: [OTel MySQL Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/mysqlreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Operational-tier series. These are starting points; tune them to your workload. | Metric | Threshold | Why it matters | |---|---|---| | `rate(mysql.connection.errors)` | Rising above 0 | Clients can't connect; check `max_connections`, auth, and network. | | `mysql.threads{kind=connected}` | Near the server max | Approaching `max_connections`; add pooling or raise the cap. | | `rate(mysql.query.slow.count)` | Rising vs baseline | Query regressions or missing indexes; inspect the slow log. | | `mysql.row_locks` (wait time) | Rising | Transactions blocking; review lock ordering and hot rows. | | `mysql.tmp_resources{kind=disk_tables}` | Rising | `tmp_table_size` too small or unindexed sorts; tune queries. | | `mysql.buffer_pool.usage` (dirty/free ratio) | Shifting toward full | Working set exceeds the pool; consider `innodb_buffer_pool_size`. | ### Access Setup Create a dedicated MariaDB user with minimal monitoring privileges: ```sql showLineNumbers title="MariaDB monitoring user setup" CREATE USER 'otel_monitor'@'%' IDENTIFIED BY ''; GRANT PROCESS, REPLICATION CLIENT ON *.* TO 'otel_monitor'@'%'; GRANT SELECT ON performance_schema.* TO 'otel_monitor'@'%'; FLUSH PRIVILEGES; ``` **Minimum required permissions:** | Permission | Purpose | | -------------------------------- | ----------------------------------------------------------- | | `PROCESS` | Access to `SHOW GLOBAL STATUS` and `SHOW GLOBAL VARIABLES` | | `REPLICATION CLIENT` | Access to `SHOW REPLICA STATUS` for replication metrics | | `SELECT ON performance_schema.*` | Statement events, table I/O, and lock-wait metrics | No write permissions are needed. The Collector only reads metrics. Ensure `performance_schema` and the slow query log are enabled: ```ini showLineNumbers title="my.cnf" [mysqld] performance_schema = ON slow_query_log = ON long_query_time = 1 ``` Test connectivity with the monitoring user: ```bash showLineNumbers title="Verify access" mariadb -h -P 3306 -u otel_monitor -p \ -e "SELECT version();" ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: mysql: endpoint: ${env:MARIADB_HOST}:3306 username: ${env:MYSQL_USER} password: ${env:MYSQL_PASSWORD} collection_interval: 10s allow_native_passwords: true tls: insecure: true insecure_skip_verify: true metrics: # Disabled by default - enable for full observability mysql.client.network.io: enabled: true mysql.commands: enabled: true mysql.connection.count: enabled: true mysql.connection.errors: enabled: true mysql.joins: enabled: true mysql.query.client.count: enabled: true mysql.query.count: enabled: true mysql.query.slow.count: enabled: true mysql.replica.sql_delay: enabled: true mysql.replica.time_behind_source: enabled: true mysql.statement_event.count: enabled: true mysql.statement_event.wait.time: enabled: true mysql.table.average_row_length: enabled: true mysql.table.lock_wait.read.count: enabled: true mysql.table.lock_wait.read.time: enabled: true mysql.table.lock_wait.write.count: enabled: true mysql.table.lock_wait.write.time: enabled: true mysql.table.rows: enabled: true mysql.table.size: enabled: true mysql.table_open_cache: enabled: true statement_events: {} processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [mysql] processors: [resource, batch] exporters: [otlphttp/b14] ``` `allow_native_passwords: true` lets the receiver authenticate against MariaDB's native password plugin. Leave the TLS block as shown only for an in-cluster or local stack with TLS disabled; against a TLS-enabled server, configure the CA and drop `insecure`. To control metric volume in production, drop the Diagnostic tier with a `filter` processor while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" MARIADB_HOST=localhost MYSQL_USER=otel_monitor MYSQL_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped MariaDB metrics docker logs otel-collector 2>&1 | grep -i "mysql" # Verify MariaDB connectivity and uptime mariadb -h ${MARIADB_HOST} -P 3306 -u otel_monitor -p \ -e "SHOW GLOBAL STATUS LIKE 'Uptime';" ``` ```sql showLineNumbers -- Thread states (mysql.threads) SHOW GLOBAL STATUS LIKE 'Threads_%'; -- InnoDB buffer pool (mysql.buffer_pool.*) SHOW GLOBAL STATUS LIKE 'Innodb_buffer_pool%'; -- Slow queries (mysql.query.slow.count) SHOW GLOBAL STATUS LIKE 'Slow_queries'; ``` ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach MariaDB at the configured endpoint. **Fix**: 1. Verify MariaDB is running: `systemctl status mariadb` or `docker ps | grep mariadb`. 2. Confirm the endpoint address and port (default 3306) in your config. 3. Check `bind-address` in `my.cnf` - set it to `0.0.0.0` if the Collector runs on a separate host. #### Authentication failed **Cause**: Monitoring credentials are wrong, or the user lacks grants. **Fix**: 1. Test credentials directly: `mariadb -h localhost -u otel_monitor -p -e "SELECT 1;"`. 2. Verify the grants: `SHOW GRANTS FOR 'otel_monitor'@'%';`. 3. Confirm `MYSQL_USER` and `MYSQL_PASSWORD` are set, and that `allow_native_passwords: true` is present if the server uses native passwords. #### Statement-event metrics always zero **Cause**: `performance_schema` is disabled, its statement consumers are off, or the digest tables haven't populated yet. **Look at**: the Diagnostic `mysql.statement_event.count` and `mysql.statement_event.wait.time` series - both stay flat at zero until `performance_schema` digests exist. **Fix**: 1. Verify it's enabled: `SHOW VARIABLES LIKE 'performance_schema';`. 2. Check the statement consumers, and enable them if they are off: ```sql showLineNumbers SELECT * FROM performance_schema.setup_consumers WHERE name LIKE 'events_statements%'; UPDATE performance_schema.setup_consumers SET ENABLED = 'YES' WHERE name LIKE 'events_statements%'; ``` #### Table-lock-wait metrics stay flat **Cause**: No contended table-lock waits have occurred. **Look at**: the Diagnostic `mysql.table.lock_wait.read.*` / `.write.*` series - they emit only when sessions actually wait on a table lock, so a quiet server reports nothing here. This is expected, not a misconfiguration. #### Replica metrics missing **Cause**: The server has no replica configured. **Look at**: `mysql.replica.sql_delay` and `mysql.replica.time_behind_source` - these emit only on a server with an active replication channel. **Fix**: No action needed on a standalone server. They surface automatically once replication is configured. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why does this use the MySQL receiver? MariaDB is wire-compatible with MySQL - both use the MySQL protocol for client connections. The Collector's `mysql` receiver works against MariaDB without modification. There is no separate MariaDB receiver. #### Does this work with MariaDB Galera Cluster? Yes. Add a receiver block per node with distinct names: ```yaml receivers: mysql/node1: endpoint: node1:3306 username: ${env:MYSQL_USER} password: ${env:MYSQL_PASSWORD} mysql/node2: endpoint: node2:3306 username: ${env:MYSQL_USER} password: ${env:MYSQL_PASSWORD} ``` Then include both in the pipeline: `receivers: [mysql/node1, mysql/node2]`. #### Does this work with MariaDB running in Kubernetes? Yes. Set `endpoint` to the MariaDB service DNS (e.g., `mariadb.default.svc.cluster.local:3306`) and inject credentials via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### What permissions does the monitoring account need? `PROCESS`, `REPLICATION CLIENT`, and `SELECT` on `performance_schema`. No write access is required - the Collector only reads metrics. #### Where is per-query latency? The receiver exposes counters and gauges, not per-request timing. `mysql.query.slow.count` flags queries over `long_query_time`; for digest breakdowns enable the `mysql.statement_event.*` metrics, which read `performance_schema` digests. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on MariaDB metrics. - [MySQL Monitoring](./mysql.md) - The same receiver against MySQL. - [PostgreSQL Monitoring](./postgres.md) - Alternative relational database. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [MySQL](./mysql.md), [PostgreSQL](./postgres.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; adjust `collection_interval` and `statement_events` limits to your query workload. --- ## Memcached OpenTelemetry Monitoring - Hit Ratio, Evictions, and Collector Setup ## Memcached The OpenTelemetry Collector's `memcachedreceiver` collects 11 metrics from Memcached 1.6+ - cache byte usage and item counts, the operation hit ratio, connection load, CPU, and network throughput. The receiver connects over TCP to the Memcached stats protocol on port 11211; no exporter or sidecar is needed. This guide configures the receiver, verifies connectivity, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Memcached | 1.6 | 1.6.x | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Memcached must be reachable over TCP from the host running the Collector. - No authentication is required - Memcached has no authentication enabled by default and uses network-level access control (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. This surface has **no `up`, no uptime, and no health metric** - those come from the Prometheus receiver, not the native `memcachedreceiver`. Liveness here is the receiver scraping the stats endpoint successfully: when it stops returning data, treat Memcached as unreachable. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `memcached.commands` | Commands executed by `command` (get/set/touch/flush) - the serving throughput KPI. | | `memcached.operation_hit_ratio` | Hit ratio per `operation` (get/increment/decrement) - the cache-efficiency KPI. | | `memcached.current_items` | Items currently stored - working-set size. | | `memcached.connections.current` | Open connections - client load, and the only liveness proxy on this surface. | `memcached.operation_hit_ratio` needs real `get` traffic - both hits and misses - or it reads 0. It is also per-`operation`: it carries `get`, `increment`, and `decrement` series, so the increment/decrement ratios stay 0 until you issue that kind of traffic. That is expected, not a silent metric. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `memcached.bytes` | Bytes currently stored - approaching the memory limit drives evictions. | | `memcached.evictions` | Items evicted under memory pressure - rising means the cache is too small for the working set. | | `memcached.network` | Bytes transferred by `direction` (sent/received) - bandwidth. | | `memcached.connections.total` | Cumulative connections opened - connection churn and connection storms. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. | Metric | What it tells you | |---|---| | `memcached.operations` | get/increment/decrement by `type` (hit/miss) - the detailed breakdown behind the hit ratio. | | `memcached.cpu.usage` | Accumulated CPU seconds by `state` (user/system). | | `memcached.threads` | Worker thread count. | Full metric reference: [OTel Memcached Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/memcachedreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. Memcached exposes no absolute service-level ceilings here, so the alerts are relative to your own baseline. | Metric | Threshold | Why it matters | |---|---|---| | Receiver no data | The `memcached` receiver produces no data for > 1m | No `up`/uptime on this surface - scrape success is liveness. Check the process and the receiver connection. | | `memcached.operation_hit_ratio{operation=get}` | Falling vs baseline | More requests are missing the cache and hitting the origin. Check key TTLs, working-set size, and eviction pressure. | | `rate(memcached.evictions)` | Rising vs baseline | Memory pressure is forcing items out - the cache is too small. Raise the memory limit or review TTLs and value sizes. | | `memcached.bytes` | Approaching the configured memory limit | The cache is filling; evictions follow. Add memory or tune TTLs. | | `memcached.connections.current` | Rising toward `max_connections` | Approaching the connection ceiling - clients will be refused. Raise the limit or pool connections. | ### Access Setup Memcached has no built-in authentication. Access control is handled at the network level - ensure only the Collector host can reach port 11211 (a firewall rule, security group, or container network policy). Verify connectivity from the host that will run the Collector: ```bash showLineNumbers title="Verify Memcached connectivity" echo "stats" | nc localhost 11211 ``` If you use a firewall or container network, confirm the Collector can reach the Memcached host and port before wiring up the receiver. ### Configuration The native `memcachedreceiver` connects over TCP to the Memcached stats protocol. `transport: tcp` must be set explicitly - the receiver defaults to an empty transport and fails to start without it. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: memcached: endpoint: ${env:MEMCACHED_HOST}:11211 # Change to your Memcached address transport: tcp # Required - must be set explicitly collection_interval: 10s metrics: # Cache usage memcached.bytes: enabled: true memcached.current_items: enabled: true memcached.evictions: enabled: true # Commands and operations memcached.commands: enabled: true memcached.operations: enabled: true memcached.operation_hit_ratio: enabled: true # Connections memcached.connections.current: enabled: true memcached.connections.total: enabled: true # Resources memcached.cpu.usage: enabled: true memcached.network: enabled: true memcached.threads: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [memcached] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" MEMCACHED_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for the Memcached receiver docker logs otel-collector 2>&1 | grep -i "memcached" # Verify Memcached is responding echo "stats" | nc localhost 11211 # Check slab allocation echo "stats slabs" | nc localhost 11211 ``` If the hit ratio reads 0, drive some `get` traffic with both hits and misses, then check `get_hits` and `get_misses` in the `stats` output. ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach Memcached at the configured endpoint. **Fix**: 1. Verify Memcached is running: `systemctl status memcached` or `docker ps | grep memcached`. 2. Confirm the endpoint address and port in your config. 3. Check firewall rules if the Collector runs on a separate host. #### Invalid transport type error **Cause**: The `transport` field is missing from the receiver config. **Fix**: Add `transport: tcp` to the receiver configuration. Unlike most receivers, the Memcached receiver requires this field to be set explicitly: ```yaml showLineNumbers title="config/otel-collector.yaml (transport fix)" receivers: memcached: endpoint: localhost:11211 transport: tcp ``` #### Hit ratio always zero **Cause**: No `get` traffic with both hits and misses has reached the cache. **Look at**: `memcached.operations` - the per-`type` (hit/miss) breakdown behind the hit ratio. If the miss series is flat, no traffic is reaching the cache. **Fix**: 1. `memcached.operation_hit_ratio` only populates once the cache serves real `get` traffic - both hits and misses. It stays 0 on an idle cache. 2. Confirm with `echo "stats" | nc localhost 11211` and check the `get_hits` and `get_misses` counters. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Memcached running in Kubernetes? Yes. Set `endpoint` to the Memcached service DNS (e.g., `memcached.default.svc.cluster.local:11211`) and ensure the Collector pod can reach port 11211. The Collector can run as a sidecar or a DaemonSet. #### How do I monitor multiple Memcached instances? Add multiple receiver blocks with distinct names: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: memcached/primary: endpoint: memcached-1:11211 transport: tcp memcached/replica: endpoint: memcached-2:11211 transport: tcp ``` Then include both in the pipeline: `receivers: [memcached/primary, memcached/replica]`. #### Why is `transport: tcp` required? The Memcached receiver defaults to an empty transport value, which causes a startup error. This is a known quirk - always set `transport: tcp` explicitly in the config. #### Can I monitor Memcached with SASL authentication? The OTel Memcached receiver does not support SASL authentication. If your Memcached instance requires SASL, run the Collector on a host with direct network access that does not require authentication, or use a sidecar deployment pattern. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Memcached metrics. - [Redis Monitoring](./redis.md) - The other in-memory cache you may run alongside Memcached. - [MongoDB Monitoring](./mongodb.md) - The backing store Memcached often fronts. - [ElastiCache Monitoring](../infra/aws/elasticache.md) - Managed Redis/Memcached cache monitoring on AWS. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Redis](./redis.md), [MongoDB](./mongodb.md), and other components. --- ## Milvus OpenTelemetry Monitoring - Search Latency, Ingestion Lag, and Collector Setup ## Milvus Milvus serves Prometheus text at `/metrics` on port `9091` with no flag to enable it, and can push OTLP traces to the Collector once tracing is turned on. This guide collects request rate and error rate, search and insert latency, per-collection entity counts, ingestion lag, and the segment and memory pressure a Milvus node actually hits. An instance with collections and traffic declares 347 metric names; the Collector scrapes them with the Prometheus receiver and receives spans on its OTLP receiver, and both pipelines ship to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Milvus | 2.6 | 2.6.23 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Milvus 2.6 is the line where standalone runs as one container, with etcd embedded in the process and data on a local volume. Earlier lines need the full external dependency stack - etcd, MinIO and Pulsar as separate services - which changes both the deployment and the metric surface, since each dependency then exposes its own endpoint to scrape. Milvus 3.0 is not covered by this guide. Before starting: - Port `9091` must be reachable from the host running the Collector. `/metrics` and `/healthz` are served there, always on, with no flag to enable them. - `/metrics` has no authentication. Scrape Milvus on the internal network, or exempt the path at a fronting proxy; it must not be exposed publicly. - Port `9091` is separate from `19530`, which carries both the gRPC API and the REST v2 API. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). :::warning Coming from a pre-2.6 deployment? On 2.6 the standalone container runs etcd in-process and stores data locally, so the separate etcd, MinIO and Pulsar services go away - along with the scrape jobs and alerts pointed at them. Full notes: [Updates & Upgrades](#updates--upgrades). ::: ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. **gRPC and REST are instrumented differently, and only gRPC gets an error rate.** This is the single most important fact about the surface. Over gRPC, `milvus_proxy_req_count` carries `function_name` (`Search`, `Insert`, and so on), a `status` label with `success`, `fail` and `total`, and a `cause` label on failures. The same requests over the REST v2 API move only `milvus_proxy_restful_api_req_count`, whose only labels are `path`, `node_id` and `le` - no status, no HTTP code. **A REST-only deployment has no error-rate metric at all.** Every official Milvus SDK defaults to gRPC, so most deployments are on the instrumented path; check which one yours is on by looking for `function_name="Search"` rows on `milvus_proxy_req_count` while search traffic is running. If your clients are on REST v2, instrument the client side to get error signals. **`status` is not a partition: `total` = `success` + `fail`.** `milvus_proxy_req_count` emits `success`, `fail` and `total` as three separate series, and `total` is already the sum of the other two. Summing across the `status` label therefore double-counts every request. The error ratio is `status="fail"` over `status="total"`: ```text title="Error ratio" rate(milvus_proxy_req_count{status="fail"}[10m]) / rate(milvus_proxy_req_count{status="total"}[10m]) ``` never `fail` over the sum of the label values. **Failed requests never reach the per-collection latency histograms.** `milvus_proxy_collection_sq_latency` and `milvus_proxy_collection_mutation_latency` count successful work only. That is what you want for a latency SLO and wrong for a request count: a panel built on their `_count` series silently undercounts by every failure. Use them for percentiles, and `milvus_proxy_req_count` for rate. **`collection_name` is an unbounded label driven by client input.** It is a real label on 19 metric families, and it takes whatever the client sent, including names of collections that do not exist. Those label values never expire, so a client looping over generated names inflates the metrics backend without limit. Treat `metric_relabel_configs` on `collection_name` as the default posture for any Milvus scrape exposed to untrusted or generated collection names - see [Configuration](#configuration) for the block. **The surface is very large before any data exists.** An idle instance with zero collections declares 219 metric names and 6370 series; two small collections take it to 347 names and 9231 series. About 75% of the raw series are histogram buckets, which the Prometheus receiver collapses into one data point each - 1827 OTel data points under load. Expect the volume, watch `scrape_samples_scraped` as the cardinality alarm, and note that the Diagnostic families are the bulk of it (the write-ahead log alone is 54 names). **There is no single metric prefix, and 31 names have no prefix at all.** Loaded, the exposition is `milvus_` (238 names), `internal_` (40), `go_` (29), `process_` (9), and 31 bare index-engine names - `build_latency`, `exec_latency`, `search_latency`, `load_latency`, `queue_latency`, `cache_hit_cnt`, `io_cnt`, `diskann_*`, `hnsw_*`, `ivf_*`. Those are generic enough to collide with anything else in a shared metrics backend, and no prefix filter can gate them. Namespace them at the Collector with a `metricstransform` processor if your backend is shared. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the Milvus metrics endpoint responded. | | `milvus_num_node` | Live nodes by `role_name`. In standalone all four roles read 1; a role dropping to 0 is a fault. | | `milvus_proxy_req_count` | Requests by `function_name`, `status` and `collection_name`. Request rate and error rate. gRPC traffic only. | | `milvus_proxy_sq_latency` | Search and query latency by `query_type`. The read SLO. | | `milvus_proxy_mutation_latency` | Insert and delete latency by `msg_type`. The write SLO. | `role_name` is not a general dimension. It appears on `milvus_num_node` only, with the four standalone roles (`proxy`, `mixcoord`, `querynode`, `datanode`); the rest of the surface is not sliceable by role. "Which role is slow" has to be answered from the subsystem in the metric name instead - `milvus_querynode_*`, `milvus_datacoord_*`, and so on. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `milvus_proxy_collection_sq_latency`, `_collection_mutation_latency` | Read and write latency split by `collection_name`. Successful work only. | | `milvus_proxy_insert_vectors_count` | Vectors inserted per collection. Ingest volume. | | `milvus_proxy_restful_api_req_count`, `_req_latency`, `_receive_bytes`, `_send_bytes` | REST v2 requests by `path`. No status label, so no error rate. | | `milvus_proxy_cache_hit_count` | Metadata cache hits and misses by `cache_name` and `cache_state`. A rising miss ratio adds a round trip to every request. | | `milvus_proxy_limiter_rate` | Rate limit currently applied, by `collection_id` and `msg_type`. A drop means Milvus is throttling clients. | | `milvus_datanode_consume_tt_lag_ms` | Ingestion time-tick lag per collection. Rising lag means writes are accepted but not yet queryable. | | `milvus_querynode_entity_num`, `_entity_size` | Entities and bytes loaded per collection by `segment_state` (`Growing`, `Sealed`). Data inventory. | | `milvus_datacoord_stored_rows_num`, `_stored_binlog_size`, `_segment_num`, `_segment_binlog_file_count` | Persisted rows, bytes and segment counts. Growth and compaction health. | | `milvus_querycoord_collection_num`, `_partition_num`, `_load_latency`, `_load_req` | Loaded collections and partitions, and how long loading takes. | | `milvus_querycoord_current_target_checkpoint_unix_seconds` | Query-side checkpoint. Distance from now is read staleness. | | `milvus_rootcoord_ddl_req_count`, `_ddl_req_latency`, `_ddl_req_latency_in_queue` | DDL rate and latency. Carries a `status="fail"` value. | | `milvus_rootcoord_disk_quota` | Configured disk quota by `scope`. A config echo, not usage - see below. | | `milvus_jemalloc_allocated_bytes`, `_active_bytes`, `_mapped_bytes`, `_fragmentation_bytes`, `_metadata_bytes`, `_overhead_bytes` | C++ allocator views. `_fragmentation_bytes` growing while allocated is flat is the memory-pressure signal. | | `process_resident_memory_bytes`, `process_open_fds`, `process_max_fds`, `process_cpu_seconds_total` | Process ceilings. `open_fds` against `max_fds` is directly alertable. | | `milvus_msg_queue_consumer_num` | Consumers on the internal message queue. | | `scrape_samples_scraped` | Series count for this scrape job. On Milvus this is the cardinality alarm - `collection_name` takes client-supplied values. | The collection appears under two different label keys. `collection_name` is used on the proxy and querynode families; `collection_id`, a numeric snowflake ID, is used on `milvus_datanode_consume_*`, `milvus_proxy_limiter_rate` and the datacoord families. No series maps one to the other, so a dashboard cannot join the two groups without an external lookup - resolve the ID through the SDK's `describe_collection` and carry it in your own dashboard variables. `milvus_rootcoord_disk_quota` reports what is configured, not what is used. On a default install it reads `1.7976931348623157e+308` - max float64, meaning unlimited - for all three of `scope="cluster"`, `"db"` and `"collection"`. Alerting on it is meaningless until you set a quota. Shard, replica and balance families under `milvus_querycoord_*` exist on a standalone node but stay at their single-node values. They become meaningful on a cluster. #### Diagnostic - for investigation and tuning Subsystem internals and runtime detail. Reach for these during an incident or a capacity review; they are also where most of the series count lives. | Group | Metrics | When you reach for it | |---|---|---| | Query node internals | `milvus_querynode_segment_access_*`, `_disk_cache_*` (59 names) | Segment access waits, disk-cache evictions and load durations. Where a slow query node is diagnosed. | | Write-ahead log | `milvus_wal_*` (54 names), by `channel_name` and `interceptor_name` | Write-path internals. The largest single contributor to series count. | | Streaming service | `milvus_streaming_*`, `milvus_streamingcoord_*` (18 names) | Streaming service internals. | | Flowgraph consumption | `milvus_datanode_consume_bytes`, `_consume_msg`, `_msg_rows_count`, `_fg_buffer_size` | Detail behind the ingestion-lag gauge. | | Runtime and bridge | `milvus_meta_*`, `milvus_cgo_*`, `milvus_thread_*`, `milvus_logging_*`, `milvus_runtime_*` | Metadata store, cgo bridge, thread pools, log volume. | | Chunk cache | `internal_cache_*` (17 names) | Cell lifetimes, evictions and watermarks. | | Storage and mmap | `internal_storage_*` (10 names), `internal_mmap_*`, `internal_cgo_*`, `internal_json_*`, `internal_core_search_latency` | Object-storage requests, memory maps, JSON indexing, core search latency. Carries `status="fail"`. | | Index engine (unprefixed) | `build_latency`, `exec_latency`, `search_latency`, `load_latency`, `queue_latency`, `cache_hit_cnt`, `io_cnt`, `bitset_ratio`, `graph_search_cnt`, `bf_search_cnt`, `ivf_search_cnt`, `re_search_cnt`, `quant_compute_cnt`, `raw_compute_cnt`, `search_topk`, `search_level`, `range_search_latency`, `ann_iterator_init_latency`, `diskann_*`, `hnsw_*`, `filter_*`, `search_emb_list_*` (31 names) | Which index type ran, how far it searched, how much it filtered. Index tuning rather than operations - and the names are bare. | | Build info | `milvus_build_info` | Info gauge; labels `version`, `git_commit`, `built`. | | Go runtime | `go_*` (29 names) | `go_memstats_heap_inuse_bytes` and `go_goroutines` are the useful two. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Prometheus receiver scrape health. `scrape_samples_scraped` sits in the Operational tier above. | `channel_name` is bounded: `rootCoord.dmlChannelNum` fixes it at 16 values from startup and it does not grow with collections. It is the second-largest label by series count but it is not a cardinality risk. The embedded etcd does not leak its own metrics - there are no `etcd_` series anywhere, even though etcd runs in-process. Standalone exposes only Milvus's own metrics. Full metric list: run `curl -s http://localhost:9091/metrics` against your Milvus node. #### What the traces show Milvus emits OTLP spans covering both user requests and internal work, and the split matters: at `sampleFraction: 1` a single user search produces roughly 100 spans across 95 distinct span names, most of them internal. The largest span name is `milvus.proto.rootcoord.RootCoord/AllocTimestamp`; several (`SetRates`, `GetProxyMetrics`, `GetDataDistribution`) fire on timers and appear with no user traffic at all. Treat `sampleFraction: 1` as a debugging window, not a steady-state setting. The instrumentation scopes are `segcore` and `knowhere` from the C++ core, `proxy`, `datanode`, `querynode`, `rootcoord` and `querycoord` from the Go services, and `otelgrpc` for the gRPC layer. Search spans carry bare, non-namespaced attribute keys - `nq`, `topk`, `k`, `dim`, `rows`, `metric_type`, `search_type`, `result_count`. Span kinds are set correctly (`Server`, `Client`, `Internal`). Three things to know before you build searches on this: - **Span status is never set.** Every span reports `Unset`, including failed operations, so errors cannot be found by span status. On gRPC spans, `rpc.grpc.status_code` is the only error signal in traces. - **No span carries a collection name.** Traces cannot be grouped or filtered by collection. - **gRPC spans use pre-1.21 semantic conventions for the peer address.** `net.sock.peer.addr` and `net.sock.peer.port`, where current semconv is `network.peer.address` and `network.peer.port`. Span processors and dashboards keyed on the current names will not match these spans. ### Key Alerts to Configure Milvus's absolute latency, lag and segment figures depend on index type, vector dimensionality, collection size and hardware, so every row below is relative to your own trailing baseline or read against a limit exposed on the same surface. Tune to your workload. | Alert | Expression | Why it matters | |---|---|---| | Milvus down | `up == 0` for 2m | The metrics endpoint stopped answering; check the container and port 9091. | | A role is gone | `milvus_num_node < 1` by `role_name` | In standalone all four roles must be present; on a cluster this counts nodes. | | Request errors | `rate(milvus_proxy_req_count{status="fail"}[10m])` over `rate(milvus_proxy_req_count{status="total"}[10m])`, rising against baseline | Clients are failing. gRPC traffic only. Never sum across `status` - `total` already includes `fail`. | | Search latency | a high quantile of `milvus_proxy_sq_latency{query_type="search"}` against its own baseline | Search is slowing. Successful searches only. | | Insert latency | a high quantile of `milvus_proxy_mutation_latency{msg_type="insert"}` against its own baseline | The write SLO. | | Ingestion lag | `milvus_datanode_consume_tt_lag_ms` rising against baseline | Writes are accepted but not yet queryable. | | Read staleness | now minus `milvus_querycoord_current_target_checkpoint_unix_seconds` rising | Queries are serving from an old checkpoint. | | Client throttling | `milvus_proxy_limiter_rate` dropping below its steady value | Milvus is rate-limiting clients; usually a quota or memory backstop. | | Metadata cache misses | `milvus_proxy_cache_hit_count{cache_state="miss"}` share rising against baseline | Every miss adds a metadata round trip to a request. | | Memory fragmentation | `milvus_jemalloc_fragmentation_bytes` rising while `milvus_jemalloc_allocated_bytes` is flat | The allocator is holding memory it cannot reuse. | | File descriptor exhaustion | `process_open_fds / process_max_fds` high | Both sides of the ratio are on this surface; raise the process fd limit. | | Segment count growth | `milvus_datacoord_segment_num` rising with no compaction | Small-segment proliferation degrades search. | | Series count growth | `scrape_samples_scraped` rising against baseline | The cardinality alarm; usually `collection_name` taking new client-supplied values. | The two latency rows are Prometheus histograms - there is no ready-made percentile series to threshold. Compute it in the alert rule, for example `histogram_quantile(0.99, rate(milvus_proxy_sq_latency_bucket{query_type="search"}[5m]))`. No alert here covers REST v2 error rate, because no metric does. ### Access Setup There is nothing to turn on for metrics. Milvus serves `/metrics` on port `9091` by default, with no flag and no credentials. What you do have to decide is the cardinality posture for `collection_name`, and, if you want traces, to edit the Milvus config - both are covered below. The official image is multi-arch, so it runs native on arm64 as well as amd64, and it ships `curl` (upstream's own healthcheck uses it). The health endpoint is `/healthz` on `9091`. ```yaml showLineNumbers title="compose.yaml (excerpt)" services: milvus: image: milvusdb/milvus:v2.6.23 command: ["milvus", "run", "standalone"] security_opt: - seccomp:unconfined # required by the C++ core's memory setup environment: ETCD_USE_EMBED: "true" ETCD_DATA_DIR: /var/lib/milvus/etcd ETCD_CONFIG_PATH: /milvus/configs/embedEtcd.yaml COMMON_STORAGETYPE: local DEPLOY_MODE: STANDALONE volumes: - ./config/embedEtcd.yaml:/milvus/configs/embedEtcd.yaml:ro - ./config/user.yaml:/milvus/configs/user.yaml:ro # trace settings - milvus-data:/var/lib/milvus ports: - "19530:19530" # gRPC and REST v2 - "9091:9091" # /metrics and /healthz healthcheck: test: ["CMD", "curl", "-f", "http://localhost:9091/healthz"] interval: 10s timeout: 10s retries: 20 start_period: 60s volumes: milvus-data: ``` Confirm the endpoint answers: ```bash showLineNumbers title="Verify access" # Health curl -s -o /dev/null -w '%{http_code}\n' http://localhost:9091/healthz # Metrics endpoint curl -s http://localhost:9091/metrics | grep '^milvus_num_node' ``` #### Turn on trace export Tracing is off by default and turning it on takes three changes to the shipped `milvus.yaml`, not one: `trace.exporter` is `noop`, `trace.sampleFraction` is `0`, and `trace.otlp.secure` is `true`. Override all three in `user.yaml`: ```yaml showLineNumbers title="config/user.yaml (Milvus)" # overrides milvus.yaml; tracing is noop with zero sampling by default trace: exporter: otlp # default noop - no spans leave the process sampleFraction: 0.01 # default 0 - start low, raise to debug otlp: endpoint: otel-collector:4317 method: grpc secure: false # default true; keep true for a TLS Collector ``` Spans arrive on the Collector's `otlp` receiver, already in the [Configuration](#configuration) block below: ```yaml showLineNumbers title="config/otel-collector.yaml (excerpt)" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: milvus scrape_interval: 15s static_configs: - targets: # host:port Milvus serves /metrics on - ${env:MILVUS_HOST}:9091 metric_relabel_configs: # collection_name takes whatever clients send, including # names that do not exist; drop it from every family - regex: collection_name action: labeldrop otlp: protocols: grpc: endpoint: 0.0.0.0:4317 # Milvus pushes spans here processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] traces: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Prometheus receiver keeps everything `/metrics` exposes. There is no per-metric enable list, so new series appear after a Milvus upgrade with no Collector change. Scout authentication for the `otlphttp/b14` exporter is covered in [Scout Exporter](../collector-setup/scout-exporter.md). #### Controlling `collection_name` cardinality The `labeldrop` rule above removes `collection_name` everywhere, which is the safe default when clients can name collections freely. If you dashboard a small, known set of collections, keep the label on those families and drop it from the rest: ```yaml showLineNumbers title="config/otel-collector.yaml (keep-list variant)" metric_relabel_configs: # mark the families that keep collection_name - source_labels: [__name__] regex: milvus_(proxy_collection_sq_latency|proxy_collection_mutation_latency|proxy_insert_vectors_count|querynode_entity_num|querynode_entity_size).* target_label: __tmp_keep_collection replacement: "yes" # everywhere else, blank the label (an empty value removes it) - source_labels: [__tmp_keep_collection] regex: "" target_label: collection_name replacement: "" - regex: __tmp_keep_collection action: labeldrop ``` Either way, watch `scrape_samples_scraped` after the change: it is the series count for this job, and it is what tells you whether the posture is holding. #### Namespacing the unprefixed index-engine names 31 metric names arrive with no prefix at all (`build_latency`, `search_latency`, `cache_hit_cnt`, `io_cnt` and so on). In a shared metrics backend they collide with any other job that uses the same generic words. Rename them with a `metricstransform` processor, not with `metric_relabel_configs`. Relabelling renames the raw scrape series, which still carry their `_bucket`, `_sum` and `_count` suffixes, so a pattern written against the metric name misses every histogram among these 31 - and renaming at the receiver drops the type, unit and description, which the Collector warns about on startup. The processor runs after the receiver has reassembled the histograms, so it matches the metric name and keeps the type: ```yaml showLineNumbers title="config/otel-collector.yaml (namespacing)" processors: metricstransform: transforms: # $${1} escapes the capture group so the Collector does not # treat it as an environment variable - include: ^(build_latency|exec_latency|search_latency|load_latency|queue_latency|cache_hit_cnt|io_cnt|bitset_ratio|graph_search_cnt|bf_search_cnt|ivf_search_cnt|re_search_cnt|quant_compute_cnt|raw_compute_cnt|search_topk|search_level|range_search_latency|ann_iterator_init_latency|diskann_.*|hnsw_.*|filter_.*|search_emb_list_.*)$ match_type: regexp action: update new_name: milvus_knowhere_$${1} ``` Add it to the metrics pipeline ahead of `batch`: ```yaml showLineNumbers title="config/otel-collector.yaml (pipeline)" service: pipelines: metrics: receivers: [prometheus] processors: [resource, metricstransform, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" MILVUS_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm the request counter exists on the endpoint curl -s http://localhost:9091/metrics | grep '^milvus_proxy_req_count' # Check Collector logs for scraped Milvus metrics docker logs otel-collector 2>&1 | grep "milvus_" ``` An idle instance with no collections still exposes 219 metric names, so a large scrape is not evidence that anything is being used. Confirm real traffic instead: `milvus_proxy_req_count` with `function_name="Search"` and `status="total"` moving, and `milvus_querynode_entity_num` non-zero for a loaded collection. In Scout, query `milvus_proxy_sq_latency` by `query_type` to confirm the read-path histograms arrived. Spans only appear after `sampleFraction` is non-zero **and** traffic has run. If both are true and nothing arrives, check the Collector logs for OTLP receive errors and see [Troubleshooting](#no-spans-are-arriving). ### Troubleshooting #### No error-rate data despite failing requests **Cause**: The clients are on the REST v2 API, which has no `status` label. `milvus_proxy_restful_api_req_count` counts requests by `path` only. **Look at**: `milvus_proxy_req_count` - if there are no `function_name="Search"` or `"Insert"` rows while search traffic is running, the traffic is REST. **Fix**: 1. Move clients to a gRPC SDK if you want a server-side error rate. Every official Milvus SDK defaults to gRPC. 2. Otherwise instrument the client side for error signals, and keep this surface for node health, inventory and resource ceilings, which are interface-independent. #### The error rate reads about twice what it should **Cause**: The query summed across the `status` label. `total` is already `success` + `fail`, so summing counts every request twice. **Fix**: 1. Compute the ratio as `status="fail"` over `status="total"`. 2. Never use `sum by (...) (milvus_proxy_req_count)` without pinning `status` to a single value. #### A request-rate panel undercounts **Cause**: The panel is built on `milvus_proxy_collection_sq_latency` or `milvus_proxy_collection_mutation_latency`. Those histograms record successful work only, so failures never reach them. **Fix**: 1. Use `milvus_proxy_req_count` for rate. 2. Keep the per-collection histograms for percentiles and per-collection latency comparisons. #### Search latency is up and the proxy metrics do not explain it **Cause**: the proxy histogram measures the whole request. When it rises with a flat request rate, the time is being spent on the query node - usually waiting on segment access or reloading from the disk cache. **Look at**: the Diagnostic tier's query-node internals, `milvus_querynode_segment_access_*` and `_disk_cache_*`, for access waits, cache evictions and load durations. `internal_cache_*` covers the chunk cache behind them, and `internal_storage_op_count` says whether the node is going back to object storage. **Fix**: give the query node enough memory to hold the working set, or reduce it - `milvus_querynode_entity_num` by `segment_state` shows how much is loaded. These families are the largest group in the Diagnostic tier, so re-enable them for the investigation rather than scraping them continuously. #### Metric names collide with another service in the backend **Cause**: 31 index-engine names arrive with no prefix - `build_latency`, `search_latency`, `cache_hit_cnt`, `io_cnt` and the rest. No prefix filter can gate them. **Look at**: the Diagnostic index-engine group; grep the exposition for `^search_latency` to see the bare names. **Fix**: Namespace them at the Collector with the `metricstransform` rename in [Configuration](#namespacing-the-unprefixed-index-engine-names). Do not try this with `metric_relabel_configs`: it operates on the raw scrape series, so it misses every histogram among these names and strips the type off the ones it does match. #### The series count climbs with no new deployments **Cause**: `collection_name` is taking client-supplied values. It is a label on 19 families and accepts names of collections that do not exist; those values never expire. **Look at**: `scrape_samples_scraped` - a steady rise against its own baseline with unchanged traffic is the signal. **Fix**: 1. Apply the `collection_name` `metric_relabel_configs` block from [Configuration](#controlling-collection_name-cardinality). 2. If the count is still climbing, check the Diagnostic families - the write-ahead log group alone is 54 names. #### A dashboard cannot join two metric families **Cause**: The collection is keyed differently in different places - `collection_name` on the proxy and querynode families, `collection_id` (a numeric snowflake ID) on `milvus_datanode_consume_*`, `milvus_proxy_limiter_rate` and the datacoord families. **Fix**: 1. Resolve the ID with the SDK's `describe_collection` and carry the mapping in your dashboard variables. No series on this surface maps one key to the other. 2. Do not join the two groups directly; the join silently returns nothing. #### No spans are arriving **Cause**: One of the three trace settings is still at its default - most often `trace.otlp.secure: true` against a plaintext Collector endpoint. **Look at**: the Milvus logs for OTLP exporter connection errors, and the Collector logs for OTLP receive activity. **Fix**: 1. Confirm all three are set: `exporter: otlp`, a non-zero `sampleFraction`, and `secure: false` for a plaintext Collector. 2. Confirm `user.yaml` is actually mounted at `/milvus/configs/user.yaml` and Milvus was restarted after the edit. 3. Send real traffic - spans exist only for work that runs. #### Trace volume is overwhelming the backend **Cause**: `sampleFraction` is at or near 1. Roughly 100 spans are produced per user search, and timer-driven internal spans arrive even with no user traffic. **Fix**: 1. Lower `sampleFraction` to a small value for steady state and raise it only for a debugging window. 2. Restart Milvus for the change to take effect. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter, and that the traces pipeline exists if you enabled tracing. ### Updates & Upgrades #### Milvus version changes - **Pre-2.6 → 2.6**: standalone runs as a single container - etcd embedded in the process, data on a local volume, no MinIO and no Pulsar. Remove those services from your deployment, and remove the scrape jobs and alerts pointed at them; their metrics disappear with them, and the embedded etcd exposes no `etcd_` series of its own. Everything in this guide is served from Milvus's own `:9091/metrics`. _(breaking for the deployment and for any dependency-scoped dashboards)_ - **3.0**: Milvus 3.0 exists as a separate line and is not covered by this guide. Its metric surface has not been confirmed against these tables; verify names against your own instance before reusing dashboards or alerts there. #### Collector / receiver changes - This guide uses the **prometheus receiver** for metrics and the **otlp receiver** for traces. Neither has a receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. New Milvus series are picked up with no Collector change, because there is no per-metric enable list. _(no breaking change)_ ### FAQ #### Does this cover REST v2 traffic? Partially. `milvus_proxy_restful_api_req_count` and its latency and byte siblings count REST requests by `path`, so you get request rate and latency. You do not get an error rate: the only labels are `path`, `node_id` and `le` - no status and no HTTP code - and REST requests do not increment `milvus_proxy_req_count` for `Search` or `Insert`. For a server-side error rate, use a gRPC SDK; otherwise instrument the client. #### Why is `total` not the sum of my `status` values? It is the sum, and that is the point. `milvus_proxy_req_count` emits `success`, `fail` and `total` as three separate series, with `total` already equal to `success` + `fail`. Adding the three together double-counts every request. Take the error ratio as `status="fail"` over `status="total"`. #### Should I turn on tracing? Yes for a debugging window, at a low sample fraction; no at `sampleFraction: 1` in steady state. At full sampling Milvus produces roughly 100 spans per user search across 95 span names, dominated by internal work such as `RootCoord/AllocTimestamp`, plus timer-driven spans that arrive with no user traffic. Also know what traces will not answer: span status is always `Unset`, so errors have to be read from `rpc.grpc.status_code`, and no span carries a collection name. #### How do I monitor a distributed Milvus cluster? Each node serves its own `/metrics` on port 9091, so add a scrape target per node and let `node_id` separate them. The shard, replica and balance families under `milvus_querycoord_*` only become meaningful there; on a standalone node they sit at their single-node values. Distributed behaviour is not covered here - confirm those series against your own cluster before alerting on them. #### How do I keep the series count under control? Two levers. Apply `metric_relabel_configs` to `collection_name`, which is the only unbounded label on the surface. Then watch `scrape_samples_scraped` to confirm the result and to catch future growth. For where the series sit: the write-ahead log group, `milvus_wal_*`, is 54 metric names and the largest single contributor to the series count. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Milvus metrics. - [Qdrant Monitoring](./qdrant.md) - Vector store with a far smaller metric surface; useful contrast when sizing scrape cost. - [Weaviate Monitoring](./weaviate.md) - Vector store with a comparable two-signal surface and the same split between REST and gRPC accounting. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Qdrant](./qdrant.md), [vLLM](./vllm.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your traffic and retention needs, and settle the `collection_name` relabel posture before opening the endpoint to client-named collections. --- ## MinIO OpenTelemetry Monitoring - S3 Request Rate, Cluster Capacity, and Drive Health ## MinIO MinIO serves Prometheus-format metrics at `/minio/metrics/v3` (the current v3 metrics API) on the S3 API port `:9000`. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint directly, collecting 100+ metrics across S3 request rate and errors, cluster capacity and drive/erasure-set health, per-drive performance, and host and process resources. This guide configures the receiver, sets up metrics authentication, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | -------------------------------------- | | MinIO | release exposing the metrics endpoint | current release (v3 metrics API) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The MinIO S3 API port (`9000`) must be reachable from the host running the Collector. - Metrics are token-gated by default - either set `MINIO_PROMETHEUS_AUTH_TYPE=public` or scrape with a bearer token (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The metric names are MinIO's native v3 exposition (`minio__*`), reproduced as the endpoint serves them. A few surface notes shape how you read this set: - **`up` is the liveness signal here.** The `prometheus` receiver emits `up = 1` when the `/minio/metrics/v3` endpoint responds. That is the monitoring-is-alive signal; `minio_cluster_health_drives_online_count` (against `minio_cluster_health_drives_count`) is the erasure-coding durability signal. - **Use the v3 endpoint.** `/minio/metrics/v3` is the current metrics API and replaces the deprecated `/minio/v2/metrics/{cluster,node,bucket}` endpoints (still present in the release, but not for new deployments). The default v3 endpoint returns the `minio_api_*`, `minio_system_*`, `minio_cluster_*`, and `minio_scanner_*` families. Per-bucket, replication, notification, ILM, and resource detail live at dedicated v3 sub-paths (for example `/minio/metrics/v3/bucket/api` and `/minio/metrics/v3/replication`) - add a scrape job per sub-path when you need that detail. - **Metrics are token-gated by default.** Either set `MINIO_PROMETHEUS_AUTH_TYPE=public` or scrape with a bearer token from `mc admin prometheus generate`. A 403 with no token is expected otherwise. - **Erasure-coding health is the storage-specific signal.** `minio_cluster_erasure_set_read_health` / `_write_health` report whether each set can still serve reads and writes. Below write quorum the set goes read-only; below read quorum it goes offline. - **Counts scale with topology.** Node, drive, and erasure-set counts are `1` on a single-node single-drive deployment. The `minio_system_drive_*` and `minio_cluster_erasure_set_*` families expand (one series per drive, one per set) in a distributed deployment. - **`go_*` is MinIO's own Go runtime**, not a storage signal. Prefer MinIO's own `minio_system_process_*` and filter `go_*` with a `minio_.*|up` keep rule. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape liveness - `1` when the MinIO metrics endpoint responded. The monitoring-is-alive signal on this surface. | | `minio_api_requests_total` | S3 API requests handled, labeled by API name - headline request throughput. | | `minio_api_requests_errors_total` | S3 API requests that returned an error - headline error signal. | | `minio_cluster_health_capacity_usable_free_bytes` | Usable free capacity after erasure-coding overhead - running out is a top object-store incident. | | `minio_cluster_health_drives_online_count` | Drives currently online (against `minio_cluster_health_drives_count`) - the erasure-coding durability signal. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | S3 errors and latency | `minio_api_requests_4xx_errors_total`, `minio_api_requests_incoming_total`, `minio_api_requests_ttfb_seconds_distribution` | Client-error volume, arriving load, and the time-to-first-byte latency SLO per API. | | S3 traffic | `minio_api_requests_traffic_received_bytes`, `minio_api_requests_traffic_sent_bytes` | Inbound (uploads) and outbound (downloads) S3 bytes. | | Cluster health | `minio_cluster_health_drives_count`, `minio_cluster_health_nodes_online_count`, `minio_cluster_health_capacity_usable_total_bytes`, `minio_cluster_health_capacity_raw_free_bytes` / `_raw_total_bytes` | Total drives, online nodes, and usable/raw capacity - the denominators for the durability and capacity ratios. | | Erasure-set health | `minio_cluster_erasure_set_health`, `minio_cluster_erasure_set_read_health`, `minio_cluster_erasure_set_write_health`, `minio_cluster_erasure_set_online_drives_count`, `minio_cluster_erasure_set_read_quorum` / `_write_quorum` | Whether each set can serve reads/writes and how close it is to losing quorum. | | Per-drive health | `minio_system_drive_health`, `minio_system_drive_used_bytes` / `_free_bytes` / `_total_bytes`, `minio_system_drive_free_inodes`, `minio_system_drive_api_latency_micros`, `minio_system_drive_perc_util`, `minio_system_drive_writes_await` / `_writes_per_sec` / `_writes_kb_per_sec` | Per-drive health, capacity, inodes, latency, and IO - a slow or full drive localizes a degraded cluster. | | Host pressure | `minio_system_cpu_load_perc`, `minio_system_cpu_avg_iowait`, `minio_system_memory_used_perc`, `minio_system_memory_available` | Host CPU load, storage-bound iowait, and memory pressure. | | MinIO process | `minio_system_process_resident_memory_bytes`, `minio_system_process_cpu_total_seconds`, `minio_system_process_file_descriptor_open_total`, `minio_system_process_file_descriptor_limit_total` | MinIO's own RSS, CPU time, and open file descriptors against the FD limit. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. They are grouped, not enumerated - representative members are named. | Group | Representative metrics | When you reach for it | |---|---|---| | CPU and memory breakdown | `minio_system_cpu_load`, `minio_system_cpu_avg_idle` / `_system` / `_user`, `minio_system_memory_total` / `_free` / `_cache` / `_buffers` | Decomposing host CPU and memory beyond the headline percentages. | | Per-drive counts and inodes | `minio_system_drive_count`, `minio_system_drive_online_count`, `minio_system_drive_total_inodes` / `_used_inodes` | Per-node drive visibility and inode accounting. | | MinIO process internals | `minio_system_process_io_rchar_bytes` / `_wchar_bytes` / `_write_bytes`, `minio_system_process_syscall_read_total` / `_write_total`, `minio_system_process_go_routine_total`, `minio_system_process_virtual_memory_bytes`, `minio_system_process_uptime_seconds` | Process IO, syscalls, goroutines, and virtual memory during a CPU or memory investigation. | | Bucket-usage staleness | `minio_cluster_usage_objects_buckets_count`, `minio_cluster_usage_objects_since_last_update_seconds`, `minio_cluster_usage_buckets_since_last_update_seconds` | Whether the object/bucket usage figures are fresh. | | IAM sync | `minio_cluster_iam_sync_successes`, `minio_cluster_iam_last_sync_duration_millis`, `minio_cluster_iam_since_last_sync_millis` | IAM replication health on a configured cluster. | | Object scanner | `minio_scanner_bucket_scans_started` / `_finished`, `minio_scanner_last_activity_seconds` | Whether the background object scanner is running. | | Runtime and scrape meta | `go_*`, `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_series_added` | MinIO's Go runtime and the receiver-side scrape meta; filter `go_*` with a `minio_.*\|up` keep rule. | Some families are not on the default v3 endpoint or read `0` until the feature is exercised: per-bucket (`minio_bucket_*`), replication, notification, ILM, KMS, and audit families live at dedicated v3 sub-paths and require those endpoints to be scraped; multi-node internode-network and healing metrics populate only in a distributed deployment. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. The state and ratio alerts read MinIO's own counts, totals, and limits - they are not invented absolutes. The rate and latency alerts are relative to your own baseline. Tune all of them to your workload. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The metrics endpoint stopped responding - check the MinIO process and the API port. | | `minio_cluster_health_drives_online_count` | `< minio_cluster_health_drives_count` | One or more drives dropped - durability is reduced; replace the drive and let MinIO heal. | | `minio_cluster_erasure_set_write_health` | `== 0` | The set can no longer accept writes - restore drives before it goes read-only or offline. | | `minio_cluster_health_capacity_usable_free_bytes / minio_cluster_health_capacity_usable_total_bytes` | `< 0.1` | The cluster is running out of usable space - expand or reclaim. | | `rate(minio_api_requests_errors_total)` | Rising vs baseline | Server-side S3 failures - check drive health, quorum, and recent changes. | | `minio_api_requests_ttfb_seconds_distribution` | p99 rising vs baseline | Requests are slow - correlate with `minio_system_drive_api_latency_micros` and iowait. | | `minio_system_drive_free_inodes` | Approaching `0` | A drive is out of inodes - new objects will fail even with free bytes. | | `minio_system_process_file_descriptor_open_total / minio_system_process_file_descriptor_limit_total` | `> 0.9` | MinIO is near its FD limit - raise the ulimit. | ### Access Setup MinIO exposes Prometheus metrics on the S3 API port, but they are token-gated by default. Pick one of the two options below. #### Option 1: Public metrics (no token) Set the environment variable before starting MinIO so the metrics endpoint serves without auth: ```bash showLineNumbers title="Public metrics" export MINIO_PROMETHEUS_AUTH_TYPE=public ``` #### Option 2: Bearer token (recommended for shared networks) Generate a scrape token with the MinIO client: ```bash showLineNumbers title="Generate bearer token" # Set up the mc alias mc alias set myminio http://localhost:9000 minioadmin minioadmin # Generate a Prometheus scrape config with a bearer token mc admin prometheus generate myminio ``` This outputs a scrape snippet containing the bearer token; use that token in the Collector config below. Verify the endpoint responds: ```bash showLineNumbers title="Verify access" # Check MinIO is live curl -s http://localhost:9000/minio/health/live # Verify the v3 metrics endpoint (use a token here if not public) curl -s http://localhost:9000/minio/metrics/v3 | head -20 ``` The default v3 endpoint returns the `minio_api_*`, `minio_system_*`, `minio_cluster_*`, and `minio_scanner_*` families. Per-bucket, replication, and resource detail live at sub-paths such as `/minio/metrics/v3/bucket/api` and `/minio/metrics/v3/replication`. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: minio scrape_interval: 10s metrics_path: /minio/metrics/v3 static_configs: - targets: - ${env:MINIO_HOST}:9000 # Change to your MinIO address metric_relabel_configs: # Scope to the MinIO namespace; drop go_* and scrape_* noise - source_labels: [__name__] regex: 'minio_.*|up' action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` If metrics are token-gated (Option 2 above), add a bearer token to the scrape job instead of running the endpoint public: ```yaml showLineNumbers title="config/otel-collector.yaml (bearer token)" receivers: prometheus: config: scrape_configs: - job_name: minio scrape_interval: 10s metrics_path: /minio/metrics/v3 authorization: type: Bearer credentials: ${env:MINIO_METRICS_TOKEN} static_configs: - targets: - ${env:MINIO_HOST}:9000 ``` The `metric_relabel_configs` keep filter scopes the pipeline to the MinIO namespace - it keeps `minio_*` and the `up` liveness series and drops the `go_*` runtime and `scrape_*` meta. #### Environment Variables ```bash showLineNumbers title=".env" MINIO_HOST=localhost MINIO_METRICS_TOKEN=your_bearer_token # Only if using Option 2 ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for the MinIO scrape docker logs otel-collector 2>&1 | grep -i "minio" # Verify MinIO is live curl -s http://localhost:9000/minio/health/live # Check the v3 metrics endpoint directly curl -s http://localhost:9000/minio/metrics/v3 \ | grep minio_cluster_health_capacity_usable_free_bytes ``` ### Troubleshooting #### 403 Forbidden on the metrics endpoint **Cause**: Metrics are token-gated and no bearer token was supplied. **Fix**: 1. Generate a token: `mc admin prometheus generate `, then add it as `authorization: { type: Bearer, credentials: ${env:MINIO_METRICS_TOKEN} }` on the scrape job. 2. Or set `MINIO_PROMETHEUS_AUTH_TYPE=public` on the MinIO server for tokenless metrics. #### Wrong or empty metrics endpoint **Cause**: Scraping a deprecated v2 path, or expecting per-bucket / replication detail on the default v3 endpoint. **Fix**: 1. Use `/minio/metrics/v3`, not the deprecated `/minio/v2/metrics/{cluster,node,bucket}` paths. 2. The default v3 endpoint returns the `minio_api_*`, `minio_system_*`, `minio_cluster_*`, and `minio_scanner_*` families only. Per-bucket, replication, notification, ILM, and resource detail live at dedicated v3 sub-paths - add a scrape job per sub-path (for example `/minio/metrics/v3/bucket/api`) when you need that detail. #### Connection refused on port 9000 **Cause**: The Collector cannot reach MinIO at the configured address. **Fix**: 1. Verify MinIO is running: `docker ps | grep minio` or `mc admin info `. 2. Confirm the S3 API port responds: `curl http://localhost:9000/minio/health/live`. 3. Check firewall rules if the Collector runs on a separate host. #### Slow requests with no obvious cause **Cause**: A slow drive or storage-bound saturation is dragging the cluster. **Look at**: the Diagnostic and per-drive series - `minio_system_drive_api_latency_micros` (a slow drive localizes a slow cluster), `minio_system_drive_perc_util` / `minio_system_drive_writes_await`, and `minio_system_cpu_avg_iowait` for storage-bound CPU. **Fix**: 1. Correlate the slow drive's latency with `minio_api_requests_ttfb_seconds_distribution`. 2. Replace or rebalance the drive if its utilization stays pinned. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with MinIO running in Kubernetes? Yes. Set `targets` to the MinIO service DNS (for example `minio.minio.svc.cluster.local:9000`). For token-gated metrics, store the bearer token in a Kubernetes secret and reference it as the scrape `credentials`; or set `MINIO_PROMETHEUS_AUTH_TYPE=public` on the StatefulSet for tokenless metrics. The Collector can run as a sidecar or a Deployment. #### How do I monitor a distributed MinIO cluster? Scrape each MinIO node - add every node's `:9000` to the scrape targets. The capacity, erasure-set, and per-drive series expand in a distributed deployment: `minio_system_drive_*` produces one series per drive and `minio_cluster_erasure_set_*` one series per set, so you see per-drive and per-set health rather than a single `1`. #### Should I use the v2 or v3 metrics endpoint? Use v3 (`/minio/metrics/v3`). The `/minio/v2/metrics/{cluster,node,bucket}` endpoints are deprecated - still present in the release, but not for new deployments. #### Do I need a bearer token, or can I scrape without auth? Metrics are token-gated by default. Set `MINIO_PROMETHEUS_AUTH_TYPE=public` for tokenless scraping (handy on internal networks), or generate a token with `mc admin prometheus generate` and supply it as the scrape `authorization` credentials. #### Where are per-bucket and replication metrics? They are not on the default v3 endpoint. Per-bucket, replication, notification, ILM, and resource detail live at dedicated v3 sub-paths (for example `/minio/metrics/v3/bucket/api` and `/minio/metrics/v3/replication`). Add a scrape job per sub-path - and configure the corresponding feature - when you need that detail. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on MinIO metrics. - [PostgreSQL Monitoring](./postgres.md) - A common backing store alongside object storage. - [Redis Monitoring](./redis.md) - A common cache in the same data tier. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Scope the scrape with `metric_relabel_configs` keep filters, and add a scrape job per `/minio/metrics/v3` sub-path (bucket, replication, internode) when you need that detail. --- ## MongoDB OpenTelemetry Monitoring - Operation Latency, Cache Pressure, and Collector Setup ## MongoDB The OpenTelemetry Collector's `mongodbreceiver` connects directly to MongoDB 4.0+ and reads `serverStatus`, `dbStats`, and `$indexStats` to collect 40+ metrics - operation throughput and latency, WiredTiger cache hit/miss, connection-pool use, lock and page-fault pressure, and per-database sizing. This guide sets up a monitoring user, configures the receiver, and ships metrics to base14 Scout. The receiver talks to MongoDB itself, so there is no `up` target-health metric (that one is Prometheus-receiver-only). On this path the liveness signal is `mongodb.health` (1 = healthy) together with the receiver scraping successfully. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | -------------------- | | MongoDB | 4.0 | 6.0+ (8.0.26) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - MongoDB must be accessible from the host running the Collector. - A monitoring user with the `clusterMonitor` role (see Access Setup). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Many `mongodbreceiver` metrics are disabled by default; the [Configuration](#configuration) block enables the curated set below. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `mongodb.health` | Server health status (1 = healthy). On this path it is the liveness signal - there is no `up`; "healthy" plus a successful scrape means the server is reachable. | | `mongodb.operation.count` | Operations by type (insert/query/update/delete/getmore/command) - the throughput KPI. | | `mongodb.operation.latency.time` | Operation latency by type (read/write/command), in microseconds - the latency KPI. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `mongodb.active.reads`, `mongodb.active.writes` | Concurrent active read / write operations - load and concurrency. | | `mongodb.connection.count` | Connections by `type` (active/available/current) - connection-pool saturation. | | `mongodb.cache.operations` | WiredTiger cache hits vs misses - rising misses mean the working set exceeds cache. | | `mongodb.global_lock.time` | Time held in the global lock - write contention. | | `mongodb.page_faults` | Page faults - memory pressure, the working set spilling to disk. | | `mongodb.memory.usage` | Memory in use by `type` (resident/virtual). | | `mongodb.cursor.count`, `mongodb.cursor.timeout.count` | Open cursors and timed-out cursors - cursor leaks or slow clients. | | `mongodb.uptime` | Time since server start - restart detection. | | `mongodb.operation.repl.count` | Replicated operations by type (replica sets; zero on a standalone). | This is operation throughput and latency, not RED's full triad. The receiver exposes **no error-rate metric** - there is no query-error counter in `serverStatus`. Errors live in the MongoDB log / profiler, not in these metrics. Likewise `mongodb.operation.repl.count` is a replicated-op *count*, **not replication lag**: a replica-lag gauge needs a separate source. #### Diagnostic - for investigation and tuning Higher cardinality and several per-`database` families; reach for these during an incident or capacity review. | Group | Metrics | When you reach for it | |---|---|---| | Document ops | `mongodb.document.operation.count` | Documents inserted/updated/deleted/returned. | | Network | `mongodb.network.io.receive`, `mongodb.network.io.transmit`, `mongodb.network.request.count` | Bytes in/out and request count. | | Index stats | `mongodb.index.access.count`, `mongodb.index.count`, `mongodb.index.size` | Index usage (per collection), index count and size. | | Per-database inventory and sizing | `mongodb.collection.count`, `mongodb.database.count`, `mongodb.object.count`, `mongodb.data.size`, `mongodb.storage.size` | Inventory and sizing per `database`. | | Locks | `mongodb.lock.acquire.count` | Lock acquisitions by type/mode. | | WiredTiger internals | `mongodb.wtcache.bytes.read`, `mongodb.flushes.rate`, `mongodb.operation.time` | Bytes read into cache, checkpoint flush rate, total operation time. | | Per-second op rates | `mongodb.{commands,queries,inserts,updates,deletes,getmores}.rate` | Pre-computed per-second rates (convenience; overlap `mongodb.operation.count`). | | Per-second replicated-op rates | `mongodb.repl_{commands,queries,inserts,updates,deletes,getmores}_per_sec` | Per-second replicated-op rates (replica sets). | | Sessions | `mongodb.session.count` | Active server sessions. | Full metric reference: [OTel MongoDB Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/mongodbreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. These are relative to your own baseline, not fixed absolutes - tune them to your workload. | Alert | Threshold | Why it matters | |---|---|---| | MongoDB unhealthy | `mongodb.health == 0`, or the `mongodb` receiver producing no data for > 1m | Server unhealthy or unreachable. There is no `up`, so health plus scrape success is the liveness check. Inspect the process and the receiver connection. | | Operation latency regression | `mongodb.operation.latency.time` (read/write) rising vs baseline | Operations are slowing. Check cache misses, locks, page faults, and slow queries. | | Connection saturation | `mongodb.connection.count{type=current}` approaching `{type=available}` | Connection pool near exhaustion; new clients get refused. Raise limits or pool better. | | Cache pressure | `mongodb.cache.operations` miss rate rising vs baseline | The working set exceeds the WiredTiger cache; reads spill to disk. Add RAM or reduce the working set. | | Lock contention | `rate(mongodb.global_lock.time)` rising vs baseline | Global-lock time climbing - write contention. Investigate hot collections and long-running operations. | | Memory pressure | `rate(mongodb.page_faults)` rising vs baseline | Faulting to disk - memory-bound. Add RAM or reduce the working set. | | Cursor timeouts | `rate(mongodb.cursor.timeout.count)` rising | Cursors timing out - leaked or slow-draining cursors. Check application cursor handling. | ### Access Setup Create a dedicated MongoDB user with the `clusterMonitor` role: ```javascript showLineNumbers title="mongodb monitoring user setup" use admin db.createUser({ user: "${MONGO_USER}", pwd: "${MONGO_PASSWORD}", roles: [ { role: "clusterMonitor", db: "admin" }, ] }) ``` **Minimum required permissions:** - `clusterMonitor` on `admin` - required for `serverStatus`, `replSetGetStatus`, and database statistics. - No write permissions are needed. The Collector only reads metrics; it does not modify MongoDB data. Test connectivity with the monitoring user: ```bash showLineNumbers title="Verify access" mongosh "mongodb://${MONGO_USER}:${MONGO_PASSWORD}@localhost:27017/"\ "admin?authSource=admin" --eval "db.serverStatus().ok" ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: mongodb: hosts: - endpoint: localhost:27017 # Change to your MongoDB host username: ${env:MONGO_USER} password: ${env:MONGO_PASSWORD} collection_interval: 60s timeout: 10s # TLS Configuration tls: insecure: true insecure_skip_verify: true direct_connection: true # false for replica sets metrics: # Disabled by default - enable for full observability mongodb.uptime: enabled: true mongodb.active.reads: enabled: true mongodb.active.writes: enabled: true mongodb.commands.rate: enabled: true mongodb.deletes.rate: enabled: true mongodb.flushes.rate: enabled: true mongodb.getmores.rate: enabled: true mongodb.health: enabled: true mongodb.inserts.rate: enabled: true mongodb.lock.acquire.count: enabled: true mongodb.lock.acquire.time: enabled: true mongodb.lock.acquire.wait_count: enabled: true mongodb.lock.deadlock.count: enabled: true mongodb.operation.latency.time: enabled: true mongodb.operation.repl.count: enabled: true mongodb.page_faults: enabled: true mongodb.queries.rate: enabled: true mongodb.repl_commands_per_sec: enabled: true mongodb.repl_deletes_per_sec: enabled: true mongodb.repl_getmores_per_sec: enabled: true mongodb.repl_inserts_per_sec: enabled: true mongodb.repl_queries_per_sec: enabled: true mongodb.repl_updates_per_sec: enabled: true mongodb.updates.rate: enabled: true mongodb.wtcache.bytes.read: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [mongodb] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" MONGO_USER=otel_monitor MONGO_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for a successful MongoDB connection docker logs otel-collector 2>&1 | grep -i "mongodb" # Verify MongoDB server status with the monitoring user mongosh "mongodb://${MONGO_USER}:${MONGO_PASSWORD}@localhost:27017/"\ "admin?authSource=admin" --eval "db.serverStatus().ok" ``` ### Troubleshooting #### Connection refused **Cause**: Collector cannot reach MongoDB at the configured endpoint. **Fix**: 1. Verify MongoDB is running: `systemctl status mongod` or `docker ps | grep mongo`. 2. Confirm the endpoint address and port (default 27017) in your config. 3. Check `bindIp` in `mongod.conf` - change to `0.0.0.0` if the Collector runs on a separate host. #### Authentication failed **Cause**: Monitoring credentials are incorrect or the user lacks permissions. **Fix**: 1. Test credentials directly: `mongosh "mongodb://user:pass@localhost:27017/admin" --eval "db.runCommand({ping:1})"`. 2. Verify the user has the `clusterMonitor` role: `db.getUser("otel_monitor")`. 3. Check the `MONGO_USER` and `MONGO_PASSWORD` environment variables. #### `(Unauthorized) ... $indexStats` error in the Collector logs **Cause**: The receiver runs `$indexStats` per collection. On the `admin` database's internal `system.*` collections this returns `(Unauthorized)` and the Collector logs a per-scrape error. **Fix**: This warning is expected and safe to ignore. `mongodb.index.access.count` is still collected for your user collections - the message only concerns the admin internal namespaces. #### Replication metrics showing zero **Cause**: MongoDB is running as a standalone instance without a replica set. **Look at**: `mongodb.operation.repl.count` and the `mongodb.repl_*_per_sec` family - on a standalone they emit zero. **Fix**: 1. Replication metrics require a replica-set configuration; on a standalone, zero is expected. 2. Set `direct_connection: false` when monitoring a replica set. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with MongoDB running in Kubernetes? Yes. Set `endpoint` to the MongoDB service DNS (e.g., `mongodb.default.svc.cluster.local:27017`) and inject credentials via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### How do I monitor a MongoDB replica set? Set `direct_connection: false` and point at the primary. For per-node metrics, add a receiver block per member: ```yaml receivers: mongodb/primary: hosts: - endpoint: mongo-1:27017 direct_connection: true mongodb/secondary: hosts: - endpoint: mongo-2:27017 direct_connection: true ``` Then include both in the pipeline: `receivers: [mongodb/primary, mongodb/secondary]`. #### What permissions does the monitoring account need? The `clusterMonitor` role on the `admin` database, read-only. No write access is required - the Collector only reads metrics. #### Why is there no error-rate metric? `serverStatus` does not expose a query-error counter, so the receiver has no error-rate metric. Operation throughput (`mongodb.operation.count`) and latency (`mongodb.operation.latency.time`) are available, but error detail comes from the MongoDB log or the database profiler. #### Why are lock deadlock counts always zero? MongoDB uses optimistic concurrency control with WiredTiger, so deadlocks are rare under normal workloads. On a standalone the lock timing and deadlock fields (`mongodb.lock.acquire.time`, `mongodb.lock.acquire.wait_count`, `mongodb.lock.deadlock.count`) emit no series at all even when enabled; non-zero values indicate contention worth investigating. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on MongoDB metrics. - [PostgreSQL Monitoring](./postgres.md) - Relational database alternative. - [MySQL Monitoring](./mysql.md) - Relational database alternative. - [Redis Monitoring](./redis.md) - In-memory data store companion. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [MySQL](./mysql.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Adjust `collection_interval` to balance metric freshness against load on MongoDB and the Collector. --- ## MySQL OpenTelemetry Monitoring - Query Performance, Buffer Pool, and Collector Setup ## MySQL The OpenTelemetry Collector's `mysqlreceiver` connects directly to MySQL and reads `SHOW GLOBAL STATUS`, global variables, and `performance_schema`, collecting 40+ metrics across queries, connections, the InnoDB buffer pool, locks, and replication when the optional metric set is enabled. This guide sets up a read-only monitoring user, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ------------------ | | MySQL | 8.0 | 8.0+ (8.4.10) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - MySQL must be accessible from the host running the Collector. - A read-only monitoring account with the required permissions (see [Access Setup](#access-setup)). - `performance_schema` enabled for statement-level and lock metrics. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `mysqlreceiver` connects directly to MySQL, so a few things differ from exporter-fronted components: - **No `up` and no health metric.** Liveness is the receiver scraping successfully plus `mysql.uptime` advancing - a reset of `mysql.uptime` means a restart. There is no `up` series (that is Prometheus-receiver only) and no health gauge. - **No single aggregate query-latency metric.** Latency detail is per-statement-digest via `mysql.statement_event.wait.time`, which requires `performance_schema`. There is no one "query latency" gauge. - **Replication lag is available but enabled-but-silent off a replica.** `mysql.replica.time_behind_source` and `mysql.replica.sql_delay` emit no series on a standalone server or a primary; they populate only when MySQL runs as a replica. Many `mysqlreceiver` metrics are disabled by default - the [Configuration](#configuration) `metrics:` block enables the optional set (query counts, slow queries, connections, statement events, table lock waits, per-table sizing, replica lag, X Protocol, and more). The tiers below reflect the enabled set. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `mysql.uptime` | Seconds since server start - liveness and restart detection (no `up`/health on this path; a reset means a restart). | | `mysql.query.count` | Total queries (Questions) - the throughput KPI. | | `mysql.query.slow.count` | Queries over `long_query_time` - the query-quality KPI. | | `mysql.threads` | Threads by `kind` (running/connected/cached/created); `running` is the saturation signal. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `mysql.connection.count` / `mysql.connection.errors` | Connections made and connection errors by type - connection saturation and failures. | | `mysql.buffer_pool.usage` / `mysql.buffer_pool.operations` | InnoDB buffer-pool bytes by state and pool operations; disk reads vs read-requests is cache efficiency. | | `mysql.row_locks` | InnoDB row-lock waits and time - write contention. | | `mysql.table.lock_wait.read.time` / `mysql.table.lock_wait.write.time` | Table lock-wait time (read/write) - table-level contention. | | `mysql.handlers` | Handler operations by `kind` (e.g. `read_rnd_next` = full scans). | | `mysql.joins` | Join types performed; full joins point at missing indexes. | | `mysql.tmp_resources` | Temp tables and files created - queries spilling to disk. | | `mysql.sorts` | Sort operations; merge passes mean sort-buffer pressure. | | `mysql.statement_event.count` / `mysql.statement_event.wait.time` | Per-digest statement counts and wait time - the closest signal to query latency (needs `performance_schema`). | | `mysql.replica.time_behind_source` / `mysql.replica.sql_delay` | Replication lag and configured SQL delay (replicas only; silent on a standalone or primary). | #### Diagnostic - for investigation and tuning Higher cardinality; many of these are per-`table` series. Reach for them during an incident or a capacity review. | Group | Metrics | When you reach for it | |---|---|---| | Command / operation rates | `mysql.commands`, `mysql.operations`, `mysql.row_operations`, `mysql.page_operations` | Command mix and InnoDB operation/row/page breakdowns. | | Per-table / per-index I/O | `mysql.table.io.wait.count` / `.time`, `mysql.index.io.wait.count` / `.time` | Localising I/O wait to a table or index. | | Per-table sizing | `mysql.table.rows`, `mysql.table.size`, `mysql.table.average_row_length` | Per-`table` row count, size, and average row length. | | Buffer-pool internals | `mysql.buffer_pool.data_pages`, `.limit`, `.page_flushes`, `.pages` | InnoDB buffer-pool internals beyond the headline usage. | | Cache / open resources | `mysql.table_open_cache`, `mysql.opened_resources` | Table-open cache hits/misses and opened tables/files. | | Lock / redo-log / doublewrite internals | `mysql.locks`, `mysql.log_operations`, `mysql.double_writes` | Table locks (immediate/waited), redo-log ops, InnoDB doublewrites. | | Statements / client | `mysql.prepared_statements`, `mysql.query.client.count` | Prepared-statement ops and client query count. | | X Protocol / network | `mysql.mysqlx_connections`, `mysql.mysqlx_worker_threads`, `mysql.client.network.io` | X Protocol connections/threads and client network I/O. | Full metric reference: [OTel MySQL Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/mysqlreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. MySQL workloads vary widely, so these are relative-to-baseline starting points - tune them to your traffic. | Metric | Threshold | Why it matters | |---|---|---| | MySQL unreachable | The `mysql` receiver producing no data for > 1m, or `mysql.uptime` resetting | No `up`/health on this path - scrape success plus uptime are liveness. Check the process and the receiver connection. | | `rate(mysql.query.slow.count)` | Rising vs baseline | More queries exceeding `long_query_time` - check the slow log, indexes, and query plans. | | `mysql.threads{kind=running}` | Rising vs baseline | Running threads spiking - contention or overload. Correlate with locks and slow queries. | | `rate(mysql.connection.errors)` | Rising vs baseline | Connections failing - check `max_connections`, auth, and network limits. | | `mysql.buffer_pool.operations` (disk reads) | Rising vs read-requests | The working set exceeds the InnoDB buffer pool and reads spill to disk. Add RAM or size the pool. | | `rate(mysql.row_locks)` | Rising vs baseline | InnoDB row-lock waits climbing - write contention on hot rows. Investigate transactions. | | `mysql.replica.time_behind_source` | Rising (replicas) | The replica is falling behind the source. Check the replica I/O and SQL threads and load. | ### Access Setup Create a dedicated MySQL user with minimal monitoring privileges: ```sql showLineNumbers title="mysql monitoring user setup" CREATE USER 'otel_monitor'@'%' IDENTIFIED BY ''; GRANT PROCESS, REPLICATION CLIENT ON *.* TO 'otel_monitor'@'%'; GRANT SELECT ON performance_schema.* TO 'otel_monitor'@'%'; FLUSH PRIVILEGES; ``` Use a plain `IDENTIFIED BY`, which takes the default `caching_sha2_password` auth. Do not use `IDENTIFIED WITH mysql_native_password` - that plugin is not loaded by default on MySQL 8.4. **Minimum required permissions:** | Permission | Purpose | | -------------------------------- | ---------------------------------------------------------- | | `PROCESS` | Access to `SHOW GLOBAL STATUS` and `SHOW GLOBAL VARIABLES`. | | `REPLICATION CLIENT` | Access to `SHOW REPLICA STATUS` for replication metrics. | | `SELECT ON performance_schema.*` | Statement events, table I/O, and lock metrics. | No write permissions are needed. Ensure `performance_schema` and the slow query log are enabled: ```ini showLineNumbers title="my.cnf" [mysqld] performance_schema = ON slow_query_log = ON long_query_time = 1 ``` Test connectivity with the monitoring user: ```bash showLineNumbers title="Verify access" mysql -h -P 3306 -u otel_monitor -p -e "SELECT version();" ``` ### Configuration Many `mysqlreceiver` metrics are disabled by default, so the `metrics:` block below is required to get the full surface. The `statement_events` block bounds the per-digest statement query that backs `mysql.statement_event.*`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: mysql: endpoint: :3306 # Change to your MySQL address username: ${env:MYSQL_USER} password: ${env:MYSQL_PASSWORD} collection_interval: 10s allow_native_passwords: true tls: insecure: true insecure_skip_verify: true metrics: # Disabled by default - enable for full observability mysql.client.network.io: enabled: true mysql.commands: enabled: true mysql.connection.count: enabled: true mysql.connection.errors: enabled: true mysql.joins: enabled: true mysql.mysqlx_worker_threads: enabled: true mysql.query.client.count: enabled: true mysql.query.count: enabled: true mysql.query.slow.count: enabled: true mysql.replica.sql_delay: enabled: true mysql.replica.time_behind_source: enabled: true mysql.statement_event.count: enabled: true mysql.statement_event.wait.time: enabled: true mysql.table.average_row_length: enabled: true mysql.table.lock_wait.read.count: enabled: true mysql.table.lock_wait.read.time: enabled: true mysql.table.lock_wait.write.count: enabled: true mysql.table.lock_wait.write.time: enabled: true mysql.table.rows: enabled: true mysql.table.size: enabled: true mysql.table_open_cache: enabled: true statement_events: digest_text_limit: 120 time_limit: 24h limit: 250 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [mysql] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" MYSQL_USER=otel_monitor MYSQL_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for a successful MySQL connection docker logs otel-collector 2>&1 | grep -i "mysql" # Verify MySQL connectivity and that uptime is advancing mysql -h -P 3306 -u otel_monitor -p \ -e "SHOW GLOBAL STATUS LIKE 'Uptime';" ``` ```sql showLineNumbers -- Check thread state SHOW GLOBAL STATUS LIKE 'Threads_%'; -- Check the InnoDB buffer pool SHOW GLOBAL STATUS LIKE 'Innodb_buffer_pool%'; -- Check slow queries SHOW GLOBAL STATUS LIKE 'Slow_queries'; ``` ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach MySQL at the configured endpoint. **Fix**: 1. Verify MySQL is running: `systemctl status mysql` or `docker ps | grep mysql`. 2. Confirm the endpoint address and port (default 3306) in your config. 3. Check `bind-address` in `my.cnf` - change to `0.0.0.0` if the Collector runs on a separate host. #### Authentication failed **Cause**: Monitoring credentials are incorrect or the user lacks permissions. **Fix**: 1. Test credentials directly: `mysql -h localhost -u otel_monitor -p -e "SELECT 1;"`. 2. Verify the user has the required grants: `SHOW GRANTS FOR 'otel_monitor'@'%';`. 3. Check the `MYSQL_USER` and `MYSQL_PASSWORD` environment variables. #### Statement event metrics always zero **Cause**: `performance_schema` is disabled or statement instrumentation is not active, so the per-digest signals stay empty. **Look at**: `mysql.statement_event.count` and `mysql.statement_event.wait.time` - both stay at zero when `performance_schema` is off. **Fix**: 1. Verify `performance_schema` is enabled: `SHOW VARIABLES LIKE 'performance_schema';`. 2. Check statement instrumentation: `SELECT * FROM performance_schema.setup_consumers WHERE name LIKE 'events_statements%';`. 3. Enable consumers if needed: `UPDATE performance_schema.setup_consumers SET ENABLED = 'YES'` `WHERE name LIKE 'events_statements%';`. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with MySQL running in Kubernetes? Yes. Set `endpoint` to the MySQL service DNS (e.g., `mysql.default.svc.cluster.local:3306`) and inject credentials via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### How do I monitor multiple MySQL instances? Add multiple receiver blocks with distinct names: ```yaml receivers: mysql/primary: endpoint: primary:3306 username: ${env:MYSQL_USER} password: ${env:MYSQL_PASSWORD} mysql/replica: endpoint: replica:3306 username: ${env:MYSQL_USER} password: ${env:MYSQL_PASSWORD} ``` Then include both in the pipeline: `receivers: [mysql/primary, mysql/replica]`. #### What permissions does the monitoring account need? `PROCESS`, `REPLICATION CLIENT`, and `SELECT` on `performance_schema`. No write access is required - the Collector only reads metrics, it does not modify MySQL data. #### Why are replication metrics showing zero? `mysql.replica.time_behind_source` and `mysql.replica.sql_delay` require MySQL to be configured as a replica. On a standalone instance or a primary, they report nothing - this is expected behavior. #### Why is there no single query-latency metric? The `mysqlreceiver` does not expose one aggregate latency gauge. Latency detail is per statement digest via `mysql.statement_event.wait.time`, which requires `performance_schema`. Aggregate by digest to find the slowest statement shapes. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on MySQL metrics. - [PostgreSQL Monitoring](./postgres.md) - Another relational database on the same receiver pattern. - [MongoDB Monitoring](./mongodb.md) - Document-database monitoring. - [Redis Monitoring](./redis.md) - In-memory cache and data store. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [MongoDB](./mongodb.md), and [Redis](./redis.md). - **Fine-tune Collection**: Adjust `collection_interval` and the `statement_events` limits to your query workload. --- ## NATS OpenTelemetry Monitoring - Message Throughput, Slow Consumers, and Collector Setup ## NATS NATS serves JSON monitoring data at its HTTP port (`:8222`). The `prometheus-nats-exporter` sidecar converts that into Prometheus text on `:7777`, and the OpenTelemetry Collector's `prometheus` receiver scrapes the exporter, collecting 80+ metrics from NATS 2.0+ across message throughput, client connections, slow consumers, JetStream storage, and server resources. This guide configures the exporter and receiver and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ------------------------ | ------- | ----------- | | NATS Server | 2.0 | 2.10+ | | Prometheus NATS Exporter | 0.12.0 | 0.15.0+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - NATS must be running with the HTTP monitoring port (`8222`) enabled. - JetStream must be enabled (`-js`) if you want the `jetstream_*` metrics. - The `prometheus-nats-exporter` must be deployed alongside the server, one per NATS node, with its port (`7777`) reachable from the host running the Collector. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things shape this surface, and they matter for every tier below: - **The exporter sidecar is mandatory.** NATS exposes its monitoring data as JSON at `:8222`, which the `prometheus` receiver cannot parse. The `prometheus-nats-exporter` converts it to Prometheus text - run one per NATS node. - **`up` is the liveness signal here.** Unlike the native-receiver components, NATS has a real `up` series: the `prometheus` receiver emits `up` = 1 when the exporter scrape succeeds. Note that `up` tracks *exporter* reachability; the `gnatsd_*` values are only fresh while the exporter can reach NATS at `:8222`. - **Everything is exposed as a Prometheus gauge.** The exporter re-reads the monitoring data each scrape and publishes even cumulative server counters - `gnatsd_varz_in_msgs`, `gnatsd_varz_out_msgs`, `gnatsd_varz_total_connections` - as gauges carrying the running total. Derive throughput with `rate()` or deltas, and expect a reset to 0 on a server restart. - **JetStream metrics need `-jsz=all` on the exporter and `-js` on the server.** The `jetstream_*` family and the `gnatsd_varz_jetstream_stats_*` series are absent otherwise. - **The `gnatsd_` prefix is legacy** - from when the server binary was `gnatsd`. The exporter keeps it for dashboard and alert compatibility. #### Core - is it up, moving messages, and keeping clients fed | Metric | What it tells you | |---|---| | `up` | Scrape liveness - 1 = the NATS exporter responded. The liveness signal on this surface. | | `gnatsd_varz_in_msgs`, `gnatsd_varz_out_msgs` | Messages received / sent - the headline broker throughput. Cumulative gauges; use `rate()` for msgs/sec. | | `gnatsd_varz_connections` | Current client connections - load. | | `gnatsd_varz_slow_consumers` | Clients or routes that fell behind and had messages dropped. NATS's signature health signal; non-zero means back-pressure. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Bandwidth | `gnatsd_varz_in_bytes`, `gnatsd_varz_out_bytes` | Bytes in / out (cumulative gauges) - throughput in bytes. | | Connections | `gnatsd_varz_subscriptions`, `gnatsd_varz_total_connections` | Active subscriptions; connections since start (a reconnect-storm / churn signal). | | Server resources | `gnatsd_varz_mem`, `gnatsd_varz_cpu` | Process RSS and CPU - memory and CPU saturation. | | Clustering | `gnatsd_varz_routes`, `gnatsd_routez_num_routes`, `gnatsd_varz_leafnodes` | Cluster routes and leaf-node connections; a missing route signals a partition. | | JetStream storage | `gnatsd_varz_jetstream_stats_storage`, `gnatsd_varz_jetstream_stats_memory` | JetStream bytes on disk / in memory - saturate against the configured max. | | JetStream API | `gnatsd_varz_jetstream_stats_api_errors`, `jetstream_server_total_messages` | API errors (alert when climbing); messages stored across all streams. | | Consumer lag | `jetstream_consumer_num_pending`, `jetstream_consumer_num_ack_pending`, `jetstream_consumer_num_redelivered` | Per-consumer lag: undelivered, awaiting-ack, and redelivered (processing-failure) messages. | | Slow-consumer breakdown | `gnatsd_varz_slow_consumer_stats_*` (by connection type: clients / routes / gateways / leafs) | Where the back-pressure is coming from. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. | Group | Representative metrics | When you reach for it | |---|---|---| | Per-connection drill-down | `gnatsd_connz_in_msgs`, `gnatsd_connz_out_msgs`, `gnatsd_connz_subscriptions`, `gnatsd_connz_pending_bytes`, `gnatsd_connz_num_connections` | Find the specific connection behind a slow consumer or a pending-bytes spike. Reads 0 when no client is connected at scrape time. | | Per-stream JetStream internals | `jetstream_stream_total_messages`, `jetstream_stream_total_bytes`, `jetstream_stream_consumer_count`, `jetstream_stream_first_seq`, `jetstream_stream_last_seq` | Stream depth, sequence range, and per-stream limits during a backlog. | | Per-consumer internals | `jetstream_consumer_delivered_stream_seq`, `jetstream_consumer_ack_floor_stream_seq`, `jetstream_consumer_num_waiting` | Delivery / ack sequence position when diagnosing a stuck consumer. | | Account / server capacity | `jetstream_account_storage_used`, `jetstream_server_total_streams`, `jetstream_server_total_consumers` | JetStream account and server-wide capacity accounting. | | Static config constants | `gnatsd_varz_max_connections`, `gnatsd_varz_max_payload`, `gnatsd_varz_ping_interval` (and the rest of the `gnatsd_varz_*` config values) | Context for a limit breach - what the server is configured to allow. | | Server identity | `gnatsd_varz_version`, `gnatsd_varz_server_id` | Confirm which server / version a series came from. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped` | Receiver-side scrape health, not from NATS. | Full metric list: run `curl -s http://localhost:7777/metrics` against the exporter. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Threshold | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The exporter scrape failed, or NATS is down behind it. Check the exporter and the NATS monitoring port. | | `gnatsd_varz_slow_consumers` | `> 0` | Clients or routes are falling behind and messages are being dropped. Increase client buffers or add consumers; inspect `connz?sort=pending`. | | `gnatsd_varz_jetstream_stats_storage / gnatsd_varz_jetstream_config_max_storage` | `> 0.85` | Streams start rejecting writes at the configured limit - add storage or tighten stream retention. | | `rate(gnatsd_varz_jetstream_stats_api_errors)` | `> 0` | JetStream operations are failing - inspect stream / consumer config and the server logs. | | `jetstream_consumer_num_pending` | Rising vs baseline | A consumer is not keeping up with producers - scale the consumer or check its processing. | | `gnatsd_varz_mem` | Rising toward the host limit | The NATS process is approaching memory pressure - check message backlog and connections. | | `gnatsd_varz_routes` | Below the expected peer count | A cluster peer is disconnected - quorum / clustering is degraded. Check the peer and network. | The storage alert is a ratio against the server's own configured limit, and the rest are read states or relative-to-baseline - so they hold regardless of your host size. Set absolute byte thresholds only against your own provisioned capacity. ### Access Setup NATS does not expose Prometheus metrics natively. Enable the HTTP monitoring port, then run the `prometheus-nats-exporter` as a sidecar that reads it. #### 1. Enable NATS monitoring Start NATS with the HTTP monitoring port enabled (add `-js` for JetStream): ```bash showLineNumbers title="Enable monitoring" # Command-line flags nats-server -m 8222 -js # Or in nats-server.conf # http_port: 8222 # jetstream: enabled ``` Verify the monitoring endpoint: ```bash showLineNumbers title="Verify NATS" # Health endpoint curl -s http://localhost:8222/healthz # Server stats curl -s http://localhost:8222/varz | head -20 ``` The monitoring port is unauthenticated by default - no credentials are needed for the exporter to read it. In production, restrict access to it at the network layer. #### 2. Deploy the Prometheus NATS Exporter The exporter converts the NATS JSON monitoring endpoints into Prometheus-format metrics. Pass the flags for the endpoints you want; `-jsz=all` is required for JetStream metrics: ```bash showLineNumbers title="Docker exporter" docker run -p 7777:7777 \ natsio/prometheus-nats-exporter:latest \ -varz -connz -routez -jsz=all \ http://nats:8222 ``` Flags control which endpoints are scraped: - `-varz` - server statistics (CPU, memory, messages, connections). - `-connz` - per-connection details. - `-routez` - cluster route metrics. - `-jsz=all` - JetStream streams, consumers, and storage. Verify the Prometheus endpoint: ```bash showLineNumbers title="Verify exporter" curl -s http://localhost:7777/metrics | head -20 ``` ### Configuration The recommended config scrapes the exporter and keeps only the NATS series with a `metric_relabel_configs` keep filter, dropping the Go-runtime and process noise the exporter also emits: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: nats scrape_interval: 10s static_configs: - targets: - ${env:NATS_EXPORTER_HOST}:7777 # exporter host:port metric_relabel_configs: - source_labels: [__name__] regex: "gnatsd_.*|jetstream_.*" action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The `up` and `scrape_*` series survive the keep filter - the `prometheus` receiver synthesizes them after relabeling - so the liveness signal is preserved. #### Environment Variables ```bash showLineNumbers title=".env" NATS_EXPORTER_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped NATS metrics docker logs otel-collector 2>&1 | grep -i "nats" # Confirm NATS monitoring is up curl -s http://localhost:8222/healthz # Confirm the exporter is serving the metric curl -s http://localhost:7777/metrics | grep gnatsd_varz_connections ``` ### Troubleshooting #### Exporter shows zero metrics **Cause**: The exporter cannot reach the NATS monitoring port. **Fix**: 1. Verify NATS is running with monitoring enabled: `curl http://localhost:8222/varz`. 2. Confirm the NATS URL passed to the exporter is correct. 3. Check that no firewall blocks access between the exporter and NATS. Remember `up` tracks the exporter, not NATS - a green `up` with stale `gnatsd_*` values means the exporter lost its link to `:8222`. #### JetStream metrics missing **Cause**: JetStream is not enabled, or the `-jsz` flag is not set on the exporter. **Look at**: the per-stream `jetstream_stream_*` and per-consumer `jetstream_consumer_*` Diagnostic series - they are absent entirely when JetStream is off. **Fix**: 1. Enable JetStream on the server: `nats-server -m 8222 -js`. 2. Start the exporter with `-jsz=all` to include stream and consumer metrics. 3. Verify: `curl http://localhost:8222/jsz`. #### Slow consumer count increasing **Cause**: A client is not consuming fast enough, so the server tracks it as a slow consumer and drops its messages. **Look at**: `gnatsd_varz_slow_consumers` for the trend, the `gnatsd_varz_slow_consumer_stats_*` breakdown for the connection type, and the per-connection `gnatsd_connz_pending_bytes` to find the offending client. **Fix**: 1. Inspect per-connection stats: `curl http://localhost:8222/connz?sort=pending`. 2. Increase client buffer sizes or add more consumer instances. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with NATS running in Kubernetes? Yes. Run the `prometheus-nats-exporter` as a sidecar in the NATS pod, pointing at `http://localhost:8222`. Set the Collector's `targets` to the exporter's service DNS (e.g., `nats-exporter.default.svc.cluster.local:7777`). The Collector can run as a sidecar or a DaemonSet. #### How do I monitor a NATS cluster? Each NATS node needs its own exporter sidecar. Add all exporter endpoints to the scrape config: ```yaml showLineNumbers title="config/otel-collector.yaml (cluster)" receivers: prometheus: config: scrape_configs: - job_name: nats static_configs: - targets: - nats-exporter-1:7777 - nats-exporter-2:7777 - nats-exporter-3:7777 ``` Each node is scraped independently and identified by its `instance` label. #### Why does the exporter use `gnatsd_` as the metric prefix? It is a legacy naming convention from when the NATS server binary was called `gnatsd`. The exporter keeps the prefix so existing dashboards and alerting rules keep working. #### Can I monitor NATS without the exporter sidecar? No. The native NATS monitoring endpoints (`/varz`, `/connz`, `/routez`, `/jsz`) return JSON, which the `prometheus` receiver cannot parse. The `prometheus-nats-exporter` is required to convert them into Prometheus-format metrics. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on NATS metrics. - [Kafka Monitoring](./kafka.md) - Consumer lag and partition offsets for another high-throughput broker. - [RabbitMQ Monitoring](./rabbitmq.md) - Queue depth and consumer health for a classic message queue. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Kafka](./kafka.md), [RabbitMQ](./rabbitmq.md), and other components. --- ## NGINX OpenTelemetry Monitoring - Request Rate, Connection Saturation, and Collector Setup ## NGINX Open-source (OSS) NGINX exposes a small set of connection and request counters through its `stub_status` module - and nothing else over HTTP. The `nginx-prometheus-exporter` scrapes `stub_status` and publishes 9 NGINX series plus `up` in Prometheus format on port 9113; the Collector's native `prometheus` receiver scrapes the exporter. This covers throughput, connections, and saturation on NGINX 1.19+. Because `stub_status` has no error or latency data, this guide also wires `nginx-module-otel` for distributed traces and the `filelog` receiver for access and error logs - the three signals together give you RED-complete coverage in base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ------------------------- | ------- | ---------------- | | NGINX | 1.19 | 1.24+ (1.27.5) | | nginx-prometheus-exporter | 1.5.1 | 1.5.1 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - NGINX 1.19+ running and reachable from the host running the exporter. - The `stub_status` module enabled on a status `server` block (see Access Setup). It ships in the standard NGINX build. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Exactly 9 `nginx_*` series plus `up` describe NGINX itself; the exporter also emits its own runtime self-telemetry, grouped into Diagnostic. `stub_status` is a connection-and-request-count endpoint only. It exposes **no HTTP status codes, no error rate, and no request latency**. RED's "Errors" and "Duration" are therefore not available from OSS NGINX metrics - they come from the access logs (the `filelog` path below) or traces (`nginx-module-otel`). The tiers here cover throughput, connections, and saturation; for error and latency monitoring, use the logs and traces sections. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Prometheus target health - the Collector reached the exporter on `:9113`. | | `nginx_up` | The exporter reached NGINX's `stub_status` (`1` = NGINX reachable). A distinct liveness layer from `up`. | | `nginx_http_requests_total` | Total HTTP requests served; the rate is the throughput KPI. | | `nginx_connections_active` | Active client connections - current load and concurrency. | Core carries **two liveness layers**, and they are different signals. `up` tells you the Collector reached the exporter (the Prometheus scrape succeeded). `nginx_up` tells you the exporter then reached NGINX's `stub_status`. `up == 1` with `nginx_up == 0` means monitoring is healthy but NGINX (or the status endpoint) is not - watch both. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `nginx_connections_accepted` | Accepted client connections (cumulative). | | `nginx_connections_handled` | Handled client connections. A rising `accepted - handled` gap means NGINX is dropping connections - the worker limit is hit. | | `nginx_connections_waiting` | Idle keep-alive connections waiting for a request. | The headline NGINX saturation signal lives here: when `rate(nginx_connections_accepted)` outpaces `rate(nginx_connections_handled)`, connections are being dropped because `worker_connections` / `worker_rlimit_nofile` is exhausted. #### Diagnostic - for investigation and tuning Higher cardinality or exporter-internal context; reach for these during an incident rather than paging on them. | Metric | When you reach for it | |---|---| | `nginx_connections_reading` | Connections reading the request header - useful when diagnosing slow-client or header-parsing stalls. | | `nginx_connections_writing` | Connections writing the response - rises when downstream or clients are slow to drain responses. | | `nginx_exporter_build_info` | Exporter build/version labels (info metric, always `1`); confirm which exporter version is running. | | `go_*`, `process_*`, `promhttp_*`, `scrape_*` | Exporter self-telemetry (Go runtime, exporter process, scrape meta). These describe the exporter, not NGINX - pull them when debugging the exporter itself. | ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. All are relative to your own baseline rather than fixed absolutes. | Alert | Threshold | Why it matters | |---|---|---| | NGINX unreachable | `nginx_up == 0` for > 1m | The exporter cannot read `stub_status` - NGINX is down, the status endpoint moved, or an `allow` / `deny` is blocking it. Check NGINX and the scrape URI. | | Exporter / scrape down | `up == 0` for > 1m | The Collector cannot reach the exporter on `:9113` - exporter down or a network issue. Check the exporter process. | | Dropped connections | `rate(nginx_connections_accepted) - rate(nginx_connections_handled) > 0` | NGINX is dropping accepted connections - `worker_connections` / `worker_rlimit_nofile` exhausted. Raise the limits or add capacity. This is the headline saturation alert. | | Request-rate anomaly | `rate(nginx_http_requests_total)` deviating sharply from baseline | A drop signals an upstream or routing failure; a spike signals a load event. Correlate with connections and access logs. | | Connection saturation | `nginx_connections_active` rising toward `worker_connections × worker_processes` | Approaching the connection ceiling; new connections will be dropped. Add workers or capacity. | ### Access Setup OSS NGINX does not expose Prometheus metrics natively. Enable `stub_status` on a status `server` block, then run the `nginx-prometheus-exporter`, which scrapes that endpoint and publishes Prometheus metrics on `:9113`. #### Step 1: Enable `stub_status` Add the following `server` block **inside** the `http` block of your `nginx.conf`: ```conf showLineNumbers title="nginx.conf" http { # ... your existing config ... server { listen 8080; server_name localhost; location /status { stub_status; allow 127.0.0.1; deny all; } } } ``` :::warning The `server` block **must** be placed inside the `http` block. Placing it outside results in: `"server" directive is not allowed here`. ::: Test and reload NGINX, then confirm the endpoint responds: ```bash showLineNumbers sudo nginx -t && sudo systemctl reload nginx curl http://127.0.0.1:8080/status ``` #### Step 2: Run the nginx-prometheus-exporter Point the exporter at the `stub_status` URI with `--nginx.scrape-uri`. It serves Prometheus metrics on `:9113/metrics`. ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash showLineNumbers docker run -d --name nginx-prometheus-exporter \ --network=host \ nginx/nginx-prometheus-exporter:1.5.1 \ --nginx.scrape-uri=http://127.0.0.1:8080/status ``` ```mdx-code-block ``` Download the exporter from the [nginx-prometheus-exporter releases page](https://github.com/nginx/nginx-prometheus-exporter/releases) (swap `amd64` for `arm64` on ARM hosts): ```bash showLineNumbers curl -LO https://github.com/nginx/nginx-prometheus-exporter/releases/download/v1.5.1/nginx-prometheus-exporter_1.5.1_linux_amd64.tar.gz tar xzf nginx-prometheus-exporter_1.5.1_linux_amd64.tar.gz sudo mv nginx-prometheus-exporter /usr/local/bin/ ``` Create and start a systemd service: ```bash showLineNumbers title="/etc/systemd/system/nginx-prometheus-exporter.service" sudo tee /etc/systemd/system/nginx-prometheus-exporter.service > /dev/null <<'EOF' [Unit] Description=Nginx Prometheus Exporter After=network.target nginx.service [Service] Type=simple ExecStart=/usr/local/bin/nginx-prometheus-exporter --nginx.scrape-uri=http://127.0.0.1:8080/status Restart=always RestartSec=5 [Install] WantedBy=multi-user.target EOF sudo systemctl daemon-reload sudo systemctl enable --now nginx-prometheus-exporter ``` ```mdx-code-block ``` Verify the exporter is serving metrics: ```bash showLineNumbers curl http://127.0.0.1:9113/metrics ``` ### Configuration The Collector scrapes the exporter with the native `prometheus` receiver. The receiver supplies `up` (target health) for free. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: nginx scrape_interval: 5s metrics_path: /metrics static_configs: - targets: ["${env:NGINX_EXPORTER_HOST}:9113"] # exporter address processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" NGINX_EXPORTER_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Collecting traces `stub_status` has no latency data, so distributed traces are how you get per-request timing and upstream propagation. `nginx-module-otel` emits spans straight from NGINX. #### Step 1: Install the NGINX OTel module Download and install the pre-built `.deb` package from the [nginx-otel-build releases](https://github.com/base-14/nginx-otel-build/releases/tag/v0.1.1) (swap `amd64` for `arm64` on ARM hosts): ```mdx-code-block ``` ```bash showLineNumbers curl -LO https://github.com/base-14/nginx-otel-build/releases/download/v0.1.1/ubuntu24.04-nginx1.24.0-amd64.deb sudo apt install ./ubuntu24.04-nginx1.24.0-amd64.deb ``` ```mdx-code-block ``` ```bash showLineNumbers curl -LO https://github.com/base-14/nginx-otel-build/releases/download/v0.1.1/ubuntu24.04-nginx1.24.0-arm64.deb sudo apt install ./ubuntu24.04-nginx1.24.0-arm64.deb ``` ```mdx-code-block ``` :::warning Take a backup of your NGINX config before installing the module. It may be overwritten by the module installation. ::: #### Step 2: Configure NGINX to send traces Add the following to your `nginx.conf`: ```conf showLineNumbers title="nginx.conf" load_module modules/ngx_otel_module.so; http { otel_exporter { endpoint 0.0.0.0:4317; } otel_service_name nginx; otel_resource_attr environment ; otel_trace on; otel_trace_context inject; } ``` > Note: replace `otel_service_name` and `otel_resource_attr` with your actual > values. The endpoint points at the Collector's gRPC port (4317). Reload NGINX and traces will flow to the Scout Collector. ### Collecting logs The access log is where the error rate and per-request detail that `stub_status` omits actually live. Read NGINX's log files with the `filelog` receiver. #### Step 1: Add the filelog receiver ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: filelog/nginx: include: - /var/log/nginx/*.log start_at: beginning ``` > Note: if you write logs to a custom directory, update the `include` block with > the correct path. Add `filelog/nginx` to the `logs` pipeline as well. :::note The OTel Collector process needs read access to the NGINX log files. If you see permission errors, add the `otelcol-contrib` user to the group that owns the log files: ```bash sudo usermod -aG otelcol-contrib ``` Replace `` with the group that owns your NGINX log directory (commonly `adm` or `www-data`). Restart the Collector after this change. ::: ### Verify the Setup Start the Collector and confirm each signal within 60 seconds: ```bash showLineNumbers # Exporter is serving NGINX metrics curl -s http://127.0.0.1:9113/metrics | grep nginx_ # stub_status is responding curl http://127.0.0.1:8080/status # Collector picked up nginx metrics docker logs otel-collector 2>&1 | grep -i "nginx" # Generate traffic so the request and connection counters advance curl -s http://127.0.0.1:80/ > /dev/null ``` ### Troubleshooting #### stub_status returns 403 Forbidden **Cause**: The `allow` directive in the status `location` block restricts access. **Fix**: 1. Add the exporter's IP to the `allow` list in the `location /status` block. 2. For Docker setups, add the container network CIDR (e.g., `allow 172.16.0.0/12;`). 3. Reload NGINX: `sudo nginx -t && sudo systemctl reload nginx`. #### `nginx_up` is 0 (no metrics on port 9113) **Cause**: The exporter is running but cannot reach the `stub_status` endpoint, or the exporter is not running at all. **Look at**: `nginx_up` (the exporter-to-NGINX liveness layer) versus `up` (the Collector-to-exporter layer). `up == 1, nginx_up == 0` isolates the problem to the exporter-to-NGINX hop. **Fix**: 1. Check the exporter is up: `systemctl status nginx-prometheus-exporter` or `docker ps | grep exporter`. 2. Verify `stub_status` is accessible: `curl http://127.0.0.1:8080/status`. 3. Confirm the exporter's `--nginx.scrape-uri` matches the status endpoint and check the exporter logs for connection errors. #### Connections are being dropped under load **Cause**: NGINX is accepting more connections than its workers can handle - the `worker_connections` / `worker_rlimit_nofile` ceiling is hit. **Look at**: the `accepted - handled` gap from `nginx_connections_accepted` and `nginx_connections_handled`; `nginx_connections_active` rising toward `worker_connections × worker_processes`; and the Diagnostic `nginx_connections_reading` / `nginx_connections_writing` split to see whether slow request reads or slow response writes dominate. **Fix**: 1. Raise `worker_connections` and `worker_rlimit_nofile`, or add `worker_processes` / capacity, if the accepted-handled gap is sustained. 2. If `nginx_connections_writing` dominates, investigate slow clients and downstream latency. #### No error rate or latency in the metrics **Cause**: This is expected. `stub_status` exposes only connection and request counts - it has no status codes, error rate, or latency. **Fix**: 1. Use the access logs (the `filelog` path) for status codes and error rate. 2. Use traces (`nginx-module-otel`) for per-request latency and upstream propagation. #### Traces not appearing in Scout **Cause**: The OTel module is not loaded, or the exporter endpoint is wrong. **Fix**: 1. Verify the module is loaded: `nginx -V 2>&1 | grep otel`. 2. Confirm `otel_exporter endpoint` points at the Collector's gRPC port (4317). 3. Check Collector logs for incoming trace data: `docker logs otel-collector 2>&1 | grep traces`. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why are there three separate collection methods? OSS NGINX does not expose all telemetry through a single interface. Metrics come from `stub_status` via the exporter, traces require `nginx-module-otel`, and logs are read from files. Each needs its own receiver in the Collector pipeline. Together they give you the throughput and saturation that metrics cover, plus the error rate and latency that only logs and traces can. #### Why is there no error-rate or latency metric? `stub_status` is a connection-and-request-count endpoint - it has no HTTP status codes, no error rate, and no request latency. That is a limitation of the OSS status surface, not the exporter. Use the access logs (`filelog`) for error rate and traces (`nginx-module-otel`) for latency. #### Can I use NGINX Plus instead of open-source NGINX? Yes. NGINX Plus provides a richer metrics API at `/api/` that includes per-upstream, per-zone, and response-code data - including the error rate and latency that `stub_status` lacks. The same `nginx-prometheus-exporter` has an NGINX Plus mode: point it at the Plus `/api/` endpoint and it exposes those richer metrics (prefixed `nginxplus_*`), which you scrape with the same `prometheus` receiver shown above. #### Does this work with NGINX running in Kubernetes? Yes. Deploy the `nginx-prometheus-exporter` as a sidecar container in the NGINX pod and point the Collector's Prometheus scrape config at the sidecar. For traces, include `nginx-module-otel` in your NGINX container image. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on NGINX metrics. - [Apache HTTP Server Monitoring](./apache-httpd.md) - Another worker-pool web server to watch the same way. - [Caddy Monitoring](./caddy.md) - A web server you may run alongside or behind NGINX. - [HAProxy Monitoring](./haproxy.md) - The load balancer in front of an NGINX pool. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Apache HTTP Server](./apache-httpd.md), [HAProxy](./haproxy.md), and other components. - **Fine-tune Collection**: Adjust the scrape interval to balance metric freshness against load. --- ## Nomad OpenTelemetry Monitoring - Raft Consensus, Scheduler, and Collector Setup ## Nomad Nomad serves Prometheus-format text at `/v1/metrics?format=prometheus` on the HTTP API port `4646` once `prometheus_metrics = true` is set in the agent telemetry block. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint, collecting 130+ server metrics across Raft consensus, the eval broker and scheduler, blocked evaluations, job status, RPC, gossip and membership, and the Go runtime. This guide configures the receiver, enables the endpoint, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Nomad | 1.3.0 | 1.9 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The Nomad HTTP API port (`4646`) must be reachable from the host running the Collector. - `prometheus_metrics` must be enabled in the agent telemetry block - it is not on by default, and without it the endpoint returns nothing. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `prometheus` receiver keeps everything the endpoint exposes; a keep filter (see [Configuration](#configuration)) scopes the scrape to the Nomad namespace. A few surface facts shape what you see: - **`up` is the liveness signal here.** The `prometheus` receiver emits `up = 1` when the API metrics endpoint responds, so you alert on the scrape itself - not on a synthetic heartbeat. `nomad_nomad_autopilot_healthy` (`1` = enough voters alive and reachable) is the headline cluster-health flag, and `nomad_nomad_blocked_evals_total_blocked` (rising = work cannot be placed) is the headline scheduling signal. - **`prometheus_metrics = true` is the on-switch.** It defaults to `false`; until it is set, `/v1/metrics?format=prometheus` returns an error and the receiver sees only `up` and the Go runtime series. - **Server vs client metrics.** A Nomad *server* emits the Raft, broker, scheduler, and job families documented here. The client and allocation families (`nomad_client_host_*`, `nomad_client_allocated_*`, `nomad_client_allocs_*`) are emitted only by Nomad *client* agents with `publish_node_metrics` / `publish_allocation_metrics` enabled - scrape the client agents (also on `:4646`) to collect them. - **Double-prefix quirk.** Server-subsystem metrics are double-prefixed `nomad_nomad_*` (for example `nomad_nomad_blocked_evals_total_blocked`) because both the telemetry prefix and the server subsystem are named `nomad`. Infrastructure families use a single prefix (`nomad_raft_*`, `nomad_serf_*`, `nomad_runtime_*`). Reproduce the names exactly as you see them on the endpoint. - **Leader-only metrics.** The eval broker, blocked evals, and `nomad_raft_leader_*` are emitted by the current leader; followers report `nomad_raft_state_follower`. #### Core - is it up, has quorum, and placing work | Metric | What it tells you | |---|---| | `up` | Scrape liveness - `1` means the Nomad API metrics endpoint responded. The liveness signal on this surface. | | `nomad_nomad_autopilot_healthy` | Cluster health per Autopilot - `1` = enough voters alive and reachable, `0` = degraded. The headline cluster-health flag. | | `nomad_raft_peers` | Number of Raft peers (voting servers) - the quorum picture. | | `nomad_raft_commitTime` | Time to commit a Raft log entry - the cluster's write-path latency. | | `nomad_nomad_blocked_evals_total_blocked` | Evaluations that cannot be placed (no capacity / failed constraints) - the headline "are jobs getting scheduled" signal. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Quorum margin | `nomad_nomad_autopilot_failure_tolerance` | How many servers can fail before quorum is lost - `0` means no redundancy left. | | Raft state | `nomad_raft_state_leader` / `_candidate` / `_follower`, `nomad_raft_transition_heartbeat_timeout` | Raft state transitions; `_candidate` or heartbeat-timeout incrementing means elections and leadership churn. | | Raft apply | `nomad_raft_apply`, `_commitNumLogs`, `_appliedIndex`, `_lastIndex`, `_barrier` | Apply rate, logs per commit, and replication-index progress. | | Leader path | `nomad_raft_leader_dispatchLog` / `_oldestLogAge`, `nomad_raft_fsm_apply`, `nomad_nomad_leader_establish_leadership` / `_reconcile` | Leader log-dispatch and FSM apply latency; leadership establishment and reconciliation timing. | | Eval broker | `nomad_nomad_broker_total_ready` / `_unacked` / `_pending` / `_waiting` / `_cancelable`, `nomad_nomad_broker_process_time` | Eval-broker queue depth and processing latency - a rising backlog means schedulers are falling behind. | | Scheduler pipeline | `nomad_nomad_plan_queue_depth` / `_apply`, `nomad_nomad_eval_create` / `_ack` / `_dequeue`, `nomad_nomad_worker_invoke_scheduler_service` / `_submit_plan` | Plan queue depth, plan-application latency, and scheduler-worker step timing - placement throughput. | | Blocked-eval breakdown | `nomad_nomad_blocked_evals_total_escaped` / `_total_quota_limit` / `_job_cpu` / `_job_memory` | Why evals are blocked - node-class escapes, quota limits, and CPU/memory pressure. | | Job status | `nomad_nomad_job_status_running` / `_pending` / `_dead`, `nomad_nomad_job_summary_running` / `_failed` / `_lost` / `_queued` / `_complete` | Job counts by status and per-job allocation summary - `_failed` / `_lost` rising means workloads are unhealthy. | | Heartbeats | `nomad_nomad_heartbeat_active` | Active client heartbeats the leader is tracking - drops mean clients disconnecting. | | RPC | `nomad_nomad_rpc_request` / `_query` / `_accept_conn` | Server RPC volume and accepted connections. | | Gossip | `nomad_serf_member_join`, `nomad_serf_queue_Event` / `_Intent`, `nomad_memberlist_gossip` / `_queue_broadcasts` | Server gossip activity and outbound queue depth - rising queues mean gossip back-pressure. | | Runtime | `nomad_runtime_alloc_bytes` / `_sys_bytes` / `_heap_objects` / `_num_goroutines` / `_gc_pause_ns` | Nomad process Go-runtime memory, goroutines, and GC pressure. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. The families below are grouped - representative members are shown, not the full list. | Group | Metrics | When you reach for it | |---|---|---| | Raft storage internals | `nomad_raft_boltdb_*` (e.g. `writeDuration`, `freelistBytes`, `numFreePages`, `logSize`, `openReadTxn`) | Storage-backend write capacity/latency and freelist/page accounting. | | Per-type FSM timing | `nomad_nomad_fsm_apply_plan_results` / `_register_job` / `_update_eval` / `_apply_scheduler_config` | Which kind of write is slow. | | Per-endpoint RPC latency | `nomad_nomad_rpc_eval_list` / `_eval_write` / `_job_write` / `_plan_write` / `_status_read` | Drill down RPC latency by API. | | Deployment / ACL / locks | `nomad_nomad_deployment_get_deployment`, `nomad_nomad_acl_*`, `nomad_variables_locks_delay_timer_num` / `_ttl_timer_num` | Deployment reads, ACL resolution, and variable-lock timers. | | Snapshot internals | `nomad_state_snapshotIndex`, `nomad_serf_snapshot_appendLine` | Raft and serf snapshot accounting. | | Endpoint meta | `go_*`, `process_*`, `scrape_duration_seconds` / `scrape_samples_scraped` | Go-runtime, process, and Prometheus scrape-side metrics the endpoint also exposes. | The eval-broker, blocked-eval, and `nomad_raft_leader_*` families are emitted by the current leader; on a server-only deployment with no client node, the `nomad_client_*` host and allocation families stay absent until a client agent is scraped. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. The state-based alerts fire on a value; the rest are relative to your own baseline. These are starting points - tune them to your workload. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The API metrics endpoint stopped responding. Check the Nomad process and the API port. | | `nomad_nomad_autopilot_healthy` | `== 0` | Autopilot sees the cluster as degraded - not enough voters alive or reachable. Check server health. | | `nomad_nomad_autopilot_failure_tolerance` | `== 0` | The cluster can lose no further server without losing quorum. Restore the missing server(s). | | `nomad_nomad_blocked_evals_total_blocked` | Rising vs baseline | Evaluations are blocked - insufficient capacity or unmet constraints. Add client capacity or fix constraints. | | `nomad_nomad_broker_total_ready` / `nomad_nomad_plan_queue_depth` | Rising vs baseline | Schedulers are falling behind. Correlate with eval rate and server load. | | `nomad_nomad_job_summary_failed` / `nomad_nomad_job_summary_lost` | Rising vs baseline | Workloads are crashing or being lost. Inspect the failing job and its clients. | ### Access Setup Enable the Prometheus metrics endpoint by adding the `telemetry` block to the Nomad agent configuration: ```hcl showLineNumbers title="nomad-config.hcl" telemetry { prometheus_metrics = true publish_allocation_metrics = true publish_node_metrics = true } ``` - `prometheus_metrics` must be `true` to expose the Prometheus endpoint (the default is `false`). - `publish_allocation_metrics` and `publish_node_metrics` drive the client and allocation families - they apply on Nomad *client* agents; a server-only agent emits the Raft, broker, and scheduler families regardless. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # Check Nomad is running nomad server members # Verify the Prometheus metrics endpoint curl -s 'http://localhost:4646/v1/metrics?format=prometheus' | head -20 ``` No authentication is required by default. ACL-enabled clusters need a token with at least `node:read` and `agent:read` - see [Configuration](#configuration) below. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: nomad scrape_interval: 30s metrics_path: /v1/metrics params: format: [prometheus] static_configs: - targets: - ${env:NOMAD_HOST}:4646 # Change to your Nomad API address processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" NOMAD_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### ACL-enabled clusters For Nomad clusters with ACLs enabled, the scrape request needs a token with at least `node:read` and `agent:read` capability: ```yaml showLineNumbers title="config/otel-collector.yaml (ACL)" receivers: prometheus: config: scrape_configs: - job_name: nomad metrics_path: /v1/metrics params: format: [prometheus] authorization: type: Bearer credentials: ${env:NOMAD_TOKEN} static_configs: - targets: - ${env:NOMAD_HOST}:4646 ``` #### Scope the scrape to the Nomad namespace The endpoint also exposes Go-runtime and process series alongside the `nomad_*` families. To keep only the Nomad namespace, add a `metric_relabel_configs` keep filter: ```yaml showLineNumbers title="config/otel-collector.yaml (keep filter)" receivers: prometheus: config: scrape_configs: - job_name: nomad scrape_interval: 30s metrics_path: /v1/metrics params: format: [prometheus] static_configs: - targets: - ${env:NOMAD_HOST}:4646 metric_relabel_configs: - source_labels: [__name__] regex: "nomad_.*" action: keep ``` This scopes the scrape to `nomad_*`; the Diagnostic-tier `go_*` / `process_*` / `scrape_*` meta is dropped while every Core and Operational series is kept. ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Nomad metrics docker logs otel-collector 2>&1 | grep -i "nomad" # Verify Nomad is healthy nomad server members # Check the metrics endpoint directly curl -s 'http://localhost:4646/v1/metrics?format=prometheus' \ | grep nomad_raft_peers ``` ### Troubleshooting #### Metrics endpoint returns empty or 404 **Cause**: `prometheus_metrics` is not enabled in the telemetry block. **Fix**: 1. Add `prometheus_metrics = true` to the `telemetry` block in the agent config. 2. Restart the Nomad agent. 3. Verify: `curl 'http://localhost:4646/v1/metrics?format=prometheus'`. #### Connection refused on port 4646 **Cause**: The Collector cannot reach Nomad at the configured address. **Fix**: 1. Verify Nomad is running: `docker ps | grep nomad` or `nomad server members`. 2. Confirm the HTTP API address: `nomad agent-info | grep Address`. 3. Check firewall rules if the Collector runs on a separate host. #### Client and allocation metrics missing **Cause**: The Collector is scraping a Nomad server, which emits only server metrics. **Look at**: the absence of `nomad_client_host_*`, `nomad_client_allocated_*`, and `nomad_client_allocs_*` - these are the client and allocation families. **Fix**: 1. Nomad servers expose only the Raft, broker, and scheduler families. Allocation resource usage and node-level metrics come from Nomad client agents. 2. Add client agent endpoints (also on port `4646`) to the scrape targets alongside the server endpoints. 3. Ensure `publish_allocation_metrics = true` and `publish_node_metrics = true` are set on the client agents. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Nomad running in Kubernetes? Yes. Set `targets` to the Nomad service DNS (e.g., `nomad-server.nomad.svc.cluster.local:4646`) and ensure `prometheus_metrics = true` is set in the Nomad Helm chart values under `server.extraConfig`. The Collector can run as a sidecar or DaemonSet. #### How do I monitor a multi-node Nomad cluster? Each Nomad server exposes its own metrics endpoint. Add all server endpoints to the scrape config: ```yaml showLineNumbers title="Multi-node scrape config" receivers: prometheus: config: scrape_configs: - job_name: nomad metrics_path: /v1/metrics params: format: [prometheus] static_configs: - targets: - nomad-1:4646 - nomad-2:4646 - nomad-3:4646 ``` Each server is scraped independently and identified by its `instance` label. #### Why are client metrics missing? A Nomad server does not emit client or allocation metrics. Allocation resource usage, task-driver stats, and node-level metrics come only from Nomad client agents. Add client agent endpoints (also on port `4646`) to your scrape targets alongside the servers, and enable `publish_allocation_metrics` and `publish_node_metrics` on those agents. #### How does this relate to Consul and Vault monitoring? Nomad, Consul, and Vault form the HashiCorp stack and are often deployed together. Each exposes Prometheus metrics via the same `/v1/metrics` pattern, so you monitor all three by adding separate scrape jobs in the same Collector config. See [Consul Monitoring](./consul.md) and [Vault Monitoring](./vault.md). ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Nomad metrics. - [Consul Monitoring](./consul.md) - Service discovery and health for the same cluster. - [Vault Monitoring](./vault.md) - Secrets and token issuance for the same workloads. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Consul](./consul.md), [Vault](./vault.md), and other components. - **Focus the Collection**: Use the `nomad_.*` keep filter to scope the scrape to the Nomad namespace, dropping the Go-runtime and process meta the endpoint also exposes. --- ## OpenSearch OpenTelemetry Monitoring - Cluster Health, Search Latency, and JVM Heap ## OpenSearch OpenSearch serves Prometheus-format metrics at `/_prometheus/metrics` on the HTTP port (`:9200`) once the [prometheus-exporter plugin](https://github.com/opensearch-project/opensearch-prometheus-exporter) is installed - the plugin version must equal the OpenSearch version exactly. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint, collecting 230+ metrics across cluster health, indexing and search throughput and latency, JVM heap and GC, OS and process resources, filesystem and storage I/O, caches, circuit breakers, and thread pools. This guide installs the plugin, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ---------------------- | | OpenSearch | 2.0 | 3.x (3.7.0) | | prometheus-exporter | match | match (e.g. 3.7.0.0) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The OpenSearch HTTP port (`9200`) must be reachable from the host running the Collector. - The prometheus-exporter plugin version must equal the OpenSearch version exactly (OpenSearch `3.7.0` needs plugin `3.7.0.0`); a mismatch fails plugin install or node start. - On clusters with the security plugin enabled, a monitoring user whose role grants the cluster monitor actions the exporter calls - `cluster:monitor/prometheus/metrics`, `cluster:monitor/health`, `cluster:monitor/state`, `cluster:monitor/nodes/info`, `cluster:monitor/nodes/stats` - plus the index permission `indices:monitor/stats` (see [Access Setup](#access-setup)). - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few facts about this surface shape the tiers: - **Liveness is the `up` series.** The `prometheus` receiver emits `up = 1` when the scrape succeeds; `up` and the four `scrape_*` series are receiver-synthesized, not plugin metrics. `opensearch_cluster_status` (green=0, yellow=1, red=2) is the headline cluster-state gauge. - **This plugin reports its counter-like accumulators (`*_count`, `*_total_*`, the `*_seconds` totals) as Prometheus gauges**, so the `prometheus` receiver ingests them as Gauge rather than Sum. Derive rates with `rate()` / delta in the backend, and expect a reset to 0 on node restart. The receiver honors the exporter's own `# TYPE` line (`gauge` to Gauge, `counter` to Sum), so confirm a series with `curl .../_prometheus/metrics | grep '^# TYPE'` if a dashboard treats it unexpectedly. - **Two families cover the same counters.** `opensearch_indices_*` is the node-level aggregate across all shards on the node; `opensearch_index_*` is the per-index breakdown carrying an `index` label. The per-index family also covers system indices (for example `.plugins-ml-config`) and adds the per-index `_status`, `_shards_number`, `_replicas_number`, `_translog_*`, and `_warmer_*` members. On a busy cluster the per-index family dominates cardinality. - **The plugin version must equal the OpenSearch version exactly.** There is no `opensearchreceiver` - OpenSearch telemetry goes through this plugin plus the `prometheus` receiver, not a native Collector receiver. - **No thread-pool `rejected` counter is exported** - use `opensearch_threadpool_tasks_number` (queue depth) as the saturation proxy. - **The `_disk_watermark_*_pct` gauges and `_disk_threshold_enabled` reflect configuration, not live disk usage** - free space is `opensearch_fs_path_available_bytes`. #### Core - is the cluster alive and the read/write path healthy | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - node reachable (receiver-synthesized). | | `opensearch_cluster_status` | 0=green, 1=yellow, 2=red - the headline cluster signal. | | `opensearch_cluster_shards_active_percent` | Percent of shards active - allocation health. | | `opensearch_jvm_mem_heap_used_percent` | Heap pressure - the primary OpenSearch saturation signal. | | `opensearch_os_cpu_percent` | Host CPU. | | `opensearch_process_cpu_percent` | OpenSearch process CPU. | | `opensearch_indices_search_query_count` | Search (query phase) throughput. | | `opensearch_indices_search_query_time_seconds` | Cumulative query time - pair with the count for average latency. | | `opensearch_indices_indexing_index_count` | Indexing throughput. | | `opensearch_indices_indexing_index_time_seconds` | Cumulative indexing time - pair with the count for average write latency. | | `opensearch_fs_total_available_bytes` | Free disk - drives disk-based shard allocation and write blocking. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `opensearch_indices_search_fetch_count` / `_time_seconds` | Fetch-phase throughput and latency. | | `opensearch_indices_search_open_contexts_number` | Open search contexts - rising means leaked scrolls. | | `opensearch_indices_search_scroll_current_number` / `_time_seconds` | Scroll usage and contexts not draining. | | `opensearch_indices_indexing_index_failed_count` | Failed index ops - should stay flat. | | `opensearch_indices_indexing_is_throttled_bool` | Indexing back-pressure (1 = throttled). | | `opensearch_indices_merges_current_number` / `_total_throttled_time_seconds` | Merge load and throttling. | | `opensearch_indices_refresh_total_count` / `_time_seconds` | Refresh cost (visibility latency). | | `opensearch_indices_flush_total_count` / `_time_seconds` | Flush cost. | | `opensearch_jvm_gc_collection_count` / `_time_seconds` | GC frequency and pause time - heap-pressure consequence. | | `opensearch_circuitbreaker_tripped_count` / `_estimated_bytes` / `_limit_bytes` | Breaker trips and headroom. | | `opensearch_threadpool_tasks_number` | Queue depth - saturation proxy (no rejected counter is exported). | | `opensearch_indices_querycache_hit_count` / `_evictions_count` | Query-cache effectiveness. | | `opensearch_indices_requestcache_evictions_count` | Shard request-cache churn. | | `opensearch_indices_fielddata_memory_size_bytes` | Fielddata footprint. | | `opensearch_index_translog_uncommitted_size_bytes` | Unflushed translog backlog (per-index). | | `opensearch_os_mem_used_percent` | Host memory. | | `opensearch_process_file_descriptors_open_number` / `_max_number` | FD headroom. | | `opensearch_transport_rx_bytes_count` / `_tx_bytes_count` | Inter-node transport volume. | | `opensearch_cluster_pending_tasks_number` / `_task_max_waiting_time_seconds` | Cluster-manager task backlog. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Representative members | When you reach for it | |---|---|---| | Per-index breakdown | `opensearch_index_*` (the full per-index family, including system indices), `opensearch_index_status` / `_shards_number` / `_replicas_number` / `_translog_*` / `_warmer_*` | Per-index detail of every `indices_*` counter, plus the per-index health and shard config. | | Inventory | `opensearch_indices_doc_number`, `_doc_deleted_number`, `_store_size_bytes`, `opensearch_indices_segments_number` / `_memory_bytes` | Document, store, and segment census. | | Get / suggest paths | `opensearch_indices_get_*`, `opensearch_indices_suggest_*` | Get-by-id and suggester/completion activity. | | Recovery / ingest / script | `opensearch_indices_recovery_current_number`, `opensearch_ingest_total_count` / `_failed_count`, `opensearch_script_compilations_count` | Shard recovery, ingest pipelines, script compile and cache. | | JVM internals | `opensearch_jvm_bufferpool_*`, `_classes_*`, `_mem_pool_*`, `_mem_nonheap_*` | Buffer pools, class loading, memory pools, non-heap. | | Filesystem / I/O | `opensearch_fs_io_total_*`, `opensearch_fs_path_available_bytes` | Per-device I/O and per-path capacity detail. | | Transport / HTTP detail | `opensearch_transport_rx_packets_count` / `_tx_packets_count`, `opensearch_http_open_server_number` | Packet-level transport and HTTP connection detail. | | Topology | `opensearch_cluster_nodes_number` / `_datanodes_number` / `_shards_number`, `opensearch_node_role_bool` | Node and shard counts, node role flags. | | Disk-watermark config | `opensearch_cluster_routing_allocation_disk_watermark_low_pct` / `_high_pct` / `_flood_stage_pct` / `_disk_threshold_enabled` | The configured watermark thresholds (configuration, not live usage). | Full metric list: install the plugin and run `curl -s http://localhost:9200/_prometheus/metrics | grep "^# TYPE"` against your OpenSearch instance. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. `up`, `opensearch_cluster_status`, `opensearch_cluster_shards_active_percent`, and `opensearch_indices_indexing_is_throttled_bool` read **states** - the `cluster_status` enum is OpenSearch's own health value, not an invented absolute. The rest are relative to your own baseline; tune them to your workload and invent no absolute thresholds. | Alert | Condition | |---|---| | OpenSearch unreachable | `up == 0` for > 1m | | Cluster red | `opensearch_cluster_status == 2` | | Cluster yellow (sustained) | `opensearch_cluster_status == 1` held beyond a recovery window | | Shards not fully active | `opensearch_cluster_shards_active_percent < 100` sustained | | JVM heap pressure | `opensearch_jvm_mem_heap_used_percent` sustained high / rising toward the heap max, with `rate(opensearch_jvm_gc_collection_time_seconds)` climbing | | Disk watermark crossed | `opensearch_fs_path_available_bytes` falling toward the `_disk_watermark_*_pct` thresholds (write blocking at flood stage) | | Search latency rising | `rate(opensearch_indices_search_query_time_seconds) / rate(opensearch_indices_search_query_count)` increasing | | Indexing failures | `rate(opensearch_indices_indexing_index_failed_count) > 0` | | Indexing throttled | `opensearch_indices_indexing_is_throttled_bool == 1` | | Circuit breaker tripped | `rate(opensearch_circuitbreaker_tripped_count) > 0` | | Leaked search contexts | `opensearch_indices_search_open_contexts_number` rising / `search_scroll_current_number` not draining | | Cache thrash | rising `querycache` / `requestcache` evictions with a falling hit ratio | | Merge back-pressure | `opensearch_indices_merges_current_number` high + `rate(opensearch_indices_merges_total_throttled_time_seconds)` rising | | Cluster task backlog | `opensearch_cluster_pending_tasks_number` rising / `_task_max_waiting_time_seconds` high | ### Access Setup The prometheus-exporter plugin is not bundled with OpenSearch. Install the release whose version equals your OpenSearch version exactly on every node: ```bash showLineNumbers title="Install prometheus-exporter plugin" # Plugin version must equal your OpenSearch version exactly bin/opensearch-plugin install \ https://github.com/opensearch-project/opensearch-prometheus-exporter/releases/download/3.7.0.0/prometheus-exporter-3.7.0.0.zip ``` Restart the node after installation. Verify the plugin is loaded: ```bash showLineNumbers title="Verify plugin" curl -s http://localhost:9200/_cat/plugins | grep prometheus ``` For Docker deployments, build a custom image with the matching plugin pre-installed: ```dockerfile showLineNumbers title="Dockerfile" FROM opensearchproject/opensearch:3.7.0 RUN /usr/share/opensearch/bin/opensearch-plugin install -b \ https://github.com/opensearch-project/opensearch-prometheus-exporter/releases/download/3.7.0.0/prometheus-exporter-3.7.0.0.zip ``` The plugin and OpenSearch version literals must stay in lockstep - bump the `FROM` tag and the plugin release together. No authentication is required when the security plugin is disabled. On secured clusters the scrape needs `basic_auth` (or client certs) and a monitoring role granting the cluster monitor actions the exporter calls - `cluster:monitor/prometheus/metrics` plus `cluster:monitor/health`, `cluster:monitor/state`, `cluster:monitor/nodes/info`, `cluster:monitor/nodes/stats` - and the index permission `indices:monitor/stats`. Create a read-only monitoring role with those actions via the OpenSearch security API, map a monitoring user to it, and supply the credentials in the scrape config (see the secured variant in [Configuration](#configuration)). ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: opensearch scrape_interval: 15s metrics_path: /_prometheus/metrics static_configs: - targets: - ${env:OPENSEARCH_HOST}:9200 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" OPENSEARCH_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Secured clusters When the security plugin is enabled, scrape over `https` with basic auth. The monitoring user's role must grant the cluster monitor actions the exporter calls (`cluster:monitor/prometheus/metrics`, `cluster:monitor/health`, `cluster:monitor/state`, `cluster:monitor/nodes/info`, `cluster:monitor/nodes/stats`) and `indices:monitor/stats`: ```yaml showLineNumbers title="config/otel-collector.yaml (secured)" receivers: prometheus: config: scrape_configs: - job_name: opensearch scrape_interval: 15s metrics_path: /_prometheus/metrics scheme: https tls_config: insecure_skip_verify: true # Set false in production with valid certs basic_auth: username: ${env:OPENSEARCH_USER} password: ${env:OPENSEARCH_PASSWORD} static_configs: - targets: - ${env:OPENSEARCH_HOST}:9200 ``` #### Scoping which families ship The endpoint exposes 230+ series, including the per-index `opensearch_index_*` family. A `metric_relabel_configs` keep rule scopes which families the Collector forwards - for example, keeping the node-level cluster, index-aggregate, JVM, OS, process, transport, and HTTP families: ```yaml showLineNumbers title="config/otel-collector.yaml (scoped families)" receivers: prometheus: config: scrape_configs: - job_name: opensearch scrape_interval: 15s metrics_path: /_prometheus/metrics static_configs: - targets: - ${env:OPENSEARCH_HOST}:9200 metric_relabel_configs: - source_labels: [__name__] regex: "opensearch_(cluster|indices|jvm|os|process|transport|http)_.*" action: keep ``` This selects which series the pipeline carries; it does not change the metric tier of anything kept. When the per-index family is what you want, drop the keep rule or replace it with an `index`-label allow-list instead. ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped OpenSearch metrics docker logs otel-collector 2>&1 | grep -i "opensearch" # Verify the metrics endpoint directly curl -s http://localhost:9200/_prometheus/metrics \ | grep opensearch_cluster_status # Check cluster health curl -s http://localhost:9200/_cluster/health?pretty ``` ### Troubleshooting #### Metrics endpoint returns 400 or not found **Cause**: The prometheus-exporter plugin is not installed or failed to load. **Fix**: 1. List installed plugins: `curl -s http://localhost:9200/_cat/plugins`. 2. Look for `prometheus-exporter` in the output. 3. If missing, install the matching-version plugin and restart the node. 4. Confirm the plugin version equals your OpenSearch version exactly. #### Connection refused on port 9200 **Cause**: The Collector cannot reach OpenSearch at the configured address. **Fix**: 1. Verify OpenSearch is running: `curl -s http://localhost:9200`. 2. For Docker, ensure both containers are on the same network. 3. Check firewall rules if the Collector runs on a separate host. #### Plugin version mismatch **Cause**: The prometheus-exporter plugin version does not equal the OpenSearch version, so the plugin fails to install or the node will not start. **Fix**: 1. Check the OpenSearch version: `curl -s http://localhost:9200 | jq .version.number`. 2. Download the matching release from [GitHub releases](https://github.com/opensearch-project/opensearch-prometheus-exporter/releases). 3. Remove the old plugin and install the version-matched one, then restart. #### Counters look flat or jump backwards in dashboards **Cause**: This plugin reports its monotonic counters (`*_count`, `*_total_*`, the `*_seconds` accumulators) as Prometheus gauges, so the receiver ingests them as Gauge rather than Sum. **Look at**: any `*_count` / `*_time_seconds` series - it carries the raw cumulative value and resets to 0 on a node restart. **Fix**: 1. Apply `rate()` / delta in the backend to turn these gauges into rates. 2. Treat a drop to 0 as a node restart, not data loss. #### Metric volume or cardinality is high **Cause**: The per-index `opensearch_index_*` family carries an `index` label and also covers system indices (for example `.plugins-ml-config`); on a busy cluster it dominates cardinality. **Look at**: the count of distinct `index` label values on the `opensearch_index_*` series. **Fix**: 1. Scope the families with the `metric_relabel_configs` keep rule (see [Configuration](#configuration)). 2. Or add an `index`-label allow-list to keep only the indices you care about; the node-level `opensearch_indices_*` aggregate stays available for cluster-wide views. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with OpenSearch running in Kubernetes? Yes. Set `targets` to the OpenSearch service DNS (e.g., `opensearch-cluster.opensearch.svc.cluster.local:9200`). The prometheus-exporter plugin must be present in the container image - bake it into a custom image or install it via an init container. The Collector can run as a sidecar or a DaemonSet. #### How do I monitor an OpenSearch cluster with multiple nodes? Add each node endpoint to the scrape config: ```yaml showLineNumbers title="Multi-node scrape" receivers: prometheus: config: scrape_configs: - job_name: opensearch metrics_path: /_prometheus/metrics static_configs: - targets: - opensearch-1:9200 - opensearch-2:9200 - opensearch-3:9200 ``` Each node exposes its own node-level and per-index series; the cluster-health series are consistent across all nodes. **What is the difference between `opensearch_index_*` and `opensearch_indices_*` metrics?** `opensearch_index_*` is the per-index breakdown, carrying an `index` label. `opensearch_indices_*` is the node-level aggregate across all indices on the node. For cluster-wide monitoring the `opensearch_indices_*` aggregate is usually enough; reach for the per-index family during an incident or a capacity review. #### Why do counters show up as gauges? This plugin reports its counter-like series as Prometheus gauges, so the receiver ingests them as Gauge. Apply `rate()` / delta in the backend to read them as rates, and expect a reset to 0 on a node restart. The receiver honors the exporter's `# TYPE` line, so any series the exporter does label `counter` arrives as a Sum. #### Can I use this instead of the OpenSearch Dashboards monitoring? Yes. The plugin exposes the same underlying cluster and node statistics. The OTel Collector approach centralizes those metrics alongside the rest of your infrastructure telemetry in base14 Scout. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on OpenSearch metrics. - [Elasticsearch Monitoring](./elasticsearch.md) - The other Lucene-based search engine, on the same Scout pipeline. - [Redis Monitoring](./redis.md) - A common companion datastore in search and caching tiers. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Elasticsearch](./elasticsearch.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Scope the per-index family with `metric_relabel_configs` and tune `scrape_interval` to your cluster size and retention needs. --- ## PgBouncer OpenTelemetry Monitoring - Pool Saturation, Client Wait, and Collector Setup ## PgBouncer PgBouncer exposes its statistics only over its admin console; the prometheuscommunity `pgbouncer_exporter` translates them to Prometheus on `:9127`, and the OpenTelemetry Collector's `prometheus` receiver scrapes it. This collects metrics across pool saturation and client wait, query and transaction throughput, client and server connection counts against the configured caps, and per-database limits, then ships them to base14 Scout. PgBouncer has no native Prometheus endpoint and there is no `pgbouncerreceiver` in collector-contrib, so the exporter is part of the pipeline. This guide configures the exporter and the receiver, sets up admin-console access, and ships metrics to Scout. :::note Running this in production pgX shows the queries holding the connections these pool metrics count. [Check out base14 pgX](https://base14.io/scout/pgx). ::: ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ------------------------ | | PgBouncer | 1.x | 1.25+ (e.g. 1.25.2) | | pgbouncer_exporter | - | 0.12+ (e.g. 0.12.0) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - PgBouncer must be reachable from the host running the exporter, over its admin console (the virtual `pgbouncer` database on the listen port, default `6432`). - The exporter must be reachable from the host running the Collector, on `:9127`. - A PgBouncer user listed in `stats_users` or `admin_users` (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things shape how you read this surface: - **Two liveness signals.** `up` (from the `prometheus` receiver) is 1 when the exporter's `/metrics` responds; `pgbouncer_up` is 1 when the exporter could reach PgBouncer's admin console. A healthy pipeline has both at 1. `up == 1` with `pgbouncer_up == 0` means the exporter is running but cannot talk to PgBouncer. - **The exporter is required.** PgBouncer exposes stats only over its admin console; there is no native Prometheus endpoint and no dedicated collector receiver. The only pure-collector alternative is the `sqlqueryreceiver` pointed at the same admin console with hand-mapped `SHOW` queries (more config, custom metric names). - **Pool exhaustion is the signal that matters.** When every server connection in a pool is busy, new clients queue: `pgbouncer_pools_client_waiting_connections` rises and `pgbouncer_pools_client_maxwait_seconds` grows. That wait is added latency on every query. Pool capacity is `pgbouncer_databases_pool_size`. - **Pool mode shapes interpretation.** Server-connection reuse - and thus the idle / active server counts - differs across session, transaction, and statement mode. - **Per-pool / per-database cardinality.** The `pgbouncer_pools_*` and `pgbouncer_databases_*` families are labeled by database and user, so series count scales with `#databases x #users`. - **Admin access.** The exporter must authenticate as a user listed in PgBouncer's `stats_users` / `admin_users`; `SHOW STATS` needs stats access. #### Core - is it up, reachable, and serving | Metric | What it tells you | |---|---| | `up` | Prometheus scrape liveness - 1 when the exporter's `/metrics` responded. | | `pgbouncer_up` | 1 when the exporter reached PgBouncer's admin console - the PgBouncer liveness signal. | | `pgbouncer_pools_client_waiting_connections` | Clients queued waiting for a server connection - pool exhaustion. | | `pgbouncer_pools_client_maxwait_seconds` | Longest a client is currently waiting for a connection - exhaustion severity / added latency. | | `pgbouncer_stats_totals_queries_pooled_total` | Queries routed through the pooler - headline throughput. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `pgbouncer_pools_client_active_connections` | Clients with an assigned server connection (actively served). | | `pgbouncer_pools_server_active_connections` | Server connections currently executing client queries. | | `pgbouncer_pools_server_idle_connections` | Idle server connections available to take work - 0 with waiting clients means saturation. | | `pgbouncer_pools_server_used_connections` | Recently used server connections. | | `pgbouncer_stats_totals_sql_transactions_pooled_total` | Transactions routed through the pooler. | | `pgbouncer_stats_totals_queries_duration_seconds_total` | Cumulative query time - average latency is its rate over `queries_pooled`. | | `pgbouncer_stats_totals_client_wait_seconds_total` | Cumulative time clients spent waiting for a connection. | | `pgbouncer_stats_totals_received_bytes_total` | Bytes received from clients. | | `pgbouncer_stats_totals_sent_bytes_total` | Bytes sent to clients. | | `pgbouncer_client_connections` | Total client connections to PgBouncer. | | `pgbouncer_config_max_client_connections` | `max_client_conn` - the global client-connection ceiling. | | `pgbouncer_databases_current_connections` | Current server connections per database. | | `pgbouncer_databases_max_connections` | Configured per-database connection limit. | | `pgbouncer_databases_pool_size` | Configured pool size per database - the saturation denominator. | | `pgbouncer_databases_paused` | 1 when the database is paused (clients cannot connect). | | `pgbouncer_free_servers` | Free server-connection slots. | | `pgbouncer_used_servers` | Used server-connection slots. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. Grouped, not exhaustive - see the upstream reference for the full list. | Group | Representative metrics | When you reach for it | |---|---|---| | Prepared-statement counters | `pgbouncer_stats_totals_binds_total`, `pgbouncer_stats_totals_client_parses_total`, `pgbouncer_stats_totals_server_parses_total` | Prepared-statement parse / bind volume; these are newer SHOW STATS columns. | | Server-connection lifecycle | `pgbouncer_pools_server_login_connections`, `pgbouncer_pools_server_testing_connections`, `pgbouncer_pools_server_being_canceled_connections` | Backends stuck in login / testing / cancel transitions. | | Cancel requests | `pgbouncer_pools_client_active_cancel_connections`, `pgbouncer_pools_client_waiting_cancel_connections` | Cancellation activity during query cancels. | | Pool / database / user counts | `pgbouncer_pools`, `pgbouncer_databases`, `pgbouncer_users` | Topology size as you add databases and users. | | DNS cache | `pgbouncer_cached_dns_names`, `pgbouncer_in_flight_dns_queries` | Backend-host resolution when PgBouncer resolves by DNS. | | Version / build info | `pgbouncer_version_info`, `pgbouncer_exporter_build_info` | The running PgBouncer and exporter versions. | | Exporter handler stats | `promhttp_metric_handler_requests_total` | The exporter's own `/metrics` handler. | | Runtime / scrape meta | `go_*`, `process_*`, `scrape_duration_seconds` | Exporter Go-runtime and Prometheus scrape housekeeping series. | Full metric reference: [pgbouncer_exporter](https://github.com/prometheus-community/pgbouncer_exporter#metrics), or run `curl -s http://localhost:9127/metrics` against the exporter. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `up` | - | `== 0` for > 1m | No PgBouncer metrics are arriving - check the exporter container. | | `pgbouncer_up` | - | `== 0` for > 1m | The exporter is up but cannot reach PgBouncer's admin console - check PgBouncer and the stats user. | | `pgbouncer_pools_client_waiting_connections` | `> 0` sustained | Rising across scrapes | Clients are queuing for server connections - raise the pool size or fix slow queries holding connections. | | `pgbouncer_pools_client_maxwait_seconds` | `>` a few seconds | Growing | A client has waited too long for a connection; the pool is saturated and latency is added to every query. | | `pgbouncer_client_connections / pgbouncer_config_max_client_connections` | `> 0.9` | Approaching 1.0 | Approaching `max_client_conn` - new clients will be refused; raise the cap or shed load. | | `pgbouncer_databases_current_connections` vs `pgbouncer_databases_max_connections` | Approaching the limit | At the limit | A database has reached its connection limit. | | `pgbouncer_databases_paused` | - | `== 1` | A database is paused - clients cannot connect (maintenance or blocked). | | `pgbouncer_pools_server_idle_connections` | - | `== 0` with waiting clients `> 0` | Every backend is busy - the pool or the backend is the bottleneck. | The `max_client_conn` ratio compares the live client count against PgBouncer's own configured cap (`pgbouncer_config_max_client_connections`), not an invented absolute. The maxwait threshold is small fixed wait-time guidance - any client that has waited several seconds for a connection is on a saturated pool. ### Access Setup PgBouncer exposes statistics only over its admin console - the virtual `pgbouncer` database on the listen port (default `6432`). The exporter authenticates there as a stats user and runs the `SHOW` commands. #### 1. Create a monitoring user Add the exporter's connecting user to `stats_users` in `pgbouncer.ini`: ```ini showLineNumbers title="pgbouncer.ini" [pgbouncer] stats_users = otel_monitor ignore_startup_parameters = extra_float_digits ``` - `stats_users` grants read-only access to the `SHOW` commands the exporter runs (`SHOW STATS`, `SHOW POOLS`, `SHOW DATABASES`, `SHOW LISTS`). A user in `admin_users` also works. - `ignore_startup_parameters` is required because the exporter's PostgreSQL driver sends `extra_float_digits` during connection startup, which PgBouncer rejects by default. #### 2. Add authentication Add the monitoring user to `userlist.txt`: ```text showLineNumbers title="userlist.txt" "otel_monitor" "your_password" ``` #### 3. Verify access Confirm the user can read stats over the admin console: ```bash showLineNumbers title="Verify admin-console access" psql -p 6432 pgbouncer -c 'SHOW STATS;' # or with an explicit connection string: psql "postgres://otel_monitor:your_password@localhost:6432/pgbouncer?sslmode=disable" \ -c 'SHOW STATS;' ``` No write permissions are needed. The exporter only reads pool and traffic statistics. ### Configuration #### pgbouncer_exporter Run the exporter alongside PgBouncer. Its connection string points at PgBouncer's admin console - the virtual `pgbouncer` database on the listen port (default `6432`): ```bash showLineNumbers title="Run pgbouncer_exporter" docker run -d \ --name pgbouncer-exporter \ -p 9127:9127 \ prometheuscommunity/pgbouncer-exporter \ --pgBouncer.connectionString="postgres://${PGBOUNCER_USER}:${PGBOUNCER_PASSWORD}@${PGBOUNCER_HOST}:6432/pgbouncer?sslmode=disable" ``` The exporter listens on `:9127` and serves the `pgbouncer_*` metrics at `/metrics`. #### OTel Collector The `prometheus` receiver scrapes the exporter. The keep filter scopes collection to the PgBouncer surface and the scrape-liveness series, dropping the exporter's own `go_*` / `process_*` / `promhttp_*` runtime metrics: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: pgbouncer scrape_interval: 10s static_configs: - targets: - ${env:PGBOUNCER_EXPORTER_HOST}:9127 metric_relabel_configs: - source_labels: [__name__] regex: 'pgbouncer_.*|up' action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` To keep more or fewer series, adjust the `regex` in `metric_relabel_configs`. Dropping the keep filter entirely sends the exporter's runtime and scrape-meta metrics too. #### Environment Variables ```bash showLineNumbers title=".env" PGBOUNCER_HOST=pgbouncer PGBOUNCER_USER=otel_monitor PGBOUNCER_PASSWORD=your_password PGBOUNCER_EXPORTER_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the exporter and Collector, then check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm the admin console answers psql -p 6432 pgbouncer -c 'SHOW STATS' # Confirm the exporter is serving metrics and reached PgBouncer curl -s http://localhost:9127/metrics | grep pgbouncer_up # Expected: pgbouncer_up 1 # Check Collector logs for the scraped PgBouncer metrics docker logs otel-collector 2>&1 | grep -i "pgbouncer" ``` A healthy pipeline shows both `up` and `pgbouncer_up` at 1. ### Troubleshooting #### `pgbouncer_up` is 0 **Cause**: The exporter is running but cannot reach PgBouncer's admin console. **Look at**: `up` is 1 (the exporter scrape works) while `pgbouncer_up` is 0 (the exporter cannot talk to PgBouncer). **Fix**: 1. Check the exporter's connection string - host, port `6432`, and the virtual `pgbouncer` database. 2. Test the admin console manually: ```bash showLineNumbers title="Test the admin console" psql "postgres://otel_monitor:your_password@localhost:6432/pgbouncer?sslmode=disable" \ -c 'SHOW STATS' ``` 3. Confirm the connecting user is listed in `stats_users` or `admin_users` in `pgbouncer.ini`. 4. Confirm `ignore_startup_parameters` includes `extra_float_digits`. #### `up` is 0 **Cause**: The exporter container is down or unreachable from the Collector. **Fix**: 1. Verify the exporter is running: `docker ps | grep pgbouncer-exporter`. 2. Confirm `:9127` is reachable: `curl http://localhost:9127/metrics`. 3. Check firewall rules if the Collector runs on a separate host. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. #### Server connection counts read differently than expected **Cause**: Interpretation depends on the pool mode. Server-connection reuse, and thus the idle / active server counts, differs across session, transaction, and statement mode. **Look at**: the Diagnostic server-lifecycle series (`pgbouncer_pools_server_login_connections`, `pgbouncer_pools_server_testing_connections`) alongside `pgbouncer_pools_server_idle_connections` and `_active_connections` to see where backends sit. **Fix**: 1. Confirm the pool mode for the database (`SHOW DATABASES` / `pgbouncer.ini`). 2. Read idle / active counts against that mode - session mode pins a backend per client for the whole session; transaction mode returns it between transactions. ### FAQ #### Why do I need a separate exporter? PgBouncer exposes its statistics only over its admin console, not over HTTP, and there is no `pgbouncerreceiver` in collector-contrib. The `pgbouncer_exporter` connects to the admin console, runs `SHOW STATS` / `SHOW POOLS` / `SHOW DATABASES` / `SHOW LISTS`, and exposes `pgbouncer_*` in Prometheus format. The only pure-collector alternative is the `sqlqueryreceiver` pointed at the same admin console with hand-mapped `SHOW` queries (more config, custom metric names). #### What is the difference between `up` and `pgbouncer_up`? There are two liveness signals. `up` comes from the `prometheus` receiver and is 1 when the exporter's `/metrics` responded. `pgbouncer_up` comes from the exporter and is 1 when it could reach PgBouncer's admin console. Both at 1 is healthy; `up == 1` with `pgbouncer_up == 0` means the exporter is running but cannot talk to PgBouncer. #### Does this work with PgBouncer in Kubernetes? Yes. Run the `pgbouncer_exporter` as a sidecar in the same pod as PgBouncer, with its connection string pointed at the admin console on `localhost:6432` since both containers share the pod network. Supply the stats-user credentials via a Kubernetes secret. Point the Collector's scrape target at the pod IP or a headless service on `:9127`. #### What pool mode should I use, and does it change monitoring? The exporter works with all pool modes (`session`, `transaction`, `statement`). Pool mode does not change the monitoring interface - the exporter reads the admin console regardless - but it changes how to read the server-connection counts, because backend reuse differs across the modes. #### How do I monitor multiple databases or PgBouncer instances? The `pgbouncer_pools_*` and `pgbouncer_databases_*` families are labeled by database and user, so series multiply with `#databases x #users` on one instance. For multiple PgBouncer instances, run one exporter per instance and add each as a scrape target; the `instance` label differentiates them: ```yaml showLineNumbers title="config/otel-collector.yaml (multiple instances)" receivers: prometheus: config: scrape_configs: - job_name: pgbouncer scrape_interval: 10s static_configs: - targets: - pgbouncer-exporter-1:9127 - pgbouncer-exporter-2:9127 ``` #### Why are some `pgbouncer_stats_totals_*` metrics missing? The `pgbouncer_stats_totals_*` set reflects PgBouncer's `SHOW STATS` columns, and the prepared-statement parse / bind counters are newer columns. Older PgBouncer versions expose fewer of them - what you see depends on the PgBouncer version, not the exporter. ### Related Guides - [PostgreSQL Monitoring](./postgres.md) - Monitor the PostgreSQL backend PgBouncer pools in front of. - [HAProxy Monitoring](./haproxy.md) - Another exporter-fronted Prometheus surface in the data path. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [HAProxy](./haproxy.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your pool churn, and widen or narrow the keep filter to the series you want to retain. --- ## PostgreSQL Advanced OpenTelemetry Monitoring with pgdashex - Query Stats, Replication, and Table Metrics ## PostgreSQL Advanced Pgdashex is a PostgreSQL monitoring agent that collects comprehensive database metrics across 17 metric groups - including query statistics, table/index sizes, replication lag, lock activity, and background writer stats - and exposes them in Prometheus format. This guide deploys pgdashex, configures the OTel Collector to scrape its metrics, and ships them to base14 Scout. :::note Running this in production pgdashex metrics are read by pgX, the PostgreSQL monitoring app in base14 Scout. [Check out base14 pgX](https://base14.io/scout/pgx). ::: ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | PostgreSQL | 9.6 | 14+ | | pgdashex | v0.5.10 | v0.5.10 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - PostgreSQL must be accessible from the host running pgdashex - Superuser access for initial monitoring user creation - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md) ### What You'll Monitor - **Core**: connections, transactions, database size, backends - **Tables & Indexes**: table/index sizes, usage stats, sequence info - **Queries**: query performance via `pg_stat_statements` - **Replication**: lag, status, publications, subscriptions - **Locks & Vacuum**: lock statistics, vacuum/analyze progress - **System**: configuration settings, extensions, roles, tablespaces Full metric groups listed in [Configuration](#metric-groups) below. ### Access Setup Create a dedicated PostgreSQL user with monitoring privileges: ```sql showLineNumbers -- Connect as superuser (postgres) CREATE USER pgdashex_monitor WITH ENCRYPTED PASSWORD ''; GRANT pg_monitor TO pgdashex_monitor; -- Enable query statistics per database CREATE EXTENSION IF NOT EXISTS pg_stat_statements; ``` > **Note**: Learn more about these predefined roles: > [PostgreSQL Predefined Roles Documentation](https://www.postgresql.org/docs/current/predefined-roles.html) > > **Note**: The `pg_stat_statements` extension tracks query execution > statistics and helps identify slow-running queries. Learn how to configure it: > [pg_stat_statements Documentation](https://www.postgresql.org/docs/current/pgstatstatements.html) Test the connection: ```bash showLineNumbers psql -h -p 5432 -U pgdashex_user -d postgres -c "SELECT version();" ``` ### Docker Image Information #### Image Details - **Image Name**: `base14/pgdashex` - **Image Tag**: `base14/pgdashex:v0.5.10` #### Exposed Ports | Port | Protocol | Description | |------|----------|-------------| | `9187` | HTTP | Prometheus metrics endpoint | #### Quick Start Pull and run the Docker image: ```bash showLineNumbers docker pull base14/pgdashex:v0.5.10 docker run -d \ --name pgdashex \ -p 9187:9187 \ -e PG_HOST=your-postgres-host \ -e PG_PORT=5432 \ -e PG_USER=pgdashex_user \ -e PG_PASSWORD='your_secure_password' \ -e PG_DATABASE=postgres \ -e PGDASHEX_COLLECT_METRICS=all \ base14/pgdashex:v0.5.10 ``` **Note**: If PostgreSQL is on the host machine, use `host.docker.internal` as PG_HOST (Docker Desktop) or `--network host` (Linux). #### Example Docker Compose ```yaml showLineNumbers title="docker-compose.yaml" version: '3.8' services: pgdashex: image: base14/pgdashex:v0.5.10 container_name: pgdashex ports: - "9187:9187" environment: # Required PostgreSQL connection settings PG_HOST: postgres-host PG_PORT: 5432 PG_USER: pgdashex_user PG_PASSWORD: your_secure_password PG_DATABASE: postgres # Optional settings PG_SSLMODE: require COLLECT_INTERVAL: 30 PGDASHEX_COLLECT_METRICS: all # OpenTelemetry integration OTEL_ENABLED: "true" OTEL_ENDPOINT: http://otel-collector:4318 OTEL_SERVICE_NAME: pgdashex OTEL_ENVIRONMENT: production restart: unless-stopped ``` ### Integrating with Scout pgdashex exposes metrics in Prometheus format on port 9187. To send these metrics to Scout, configure your OpenTelemetry Collector to scrape pgdashex and forward to Scout. #### Configure OpenTelemetry Collector Update your Scout Collector configuration to scrape pgdashex metrics: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: # Scrape Prometheus metrics from pgdashex prometheus: config: scrape_configs: - job_name: 'pgdashex' scrape_interval: 30s static_configs: - targets: ['pgdashex:9187'] # Receive traces from pgdashex (if OTEL_ENABLED=true) otlp: protocols: http: endpoint: 0.0.0.0:4318 processors: batch: timeout: 10s send_batch_size: 1024 resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert extensions: oauth2client: client_id: __YOUR_CLIENT_ID__ client_secret: __YOUR_CLIENT_SECRET__ endpoint_params: audience: b14collector token_url: https://id.b14.dev/realms/__ORG_NAME__/protocol/openid-connect/token tls: insecure_skip_verify: true exporters: otlp/scout: endpoint: https://api.scout.base14.io:4317 auth: authenticator: oauth2client tls: insecure_skip_verify: true service: extensions: [oauth2client] pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlp/scout] traces: receivers: [otlp] processors: [resource, batch] exporters: [otlp/scout] ``` ### Configuration #### Environment Variables pgdashex is configured using environment variables: | Variable | Default | Description | |----------|---------|-------------| | `PG_HOST` | `localhost` | PostgreSQL server hostname | | `PG_PORT` | `5432` | PostgreSQL server port | | `PG_USER` | `postgres` | PostgreSQL username | | `PG_PASSWORD` | - | PostgreSQL password (special characters areauto-encoded) | | `PG_DATABASE` | `postgres` | PostgreSQL database name | | `PG_SSLMODE` | `disable` | SSL mode (`disable`, `require`, `verify-ca`,`verify-full`) | | `PG_ALL_DBS` | `false` | Collect metrics from all databases in the cluster | | `PG_DATABASES` | - | Comma-separated list of databases to monitor(overrides `PG_ALL_DBS`) | | `CLUSTER_NAME` | - | Cluster name label added to all metrics(falls back to connection hostname if not set) | | `LISTEN_ADDRESS` | `:9187` | Address to expose metrics | | `METRICS_PATH` | `/metrics` | Path to expose metrics | | `SCRAPE_TIMEOUT` | `10` | Timeout in seconds for metrics collection | | `COLLECT_INTERVAL` | `30` | Interval in seconds between collections | | `PGDASHEX_COLLECT_METRICS` | `basic` | Metric groups to collect (see below) | | `TLS_ENABLED` | `false` | Enable TLS for metrics endpoint | | `TLS_CERT_FILE` | - | Path to TLS certificate file | | `TLS_KEY_FILE` | - | Path to TLS key file | | `OTEL_ENABLED` | `true` | Enable OpenTelemetry tracing | | `OTEL_ENDPOINT` | `http://localhost:4318` | OpenTelemetry collector endpoint | | `OTEL_SERVICE_NAME` | `pgdashex` | Service name for traces | | `OTEL_ENVIRONMENT` | `development` | Environment name for traces | #### Metric Groups Control which metrics are collected using the `PGDASHEX_COLLECT_METRICS` environment variable: **Predefined Values:** - `all` - Collect all available metrics (recommended for comprehensive monitoring) - `basic` - Collect essential metrics only (lower overhead) **Custom Groups:** Specify a comma-separated list of metric groups: ```bash showLineNumbers PGDASHEX_COLLECT_METRICS=basic,tables,indexes,queries,replication ``` **Available Metric Groups:** - `basic` - Core database metrics (connections, transactions, database size) - `tables` - Table statistics and sizes - `indexes` - Index usage and sizes - `queries` - Query performance (requires pg_stat_statements) - `replication` - Replication lag and status - `backends` - Active connections and backend processes - `locks` - Lock statistics - `sequences` - Sequence information - `functions` - Function statistics - `system` - System-level metrics - `settings` - PostgreSQL configuration - `extensions` - Installed extensions - `tablespaces` - Tablespace information - `progress` - Vacuum and analyze progress - `publications` - Logical replication publications - `subscriptions` - Logical replication subscriptions - `metadata` - Database metadata - `roles` - User and role information **Examples:** ```bash showLineNumbers # Collect all metrics PGDASHEX_COLLECT_METRICS=all # Collect basic metrics plus table and index stats PGDASHEX_COLLECT_METRICS=basic,tables,indexes # Comprehensive monitoring for production PGDASHEX_COLLECT_METRICS=basic,tables,indexes,queries,replication,backends,locks ``` ### Troubleshooting #### pgdashex cannot connect to PostgreSQL **Cause**: Network, credentials, or SSL configuration issue. **Fix**: ```bash showLineNumbers # Test PostgreSQL connection psql -h $PG_HOST -p $PG_PORT -U $PG_USER -d $PG_DATABASE -c "SELECT version();" ``` 1. Verify hostname and port are correct 2. Check `pg_hba.conf` allows connections from the pgdashex host 3. Confirm SSL mode matches your PostgreSQL configuration 4. Check firewall rules between pgdashex and PostgreSQL #### No metrics on port 9187 **Cause**: pgdashex is not running or the port is not exposed. **Fix**: 1. Check container status: `docker ps | grep pgdashex` 2. Verify port mapping: `curl -s http://localhost:9187/metrics | head -20` 3. Check pgdashex logs: `docker logs pgdashex` #### Query statistics not appearing **Cause**: `pg_stat_statements` extension is not installed or the metric group is not enabled. **Fix**: 1. Verify the extension: `SELECT * FROM pg_extension WHERE extname = 'pg_stat_statements';` 2. Ensure `PGDASHEX_COLLECT_METRICS` includes `queries` or is set to `all` ### FAQ #### What is the difference between Basic and Advanced PostgreSQL monitoring? The [Basic guide](./postgres.md) uses the OTel PostgreSQL receiver for core database metrics (34 metrics). This Advanced guide uses pgdashex, which collects deeper metrics across 17 groups including query-level statistics, per-table I/O, and logical replication. #### Can I run pgdashex alongside the Basic PostgreSQL receiver? Yes. They collect different metrics and use different endpoints. The Basic receiver connects directly to PostgreSQL, while pgdashex exposes a Prometheus endpoint that the Collector scrapes separately. #### How do I monitor multiple PostgreSQL databases? Set `PG_ALL_DBS=true` to monitor all databases in the cluster, or use `PG_DATABASES=db1,db2,db3` to monitor specific databases. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) - **Monitor More Components**: Add monitoring for [MySQL](./mysql.md), [MongoDB](./mongodb.md), and other components - **Fine-tune Collection**: Optimize metric groups using `PGDASHEX_COLLECT_METRICS` - use `basic,tables,indexes,queries` for targeted monitoring or `all` for comprehensive coverage ### Related Guides - [PostgreSQL Basic Monitoring](./postgres.md) - Core PostgreSQL metrics via OTel receiver - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) — Advanced collector configuration - [Docker Compose Setup](../collector-setup/docker-compose-example.md) — Collector setup with Docker Compose - [Filtering pgX Metrics](../../operate/filters-and-transformations/filtering-pgx-metrics.md) - Filter and tune pgdashex metrics in the Collector pipeline --- ## PostgreSQL OpenTelemetry Monitoring - Connections, Transactions, and Collector Setup ## PostgreSQL Basic The OpenTelemetry Collector's PostgreSQL receiver collects 23 metrics from PostgreSQL, including backend connections, transaction commit and rollback throughput, lock and deadlock activity, cache-miss pressure, and per-table and per-index statistics. This guide configures the receiver, sets up a read-only monitoring user, and ships metrics to base14 Scout. > For advanced monitoring with query statistics, per-table I/O, and > replication details, see > [PostgreSQL Advanced Monitoring](./postgres-advanced.md). :::note Running this in production pgX adds query, lock, and connection analysis on top of these metrics. [Check out base14 pgX](https://base14.io/scout/pgx). ::: ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | PostgreSQL | 9.6 | 18+ | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | — | Before starting: - PostgreSQL must be accessible from the host running the Collector. - Superuser access once, to create the monitoring user. - A read-only monitoring account with the `pg_monitor` role (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `postgresql.backends` | Active backend connections - reachability plus connection load. | | `postgresql.commits` | Committed transactions; the headline throughput KPI. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `postgresql.rollbacks` | Rolled-back transactions - an abort / error signal. | | `postgresql.deadlocks` | Deadlocks detected; lock-ordering contention. | | `postgresql.database.locks` | Locks held, by mode - contention pressure. | | `postgresql.connection.max` | Configured max connections; the saturation ceiling for `backends`. | | `postgresql.db_size` | On-disk database size - capacity trend. | | `postgresql.blocks_read` | Disk blocks read; cache-miss / IO pressure. | | `postgresql.temp_files` | Temp files written - query spill to disk. | | `postgresql.sequential_scans` | Sequential scans; a missing-index signal. | #### Diagnostic - for investigation and tuning Higher cardinality - per-table, per-index, and background-writer internals. Enable on demand; in production you can drop this tier to control metric volume and keep Core + Operational. | Metric | What it tells you | |---|---| | `postgresql.rows` | Rows read / returned, by operation. | | `postgresql.operations` | Row operations (insert / update / delete / hot). | | `postgresql.database.count` | Number of databases on the server. | | `postgresql.table.count` | Live and dead tables. | | `postgresql.table.size` | Per-table on-disk size. | | `postgresql.table.vacuum.count` | Vacuum operations per table. | | `postgresql.index.scans` | Index scans per index. | | `postgresql.index.size` | Per-index on-disk size. | | `postgresql.bgwriter.buffers.allocated` | Buffers allocated. | | `postgresql.bgwriter.buffers.writes` | Buffers written, by source. | | `postgresql.bgwriter.checkpoint.count` | Checkpoints, by type. | | `postgresql.bgwriter.duration` | Checkpoint write / sync time. | | `postgresql.bgwriter.maxwritten` | Background-writer stop-on-maxwritten count. | `postgresql.wal.age` and `postgresql.wal.lag` are worth enabling but stay silent on a single-node server with no replication slot or standby - they need replication context to emit. Keep them enabled; both surface once replication is configured. Full metric reference: [OTel PostgreSQL Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/postgresqlreceiver) ### Key Alerts to Configure Threshold guidance for the most useful Operational-tier series. Tune to your workload; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `postgresql.backends` vs `postgresql.connection.max` | > 80% of max | Approaching max | The app starts failing to connect. Raise `max_connections` or add a connection pooler. | | `rate(postgresql.rollbacks) / rate(postgresql.commits)` | Rising vs baseline | Sustained climb | App errors or contention; inspect the failing transactions. | | `rate(postgresql.deadlocks)` | > 0 | Sustained > 0 | Lock-ordering contention; review transaction access patterns. | | `rate(postgresql.temp_files)` | > 0 rising | Sustained rise | `work_mem` is too small for the workload; tune it or optimise the queries. | | `rate(postgresql.blocks_read)` | Rising vs baseline | Sustained rise | `shared_buffers` undersized or the working set grew; review IO. | | `postgresql.db_size` | Growth trend | Approaching volume capacity | Plan storage before the volume fills. | ### Access Setup Create a dedicated read-only monitoring user. The `pg_monitor` role grants access to all the statistics views and functions the receiver queries, without superuser privileges. ```sql showLineNumbers title="postgres monitoring user setup" -- Connect as a superuser (e.g. postgres) CREATE USER otel_monitor WITH PASSWORD ''; GRANT pg_monitor TO otel_monitor; ``` **Minimum required permissions:** - `pg_monitor`: read access to `pg_stat_*` views for connection, transaction, lock, table, and index statistics. The role exists on PostgreSQL 10+; on 9.6 grant `pg_stat_scan_tables` and access to `pg_stat_activity` individually. No write permissions are needed. Test connectivity with the monitoring user: ```bash showLineNumbers title="Verify access" psql -h localhost -p 5432 -U otel_monitor -d \ -c "SELECT version();" ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: postgresql: endpoint: localhost:5432 # Change to your PostgreSQL address username: ${env:POSTGRES_USER} password: ${env:POSTGRES_PASSWORD} databases: - # One or more databases to monitor collection_interval: 10s tls: insecure_skip_verify: true # Set to false with TLS in production metrics: postgresql.connection.max: enabled: true postgresql.database.locks: enabled: true postgresql.deadlocks: enabled: true postgresql.sequential_scans: enabled: true postgresql.temp_files: enabled: true postgresql.wal.age: enabled: true # Emits once replication is configured postgresql.wal.lag: enabled: true # Emits once a standby is connected processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [postgresql] processors: [resource, batch] exporters: [otlphttp/b14] ``` The metrics not listed in the `metrics:` block are enabled by the receiver by default; the entries above turn on the ones that are off by default and that this guide relies on. To control metric volume in production, drop the Diagnostic tier with a `filter` processor while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" POSTGRES_USER=otel_monitor POSTGRES_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for the PostgreSQL receiver starting docker logs otel-collector 2>&1 | grep -i "postgresql" # Confirm the monitoring user can reach the server psql -h localhost -p 5432 -U otel_monitor -d \ -c "SELECT version();" ``` A few of the headline series only populate after the server does work, so run some traffic and confirm `postgresql.commits` and `postgresql.backends` move: ```sql showLineNumbers -- Connection load and transaction counts SELECT numbackends, xact_commit, xact_rollback FROM pg_stat_database WHERE datname = ''; ``` ### Troubleshooting #### Connection refused **Cause**: The Collector cannot reach PostgreSQL at the configured endpoint. **Fix**: 1. Verify PostgreSQL is running: `docker ps | grep postgres` or `systemctl status postgresql`. 2. Confirm `pg_hba.conf` allows connections from the Collector host. 3. Check PostgreSQL is listening on the expected port: `ss -tlnp | grep 5432`. #### Authentication failed **Cause**: The monitoring credentials are wrong, or the user lacks the `pg_monitor` role. **Fix**: 1. Test credentials directly: `psql -h localhost -U otel_monitor -d postgres`. 2. Verify the role is granted: `SELECT rolname FROM pg_roles WHERE pg_has_role('otel_monitor', oid, 'member');`. #### Queries are spilling to disk or the cache is thrashing **Cause**: `work_mem` is too small for the workload, or `shared_buffers` is undersized and the working set no longer fits in cache. **Look at**: `postgresql.temp_files` - a rising rate means sorts and hashes are spilling to disk. `postgresql.blocks_read` climbing against a flat buffer-hit trend means reads are missing the buffer cache. The Diagnostic `postgresql.sequential_scans` and `postgresql.index.scans` series tell you whether a query is scanning a table instead of using an index. **Fix**: 1. Raise `work_mem` for sort / hash-heavy workloads if `temp_files` climbs. 2. Increase `shared_buffers` or add an index where `sequential_scans` dominates for a large table. #### WAL metrics show null or zero **Cause**: `postgresql.wal.age` and `postgresql.wal.lag` need replication context. On a single-node server with no standby or replication slot they do not emit. **Fix**: 1. Keep both metrics enabled - they surface automatically once a replica connects or a replication slot exists. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with PostgreSQL running in Kubernetes? Yes. Set `endpoint` to the PostgreSQL service DNS (e.g., `postgresql.default.svc.cluster.local:5432`) and inject the credentials via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### What permissions does the monitoring account need? The `pg_monitor` role. It grants read access to the `pg_stat_*` views the receiver queries. No write access is required. #### How do I monitor multiple PostgreSQL instances with OpenTelemetry? Add multiple receiver blocks with distinct names, then include both in the pipeline: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: postgresql/primary: endpoint: primary:5432 username: ${env:POSTGRES_USER} password: ${env:POSTGRES_PASSWORD} databases: [] postgresql/replica: endpoint: replica:5432 username: ${env:POSTGRES_USER} password: ${env:POSTGRES_PASSWORD} databases: [] service: pipelines: metrics: receivers: [postgresql/primary, postgresql/replica] ``` #### What is the difference between Basic and Advanced PostgreSQL monitoring? This guide uses the OTel PostgreSQL receiver for core database metrics. The [Advanced guide](./postgres-advanced.md) adds deeper query-level statistics, per-table I/O, and detailed replication monitoring. #### Why are the WAL metrics not showing up? `postgresql.wal.age` and `postgresql.wal.lag` only emit once replication is configured. On a single-node server with no standby or replication slot they stay silent even when enabled. Keep them on and they surface once a replica connects. ### Related Guides - [PostgreSQL Advanced](./postgres-advanced.md) - Deeper query and table-level monitoring. - [Azure Database for PostgreSQL](../infra/azure/database-for-postgresql.md) - Managed Flexible Server delta on this guide: Azure Monitor surface metrics, `azure_pg_admin` grants, `pg_stat_statements` via Server Parameters, and the Diagnostic Settings → Event Hubs logs path. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [MySQL Monitoring](./mysql.md) - A common companion relational database. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [MySQL](./mysql.md), [MongoDB](./mongodb.md), and other components. - **Go Deeper**: Start with the [Advanced monitoring guide](./postgres-advanced.md) for query-level statistics and per-table metrics. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Pulsar OpenTelemetry Monitoring - Broker Throughput, Message Backlog, and Collector Setup ## Pulsar Apache Pulsar serves Prometheus text at `/metrics` on its web port (`:8080`). A standalone process hosts the broker, the BookKeeper managed-ledger storage, and the functions worker together, and exposes all of their metrics on that one endpoint. The OpenTelemetry Collector's `prometheus` receiver scrapes it, collecting 270+ metrics from Pulsar 2.x+ across broker message rate / throughput / backlog and publish latency, per-topic and per-subscription rates and backlog, the BookKeeper storage write-latency path, and the JVM runtime. This guide configures the receiver and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | -------------- | | Apache Pulsar | 2.x | 4.x (4.0.3) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The Pulsar web port (`8080`) must be reachable from the host running the Collector. - Metrics are enabled by default - no configuration changes are needed on the Pulsar side. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things shape this surface, and they matter for every tier below: - **`up` is the liveness signal here.** The `prometheus` receiver emits `up` = 1 when `/metrics` responds - that is the scrape liveness signal. `pulsar_health` (Pulsar 4.0.0+) is Pulsar's own broker self health-check (1 = healthy), and broker-wide backlog (`pulsar_broker_msg_backlog`) is the headline "are consumers keeping up" signal. - **Standalone collapses several roles into one `/metrics`.** Broker aggregates (`pulsar_broker_*`), per-topic series (`pulsar_*` with a `topic` label), per-subscription series (`pulsar_subscription_*`), and the BookKeeper managed-ledger internals (`pulsar_ml_*`) all come from the same endpoint. A real cluster splits these across broker, bookie, and function-worker processes - the metric names are identical, so the same scrape config applies per process. - **Two write paths, two latency histograms.** `pulsar_broker_publish_latency` is the producer-facing publish latency, while `pulsar_storage_write_latency_*` and `pulsar_storage_ledger_write_latency_*` are the BookKeeper persistence latencies behind it. Compare them to localize a publish slowdown to broker vs storage. - **Histograms expand into buckets.** The `_le_*` / `_sum` / `_count` families are Pulsar's native bucket layout, not OTel exponential histograms; the receiver keeps each bucket as its own series. - **Managed-ledger names keep their case as exposed.** `pulsar_ml_AddEntryErrors`, `pulsar_ml_ReadEntriesRate`, and `pulsar_ml_StoredMessagesSize` reproduce BookKeeper's camel-case exactly - they are not normalized to snake_case. - **The per-topic, per-subscription, and managed-ledger families warm up under traffic.** They populate only after a topic exists and produces / consumes - a fresh idle standalone shows mostly broker-level zeros plus the JVM runtime. Left enabled, they populate once traffic flows. - **The JVM / Jetty / Caffeine / process families are the host runtime**, not Pulsar product signals: `jvm_*`, `jetty_*`, `caffeine_cache_*`, `process_*`. Filter to `pulsar_.*|up` with a keep rule if the runtime is covered elsewhere. #### Core - is it up, moving messages, and keeping consumers fed | Metric | What it tells you | |---|---| | `up` | Scrape liveness - 1 = the Pulsar metrics endpoint responded. The liveness signal on this surface. | | `pulsar_health` | Broker self health-check result - 1 = healthy (Pulsar 4.0.0+). | | `pulsar_broker_rate_in` | Broker-wide messages published per second - headline ingest throughput. | | `pulsar_broker_rate_out` | Broker-wide messages dispatched per second - headline delivery throughput. | | `pulsar_broker_msg_backlog` | Broker-wide unacked-message backlog - the headline "are consumers keeping up" signal. | | `pulsar_broker_publish_latency` | Producer-facing publish latency - the write SLO. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Broker throughput | `pulsar_broker_throughput_in`, `pulsar_broker_throughput_out` | Broker-wide inbound / outbound bytes per second. | | Broker entity counts | `pulsar_broker_topics_count`, `pulsar_broker_subscriptions_count`, `pulsar_broker_producers_count`, `pulsar_broker_consumers_count`, `pulsar_active_connections` | Topics, subscriptions, producers, consumers, and live client connections on the broker. | | Dispatch backpressure | `pulsar_broker_pending_bytes_to_dispatch`, `pulsar_broker_throttled_connections` | Bytes queued for dispatch and connections being throttled - producers hitting rate limits. | | Lookup path | `pulsar_broker_lookup_failures_total`, `pulsar_broker_lookup_pending_requests`, `pulsar_broker_topic_load_pending_requests` | Failed topic lookups, lookups in flight, and queued topic-load requests. | | Broker storage | `pulsar_broker_storage_size`, `pulsar_broker_storage_write_rate`, `pulsar_broker_storage_read_rate`, `pulsar_broker_storage_read_cache_misses_rate`, `pulsar_broker_storage_backlog_quota_exceeded_evictions_total` | Stored size, write / read rates, read-cache misses, and messages evicted by quota policy (data loss). | | Per-topic rate / throughput | `pulsar_rate_in`, `pulsar_rate_out`, `pulsar_throughput_in`, `pulsar_throughput_out`, `pulsar_publish_rate_limit_times` | Per-topic publish / dispatch message rate, bytes per second, and rate-limit hits. | | Per-topic backlog | `pulsar_msg_backlog`, `pulsar_storage_backlog_size`, `pulsar_storage_backlog_age_seconds`, `pulsar_storage_backlog_quota_limit` | Per-topic unacked backlog, backlog bytes, age of the oldest unacked message, and the configured quota. | | Storage write latency | `pulsar_storage_write_latency_sum`, `pulsar_storage_write_latency_count`, `pulsar_storage_write_latency_le_*` | Per-topic persistence write-latency distribution - the storage write SLO behind a publish. | | Per-subscription health | `pulsar_subscription_back_log`, `pulsar_subscription_unacked_messages`, `pulsar_subscription_blocked_on_unacked_messages`, `pulsar_subscription_msg_rate_redeliver`, `pulsar_subscription_msg_drop_rate`, `pulsar_subscription_msg_rate_out` | Per-subscription backlog, unacked count, the blocked flag, redelivery and drop rate, and dispatch rate. | | Write errors | `pulsar_ml_AddEntryErrors`, `pulsar_ml_ReadEntriesErrors` | Managed-ledger entry-write / read errors - the BookKeeper path is failing. | | Topic load / metadata | `pulsar_topic_load_failed_count`, `pulsar_metadata_store_ops_latency_ms` | Failed topic loads and metadata-store (ZooKeeper / RocksDB) operation latency - slow metadata stalls topic ops cluster-wide. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. | Group | Representative metrics | When you reach for it | |---|---|---| | Per-topic detail | `pulsar_average_msg_size`, `pulsar_in_bytes_total`, `pulsar_out_bytes_total`, `pulsar_in_messages_total`, `pulsar_out_messages_total`, `pulsar_storage_logical_size`, `pulsar_storage_offloaded_size`, `pulsar_storage_write_rate`, `pulsar_delayed_message_index_size_bytes` | Per-topic byte / message totals, logical and offloaded storage size, and delayed-delivery index size. | | Entry-size / ledger-write histograms | `pulsar_entry_size_sum` / `_count` / `_le_*`, `pulsar_storage_ledger_write_latency_sum` / `_count` / `_le_*` | The message-entry size distribution and the BookKeeper ledger write latency behind the topic write path. | | Per-namespace counts | `pulsar_producers_count`, `pulsar_consumers_count`, `pulsar_subscriptions_count`, `pulsar_topics_count` | Per-namespace producer / consumer / subscription / topic accounting. | | Per-subscription detail | `pulsar_subscription_consumers_count`, `pulsar_subscription_msg_ack_rate`, `pulsar_subscription_msg_throughput_out`, `pulsar_subscription_msg_rate_expired`, `pulsar_subscription_delayed`, `pulsar_subscription_in_replay` | Consumer count, ack rate, outbound throughput, TTL expiry, and delayed / replay detail on a subscription. | | Subscription progress timestamps | `pulsar_subscription_last_acked_timestamp`, `pulsar_subscription_last_consumed_timestamp`, `pulsar_subscription_last_mark_delete_advanced_timestamp` | A stalled timestamp marks a stuck consumer. | | Subscription server-side filters | `pulsar_subscription_filter_accepted_msg_count`, `pulsar_subscription_filter_rejected_msg_count`, `pulsar_subscription_filter_rescheduled_msg_count` | Outcomes when a subscription has a server-side selector attached. | | Managed-ledger internals | `pulsar_ml_AddEntryBytesRate`, `pulsar_ml_ReadEntriesRate`, `pulsar_ml_StoredMessagesSize`, `pulsar_ml_NumberOfMessagesInBacklog`, `pulsar_ml_MarkDeleteRate`, `pulsar_ml_cache_*`, `pulsar_ml_AddEntryLatencyBuckets`, `pulsar_ml_LedgerSwitchLatencyBuckets` | BookKeeper add / read rates, stored size, mark-delete rate, the read cache, and the latency bucket layouts. | | Schema registry / topic load | `pulsar_schema_get_ops_latency`, `pulsar_schema_put_ops_latency`, `pulsar_topic_load_rate_s`, `pulsar_topic_load_times`, `pulsar_topic_load_time_*_ms` | Schema read / write latency and topic-load rate / time percentiles. | | Transactions / resource groups | `pulsar_txn_tb_active_total`, `pulsar_txn_tb_committed_total`, `pulsar_txn_tb_aborted_total`, `pulsar_resource_group_aggregate_usage_secs`, `pulsar_resource_group_calculate_quota_secs` | Transaction-buffer counts and resource-group usage / quota timings. | | Functions worker | `pulsar_function_worker_*` | Functions-worker scheduling, rebalance, instance-count, and leader state. | | Web thread pool | `pulsar_web_executor_active_threads`, `pulsar_web_executor_idle_threads`, `pulsar_web_executor_max_threads` | Web / admin thread-pool sizing. | | JVM / Jetty / Caffeine / process runtime | `jvm_memory_bytes_used`, `jvm_memory_direct_bytes_used`, `jvm_gc_collection_seconds`, `jvm_threads_current`, `jetty_*`, `caffeine_cache_*`, `process_cpu_seconds_total`, `process_resident_memory_bytes`, `log4j2_appender_total` | Host runtime - heap, off-heap direct memory, GC, threads, the admin HTTP server, in-process caches, and OS process stats. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped` | Receiver-side scrape health, not from Pulsar. | Full metric list: run `curl -s http://localhost:8080/metrics` against your Pulsar broker. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Threshold | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The metrics endpoint stopped responding - check the broker process and the web port. | | `pulsar_health` | `< 1` | The broker self health-check is failing (Pulsar 4.0.0+) - check BookKeeper and the metadata store. | | `pulsar_broker_msg_backlog` / `pulsar_storage_backlog_age_seconds` | Backlog rising vs baseline, or age climbing | Consumers are not keeping up - scale consumers or investigate slow processing. | | `pulsar_subscription_blocked_on_unacked_messages` | `== 1` | A subscription hit its unacked-message limit - consumers are not acking; check consumer health. | | `pulsar_subscription_msg_rate_redeliver` | Rising vs baseline | Consumers are failing to ack and messages are being redelivered - check consumer errors and ack timeout. | | `pulsar_ml_AddEntryErrors` | `> 0` | The BookKeeper write path is failing - check bookie health and disk. | | `pulsar_broker_publish_latency` / `pulsar_storage_write_latency_*` | p99 rising vs baseline | Writes are slow - compare broker vs storage latency to localize. | | `rate(pulsar_broker_storage_backlog_quota_exceeded_evictions_total)` | `> 0` | Messages are being evicted by quota policy (data loss) - raise the quota or drain the backlog. | | `rate(pulsar_broker_lookup_failures_total)` | `> 0` | Clients cannot resolve topic ownership - check the metadata store and broker load. | | `pulsar_metadata_store_ops_latency_ms` | p99 rising vs baseline | Slow metadata operations stall topic load / unload cluster-wide - check ZooKeeper / RocksDB. | The liveness, health, blocked-flag, and error / eviction alerts read states or events; the latency and backlog alerts are relative to your own baseline. Set absolute thresholds only against your own workload and provisioned capacity. ### Access Setup Pulsar exposes Prometheus metrics natively - no exporter sidecar is needed. The `/metrics` endpoint on the web port (`8080`) is unauthenticated by default. Bring up a standalone instance, which runs the broker, BookKeeper storage, and functions worker in one process: ```bash showLineNumbers title="Run Pulsar standalone" docker run -d --name pulsar \ -p 6650:6650 -p 8080:8080 \ apachepulsar/pulsar:4.0.3 \ bin/pulsar standalone ``` Verify the metrics endpoint is serving: ```bash showLineNumbers title="Verify access" # Confirm the broker is healthy curl -s http://localhost:8080/admin/v2/brokers/health # Confirm the Prometheus endpoint responds curl -s http://localhost:8080/metrics | head -20 ``` A secured production cluster fronts the web port with TLS and authentication. When metrics are behind auth, point the scrape job at `https` and supply the broker's credentials to the receiver; restrict the endpoint at the network layer either way. ### Configuration The recommended config scrapes Pulsar's `/metrics` and keeps only the Pulsar series with a `metric_relabel_configs` keep filter, dropping the JVM / Jetty / Caffeine runtime noise the endpoint also emits: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: pulsar scrape_interval: 10s static_configs: - targets: - ${env:PULSAR_HOST}:8080 # Pulsar web port; default /metrics metric_relabel_configs: - source_labels: [__name__] regex: "pulsar_.*|up" action: keep processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The keep filter scopes collection to the `pulsar_*` product families plus the `up` liveness series, and drops the `jvm_*` / `jetty_*` / `caffeine_cache_*` / `process_*` host-runtime series. Remove the filter if you want the runtime in Scout too. #### Environment Variables ```bash showLineNumbers title=".env" PULSAR_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Pulsar metrics docker logs otel-collector 2>&1 | grep -i "pulsar" # Confirm the broker health metric is exposed curl -s http://localhost:8080/metrics | grep pulsar_health # Confirm broker throughput is exposed curl -s http://localhost:8080/metrics | grep pulsar_broker_rate_in ``` ### Troubleshooting #### Connection refused on port 8080 **Cause**: The Collector cannot reach the Pulsar web endpoint. **Fix**: 1. Verify Pulsar is running: `docker ps | grep pulsar` or `bin/pulsar-admin brokers list`. 2. Confirm the web port is open: `curl http://localhost:8080/metrics`. 3. Check firewall rules if the Collector runs on a separate host. #### Only broker-level metrics appear **Cause**: There is no topic with traffic yet. The per-topic (`pulsar_*` with a `topic` label), per-subscription (`pulsar_subscription_*`), and managed-ledger (`pulsar_ml_*`) families populate only once a topic exists and produces / consumes. **Look at**: the broker-level series first - if `pulsar_broker_*` populates but the per-topic / per-subscription / `pulsar_ml_*` families read 0 or are absent, the broker is healthy and simply idle. **Fix**: 1. Create a topic and produce a test message: `bin/pulsar-client produce persistent://public/default/test -m "hello"`. 2. Run a consumer so the subscription and managed-ledger families advance. 3. Re-check: `curl -s http://localhost:8080/metrics | grep pulsar_subscription`. #### Publish latency is high **Cause**: Writes are slow, either at the broker or in BookKeeper storage. **Look at**: `pulsar_broker_publish_latency` against the storage latencies - `pulsar_storage_write_latency_*` and the Diagnostic `pulsar_storage_ledger_write_latency_*`. If the storage latency tracks the publish latency, the bottleneck is BookKeeper; if not, it is broker-side. Check `pulsar_ml_AddEntryErrors` for write-path failures. **Fix**: 1. Inspect bookie health and disk if storage latency is climbing. 2. Check broker CPU and `jvm_gc_collection_seconds` if the broker side is slow. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Pulsar running in Kubernetes? Yes. Set the Collector's `targets` to the broker's web-port service DNS (e.g., `pulsar-broker.pulsar.svc.cluster.local:8080`). With the Apache Pulsar Helm chart the broker web port is exposed by default. The Collector can run as a sidecar or a DaemonSet. #### What is the difference between standalone and a cluster for monitoring? Standalone runs the broker, BookKeeper bookie, and functions worker in one process, so all metrics come from one `/metrics`. A production cluster splits those roles across separate processes - the metric names are the same, so add a scrape job per broker, bookie, and function-worker endpoint: ```yaml showLineNumbers title="config/otel-collector.yaml (cluster)" receivers: prometheus: config: scrape_configs: - job_name: pulsar-broker static_configs: - targets: - broker-1:8080 - broker-2:8080 - job_name: pulsar-bookie static_configs: - targets: - bookie-1:8000 - bookie-2:8000 - job_name: pulsar-function-worker static_configs: - targets: - fn-worker-1:6750 ``` Each process is scraped independently and identified by its `instance` label. #### Why do I only see broker-level metrics? The per-topic, per-subscription, and managed-ledger families populate only once a topic exists and has active producers or consumers. An idle standalone shows mostly broker-level zeros plus the JVM runtime. Produce and consume on a topic to advance them. #### Why are the `pulsar_ml_*` metrics in camel-case? The BookKeeper managed-ledger family (`pulsar_ml_AddEntryErrors`, `pulsar_ml_ReadEntriesRate`, `pulsar_ml_StoredMessagesSize`, and the rest) keeps BookKeeper's camel-case by design. The `prometheus` receiver reproduces the name exactly as exposed and does not normalize it to snake_case. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Pulsar metrics. - [Kafka Monitoring](./kafka.md) - Consumer lag and partition offsets for another high-throughput streaming broker. - [RabbitMQ Monitoring](./rabbitmq.md) - Queue depth and consumer health for a classic message queue. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Kafka](./kafka.md), [RabbitMQ](./rabbitmq.md), and other components. - **Fine-tune Collection**: The Diagnostic tier is higher cardinality. You can scope its collection with `metric_relabel_configs` if you need to, and reach for it during incident investigation. --- ## Qdrant OpenTelemetry Monitoring - Search Latency, Collection Points, and Collector Setup ## Qdrant Qdrant serves Prometheus text at `/metrics` on its REST port (`6333`) with no flag to enable it. The OpenTelemetry Collector scrapes it with the Prometheus receiver, collecting request rate, error rate and latency for the points data plane, per-collection point and vector counts, the write and optimization queue, and the memory, mmap and file-descriptor ceilings a Qdrant node actually hits. A node with collections and traffic exposes 49 metric names. This guide configures the receiver, sets the metric prefix, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Qdrant | 1.16 | 1.19 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Qdrant 1.16 introduced `QDRANT__SERVICE__METRICS_PREFIX`. Below it there is no way to namespace the metric names, and the generic defaults (`app_info`, `collections_total`, `memory_resident_bytes`) are the only option. Before starting: - The REST port (`6333`) must be reachable from the host running the Collector. `/metrics` is served there, always on, with no flag to enable it. - `/metrics` has no authentication and sits on the same port as the REST API, so it must not be exposed publicly. Scrape Qdrant on the internal network, or exempt the `/metrics` path at a fronting proxy. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). :::warning Adopting the metric prefix? Metric names are unprefixed unless you set `QDRANT__SERVICE__METRICS_PREFIX`. Turning it on renames every series, so dashboards and alert rules have to change in lockstep. Full notes: [Updates & Upgrades](#updates--upgrades). ::: ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. **Names are unprefixed by default.** Without `QDRANT__SERVICE__METRICS_PREFIX`, Qdrant exposes `app_info`, `collections_total`, `cpu_cores_used` and `memory_resident_bytes`, names generic enough to collide with any other job in a shared backend. Setting `QDRANT__SERVICE__METRICS_PREFIX=qdrant_` prefixes all of them and changes nothing else. The setting is available from Qdrant 1.16, and upstream left it off by default for backward compatibility. Every metric name and query below uses the prefixed form, so set the variable to get these names. **There are no gRPC metrics at all.** Qdrant serves gRPC on `:6334` and nothing about it reaches `/metrics` - a grep for `grpc` over the exposition returns nothing. gRPC is the faster path and what most Qdrant SDKs default to, so a deployment whose clients use it gets zero request rate, zero error rate and zero latency from this surface. This is the single most important limitation of Qdrant's metrics. If your traffic is gRPC, instrument the client side to get request signals at all. **Only the points data plane is counted.** `qdrant_rest_responses_total` and its duration siblings cover `PUT /collections/{collection_name}/points`, `POST /collections/{collection_name}/points` and `POST /collections/{collection_name}/points/search`. GET requests are not counted, collection management (creating, listing, describing or deleting a collection) is not counted, and a 404 from a missing collection is never recorded. That is a scope limit on the error rate: an alert built on this metric will not see a client hammering a bad URL. **The idle surface is less than half the real one.** A fresh instance with no collections and no traffic exposes 21 metric names; with collections and traffic it exposes 49. The collection-scoped and REST families do not exist until there is a collection to describe and a request to count, so do not build an alert list from a scrape of an empty instance. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the Qdrant metrics endpoint responded. | | `qdrant_app_status_recovery_mode` | 1 means the node started in recovery mode and is not serving normally. A state read, not a threshold. | | `qdrant_rest_responses_total` | REST responses by `method`, `endpoint` and `status`. Request rate and error rate for the points data plane. | | `qdrant_rest_responses_duration_seconds` | REST response duration by `method`, `endpoint` and `status`. The latency SLO. | The `endpoint` label is templated - the value is the literal `/collections/{collection_name}/points`, not the resolved path. Collection names never enter labels, so cardinality stays flat no matter how many collections exist, and a request to a nonexistent collection creates no new label value. Latency is exposed twice, in two different shapes. There is a real histogram (`qdrant_rest_responses_duration_seconds`, with `_bucket`, `_sum` and `_count`) and three pre-computed gauges (`_avg_duration_seconds`, `_min_duration_seconds`, `_max_duration_seconds`). The min and max are extremes since process start, so `max` never comes back down and is not an incident signal. Use the histogram for percentiles. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `qdrant_collection_points` | Points per collection, keyed by `id`. Data inventory and growth. | | `qdrant_collection_vectors` | Vectors per collection, keyed by `collection` and `vector`. | | `qdrant_collections_total` | Collections on the node. | | `qdrant_collections_vector_total` | Vectors across all collections. | | `qdrant_collection_update_queue_length` | Pending updates per collection. A rising queue means writes are outrunning the optimizer. | | `qdrant_collection_update_queue_deferred_points` | Points deferred from the update queue. | | `qdrant_collection_running_optimizations` | Optimizations in progress. Sustained non-zero under write load is normal; sustained non-zero at idle is not. | | `qdrant_collection_indexed_only_excluded_points` | Points excluded from `indexed_only` searches because they are not yet indexed. Non-zero means those searches return incomplete results. | | `qdrant_collection_dead_replicas` | Replicas the node considers dead. Any non-zero value on a cluster is a fault. | | `qdrant_collection_active_replicas_min`, `_max` | Active replica count range across shards. | | `qdrant_memory_resident_bytes` | Process RSS. The number to compare against the container limit. | | `qdrant_memory_allocated_bytes`, `_active_bytes`, `_retained_bytes` | Allocator views: bytes in live allocations, in active pages, and retained by the allocator rather than returned to the OS. | | `qdrant_process_open_mmaps` | Memory maps open. Qdrant maps segment files, so this grows with data. | | `qdrant_system_max_mmaps` | The host `vm.max_map_count` ceiling. Denominator for the mmap ratio. | | `qdrant_process_open_fds`, `qdrant_process_max_fds` | File descriptors in use and the limit. | | `qdrant_cpu_cores_used` | CPU cores consumed. | | `qdrant_process_major_page_faults_total` | Major page faults. A rising rate means the working set no longer fits in RAM and Qdrant is reading mapped segments from disk. | | `qdrant_snapshot_creation_running`, `qdrant_snapshot_recovery_running` | A snapshot is being written or restored. Both are heavy operations that compete with serving. | | `qdrant_snapshot_created_total` | Snapshots created, keyed by `id`. | The collection name lives under two different label keys. `qdrant_collection_points` and the whole `qdrant_collection_hardware_metric_*` family use `id="docs"`, while `qdrant_collection_vectors` uses `collection="docs"` plus a `vector=""` key for the named-vector slot. A dashboard that joins on one key silently drops the other family. `qdrant_process_open_mmaps` against `qdrant_system_max_mmaps` is a real ceiling. Qdrant maps segment files, and hosts with a low `vm.max_map_count` hit the limit; both sides of the ratio are on this surface, so it is directly alertable. The replica and snapshot series exist on a single node but read 0 there: `qdrant_collection_dead_replicas` is 0, the active-replica gauges report 1, and the snapshot gauges stay at 0 until a snapshot runs. They become meaningful on a cluster and during snapshot operations. #### Diagnostic - for investigation and tuning Per-collection attribution, allocator internals, and since-start aggregates. Reach for these during an incident or a capacity review. | Group | Metrics | When you reach for it | |---|---|---| | Per-collection I/O | `qdrant_collection_hardware_metric_vector_io_read`, `_vector_io_write`, `_payload_io_read`, `_payload_io_write`, `_payload_index_io_read`, `_payload_index_io_write` | Finding which collection is driving disk load, split by vector data, payload and payload index. | | Per-collection CPU | `qdrant_collection_hardware_metric_cpu` | CPU accounting per collection, keyed by `id`. | | Shard transfers | `qdrant_collection_shard_transfer_incoming`, `_outgoing` | Shard transfers in flight. Zero on a single node. | | Duration aggregates | `qdrant_rest_responses_avg_duration_seconds`, `_min_duration_seconds`, `_max_duration_seconds` | Context only - these are since process start, so min and max never recover. | | Allocator detail | `qdrant_memory_metadata_bytes` | Allocator metadata overhead. | | Page faults | `qdrant_process_minor_page_faults_total` | Minor faults are served from memory. Context for the major-fault count in the Operational tier. | | Threads | `qdrant_process_threads` | Thread count. | | Build and mode | `qdrant_app_info` (labels `name`, `version`), `qdrant_cluster_enabled` | Which build is running and whether distributed mode is on. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Prometheus receiver scrape health. | Full metric list: run `curl -s http://localhost:6333/metrics` against your Qdrant node. ### Key Alerts to Configure Threshold guidance for the Core and Operational series. Qdrant's absolute latency, point counts and memory figures depend entirely on index size, vector dimensionality and hardware, so every row below is relative to your own trailing baseline or read against a limit exposed on the same surface. Tune to your workload. | Alert | Expression | Why it matters | |---|---|---| | Qdrant down | `up == 0` for 2m | The metrics endpoint stopped answering; check the container and port 6333. | | Recovery mode | `qdrant_app_status_recovery_mode == 1` | The node came up degraded and is not serving normally. A state read, not a tuned threshold. | | Request errors | `rate(qdrant_rest_responses_total{status=~"4..\|5.."}[10m])` rising against baseline | Clients are failing on the points endpoints. Covers the points data plane only; GETs and collection management are not counted. | | Search latency | a high quantile of `qdrant_rest_responses_duration_seconds` for the search endpoint, against its own baseline | Search is slowing. Use the histogram, not the min and max gauges. | | Write queue backing up | `qdrant_collection_update_queue_length` rising against baseline | Writes are outrunning the optimizer; slow the ingest rate or add capacity. | | Stale search results | `qdrant_collection_indexed_only_excluded_points > 0` sustained | `indexed_only` searches are silently returning incomplete results. | | mmap exhaustion | `qdrant_process_open_mmaps / qdrant_system_max_mmaps` above a fraction of the ceiling | Running out of maps takes the node down; raise `vm.max_map_count` on the host. | | File descriptor exhaustion | `qdrant_process_open_fds / qdrant_process_max_fds` high | Same shape, same consequence; raise the process fd limit. | | Memory against the container limit | `qdrant_memory_resident_bytes` approaching the configured limit | The limit is a deployment constant, not a metric, so compare against the value you set. | | Working set no longer resident | `rate(qdrant_process_major_page_faults_total[15m])` rising from a near-zero baseline | Segments are being read from disk; latency follows. Add RAM or shrink the working set. | | Dead replicas | `qdrant_collection_dead_replicas > 0` | A replica is unreachable. Cluster deployments only. | The latency row is a Prometheus histogram - there is no ready-made percentile series to threshold. Compute it in the alert rule, for example `histogram_quantile(0.99, rate(qdrant_rest_responses_duration_seconds_bucket[5m]))`. No alert here covers gRPC traffic, because no metric does. ### Access Setup There is nothing to turn on. Qdrant serves `/metrics` on the REST port by default, with no flag and no credentials. What you do have to set is the metric prefix, so the names do not collide with other jobs in a shared backend. The official image is multi-arch, so it runs native on arm64 as well as amd64. ```yaml showLineNumbers title="compose.yaml (excerpt)" services: qdrant: image: qdrant/qdrant:v1.19.1 environment: QDRANT__SERVICE__METRICS_PREFIX: qdrant_ # prefixes every metric name ports: - "6333:6333" # REST API and /metrics - "6334:6334" # gRPC - not covered by /metrics volumes: - qdrant-storage:/qdrant/storage healthcheck: test: ["CMD", "bash", "-c", "exec 3<>/dev/tcp/127.0.0.1/6333 && printf 'GET /readyz HTTP/1.0\r\n\r\n' >&3 && head -1 <&3 | grep -q '200 OK'"] interval: 10s timeout: 5s retries: 5 volumes: qdrant-storage: ``` The Qdrant image ships no `curl`, `wget`, `nc` or `python`, only `bash`, so a container healthcheck has to open the socket with bash's `/dev/tcp`, as above. The health endpoints are `/healthz`, `/livez` and `/readyz`. Confirm the endpoint answers from a host that has `curl`: ```bash showLineNumbers title="Verify access" # Readiness curl -s -o /dev/null -w '%{http_code}\n' http://localhost:6333/readyz # Metrics endpoint, prefixed names curl -s http://localhost:6333/metrics | grep '^qdrant_' | head -20 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: qdrant scrape_interval: 15s static_configs: - targets: # host:port Qdrant's REST API is reachable on - ${env:QDRANT_HOST}:6333 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Prometheus receiver keeps everything `/metrics` exposes. There is no per-metric enable list; new series appear after a Qdrant upgrade with no Collector change. Scout authentication for the `otlphttp/b14` exporter is covered in [Scout Exporter](../collector-setup/scout-exporter.md). #### Setting the metric prefix The metric names in this guide are prefixed. Without `QDRANT__SERVICE__METRICS_PREFIX` the names have no prefix at all - `collections_total`, not `qdrant_collections_total` - and will collide with other jobs in a shared backend. Set it on the Qdrant process: ```bash showLineNumbers title="Qdrant environment" QDRANT__SERVICE__METRICS_PREFIX=qdrant_ ``` The equivalent config-file form sets the same key: ```yaml showLineNumbers title="config/config.yaml (Qdrant)" service: metrics_prefix: qdrant_ ``` #### Environment Variables ```bash showLineNumbers title=".env" QDRANT_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Qdrant metrics docker logs otel-collector 2>&1 | grep "qdrant_" # Confirm the request counter exists on the endpoint curl -s http://localhost:6333/metrics | grep '^qdrant_rest_responses_total' # Generate a counted request against an existing collection - the vector # must match that collection's configured dimensionality curl -s -X PUT 'http://localhost:6333/collections//points?wait=true' \ -H 'Content-Type: application/json' \ -d '{"points": [{"id": 1, "vector": [0.1, 0.2, 0.3, 0.4]}]}' ``` A freshly started node with no collections shows only the 21 node-level names. `qdrant_rest_responses_total`, the duration histogram and every `qdrant_collection_*` series appear once a collection exists and traffic has hit the points endpoints. In Scout, query `qdrant_collection_points` by `id` to confirm the per-collection series arrived. ### Troubleshooting #### Metric names have no prefix **Cause**: `QDRANT__SERVICE__METRICS_PREFIX` is not set. Qdrant exposes unprefixed names by default. **Look at**: the exposition - `collections_total` and `memory_resident_bytes` instead of `qdrant_collections_total` and `qdrant_memory_resident_bytes`. **Fix**: 1. Set `QDRANT__SERVICE__METRICS_PREFIX=qdrant_` on the Qdrant process, or `service.metrics_prefix` in its config file, and restart. 2. Update dashboards and alert rules to the new names at the same time - every series name changes. #### Far fewer metrics than expected **Cause**: The node has no collections, or no traffic has reached the points endpoints. The collection-scoped and REST families only exist once there is something to describe and something to count. **Look at**: `qdrant_collections_total` - if it reads 0, only the 21 node-level names are being exposed. **Fix**: 1. Create a collection and send an upsert or a search. 2. Re-scrape; the collection and REST families appear. #### Request metrics stay empty despite heavy traffic **Cause**: The clients are using the gRPC interface on port 6334, which is not instrumented at all. Nothing about gRPC reaches `/metrics`. **Look at**: `qdrant_rest_responses_total` flat while the node is clearly busy - `qdrant_cpu_cores_used` and `qdrant_collection_points` move. **Fix**: 1. Instrument the client side to get request rate, error rate and latency for gRPC traffic. 2. Keep using this surface for node health, collection inventory and the resource ceilings, which are interface-independent. #### The error rate looks clean but users report failures **Cause**: Only the points endpoints are counted. GET requests and collection management are not, and a 404 from a missing collection is never recorded. **Look at**: `qdrant_rest_responses_total` label values - the `endpoint` set covers `/collections/{collection_name}/points` and `/collections/{collection_name}/points/search` only. **Fix**: 1. Check the Qdrant logs or a fronting proxy's access logs for the uncounted paths. 2. Treat the metric error rate as a data-plane signal, not a whole-service one. #### The healthcheck never passes and dependent containers never start **Cause**: The healthcheck uses `curl` or `wget`. The Qdrant image ships neither, nor `nc` or `python` - only `bash`. **Fix**: 1. Use the bash `/dev/tcp` healthcheck in [Access Setup](#access-setup). 2. Check readiness from outside the container against `/readyz` if you need a richer probe. #### A dashboard shows points but not vectors, or the reverse **Cause**: The collection name is under two different label keys. `qdrant_collection_points` and the `qdrant_collection_hardware_metric_*` family use `id`, while `qdrant_collection_vectors` uses `collection` plus a `vector` key. **Fix**: 1. Join on `id` for points and the hardware-metric family, on `collection` for vectors. 2. Relabel one of them in the scrape job if you want a single key across both. #### Latency is up and you cannot tell which collection is responsible **Cause**: `qdrant_rest_responses_avg_duration_seconds` and the request counters carry no collection dimension, so a node-level latency rise says nothing about which collection caused it. **Look at**: the Diagnostic tier's per-collection attribution, keyed by `id` - `qdrant_collection_hardware_metric_cpu` for compute and `qdrant_collection_hardware_metric_vector_io_read`, `_vector_io_write`, `_payload_io_read` and `_payload_io_write` for disk. These are the only per-collection performance series on this surface; the other per-collection families count points and vectors, not work done. **Fix**: size or index the collection that dominates the split. Note the label key: this family uses `id`, while `qdrant_collection_vectors` uses `collection`, so a dashboard joining on one key drops the other. #### The node dies under load with mmap or file errors **Cause**: The process hit the host's `vm.max_map_count` ceiling or its file-descriptor limit. Qdrant maps segment files, so open maps grow with data. **Look at**: `qdrant_process_open_mmaps` against `qdrant_system_max_mmaps`, and `qdrant_process_open_fds` against `qdrant_process_max_fds`. `qdrant_process_major_page_faults_total` shows whether the working set is also being read from disk, and the Diagnostic-tier `qdrant_process_minor_page_faults_total` is the contrast: minor faults are served from memory, so a high minor count with a flat major count means the working set still fits. **Fix**: 1. Raise `vm.max_map_count` on the host. 2. Raise the process file-descriptor limit. 3. If major page faults are climbing too, add RAM or reduce the resident working set. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. 4. Query the prefixed name if the prefix is set, the unprefixed name if it is not. ### Updates & Upgrades #### Qdrant version changes - **1.16**: added `QDRANT__SERVICE__METRICS_PREFIX` (config key `service.metrics_prefix`), off by default for backward compatibility. Turning it on renames every stored series - `collections_total` becomes `qdrant_collections_total` and so on for all of them - so dashboards and alert rules must be updated in lockstep, and historical series keep the old names. Nothing else about the exposition changes. _(additive in Qdrant; breaking for your queries at the moment you adopt it)_ #### Collector / receiver changes - This guide uses the **prometheus receiver**, which has no receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. New Qdrant series are picked up with no Collector change, because there is no per-metric enable list. _(no breaking change on the Prometheus path)_ ### FAQ #### Does this cover gRPC traffic? No. Qdrant serves gRPC on port 6334 and exposes nothing about it on `/metrics` - no request count, no error count, no latency. Since most Qdrant SDKs default to gRPC, a deployment can be fully loaded while `qdrant_rest_responses_total` stays flat. Instrument the client side for request signals on gRPC traffic; the node health, collection inventory and resource metrics in this guide are interface-independent and still apply. #### Why does a new Qdrant instance expose so few metrics? A node with no collections and no traffic exposes 21 metric names; with collections and traffic it exposes 49. The collection-scoped and REST families only come into existence once there is a collection to describe and a request to count. Build your alert list against a node that is actually serving, not a fresh one. #### Should I set the metrics prefix? Yes if the metrics backend is shared with other services - the default names (`app_info`, `collections_total`, `cpu_cores_used`, `memory_resident_bytes`) are generic enough to collide with any other job. Set `QDRANT__SERVICE__METRICS_PREFIX=qdrant_`. Every series name changes when you do, so update dashboards and alert rules at the same time. #### How do I monitor a distributed Qdrant cluster? Each node serves its own `/metrics` on its REST port, so add a scrape target per node and let the `instance` label separate them. The replica and shard-transfer gauges (`qdrant_collection_dead_replicas`, `qdrant_collection_active_replicas_min` / `_max`, `qdrant_collection_shard_transfer_incoming` / `_outgoing`) only become meaningful there; on a single node they read 0 or 1. Distributed behaviour is not covered here - confirm those series against your own cluster before alerting on them. #### Which latency series should I chart? The histogram, `qdrant_rest_responses_duration_seconds`, and compute percentiles from its buckets. The pre-computed `_min_duration_seconds` and `_max_duration_seconds` gauges are extremes since process start, so one slow request pins `max` for the life of the process and it never recovers. They are context, not incident signals. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Qdrant metrics. - [Milvus Monitoring](./milvus.md) - Vector store with a much larger metric surface, and traces as well as metrics. - [Weaviate Monitoring](./weaviate.md) - Vector store whose request accounting splits across REST, GraphQL and gRPC. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [OpenSearch](./opensearch.md), [vLLM](./vllm.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your traffic and retention needs, and split dashboards per collection using the `id` and `collection` labels. --- ## RabbitMQ OpenTelemetry Monitoring - Queue Depth, Message Rates, and Consumer Metrics ## RabbitMQ The OpenTelemetry Collector's `rabbitmqreceiver` collects 70+ metrics (74 node-level plus 5 queue-level) from RabbitMQ 3.x and 4.x via the RabbitMQ Management HTTP API - queue depth, message throughput, node memory and disk usage, resource alarms, file descriptors, I/O, and garbage collection. The receiver reads `/api/nodes` for node metrics and `/api/queues` for per-queue metrics. This guide configures the receiver, sets up monitoring credentials, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------------- | | RabbitMQ | 3.x | 4.x (4.3.2) | | Management plugin | enabled | enabled | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - RabbitMQ must be running with the management plugin enabled (HTTP API on port 15672). - A user with the `monitoring` tag (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things about this surface before the tables: - **Two scrape sources.** Queue-level metrics (`rabbitmq.message.*`, `rabbitmq.consumer.count`) come from `/api/queues` and only emit when at least one queue exists with activity. Node metrics (`rabbitmq.node.*`) come from `/api/nodes` and emit as soon as the node is up. With no queues, you will see only the `rabbitmq.node.*` set. - **No `up` or health metric.** Liveness is the receiver scraping the management API successfully plus `rabbitmq.node.uptime` advancing - a reset means the node restarted. `rabbitmq.node.mem_alarm` and `rabbitmq.node.disk_free_alarm` are the binary resource-alarm flags. - **Almost every node counter has a `_details.rate` companion** (for example `rabbitmq.node.io_read_count` and `rabbitmq.node.io_read_count_details.rate`). These are RabbitMQ's own server-side rate calculations; prefer computing rates in your backend from the base counter and treat the `_details.rate` variants as Diagnostic. They roughly double the node surface. #### Core - is it up and doing its job | Metric | What it tells you | |---|---| | `rabbitmq.message.current` | Messages currently in the queue (per `state`: ready / unacknowledged) - queue depth, the headline KPI. | | `rabbitmq.message.published` | Messages published into the queue - inbound throughput. | | `rabbitmq.message.delivered` | Messages delivered to consumers - outbound throughput; compared with published it shows whether the backlog is growing. | | `rabbitmq.node.uptime` | Seconds since node start - liveness and restart detection. There is no `up` or health gauge on this surface, so scrape success plus an advancing uptime is your liveness signal. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `rabbitmq.consumer.count` | Consumers attached per queue - zero on a non-empty queue means a stuck pipeline. | | `rabbitmq.message.acknowledged` | Messages acked by consumers - compared with delivered it shows unacked buildup. | | `rabbitmq.message.dropped` | Messages dropped (unroutable or dead-lettered without a DLX) - silent in a healthy flow; any value is a problem. | | `rabbitmq.node.mem_used` / `mem_limit` / `mem_alarm` | Node memory used, the high-watermark limit, and the binary memory alarm (`1` = publishers blocked). | | `rabbitmq.node.disk_free` / `disk_free_limit` / `disk_free_alarm` | Free disk, the limit, and the binary disk alarm (`1` = below limit). | | `rabbitmq.node.fd_used` / `fd_total` | File descriptors used vs total - saturation. | | `rabbitmq.node.sockets_used` / `sockets_total` | Sockets used vs total - saturation. | | `rabbitmq.node.proc_used` / `proc_total` | Erlang processes used vs total - saturation. | #### Diagnostic - for investigation and tuning Higher cardinality and volume; reach for these during an incident or a capacity review. The `_details.rate` companions alone roughly double the node surface. | Group | Representative metrics | When you reach for it | |---|---|---| | Connection / channel churn | `rabbitmq.node.connection_created` / `connection_closed`, `rabbitmq.node.channel_created` / `channel_closed` (+ `_details.rate`) | Reconnect storms and client churn. | | Queue lifecycle | `rabbitmq.node.queue_declared` / `queue_created` / `queue_deleted` (+ `_details.rate`) | Churn from short-lived or auto-delete queues. | | Scheduler / runtime | `rabbitmq.node.run_queue`, `processors`, `context_switches`, `gc_num`, `gc_bytes_reclaimed` (+ `_details.rate`) | Scheduler pressure and GC behavior. | | Disk I/O | `rabbitmq.node.io_read_*`, `io_write_*`, `io_sync_*`, `io_seek_*`, `io_reopen_*` - count / bytes / avg_time (+ `_details.rate`) | Disk-bound persistence latency. | | Message store / queue index | `rabbitmq.node.msg_store_read_count` / `msg_store_write_count`, `rabbitmq.node.queue_index_read_count` / `queue_index_write_count` (+ `_details.rate`) | Persistence-layer throughput. | | Mnesia transactions | `rabbitmq.node.mnesia_ram_tx_count` / `mnesia_disk_tx_count` (+ `_details.rate`) | Metadata store activity. | | `_details.rate` variants | Every node counter's server-side rate companion | Only when you prefer RabbitMQ's own rate calc over a backend-computed rate. | Full metric reference: [OTel RabbitMQ Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/rabbitmqreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. Most are relative to your own baseline; the two resource alarms and a consumer count of zero read a state RabbitMQ reports directly, so the comparison is exact. Tune the rest to your workload - these are starting points. | Alert | Threshold | Why it matters | |---|---|---| | RabbitMQ unreachable | the `rabbitmq` receiver producing no data for > 1m, or `rabbitmq.node.uptime` resetting | No `up` or health on this surface - scrape success plus uptime are your liveness signal. Check the node and the management API. | | Memory alarm active | `rabbitmq.node.mem_alarm` = 1 | RabbitMQ has hit the memory high watermark and is blocking publishers. Free memory or raise the watermark. | | Disk alarm active | `rabbitmq.node.disk_free_alarm` = 1 | Free disk is below the limit; publishers are blocked. Free disk or lower the limit. | | Queue backlog growing | `rabbitmq.message.current` rising vs baseline | Consumers are not keeping up with publishers. Scale consumers or investigate slow processing. | | No consumers on an active queue | `rabbitmq.consumer.count` = 0 while `rabbitmq.message.current` > 0 | Messages are arriving with nothing to drain them - a stuck or crashed consumer. | | Unacked buildup | `rabbitmq.message.delivered` outpacing `rabbitmq.message.acknowledged` | Consumers receive but fail to ack - slow processing or a redelivery loop. | | Resource saturation | `rabbitmq.node.fd_used` / `sockets_used` / `proc_used` approaching their `*_total` | The node is running out of file descriptors, sockets, or Erlang processes. Raise limits or reduce load. | ### Access Setup Ensure the RabbitMQ management plugin is enabled - it exposes the HTTP API the receiver reads: ```bash showLineNumbers title="Enable RabbitMQ management plugin" # Enable management plugin rabbitmq-plugins enable rabbitmq_management # Verify management plugin is running rabbitmq-plugins list | grep management ``` Create a dedicated monitoring user: ```bash showLineNumbers title="Create monitoring user" # Create monitoring user rabbitmqctl add_user rabbitmq_monitor # Grant read-only access and the monitoring tag rabbitmqctl set_permissions -p / rabbitmq_monitor "" "" ".*" rabbitmqctl set_user_tags rabbitmq_monitor monitoring # Test connectivity curl -u rabbitmq_monitor: http://localhost:15672/api/overview ``` **Minimum required permissions:** - `monitoring` tag - required for management API access. - No write permissions to queues or exchanges are needed. ### Configuration Many `rabbitmqreceiver` metrics are disabled by default, so the `metrics:` enable block below is required to collect the full set described above. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: rabbitmq: endpoint: http://:15672 # Change to your RabbitMQ address username: ${env:RABBITMQ_USERNAME} password: ${env:RABBITMQ_PASSWORD} collection_interval: 10s metrics: # Queue metrics rabbitmq.consumer.count: enabled: true rabbitmq.message.acknowledged: enabled: true rabbitmq.message.current: enabled: true rabbitmq.message.delivered: enabled: true rabbitmq.message.dropped: enabled: true rabbitmq.message.published: enabled: true # Node metrics - memory rabbitmq.node.mem_used: enabled: true rabbitmq.node.mem_limit: enabled: true rabbitmq.node.mem_alarm: enabled: true rabbitmq.node.mem_used_details.rate: enabled: true # Node metrics - disk rabbitmq.node.disk_free: enabled: true rabbitmq.node.disk_free_limit: enabled: true rabbitmq.node.disk_free_alarm: enabled: true rabbitmq.node.disk_free_details.rate: enabled: true # Node metrics - file descriptors rabbitmq.node.fd_used: enabled: true rabbitmq.node.fd_total: enabled: true rabbitmq.node.fd_used_details.rate: enabled: true # Node metrics - sockets rabbitmq.node.sockets_used: enabled: true rabbitmq.node.sockets_total: enabled: true rabbitmq.node.sockets_used_details.rate: enabled: true # Node metrics - processes rabbitmq.node.proc_used: enabled: true rabbitmq.node.proc_total: enabled: true rabbitmq.node.proc_used_details.rate: enabled: true # Node metrics - runtime rabbitmq.node.uptime: enabled: true rabbitmq.node.run_queue: enabled: true rabbitmq.node.processors: enabled: true rabbitmq.node.context_switches: enabled: true rabbitmq.node.context_switches_details.rate: enabled: true # Node metrics - garbage collection rabbitmq.node.gc_num: enabled: true rabbitmq.node.gc_num_details.rate: enabled: true rabbitmq.node.gc_bytes_reclaimed: enabled: true rabbitmq.node.gc_bytes_reclaimed_details.rate: enabled: true # Node metrics - I/O read rabbitmq.node.io_read_count: enabled: true rabbitmq.node.io_read_bytes: enabled: true rabbitmq.node.io_read_avg_time: enabled: true rabbitmq.node.io_read_count_details.rate: enabled: true rabbitmq.node.io_read_bytes_details.rate: enabled: true rabbitmq.node.io_read_avg_time_details.rate: enabled: true # Node metrics - I/O write rabbitmq.node.io_write_count: enabled: true rabbitmq.node.io_write_bytes: enabled: true rabbitmq.node.io_write_avg_time: enabled: true rabbitmq.node.io_write_count_details.rate: enabled: true rabbitmq.node.io_write_bytes_details.rate: enabled: true rabbitmq.node.io_write_avg_time_details.rate: enabled: true # Node metrics - I/O sync and seek rabbitmq.node.io_sync_count: enabled: true rabbitmq.node.io_sync_avg_time: enabled: true rabbitmq.node.io_sync_count_details.rate: enabled: true rabbitmq.node.io_sync_avg_time_details.rate: enabled: true rabbitmq.node.io_seek_count: enabled: true rabbitmq.node.io_seek_avg_time: enabled: true rabbitmq.node.io_seek_count_details.rate: enabled: true rabbitmq.node.io_seek_avg_time_details.rate: enabled: true rabbitmq.node.io_reopen_count: enabled: true rabbitmq.node.io_reopen_count_details.rate: enabled: true # Node metrics - Mnesia transactions rabbitmq.node.mnesia_ram_tx_count: enabled: true rabbitmq.node.mnesia_disk_tx_count: enabled: true rabbitmq.node.mnesia_ram_tx_count_details.rate: enabled: true rabbitmq.node.mnesia_disk_tx_count_details.rate: enabled: true # Node metrics - message store rabbitmq.node.msg_store_read_count: enabled: true rabbitmq.node.msg_store_write_count: enabled: true rabbitmq.node.msg_store_read_count_details.rate: enabled: true rabbitmq.node.msg_store_write_count_details.rate: enabled: true # Node metrics - queue index rabbitmq.node.queue_index_write_count: enabled: true rabbitmq.node.queue_index_read_count: enabled: true rabbitmq.node.queue_index_write_count_details.rate: enabled: true rabbitmq.node.queue_index_read_count_details.rate: enabled: true # Node metrics - connections and channels rabbitmq.node.connection_created: enabled: true rabbitmq.node.connection_closed: enabled: true rabbitmq.node.connection_created_details.rate: enabled: true rabbitmq.node.connection_closed_details.rate: enabled: true rabbitmq.node.channel_created: enabled: true rabbitmq.node.channel_closed: enabled: true rabbitmq.node.channel_created_details.rate: enabled: true rabbitmq.node.channel_closed_details.rate: enabled: true # Node metrics - queue lifecycle rabbitmq.node.queue_declared: enabled: true rabbitmq.node.queue_created: enabled: true rabbitmq.node.queue_deleted: enabled: true rabbitmq.node.queue_declared_details.rate: enabled: true rabbitmq.node.queue_created_details.rate: enabled: true rabbitmq.node.queue_deleted_details.rate: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 # Export to base14 Scout exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [rabbitmq] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" RABBITMQ_USERNAME=rabbitmq_monitor RABBITMQ_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for the RabbitMQ receiver docker logs otel-collector 2>&1 | grep -i "rabbitmq" # Test the RabbitMQ management API directly curl -u ${RABBITMQ_USERNAME}:${RABBITMQ_PASSWORD} \ http://:15672/api/overview ``` ```bash showLineNumbers title="Check RabbitMQ node status" # Check node status rabbitmq-diagnostics -q ping # List queues rabbitmqctl list_queues # Check cluster status (if clustered) rabbitmqctl cluster_status ``` ### Troubleshooting #### Connection refused on port 15672 **Cause**: The management plugin is not enabled or not listening on the expected port. **Fix**: 1. Enable the plugin: `rabbitmq-plugins enable rabbitmq_management`. 2. Verify the management port: `ss -tlnp | grep 15672`. 3. Check that RabbitMQ is running: `systemctl status rabbitmq-server` or `docker ps | grep rabbitmq`. #### Authentication failed **Cause**: Monitoring credentials are incorrect or the user lacks the `monitoring` tag. **Fix**: 1. Test credentials directly: `curl -u user:pass http://localhost:15672/api/overview`. 2. Verify user tags: `rabbitmqctl list_users`. 3. Add the monitoring tag if missing: `rabbitmqctl set_user_tags rabbitmq_monitor monitoring`. #### Only node metrics appear, no message metrics **Cause**: There are no queues yet. Queue-level metrics (`rabbitmq.message.*`, `rabbitmq.consumer.count`) come from `/api/queues` and need at least one active queue, while node metrics (`rabbitmq.node.*`) emit as soon as the node is up. **Fix**: 1. Confirm a queue exists with traffic: `rabbitmqctl list_queues`. 2. Once a queue is declared and messages flow, the `rabbitmq.message.*` series start emitting on the next scrape. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. #### Memory or disk alarm metrics showing 1 **Cause**: RabbitMQ has triggered a resource alarm - this is a real operational issue, not a collection problem. **Look at**: `rabbitmq.node.mem_alarm` and `rabbitmq.node.disk_free_alarm` against `rabbitmq.node.mem_used` / `mem_limit` and `rabbitmq.node.disk_free` / `disk_free_limit`; if I/O is involved, the Diagnostic `rabbitmq.node.io_write_*` and `msg_store_write_count` families show persistence pressure. **Fix**: 1. `rabbitmq.node.mem_alarm = 1` means memory usage exceeds the high watermark - publishers are blocked. Free memory or raise the watermark. 2. `rabbitmq.node.disk_free_alarm = 1` means free disk is below the limit - publishers are blocked. Free disk or lower the limit. 3. The alarm metrics are working correctly; resolve the underlying resource issue. ### FAQ #### Does this work with RabbitMQ running in Kubernetes? Yes. Set `endpoint` to the RabbitMQ management service DNS (for example `http://rabbitmq.default.svc.cluster.local:15672`) and inject credentials via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### How do I monitor a RabbitMQ cluster? The management API returns cluster-wide data from any node. Point the receiver at one node and you get metrics for all nodes. For redundancy, add per-node receiver blocks pointing to different nodes: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-node)" receivers: rabbitmq/node1: endpoint: http://rabbitmq-1:15672 username: ${env:RABBITMQ_USERNAME} password: ${env:RABBITMQ_PASSWORD} rabbitmq/node2: endpoint: http://rabbitmq-2:15672 username: ${env:RABBITMQ_USERNAME} password: ${env:RABBITMQ_PASSWORD} ``` #### What permissions does the monitoring account need? The `monitoring` user tag is required for management API access. No queue read/write permissions are needed - the Collector only reads metrics and does not modify RabbitMQ data. #### Does this work with both RabbitMQ 3.x and 4.x? The receiver reads the management HTTP API, which works on both 3.x and 4.x, but the node-metric set is not identical. RabbitMQ 4.x deprecates management-plugin metric collection in favor of the Prometheus plugin, and some node I/O metrics (for example `rabbitmq.node.io_read_avg_time` and `rabbitmq.node.io_write_avg_time`) are deprecated or no longer meaningful from 4.2 onward. The Core and Operational signals in this guide still collect on 4.x; for the fullest metric set on 4.x, RabbitMQ recommends scraping its Prometheus plugin. #### Why do I only see node metrics and no message metrics? You have no queues yet. The queue-level metrics (`rabbitmq.message.*`, `rabbitmq.consumer.count`) come from `/api/queues` and need at least one active queue; the node metrics (`rabbitmq.node.*`) emit as soon as the node is up. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on RabbitMQ metrics. - [Redis Monitoring](./redis.md) - In-memory data store and cache. - [PostgreSQL Monitoring](./postgres.md) - Relational database monitoring. - [MongoDB Monitoring](./mongodb.md) - Document database monitoring. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Redis](./redis.md), [PostgreSQL](./postgres.md), [MongoDB](./mongodb.md), and other components. - **Fine-tune Collection**: Adjust `collection_interval` to balance metric freshness against load on RabbitMQ and the Collector. --- ## Ray OpenTelemetry Monitoring - Task State, Cluster Resources, and Collector Setup ## Ray Ray's head node serves Prometheus text on the port passed to `--metrics-export-port`; the OpenTelemetry Collector's Prometheus receiver scrapes it, collecting 116 metric names covering task and actor state, cluster resources, per-node CPU, memory and disk, the object store and its spilling path, scheduler placement, and Ray's internal control plane. The metrics port is **opt-in and has no default** - without `--metrics-export-port` there is no endpoint at all, and you choose the port. This guide starts the head node with the port open, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Ray | 2.53 | 2.58 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Ray states no minimum version for the metrics themselves. 2.53 is the meaningful floor: it is the release that introduced `RAY_metric_cardinality_level` and changed its default, so below it every series carries a real `WorkerId` with no way to limit the fan-out. Before starting: - The head node must be started with `--metrics-export-port `. The endpoint is opt-in and has no default port - without the flag nothing is served, and the Collector must scrape the same port you chose. - That port must be reachable from the host running the Collector. - The endpoint has no authentication. Scrape it on the internal network and do not expose it publicly. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). :::warning Upgrading? Ray 2.53 introduced `RAY_metric_cardinality_level` and defaults it to `recommended`, which stops exporting the real worker ID on `ray_tasks` and `ray_actors`. Dashboards and alerts that group either family by `WorkerId` stop resolving. Full notes: [Updates & Upgrades](#updates--upgrades). ::: ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is the cluster there and is work moving | Metric | What it tells you | |---|---| | `up` | Prometheus scrape liveness - 1 means the Ray metrics port responded. | | `ray_cluster_active_nodes` | Alive nodes by `node_type`. Node loss shows here first. | | `ray_tasks` | Current task count per `State`, including `FAILED`. The headline workload signal. | | `ray_resources` | Logical cluster resources per `Name` (`CPU`, `memory`, `object_store_memory`) split by `State` (`AVAILABLE`, `USED`). Whether the cluster has room to run work. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Actors and jobs | `ray_actors`, `ray_running_jobs`, `ray_finished_jobs_total`, `ray_job_duration_s` | Current actor count per `State`, jobs running and finished, and job duration in seconds. | | Scheduling | `ray_scheduler_tasks`, `ray_scheduler_unscheduleable_tasks`, `ray_internal_num_infeasible_scheduling_classes`, `ray_scheduler_failed_worker_startup_total` | Tasks known to the scheduler per state; work it cannot place; scheduling classes the current cluster shape can never satisfy; worker processes that failed to start. | | Node CPU and memory | `ray_node_cpu_utilization`, `ray_node_cpu_count`, `ray_node_mem_used`, `ray_node_mem_total`, `ray_node_mem_available` | Per-node CPU percentage and count, and per-node memory. Memory pressure precedes worker kills. | | Node disk | `ray_node_disk_usage`, `ray_node_disk_free` | Per-node disk. Object spilling consumes it. | | Object store | `ray_object_store_used_memory`, `ray_object_store_available_memory`, `ray_object_store_fallback_memory`, `ray_object_store_num_local_objects` | Bytes in use and free (the fill ratio), bytes served from fallback allocation, and objects held locally. Non-zero fallback means the store is over its shared-memory budget. | | Spilling | `ray_spill_manager_objects_bytes`, `ray_spill_manager_objects`, `ray_spill_manager_request_total`, `ray_internal_num_spilled_tasks` | Bytes and objects spilled to disk, spill and restore requests, and tasks spilled to another node. Spilling is the object store's back-pressure. | | Task events | `ray_gcs_task_manager_task_events_dropped` | Task events the GCS dropped. Non-zero means the dashboard and state API are showing an incomplete picture. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Metrics | When you reach for it | |---|---|---| | Internal gRPC | `ray_grpc_server_req_process_time_ms` and the `ray_grpc_server_req_*_total` counters | Internal gRPC handling latency and request counts by `Method`. The single largest series producer. | | GCS storage and state | `ray_gcs_storage_operation_latency_ms`, `ray_gcs_storage_operation_count_total`, `ray_gcs_actors_count`, `ray_gcs_placement_group_count` | GCS storage operations by `Operation`, and the GCS view of actors and placement groups by state. | | Task event pipeline | `ray_gcs_task_manager_task_events_reported`, `_stored` | Throughput of the task event pipeline; the denominators for the drop rate. | | Operation queues | `ray_operation_queue_time_ms`, `ray_operation_run_time_ms`, `ray_operation_active_count`, `ray_operation_count_total` | Internal operation queue and run time by `Name`. | | Control-plane responsiveness | `ray_io_context_event_loop_lag_ms`, `ray_io_context_monitor_latency_ms`, `ray_health_check_rpc_latency_ms` | Event-loop lag inside Ray components and node health-check RPC latency. Rising lag precedes control-plane slowness. | | Placement latency | `ray_scheduler_placement_time_ms` plus its pre-computed `_max`, `_mean`, `_p50`, `_p95`, `_p99` gauges | Task placement latency. Ray exports the percentiles alongside the histogram. | | Object accounting | `ray_object_store_memory`, `ray_object_store_dist`, `ray_owned_objects`, `ray_owned_objects_size`, `ray_total_lineage_bytes` | Object store bytes by `Location` and `ObjectState`, object size distribution, and per-owner object counts, bytes and lineage bytes. | | Object directory | the `ray_object_directory_*` family (`_lookups`, `_updates`, `_subscriptions`, and the location counters) | Object directory traffic. | | Object transfer | the `ray_object_manager_*`, `ray_pull_manager_*` and `ray_push_manager_*` families | Object movement between nodes and the pull and push queue detail. Flat on a single-node cluster, which has nowhere to transfer to. | | Worker processes | `ray_internal_num_processes_started`, `_from_cache`, `ray_worker_register_time_ms`, `ray_local_resource_view_node_count` | Worker starts and cache reuse, registration latency, and the nodes in the raylet's local resource view. | | Per-component process use | the `ray_component_*` family (`_cpu_percentage`, `_rss_bytes`, `_uss_bytes`, `_num_fds`, and the MB variants) | Process resource use per `Component` - raylet, GCS, dashboard, agents. | | Host and cgroup memory | `ray_node_cgroup_mem_total`, `_used`, `ray_node_mem_total_host`, `_used_host`, `ray_node_mem_shared_bytes` | Cgroup and host memory views alongside the Ray view. | | Node I/O detail | the `ray_node_disk_io_*` and `ray_node_disk_*_iops` families, `ray_node_disk_utilization_percentage`, and `ray_node_network_*` | Per-node disk and network I/O detail. | | Exporter internals | `process_*`, `python_*`, and the `scrape_*` meta | The exporting process itself, Python GC, and the receiver's own scrape statistics. | GPU nodes additionally export `ray_node_gpus_utilization`, `ray_node_gpus_available`, `ray_node_gpu_power_milliwatts`, `ray_node_gpu_temperature_celsius`, `ray_node_gram_used` and `ray_node_gram_available`. They are absent on CPU-only hardware. #### How the Ray metric surface behaves Six things about this surface change how you build dashboards and alerts on it. **Every Ray series carries `SessionName`, and it changes on every cluster restart.** The exceptions are the `process_*`, `python_*` and scrape meta. The value is `session__`, so a `ray stop; ray start` replaces the entire series set rather than continuing it. Never pin a `SessionName` in a dashboard or an alert, and expect storage cost to grow with restart frequency. **Labels, not names, drive the volume.** 116 metric names produce 556 data points per scrape on a single-node cluster with two CPUs. One family, `ray_grpc_server_req_process_time_ms_bucket`, accounts for 273 of the 1093 raw series, and `ray_operation_run_time_ms_bucket`, `ray_operation_queue_time_ms_bucket` and `ray_gcs_storage_operation_latency_ms_bucket` add 169 more. These are internal RPC histograms; a keep or drop rule on the scrape job is the lever that decides which of them ship - see [Scoping the internal histogram families](#scoping-the-internal-histogram-families). **The cardinality level does not do what Ray's documentation says.** Ray's system-metrics reference states that "Starting with Ray 2.53+, the `WorkerId` label is no longer exported by default due to its high cardinality". On Ray 2.58+, with the default `RAY_metric_cardinality_level=recommended`, the behaviour is narrower: - The `WorkerId` label **key** is still present on most series, almost always empty. - The real worker ID is stripped from `ray_tasks` and `ray_actors` only. - Nine families still carry a real worker ID: `ray_object_store_memory`, `ray_owned_objects`, `ray_owned_objects_size`, the five `ray_scheduler_placement_time_ms_max`, `_mean`, `_p50`, `_p95`, `_p99` series, and `ray_total_lineage_bytes`. Setting the level to `legacy` additionally restores the real worker ID on `ray_tasks` and `ray_actors`. The `low` level is documented to also drop the `Name` label from tasks and actors; that behaviour is unverified. **`ray_tasks` and `ray_actors` are state gauges, not counters.** They report the current count per `State`. Task states are `SUBMITTED_TO_WORKER`, `RUNNING`, `RUNNING_IN_RAY_GET`, `RUNNING_IN_RAY_WAIT`, `PENDING_NODE_ASSIGNMENT`, `PENDING_ARGS_AVAIL`, `GETTING_AND_PINNING_ARGS`, `FINISHED` and `FAILED`. Actor states are `ALIVE`, `ALIVE_IDLE` and `ALIVE_RUNNING_TASKS`. **`ray_resources` uses `Name` for two different things.** `Name="CPU"`, `Name="memory"` and `Name="object_store_memory"` are the real resources, split by `State="AVAILABLE"` and `State="USED"`. `Name="session_<...>"` is Ray's implicit per-node resource. Filter on the three real names rather than taking every `ray_resources` series. **`RAY_enable_open_telemetry` does not give you OTLP.** It defaults to true on Ray 2.58+ and only swaps Ray's internal metric recorder from OpenCensus to OpenTelemetry. It does not change the Prometheus exposition and does not add an OTLP exporter, so the scrape path is the same either way. ### Key Alerts to Configure Thresholds are relative to a trailing baseline or to your own cluster shape - Ray's absolute rates depend entirely on node count, CPU count and workload. Tune these to what your cluster normally does. | Alert | Expression | Why it matters | |---|---|---| | Metrics endpoint down | `up == 0` for 2m | The head node's metrics port stopped answering. Also fires when a restart omits `--metrics-export-port`. | | Node lost | `ray_cluster_active_nodes` below the expected node count for 5m | Node loss shows here first. The expected count is a deployment constant, not a metric - carry it in the alert expression. | | Tasks failing | `ray_tasks{State="FAILED"}` rising against its own baseline | The workload is erroring, not just slow. | | Work cannot be placed | `ray_scheduler_unscheduleable_tasks > 0` for 10m, or `ray_internal_num_infeasible_scheduling_classes > 0` | The first is transient pressure and usually clears with capacity; the second means no node in the cluster can ever satisfy the request, so the resource spec or the cluster shape has to change. | | Object store filling | `ray_object_store_used_memory / (ray_object_store_used_memory + ray_object_store_available_memory)` high against baseline | Spilling and then task back-pressure follow. Add object store memory or reduce object retention. | | Object spilling | `rate(ray_spill_manager_request_total[10m])` rising from a zero baseline, or `ray_object_store_fallback_memory > 0` | Spilling to disk means the object store is out of room; fallback allocation means it has exceeded shared memory. | | Worker startup failures | `rate(ray_scheduler_failed_worker_startup_total[10m]) > 0` | Workers are not coming up - usually resource limits or a bad runtime environment. | | Task events dropped | `ray_gcs_task_manager_task_events_dropped` rising | The dashboard and state API are showing an incomplete picture, so debugging views cannot be trusted. | | Node memory pressure | `ray_node_mem_used / ray_node_mem_total` high against baseline | Ray kills workers under memory pressure before the node OOMs, so this fires ahead of unexplained task failures. | ### Access Setup `--metrics-export-port` is the only thing that creates the metrics endpoint. There is no default port and no default-on endpoint: pick a port, pass it to the head node, and scrape that same port. The examples here use `8080`. ```bash showLineNumbers title="Start the head node" ray start --head \ --dashboard-host 0.0.0.0 \ --metrics-export-port 8080 \ --num-cpus 2 ``` The endpoint has no authentication. Bind it to the internal network the Collector runs on and do not expose it publicly. The dashboard and the metrics agent need the `ray[default]` extra. The official images already include it, so no extra install is needed there. **Docker setup** - the official image publishes `linux/amd64` and `linux/arm64` manifests, so no wheel build is needed on Apple Silicon or Graviton: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: ray-head: image: rayproject/ray:2.58.0-py312-cpu command: > ray start --head --dashboard-host 0.0.0.0 --metrics-export-port 8080 --num-cpus 2 --block shm_size: 2gb ports: - "8080:8080" - "8265:8265" healthcheck: test: - CMD - python - -c - "import urllib.request,sys; sys.exit(0 if urllib.request.urlopen('http://localhost:8080/metrics', timeout=2).status == 200 else 1)" interval: 10s timeout: 5s retries: 10 otel-collector: image: otel/opentelemetry-collector-contrib:latest volumes: - ./config/otel-collector.yaml:/etc/otelcol-contrib/config.yaml depends_on: ray-head: condition: service_healthy ``` Two details in that snippet matter: - `shm_size: 2gb` sizes `/dev/shm` for the object store. On the Docker default of 64 MB, Ray falls back to `/tmp` for the object store and warns about it, which puts object traffic on disk. - The healthcheck uses Python, not `curl`. The Ray image ships no `curl`, so a `curl`-based healthcheck never passes and anything waiting on `service_healthy` never starts. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: ray scrape_interval: 15s static_configs: - targets: # host:port passed to --metrics-export-port - ${env:RAY_HEAD_HOST}:8080 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Prometheus receiver keeps everything the metrics port exposes. There is no per-metric enable list, so new series appear after a Ray upgrade with no Collector change. The `up` series and the four `scrape_*` series are synthesized by the receiver, not by Ray. Scout authentication for the `otlphttp/b14` exporter is covered in [Scout Exporter](../collector-setup/scout-exporter.md). #### Environment Variables ```bash showLineNumbers title=".env" RAY_HEAD_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Scoping the internal histogram families Four histogram families - internal gRPC handling time, operation run and queue time, and GCS storage operation latency - account for the bulk of the raw series a head node exposes. A `metric_relabel_configs` rule on the scrape job decides whether they ship: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" metric_relabel_configs: - source_labels: [__name__] regex: "ray_(grpc_server_req_process_time_ms|operation_run_time_ms|operation_queue_time_ms|gcs_storage_operation_latency_ms)_(bucket|sum|count)" action: drop ``` Invert it with `action: keep` and a regex over the families you want if you prefer an allowlist. These are Diagnostic-tier series: dropping them removes control-plane latency detail from incident investigation, so decide per environment rather than by default. ### Verify the Setup Start the head node and the Collector, then check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm the metrics port is serving (run from a host that has curl - # the Ray image does not) curl -s http://localhost:8080/metrics | grep ray_cluster_active_nodes # Check Collector logs for scraped Ray metrics docker logs otel-collector 2>&1 | grep -i "ray_" ``` `ray status`, run inside the head node container, shows the same cluster view from Ray's side - node count and resource usage - and is a quick cross-check when a metric looks wrong: ```bash showLineNumbers title="Cross-check with ray status" docker exec ray-head ray status ``` ### Troubleshooting #### Nothing is served on the metrics port **Cause**: The head node was started without `--metrics-export-port`. There is no default port and no endpoint until the flag is passed. **Fix**: 1. Restart the head node with `--metrics-export-port `. 2. Confirm the Collector's scrape target uses the same port. 3. Check the port is reachable from the Collector host, and published if Ray runs in a container. #### The healthcheck never passes and dependent containers never start **Cause**: The Ray image ships no `curl`, so a `curl`-based container healthcheck fails immediately and anything with `condition: service_healthy` waits forever. **Fix**: Use the Python already in the image: ```bash showLineNumbers title="Healthcheck without curl" python -c "import urllib.request,sys; sys.exit(0 if urllib.request.urlopen('http://localhost:8080/metrics', timeout=2).status == 200 else 1)" ``` #### Every dashboard broke after a cluster restart **Cause**: The `SessionName` label changed. Its value is `session__` and it is regenerated on every `ray start`, so the old series stopped and a new set began. **Look at**: any Ray series' `SessionName` label before and after the restart - they will differ. **Fix**: 1. Remove `SessionName` from dashboard queries and alert expressions. 2. Group on `node_type`, `Name`, `State` or `Component` instead. 3. Account for the series churn in retention planning; each restart adds a full new series set. #### Far more series arrive than expected **Cause**: The internal gRPC and operation histograms dominate the surface. The `ray_grpc_server_req_process_time_ms_bucket` family alone is roughly a quarter of the raw series a head node exposes, with the operation and GCS storage latency histograms adding around a sixth more. **Look at**: the Diagnostic-tier `ray_grpc_server_req_process_time_ms`, `ray_operation_run_time_ms`, `ray_operation_queue_time_ms` and `ray_gcs_storage_operation_latency_ms` families. **Fix**: Scope them with `metric_relabel_configs` - see [Scoping the internal histogram families](#scoping-the-internal-histogram-families). #### `WorkerId` still appears on Ray 2.53+ **Cause**: The default `recommended` cardinality level is a partial control, not a switch that removes the label. It strips the real worker ID from `ray_tasks` and `ray_actors` only, and leaves the empty label key on most of the rest. **Look at**: `ray_object_store_memory`, `ray_owned_objects`, `ray_owned_objects_size`, the `ray_scheduler_placement_time_ms_*` percentile gauges and `ray_total_lineage_bytes` - these nine families keep a real worker ID at the default level. **Fix**: Drop or aggregate away the `WorkerId` label on those families in the Collector if the fan-out matters, rather than expecting the cardinality level to do it. #### Object store errors, or Ray falls back to `/tmp` **Cause**: `/dev/shm` is too small for the object store. Docker's default is 64 MB; Ray warns and uses `/tmp` instead, which puts object traffic on disk. **Look at**: `ray_object_store_fallback_memory` (non-zero means the store exceeded its shared-memory budget) and `ray_node_disk_usage`. **Fix**: Raise `shm_size` on the container (`shm_size: 2gb` is a reasonable start) and restart the head node. #### The cluster feels slow but no resource is saturated **Cause**: the control plane is the bottleneck, not the workers. CPU, memory and object store all read normally while task submission, placement and actor creation take longer than they should. **Look at**: the Diagnostic tier's control-plane group. `ray_io_context_event_loop_lag_ms` rises before anything else does; `ray_gcs_storage_operation_latency_ms` by `Operation` says whether the GCS store is the cause; `ray_scheduler_placement_time_ms` and its pre-computed `_p95` and `_p99` gauges show the cost landing on task placement. `ray_component_cpu_percentage` and `ray_component_rss_bytes` by `Component` say which process - raylet, GCS, dashboard - is the one under pressure. **Fix**: give the head node more CPU, or move the dashboard and agents off it. If `ray_gcs_storage_operation_latency_ms` is the outlier, the GCS store is the constraint rather than the scheduler. #### Tasks are stuck pending **Cause**: Either the cluster is temporarily short of resources, or the task asks for a resource shape no node can provide. **Look at**: `ray_scheduler_unscheduleable_tasks` - non-zero but falling is transient pressure. `ray_internal_num_infeasible_scheduling_classes` above zero means no node in the cluster can ever satisfy the request. Cross-check `ray_resources` split by `State` for what is actually available. **Fix**: 1. Add capacity or wait out the queue if only `ray_scheduler_unscheduleable_tasks` is set. 2. Correct the task's resource spec, or add a node type that matches it, if `ray_internal_num_infeasible_scheduling_classes` is set. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### Updates & Upgrades #### Ray version changes - **2.53**: introduced `RAY_metric_cardinality_level`, defaulting it to `recommended`. The real worker ID is no longer exported on `ray_tasks` and `ray_actors`, so dashboards and alerts that group either family by `WorkerId` stop resolving after the upgrade. Rebuild those queries on `Name` and `State`, or set `RAY_metric_cardinality_level=legacy` on the head node to restore the previous labelling. Nine other families keep a real worker ID at the default level, so the label does not disappear from the surface. _(breaking for `WorkerId`-keyed queries on tasks and actors)_ #### Collector / receiver changes - This guide uses the **prometheus receiver**, which has no receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. New Ray metric names appear after a Ray upgrade with no Collector change, because the scrape job has no enable list. _(no breaking change on the Prometheus path)_ ### FAQ #### How do I monitor a multi-node cluster? Every node exposes its own metrics port, so give each one `--metrics-export-port` and add a scrape target per node - or point the Prometheus receiver at service discovery and let it find them. The head head node is the one that carries the GCS and cluster-wide series (`ray_cluster_active_nodes`, `ray_resources`, `ray_gcs_*`), so expect to lose the cluster view if you scrape only the workers. Confirm the split against your own cluster before you build dashboards on it. #### How does this relate to KubeRay? The mechanism is the same: each Ray pod serves Prometheus text on its metrics port, and something scrapes it. Scrape it with a Kubernetes `ServiceMonitor`/`PodMonitor` if you already run the Prometheus Operator, or run the Collector as a DaemonSet with Kubernetes service discovery in the scrape config. Expect the metric names, labels and `SessionName` behaviour to carry over unchanged, since they come from Ray rather than from how it is deployed. #### Why do `ray_tasks` and `ray_actors` look like gauges? Because they are. Both report the current count per `State` rather than a monotonic total, so read them directly - `ray_tasks{State="FAILED"}` is the number of failed tasks Ray currently knows about. Do not wrap them in `rate()`; that produces a meaningless number for a gauge that goes up and down. #### What can I do about metric volume? Volume comes from labels, not from the 116 metric names. Four internal histogram families - gRPC request handling time, operation run and queue time, and GCS storage operation latency - produce most of the raw series. A `metric_relabel_configs` keep or drop rule on the scrape job scopes which of them ship; see [Scoping the internal histogram families](#scoping-the-internal-histogram-families). They are Diagnostic-tier series, so dropping them costs incident detail. #### Can Ray export OTLP directly? No. `RAY_enable_open_telemetry` only swaps Ray's internal metric recorder from OpenCensus to OpenTelemetry; it does not change the Prometheus exposition and does not add an OTLP exporter. Scraping the metrics port is how the data gets out. Ray also has an in-process tracing hook configured through its Python API rather than the CLI, which is a separate mechanism and does not affect the metrics path described here. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Ray cluster metrics. - [vLLM Monitoring](./vllm.md) - Self-hosted model server commonly run on the same cluster as the Ray tasks. - [llama.cpp Monitoring](./llama-cpp.md) - Self-hosted model server for CPU and small-GPU nodes alongside a Ray cluster. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [vLLM](./vllm.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your cluster size, and split dashboards by `node_type` and by `ray_resources` `Name` once you are running more than one node type. --- ## Redis OpenTelemetry Monitoring - Memory, Keyspace, and Latency Metrics ## Redis The OpenTelemetry Collector's Redis receiver collects 33 metrics from Redis 6.0+ over a single TCP connection, including command throughput, keyspace hit/miss ratio, memory saturation, fragmentation, connection load, persistence state, and replication offset. The receiver reads Redis `INFO` and `COMMAND` introspection - no exporter sidecar is needed. This guide configures the receiver, verifies connectivity, and ships metrics to base14 Scout. > **Running Azure Cache for Redis (PaaS)?** Use the > [Azure Cache for Redis monitoring guide](../infra/azure/cache-for-redis.md) > instead. The PaaS surface publishes through Azure Monitor with > resource-level dimensions; this guide's `redis` receiver path scrapes > raw INFO output and produces a different (richer per-key, per-command) > metric set. The two paths can run in the same collector for hybrid > deployments. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Redis | 6.0 | 8.0+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Redis must be accessible over TCP from the host running the Collector (default port 6379). - Redis password (if authentication is enabled). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `redis` receiver has no `up` metric. The presence of fresh samples is the real liveness signal - a failed scrape emits nothing. `redis.commands` then shows whether a live server is doing work, though an idle but healthy server legitimately reads zero. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `redis.commands` | Commands processed per second - throughput KPI and liveness proxy. | | `redis.keyspace.hits`, `redis.keyspace.misses` | The hit ratio `hits / (hits + misses)` - the defining health signal for a cache. | | `redis.memory.used` | Memory in use by the dataset - the saturation anchor; memory pressure is the most common Redis incident. | | `redis.memory.fragmentation_ratio` | RSS / used; fragmentation overhead read alongside used memory, so waste is visible without leaving Core. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Memory ceiling and pressure | `redis.maxmemory`, `redis.keys.evicted`, `redis.memory.rss` | The configured ceiling, keys dropped under pressure, and resident memory the OS sees. | | Connections | `redis.clients.connected`, `redis.clients.blocked`, `redis.connections.rejected` | Connection load, clients stuck on blocking calls (BLPOP etc.), and connections refused at `maxclients`. | | CPU | `redis.cpu.time` | CPU consumed, by mode (sys/user, main/children). | | Persistence | `redis.rdb.changes_since_last_save`, `redis.latest_fork` | Unsaved writes since the last RDB save, and the duration of the last fork (blocks during bgsave). | | Replication | `redis.slaves.connected`, `redis.replication.offset` | Connected replicas and the master replication offset. | | Expiry | `redis.keys.expired` | Keys removed on TTL expiry. | #### Diagnostic - for investigation and tuning Higher cardinality; enable on demand. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | Per-command breakdown | `redis.cmd.calls`, `redis.cmd.usec`, `redis.cmd.latency` (by `cmd` label) | Find the command driving latency or CPU; high cardinality. | | Per-database breakdown | `redis.db.keys`, `redis.db.expires`, `redis.db.avg_ttl` (by `db` label) | Key counts, TTL coverage, and average TTL (ms) per logical DB. | | Memory internals | `redis.memory.peak`, `redis.memory.lua` | Peak consumption and Lua-engine memory. | | Network throughput | `redis.net.input`, `redis.net.output` | Bytes received and sent over the network. | | Cumulative counters | `redis.commands.processed`, `redis.connections.received` | Lifetime totals for commands and accepted connections. | | Buffer and backlog internals | `redis.clients.max_input_buffer`, `redis.clients.max_output_buffer`, `redis.replication.backlog_first_byte_offset` | Largest client buffers and the replication backlog start offset. | | Uptime | `redis.uptime` | Server uptime in seconds; a reset flags a restart. | Full metric reference: [OTel Redis Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/redisreceiver). The receiver's `redis.cmd.calls`, `redis.cmd.usec`, `redis.cmd.latency`, and `redis.maxmemory` metrics are default-off; the config below enables them. `redis.cmd.latency` is sourced from `INFO latencystats`, which exists only on Redis 7.0+; on older servers it stays empty even when enabled. `redis.cluster.*`, `redis.memory.used_memory_overhead`, `redis.memory.used_memory_startup`, and `redis.mode` are also default-off and not applicable to a standalone instance. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `redis.memory.used / redis.maxmemory` | > 0.80 | Approaching 1.0 | Next writes trigger eviction or OOM; raise `maxmemory` or scale out. | | `rate(redis.keys.evicted)` | > 0 sustained | Rising across scrapes | Working set exceeds `maxmemory`; keys are being dropped. Resize or review TTLs. | | `hits / (hits + misses)` | Falling vs baseline | Sharp drop | Cache effectiveness dropping; review key TTLs, sizing, or access patterns. | | `rate(redis.connections.rejected)` | > 0 | Sustained > 0 | `maxclients` reached; raise it or fix a client connection leak. | | `redis.clients.blocked` | Rising vs baseline | Climbing and not draining | Consumers stuck on blocking commands; check workers draining lists/streams. | | `redis.memory.fragmentation_ratio` | Elevated vs ~1.0 | Far above 1.0 | RSS far above used memory; consider active defrag or a planned restart. | | `redis.rdb.changes_since_last_save` | Growing with no recent `redis.latest_fork` | Sustained growth | Unsaved writes accumulating; check disk and `save` policy for data-loss risk. | ### Access Setup Redis uses password-based authentication when `requirepass` (or an ACL user) is configured. No special monitoring user is required - the receiver connects with the standard `AUTH` command and reads `INFO` output (it issues `INFO all`), which is available to any authenticated client. The keyspace, command-stats, and latency-stats metrics are all parsed from `INFO` sections, not separate commands. For least privilege, you can scope a dedicated ACL user to just that command: ```bash showLineNumbers title="redis monitoring user setup (optional)" # Read-only monitoring user limited to INFO (the only command the receiver issues) redis-cli ACL SETUSER otel_monitor on >your_password +info # Add +cluster|info as well if you enable the redis.cluster.* metrics ``` Verify connectivity from the host running the Collector: ```bash showLineNumbers title="Verify access" # With authentication redis-cli -h -p -a ping # Without authentication redis-cli -h -p ping ``` ### Configuration The four default-off metrics worth enabling are `redis.maxmemory` (so the saturation alert has a denominator) and the per-command series `redis.cmd.calls` / `redis.cmd.usec` / `redis.cmd.latency`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: redis: endpoint: ${env:REDIS_ENDPOINT} # Change to your Redis host:port collection_interval: 10s # password: ${env:REDIS_PASSWORD} # Uncomment if authentication is enabled metrics: redis.maxmemory: enabled: true redis.cmd.calls: enabled: true redis.cmd.usec: enabled: true redis.cmd.latency: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [redis] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic tier with a `filter` processor while keeping the Core and Operational series. The per-command (`redis.cmd.*`) and per-database (`redis.db.*`) series carry the most cardinality, so they are the first to drop. #### Environment Variables ```bash showLineNumbers title=".env" REDIS_ENDPOINT=localhost:6379 REDIS_PASSWORD=your_password ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for the receiver starting and scraping docker logs otel-collector 2>&1 | grep -i "redis" # Verify Redis is responding redis-cli -h ${REDIS_HOST} -p ${REDIS_PORT} info server # Generate traffic so keyspace and hit/miss metrics populate redis-cli -h ${REDIS_HOST} -p ${REDIS_PORT} set probe 1 redis-cli -h ${REDIS_HOST} -p ${REDIS_PORT} get probe redis-cli -h ${REDIS_HOST} -p ${REDIS_PORT} get missing-key ``` ### Troubleshooting #### Connection refused **Cause**: Collector cannot reach Redis at the configured endpoint. **Fix**: 1. Verify Redis is running: `systemctl status redis` or `docker ps | grep redis`. 2. Confirm the endpoint address and port (default 6379) in your config. 3. Check the `bind` directive in `redis.conf` - change to `0.0.0.0` if the Collector runs on a separate host. #### Authentication failed (NOAUTH) **Cause**: Redis requires a password but none is configured in the receiver. **Fix**: 1. Uncomment the `password` field in the receiver config. 2. Set `REDIS_PASSWORD` in your environment variables. 3. Test credentials: `redis-cli -a $REDIS_PASSWORD ping`. #### Hit ratio looks low or commands are slow **Cause**: A few commands dominate latency or the access pattern is missing the cache. **Look at**: the Diagnostic `redis.cmd.latency` and `redis.cmd.usec` series (by `cmd` label) to find the offending command, and `redis.keyspace.hits` / `redis.keyspace.misses` for the ratio trend. Cross-check `redis.db.keys` and `redis.db.avg_ttl` to see whether a logical DB is under-populated or its keys are expiring too fast. **Fix**: 1. Review TTLs and key sizing for the workload driving misses. 2. If one command dominates `redis.cmd.usec`, profile or rate-limit it. #### Memory keeps climbing or eviction starts **Cause**: The working set is approaching `maxmemory`, or memory is fragmented. **Look at**: `redis.memory.used` against `redis.maxmemory`, `redis.keys.evicted` (rising means keys are being dropped), and `redis.memory.fragmentation_ratio` (well above 1.0 means RSS far exceeds used memory). `redis.memory.peak` shows the high-water mark. **Fix**: 1. Raise `maxmemory` or scale out if `used` is approaching the ceiling. 2. Enable `activedefrag` or schedule a restart if fragmentation is high. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Redis running in Kubernetes? Yes. Set `endpoint` to the Redis service DNS (e.g., `redis.default.svc.cluster.local:6379`) and inject the password via a Kubernetes secret. The Collector can run as a sidecar or DaemonSet. #### How do I monitor multiple Redis instances? Add multiple receiver blocks with distinct names: ```yaml receivers: redis/primary: endpoint: redis-1:6379 redis/replica: endpoint: redis-2:6379 ``` Then include both in the pipeline: `receivers: [redis/primary, redis/replica]`. #### What about Redis Cluster mode? Each Redis Cluster node must be monitored individually. Add a separate receiver block for each node endpoint. The Collector connects to each node's standard Redis port, not the cluster bus port. #### Why are replication metrics showing zero? `redis.slaves.connected` and `redis.replication.offset` require replication to be configured. On a standalone instance with no replicas, these report zero - this is expected. #### Why is `redis.maxmemory` not showing up? It is default-off in the receiver. Enable it under `metrics:` (as in the config above) so the memory-saturation alert has a denominator. ### Related Guides - [Azure Cache for Redis Monitoring](../infra/azure/cache-for-redis.md) - the PaaS path for Azure-managed deployments. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Redis metrics. - [Memcached Monitoring](./memcached.md) - Alternative caching service. - [ElastiCache Monitoring](../infra/aws/elasticache.md) - AWS-managed Redis and Memcached. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Memcached](./memcached.md), [RabbitMQ](./rabbitmq.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Restate OpenTelemetry Monitoring - Invocation Outcomes, Partition Lag, and Collector Setup ## Restate Restate serves Prometheus text on the node-control port `5122` with no switch to turn on, and the OpenTelemetry Collector's `prometheus` receiver scrapes it for 211 metric families covering invocation inflow and outcome, invoker and connection-pool saturation, partition health, log and metadata latency, and the RocksDB storage engine underneath. Restate also pushes OTLP traces that follow an invocation from the ingress through every retry attempt to its terminal result, which makes it one of the few durable-execution engines where the trace surface describes your workflows rather than the engine's internals. This guide covers both surfaces, the Collector configuration and shipping to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | --------- | ----------- | | Restate | 1.7 | 1.7.9 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | :::warning Upgrading? Restate renames metrics inside a minor line as well as across one, and five Operational families are absent on 1.7.0. Pin 1.7.9 or later. Full notes: [Updates & Upgrades](#updates--upgrades). ::: Before starting: - The Collector must reach port `5122` over plain HTTP. Restate serves the exposition with no authentication, so restrict the port at the network layer rather than at the application. - Set `RESTATE_NODE_NAME`. Left unset it defaults to the container ID, which changes on every recreate and strands every series that carried the old value. - Decide the partition count before provisioning. It is fixed at provisioning time and it drives cardinality - see [Partition count sets cardinality](#partition-count-sets-cardinality). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or a capacity review. Every series carries `cluster_name` and `node_name`. The labels listed below are the ones beyond those two. #### Core - are invocations arriving, completing and keeping up | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the node is reachable. | | `restate_ingress_requests_total` | Invocation inflow and outcome at the ingress, by `status`, `rpc_service` and `rpc_type`. The headline signal. | | `restate_ingress_request_duration_seconds` | End-to-end ingress latency. Use `_sum` and `_count`, not the quantile series. | | `restate_invoker_invocation_tasks_total` | Invocation attempts started, completed and failed against the service deployment, by `status`, `transient` and `partition_id`. | | `restate_invoker_client_requests_total` | HTTP status of the invoker's calls to the service deployment, by `status_code` and `type`. Non-200 means the deployment is unreachable or broken. | | `restate_partition_applied_lsn_lag` | Records between the last applied LSN and the log tail. The backlog signal. Gauge with a `quantile` label. | | `restate_num_partitions` | Partitions in the partition table. | | `restate_num_active_partitions` | Partitions this node has started. Below `restate_num_partitions` means a partition failed to start. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `restate_num_active_partition_leaders` | Partitions this node leads. | | `restate_invoker_enqueue_total` | Invocations added to the invoker queue, by `partition_id`. | | `restate_invoker_concurrency_limit` | Concurrency slots per `invoker_id`. Defaults to 1000. | | `restate_invoker_concurrency_slots_acquired` | Slots taken. | | `restate_invoker_concurrency_slots_released` | Slots given back. Acquired minus released is in-flight work. | | `restate_invoker_task_duration_seconds` | Time to complete one invocation attempt. | | `restate_invoker_sent_bytes_total`, `restate_invoker_received_bytes_total` | Bytes exchanged with service deployments, by `type`. | | `restate_invocation_client_requests_total` | Partition-processor RPC attempts, by `partition_id` and `status`. | | `restate_ingress_http_connection_created_total`, `restate_ingress_http_connection_dropped_total` | Ingress connection churn. The dropped counter carries `status`. | | `restate_failure_detector_nodes_total` | Nodes per `state`: `alive`, `dead`, `suspect`, `failing_over`. | | `restate_failure_detector_lonely` | This node has not heard gossip for too long. | | `restate_partition_start_total` | Partition-processor starts per `partition`. Repeated increases mean crash-restart churn. | | `restate_partition_num_unknown_applied_lsn_lag` | Partitions whose lag cannot be computed. | | `restate_partition_snapshot_age_seconds` | Age of the newest partition snapshot. `NaN` until a snapshot destination is configured. | | `restate_partition_time_since_last_status_update_seconds` | Staleness of partition status reporting. | | `restate_partition_apply_command_duration_seconds` | Time to apply one partition-processor command, by `command` and `leader`. | | `restate_partition_record_committed_to_read_latency_seconds` | Commit-to-read delay on the log. | | `restate_bifrost_sequencer_append_duration_seconds` | Log append latency as the sequencer sees it. | | `restate_bifrost_sequencer_store_duration_seconds` | Log-server store latency, by `node_id`. | | `restate_log_server_store_records_total`, `restate_log_server_store_bytes_total` | Records and bytes accepted into the log store, by `status`. | | `restate_metadata_client_get_total`, `restate_metadata_client_put_total` | Metadata reads and writes, by `status`. | | `restate_metadata_client_get_duration_seconds`, `restate_metadata_client_put_duration_seconds` | Metadata operation latency. | | `restate_connection_pool_connection_open_failed_total`, `restate_connection_pool_stream_open_failed_total` | Failed HTTP/2 connection attempts and stream reservations against service deployments. | | `restate_connection_pool_acquire_stream_duration_seconds` | Time blocked waiting for a free HTTP/2 stream. | | `restate_jemalloc_resident_bytes` | Resident memory. Restate is Rust, so there are no `go_` or `process_` families here. | | `restate_memory_pool_usage_bytes`, `restate_memory_pool_capacity_bytes` | Memory pool usage and capacity, by `name`. | `restate_bifrost_*` is Restate's internal log abstraction. It has nothing to do with the LLM gateway of the same name covered in [Bifrost Monitoring](./bifrost.md). The two `connection_pool` failure counters register only after an open actually fails, so a healthy node exposes neither. Write those alerts so an absent series reads as zero. #### Diagnostic - for investigation and tuning This tier holds most of the family count and none of the alerts. On a node with the default 24 partitions it is about 170 of the 211 families. | Metric group | Count | When you reach for it | |---|---|---| | `restate_rocksdb_*` | 125 | Storage-engine internals: compaction, write stalls, block cache, memtables, SST reads, per-column-family sizes. | | `restate_metadata_server_*` | 14 | Raft internals of the embedded metadata server: LSNs, indexes, leader id, snapshot size, per-operation counts and durations. | | `restate_connection_pool_*` (remaining) | 6 | HTTP/2 connection and stream lifecycle counts. | | `restate_bifrost_replicatedloglet_*` | 5 | Record-cache hits and enqueued bytes inside the log abstraction. | | `restate_jemalloc_*` (remaining) | 5 | Allocator detail: active, allocated, mapped, metadata, retained. | | `restate_metadata_client_get_version_*`, `restate_metadata_server_get_version_*` | 4 | Metadata version-check traffic. | | `restate_usage_leader_action_count_total`, `restate_usage_leader_journal_entry_count_total` | 2 | Invocation actions and journal entries processed by partition leaders. | | `restate_partition_shuffle_inflight`, `restate_partition_shuffle_message_total` | 2 | Cross-partition message shuffling. | | `restate_tokio_worker_mean_poll_time`, `restate_tokio_worker_poll_count` | 2 | Async-runtime scheduling detail, by `runtime` and `worker`. | | `restate_log_server_loglet_started_total`, `restate_log_server_write_batch_size_bytes` | 2 | Log-server lifecycle and batch sizes. | | `restate_failure_detector_instance`, `restate_failure_detector_gossip_sent_total` | 2 | Gossip identity and volume. | | `restate_partition_handle_leader_action_total` | 1 | Leader actions by `action` type. | | `restate_network_service_accepted_request_bytes_total` | 1 | Bytes accepted per internal service `target`. | #### Reading the ingress counter `restate_ingress_requests_total` carries four `status` values and they do not form one partition. `admitted` counts every request the ingress accepted and carries no `rpc_service` or `rpc_type` label. `completed`, `invocation_error` and `request_error` split those same requests and do carry both labels. Summing across `status` therefore double-counts every request, and a per-service error ratio cannot use `admitted` as its denominator - the label it would need is not there. Use `completed + invocation_error + request_error` as the denominator for an error ratio, and `admitted` minus that sum as an in-flight estimate. The three terminal statuses mean different things: - `invocation_error` - the handler ran and failed permanently. A business failure. - `request_error` - the ingress rejected the request before any handler ran: unknown handler, malformed body, wrong content type. A caller problem. - `completed` - the handler returned successfully. #### A handler failure is not an invoker failure A handler that fails permanently returns its failure in-band. The invocation attempt completes, `restate_invoker_client_requests_total` records HTTP 200, and `restate_invoker_invocation_tasks_total{status="failed"}` does not move. Terminal failures surface only as `restate_ingress_requests_total{status="invocation_error"}`. `restate_invoker_invocation_tasks_total{status="failed"}` carries a `transient` label, and only `transient="true"` is emitted in practice - those are the retryable failures the invoker itself saw. Infrastructure failures and business failures live in different families, so alert on both. #### Summaries, quantiles and NaN 42 of the families are Prometheus summaries, and three more are declared `gauge` but carry a `quantile` label. Three things follow. **Quantile series are rolling and read zero when idle.** The quantile a summary reports is computed over a rolling window, not since process start. When traffic stops, the quantile decays to `0` within about a minute while `_count` stays frozen at its last value. A latency panel built on `quantile="0.99"` reads 0 on an idle service, which looks identical to "very fast". Build latency panels on `rate(_sum) / rate(_count)`, which is cumulative and aggregatable. **The quantile set is not uniform, and the maximum has two spellings.** Most summaries carry `0.5`, `0.9`, `0.99` and `1`. Twenty RocksDB summaries carry `0.5`, `0.95`, `0.99` and `1.0` instead. A query pinned to `quantile="0.9"` returns nothing for those twenty, and one pinned to `quantile="1"` misses every series that spells the maximum `1.0`. **Three gauges need a quantile pin too.** `restate_partition_applied_lsn_lag`, `restate_partition_snapshot_age_seconds` and `restate_partition_time_since_last_status_update_seconds` are gauges with `quantile` values `0.5`, `0.9`, `0.99` and `1.0`, and no `_sum` or `_count` companions. Every query against them must pin a quantile or it returns four series per node. `restate_partition_snapshot_age_seconds` reports `NaN` on all four quantiles until a snapshot destination is configured, and the Collector passes `NaN` straight through. A `> threshold` alert on it never fires until snapshots are turned on. #### Partition count sets cardinality `default-num-partitions` defaults to 24. Each partition gets its own RocksDB column family, and RocksDB families are emitted once per column family, so the series count scales with it: roughly 61 series per partition on top of a fixed base. A node provisioned with 4 partitions serves about 1800 idle series where the default serves about 3000. `partition_id` is also a label on the invoker and invocation-client families. The value is baked in at cluster provisioning and cannot be changed afterwards, so choose it before the first start. #### Duplicate `# TYPE` lines The exposition carries about 1193 `# TYPE` lines for 211 distinct names, because each RocksDB family is emitted once per column family with its own header. The Prometheus exposition format forbids that. The OpenTelemetry Prometheus receiver accepts it without warning and every family arrives intact, so this needs no workaround - but a stricter Prometheus-compatible scraper may reject the payload. #### What the traces show Restate pushes OTLP traces that describe invocations, not engine internals. Each invocation produces four spans, all `Kind: Internal`: | Span name | Meaning | |---|---| | `ingress ` | The HTTP request that admitted the invocation. Root span when the caller sends no `traceparent`. | | `invocation-start ` | The invocation's durable life. Carries the journal as span events. | | `invocation-attempt ` | One attempt against the service deployment. A retried invocation has several. | | `invocation-end ` | The terminal result. | `` is the invocation target with the key templated, so `counter/{key}/add` rather than `counter/user-42/add`. Virtual-object and workflow keys never reach span names, which keeps span-name cardinality at four per handler rather than four per invocation. Four properties make this surface useful: - **An incoming `traceparent` is honoured.** A caller's trace continues through the durable invocation: all four spans join the caller's trace and the `ingress` span is parented to the caller's span. - **Service-to-service calls stay in one trace.** A handler that fans out to four others produces a single trace carrying a start / attempt / end triple for each callee, each parented to the caller's attempt span. - **Retries are visible as repeated attempts.** A handler that fails twice before succeeding produces three `invocation-attempt` spans against one `invocation-start` and one `invocation-end`. - **The journal is on the span.** `restate.invocation.lifecycle.new_command` events on `invocation-start` carry `restate.journal.command.type`, with values such as `Command/Call`, `Command/Sleep`, `Command/Run`, `Command/SetState` and `Command/GetEagerState`. A `restate.invocation.lifecycle.run_ended` event names the completed `ctx.run` side-effect block. Span attributes are `rpc.*` plus Restate's own `restate.*` namespace. `invocation-attempt` carries `restate.deployment.address`, `restate.deployment.id` and `restate.deployment.service_protocol_version`. `invocation-end` carries `restate.invocation.result` (`success` or `failure`) and, on failure, `restate.invocation.error.code` and `error.message`. Two things to know before you build searches on this: - **Only `invocation-attempt` and `invocation-end` set an error status.** `ingress` and `invocation-start` stay `Unset` even for invocations that failed. Search for failures on `invocation-end`. - **The ingress spans use deprecated attribute names.** `client.socket.address` and `client.socket.port` were replaced by `network.peer.address` and `network.peer.port` in semantic conventions 1.21. Restate still emits the old pair. Restate sets `service.name=restate`, `service.namespace=Restate`, `service.version` and `service.instance.id=/` on its own spans. A `resource` processor that upserts `service.name` overwrites Restate's value; the other three survive. Leave `service.name` out of the processor if you want Restate's own naming. ### Key Alerts to Configure Invocation rate, partition lag and run duration are workload-specific, so most rows below are written as ratios or as comparisons against your own history rather than as absolute numbers. | Metric | Threshold | Why it matters | |---|---|---| | `up` | `== 0` for 2 scrapes | The node is gone or unreachable. | | `restate_ingress_requests_total` | `invocation_error` ratio against the sum of the three terminal statuses above the 7-day ratio by `> 2x` over 15m | Handlers are failing permanently. Never use `admitted` as the denominator. | | `restate_ingress_requests_total` | `request_error` rate above the 24h p95 for 10m | Callers are sending requests the ingress rejects before any handler runs. | | `restate_ingress_request_duration_seconds` | `rate(_sum) / rate(_count)` above the 7-day mean for that `rpc_service` by `> 2x` over 15m | End-to-end latency regression. Quantile series are unusable for this. | | `restate_invoker_client_requests_total` | any `status_code` other than 200 increasing over 10m | The service deployment is unreachable or returning HTTP errors, as distinct from handlers failing. | | `restate_invoker_invocation_tasks_total` | `status="failed"` rate above the 24h p95 for 10m | Transient failures are driving retries. | | `restate_partition_applied_lsn_lag` | `quantile="1.0"` above the 24h p95 for 10m | A partition processor is falling behind the log. | | `restate_num_active_partitions` | `< restate_num_partitions` for 5m | A partition failed to start on this node. | | `restate_partition_start_total` | any increase over 10m after steady state | Partition processors are crash-restarting. | | `restate_failure_detector_nodes_total` | `state="dead"` or `state="suspect"` `> 0` for 5m | Cluster membership is degraded. | | `restate_invoker_concurrency_slots_acquired` | acquired minus released within `10%` of `restate_invoker_concurrency_limit` for 10m | The invoker is saturated and new invocations queue. | | `restate_connection_pool_connection_open_failed_total` | any increase over 10m | The node cannot open connections to service deployments. | | `restate_metadata_client_put_total` | `status` other than success increasing over 10m | Metadata writes are failing, which blocks cluster changes. | | `restate_jemalloc_resident_bytes` | above the 24h p95 by `> 1.5x` | Memory growth ahead of an OOM. | | `restate_partition_snapshot_age_seconds` | `quantile="1.0"` above your snapshot interval by `> 3x` | Snapshots have stopped. Only meaningful once a snapshot destination is configured. | ### Access Setup #### Reach the metrics endpoint The endpoint is on by default and needs no flag. It lives on the node-control port, which is separate from both the ingress and the admin API: | Port | Serves | `/metrics` | |---|---|---| | 8080 | Ingress (invocations) | Returns 400 - the ingress reads the path as an invocation target | | 9070 | Admin API | Returns 404 | | 5122 | Node control | The exposition, plus `/health` | ```yaml showLineNumbers title="compose.yaml (excerpt)" services: restate: image: restatedev/restate:1.7.9 environment: # without this, node_name defaults to the container ID RESTATE_NODE_NAME: restate-1 ports: - "8080:8080" # ingress - "9070:9070" # admin - "5122:5122" # node control, serves /metrics volumes: - restate-data:/restate-data ``` Confirm the exposition before touching the Collector: ```bash showLineNumbers title="Verify access" curl -s http://localhost:5122/metrics | grep -c '^restate_' curl -s http://localhost:5122/metrics | grep '^restate_ingress_requests_total' ``` `RESTATE_DISABLE_PROMETHEUS=true` does not turn the endpoint off. It turns off Restate's own recorder while the RocksDB statistics path keeps serving, so the endpoint still returns 200 with about 115 RocksDB families and no `cluster_name` or `node_name` labels on any of them. If you want no metrics surface, block the port; the switch will not do it. The exposition is plain HTTP with no authentication. Bind port 5122 to an internal interface or restrict it to the Collector's address. #### Turn on trace export Traces are off by default and push to the Collector rather than being scraped: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: restate: environment: # OTLP gRPC; also settable as --tracing-endpoint RESTATE_TRACING_ENDPOINT: "http://otel-collector:4317" # default RESTATE_TRACING_FILTER: "info" ``` Restate can split trace export in two: `--tracing-services-endpoint` takes the invocation spans described above and `--tracing-runtime-endpoint` takes the engine's internal spans. `--tracing-endpoint` sets both. On the default `info` filter only the invocation spans are produced, so the single endpoint is the right starting point. ### Configuration The `prometheus` receiver handles metrics and the `otlp` receiver handles the pushed traces. The scrape is unfiltered, so no metric enable list is needed; the Prometheus receiver synthesises the `up` series alongside `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling` and `scrape_series_added`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: restate scrape_interval: 15s static_configs: - targets: - ${env:RESTATE_HOST}:5122 otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] traces: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` Run the Collector on `otel/opentelemetry-collector-contrib:latest` or a pinned tag of it. Drop the traces pipeline if you are only collecting metrics. The `resource` processor deliberately does not set `service.name`. Restate sets its own on the trace path, and on the metrics path the `job_name` above supplies it. Adding a `service.name` upsert overwrites Restate's value on spans. The RocksDB families are most of the payload. If you do not want them, drop them at the receiver rather than downstream: ```yaml showLineNumbers title="config/otel-collector.yaml (Diagnostic drop)" metric_relabel_configs: - source_labels: [__name__] regex: 'restate_(rocksdb|metadata_server|tokio)_.*' action: drop ``` That takes the family count from 211 to about 70, and since the RocksDB families are emitted once per column family it removes most of the series too. Keep `restate_rocksdb_*` if you are tuning storage or chasing write stalls. #### Environment Variables ```bash showLineNumbers title=".env" RESTATE_HOST=localhost ENVIRONMENT=your_environment OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check within 60 seconds: ```bash showLineNumbers # The exposition is reachable curl -s http://localhost:5122/metrics | grep -c '^restate_' # The Collector is scraping Restate docker logs otel-collector 2>&1 | grep -i "restate_ingress_requests_total" # Traces are arriving, if the traces pipeline is enabled docker logs otel-collector 2>&1 | grep -i "invocation-start" ``` In Scout, `up{job="restate"}` should read 1 and `restate_ingress_requests_total` should climb as invocations run. On a node that has served no traffic, expect about 192 families rather than 211: the ingress, invoker and connection-pool families register on first use. ### Troubleshooting #### `/metrics` returns 400 or 404 **Cause**: the scrape is pointed at the ingress port or the admin port. **Look at**: the `up` series for the `restate` job, and the status code from a manual `curl`. The ingress on 8080 returns 400 because it reads `/metrics` as an invocation target; the admin API on 9070 returns 404. **Fix**: point the scrape at port `5122`. #### The endpoint returns 200 but no `restate_ingress_*` series arrive **Cause**: either the node has served no invocations yet, or `RESTATE_DISABLE_PROMETHEUS` is set. **Look at**: whether the response carries `cluster_name` and `node_name` labels. With the recorder disabled, only RocksDB families remain and none of them carry those labels. **Fix**: 1. Unset `RESTATE_DISABLE_PROMETHEUS` and restart the node. 2. Send an invocation and re-scrape. The ingress and invoker families register on first use. #### Latency panels read zero on a quiet service **Cause**: the panel is built on a summary's `quantile` series, which is computed over a rolling window and decays to `0` when traffic stops. **Look at**: the matching `_count` series. If it is frozen and the quantile is 0, the service is idle rather than fast. **Fix**: rebuild the panel on `rate(_sum) / rate(_count)`. #### A quantile query returns no data **Cause**: the quantile label set is not uniform. Most summaries carry `0.9`; twenty RocksDB summaries carry `0.95` instead, and the maximum is spelled `1` on some families and `1.0` on others. **Fix**: check the label values on that specific family before pinning one, or match with `quantile=~"0.9|0.95"` and `quantile=~"1|1.0"`. #### Invocations slow down but the invoker looks healthy **Cause**: the storage engine is throttling writes. Invoker concurrency and handler latency both read normally while every journal append waits on RocksDB. **Look at**: the Diagnostic-tier `restate_rocksdb_*` group, starting with `restate_rocksdb_actual_delayed_write_rate_bytes`. A non-zero value means RocksDB has entered write throttling; the compaction and memtable families in the same group say which column family is behind. **Fix**: give the data volume faster storage or more of it, then re-check the rate. If you dropped `restate_rocksdb_*` at the receiver to save series, re-enable it for the investigation and drop it again after. #### Memory climbs steadily under constant load **Cause**: allocator retention rather than a leak. Restate is Rust and reports through jemalloc, so resident memory can hold well above live allocations. **Look at**: `restate_jemalloc_resident_bytes` against the Diagnostic tier's `restate_jemalloc_*` detail - `active`, `allocated`, `mapped`, `metadata` and `retained`. Resident far above allocated is retention; allocated rising with it is real growth. **Fix**: alert on `restate_jemalloc_resident_bytes` against its own 24h p95 rather than a fixed ceiling, and treat a rising `allocated` as the signal that needs a service-side answer. #### Series disappear after a restart **Cause**: `RESTATE_NODE_NAME` is unset, so `node_name` carries the container ID and changes on every recreate. **Fix**: set `RESTATE_NODE_NAME` to a stable value and keep it stable across recreates. #### Metrics arrive but traces do not **Cause**: `RESTATE_TRACING_ENDPOINT` is unset, or the Collector has no `otlp` receiver on the traces pipeline. **Look at**: Collector logs for OTLP receiver startup, and the node's logs for export errors. **Fix**: 1. Set `RESTATE_TRACING_ENDPOINT` to the Collector's gRPC address with an `http://` scheme. 2. Confirm the traces pipeline lists both the `otlp` receiver and the exporter. ### Updates & Upgrades Restate's metric surface is not additive across releases, and renames land inside a minor line as well as across one. #### Restate version changes - **1.5 → 1.6**: a `_count` suffix is dropped from 25 RocksDB families. Rewrite any query that carries it. _(breaking)_ - **1.6 → 1.7**: `restate_invoker_available_slots` is replaced by `restate_invoker_concurrency_slots_acquired` and `_released`, read against `restate_invoker_concurrency_limit`; `restate_rocksdb_actual_delayed_write_rate` gains a `_bytes` suffix; `restate_network_message_processing_duration_seconds` and `restate_network_message_received_bytes_total` are replaced by `restate_network_service_accepted_request_bytes_total`; and `restate_rocksdb_min_log_number_to_keep` is removed. _(breaking)_ - **1.6 → 1.7**: the whole `restate_connection_pool_*` group, `restate_ingress_http_connection_*`, `restate_invoker_client_requests_total`, `restate_invoker_sent_bytes_total` and `_received_bytes_total`, `restate_log_server_store_*`, `restate_memory_pool_*` and 40 RocksDB families arrive. `restate_invoker_client_requests_total` is what separates a broken service deployment from a failing handler, which is why 1.7 is the floor for the Core tier. _(additive)_ - **1.7.0 → 1.7.9**: four renames land inside the minor line. `restate_partition_time_since_last_status_update` gains a `_seconds` suffix, `restate_partition_shuffle_message_count` becomes `restate_partition_shuffle_message_total`, `restate_partition_shuffle_inflight_count` becomes `restate_partition_shuffle_inflight`, and `restate_partition_is_effective_leader` is replaced by `restate_num_active_partition_leaders`. A dashboard built against 1.7.0 needs review at 1.7.9. _(breaking)_ - **1.7.0 → 1.7.9**: `restate_invocation_client_requests_total`, `restate_partition_num_unknown_applied_lsn_lag` and `restate_partition_snapshot_age_seconds` arrive. With `restate_num_active_partition_leaders` and `restate_partition_time_since_last_status_update_seconds` from the renames above, that is five Operational families absent on 1.7.0 and present on 1.7.9, so run 1.7.9 or later for the full set. _(additive)_ #### Collector / receiver changes - This guide uses the **prometheus receiver**, which has no receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. Every rename above is component-side: it changes the series names in Scout and the queries built on them, not the scrape config. _(no breaking change on the Prometheus path)_ ### FAQ #### Do I need to turn the metrics endpoint on? No. It is on by default on port 5122 and there is no enable flag. `RESTATE_DISABLE_PROMETHEUS` does not turn it off either - it strips Restate's own families and leaves the RocksDB ones serving. #### Why is my node name a random hex string? `RESTATE_NODE_NAME` is unset, so it defaults to the container ID. Set it to a stable value; otherwise every recreate starts a new set of series and abandons the old ones. #### Can I reduce the number of series? Yes, two ways. Drop `restate_rocksdb_*`, `restate_metadata_server_*` and `restate_tokio_*` at the receiver, which takes the family count from 211 to about 70 and most of the series with it. And provision fewer partitions - each one adds a RocksDB column family and roughly 61 series - but that choice is fixed at provisioning and cannot be changed later. #### Do the traces show my workflow runs? Yes. Unlike engines whose trace surface covers scheduler internals, Restate emits a span per invocation lifecycle stage, honours an incoming `traceparent`, keeps service-to-service calls in one trace, and shows each retry as its own `invocation-attempt` span. The journal appears as span events on `invocation-start`. #### Is `restate_bifrost_*` related to the Bifrost LLM gateway? No. Bifrost is the name of Restate's internal log abstraction, the layer that sequences and stores the replicated log. See [Bifrost Monitoring](./bifrost.md) for the unrelated LLM gateway. #### Why does a handler failure not show up in the invoker metrics? Because a permanent handler failure is returned in-band. The invocation attempt completes, the invoker records HTTP 200 against the service deployment, and the failure appears only as `restate_ingress_requests_total{status="invocation_error"}`. The invoker counters cover infrastructure failures, not business ones. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Restate metrics. - [Temporal Monitoring](./temporal.md) - Durable-execution engine with a workflow-and-activity model rather than Restate's journal-and-handler one. - [Hatchet Monitoring](./hatchet.md) - Task queue and durable-execution engine; compare backlog signals across the two. ### What's Next? - **Create Dashboards**: Start with `restate_ingress_requests_total` split by `status`, `rate(_sum) / rate(_count)` on `restate_ingress_request_duration_seconds`, and `restate_partition_applied_lsn_lag` at `quantile="1.0"`. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add [Temporal](./temporal.md) or [Hatchet](./hatchet.md) if you run more than one execution engine. - **Fine-tune Collection**: Decide whether you keep the RocksDB tier, and set the partition count deliberately before you provision - it drives both cardinality and throughput and cannot be changed afterwards. --- ## ScyllaDB OpenTelemetry Monitoring - CQL Throughput, Coordinator Latency, and Collector Setup ## ScyllaDB ScyllaDB is a C++/seastar rewrite of Cassandra: same CQL wire protocol and data model, different engine. If you already run Cassandra, the query side is familiar - what changes is the telemetry. ScyllaDB has **no JVM, no JMX, and no Prometheus JMX-exporter sidecar**. The database process serves a **native, built-in Prometheus endpoint** on port `:9180` at `/metrics` (prefix `scylla_*`). The OpenTelemetry Collector scrapes that endpoint directly with the `prometheus` receiver - one scrape job fanning across the cluster - and collects 460+ `scylla_*` metrics covering CQL throughput, coordinator latency, gossip membership, compaction, and the seastar shard-per-core runtime. This guide configures the scrape, exposes the native endpoint, and ships metrics to base14 Scout. This is the Cassandra-compatible delta on [Cassandra](./cassandra.md). Read that guide for the CQL model; read this one for what is different - the telemetry mechanism and the seastar architecture. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | ScyllaDB | 5.0 | 2026.1+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - ScyllaDB must be running with its native Prometheus endpoint reachable on `:9180` from the host running the Collector. - No monitoring user or credentials - the metrics endpoint needs no authentication (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor ScyllaDB speaks the Cassandra CQL protocol, so the query model is familiar. What is new is the telemetry: every series is `scylla_*` (there are no `jvm_*`, `go_*`, or `process_*` runtime families, because the engine is C++/seastar, not a JVM), and every series carries a `shard` label. seastar is shard-per-core, so each CPU core is one shard: a single-core node has one `shard="0"`, and a multi-core node fans the same metric out to one series per core. That `shard` label has no Cassandra analogue and shapes how you read saturation. Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `scylla_node_operation_mode` | The node's lifecycle state (`NORMAL` when fully serving; any other value while starting, joining, leaving, draining, or in maintenance). The per-node "is this node in the cluster and serving" headline, surfaced natively - no JMX/JVM analogue. | | `scylla_cql_reads`, `scylla_cql_inserts`, `scylla_cql_updates`, `scylla_cql_deletes` | CQL operations served on this node, split by statement type - the headline throughput KPI. The native-Prometheus delta on Cassandra's JMX `clientrequest` Read/Write counts (also broken out per keyspace by `scylla_cql_*_per_ks`). | | `scylla_gossip_live`, `scylla_gossip_unreachable` | Cluster membership as this node sees it over gossip: peers live vs unreachable. `unreachable > 0` means a peer is down or partitioned - the signature distributed-cluster health signal. | | `scylla_storage_proxy_coordinator_write_latency`, `scylla_storage_proxy_coordinator_read_latency` | Client-request latency at the coordinator - the path a CQL client actually waits on, across replicas. The user-facing latency headline (the `_latency_summary` variants carry quantiles). | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `scylla_database_total_writes_failed`, `scylla_database_total_reads_failed` | Writes/reads that failed at the replica - the reliability SLI. Should track ~0 against the `total_writes` / `total_reads` rate. | | `scylla_database_total_writes_timedout` | Writes that did not get enough replica acks within the timeout - replica slowness or a partial outage at the chosen consistency level. | | `scylla_database_total_writes_rate_limited`, `scylla_database_total_reads_rate_limited` | Operations rejected by per-partition rate limiting - a hot partition being shed. | | `scylla_transport_cql_errors_total` | CQL native-protocol errors returned to clients - the transport layer underneath the per-statement counters. | | `scylla_hints_manager_pending_sends`, `scylla_hints_manager_size_of_hints_in_progress` | Hinted-handoff backlog: a replica was unreachable, so writes are stored for replay. Rising means a node is down and the cluster is buffering for it - a distributed signal with no single-node analogue. | | `scylla_compaction_manager_pending_compactions`, `scylla_compaction_manager_backlog` | Compaction falling behind - read amplification and disk growth follow. | | `scylla_reactor_utilization` | Per-shard seastar reactor busy fraction - the shard-per-core saturation signal. A single hot shard caps throughput even when the node looks idle in aggregate. No Cassandra analogue. | | `scylla_storage_proxy_coordinator_current_throttled_writes` | Writes the coordinator is throttling - backpressure from overloaded replicas or materialized-view flow control. | | `scylla_cache_partition_hits`, `scylla_cache_partition_misses` | Row-cache hit ratio. A falling ratio pushes reads to SSTables and drives read latency and disk IO. | | `scylla_commitlog_pending_flushes`, `scylla_commitlog_requests_blocked_memory` | Commitlog flush backlog and writers blocked on commitlog memory - write-path stalls. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review. In production you can drop this tier with `metric_relabel_configs` and keep Core plus Operational. These are grouped families, not individual rows - the counts are the distinct `scylla_*` names in each family of the 464 total. | Family | Count | What it covers | |---|---|---| | `scylla_database_*` | 48 | Top-level read/write totals, reliability (failed/timedout/rate-limited), querier, multishard query, view-update push/fail. | | `scylla_sstables_*` | 45 | On-disk read/write, index and promoted-index page cache, bloom filters, partition/row/range scans. | | `scylla_cache_*` | 35 | Unified row cache: hits/misses/evictions/insertions/removals, tombstone reads, bytes. | | `scylla_reactor_*` | 30 | Per-shard seastar reactor: utilization, stalls, CPU, AIO. | | `scylla_storage_proxy_*` | 25 | Coordinator and replica request paths, speculative reads, LWT/CAS, view-update backlog. | | `scylla_raft_*` | 24 | Raft consensus for cluster metadata / group0 / tablets. | | `scylla_cql_*` | 24 | CQL statement counters (reads/inserts/updates/deletes, batches), including per-keyspace. | | `scylla_hints_*` | 22 | Hinted handoff: pending sends/drains, written/sent, errors, in-progress size. | | `scylla_schema_commitlog_*` | 20 | Dedicated commitlog for schema changes. | | `scylla_commitlog_*` | 20 | Data write-ahead log: segments, pending flushes, disk/memory bytes. | | `scylla_io_queue_*` | 19 | Per-shard IO scheduler: delay, disk queue length, operations. | | `scylla_memory_*` | 16 | Seastar allocator: allocated/free memory, malloc failures, reclaim. | | `scylla_transport_*` | 15 | CQL native protocol: connections, in-flight requests, memory, errors. | | `scylla_lsa_*` | 13 | Log-structured allocator occupancy/compaction. | | `scylla_column_family_*` | 13 | Per-table SSTable/memtable/read/write (carries `cf`/`ks`; high cardinality in wide schemas). | | `scylla_load_balancer_*` | 10 | Tablet load-balancing decisions. | | `scylla_tracing_*` | 10 | Request tracing sink to `system_traces`. | | `scylla_view_*` | 8 | Materialized-view update generator pipeline (`view_update` / `view_builder`). | | `scylla_compaction_manager_*` | 8 | Compaction: pending/completed/failed, backlog. | | `scylla_scheduler_*` | 7 | Per-shard task scheduler: runtime, wait, starvation, quota violations. | | `scylla_rpc_*` | 7 | Inter-node messaging-service RPC client. | | remaining (`scylla_gossip_*`, `scylla_streaming_*`, `scylla_memtables_*`, `scylla_node_*`, `scylla_tablet*`, `scylla_per_partition_rate_limiter_*`, `scylla_httpd_*`, `scylla_execution_stages_*`, `scylla_mapreduce_service_*`, `scylla_alien_*`, ...) | ~57 | Gossip membership, data streaming, memtable flush, node ops, tablets, per-partition rate limiter, REST httpd, execution stages, map-reduce aggregation, cross-shard alien queues. | Full metric surface: run `curl -s http://localhost:9180/metrics` against any ScyllaDB node. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `scylla_node_operation_mode` (per node) | != `NORMAL` briefly | != `NORMAL` sustained | The node is joining, draining, or stuck rather than serving. Check the node and its gossip view. | | `scylla_gossip_unreachable` (per node) | > 0 briefly | > 0 sustained | A peer is unreachable (down or partitioned); confirm with `nodetool status`. | | `rate(scylla_cql_reads) + rate(scylla_cql_inserts)` | Falling under expected load | ≈ 0 sustained | The node has stopped serving CQL; check `scylla_node_operation_mode` and gossip. | | `rate(scylla_database_total_writes_failed) / rate(scylla_database_total_writes)` | Rising vs baseline | Sustained climb | Write failures climbing relative to the workload's normal failure ratio. | | `scylla_database_total_writes_timedout` | Increasing | Rising across scrapes | Writes not acked within timeout; a replica is slow or down at the chosen consistency level. | | `scylla_storage_proxy_coordinator_write_latency` / `_read_latency` p99 | Above baseline | Well above baseline | Coordinator latency regression, relative to the workload's normal p99. | | `scylla_hints_manager_pending_sends` | > 0 sustained | Not draining | A replica is down and hints are accumulating; the cluster is healing, not healed. | | `scylla_compaction_manager_pending_compactions` / `_backlog` | Rising | Not draining | Compaction cannot keep up; read amplification and disk growth follow. | | `scylla_reactor_utilization` (per shard) | Near 1.0 briefly | Near 1.0 sustained | That shard is saturated; throughput is shard-bound even if the node looks idle in aggregate. | | `scylla_cache_partition_misses / (_hits + _misses)` | Rising | Sustained climb | Row-cache hit ratio dropping; reads are spilling to SSTables. | | `scylla_commitlog_requests_blocked_memory` | > 0 | Sustained > 0 | Writers blocked on commitlog memory; the write path is stalling. | ### Access Setup ScyllaDB's metrics endpoint needs **no exporter and no authentication**. The native Prometheus endpoint is served by the database process itself - this is the structural delta over Cassandra, where you download a JMX exporter JAR, add a `-javaagent` flag, and scrape it on `:9404`. None of that applies here: there is no JAR, no agent flag, and no CQL auth for metrics. Expose the native endpoint instead. ScyllaDB serves `/metrics` on port `:9180` by default. Two `scylla.yaml` settings control it: ```yaml showLineNumbers title="scylla.yaml (excerpt)" # Port for the native Prometheus metrics endpoint (default 9180). prometheus_port: 9180 # Address the metrics endpoint binds to. Bind to the node's listen # address (or 0.0.0.0) so the Collector can reach it; leaving it on # loopback hides it from a Collector on another host. prometheus_address: 0.0.0.0 ``` In Docker, publish or network-attach `:9180` from each node so the Collector can reach it. Verify the endpoint before wiring the Collector: ```bash showLineNumbers title="Verify access" # Confirm the node is serving and NORMAL nodetool status # Verify the native Prometheus endpoint curl -s http://localhost:9180/metrics | grep scylla_node_operation_mode ``` ### Configuration The Collector uses the `prometheus` receiver to scrape the native endpoint. One scrape job (`job_name: scylla`) fans across every node at `metrics_path: /metrics` on `:9180` - no JMX exporter, no `:9404` target, no `jmx-config.yaml`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: scylla scrape_interval: 15s metrics_path: /metrics static_configs: - targets: # One target per node's native :9180 endpoint - scylla1:9180 - scylla2:9180 - scylla3:9180 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` Each node is identified by its `instance` label (`host:9180`). To control metric volume in production, drop the Diagnostic-tier families with a `metric_relabel_configs` block on the scrape config while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped ScyllaDB metrics docker logs otel-collector 2>&1 | grep -i "scylla" # Verify the native endpoint is serving metrics curl -s http://localhost:9180/metrics | grep scylla_cql_reads # Confirm the node is in the cluster and serving nodetool status ``` `scylla_node_operation_mode` should read `NORMAL` on every serving node, and `scylla_gossip_unreachable` should be `0` in a healthy cluster. ### Troubleshooting #### Metrics endpoint not responding on port 9180 **Cause**: The native Prometheus endpoint is bound to loopback or the port is blocked between the node and the Collector. **Fix**: 1. Confirm `prometheus_address` in `scylla.yaml` binds the node's reachable address (or `0.0.0.0`), not loopback. 2. Confirm `prometheus_port` matches the Collector scrape target (`:9180`). 3. Check firewall and Docker network rules if the Collector runs on a separate host. #### A node is not serving CQL **Cause**: The node is joining, draining, or stuck rather than `NORMAL`, or it cannot see its peers. **Look at**: `scylla_node_operation_mode` (any value other than `NORMAL` means it is not fully serving) and `scylla_gossip_unreachable` (a non-zero count means a peer is down or partitioned). Confirm with `nodetool status`. **Fix**: 1. If `scylla_node_operation_mode` is not `NORMAL`, wait for the join/drain to finish or investigate the node's startup logs. 2. If `scylla_gossip_unreachable > 0`, find the unreachable peer and restore it; hints (`scylla_hints_manager_pending_sends`) will replay buffered writes once it returns. #### Writes are timing out or failing **Cause**: A replica is slow or down at the chosen consistency level, or the coordinator is throttling under backpressure. **Look at**: `scylla_database_total_writes_timedout` and `scylla_database_total_writes_failed` (the reliability SLI), and the Diagnostic `scylla_storage_proxy_*` coordinator/replica paths plus `scylla_storage_proxy_coordinator_current_throttled_writes` for backpressure. **Fix**: 1. Restore or speed up the slow replica; check its gossip and operation mode. 2. If the coordinator is throttling, investigate overloaded replicas or materialized-view flow control. #### A shard is saturated but the node looks idle **Cause**: seastar is shard-per-core - one hot shard caps throughput even when the node's aggregate CPU looks free. **Look at**: `scylla_reactor_utilization` per `shard` (near 1.0 on one shard is the signal), and the Diagnostic `scylla_scheduler_*` and `scylla_io_queue_*` families for where that shard's time is going. **Fix**: 1. Identify the hot partition or skewed key driving the shard; rebalance the workload or schema. 2. Confirm core count and `--smp` settings match the node's CPU allocation. #### Reads are slow and disk IO is climbing **Cause**: The row cache is missing more often, pushing reads to SSTables, or compaction is falling behind. **Look at**: `scylla_cache_partition_hits` / `_misses` (the hit ratio), and the Diagnostic `scylla_compaction_manager_*` and `scylla_sstables_*` families for compaction backlog and on-disk read amplification. **Fix**: 1. If the cache hit ratio is dropping, review working-set size and query patterns. 2. If `scylla_compaction_manager_pending_compactions` / `_backlog` is rising and not draining, add IO capacity or tune the compaction strategy. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Why is there no exporter or JMX agent like Cassandra? ScyllaDB is a C++/seastar rewrite of Cassandra, so there is no JVM and no JMX. The database process serves a native Prometheus endpoint on `:9180` at `/metrics`. You scrape it directly with the `prometheus` receiver - there is no JAR to download, no `-javaagent` flag, and no `:9404` exporter. The entire metric surface is `scylla_*`, with no `jvm_*`, `go_*`, or `process_*` runtime families. #### What is the `shard` label on every metric? seastar is shard-per-core: each CPU core is one shard, with its own thread, memory, and IO queue. A single-core node has one `shard="0"`; a multi-core node emits the same metric once per core. Read saturation per shard (`scylla_reactor_utilization`), not just per node - a single hot shard caps throughput while the node's aggregate CPU looks idle. #### Does this work with ScyllaDB running in Kubernetes? Yes. Point the scrape `targets` at each node's service DNS on `:9180` (e.g., `scylla-0.scylla.default.svc.cluster.local:9180`). The Collector can run as a sidecar or a Deployment. No credentials are needed for the metrics endpoint. #### How do I monitor a multi-node ScyllaDB cluster? Add every node's `:9180` endpoint to the single `scylla` scrape job's `targets` list. Each node is scraped independently and identified by its `instance` label, and seastar's `shard` label separates per-core series within each node. #### Why are some metric families reading zero? Families like `scylla_streaming_*`, `scylla_view_*`, and `scylla_load_balancer_*` only move on topology change or when materialized views or LWT are in use. They are available surface, not missing - they will populate when the corresponding operation runs. ### Related Guides - [Cassandra Monitoring](./cassandra.md) - The Cassandra-compatible counterpart; the JMX-exporter guide this is the native-telemetry delta on. - [CockroachDB Monitoring](./cockroachdb.md) - Distributed SQL database with a native Prometheus endpoint. - [YugabyteDB Monitoring](./yugabytedb.md) - Distributed SQL database that also speaks the CQL protocol. - [TiDB Monitoring](./tidb.md) - Distributed SQL database with per-component Prometheus metrics. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on ScyllaDB metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Cassandra](./cassandra.md), [CockroachDB](./cockroachdb.md), and other distributed databases. - **Fine-tune Collection**: Drop the Diagnostic tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## SNMP OpenTelemetry Monitoring - Routers, UPSes, Linux Hosts, and Collector Setup ## SNMP The OpenTelemetry Collector's `snmpreceiver` polls SNMP-speaking devices over UDP, converts enterprise and standard MIB OIDs to named metrics, and exports OTLP to base14 Scout. Use it for network gear (routers, switches, firewalls), power infrastructure (UPSes, PDUs), printers, and any host running `net-snmp`. This guide configures three representative device profiles — a Linux host, a Cisco-style router, and an APC-style UPS — and ships the metrics upstream. The same pattern generalises to any SNMPv1/v2c/v3-capable device. Because `snmpreceiver` is poll-only, it is particularly well suited to monitoring infrastructure that cannot run agents itself — which makes SNMP a natural bridge into broader IoT and OT telemetry work. ### Prerequisites | Requirement | Minimum | Recommended | | --- | --- | --- | | SNMP version | v1 | v2c or v3 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | Target devices | SNMP-enabled | SNMPv2c/v3 with community or user configured | | base14 Scout | Any | - | Before starting: - Devices must be reachable over UDP/161 from the Collector host - A read-only community string (v1/v2c) or SNMPv3 user with appropriate auth/priv keys - OTel Collector installed — see [Docker Compose Setup](../collector-setup/docker-compose-example.md) ### What You'll Monitor `snmpreceiver` has no fixed metric set. Each metric below exists because the config maps an OID — scalar or column — to an OTel dotted name with an explicit unit and type, so the emitted set IS the config; you choose the names when you map each OID. The tiers are organised by how you use the metrics across three device classes: `[net]` for the router, `[ups]` for the UPS, `[host]` for the Linux host. Four things shape how this surface reads, regardless of device: - **There is no `up` series and no health metric.** Liveness is the receiver scraping the device successfully — the device answering its OIDs. A sustained scrape error in the Collector log is the device-unreachable signal. - **Two metric types.** `network.io` and `network.errors` are monotonic cumulative sums (interface octet/error counters, each carrying a `direction` attribute); everything else is a gauge. - **One endpoint per receiver instance.** Use one `snmp/` block per device (or per device class sharing credentials). Each pipeline stamps a distinct `service.name`, so every device appears as its own service in Scout. Column OIDs fan out to one resource per row — `network.interface.name` from `ifName`, `cpu.index` from the `hrProcessorTable`. - **Static labels come from a processor, not the receiver.** `device.kind` (compute / network / power), `device.manufacturer`, `device.model.identifier`, and `site.id` are added by a `resource` processor — `snmpreceiver` can only attach values it actually fetches over SNMP. Several MIBs store fixed-point values as scaled integers: `system.cpu.load_average.*` is `laLoadInt` (×100), `ups.battery.runtime_remaining` is `TimeTicks` (centiseconds, not seconds), and some PowerNet frequencies use units of 0.1 Hz. Rescale these in the backend or a `transform` processor; do not assume base units. #### Core - is the link, power, or host healthy The per-device-class headline pair: link state plus throughput for the router, output state plus battery runway for the UPS, load plus available memory for the host. | Metric | Type | Class | What it tells you | |---|---|---|---| | `network.interface.oper_status` | gauge | [net] | Operational link state (1=up, 2=down, …) — the outage signal. | | `network.io` | sum | [net] | Per-interface bytes in/out (ifHCOctets) — headline throughput. | | `ups.output.status` | gauge | [ups] | 2=onLine, 3=onBattery, … — the utility-power-lost signal. | | `ups.battery.capacity` | gauge | [ups] | Remaining battery capacity (%) — the runway. | | `system.cpu.load_average.1m` | gauge | [host] | 1-minute load average ×100 — headline host load. | | `system.memory.available` | gauge | [host] | Available real memory (KiB) — headline host memory. | #### Operational - what to alert on The error counters, status/replace enums, voltage and load readings, and the saturation denominators (`network.interface.speed`, `system.memory.total`) the Core numbers are read against. | Metric | Type | Class | What it tells you | |---|---|---|---| | `network.errors` | sum | [net] | Interface in/out errors — rising = a link or cabling problem. | | `network.interface.admin_status` | gauge | [net] | Administrative state (1=up, 2=down) — compare with oper_status. | | `network.interface.speed` | gauge | [net] | Nominal speed (Mbit/s) — denominator for saturation. | | `ups.battery.status` | gauge | [ups] | 1=unknown, 2=normal, 3=low (replace is the separate `ups.battery.replace_indicator`). | | `ups.battery.replace_indicator` | gauge | [ups] | 2=battery needs replacing. | | `ups.battery.runtime_remaining` | gauge | [ups] | Estimated runtime (centiseconds, TimeTicks). | | `ups.input.voltage` | gauge | [ups] | Input line voltage (V) — utility quality. | | `ups.output.load` | gauge | [ups] | Output load (% of rated capacity) — overload risk. | | `system.cpu.utilization` | gauge | [host] | Per-CPU utilization (%, per-core fan-out). | | `system.cpu.load_average.5m` | gauge | [host] | 5-minute load average ×100. | | `system.cpu.load_average.15m` | gauge | [host] | 15-minute load average ×100. | | `system.memory.total` | gauge | [host] | Total real memory (KiB) — denominator for memory pressure. | | `system.processes.count` | gauge | [host] | Running process count. | #### Diagnostic - for investigation and tuning Inventory and second-order context. Reach for these during an incident or a capacity review. | Metric | Type | Class | What it tells you | |---|---|---|---| | `system.network.interfaces.count` | gauge | [net] | ifNumber — interface inventory. | | `system.users.count` | gauge | [host] | Active user sessions. | | `system.memory.cached` | gauge | [host] | Cached memory (KiB). | | `system.memory.buffered` | gauge | [host] | Buffered memory (KiB). | | `ups.battery.temperature` | gauge | [ups] | Battery temperature (Cel). | | `ups.input.frequency` | gauge | [ups] | Input line frequency (Hz). | | `ups.output.voltage` | gauge | [ups] | Output voltage (V). | | `ups.output.current` | gauge | [ups] | Output current (A). | Full receiver reference: [OTel SNMP Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/snmpreceiver). The runnable example with a built-in SNMP simulator lives at [base14/examples — components/snmp-telemetry](https://github.com/base-14/examples/tree/main/components/snmp-telemetry). It ships three simulated devices (communities `linux-host`, `cisco-router`, `apc-ups`) on `udp://snmpsim:1161`, so the config below works unchanged against the simulator if you swap the real endpoints for that address. ### Key Alerts to Configure The state reads below — `oper_status == 2`, `output.status == 3`, `battery.status == 3`, `replace_indicator == 2` — are MIB-defined enum values, not invented thresholds. Everything else is relative to your own baseline or the device's own rating; tune to your fleet. | Alert | Condition | Why it matters | |---|---|---| | Link down (unplanned) | `network.interface.oper_status` == 2 while `network.interface.admin_status` == 1 | The interface is administratively up but operationally down — an unplanned outage, not a config change. | | Interface errors rising | `rate(network.errors)` > 0 / rising vs baseline | Errors climbing point to a link, duplex, or cabling fault. | | Interface saturation | `network.io` rate approaching `network.interface.speed` | The link is near its nominal capacity; expect drops and queueing. | | UPS on battery | `ups.output.status` == 3 (onBattery) | Utility power is lost; the load is now on battery runway. | | UPS battery low / replace | `ups.battery.status` == 3 or `ups.battery.replace_indicator` == 2 | The battery is degraded or end-of-life; schedule a replacement. | | UPS battery runway short | `ups.battery.capacity` dropping vs baseline / `ups.battery.runtime_remaining` falling | Remaining runtime is shrinking; plan a graceful shutdown before it hits zero. | | UPS overload | `ups.output.load` high vs the unit's rated capacity | The UPS is carrying more than it should; shed load or upgrade. | | Host memory pressure | `system.memory.available` dropping vs baseline | Free real memory is shrinking toward swap or OOM. | | Host CPU saturation | `system.cpu.load_average.1m` rising above the core count | Sustained load above the core count means the run queue is backing up. | | Device unreachable | sustained `snmpreceiver` scrape errors / no data for the device | The device stopped answering its OIDs — there is no `up` series, so the scrape error is the liveness signal. | ### Access Setup No code runs on the device. All you need is SNMP read access. **SNMPv2c** — enable `snmpd` and set a read-only community: ```text showLineNumbers title="/etc/snmp/snmpd.conf (Linux)" rocommunity readonly_community_here default sysLocation "rack-A1, row-3" sysContact "ops@example.com" ``` Then restart `snmpd` and test from the host that will run the Collector: ```bash showLineNumbers snmpwalk -v2c -c readonly_community_here -t 2 target-host:161 \ 1.3.6.1.2.1.1.1 ``` **SNMPv3** — prefer `authPriv` with SHA/AES: ```text showLineNumbers title="/etc/snmp/snmpd.conf" createUser monitor SHA "auth-key-here" AES "priv-key-here" rouser monitor priv ``` For network gear, the vendor CLI equivalents apply (Cisco `snmp-server community`, Junos `snmp { community }`, etc.). Always scope communities and SNMPv3 users to the Collector host's source address when the device supports it. ### Configuration The `snmpreceiver` takes one endpoint per receiver instance, so use one instance per device (or per device class sharing credentials). Metrics are defined by OID with an explicit `unit` and either `scalar_oids` (values ending in `.0`) or `column_oids` (indexed tables). Table rows fan out to separate resources via `resource_attributes`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: snmp/linux: collection_interval: 30s endpoint: udp://linux-host.internal:161 version: v2c community: ${env:SNMP_COMMUNITY_LINUX} resource_attributes: device.id: scalar_oid: "1.3.6.1.2.1.1.5.0" # sysName cpu.index: indexed_value_prefix: "cpu_" metrics: system.processes.count: description: Number of processes running (hrSystemProcesses) unit: "{processes}" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.2.1.25.1.6.0" system.users.count: description: Active user sessions (hrSystemNumUsers) unit: "{users}" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.2.1.25.1.5.0" system.memory.total: description: Total real memory (UCD memTotalReal) unit: KiBy gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.4.5.0" system.memory.available: description: Available real memory (UCD memAvailReal) unit: KiBy gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.4.6.0" system.memory.cached: description: Cached memory (UCD memCached) unit: KiBy gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.4.11.0" system.memory.buffered: description: Buffered memory (UCD memBuffer) unit: KiBy gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.4.14.0" system.cpu.load_average.1m: description: "1-minute load average x 100 (UCD laLoadInt.1)" unit: "1" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.10.1.5.1" system.cpu.load_average.5m: description: "5-minute load average x 100 (UCD laLoadInt.2)" unit: "1" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.10.1.5.2" system.cpu.load_average.15m: description: "15-minute load average x 100 (UCD laLoadInt.3)" unit: "1" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.2021.10.1.5.3" system.cpu.utilization: description: Per-CPU utilization (hrProcessorLoad) unit: "%" gauge: { value_type: int } column_oids: - oid: "1.3.6.1.2.1.25.3.3.1.2" resource_attributes: [cpu.index] snmp/router: collection_interval: 30s endpoint: udp://edge-router.internal:161 version: v2c community: ${env:SNMP_COMMUNITY_ROUTER} resource_attributes: device.id: scalar_oid: "1.3.6.1.2.1.1.5.0" network.interface.name: oid: "1.3.6.1.2.1.31.1.1.1.1" # ifName attributes: direction: enum: [receive, transmit] metrics: system.network.interfaces.count: description: Number of network interfaces (IF-MIB ifNumber) unit: "{interfaces}" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.2.1.2.1.0" network.io: description: Interface I/O bytes (ifHCInOctets / ifHCOutOctets) unit: By sum: value_type: int monotonic: true aggregation: cumulative column_oids: - oid: "1.3.6.1.2.1.31.1.1.1.6" resource_attributes: [network.interface.name] attributes: - { name: direction, value: receive } - oid: "1.3.6.1.2.1.31.1.1.1.10" resource_attributes: [network.interface.name] attributes: - { name: direction, value: transmit } network.errors: description: Interface errors (ifInErrors / ifOutErrors) unit: "{errors}" sum: value_type: int monotonic: true aggregation: cumulative column_oids: - oid: "1.3.6.1.2.1.2.2.1.14" resource_attributes: [network.interface.name] attributes: - { name: direction, value: receive } - oid: "1.3.6.1.2.1.2.2.1.20" resource_attributes: [network.interface.name] attributes: - { name: direction, value: transmit } network.interface.speed: description: Interface nominal speed (ifHighSpeed) unit: "Mbit/s" gauge: { value_type: int } column_oids: - oid: "1.3.6.1.2.1.31.1.1.1.15" resource_attributes: [network.interface.name] network.interface.admin_status: description: "ifAdminStatus - 1=up, 2=down, 3=testing" unit: "1" gauge: { value_type: int } column_oids: - oid: "1.3.6.1.2.1.2.2.1.7" resource_attributes: [network.interface.name] network.interface.oper_status: description: "ifOperStatus - 1=up, 2=down, 3=testing, 4=unknown, 5=dormant" unit: "1" gauge: { value_type: int } column_oids: - oid: "1.3.6.1.2.1.2.2.1.8" resource_attributes: [network.interface.name] snmp/ups: collection_interval: 30s endpoint: udp://ups-dc01.internal:161 version: v2c community: ${env:SNMP_COMMUNITY_UPS} resource_attributes: device.id: scalar_oid: "1.3.6.1.2.1.1.5.0" metrics: ups.battery.status: description: "Battery status - 1=unknown, 2=normal, 3=low" unit: "1" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.2.1.1.0" ups.battery.capacity: description: Remaining battery capacity (upsAdvBatteryCapacity) unit: "%" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.2.2.1.0" ups.battery.temperature: description: Battery temperature (upsAdvBatteryTemperature) unit: "Cel" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.2.2.2.0" ups.battery.runtime_remaining: description: Estimated runtime remaining, centiseconds (TimeTicks) unit: "cs" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.2.2.3.0" ups.battery.replace_indicator: description: "1=no replacement needed, 2=battery needs replacement" unit: "1" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.2.2.4.0" ups.input.voltage: description: Input line voltage (upsAdvInputLineVoltage) unit: "V" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.3.2.1.0" ups.input.frequency: description: Input line frequency (upsAdvInputFrequency) unit: "Hz" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.3.2.4.0" ups.output.status: description: "Output status - 2=onLine, 3=onBattery, 4=onSmartBoost, ..." unit: "1" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.4.1.1.0" ups.output.voltage: description: Output voltage (upsAdvOutputVoltage) unit: "V" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.4.2.1.0" ups.output.load: description: Output load as percent of rated capacity unit: "%" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.4.2.3.0" ups.output.current: description: Output current (upsAdvOutputCurrent) unit: "A" gauge: { value_type: int } scalar_oids: - oid: "1.3.6.1.4.1.318.1.1.1.4.2.4.0" processors: memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 25 batch: timeout: 10s send_batch_size: 1024 # Static metadata per pipeline. snmpreceiver only attaches values # it can retrieve via SNMP; constants like service.name and # device.kind are added here. Each device gets a distinct # service.name so it appears as its own service in Scout. resource/linux: attributes: - { key: service.name, value: "linux-host-01", action: insert } - { key: service.namespace, value: ${env:SERVICE_NAMESPACE}, action: insert } - { key: deployment.environment.name, value: ${env:ENVIRONMENT}, action: insert } - { key: environment, value: ${env:ENVIRONMENT}, action: insert } - { key: device.kind, value: compute, action: insert } - { key: device.manufacturer, value: "generic-linux", action: insert } - { key: device.model.identifier, value: "net-snmp", action: insert } - { key: site.id, value: ${env:SITE_ID}, action: insert } resource/router: attributes: - { key: service.name, value: "cisco-router-01", action: insert } - { key: service.namespace, value: ${env:SERVICE_NAMESPACE}, action: insert } - { key: deployment.environment.name, value: ${env:ENVIRONMENT}, action: insert } - { key: environment, value: ${env:ENVIRONMENT}, action: insert } - { key: device.kind, value: network, action: insert } - { key: device.manufacturer, value: "cisco", action: insert } - { key: device.model.identifier, value: "ISR-C2900", action: insert } - { key: site.id, value: ${env:SITE_ID}, action: insert } resource/ups: attributes: - { key: service.name, value: "apc-ups-01", action: insert } - { key: service.namespace, value: ${env:SERVICE_NAMESPACE}, action: insert } - { key: deployment.environment.name, value: ${env:ENVIRONMENT}, action: insert } - { key: environment, value: ${env:ENVIRONMENT}, action: insert } - { key: device.kind, value: power, action: insert } - { key: device.manufacturer, value: "apc", action: insert } - { key: device.model.identifier, value: "Smart-UPS-SRT", action: insert } - { key: site.id, value: ${env:SITE_ID}, action: insert } exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics/linux: receivers: [snmp/linux] processors: [memory_limiter, resource/linux, batch] exporters: [otlphttp/b14] metrics/router: receivers: [snmp/router] processors: [memory_limiter, resource/router, batch] exporters: [otlphttp/b14] metrics/ups: receivers: [snmp/ups] processors: [memory_limiter, resource/ups, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" SNMP_COMMUNITY_LINUX=readonly_community_here SNMP_COMMUNITY_ROUTER=readonly_community_here SNMP_COMMUNITY_UPS=readonly_community_here # Service identity — each device pipeline stamps its own service.name # (linux-host-01 / cisco-router-01 / apc-ups-01). These env vars # apply to all three. SERVICE_NAMESPACE=network-infra ENVIRONMENT=demo SITE_ID=your-site-id OTEL_EXPORTER_OTLP_ENDPOINT=https://otel..base14.io ``` Every metric carries a service.name/service.namespace/environment set and the IoT device schema: `device.id`, `device.kind` (`compute` / `network` / `power`), `device.manufacturer`, `device.model.identifier`, `site.id`. Network gear is a compute device with `device.kind=network` — there is no separate `network.device.*` namespace. Each simulated (or real) device appears as its own service in Scout because each receiver pipeline stamps a distinct `service.name`. #### Shipping via a Local Scout Collector The `otlphttp/b14` exporter above ships directly to Scout. If you already run a tenant-local Scout Collector — recommended when you have multiple apps on the same host, need local buffering, or want a single point of auth — forward metrics to it instead: ```yaml showLineNumbers title="config/otel-collector.yaml (alternative)" exporters: otlphttp/upstream: endpoint: http://otel-collector-base14:4318 ``` Then join the Scout Collector's Docker network so DNS resolves the container name: ```yaml showLineNumbers title="docker-compose.yaml" services: otel-collector: # ... networks: - default - otel-collector-network networks: otel-collector-network: external: true ``` For setting up that upstream Scout Collector, see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### Verify the Setup Start the Collector and check for successful scrapes within 60 seconds. From the host running the Collector: ```bash showLineNumbers # Probe each device reachability and credentials snmpwalk -v2c -c "$SNMP_COMMUNITY_LINUX" -t 2 linux-host.internal:161 1.3.6.1.2.1.1.1 snmpwalk -v2c -c "$SNMP_COMMUNITY_ROUTER" -t 2 edge-router.internal:161 1.3.6.1.2.1.31.1.1.1.6 snmpwalk -v2c -c "$SNMP_COMMUNITY_UPS" -t 2 ups-dc01.internal:161 1.3.6.1.4.1.318.1.1.1.2.2 # Confirm the Collector emitted metrics docker logs otel-collector 2>&1 | grep -E 'Name: (network\.io|ups\.|system\.)' ``` ### Troubleshooting #### `no such host` or DNS lookup failures **Cause**: The Collector cannot resolve the device hostname, or a Docker network isolates it from the device. **Fix**: 1. Use an IP literal in `endpoint` if DNS is not available inside the Collector container 2. On Docker Desktop, use `host.docker.internal` to reach services on the host 3. Run the Collector with `network_mode: host` if the target is on the host's network segment #### `Request timeout` on scrape **Cause**: Device is slow to respond, or UDP packets are being dropped. **Fix**: 1. Raise `timeout: 10s` on the receiver block 2. Lower `collection_interval` pressure if the device is resource- constrained (default 30s is usually fine) 3. Verify UDP/161 is not blocked by an ACL or firewall between Collector and device #### `No Such Instance` for Counter64 OIDs **Cause**: The device does not support the `ifXTable` (IF-MIB high-capacity counters), common on older hardware. **Fix**: Fall back to 32-bit counters: ```yaml column_oids: - oid: "1.3.6.1.2.1.2.2.1.10" # ifInOctets (Counter32) resource_attributes: [network.interface.name] attributes: - { name: direction, value: receive } ``` Expect wraparound on high-throughput interfaces; as a Counter32 in octets, ifInOctets wraps at 2^32 bytes (~4 GiB), so a busy link can roll over in seconds. #### Metric values look wrong by a factor of 10 or 100 **Cause**: Several MIBs store fixed-point values as scaled integers (for example, UCD `laLoadInt` uses ×100; PowerNet `upsAdvOutputFrequency` uses units of 0.1 Hz). `upsAdvBatteryRunTimeRemaining` is a `TimeTicks` value — centiseconds, not seconds — so a 30-minute runtime reads as `180000`. The Operational `ups.battery.runtime_remaining` and the Diagnostic `ups.input.frequency` are the series this most often bites. **Look at**: the raw `system.cpu.load_average.*` and `ups.battery.runtime_remaining` values against what the device's own CLI reports — a clean ×100 or centisecond offset confirms it is a scaling issue, not a bad OID. **Fix**: 1. Check the MIB definition for the OID's `UNITS` clause 2. Document the scale in the metric `description`, or 3. Apply a `transform` processor to rescale before export #### Scrape errors flood the log during a device outage **Cause**: The receiver logs each failed scrape at error level. With no `up` series, a sustained run of these entries is the device-unreachable signal. **Look at**: whether the affected pipeline's metrics go stale in Scout (`network.io`, `ups.output.status`, or `system.memory.available` stop updating) — that, alongside the scrape errors, confirms the device is down rather than a transient packet drop. **Fix**: The Collector pipeline keeps running — the error entries are expected and recoverable. To quiet them, increase `collection_interval` for the flaky receiver, or route the Collector's own logs through a `filter/logs` processor that drops `snmp` scrape errors. ### FAQ #### Does this work with SNMPv3? Yes. Set `version: v3` and provide `user`, `security_level`, `auth_type`, `auth_password`, `privacy_type`, and `privacy_password` as appropriate. Prefer `authPriv` with SHA-256 and AES-256 on production gear. #### How do I monitor many similar devices without repeating YAML? `snmpreceiver` does not have a native templating feature, but the Collector config can be rendered from a template (Jinja, envsubst, Helm). Generate one `snmp/` block per target and share the metric definitions via YAML anchors, or manage the config as code and let the generator emit identical metric blocks. #### Can I receive SNMP traps with this receiver? No. `snmpreceiver` is poll-only, and the Collector has no SNMP-trap receiver (the request to add one was declined). To capture traps, forward them into the Collector as logs via `snmptrapd` + a file or syslog receiver. #### `scalar_oid` or `oid` under `resource_attributes`: which one? `scalar_oid` fetches a single value (must end in `.0`) and stamps every metric from this receiver with it — use it for device-wide attributes like `device.id` from `sysName`. `oid` points to a column and produces per-index resources — use it for things that vary per row like interface names. #### Why is `device.kind` set by a processor and not the receiver? `snmpreceiver` can only attach values it fetches over SNMP. Static labels like `device.kind=network` don't exist on the device, so we add them with a `resource` processor scoped to each device pipeline. This keeps each pipeline self-contained. #### Can I map string values (DisplayString) to numeric metrics? No. A numeric metric needs a numeric SNMP type (Integer, Counter*, Gauge32, TimeTicks); `snmpreceiver` can read a DisplayString only as a resource-attribute value, not as a metric. If a MIB returns a DisplayString like UCD `laLoad` (`"0.21"`), switch to the integer-scaled sibling OID (`laLoadInt`, ×100) and document the scaling in the metric description. #### Does polling add significant load on devices? A 30-second `collection_interval` against a dozen scalar OIDs and a single interface table is negligible for modern network gear. For very large `ifTable` walks on older devices, raise the interval or reduce the column list. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) — Advanced Collector configuration - [Docker Compose Setup](../collector-setup/docker-compose-example.md) — Run the Collector locally - [Docker Monitoring](./docker.md) — Host-level container metrics alongside network gear - [HAProxy Monitoring](./haproxy.md) — Monitor the load balancer in front of those network devices - [IoT & Edge Instrumentation](../iot/index.md) — MQTT, Sparkplug B, OPC-UA, and edge Collector patterns beyond SNMP ### What's Next? - **Create Dashboards**: Start with interface throughput, CPU load, and UPS battery capacity panels. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md) - **Add more devices**: Drop in a switch MIB, a PDU MIB, or a printer MIB — the `snmpreceiver` pattern is the same. The runnable example at [components/snmp-telemetry](https://github.com/base-14/examples/tree/main/components/snmp-telemetry) shows how to add a fourth device. - **Broaden IoT coverage**: SNMP is the first hop into IoT monitoring. See the [IoT & Edge instrumentation](../iot/index.md) guides for [MQTT](../iot/mqtt-trace-propagation.md), [Sparkplug B](../iot/sparkplug.md), and [OPC-UA](../iot/opcua.md) paths when you need protocols SNMP cannot reach. --- ## Solr OpenTelemetry Monitoring - Request Latency, Cache Hit Ratio, and Collector Setup ## Solr Solr exposes Prometheus-format metrics natively at `/solr/admin/metrics?wt=prometheus`, so no exporter sidecar is needed. The OpenTelemetry Collector scrapes that endpoint with the `prometheus` receiver to collect 70+ metrics spanning request throughput and latency, searcher cache hit ratios, JVM heap and GC, indexing backlog, and index and disk capacity from Solr 7.x+. This guide configures the receiver, points it at a Solr node, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Solr | 7.x | 10.0 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - Solr's HTTP port (8983) must be reachable from the host running the Collector. - The `/solr/admin/metrics` endpoint is enabled by default. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the metrics endpoint is reachable and monitoring itself is alive. | | `solr_core_requests_total` | Request throughput per handler and core - the headline KPI for "is Solr answering queries". | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Request latency | `solr_core_requests_times_milliseconds`, `solr_node_requests_times_milliseconds` | Per-handler and node-level request latency (count / sum / quantiles). | | Node throughput | `solr_node_requests_total` | Node-level request count alongside the per-core total. | | Searcher cache | `solr_core_indexsearcher_cache_lookups_total`, `solr_core_indexsearcher_cache_ops_total` | Cache lookups and hits / inserts / evictions by op - the inputs to hit ratio. | | JVM memory | `jvm_memory_used_bytes`, `jvm_memory_limit_bytes` | Heap / non-heap in use against the ceiling; the saturation signal for OOM and GC risk. | | GC | `jvm_gc_duration_seconds` | Stop-the-world pause time; rising pauses hurt query latency. | | Indexing backlog | `solr_core_update_docs_pending_commit` | Docs added but not yet committed - a climbing value means commits are stalled. | | Capacity | `solr_core_index_size_megabytes`, `solr_disk_space_megabytes`, `solr_cores_loaded` | On-disk index size per core, free disk for Solr data, and the count of loaded cores. | Hit ratio is not a single metric - derive it as `solr_core_indexsearcher_cache_ops_total{...hits}` over `solr_core_indexsearcher_cache_lookups_total`. #### Diagnostic - for investigation and tuning Higher cardinality; enable on demand. In production you can drop this tier with `metric_relabel_configs` and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | Searcher caches | `solr_core_indexsearcher_cache_size`, `_cache_ram_used_bytes`, `_cache_warmup_time_milliseconds`, `_live_docs_cache_total`, `_termstats_cache`, `solr_core_field_cache_entries`, `_field_cache_size_bytes` | Per-cache sizing, RAM, and warmup cost when tuning cache configuration. | | Index / searcher detail | `solr_core_indexsearcher_index_docs`, `_index_num_docs`, `_index_version`, `_index_commit_size_megabytes`, `_open_time_milliseconds`, `_open_warmup_time_milliseconds`, `solr_core_segments`, `solr_core_searcher_new_total`, `solr_core_indexwriter_flushes_total`, `solr_core_disk_space_megabytes`, `solr_core_ref_count` | Segment counts, searcher reopens, and index internals during merge or commit investigation. | | Update / transaction log | `solr_core_update_auto_commits_total`, `_commit_ops_total`, `_commit_stats`, `_committed_ops_total`, `_cumulative_ops`, `_log_buffered_ops`, `_log_replay_logs_remaining`, `_log_size_remaining_bytes`, `_log_state`, `_submitted_ops_total` | Commit cadence and tlog replay state when indexing or recovery misbehaves. | | Replication | `solr_core_replication_index_generation`, `_index_size_megabytes`, `_index_version`, `_is_enabled`, `_is_follower`, `_is_leader` | Leader / follower role and replication progress (read their not-configured defaults on a standalone node). | | Executors / thread pools | `solr_core_executor_thread_pool_size`, `_executor_thread_pool_tasks`, `solr_node_executor_task_times_milliseconds`, `_executor_tasks_running`, `_executor_tasks_total`, `_executor_thread_pool_size`, `_executor_thread_pool_tasks` | Thread-pool depth and task timing under concurrency. | | JVM detail | `jvm_buffer_*`, `jvm_class_*`, `jvm_cpu_*`, `jvm_memory_allocation_bytes`, `_memory_committed_bytes`, `_memory_init_bytes`, `_memory_used_after_last_gc_bytes`, `jvm_network_*`, `jvm_system_cpu_utilization_ratio`, `jvm_thread_count` | The full JVM breakdown - buffers, class loading, CPU, allocation, and threads - for deep JVM tuning. | Full metric reference: run `curl -s 'http://localhost:8983/solr/admin/metrics?wt=prometheus'` against your Solr instance, or see the [Solr metrics reporting](https://solr.apache.org/guide/solr/latest/deployment-guide/metrics-reporting.html) documentation. SolrCloud-only series (overseer, ZooKeeper, shard / replica state) do not appear on a standalone node, and the replication series read their not-configured defaults until replication is set up. ### Key Alerts to Configure Threshold guidance for the most useful Operational-tier series. Tune to your workload; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `solr_core_requests_times_milliseconds` (p95) | Rising vs baseline | Sustained regression | Query slowdown; check cache hit ratio, GC, and slow queries. | | `cache_ops_total{...hits}` / `cache_lookups_total` | Hit ratio falling | Sharply low | Cache too small or churning; tune cache sizes / autowarm. | | `jvm_memory_used_bytes` / `jvm_memory_limit_bytes` | > 80% of limit | Near limit | OOM and long-GC risk; raise heap or reduce cache / field load. | | `rate(jvm_gc_duration_seconds)` | Rising | Sustained high | Stop-the-world pauses hurting latency; tune heap / GC. | | `solr_core_update_docs_pending_commit` | Climbing without commit | Not draining | Commits stalled; check commit settings and indexing throughput. | | `solr_disk_space_megabytes` (free) | Trending down | < 10% of volume | Plan storage before the volume fills as `index_size_megabytes` grows. | ### Access Setup Solr serves Prometheus-format metrics natively - there is no exporter to run. The metrics live at `/solr/admin/metrics` and the `wt=prometheus` query parameter selects the Prometheus rendering. Verify the endpoint is reachable: ```bash showLineNumbers title="Verify access" # Check Solr status curl -s http://localhost:8983/solr/admin/info/system | head -20 # List cores curl -s http://localhost:8983/solr/admin/cores # Verify Prometheus metrics endpoint curl -s 'http://localhost:8983/solr/admin/metrics?wt=prometheus' | head -20 ``` No authentication is required by default. Clusters with Basic Authentication enabled need credentials on the scrape - see [Authentication](#authentication) below. The Collector's `prometheus` receiver must override the default `/metrics` path with `metrics_path: /solr/admin/metrics` and pass `params: { wt: [prometheus] }`. Both are set in the [Configuration](#configuration) section. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: solr scrape_interval: 30s metrics_path: /solr/admin/metrics # Solr's endpoint, not the default /metrics params: wt: [prometheus] # Select Prometheus rendering static_configs: - targets: - ${env:SOLR_HOST}:8983 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic tier with a `metric_relabel_configs` block on the scrape config while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" SOLR_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Authentication For Solr clusters with Basic Authentication enabled, add `basic_auth` to the scrape config: ```yaml showLineNumbers title="config/otel-collector.yaml (auth)" receivers: prometheus: config: scrape_configs: - job_name: solr metrics_path: /solr/admin/metrics params: wt: [prometheus] basic_auth: username: ${env:SOLR_USERNAME} password: ${env:SOLR_PASSWORD} static_configs: - targets: - ${env:SOLR_HOST}:8983 ``` #### Filtering Metrics To collect only specific metric groups, use Solr's `group` parameter: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" receivers: prometheus: config: scrape_configs: - job_name: solr metrics_path: /solr/admin/metrics params: wt: [prometheus] group: [jvm, node, core] # Limit to selected metric groups static_configs: - targets: - ${env:SOLR_HOST}:8983 ``` Available groups: `jvm`, `jetty`, `node`, `core`, `overseer`. ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Solr metrics (grep the metric prefix) docker logs otel-collector 2>&1 | grep -i "solr_core" # Confirm the endpoint is serving Prometheus-format metrics curl -s 'http://localhost:8983/solr/admin/metrics?wt=prometheus' \ | grep solr_core_requests_total # Generate request and index traffic so the series move curl -s 'http://localhost:8983/solr/demo/select?q=*:*' > /dev/null ``` ### Troubleshooting #### Connection refused on port 8983 **Cause**: The Collector cannot reach Solr at the configured address. **Fix**: 1. Verify Solr is running: `docker ps | grep solr` or `systemctl status solr`. 2. Confirm Solr is listening: `curl http://localhost:8983/solr/`. 3. Check firewall rules if the Collector runs on a separate host. #### Metrics endpoint returns JSON instead of Prometheus format **Cause**: The `wt=prometheus` parameter is missing from the scrape config, so Solr falls back to JSON, which the `prometheus` receiver cannot parse. **Fix**: 1. Ensure `params: { wt: [prometheus] }` is set on the scrape job. 2. Confirm `metrics_path` is `/solr/admin/metrics`, not the default `/metrics`. 3. Verify with `curl 'http://localhost:8983/solr/admin/metrics?wt=prometheus'`. #### Queries are slow or latency is climbing **Cause**: A low cache hit ratio, JVM heap pressure, or GC pauses. **Look at**: the searcher-cache Diagnostic series - `solr_core_indexsearcher_cache_size`, `_cache_ram_used_bytes`, and `_cache_warmup_time_milliseconds` - alongside `jvm_memory_used_bytes` against `jvm_memory_limit_bytes` and the `jvm_gc_duration_seconds` rate. A hit ratio falling while warmup time climbs points at undersized or churning caches; heap near the limit with rising GC points at memory pressure. **Fix**: 1. Tune cache sizes and autowarm counts if the hit ratio is low. 2. Raise heap or reduce cache / field load if `jvm_memory_used_bytes` sits near `jvm_memory_limit_bytes`. #### Indexing backlog grows and commits stall **Cause**: Commits are not keeping up with indexing, or the transaction log is replaying. **Look at**: the update / tlog Diagnostic series - `solr_core_update_commit_ops_total`, `solr_core_update_auto_commits_total`, and `solr_core_update_log_replay_logs_remaining` - against the Operational `solr_core_update_docs_pending_commit`. A pending count that climbs while commit ops stay flat means commits are stalled; non-zero replay logs means the node is still recovering its tlog. **Fix**: 1. Review autoCommit / autoSoftCommit settings and commit cadence. 2. Throttle indexing throughput or add capacity if commits cannot keep up. #### Core-level metrics missing **Cause**: Core metrics (`solr_core_*`) only appear when at least one core is loaded. **Fix**: 1. Create a core: `curl 'http://localhost:8983/solr/admin/cores?action=CREATE&name=demo&configSet=_default'`. 2. Verify cores exist: `curl http://localhost:8983/solr/admin/cores`. 3. Check `solr_cores_loaded` reflects the expected count. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Solr running in Kubernetes? Yes. Set `targets` to the Solr pod or service DNS (e.g., `solr-0.solr.default.svc.cluster.local:8983`) and keep the `metrics_path` and `params` overrides. The Collector can run as a sidecar or a DaemonSet. #### How do I monitor a SolrCloud cluster? Add every node endpoint to the scrape config. Each node is scraped independently and identified by its `instance` label: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-node)" receivers: prometheus: config: scrape_configs: - job_name: solr metrics_path: /solr/admin/metrics params: wt: [prometheus] static_configs: - targets: - solr-1:8983 - solr-2:8983 - solr-3:8983 ``` #### What is the difference between `node` and `core` metrics? Node metrics (`solr_node_*`) cover the whole instance - aggregate request counts, latency, and executor pools. Core metrics (`solr_core_*`) are per-core and include request throughput, searcher caches, index size, and update-handler stats. Core metrics only appear once a core is loaded. #### Why are `overseer` and replication metrics empty? Overseer metrics only appear in SolrCloud mode on the elected overseer node, so a standalone instance does not emit them. The `solr_core_replication_*` series read their not-configured defaults (for example `solr_core_replication_is_enabled`) until replication is actually set up. #### Why is the cache hit ratio not a single metric? Solr exposes the inputs, not the ratio. Derive it as `solr_core_indexsearcher_cache_ops_total{...hits}` over `solr_core_indexsearcher_cache_lookups_total` and chart or alert on the quotient. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Solr metrics. - [Elasticsearch Monitoring](./elasticsearch.md) - Another search engine you may run alongside Solr. - [Redis Monitoring](./redis.md) - A common caching layer in front of search. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Elasticsearch](./elasticsearch.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with `metric_relabel_configs` to control volume; keep it available for incident investigation. --- ## SQL Server OpenTelemetry Monitoring - Batch Throughput, Locks, and Buffer Cache Metrics ## SQL Server The OpenTelemetry Collector's `sqlserverreceiver` connects to Microsoft SQL Server 2017+ over TDS and collects 34 metrics on Linux, including batch request rate, buffer cache hit ratio, page life expectancy, deadlock rate, lock waits, blocked processes, and tempdb space. It reads the server's dynamic management views (DMVs) through a least-privilege monitoring login, so no agent or exporter sits on the database host. This guide creates that login, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | SQL Server | 2017 | 2022+ | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - SQL Server must be reachable on TCP 1433 from the host running the Collector. - A login with permission to create logins (typically `sa` or another sysadmin) is needed once, to bootstrap the read-only monitoring login. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). The `sqlserverreceiver` has two collection paths: the DMV path runs on any platform, and a Windows performance-counter path adds extra metrics only on Windows hosts. 13 of the receiver's default metrics come from Windows perfcounters and emit nothing on a Linux container by design. The tiers below reflect the DMV-backed set available everywhere; a Windows host adds page-checkpoint and transaction-log perfcounter rates on top. ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `sqlserver.user.connection.count` | Users connected to the server - reachability and connection load. | | `sqlserver.batch.request.rate` | Batch requests per second - the headline workload throughput. | | `sqlserver.page.life_expectancy` | Seconds a page stays in the buffer pool; a first-order memory-health signal. | | `sqlserver.page.buffer_cache.hit_ratio` | Pages served from the buffer pool without a disk read - working-set health. | For SQL Server, buffer-pool health is a first-order indicator of server health, so the two memory-health signals sit alongside throughput in Core. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `sqlserver.database.execution.errors` | Execution errors - failing queries or app errors. | | `sqlserver.deadlock.rate` | Deadlocks detected; lock-ordering contention. | | `sqlserver.processes.blocked` | Processes currently blocked - head-of-line blocking. | | `sqlserver.lock.wait.rate` | Lock requests that resulted in a wait; growing contention. | | `sqlserver.lock.timeout.rate` | Lock timeouts - sessions abandoning lock requests. | | `sqlserver.memory.grants.pending.count` | Queries waiting for a memory grant; memory-grant pressure. | | `sqlserver.transaction.delay` | Time consumed in transaction delays - commit / HADR latency. | | `sqlserver.batch.sql_recompilation.rate` | SQL recompilations - plan-cache churn. | | `sqlserver.database.tempdb.space` | Free space in tempdb; fill risks a server-wide outage. | | `sqlserver.database.full_scan.rate` | Unrestricted full table/index scans - a missing-index signal. | #### Diagnostic - for investigation and tuning Higher cardinality or static inventory; enable on demand. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | Lock and wait detail | `sqlserver.lock.wait.count`, `sqlserver.os.wait.duration` (per wait type) | Attribute contention to a wait type during an incident. | | Compilation / index internals | `sqlserver.batch.sql_compilation.rate`, `sqlserver.index.search.rate`, `sqlserver.page.lookup.rate` | Context for recompilation storms and scan-heavy plans. | | Buffer-pool detail | `sqlserver.page.buffer_cache.free_list.stalls.rate` | Confirm buffer-pool pressure behind a falling hit ratio. | | TempDB internals | `sqlserver.database.tempdb.version_store.size` | Long-running transactions bloating the version store. | | Activity rates | `sqlserver.database.backup_or_restore.rate`, `sqlserver.login.rate`, `sqlserver.logout.rate` | Backup windows and connection churn. | | Inventory and host | `sqlserver.memory.usage`, `sqlserver.computer.uptime`, `sqlserver.cpu.count`, `sqlserver.database.count`, `sqlserver.table.count` | Restart detection and static capacity context. | | HADR / mirroring / Resource Governor | `sqlserver.replica.data.rate`, `sqlserver.transaction.mirror_write.rate`, `sqlserver.resource_pool.disk.operations`, `sqlserver.resource_pool.disk.throttled.read.rate`, `sqlserver.resource_pool.disk.throttled.write.rate` | Only carry signal when availability groups, mirroring, or Resource Governor are configured. | The per-database file-IO metrics - `sqlserver.database.io`, `sqlserver.database.latency`, and `sqlserver.database.operations` - are worth enabling but stay silent until the underlying per-database file stats are populated by activity. Leave them enabled so file-level read/write bytes, latency, and operations surface once a database sees load. Full receiver reference: [OTel SQL Server Receiver][sqlserver-receiver-readme]. [sqlserver-receiver-readme]: https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/sqlserverreceiver ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Threshold | Why it matters | |---|---|---| | `rate(sqlserver.database.execution.errors)` | > 0 sustained | Failing queries or app errors; inspect the SQL error log. | | `rate(sqlserver.deadlock.rate)` | > 0 sustained | Lock-ordering contention; review transaction patterns. | | `sqlserver.processes.blocked` | > 0 sustained | A head blocker is stalling sessions; find and resolve the blocking chain. | | `rate(sqlserver.lock.wait.rate)` | Climbing vs baseline | Growing contention; review hot tables and transaction scope. | | `rate(sqlserver.lock.timeout.rate)` | > 0 rising | Sessions abandoning lock requests; investigate blocking. | | `sqlserver.page.life_expectancy` | Dropping vs baseline (RAM-dependent) | Buffer-pool memory pressure; check memory grants and workload. | | `sqlserver.page.buffer_cache.hit_ratio` | Falling vs baseline | Working set exceeds the buffer pool; add memory or tune queries. | | `sqlserver.memory.grants.pending.count` | > 0 sustained | Queries starved for memory grants; reduce concurrency or query memory. | | `rate(sqlserver.transaction.delay)` | Rising vs baseline | Commit latency or HADR sync pressure; check IO and replica health. | | `rate(sqlserver.batch.sql_recompilation.rate)` | High relative to `batch.request.rate` | Plan-cache churn; review parameterization and schema changes. | | `sqlserver.database.tempdb.space` (free) | Trending toward 0 | TempDB exhaustion risks a server-wide outage; add tempdb files or space. | | `rate(sqlserver.database.full_scan.rate)` | Climbing vs baseline | Missing index or plan regression; review query plans. | Page life expectancy has no universal absolute - it scales with the RAM allocated to the buffer pool - so alert on a drop relative to the instance's own baseline rather than a fixed number. ### Access Setup Create a read-only login the collector connects as. The grants differ between SQL Server 2022+ (which introduced the more granular `VIEW SERVER PERFORMANCE STATE`) and earlier versions. #### SQL Server 2022 and later ```sql showLineNumbers title="bootstrap.sql" USE [master]; GO CREATE LOGIN [otel_monitor] WITH PASSWORD = N'', CHECK_POLICY = ON; GO GRANT VIEW SERVER PERFORMANCE STATE TO [otel_monitor]; GRANT VIEW ANY DATABASE TO [otel_monitor]; GO ``` #### SQL Server 2017 - 2019 ```sql showLineNumbers title="bootstrap-legacy.sql" USE [master]; GO CREATE LOGIN [otel_monitor] WITH PASSWORD = N'', CHECK_POLICY = ON; GO GRANT VIEW SERVER STATE TO [otel_monitor]; GRANT VIEW ANY DATABASE TO [otel_monitor]; GO ``` `VIEW SERVER PERFORMANCE STATE` (or `VIEW SERVER STATE` on older versions) gives the receiver access to the dynamic management views it queries, including the per-database file IO and latency stats. `VIEW ANY DATABASE` lets it enumerate the databases to scrape; the receiver also accepts `CREATE DATABASE` or `ALTER ANY DATABASE` in its place. No write permissions are needed. Test the credentials before configuring the collector: ```bash showLineNumbers title="Verify access" sqlcmd -S ,1433 -U otel_monitor -P '' \ -C -Q "SELECT @@VERSION;" ``` The `-C` flag trusts the server certificate. SQL Server enables encryption by default; production deployments should ship a real certificate the collector can validate against. ### Configuration The receiver enables 30 optional metrics on top of its DMV-backed defaults. None of the 30 are Windows-only, though three per-database file-IO metrics among them stay silent until a database sees activity. The 13 Windows-only default metrics need no toggle and silently skip on Linux. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: sqlserver: collection_interval: 10s username: ${env:SQLSERVER_USER} password: ${env:SQLSERVER_PASSWORD} server: # Change to your SQL Server address port: 1433 metrics: sqlserver.computer.uptime: enabled: true sqlserver.cpu.count: enabled: true sqlserver.database.backup_or_restore.rate: enabled: true sqlserver.database.count: enabled: true sqlserver.database.execution.errors: enabled: true sqlserver.database.full_scan.rate: enabled: true sqlserver.database.io: enabled: true sqlserver.database.latency: enabled: true sqlserver.database.operations: enabled: true sqlserver.database.tempdb.space: enabled: true sqlserver.database.tempdb.version_store.size: enabled: true sqlserver.deadlock.rate: enabled: true sqlserver.index.search.rate: enabled: true sqlserver.lock.timeout.rate: enabled: true sqlserver.lock.wait.count: enabled: true sqlserver.login.rate: enabled: true sqlserver.logout.rate: enabled: true sqlserver.memory.grants.pending.count: enabled: true sqlserver.memory.usage: enabled: true sqlserver.os.wait.duration: enabled: true sqlserver.page.buffer_cache.free_list.stalls.rate: enabled: true sqlserver.page.lookup.rate: enabled: true sqlserver.processes.blocked: enabled: true sqlserver.replica.data.rate: enabled: true sqlserver.resource_pool.disk.operations: enabled: true sqlserver.resource_pool.disk.throttled.read.rate: enabled: true sqlserver.resource_pool.disk.throttled.write.rate: enabled: true sqlserver.table.count: enabled: true sqlserver.transaction.delay: enabled: true sqlserver.transaction.mirror_write.rate: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [sqlserver] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic-tier metrics with a `filter` processor while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" SQLSERVER_USER=otel_monitor SQLSERVER_PASSWORD= ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Confirm the monitoring login resolves from where the collector runs: ```bash showLineNumbers sqlcmd -S ,1433 -U otel_monitor -P "$SQLSERVER_PASSWORD" \ -C -Q "SELECT name FROM sys.server_principals WHERE name = N'otel_monitor';" ``` Then start the collector and confirm metrics appear within 30 seconds: ```bash showLineNumbers docker logs otel-collector 2>&1 | grep -oE "Name: sqlserver\.[a-z_.]+" \ | sort -u | wc -l ``` Expect 30+ unique metric names on Linux. A few per-database metrics like `sqlserver.database.io` only appear once a database sees activity, so drive some queries against the server if those rows are missing. ### Troubleshooting #### Connection refused or timeout **Cause**: The collector cannot reach SQL Server at the configured endpoint, or SQL Server is still warming up. **Fix**: 1. Verify SQL Server is listening on TCP: `ss -tlnp | grep 1433` on the host. 2. SQL Server containers on Apple Silicon run under x86 emulation, so the first cold start takes 30-60 seconds. Use a healthcheck that tolerates this and gate the collector on `depends_on.condition: service_healthy`. 3. Confirm SQL Server's TCP/IP protocol is enabled - it is by default in containers, but disabled on a fresh Windows install. #### Login failed for user 'otel_monitor' **Cause**: Password mismatch, missing grants, or `CHECK_POLICY = ON` rejected the password. **Fix**: 1. Test credentials directly from a shell that can reach the instance: `sqlcmd -S ,1433 -U otel_monitor -P '' -C`. 2. Re-run the bootstrap SQL; wrap `CREATE LOGIN` in an `IF NOT EXISTS` check to make it idempotent. 3. Confirm the grants landed: `SELECT * FROM sys.server_permissions` filtered on the login's principal. #### Contention is rising but the cause is unclear **Cause**: Lock waits, blocking, or deadlocks are climbing and you need to attribute them to a wait type or a blocking chain. **Look at**: the Diagnostic `sqlserver.os.wait.duration` series (per wait type) to see where time is going, and `sqlserver.lock.wait.count` for cumulative lock-wait volume. Pair these with the Operational `sqlserver.processes.blocked` and `sqlserver.deadlock.rate`. **Fix**: 1. If a single wait type dominates, target it - `PAGEIOLATCH_*` points at storage, `LCK_*` at lock contention, `RESOURCE_SEMAPHORE` at memory grants. 2. If `processes.blocked` is non-zero, find the head blocker and resolve the blocking chain. #### Falling page life expectancy or buffer cache hit ratio **Cause**: The working set exceeds the buffer pool, so pages are evicted and re-read from disk. **Look at**: the Diagnostic `sqlserver.page.buffer_cache.free_list.stalls.rate` - a non-zero free-list stall rate confirms buffer-pool pressure behind the falling Core ratios. Cross-check `sqlserver.memory.grants.pending.count`. **Fix**: 1. Add memory to the instance or raise `max server memory` if it is capped below available RAM. 2. Tune the heaviest queries to read fewer pages, and review `sqlserver.database.full_scan.rate` for missing indexes. #### Many default metrics are not appearing **Cause**: The `sqlserverreceiver` has two collection paths. The DMV path runs everywhere; the performance-counter path is Windows-only. **Fix**: 1. On Linux containers and managed Linux SQL Server, only DMV-backed metrics emit. The 13 Windows-perfcounter defaults skip silently by design. 2. To get the full set, run the collector on a Windows host alongside a Windows SQL Server instance, with `computer_name` and `instance_name` set per the receiver README. #### No metrics appearing in Scout **Cause**: Metrics are scraped but not exported, or exported with bad auth. **Fix**: 1. Add a `debug` exporter to the metrics pipeline temporarily and confirm metrics print to the collector's stdout - this isolates the receiver from the exporter. 2. Check the collector logs for `Exporting failed` errors with HTTP 401 or 403, which point at the credentials for `otlphttp/b14`. 3. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. ### FAQ #### Does this work with SQL Server running in Kubernetes? Yes. Set the receiver `server` to the SQL Server service DNS (e.g., `sqlserver.default.svc.cluster.local`) on port 1433 and inject the monitoring credentials via a Kubernetes secret. The Collector can run as a sidecar or a Deployment. #### What permissions does the SQL Server monitoring login need? On SQL Server 2022+: `VIEW SERVER PERFORMANCE STATE` plus `VIEW ANY DATABASE`. On SQL Server 2017-2019: `VIEW SERVER STATE` plus `VIEW ANY DATABASE`. No write permissions are required. #### How do I monitor multiple SQL Server instances with OpenTelemetry? Add multiple receiver blocks with distinct names, then include both in the pipeline: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: sqlserver/primary: server: primary port: 1433 username: ${env:SQLSERVER_USER} password: ${env:SQLSERVER_PASSWORD} sqlserver/replica: server: replica port: 1433 username: ${env:SQLSERVER_USER} password: ${env:SQLSERVER_PASSWORD} service: pipelines: metrics: receivers: [sqlserver/primary, sqlserver/replica] ``` #### Why is a default metric like `sqlserver.transaction_log.usage` missing? It is one of the 13 Windows-perfcounter metrics the receiver silently skips on Linux. On a Linux instance you can capture log usage indirectly with the `sqlquery` receiver, or run the collector on a Windows host for the full set. #### Does this work with Azure SQL Database or Azure SQL Managed Instance? This guide targets self-hosted SQL Server. Azure SQL Database and Azure SQL Managed Instance expose metrics through Azure Monitor; collect them with the `azuremonitorreceiver` instead. See the [Azure SQL Database guide](../infra/azure/sql-database.md) for the managed path. #### Why are some default SQL Server metrics missing on a Linux container? 13 of the `sqlserverreceiver` default metrics read Windows performance counters and emit nothing on a Linux container by design. On Linux you get the DMV-backed set; running the collector against a Windows SQL Server host adds the Windows-only perfcounter metrics. ### Related Guides - [Azure SQL Database](../infra/azure/sql-database.md) - The managed PaaS (Azure SQL Database / Managed Instance), collected via the `azure_monitor` receiver instead of `sqlserverreceiver`. - [PostgreSQL Monitoring](./postgres.md) - Adjacent relational database. - [MySQL Monitoring](./mysql.md) - Adjacent relational database. - [.NET Aspire](../apps/auto-instrumentation/dotnet-aspire.md) - App-side .NET telemetry to pair with the database metrics. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on SQL Server metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [MySQL](./mysql.md), and [Redis](./redis.md). - **Instrument the App**: Pair the database telemetry with application traces from [.NET Aspire](../apps/auto-instrumentation/dotnet-aspire.md) for end-to-end visibility. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Temporal OpenTelemetry Monitoring - Persistence Latency, Task Queues, and Collector Setup ## Temporal Temporal exposes Prometheus text on `:8000` when the `PROMETHEUS_ENDPOINT` environment variable is set. The OpenTelemetry Collector's `prometheus` receiver scrapes that endpoint, collecting 150+ metrics from Temporal 1.20+ across frontend service requests and latency, persistence (database) latency, task-queue backlog, task processing, history shards, the mutable-state cache, and the Go runtime. This guide configures the receiver and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | -------------- | | Temporal Server | 1.20 | 1.24+ (1.27.0) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Temporal Server requires PostgreSQL as its persistence backend - the `auto-setup` Docker image does not support SQLite. - Temporal must be started with `PROMETHEUS_ENDPOINT=0.0.0.0:8000` to expose metrics; the endpoint is not enabled by default. - The metrics port (`8000`) must be reachable from the host running the Collector. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things shape this surface, and they matter for every tier below: - **`up` is the liveness signal here.** Temporal has a real `up` series: the `prometheus` receiver emits `up` = 1 when `/metrics` responds. `restarts` counts process restarts and `build_information` carries the version labels. - **One endpoint, four roles.** In the single-binary (`auto-setup`) distribution the frontend, history, matching, and worker roles share one `/metrics`, and metrics carry an `operation` label that names the RPC or task type. A production deployment runs each role as a separate process with its own `:8000` endpoint - the metric names are identical, so the same scrape config applies per role (see the four-job example in [Configuration](#configuration)). - **Persistence is a primary signal to watch.** Temporal depends heavily on its persistence store, so `persistence_latency`, `persistence_requests` (keyed by `operation`), and `persistence_error_with_type` are a leading indicator of store and connection health - a slow store backs up task processing. - **Task-queue backlog is the worker-health signal.** `approximate_backlog_count` and `approximate_backlog_age_seconds` (per task queue) say whether workers are keeping up; a rising backlog means tasks are produced faster than they are polled. - **Latency metrics are histograms.** `service_latency`, `persistence_latency`, the `task_latency*` family, `cache_latency`, and the `*_lock_latency` family expand into `_bucket` / `_sum` / `_count` in Prometheus form; the receiver represents each as one OTel histogram. - **Two naming domains.** Unprefixed names (`service_*`, `persistence_*`, `task_*`, `cache_*`, `history_*`, and the shard / queue families) are the **server** metrics. The `temporal_*` names (`temporal_request*`, `temporal_long_request*`, `temporal_worker_*`, `temporal_num_pollers`) are the **SDK client** metrics from Temporal's internal system worker - the same names a user-written worker emits. - **`tally_internal_*` is the Tally metrics library's own bookkeeping** (scope and cardinality counts), and `memory_*` / `num_goroutines` / `gomaxprocs` are the Go runtime - filter these with a keep rule if the runtime is covered elsewhere. #### Core - is it up, serving RPCs, and is the database healthy | Metric | What it tells you | |---|---| | `up` | Scrape liveness - 1 = the Temporal metrics endpoint responded. The liveness signal on this surface. | | `service_requests` | Frontend RPCs handled, keyed by `operation` - headline request throughput. | | `service_latency` | Frontend RPC latency by `operation` - the API SLO (histogram). | | `service_error_with_type` | Frontend RPC errors by `operation` and error type. | | `persistence_requests` | Persistence (database) operations by `operation` - backend throughput. | | `persistence_latency` | Persistence operation latency - a leading indicator of store and connection health; a slow store backs up task processing (histogram). | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Frontend saturation | `service_pending_requests`, `service_latency_nouserlatency`, `service_authorization_latency` | RPCs queued but not yet handled; server-side latency with user-blocked time excluded; authorization-check latency. | | Persistence health | `persistence_error_with_type`, `persistence_shard_rps`, `persistence_session_refresh_attempts` | Database errors by type; per-shard request rate (hot-spotting); session-refresh attempts (connection churn). | | Visibility store | `visibility_persistence_requests`, `visibility_persistence_latency` | Visibility-store request rate and latency - drives the list / search API. | | Inter-service calls | `client_requests`, `client_latency`, `client_errors`, `client_redirection_errors` | History / matching client call rate, latency, errors, and cross-node redirection failures. | | Task processing | `task_requests`, `task_latency`, `task_latency_processing`, `task_latency_queue`, `task_attempt`, `task_lag_per_tl`, `pending_tasks`, `queue_actions` | Task operations and end-to-end latency, broken into processing / queue-wait phases; retries; per-task-list lag; pending tasks. | | Task-queue backlog | `approximate_backlog_count`, `approximate_backlog_age_seconds`, `poll_latency`, `poll_timeouts` | Headline "are workers keeping up" backlog and oldest-task age; poll latency; long-poll timeouts. | | Shards | `acquire_shards_latency`, `acquire_shards_count`, `get_engine_for_shard_latency`, `sharditem_acquisition_latency`, `numshards_gauge` | Time and count to acquire history shards; engine / item acquisition latency; shards owned by this host. | | Cluster health | `membership_changed_count`, `lock_latency`, `semaphore_latency` | Cluster membership churn (node flapping); internal lock / semaphore wait time (contention). | | Mutable-state cache | `cache_requests`, `cache_latency`, `cache_miss` | History mutable-state cache request rate, latency, and misses - a miss forces a persistence read. | | Workflow history | `history_size`, `history_count`, `state_transition_count` | Workflow history size in bytes and event count (large histories slow replay); workflow state transitions. | | Replication | `replication_tasks_lag` | Multi-cluster replication lag - how far a replica is behind. | | SDK worker | `temporal_worker_task_slots_available`, `temporal_worker_task_slots_used`, `temporal_num_pollers` | SDK worker task-slot capacity / usage and pollers running - a worker pinned at full slots is the bottleneck. | | Runtime | `host_rps_limit`, `memory_heapinuse`, `memory_allocated`, `memory_gc_pause_ms`, `num_goroutines` | Per-host RPS limit; Go heap in use / allocated; GC pause time; goroutine count (a runaway count signals a leak). | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Representative metrics | When you reach for it | |---|---|---| | Mutable-state component sizes | `mutable_state_size`, `execution_info_size`, `execution_state_size`, `memo_size`, `event_blob_size` | Drill into large / slow workflows by component size. | | Per-workflow counts and sizes | `activity_info_count` / `_size`, `timer_info_*`, `child_info_*`, `signal_info_*`, `buffered_events_*` | Pending activity, timer, child-workflow, signal, and buffered-event counts and sizes. Advance only as workflows accumulate those components. | | Cumulative workflow counts | `total_activity_count`, `total_child_execution_count`, `total_signal_count`, `total_user_timer_count` | Cumulative per-workflow activity, child, signal, and timer counts. | | Deadlock-detector locks | `dd_shard_lock_latency`, `dd_namespace_registry_lock_latency`, `dd_shard_io_semaphore_latency` (and the rest of the `dd_*` family) | Lock / IO-semaphore wait times on internal structures. | | Task-queue internals | `loaded_task_queue_count`, `loaded_task_queue_partition_count`, `forwarded`, `forwarded_per_tl` | Loaded / force-loaded queue and partition counts; tasks forwarded between matching partitions. | | History task-processor | `task_count`, `task_batch_complete_counter`, `ack_level_update`, `queue_reader_count`, `queue_slice_count` | Batch, ack-level, and queue-reader internals behind a processing stall. | | Cache sizing | `cache_size`, `cache_usage`, `cache_pinned_usage`, `cache_ttl`, `history_workflow_execution_cache_lock_hold_duration` | Mutable-state cache size, usage, pinned usage, TTL, and lock-hold time. | | Shard-info internals | `sharditem_created_count`, `time_between_shardinfo_update`, `new_timer_notifications`, `workflow_context_cleared` | Shard-info update cadence, timer notifications, and history-engine internals. | | Replication cleanup | `replication_task_cleanup_count`, `lease_requests` | Replication-task cleanup and shard-lease request counts (multi-cluster only). | | SDK client detail | `temporal_request`, `temporal_request_latency`, `temporal_long_request`, `temporal_poller_start`, `temporal_activity_poll_no_task` | SDK client request / long-poll count, attempts, and latency; poller and empty-poll counters. | | Library and runtime | `tally_internal_counter_cardinality`, `memory_heap`, `memory_num_gc`, `gomaxprocs` | Tally's own cardinality / scope bookkeeping and additional Go-runtime heap / GC / scheduler detail. | | Version and scrape meta | `build_information`, `build_age`, `version_check_latency`, `action`, `restarts`, `scrape_duration_seconds`, `scrape_samples_scraped` | Build labels and age, version-check result and timing, billable action count, process restarts, and receiver-side scrape meta. | Full metric list: run `curl -s http://localhost:8000/metrics` against your Temporal instance. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. `up == 0` and the error counters read as states; the rest compare against your own baseline, since latencies and backlog are workload-dependent. These are starting points - tune them to your workload. | Alert | Condition | Why it matters | |---|---|---| | Temporal unreachable | `up == 0` for > 1m | The metrics endpoint stopped responding - check the server process and port 8000. | | Persistence latency high | `persistence_latency` p99 rising vs baseline | The store is slow - check the database, connections, and shard RPS. | | Persistence errors | `rate(persistence_error_with_type)` > 0 | Database operations are failing - check connectivity and the backing store. | | Frontend errors rising | `rate(service_error_with_type)` > 0 vs baseline | RPCs are failing - inspect the error-type label and correlate with persistence. | | Frontend latency high | `service_latency` p99 rising vs baseline | RPCs are slow - compare with `service_latency_nouserlatency` to separate server from downstream. | | Task-queue backlog growing | `approximate_backlog_count` rising, or `approximate_backlog_age_seconds` climbing | Workers are not keeping up - scale workers or investigate slow task execution. | | Task processing slow | `task_latency` p99 rising, or `task_latency_queue` rising | Tasks are slow or queued - localize via the task-latency phase breakdown. | | Shard acquisition slow | `acquire_shards_latency` p99 rising | History shards are slow to load - parts of the cluster may be unavailable; check the history service and store. | | Membership churn | `rate(membership_changed_count)` > 0 sustained | Nodes are joining / leaving repeatedly - investigate node health and the membership backend. | | Cache miss rate high | `cache_miss / cache_requests` rising vs baseline | The mutable-state cache is thrashing - more reads hit persistence; check cache sizing and load. | | Replication lag | `replication_tasks_lag` rising vs baseline | A replica cluster is falling behind - check cross-cluster connectivity and the replication queue. | ### Access Setup Temporal does not expose Prometheus metrics by default. Enable the endpoint by setting `PROMETHEUS_ENDPOINT` on the server, and provide a PostgreSQL persistence backend (the `auto-setup` image does not support SQLite). ```bash showLineNumbers title="Enable the metrics endpoint" # Set on the Temporal server (Docker / Docker Compose env) PROMETHEUS_ENDPOINT=0.0.0.0:8000 ``` Bind to `0.0.0.0`, not `127.0.0.1`, so the Collector can reach the endpoint from another container or host. Make sure port `8000` is reachable from the host running the Collector (in Docker, map or expose it on the Temporal service). Verify the endpoint is serving metrics: ```bash showLineNumbers title="Verify access" curl -s http://localhost:8000/metrics | head -20 ``` For Kubernetes, set `PROMETHEUS_ENDPOINT` on each Temporal pod's container env and expose port `8000` on the service. ### Configuration The `prometheus` receiver scrapes Temporal's `/metrics` on `:8000`. A single-binary (`auto-setup`) deployment serves all four roles on one endpoint, so one scrape job covers it: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: temporal scrape_interval: 10s static_configs: - targets: - ${env:TEMPORAL_HOST}:8000 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The server must be started with `PROMETHEUS_ENDPOINT=0.0.0.0:8000` for this scrape to return anything (see [Access Setup](#access-setup)). #### Environment Variables ```bash showLineNumbers title=".env" TEMPORAL_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Production: one scrape job per role A production deployment runs the frontend, history, matching, and worker roles as separate processes, each exposing the same metric names on its own `:8000`. Add one scrape job per role: ```yaml showLineNumbers title="config/otel-collector.yaml (per-role)" receivers: prometheus: config: scrape_configs: - job_name: temporal-frontend scrape_interval: 10s static_configs: - targets: [temporal-frontend:8000] - job_name: temporal-history scrape_interval: 10s static_configs: - targets: [temporal-history:8000] - job_name: temporal-matching scrape_interval: 10s static_configs: - targets: [temporal-matching:8000] - job_name: temporal-worker scrape_interval: 10s static_configs: - targets: [temporal-worker:8000] ``` #### Scoping collection to the product metrics Temporal exposes 150+ metrics, including the Go-runtime `memory_*` / `num_goroutines` and the `tally_internal_*` library-bookkeeping families. To keep collection focused on the Temporal product metrics, scope it with a keep rule: ```yaml showLineNumbers title="config/otel-collector.yaml (keep filter)" receivers: prometheus: config: scrape_configs: - job_name: temporal scrape_interval: 10s static_configs: - targets: - ${env:TEMPORAL_HOST}:8000 metric_relabel_configs: - source_labels: [__name__] regex: "service_.*|persistence_.*|task_.*|approximate_backlog_.*|cache_.*|history_.*|.*shard.*|membership_.*|replication_.*|up" action: keep ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Temporal metrics docker logs otel-collector 2>&1 | grep -i "temporal" # Verify Temporal is serving the frontend request series curl -s http://localhost:8000/metrics | grep service_requests # Check persistence latency is present curl -s http://localhost:8000/metrics | grep persistence_latency ``` ### Troubleshooting #### Metrics endpoint returns empty or connection refused **Cause**: `PROMETHEUS_ENDPOINT` is not set on the Temporal server. **Fix**: 1. Set `PROMETHEUS_ENDPOINT=0.0.0.0:8000` in the Temporal server environment. 2. Restart the Temporal server. 3. Verify: `curl http://localhost:8000/metrics`. #### Connection refused on port 8000 **Cause**: The Collector cannot reach Temporal at the configured endpoint. **Fix**: 1. Confirm `PROMETHEUS_ENDPOINT` binds `0.0.0.0:8000`, not `127.0.0.1:8000`, so it is reachable from the Collector's network. 2. Verify the port is exposed if running in Docker: `ports: ["8000:8000"]`. 3. Test from the Collector's network: `docker exec otel-collector wget -qO- http://temporal:8000/metrics`. #### Workflow and task-outcome metrics read idle values **Cause**: The task-execution and workflow families need real workflows running - an SDK worker polling a task queue. **Look at**: `approximate_backlog_count`, `temporal_worker_task_slots_used`, and the `task_latency_*` phases - they populate fully only once a worker polls a task queue and executes workflows. Until then they read idle values, which is expected and not a fault. **Fix**: 1. Run an SDK worker against the cluster and execute a workflow. 2. Re-check the task and backlog series; they advance as work flows. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Temporal running in Kubernetes? Yes. Set `targets` to the Temporal service DNS endpoint per role (e.g., `temporal-frontend.temporal.svc.cluster.local:8000`), and set `PROMETHEUS_ENDPOINT` on each Temporal pod's container env. The Collector can run as a sidecar or DaemonSet. #### Single-binary or microservices deployment: what is the difference? The `auto-setup` image runs all four roles - frontend, history, matching, and worker - in one process behind a single `/metrics`, with an `operation` label on the metrics. A production deployment splits the roles across processes, each with its own `:8000`. The metric names are identical, so you add one scrape job per role (see [Configuration](#configuration)). #### Why does persistence matter so much? Temporal depends heavily on its persistence store. Every workflow state change, task, and history event is a persistence operation, so a slow store backs up task processing and RPC latency. That makes `persistence_latency`, `persistence_requests`, and `persistence_error_with_type` among the first signals to check during a Temporal incident. #### What is the difference between the `temporal_*` and the unprefixed metrics? Unprefixed names (`service_*`, `persistence_*`, `task_*`, `cache_*`, `history_*`, and the shard / queue families) are the **server** metrics. The `temporal_*` names are the **SDK client** metrics from Temporal's internal system worker - the same names a user-written worker emits. #### Why are some metrics idle or zero? The workflow-completion, activity-execution, and task-outcome families need real workflows running - an SDK worker polling a task queue. Without one, they read idle values, which is expected. The `replication_*` families are meaningful only in a multi-cluster (replication) deployment. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Temporal metrics. - [PostgreSQL Monitoring](./postgres.md) - Watch the database that bounds Temporal's throughput. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), Temporal's persistence backend, and other components. - **Fine-tune Collection**: The keep rule scopes collection to the Temporal product metrics and drops the Go-runtime and `tally_internal_*` noise families; remove it when you need that runtime detail during an incident. --- ## TiDB OpenTelemetry Monitoring - Store Liveness, Region Replication, and Collector Setup ## TiDB TiDB is a distributed, MySQL-wire-compatible SQL database: the SQL layer speaks the MySQL protocol on port `4000`, so if you already run the [MySQL receiver](./mysql.md) you know most of the query-layer signals here. What you do not have a single-node-MySQL analogue for is the distributed machinery - whether every storage node is in the cluster, whether every region is fully replicated, and whether the cluster's single source of time is healthy. Those are the signals that page you when a multi-node cluster degrades, and they are the reason this is a separate guide. A TiDB cluster is three separate component types, each with its own Prometheus `/metrics` endpoint on a different port: - **PD** (Placement Driver) on `2379` - cluster metadata, region scheduling, the TSO timestamp oracle, and an embedded etcd. - **TiKV** (the distributed key-value storage tier) on status port `20180` - regions, RocksDB, and Raft. Three TiKV stores give the default 3-replica (RF-3) region placement, which is why region and replication signals are meaningful. - **TiDB** (the stateless MySQL-wire SQL layer) on status port `10080` - the query engine, sessions, and the TiKV client. There is no native TiDB receiver and no `information_schema` / `SHOW STATUS` scraping in play - the OpenTelemetry Collector's `prometheus` receiver scrapes each component's status endpoint directly. Metric names are prefixed per component (`pd_*`, `tikv_*`, `tidb_*`), plus PD's embedded `etcd_*` and TiKV's `raft_engine_*` (the Raft log WAL) and `tikv_engine_*` (RocksDB); the cluster emits 900+ distinct metric names across the three endpoints. This guide configures the receiver and ships the metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | TiDB (PD/TiKV/TiDB) | 6.5 | 8.5+ | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - Each component's status port must be reachable from the host running the Collector: PD `2379`, TiKV `20180`, TiDB `10080`. - No SQL monitoring user is required - the Prometheus endpoints are plain HTTP (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Every series carries its scrape `job` (`tidb-pd` / `tidb-tikv` / `tidb-tidb`) and `instance` (the component's `host:port`); per-store TiKV series additionally carry the store endpoint. The tiers below lead with the distributed signals that single-node MySQL cannot show - store liveness, region replication, and the centralized timestamp oracle - then cover the familiar MySQL-wire throughput and latency series. The MySQL-wire QPS KPI carries over from single MySQL; the other Core signals are the ones single MySQL has no analogue for. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `pd_cluster_status` (`type="store_up_count"` / `region_count` / `storage_size`) | The cluster brain's census: live TiKV stores (= the store count when whole), total regions, and used bytes. The "is the cluster whole" headline. No single-MySQL analogue. | | `tidb_server_query_total` (by `type` / `result`) | MySQL-wire statements served on the SQL layer - the headline throughput KPI, and the `result="Error"` split is the error-rate SLI. The direct delta on single MySQL's `Queries` / `Com_*`. | | `pd_regions_status` (`type="miss-peer-region-count"` / `down-peer-region-count` / `pending-peer-region-count`) | Region replication health: peers missing, down, or pending. 0 in steady state; greater than 0 means regions are under-replicated and the cluster is healing or stuck. The signature distributed signal. | | `tso_monitor_time_jump_back_total` | The PD timestamp oracle's physical clock moved backwards. TiDB orders every transaction by TSO, so a jump-back is the centralized-clock health signal. No single-MySQL analogue. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `pd_cluster_status` (`type="store_down_count"` / `store_unhealth_count"` / `store_low_space_count"`) | PD has marked a TiKV store down, unhealthy, or low on space; each should be 0. Distributed signal. | | `tidb_server_handle_query_duration_seconds` | SQL-layer query latency distribution (histogram) - the user-facing latency SLI. | | `tidb_server_execute_error_total` / `tidb_server_critical_error_total` | SQL execution errors and critical (panic-class) errors on the TiDB node. | | `tidb_server_connections` | Open client connections, against the `max-server-connections` limit (0 = unlimited by default). `token-limit` separately caps concurrently-running requests. The MySQL-wire connection-count delta. | | `tidb_tikvclient_backoff_seconds` | TiDB backing off while waiting on TiKV; rising means the storage layer is slow or a region is unavailable. Distributed retry-pressure signal with no single-MySQL analogue. | | `tikv_grpc_msg_duration_seconds` | TiKV-side request latency per command - the storage-layer SLI underneath the SQL layer. | | `tikv_store_size_bytes` (`type="capacity"` / `available"`) | Per-store disk capacity and available bytes - storage pressure that drives PD rebalancing and, at the limit, write stalls. | | `tikv_raftstore_region_count` (`type="region"` / `leader"`) | Regions and Raft leaders held per store; leader imbalance across stores concentrates load (hotspot). | | `etcd_server_has_leader` / `etcd_server_leader_changes_seen_total` | PD's embedded etcd leader health. If PD's etcd has no leader or flaps, scheduling and TSO stall cluster-wide. | | `pd_scheduler_handle_region_heartbeat_duration_seconds` | How long PD takes to process region heartbeats; rising latency means the scheduler is falling behind on a large cluster. | #### Diagnostic - for investigation and tuning Higher cardinality - the storage engine internals, the Raft and scheduler machinery, and the SQL-to-storage RPC layer. Enable on demand; in production you can drop this tier with a `metric_relabel_configs` block while keeping Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | TiKV RocksDB engine (`tikv_engine_*`) | `tikv_engine_size_bytes`, `tikv_engine_compaction_duration_seconds`, `tikv_engine_cache_efficiency`, `tikv_engine_bytes_per_read` / `_per_write`, plus the Titan blob-storage `tikv_engine_blob_*` family | Storage-engine size, compaction stalls, and cache behavior under load. | | TiKV Raft store (`tikv_raftstore_*`) | `tikv_raftstore_apply_log_duration_seconds`, `_commit_log_duration_seconds`, `_append_log_duration_seconds`, `tikv_raftstore_raft_ready_handled_total`, `tikv_raftstore_leader_missing`, `tikv_raftstore_process_busy` | Raft replication latency and whether the raftstore thread is saturated. | | TiKV Raft log engine (`raft_engine_*`) | `raft_engine_write_duration_seconds`, `raft_engine_sync_log_duration_seconds`, `raft_engine_log_entry_count`, `raft_engine_memory_usage` | The WAL underneath Raft - write/sync latency and log-entry backlog. | | TiKV scheduler / coprocessor / storage (`tikv_scheduler_*`, `tikv_coprocessor_*`, `tikv_storage_*`) | `tikv_scheduler_latch_wait_duration_seconds`, `tikv_scheduler_commands_pri_total`, write-conflict and command-stage counters | Transaction-scheduler contention and pushed-down read execution. | | TiDB → TiKV client (`tidb_tikvclient_*`) | `tidb_tikvclient_txn_cmd_duration_seconds`, `tidb_tikvclient_request_seconds`, region-cache and 2PC commit counters (`tidb_tikvclient_backoff_seconds` is also Operational) | The SQL-to-storage RPC layer - txn latency, region-cache misses, commit pressure. | | TiDB session / executor / DDL (`tidb_session_*`, `tidb_executor_*`, `tidb_ddl_*`) | `tidb_session_transaction_duration_seconds`, `tidb_session_retry_error_total`, `tidb_executor_statement_total`, `tidb_ddl_worker_operation_total` | Transaction retries, statement mix, and schema-change progress. | | TiDB optimizer stats / SLI (`tidb_statistics_*`, `tidb_sli_*`, `tidb_topsql_*`) | auto-analyze and stats-cache health; `tidb_sli_*` small-transaction SLI | Stale-statistics regressions and per-transaction SLI. | | PD scheduling (`pd_scheduler_*`, `pd_schedule_*`, `pd_checker_*`) | `pd_scheduler_region_heartbeat`, `pd_schedule_operators_count`, hot-region and balance operators | Whether PD is rebalancing, splitting hot regions, or stuck. | | PD client / replication / TSO (`pd_client_*`, `pd_replication_*`, `pd_tso_*`) | request latencies, replication mode, TSO issuance (`pd_tso_events`) | PD-client RPC latency and TSO issuance rate. | | PD embedded etcd internals (`etcd_*`) | `etcd_disk_wal_fsync_duration_seconds`, `etcd_disk_backend_commit_duration_seconds`, `etcd_mvcc_db_total_size_in_bytes`, `etcd_server_proposals_*` | PD's own storage and consensus health behind the cluster metadata. | | TiDB Resource Control (`resource_manager_*`) | per-resource-group Request Unit accounting (`resource_manager_resource_unit_read_request_unit_sum` / `_write_…`, `resource_manager_client_token_request_*`) | Request-Unit consumption - only meaningful when resource groups are configured. | The long diagnostic tail groups into families, with distinct-name counts: `tikv_raftstore_*` (103), `etcd_*` (75), `tikv_engine_*` (73), `tidb_tikvclient_*` (73), `tidb_server_*` (52), `tikv_resolved_*` / `tikv_cdc_*` (39, resolved-ts safe-point and change-data-capture), `tikv_scheduler_*` (24), `resource_manager_*` (20), `tidb_session_*` (18), `pd_scheduler_*` (17), `raft_engine_*` (16), `tidb_statistics_*` (16), `tikv_coprocessor_*` (14), and `pd_server_*` / `pd_cluster_*` (24). The Go and process runtime families (`go_*`, `process_*`) are emitted by every PD/TiKV/TiDB binary. Full metric reference: [TiDB monitoring metrics](https://docs.pingcap.com/tidb/stable/grafana-overview-dashboard/), or `curl -s http://localhost:10080/metrics` (TiDB), `http://localhost:2379/metrics` (PD), and `http://localhost:20180/metrics` (TiKV) against the components. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. Tune to your workload and cluster size; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `pd_cluster_status{type="store_up_count"}` (summed) | < store count | Falling further | A TiKV store is down or partitioned; investigate the missing store before region replication is at risk. | | `pd_cluster_status{type="store_down_count"}` | > 0 | > 0 sustained | PD has declared a TiKV store down; recover or replace it. | | `pd_regions_status{type="miss-peer-region-count"}` / `down-peer-region-count` | > 0 | > 0 sustained | Regions are under-replicated and not healing; a store loss is not recovering. Restore the missing store or add capacity. | | `tso_monitor_time_jump_back_total` | Any increase | Increasing across scrapes | The PD timestamp oracle's clock jumped backwards; transaction ordering is at risk. Check the PD host clock / NTP. | | `rate(tidb_server_query_total{result="OK"})` | Dipping vs baseline | ≈ 0 sustained under expected load | The SQL layer has stopped serving; check the TiDB nodes and TiKV health. | | `rate(tidb_server_query_total{result="Error"}) / rate(tidb_server_query_total)` | Rising vs baseline | Climbing steeply | SQL error rate climbing; express the threshold as an error-ratio relative to your workload's baseline. | | `tidb_server_handle_query_duration_seconds` (p99) | Rising vs baseline | Well above normal p99 | Query-latency regression; relate the threshold to the workload's normal p99. | | `tidb_tikvclient_backoff_seconds` | Rising vs baseline | Sustained high | TiDB is backing off on TiKV; the storage layer is slow or a region is unavailable. | | `tikv_store_size_bytes{type="available"}` | < a low fraction of `{type="capacity"}` | Approaching zero | A TiKV store is filling; writes stall when a store runs out of space. Add storage or rebalance. | | `etcd_server_has_leader` (PD) | == 0 | == 0 sustained, or `rate(etcd_server_leader_changes_seen_total) > 0` sustained | PD's embedded etcd has no stable leader; scheduling and TSO are impaired cluster-wide. | ### Access Setup TiDB needs no SQL monitoring user for metrics. Unlike the MySQL receiver - which connects over the MySQL wire protocol with a `GRANT`-ed monitoring account - TiDB's metrics come from each component's plain-HTTP status endpoint. "Access setup" here means exposing the three components' status ports to the Collector: PD `2379`, TiKV `20180`, and TiDB `10080`. Every component serves its own metrics, and each TiKV store serves its own, so the Collector scrapes each component instance - the per-store TiKV series are exactly what the region and replication tiers depend on. ```yaml showLineNumbers title="docker-compose.yaml (excerpt)" services: pd0: image: pingcap/pd:v8.5.6 command: - --name=pd0 - --client-urls=http://0.0.0.0:2379 - --advertise-client-urls=http://pd0:2379 ports: - "2379:2379" # PD client + /metrics tikv0: image: pingcap/tikv:v8.5.6 command: - --pd=pd0:2379 - --addr=0.0.0.0:20160 - --advertise-addr=tikv0:20160 - --status-addr=0.0.0.0:20180 # TiKV /metrics depends_on: [pd0] # tikv1, tikv2 are identical with their own advertise-addr - three stores # give the default 3-replica (RF-3) region placement. tidb0: image: pingcap/tidb:v8.5.6 command: - --store=tikv - --path=pd0:2379 - --status=10080 # TiDB /metrics ports: - "4000:4000" # MySQL wire protocol - "10080:10080" # TiDB status + /metrics depends_on: [tikv0] ``` The status endpoints carry no secrets but should not be public. In a secured deployment the status ports serve over `https` (TiDB and PD support TLS on the status/client ports); expose them to the Collector over a trusted network path and switch the scrape scheme to `https` with `tls` settings when TLS is on. Verify each endpoint serves metrics: ```bash showLineNumbers title="Verify access" # PD - cluster status and region health curl -s http://localhost:2379/metrics | grep -E '^pd_cluster_status|^pd_regions_status' # TiKV - per-store size and region count curl -s http://localhost:20180/metrics | grep -E '^tikv_store_size_bytes|^tikv_raftstore_region_count' # TiDB - MySQL-wire query throughput curl -s http://localhost:10080/metrics | grep -E '^tidb_server_query_total' ``` ### Configuration The `prometheus` receiver scrapes the three endpoint types with one scrape job per component, all at the default `metrics_path` `/metrics`. The `tidb-tikv` job fans across every store so each TiKV instance's series are collected. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: tidb-pd scrape_interval: 15s static_configs: - targets: - pd0:2379 # PD client/metrics port - job_name: tidb-tikv scrape_interval: 15s static_configs: - targets: - tikv0:20180 # Each TiKV store's status port - tikv1:20180 - tikv2:20180 - job_name: tidb-tidb scrape_interval: 15s static_configs: - targets: - tidb0:10080 # TiDB status port processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The three endpoints deliver their full `/metrics` surface with no filter (900+ distinct names across PD, TiKV, and TiDB). To control metric volume in production, drop the Diagnostic tier with a `metric_relabel_configs` block on the scrape jobs while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped TiDB metrics across the three components docker logs otel-collector 2>&1 | grep -iE "tidb_server_query_total|pd_cluster_status|tikv_store_size_bytes" # Confirm each component is serving metrics on its status endpoint curl -s http://localhost:2379/metrics | grep -E '^pd_cluster_status' curl -s http://localhost:10080/metrics | grep -E '^tidb_server_query_total' ``` The SQL counters only move once the cluster does work. Drive some MySQL-wire load against TiDB and confirm `tidb_server_query_total` rises, all stores report up, and regions are fully replicated: ```bash showLineNumbers title="Generate MySQL-wire load" # TiDB speaks the MySQL protocol on port 4000 - use any MySQL client mysql -h 127.0.0.1 -P 4000 -u root -e \ "CREATE DATABASE IF NOT EXISTS bench; USE bench; CREATE TABLE IF NOT EXISTS t (id INT PRIMARY KEY, n INT); INSERT INTO t VALUES (1,1) ON DUPLICATE KEY UPDATE n=n+1; SELECT COUNT(*) FROM t;" # PD should report all stores up and no under-replicated regions curl -s http://localhost:2379/metrics | grep -E 'store_up_count|miss-peer-region-count' ``` ### Troubleshooting #### No TiDB metrics in the Collector **Cause**: The Collector cannot reach one of the component status endpoints, or a scrape job targets the wrong port. **Fix**: 1. Confirm the components are running and joined: PD on `2379`, each TiKV on `20180`, TiDB on `10080`. 2. Verify each job's targets and ports match the scrape config - the three component types use three different ports. 3. Confirm the `tidb-tikv` job lists every store; a missing store target means that store's `tikv_*` series never arrive even when the store is healthy. #### Metric name present but no datapoints **Cause**: The cluster is idle, so the SQL and TiKV counters have not moved since the last scrape. **Look at**: `tidb_server_query_total` (should rise under load) and `tidb_server_connections` (open connections). `pd_cluster_status{type="store_up_count"}` should equal your store count even when idle. **Fix**: 1. Drive MySQL-wire load against TiDB on port `4000` and re-check. #### A TiKV store dropped out of the cluster **Cause**: A store failed its heartbeats to PD, or PD marked it down. **Look at**: `pd_cluster_status{type="store_down_count"}` (greater than 0 means PD declared a store down) and the Diagnostic `tikv_raftstore_leader_missing` on the affected store. `tidb_tikvclient_backoff_seconds` rising on the SQL side confirms TiDB is retrying against the missing store. **Fix**: 1. Restore network reachability or restart the store, then confirm `pd_cluster_status{type="store_up_count"}` returns to the store count. #### Regions stay under-replicated **Cause**: A store is down long enough that PD cannot meet the 3-replica target, or rebalancing is stuck. **Look at**: `pd_regions_status{type="miss-peer-region-count"}` / `down-peer-region-count` (not converging back to 0). The Diagnostic `pd_scheduler_*` operators and `pd_scheduler_handle_region_heartbeat_duration_seconds` show whether PD is actively re-replicating or falling behind. **Fix**: 1. Bring the missing store back or add a store so PD can restore the replication target. 2. If `tikv_store_size_bytes{type="available"}` is low on the remaining stores, PD cannot place new replicas - add storage or rebalance first. #### Transaction ordering or clock alarms **Cause**: PD's physical clock moved backwards, or PD's embedded etcd lost its leader, so the TSO cannot issue ordered timestamps. **Look at**: `tso_monitor_time_jump_back_total` (any increase is a clock jump-back) and `etcd_server_has_leader` / `etcd_server_leader_changes_seen_total` on PD. The Diagnostic `etcd_disk_wal_fsync_duration_seconds` shows whether PD's etcd disk is the bottleneck behind leader flaps. **Fix**: 1. Fix clock sync (NTP / chrony) on the PD host if `tso_monitor_time_jump_back_total` increments. 2. If PD's etcd has no stable leader, check the PD host disk and network; a slow `etcd_disk_wal_fsync_duration_seconds` drives leader churn. #### No metrics appearing in Scout **Cause**: Metrics are scraped but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `prometheus` receiver and the `otlphttp/b14` exporter. ### FAQ #### Which ports and path does TiDB use for metrics? TiDB is three component types, each with its own Prometheus `/metrics` endpoint: PD on `2379`, TiKV on status port `20180`, and TiDB on status port `10080`. The Collector runs one `prometheus` scrape job per component type, all at `metrics_path` `/metrics`. No SQL login is involved - these are HTTP status endpoints, not the MySQL wire protocol on port `4000`. #### Do I need a MySQL monitoring user like the `mysqlreceiver` needs? No. Unlike the MySQL receiver, which connects over the MySQL wire protocol with a `GRANT`-ed monitoring user, TiDB's metrics come from plain-HTTP status endpoints on PD, TiKV, and TiDB. Access setup is exposing those status ports (`2379`, `20180`, `10080`) to the Collector, not creating a `CREATE USER` / `GRANT` monitoring account. #### How do I monitor all the stores in a cluster? Add every TiKV store's `host:20180` to the `tidb-tikv` job's `static_configs.targets`, every PD's `host:2379` to `tidb-pd`, and every TiDB node's `host:10080` to `tidb-tidb`. Each instance serves only its own series, tagged with `job` and `instance`, so scraping each one is what makes the per-store region and replication tiers work. #### What does `pd_cluster_status{type="store_up_count"}` report? The number of TiKV stores PD currently considers live. In a healthy cluster it equals the store count; a drop signals a store PD can no longer reach. Single-node MySQL has no analogue - this is a distributed-cluster liveness signal. #### Why monitor `tso_monitor_time_jump_back_total`? PD's timestamp oracle (TSO) issues the timestamps TiDB uses to order every transaction. `tso_monitor_time_jump_back_total` increments when PD's physical clock moves backwards, which puts transaction ordering at risk. A rising counter means you should check the PD host clock and NTP. ### Related Guides - [MySQL Monitoring](./mysql.md) - The single-node MySQL-wire counterpart; the SQL-layer signals here mirror its receiver, and this guide is the distributed delta on it (store liveness, region replication, the TSO clock). - [CockroachDB Monitoring](./cockroachdb.md) - Another distributed SQL database, PostgreSQL-wire instead of MySQL-wire. - [YugabyteDB Monitoring](./yugabytedb.md) - PostgreSQL-wire distributed SQL; the same Prometheus-scrape pattern across a multi-process cluster. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on store liveness and region replication. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [MySQL](./mysql.md), [CockroachDB](./cockroachdb.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `metric_relabel_configs` block to control volume; keep it available for incident investigation. --- ## Tomcat OpenTelemetry Monitoring - Request Rates, Thread Pools, and Collector Setup ## Tomcat The OpenTelemetry JMX Scraper connects to Apache Tomcat 8.5+ over JMX RMI and collects 8 Tomcat-specific metrics and 19 JVM metrics - request throughput, error counts, request latency, connector thread-pool saturation, network I/O, and JVM heap / CPU / thread health - then pushes them over OTLP to the Collector. Tomcat exposes its Catalina MBeans (`GlobalRequestProcessor`, `ThreadPool`) and JVM MBeans over JMX with no Prometheus or OpenTelemetry endpoint of its own, so the scraper translates the MBeans into OTel metrics. This guide enables JMX on Tomcat, configures the scraper and Collector, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | -------------- | ------- | ----------- | | Apache Tomcat | 8.5 | 11.0+ | | JMX Scraper | 1.46.0 | 1.54.0+ | | Java (scraper) | 11 | 17+ | | OTel Collector | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - Tomcat must be reachable over JMX from the host running the scraper (JMX port, default 9010). - The JMX Scraper runs as a standalone Java process and needs its own JRE. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `tomcat.*` connector metrics carry a `tomcat.request.processor.name` attribute (for example `http-nio-8080`); the `jvm.memory.*` metrics carry `jvm.memory.type` (heap / non_heap) and the pool name. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `tomcat.request.count` | Requests handled by the connector - the throughput KPI. | | `jvm.memory.used` | JVM memory in use. JMX exposes no `up` metric, so heap-in-use doubles as the process-alive and heap-health anchor. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `tomcat.error.count` | Request errors at the connector - the error-rate signal. | | `tomcat.request.duration.sum` | Cumulative request-processing time; divide by request count for mean latency. | | `tomcat.request.duration.max` | Longest request-processing time - tail latency. | | `tomcat.thread.busy.count` | Connector threads actively handling requests. | | `tomcat.thread.count` | Connector threads currently in the pool. | | `tomcat.thread.limit` | Connector thread-pool ceiling - the saturation denominator. | | `tomcat.network.io` | Connector bytes sent and received. | | `jvm.memory.limit` | JVM memory ceiling - the saturation denominator against `jvm.memory.used`. | | `jvm.cpu.recent_utilization` | Recent process CPU utilization. | | `jvm.thread.count` | Total live JVM threads - a leak signal. | #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. In production you can drop this tier with a `filter` processor and keep Core + Operational. | Group | Metrics | When you reach for it | |---|---|---| | JVM memory detail | `jvm.memory.committed`, `jvm.memory.init`, `jvm.memory.used_after_last_gc` | Heap sizing and post-GC live-set; GC churn analysis. | | Class loading | `jvm.class.count`, `jvm.class.loaded`, `jvm.class.unloaded` | Classloader leaks and redeploy churn. | | CPU / system | `jvm.cpu.count`, `jvm.cpu.time`, `jvm.system.cpu.load_1m`, `jvm.system.cpu.utilization` | Host-level CPU pressure vs process CPU. | | Buffers / descriptors | `jvm.buffer.count`, `jvm.buffer.memory.limit`, `jvm.buffer.memory.used`, `jvm.file_descriptor.count`, `jvm.file_descriptor.limit` | Direct-buffer growth and fd usage against the ceiling. | Session metrics (`tomcat.session.*`) only appear when a session-bearing web application is deployed; an empty Tomcat with no contexts emits no session metrics. See [Troubleshooting](#session-metrics-missing). Full metric reference: [OTel JMX Tomcat metrics](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/instrumentation/jmx-metrics/library/tomcat.md). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `rate(tomcat.error.count)` vs `rate(tomcat.request.count)` | Error fraction climbing | Sustained rise | Application or upstream errors; inspect logs and the failing endpoints. | | `tomcat.thread.busy.count` / `tomcat.thread.limit` | > 0.80 | Approaching 1.0 | Connector running out of worker threads; raise `maxThreads` or shed load. | | `tomcat.request.duration.sum` / request count (mean), or `tomcat.request.duration.max` | Rising vs baseline | Sustained spike | Slow request handling; check downstream calls and GC. | | `jvm.memory.used` / `jvm.memory.limit` | > 0.80 | > 0.90 | GC churn and OOM risk; raise heap or reduce allocation. | | `jvm.cpu.recent_utilization` | Sustained high | Pinned near 1.0 | Process is CPU-bound; scale out or profile the hot paths. | ### Access Setup Tomcat exposes metrics over JMX (Java Management Extensions). Enable remote JMX access by adding the flags below to `setenv.sh` (or `CATALINA_OPTS` in your deployment). #### Enable JMX on Tomcat ```bash showLineNumbers title="bin/setenv.sh" export CATALINA_OPTS="$CATALINA_OPTS \ -Dcom.sun.management.jmxremote \ -Dcom.sun.management.jmxremote.port=9010 \ -Dcom.sun.management.jmxremote.rmi.port=9010 \ -Dcom.sun.management.jmxremote.ssl=false \ -Dcom.sun.management.jmxremote.authenticate=false \ -Djava.rmi.server.hostname=" # Your Tomcat host IP or hostname ``` Setting `rmi.port` equal to `port` keeps RMI from opening a random second port, which simplifies firewall and Docker networking. For Docker, pass `CATALINA_OPTS` as an environment variable and set the container `hostname` so RMI hands back a reachable address: ```yaml showLineNumbers title="docker-compose.yaml (Tomcat service)" tomcat: image: tomcat:11.0.22-jdk17-temurin hostname: tomcat environment: CATALINA_OPTS: >- -Dcom.sun.management.jmxremote -Dcom.sun.management.jmxremote.port=9010 -Dcom.sun.management.jmxremote.rmi.port=9010 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname=tomcat ``` The flags above run JMX with no auth and no TLS, which is fine inside a trusted network or pod. Production exposed over an untrusted network should enable both. #### With Authentication (Production) ```bash showLineNumbers title="bin/setenv.sh (authenticated)" export CATALINA_OPTS="$CATALINA_OPTS \ -Dcom.sun.management.jmxremote \ -Dcom.sun.management.jmxremote.port=9010 \ -Dcom.sun.management.jmxremote.rmi.port=9010 \ -Dcom.sun.management.jmxremote.ssl=true \ -Dcom.sun.management.jmxremote.authenticate=true \ -Dcom.sun.management.jmxremote.password.file=/path/to/jmxremote.password \ -Dcom.sun.management.jmxremote.access.file=/path/to/jmxremote.access \ -Djava.rmi.server.hostname=" ``` The JMX Scraper connects with credentials via the `OTEL_JMX_USERNAME` and `OTEL_JMX_PASSWORD` environment variables. ### Configuration Tomcat monitoring uses two components: the JMX Scraper (connects to Tomcat over JMX RMI, targets the `jvm,tomcat` systems, exports OTLP) and the OTel Collector (receives OTLP, ships to Scout). ```text Tomcat (JMX:9010) ← JMX/RMI → JMX Scraper → OTLP/gRPC → OTel Collector → Scout ``` #### JMX Scraper Download the scraper JAR from [Maven Central](https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/) and run it: ```bash showLineNumbers title="Run the JMX Scraper" OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://localhost:9010/jmxrmi \ OTEL_JMX_TARGET_SYSTEM=jvm,tomcat \ OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 \ OTEL_METRIC_EXPORT_INTERVAL=10000 \ java -jar opentelemetry-jmx-scraper-1.57.0-alpha.jar ``` Move the JAR to a permanent location: ```bash showLineNumbers title="Install the scraper JAR" sudo mkdir -p /opt/otel sudo mv opentelemetry-jmx-scraper-1.57.0-alpha.jar /opt/otel/ ``` Run the scraper as a managed systemd service: ```bash showLineNumbers title="/etc/systemd/system/otel-jmx-scraper.service" sudo tee /etc/systemd/system/otel-jmx-scraper.service > /dev/null <<'EOF' [Unit] Description=OpenTelemetry JMX Scraper for Tomcat After=network.target tomcat.service [Service] Type=simple Environment=OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://localhost:9010/jmxrmi Environment=OTEL_JMX_TARGET_SYSTEM=jvm,tomcat Environment=OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 Environment=OTEL_METRIC_EXPORT_INTERVAL=10000 ExecStart=/usr/bin/java -jar /opt/otel/opentelemetry-jmx-scraper-1.57.0-alpha.jar Restart=always RestartSec=5 [Install] WantedBy=multi-user.target EOF ``` ```bash showLineNumbers title="Enable the scraper service" sudo systemctl daemon-reload sudo systemctl enable --now otel-jmx-scraper ``` For Docker, build a small image with the scraper JAR: ```dockerfile showLineNumbers title="jmx-scraper/Dockerfile" FROM eclipse-temurin:17-jre ARG SCRAPER_VERSION=1.57.0-alpha # Update to match your target version ADD https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/${SCRAPER_VERSION}/opentelemetry-jmx-scraper-${SCRAPER_VERSION}.jar /opt/scraper.jar ENTRYPOINT ["java", "-jar", "/opt/scraper.jar"] ``` #### OTel Collector The Collector receives metrics from the scraper over OTLP/gRPC: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` To control metric volume in production, drop the Diagnostic tier with a `filter` processor on the metrics pipeline while keeping the Core and Operational series. #### Environment Variables ```bash showLineNumbers title=".env" # JMX Scraper OTEL_JMX_SERVICE_URL=service:jmx:rmi:///jndi/rmi://tomcat:9010/jmxrmi OTEL_JMX_TARGET_SYSTEM=jvm,tomcat OTEL_METRIC_EXPORT_INTERVAL=10000 # OTEL_JMX_USERNAME=monitor # Uncomment for authenticated JMX # OTEL_JMX_PASSWORD=your_password # Uncomment for authenticated JMX # OTel Collector ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Docker Compose Full working example with all three components: ```yaml showLineNumbers title="docker-compose.yaml" services: tomcat: image: tomcat:11.0.22-jdk17-temurin hostname: tomcat container_name: tomcat ports: - "8080:8080" - "9010:9010" environment: CATALINA_OPTS: >- -Dcom.sun.management.jmxremote -Dcom.sun.management.jmxremote.port=9010 -Dcom.sun.management.jmxremote.rmi.port=9010 -Dcom.sun.management.jmxremote.ssl=false -Dcom.sun.management.jmxremote.authenticate=false -Djava.rmi.server.hostname=tomcat healthcheck: test: ["CMD-SHELL", "curl -so /dev/null http://localhost:8080/ || exit 1"] interval: 10s timeout: 5s retries: 10 start_period: 30s jmx-scraper: build: ./jmx-scraper container_name: jmx-scraper environment: OTEL_JMX_SERVICE_URL: ${OTEL_JMX_SERVICE_URL} OTEL_JMX_TARGET_SYSTEM: ${OTEL_JMX_TARGET_SYSTEM} OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: ${OTEL_METRIC_EXPORT_INTERVAL} depends_on: tomcat: condition: service_healthy otel-collector: image: otel/opentelemetry-collector-contrib:latest container_name: otel-collector volumes: - ./config/otel-collector.yaml:/etc/otelcol-contrib/config.yaml:ro depends_on: - tomcat ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check the JMX Scraper logs for a successful JMX connection docker logs jmx-scraper 2>&1 | head -10 # Confirm Tomcat started with JMX enabled docker logs tomcat 2>&1 | grep "jmxremote" # Check Collector logs for Tomcat metrics docker logs otel-collector 2>&1 | grep -i "tomcat" # Drive traffic so the request / error / duration counters advance curl -s http://localhost:8080/ > /dev/null ``` ### Troubleshooting #### JMX connection refused **Cause**: The JMX Scraper cannot reach Tomcat's JMX port. **Fix**: 1. Verify Tomcat is running: `docker ps | grep tomcat`. 2. Confirm JMX is enabled - look for `-Dcom.sun.management.jmxremote` in Tomcat's startup args: `ps aux | grep jmxremote`. 3. Verify the JMX port matches between Tomcat's config and the scraper's `OTEL_JMX_SERVICE_URL`. 4. In Docker, ensure `hostname` is set on the Tomcat container and matches `-Djava.rmi.server.hostname`. #### Only JVM metrics, no Tomcat metrics **Cause**: `OTEL_JMX_TARGET_SYSTEM` does not include `tomcat`. **Fix**: 1. Set `OTEL_JMX_TARGET_SYSTEM=jvm,tomcat` (both targets, comma-separated). 2. Verify Tomcat has fully started - the Catalina MBeans (`GlobalRequestProcessor`, `ThreadPool`) are only registered after Catalina initializes. #### Session metrics missing **Cause**: Session metrics only appear when at least one session-bearing web application is deployed. The session MBeans are per-context (`Catalina:type=Manager,host=localhost,context=/myapp`), so an empty Tomcat with no contexts emits none. **Fix**: 1. Deploy a web application to Tomcat - empty instances with no contexts do not emit session metrics. 2. Confirm requests are actually creating sessions in your app. #### Requests are slow or threads are piling up **Cause**: The connector thread pool is saturated, or the JVM is under memory or CPU pressure. **Look at**: `tomcat.thread.busy.count` against `tomcat.thread.limit` (pool saturation) and `tomcat.request.duration.max` (tail latency). On the JVM side, the Diagnostic `jvm.memory.used_after_last_gc` (live set after GC) and `jvm.system.cpu.utilization` / `jvm.system.cpu.load_1m` (host CPU pressure) show whether GC churn or a CPU-bound host is the cause. **Fix**: 1. Raise `maxThreads` on the connector or shed load if the busy count is pinned at the limit. 2. Raise heap or reduce allocation if `used_after_last_gc` keeps climbing between collections. #### Suspected memory or descriptor leak **Cause**: Long-running growth in live threads, loaded classes, direct buffers, or open file descriptors. **Look at**: `jvm.thread.count` (Operational), and the Diagnostic `jvm.class.loaded` / `jvm.class.unloaded` (classloader leaks on redeploy), `jvm.buffer.memory.used` (direct-buffer growth), and `jvm.file_descriptor.count` (fd exhaustion). **Fix**: 1. Correlate the rising series with deploy events or traffic shape. 2. Capture a heap or thread dump for the offending component. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Tomcat running in Kubernetes? Yes. Run the JMX Scraper as a sidecar in the same pod and set `OTEL_JMX_SERVICE_URL` to `service:jmx:rmi:///jndi/rmi://localhost:9010/jmxrmi`, since both containers share the pod network. No firewall rules are needed for intra-pod communication. The Collector receives OTLP from the scraper. #### Can I use this with embedded Tomcat (Spring Boot)? Yes. Spring Boot's embedded Tomcat registers MBeans under the `Tomcat:` domain instead of `Catalina:`. The scraper's `tomcat` target system handles both. Enable JMX remote access on the app with the same `-Dcom.sun.management.jmxremote.*` flags. #### What happened to the OTel Collector JMX receiver? The Collector's `jmxreceiver` was deprecated in January 2026. It needed a JRE inside the Collector container and ran a Java subprocess internally. The standalone JMX Scraper replaces it - the same metric definitions, a cleaner operational model. #### How do I monitor multiple Tomcat instances? Run one JMX Scraper per Tomcat instance, each with a different `OTEL_JMX_SERVICE_URL`. All scrapers export to the same Collector: ```yaml showLineNumbers title="docker-compose.yaml (multiple instances)" jmx-scraper-primary: environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://tomcat-1:9010/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,tomcat OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 jmx-scraper-replica: environment: OTEL_JMX_SERVICE_URL: service:jmx:rmi:///jndi/rmi://tomcat-2:9010/jmxrmi OTEL_JMX_TARGET_SYSTEM: jvm,tomcat OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 ``` #### Why is there no `up` metric? JMX exposes no liveness gauge. Use `jvm.memory.used` as the process-alive anchor - if it stops reporting, the scraper has lost its JMX connection to Tomcat. ### Related Guides - [JMX Metrics Guide](../collector-setup/jmx-metrics-collection-guide.md) - Compare the JMX Scraper and the JMX Exporter. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Cassandra Monitoring](./cassandra.md) - Another JMX-based monitoring setup. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Tomcat metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Nginx](./nginx.md), [PostgreSQL](./postgres.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier in production with a `filter` processor to control volume; keep it available for incident investigation. --- ## Traefik OpenTelemetry Monitoring - Request Rates, Edge Latency, and Collector Setup ## Traefik Traefik exposes Prometheus-format metrics on a dedicated metrics entrypoint (default `:8082/metrics`) when `--metrics.prometheus` is enabled. The OpenTelemetry Collector's `prometheus` receiver scrapes that entrypoint, collecting 15+ metrics across entrypoint, router, and service request rates, request-duration histograms, request and response bytes, open connections, and config reloads - from Traefik 2.0+. This guide enables the metrics entrypoint, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Traefik | 2.0 | 3.3 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Traefik must be running with a dedicated metrics entrypoint and `--metrics.prometheus` enabled. - The metrics port must be reachable from the host running the Collector. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things shape what you see on this surface: - `up` is the liveness signal here. The `prometheus` receiver emits `up = 1` when the metrics entrypoint responds, so it is the is-the-proxy-reachable check. - Before any traffic flows, only Go-runtime metrics appear. `traefik_entrypoint_requests_total` and the per-entrypoint families need at least one request to materialize. - On Traefik v3 the per-entrypoint and per-service label breakdowns are emitted by default (`addEntryPointsLabels` / `addServicesLabels` default to `true`); the per-router breakdown is off by default and needs `addRoutersLabels: true`. These are Traefik's own emit knobs - they change what Traefik exposes, not what the Collector keeps. - `traefik_entrypoint_requests_total` carries `code` / `method` / `protocol` labels, so it is both the throughput signal and the HTTP error-rate signal (filter on `code=~"5.."`). #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape liveness - 1 = the Traefik metrics entrypoint responded. The liveness signal on this surface. | | `traefik_config_last_reload_success` | 1 = the last dynamic-config reload succeeded, 0 = it failed and Traefik is running stale/last-good config. The config-health signal. | | `traefik_entrypoint_requests_total` | Requests handled per entrypoint, labeled by `code` / `method` / `protocol` - edge throughput and status-code mix (error rate). | | `traefik_entrypoint_request_duration_seconds` | Request latency at the edge per entrypoint - the headline latency SLO (a histogram: `_bucket` / `_sum` / `_count`). | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `traefik_service_requests_total` | Requests proxied to each backend service, by `code` - per-backend volume and error rate. | | `traefik_service_request_duration_seconds` | Per-backend response latency - isolates a slow backend from a slow proxy. | | `traefik_router_requests_total` | Requests per router (after rule matching), by `code` - which route carries the traffic and errors. | | `traefik_router_request_duration_seconds` | Per-router request latency. | | `traefik_open_connections` | Current open connections by entrypoint / protocol - concurrency and saturation. | | `traefik_entrypoint_requests_bytes_total`, `traefik_entrypoint_responses_bytes_total` | Edge request/response bytes - ingress/egress bandwidth per entrypoint. | | `traefik_service_requests_bytes_total`, `traefik_service_responses_bytes_total` | Per-backend request/response bytes. | | `traefik_config_reloads_total` | Count of dynamic-config reloads - high churn means a flapping provider. | #### Diagnostic - for investigation and tuning Drill-down detail; reach for these during an incident or capacity review. | Group | Representative members | When you reach for it | |---|---|---| | Per-router bandwidth | `traefik_router_requests_bytes_total`, `traefik_router_responses_bytes_total` | Bandwidth attribution by route. | | Go-runtime / process | `go_*`, `process_*` | Endpoint runtime and process health; scope these out with a `traefik_.*` keep rule in production. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_series_added` | Receiver-side scrape health (not emitted by Traefik). | A few documented Traefik metrics stay silent until their feature is configured, then appear automatically: - `traefik_service_server_up` - requires a `healthCheck` on the service; reports per-backend-server health. - `traefik_service_retries_total` - requires a retry middleware. - `traefik_tls_certs_not_after` - requires a TLS-terminating entrypoint; reports certificate expiry. - 404 status-code series on the entrypoint - appear when traffic matches no router. Full metric list: run `curl -s http://localhost:8082/metrics` against your Traefik instance with the Prometheus metrics entrypoint enabled. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. These are starting points; tune them to your workload. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The metrics entrypoint stopped responding. Check the Traefik process and the metrics port. | | `traefik_config_last_reload_success` | `== 0` | Traefik is running stale config after a bad reload - fix the dynamic config; new routes and services are not applied. | | `rate(traefik_entrypoint_requests_total{code=~"5.."})` | Rising vs baseline | Server-side errors at the edge - check backends and recent config or deploys. | | `traefik_entrypoint_request_duration_seconds` (p99) | Rising vs baseline | Requests are slow at the edge - correlate with service latency to localize. | | `traefik_service_request_duration_seconds` (p99) | Rising vs baseline | A backend is slow; the proxy is fine - investigate that service. | | `traefik_open_connections` | Rising toward limits | Concurrency is climbing - check backend capacity and keep-alive behavior. | ### Access Setup Enable Prometheus metrics on a dedicated metrics entrypoint. Add these flags to the Traefik static configuration: ```bash showLineNumbers title="Traefik CLI flags" --entryPoints.metrics.address=:8082 --metrics.prometheus=true --metrics.prometheus.entryPoint=metrics --metrics.prometheus.addEntryPointsLabels=true --metrics.prometheus.addRoutersLabels=true --metrics.prometheus.addServicesLabels=true ``` Or in a static configuration file: ```yaml showLineNumbers title="traefik.yaml" entryPoints: web: address: ":80" metrics: address: ":8082" metrics: prometheus: entryPoint: metrics addEntryPointsLabels: true addRoutersLabels: true addServicesLabels: true ``` - `addEntryPointsLabels` - emit the per-entrypoint request families with an `entrypoint` label (default `true` on v3). - `addRoutersLabels` - emit the per-router families with a `router` label (default `false` on v3 - enable it for per-router metrics). - `addServicesLabels` - emit the per-service families with a `service` label (default `true` on v3). On Traefik v3 the per-router family is off by default; the snippet above enables all three explicitly so every breakdown is emitted. Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # Check the Traefik metrics endpoint curl -s http://localhost:8082/metrics | head -20 # Verify Traefik-specific metrics curl -s http://localhost:8082/metrics \ | grep traefik_entrypoint_requests_total ``` No authentication is enabled on the metrics entrypoint by default. Keep it on a separate port from your production entrypoints and restrict access with firewall rules in production. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: traefik scrape_interval: 30s static_configs: - targets: - ${env:TRAEFIK_HOST}:8082 # default metrics_path /metrics processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Traefik metrics entrypoint serves at the default `/metrics` path, so no `metrics_path` override is needed. #### Scoping to the Traefik namespace The metrics entrypoint also serves the endpoint's own `go_*` / `process_*` runtime series. To ship only the Traefik metrics, add a keep filter that scopes to the `traefik_` namespace: ```yaml showLineNumbers title="config/otel-collector.yaml (namespace scope)" receivers: prometheus: config: scrape_configs: - job_name: traefik scrape_interval: 30s static_configs: - targets: - ${env:TRAEFIK_HOST}:8082 metric_relabel_configs: - source_labels: [__name__] regex: "traefik_.*" action: keep ``` This keeps every `traefik_*` series and drops the Go-runtime and process families. #### Environment Variables ```bash showLineNumbers title=".env" TRAEFIK_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped Traefik metrics docker logs otel-collector 2>&1 | grep -i "traefik" # Verify the metrics endpoint directly curl -s http://localhost:8082/metrics \ | grep traefik_entrypoint_requests_total # Generate edge traffic so the request families materialize curl -s http://localhost/ > /dev/null ``` ### Troubleshooting #### Metrics endpoint returns 404 **Cause**: The Prometheus metrics entrypoint is not configured. **Fix**: 1. Verify `--metrics.prometheus=true` and `--metrics.prometheus.entryPoint=metrics` are set in the Traefik static configuration. 2. Confirm the metrics entrypoint is defined: `--entryPoints.metrics.address=:8082`. 3. Restart Traefik - the metrics entrypoint is static configuration and a change requires a restart. #### Only Go-runtime metrics appear, no traefik_ metrics **Cause**: No traffic has passed through Traefik yet. The request families only appear after at least one request is processed. **Fix**: 1. Send a test request through Traefik: `curl http://localhost/`. 2. Verify at least one router and service are configured - check the Traefik dashboard or API. 3. After traffic flows, `traefik_entrypoint_requests_total` and the per-entrypoint families appear. #### Per-router metrics are missing **Cause**: On Traefik v3 the per-router breakdown is off by default - `addRoutersLabels` defaults to `false`. (Per-entrypoint and per-service metrics are on by default.) **Look at**: whether `traefik_router_requests_total` appears in `curl -s http://localhost:8082/metrics`. **Fix**: 1. Enable `--metrics.prometheus.addRoutersLabels=true` (or the `addRoutersLabels` key in the static file), then restart Traefik. 2. On the Collector side, the `traefik_.*` keep filter scopes shipping to the `traefik_` namespace; it does not change which families Traefik emits. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Traefik running in Kubernetes? Yes. Set `targets` to the Traefik pod or service DNS (e.g., `traefik.traefik.svc.cluster.local:8082`). With the Traefik Helm chart, set `metrics.prometheus.entryPoint` (and the label options) in `values.yaml`. The Collector can run as a sidecar or DaemonSet. #### How do I monitor multiple Traefik instances? Add all Traefik metrics endpoints to the scrape config: ```yaml showLineNumbers title="config/otel-collector.yaml (cluster)" receivers: prometheus: config: scrape_configs: - job_name: traefik static_configs: - targets: - traefik-1:8082 - traefik-2:8082 ``` Each instance is scraped independently and identified by its `instance` label. #### What is the difference between entrypoint, router, and service metrics? The same request is counted at three scopes. Entrypoint metrics count all traffic arriving at a port (including traffic that matched no router). Router metrics break it down by routing rule after rule matching (e.g. `Host(example.com)`). Service metrics track traffic reaching each backend. Entrypoint counts are therefore greater than or equal to router and service counts; the gap is unrouted traffic such as edge 404s. #### Why use a separate metrics entrypoint? Serving metrics on the same port as production traffic exposes them on your public entrypoints. A dedicated metrics entrypoint on a separate port (e.g. 8082) lets you restrict access with firewall rules while keeping production entrypoints clean. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Traefik metrics. - [NGINX Monitoring](./nginx.md) - Reverse proxy and web-server request metrics. - [HAProxy Monitoring](./haproxy.md) - Load-balancer frontend and backend health. - [Envoy Monitoring](./envoy.md) - Service-proxy listener and upstream metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [NGINX](./nginx.md), [HAProxy](./haproxy.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your traffic and retention needs, and use the `traefik_.*` keep filter to scope shipping to the Traefik namespace. --- ## Varnish OpenTelemetry Monitoring - Cache Hit Ratio, Backend Health, and Collector Setup ## Varnish The OpenTelemetry Collector scrapes a `prometheus_varnish_exporter` sidecar to collect 190+ Varnish metrics - cache hit/miss ratios, backend health, thread-pool saturation, and storage usage - from Varnish 6.0+. Varnish keeps statistics in shared memory (VSM) with no HTTP endpoint, so the exporter is required to expose them in Prometheus format on port 9131. This guide configures the exporter and receiver and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | --------------------------- | ------- | ----------- | | Varnish | 6.0 | 9.0 | | prometheus_varnish_exporter | 1.6 | 1.6.1 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Varnish must be running with a configured backend. - The exporter needs read access to Varnish shared memory (VSM). In Docker this means sharing a volume at `/var/lib/varnish`. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). :::warning Upgrading? Bumping the Varnish image also requires rebuilding the exporter from a matching `varnish:` base. The exporter's bundled `varnishstat` must match the server's major version, or the `varnish_version` metric mislabels the server and a cross-major VSM read is unsupported. Full notes: [Updates & Upgrades](#updates--upgrades). ::: ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `varnish_up` | Scrape succeeded - monitoring itself is alive. | | `varnish_main_uptime`, `varnish_mgt_uptime` | Child and manager uptime; a reset flags a child restart or panic. | | `varnish_main_client_req` | Request throughput. | | `varnish_main_cache_hit`, `varnish_main_cache_miss` | The hit ratio `hit / (hit + miss)` - the primary efficiency KPI. | | `varnish_backend_up`, `varnish_backend_happy` | Origin reachability and health-probe state. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Client errors | `varnish_main_client_req_400`, `_client_req_417`, `_client_resp_500`, `_req_dropped`, `_req_reset`, `varnish_main_sc_*` | Error and abuse rate; dropped or reset requests. | | Origin health | `varnish_backend_fail` (+ `_econnrefused` / `_etimedout` / ...), `varnish_backend_busy`, `varnish_main_backend_retry` / `_reuse` / `_wait_fail` | Origin failures by cause; connection-pool strain. | | Connections | `varnish_main_sessions`, `varnish_main_sessions_total` | Accepted-connection load; a fall or stall signals accept-queue or fd saturation. | | Thread saturation | `varnish_main_threads`, `_threads_failed`, `_threads_limited`, `varnish_main_thread_queue_len`, `varnish_main_ws_*_overflow` | Worker-pool backlog; a queue above zero means requests are waiting. | | Cache pressure | `varnish_sma_g_bytes`, `varnish_sma_g_space`, `varnish_sma_c_fail`, `varnish_main_n_lru_nuked`, `_n_lru_limited`, `varnish_main_cache_hitpass` | Storage fill and evictions; cacheability problems. | | Bandwidth | `varnish_main_s_resp_bodybytes`, `_s_req_bodybytes`, `varnish_backend_beresp_bodybytes` | Traffic volume served and fetched. | Request latency is not in this set - `varnishstat` exposes counters and gauges only. Per-request timing lives in the Varnish log (VSL) / access logs or your trace path, not in these metrics. #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Metrics | When you reach for it | |---|---|---| | Memory pools | `varnish_mempool_*` (incl. native-TLS `ssl_buf*` pools) | Pool sizing and allocation churn. | | Lock contention | `varnish_lck_*`, `varnish_lock_*` | Contention at high concurrency. | | SHM log pressure | `varnish_main_shm_*` | High `shm_cycles` / `shm_cont` means log overrun starving `varnishlog`. | | Object accounting | `varnish_main_n_object`, `_n_objecthead`, `_n_objectcore`, `_n_superseded` | Cache composition. | | Invalidation | `varnish_main_bans_*` | Ban-lurker contention and persisted ban bytes. | | Workload internals | `varnish_main_esi_*`, `_n_gzip` / `_n_gunzip`, `varnish_backend_pipe_*`, `varnish_main_hcb_*` | ESI, compression, pipe, and hash internals. | | New since 7.6 (added 8.0) | `varnish_main_transit_buffered` / `_stored`, `varnish_main_http1_absolute_form`, `varnish_main_vcp_ref_hit` / `_miss` | Transit-buffer usage, HTTP/1 absolute-form requests, backend connection-pool reuse. | Full metric list: [prometheus_varnish_exporter](https://github.com/jonnenauha/prometheus_varnish_exporter), or run `curl -s http://localhost:9131/metrics` against the exporter. ### Key Alerts to Configure Threshold guidance for the most useful Operational-tier series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `cache_hit / (cache_hit + cache_miss)` | < 0.80 | < 0.50 | A falling hit ratio shifts load to origin; check TTLs, `Vary`, and `cache_hitpass`. | | `varnish_backend_up` (per backend) | Any backend down | All backends down | Origin unreachable; inspect the `backend_fail` cause breakdown and origin health. | | `rate(varnish_backend_fail)` | > 0 sustained | Rising across scrapes | Backend connection failures; check `_econnrefused` / `_etimedout` and origin capacity. | | `varnish_main_thread_queue_len` | > 0 sustained | Growing | Requests waiting on workers; raise `thread_pool_max` or shed load. | | `varnish_main_threads_limited` | > 0 | Sustained > 0 | The worker pool hit its ceiling; raise thread-pool limits. | | `varnish_sma_g_space` (free) | < 20% of total | < 5% of total | Storage is filling; evictions (`n_lru_nuked`) follow. Add storage or tune TTLs. | ### Access Setup Varnish does not expose Prometheus metrics natively. Run the `prometheus_varnish_exporter` as a sidecar that reads Varnish shared memory (VSM). **Docker setup** - build a custom exporter image (the project does not publish one) on a `varnish` base that matches your server, and share a volume at `/var/lib/varnish`: ```yaml showLineNumbers title="docker-compose.yaml (excerpt)" services: varnish: image: varnish:9.0 volumes: - varnish-data:/var/lib/varnish varnish-exporter: build: ./exporter volumes: - varnish-data:/var/lib/varnish:ro ports: - "9131:9131" depends_on: varnish: condition: service_healthy volumes: varnish-data: ``` The exporter Dockerfile builds the binary, then runs it on a `varnish:9.0` base so the bundled `varnishstat` matches the server: ```dockerfile showLineNumbers title="exporter/Dockerfile" FROM golang:1.22-bookworm AS builder ARG EXPORTER_VERSION=1.6.1 RUN git clone --depth 1 --branch ${EXPORTER_VERSION} \ https://github.com/jonnenauha/prometheus_varnish_exporter.git /src WORKDIR /src RUN CGO_ENABLED=0 go build -o /prometheus_varnish_exporter . FROM varnish:9.0 COPY --from=builder /prometheus_varnish_exporter /usr/local/bin/prometheus_varnish_exporter EXPOSE 9131 ENTRYPOINT ["prometheus_varnish_exporter"] ``` **Bare-metal setup** - install the exporter binary and run it on the same host as Varnish: ```bash showLineNumbers title="Install exporter" curl -LO https://github.com/jonnenauha/prometheus_varnish_exporter/releases/latest/download/prometheus_varnish_exporter-linux-amd64.tar.gz tar xzf prometheus_varnish_exporter-linux-amd64.tar.gz ./prometheus_varnish_exporter ``` Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # Check Varnish is running varnishadm status # Verify exporter metrics endpoint curl -s http://localhost:9131/metrics | head -20 ``` #### VCL Configuration Varnish needs a backend to serve traffic. A minimal `vcl 4.1` config (valid since Varnish 6.0, unchanged on 9.0): ```text showLineNumbers title="config/default.vcl" vcl 4.1; backend default { .host = "backend"; # Your backend hostname or IP .port = "80"; } ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: varnish scrape_interval: 30s static_configs: - targets: - ${env:VARNISH_EXPORTER_HOST}:9131 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" VARNISH_EXPORTER_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped Varnish metrics docker logs otel-collector 2>&1 | grep -i "varnish" # Verify the exporter is serving metrics curl -s http://localhost:9131/metrics | grep varnish_main # Generate cache traffic (first request misses, the rest hit) curl -s http://localhost:6081/ > /dev/null ``` ### Troubleshooting #### Exporter returns no Varnish metrics **Cause**: The exporter cannot read Varnish shared memory (VSM). **Fix**: 1. In Docker, verify both containers share the `/var/lib/varnish` volume. The Varnish container needs `:rw`, the exporter can use `:ro`. 2. On bare metal, verify the exporter process has read access to `/var/lib/varnish`. 3. Check the exporter logs for VSM access errors. #### `varnish_version` reports the wrong version after an upgrade **Cause**: The exporter image was built on an older `varnish` base than the running server, so its bundled `varnishstat` mislabels the server. **Look at**: `varnish_version` - the reported version is the exporter's binary, not the server. **Fix**: Rebuild the exporter from a `varnish:` base that matches the server's major version (see [Updates & Upgrades](#updates--upgrades)), then redeploy. #### Requests are slow or piling up **Cause**: The worker pool is saturated, or the origin is slow. **Look at**: `varnish_main_thread_queue_len` (requests waiting) and `varnish_main_threads_limited` (pool hit its ceiling); on the origin side, `varnish_backend_busy` and the `varnish_backend_fail` breakdown. **Fix**: 1. Raise `thread_pool_max` or add Varnish capacity if the queue is sustained. 2. Investigate origin latency and capacity if backend metrics climb. #### `varnishlog` drops records or CPU spikes at high concurrency **Cause**: Shared-memory log overrun or lock contention under load. **Look at**: the Diagnostic `varnish_main_shm_*` series - rising `shm_cycles` / `shm_cont` means the SHM log is cycling faster than `varnishlog` can drain it. `varnish_lck_*` / `varnish_lock_*` surface lock contention that shows up as CPU at high concurrency. **Fix**: 1. Reduce VSL consumers or raise the VSL buffer if `shm_*` climbs. 2. Profile the lock classes in `varnish_lck_*` if contention persists. #### Cache hit metrics showing zero **Cause**: No traffic has passed through Varnish. **Fix**: 1. Send requests through Varnish: `curl http://localhost:6081/`. 2. Cache hit metrics only populate after Varnish processes requests. 3. The first request is always a miss - repeat to see hits. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### Updates & Upgrades #### Varnish version changes - **7.6 → 9.0**: +37 counters, none removed or renamed - the upgrade is purely additive for coverage, and the whitelist-free exporter surfaces the new counters automatically. New named counters (added in Varnish 8.0): `transit_stored` / `transit_buffered` (uncacheable-body bytes and transit-buffer usage), `VCP.ref_hit` / `ref_miss` (backend connection-pool reuse), and `http1_absolute_form` (HTTP/1 absolute-form request targets). Native-TLS memory pools (`ssl_buf*`) and new lock classes surface as new label values on existing `varnish_mempool_*` and `varnish_lck_*` series. **You must rebuild the exporter from a matching `varnish:` base** - its bundled `varnishstat` must match the server's major version, or `varnish_version` mislabels the server. _(additive; exporter rebuild required)_ #### Collector / receiver changes - This guide uses the **prometheus receiver**, which has no receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. Pin both the exporter and Collector image tags; an exporter built on a stale `varnish` base mislabels `varnish_version` even when counters still read. _(no breaking change on the Prometheus path)_ ### FAQ #### Why do I need a separate exporter? Varnish stores statistics in shared memory (VSM), not over HTTP. The `prometheus_varnish_exporter` reads VSM counters and translates them to Prometheus format. Varnish has no built-in Prometheus or OpenTelemetry endpoint. #### Does this work in Kubernetes? Yes. Run the exporter as a sidecar container in the same pod as Varnish, sharing an `emptyDir` volume at `/var/lib/varnish`. The Collector scrapes the exporter sidecar. #### How do I monitor multiple Varnish instances? Deploy an exporter sidecar per Varnish instance, each on a different port, and add all of them to the scrape targets: ```yaml showLineNumbers title="config/otel-collector.yaml (multi-instance)" receivers: prometheus: config: scrape_configs: - job_name: varnish static_configs: - targets: - varnish-exporter-1:9131 - varnish-exporter-2:9131 ``` Each instance is identified by its `instance` label. #### What does `varnish_main_cache_hit` vs `varnish_main_cache_hitpass` mean? `cache_hit` is a normal cache hit - the response was served from cache. `cache_hitpass` means Varnish remembered that a previous request for this object was uncacheable, so it passed directly to the backend without a cache lookup. Monitor `cache_hit / (cache_hit + cache_miss)` for overall efficiency. #### Why is request latency missing from the metrics? `varnishstat` exposes counters and gauges only, so per-request timing is not in this metric surface. It lives in the Varnish log (VSL) / access logs or your trace path. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Varnish metrics. - [NGINX Monitoring](./nginx.md) - A common companion web server. - [Caddy Monitoring](./caddy.md) - A common companion web server. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [NGINX](./nginx.md), [Caddy](./caddy.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your traffic and retention needs. --- ## Vault OpenTelemetry Monitoring - Seal State, Token Lifecycle, and Collector Setup ## Vault Vault serves Prometheus-format metrics at `/v1/sys/metrics?format=prometheus` on the API port `8200`. Vault retains Prometheus metrics by default, and the endpoint is token-gated, so the OpenTelemetry Collector's `prometheus` receiver scrapes it with a Bearer token, collecting 65+ metrics across core leadership and seal state, token and auth operations, storage barrier performance, lease management, and Go runtime. This guide enables the endpoint, configures the receiver, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Vault | 1.1 | 1.18 | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - Vault's HTTP API port (`8200`) must be reachable from the host running the Collector. - Vault retains Prometheus metrics by default (`prometheus_retention_time` defaults to `24h`); setting it to `0` disables them. - A Vault token with `read` capability on `sys/metrics` (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. A few things shape how you read this surface: - **`up` is the liveness signal, and it catches the sealed state.** A *sealed* Vault cannot read storage to build metrics, so `/v1/sys/metrics` returns HTTP `503` - the scrape fails and `up` drops to `0` (and `vault_core_unsealed` stops being scraped at the same time). So `up == 0` means Vault is down, sealed, or unreachable; for an authoritative sealed-vs-down split, check the unauthenticated `/v1/sys/seal-status` endpoint, which is outside the metrics pipeline. `vault_core_unsealed` reads `1` in normal operation as the in-band confirmation the node is unsealed. - **The scrape needs a Vault token with `read` on `sys/metrics`**, and the endpoint is only reachable from the root namespace. - **Only the active (leader) node serves metrics.** `vault_core_active` (`1` = leader) identifies it - point the Collector at the active node. - **Three leadership metrics use a bare `core_*` prefix before Vault 1.20.** `core_leadership_lost`, `core_leadership_setup_failed`, and `core_step_down` are emitted without the `vault_` prefix on Vault releases earlier than 1.20; Vault 1.20+ renamed them to the `vault_core_*` form. A keep filter matching `vault_.*|core_.*` retains them on either version. #### Core - is it up, unsealed, and serving | Metric | What it tells you | |---|---| | `up` | Scrape liveness - `1` = the metrics endpoint responded (Vault up and unsealed). A sealed Vault returns `503`, so `up` drops to `0` when sealed, down, or unreachable. | | `vault_core_unsealed` | `1` = this node is unsealed and serving. A sealed node returns `503` on the metrics endpoint, so this series stops being scraped while sealed - read it as the in-band unsealed confirmation, and use `up == 0` to catch the sealed/down state. | | `vault_core_active` | `1` = this node is the active (leader) node in an HA cluster. | | `vault_core_handle_request` | Latency and count of all requests Vault handled - headline throughput and latency. | | `vault_expire_num_leases` | Number of active leases - a runaway count is a classic Vault incident (memory / storage pressure). | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Auth path | `vault_core_handle_login_request` | Login-request latency and count - auth load distinct from general requests. | | Leadership | `core_leadership_lost`, `core_step_down`, `core_leadership_setup_failed` | HA leadership transitions; repeated events mean leader instability. (Bare `core_*` before Vault 1.20; `vault_core_*` from 1.20.) | | Seal lifecycle | `vault_core_pre_seal`, `vault_core_post_unseal` | Seal / unseal step timing. | | Leases | `vault_expire_num_irrevocable_leases`, `vault_expire_revoke`, `vault_expire_register_auth` | Leases Vault failed to revoke (non-zero needs investigation) and expiration-manager churn. | | Tokens | `vault_token_create`, `vault_token_lookup`, `vault_token_revoke_tree`, `vault_token_store` | Token lifecycle volume and latency. | | Seal crypto | `vault_seal_encrypt`, `vault_seal_encrypt_time`, `vault_seal_decrypt`, `vault_seal_decrypt_time` | Seal-wrap crypto count and latency - auto-unseal / HSM / KMS round-trip cost. | | Storage barrier | `vault_barrier_get`, `vault_barrier_put`, `vault_barrier_delete`, `vault_barrier_list`, `vault_barrier_estimated_encryptions` | Encrypted storage-barrier operation latency and encryption count - Vault's throughput is bounded by the backend. | | Cache | `vault_cache_hit`, `vault_cache_miss`, `vault_cache_write` | Physical-cache effectiveness in front of the storage backend. | | Policy | `vault_policy_get_policy` | Policy fetch / evaluation latency. | | Runtime | `vault_runtime_alloc_bytes`, `vault_runtime_num_goroutines`, `vault_runtime_gc_pause_ns`, `vault_runtime_heap_objects` | Vault process Go-runtime memory, goroutines, and GC pressure. | Enterprise replication and performance-standby flags (`vault_core_replication_performance_primary` / `_secondary`, `vault_core_performance_standby`) read `0` on OSS and populate on Vault Enterprise. #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or a capacity review. | Group | Representative metrics | When you reach for it | |---|---|---| | Per-mount routing | `vault_route_read_secret_`, `vault_route_update_transit_`, `vault_route_read_auth_token_` | Per-mount request routing latency. The family carries the mount path, so it grows per engine. | | Lease accounting | `vault_expire_fetch_lease_times`, `vault_expire_fetch_lease_times_by_token` | Lease-time accounting internals. | | Core internals | `vault_core_mount`, `vault_core_unseal`, `vault_core_fetch` | Internal core-operation timings. | | Runtime / process meta | `go_*`, `process_*` | Go-runtime and process series the endpoint also exposes. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_series_added` | Prometheus scrape meta - receiver-side, not from Vault. | Full metric list: run `curl -s -H "X-Vault-Token: $VAULT_TOKEN" 'http://localhost:8200/v1/sys/metrics?format=prometheus'` against your Vault instance. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. The state checks (`== 0`) are exact; the rest are relative to your own baseline. These are starting points - tune them to your workload. | Metric | Condition | Why it matters | |---|---|---| | `up` | `== 0` for > 1m | The metrics endpoint stopped responding - Vault is **down or sealed** (a sealed Vault returns `503`). Check the process, the API port, and `vault status` / the `/v1/sys/seal-status` endpoint. The most urgent Vault alert. | | `vault_core_active` | `== 0` across all nodes | The HA cluster has no leader; clients cannot write. Check the cluster and storage backend. | | `core_leadership_lost` / `core_step_down` | Rising (rate > 0) | Leadership is changing repeatedly - unstable HA. Check storage latency and networking. | | `vault_core_handle_request` | Rising vs baseline | Request handling is slowing - correlate with storage barrier latency and load. | | `vault_expire_num_leases` | Rising sharply vs baseline | Runaway lease creation exhausts memory / storage - find the source and shorten TTLs. | | `vault_expire_num_irrevocable_leases` | `> 0` | Vault could not revoke leases - investigate the backend and force-revoke. | | `vault_barrier_put` / `vault_barrier_get` | Rising vs baseline | The storage backend is slow - Vault throughput is bounded by it. | | `vault_seal_encrypt_time` / `vault_seal_decrypt_time` | Rising vs baseline | Auto-unseal KMS / HSM round-trips are slow - check the seal provider. | | `vault_runtime_alloc_bytes` / `vault_runtime_num_goroutines` | Rising vs baseline | Sustained pressure or a leak - correlate with lease count and request volume. | ### Access Setup Vault retains Prometheus metrics by default, so the endpoint works out of the box. The optional `telemetry` block below tunes retention and cleans up metric labels: ```hcl showLineNumbers title="vault-config.hcl" telemetry { prometheus_retention_time = "60s" disable_hostname = true } ``` - `prometheus_retention_time` defaults to `24h`; lower it (e.g. `60s`) to reduce in-memory retention, or set `0` to disable Prometheus metrics. Keep it at least 2x the scrape interval. - `disable_hostname` strips hostname prefixes from metric names for cleaner Prometheus labels. The endpoint is ACL-protected. Create a policy that grants `read` on `sys/metrics` and mint a token for the Collector: ```bash showLineNumbers title="Create the monitoring token" # Create a read-only monitoring policy vault policy write otel-monitor - <.base14.io ``` #### TLS For Vault clusters with TLS on the API listener, scrape over `https` and supply the CA: ```yaml showLineNumbers title="config/otel-collector.yaml (TLS)" receivers: prometheus: config: scrape_configs: - job_name: vault scheme: https metrics_path: /v1/sys/metrics params: format: [prometheus] authorization: type: Bearer credentials: ${env:VAULT_TOKEN} tls_config: ca_file: /certs/vault-ca.pem static_configs: - targets: - ${env:VAULT_HOST}:8200 ``` #### Scope to the Vault namespace The metrics endpoint also exposes the endpoint's own `go_*` / `process_*` runtime series and the prometheus `scrape_*` meta. To keep only Vault's metrics, add a keep filter. Match `core_.*` as well as `vault_.*` so the bare-`core_*` leadership metrics on Vault < 1.20 are retained (Vault 1.20+ emits them as `vault_core_*`, which `vault_.*` already covers): ```yaml showLineNumbers title="config/otel-collector.yaml (keep filter)" receivers: prometheus: config: scrape_configs: - job_name: vault scrape_interval: 30s metrics_path: /v1/sys/metrics params: format: [prometheus] authorization: type: Bearer credentials: ${env:VAULT_TOKEN} static_configs: - targets: - ${env:VAULT_HOST}:8200 metric_relabel_configs: - source_labels: [__name__] regex: "vault_.*|core_.*" action: keep ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for a successful Vault scrape docker logs otel-collector 2>&1 | grep -i "vault" # Confirm Vault is unsealed and active vault status # Check the metrics endpoint directly for the leader flag curl -s -H "X-Vault-Token: $VAULT_TOKEN" \ 'http://localhost:8200/v1/sys/metrics?format=prometheus' \ | grep vault_core_active ``` ### Troubleshooting #### Metrics endpoint returns 403 or permission denied **Cause**: The Vault token lacks `read` on `sys/metrics`, or the request is not against the root namespace. **Fix**: 1. Confirm the token policy includes `path "sys/metrics" { capabilities = ["read"] }`. 2. Check the token is valid: `vault token lookup $VAULT_TOKEN`. 3. Make the request against the root namespace - the metrics endpoint is only accessible there. #### Metrics endpoint returns JSON, empty, or 503 **Cause**: the request omitted `?format=prometheus` (Vault returns JSON telemetry), `prometheus_retention_time` was set to `0` (Prometheus metrics disabled), or Vault is sealed (a sealed Vault returns `503`). **Fix**: 1. Include `?format=prometheus` in the scrape path. 2. Confirm `prometheus_retention_time` is non-zero - it defaults to `24h`; only an explicit `0` disables it. 3. Check Vault is unsealed: `vault status`. A sealed Vault returns `503` until unsealed. #### Standby node returns no metrics **Cause**: The `/v1/sys/metrics` endpoint is only active on the leader. **Look at**: `vault_core_active` - `1` identifies the leader. **Fix**: 1. Point the Collector at the active node, or at a load balancer that routes to it. 2. Use `vault_core_active` to find which node is leading. 3. On Vault Enterprise, standby nodes can serve their own metrics when unauthenticated metrics access is enabled. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### FAQ #### Does this work with Vault running in Kubernetes? Yes. Set `targets` to the active-service DNS (e.g., `vault-active.vault.svc.cluster.local:8200`) so the scrape always hits the leader, and inject `VAULT_TOKEN` from a Kubernetes secret. The Collector can run as a sidecar or a Deployment. #### How do I monitor a Vault HA cluster? Only the active node serves metrics at `/v1/sys/metrics`, so point the Collector at the active service endpoint and use `vault_core_active` (`1` = leader) to confirm which node it is. For Vault Enterprise with performance standbys, each standby can optionally expose its own metrics. #### Why do additional metrics appear after enabling secrets engines? Vault generates metrics dynamically per active secrets engine, auth method, and audit device. A production instance with multiple backends emits more series - notably the per-mount `vault_route_*` family, which carries the mount path - than a fresh dev server. #### What does `vault_barrier_estimated_encryptions` indicate? It tracks the estimated number of barrier encryption operations since the last rekey. Watch it for compliance requirements that mandate periodic rekeying after a threshold of encryption operations. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Vault metrics. - [Consul Monitoring](./consul.md) - The storage backend and service mesh that often sits behind Vault. - [Nomad Monitoring](./nomad.md) - The workload scheduler that fetches secrets from Vault. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Consul](./consul.md), [Nomad](./nomad.md), and other components. - **Fine-tune Collection**: Apply the `vault_.*|core_.*` keep filter to scope the scrape to Vault, and tune `scrape_interval` to your retention and alerting needs. --- ## vLLM OpenTelemetry Monitoring - KV-Cache Usage, Request Queueing, and Collector Setup ## vLLM vLLM's OpenAI-compatible server serves Prometheus text at `/metrics` on its API port (`8000`). The OpenTelemetry Collector scrapes it with the Prometheus receiver, collecting 90+ metrics across scheduler state (running, waiting, KV-cache usage, preemptions), request latency phases (queue, prefill, decode, time to first token, inter-token), token throughput, prefix-cache hit rate, the HTTP layer, and process resources, on vLLM 0.28+. This guide configures the receiver, runs vLLM with the shared memory it needs, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | vLLM | 0.8 | 0.28 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | vLLM 0.8 made the V1 engine the default; it emits the scheduler and latency phase metrics in this guide. Before starting: - The API port (`8000`) must be reachable from the host running the Collector. `/metrics` is served there, always on, with no flag to enable it. - `/metrics` has no authentication. If the API port is fronted by a reverse proxy with an API key, scrape vLLM directly on the internal network or exempt the `/metrics` path. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The metric prefix is `vllm:`, with a colon. Prometheus accepts colons in metric names, the Prometheus receiver passes them through unchanged, and Scout stores them as-is. Query the names verbatim. Every `vllm:` series carries `model_name` and `engine` labels. `vllm:request_success_total` adds `finished_reason` (`stop`, `length`, `abort`, `error`, `repetition`); `vllm:num_requests_waiting_by_reason` adds `reason` (`capacity`, `deferred`). #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Scrape succeeded - the vLLM metrics endpoint responded. | | `vllm:num_requests_running` | Requests in model execution batches. Headline concurrency. | | `vllm:num_requests_waiting` | Requests waiting to be scheduled. Saturation signal. | | `vllm:kv_cache_usage_perc` | KV-cache usage as a fraction, 0 to 1 despite the name; 1 = full. The capacity signal that precedes preemption and queueing. | | `vllm:request_success_total` | Finished requests by `finished_reason`. Throughput and the error and abort rate. | | `vllm:e2e_request_latency_seconds` | End-to-end request latency. The request SLO. | | `vllm:time_to_first_token_seconds` | Time to first token. The user-perceived responsiveness SLO. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `vllm:inter_token_latency_seconds` | Latency between consecutive output tokens. Streaming smoothness. | | `vllm:request_queue_time_seconds` | Time spent waiting before scheduling. Rising queue time means capacity, not model speed. | | `vllm:request_time_per_output_token_seconds` | Per-request mean time per output token. | | `vllm:prompt_tokens_total` | Prefill tokens processed. Input token throughput and cost driver. | | `vllm:generation_tokens_total` | Generation tokens processed. Output token throughput and cost driver. | | `vllm:num_preemptions_total` | Requests preempted by the engine, normally for KV-cache pressure. Any sustained rate is a capacity problem. | | `vllm:num_requests_waiting_by_reason` | Waiting requests split by `reason` (`capacity`, `deferred`). Sums to `num_requests_waiting`. | | `vllm:prefix_cache_queries_total` | Tokens queried against the prefix cache. Denominator of the hit rate. | | `vllm:prefix_cache_hits_total` | Tokens served from the prefix cache. Numerator of the hit rate; a direct compute saver for shared system prompts. | | `vllm:engine_sleep_state` | Engine sleep level by `sleep_state`; `awake` = 1 means serving. | | `http_requests_total` | API requests by `handler`, `method`, `status` class. The HTTP-level error rate, including 4xx before the engine. | | `http_request_duration_seconds` | API request duration by handler. | | `process_resident_memory_bytes` | Server process RSS. Model weights plus KV cache on the CPU backend. | | `process_cpu_seconds_total` | Server process CPU time. | Three latency phases are exposed per request: queue time (`vllm:request_queue_time_seconds`), prefill (`vllm:request_prefill_time_seconds`) and decode (`vllm:request_decode_time_seconds`). `vllm:request_inference_time_seconds` covers prefill plus decode, and `vllm:e2e_request_latency_seconds` covers all three. Time to first token and inter-token latency are the user-facing pair; the phase histograms are how you localize which one moved. #### Diagnostic - for investigation and tuning Higher cardinality or per-request distributions. | Group | Metrics | When you reach for it | |---|---|---| | Latency phases | `vllm:request_prefill_time_seconds`, `vllm:request_decode_time_seconds`, `vllm:request_inference_time_seconds` | Splitting an end-to-end latency regression into prefill, decode, or prefill plus decode. | | Request size | `vllm:request_prompt_tokens`, `vllm:request_generation_tokens`, `vllm:request_max_num_generation_tokens`, `vllm:request_prefill_kv_computed_tokens` | Input and output size distribution; new KV tokens computed per prefill, excluding cached tokens. | | Request parameters | `vllm:request_params_max_tokens`, `vllm:request_params_n` | The `max_tokens` and `n` parameters clients send. | | Batch efficiency | `vllm:iteration_tokens_total` | Tokens per engine step. | | Cache detail | `vllm:prompt_tokens_by_source_total`, `vllm:prompt_tokens_cached_total`, `vllm:external_prefix_cache_queries_total`, `vllm:external_prefix_cache_hits_total`, `vllm:mm_cache_queries_total`, `vllm:mm_cache_hits_total` | Prompt tokens by `source`; prefix cache across a KV connector (cross-instance sharing); multi-modal cache. | | MFU estimates | `vllm:estimated_flops_per_gpu_total`, `vllm:estimated_read_bytes_per_gpu_total`, `vllm:estimated_write_bytes_per_gpu_total` | Model FLOPs Utilization inputs. Read 0 on the CPU backend. | | Cache config | `vllm:cache_config_info` | Info gauge (value 1) whose labels carry `block_size`, `num_gpu_blocks`, `kv_cache_size_tokens`, `kv_cache_memory_bytes`, `enable_prefix_caching`, `gpu_memory_utilization`, `kv_cache_max_concurrency`. | | HTTP sizes | `http_request_size_bytes`, `http_response_size_bytes`, `http_request_duration_highr_seconds` | Body sizes; high-resolution duration with no `handler` label. | | Process | `process_open_fds`, `process_max_fds`, `process_virtual_memory_bytes`, `process_start_time_seconds` | File descriptors, virtual memory, start time. | | Python | `python_gc_collections_total`, `python_gc_objects_collected_total`, `python_gc_objects_uncollectable_total`, `python_info` | Interpreter GC and version. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Prometheus receiver scrape health. | | `*_created` | 26 `vllm:` and 5 `http_` gauges | Series creation timestamps. No operational meaning; optional to drop. | Several families read zero until the workload exercises them: `vllm:external_prefix_cache_*` need a KV connector, `vllm:mm_cache_*` need a multi-modal model, `vllm:prompt_tokens_cached_total` follows prefix hits, and the `vllm:estimated_*_per_gpu_total` estimates stay 0 on the CPU backend. Full metric list: see the [vLLM metrics reference](https://docs.vllm.ai/en/latest/design/metrics.html), or run `curl -s http://localhost:8000/metrics` against your vLLM instance. ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. Absolute latency numbers depend on the model, hardware, and prompt shape, so the latency rows are relative to your own baseline. Tune to your workload; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `up` | - | `== 0` for > 1m | The metrics endpoint stopped responding; check the container and port 8000. | | `vllm:kv_cache_usage_perc` | `> 0.9` sustained | `> 0.9` with preemptions | Preemption and queueing follow; add replicas, lower `max_model_len`, or raise the cache budget. | | `vllm:num_requests_waiting` | `> 0` sustained | Growing | Capacity, not model speed; scale out or shed load. Check `num_requests_waiting_by_reason` for `capacity` vs `deferred`. | | `vllm:request_queue_time_seconds` (p99) | Rising vs baseline | Sustained rise | Requests wait before scheduling; same capacity remedy. | | `rate(vllm:num_preemptions_total)` | `> 0` | Sustained | The engine is evicting requests for cache space; correlate with KV-cache usage. | | `rate(vllm:request_success_total{finished_reason=~"error\|abort"})` | `> 0` vs baseline | Rising | Requests are failing or clients are disconnecting; inspect the API logs and client timeouts. | | `vllm:time_to_first_token_seconds` (p99) | Rising vs baseline | Sustained rise | Prefill or queueing is slow; check queue time first, then prompt length distribution. | | `vllm:e2e_request_latency_seconds` (p99) | Rising vs baseline | Sustained rise | Split via the phase histograms: queue, prefill, decode. | | `vllm:inter_token_latency_seconds` (p99) | Rising vs baseline | Sustained rise | Decode is slow; batch too large for the hardware or memory-bandwidth bound. | | `rate(vllm:prefix_cache_hits_total) / rate(vllm:prefix_cache_queries_total)` | Below baseline | - | Shared system prompts are not being reused; check `enable_prefix_caching` and block alignment. | | `rate(http_requests_total{status="5xx"})` | `> 0` | Sustained | The API layer is failing before or after the engine; check server logs. | | `vllm:engine_sleep_state{sleep_state="awake"}` | - | `== 0` | The engine was put to sleep and is not serving; wake it or check the orchestrator. | The latency rows are Prometheus histograms - there is no ready-made `p99` series to threshold. Compute the percentile from the buckets in your alert rule, for example `histogram_quantile(0.99, rate(vllm:time_to_first_token_seconds_bucket[5m]))`. ### Access Setup vLLM exposes `/metrics` on the API port with no flag to enable it and no credentials. Access setup is about running the server so the engine starts, and confirming the endpoint answers. The engine core creates a multiprocess message queue in `/dev/shm` at startup. Docker's default 64 MB `/dev/shm` is too small and the engine core fails before serving. Set `shm_size: "2g"` and `ipc: host` on the service. **Docker setup** - the GPU image `vllm/vllm-openai`, with the model as a positional argument to `vllm serve` (the `--model` flag is deprecated): ```yaml showLineNumbers title="compose.yaml (excerpt)" services: vllm: image: vllm/vllm-openai:latest command: - your-org/your-model # positional model; --model is deprecated - --max-model-len - "4096" gpus: all shm_size: "2g" ipc: host volumes: - ~/.cache/huggingface:/root/.cache/huggingface ports: - "8000:8000" ``` For hosts without a GPU, use the CPU image `vllm/vllm-openai-cpu`. The same `shm_size` and `ipc` settings apply, and `VLLM_CPU_KVCACHE_SPACE` sets the KV-cache size in GiB: ```yaml showLineNumbers title="compose.yaml (CPU excerpt)" services: vllm: image: vllm/vllm-openai-cpu:latest command: - your-org/your-model - --max-model-len - "512" environment: VLLM_CPU_KVCACHE_SPACE: "2" # KV cache in GiB shm_size: "2g" ipc: host ports: - "8000:8000" ``` **Bare-metal setup** - install vLLM into a virtualenv and start the server on the host. `/dev/shm` on a bare host is normally large enough; the shared-memory constraint is a container default. ```bash showLineNumbers title="Start vLLM" pip install vllm vllm serve your-org/your-model --max-model-len 4096 ``` Verify the endpoint is working: ```bash showLineNumbers title="Verify access" # The server lists the loaded model once the engine is up curl -s http://localhost:8000/v1/models # Verify the metrics endpoint curl -s http://localhost:8000/metrics | grep '^vllm:' | head -20 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: vllm scrape_interval: 10s static_configs: - targets: # host:port vLLM's API is reachable on - ${env:VLLM_HOST}:${env:VLLM_PORT} processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` The Prometheus receiver keeps everything `/metrics` exposes. There is no per-metric enable list; new series appear after a vLLM upgrade with no Collector change. Scout authentication for the `otlphttp/b14` exporter is covered in [Scout Exporter](../collector-setup/scout-exporter.md). #### Environment Variables ```bash showLineNumbers title=".env" VLLM_HOST=localhost VLLM_PORT=8000 ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Controlling metric volume Every counter and histogram vLLM exposes has a `_created` companion gauge carrying the series start time. The receiver emits them as separate gauges - 26 `vllm:` and 5 `http_` - with no operational meaning. A drop rule on the scrape job removes them: ```yaml showLineNumbers title="config/otel-collector.yaml (filter)" metric_relabel_configs: - source_labels: [__name__] regex: ".*_created" action: drop ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check Collector logs for scraped vLLM metrics docker logs otel-collector 2>&1 | grep "vllm:" # Check the scheduler gauges directly on the metrics endpoint curl -s http://localhost:8000/metrics | grep -E '^vllm:num_requests_(running|waiting) ' # Generate traffic so the request counters and histograms advance curl -s http://localhost:8000/v1/completions \ -H 'Content-Type: application/json' \ -d '{"model": "your-org/your-model", "prompt": "Hello", "max_tokens": 32}' # Confirm a finished request was counted curl -s http://localhost:8000/metrics | grep '^vllm:request_success_total' ``` In Scout, query `vllm:num_requests_running` by `model_name` to confirm the series arrived with the colon-prefixed name intact. ### Troubleshooting #### Engine core fails at startup **Cause**: The engine core could not create its multiprocess message queue in `/dev/shm`. Docker's default 64 MB `/dev/shm` is too small. **Look at**: the container log at startup. The API port never opens, so `up` reads 0 and no `vllm:` series appear. **Fix**: 1. Set `shm_size: "2g"` and `ipc: host` on the vLLM service (see [Access Setup](#access-setup)). 2. On Kubernetes, mount an `emptyDir` with `medium: Memory` at `/dev/shm`. #### `/v1/chat/completions` returns 4xx **Cause**: The model has no chat template, so the chat endpoint rejects the request before it reaches the engine. Base models such as `facebook/opt-125m` ship without one. **Look at**: `http_requests_total{status="4xx"}` advancing by `handler` while `vllm:request_success_total` and the `vllm:` latency histograms do not move - the request failed in the API layer, not in the engine. **Fix**: 1. Use `/v1/completions` for base models. 2. For chat, serve an instruction-tuned model that ships a chat template, or pass one with `--chat-template`. #### `vllm:prefix_cache_hits_total` stays 0 **Cause**: Prefix-cache hits need prompts that share at least one full block; `block_size` is 128 tokens by default. Prompts shorter than one block, or that diverge before the first block boundary, never hit. **Look at**: `vllm:prefix_cache_queries_total` advancing while hits stay at 0. The Diagnostic `vllm:cache_config_info` labels show `block_size` and whether `enable_prefix_caching` is on. **Fix**: 1. Confirm `enable_prefix_caching` reads true in `cache_config_info`. 2. Front prompts with a shared system prompt of at least one full block. 3. Hits appear once prompts share a complete block; short one-off prompts do not. #### End-to-end latency is rising **Cause**: One of the three request phases has slowed, and the end-to-end histogram does not say which. **Look at**: `vllm:request_queue_time_seconds` first (Operational). If queue time is flat, the Diagnostic `vllm:request_prefill_time_seconds` and `vllm:request_decode_time_seconds` split the remainder. `vllm:request_prompt_tokens` and `vllm:request_generation_tokens` show whether request sizes changed at the same time. **Fix**: 1. Queue time up: capacity. Scale out, or check `vllm:kv_cache_usage_perc` and `vllm:num_preemptions_total`. 2. Prefill up: longer prompts, or prefix-cache reuse dropped. 3. Decode up: batch too large for the hardware, or memory-bandwidth bound; `vllm:iteration_tokens_total` shows tokens per step. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. 4. Query the name with the colon, `vllm:num_requests_running`, not `vllm_num_requests_running`. ### FAQ #### Does `/metrics` need a GPU? No. The endpoint is served by the API process on both the GPU image and the CPU image (`vllm/vllm-openai-cpu`). The metric surface is the same; the `vllm:estimated_*_per_gpu_total` estimates read 0 on the CPU backend. #### Why do the metric names contain colons? vLLM uses `vllm:` as its Prometheus namespace. Colons are valid in Prometheus metric names, the Prometheus receiver passes them through, and Scout stores them unchanged. Query `vllm:kv_cache_usage_perc`, not `vllm_kv_cache_usage_perc`. #### What is the `engine` label? The data-parallel engine index. A single-engine deployment has one value; with data parallelism each engine reports its own scheduler gauges, so sum or group by `engine` for the instance-wide picture. #### Is `vllm:kv_cache_usage_perc` a percentage? No. It is a fraction from 0 to 1 despite the name. Alert on `> 0.9`, not `> 90`. #### Does this work with vLLM running in Kubernetes? Yes. Set `targets` to the vLLM service DNS (for example `vllm.default.svc.cluster.local:8000`), or use `kubernetes_sd_configs` to discover pods. Mount a memory-backed `emptyDir` at `/dev/shm` so the engine core starts. #### Can vLLM emit traces as well? Yes. vLLM can send OTLP traces for each request with `--otlp-traces-endpoint`. This guide covers the metrics surface only. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on vLLM metrics. - [LiteLLM Gateway Monitoring](./litellm.md) - LLM gateway that commonly fronts vLLM; pair both for the gateway-to-backend view. - [LLM Observability](../../guides/ai-observability/llm-observability.md) - Application-side tracing of LLM calls, token usage and cost. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Redis](./redis.md), [NGINX](./nginx.md), and other components. - **Fine-tune Collection**: Drop the `_created` gauges with `metric_relabel_configs`, and use the `model_name` and `engine` labels to split dashboards per served model. --- ## Weaviate OpenTelemetry Monitoring - Request Latency, Vector Index Queue, and Collector Setup ## Weaviate Weaviate serves Prometheus text on port `2112` once `PROMETHEUS_MONITORING_ENABLED` is set. The endpoint is off by default, and without that variable the port is not served at all. The OpenTelemetry Collector's Prometheus receiver scrapes it, collecting 258 metric names covering request accounting across REST, GraphQL and gRPC, query and write latency, the vector index and its ingestion queue, and the LSM storage engine. Only 131 appear on an idle node; the rest arrive once traffic runs. This guide enables the endpoint, configures the receiver, wires the trace path, and ships both signals to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ----------- | | Weaviate | 1.39 | 1.39.2 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | The metric surface described below is the 1.39 line, and earlier lines differ enough that this guide does not carry over to them - see [Updates & Upgrades](#updates--upgrades). The trace path is gated behind variables named `EXPERIMENTAL_*` on 1.39, so treat those variable names as version-specific and re-check them on a minor upgrade. Before starting: - Weaviate must run with `PROMETHEUS_MONITORING_ENABLED=true`. The metrics endpoint is off by default. Without the variable, a scrape of port 2112 gets a connection refused, not an empty page. - The port is fixed at 2112 and cannot be changed. The config struct carries a port default of `8081`, but `PROMETHEUS_MONITORING_ENABLED` forces 2112 and the struct tag has no effect. - Port 2112 must be reachable from the host running the Collector, and is separate from `8080` (REST and GraphQL) and `50051` (the gRPC data API). - The metrics endpoint has no authentication. Scrape it on the internal network, or exempt the path at a fronting proxy; it must not be exposed publicly. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). :::warning Upgrading from a pre-1.39 line? The metric surface changed substantially. On 1.27 the endpoint serves 88 names rather than 258, three of the Core metrics below do not exist, and the async index queue is named `index_queue_*` rather than `queue_*`. Full notes: [Updates & Upgrades](#updates--upgrades). ::: ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or a capacity review. Two properties of this surface shape everything you build on it. There is no single metric prefix - 149 names carry `weaviate_` and 68 carry nothing at all - so names have to be namespaced at the Collector before they reach a shared backend. And the two client interfaces are counted by two different metrics that do not overlap, so a dashboard built on one of them under-reports a normal client. Both are handled in [Configuration](#configuration) and explained under Core below. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `up` | Whether the last scrape of port 2112 succeeded. Liveness. Added by the receiver, not by Weaviate. | | `requests_total` | REST and GraphQL requests by `api`, `class_name`, `query_type` and `status`. The only error rate for those two interfaces. | | `weaviate_grpc_server_request_duration_seconds` | Latency and errors for the gRPC data API by `grpc_service`, `method` and `status`. The only view of gRPC search. | | `weaviate_http_request_duration_seconds` | HTTP latency and status by `method`, `route` and `status_code`. No `class_name`, so it is the route-level view that survives a cardinality cap. | | `queries_durations_ms` | Query latency as the client experiences it, by `class_name` and `query_type`. | | `objects_durations_ms` | Write latency by `class_name`, `operation`, `shard_name` and `step`. | | `object_count` | Objects per `class_name` and `shard_name`. Dataset size, and the signal that an unexpected collection appeared. | | `vector_index_size` | Index growth per collection and shard, against the memory you have. | | `queue_size` | Async indexing backlog per collection and shard. | **Both request counters are in Core because neither alone covers a normal client.** `requests_total` counts REST and GraphQL only; there is no `api="grpc"` series at any point. gRPC traffic is counted solely by `weaviate_grpc_server_request_duration_seconds`. The official clients are hybrid: `weaviate-client` connected with `grpc_port=50051` sends searches over gRPC and inserts over REST, so a dashboard built on `requests_total` alone under-reports a Python or TypeScript client by the whole of its search volume. This is also why the alerts below carry two separate error-ratio rows. The two counters differ in what they can tell you about a failure: - gRPC error status is coarse. Searches against a collection that does not exist record `status="Unknown"`, not `NotFound`. The observed status values are `OK`, `Unknown` and `ResourceExhausted`. - The gRPC path carries no `class_name`, so gRPC failures cannot be attributed to a collection from metrics, and the auto-schema hazard described in [Configuration](#auto-schema-and-metric-cardinality) is a REST and GraphQL problem only. - `status` on `requests_total` has three values - `ok`, `user_error` and `server_error` - and the split is not a clean client/server split. A write with a vector of the wrong width, unambiguously a client mistake, returns HTTP 500 and records `server_error`. Do not read `user_error` as "client error". **`requests_total` is declared a gauge.** The exposition carries `# TYPE requests_total gauge` despite the `_total` suffix and monotonic values, so the Collector forwards it as a gauge and it arrives in Scout as a gauge. Check the panel type before writing a `rate()` query against it. Six other names share the mismatch: `concurrent_queries_count`, `lsm_segment_count`, `object_count`, `queue_count`, `weaviate_index_shards_total` and `weaviate_lsm_bucket_segment_total`. The last two are genuinely gauges; `requests_total` is not. #### Operational - what to alert on | Metric | What it tells you | |---|---| | `concurrent_queries_count` | Queries in flight by `class_name` and `query_type`. | | `queries_filtered_vector_durations_ms` | Filtered vector search latency by `class_name`, `operation` and `shard_name`. | | `vector_index_durations_ms` | Time spent inside the index, broken out by `step`. | | `vector_index_operations` | Index operations by `class_name`, `operation` and `shard_name`. | | `vector_index_queue_insert_count`, `vector_index_queue_delete_count` | Work entering and leaving the async index queue, by `target_vector`. | | `vector_index_tombstones`, `vector_index_tombstone_cleaned` | Deleted vectors awaiting cleanup, and cleanup progress. Read them together. | | `queue_partition_processing_duration_ms` | How long a queue partition takes to drain. | | `queue_disk_usage` | Bytes the async queue is holding on disk. | | `queue_paused` | Whether the indexing queue is paused. | | `lsm_memtable_size`, `lsm_active_segments` | Live memtable size and active segments per bucket, by `path` and `strategy`. | | `lsm_segment_count`, `lsm_segment_size` | Segments and bytes per `level`. Growth here is compaction falling behind. | | `weaviate_lsm_memtable_flush_failures_total` | Memtable flushes that failed, by `strategy`. Alert on any increase. | | `weaviate_lsm_bucket_compaction_failure_count` | Compactions that failed, by `strategy`. Alert on any increase. | | `weaviate_lsm_bucket_write_operation_failure_count`, `weaviate_lsm_bucket_read_operation_failure_count` | Storage-engine write and read failures. The write counter carries `operation`; the read counter carries `component` and `operation`. | | `weaviate_http_requests_inflight` | Concurrent HTTP requests by `method` and `route`. | | `weaviate_grpc_server_requests_inflight` | Concurrent gRPC calls by `grpc_service` and `method`. | | `weaviate_index_shards_total` | Shards by `status` (`READY`, `LOADING`). A shard stuck in `LOADING` is not serving. | | `weaviate_schema_shards`, `weaviate_schema_collections` | Schema-side shard and collection counts. Shards by `nodeID` and `status`; collections by `nodeID` and `collection_namespace`. | | `shards_loaded`, `shards_loading`, `shards_unloaded`, `shards_unloading` | Node-level shard state totals. | | `startup_progress`, `startup_durations_ms` | Shard load progress and elapsed time at boot, by collection, operation and shard. | | `query_dimensions_total` | Vector dimensions touched by queries, by `class_name`, `operation` and `query_type`. | | `token_count_total` | Tokens processed, by `tokenizer`. | | `weaviate_vector_index_memory_allocation_rejected_total` | The index refused an allocation. Any increase means writes are hitting a memory ceiling. | | `weaviate_build_info` | Version, revision, `goversion` and build tags as labels. Use it to confirm what is actually running. | #### Diagnostic - for investigation and tuning The bulk of the surface. Higher cardinality and mostly internal; reach for these during an incident or a capacity review. | Group | Metrics | When you reach for it | |---|---|---| | LSM internals | `weaviate_lsm_bucket_*`, `weaviate_lsm_memtable_*` (about 30 names), `lsm_memtable_durations_ms` (192 series) | Write stalls, compaction behaviour, and where storage time goes. | | Replication | `weaviate_async_replication_*`, `weaviate_replication_*` (about 35 names) | Cluster replication health. Structurally near-empty on a single node. | | Raft and cluster membership | `weaviate_internal_*` raft and memberlist samplers and timers (about 20 summaries) | Leadership, apply latency and membership churn on a cluster. | | Object TTL | `weaviate_objects_ttl_deletion_*` (12 names) | Whether a TTL policy is deleting on schedule. | | Export and tenancy | `weaviate_export_*`, `weaviate_auto_tenant_*` | Export jobs and multi-tenancy activity. | | Storage and IO internals | `checksum_*`, `mmap_*`, `file_io_*`, `batch_size_*`, `tombstone_find_*` | Disk-level behaviour behind a slow write path. | | Tokenizer | `tokenizer_duration_seconds`, `token_count_per_request` | Text-tokenisation cost per request. | | MCP | `weaviate_mcp_write_access_enabled` | Whether the MCP server has write access. | | Runtime | `go_*` (30), `process_*` (9), `promhttp_*` (2) | Go heap, GC, file descriptors and CPU. | | Scrape meta | `scrape_duration_seconds`, `scrape_samples_scraped`, `scrape_samples_post_metric_relabeling`, `scrape_series_added` | Receiver-side scrape health, not from Weaviate. `scrape_samples_scraped` is the cardinality alarm. | Several families are present in the exposition but read zero unless the matching feature is in use, and they are worth keeping for that reason: - `weaviate_async_replication_*`, `weaviate_replication_*` and `weaviate_cluster_store_fsm_apply_failures_total` are zero on a single node, because there is nothing to replicate and single-node raft does not fail an apply. - `weaviate_export_*` and `weaviate_objects_ttl_deletion_*` are zero until an export or a TTL policy is configured. - `weaviate_auto_tenant_*` is zero until multi-tenancy is enabled. - `weaviate_module_request_resends_total` is zero when no vectorizer module is loaded, because no module requests exist to resend. - `graphql_namespaces_blocked_requests_total` is zero without namespace blocking. - `weaviate_mcp_write_access_enabled` is zero when the MCP server is not in use. The full list is on the endpoint itself: `curl -s http://localhost:2112/metrics | grep '^# TYPE'`. #### What the traces show Weaviate produces eight span names, all `Kind: Server`: | Span name | Scope | |---|---| | `POST /v1/graphql` | `weaviate-http` | | `POST /v1/objects` | `weaviate-http` | | `GET /v1/.well-known/ready` | `weaviate-http` | | `GET /v1/schema` | `weaviate-http` | | `POST /v1/schema` | `weaviate-http` | | `/weaviate.internal.cluster.ClusterService/JoinPeer` | `weaviate-grpc` | | `/weaviate.internal.cluster.ClusterService/Query` | `weaviate-grpc` | | `/weaviate.internal.cluster.ClusterService/NotifyPeer` | `weaviate-grpc` | Two limits decide what traces can answer here: - **There are no internal spans.** No span for a vector search, a GraphQL resolver, or an LSM read. Tracing gives you the request envelope and its duration, and nothing about where the time went inside Weaviate. For that, use `queries_durations_ms` and `vector_index_durations_ms`, which are broken out by `step`. - **The gRPC spans are internal cluster RPCs**, on `weaviate.internal.cluster.ClusterService`. The client data API on 50051 produces metrics but no spans, so gRPC client traffic is invisible to traces. Span attributes use pre-1.21 HTTP semantic conventions. These are the deprecated keys, so processors and dashboards keyed on current semconv will not match: | Key on the span | Observed values | Current semconv equivalent | |---|---|---| | `http.method` | `GET`, `POST` | `http.request.method` | | `http.url` | `/v1/objects`, `/v1/graphql` | `url.path` | | `http.status_code` | `200`, `422`, `500` | `http.response.status_code` | | `http.user_agent` | `curl/8.22.0`, `Wget` | `user_agent.original` | Some keys have no semconv equivalent at all: `duration_ms`, `http.duration_ms`, `rpc.duration_ms`, `http.response_size`, `http.request_id`, and a bare `status_code` duplicating `http.status_code`. The keys that are correct are `rpc.system`, `rpc.method`, `rpc.grpc.status_code`, `service.name` and `service.version`. ### Key Alerts to Configure Weaviate's absolute latency, queue depth and object counts depend on vector dimensionality, index type, dataset size and hardware, so every row below is relative to your own trailing baseline. Tune to your workload. | Alert | Expression | Why it matters | |---|---|---| | REST/GraphQL error ratio | `requests_total{status!="ok"}` over all `requests_total`, rising against baseline | Clients on REST or GraphQL are failing. Covers no gRPC traffic. | | gRPC error ratio | `weaviate_grpc_server_request_duration_seconds_count{status!="OK"}` over all, rising against baseline | Clients on the gRPC data API are failing. Needed separately because `requests_total` never sees them. | | Query latency regression | a high quantile of `queries_durations_ms` against its own trailing baseline | Reads are slowing as the client experiences them. | | Write latency regression | a high quantile of `objects_durations_ms{step="total"}` against baseline | The write SLO. Break it down by `step` to find where the time went. | | Async index backlog growing | `queue_size` rising for 15 minutes without draining | Writes are accepted but not yet searchable, and the gap is widening. | | Unexpected collection appeared | count of distinct `class_name` on `object_count` increases | A client created a collection you did not deploy. See below. | | Vector index memory rejection | `weaviate_vector_index_memory_allocation_rejected_total` increases | The index hit a memory ceiling and refused an allocation. | | Shard stuck loading | `weaviate_index_shards_total{status="LOADING"}` above zero for 10 minutes | A shard is not serving. Check `startup_progress` for where it stopped. | | Memtable flush failing | `weaviate_lsm_memtable_flush_failures_total` increases | Writes are not reaching disk; data loss risk on restart. | | Compaction failing | `weaviate_lsm_bucket_compaction_failure_count` increases | Segment count and read amplification will climb. | | Tombstones accumulating | `vector_index_tombstones` rising while `vector_index_tombstone_cleaned` is flat | Deleted vectors are not being cleaned up; the index keeps paying for them. | | Endpoint stopped serving | `up == 0` for 2 scrape intervals | The metrics endpoint stopped answering. Check the container and port 2112. | The "unexpected collection appeared" row is the auto-schema alert, and it is the only cheap detection for a client typo silently creating a collection. The offending write returns HTTP 200 and records `status="ok"`, so nothing in the error metrics moves. See [Auto-schema and metric cardinality](#auto-schema-and-metric-cardinality). Types differ across the latency rows. The two `_duration_seconds` metrics are histograms, so a percentile comes from `histogram_quantile` over the `_bucket` series. `queries_durations_ms` and `objects_durations_ms` are summaries, so check the exposition for which quantile series they publish before writing the rule, and fall back to `_sum / _count` for a mean. ### Access Setup Weaviate serves metrics itself; no exporter is needed. The endpoint is off by default, so turn it on with an environment variable: ```yaml showLineNumbers title="compose.yaml (excerpt)" services: weaviate: image: cr.weaviate.io/semitechnologies/weaviate:1.39.2 environment: # Off by default. Without this, port 2112 is not served at all. PROMETHEUS_MONITORING_ENABLED: "true" # Collapses class_name and shard_name to "n/a" - see below. PROMETHEUS_MONITORING_GROUP: "false" # Rejects writes to collections that do not exist - see below. AUTOSCHEMA_ENABLED: "false" ports: - "8080:8080" # REST and GraphQL - "50051:50051" # gRPC data API - "2112:2112" # Prometheus metrics, fixed port volumes: - weaviate-data:/var/lib/weaviate volumes: weaviate-data: ``` Confirm the endpoint before pointing the Collector at it: ```bash showLineNumbers title="Verify access" # Expect metric text. A connection refused here means # PROMETHEUS_MONITORING_ENABLED is not set on the running container. curl -s http://localhost:2112/metrics | head -20 # Count declared names curl -s http://localhost:2112/metrics | grep -c '^# TYPE' ``` #### Turn on trace export Traces are off by default and sit behind variables named `EXPERIMENTAL_*` on 1.39. Four variables are needed, not two: ```yaml showLineNumbers title="compose.yaml (Weaviate trace variables)" environment: EXPERIMENTAL_OTEL_ENABLED: "true" EXPERIMENTAL_OTEL_EXPORTER_OTLP_ENDPOINT: otel-collector:4317 EXPERIMENTAL_OTEL_EXPORTER_OTLP_PROTOCOL: grpc # Default is 0.01. Without this you get one span in a hundred. EXPERIMENTAL_OTEL_TRACES_SAMPLER_ARG: "1.0" ``` The sampler argument is the one people miss. The default is `0.01`, so setting only the endpoint and the enable flag gives one span in a hundred and looks like broken tracing. Set it explicitly - to `1.0` while you are wiring things up, then to whatever volume you can carry. Spans arrive on the Collector's `otlp` receiver, already present in the [Configuration](#configuration) block below. ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: weaviate scrape_interval: 30s static_configs: - targets: - ${env:WEAVIATE_HOST}:2112 # Fixed metrics port otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert metricstransform: transforms: # $${1} escapes the capture group so the Collector does not # treat it as an environment variable - include: ^(requests_total|object_count|concurrent_queries_count|query_dimensions_total|graphql_namespaces_blocked_requests_total|tokenizer_duration_seconds|token_count_.*|queries_.*|objects_.*|vector_index_.*|queue_.*|shards_.*|startup_.*|lsm_.*|checksum_.*|mmap_.*|file_io_.*|batch_size_.*|tombstone_find_.*)$ match_type: regexp action: update new_name: weaviate_$${1} batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [prometheus] processors: [resource, metricstransform, batch] exporters: [otlphttp/b14] traces: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Auto-schema and metric cardinality `AUTOSCHEMA_ENABLED` defaults to true, and it turns a client typo into permanent metric cardinality. A write naming a collection that does not exist returns **HTTP 200**, silently creates it, and adds about **160 series** that persist for the life of the volume. With `AUTOSCHEMA_ENABLED=false` the same write returns **HTTP 422** with `class "X" not found in schema` and adds exactly **2 series**. Deleting the collection through `DELETE /v1/schema/` removes its series, but the next misspelled write recreates both the collection and the series. Pick one of two postures: - Set `AUTOSCHEMA_ENABLED=false` and create collections through a deployment step. Typos then fail loudly at the client instead of landing in the schema. - Leave auto-schema on and alert on the collection count, using the "unexpected collection appeared" row in [Key Alerts](#key-alerts-to-configure). This is the fallback when clients legitimately create collections at runtime. The hazard is confined to REST and GraphQL. The gRPC path carries no `class_name`, so failing gRPC calls against a non-existent collection add no `class_name`-labelled series. #### Controlling `class_name` and `shard_name` cardinality `class_name` and `shard_name` are the two dominant cardinality drivers on this surface. `PROMETHEUS_MONITORING_GROUP=true` collapses both to the single value `n/a`. It works, it is the documented control, and it costs you every per-collection and per-shard breakdown - no latency by collection, no object counts by shard, no way to tell which collection is growing. Take the trade only when the collection count is unbounded and you have accepted route-level monitoring through `weaviate_http_request_duration_seconds` instead. `class_name="n/a"` also appears without the setting, on metrics that are not collection-scoped. Seeing it is not proof that grouping is on. #### Namespacing the unprefixed metric names 68 of the 258 names arrive with no prefix at all, including `object_count`, `requests_total`, `queue_size`, `queue_count`, `startup_progress`, `shards_loaded`, `lsm_memtable_size`, `token_count_total`, `concurrent_queries_count` and `file_io_writes_total_bytes`. Those are generic enough to collide with any other job in a shared metrics backend. Weaviate cannot fix this for you. `PROMETHEUS_MONITORING_METRIC_NAMESPACE` prefixes nothing on 1.39.2: the value is parsed and never applied, so setting it to `weaviate` or to any other string produces a byte-identical metric set with no renamed names. Do not use it. Prefix at the Collector instead. The `metricstransform` processor in the config above is the fix, and its anchored patterns leave the `weaviate_`, `go_`, `process_` and `promhttp_` families alone. Do not do this with `metric_relabel_configs`. Relabelling runs on the raw scrape series, which still carry their `_bucket`, `_sum` and `_count` suffixes, so an anchored pattern written against the metric name misses every histogram and summary among these names - and renaming at the receiver drops the type, unit and description. The processor runs after the receiver has reassembled the histograms, so it matches the metric name and keeps the type. #### Environment Variables ```bash showLineNumbers title=".env" WEAVIATE_HOST=localhost ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Confirm the request counter exists on the endpoint curl -s http://localhost:2112/metrics | grep '^requests_total' # Check Collector logs for the scrape job docker logs otel-collector 2>&1 | grep -i weaviate ``` An idle node already exposes 131 metric names, so a non-empty scrape is not evidence that anything is being used. Confirm real traffic instead: `requests_total` moving for your `api` and `query_type`, and `object_count` non-zero for a collection you loaded. In Scout, query `queries_durations_ms` by `class_name` to confirm the read path arrived, and `weaviate_grpc_server_request_duration_seconds` by `method` to confirm the gRPC path arrived. If you applied the `metricstransform` processor, query the renamed series (`weaviate_requests_total`, `weaviate_object_count`) rather than the originals. Spans appear only after `EXPERIMENTAL_OTEL_TRACES_SAMPLER_ARG` is raised **and** traffic has run. If both are true and nothing arrives, check the Collector logs for OTLP receive errors. ### Troubleshooting #### Connection refused on port 2112 **Cause**: `PROMETHEUS_MONITORING_ENABLED` is not set on the running container. The endpoint is off by default and the port is not bound at all, so this is a refused connection rather than an empty response. **Fix**: 1. Set `PROMETHEUS_MONITORING_ENABLED=true` and restart Weaviate. 2. Confirm with `curl -s http://localhost:2112/metrics | head`. 3. Do not try to move the port. It is fixed at 2112; the port default in the config struct has no effect once monitoring is enabled. #### A dashboard undercounts search traffic **Cause**: The panel is built on `requests_total`, which covers REST and GraphQL only. The official clients send searches over gRPC. **Look at**: `weaviate_grpc_server_request_duration_seconds_count` by `method`. If it is moving while `requests_total` is flat for searches, the client is on gRPC. **Fix**: 1. Add `weaviate_grpc_server_request_duration_seconds` to the panel and to the error-ratio alert. 2. Expect no `class_name` on the gRPC series - break gRPC down by `method` instead. #### `rate()` on `requests_total` returns nothing useful **Cause**: `requests_total` is declared a gauge in the exposition, so it reaches the backend as a gauge despite the `_total` suffix. **Look at**: the metric type in Scout before writing the query. The same mismatch affects `concurrent_queries_count`, `lsm_segment_count`, `object_count` and `queue_count`. **Fix**: 1. Use a gauge-appropriate expression - a delta over the window rather than `rate()`. 2. Where you need a true rate of failures, derive it from the gauge difference, or use the gRPC histogram's `_count`, which is a real counter. #### Series count keeps climbing with no deployments **Cause**: Auto-schema. A client wrote to a misspelled collection, Weaviate created it, and about 160 series came with it. **Look at**: distinct `class_name` values on `object_count`, and `scrape_samples_scraped` for the total series count per scrape. **Fix**: 1. Delete the unwanted collection: `DELETE /v1/schema/`. The series go with it. 2. Set `AUTOSCHEMA_ENABLED=false` so the next typo returns HTTP 422 instead of creating the collection again. 3. If clients must create collections at runtime, keep the collection-count alert and consider `PROMETHEUS_MONITORING_GROUP=true`. #### Metric names collide with another service in the backend **Cause**: 68 names carry no prefix, and `PROMETHEUS_MONITORING_METRIC_NAMESPACE` does not apply the one you set. **Fix**: 1. Add the `metricstransform` processor from [Configuration](#namespacing-the-unprefixed-metric-names). 2. Update dashboards and alerts to the renamed series in the same change; the rename is not backward compatible. #### Only about half the metric names are there **Cause**: The node is idle. 131 names are present at rest; the remaining 127 appear only once queries and writes run. **Fix**: 1. Run representative traffic, then re-check `curl -s http://localhost:2112/metrics | grep -c '^# TYPE'`. 2. Do not whitelist against an idle scrape - it will drop the metrics you actually alert on. #### Writes are slow or stalling **Cause**: The storage engine or the async index queue is behind. **Look at**: `objects_durations_ms` by `step` first to find the slow stage, then the Diagnostic LSM group - `lsm_memtable_durations_ms`, `weaviate_lsm_bucket_*` and `weaviate_lsm_memtable_*` - for flush and compaction behaviour. `queue_size` and `queue_disk_usage` show whether indexing is the backlog. **Fix**: 1. If flush or compaction failure counters are increasing, check disk space and IO before anything else. 2. If `queue_size` is growing while writes are steady, the index cannot keep up with ingestion; reduce concurrency or add capacity. #### Writes are rejected with the node still running **Cause**: the vector index hit a memory ceiling. `weaviate_vector_index_memory_allocation_rejected_total` increments and the write fails, but the process stays up, so nothing restarts and nothing else looks wrong. **Look at**: `vector_index_size` by collection and shard for which index grew into the ceiling, then the Diagnostic tier's Runtime group - the `go_*` heap and GC families and `process_*` for resident size - to separate index growth from general heap pressure. Weaviate holds the index in memory, so resident size tracks index size closely. **Fix**: raise the container memory limit, shard the collection, or switch the affected collection to a disk-backed index. The rejection counter is the only signal that writes are failing for this reason; request-level errors report it as a generic failure. #### gRPC errors all report `status="Unknown"` **Cause**: The gRPC status mapping is coarse. Searches against a collection that does not exist record `Unknown`, not `NotFound`. **Look at**: the `status` values on `weaviate_grpc_server_request_duration_seconds`. `OK`, `Unknown` and `ResourceExhausted` are the ones you will see. **Fix**: 1. Alert on the non-`OK` ratio rather than on specific status values. 2. Go to the application logs or the client for the actual cause; the metric will not distinguish it. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. ### Updates & Upgrades #### Weaviate version changes - **1.27 → 1.39**: the metric surface roughly tripled, from 88 names under load to 258, and `weaviate_build_info` stopped being the only `weaviate_`-prefixed name. Three metrics this guide puts in Core do not exist on 1.27 at all: `weaviate_http_request_duration_seconds`, `weaviate_grpc_server_request_duration_seconds` and `queue_size`. A dashboard built from this guide will render empty panels against an older server. _(additive in Weaviate; the Core tier here assumes 1.39)_ - **The async index queue family was renamed**: `index_queue_*` on 1.27 became `queue_*` by 1.39, so `index_queue_size` is now `queue_size` and `index_queue_paused` is now `queue_paused`. Queries and alert rules written against the old names stop resolving on upgrade, and historical series keep the old names. _(breaking for your queries)_ - **`weaviate_mcp_write_access_enabled` and the `weaviate_objects_ttl_deletion_*` family are recent additions** and are absent from 1.27. Nothing needs to change for them; they appear on upgrade. _(additive)_ - **The trace path is behind `EXPERIMENTAL_*` variable names on 1.39.** Treat the variable names themselves as version-specific and re-check them on a minor upgrade, not just the values. _(may break on upgrade)_ #### Collector / receiver changes - This guide uses the **prometheus receiver**, which has no receiver-key rename across the supported Collector range, so the Collector config is stable on an image bump. New Weaviate series are picked up with no Collector change, because there is no per-metric enable list. The `metricstransform` rename in the config below is anchored to the unprefixed names, so a new unprefixed name upstream needs adding to that pattern. _(no breaking change on the Prometheus path)_ ### FAQ #### Why do half the metric names have no `weaviate_` prefix? Weaviate registers 149 names under `weaviate_` and 68 with no prefix at all, including generic ones like `object_count`, `requests_total` and `queue_size`. There is no setting that fixes this on the component side - `PROMETHEUS_MONITORING_METRIC_NAMESPACE` is parsed and never applied. Prefix them at the Collector with the `metricstransform` processor shown in [Configuration](#namespacing-the-unprefixed-metric-names). #### Why does my Python client's search traffic not show in `requests_total`? `requests_total` covers REST and GraphQL only; there is no `api="grpc"` value. The official clients are hybrid - connected with `grpc_port=50051`, `weaviate-client` sends searches over gRPC and inserts over REST. Searches are counted by `weaviate_grpc_server_request_duration_seconds` instead. Chart and alert on both. #### How do I stop a client typo from creating a collection? Set `AUTOSCHEMA_ENABLED=false`. The write then returns HTTP 422 with `class "X" not found in schema` and adds 2 series instead of creating the collection and about 160 series. If clients legitimately create collections at runtime, keep auto-schema on and alert on the count of distinct `class_name` values on `object_count` - the write itself returns HTTP 200 and `status="ok"`, so no error metric will flag it. #### Does tracing show what happens inside a vector search? No. Weaviate emits eight span names, all `Kind: Server`, covering the HTTP request envelope and internal cluster RPCs. There is no span for a vector search, a GraphQL resolver or an LSM read. Use `queries_durations_ms` and `vector_index_durations_ms`, which break the work out by `step`. #### Does this work with Weaviate running in Kubernetes? Yes. Set `PROMETHEUS_MONITORING_ENABLED=true` in the pod spec, expose container port 2112, and point the scrape target at the Weaviate service DNS (for example `weaviate.default.svc.cluster.local:2112`). Everything else in this guide is unchanged. #### How do I keep the series count under control? `class_name` and `shard_name` are the two dominant drivers. `PROMETHEUS_MONITORING_GROUP=true` collapses both to `n/a` and works, at the cost of all per-collection and per-shard visibility. Before reaching for it, turn off auto-schema so client typos stop adding collections. Watch `scrape_samples_scraped` to confirm the effect. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on Weaviate metrics. - [Qdrant Monitoring](./qdrant.md) - Vector store with a much smaller metric surface and no collection-level labels. - [Milvus Monitoring](./milvus.md) - Vector store with the same unprefixed name problem, fixed the same way at the Collector. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Qdrant](./qdrant.md), [Milvus](./milvus.md), and other components. - **Fine-tune Collection**: Adjust the `scrape_interval` to your traffic and retention needs, and settle the auto-schema and `PROMETHEUS_MONITORING_GROUP` posture before opening the API to client-named collections. --- ## WildFly OpenTelemetry Monitoring - Undertow Requests, Datasource Pools, and Collector Setup ## WildFly The OpenTelemetry JMX Scraper collects 14 WildFly-specific metrics and 19 JVM metrics from WildFly 26+ - Undertow request throughput, 5xx error counts, request duration, datasource connection pools, transaction activity, and HTTP session load. WildFly does not expose standard JMX/RMI; it serves JMX through its management interface on port 9990 over the `remote+http` protocol, so the scraper connects with the WildFly client JAR on its classpath and pushes OTLP to the Collector. This guide configures a management user, sets up the scraper with the correct JMX URL, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | -------------- | ------- | -------------- | | WildFly | 26 | 40.0.0.Final | | JMX Scraper | 1.46.0 | 1.57.0-alpha | | Java (scraper) | 11 | 17 | | OTel Collector | 0.90.0 | latest | | base14 Scout | Any | - | Before starting: - WildFly's management interface (port 9990) must be reachable from the host running the JMX Scraper. - A management-realm user is required for remote JMX access - unauthenticated access is not supported. - The JMX Scraper needs `jboss-client.jar` on its classpath, copied from the matching WildFly version. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The metric names are defined by the JMX Scraper's `jvm,wildfly` target rules, not by WildFly. Session metrics live on the Undertow deployment MBean and only appear once a session-bearing application is deployed; datasource metrics require a configured datasource. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `wildfly.request.count` | Requests served by the Undertow listener - the throughput KPI. | | `jvm.memory.used` | JVM memory in use. JMX exposes no `up` metric, so heap-in-use doubles as the process-alive and heap-health anchor. | #### Operational - what to alert on | Group | Metrics | What it tells you | |---|---|---| | Errors | `wildfly.error.count` | Undertow requests that returned a 5xx response - the error-rate signal. | | Latency | `wildfly.request.duration.sum` | Cumulative request-processing time; divide by request count for mean latency. | | Throughput | `wildfly.network.io` | Bytes transmitted and received by the listener (`network.io.direction`). | | Datasource pool | `wildfly.db.client.connection.count`, `wildfly.db.client.connection.wait.count` | Open connections (used/idle) and requests that had to wait for the pool. | | Transactions | `wildfly.transaction.count`, `wildfly.transaction.created`, `wildfly.transaction.committed`, `wildfly.transaction.rollback` | In-flight, created, committed, and rolled-back transactions (rollbacks carry `wildfly.rollback.cause`). | | Sessions | `wildfly.session.active.count`, `wildfly.session.rejected` | Currently active HTTP sessions and sessions dropped at the session limit. | | JVM health | `jvm.memory.limit`, `jvm.cpu.recent_utilization`, `jvm.thread.count` | Heap ceiling (saturation denominator), recent process CPU, and live thread count (leak signal). | `wildfly.session.active.limit` is whitelisted by the scraper but does not emit: it maps to Undertow's `maxActiveSessions`, which defaults to `-1` (unlimited), and the scraper rule drops negative values. It surfaces only when a deployment configures a finite session limit. #### Diagnostic - for investigation and tuning Higher cardinality; reach for these during an incident or capacity review, not as paging signals. | Group | Metrics | When you reach for it | |---|---|---| | Session lifecycle | `wildfly.session.created`, `wildfly.session.expired` | Session churn vs active count; expiry behaviour. | | JVM memory detail | `jvm.memory.committed`, `jvm.memory.init`, `jvm.memory.used_after_last_gc` | GC effectiveness and committed-vs-used gap. | | JVM class loading | `jvm.class.count`, `jvm.class.loaded`, `jvm.class.unloaded` | Classloader leaks after repeated redeploys. | | JVM CPU / system | `jvm.cpu.count`, `jvm.cpu.time`, `jvm.system.cpu.load_1m`, `jvm.system.cpu.utilization` | Host vs process CPU attribution. | | JVM buffers / descriptors | `jvm.buffer.count`, `jvm.buffer.memory.limit`, `jvm.buffer.memory.used`, `jvm.file_descriptor.count`, `jvm.file_descriptor.limit` | Direct-buffer pressure and fd usage against the ceiling. | Full metric reference: [OTel WildFly JMX Metrics](https://github.com/open-telemetry/opentelemetry-java-instrumentation/blob/main/instrumentation/jmx-metrics/library/wildfly.md). ### Key Alerts to Configure Threshold guidance for the most useful Operational-tier series. These are starting points; tune them to your workload. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `rate(wildfly.error.count)` vs `rate(wildfly.request.count)` | Rising vs normal | Sustained climb | Application or upstream errors; inspect logs and failing endpoints. | | `wildfly.request.duration.sum` / request count (mean) | Rising vs normal | Sustained climb | Slow request handling; check downstream calls and GC. | | `wildfly.db.client.connection.wait.count` | > 0 sustained | Climbing | Pool too small or connections held too long; raise pool size or fix leaks. | | `rate(wildfly.transaction.rollback)` vs `wildfly.transaction.committed` | Rising | Sustained climb | Failing transactions; inspect rollback cause (application/resource/system) and downstream resources. | | `wildfly.session.rejected` | > 0 | Sustained > 0 | Session limit reached and sessions dropped; raise the limit or investigate session leaks. | | `jvm.memory.used` / `jvm.memory.limit` | > 80% | Approaching limit | GC churn / OOM risk; raise heap or reduce allocation. | | `jvm.cpu.recent_utilization` | High | Sustained high | Process CPU-bound; scale out or profile hot paths. | ### Access Setup WildFly does **not** use standard JMX/RMI. It exposes JMX through its management interface on port 9990 using the `remote+http` protocol, which requires a management-realm user and the WildFly client JAR. #### Create a Management User WildFly requires a management-realm user for remote JMX access: ```bash showLineNumbers title="Create a monitoring user" $JBOSS_HOME/bin/add-user.sh -u otel-monitor -p ``` Authentication is mandatory - the scraper connects with `OTEL_JMX_USERNAME` and `OTEL_JMX_PASSWORD`, and unauthenticated remote JMX is not supported. #### Bind the Management Interface WildFly binds the management interface to localhost by default. For Docker or remote access, bind it to all interfaces: ```bash showLineNumbers title="Start WildFly with remote management" $JBOSS_HOME/bin/standalone.sh -b 0.0.0.0 -bmanagement 0.0.0.0 ``` For Docker, create the management user and bind the interface at startup: ```yaml showLineNumbers title="docker-compose.yaml (WildFly service)" wildfly: image: quay.io/wildfly/wildfly:40.0.0.Final-jdk17 hostname: wildfly container_name: wildfly command: > /bin/bash -c " /opt/jboss/wildfly/bin/add-user.sh -u monitor -p ${WILDFLY_MGMT_PASSWORD} --silent && /opt/jboss/wildfly/bin/standalone.sh -b 0.0.0.0 -bmanagement 0.0.0.0 " ports: - "8080:8080" - "9990:9990" ``` #### Provide the WildFly Client JAR The `remote+http` protocol requires `jboss-client.jar` on the scraper's classpath. Copy it from a WildFly installation that matches the running server's major version - a version-skewed client risks a fragile `remote+http` JMX handshake: ```bash showLineNumbers title="Install the scraper JAR and WildFly client JAR" sudo mkdir -p /opt/otel # Download the JMX Scraper from Maven Central curl -sL -o /opt/otel/opentelemetry-jmx-scraper-1.57.0-alpha.jar \ https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/1.57.0-alpha/opentelemetry-jmx-scraper-1.57.0-alpha.jar # Copy jboss-client.jar from a WildFly install matching the server's version sudo cp $JBOSS_HOME/bin/client/jboss-client.jar /opt/otel/ ``` ### Configuration WildFly monitoring uses two components: the JMX Scraper (connects to the management interface, exports OTLP) and the OTel Collector (receives OTLP, ships to Scout). ```text WildFly (mgmt:9990) ← remote+http → JMX Scraper → OTLP → OTel Collector → Scout ``` #### JMX Scraper The WildFly JMX URL uses `remote+http`, **not** standard RMI. Set both the `jvm` and `wildfly` target systems so the scraper emits the full surface: ```bash showLineNumbers title="Run the JMX Scraper" OTEL_JMX_SERVICE_URL=service:jmx:remote+http://localhost:9990 \ OTEL_JMX_TARGET_SYSTEM=jvm,wildfly \ OTEL_JMX_USERNAME=${OTEL_JMX_USERNAME} \ OTEL_JMX_PASSWORD=${OTEL_JMX_PASSWORD} \ OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 \ OTEL_METRIC_EXPORT_INTERVAL=10000 \ java -cp /opt/otel/opentelemetry-jmx-scraper-1.57.0-alpha.jar:/opt/otel/jboss-client.jar \ io.opentelemetry.contrib.jmxscraper.JmxScraper ``` Run it as a managed service with systemd: ```bash showLineNumbers title="/etc/systemd/system/otel-jmx-scraper.service" sudo tee /etc/systemd/system/otel-jmx-scraper.service > /dev/null <<'EOF' [Unit] Description=OpenTelemetry JMX Scraper for WildFly After=network.target wildfly.service [Service] Type=simple Environment=OTEL_JMX_SERVICE_URL=service:jmx:remote+http://localhost:9990 Environment=OTEL_JMX_TARGET_SYSTEM=jvm,wildfly Environment=OTEL_JMX_USERNAME=monitor Environment=OTEL_JMX_PASSWORD= Environment=OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4317 Environment=OTEL_METRIC_EXPORT_INTERVAL=10000 ExecStart=/usr/bin/java -cp /opt/otel/opentelemetry-jmx-scraper-1.57.0-alpha.jar:/opt/otel/jboss-client.jar io.opentelemetry.contrib.jmxscraper.JmxScraper Restart=always RestartSec=5 [Install] WantedBy=multi-user.target EOF sudo systemctl daemon-reload sudo systemctl enable --now otel-jmx-scraper ``` For Docker, build an image that bundles both the scraper JAR and a `jboss-client.jar` copied from the matching WildFly image: ```dockerfile showLineNumbers title="jmx-scraper/Dockerfile" FROM quay.io/wildfly/wildfly:40.0.0.Final-jdk17 AS wildfly FROM eclipse-temurin:17-jre ARG SCRAPER_VERSION=1.57.0-alpha ADD https://repo1.maven.org/maven2/io/opentelemetry/contrib/opentelemetry-jmx-scraper/${SCRAPER_VERSION}/opentelemetry-jmx-scraper-${SCRAPER_VERSION}.jar /opt/scraper.jar COPY --from=wildfly /opt/jboss/wildfly/bin/client/jboss-client.jar /opt/jboss-client.jar ENTRYPOINT ["java", "-cp", "/opt/scraper.jar:/opt/jboss-client.jar", "io.opentelemetry.contrib.jmxscraper.JmxScraper"] ``` #### OTel Collector The Collector receives metrics from the scraper over OTLP/gRPC: ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [otlp] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" # JMX Scraper OTEL_JMX_SERVICE_URL=service:jmx:remote+http://wildfly:9990 OTEL_JMX_TARGET_SYSTEM=jvm,wildfly OTEL_JMX_USERNAME=monitor OTEL_JMX_PASSWORD=your_password OTEL_METRIC_EXPORT_INTERVAL=10000 # OTel Collector ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` #### Docker Compose A full working example with all three components: ```yaml showLineNumbers title="docker-compose.yaml" services: wildfly: image: quay.io/wildfly/wildfly:40.0.0.Final-jdk17 hostname: wildfly container_name: wildfly command: > /bin/bash -c " /opt/jboss/wildfly/bin/add-user.sh -u monitor -p ${WILDFLY_MGMT_PASSWORD} --silent && /opt/jboss/wildfly/bin/standalone.sh -b 0.0.0.0 -bmanagement 0.0.0.0 " ports: - "8080:8080" - "9990:9990" healthcheck: test: ["CMD-SHELL", "curl -so /dev/null http://localhost:8080/ || exit 1"] interval: 10s timeout: 5s retries: 10 start_period: 30s jmx-scraper: build: ./jmx-scraper container_name: jmx-scraper environment: OTEL_JMX_SERVICE_URL: ${OTEL_JMX_SERVICE_URL} OTEL_JMX_TARGET_SYSTEM: ${OTEL_JMX_TARGET_SYSTEM} OTEL_JMX_USERNAME: ${OTEL_JMX_USERNAME} OTEL_JMX_PASSWORD: ${OTEL_JMX_PASSWORD} OTEL_EXPORTER_OTLP_ENDPOINT: http://otel-collector:4317 OTEL_METRIC_EXPORT_INTERVAL: ${OTEL_METRIC_EXPORT_INTERVAL} depends_on: wildfly: condition: service_healthy otel-collector: image: otel/opentelemetry-collector-contrib:latest container_name: otel-collector volumes: - ./config/otel-collector.yaml:/etc/otelcol-contrib/config.yaml:ro depends_on: - wildfly ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers title="Verify metrics collection" # Check the JMX Scraper connected over remote+http docker logs jmx-scraper 2>&1 | head -10 # Confirm WildFly's management interface is up docker logs wildfly 2>&1 | grep "management" # Check Collector logs for WildFly metrics docker logs otel-collector 2>&1 | grep "wildfly" ``` A steady-state scrape with traffic produces 28 component metrics (18 `jvm.*` plus 10 `wildfly.*`). Deploying a session-bearing application adds the four `wildfly.session.*` metrics, for 32. ### Troubleshooting #### JMX connection refused **Cause**: The scraper cannot reach WildFly's management interface. **Fix**: 1. Verify WildFly is running: `docker ps | grep wildfly`. 2. Confirm the JMX URL uses `remote+http`, **not** `rmi`: `service:jmx:remote+http://wildfly:9990`. 3. Verify the management user exists - run `add-user.sh` if needed. 4. Confirm the management interface is bound to `0.0.0.0` (`-bmanagement 0.0.0.0`). 5. Verify `jboss-client.jar` is on the scraper's classpath. #### Only JVM metrics, no WildFly metrics **Cause**: `OTEL_JMX_TARGET_SYSTEM` does not include `wildfly`, or the scraper is missing `jboss-client.jar`. **Fix**: 1. Set `OTEL_JMX_TARGET_SYSTEM=jvm,wildfly` (both targets, comma-separated). 2. Verify `jboss-client.jar` is on the classpath - without it the scraper may connect via fallback and see only JVM MBeans. 3. Confirm WildFly has started fully - MBeans appear only after the subsystems initialise. #### No session metrics **Cause**: The five `wildfly.session.*` metrics live on the `jboss.as:deployment=*,subsystem=undertow` MBean, which exists only once a session-bearing application is deployed. **Look at**: `wildfly.session.active.count` and the lifecycle metrics `wildfly.session.created` / `wildfly.session.expired` - all zero or absent until a `.war` with active session handling is deployed. **Fix**: 1. Deploy a web application that calls `getSession()`. 2. Restart the scraper after the deploy so it re-discovers the new `deployment=*` MBean. #### No datasource metrics **Cause**: `wildfly.db.client.connection.*` require a configured datasource. The default `standalone.xml` includes `ExampleDS` (H2 in-memory). **Fix**: 1. Verify a datasource is configured: `$JBOSS_HOME/bin/jboss-cli.sh --connect --command="/subsystem=datasources:read-resource"`. 2. Use `standalone-full.xml` for additional subsystems: `standalone.sh --server-config=standalone-full.xml`. #### Requests slow or transactions failing **Cause**: Pool starvation, GC pressure, or failing downstream resources. **Look at**: `wildfly.db.client.connection.wait.count` (requests queued on the pool), `jvm.memory.used_after_last_gc` (heap retained after GC), and `wildfly.transaction.rollback` by `wildfly.rollback.cause` (application/resource/system) to attribute failures. **Fix**: 1. Raise the datasource pool size or fix connection leaks if waits climb. 2. Raise heap or reduce allocation if post-GC heap stays high. 3. Inspect the rollback cause and the corresponding downstream resource. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and exporter. ### FAQ #### Does this work with JBoss EAP? Yes. JBoss EAP is based on WildFly and uses the same management interface and JMX URL scheme. Use `service:jmx:remote+http://:9990` with a management user created via `add-user.sh`. #### Can I use standard JMX RMI instead of `remote+http`? No. WildFly removed standard JMX/RMI access. All remote JMX goes through the management interface using the `remote+http` protocol, which requires `jboss-client.jar` on the connecting client's classpath. #### Does this work with WildFly in Kubernetes? Yes. Run the JMX Scraper as a sidecar container in the same pod and set `OTEL_JMX_SERVICE_URL` to `service:jmx:remote+http://localhost:9990`. The sidecar needs `jboss-client.jar` on its classpath - use the multi-stage Dockerfile shown above. #### How do I get session metrics? Deploy a web application (`.war`) that creates HTTP sessions. The `wildfly.session.*` metrics live on the Undertow deployment MBean, which exists only once a session-bearing application is deployed. A default WildFly install without applications produces Undertow, datasource, and transaction metrics but no session metrics. Restart the scraper after deploying so it picks up the new MBean. #### Why is `wildfly.session.active.limit` missing? It maps to Undertow's `maxActiveSessions`, which defaults to `-1` (unlimited). The scraper drops negative values, so the metric only emits once a deployment configures a finite session limit. ### Related Guides - [JMX Metrics Guide](../collector-setup/jmx-metrics-collection-guide.md) - Compare the JMX Scraper and the JMX Exporter. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Tomcat Monitoring](./tomcat.md) - Another Java application server. - [Jetty Monitoring](./jetty.md) - Another Java application server. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on WildFly metrics. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Tomcat](./tomcat.md), [Jetty](./jetty.md), and other Java application servers. - **Fine-tune Collection**: Adjust `OTEL_METRIC_EXPORT_INTERVAL` to control scrape frequency, and drop the Diagnostic tier in production to control volume while keeping it available for incident investigation. --- ## YugabyteDB OpenTelemetry Monitoring - Tablet-Server Liveness, Clock Skew, and Collector Setup ## YugabyteDB YugabyteDB is distributed SQL whose YSQL API speaks the PostgreSQL wire protocol, so if you already run the [PostgreSQL receiver](./postgres.md) you know most of the SQL-layer signals here. What single-node PostgreSQL gives you no analogue for is the distributed machinery: tablet-server liveness, clock skew across peers, and re-replication while the cluster heals from a node loss. Those are the signals that page you when a multi-node cluster degrades, and they are the reason this is a separate guide. YugabyteDB exposes metrics in Prometheus format at `/prometheus-metrics`, but on **four ports per node**: `7000` (yb-master), `9000` (yb-tserver), `13000` (YSQL, the Postgres-wire API), and `12000` (YCQL, the Cassandra-wire API). Every node runs both a yb-master and a yb-tserver. There is no native YugabyteDB receiver and no `pg_stat` views in play - the OpenTelemetry Collector's `prometheus` receiver scrapes each endpoint directly with one scrape job per endpoint type. Metric names are un-prefixed and split across the daemons (`handler_latency_yb_*`, `rocksdb_*` / `intentsdb_rocksdb_*` for the two per-tablet RocksDB stores, `hybrid_clock_*`, `num_tablet_servers_*`, `follower_lag_ms`), 3,400+ distinct names in all. This guide configures the receiver and ships the metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ---------- | ------------ | | YugabyteDB | 2.18 | 2025.2+ | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | — | Before starting: - Each YugabyteDB node's metrics ports (`7000`, `9000`, `13000`, `12000`) must be reachable from the host running the Collector. - No SQL monitoring user is required - the Prometheus endpoints are plain HTTP (see [Access Setup](#access-setup)). - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. Every series carries `exported_instance` (the node's `host:port`) and a `metric_id` namespace (`yb.tabletserver`, `yb.master`, ...); per-tablet series also carry `table_id` and `tablet_id`. The tiers below lead with the distributed signals that have no single-node PostgreSQL counterpart - tablet-server liveness, clock skew, and re-replication - then cover the familiar YSQL throughput and latency series. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `num_tablet_servers_live` | Live tablet servers the master sees; equals the node count when healthy. Distributed signal with no PostgreSQL analogue. | | `hybrid_clock_skew` | Live clock skew versus peers. YugabyteDB tolerates skew up to `hybrid_clock_error` (the `max_clock_skew_usec` setting, 500ms / 500000 µs by default); beyond it, reads restart and a node can stall. The signature distributed-SQL health signal. | | `num_tablet_peers_undergoing_rbs` | Tablet peers being remote-bootstrapped (re-replicated); 0 in steady state, greater than 0 while the cluster heals from a node loss. The "is the cluster recovering" headline. Distributed signal. | | `handler_latency_yb_ysqlserver_SQLProcessor_SelectStmt_count` (+ `InsertStmt` / `UpdateStmt` / `DeleteStmt`) | YSQL statements served on the Postgres-wire API - the headline throughput KPI. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `num_tablet_servers_live` | Below the node count means a tablet server is down or partitioned. Distributed signal. | | `num_tablet_servers_dead` | The master has declared a tablet server dead; should sit at 0. Distributed signal. | | `handler_latency_yb_tserver_TabletServerService_Read` / `Write` | DocDB read/write latency distribution (histogram via `_sum` / `_count`) - the latency SLI. | | `follower_lag_ms` | Max follower replication lag per tablet; a rising value means a replica is falling behind its leader. Distributed signal. | | `yb_ysqlserver_active_connection_total` / `yb_ysqlserver_connection_total` | Active and open YSQL connections versus `yb_ysqlserver_max_connection_total` (saturation). Postgres-wire delta. | | `yb_ysqlserver_connection_over_limit_total` | YSQL connections rejected over the configured limit. | #### Diagnostic - for investigation and tuning Higher cardinality - per-statement throughput, the per-tablet RocksDB stores, WAL/Raft internals, and the large RPC families. Enable on demand; in production you can drop this tier with a `metric_relabel_configs` block while keeping Core + Operational. | Metric | What it tells you | |---|---| | `handler_latency_yb_ysqlserver_SQLProcessor_{SelectStmt,InsertStmt,UpdateStmt,DeleteStmt}_{count,sum}`, `_Transactions_`, `_SingleShardTransactions_` | YSQL per-statement throughput and latency by operation. | | `yb_ysqlserver_CatalogCacheMisses_count`, `yb_ysqlserver_CatCacheRefresh_count` | YSQL catalog-cache pressure. | | `handler_latency_yb_tserver_TabletServerService_Write_count` / `_Read_count` | API-independent DocDB op rate underneath both YSQL and YCQL (the YSQL statement counters are the page-worthy KPI; these are the storage-layer detail). | | `majority_sst_files_rejections`, `rocksdb_stall_micros`, `intentsdb_rocksdb_stall_micros` | Storage backpressure - writes rejected on too many SST files, and time the storage engine stalled writes. | | `rocksdb_current_version_num_sst_files`, `rocksdb_current_version_sst_files_size`, `rocksdb_bytes_written` / `rocksdb_bytes_read`, `rocksdb_compaction_times_micros_*` (+ the `intentsdb_rocksdb_*` mirror) | DocDB RocksDB stores - the regular store and the intents (provisional-records) store, one of each per tablet. | | `log_append_latency_*`, `log_sync_latency_*`, `log_wal_size`, `raft_term`, `handler_latency_yb_consensus_ConsensusService_UpdateConsensus_*`, `RunLeaderElection_count`, `LeaderElectionLost_count` | WAL append/sync and Raft replication RPC, terms, and elections. | | `ts_live_tablet_peers`, `ts_supportable_tablet_peers`, `Create_Tablet_Task_count`, `AddServer_ChangeConfig_Task_count`, `is_load_balancing_enabled`, `blacklisted_leaders` | Tablet topology and master cluster-management tasks. | | `generic_heap_size`, `mem_tracker_server` (+ `BlockBasedTable`, `Call`, `LogCache` subtrackers) | Server heap and per-component memory trackers. | YugabyteDB also exposes a Cassandra-wire API (YCQL) on port `12000` with the parallel `handler_latency_yb_cqlserver_SQLProcessor_*` per-statement counters and `rpc_connections_alive`. The Configuration below scrapes it; if you do not run YCQL workloads, those counters stay near zero. The primary delta in this guide is against [PostgreSQL](./postgres.md) on the YSQL API. The long diagnostic tail groups into RPC and engine families. The largest are `proxy_*` / `service_*_bytes` (per-RPC-method request/response byte counters), `handler_latency_yb_master_*` (master admin / cluster / DDL / client RPC), `handler_latency_yb_tserver_*` (TServer RPC), `intentsdb_rocksdb_*` and `rocksdb_*` (the two DocDB stores), `handler_latency_yb_cqlserver_*` (YCQL engine), `mem_tracker_*`, `handler_latency_yb_consensus_*` (Raft), `handler_latency_yb_ysqlserver_*` (YSQL per-statement), `log_*` (WAL), `yb_ysqlserver_*` / `ysql_conn_mgr_*` (connections, catalog cache), `transaction_*` / `pgsql_*` (distributed transaction coordinator), and `hybrid_clock_*` (clock skew / error / hybrid-time). Full metric reference: [YugabyteDB metrics](https://docs.yugabyte.com/preview/launch-and-manage/monitor-and-alert/metrics/), or `curl -s http://localhost:9000/prometheus-metrics` against any tablet server. ### Key Alerts to Configure Threshold guidance for the most useful Core- and Operational-tier series. Tune to your workload and cluster size; these are starting points. | Metric | Warning | Critical | Why it matters | |---|---|---|---| | `num_tablet_servers_live` | < node count | Falling further | A tablet server is down or partitioned; investigate the missing node. | | `num_tablet_servers_dead` | > 0 | > 0 sustained | The master has declared a tablet server dead. | | `hybrid_clock_skew` | > 40% of `hybrid_clock_error` | ≈ 80% of `hybrid_clock_error` (≈400ms at the 500ms default) | Clock-skew risk; skew beyond the configured max drives read restarts and can stall the node. Check NTP/chrony on the affected host. | | `num_tablet_peers_undergoing_rbs` | > 0 | > 0 sustained | Re-replication (remote bootstrap) is not completing; a node loss is not healing. | | `rate(handler_latency_yb_ysqlserver_SQLProcessor_SelectStmt_count + InsertStmt_count + UpdateStmt_count + DeleteStmt_count)` | Dipping vs baseline | ≈ 0 sustained under expected load | YSQL serving has stalled; check the YSQL layer and node health. | | `follower_lag_ms` | Rising above your baseline follower lag | Sustained at a multiple of baseline / not converging | A replica is falling behind; replication is not converging. | | `yb_ysqlserver_connection_over_limit_total` | > 0 | Increasing | YSQL is rejecting connections; raise `ysql_max_connections` or add a pooler. | ### Access Setup YugabyteDB needs no SQL monitoring user for metrics. Unlike the PostgreSQL receiver - which connects over the SQL wire protocol with a `pg_monitor`-role account - YugabyteDB's `prometheus` endpoints are plain HTTP. "Access setup" here means exposing each node's four metrics ports to the Collector: - `7000` - yb-master - `9000` - yb-tserver - `13000` - YSQL (Postgres-wire) - `12000` - YCQL (Cassandra-wire) Every node serves its own metrics, so the Collector scrapes each node, not a single load-balanced endpoint - the per-node `exported_instance` series is exactly what the liveness, clock-skew, and replication tiers depend on. ```yaml showLineNumbers title="docker-compose.yaml (excerpt)" services: yb1: # Seed node - the others join it image: yugabytedb/yugabyte:2025.2.3.2-b1 command: bin/yugabyted start --background=false ports: - "7000:7000" # yb-master metrics + UI - "9000:9000" # yb-tserver metrics + UI - "13000:13000" # YSQL metrics - "12000:12000" # YCQL metrics - "5433:5433" # YSQL (Postgres-wire) SQL port yb2: image: yugabytedb/yugabyte:2025.2.3.2-b1 command: bin/yugabyted start --background=false --join=yb1 yb3: image: yugabytedb/yugabyte:2025.2.3.2-b1 command: bin/yugabyted start --background=false --join=yb1 ``` On a secure deployment the endpoints serve over `https`. Expose them to the Collector over a trusted network path - the metrics carry no secrets, but the endpoints should not be public. The scrape config below uses `http`; switch the scheme to `https` and supply `tls` settings when the deployment is secure. Verify the endpoints serve metrics: ```bash showLineNumbers title="Verify access" # yb-master liveness view curl -s http://localhost:7000/prometheus-metrics | grep -E '^num_tablet_servers_live' # yb-tserver clock skew + DocDB curl -s http://localhost:9000/prometheus-metrics | grep -E '^hybrid_clock_skew' # YSQL throughput curl -s http://localhost:13000/prometheus-metrics | grep -E 'SQLProcessor_SelectStmt_count' ``` ### Configuration YugabyteDB serves metrics at the non-default `/prometheus-metrics` path on four ports, so set `metrics_path` explicitly and run one scrape job per endpoint type, each targeting every node on its port. Each node returns its own series, tagged with `exported_instance`. ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: prometheus: config: scrape_configs: - job_name: yb-master scrape_interval: 15s metrics_path: /prometheus-metrics # Not the default /metrics static_configs: - targets: - yb1:7000 # Each node's yb-master port - yb2:7000 - yb3:7000 - job_name: yb-tserver scrape_interval: 15s metrics_path: /prometheus-metrics static_configs: - targets: - yb1:9000 # Each node's yb-tserver port - yb2:9000 - yb3:9000 - job_name: yb-ysql scrape_interval: 15s metrics_path: /prometheus-metrics static_configs: - targets: - yb1:13000 # Each node's YSQL port - yb2:13000 - yb3:13000 - job_name: yb-ycql scrape_interval: 15s metrics_path: /prometheus-metrics static_configs: - targets: - yb1:12000 # Each node's YCQL port - yb2:12000 - yb3:12000 processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true # Set to false with TLS in production service: pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` YugabyteDB's `/prometheus-metrics` is whitelist-free - the receiver delivers the full 3,400+ metric surface across the four endpoints with no filter. To control metric volume in production, drop the Diagnostic tier with a `metric_relabel_configs` block on the scrape configs while keeping the Core and Operational series. If you do not run YCQL workloads, dropping the `yb-ycql` job is the simplest first cut. #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for scraped YugabyteDB metrics docker logs otel-collector 2>&1 | grep -iE "num_tablet_servers_live|hybrid_clock_skew" # Confirm a node is serving metrics on its yb-master endpoint curl -s http://localhost:7000/prometheus-metrics | grep -E '^num_tablet_servers_live' ``` Several YSQL counters only move once the cluster does work. Drive some load and confirm the statement counters rise and `num_tablet_servers_live` equals your node count: ```bash showLineNumbers title="Generate YSQL load" # YSQL speaks the Postgres wire protocol on port 5433 ysqlsh -h localhost -p 5433 -U yugabyte -c \ "CREATE TABLE IF NOT EXISTS kv (k int PRIMARY KEY, v int);" ysqlsh -h localhost -p 5433 -U yugabyte -c \ "INSERT INTO kv VALUES (1, 1) ON CONFLICT (k) DO UPDATE SET v = kv.v + 1; SELECT count(*) FROM kv;" ``` The load runs over the YSQL SQL port (`5433`), which is separate from the metrics scrape on ports `7000` / `9000` / `13000` / `12000`. Writes replicate across all nodes (RF-3), so the statement counters move on every tablet server. ### Troubleshooting #### No YugabyteDB metrics in the Collector **Cause**: The Collector cannot reach a node's metrics endpoint, or the scrape path is wrong. **Fix**: 1. Confirm the nodes are running and joined - the yb-master UI on `7000` lists the live tablet servers. 2. Verify each target's host and port (`7000` / `9000` / `13000` / `12000`) match the scrape configs. 3. Confirm `metrics_path` is set to `/prometheus-metrics` on every job. The receiver defaults to `/metrics`, which YugabyteDB does not serve. #### Metric name present but no datapoints **Cause**: The cluster is idle, so the YSQL counters have not moved since the last scrape. **Look at**: `handler_latency_yb_ysqlserver_SQLProcessor_SelectStmt_count` (should rise under load) and the YSQL connection counters (`yb_ysqlserver_active_connection_total`). `num_tablet_servers_live` should equal your node count even when idle. **Fix**: 1. Run YSQL against the cluster on the SQL port (`5433`) and re-check. #### A tablet server dropped out of the cluster **Cause**: A tablet server failed its heartbeats, was partitioned, or stalled on clock skew. **Look at**: `num_tablet_servers_dead` (should be 0) and `num_tablet_servers_live` (below the node count means one is gone). `hybrid_clock_skew` approaching `hybrid_clock_error` means the node is at risk of read restarts and stalls - check NTP/chrony on that host. **Fix**: 1. Restore network reachability or restart the node, then confirm `num_tablet_servers_live` returns to the node count. 2. Fix clock sync on the affected host if `hybrid_clock_skew` is high. #### Re-replication does not complete or followers lag **Cause**: A node is down long enough that the cluster is remote-bootstrapping tablet peers, or a replica cannot keep up with its leader. **Look at**: `num_tablet_peers_undergoing_rbs` (greater than 0 sustained means re-replication is not finishing) and `follower_lag_ms` (rising means a replica is falling behind). The Diagnostic `log_sync_latency_*` and the Raft `handler_latency_yb_consensus_*` series show whether replication RPC is the bottleneck. **Fix**: 1. Bring the missing node back or add capacity so remote bootstrap can finish and `num_tablet_peers_undergoing_rbs` returns to 0. 2. Investigate disk or network on the lagging replica if `follower_lag_ms` stays high. #### Writes are being rejected or the storage engine stalls **Cause**: A tablet has accumulated too many SST files, so DocDB throttles writes. **Look at**: `majority_sst_files_rejections` (writes rejected on the SST-file ceiling) and `rocksdb_stall_micros` / `intentsdb_rocksdb_stall_micros` (time the regular and intents stores stalled writes). `rocksdb_current_version_num_sst_files` shows the file count driving it. **Fix**: 1. Let compaction catch up or tune compaction settings if SST-file counts climb faster than they are merged. #### No metrics appearing in Scout **Cause**: Metrics are scraped but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the `prometheus` receiver and the `otlphttp/b14` exporter. ### FAQ #### Which ports and path does YugabyteDB use for metrics? Each node serves Prometheus-format metrics at `/prometheus-metrics` on four ports: `7000` (yb-master), `9000` (yb-tserver), `13000` (YSQL, Postgres-wire), and `12000` (YCQL, Cassandra-wire). The `prometheus` receiver runs one scrape job per endpoint type across all nodes. No SQL login is involved - the endpoints are HTTP, not the SQL wire protocol. #### Do I need a monitoring user like the PostgreSQL `pg_monitor` role? No. Unlike the PostgreSQL receiver, which connects over the SQL wire protocol with a `pg_monitor`-role account, YugabyteDB's Prometheus endpoints are plain HTTP and need no SQL credentials. Access setup is exposing the four HTTP ports to the Collector. #### How do I monitor all the nodes in a cluster? Add every node's `host:port` to each job's `static_configs.targets`. Each node serves only its own series, tagged with `exported_instance`, so scraping each node is what makes the per-node liveness, clock-skew, and replication tiers work. Do not scrape a single load-balanced endpoint - you would lose per-node visibility. #### What does `num_tablet_servers_live` report in YugabyteDB? The number of tablet servers the master currently considers live. In a healthy cluster it equals the node count; a drop signals a tablet server the cluster can no longer reach. Single-node PostgreSQL has no analogue - this is a distributed-cluster signal. #### Why monitor `hybrid_clock_skew` in YugabyteDB? YugabyteDB tolerates clock skew up to `hybrid_clock_error` (the `max_clock_skew_usec` setting, 500ms by default). Beyond that bound, reads restart and a node can stall, so tracking `hybrid_clock_skew` against `hybrid_clock_error` warns you before consistency is at risk. It is the signature distributed-SQL health signal with no single-node PostgreSQL equivalent. #### Does YugabyteDB also expose Cassandra-wire (YCQL) metrics? Yes. The YCQL API on port `12000` exposes parallel `handler_latency_yb_cqlserver_SQLProcessor_*` per-statement counters. The Configuration here scrapes it, but if you only run YSQL (Postgres-wire) workloads those counters stay near zero, and you can drop the `yb-ycql` scrape job to trim volume. ### Related Guides - [PostgreSQL Monitoring](./postgres.md) - The single-node PostgreSQL counterpart; the YSQL-layer signals here speak its wire protocol, and this guide is the distributed delta on it (tablet-server liveness, clock skew, re-replication). - [CockroachDB Monitoring](./cockroachdb.md) - The other distributed, PostgreSQL-wire-compatible SQL database, with the same Prometheus-scrape pattern and distributed signals. - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on tablet-server liveness and clock skew. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [PostgreSQL](./postgres.md), [CockroachDB](./cockroachdb.md), and other components. - **Fine-tune Collection**: Drop the Diagnostic tier (and the `yb-ycql` job if unused) in production with a `metric_relabel_configs` block to control volume; keep it available for incident investigation. --- ## ZooKeeper OpenTelemetry Monitoring - Health, Request Latency, and Collector Setup ## ZooKeeper The OpenTelemetry Collector's `zookeeperreceiver` collects 16 metrics from ZooKeeper 3.5+, spanning active connections, request latency, znode counts, watches, file descriptors, and the `ruok` health check. The receiver connects over plain TCP to the client port and parses the `mntr` and `ruok` four-letter-word (4LW) commands - no exporter sidecar needed. This guide configures the receiver, whitelists the required 4LW commands, and ships metrics to base14 Scout. ### Prerequisites | Requirement | Minimum | Recommended | | ---------------------- | ------- | ------------ | | ZooKeeper | 3.5 | 3.9+ (3.9.5) | | OTel Collector Contrib | 0.90.0 | 0.153.0 | | base14 Scout | Any | - | Before starting: - The ZooKeeper client port (2181) must be reachable from the host running the Collector. - The `mntr` and `ruok` four-letter-word commands must be whitelisted - ZooKeeper 3.5.3+ disables them by default (see [Access Setup](#access-setup)). - ZooKeeper must use the default metrics provider, not `PrometheusMetricsProvider`; with the Prometheus provider the `mntr` format changes and the receiver cannot parse it. - A Scout account and OTLP endpoint. - OTel Collector installed - see [Docker Compose Setup](../collector-setup/docker-compose-example.md). ### What You'll Monitor Metrics are grouped into three tiers by how you use them. Scrape Core always, alert on Operational, and reach for Diagnostic during an incident or capacity review. The `zookeeperreceiver` connects over plain TCP and reads the `mntr` and `ruok` 4LW output, so a few surface facts shape what you see: - **ZooKeeper has its own health signal.** There is no `up` series on this surface (that belongs to the Prometheus receiver), but `ruok` returns `imok`, surfaced as `zookeeper.ruok` (1 = imok). Liveness is the receiver scraping successfully *plus* `zookeeper.ruok` = 1. There is no uptime counter here. - **The 4LW commands must be whitelisted.** ZooKeeper 3.5.3+ disables `mntr` and `ruok` by default; without whitelisting them the receiver gets nothing. - **Three metrics are role- or condition-gated.** `zookeeper.follower.count` and `zookeeper.sync.pending` are leader-only and emit no series on a standalone or follower node; `zookeeper.fsync.exceeded_threshold.count` is absent until a fsync first exceeds the warn threshold. Leave them enabled - they populate under the right role or condition. - **Resource attributes.** The receiver stamps `server.state` (leader / follower / standalone) and `zk.version` on every metric. - **The default metrics provider is required.** If ZooKeeper's `metricsProvider.className` is `PrometheusMetricsProvider`, the `mntr` format changes and the receiver cannot parse it. #### Core - is it up and serving | Metric | What it tells you | |---|---| | `zookeeper.ruok` | Health response (1 = imok) - the headline liveness signal. There is no `up` on this surface; liveness is scrape success plus `ruok` = 1. | | `zookeeper.connection.active` | Active client connections - client load. | | `zookeeper.latency.avg` | Average request-processing latency (ms) - the serving KPI. | | `zookeeper.znode.count` | Total znodes - data-tree size / state. | #### Operational - what to alert on | Metric | What it tells you | |---|---| | `zookeeper.latency.max` | Worst-case request latency (ms) - tail latency. | | `zookeeper.request.active` | In-flight (outstanding) requests - backlog / saturation. | | `zookeeper.watch.count` | Watches set - watch storms and per-watch memory. | | `zookeeper.packet.count` | Packets received/sent by `direction` - protocol throughput. | | `zookeeper.file_descriptor.open` / `zookeeper.file_descriptor.limit` | Open file descriptors against the limit - fd saturation. | | `zookeeper.fsync.exceeded_threshold.count` | Fsyncs exceeding the warn threshold - txn-log disk too slow. Silent until the first breach. | | `zookeeper.follower.count` / `zookeeper.sync.pending` | Followers connected to the leader and pending leader→follower syncs. Leader-only. | #### Diagnostic - for investigation and tuning | Metric | What it tells you | |---|---| | `zookeeper.latency.min` | Best-case request latency (ms). | | `zookeeper.data_tree.ephemeral_node.count` | Ephemeral znodes (session-tied) - drops when sessions close. | | `zookeeper.data_tree.size` | Approximate data-tree size in bytes. | Full metric reference: [OTel ZooKeeper Receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/zookeeperreceiver). ### Key Alerts to Configure Threshold guidance for the most useful Core and Operational series. Most are relative to your own baseline; `zookeeper.ruok`, the fsync counter, and the follower count read ZooKeeper's own state and events rather than an invented absolute. Tune to your workload; these are starting points. | Alert | Condition | Why it matters | |---|---|---| | ZooKeeper unhealthy | `zookeeper.ruok` != 1, or the receiver produces no data for > 1m | `ruok` is ZooKeeper's own health flag; not `imok` (or no data) means the node is unhealthy. Check the process, disk, and 4LW whitelist. | | Request latency rising | `zookeeper.latency.avg` / `zookeeper.latency.max` rising vs baseline | Slow request processing - check disk, GC, and load. | | Outstanding requests | `zookeeper.request.active` rising vs baseline | Request backlog building - correlate with latency and connections. | | FD saturation | `zookeeper.file_descriptor.open` approaching `zookeeper.file_descriptor.limit` | Approaching the descriptor ceiling - raise the ulimit before connections are refused. | | Fsync too slow | `rate(zookeeper.fsync.exceeded_threshold.count)` > 0 | The txn-log disk cannot keep up with fsync; move the `dataLogDir` to faster storage. | | Followers missing | `zookeeper.follower.count` below the expected ensemble size (on the leader) | A member is disconnected - quorum is at risk. Check the down node and network. | ### Access Setup The receiver connects to ZooKeeper over plain TCP on the client port - no authentication or monitoring user is required. It does need the `mntr` and `ruok` four-letter-word commands, which ZooKeeper 3.5.3+ disables by default. Whitelist them in `zoo.cfg`: ```text showLineNumbers title="zoo.cfg" 4lw.commands.whitelist=mntr,ruok,srvr ``` For Docker deployments, set the environment variable instead: ```bash showLineNumbers ZOO_4LW_COMMANDS_WHITELIST=mntr,ruok,srvr ``` Restart ZooKeeper after changing the whitelist, then verify the commands respond: ```bash showLineNumbers title="Verify 4LW access" # Test mntr (metrics) echo "mntr" | nc localhost 2181 # Test ruok (health check) - should return "imok" echo "ruok" | nc localhost 2181 ``` ### Configuration ```yaml showLineNumbers title="config/otel-collector.yaml" receivers: zookeeper: endpoint: localhost:2181 # Change to your :2181 collection_interval: 10s metrics: # Connections zookeeper.connection.active: enabled: true # Latency zookeeper.latency.avg: enabled: true zookeeper.latency.max: enabled: true zookeeper.latency.min: enabled: true # Data tree zookeeper.znode.count: enabled: true zookeeper.data_tree.ephemeral_node.count: enabled: true zookeeper.data_tree.size: enabled: true zookeeper.watch.count: enabled: true # Packets zookeeper.packet.count: enabled: true # Requests zookeeper.request.active: enabled: true # Resources zookeeper.file_descriptor.open: enabled: true zookeeper.file_descriptor.limit: enabled: true # Health zookeeper.ruok: enabled: true zookeeper.fsync.exceeded_threshold.count: enabled: true # Leader-only (only emitted when server is a leader) zookeeper.follower.count: enabled: true zookeeper.sync.pending: enabled: true processors: resource: attributes: - key: deployment.environment.name value: ${env:ENVIRONMENT} action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [zookeeper] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment Variables ```bash showLineNumbers title=".env" ENVIRONMENT=your_environment SERVICE_NAME=your_service_name OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` ### Verify the Setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Check Collector logs for the ZooKeeper receiver docker logs otel-collector 2>&1 | grep -i "zookeeper" # Verify mntr is responding echo "mntr" | nc localhost 2181 # Verify ruok returns "imok" echo "ruok" | nc localhost 2181 ``` ### Troubleshooting #### Connection refused on port 2181 **Cause**: The Collector cannot reach ZooKeeper at the configured endpoint. **Fix**: 1. Verify ZooKeeper is running: `echo "ruok" | nc localhost 2181` should return `imok`. 2. Confirm the client port in `zoo.cfg` matches the receiver endpoint. 3. Check firewall rules if the Collector runs on a separate host. #### `mntr` command not whitelisted **Cause**: ZooKeeper 3.5.3+ disables `mntr` by default, so the receiver reads nothing. **Fix**: 1. Add `4lw.commands.whitelist=mntr,ruok,srvr` to `zoo.cfg`. 2. For Docker: set `ZOO_4LW_COMMANDS_WHITELIST=mntr,ruok,srvr`. 3. Restart ZooKeeper after changing the whitelist. #### No metrics appearing in Scout **Cause**: Metrics are collected but not exported. **Fix**: 1. Check Collector logs for export errors: `docker logs otel-collector`. 2. Verify `OTEL_EXPORTER_OTLP_ENDPOINT` is set correctly. 3. Confirm the pipeline includes both the receiver and the exporter. #### Follower and sync metrics missing **Cause**: `zookeeper.follower.count` and `zookeeper.sync.pending` are leader-only - they emit no series on a standalone or follower node. **Look at**: `server.state` (a resource attribute) to confirm the node's role, and `zookeeper.data_tree.ephemeral_node.count` to check session-tied state during the same investigation. **Fix**: 1. These metrics do not appear on standalone or follower nodes. 2. Verify the server role: `echo "mntr" | nc localhost 2181 | grep zk_server_state`. 3. In a cluster, point the Collector at the leader node to collect these metrics. ### FAQ #### Does this work with ZooKeeper running in Kubernetes? Yes. Set `endpoint` to the ZooKeeper service DNS (e.g., `zookeeper.default.svc.cluster.local:2181`). The Collector can run as a sidecar or DaemonSet. Make sure the 4LW whitelist is configured in the StatefulSet pod spec (`ZOO_4LW_COMMANDS_WHITELIST=mntr,ruok,srvr`), or the receiver reads nothing. #### How do I monitor a ZooKeeper ensemble? Add a receiver block per node with distinct names: ```yaml showLineNumbers title="config/otel-collector.yaml (ensemble)" receivers: zookeeper/node1: endpoint: zookeeper-1:2181 zookeeper/node2: endpoint: zookeeper-2:2181 zookeeper/node3: endpoint: zookeeper-3:2181 ``` Then include all of them in the pipeline: `receivers: [zookeeper/node1, zookeeper/node2, zookeeper/node3]`. The leader-only metrics emit from whichever node is currently the leader. #### Does this receiver work with the ZooKeeper Prometheus metrics provider? No. If `metricsProvider.className` is set to `PrometheusMetricsProvider`, the `mntr` output format changes and the receiver cannot parse it. Use the default metrics provider with this receiver. #### What resource attributes are added to metrics? The receiver stamps `server.state` (leader, follower, or standalone) and `zk.version` as resource attributes on every emitted metric. ### Related Guides - [OTel Collector Configuration](../collector-setup/otel-collector-config.md) - Advanced collector configuration. - [Docker Compose Setup](../collector-setup/docker-compose-example.md) - Run the Collector locally. - [Kubernetes Helm Setup](../collector-setup/kubernetes-helm-setup.md) - Production deployment. - [Creating Alerts](../../guides/creating-alerts-with-logx.md) - Alert on ZooKeeper metrics. - [Kafka Monitoring](./kafka.md) - The broker ZooKeeper most often coordinates. - [Redis Monitoring](./redis.md) - Another stateful service to put on Scout. ### What's Next? - **Create Dashboards**: Explore pre-built dashboards or build your own. See [Create Your First Dashboard](../../guides/create-your-first-dashboard.md). - **Monitor More Components**: Add monitoring for [Kafka](./kafka.md), [Redis](./redis.md), and other components. - **Fine-tune Collection**: Adjust `collection_interval` based on your ensemble size and workload. --- ## AWS Amazon MQ Monitoring - ActiveMQ & RabbitMQ Metrics via CloudWatch ### Overview This guide covers collecting Amazon MQ broker and queue metrics (connection counts, message counts, CPU, and memory) via CloudWatch Metrics Stream, plus broker logs. We recommend CloudWatch Metrics Stream over Prometheus exporters: it needs no per-broker exporter and delivers metrics to Scout in 3-5 minutes end-to-end. ### What You'll Monitor Amazon MQ monitoring combines CloudWatch broker metrics with optional RabbitMQ receiver metrics for node-level internals: **CloudWatch Metrics Stream (AWS/AmazonMQ):** | Metric | Engine | What it tells you | | ------ | ------ | ----------------- | | `CpuUtilization` | Both | Broker instance CPU usage (%) | | `HeapUsage` | ActiveMQ | JVM heap used (%) | | `RabbitMQMemUsed` / `RabbitMQMemLimit` | RabbitMQ | Memory used vs the high-watermark limit | | `RabbitMQDiskFree` / `RabbitMQDiskFreeLimit` | RabbitMQ | Free disk vs the low-watermark limit | | `RabbitMQFdUsed` | RabbitMQ | File descriptors in use | | `StorePercentUsage` | ActiveMQ | Percent of the message store consumed | | `MemoryPercentUsage` / `TempPercentUsage` | ActiveMQ | Percent of memory / temp store used | | `ConsumerCount` / `ProducerCount` | Both | Consumers / producers attached to a queue | | `MessageCount` / `QueueSize` | Both | Messages currently held in a queue | | `MessageReadyCount` | RabbitMQ | Messages ready for delivery (backlog) | | `MessageUnacknowledgedCount` | RabbitMQ | Delivered but not yet acknowledged | | `EnqueueCount` / `DequeueCount` | ActiveMQ | Messages published / consumed per period | | `CurrentConnectionsCount` | Both | Open client connections to the broker | | `NetworkIn` / `NetworkOut` | Both | Network throughput (bytes) | **OTel RabbitMQ receiver (node internals, RabbitMQ only):** | Metric | What it tells you | | ------ | ----------------- | | `rabbitmq.node.mem_used` / `rabbitmq.node.mem_limit` | Node memory used vs its limit | | `rabbitmq.node.mem_alarm` | Whether the memory alarm has tripped | | `rabbitmq.node.disk_free` / `rabbitmq.node.disk_free_limit` | Node free disk vs its limit | | `rabbitmq.node.disk_free_alarm` | Whether the disk alarm has tripped | | `rabbitmq.node.fd_used` / `rabbitmq.node.fd_total` | File descriptors used vs available | | `rabbitmq.node.sockets_used` / `rabbitmq.node.sockets_total` | Sockets used vs available | | `rabbitmq.node.proc_used` / `rabbitmq.node.proc_total` | Erlang processes used vs the limit | ### Prerequisites | Requirement | Minimum | Recommended | | ----------- | ------- | ----------- | | Amazon MQ | ActiveMQ 5.x or RabbitMQ 3.x | RabbitMQ 3.13 | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | | AWS permissions | CloudWatch, Amazon Data Firehose, S3, CloudWatch Logs | - | Before starting: - An Amazon MQ broker (ActiveMQ or RabbitMQ) running and serving traffic. - CloudWatch Metrics Stream infrastructure set up (see Step 1). - For the RabbitMQ receiver: the broker's HTTPS management endpoint reachable from the Collector, plus management-API credentials. ### Collecting Amazon MQ Metrics For collecting Amazon MQ metrics, we recommend using **CloudWatch Metrics Stream** instead of Prometheus exporters. CloudWatch Metrics Stream provides: - **Faster delivery**: 3-5 minutes end-to-end vs 5+ minutes with polling. - **Lower cost**: No need to run dedicated exporters. - **Better scalability**: Native AWS service integration. - **Automatic metric discovery**: No need to manually configure metric lists. #### Step 1: Set up CloudWatch Metrics Stream Follow our comprehensive [CloudWatch Metrics Stream guide](cloudwatch-metrics/cloudwatch-metrics-stream.md) to set up the infrastructure. #### Step 2: Configure Amazon MQ metrics filtering When configuring your CloudWatch Metrics Stream in **Step 3** of the setup guide, make sure to: 1. **Select specific namespaces** instead of "All namespaces" 2. **Choose only AWS/AmazonMQ** from the namespace list 3. This ensures you only collect Amazon MQ metrics, reducing costs and data volume #### Step 3: Create OTel Collector config for RabbitMQ metrics (Optional) If you're using RabbitMQ as your broker engine and need detailed broker-specific metrics, create `amazon-mq-metrics-collection-config.yaml`. Set `RABBITMQ_ENDPOINT` to the broker's HTTPS management URL, for example `https://b-xxxxx.mq..amazonaws.com` (port 443): ```yaml receivers: rabbitmq: endpoint: ${env:RABBITMQ_ENDPOINT} username: ${env:RABBITMQ_USERNAME} password: ${env:RABBITMQ_PASSWORD} collection_interval: 10s metrics: rabbitmq.node.disk_free: enabled: true rabbitmq.node.disk_free_limit: enabled: true rabbitmq.node.disk_free_alarm: enabled: true rabbitmq.node.mem_used: enabled: true rabbitmq.node.mem_limit: enabled: true rabbitmq.node.mem_alarm: enabled: true rabbitmq.node.fd_used: enabled: true rabbitmq.node.fd_total: enabled: true rabbitmq.node.sockets_used: enabled: true rabbitmq.node.sockets_total: enabled: true rabbitmq.node.proc_used: enabled: true rabbitmq.node.proc_total: enabled: true rabbitmq.node.disk_free_details.rate: enabled: true rabbitmq.node.fd_used_details.rate: enabled: true rabbitmq.node.mem_used_details.rate: enabled: true rabbitmq.node.proc_used_details.rate: enabled: true rabbitmq.node.sockets_used_details.rate: enabled: true exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics/amazon_mq: receivers: [rabbitmq] exporters: [otlphttp/b14] ``` > **Note**: CloudWatch Metrics Stream will automatically deliver AWS/AmazonMQ > metrics (CPU utilization, connection counts, message counts, etc.), while the > RabbitMQ receiver collects detailed broker-specific metrics if needed. ### Collecting Amazon MQ Logs The log collection of Amazon MQ requires specifying the list of log group names. From the AWS CloudWatch console, please find the log group(s) relevant to the integration. #### Create the Collector config file ```yaml receivers: awscloudwatch/amazon_mq_logs: region: ${env:AWS_REGION} logs: poll_interval: 1m groups: named: # replace with your Amazon MQ log group name /aws/amazonmq/: processors: attributes/add_source_amazon_mq: actions: - key: source value: "amazonMQ" action: insert batch: send_batch_size: 10000 send_batch_max_size: 11000 timeout: 10s exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: logs/amazonmq: receivers: [awscloudwatch/amazon_mq_logs] processors: [attributes/add_source_amazon_mq, batch] exporters: [otlphttp/b14] ``` The collector configs above export to Scout through the `otlphttp/b14` exporter. Set `OTEL_EXPORTER_OTLP_ENDPOINT` and the OAuth2 credentials as shown in the [Scout exporter guide](../../collector-setup/scout-exporter.md). ### Verify the setup After deploying, generate traffic on the broker, then confirm telemetry is flowing: 1. In Scout, check for the CloudWatch metrics, named `amazonaws.com/AWS/AmazonMQ/` (CPU, connection counts, message counts). 2. If you enabled the RabbitMQ receiver, check for the `rabbitmq.*` metrics. 3. For logs, confirm records appear with `source = amazonMQ`. Allow 5-10 minutes for the first metrics to arrive through the stream. ### Key alerts to configure Once telemetry is flowing, set up alerts on the signals that predict broker trouble: | Metric | Warning | Critical | Why | | ------ | ------- | -------- | --- | | `MessageReadyCount` (RabbitMQ) | rising trend | sustained growth | Consumers are falling behind producers | | `MessageUnacknowledgedCount` (RabbitMQ) | > 0 and growing | sustained | Consumers receive but fail to acknowledge messages | | `ConsumerCount` on an active queue | dropping | 0 | Nothing is draining the queue | | `CpuUtilization` | > 70% | > 85% | CPU pressure slows message throughput | | `RabbitMQMemUsed` / `HeapUsage` | > 70% | > 85% | Memory pressure triggers broker flow control | | `StorePercentUsage` (ActiveMQ) | > 70% | > 85% | A full message store blocks producers | | `RabbitMQDiskFree` (RabbitMQ) | near the limit | at the limit | The disk alarm blocks all publishing | CloudWatch Metrics Stream adds 3-5 minutes of latency, so treat these as trend and capacity alerts, not sub-minute failure detection. ### Troubleshooting #### AWS/AmazonMQ metrics not appearing in Scout **Cause**: Metrics Stream isn't active or isn't filtered to the Amazon MQ namespace. **Fix**: 1. In CloudWatch > Metrics > Streams, verify the stream is active 2. Confirm the namespace filter includes `AWS/AmazonMQ` 3. Check that Firehose delivery is succeeding (look at the S3 error prefix) 4. Allow 5-10 minutes for initial metrics to flow #### RabbitMQ receiver shows no metrics **Cause**: The Collector can't reach the broker's management endpoint. **Fix**: 1. Confirm `RABBITMQ_ENDPOINT` is the HTTPS management URL (`https://b-xxxxx.mq..amazonaws.com`, port 443) 2. Verify the management-API username and password 3. Check the broker's security group allows the Collector's IP 4. Ensure the RabbitMQ management plugin is enabled on the broker #### Broker logs not reaching Scout **Cause**: Wrong log group name or region. **Fix**: 1. Set the real Amazon MQ log group name under `groups.named` 2. Confirm `AWS_REGION` matches the broker's region 3. Verify the Collector's IAM role can read CloudWatch Logs 4. Enable general or audit logging on the broker if the log group is empty ### FAQ #### How do I monitor AWS Amazon MQ with OpenTelemetry? Use CloudWatch Metrics Stream for broker metrics (CPU, memory, connections, message counts) and, for RabbitMQ, add the OTel RabbitMQ receiver for node-level internals. Both feed into base14 Scout. #### What Amazon MQ metrics does CloudWatch collect? AWS/AmazonMQ metrics including `CpuUtilization`, `HeapUsage` (ActiveMQ), `RabbitMQMemUsed` and `RabbitMQDiskFree` (RabbitMQ), `ConsumerCount`, `ProducerCount`, `MessageCount`, `MessageReadyCount`, and `MessageUnacknowledgedCount`, plus connection and network metrics. #### Should I use CloudWatch Metrics Stream or Prometheus for Amazon MQ? CloudWatch Metrics Stream is recommended: no per-broker exporter, native AWS integration, and 3-5 minute end-to-end delivery. Add the RabbitMQ receiver only when you need node-level internals. #### How do I collect Amazon MQ broker logs with OpenTelemetry? Use the AWS CloudWatch Logs receiver in the Collector with your Amazon MQ log group name. Enable general or audit logging on the broker first so the group has data. #### How do I set up alerts for Amazon MQ? Route metrics through CloudWatch Metrics Stream to Scout, then alert on rising `MessageReadyCount`, `ConsumerCount` dropping to zero, `CpuUtilization` above 85%, memory or heap above 85%, and `StorePercentUsage` above 85%. #### Can I monitor both RabbitMQ and ActiveMQ with OpenTelemetry? Yes. CloudWatch Metrics Stream covers both engines. RabbitMQ additionally supports the OTel RabbitMQ receiver for node-level metrics; ActiveMQ internals come from CloudWatch or JMX. ### Related Guides - Set up AWS metrics streaming with [CloudWatch Metrics Stream Setup](./cloudwatch-metrics/cloudwatch-metrics-stream.md). - [RabbitMQ Monitoring](../../component/rabbitmq.md) - Self-hosted RabbitMQ monitoring guide - [OTel Collector Configuration](../../collector-setup/otel-collector-config.md) for advanced collector configuration --- ## AWS VPC Flow Logs to OpenTelemetry ## Send AWS VPC Flow Logs You can send AWS VPC Flow Logs through an S3 bucket to a Scout endpoint using an AWS Lambda function. This approach uses S3 Event Notifications to trigger the Lambda function whenever a new Flow Log file arrives in the bucket. ### Prerequisites - AWS VPC services (S3, Lambda, IAM). - Scout authentication credentials - Scout Collector has been configured with an OTLP receiver endpoint (HTTP or gRPC) ready to accept logs. --- ### Step 1: Configure VPC Flow Logs to Deliver to S3 1. **Navigate to VPC:** Go to the AWS VPC console. 1. **Select VPC:** Choose the VPC for which you want to enable Flow Logs. 1. **Flow Logs Tab:** Go to the "Flow Logs" tab. 1. **Create Flow Log:** Click "Create flow log". 1. **Configure Filter:** Choose the traffic to capture (Accepted, Rejected, or All). 1. **Maximum Aggregation Interval:** Select an interval (e.g., 1 minute, 5 minutes). Shorter intervals mean more files and potentially more Lambda invocations. 1. **Destination:** Select **"Send to an S3 bucket"**. 1. **S3 Bucket ARN:** Specify the ARN of the S3 bucket where logs should be delivered (e.g., `arn:aws:s3:::your-vpc-flow-log-bucket`). Create the bucket if it doesn't exist. _Ensure the bucket policy grants `vpc-flow-logs.amazonaws.com` permissions to `PutObject`._ 1. **Log Format:** Choose either the "AWS default format" or a "Custom format". **Note down the fields and their order if using Custom format**, as you'll need this for parsing in the Lambda. The default format is space-delimited: ```csv version account-id interface-id srcaddr dstaddr srcport dstport protocol packets bytes start end action log-status ``` 1. **Log file format:** Select text (default). Parquet is also an option but requires different handling in Lambda. 1. **Partitioning:** Decide if you want logs partitioned by time (Hourly/Daily). This also affects the S3 object key structure and potentially how you configure the S3 trigger. 1. **Create Flow Log:** Confirm and create. --- ### Step 2: Create the Lambda Function (Python Example) 1. **Create Function:** Go to the AWS Lambda console and click "Create function". 2. **Author from Scratch:** Choose "Author from scratch". 3. **Function Name:** Give it a descriptive name (e.g., `vpc-flow-log-s3-to-otlp-processor`). 4. **Runtime:** Select a runtime like **Python 3.10** (or newer). 5. **Architecture:** Choose `x86_64` or `arm64`. 6. **Permissions:** Choose "Create a new role with basic Lambda permissions". We will modify this role later (Step 3). 7. **Create Function:** Click "Create function". 8. **Write Lambda Code:** Replace the template code with the following structure (this is a conceptual outline; you'll need to fill in the parsing and OTLP details): ```python import boto3 import os import gzip import logging from urllib.parse import unquote_plus # --- OpenTelemetry Imports (Add these to requirements.txt/Layer) --- from opentelemetry import trace, logs from opentelemetry.sdk.trace import TracerProvider from opentelemetry.sdk.logs import LoggerProvider, LoggingHandler from opentelemetry.sdk.logs.export import BatchLogRecordProcessor from opentelemetry.exporter.otlp.proto.http.log_exporter import OTLPLogExporter # or use OTLPLogExporterGRPC from opentelemetry.sdk.resources import Resource from opentelemetry_semantic_conventions.resource import ResourceAttributes logger = logging.getLogger() logger.setLevel(logging.INFO) # -- OTel Configuration (Best practice: Initialize outside handler for reuse) -- # Configure resource attributes for your logs resource = Resource(attributes={ ResourceAttributes.SERVICE_NAME: "vpc-flow-log-processor", # Add other relevant attributes like cloud provider, region, etc. ResourceAttributes.CLOUD_PROVIDER: "aws", ResourceAttributes.CLOUD_REGION: os.environ.get("AWS_REGION", "unknown"), # ResourceAttributes.HOST_ID: ... # May not apply directly in Lambda }) # Configure OTLP Exporter (using environment variables is recommended) otlp_endpoint = os.environ.get("OTEL_EXPORTER_OTLP_ENDPOINT", "") otlp_headers = os.environ.get("OTEL_EXPORTER_OTLP_HEADERS", "") # e.g., "key1=value1,key2=value2" headers_dict = dict(item.split("=") for item in otlp_headers.split(",") if "=" in item) if otlp_headers else {} # Use OTLP/HTTP Exporter otlp_exporter = OTLPLogExporter( endpoint=otlp_endpoint, headers=headers_dict # Optional: certificate_file=..., timeout=... ) # Setup LoggerProvider with the exporter and resource logger_provider = LoggerProvider(resource=resource) log_processor = BatchLogRecordProcessor(otlp_exporter) logger_provider.add_log_record_processor(log_processor) # Create a dedicated OTel logger otel_log_emitter = logs.get_logger(__name__, logger_provider=logger_provider) # --- AWS SDK Client --- s3_client = boto3.client('s3') # --- Flow Log Parsing Configuration (Adjust based on your Flow Log Format) --- # Example for AWS Default Format DEFAULT_FIELDS = [ "version", "account_id", "interface_id", "srcaddr", "dstaddr", "srcport", "dstport", "protocol", "packets", "bytes", "start", "end", "action", "log_status" ] FIELD_TYPES = { # Optional: Specify types for potential conversion "srcport": int, "dstport": int, "packets": int, "bytes": int, "start": int, "end": int } def parse_flow_log_line(line, fields=DEFAULT_FIELDS, types=FIELD_TYPES): """Parses a single space-delimited flow log line.""" values = line.strip().split() if len(values) != len(fields): logger.warning(f"Skipping line due to field count mismatch: {line}") return None log_data = {} for i, field in enumerate(fields): value = values[i] if value == "-": # Handle null values represented by "-" log_data[field] = None continue try: target_type = types.get(field) if target_type: log_data[field] = target_type(value) else: log_data[field] = value except ValueError: logger.warning(f"Skipping field '{field}' due to type conversion error: {value}") log_data[field] = value # Keep as string if conversion fails return log_data def lambda_handler(event, context): logger.info(f"Received event: {event}") for record in event.get('Records', []): s3_info = record.get('s3', {}) bucket_name = s3_info.get('bucket', {}).get('name') object_key = s3_info.get('object', {}).get('key') if not bucket_name or not object_key: logger.warning("Missing bucket name or object key in S3 event record.") continue # S3 keys can have URL encoding (e.g., spaces become '+') object_key = unquote_plus(object_key) logger.info(f"Processing object {object_key} from bucket {bucket_name}") try: # Get the flow log file from S3 response = s3_client.get_object(Bucket=bucket_name, Key=object_key) body = response['Body'] # Decompress if it's a .gz file if object_key.endswith('.gz'): content = gzip.decompress(body.read()).decode('utf-8') else: content = body.read().decode('utf-8') lines = content.splitlines() header = lines[0] # First line is usually the header defining fields log_lines = lines[1:] # Actual log data # Simple check if header matches expected default fields # (customize if needed) if header != ' '.join(DEFAULT_FIELDS): logger.warning(f"Log header '{header}' does not match expected default fields. Parsing might be incorrect.") # Potentially parse the header here to dynamically # determine fields if needed logger.info(f"Processing {len(log_lines)} log entries from {object_key}") # Process and send logs in batches (managed by BatchLogRecordProcessor) for line in log_lines: if not line or line.isspace(): continue parsed_log = parse_flow_log_line(line) if parsed_log: # Emit the log using the OpenTelemetry Logger # Convert timestamp if needed # (Flow log 'start'/'end' are Unix seconds) # OTel expects nanoseconds since epoch timestamp_ns = parsed_log.get('start', 0) * 1_000_000_000 otel_log_emitter.emit(logs.LogRecord( timestamp=timestamp_ns, observed_timestamp=timestamp_ns, severity_text=parsed_log.get('log_status'), severity_number=logs.SeverityNumber.INFO, body=f"VPC Flow Log: {parsed_log.get('srcaddr')}:{parsed_log.get('srcport')} -> {parsed_log.get('dstaddr')}:{parsed_log.get('dstport')}", attributes=parsed_log )) logger.info(f"Finished processing {object_key}. Logs submitted to OTLP exporter.") except Exception as e: logger.error(f"Error processing object {object_key} from bucket {bucket_name}: {e}") # Consider adding to a Dead Letter Queue (DLQ) # or raising exception for Lambda retry # Raising an exception might re-process the entire file # if not handled carefully # Explicitly flush the batch processor at the end of the invocation # Note: If function times out, flush might not complete. Adjust timeout accordingly. logger_provider.force_flush() return {'statusCode': 200, 'body': 'Processing complete'} ``` 1. **Create Deployment Package/Layer:** - Create a requirements.txt file in your project directory: ```plaintext boto3 # Usually included in Lambda runtime, but good practice opentelemetry-api opentelemetry-sdk opentelemetry-exporter-otlp-proto-http # Or -grpc if using gRPC opentelemetry-semantic-conventions ``` - Install dependencies into a package directory: `pip install -r requirements.txt -t ./package` - Create a zip file containing the contents of the package directory and your lambda_function.py file. ```bash cd package && zip -r ../deployment_package.zip . && cd .. zip -g deployment_package.zip lambda_function.py ``` - Alternatively, create a Lambda Layer containing the dependencies and upload it separately. Then add the layer to your function. 1. **Upload Code:** Upload the deployment_package.zip file to your Lambda function via the console or AWS CLI. 1. **Configure Environment Variables:** - BASE14_OTLP_ENDPOINT: Your OTLP endpoint URL (e.g. [https://otel.play.b14.dev/01jm94npk4h8ys63x1kzw2bjes/otlp](https://otel.play.b14.dev/01jm94npk4h8ys63x1kzw2bjes/otlp)). - AWS_REGION: Set this to the region your function is running in (e.g., us-east-1). 1. **Adjust Timeout and Memory:** VPC flow log files can be large. Increase the function's **Timeout** (e.g., to 1-5 minutes) and **Memory** (e.g., 512MB or more) under "General configuration" as needed. --- ### Step 3: Configure IAM Role Permissions 1. **Find Role:** Go to the IAM console -> Roles. Find the role automatically created for your Lambda function (e.g., `vpc-flow-log-s3-to-otlp-processor-role-xxxxxx`). 2. **Attach Policies:** - **S3 Read Access:** Click "Add permissions" -> "Attach policies". Search for and attach `AmazonS3ReadOnlyAccess` OR create a more specific inline policy granting `s3:GetObject` permissions only for your specific VPC Flow Log bucket (`arn:aws:s3:::your-vpc-flow-log-bucket/*`). ```JSON // Example Inline Policy for S3 Read { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": "s3:GetObject", "Resource": "arn:aws:s3:::your-vpc-flow-log-bucket/*" } ] } ``` - **Basic Execution Role:** Ensure the AWSLambdaBasicExecutionRole policy (or equivalent for CloudWatch Logs `logs:CreateLogGroup`, `logs:CreateLogStream`, `logs:PutLogEvents`) is attached (usually added by default). --- ### Step 4: Configure S3 Event Notification Trigger 1. **Navigate to S3 Bucket:** Go to the S3 console and select your VPC Flow Log bucket. 2. **Properties Tab:** Go to the "Properties" tab. 3. **Event Notifications:** Scroll down to "Event notifications" and click "Create event notification". 4. **Event Name:** Give it a name (e.g., trigger-flow-log-lambda). 5. **Prefix (Optional but Recommended):** Specify the S3 prefix where your flow logs are stored (e.g., `AWSLogs/`). This prevents triggering on other files. Check your S3 bucket to see the exact path structure created by Flow Logs. 6. **Suffix (Optional but Recommended):** Specify `.gz` (or `.log` if uncompressed) to only trigger on log files. 7. **Event Types:** Select `s3:ObjectCreated:Put` or `s3:ObjectCreated:CompleteMultipartUpload` (or just All object create events). `Put` is usually sufficient for Flow Logs. 8. **Destination:** Choose "Lambda function". 9. **Lambda Function:** Select the Lambda function you created (`vpc-flow-log-s3-to-otlp-processor`). 10. **Save Changes:** Click "Save changes". S3 will automatically attempt to add the necessary permissions to the Lambda function to allow S3 to invoke it. --- ### Step 5: Test and Monitor 1. **Wait for Logs:** Allow some time for VPC Flow Logs to generate new files in the S3 bucket. 2. **Check Lambda Invocations:** Monitor the Lambda function in the Scout Dashboards under "Library" > "Logs View" 3. **Check Lambda Logs:** Examine the Log Group associated with your Lambda function for detailed execution logs, including any print statements or error messages. Look for lines like "Processing object..." and "Finished processing...". --- This detailed setup provides a robust way to process VPC Flow Logs from S3 using Lambda and forward them via OTLP. We can further adjust parsing logic, OTel configuration, and IAM permissions based on your specific Flow Log format and environment. ### FAQ #### Why go through S3 instead of sending VPC Flow Logs straight to a collector? VPC Flow Logs have no OTLP delivery option, so something has to read the files and forward them. This guide uses S3 as the destination and an S3 event notification to invoke the Lambda function for each new file, so there is no polling and no long-running process to operate. #### How does the Lambda function authenticate to the Scout collector? Set `OTEL_EXPORTER_OTLP_HEADERS` on the function, for example `Authorization=Bearer `. The handler parses that variable into request headers for the OTLP log exporter, so no credentials are hard-coded. #### What happens when a flow log file is large? The handler reads and decompresses the whole object into memory before parsing, so size the function for your largest flow log file. Records are exported through a `BatchLogRecordProcessor`, so export itself does not grow with file size. If invocations time out, raise the function timeout so the final `force_flush()` completes, otherwise buffered records are lost. #### Can I use a custom flow log format? Yes. Update `DEFAULT_FIELDS` in the handler to match the field order you chose when creating the flow log. The handler warns when the file header does not match the expected fields, which is the first thing to check if attributes look wrong in Scout. #### How do I keep the Lambda from triggering on other objects in the bucket? Set a prefix such as `AWSLogs/` and a suffix of `.gz` on the S3 event notification. Only flow log files then invoke the function. ### Related Guides - [Application Load Balancer Monitoring](./elb.md) - Monitor AWS ALB with logs and metrics - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development - [OTel Collector Configuration](../../collector-setup/otel-collector-config.md) \- Advanced collector configuration --- ## Query AWS CloudWatch in base14 Scout with the CloudWatch Datasource ### Overview base14 Scout can query AWS CloudWatch directly through a **CloudWatch datasource**, so you can chart AWS metrics **without ingesting or storing them in Scout**. This is a **pull** approach, but unlike the other approaches it stores nothing. It is query federation: each dashboard render calls CloudWatch live. That makes it the fastest path to CloudWatch dashboards, at the cost of no retention in Scout and no correlation with your OTLP telemetry. For a comparison of all approaches, see the [AWS CloudWatch overview](./overview.md). :::info Provisioned by base14 Scout provisions datasources centrally. To enable the CloudWatch datasource, [contact the base14 team](mailto:support@base14.io). ::: ### How it works ```text Scout ─ query at render time ─▶ CloudWatch API │ └─ renders panels directly; nothing stored in Scout ``` ### Is this the right approach? | Aspect | CloudWatch datasource | | --- | --- | | Ingestion | None - queried live at render time | | Stored in Scout | No | | Correlate with OTLP telemetry | No - separate from the Scout data lake | | Retention | Bounded by CloudWatch (up to 15 months) | | Latency | Query time, bounded by CloudWatch availability | | Cost driver | CloudWatch `GetMetricData` per dashboard query | | Setup effort | Lowest of the four approaches | Use it to visualize CloudWatch quickly. If you need durable storage, long retention, or correlation with your OTLP metrics, logs, and traces, ingest the data with a [push](./cloudwatch-firehose-receiver.md) or [pull](./cloudwatch-prometheus-exporter.md) approach instead. ### Prerequisites - A base14 Scout tenant with the CloudWatch datasource enabled (see Step 1). - AWS credentials with CloudWatch read access (see Step 2). - The AWS region where your metrics live. ### Step 1: Enable the CloudWatch datasource To enable the CloudWatch datasource in Scout, [contact the base14 team](mailto:support@base14.io). ### Step 2: Grant CloudWatch read permissions The datasource needs read-only access to the CloudWatch metrics APIs. Attach a policy like this to the IAM identity the datasource authenticates as: ```json showLineNumbers title="cloudwatch-datasource-policy.json" { "Version": "2012-10-17", "Statement": [ { "Sid": "AllowReadingMetricsFromCloudWatch", "Effect": "Allow", "Action": [ "cloudwatch:DescribeAlarmsForMetric", "cloudwatch:DescribeAlarmHistory", "cloudwatch:DescribeAlarms", "cloudwatch:ListMetrics", "cloudwatch:GetMetricData", "cloudwatch:GetInsightRuleReport" ], "Resource": "*" }, { "Sid": "AllowReadingResourcesForTags", "Effect": "Allow", "Action": ["ec2:DescribeRegions", "tag:GetResources"], "Resource": "*" } ] } ``` For authentication, you have two practical options: - **Access and secret key** - create an IAM user with the policy above and use its keys. - **Assume role** - let the datasource assume a role in your account. The role must trust base14's Scout account as the calling principal; coordinate the role ARN and trust policy with base14. ### Step 3: Configure the datasource in Scout Once base14 has enabled it, in Scout go to **Connections > Data sources > Add data source > CloudWatch**, then set: - **Authentication Provider** - `Access & secret key` (paste the IAM user keys) or `Assume Role ARN` (enter the role ARN from Step 2). - **Default Region** - the region your metrics live in, for example `us-east-1`. - **Namespaces of Custom Metrics** - optional, only if you publish custom CloudWatch namespaces. Click **Save & test**. A green result confirms Scout can reach CloudWatch with the credentials. ### Step 4: Build panels against the CloudWatch datasource When you create a panel, select the **CloudWatch** datasource instead of the Scout data lake. Then choose: - **Namespace** - for example `AWS/EC2`, `AWS/RDS`, `AWS/ApplicationELB`. - **Metric name** - for example `CPUUtilization`, `RequestCount`. - **Statistic** - for example `Average`, `Sum`, `p99`. - **Dimensions** - for example `InstanceId`, `DBInstanceIdentifier`. The panel now renders CloudWatch data live. Repeat for each panel; every panel that uses this datasource queries CloudWatch when the dashboard loads. ### Verify the setup 1. On the datasource page, **Save & test** returns a green success message. 2. A new panel using the CloudWatch datasource renders data for a namespace you know is active (for example `AWS/EC2` `CPUUtilization`). 3. Changing the dashboard time range re-queries CloudWatch and updates the panel. ### Troubleshooting #### The CloudWatch datasource is not available in Scout **Cause**: the datasource is not enabled for your tenant. **Fix**: [contact the base14 team](mailto:support@base14.io) (Step 1). #### Save & test fails **Cause**: credentials, permissions, or region are wrong. **Fix**: 1. Confirm the IAM policy from Step 2 is attached. 2. Verify the access key or assume-role ARN is correct and, for assume-role, that the trust policy allows base14's account. 3. Check the default region matches where the metrics live. #### A panel shows no data **Cause**: the namespace, metric, dimension, or region does not match. **Fix**: confirm the namespace and metric exist in that region, and that the dimension names and values are exact (they are case-sensitive). #### Dashboards are slow or CloudWatch cost is rising **Cause**: frequent queries against many metrics. **Fix**: widen the dashboard auto-refresh interval, reduce the number of high-cardinality panels, and remember each query bills `GetMetricData`. For heavy or always-on dashboards, ingesting the metrics with a [push](./cloudwatch-firehose-receiver.md) or [pull](./cloudwatch-prometheus-exporter.md) approach is usually cheaper. ### FAQ #### What is the CloudWatch datasource in base14 Scout? base14 Scout can query the AWS CloudWatch API directly through a CloudWatch datasource, so you can chart AWS metrics without ingesting or storing them in Scout. base14 enables the datasource for your tenant. #### Is CloudWatch data stored in Scout when I use the datasource? No. This is query federation, not ingestion. Nothing is written to the Scout data lake. Each dashboard load queries CloudWatch live, so the data is bound by CloudWatch retention and cannot be joined with your OTLP telemetry in Scout. #### How do I enable the CloudWatch datasource in Scout? Scout provisions datasources centrally. To enable the CloudWatch datasource, [contact the base14 team](mailto:support@base14.io). #### When should I use the CloudWatch datasource instead of ingesting metrics? Use it when you only need to visualize CloudWatch and do not need the data stored, retained, or correlated with OTLP telemetry in Scout. It is the fastest path to standing up CloudWatch dashboards. For durable storage and correlation, ingest with a push or pull approach instead. ### Related Guides - [AWS CloudWatch Overview](./overview.md) - compare all four approaches. - [Firehose to the OTel Collector](./cloudwatch-firehose-receiver.md) - push ingestion with the lowest latency. - [Prometheus CloudWatch exporter](./cloudwatch-prometheus-exporter.md) - pull ingestion with fine-grained metric selection. - [CloudWatch Metrics Stream (S3 + Lambda)](./cloudwatch-metrics-stream.md) - push ingestion without an inbound endpoint. - [Create Your First Dashboard](../../../../guides/create-your-first-dashboard.md) - build panels in Scout. --- ## CloudWatch Metrics to the OpenTelemetry Collector via Kinesis Firehose ### Overview This guide streams AWS CloudWatch metrics directly into the OpenTelemetry Collector using the [`awsfirehosereceiver`](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/awsfirehosereceiver). A CloudWatch Metric Stream pushes metrics through Amazon Data Firehose (formerly Kinesis Data Firehose), which delivers them over HTTP to the Collector. The Collector decodes the CloudWatch payload and forwards it to **base14 Scout** over OTLP. Compared to the [Firehose to S3 to Lambda](./cloudwatch-metrics-stream.md) approach, this path has no S3 bucket, no Lambda code to maintain, and lower latency. The trade-off is that the Collector must expose an inbound HTTPS endpoint that Firehose can reach. For a comparison of all approaches, see the [AWS CloudWatch overview](./overview.md). :::caution Configuration pending validation The Collector configuration below is authored from the OpenTelemetry Collector Contrib documentation and has not yet been validated end-to-end against a live AWS account and Scout tenant. Test it in a non-production environment and confirm metrics arrive in Scout before relying on it. ::: ### How it works ```text CloudWatch ─▶ Metric Stream ─▶ Amazon Data Firehose ─▶ OTel Collector ─▶ Scout (JSON format) (HTTP endpoint) awsfirehosereceiver (OTLP) ``` The `awsfirehosereceiver` listens on an HTTP port. Firehose posts batches of records to it, authenticating each request with a shared access key sent in the `X-Amz-Firehose-Access-Key` header. With `record_type: cwmetrics`, the receiver decodes CloudWatch Metric Stream JSON into OTel metrics. ### Prerequisites | Requirement | Minimum | Recommended | | ----------- | ------- | ----------- | | OTel Collector Contrib | 0.90.0 | latest | | Public HTTPS endpoint | valid CA-signed cert | ACM cert on a load balancer | | base14 Scout | Any | - | | AWS permissions | CloudWatch, Amazon Data Firehose, S3 (backup) | - | Before starting: - The Collector must be reachable from AWS over HTTPS with a valid certificate. Firehose does not deliver to self-signed certificates. - Have your Scout OAuth client ID, client secret, token URL, and OTLP endpoint ready (see [Scout Exporter Configuration](../../../collector-setup/scout-exporter.md)). - Choose a strong shared secret for the Firehose access key. ### Step 1: Deploy the Collector with the Firehose receiver Create `otel-collector-config.yaml`. This reuses the Scout `oauth2client` extension and `otlphttp/b14` exporter, and adds the `awsfirehose` receiver: ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: ${env:SCOUT_TOKEN_URL} tls: insecure_skip_verify: true receivers: awsfirehose: endpoint: 0.0.0.0:4433 record_type: cwmetrics access_key: ${env:FIREHOSE_ACCESS_KEY} # Firehose requires HTTPS with a valid certificate. Terminate TLS here, # or omit this block and terminate at a load balancer (see below). tls: cert_file: /etc/otel/certs/server.crt key_file: /etc/otel/certs/server.key processors: resource: attributes: - key: cloud.provider value: aws action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true service: extensions: [oauth2client] pipelines: metrics: receivers: [awsfirehose] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment variables ```bash showLineNumbers title=".env" SCOUT_CLIENT_ID=__YOUR_CLIENT_ID__ SCOUT_CLIENT_SECRET=__YOUR_CLIENT_SECRET__ SCOUT_TOKEN_URL=https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token OTEL_EXPORTER_OTLP_ENDPOINT=https://otel.play.b14.dev/__YOUR_TENANT__/otlp FIREHOSE_ACCESS_KEY= ENVIRONMENT=production ``` > **TLS termination:** the cleanest production pattern is to terminate TLS at > a load balancer with an AWS Certificate Manager (ACM) certificate and let > the Collector listen on plain HTTP behind it. In that case, omit the `tls` > block on the receiver and point Firehose at the load balancer's HTTPS URL. > The `X-Amz-Firehose-Access-Key` header still passes through, so the > `access_key` check continues to work. ### Step 2: Create the Firehose stream (HTTP endpoint delivery) 1. Open the [Amazon Data Firehose console](https://console.aws.amazon.com/firehose/home) and click **Create Firehose stream**. 2. Set **Source** to `Direct PUT` and **Destination** to `HTTP Endpoint`. 3. Under **HTTP endpoint details**, set: - **HTTP endpoint URL** to your Collector's public HTTPS URL, for example `https://collector.example.com:4433` (or the load balancer URL on 443). - **Access key** to the same value as `FIREHOSE_ACCESS_KEY`. - **Content encoding** to `GZIP`. 4. Under **Buffer hints**, a buffer of `1 MiB` or `60 seconds` is a reasonable start. 5. Under **Backup settings**, select **Failed data only** and choose an S3 bucket. Firehose requires a backup bucket for records it cannot deliver. 6. Click **Create Firehose stream**. ### Step 3: Create the CloudWatch Metric Stream 1. Open the [CloudWatch console](https://console.aws.amazon.com/cloudwatch/home), go to **Metrics > Streams**, and click **Create metric stream**. 2. Choose **Custom setup with Firehose** and select the Firehose stream from Step 2. 3. Set **Output format** to `JSON` to match `record_type: cwmetrics`. 4. Under **Metrics to be streamed**, select the specific namespaces you want (for example `AWS/EC2`, `AWS/RDS`) instead of all namespaces to reduce volume and cost. 5. Give the stream a name and click **Create metric stream**. Metrics now flow CloudWatch → Firehose → Collector → Scout. :::note IAM roles are created for you As you complete Steps 2 and 3 in the console, AWS creates two service roles automatically: a Firehose role that can write to the S3 backup bucket (`s3:PutObject`, `s3:AbortMultipartUpload`, `s3:GetBucketLocation`, `s3:ListBucket`) and log delivery errors, and a CloudWatch Metric Stream role that trusts `streams.metrics.cloudwatch.amazonaws.com` and can call `firehose:PutRecord` and `firehose:PutRecordBatch` on the stream. If you provision with Terraform or CloudFormation instead, create both roles explicitly with those permissions. ::: ### Verify the setup 1. In the Firehose console, open your stream's **Monitoring** tab and confirm `DeliveryToHTTPEndpoint.Success` is non-zero and the failed-delivery count is flat. 2. Check the Collector logs for accepted requests from the receiver: ```bash showLineNumbers docker logs otel-collector | grep -i firehose ``` 3. In Scout, confirm the CloudWatch metrics appear (metric names are prefixed `amazonaws.com//`). Allow 5-10 minutes for the first metrics to arrive. ### Troubleshooting #### Firehose delivery is failing (records land in the S3 backup) **Cause**: the Collector endpoint is not reachable or its certificate is not valid. **Fix**: 1. Confirm the endpoint is publicly reachable over HTTPS and the certificate is CA-signed, not self-signed. 2. Verify the port and path in the Firehose HTTP endpoint URL match the receiver's `endpoint`. 3. Check the Firehose stream's error logs for the HTTP status returned by the Collector. #### Firehose reports 401 or 403 from the Collector **Cause**: the access key does not match. **Fix**: confirm the Firehose **Access key** equals `FIREHOSE_ACCESS_KEY` on the receiver. The receiver validates the `X-Amz-Firehose-Access-Key` header. #### Requests arrive but no metrics reach Scout **Cause**: a record-type or output-format mismatch, or an export failure. **Fix**: 1. If the Metric Stream output format is `OpenTelemetry 1.0.0`, set `record_type: otlp_v1` on the receiver. Use `cwmetrics` only with `JSON` output. 2. Check the Collector logs for OTLP export errors and confirm the `oauth2client` values and `OTEL_EXPORTER_OTLP_ENDPOINT` are correct. ### FAQ #### What is the `awsfirehosereceiver`? The `awsfirehosereceiver` is an OpenTelemetry Collector Contrib receiver that accepts records pushed by Amazon Data Firehose over an HTTP endpoint. With `record_type` set to `cwmetrics` it decodes CloudWatch Metric Stream JSON directly into OTel metrics, so no S3 bucket or Lambda function is needed. #### Do I need a public endpoint for Firehose HTTP delivery? Yes. Amazon Data Firehose HTTP endpoint delivery requires a publicly reachable HTTPS endpoint with a valid, CA-signed certificate. Terminate TLS on the Collector directly or behind a load balancer with an ACM certificate. Firehose will not deliver to a self-signed certificate. #### What output format should the CloudWatch Metric Stream use? Use `JSON` output format with `record_type: cwmetrics` on the receiver. If you set the Metric Stream output format to `OpenTelemetry 1.0.0` instead, set `record_type: otlp_v1` so the receiver decodes the OTLP payload. #### How is this different from the Firehose to S3 to Lambda approach? This approach delivers straight from Firehose to the Collector's receiver, with no S3 bucket and no Lambda code to maintain, and lower latency. The trade-off is that the Collector must expose an inbound HTTPS endpoint that Firehose can reach, whereas the [S3 and Lambda path](./cloudwatch-metrics-stream.md) needs no inbound endpoint. ### Related Guides - [AWS CloudWatch Overview](./overview.md) - compare all four approaches. - [CloudWatch Metrics Stream (S3 + Lambda)](./cloudwatch-metrics-stream.md) - the push approach without an inbound endpoint. - [Prometheus CloudWatch exporter](./cloudwatch-prometheus-exporter.md) - the pull alternative with no inbound endpoint. - [Scout Exporter Configuration](../../../collector-setup/scout-exporter.md) - OAuth2 authentication and the OTLP endpoint. - [AWS ECS/Fargate Setup](../../../collector-setup/ecs-setup.md) - deploy the Collector on AWS. --- ## CloudWatch Metric Streams to OpenTelemetry - Complete Setup Guide Using Amazon CloudWatch Metric Streams and Amazon Data Firehose (formerly Kinesis Data Firehose), you can get CloudWatch metrics into base14 Scout with low latency. Firehose buffers the stream in S3, and a Lambda function converts each batch to OTLP and forwards it to Scout, so end-to-end delivery is typically three to five minutes - faster than polling the CloudWatch APIs. :::note Why S3 and Lambda? Amazon Data Firehose can deliver to an HTTP endpoint directly, but base14 Scout expects OTLP over an OAuth2-authenticated endpoint, which Firehose cannot produce on its own. This pipeline uses S3 as a buffer and a Lambda to convert each batch to OTLP and attach the OAuth2 token. If you can run a public HTTPS OpenTelemetry Collector, the [Firehose to the OTel Collector](./cloudwatch-firehose-receiver.md) approach skips S3 and Lambda for lower latency. ::: ### Step 1: Creating an S3 bucket First, we'll create an S3 bucket to store the metrics. #### 1. Go to the [S3 Dashboard](https://console.aws.amazon.com/s3) ![S3 Search in Console](/img/cloudwatch-kinesis-stream/search-s3-aws-console.png) #### 2. Click `Create bucket` ![S3 Dashboard ScreenShot](/img/cloudwatch-kinesis-stream/s3-dashboard.png) #### 3. Enter the bucket name as `cloudwatch-metrics-stream-bucket` > Leave all the other settings at their default options. ![S3 config page screenshot](/img/cloudwatch-kinesis-stream/create-s3-page.png) #### 4. Scroll down and click `Create bucket` ### Step 2: Creating an Amazon Data Firehose stream Now, we'll create an Amazon Data Firehose stream that CloudWatch can use to stream metrics. #### 1. Go to the [Amazon Data Firehose Dashboard](https://console.aws.amazon.com/firehose) ![Amazon Data Firehose Search in Console](/img/cloudwatch-kinesis-stream/search-kinesis-firehose.png) #### 2. Click `Create Firehose Stream` ![Amazon Data Firehose Dashboard](/img/cloudwatch-kinesis-stream/kinesis-firehose-dashboard.png) #### 3. Set up the sources - Select `Direct PUT` as the input source and `S3` as the output. - Select the S3 bucket name we created. > Format is `s3://` - Enable `New Line Delimiter` and leave everything else as default settings. - Scroll down and click `Create Firehose Stream`. ![Firehose source config](/img/cloudwatch-kinesis-stream/configure-source-in-kinesis.png) ### Step 3: Creating a Metric Stream pipeline Now, we'll configure CloudWatch to use the Firehose stream to send metrics to S3. #### 1. Navigate to the CloudWatch dashboard and select Streams under Metrics ![cloudwatch dashboard](/img/cloudwatch-kinesis-stream/cloudwatch-dashboard.png) #### 2. Click `Create Metric Stream` ![cloudwatch metrics stream dashboard](/img/cloudwatch-kinesis-stream/cloudwatch-metrics-stream.png) #### 3. Configuring the stream - Select `Custom Setup with Firehose`. - Change the output format to `JSON`. - Select the required metrics. - Give the pipeline a name, then click `Create Metric Stream`. > Firehose is now writing CloudWatch metric batches to the S3 bucket. :::note IAM roles are created for you As you complete Steps 2 and 3 in the console, AWS creates two service roles automatically: a Firehose role that can write to the destination S3 bucket (`s3:PutObject`, `s3:AbortMultipartUpload`, `s3:GetBucketLocation`, `s3:ListBucket`) and log delivery errors, and a CloudWatch Metric Stream role that trusts `streams.metrics.cloudwatch.amazonaws.com` and can call `firehose:PutRecord` and `firehose:PutRecordBatch` on the stream. If you provision with Terraform or CloudFormation instead, create both roles explicitly with those permissions. (The Lambda's own read role is configured in Step 4.) ::: ### Step 4: Creating a Lambda function Now, let's create a Lambda function to read from S3 and forward the metrics to base14 Scout. #### 1. Create a layer with all the necessary packages ```shell mkdir python # move into that directory cd python # install requests module pip install --target . requests # zip the contents under the name dependencies.zip zip -r dependencies.zip ../python ``` #### 2. Navigate to the AWS Lambda dashboard and click `Layers` ![lambda dashboard](/img/cloudwatch-kinesis-stream/lambda-dashboard.png) - Click `Create layer`. #### 3. Fill in the necessary details and upload the zip file ![create lambda page](/img/cloudwatch-kinesis-stream/create-lambda-layer-page.png) #### 4. Navigate to the Functions page and click `Create function` ![lambda functions page](/img/cloudwatch-kinesis-stream/lambda-functions-page.png) - Select `Author from scratch`. - Give a function name (e.g., `cloudwatch-metrics-to-scout`). - Choose `Python 3.12` as the runtime. - Select `x86_64` as the Architecture. - Click `Create function`. #### 5. Configure the Lambda function Once the function is created, follow the steps below to configure it. ##### Add S3 permissions The Lambda execution role needs access to read objects from the S3 bucket where Firehose writes metrics. 1. Click on the `Configuration` tab and then click on `Permissions`. 2. Click on the **Role name** link to open the IAM role in a new tab. 3. Click `Add permissions` then `Create inline policy`. 4. Switch to the `JSON` tab and paste the following policy: ```json showLineNumbers title="s3-read-policy.json" { "Version": "2012-10-17", "Statement": [ { "Sid": "AllowListBucket", "Effect": "Allow", "Action": "s3:ListBucket", "Resource": "arn:aws:s3:::cloudwatch-metrics-stream-bucket" }, { "Sid": "AllowGetObject", "Effect": "Allow", "Action": "s3:GetObject", "Resource": "arn:aws:s3:::cloudwatch-metrics-stream-bucket/*" } ] } ``` > Replace `cloudwatch-metrics-stream-bucket` with your actual > bucket name if you chose a different name in Step 1. 1. Click `Next`, give the policy a name (e.g., `cloudwatch-stream-s3-read`), and click `Create policy`. ##### Set the timeout The default Lambda timeout of 3 seconds is too short for reading S3 objects and forwarding metrics over HTTP. 1. In the `Configuration` tab, click on `General configuration`. 2. Click `Edit`. 3. Set **Timeout** to `1 min 0 sec`. 4. Click `Save`. ##### Add the dependencies layer 1. Click on `Code` and scroll down to the **Layers** section. 2. Click `Add a layer`. 3. Select `Custom layers` and choose the layer created in step 1. 4. Click `Add`. ##### Add the S3 trigger 1. Navigate back to the function overview and click `Add trigger`. 2. Select `S3` as the source. 3. Select the bucket (`cloudwatch-metrics-stream-bucket`) from the dropdown. 4. Leave the event type as `All object create events`. 5. Click `Add`. ##### Set environment variables The Lambda code reads four environment variables for authentication and endpoint configuration. 1. In the `Configuration` tab, click on `Environment variables`. 2. Click `Edit` and add the following variables: | Key | Value | | --------------- | ----------------------------------------------- | | `CLIENT_ID` | Your Scout OAuth client ID | | `CLIENT_SECRET` | Your Scout OAuth client secret | | `TOKEN_URL` | Your Scout token endpoint URL | | `ENDPOINT_URL` | Full Scout OTLP metrics URL (include `/v1/metrics`) | 1. Click `Save`. `ENDPOINT_URL` is the exact URL the Lambda POSTs to. It does not append `/v1/metrics` for you, so include the full path, for example `https://otel.play.b14.dev//otlp/v1/metrics`. Now, copy the code below into the `Code source` editor of your Lambda function. :::warning Keep TLS verification on The requests below verify TLS certificates by default. Do not set `verify=False` in production - it disables certificate validation and exposes your credentials and metrics to interception. base14 Scout endpoints use valid, publicly trusted certificates, so verification works out of the box. ::: ```python import boto3 import requests import os import json from collections import defaultdict s3 = boto3.client('s3') client_id = os.environ.get('CLIENT_ID') client_secret = os.environ.get('CLIENT_SECRET') token_url = os.environ.get('TOKEN_URL') endpoint_url = os.environ.get('ENDPOINT_URL') def parse_cloudwatch_json_file(buffer): """ Parse CloudWatch Metrics Stream JSON file (newline-delimited JSON). Returns a list of metric dictionaries. """ metrics = [] content = buffer.decode('utf-8') for line in content.strip().split('\n'): line = line.strip() if not line: continue try: metric = json.loads(line) metrics.append(metric) except json.JSONDecodeError as e: print(f"Failed to parse JSON line: {e}") continue return metrics def convert_to_otlp_json(metrics): """ Convert CloudWatch metrics to OTLP JSON format. Groups metrics by account/region for efficient batching. Preserves attribute format: Namespace, MetricName, Dimensions (as JSON string) """ grouped = defaultdict(list) for metric in metrics: key = (metric.get('account_id', ''), metric.get('region', '')) grouped[key].append(metric) resource_metrics = [] for (account_id, region), account_metrics in grouped.items(): # Resource attributes resource_attributes = [ {"key": "cloud.provider", "value": {"stringValue": "aws"}}, {"key": "cloud.account.id", "value": {"stringValue": account_id}}, {"key": "cloud.region", "value": {"stringValue": region}}, {"key": "service.name", "value": {"stringValue": "aws-cloudwatch-stream"}}, {"key": "environment", "value": {"stringValue": "production"}}, ] otlp_metrics = [] for cw_metric in account_metrics: metric_name = cw_metric.get('metric_name', 'unknown') namespace = cw_metric.get('namespace', '') timestamp_ms = cw_metric.get('timestamp', 0) timestamp_ns = timestamp_ms * 1_000_000 value = cw_metric.get('value', {}) unit = cw_metric.get('unit', '') dimensions = cw_metric.get('dimensions', {}) datapoint_attributes = [ {"key": "Namespace", "value": {"stringValue": namespace}}, {"key": "MetricName", "value": {"stringValue": metric_name}}, {"key": "Dimensions", "value": {"stringValue": json.dumps(dimensions)}}, ] otlp_metrics.append({ "name": f"amazonaws.com/{namespace}/{metric_name}", "unit": unit if unit != "None" else "", "summary": { "dataPoints": [{ "timeUnixNano": str(timestamp_ns), "count": str(int(value.get('count', 0))), "sum": value.get('sum', 0.0), "quantileValues": [ {"quantile": 0.0, "value": value.get('min', 0.0)}, {"quantile": 1.0, "value": value.get('max', 0.0)} ], "attributes": datapoint_attributes }] } }) resource_metrics.append({ "resource": {"attributes": resource_attributes}, "scopeMetrics": [{ "scope": {"name": "aws.cloudwatch", "version": "1.0.0"}, "metrics": otlp_metrics }] }) return {"resourceMetrics": resource_metrics} def lambda_handler(event, context): for record in event['Records']: bucket_name = record['s3']['bucket']['name'] file_key = record['s3']['object']['key'] print(f"Processing file: {file_key}") file_obj = s3.get_object(Bucket=bucket_name, Key=file_key) buffer = file_obj['Body'].read() try: metrics = parse_cloudwatch_json_file(buffer) print(f"Parsed {len(metrics)} metrics from file") except Exception as e: print(f"Error parsing file: {e}") raise if not metrics: print("No metrics found in file") continue try: otlp_payload = convert_to_otlp_json(metrics) print(f"Converted to OTLP format with {len(otlp_payload['resourceMetrics'])} resource groups") except Exception as e: print(f"Error converting to OTLP: {e}") raise try: token_response = requests.post( token_url, data={ "grant_type": "client_credentials", "audience": "b14collector", }, auth=(client_id, client_secret), ) token_response.raise_for_status() access_token = token_response.json()["access_token"] except Exception as e: print(f"Failed to get auth token: {e}") raise headers = { "Content-Type": "application/json", "Authorization": f"Bearer {access_token}" } try: response = requests.post( endpoint_url, json=otlp_payload, headers=headers, ) if response.status_code == 200: print(f"Successfully forwarded {len(metrics)} metrics to OTLP endpoint") else: print(f"Failed to send metrics. Status: {response.status_code}, Response: {response.text}") except Exception as e: print(f"Error sending to endpoint: {e}") raise return { 'statusCode': 200, 'body': f'Processed {len(event["Records"])} files' } ``` - Click `Deploy`. ### Verify the setup Confirm metrics are flowing at each hop: - **Firehose**: open your stream in the Firehose console, check **Monitoring**, and confirm `DeliveryToS3.Success` is non-zero. - **S3**: the bucket should show new objects accumulating under the prefix. - **Lambda**: check the function's logs for successful forwards and no 4xx or 5xx responses from the OTLP endpoint. - **Scout**: query a known metric such as `amazonaws.com/AWS/EC2/CPUUtilization`. Allow three to five minutes for the full path from stream through S3 and Lambda to reach Scout. ### FAQ #### What is CloudWatch Metrics Stream and how does it work with base14 Scout? Amazon CloudWatch Metric Streams push metrics continuously through Amazon Data Firehose. In this setup Firehose writes batches to S3, an S3-triggered Lambda converts each batch to OTLP and forwards it to base14 Scout. End-to-end latency is typically three to five minutes, faster than polling the CloudWatch APIs. #### How do I set up CloudWatch Metrics Stream for base14 Scout? Create an S3 bucket, set up an Amazon Data Firehose stream with Direct PUT as input and S3 as output, configure a CloudWatch Metric Stream to send metrics through Firehose, then add a Lambda that converts the S3 objects to OTLP and forwards them to base14 Scout. #### Is CloudWatch Metrics Stream faster than polling CloudWatch APIs? Yes. Metric Streams deliver to Firehose in two to three minutes. With the S3 and Lambda forwarding hop, end-to-end delivery to Scout is typically three to five minutes, still faster than the five or more minutes typical of API polling. #### Can I filter which AWS metrics are streamed via CloudWatch Metrics Stream? Yes. When creating the Metric Stream you can select specific namespaces such as AWS/EC2 or AWS/RDS instead of all namespaces, which reduces cost and data volume. #### What AWS infrastructure do I need for CloudWatch Metrics Stream? You need an S3 bucket, an Amazon Data Firehose stream configured with Direct PUT, a CloudWatch Metric Stream that routes metrics through Firehose to S3, and a Lambda function that forwards the metrics to base14 Scout over OTLP. ### Related Guides - [AWS CloudWatch Overview](./overview.md) - Compare all four approaches to get CloudWatch metrics into Scout. - [Firehose to the OTel Collector](./cloudwatch-firehose-receiver.md) - The same stream without S3 or Lambda, using the `awsfirehosereceiver`. - [Prometheus CloudWatch exporter](./cloudwatch-prometheus-exporter.md) - The pull alternative. - [Application Load Balancer Monitoring](../elb.md) - Monitor AWS ALB with CloudWatch Metrics Stream. - [RDS Monitoring](../rds.md) - Monitor AWS RDS databases. - [ElastiCache Monitoring](../elasticache.md) - Monitor Redis and Memcached. - [Scout Exporter Configuration](../../../collector-setup/scout-exporter.md) - Configure authentication and endpoints. --- ## AWS CloudWatch Metrics via the Prometheus CloudWatch Exporter ### Overview This guide pulls AWS CloudWatch metrics using the [Prometheus CloudWatch exporter](https://github.com/prometheus/cloudwatch_exporter). The exporter polls the CloudWatch API on an interval and exposes the results at `/metrics`. The OpenTelemetry Collector's Prometheus receiver scrapes that endpoint and forwards the metrics to **base14 Scout** over OTLP. This is a **pull** approach. Nothing inbound is required - both the exporter and the Collector reach out to AWS. It fits teams that already run a Prometheus scrape model and want precise control over which metrics are collected. The trade-off is latency (scrape interval plus CloudWatch delay) and per-request CloudWatch API cost. For a comparison of all approaches, see the [AWS CloudWatch overview](./overview.md). :::caution Configuration pending validation The exporter and Collector configuration below is authored from the upstream project documentation and has not yet been validated end-to-end against a live AWS account and Scout tenant. Test it in a non-production environment and confirm metrics arrive in Scout before relying on it. ::: ### How it works ```text poll GetMetricData OTel Collector ◀─ scrape /metrics ─ CloudWatch exporter ──────────────▶ CloudWatch │ API └─ OTLP ─▶ Scout ``` ### Prerequisites | Requirement | Minimum | Recommended | | ----------- | ------- | ----------- | | CloudWatch exporter | 0.15.0 | latest | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | | AWS permissions | `GetMetricData`, `GetMetricStatistics`, `ListMetrics`, `tag:GetResources` | - | Before starting: - AWS credentials for the exporter, via an IAM user, an EC2 instance role, or EKS Pod Identity or IRSA. - Have your Scout OAuth client ID, client secret, token URL, and OTLP endpoint ready (see [Scout Exporter Configuration](../../../collector-setup/scout-exporter.md)). ### Step 1: Grant CloudWatch read permissions Attach this read-only policy to the identity the exporter runs as: ```json showLineNumbers title="cloudwatch-read-policy.json" { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": [ "cloudwatch:GetMetricData", "cloudwatch:GetMetricStatistics", "cloudwatch:ListMetrics", "tag:GetResources" ], "Resource": "*" } ] } ``` ### Step 2: Deploy the Prometheus CloudWatch exporter Create `config.yml` listing the namespaces, metrics, dimensions, and statistics to collect. Select only what you need - each metric adds a `GetMetricData` call and CloudWatch bills per request: ```yaml showLineNumbers title="config.yml" region: us-east-1 period_seconds: 60 delay_seconds: 120 set_timestamp: false metrics: - aws_namespace: AWS/EC2 aws_metric_name: CPUUtilization aws_dimensions: [InstanceId] aws_statistics: [Average] - aws_namespace: AWS/RDS aws_metric_name: CPUUtilization aws_dimensions: [DBInstanceIdentifier] aws_statistics: [Average] - aws_namespace: AWS/RDS aws_metric_name: FreeableMemory aws_dimensions: [DBInstanceIdentifier] aws_statistics: [Average] - aws_namespace: AWS/ApplicationELB aws_metric_name: RequestCount aws_dimensions: [LoadBalancer] aws_statistics: [Sum] ``` Run the exporter with Docker. It reads `/config/config.yml` and serves metrics on port 9106: ```bash showLineNumbers title="Run the exporter" docker run -d --name cloudwatch-exporter -p 9106:9106 \ -e AWS_ACCESS_KEY_ID=__YOUR_KEY__ \ -e AWS_SECRET_ACCESS_KEY=__YOUR_SECRET__ \ -v "$(pwd)/config.yml:/config/config.yml" \ prom/cloudwatch-exporter:latest ``` On Kubernetes, run it as a Deployment with the config in a ConfigMap and AWS access granted to its ServiceAccount. Apply the manifests below, then grant the ServiceAccount access (next section): ```yaml showLineNumbers title="cloudwatch-exporter.yaml" apiVersion: v1 kind: ConfigMap metadata: name: cloudwatch-exporter-config data: config.yml: | region: us-east-1 period_seconds: 60 delay_seconds: 120 set_timestamp: false metrics: - aws_namespace: AWS/EC2 aws_metric_name: CPUUtilization aws_dimensions: [InstanceId] aws_statistics: [Average] - aws_namespace: AWS/RDS aws_metric_name: CPUUtilization aws_dimensions: [DBInstanceIdentifier] aws_statistics: [Average] - aws_namespace: AWS/RDS aws_metric_name: FreeableMemory aws_dimensions: [DBInstanceIdentifier] aws_statistics: [Average] - aws_namespace: AWS/ApplicationELB aws_metric_name: RequestCount aws_dimensions: [LoadBalancer] aws_statistics: [Sum] --- apiVersion: v1 kind: ServiceAccount metadata: name: cloudwatch-exporter --- apiVersion: apps/v1 kind: Deployment metadata: name: cloudwatch-exporter spec: replicas: 1 selector: matchLabels: app: cloudwatch-exporter template: metadata: labels: app: cloudwatch-exporter spec: serviceAccountName: cloudwatch-exporter containers: - name: cloudwatch-exporter image: prom/cloudwatch-exporter:latest ports: - containerPort: 9106 volumeMounts: - name: config mountPath: /config volumes: - name: config configMap: name: cloudwatch-exporter-config --- apiVersion: v1 kind: Service metadata: name: cloudwatch-exporter spec: selector: app: cloudwatch-exporter ports: - port: 9106 targetPort: 9106 ``` #### Grant the ServiceAccount AWS access The `cloudwatch-exporter` ServiceAccount needs the read-only policy from Step 1. On EKS, prefer **Pod Identity** - it needs no OIDC provider or per-cluster trust policy. IRSA still works for Fargate or existing OIDC clusters. **EKS Pod Identity (recommended).** Create an IAM role that trusts the `pods.eks.amazonaws.com` principal (allowing `sts:AssumeRole` and `sts:TagSession`), attach the Step 1 policy, install the `eks-pod-identity-agent` add-on, then associate the role: ```bash showLineNumbers title="Pod Identity association" aws eks create-pod-identity-association \ --cluster-name \ --namespace \ --service-account cloudwatch-exporter \ --role-arn arn:aws:iam:::role/cloudwatch-exporter ``` **IRSA (alternative).** Create the role with an OIDC trust policy for the cluster, then annotate the ServiceAccount so the pod assumes it: ```yaml showLineNumbers title="ServiceAccount IRSA annotation" metadata: name: cloudwatch-exporter annotations: eks.amazonaws.com/role-arn: arn:aws:iam:::role/cloudwatch-exporter ``` ### Step 3: Scrape the exporter with the Collector Point the Collector's Prometheus receiver at the exporter and forward to Scout. This reuses the Scout `oauth2client` extension and `otlphttp/b14` exporter: ```yaml showLineNumbers title="otel-collector-config.yaml" extensions: oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} endpoint_params: audience: b14collector token_url: ${env:SCOUT_TOKEN_URL} tls: insecure_skip_verify: true receivers: prometheus: config: scrape_configs: - job_name: cloudwatch-exporter scrape_interval: 60s metrics_path: /metrics static_configs: - targets: ["cloudwatch-exporter:9106"] processors: resource: attributes: - key: cloud.provider value: aws action: upsert - key: environment value: ${env:ENVIRONMENT} action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} auth: authenticator: oauth2client tls: insecure_skip_verify: true service: extensions: [oauth2client] pipelines: metrics: receivers: [prometheus] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment variables ```bash showLineNumbers title=".env" SCOUT_CLIENT_ID=__YOUR_CLIENT_ID__ SCOUT_CLIENT_SECRET=__YOUR_CLIENT_SECRET__ SCOUT_TOKEN_URL=https://id.b14.dev/realms/__YOUR_TENANT__/protocol/openid-connect/token OTEL_EXPORTER_OTLP_ENDPOINT=https://otel.play.b14.dev/__YOUR_TENANT__/otlp ENVIRONMENT=production ``` ### Verify the setup 1. Confirm the exporter is serving metrics: ```bash showLineNumbers curl -s http://localhost:9106/metrics | grep aws_ec2_cpuutilization ``` 2. Check the Collector logs for a successful scrape of the `cloudwatch-exporter` job. 3. In Scout, confirm the metrics appear (the exporter names them `aws___`). Allow a few minutes for the first scrape plus CloudWatch's availability delay. ### Alternatives - **YACE (Yet Another CloudWatch Exporter)** - [nerdswords/yet-another-cloudwatch-exporter](https://github.com/nerdswords/yet-another-cloudwatch-exporter) discovers resources by tag and batches `GetMetricData` calls, which is more efficient and lower-maintenance at scale. Scrape it with the same Prometheus receiver. - **Native `awscloudwatchmetricsreceiver`** - the OpenTelemetry Collector Contrib [`awscloudwatchmetricsreceiver`](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/awscloudwatchmetricsreceiver) pulls CloudWatch metrics directly into the Collector, removing the separate exporter. It is earlier in its stability lifecycle, so validate it against your Collector version before adopting it. ### Troubleshooting #### The exporter's `/metrics` endpoint is empty or missing series **Cause**: IAM permissions, region, or metric names do not match. **Fix**: 1. Confirm the identity has `GetMetricData`, `GetMetricStatistics`, `ListMetrics`, and `tag:GetResources`. 2. Check the `region` in `config.yml` matches where the resources live. 3. Verify the `aws_namespace`, `aws_metric_name`, and `aws_dimensions` exactly match CloudWatch (case-sensitive). #### The exporter logs `AccessDenied` **Cause**: the IAM policy is missing a required action. **Fix**: attach the policy from Step 1 and confirm the credentials or role are the ones the container is using. #### CloudWatch bill higher than expected **Cause**: too many metrics or too short a period. **Fix**: trim the metric list, raise `period_seconds`, and prefer YACE's batched `GetMetricData` for large estates. CloudWatch bills per metric requested. #### The Collector is not scraping the exporter **Cause**: the scrape target is unreachable. **Fix**: confirm the `targets` host and port resolve from the Collector, and that the exporter is listening on 9106. ### FAQ #### How does the Prometheus CloudWatch exporter work? The Prometheus CloudWatch exporter polls the CloudWatch `GetMetricData` API for the namespaces and metrics you list in its config and exposes them at `/metrics` on port 9106. The OpenTelemetry Collector's Prometheus receiver scrapes that endpoint and forwards the metrics to base14 Scout over OTLP. #### Do I need a public endpoint to pull CloudWatch metrics? No. The exporter and the Collector reach out to the CloudWatch API; nothing inbound is required. This is the main operational advantage of the pull approach over Firehose HTTP endpoint delivery. #### What IAM permissions does the CloudWatch exporter need? `cloudwatch:GetMetricData`, `cloudwatch:GetMetricStatistics`, `cloudwatch:ListMetrics`, and `tag:GetResources`. These are read-only and can be granted through an IAM user, an instance role, or EKS Pod Identity or IRSA. #### How fresh are metrics pulled through the exporter? Freshness is the scrape interval plus CloudWatch's own metric-availability delay, which is typically a couple of minutes. This is slower than the push approaches, so choose pull when scrape-model fit and metric selection matter more than latency. To control cost, select only the metrics you need and raise `period_seconds`, or use YACE for tag-based discovery with batched `GetMetricData`. ### Related Guides - [AWS CloudWatch Overview](./overview.md) - compare all four approaches. - [Firehose to the OTel Collector](./cloudwatch-firehose-receiver.md) - the low-latency push alternative. - [kube-state-metrics](../../../component/kube-state-metrics.md) - another Prometheus receiver scrape pattern. - [Scout Exporter Configuration](../../../collector-setup/scout-exporter.md) - OAuth2 authentication and the OTLP endpoint. --- ## AWS CloudWatch to base14 Scout - Push and Pull Approaches Compared ### Overview This is the architectural landing page for getting **AWS CloudWatch** metrics into **base14 Scout**. AWS resources publish their operational metrics to CloudWatch (`AWS/EC2`, `AWS/RDS`, `AWS/ApplicationELB`, and so on). There are four supported ways to get that data to Scout, split across **push** and **pull** mechanisms. This page frames the trade-offs and points you at the right per-approach guide. The reader profile is **DevOps and SRE engineers** who run AWS workloads and want to choose an ingestion path before configuring it. For execution, jump to the guides linked in the [approach guides](#approach-guides) table below. :::tip TL;DR There is no single best path - pick by your latency, cost, and infrastructure constraints. - **Lowest latency, stored in Scout, no custom code:** [Firehose to the OTel Collector](./cloudwatch-firehose-receiver.md) with the `awsfirehosereceiver`. Needs a public HTTPS collector. - **Push without an inbound endpoint:** [Firehose to S3 to Lambda](./cloudwatch-metrics-stream.md). S3 buffers the stream and a Lambda forwards OTLP. - **Pull, Kubernetes-native, fine-grained metric selection:** the [Prometheus CloudWatch exporter](./cloudwatch-prometheus-exporter.md) scraped by the Collector. - **Visualize without ingesting or retaining in Scout:** the [CloudWatch datasource](./cloudwatch-datasource.md). ::: ### Push vs pull CloudWatch metrics reach Scout by one of two mechanisms: - **Push** - AWS sends metrics out as they are published. CloudWatch Metric Streams deliver continuously through Amazon Data Firehose (formerly Kinesis Data Firehose) with 2-3 minute latency. This is the freshest data and it lands in the Scout data lake, but it needs streaming infrastructure on the AWS side. - **Pull** - something polls the CloudWatch API on an interval and either ships the result to Scout or renders it directly. Pull is simpler to reason about and needs no inbound endpoint, but it adds the poll interval on top of CloudWatch's own metric-availability delay and it bills against the CloudWatch query APIs. The two push approaches differ only in what carries the stream to the Collector. The two pull approaches differ in whether the data is stored in Scout at all. ### Architecture at a glance **Approach 1 - Firehose to the Collector (push):** ```text CloudWatch ─▶ Metric Stream ─▶ Amazon Data Firehose ─▶ OTel Collector ─▶ Scout (JSON format) (HTTP endpoint) awsfirehosereceiver (OTLP) ``` **Approach 2 - Firehose to S3 to Lambda (push):** ```text CloudWatch ─▶ Metric Stream ─▶ Firehose ─▶ S3 ─▶ Lambda ─▶ Scout (JSON format) (OTLP forwarder) (OTLP) ``` **Approach 3 - Prometheus CloudWatch exporter (pull):** ```text poll GetMetricData OTel Collector ◀─ scrape /metrics ─ CloudWatch exporter ──────────────▶ CloudWatch │ API └─ OTLP ─▶ Scout ``` **Approach 4 - CloudWatch datasource (pull, no ingestion):** ```text Scout ─ query at render time ─▶ CloudWatch API │ └─ renders panels directly; nothing stored in Scout ``` ### Choosing an approach | Approach | Mechanism | Data path | Latency | Stored in Scout? | Main cost driver | Best for | | --- | --- | --- | --- | --- | --- | --- | | **1. Firehose to Collector** | Push | Metric Stream → Firehose → `awsfirehosereceiver` → OTLP | Stream delivery (~2-3 min) | Yes | Firehose ingestion + Scout ingest | Lowest-latency push, no custom code, when you can run a public HTTPS collector | | **2. Firehose to S3 to Lambda** | Push | Metric Stream → Firehose → S3 → Lambda → OTLP | Stream + S3/Lambda hop (~3-5 min) | Yes | Firehose + S3 + Lambda + Scout ingest | Push without an inbound endpoint; already documented and deployed | | **3. Prometheus exporter** | Pull | Exporter polls CloudWatch → Collector scrapes → OTLP | Scrape interval + CloudWatch delay | Yes | CloudWatch `GetMetricData` API + Scout ingest | Kubernetes-native scrape model, fine-grained metric selection, no inbound endpoint | | **4. CloudWatch datasource** | Pull | Scout queries CloudWatch at render time | Live at query time | No | CloudWatch `GetMetricData` API | Visualizing CloudWatch without ingesting or retaining in Scout | ### Decision guide **Choose Firehose to the Collector when:** - You want the freshest CloudWatch data stored in Scout and can expose a publicly reachable HTTPS collector endpoint. - You prefer a native Collector receiver over maintaining Lambda code. **Choose Firehose to S3 to Lambda when:** - You cannot expose an inbound collector endpoint to Firehose. - You want S3 to buffer and retain the raw stream, or you already run this pipeline and do not want to change it. **Choose the Prometheus CloudWatch exporter when:** - You already run a Prometheus-style scrape model, especially in Kubernetes. - You want precise control over which namespaces, metrics, and dimensions are collected, and latency is not your first concern. - You cannot or do not want to expose an inbound endpoint - the collector pulls, so nothing inbound is required. **Choose the CloudWatch datasource when:** - You only need to visualize CloudWatch metrics and do not need them stored or retained in Scout. - You want the fastest possible setup and are comfortable that the data cannot be correlated with your OTLP telemetry. ### Approach guides Each guide is the execution playbook for one approach, with the exact AWS setup, the Collector or datasource configuration, and verification steps. | Approach | Mechanism | Guide | | --- | --- | --- | | Firehose to the OTel Collector | Push | [Firehose receiver guide](./cloudwatch-firehose-receiver.md) | | Firehose to S3 to Lambda | Push | [Metrics stream guide](./cloudwatch-metrics-stream.md) | | Prometheus CloudWatch exporter | Pull | [Prometheus exporter guide](./cloudwatch-prometheus-exporter.md) | | CloudWatch datasource | Pull | [CloudWatch datasource guide](./cloudwatch-datasource.md) | The per-service AWS guides ([RDS](../rds.md), [ELB](../elb.md), [ElastiCache](../elasticache.md), [Amazon MQ](../amazonMQ.md)) all build on the push mechanism and delegate the streaming setup to these approach guides. ### Frequently Asked Questions #### What are the ways to get AWS CloudWatch metrics into base14 Scout? Four. Two push: CloudWatch Metric Streams through Amazon Data Firehose into the OpenTelemetry Collector's `awsfirehosereceiver`, or the same stream through Firehose to S3 with a Lambda that forwards OTLP. Two pull: the Prometheus CloudWatch exporter scraped by the Collector, or the CloudWatch datasource that queries CloudWatch directly at dashboard render time without ingesting anything. #### Which approach has the lowest latency? The push approaches. CloudWatch Metric Streams deliver in 2-3 minutes, so the Firehose-to-Collector path is the lowest-latency option that stores data in Scout. Pulling with the Prometheus exporter adds your scrape interval on top of CloudWatch's own metric-availability delay, so it is typically slower. #### Which approach avoids ingestion and storage cost in Scout? The CloudWatch datasource. It queries CloudWatch directly when a dashboard loads, so nothing is ingested or stored in Scout. You pay CloudWatch query API costs instead, and the data is bound by CloudWatch retention rather than kept long-term in Scout. #### Do I need a public OpenTelemetry Collector to receive CloudWatch metrics? Only for the Firehose-to-Collector push approach. Amazon Data Firehose HTTP endpoint delivery requires a publicly reachable HTTPS endpoint with a valid certificate. The Firehose-to-S3-to-Lambda path and the Prometheus exporter path do not need an inbound endpoint because the collector or Lambda reaches out to AWS. #### Can I query CloudWatch metrics in Scout without ingesting them? Yes. Enable the CloudWatch datasource in Scout and query CloudWatch directly from dashboards. base14 provisions the datasource for your tenant. This is query federation, not ingestion, so the metrics are not stored in Scout and cannot be joined with your OTLP telemetry. #### Push or pull for CloudWatch metrics? Push (CloudWatch Metric Streams through Firehose) when you want the lowest latency and durable storage in Scout. Pull (Prometheus exporter) when a Kubernetes-native scrape model and fine-grained metric selection matter more than latency, or when you cannot expose an inbound endpoint. Use the CloudWatch datasource when you only need to visualize CloudWatch and do not need to retain the data in Scout. ### Related Guides - [Scout Exporter Configuration](../../../collector-setup/scout-exporter.md) - OAuth2 authentication and the OTLP endpoint every Collector-based approach reuses. - [AWS RDS Monitoring](../rds.md) - stream RDS metrics and scrape database internals. - [AWS ELB Monitoring](../elb.md) - stream Application Load Balancer metrics. - [AWS ElastiCache Monitoring](../elasticache.md) - monitor Redis and Memcached. - [AWS Amazon MQ Monitoring](../amazonMQ.md) - monitor RabbitMQ and ActiveMQ. --- ## AWS ElastiCache Monitoring with OpenTelemetry - Redis & Memcached Metrics ### Overview This guide covers monitoring AWS ElastiCache (Redis and Memcached) using OpenTelemetry and CloudWatch Metrics Stream. You'll collect infrastructure metrics from CloudWatch, cache-specific metrics from the Redis receiver, and slow logs - all flowing into base14 Scout. ### What You'll Monitor ElastiCache monitoring combines CloudWatch metrics with optional Redis receiver metrics for complete visibility: **CloudWatch Metrics Stream (infrastructure + cache basics):** | Metric | What it tells you | | ------ | ----------------- | | `CPUUtilization` | Instance CPU usage (%) | | `EngineCPUUtilization` | Redis/Memcached engine CPU (%) - more relevant than host CPU | | `FreeableMemory` | Available RAM (bytes) | | `BytesUsedForCache` | Memory used by the cache engine | | `CacheHits` / `CacheMisses` | Cache effectiveness | | `Evictions` | Keys removed due to memory pressure | | `CurrConnections` / `NewConnections` | Client connection counts | | `NetworkBytesIn` / `NetworkBytesOut` | Network throughput | | `ReplicationLag` | Replica delay (seconds, Redis only) | | `SaveInProgress` | Whether a background save is running (Redis) | | `CurrItems` | Number of items in the cache | **OTel Redis receiver (cache internals, Redis only):** | Metric | What it tells you | | ------ | ----------------- | | `redis.memory.used` | Actual memory consumed by Redis | | `redis.maxmemory` | Configured memory limit | | `redis.connected_clients` | Currently connected client count | | `redis.keyspace.hits` / `redis.keyspace.misses` | Per-keyspace hit/miss rates | | `redis.keys.expired` | Keys expired by TTL | | `redis.keys.evicted` | Keys evicted under memory pressure | | `redis.uptime` | Time since last restart (seconds) | | `redis.memory.fragmentation_ratio` | Memory fragmentation (> 1.5 is a concern) | | `redis.commands.processed` | Total commands processed | | `redis.connections.received` | Total connections received since start | ### Prerequisites | Requirement | Minimum | Recommended | | ----------- | ------- | ----------- | | ElastiCache | Redis 6.x or Memcached 1.6 | Redis 7.x | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | | AWS permissions | CloudWatch, Amazon Data Firehose, S3, CloudWatch Logs | - | Before starting: - ElastiCache cluster must be accessible from the host running the OTel Collector (same VPC). - For the Redis receiver: AUTH token if encryption in transit is enabled. - CloudWatch Metrics Stream infrastructure set up (see Step 1). ### Step 1: Set up CloudWatch Metrics Stream Follow our comprehensive [CloudWatch Metrics Stream guide](cloudwatch-metrics/cloudwatch-metrics-stream.md) to set up the streaming infrastructure (S3 bucket, Amazon Data Firehose, Metrics Stream). When configuring the Metrics Stream: 1. Select **specific namespaces** instead of "All namespaces" 2. Choose **AWS/ElastiCache** from the namespace list 3. This ensures you only collect ElastiCache metrics, reducing costs and data volume ### Step 2: Configure the OTel Collector for Redis metrics For Redis clusters, add the Redis receiver for cache-internal metrics that CloudWatch doesn't expose: ```yaml showLineNumbers title="elasticache-redis-config.yaml" receivers: redis: endpoint: ${env:REDIS_ENDPOINT} collection_interval: 60s password: ${env:REDIS_AUTH_TOKEN} tls: insecure: false ca_file: /etc/ssl/certs/ca-certificates.crt metrics: redis.maxmemory: enabled: true redis.connected_clients: enabled: true redis.uptime: enabled: true redis.memory.used: enabled: true redis.memory.fragmentation_ratio: enabled: true redis.keys.expired: enabled: true redis.keys.evicted: enabled: true redis.keyspace.hits: enabled: true redis.keyspace.misses: enabled: true redis.commands.processed: enabled: true redis.connections.received: enabled: true processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert - key: cloud.provider value: aws action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [redis] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment variables ```bash showLineNumbers title=".env" REDIS_ENDPOINT=your-cluster.xxxxx.ng.0001.use1.cache.amazonaws.com:6379 REDIS_AUTH_TOKEN=your_auth_token ENVIRONMENT=production SERVICE_NAME=elasticache-redis OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` > **Note**: CloudWatch Metrics Stream delivers the infrastructure > metrics (CPU, memory, connections, evictions) automatically. The > Redis receiver above adds cache internals like keyspace hit rates, > memory fragmentation, and connection details. For Memcached > clusters, use the > [Memcached receiver](../../component/memcached.md) instead. ### Step 3: Collect ElastiCache logs ElastiCache Redis supports two log types through CloudWatch: - **Slow log** - commands exceeding a latency threshold. - **Engine log** - connection events, failovers, configuration changes. Configure the CloudWatch Logs receiver: ```yaml showLineNumbers title="elasticache-logs-config.yaml" receivers: awscloudwatch/elasticache: region: ${env:AWS_REGION} logs: poll_interval: 1m groups: named: # Use the log group names you set as ElastiCache log-delivery # destinations (these names are user-chosen, not fixed by AWS) /aws/elasticache/cluster/${env:CLUSTER_ID}/slow-log: /aws/elasticache/cluster/${env:CLUSTER_ID}/engine-log: processors: attributes/add_source: actions: - key: source value: "elasticache" action: insert - key: cloud.provider value: "aws" action: insert batch: send_batch_size: 10000 send_batch_max_size: 11000 timeout: 10s exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: logs/elasticache: receivers: [awscloudwatch/elasticache] processors: [attributes/add_source, batch] exporters: [otlphttp/b14] ``` #### Enable slow log in ElastiCache In your ElastiCache parameter group, set: ```text slowlog-log-slower-than = 10000 # Log commands over 10ms (microseconds) slowlog-max-len = 128 # Keep last 128 slow commands ``` Then in the ElastiCache console, enable **Log delivery** for both slow log and engine log, targeting CloudWatch Logs. ### Verify the setup Start the Collector and check for metrics: ```bash showLineNumbers # Test Redis connectivity from the Collector host redis-cli -h ${REDIS_ENDPOINT%:*} -p 6379 \ --tls --cacert /etc/ssl/certs/ca-certificates.crt \ -a ${REDIS_AUTH_TOKEN} ping ``` Check Scout for both the CloudWatch metrics (named `amazonaws.com/AWS/ElastiCache/`) and the Redis receiver metrics (prefixed `redis.*`). ### Key alerts to configure | Metric | Warning | Critical | Why | | ------ | ------- | -------- | --- | | Cache hit rate | < 90% | < 80% | Low hit rate means cache isn't effective - requests hit the database instead | | `Evictions` | > 0 (sustained) | > 100/min | Evictions mean memory pressure is forcing useful data out | | `EngineCPUUtilization` | > 65% | > 80% | Redis is single-threaded - high CPU means commands are queuing | | `BytesUsedForCache` | > 80% of max | > 90% of max | Approaching memory limit triggers aggressive eviction | | `CurrConnections` | > 80% of max | > 90% of max | Connection exhaustion causes application errors | | `ReplicationLag` | > 5s | > 30s | High lag means replicas serve stale data | | `redis.memory.fragmentation_ratio` | > 1.5 | > 2.0 | High fragmentation wastes memory - consider a restart | | Slow log entries | > 10/min | > 50/min | Frequent slow commands indicate saturation - check slow log | **Cache hit rate formula:** `CacheHits / (CacheHits + CacheMisses) * 100` > **Why EngineCPUUtilization, not CPUUtilization?** ElastiCache Redis > is single-threaded. `CPUUtilization` shows total host CPU across > all cores, which can look low even when the Redis engine core is > saturated. `EngineCPUUtilization` shows the single-core usage that > actually matters. ### Troubleshooting #### Redis receiver shows no metrics **Cause**: Collector can't reach the ElastiCache cluster. **Fix**: 1. ElastiCache is VPC-only - the Collector must run in the same VPC or a peered VPC 2. Check the security group allows inbound on port 6379 from the Collector's security group 3. If encryption in transit is enabled, the Redis receiver must use TLS (`tls.insecure: false` with a CA cert) 4. Test connectivity: `redis-cli -h -p 6379 --tls -a ping` #### CloudWatch metrics not appearing **Cause**: Metrics Stream not configured for the AWS/ElastiCache namespace. **Fix**: 1. In CloudWatch > Metrics > Streams, verify the stream is active 2. Check that the namespace filter includes `AWS/ElastiCache` 3. Verify Amazon Data Firehose delivery is succeeding 4. Allow 5-10 minutes for initial metrics to flow #### High evictions but low memory usage **Cause**: The `maxmemory-policy` is set to a volatile policy (like `volatile-lru`) and keys without TTLs are filling memory, while keys with TTLs get evicted. **Fix**: 1. Check the eviction policy: `redis-cli CONFIG GET maxmemory-policy` 2. If using `volatile-lru`, consider switching to `allkeys-lru` 3. Review key TTL distribution - sample keys and check their TTLs to identify keys without expiration #### Cache hit rate dropping **Cause**: Application pattern change, insufficient memory, or key expiration settings. **Fix**: 1. Check if evictions are increasing (memory pressure pushing out useful keys) 2. Review whether application code is requesting keys that were never cached 3. Compare `CurrItems` trend - a sudden drop suggests mass expiration 4. Consider increasing node size or adding shards ### FAQ #### Should I use CloudWatch Metrics Stream or the Redis receiver? Use both. CloudWatch Metrics Stream provides host-level metrics (CPU, memory, network, evictions). The OTel Redis receiver adds cache internals like keyspace hit rates, memory fragmentation, and per-command detail. Together they give complete visibility. #### How do I monitor ElastiCache Redis slow commands? Enable the slow log in your ElastiCache parameter group by setting `slowlog-log-slower-than` to a threshold in microseconds (10000 = 10ms). Enable log delivery to CloudWatch Logs, then forward it to Scout via the CloudWatch Logs receiver. #### What is a good cache hit rate for ElastiCache Redis? Above 95% is healthy. Below 90% means a significant portion of requests miss the cache and hit the backend database. Track `CacheHits / (CacheHits + CacheMisses)` over time - a gradual decline often indicates growing data volume without proportional cache capacity. #### Can I monitor Memcached clusters with OpenTelemetry? Yes. CloudWatch Metrics Stream covers Memcached infrastructure metrics. For cache-specific metrics, the OTel Collector has a [Memcached receiver](../../component/memcached.md) that collects hit rates, evictions, connection counts, and memory usage - the Memcached equivalent of the Redis receiver above. #### How do I monitor multiple ElastiCache clusters? Add multiple Redis receiver blocks with distinct names: ```yaml receivers: redis/sessions: endpoint: sessions-cluster.xxxxx.cache.amazonaws.com:6379 redis/cache: endpoint: cache-cluster.xxxxx.cache.amazonaws.com:6379 ``` Then include both in the pipeline: `receivers: [redis/sessions, redis/cache]`. #### How do I set up alerts for ElastiCache? Route metrics through CloudWatch Metrics Stream to Scout, then alert on cache hit rate below 90%, sustained evictions above zero, memory usage above 80%, `EngineCPUUtilization` above 65%, replication lag above 5 seconds, and connections approaching the max. ### Related Guides - Configure AWS metrics streaming with [CloudWatch Metrics Stream Setup](./cloudwatch-metrics/cloudwatch-metrics-stream.md). - [Redis Monitoring](../../component/redis.md) - Self-hosted Redis monitoring with OpenTelemetry - [Memcached Monitoring](../../component/memcached.md) - Self-hosted Memcached monitoring - [RDS Monitoring](./rds.md) - Monitor AWS RDS databases - [ALB Monitoring](./elb.md) - Monitor AWS Application Load Balancers - [OTel Collector Configuration](../../collector-setup/otel-collector-config.md) for collector setup basics --- ## AWS ALB Monitoring with OpenTelemetry - Application Load Balancer Metrics ### Overview This guide covers collecting Application Load Balancer metrics (request counts, response times, HTTP status codes, and target health) via CloudWatch Metrics Stream, plus access logs through a Lambda forwarder. We recommend CloudWatch Metrics Stream over Prometheus exporters: it needs no per-service exporter and integrates natively with AWS. ### What You'll Monitor ALB monitoring combines two data sources - CloudWatch metrics for the aggregate picture and access logs for per-request detail: **CloudWatch Metrics Stream (AWS/ApplicationELB):** | Metric | What it tells you | | ------ | ----------------- | | `RequestCount` | Total requests the load balancer processed | | `TargetResponseTime` | Time targets took to respond (watch p90/p99) | | `HTTPCode_Target_2XX_Count` / `4XX` / `5XX` | Response codes returned by your targets | | `HTTPCode_ELB_4XX_Count` / `5XX_Count` | Errors generated by the load balancer itself | | `HealthyHostCount` / `UnHealthyHostCount` | Targets passing / failing health checks | | `ActiveConnectionCount` | Concurrent connections through the load balancer | | `NewConnectionCount` | New connections established per period | | `RejectedConnectionCount` | Connections dropped after hitting the connection limit | | `TargetConnectionErrorCount` | Connections that failed to reach a target | | `ProcessedBytes` | Total bytes processed (request and response) | | `ConsumedLCUs` | Capacity units consumed - the main cost driver | | `RequestCountPerTarget` | Average requests per target (scaling signal) | **Access logs (per-request fields via the Lambda forwarder):** | Field | What it tells you | | ----- | ----------------- | | `elb_status_code` | Status the load balancer returned to the client | | `target_status_code` | Status the target returned to the load balancer | | `target_processing_time` | Seconds the target took to process the request | | `request_processing_time` / `response_processing_time` | Time spent inside the load balancer | | `client:port` | Client IP and port that made the request | | `target:port` | Target IP and port that served it | | `request` | Method, URL, and HTTP version | | `user_agent` | Client user agent string | | `ssl_cipher` / `ssl_protocol` | TLS cipher and protocol negotiated | | `trace_id` | `X-Amzn-Trace-Id` for correlating across hops | ### Prerequisites | Requirement | Minimum | Recommended | | ----------- | ------- | ----------- | | Load balancer | Application Load Balancer | ALB with access logs enabled | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | | AWS permissions | CloudWatch, Amazon Data Firehose, S3, Lambda | - | Before starting: - An Application Load Balancer serving traffic. This guide covers the `AWS/ApplicationELB` namespace, not Network or Classic load balancers. - CloudWatch Metrics Stream infrastructure set up (see Step 1). - For access logs: an S3 bucket with ALB access logging enabled and the Lambda forwarder built below. ### Collecting Application ELB Metrics For collecting Application ELB metrics, we recommend using **CloudWatch Metrics Stream** instead of Prometheus exporters. CloudWatch Metrics Stream provides: - **Faster delivery**: 3-5 minutes end-to-end vs 5+ minutes with polling. - **Lower cost**: No need to run dedicated exporters. - **Better scalability**: Native AWS service integration. - **Automatic metric discovery**: No need to manually configure metric lists. #### Step 1: Set up CloudWatch Metrics Stream Follow our comprehensive [CloudWatch Metrics Stream guide](cloudwatch-metrics/cloudwatch-metrics-stream.md) to set up the infrastructure. #### Step 2: Configure Application ELB metrics filtering When configuring your CloudWatch Metrics Stream in **Step 3** of the setup guide, make sure to: 1. **Select specific namespaces** instead of "All namespaces" 2. **Choose only AWS/ApplicationELB** from the namespace list 3. This ensures you only collect Application ELB metrics, reducing costs and data volume > **Note**: CloudWatch Metrics Stream will automatically deliver all > AWS/ApplicationELB metrics including request counts, response times, HTTP > status codes, target health, connection counts, and more. ### Collecting Application ELB Logs Before wiring up the Lambda, enable access logging on the load balancer so log files land in S3. In the EC2 console, open your load balancer, go to **Attributes** > **Edit**, turn on **Access logs**, and point them at an S3 bucket. AWS also needs a bucket policy allowing the ELB log-delivery account to write there; the console offers to create it. Without this, the bucket stays empty and the Lambda never fires. #### Step 1: Creating a Lambda function 1. Go to your AWS console and search for AWS Lambda, go to Functions and click on Create Function. 2. Choose the `Author from scratch` checkbox and proceed to fill in the function name. 3. Choose `Python 3.x` as the Runtime version, `x86_64` as Architecture (preferably), and keep other settings as default. Select `Create a new role with basic Lambda permissions` for now, we'll require more permissions later. So for now, select this option. 4. Once you are done configuring the Lambda function, your Lambda function is created. #### Step 2: Configuring Policies for Lambda function > As said in previous step, we need extra permissions in order to access the S3 > Bucket for execution of our Lambda code, follow along to set it up. 1. Scroll down from your Lambda page, you'll see a few tabs there. Go to `Configurations` and select `Permissions` from the left sidebar. 2. Click on the `Execution Role name` link just under Role name to open the role in the AWS IAM console. 3. Click `Add permissions` > `Create inline policy`, switch to the JSON editor, paste the policy below (scoped to your log bucket only), then name and create it. ```json title="lambda-s3-read-policy.json" { "Version": "2012-10-17", "Statement": [ { "Effect": "Allow", "Action": "s3:GetObject", "Resource": "arn:aws:s3:::your-alb-logs-bucket/*" } ] } ``` Replace `your-alb-logs-bucket` with your bucket name. The function only needs to read log objects, so avoid broad policies like `AmazonS3FullAccess`. #### Step 3: Adding Triggers 1. Navigate to the Lambda function we just created. 2. Click on the `+ Add trigger` button from the Lambda console. 3. Select S3 from the first drop down of AWS services list. Pick your S3 bucket for the second field. 4. For the Event types field, you can select any number of options you wish. The trigger will occur depending upon what option(s) you choose here. By default, the `All object create events` will be selected. 5. Verify the settings and click on `Add` button at bottom right to add this trigger. #### Step 4: Adding Request Layer We will be using python's request module which is not included by default in Lambda. ```bash # create the layer directory (Lambda expects dependencies under python/) mkdir -p python # install the requests module into it pip install --target python requests # zip it with python/ at the archive root zip -r dependencies.zip python ``` 1. Run the above commands to create a zip of the request module and add it as a layer to make it work on AWS Lambda. 2. To upload your zip file, go to AWS Lambda > Layers and click on `Create Layer`. [Not inside your specific Lambda function, just the landing page of AWS Lambda]. 3. You'll be redirected to Layer configurations page. Here, give a name to your layer, an optional description, select `Upload a .zip file`, click on `Upload` and locate the `dependencies.zip` file. 4. Select the **same architecture** and Python runtime as the function - the layer must match, or the `requests` import fails at runtime. Hit `Create` to build the layer. 5. Go to your Lambda function, scroll down to Layers section and on the right of it, you'll find a button that says `Add a layer` to click on. 6. Pick `Custom layers` from the checkbox and select your custom layer from the given drop down below and then click on the button `Add`. #### Step 5: The Lambda Function The Lambda function reads gzipped ALB access-log files from S3, converts each log line to OTLP JSON, and posts the result to your Collector endpoint. ```python import json import gzip import boto3 import requests import shlex import os from datetime import datetime # Create an S3 client s3 = boto3.client('s3') client_id=os.environ.get('CLIENT_ID') client_secret=os.environ.get('CLIENT_SECRET') token_url=os.environ.get('TOKEN_URL') endpoint_url=os.environ.get('ENDPOINT_URL') # Function to convert a log line into a JSON object def convert_log_line_to_json(line): # Define the headers to be used for the JSON keys (ALB log format) headers = ["type", "time", "elb", "client:port", "target:port", "request_processing_time", "target_processing_time", "response_processing_time", "elb_status_code", "target_status_code", "received_bytes", "sent_bytes", "request", "user_agent", "ssl_cipher", "ssl_protocol", "target_group_arn", "trace_id", "domain_name", "chosen_cert_arn", "matched_rule_priority", "request_creation_time", "actions_executed", "redirect_url", "error_reason", "target:port_list", "target_status_code_list", "classification", "classification_reason"] # Split the log line using shell-like syntax (keeping quotes, etc.) parts = shlex.split(line, posix=False) # Create a dictionary with as many pairs as possible result = {} for i in range(min(len(headers), len(parts))): result[headers[i]] = parts[i] return result # Convert logs to OTLP format def convert_to_otlp_format(logs): current_time_ns = int(datetime.now().timestamp() * 1_000_000_000) # nanoseconds # Create OTLP log records resource_logs = { "resourceLogs": [{ "resource": { "attributes": [ {"key": "service.name", "value": {"stringValue": "alb"}}, {"key": "cloud.provider", "value": {"stringValue": "aws"}}, {"key": "environment", "value": {"stringValue": os.environ.get('ENVIRONMENT', 'production')}} ] }, "scopeLogs": [{ "scope": {}, "logRecords": [] }] }] } # Add each log entry as a log record for log in logs: # Create attributes from log fields attributes = [] for key, value in log.items(): attributes.append({ "key": key, "value": {"stringValue": value} }) # Get timestamp if available, or use current time timestamp = current_time_ns if "time" in log: try: # Try to parse the ALB log timestamp format dt = datetime.strptime(log["time"], "%Y-%m-%dT%H:%M:%S.%fZ") timestamp = int(dt.timestamp() * 1_000_000_000) except (ValueError, TypeError): pass # Create a log record log_record = { "timeUnixNano": timestamp, "severityText": "INFO", "body": {"stringValue": json.dumps(log)}, "attributes": attributes } resource_logs["resourceLogs"][0]["scopeLogs"][0]["logRecords"].append(log_record) return resource_logs # Lambda function handler def lambda_handler(event, context): try: # Check if this is being triggered by an S3 event if 'Records' in event and event['Records'][0].get('eventSource') == 'aws:s3': # Get the S3 bucket and key from the event s3_event = event['Records'][0]['s3'] bucket_name = s3_event['bucket']['name'] file_key = s3_event['object']['key'] # Only process log files if not file_key.endswith('.log.gz'): print(f"Skipping non-log file: {file_key}") return { 'statusCode': 200, 'body': 'Skipped non-log file' } log_files = [file_key] else: print(f"Manual Trigger is not supported yet") return { 'statusCode': 403, 'body': 'Manual Trigger is not supported yet' } processed_files = 0 total_logs = 0 # Process each log file for file_key in log_files: print(f"Processing file: {bucket_name}/{file_key}") # Download the gzipped file content file_obj = s3.get_object(Bucket=bucket_name, Key=file_key) file_content = file_obj['Body'].read() # Decompress the gzipped content decompressed_content = gzip.decompress(file_content) # Convert bytes to string log_text = str(decompressed_content, encoding='utf-8') # Split the string into lines and filter out empty lines lines = [line for line in log_text.strip().split('\n') if line.strip()] log_count = len(lines) print(f"File contains {log_count} log entries") # Process logs in batches to prevent timeouts batch_size = int(os.environ.get('BATCH_SIZE', '100')) for i in range(0, log_count, batch_size): batch_lines = lines[i:min(i + batch_size, log_count)] # Convert each log line string into a JSON object json_logs = [convert_log_line_to_json(line) for line in batch_lines] # Convert to OTLP format otlp_data = convert_to_otlp_format(json_logs) # Set headers for OTEL collector headers = { 'Content-Type': 'application/json' } http_url = f"{endpoint_url}/v1/logs" token_response = requests.post( token_url, data={ "grant_type": "client_credentials", "audience": "b14collector", }, auth=(client_id, client_secret), ) token_response.raise_for_status() access_token = token_response.json()["access_token"] headers["Authorization"] = f"Bearer {access_token}" # Send the JSON data to the OTEL collector try: response = requests.post(http_url, json=otlp_data, headers=headers, timeout=float(os.environ.get('REQUEST_TIMEOUT', '5'))) response.raise_for_status() print(f"Sent batch of {len(batch_lines)} logs to {http_url}. Response: {response.status_code}") except requests.exceptions.RequestException as e: print(f"Error sending logs to OTEL collector: {str(e)}") if hasattr(e, 'response') and e.response: print(f"Response status: {e.response.status_code}") print(f"Response body: {e.response.text[:200]}...") total_logs += log_count processed_files += 1 return { 'statusCode': 200, 'body': f'Successfully processed {processed_files}:{total_logs} log entries' } except Exception as e: print(f"Error processing logs: {str(e)}") import traceback traceback.print_exc() return { 'statusCode': 500, 'body': f'Error: {str(e)}' } ``` > Set the Lambda's environment variables: `CLIENT_ID`, `CLIENT_SECRET`, > `TOKEN_URL`, `ENDPOINT_URL` (your Scout OTLP base endpoint - the function > appends `/v1/logs`), and `ENVIRONMENT` (for example `production`). ### Verify the setup After deploying, send traffic through the load balancer, then confirm both paths are flowing: 1. In Scout, check for the CloudWatch metrics, named `amazonaws.com/AWS/ApplicationELB/` (request counts, response times, HTTP status codes). 2. Wait for an access-log object to land in the S3 bucket, then open the Lambda's CloudWatch log group - a successful run logs `Sent batch of N logs ... Response: 200`. 3. In Scout, check for logs with `service.name = alb`. Allow 5-10 minutes for the first metrics to arrive through the stream. ### Key alerts to configure Once telemetry is flowing, set up alerts on these thresholds: | Metric | Warning | Critical | Why | | ------ | ------- | -------- | --- | | `HTTPCode_ELB_5XX_Count` | > 0 sustained | spiking | The load balancer itself is failing requests | | `HTTPCode_Target_5XX_Count` | > 1% of requests | > 5% of requests | Targets are returning server errors | | `TargetResponseTime` (p99) | > 1s | > 3s | Backend latency is degrading user experience | | `UnHealthyHostCount` | > 0 | half the targets or more | Targets are failing health checks | | `RejectedConnectionCount` | > 0 | sustained | Connection limit reached (LCU saturation) | | `TargetConnectionErrorCount` | > 0 | sustained | Load balancer cannot reach its targets | CloudWatch Metrics Stream adds 3-5 minutes of latency, so treat these as trend and capacity alerts, not sub-minute failure detection. The access logs add the per-request detail - client IP, target, `elb_status_code`, processing times - to debug the 5xx spikes the metrics surface. ### Troubleshooting #### ALB metrics not appearing in Scout **Cause**: Metrics Stream isn't active or isn't filtered to the ELB namespace. **Fix**: 1. In CloudWatch > Metrics > Streams, verify the stream is active 2. Confirm the namespace filter includes `AWS/ApplicationELB` 3. Check that Firehose delivery is succeeding (look at the S3 error prefix) 4. Allow 5-10 minutes for initial metrics to flow #### Access logs never reach Scout **Cause**: Access logging is off, or the Lambda isn't triggered. **Fix**: 1. Confirm access logging is enabled on the load balancer and objects are landing in the S3 bucket 2. Verify the bucket policy grants the ELB log-delivery account write access 3. Check the S3 trigger fires the Lambda on object-create events 4. Read the Lambda's CloudWatch logs for errors #### Lambda fails with "No module named requests" **Cause**: The requests layer isn't attached, or its architecture doesn't match. **Fix**: 1. Attach the `dependencies.zip` layer to the function 2. Ensure the dependencies sit under `python/` at the archive root 3. Confirm the layer's architecture and Python runtime match the function #### Lambda gets 401 or 403 from the Collector **Cause**: Wrong OAuth2 credentials or endpoint. **Fix**: 1. Verify `CLIENT_ID`, `CLIENT_SECRET`, and `TOKEN_URL` 2. Confirm `ENDPOINT_URL` is the base OTLP endpoint (the function appends `/v1/logs`) 3. Check the token `audience` is `b14collector` ### FAQ #### How do I monitor AWS ALB with OpenTelemetry? Use CloudWatch Metrics Stream to collect AWS/ApplicationELB metrics with 3-5 minute end-to-end latency, then forward them through an OpenTelemetry Collector to base14 Scout for visualization and alerting. #### What ALB metrics does CloudWatch Metrics Stream provide? All AWS/ApplicationELB metrics - request counts, target response times, HTTP status codes (ELB and target), healthy/unhealthy host counts, connection counts, and consumed LCUs. #### How do I collect AWS ALB access logs with OpenTelemetry? Enable access logging on the load balancer, then trigger a Lambda on S3 object-create events. The Lambda reads each gzipped log file, converts entries to OTLP, and forwards them to your Collector endpoint. #### Should I use CloudWatch Metrics Stream or Prometheus for ALB monitoring? CloudWatch Metrics Stream is recommended: faster delivery (3-5 min end-to-end vs 5+ min), no dedicated exporter to run, and automatic metric discovery for AWS services. #### How do I filter ALB metrics in CloudWatch Metrics Stream? When configuring the stream, select specific namespaces and choose only `AWS/ApplicationELB`. This keeps costs and data volume down in Scout. #### How do I set up alerts for AWS ALB? Route AWS/ApplicationELB metrics through CloudWatch Metrics Stream to Scout, then alert on sustained `HTTPCode_ELB_5XX_Count`, `HTTPCode_Target_5XX_Count` above 1% of requests, `TargetResponseTime` p99 above 1s, `UnHealthyHostCount` above zero, and rising `RejectedConnectionCount` or `TargetConnectionErrorCount`. ### Related Guides - Set up AWS metrics streaming with [CloudWatch Metrics Stream Setup](./cloudwatch-metrics/cloudwatch-metrics-stream.md). - [RDS Monitoring](./rds.md) - Monitor AWS RDS databases - [ElastiCache Monitoring](./elasticache.md) - Monitor Redis and Memcached - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - Set up collector for local development --- ## AWS Monitoring with base14 Scout - Metrics, Logs, and Traces ### Overview base14 Scout ingests AWS telemetry through the OpenTelemetry Collector - metrics from CloudWatch, logs from CloudWatch Logs and S3, and traces from instrumented applications. Use the guides below to wire up each AWS service. ### In this section | Guide | What it covers | | ----- | -------------- | | [CloudWatch Metrics](./cloudwatch-metrics/overview.md) | Four ways to get CloudWatch metrics into Scout - push and pull compared. | | [AWS RDS](./rds.md) | PostgreSQL metrics, logs, and alerts. | | [AWS ALB](./elb.md) | Load balancer request rates, latencies, and target health. | | [AWS ElastiCache](./elasticache.md) | Redis and Memcached cache metrics. | | [AWS Amazon MQ](./amazonMQ.md) | RabbitMQ and ActiveMQ broker metrics and logs. | | [AWS Lambda](./lambda.md) | Auto-instrument functions for traces, metrics, and logs. | | [AWS VPC Flow Logs](./aws-vpc.md) | Stream VPC flow logs to Scout via S3 and Lambda. | ### Getting started with CloudWatch metrics Most AWS services publish their metrics to CloudWatch, so that's where most setups begin. The [CloudWatch Metrics](./cloudwatch-metrics/overview.md) section compares four approaches - two push paths (Amazon Data Firehose to the Collector, or Firehose to S3 to Lambda), the Prometheus CloudWatch exporter (pull), and the CloudWatch datasource (query at render time, no ingestion) - so you can pick the one that fits your latency and cost constraints. The per-service guides build on whichever approach you choose. ### Related guides - [Scout OTLP exporter](../../collector-setup/scout-exporter.md) - the Collector export block every AWS pipeline reuses. --- ## AWS Lambda OpenTelemetry Instrumentation - Traces, Metrics & Logs Brief guide to instrument AWS Lambda functions with OpenTelemetry using Lambda layers for automatic tracing with direct export to Scout Collector. ### Overview This guide covers auto-instrumentation of AWS Lambda functions using OpenTelemetry Lambda layers. The language-specific layer automatically instruments your code and exports traces to the Scout collector. **Key benefits:** - Zero-code instrumentation - Automatic trace generation - Minimal performance overhead ### Prerequisites - AWS Lambda function (Python 3.8+, Node.js 18+, Java 17+, or Ruby 3.2+) - Lambda execution role with CloudWatch Logs permissions - Scout Collector OTLP endpoint URL ### Layer ARNs by Region OpenTelemetry Lambda layers are available in all AWS regions. Use the following ARN format: ```text arn:aws:lambda::184161586896:layer:opentelemetry--:1 ``` **Example for `ap-south-1` (Mumbai):** - Python: `arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-python-0_17_0:1` - Node.js: `arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-nodejs-0_17_0:1` - Java Agent: `arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-javaagent-0_16_0:1` - Ruby: `arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-ruby-0_10_0:1` Replace `` with your AWS region and check [OpenTelemetry Lambda releases](https://github.com/open-telemetry/opentelemetry-lambda/releases) for the latest versions. ### Step 1: Add Lambda Layers Add both the language-specific layer and collector layer to your function: ```mdx-code-block import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --layers \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-python-0_17_0:1" \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-collector-amd64-0_18_0:1" ``` ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --layers \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-nodejs-0_17_0:1" \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-collector-amd64-0_18_0:1" ``` ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --layers \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-javaagent-0_16_0:1" \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-collector-amd64-0_18_0:1" ``` ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --layers \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-ruby-0_10_0:1" \ "arn:aws:lambda:ap-south-1:184161586896:layer:opentelemetry-collector-amd64-0_18_0:1" ``` ```mdx-code-block ``` **Note**: For ARM64 architecture, replace `amd64` with `arm64` in the collector layer ARN. ### Step 2: Understanding the Collector Layer and TelemetryAPI The OpenTelemetry Collector layer serves as a sidecar process that collects and exports telemetry data from your Lambda function. It subscribes to the **AWS Lambda Telemetry API** to automatically capture platform-level telemetry. #### What the Collector Layer Collects The collector layer collects three types of telemetry: **1. Traces (from instrumentation layer)** - Application spans, HTTP/HTTPS requests, database queries, external service calls, and custom spans **2. Logs (via TelemetryAPI)** - Function logs (stdout/stderr), platform logs (START, END, REPORT), runtime errors, and structured logs #### Resource Requirements - **Memory overhead**: 64-128 MB for collector process - **Timeout**: Add 5-10 seconds to allow telemetry export - **Cold start impact**: +50-100ms ### Step 3: Configure Environment Variables Set required environment variables to enable auto-instrumentation: ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --environment "Variables={ AWS_LAMBDA_EXEC_WRAPPER=/opt/otel-instrument, OTEL_PYTHON_LOGGING_AUTO_INSTRUMENTATION_ENABLED=true OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_LOG_LEVEL=error OTEL_SERVICE_NAME=, OTEL_TRACES_EXPORTER=otlp, OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318, OPENTELEMETRY_COLLECTOR_CONFIG_URI=/var/task/collector.yaml }" ``` ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --environment "Variables={ AWS_LAMBDA_EXEC_WRAPPER=/opt/otel-handler, OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_LOG_LEVEL=error OTEL_SERVICE_NAME=, OTEL_NODE_ENABLED_INSTRUMENTATIONS=aws-lambda,http OTEL_TRACES_EXPORTER=otlp, OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318, OPENTELEMETRY_COLLECTOR_CONFIG_URI=/var/task/collector.yaml }" ``` ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --environment "Variables={ AWS_LAMBDA_EXEC_WRAPPER=/opt/otel-handler, OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_LOG_LEVEL=error OTEL_SERVICE_NAME=, OTEL_TRACES_EXPORTER=otlp, OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318, OPENTELEMETRY_COLLECTOR_CONFIG_URI=/var/task/collector.yaml }" ``` ```mdx-code-block ``` ```bash aws lambda update-function-configuration \ --function-name \ --region ap-south-1 \ --environment "Variables={ AWS_LAMBDA_EXEC_WRAPPER=/opt/otel-handler, OTEL_EXPORTER_OTLP_PROTOCOL=http/protobuf OTEL_LOG_LEVEL=error OTEL_SERVICE_NAME=, OTEL_TRACES_EXPORTER=otlp, OTEL_EXPORTER_OTLP_ENDPOINT=http://localhost:4318, OPENTELEMETRY_COLLECTOR_CONFIG_URI=/var/task/collector.yaml }" ``` ```mdx-code-block ``` **Note**: The `OTEL_EXPORTER_OTLP_ENDPOINT` is set to `http://localhost:4318`, which points to the OTel Collector layer running alongside your Lambda function. ### Step 4: Create Collector Configuration Create a `collector.yaml` file in your Lambda function package to configure how the collector exports telemetry to Scout: ```yaml title="collector.yaml" receivers: otlp: protocols: http: endpoint: localhost:4318 telemetryapi: exporters: otlphttp: endpoint: service: pipelines: traces: receivers: [otlp, telemetryapi] exporters: [otlphttp] metrics: receivers: [otlp] exporters: [otlphttp] logs: receivers: [otlp, telemetryapi] exporters: [otlphttp] ``` Replace `` with your Scout collector OTLP endpoint **Deploy the collector config with your function:** ```bash # Add collector.yaml to your deployment package zip function.zip lambda_function.* collector.yaml # Update function code aws lambda update-function-code \ --function-name \ --zip-file fileb://function.zip \ --region ap-south-1 ``` ### Step 5: Test Your Instrumentation Invoke your Lambda function to generate traces. You can use the AWS CLI, AWS Console, or any trigger configured for your function. View traces in Scout dashboard #### Resource Attributes Add custom resource attributes to all spans: ```bash OTEL_RESOURCE_ATTRIBUTES=environment=demo,team=backend ``` ### FAQ #### Do I need to change my function code to get traces from Lambda? No. The language layer wraps the handler through `AWS_LAMBDA_EXEC_WRAPPER` and instruments HTTP clients, AWS SDK calls, and supported frameworks automatically. Code changes are only needed for custom spans or attributes. #### Why does the OTLP endpoint point at localhost? The collector layer runs as an extension inside the same execution environment. The instrumentation layer sends spans to `http://localhost:4318`, and the collector, configured through `collector.yaml`, forwards them to Scout. Only the collector needs the Scout endpoint and credentials. #### How much latency does the collector layer add? Plan for 50-100 ms on cold starts and 64-128 MB of extra memory for the collector process. Add 5-10 seconds to the function timeout so the collector can flush telemetry before the environment is frozen. #### How do I get function logs, not just traces, into Scout? Add the `telemetryapi` receiver to the logs pipeline in `collector.yaml`. It subscribes to the Lambda Telemetry API and captures stdout, stderr, and the platform START, END, and REPORT records without any log shipping code. #### Does this work on ARM64 (Graviton) functions? Yes. Use the `arm64` collector layer ARN instead of `amd64`. The language layers are architecture independent. ### Related Guides - [OTel Collector Configuration](../../collector-setup/otel-collector-config.md) \- Detailed collector setup - [AWS ECS OTel Setup](../../collector-setup/ecs-setup.md) - Container-based deployments - [Python Custom Instrumentation](../../apps/custom-instrumentation/python.md) \- Manual Python tracing - [Node.js Custom Instrumentation](../../apps/custom-instrumentation/javascript-node.md) \- Manual Node.js tracing - [Java Custom Instrumentation](../../apps/custom-instrumentation/java.md) \- Manual Java tracing ### References - [OpenTelemetry Lambda GitHub](https://github.com/open-telemetry/opentelemetry-lambda) - [OpenTelemetry Lambda Releases](https://github.com/open-telemetry/opentelemetry-lambda/releases) --- ## AWS RDS PostgreSQL Monitoring with OpenTelemetry - Metrics, Logs & Alerts :::note Running this in production pgX adds query, lock, and connection analysis on top of these metrics. [Check out base14 pgX](https://base14.io/scout/pgx). ::: ### Overview This guide covers monitoring AWS RDS PostgreSQL instances using OpenTelemetry and CloudWatch Metrics Stream. You'll collect infrastructure metrics from CloudWatch, database-specific metrics from the PostgreSQL receiver, and logs from CloudWatch Logs - all flowing into base14 Scout for unified visibility. ### What You'll Monitor RDS PostgreSQL monitoring combines two metric sources that together provide complete visibility: **CloudWatch Metrics Stream (infrastructure):** | Metric | What it tells you | | ------ | ----------------- | | `CPUUtilization` | Instance CPU usage (%) | | `FreeableMemory` | Available RAM (bytes) | | `FreeStorageSpace` | Remaining disk space (bytes) | | `ReadIOPS` / `WriteIOPS` | Disk read/write operations per second | | `ReadLatency` / `WriteLatency` | Average time per disk I/O operation | | `DatabaseConnections` | Active database connections | | `ReplicaLag` | Replication delay for read replicas (seconds) | | `DiskQueueDepth` | Number of I/O requests waiting | | `NetworkReceiveThroughput` / `NetworkTransmitThroughput` | Network bytes in/out | | `SwapUsage` | Swap space used (bytes) | | `BurstBalance` | Remaining I/O burst credits (gp2) | **OTel PostgreSQL receiver (database internals):** | Metric | What it tells you | | ------ | ----------------- | | `postgresql.backends` | Active connections per database | | `postgresql.commits` / `postgresql.rollbacks` | Transaction rates | | `postgresql.database.locks` | Active locks by type | | `postgresql.deadlocks` | Deadlock count | | `postgresql.sequential_scans` / `postgresql.index.scans` | Scan type distribution | | `postgresql.rows` | Rows affected by operations | | `postgresql.table.size` / `postgresql.index.size` | Storage per table/index | | `postgresql.table.vacuum.count` | Vacuum frequency | | `postgresql.blks_hit` / `postgresql.blks_read` | Buffer cache hit ratio | | `postgresql.replication.data_delay` | Replication byte lag | | `postgresql.tup_inserted` / `postgresql.tup_updated` / `postgresql.tup_deleted` | Tuple operations | ### Prerequisites | Requirement | Minimum | Recommended | | ----------- | ------- | ----------- | | RDS PostgreSQL | 11 | 14+ | | OTel Collector Contrib | 0.90.0 | latest | | base14 Scout | Any | - | | AWS permissions | CloudWatch, Amazon Data Firehose, S3, CloudWatch Logs | - | Before starting: - RDS instance must be accessible from the host running the OTel Collector (same VPC or VPC peering). - A monitoring user with `pg_monitor` role for the PostgreSQL receiver. - CloudWatch Metrics Stream infrastructure set up (see Step 1). ### Step 1: Set up CloudWatch Metrics Stream Follow our comprehensive [CloudWatch Metrics Stream guide](cloudwatch-metrics/cloudwatch-metrics-stream.md) to set up the streaming infrastructure (S3 bucket, Amazon Data Firehose, Metrics Stream). When configuring the Metrics Stream, select the **AWS/RDS** namespace instead of "All namespaces" to only collect RDS metrics and reduce costs. ### Step 2: Create a monitoring user on RDS Connect to your RDS PostgreSQL instance and create a dedicated monitoring user: ```sql CREATE USER otel_monitor WITH PASSWORD ''; GRANT pg_monitor TO otel_monitor; ``` The `pg_monitor` role provides read-only access to all statistics views needed for monitoring. No write permissions required. For RDS instances, ensure the security group allows connections from the Collector host on port 5432. ### Step 3: Configure the OTel Collector for PostgreSQL metrics Create `rds-postgres-config.yaml` with both the PostgreSQL receiver and the CloudWatch metrics pipeline: ```yaml showLineNumbers title="rds-postgres-config.yaml" receivers: postgresql: endpoint: ${env:RDS_ENDPOINT} collection_interval: 10s username: ${env:RDS_MONITOR_USER} password: ${env:RDS_MONITOR_PASSWORD} databases: ["${env:RDS_DATABASE}"] tls: insecure_skip_verify: true metrics: postgresql.database.locks: enabled: true postgresql.deadlocks: enabled: true postgresql.sequential_scans: enabled: true postgresql.index.scans: enabled: true postgresql.backends: enabled: true postgresql.commits: enabled: true postgresql.rollbacks: enabled: true postgresql.db_size: enabled: true postgresql.table.count: enabled: true postgresql.table.size: enabled: true postgresql.index.size: enabled: true postgresql.table.vacuum.count: enabled: true postgresql.rows: enabled: true postgresql.blks_hit: enabled: true postgresql.blks_read: enabled: true postgresql.tup_inserted: enabled: true postgresql.tup_updated: enabled: true postgresql.tup_deleted: enabled: true postgresql.tup_fetched: enabled: true postgresql.replication.data_delay: enabled: true processors: resource: attributes: - key: environment value: ${env:ENVIRONMENT} action: upsert - key: service.name value: ${env:SERVICE_NAME} action: upsert - key: cloud.provider value: aws action: upsert batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: metrics: receivers: [postgresql] processors: [resource, batch] exporters: [otlphttp/b14] ``` #### Environment variables ```bash showLineNumbers title=".env" RDS_ENDPOINT=your-rds-instance.xxxxx.us-east-1.rds.amazonaws.com:5432 RDS_MONITOR_USER=otel_monitor RDS_MONITOR_PASSWORD=your_password RDS_DATABASE=your_database ENVIRONMENT=production SERVICE_NAME=rds-postgres OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io ``` > **Note**: CloudWatch Metrics Stream delivers the infrastructure > metrics (CPU, memory, IOPS) automatically. The PostgreSQL receiver > above collects the database-internal metrics. Read them together to > correlate host pressure with in-database activity. ### Step 4: Collect RDS PostgreSQL logs RDS PostgreSQL publishes logs to CloudWatch Log Groups. Use the CloudWatch Logs receiver to forward them: ```yaml showLineNumbers title="rds-postgres-logs-config.yaml" receivers: awscloudwatch/rds_postgres: region: ${env:AWS_REGION} logs: poll_interval: 1m groups: named: # Replace with your RDS log group name /aws/rds/instance/${env:RDS_INSTANCE_ID}/postgresql: processors: attributes/add_source: actions: - key: source value: "rds_postgres" action: insert - key: cloud.provider value: "aws" action: insert batch: send_batch_size: 10000 send_batch_max_size: 11000 timeout: 10s exporters: otlphttp/b14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} tls: insecure_skip_verify: true service: pipelines: logs/rds: receivers: [awscloudwatch/rds_postgres] processors: [attributes/add_source, batch] exporters: [otlphttp/b14] ``` #### Enable recommended RDS log types In the RDS console under **Configuration > Log exports**, enable: - **PostgreSQL log** - query errors, connection events, autovacuum. - **Upgrade log** - major version upgrade details. For query-level logging, set these RDS parameter group values: ```text log_statement = 'ddl' log_min_duration_statement = 1000 # Log queries over 1 second log_connections = on log_disconnections = on ``` ### Verify the setup Start the Collector and check for metrics within 60 seconds: ```bash showLineNumbers # Test PostgreSQL connectivity from the Collector host psql -h ${RDS_ENDPOINT%:*} -p 5432 -U otel_monitor \ -d ${RDS_DATABASE} -c "SELECT version();" ``` ```sql showLineNumbers -- Verify monitoring permissions SELECT * FROM pg_stat_database WHERE datname = 'your_database'; SELECT * FROM pg_stat_user_tables LIMIT 5; ``` Check Scout for both the CloudWatch metrics (named `amazonaws.com/AWS/RDS/`) and the PostgreSQL receiver metrics (prefixed `postgresql.*`). ### Key alerts to configure Once metrics are flowing, set up alerts on these thresholds: | Metric | Warning | Critical | Why | | ------ | ------- | -------- | --- | | `CPUUtilization` | > 70% | > 85% | Sustained high CPU degrades query performance | | `DatabaseConnections` | > 80% of max | > 90% of max | Connection exhaustion causes application errors | | `FreeStorageSpace` | < 20% | < 10% | Running out of storage crashes the instance | | `ReplicaLag` | > 10s | > 60s | High lag means read replicas serve stale data | | `ReadLatency` / `WriteLatency` | > 10ms | > 20ms | I/O latency spikes indicate storage bottlenecks | | `DiskQueueDepth` | > 10 | > 20 | Deep queue means I/O is saturated | | `postgresql.deadlocks` | > 0 | > 5/min | Deadlocks indicate application-level locking issues | | Buffer hit ratio | < 95% | < 90% | Low hit ratio means too many disk reads | Buffer hit ratio: calculate as `blks_hit / (blks_hit + blks_read) * 100`. ### Troubleshooting #### PostgreSQL receiver shows no metrics **Cause**: Collector can't reach the RDS instance. **Fix**: 1. Verify the RDS instance security group allows inbound on port 5432 from the Collector's IP or security group 2. Confirm the RDS instance is not in a private subnet without a route to the Collector 3. Test connectivity: `psql -h -U otel_monitor -d ` 4. Check the monitoring user has `pg_monitor` role: `SELECT rolname FROM pg_roles WHERE pg_has_role('otel_monitor', oid, 'member');` #### CloudWatch metrics not appearing **Cause**: Metrics Stream not configured for the AWS/RDS namespace. **Fix**: 1. In CloudWatch > Metrics > Streams, verify the stream is active 2. Check that the namespace filter includes `AWS/RDS` 3. Verify Amazon Data Firehose delivery is succeeding (check the S3 error bucket) 4. Allow 5-10 minutes for initial metrics to flow #### Replication lag metrics showing zero **Cause**: No read replicas configured, or the instance is a replica (not the primary). **Fix**: 1. `ReplicaLag` is only populated on read replica instances 2. `postgresql.replication.data_delay` requires at least one replica connected to the primary 3. On the primary, check: `SELECT * FROM pg_stat_replication;` #### High connection count but low CPU **Cause**: Idle connections consuming connection slots. **Fix**: 1. Check for idle connections: `SELECT count(*) FROM pg_stat_activity WHERE state = 'idle';` 2. Consider connection pooling (PgBouncer or RDS Proxy) 3. Set `idle_in_transaction_session_timeout` in the parameter group ### FAQ #### Do I need both CloudWatch Metrics Stream and the PostgreSQL receiver? Yes. CloudWatch Metrics Stream delivers infrastructure metrics (CPU, memory, IOPS, connections), while the PostgreSQL receiver adds database internals like locks, deadlocks, sequential scans, and tuple operations. Together they give complete visibility. #### How do I collect RDS PostgreSQL logs with OpenTelemetry? Use the AWS CloudWatch Logs receiver (`awscloudwatch`) with your RDS log group names. The Collector polls CloudWatch Logs and forwards the entries to Scout. Enable the PostgreSQL and upgrade log exports in the RDS console first. #### How do I monitor RDS PostgreSQL query performance? Enable the `pg_stat_statements` extension for per-query statistics, then use the [PostgreSQL Advanced guide](../../component/postgres-advanced.md) for detailed query-level monitoring. #### What is the difference between CloudWatch metrics and Enhanced Monitoring? CloudWatch metrics are collected at 1-minute intervals and cover instance-level stats. Enhanced Monitoring provides OS-level metrics at up to 1-second granularity (per-process CPU, memory, file system). Enable Enhanced Monitoring when you need to diagnose issues that 1-minute intervals miss. #### Can I monitor multiple RDS instances with one Collector? Yes. Add multiple PostgreSQL receiver blocks with distinct names: ```yaml receivers: postgresql/primary: endpoint: primary.xxxxx.rds.amazonaws.com:5432 postgresql/replica: endpoint: replica.xxxxx.rds.amazonaws.com:5432 ``` Then include both in the pipeline: `receivers: [postgresql/primary, postgresql/replica]`. #### How do I set up alerts for RDS PostgreSQL? Route metrics through CloudWatch Metrics Stream to Scout, then alert on CPU above 70%, connections above 80% of max, replication lag beyond your SLA, storage below 20% free, and read/write latency spikes. ### Related Guides - Configure AWS metrics streaming with [CloudWatch Metrics Stream Setup](./cloudwatch-metrics/cloudwatch-metrics-stream.md). - [PostgreSQL Basic Monitoring](../../component/postgres.md) - Direct PostgreSQL monitoring with the OTel receiver - [PostgreSQL Advanced Monitoring](../../component/postgres-advanced.md) - Query statistics, per-table I/O, replication details - [ALB Monitoring](./elb.md) - Monitor AWS Application Load Balancers - [ElastiCache Monitoring](./elasticache.md) - Monitor Redis and Memcached on AWS --- ## Azure Kubernetes Service Monitoring with OpenTelemetry Helm Releases :::note Looking for the canonical operator-managed AKS guide? See [the operator guide](aks.md). This guide uses raw Helm releases for readers who prefer not to install the OpenTelemetry Operator (cluster-scoped CRDs blocked by org policy, or operator already in use for unrelated workloads). ::: This guide runs the OpenTelemetry Collector twice in an Azure Kubernetes Service (AKS) cluster - as a DaemonSet for per-node metrics, and as a single-replica Deployment for cluster-wide state. Both ship OTLP/HTTP to base14 Scout. :::tip Architecture overview This guide is the **execution playbook** for AKS via the OpenTelemetry Helm chart. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide covers the **in-cluster pattern** (agent DaemonSet + cluster collector + kube-state-metrics, plus pod-log collection via `filelog`) - the recommended default for AKS because it captures pod, node, and container signals natively. Scout accepts telemetry from any path you choose; if you also want AKS control-plane signals via the Diagnostic Settings → Event Hubs route described in the [overview](./overview.md), wire it alongside this in-cluster setup. ::: ### Why Scout for AKS observability Microsoft recommends **Managed Prometheus + Container Insights + Managed Grafana** as the AKS observability stack ([learn.microsoft.com/azure/aks/monitor-aks](https://learn.microsoft.com/azure/aks/monitor-aks), updated 2026-01-20). It works, but it ties your telemetry to Azure: metrics land in a Log Analytics workspace, alerts route through Azure Monitor, and dashboards live in Managed Grafana. Multi-cloud, hybrid, or migrating customers prefer this guide because the same OpenTelemetry Collector ships to Scout, to a self-hosted Prometheus, or to any OTLP-compatible backend - switching backends is a values-file change, not a redeployment of agents. ### Choosing the right pattern Three viable patterns for wiring AKS metrics to Scout. They differ in coverage, identity model, and operator effort. | Pattern | Metric coverage | Auth model | Setup | |---|---|---|---| | **A. In-cluster + kube-state-metrics** (default) | ~286 metrics; rich pod / container / cluster-state | Workload Identity Federation | Helm install x 2 + KSM (Steps 1-5) | | **B. A + `azure_monitor` for control plane** | A + 18 control-plane metrics (apiserver, etcd, autoscaler) | WIF in-cluster + Service Principal standalone | Pattern A + Step 6 | | **C. `azure_monitor` only** | 18 metrics on a vanilla cluster; more if Container Insights / Managed Prometheus add-ons are enabled | Service Principal | Step 6 standalone | - **Pick A** if pod / container / cluster-state visibility is what you need. Steps 1-5 get you there; skip Step 6. - **Pick B** if API server SLO tracking, etcd usage trending, or cluster-autoscaler decisions matter operationally. Do Steps 1-5, then add Step 6. - **Pick C** only if you already have Container Insights or Managed Prometheus enabled (otherwise it's 18 metrics for the cost of a Service Principal). Skip Steps 1-5 and do Step 6 standalone. The rest of this guide walks Pattern A in Steps 1-5 and adds the Step 6 overlay for Patterns B and C. ### What you'll monitor Pattern A's two collectors emit ~286 distinct metric names against a working cluster; Step 6 adds 18 control-plane series on top. They share the same `cloud.region` / `k8s.cluster.name` / `cloud.account.id` resource attributes so you can group across them in Scout. | Receiver | Mode | What it covers | Example metrics | |---|---|---|---| | `kubeletstats` | DaemonSet (Pattern A) | Pod / container / node / volume usage from the kubelet | `k8s.pod.cpu.usage`, `k8s.node.memory.working_set`, `container.memory.rss`, `k8s.volume.available`, `k8s.pod.cpu_limit_utilization` | | `hostmetrics` | DaemonSet (Pattern A) | Node OS-level telemetry | `system.cpu.time`, `system.disk.io`, `system.network.errors`, `system.processes.count`, `system.uptime` | | `k8s_cluster` | Deployment, 1 replica (Pattern A) | K8s API objects | `k8s.deployment.available`, `k8s.daemonset.ready_nodes`, `k8s.pod.phase`, `k8s.cronjob.active_jobs`, `k8s.hpa.current_replicas`, `k8s.statefulset.ready_pods`, `k8s.persistentvolumeclaim.status.phase` | | `prometheus` (scrapes kube-state-metrics) | Deployment, 1 replica (Pattern A) | Detailed K8s state in Prometheus form | `kube_node_status_allocatable`, `kube_pod_container_resource_limits`, `kube_horizontalpodautoscaler_status_current_replicas`, `kube_job_status_succeeded` | | `azure_monitor` | Standalone (Patterns B and C, optional) | AKS resource control plane via Azure Monitor | `azure_apiserver_cpu_usage_percentage_average`, `azure_etcd_database_usage_percentage_maximum`, `azure_cluster_autoscaler_unschedulable_pods_count_total` | ### Prerequisites - An AKS cluster with **OIDC issuer** and **Workload Identity** enabled (`oidcIssuerProfile.enabled: true`, `securityProfile.workloadIdentity.enabled: true`). These are off by default; enable via Bicep / ARM / `az aks update`. - `kubectl` >= 1.30, `helm` >= 3.14. - A User-assigned Managed Identity (UAMI). The chart auto-creates one ServiceAccount per Helm release, so you'll federate two subjects: `system:serviceaccount:otel:otel-agent` and `system:serviceaccount:otel:otel-cluster`. - Scout OAuth2 client credentials (`SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, `SCOUT_TOKEN_URL`, `SCOUT_OTLP_ENDPOINT`). ### Collector image version This guide uses upstream Helm chart `opentelemetry-collector` v0.153.0 and pins the image to `otel/opentelemetry-collector-contrib:0.151.0` on every release. Contrib versions that change config behavior for the components used here: | Version | Change | Impact on this guide | |---|---|---| | **v0.124.0** (Apr 2025) | `azure_monitor` gains `use_batch_api` (12k → 360k Metrics API calls/hour ceiling). | Step 6 sets `use_batch_api: true`. Field does not exist on older images. | | **v0.129.0** (Jun 2025) | `azure_monitor` auth via the `azure_auth` extension (`auth.authenticator`) becomes canonical; inline `credentials:` block deprecated (extension pattern introduced v0.127.0). | Step 6 uses `auth: {authenticator: azure_auth}`. Pre-v0.127.0 images need an inline `credentials:` block on the receiver. | | **v0.144.0** (Jan 2026) | `otlphttp` → `otlp_http` exporter rename. | Deprecated alias kept; not a parse-time break either way. | | **v0.148.0** (Mar 2026) | Snake-case rename: `azuremonitor` → `azure_monitor` (receiver), `azureauth` → `azure_auth` (extension); `auth.authenticator` value follows. | **Parse-time pivot for Step 6.** v0.148.0+ accepts both forms (legacy logs a startup warning); pre-v0.148.0 rejects the snake-case form. Resource-attribute prefix `azuremonitor.*` (e.g. `azuremonitor.subscription_id`) is unchanged on both sides. | | **v0.150.0** (Apr 2026) | `kubeletstats` deprecated attrs off by default (`aws.volume.id`, `fs.type`, `gce.pd.name`, `glusterfs.*`, `partition`). `k8s_cluster` entity-event label keys prefixed `k8s..label.`. | Affects Step 3 and Step 4. Re-enable kubeletstats attrs under `metrics:` only if Scout dashboards depend on them. Update Scout queries keying on unprefixed pod / node labels. | ### Step 1: Federate the UAMI to both ServiceAccounts ```bash RG= CLUSTER= UAMI= ISSUER="$(az aks show -g "$RG" -n "$CLUSTER" --query oidcIssuerProfile.issuerURL -o tsv)" for SA in otel-agent otel-cluster; do az identity federated-credential create \ --name "fc-$SA" \ --identity-name "$UAMI" \ --resource-group "$RG" \ --issuer "$ISSUER" \ --subject "system:serviceaccount:otel:$SA" \ --audiences "api://AzureADTokenExchange" done ``` These shell variables (`$RG`, `$CLUSTER`, `$UAMI`) carry through the rest of this guide; keep your shell session open or re-export them in Step 4. ### Step 2: Create the namespace, Secret, and ConfigMap The collectors read Scout credentials from a Secret and cluster-context from a ConfigMap so the values files stay portable across clusters. ```bash kubectl create namespace otel kubectl create secret generic scout-oauth2 -n otel \ --from-literal=client_id="" \ --from-literal=client_secret="" SUB="$(az account show --query id -o tsv)" kubectl create configmap otel-azure-context -n otel \ --from-literal=subscription_id="$SUB" \ --from-literal=region="" \ --from-literal=cluster_name="" ``` ### Step 3: Helm-deploy the agent (DaemonSet) ```yaml title="helm/values-agent.yaml" mode: daemonset image: repository: otel/opentelemetry-collector-contrib tag: "0.151.0" pullPolicy: IfNotPresent serviceAccount: create: true name: otel-agent # Required pod label for the workload-identity webhook to inject the projected token. podLabels: azure.workload.identity/use: "true" presets: kubeletMetrics: enabled: true hostMetrics: enabled: true # *.node.utilization metrics need API-server-proxy access to /pods. clusterRole: rules: - apiGroups: [""] resources: ["nodes/proxy"] verbs: ["get"] # Metrics-emitting collector - disable inbound ports. ports: otlp: {enabled: false} otlp-http: {enabled: false} jaeger-compact: {enabled: false} jaeger-thrift: {enabled: false} jaeger-grpc: {enabled: false} zipkin: {enabled: false} metrics: {enabled: false} extraEnvs: - name: AZURE_SUBSCRIPTION_ID valueFrom: {configMapKeyRef: {name: otel-azure-context, key: subscription_id}} - name: AZURE_REGION valueFrom: {configMapKeyRef: {name: otel-azure-context, key: region}} - name: AKS_CLUSTER_NAME valueFrom: {configMapKeyRef: {name: otel-azure-context, key: cluster_name}} - name: ENVIRONMENT value: production - name: SCOUT_CLIENT_ID valueFrom: {secretKeyRef: {name: scout-oauth2, key: client_id}} - name: SCOUT_CLIENT_SECRET valueFrom: {secretKeyRef: {name: scout-oauth2, key: client_secret}} - name: SCOUT_TOKEN_URL value: https://id.b14.dev/realms//protocol/openid-connect/token - name: SCOUT_OTLP_ENDPOINT value: https://otel..base14.io//otlp config: receivers: otlp: null hostmetrics: collection_interval: 30s scrapers: # Azure Linux mounts /boot/efi root-only - exclude to silence the # otherwise per-scrape "permission denied" noise. filesystem: exclude_mount_points: match_type: regexp mount_points: - /dev/* - /proc/* - /sys/* - /run/k3s/containerd/* - /var/lib/docker/* - /var/lib/kubelet/* - /boot/efi - /boot processes: {} system: {} kubeletstats: collection_interval: 30s # K8S_NODE_NAME is auto-injected by the chart's kubeletMetrics preset # via the downward API. Do NOT add it to extraEnvs (duplicate keys # break the DaemonSet apply). node: ${env:K8S_NODE_NAME} # `volume` must be added explicitly to emit k8s.volume.* for PVCs. metric_groups: [container, pod, node, volume] metrics: # Enable every default-disabled kubeletstats metric. container.uptime: {enabled: true} k8s.container.cpu_limit_utilization: {enabled: true} k8s.container.cpu_request_utilization: {enabled: true} k8s.container.memory_limit_utilization: {enabled: true} k8s.container.memory_request_utilization: {enabled: true} k8s.node.uptime: {enabled: true} k8s.pod.cpu_limit_utilization: {enabled: true} k8s.pod.cpu_request_utilization: {enabled: true} k8s.pod.memory_limit_utilization: {enabled: true} k8s.pod.memory_request_utilization: {enabled: true} k8s.pod.uptime: {enabled: true} k8s.pod.volume.usage: {enabled: true} k8s.container.cpu.node.utilization: {enabled: true} k8s.container.memory.node.utilization: {enabled: true} k8s.pod.cpu.node.utilization: {enabled: true} k8s.pod.memory.node.utilization: {enabled: true} extensions: health_check: {} # chart-injected default; override with explicit endpoint if needed oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s processors: batch: {} # chart-injected default; override e.g. with timeout: 5s, send_batch_size: 1024 resource: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_aks, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} - {key: k8s.cluster.name, value: "${env:AKS_CLUSTER_NAME}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: deployment.environment, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: otel-agent, action: insert} exporters: debug: {verbosity: basic} otlp_http/b14: endpoint: ${env:SCOUT_OTLP_ENDPOINT} auth: {authenticator: oauth2client} compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [health_check, oauth2client] pipelines: metrics: receivers: [kubeletstats, hostmetrics] processors: [resource, batch] exporters: [debug, otlp_http/b14] traces: null logs: null resources: requests: {cpu: 100m, memory: 128Mi} limits: {memory: 512Mi} ``` Install: ```bash UAMI_CLIENT_ID="$(az identity show -g "$RG" -n "$UAMI" --query clientId -o tsv)" WI_ANNOT='serviceAccount.annotations.azure\.workload\.identity/client-id' helm repo add open-telemetry https://open-telemetry.github.io/opentelemetry-helm-charts helm repo update helm upgrade --install otel-agent open-telemetry/opentelemetry-collector \ --version 0.153.0 -n otel -f helm/values-agent.yaml \ --set "$WI_ANNOT=$UAMI_CLIENT_ID" --wait ``` ### Step 4: Helm-deploy the cluster collector (Deployment) The cluster collector scrapes the K8s API plus kube-state-metrics. The chart's deployment-mode auto-creates a `Service`; with all inbound ports disabled, K8s rejects the empty-ports Service. Disable it explicitly with `service: {enabled: false}`. The values file shares most blocks with `values-agent.yaml` from Step 3 (`extraEnvs`, `extensions.oauth2client`, `processors.resource`, `exporters.{debug,otlp_http/b14}`). Copy them across; only the receiver, pipeline, and a couple of structural differences are unique to this release: ```yaml title="helm/values-cluster.yaml" mode: deployment replicaCount: 1 image: repository: otel/opentelemetry-collector-contrib tag: "0.151.0" pullPolicy: IfNotPresent serviceAccount: create: true name: otel-cluster podLabels: azure.workload.identity/use: "true" presets: clusterMetrics: enabled: true # Required by the prometheus receiver scraping kube-state-metrics + the # additional k8s_cluster metrics enabled below. clusterRole: rules: - apiGroups: [""] resources: ["persistentvolumes", "persistentvolumeclaims"] verbs: ["get", "list", "watch"] - apiGroups: ["discovery.k8s.io"] resources: ["endpointslices"] verbs: ["get", "list", "watch"] ports: otlp: {enabled: false} otlp-http: {enabled: false} jaeger-compact: {enabled: false} jaeger-thrift: {enabled: false} jaeger-grpc: {enabled: false} zipkin: {enabled: false} metrics: {enabled: false} # In deployment mode the chart creates a Service even with all ports # disabled, which K8s rejects (empty spec.ports). Disable it. service: enabled: false extraEnvs: # ---- IDENTICAL to values-agent.yaml ---- - name: AZURE_SUBSCRIPTION_ID valueFrom: {configMapKeyRef: {name: otel-azure-context, key: subscription_id}} - name: AZURE_REGION valueFrom: {configMapKeyRef: {name: otel-azure-context, key: region}} - name: AKS_CLUSTER_NAME valueFrom: {configMapKeyRef: {name: otel-azure-context, key: cluster_name}} - name: ENVIRONMENT value: production - name: SCOUT_CLIENT_ID valueFrom: {secretKeyRef: {name: scout-oauth2, key: client_id}} - name: SCOUT_CLIENT_SECRET valueFrom: {secretKeyRef: {name: scout-oauth2, key: client_secret}} - name: SCOUT_TOKEN_URL value: https://id.b14.dev/realms//protocol/openid-connect/token - name: SCOUT_OTLP_ENDPOINT value: https://otel..base14.io//otlp config: receivers: otlp: null prometheus: config: scrape_configs: - job_name: kube-state-metrics scrape_interval: 30s static_configs: - targets: - kube-state-metrics.kube-state-metrics.svc.cluster.local:8080 k8s_cluster: collection_interval: 30s metrics: # Enable every default-disabled k8s_cluster metric. k8s.container.status.reason: {enabled: true} k8s.container.status.state: {enabled: true} k8s.node.condition: {enabled: true} k8s.persistentvolume.status.phase: {enabled: true} k8s.persistentvolume.storage.capacity: {enabled: true} k8s.persistentvolumeclaim.status.phase: {enabled: true} k8s.persistentvolumeclaim.storage.capacity: {enabled: true} k8s.persistentvolumeclaim.storage.request: {enabled: true} k8s.pod.status_reason: {enabled: true} k8s.service.endpoint.count: {enabled: true} k8s.service.load_balancer.ingress.count: {enabled: true} extensions: # ---- IDENTICAL to values-agent.yaml ---- health_check: {} # chart-injected default; override with explicit endpoint if needed oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s processors: # ---- IDENTICAL to values-agent.yaml - except service.name = otel-cluster ---- batch: {} # chart-injected default; override e.g. with timeout: 5s, send_batch_size: 1024 resource: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_aks, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} - {key: k8s.cluster.name, value: "${env:AKS_CLUSTER_NAME}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: deployment.environment, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: otel-cluster, action: insert} exporters: # ---- IDENTICAL to values-agent.yaml ---- debug: {verbosity: basic} otlp_http/b14: endpoint: ${env:SCOUT_OTLP_ENDPOINT} auth: {authenticator: oauth2client} compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [health_check, oauth2client] pipelines: metrics: receivers: [k8s_cluster, prometheus] processors: [resource, batch] exporters: [debug, otlp_http/b14] traces: null logs: null resources: requests: {cpu: 50m, memory: 128Mi} limits: {memory: 512Mi} ``` Install: ```bash helm upgrade --install otel-cluster open-telemetry/opentelemetry-collector \ --version 0.153.0 -n otel -f helm/values-cluster.yaml \ --set "$WI_ANNOT=$UAMI_CLIENT_ID" --wait ``` ### Step 5: Install kube-state-metrics The cluster collector's `prometheus` receiver above scrapes kube-state-metrics for `kube_*` metrics that `k8s_cluster` doesn't cover. Install it once: ```bash helm repo add prometheus-community https://prometheus-community.github.io/helm-charts helm repo update helm install kube-state-metrics prometheus-community/kube-state-metrics \ --namespace kube-state-metrics --create-namespace --wait ``` ### Step 6 (optional): Add control-plane metrics with `azure_monitor` This is Pattern B from "Choosing the right pattern" (or Pattern C if you skipped Steps 1-5). Skip if control-plane visibility - API server uptime, etcd usage, autoscaler decisions - isn't a priority for your workload. #### What you'll get Nine ARM-level metrics published by Azure Monitor for the AKS resource, each emitted at two aggregations (18 distinct series total): | Metric | What it tells you | |---|---| | `apiserver_cpu_usage_percentage` (avg / max) | API server load - spikes correlate with kubectl traffic / controller storms. | | `apiserver_memory_usage_percentage` (avg / max) | API server memory pressure. | | `etcd_cpu_usage_percentage` (avg / max) | etcd CPU - affects write latency. | | `etcd_database_usage_percentage` (avg / max) | etcd storage usage - nearing 100% means writes will start failing. | | `etcd_memory_usage_percentage` (avg / max) | etcd memory pressure. | | `cluster_autoscaler_cluster_safe_to_autoscale` (total / avg) | Whether the autoscaler is allowed to act. | | `cluster_autoscaler_scale_down_in_cooldown` (total / avg) | Why scale-down isn't happening. | | `cluster_autoscaler_unneeded_nodes_count` (total / avg) | Nodes the autoscaler wants to remove. | | `cluster_autoscaler_unschedulable_pods_count` (total / avg) | Pods waiting because the autoscaler can't fit them. | #### What requires Container Insights or Managed Prometheus Azure Monitor registers more metric definitions for the AKS resource type (`kube_*`, `node_disk_usage_*`, `node_network_*`) but they only have data when the **Container Insights** or **Managed Prometheus** add-ons are enabled on the cluster. Without those, the `metrics:getBatch` call returns 401 (not "no data") for those names - Azure's API surfaces "RBAC not enabled for this metric source" as an authorization failure. Enabling Container Insights or Managed Prometheus is a customer choice that gives you more control-plane data but reintroduces the Azure-Monitor ingestion costs and lock-in this guide is positioned against. The canonical recommendation is Pattern A (in-cluster collectors + KSM) for the rich data and Step 6 for control plane only when explicitly needed. #### Cluster autoscaling required for autoscaler metrics The four `cluster_autoscaler_*` metrics have two distinct behaviors depending on your node pool configuration: - If cluster autoscaling is not enabled on any node pool, the four metrics return 401 (no backing data source). Remove them from the receiver's metric whitelist in that case. - If cluster autoscaling is enabled but the pool is pinned (e.g. `minCount = maxCount = 1`), the metrics emit with zero/idle values; that is expected and indicates the autoscaler is healthy but inactive. Enable autoscaling with `enableAutoScaling: true, minCount: N, maxCount: M` in Bicep, or `--enable-cluster-autoscaler` via CLI. #### Service Principal + Monitoring Reader The standalone collector authenticates to Azure via a Service Principal. Workload Identity Federation requires running in-Azure with an attached Managed Identity; a standalone collector on a Mac, in a Container Apps job, or in a Container Instance uses SP credentials. ```bash # (Pattern C readers who skipped Steps 1-5 should set $RG to their cluster's # resource group now; Pattern B readers already have it from Step 1.) SP_NAME=otel-aks-control-plane SP_JSON="$(az ad sp create-for-rbac --name "$SP_NAME" --skip-assignment)" APP_ID="$(echo "$SP_JSON" | jq -r .appId)" PASSWORD="$(echo "$SP_JSON" | jq -r .password)" TENANT="$(echo "$SP_JSON" | jq -r .tenant)" # Store as AZURE_CLIENT_ID, AZURE_CLIENT_SECRET, AZURE_TENANT_ID # respectively (see the env-file block below). SP_OBJECT_ID="$(az ad sp show --id "$APP_ID" --query id -o tsv)" SUB="$(az account show --query id -o tsv)" az role assignment create \ --assignee-object-id "$SP_OBJECT_ID" \ --assignee-principal-type ServicePrincipal \ --role "Monitoring Reader" \ --scope "/subscriptions/$SUB/resourceGroups/$RG" ``` `Monitoring Reader` propagates immediately on the legacy ARM `/metrics` endpoint. The newer `metrics:getBatch` data-plane endpoint can lag 5-30 minutes after the grant. Step 6 pins `use_batch_api: true` for the higher rate-limit ceiling (12k → 360k calls/hour) and batched fan-out across resources; flip to `false` only as a temporary fallback if the data plane is still 401-ing after propagation should have completed (see Troubleshooting). #### Standalone collector config ```yaml title="config/otel-collector-control-plane.yaml" extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: {audience: b14collector} timeout: 10s # Liveness probe - useful when running this collector as a Container Apps # job, in Container Instances, or behind a load balancer. health_check: endpoint: 0.0.0.0:13133 receivers: azure_monitor: subscription_ids: ["${env:AZURE_SUBSCRIPTION_ID}"] resource_groups: ["${env:AZURE_RESOURCE_GROUP}"] services: ["Microsoft.ContainerService/managedClusters"] auth: {authenticator: azure_auth} collection_interval: 60s # Metrics Data Plane (metrics:getBatch). Raises ceiling 12k -> 360k # calls/hour and batches up to 50 resources per call. RBAC propagates # 5-30 min after the Monitoring Reader grant; flip to false as a # temporary fallback to the legacy ARM /metrics endpoint if needed. use_batch_api: true cache_resources: 60 dimensions: {enabled: true} # Whitelist explicit metrics. Discovery-mode iterates EVERY metric # definition the resource type registers and 401s on those whose # data sources aren't enabled (kube_*, node_disk_usage_*). metrics: "Microsoft.ContainerService/managedClusters": apiserver_cpu_usage_percentage: [] apiserver_memory_usage_percentage: [] etcd_cpu_usage_percentage: [] etcd_database_usage_percentage: [] etcd_memory_usage_percentage: [] # Remove these four if cluster autoscaling is not enabled on any node pool. # If autoscaling IS enabled but the pool is pinned (minCount = maxCount), # the metrics emit with zero/idle values - that is expected behavior. cluster_autoscaler_cluster_safe_to_autoscale: [] cluster_autoscaler_scale_down_in_cooldown: [] cluster_autoscaler_unneeded_nodes_count: [] cluster_autoscaler_unschedulable_pods_count: [] processors: resource: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_aks, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:AKS_RESOURCE_ID}", action: insert} - {key: k8s.cluster.name, value: "${env:AKS_CLUSTER_NAME}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: deployment.environment, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: aks-control-plane, action: insert} batch: {timeout: 5s, send_batch_size: 1024} memory_limiter: {check_interval: 5s, limit_percentage: 80, spike_limit_percentage: 25} exporters: debug: {verbosity: basic} otlp_http/b14: endpoint: ${env:SCOUT_OTLP_ENDPOINT} auth: {authenticator: oauth2client} compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [health_check, azure_auth, oauth2client] pipelines: metrics: receivers: [azure_monitor] processors: [memory_limiter, resource, batch] exporters: [debug, otlp_http/b14] # Self-telemetry - exposes /metrics on :8888 inside the container so the # Verify section's curl-for-otelcol_exporter_sent_metric_points_total # check works for this standalone collector too. telemetry: logs: {level: info} metrics: readers: - pull: exporter: prometheus: host: 0.0.0.0 port: 8888 ``` Run it as a docker container (locally for validation, in Azure Container Instances or as a Container Apps job for production). Three env files keep the values out of the docker run command line: ```bash # Service Principal credentials (from `az ad sp create-for-rbac` above) cat > azure-sp.env </resourceGroups//providers/Microsoft.ContainerService/managedClusters/ AKS_RESOURCE_ID="$(az aks show -g "$RG" -n "$CLUSTER" --query id -o tsv)" cat > aks-context.env < 1/min for 5 min | rate > 5/min for 5 min | Container is crashlooping or being OOM-killed. | | Node memory utilization | `k8s.node.memory.working_set / k8s.node.memory.usage` (kubeletstats) | > 80% for 10 min | > 90% for 5 min | Node pressure, eviction risk. | | Pod CPU throttled | `k8s.pod.cpu_limit_utilization` (kubeletstats) | > 0.8 for 10 min | > 0.95 for 5 min | Workload exceeding its CPU limit; latency suffers. | | HPA stuck at max | `k8s.hpa.current_replicas / k8s.hpa.max_replicas` (k8s_cluster) | >= 1.0 for 15 min | (alert at warning) | Workload demand exceeds the autoscaler ceiling. | | Volume usage | `k8s.volume.available / k8s.volume.capacity` (kubeletstats) | > 80% | > 90% | PVC nearing capacity; risk of write failures. | | PVC pending | `k8s.persistentvolumeclaim.status.phase == Pending` for 10 min | true | (alert at warning) | Storage class / provisioner issue. | | Daemonset misscheduled | `k8s.daemonset.misscheduled_nodes` (k8s_cluster) | > 0 | > 0 for 30 min | Node-selector / taint mismatch. | | Job failures | `kube_job_status_failed` (kube-state-metrics) | > 0 in 1 hour | > 5 in 1 hour | Scheduled work failing repeatedly. | | Container restart by reason | `k8s.container.status.reason` (k8s_cluster) | OOMKilled count > 0 in 10 min | OOMKilled count > 3 in 5 min | OOM kills indicate undersized memory limits. | | API server CPU (Step 6) | `azure_apiserver_cpu_usage_percentage_average` | > 60% for 10 min | > 80% for 5 min | Control plane stressed; possibly oversized cluster. | | etcd database usage (Step 6) | `azure_etcd_database_usage_percentage_average` | > 60% | > 80% | etcd nearing storage limit; affects writes. | | Autoscaler unschedulable pods (Step 6) | `azure_cluster_autoscaler_unschedulable_pods_count_total` | > 0 for 10 min | > 5 for 5 min | Autoscaler can't schedule due to taints, quotas, or VM SKU availability. | ### Troubleshooting #### `service.telemetry.resource` legacy format warning at startup Upstream chart `0.153.0` emits the chart's auto-generated `service.telemetry.resource` in the legacy inline-map format. The collector logs a one-shot deprecation warning at startup; functionality is unaffected. Overriding `service.telemetry.resource.attributes` from your values causes the collector to error out (chart-injected keys still merge in). Carry the warning until the chart upgrades. #### `failed to read usage at /hostfs/boot/efi: permission denied` Per-scrape (every 30s) error. Azure Linux mounts the EFI System Partition at `/boot/efi` root-only, the unprivileged hostmetrics collector can't `df` it. Add `/boot/efi` and `/boot` to `hostmetrics.scrapers.filesystem.exclude_mount_points.mount_points`. The override replaces the chart preset's defaults, so include the chart's defaults too. #### `Service ... is invalid: spec.ports: Required value` on `helm install` Hits the cluster-mode (Deployment) release. With all inbound ports disabled the chart still tries to create a `Service` with zero ports, which K8s rejects. Set `service: {enabled: false}` in the cluster values. #### `k8s.volume.*` not emitting despite a pod with PVC `kubeletstats` defaults `metric_groups` to `[container, pod, node]`. The `volume` group must be added explicitly (`metric_groups: [container, pod, node, volume]`). #### Pods stuck in `CreateContainerConfigError` Almost always: the `scout-oauth2` Secret is missing or has wrong keys. The chart values reference `secretKeyRef: {name: scout-oauth2, key: client_id|client_secret}` and won't start the container until both exist. Recreate it (Step 2) and the pods will progress to `Running`. #### Step 6 returns 401 `AuthorizationFailed` on `metrics:getBatch` Azure Monitor's data-plane API at `*.metrics.monitor.azure.com` requires separate RBAC propagation (5-30 min after the `Monitoring Reader` grant) on top of the legacy ARM `/metrics` endpoint. Wait for propagation; the receiver retries automatically. If you need metrics flowing immediately, flip `use_batch_api` to `false` to fall back to the legacy ARM endpoint (RBAC there is immediate), then return to `true` once the data plane has settled - the batch API is the only setting that survives a real fleet's call volume. #### Step 6 returns 401 for `kube_*` / `node_disk_usage_*` metrics Those metric definitions exist in Azure Monitor for the AKS resource type but have no backing data source unless the **Container Insights** or **Managed Prometheus** add-on is enabled on the cluster. Without those, AzMon returns 401 (not "no data" - the API doesn't distinguish). The metric whitelist in the receiver config filters to ARM-only metrics that work everywhere. Extend the whitelist with names from your Azure Portal → Metrics blade if you've enabled the add-ons. ### Frequently Asked Questions #### How do I monitor an Azure Kubernetes Service cluster with OpenTelemetry? Deploy the upstream OpenTelemetry Collector Helm chart twice in your AKS cluster - once as a DaemonSet (kubeletstats + hostmetrics) for per-node metrics, once as a Deployment (k8s_cluster + prometheus scraping kube-state-metrics) for cluster-state and additional `kube_*` metrics. Both ship OTLP/HTTP to base14 Scout authenticated via OAuth2 client credentials. ServiceAccounts authenticate to Azure via Workload Identity Federation. #### How does the in-cluster collector authenticate to base14 Scout? Via the OpenTelemetry Collector `oauth2client` extension. Store the Scout-issued `client_id` and `client_secret` in a Kubernetes Secret, reference them in the chart values via `secretKeyRef`, and the `otlp_http/b14` exporter automatically fetches short-lived bearer tokens from your Scout token URL, cached until expiry. #### Why do I need two Helm releases instead of one? The `kubeletstats` receiver runs per-node (DaemonSet mode) so each kubelet is scraped from its own pod. The `k8s_cluster` receiver pulls cluster-wide state from the K8s API once and would emit duplicates if scaled horizontally - it runs as a single-replica Deployment. Splitting into two releases gives each receiver the right Pod controller without compromise. #### How is this different from Microsoft's Managed Prometheus and Container Insights? Managed Prometheus and Container Insights are Azure-tenant-bound, billed per-GB ingested, and visualized in Managed Grafana / Log Analytics. The OpenTelemetry Collector is vendor-neutral - the same image ships to base14 Scout or any OTLP-compatible backend without redeployment. Customers running multi-cloud or migrating off Azure-native observability prefer this. #### What is kube-state-metrics and why is it part of this guide? kube-state-metrics exposes detailed Kubernetes object state (HPA replicas, Job completions, PVC capacity, node allocatable resources) in Prometheus-format. The `k8s_cluster` OTel receiver covers some of this, but kube-state-metrics has wider coverage. The cluster-mode collector includes a `prometheus` receiver that scrapes kube-state-metrics so both metric families flow to Scout in one pipeline. #### How do I add control-plane metrics like API-server uptime? Follow Step 6 above. It deploys a standalone OpenTelemetry Collector with the `azure_monitor` receiver against the AKS resource, authenticated via Service Principal. You get 18 control-plane series (9 metrics emitted at two aggregations each - apiserver, etcd, autoscaler) on a vanilla cluster, or more if Container Insights / Managed Prometheus are enabled. Most workloads don't need this - the in-cluster pattern in Steps 1-5 covers pod / container / cluster-state visibility, which is where most operational signals live. ### Related Guides - [Azure Kubernetes Service (Operator)](aks.md) - the canonical pattern using the OpenTelemetry Operator and CRDs. - [Kubernetes (Scout Helm chart)][scout-helm] - alternative deployment pattern using Scout's own Helm chart instead of the upstream OpenTelemetry chart this guide uses. Useful for non-AKS Kubernetes platforms or operators who prefer a single Scout-curated chart over the upstream + values-file approach. - [CloudWatch Metrics Stream](../aws/cloudwatch-metrics/cloudwatch-metrics-stream.md) is the AWS infrastructure-metrics guide. Different pattern from this one (CloudWatch → Kinesis Firehose → Scout, push-stream forwarder; this guide is pull-based collectors). - [OpenTelemetry Collector Helm chart][otel-helm] - upstream chart documentation. - [kube-state-metrics Helm chart][ksm-helm] - exporter source and configuration. [scout-helm]: ../../collector-setup/kubernetes-helm-setup.md [otel-helm]: https://github.com/open-telemetry/opentelemetry-helm-charts/tree/main/charts/opentelemetry-collector [ksm-helm]: https://github.com/prometheus-community/helm-charts/tree/main/charts/kube-state-metrics --- ## Azure Kubernetes Service Monitoring with OpenTelemetry Operator This guide deploys the OpenTelemetry Operator on AKS, then uses `OpenTelemetryCollector` CRs to manage three collectors in-cluster plus an `Instrumentation` CR for zero-code app auto-instrumentation. :::tip Architecture overview This guide is the **execution playbook** for AKS. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide covers the **in-cluster pattern** (OTel agent DaemonSet + cluster collector + kube-state-metrics, plus pod-log collection via `filelog`) - the recommended default for AKS because it captures pod, node, and container signals natively without round-tripping through Azure Monitor. Scout accepts telemetry from any path you choose; if you also want AKS control-plane signals via the Diagnostic Settings → Event Hubs route described in the [overview](./overview.md), wire it alongside this in-cluster setup. ::: ### Why Scout for AKS observability Microsoft recommends Managed Prometheus, Container Insights, and Managed Grafana as the AKS observability stack ([learn.microsoft.com/azure/aks/monitor-aks](https://learn.microsoft.com/azure/aks/monitor-aks), updated 2026-01-20). That stack works, but it ties your telemetry to Azure: metrics land in a Log Analytics workspace, alerts route through Azure Monitor, and dashboards live in Managed Grafana. Teams running multi-cloud environments or planning to migrate off Azure-native observability prefer the OpenTelemetry Collector because the same image and configuration ships to Scout, to a self-hosted Prometheus, or to any OTLP-compatible backend without redeploying agents. Switching backends is a config change, not an agent swap. ### Why the OpenTelemetry Operator Three reasons to use the operator over raw Helm releases. **Declarative lifecycle.** The operator introduces `OpenTelemetryCollector` and `Instrumentation` CRDs. Applying a CR is all it takes to deploy, update, or remove a collector. The operator handles ServiceAccount creation, RBAC scoping per receiver, Service creation, and rolling updates. No per-release Helm value files to maintain. **Zero-code application auto-instrumentation across four languages.** The `Instrumentation` CR pre-configures SDK init containers for Python, Node.js, Java, and Go (eBPF). Your application pods opt in with one annotation. No SDK imports, no source changes. **Single upgrade surface.** One Helm chart version pins the operator release. The operator then reconciles all CRs to the collector image version you specify in `spec.image`. Upgrading the contrib image version across three collectors is one field change per CR. Prefer raw Helm releases? See the [Azure Kubernetes Service (Helm)](aks-with-helm.md) guide. ### What you'll monitor | Receiver | Mode | What it covers | Example metrics | |---|---|---|---| | `kubeletstats` | DaemonSet | Pod, container, node, and volume usage from the kubelet | `k8s.pod.cpu.usage`, `k8s.node.memory.working_set`, `container.memory.rss`, `k8s.volume.available`, `k8s.pod.cpu_limit_utilization` | | `hostmetrics` | DaemonSet | Node OS-level telemetry | `system.cpu.time`, `system.disk.io`, `system.network.errors`, `system.processes.count`, `system.uptime` | | `k8s_cluster` | Deployment, 1 replica | K8s API object state | `k8s.deployment.available`, `k8s.daemonset.ready_nodes`, `k8s.pod.phase`, `k8s.hpa.current_replicas`, `k8s.persistentvolumeclaim.status.phase` | | `prometheus` scraping kube-state-metrics | Deployment, 1 replica | Detailed K8s state in Prometheus format | `kube_node_status_allocatable`, `kube_pod_container_resource_limits`, `kube_horizontalpodautoscaler_status_current_replicas`, `kube_job_status_succeeded` | | `azure_monitor` | Deployment, 1 replica | AKS control-plane via Azure Monitor | `azure_apiserver_cpu_usage_percentage_average`, `azure_etcd_database_usage_percentage_maximum`, `azure_cluster_autoscaler_unschedulable_pods_count_total` | | `Instrumentation` CR | Init container (per pod) | Application traces, metrics, and logs from Python, Node.js, Java, and Go pods | HTTP request spans, duration histograms, error counts | ### Prerequisites - An AKS cluster with **OIDC issuer** and **Workload Identity** enabled (`oidcIssuerProfile.enabled: true`, `securityProfile.workloadIdentity.enabled: true`). These are off by default; enable via Bicep or `az aks update`. - `kubectl` >= 1.30, `helm` >= 3.14. - **cert-manager** installed in the cluster (the operator's webhook requires TLS certificates issued by cert-manager). Step 1 covers this. - Scout OAuth2 client credentials: `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, `SCOUT_TOKEN_URL`, `SCOUT_OTLP_ENDPOINT`. - A Service Principal with `Monitoring Reader` on the resource group (required only for the optional control-plane Step 7 - the operator-managed `azure_monitor` collector). Create one with: ```bash SP_JSON="$(az ad sp create-for-rbac --name otel-aks-control-plane --skip-assignment)" APP_ID="$(echo "$SP_JSON" | jq -r .appId)" PASSWORD="$(echo "$SP_JSON" | jq -r .password)" TENANT="$(echo "$SP_JSON" | jq -r .tenant)" SP_OBJECT_ID="$(az ad sp show --id "$APP_ID" --query id -o tsv)" RG= SUB="$(az account show --query id -o tsv)" az role assignment create --assignee-object-id "$SP_OBJECT_ID" \ --assignee-principal-type ServicePrincipal --role "Monitoring Reader" \ --scope "/subscriptions/$SUB/resourceGroups/$RG" ``` Capture `APP_ID`, `PASSWORD`, `TENANT` for Step 3's `azure-sp` Secret. The operator's v1beta1 CRD removed `spec.podLabels`, which means the Workload Identity webhook cannot inject the projected token into operator-managed pods. Service Principal env-var auth via a Kubernetes Secret is the workaround for any collector that needs Azure API access. ### Collector image version This guide pins `otel/opentelemetry-collector-contrib:0.152.1` on every `OpenTelemetryCollector` CR. Contrib versions that change config behavior for the components used here: | Version | Change | Impact on this guide | |---|---|---| | **v0.124.0** (Apr 2025) | `azure_monitor` gains `use_batch_api` (12k → 360k Metrics API calls/hour ceiling). | Step 7 sets `use_batch_api: true`. Field does not exist on older images. | | **v0.129.0** (Jun 2025) | `azure_monitor` auth via the `azure_auth` extension (`auth.authenticator`) becomes canonical; inline `credentials:` block deprecated (extension pattern introduced v0.127.0). | Step 7 uses `auth: {authenticator: azure_auth}`. Pre-v0.127.0 images need an inline `credentials:` block on the receiver. | | **v0.144.0** (Jan 2026) | `otlphttp` → `otlp_http` exporter rename. | Deprecated alias kept; not a parse-time break either way. | | **v0.148.0** (Mar 2026) | Snake-case rename: `azuremonitor` → `azure_monitor` (receiver), `azureauth` → `azure_auth` (extension); `auth.authenticator` value follows. | **Parse-time pivot for Step 7.** v0.148.0+ accepts both forms (legacy logs a startup warning); pre-v0.148.0 rejects the snake-case form. Resource-attribute prefix `azuremonitor.*` (e.g. `azuremonitor.subscription_id`) is unchanged on both sides. | | **v0.150.0** (Apr 2026) | `kubeletstats` deprecated attrs off by default (`aws.volume.id`, `fs.type`, `gce.pd.name`, `glusterfs.*`, `partition`). `k8s_cluster` entity-event label keys prefixed `k8s..label.`. | Affects Step 4 and Step 6. Re-enable kubeletstats attrs under `metrics:` only if Scout dashboards depend on them. Update Scout queries keying on unprefixed pod / node labels. | ### Step 1: Install cert-manager The operator's admission webhook requires TLS certificates. cert-manager issues and rotates them automatically. ```bash CERT_MANAGER_VERSION="v1.20.2" kubectl apply -f "https://github.com/cert-manager/cert-manager/releases/download/$CERT_MANAGER_VERSION/cert-manager.yaml" kubectl wait --for=condition=Available deployment/cert-manager -n cert-manager --timeout=300s kubectl wait --for=condition=Available deployment/cert-manager-webhook -n cert-manager --timeout=300s kubectl wait --for=condition=Available deployment/cert-manager-cainjector -n cert-manager --timeout=300s ``` ### Step 2: Install the OpenTelemetry Operator Chart `0.111.0` ships operator `v0.149.0`. The `manager.collectorImage` flags pin the default contrib image so every CR you create without an explicit `spec.image` starts at `0.152.1`. ```bash helm repo add open-telemetry https://open-telemetry.github.io/opentelemetry-helm-charts helm repo update open-telemetry helm upgrade --install opentelemetry-operator open-telemetry/opentelemetry-operator \ --version 0.111.0 \ --namespace opentelemetry-operator-system \ --create-namespace \ --set "manager.collectorImage.repository=otel/opentelemetry-collector-contrib" \ --set "manager.collectorImage.tag=0.152.1" \ --wait --timeout 5m kubectl wait --for=condition=Available \ deployment/opentelemetry-operator \ -n opentelemetry-operator-system --timeout=300s ``` ### Step 3: Create namespace, Secrets, and ConfigMap The `otel` namespace needs `pod-security.kubernetes.io/enforce: privileged` because the Go eBPF sample app runs a privileged sidecar. All collectors and sample apps land in this namespace. ```bash kubectl create namespace otel kubectl label namespace otel \ pod-security.kubernetes.io/enforce=privileged \ pod-security.kubernetes.io/warn=privileged \ pod-security.kubernetes.io/audit=privileged # Scout OAuth2 client credentials. kubectl create secret generic scout-oauth2 -n otel \ --from-literal=SCOUT_CLIENT_ID="" \ --from-literal=SCOUT_CLIENT_SECRET="" \ --from-literal=SCOUT_TOKEN_URL="https://id.b14.dev/realms//protocol/openid-connect/token" \ --from-literal=SCOUT_OTLP_ENDPOINT="https://otel..base14.io//otlp" # Cluster context injected into all three collectors. SUB="$(az account show --query id -o tsv)" RG= CLUSTER= REGION="$(az aks show -g "$RG" -n "$CLUSTER" --query location -o tsv)" AKS_ID="$(az aks show -g "$RG" -n "$CLUSTER" --query id -o tsv)" kubectl create configmap otel-azure-context -n otel \ --from-literal=AZURE_SUBSCRIPTION_ID="$SUB" \ --from-literal=AZURE_RESOURCE_GROUP="$RG" \ --from-literal=AZURE_REGION="$REGION" \ --from-literal=AKS_CLUSTER_NAME="$CLUSTER" \ --from-literal=AKS_RESOURCE_ID="$AKS_ID" # Service Principal credentials for Step 7 (control-plane azure_monitor). # Use the APP_ID, PASSWORD, and TENANT captured from the SP creation in Prerequisites. kubectl create secret generic azure-sp -n otel \ --from-literal=AZURE_TENANT_ID="" \ --from-literal=AZURE_CLIENT_ID="" \ --from-literal=AZURE_CLIENT_SECRET="" ``` ### Step 4: Apply the agent OpenTelemetryCollector CR (DaemonSet) The agent collector runs one pod per node. It scrapes `kubeletstats` and `hostmetrics` from the local node, and also accepts OTLP inbound from auto-instrumented sample apps on the same node. Traces, metrics, and logs from those apps all route through this collector to Scout. ```yaml apiVersion: opentelemetry.io/v1beta1 kind: OpenTelemetryCollector metadata: name: otel-agent namespace: otel spec: mode: daemonset image: otel/opentelemetry-collector-contrib:0.152.1 resources: requests: cpu: 100m memory: 128Mi limits: memory: 512Mi envFrom: - secretRef: name: scout-oauth2 - configMapRef: name: otel-azure-context env: - name: K8S_NODE_NAME valueFrom: fieldRef: fieldPath: spec.nodeName - name: ENVIRONMENT value: demo config: receivers: hostmetrics: collection_interval: 10s # 10s suits per-node DaemonSet scale; bump to 30s on large clusters to reduce volume. scrapers: cpu: {} load: {} memory: {} disk: {} network: {} paging: {} processes: {} system: {} filesystem: exclude_mount_points: match_type: regexp mount_points: - /dev/* - /proc/* - /sys/* - /run/k3s/containerd/* - /var/lib/docker/* - /var/lib/kubelet/* - /boot/efi - /boot kubeletstats: collection_interval: 10s # 10s suits per-node DaemonSet scale; bump to 30s on large clusters to reduce volume. node: ${env:K8S_NODE_NAME} auth_type: serviceAccount endpoint: https://${env:K8S_NODE_NAME}:10250 insecure_skip_verify: true metric_groups: [container, pod, node, volume] metrics: container.uptime: {enabled: true} k8s.container.cpu_limit_utilization: {enabled: true} k8s.container.cpu_request_utilization: {enabled: true} k8s.container.memory_limit_utilization: {enabled: true} k8s.container.memory_request_utilization: {enabled: true} k8s.node.uptime: {enabled: true} k8s.pod.cpu_limit_utilization: {enabled: true} k8s.pod.cpu_request_utilization: {enabled: true} k8s.pod.memory_limit_utilization: {enabled: true} k8s.pod.memory_request_utilization: {enabled: true} k8s.pod.uptime: {enabled: true} k8s.pod.volume.usage: {enabled: true} k8s.container.cpu.node.utilization: {enabled: true} k8s.container.memory.node.utilization: {enabled: true} k8s.pod.cpu.node.utilization: {enabled: true} k8s.pod.memory.node.utilization: {enabled: true} otlp: protocols: http: endpoint: 0.0.0.0:4318 extensions: health_check: endpoint: 0.0.0.0:13133 oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s processors: batch: timeout: 5s send_batch_size: 1024 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 25 resource: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_aks, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} - {key: k8s.cluster.name, value: "${env:AKS_CLUSTER_NAME}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: deployment.environment, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: otel-agent, action: insert} exporters: debug: verbosity: basic otlp_http/b14: endpoint: ${env:SCOUT_OTLP_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [health_check, oauth2client] pipelines: traces: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [debug, otlp_http/b14] metrics: receivers: [otlp, kubeletstats, hostmetrics] processors: [memory_limiter, resource, batch] exporters: [debug, otlp_http/b14] logs: receivers: [otlp] processors: [memory_limiter, resource, batch] exporters: [debug, otlp_http/b14] ``` Apply it: ```bash kubectl apply -f manifests/03-collector-agent.yaml ``` The operator auto-creates the ServiceAccount `otel-agent-collector` and its ClusterRole, but on AKS the operator's ClusterRole does NOT include `nodes/stats` or `nodes/proxy` access, which AKS's kubelet authn webhook requires. Apply this supplemental RBAC before the first scrape: ```yaml apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRole metadata: name: otel-kubeletstats rules: - apiGroups: [""] resources: ["nodes/stats", "nodes/proxy"] verbs: ["get"] --- apiVersion: rbac.authorization.k8s.io/v1 kind: ClusterRoleBinding metadata: name: otel-agent-kubeletstats subjects: - kind: ServiceAccount name: otel-agent-collector namespace: otel roleRef: kind: ClusterRole name: otel-kubeletstats apiGroup: rbac.authorization.k8s.io ``` ```bash kubectl apply -f manifests/rbac-kubeletstats.yaml ``` ### Step 5: Install kube-state-metrics The cluster collector's `prometheus` receiver (Step 6) scrapes kube-state-metrics for `kube_*` metrics that `k8s_cluster` doesn't cover. Install it once per cluster before applying the cluster CR. ```bash helm repo add prometheus-community https://prometheus-community.github.io/helm-charts helm repo update prometheus-community helm upgrade --install kube-state-metrics prometheus-community/kube-state-metrics \ --namespace kube-state-metrics --create-namespace --wait --timeout 5m ``` ### Step 6: Apply the cluster OpenTelemetryCollector CR (Deployment) The cluster collector runs as a single-replica Deployment. It pulls cluster-wide state via `k8s_cluster` and scrapes kube-state-metrics via a `prometheus` receiver. kube-state-metrics must be installed first (Step 5). ```yaml apiVersion: opentelemetry.io/v1beta1 kind: OpenTelemetryCollector metadata: name: otel-cluster namespace: otel spec: mode: deployment replicas: 1 image: otel/opentelemetry-collector-contrib:0.152.1 resources: requests: cpu: 50m memory: 128Mi limits: memory: 512Mi envFrom: - secretRef: name: scout-oauth2 - configMapRef: name: otel-azure-context env: - name: ENVIRONMENT value: demo config: receivers: k8s_cluster: auth_type: serviceAccount collection_interval: 10s node_conditions_to_report: - Ready - MemoryPressure - DiskPressure - PIDPressure - NetworkUnavailable metrics: k8s.container.status.reason: {enabled: true} k8s.container.status.state: {enabled: true} k8s.node.condition: {enabled: true} k8s.persistentvolume.status.phase: {enabled: true} k8s.persistentvolume.storage.capacity: {enabled: true} k8s.persistentvolumeclaim.status.phase: {enabled: true} k8s.persistentvolumeclaim.storage.capacity: {enabled: true} k8s.persistentvolumeclaim.storage.request: {enabled: true} k8s.pod.status_reason: {enabled: true} k8s.service.endpoint.count: {enabled: true} k8s.service.load_balancer.ingress.count: {enabled: true} prometheus: config: scrape_configs: - job_name: kube-state-metrics scrape_interval: 30s static_configs: - targets: - kube-state-metrics.kube-state-metrics.svc.cluster.local:8080 extensions: health_check: endpoint: 0.0.0.0:13133 oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s processors: batch: timeout: 5s send_batch_size: 1024 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 25 resource: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_aks, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} - {key: k8s.cluster.name, value: "${env:AKS_CLUSTER_NAME}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: deployment.environment, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: otel-cluster, action: insert} exporters: debug: verbosity: basic otlp_http/b14: endpoint: ${env:SCOUT_OTLP_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [health_check, oauth2client] pipelines: metrics: receivers: [k8s_cluster, prometheus] processors: [memory_limiter, resource, batch] exporters: [debug, otlp_http/b14] ``` ```bash kubectl apply -f manifests/04-collector-cluster.yaml ``` ### Step 7: Apply the control-plane OpenTelemetryCollector CR (Deployment) This collector runs the `azure_monitor` receiver against the AKS resource and emits 18 control-plane series (9 metrics at two aggregations each: apiserver, etcd, autoscaler). It is optional. Skip it if control-plane visibility is not a priority. **Why Service Principal auth instead of Workload Identity Federation:** the operator's v1beta1 CRD removed `spec.podLabels`. The Workload Identity webhook injects the projected token only when the pod carries the label `azure.workload.identity/use: "true"`. Without a CRD field to set it, the webhook never fires and WIF cannot be used. The control-plane collector falls back to Service Principal env-var auth via the `azure-sp` Secret created in Step 3. **Why `use_batch_api: true`:** the `metrics:getBatch` data-plane endpoint raises the per-tenant ceiling from 12k to 360k API calls/hour and batches up to 50 resources per call - the only setting that survives a real fleet. The data-plane endpoint propagates Monitoring Reader RBAC 5-30 minutes after the role assignment, independently of the legacy ARM `/metrics` endpoint. If Step 7 returns 401 `AuthorizationFailed` immediately after SP creation, wait for propagation; flip to `false` only as a temporary fallback (see Troubleshooting). ```yaml apiVersion: opentelemetry.io/v1beta1 kind: OpenTelemetryCollector metadata: name: otel-control-plane namespace: otel spec: mode: deployment replicas: 1 image: otel/opentelemetry-collector-contrib:0.152.1 resources: requests: cpu: 50m memory: 128Mi limits: memory: 256Mi envFrom: - secretRef: name: scout-oauth2 - secretRef: name: azure-sp - configMapRef: name: otel-azure-context env: - name: ENVIRONMENT value: demo config: extensions: health_check: endpoint: 0.0.0.0:13133 azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} oauth2client: client_id: ${env:SCOUT_CLIENT_ID} client_secret: ${env:SCOUT_CLIENT_SECRET} token_url: ${env:SCOUT_TOKEN_URL} endpoint_params: audience: b14collector timeout: 10s receivers: azure_monitor: subscription_ids: ["${env:AZURE_SUBSCRIPTION_ID}"] resource_groups: ["${env:AZURE_RESOURCE_GROUP}"] services: ["Microsoft.ContainerService/managedClusters"] auth: {authenticator: azure_auth} collection_interval: 60s use_batch_api: true cache_resources: 60 dimensions: enabled: true metrics: "Microsoft.ContainerService/managedClusters": apiserver_cpu_usage_percentage: [] apiserver_memory_usage_percentage: [] etcd_cpu_usage_percentage: [] etcd_database_usage_percentage: [] etcd_memory_usage_percentage: [] # Remove these four if cluster autoscaling is not enabled on any node pool. # If autoscaling IS enabled but the pool is pinned (minCount = maxCount), # the metrics emit with zero/idle values - that is expected behavior. cluster_autoscaler_cluster_safe_to_autoscale: [] cluster_autoscaler_scale_down_in_cooldown: [] cluster_autoscaler_unneeded_nodes_count: [] cluster_autoscaler_unschedulable_pods_count: [] processors: batch: timeout: 5s send_batch_size: 1024 memory_limiter: check_interval: 5s limit_percentage: 80 spike_limit_percentage: 25 resource: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_aks, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:AKS_RESOURCE_ID}", action: insert} - {key: k8s.cluster.name, value: "${env:AKS_CLUSTER_NAME}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: deployment.environment, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: aks-control-plane, action: insert} exporters: debug: verbosity: basic otlp_http/b14: endpoint: ${env:SCOUT_OTLP_ENDPOINT} auth: authenticator: oauth2client compression: gzip timeout: 30s retry_on_failure: enabled: true initial_interval: 1s max_interval: 30s max_elapsed_time: 300s service: extensions: [health_check, azure_auth, oauth2client] pipelines: metrics: receivers: [azure_monitor] processors: [memory_limiter, resource, batch] exporters: [debug, otlp_http/b14] ``` ```bash kubectl apply -f manifests/05-collector-control-plane.yaml ``` ### Step 8: Auto-instrument your applications Apply the Instrumentation CR. It configures the init container images and exporter endpoint for all four languages. Sample-app pods reference it via annotation. ```yaml apiVersion: opentelemetry.io/v1alpha1 kind: Instrumentation metadata: name: scout-instrumentation namespace: otel spec: exporter: endpoint: http://$(NODE_IP):4318 propagators: - tracecontext - baggage sampler: type: parentbased_traceidratio argument: "1.0" resource: addK8sUIDAttributes: true java: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-java:1.33.6 python: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-python:0.61b0 env: - name: OTEL_PYTHON_LOG_CORRELATION value: "true" nodejs: image: ghcr.io/open-telemetry/opentelemetry-operator/autoinstrumentation-nodejs:0.73.0 go: image: ghcr.io/open-telemetry/opentelemetry-go-instrumentation/autoinstrumentation-go:v0.23.0 ``` ```bash kubectl apply -f manifests/06-instrumentation.yaml ``` Annotate your Deployment pods to opt in. The annotation value is `/`: import Tabs from '@theme/Tabs'; import TabItem from '@theme/TabItem'; **Python** Add one annotation to your pod template. The Python SDK auto-emits metrics and logs alongside traces; the agent collector's `metrics` and `logs` pipelines (Step 4) handle those. ```yaml apiVersion: apps/v1 kind: Deployment metadata: name: python-fastapi namespace: otel spec: replicas: 1 selector: matchLabels: {app: python-fastapi} template: metadata: labels: {app: python-fastapi} annotations: instrumentation.opentelemetry.io/inject-python: "otel/scout-instrumentation" spec: containers: - name: app image: python:3.14-slim env: - name: OTEL_EXPORTER_OTLP_ENDPOINT value: "http://otel-agent-collector.otel.svc.cluster.local:4318" - name: OTEL_SERVICE_NAME value: python-fastapi ``` **Node.js** Node.js auto-instrumentation requires Node.js >= 18 for the init container's instrumentation module to load correctly. ```yaml apiVersion: apps/v1 kind: Deployment metadata: name: nodejs-express namespace: otel spec: replicas: 1 selector: {matchLabels: {app: nodejs-express}} template: metadata: labels: {app: nodejs-express} annotations: instrumentation.opentelemetry.io/inject-nodejs: "otel/scout-instrumentation" spec: containers: - name: app image: node:25-alpine workingDir: /app env: - name: OTEL_EXPORTER_OTLP_ENDPOINT value: "http://otel-agent-collector.otel.svc.cluster.local:4318" - name: OTEL_SERVICE_NAME value: nodejs-express volumeMounts: - name: source mountPath: /src - name: workspace mountPath: /app volumes: - name: source configMap: name: nodejs-app-source - name: workspace emptyDir: {} ``` The ConfigMap source is mounted at `/src` (read-only); a writable `emptyDir` at `/app` is where `npm install` runs. Mounting the ConfigMap directly at `/app` is read-only and causes `npm install` to fail silently. **Java** Pin your Java base image to LTS 21. The bundled javaagent `v1.33.6` throws `InaccessibleObjectException` on Java 25's stricter module access. First request after pod start adds approximately 30-45 seconds for JIT warm-up; that is expected behavior, not an error. ```yaml apiVersion: apps/v1 kind: Deployment metadata: name: java-spring namespace: otel spec: replicas: 1 selector: {matchLabels: {app: java-spring}} template: metadata: labels: {app: java-spring} annotations: instrumentation.opentelemetry.io/inject-java: "otel/scout-instrumentation" spec: containers: - name: app image: maven:3.9-eclipse-temurin-21 workingDir: /app env: - name: OTEL_EXPORTER_OTLP_ENDPOINT value: "http://otel-agent-collector.otel.svc.cluster.local:4318" - name: OTEL_SERVICE_NAME value: java-spring volumeMounts: - name: source mountPath: /src volumes: - name: source configMap: name: java-app-source ``` **Go (eBPF)** Go auto-instrumentation uses an eBPF sidecar injected by the operator. The pod requires `securityContext.privileged: true` (for the sidecar to load eBPF programs) and `hostPID: true` (for `/proc` lookups). Do NOT also set `shareProcessNamespace: true`; K8s rejects the combination. The binary must retain debug symbols. Do not build with `-ldflags="-s -w"` (strips symbols) or the eBPF agent cannot find HTTP handlers at runtime. ```yaml apiVersion: apps/v1 kind: Deployment metadata: name: go-ebpf namespace: otel spec: replicas: 1 selector: {matchLabels: {app: go-ebpf}} template: metadata: labels: {app: go-ebpf} annotations: instrumentation.opentelemetry.io/inject-go: "otel/scout-instrumentation" instrumentation.opentelemetry.io/otel-go-auto-target-exe: "/app/hello" spec: hostPID: true containers: - name: app image: golang:1.24-alpine workingDir: /app env: - name: OTEL_EXPORTER_OTLP_ENDPOINT value: "http://otel-agent-collector.otel.svc.cluster.local:4318" - name: OTEL_SERVICE_NAME value: go-ebpf securityContext: privileged: true volumeMounts: - name: source mountPath: /src - name: build mountPath: /app volumes: - name: source configMap: name: go-app-source - name: build emptyDir: {} ``` The namespace must carry `pod-security.kubernetes.io/enforce: privileged` (applied in Step 3). Without it, the admission controller rejects the pod. :::note .NET The Instrumentation CR supports .NET via the CLR profiler pattern (same annotation style as Java/Python/Node). However, compile-on-startup setups (running `dotnet run` from a ConfigMap-mounted source directory) conflict with the profiler at Kestrel startup. Production .NET workloads should use pre-baked images (`dotnet publish` baked into a Dockerfile). The annotation pattern is the same; only the application container image differs. ::: ### Verify the setup ```bash # Check all collector pods are Running. kubectl get pods -n otel # Confirm the agent is scraping and exporting metrics. kubectl port-forward -n otel daemonset/otel-agent-collector 8888 & sleep 2 curl -s localhost:8888/metrics | grep otelcol_exporter_sent_metric_points_total # Expect: otelcol_exporter_sent_metric_points_total{exporter="otlp_http/b14",...} N (> 0) # Confirm span export (from auto-instrumented apps). curl -s localhost:8888/metrics | grep otelcol_exporter_sent_spans_total # Expect: otelcol_exporter_sent_spans_total{exporter="otlp_http/b14",...} N (> 0) # Confirm log export. curl -s localhost:8888/metrics | grep otelcol_exporter_sent_log_records_total # Expect: otelcol_exporter_sent_log_records_total{exporter="otlp_http/b14",...} N (> 0) ``` In the validation pass, the agent emitted 67,214 metric points (kubeletstats 58,910 + hostmetrics 5,798 + app OTLP 2,506), 99 spans, and 5 log records across all three signals with 0 drops. ### Key alerts to configure | Alert | Source | Warning | Critical | Why | |---|---|---|---|---| | Pod restart spike | `k8s.container.restarts` (k8s_cluster) | rate > 1/min for 5 min | rate > 5/min for 5 min | Container crashlooping or OOM-killed. | | Node memory utilization | `k8s.node.memory.working_set / k8s.node.memory.usage` (kubeletstats) | > 80% for 10 min | > 90% for 5 min | Node pressure, eviction risk. | | Pod CPU throttled | `k8s.pod.cpu_limit_utilization` (kubeletstats) | > 0.8 for 10 min | > 0.95 for 5 min | Workload exceeding CPU limit, latency increases. | | HPA stuck at max | `k8s.hpa.current_replicas / k8s.hpa.max_replicas` (k8s_cluster) | >= 1.0 for 15 min | (alert at warning) | Demand exceeds the autoscaler ceiling. | | Volume usage | `k8s.volume.available / k8s.volume.capacity` (kubeletstats) | > 80% | > 90% | PVC nearing capacity, write failures risk. | | PVC pending | `k8s.persistentvolumeclaim.status.phase == Pending` for 10 min | true | (alert at warning) | Storage class or provisioner issue. | | Daemonset misscheduled | `k8s.daemonset.misscheduled_nodes` (k8s_cluster) | > 0 | > 0 for 30 min | Node-selector or taint mismatch. | | Job failures | `kube_job_status_failed` (kube-state-metrics) | > 0 in 1 hour | > 5 in 1 hour | Scheduled work failing repeatedly. | | Container restart by reason | `k8s.container.status.reason` (k8s_cluster) | OOMKilled count > 0 in 10 min | OOMKilled count > 3 in 5 min | OOM kills indicate undersized memory limits. | | API server CPU (Step 7) | `azure_apiserver_cpu_usage_percentage_average` | > 60% for 10 min | > 80% for 5 min | Control plane stressed. | | etcd database usage (Step 7) | `azure_etcd_database_usage_percentage_average` | > 60% | > 80% | etcd nearing storage limit, affects writes. | | Autoscaler unschedulable pods (Step 7) | `azure_cluster_autoscaler_unschedulable_pods_count_total` | > 0 for 10 min | > 5 for 5 min | Autoscaler cannot schedule due to taints, quotas, or VM SKU availability. | | HTTP 5xx rate (app spans) | spans with `http.status_code >= 500` | > 1% of requests | > 5% of requests | Application error rate rising. | | p95 request latency (app spans) | span duration p95 | > 1s | > 3s | Latency degradation visible to users. | | Auto-instrumentation init failures | `kubectl get events -n otel \| grep BackOff` | 3 occurrences in 10 min | (alert at warning) | Init container not pulling or crashing; pods stuck in Init. | ### Troubleshooting #### Operator pods not starting cert-manager is not installed or its webhook is not ready. The operator's admission webhook requires TLS certs from cert-manager. Run `kubectl get pods -n cert-manager` and confirm all three deployments are `Running`. If they are, wait another 30 seconds for the webhook to register before retrying the operator install. #### Sample-app pods stuck in Init The `Instrumentation` CR is either not applied or is in a different namespace from the pod. The CR must be in the same namespace as the pod (`otel` in this guide). Check with: ```bash kubectl get instrumentation -n otel ``` #### Sample-app traces not visible in Scout but pods are Ready Check that `OTEL_EXPORTER_OTLP_ENDPOINT` points at the agent collector's Service DNS: `http://otel-agent-collector.otel.svc.cluster.local:4318`. The Instrumentation CR's `spec.exporter.endpoint` uses `$(NODE_IP)` which resolves correctly only if the pod's `NODE_IP` env var is set via the downward API. Sample app deployments should set it explicitly and override with the Service DNS instead. #### kubeletstats receiver: 403 Forbidden on `/stats/summary` The operator's auto-created ClusterRole does not include `nodes/stats` or `nodes/proxy`. Apply the supplemental ClusterRole and ClusterRoleBinding from Step 4. Once applied, the scrape recovers within one collection interval. #### Agent collector returns 404 on `/v1/metrics` or `/v1/logs` The agent CR's OTLP receiver is not wired into the `metrics` or `logs` pipelines. Auto-instrumented apps that emit metrics (Python, especially) or logs alongside traces will get 404 on those endpoints. Add `otlp` to the `receivers` list in each pipeline (Step 4's YAML already includes this). #### Go eBPF pod fails admission K8s rejects when both `hostPID: true` and `shareProcessNamespace: true` are set: `"ShareProcessNamespace and HostPID cannot both be enabled"`. Use `hostPID: true` only. Also confirm the `otel` namespace carries `pod-security.kubernetes.io/enforce: privileged` from Step 3. #### Java JIT slowness on first request Spring Boot plus javaagent adds approximately 30-45 seconds of JIT warm-up latency on the first request after pod start. This is not an error. Allow the pod time to warm up before running load tests. #### Java 25 InaccessibleObjectException The bundled javaagent `v1.33.6` has not yet caught up to Java 25's stricter module access policy. Pin the Java container image to LTS 21 (`eclipse-temurin-21` or `maven:3.9-eclipse-temurin-21`). #### Step 7 control-plane returns 401 on `metrics:getBatch` The data-plane RBAC for `metrics:getBatch` at `*.metrics.monitor.azure.com` propagates 5-30 minutes after the Monitoring Reader grant, independently of the legacy ARM `/metrics` endpoint. Wait for propagation; the receiver retries automatically. If you need metrics flowing immediately, flip `use_batch_api` to `false` to fall back to the legacy ARM endpoint (RBAC there is immediate), then return to `true` once the data-plane RBAC has settled. #### `spec.podLabels` workaround The operator's v1beta1 CRD removed `spec.podLabels`. Workload Identity Federation requires the pod label `azure.workload.identity/use: "true"`, which the WI webhook injects only when that label is present. Without `spec.podLabels`, the webhook never fires. For any collector that needs Azure API access (the control-plane collector in Step 7), use Service Principal env-var auth via the `azure-sp` Secret. The agent and cluster collectors do not talk to Azure and are unaffected. ### Frequently Asked Questions #### How do I monitor an AKS cluster with the OpenTelemetry Operator? Install cert-manager, then deploy the `opentelemetry-operator` Helm chart. Create `OpenTelemetryCollector` CRs for a DaemonSet (kubeletstats + hostmetrics), a cluster Deployment (k8s_cluster + prometheus scraping kube-state-metrics), and optionally a control-plane Deployment (azure_monitor). Apply an `Instrumentation` CR and annotate your pods to enable zero-code auto-instrumentation for Python, Node.js, Java, and Go. #### How does the operator-managed collector authenticate to base14 Scout? Via the `oauth2client` extension. Store the Scout-issued `client_id` and `client_secret` in a Kubernetes Secret named `scout-oauth2` in the `otel` namespace, reference them in the `OpenTelemetryCollector` CR's `envFrom`, and the `otlp_http/b14` exporter fetches short-lived bearer tokens automatically (cached until expiry). #### Why three OpenTelemetryCollector CRs instead of one? Each CR maps to a specific Pod controller and receiver family. `kubeletstats` needs a DaemonSet (one pod per node). `k8s_cluster` needs a single-replica Deployment (it would emit duplicates if scaled horizontally). `azure_monitor` is a lightweight control-plane scraper that runs as a separate Deployment so you can scope its Service Principal credentials independently. Merging them would force compromises on controller type or RBAC scope. #### How does this differ from Microsoft's Managed Prometheus and Container Insights? Managed Prometheus and Container Insights are Azure-tenant-bound, billed per-GB ingested, and visualized in Managed Grafana or Log Analytics. The OpenTelemetry Collector is vendor-neutral. The same CRs and image ship to base14 Scout or any OTLP-compatible backend without redeployment. Multi-cloud and hybrid teams prefer this pattern because backend switches are config changes, not agent re-deployments. #### What languages support auto-instrumentation here, and which are not yet validated? Validated in this guide: Python (FastAPI), Node.js (Express), Java (Spring Boot 3 on LTS 21), and Go (eBPF, net/http). .NET is supported by the operator's Instrumentation CR pattern but the ConfigMap-mounted `dotnet run` on-startup shape conflicts with the CLR profiler. Use pre-baked images (`dotnet publish`) for production .NET workloads. #### How do I add control-plane metrics like API server uptime? Apply the `otel-control-plane` CR from Step 7. It runs the `azure_monitor` receiver against the AKS resource, authenticated via Service Principal env-var auth. You get 18 control-plane series (9 metrics at two aggregations each - apiserver, etcd, autoscaler) on a vanilla cluster. If cluster autoscaling is not enabled on any node pool, the four `azure_cluster_autoscaler_*` metrics return 401 (no backing data source) - remove them from the receiver's metric whitelist. If autoscaling is enabled but the pool is pinned (e.g. `minCount = maxCount = 1`), the metrics emit with zero/idle values; that is expected and indicates the autoscaler is healthy but inactive. Most workloads need only Steps 1-6 for pod, container, and cluster-state visibility. ### Related Guides - [Azure Kubernetes Service (Helm)](aks-with-helm.md) - alternative pattern using raw Helm releases, no operator required. - [OpenTelemetry Operator setup][otel-operator-setup] - generic operator install and concepts. - [OpenTelemetry Operator GitHub][otel-operator-repo] - CRD reference and release notes. - [cert-manager](https://cert-manager.io/) - required dependency for the operator's admission webhook. [otel-operator-setup]: ../../collector-setup/opentelemetry-operator-setup.md [otel-operator-repo]: https://github.com/open-telemetry/opentelemetry-operator --- ## Azure API Management Monitoring with OpenTelemetry - Gateway Latency, Request Counts, and Backend Health ### Overview This guide is the **execution playbook** for Azure API Management. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running APIM in production who want to add gateway telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.ApiManagement/service` metrics every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. The receiver does not proxy or terminate traffic - it queries Azure Monitor for whatever your APIM service auto-publishes. The receiver does not connect to APIM directly. It queries Azure Monitor for any APIM service your subscription auto-publishes to, so the same configuration covers Consumption, Developer, Basic, Standard, Premium, and Premium v2 tiers across any number of APIs, operations, products, and subscriptions per service. This guide is metrics-only. For ingesting APIM diagnostic logs (`GatewayLogs`, `WebSocketConnectionLogs`, `DeveloperPortalAuditLogs`), see [Logs](#logs) for the Diagnostic Settings → Event Hubs handoff. ### API Management at a glance API Management is Azure's full-lifecycle gateway product: a request hits a published API, APIM applies a per-API or per-operation policy chain (auth, transformation, rate limiting, caching, validation), forwards to the configured backend, and applies a response policy chain on the way out. Every step contributes to observable signals. | Layer | What it produces | | --- | --- | | Listener | Total incoming request count, including pre-auth rejects. | | Authentication and policy | Subscription-key validation, JWT validation, IP filtering, policy-based rate limiting. | | Backend forwarding | One request per inbound request to the configured `serviceUrl` (or a backend pool). | | Response handling | Status code, latency, transformation, response cache lookup. | The receiver does not see the per-step breakdown - Azure Monitor publishes coarse counters (request counts split by gateway response category, plus end-to-end and backend latency aggregations). For the per-step breakdown, ship logs via Diagnostic Settings. ### Tier choice Azure API Management has six pricing tiers as of 2026. Each gates feature availability, which in turn gates which metrics emit data. | Tier | Pricing model | Provisioning | Metric coverage | | --- | --- | --- | --- | | **Consumption** | Serverless: $3.50 per million calls, near-zero idle | ~5-10 min | Request counts, end-to-end latency, backend latency. **No** `Capacity`, `CpuPercent_Gateway`, `MemoryPercent_Gateway`, `EventHubTotal*`, `NetworkConnectivity`, `WebSocketMessages`, `ConnectionAttempts`. | | **Developer** | Single dedicated unit, ~$0.07/hour | 30-45 min | All Consumption metrics + `Capacity` + `CpuPercent_Gateway` + `MemoryPercent_Gateway` + `EventHubTotal*` + `NetworkConnectivity` + `WebSocketMessages` + `ConnectionAttempts`. | | **Basic** | 1-2 dedicated units, ~$0.20/hour per unit | 30-45 min | Same as Developer + multi-unit autoscale. | | **Standard** | 1-4 dedicated units, ~$0.95/hour per unit | 30-45 min | Same as Basic + custom domains + zone redundancy. | | **Premium** | 1-N dedicated units, ~$3.78/hour per unit, multi-region | 45-60 min | Same as Standard + multi-region deploy + VNet integration + private endpoints. | | **Premium v2** | Same as Premium plus Stv2 platform | 45-60 min | Same metrics; runtime improvements only. | The receiver configuration is identical across tiers. Tier-gated metrics that the resource does not publish simply emit no data points - there is no error and no zero-valued series. The whitelist below intersects what every tier publishes; expand it for Developer and above by adding `Capacity` + `CpuPercent_Gateway` + `MemoryPercent_Gateway`. Pick Consumption for spiky workloads where idle cost matters more than metric depth. Pick Developer for non-production environments that need the full metric surface for dashboarding. Production lives on Standard, Premium, or Premium v2. ### Receiver configuration Drop this into your existing collector. The receiver, resource processor, transform processor (for receiver bug #45942), and pipeline are all keyed `/apimanagement` so they coexist with other Azure receivers under one collector and one Scout exporter. ```yaml extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/apimanagement: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:APIMANAGEMENT_RESOURCE_GROUP} services: - Microsoft.ApiManagement/service auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.ApiManagement/service": # Universal counters (Consumption + Developer + Basic + Standard + Premium + Premium v2) Requests: [Total] SuccessfulRequests: [Total] FailedRequests: [Total] OtherRequests: [Total] UnauthorizedRequests: [Total] # Universal latency, dual-aggregation Duration: [Average, Maximum] BackendDuration: [Average, Maximum] # Developer / Basic / Standard / Premium / Premium v2 only Capacity: [Average] CpuPercent_Gateway: [Average] MemoryPercent_Gateway: [Average] # Diagnostic-Settings-to-Event-Hubs egress (whitelisted but silent unless configured) EventHubTotalEvents: [Total] EventHubTotalBytesSent: [Total] processors: resource/apimanagement: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_api_management, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:APIMANAGEMENT_REGION}", action: insert} # cloud.resource_id is recommended but optional - the receiver injects # azuremonitor.resource_id per data point automatically. - {key: cloud.resource_id, value: "${env:APIMANAGEMENT_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:APIMANAGEMENT_SERVICE_NAME}", action: insert} # Workaround for receiver bug #45942 (case-mismatch on metadata_* # dimensions, observed on v0.151.0). Lowercases the PascalCase # variants to deduplicate. The `set(...) where ... == nil` guard # prevents overwriting any legitimate lowercase value that the # receiver already emitted on the same data point. See # [Bug #45942](#bug-45942-case-mismatched-dimension-keys). transform/apim_dim_lowercase: metric_statements: - context: datapoint statements: - set(attributes["metadata_apiid"], attributes["metadata_ApiId"]) where attributes["metadata_ApiId"] != nil and attributes["metadata_apiid"] == nil - delete_key(attributes, "metadata_ApiId") where attributes["metadata_ApiId"] != nil - set(attributes["metadata_hostname"], attributes["metadata_Hostname"]) where attributes["metadata_Hostname"] != nil and attributes["metadata_hostname"] == nil - delete_key(attributes, "metadata_Hostname") where attributes["metadata_Hostname"] != nil - set(attributes["metadata_location"], attributes["metadata_Location"]) where attributes["metadata_Location"] != nil and attributes["metadata_location"] == nil - delete_key(attributes, "metadata_Location") where attributes["metadata_Location"] != nil service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/apimanagement: receivers: [azure_monitor/apimanagement] processors: [memory_limiter, resource/apimanagement, transform/apim_dim_lowercase, batch] exporters: [otlphttp/b14] ``` The Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. ### Authentication and RBAC Pick the `azure_auth` mode for where the collector runs: - **AKS pod** - `workload_identity` (federated credential, no secret). - **Container Apps / VMSS / Azure VM** - `managed_identity` (user-assigned survives instance replacement). - **External or on-prem** - `service_principal`. - **Local dev only** - `use_default: true` (Azure SDK credential chain). Grant `Monitoring Reader` at the resource group containing your APIM service. For mode-by-mode YAML, federation-credential setup, and the `az role assignment create` snippet, see [Azure Service Bus § Authentication](./service-bus.md#authentication) - the configuration is identical except for the receiver's `services:` line and the resource processor's `cloud.platform` value. This guide defaults `use_batch_api: false` to match the validated runnable example. Flip to `true` once the data-plane RBAC has settled (5-30 minutes after a fresh `Monitoring Reader` grant) for the 360,000-calls/hour ceiling. ### What you'll monitor Twelve metrics from `Microsoft.ApiManagement/service`. The receiver renames them from Azure's PascalCase (e.g. `Duration`) to OTel-style `azure__` (e.g. `azure_duration_average`). | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `Requests` | `azure_requests_total` | Count | Total inbound request count to the gateway. The `metadata_GatewayResponseCode` dimension splits by HTTP status; `metadata_GatewayResponseCodeCategory` rolls them into 2xx / 4xx / 5xx buckets. | | `SuccessfulRequests` | `azure_successfulrequests_total` | Count | HTTP 2xx subset. Pair with `Requests` to derive a success rate. | | `FailedRequests` | `azure_failedrequests_total` | Count | HTTP 5xx subset. *Silent-when-quiet.* | | `OtherRequests` | `azure_otherrequests_total` | Count | HTTP 4xx subset. Includes both client errors (400, 401, 404, 422) and APIM-policy rate-limit rejects (429 with `metadata_LastErrorReason: RateLimitExceeded`). See [Gateway 429s vs backend 429s](#gateway-429s-vs-backend-429s). | | `UnauthorizedRequests` | `azure_unauthorizedrequests_total` | Count | HTTP 401 + 403 subset. Subscription-key invalid, JWT expired, IP-filter rejection. Useful as a security signal independent of `OtherRequests`. | | `Duration` | `azure_duration_average` + `azure_duration_maximum` | ms | End-to-end gateway latency: client request received to client response sent. Includes policy execution + backend forwarding + response handling. | | `BackendDuration` | `azure_backendduration_average` + `azure_backendduration_maximum` | ms | Backend leg only: APIM-to-backend send to backend response received. `Duration - BackendDuration` is APIM's own overhead (policy + transformation + caching). | | `Capacity` | `azure_capacity_average` | Percent | Gateway capacity utilisation as a single percent. Single dedicated unit on Developer; sums across units on Basic / Standard / Premium. | | `CpuPercent_Gateway` | `azure_cpupercent_gateway_average` | Percent | Per-unit CPU. Published at PT5M (5-minute) granularity. Silent on a freshly-deployed gateway with low traffic; populates within 10-30 min of sustained load. | | `MemoryPercent_Gateway` | `azure_memorypercent_gateway_average` | Percent | Per-unit memory. Same PT5M granularity and load floor as CpuPercent. | | `EventHubTotalEvents` | `azure_eventhubtotalevents_total` | Count | Diagnostic Settings → Event Hubs egress count. *Silent unless configured.* | | `EventHubTotalBytesSent` | `azure_eventhubtotalbytessent_total` | Bytes | Diagnostic Settings → Event Hubs egress bytes. *Silent unless configured.* | `metadata_apiid` rides alongside every per-API metric, splitting the service-scope series into per-API series automatically. Operations within an API are not split at the metric level - operation-level attribution requires Diagnostic Settings logs. **Silent-when-quiet.** Azure Monitor returns data points only for time windows where the underlying condition occurred. A healthy gateway emits zero series for `FailedRequests`. Wire alerts on this metric to fire on series presence in window, not on threshold crossings. **Tier-gated metrics.** `Capacity`, `CpuPercent_Gateway`, and `MemoryPercent_Gateway` are not published on Consumption tier. The receiver still queries them; Azure Monitor returns an empty set and the receiver passes that through unchanged. **Diagnostic-Settings-gated metrics.** `EventHubTotalEvents` and `EventHubTotalBytesSent` only emit when Diagnostic Settings → Event Hubs is configured at the APIM service. They quantify the **egress to Event Hubs**, not the API request volume. Drop them from the whitelist on fleets that do not use Diagnostic Settings egress to keep the metric cardinality clean. ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | --- | --- | --- | | Legacy Azure Resource Manager `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Default in this guide. Immediate RBAC propagation. | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Switch once data-plane RBAC has propagated (5-30 min after grant). | At a 60-second collection interval, a single APIM service costs roughly 60 calls per hour (one per metric per poll, deduplicated within the receiver). A 50-service fleet running on legacy `/metrics` consumes ~3,000 calls per hour - well within the 12k ceiling. Above ~150 services per subscription, switch to `use_batch_api: true` to lift the per-subscription ceiling and benefit from batched fan-out. The receiver shares one rate-limit budget across all subscriptions in the list; it does not bypass per-subscription quotas. Splitting heavy subscriptions across separate collector instances lifts the aggregate ceiling linearly. `cache_resources` is the resource-list cache TTL in seconds. The receiver default is `86400` (24 hours), which is correct for a stable fleet. Lower to `3600` or `600` only if APIM services are created and destroyed frequently enough that 24-hour-stale resource lists become a problem. ### Cardinality control By default, the receiver emits one OTel series per `(resource × metric × aggregation × dimension-combination)`. APIM publishes more dimensions than most Azure surfaces: `ApiId`, `Location`, `Hostname`, `GatewayResponseCode`, `GatewayResponseCodeCategory`, `BackendResponseCode`, `BackendResponseCodeCategory`, and `LastErrorReason`. The product across these dimensions can blow up cardinality on busy gateways. A worked example: 1 service × 12 metrics × 1 aggregation each (with the dual-aggregation Duration / BackendDuration counted separately) × average 4-dimension-value combinations per metric ≈ 56 series for one quiet API. Add a second API and the per-API metrics double; add the `GatewayResponseCode` split (typically 5-8 active values during error windows) and request-count metrics multiply 5-8×. Two control levers, in order of preference: 1. **`dimensions.overrides`** drops or whitelists dimensions per metric. Drop `BackendResponseCode` on metrics where it is always identical to `GatewayResponseCode` (most happy-path traffic); drop `Hostname` on single-region single-domain services; drop `LastErrorReason` on metrics that are not the error counters. The override config uses the **bare Azure dimension name** (e.g. `ApiId`, not `metadata_apiid`); the receiver adds the `metadata_` prefix when it emits. ```yaml azure_monitor/apimanagement: dimensions: enabled: true overrides: "Microsoft.ApiManagement/service": Requests: - ApiId - GatewayResponseCodeCategory SuccessfulRequests: - ApiId FailedRequests: - ApiId - LastErrorReason OtherRequests: - ApiId - LastErrorReason - GatewayResponseCode Duration: - ApiId BackendDuration: - ApiId ``` 2. **Per-service receiver instances.** Split high-cardinality APIs into separate `azure_monitor/apimanagement-public` and `azure_monitor/apimanagement-internal` receivers with different override profiles. Both contribute to the same `metrics/apimanagement` pipeline. Receiver bug #45942 emits these dimensions in both PascalCase and lowercase forms on the same metric; the `transform` processor in the [Receiver configuration](#receiver-configuration) snippet canonicalises them to lowercase. See [Bug #45942](#bug-45942-case-mismatched-dimension-keys). Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's Prometheus self-telemetry endpoint (port 8888 by default) to see actual cardinality after `overrides` apply. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points; derive your own from observed 99th percentile over a representative week. `azure_failedrequests_total` only emits data points when 5xx responses occur. Wire alerts on this metric to fire on series presence in window, not on numeric thresholds; a healthy gateway emits no points at all. | Metric (OTel name) | Warning | Critical | Why it matters | | --- | --- | --- | --- | | `azure_failedrequests_total` (per `metadata_apiid`) | `> 0` over 5m | `> 0` over 15m | Backend or APIM gateway 5xx. Investigate backend health and APIM Diagnostic Logs together. | | `azure_otherrequests_total / azure_requests_total` (4xx ratio) | > 5% / 5m | > 15% / 5m | High client-error rate. Slice by `metadata_LastErrorReason` to distinguish `RateLimitExceeded` (gateway throttling) from `OperationNotFound` (consumer routing bugs) from `KeyNotFound` (auth misconfiguration). | | `azure_unauthorizedrequests_total` | > 1% / 5m | > 5% / 5m | Brute-force or expired-key window. Cross-check IP-filter logs in Diagnostic Settings. | | `azure_duration_average` (per `metadata_apiid`) | > 1s | > 3s | End-to-end gateway latency. If `BackendDuration` is the dominant component, the upstream is slow; if `Duration - BackendDuration` is dominant, APIM policy execution is slow. | | `azure_backendduration_maximum` (per `metadata_apiid`) | > p99 baseline × 2 | > p99 baseline × 5 | Tail latency at the upstream. Driven by retry storms or upstream saturation. | | `azure_capacity_average` (single-unit) / `100` | > 70% | > 90% | Gateway saturation. On Developer this is the single unit; on Basic / Standard / Premium it summarises the autoscale pool. | | `azure_cpupercent_gateway_average` (per unit) | > 70% | > 90% | Per-unit CPU. Add capacity (autoscale) or upgrade tier. | | `azure_memorypercent_gateway_average` (per unit) | > 70% | > 90% | Per-unit memory. Memory pressure surfaces as 502s before CPU saturation does. | #### RED method on the gateway If you run APIM as part of a service backed by service-level objectives (SLOs), frame APIM metrics as RED (rate, errors, duration) on the gateway: - **Rate.** `azure_requests_total` per service, sliced by API (`metadata_apiid`). - **Errors.** Split into two service-level indicators (SLIs): - **Availability error rate** = `(azure_failedrequests_total + azure_otherrequests_total{metadata_LastErrorReason="RateLimitExceeded"}) / azure_requests_total`. Routes to platform on-call. - **Request-quality error rate** = `azure_otherrequests_total{metadata_LastErrorReason!="RateLimitExceeded"} / azure_requests_total`. Routes to the owning API team. - **Duration.** `azure_duration_maximum` for tail; `azure_duration_average` for steady state. APIM's overhead = `Duration - BackendDuration`; upstream contribution = `BackendDuration`. For saturation (the U in USE), pair `azure_capacity_average`, `azure_cpupercent_gateway_average`, and `azure_memorypercent_gateway_average`. On Consumption tier, capacity metrics are absent; saturation is governed by Azure's per-call quotas which surface as 429s in `OtherRequests`. ### Production-tier additions Standard, Premium, and Premium v2 publish a handful of metrics not exposed on Consumption or Developer. Extend the whitelist when the service is at one of those tiers: ```yaml metrics: "Microsoft.ApiManagement/service": # ...all 12 from the universal + Capacity + EventHub set above... NetworkConnectivity: [Average] # 0 / 1 health to dependencies (DNS, AAD, Storage) WebSocketMessages: [Total] # WebSocket frame count, when WS APIs are configured ConnectionAttempts: [Total] # TCP connection attempts to the gateway ``` Aggregations match the rest of the whitelist: one per metric. `NetworkConnectivity` is a binary health score; alert on `< 1` for any data point. `WebSocketMessages` is silent unless the service hosts WebSocket APIs. `ConnectionAttempts` is useful as a denominator for `azure_unauthorizedrequests_total / azure_connectionattempts_total` to derive an attack-attempt ratio. The Diagnostic-Settings-to-Event-Hubs egress family is broader on production tiers - `EventHubSuccessfulEvents`, `EventHubTotalFailedEvents`, `EventHubRejectedEvents`, `EventHubThrottledEvents`, `EventHubTimedoutEvents`, `EventHubDroppedEvents`. Add the variants you care about to the whitelist; otherwise stick with the two on the default whitelist. ### Gateway 429s vs backend 429s APIM is a frequent source of 429 responses, and distinguishing the source is essential because the remediation differs. | Source | Signature | Remediation | | --- | --- | --- | | **APIM gateway 429** (rate-limit policy tripped before backend forwarding) | `metadata_GatewayResponseCode: 429` + `metadata_BackendResponseCode: 0` + `metadata_LastErrorReason: RateLimitExceeded` | Tune the `rate-limit-by-key` or `rate-limit` policy - raise the threshold, change the scoping (per-key vs per-IP), or move rate-limit out of APIM into the backend. | | **Backend 429** (upstream returned 429, APIM forwarded as-is) | `metadata_GatewayResponseCode: 429` + `metadata_BackendResponseCode: 429` + `metadata_LastErrorReason: None` | Investigate upstream capacity. APIM has done its job; the backend is the bottleneck. | | **Quota policy 429** (Quota or QuotaByKey policy hit, distinct from rate-limit) | `metadata_GatewayResponseCode: 429` + `metadata_BackendResponseCode: 0` + `metadata_LastErrorReason: QuotaExceeded` | Reset the quota window or raise the per-window allowance. Quota is daily / monthly; rate-limit is per-N-seconds. | All three appear in `azure_otherrequests_total` (the 4xx bucket). Slicing by `metadata_LastErrorReason` separates them. APIM's default Developer-tier setup includes a permissive built-in rate-limit on the `starter` product that trips around 5 sustained requests / second per subscription key - surprising operators who expect throttling only when an explicit policy is configured. ### Apps-side instrumentation This guide is metrics-only. APIM does not produce W3C trace context spans for the request path through the gateway - there is no current first-party way to link an inbound client span through the gateway to the backend span via the OTel receiver. For end-to-end traces, instrument the client and backend code: - **Backend service spans.** Auto-instrumented via the OTel agent for the language. APIM forwards the inbound request including trace headers if the client sent them; the backend span will be a child of the client span automatically when `traceparent` propagates. - **APIM as a "missing middle".** APIM's `Duration` and `BackendDuration` metric series fill the gap that traces would otherwise reveal. A long `Duration - BackendDuration` interval flags policy-execution overhead even though there is no APIM span to drill into. For per-request audit (which API, which operation, which subscription key, which client IP, which response code), use Diagnostic Settings to Log Analytics or Event Hubs - see [Logs](#logs). ### Logs `GatewayLogs` is one row per inbound request: API, operation, response code, latency, subscription-key prefix, and client IP. That row-level detail is what you reach for when you need: - **Per-operation latency** - operation-level attribution lives in logs; metric series carry `ApiId` but not `OperationId`. - **Percentile aggregations** - Azure Monitor pre-aggregates `Duration` as Average / Maximum / Minimum only. p99 and p95 are computed from raw per-request samples. - **Per-key or per-IP audit** - subscription-key prefix, client IP, and per-request status code are log-only fields. APIM publishes three diagnostic log categories: | Category | What it contains | Volume guidance | | --- | --- | --- | | `GatewayLogs` | One row per request, with API + operation + response code + latency + subscription key prefix + client IP. | High - equivalent to one record per inbound request. Sample at the source if cost matters. | | `WebSocketConnectionLogs` | WebSocket connection lifecycle events. | Low - only emits when WS APIs are configured. | | `DeveloperPortalAuditLogs` | Developer portal admin operations. | Low - emits per portal admin action. | The recommended pattern is **Diagnostic Settings → Event Hubs → `azureeventhubreceiver`** in the same collector. The receiver ingests events as OTel logs and routes them to Scout via the same `oauth2client` / `otlphttp/b14` pipeline used for metrics. That configuration is documented separately and lives in a sibling fragment under `_shared/azure/scraper/conf.d/`. Diagnostic Settings → Log Analytics is a viable alternative when your organisation already centralises in Log Analytics. Scout ingestion from Log Analytics is supported via the LA query API but is not covered here. ### Troubleshooting #### `AuthorizationFailed` from the receiver in the first 60 seconds Symptom: scraper logs `AuthorizationFailed` or `403` shortly after provisioning. Cause: `Monitoring Reader` was granted but Azure RBAC is still propagating to the data-plane endpoint. Fix: wait 60-300 seconds. The receiver retries on its next poll cycle. If the error persists after 5 minutes, verify the role assignment with `az role assignment list --assignee --scope `. #### `metrics_definitions_count: 0` on first poll after provisioning Symptom: the receiver logs `metrics_definitions_count: 0` and emits no metrics. Cause: Azure Monitor's metricDefinitions catalog has not yet populated for the freshly-deployed APIM service (typically true within 60-180 seconds of `provisioningState: Succeeded`). Fix: restart the scraper after the APIM service has been up for at least 3 minutes, OR wait 5-10 minutes and the next 60-second poll will pick up the now-populated catalog. #### `CpuPercent_Gateway` and `MemoryPercent_Gateway` stay silent on Developer Symptom: the two gateway-resource metrics emit no data points despite running on Developer (or Basic / Standard / Premium). Cause: Azure Monitor publishes both at PT5M (5-minute) granularity and only emits data points when measurable load is present. A freshly-deployed gateway with sub-second traffic spikes can keep these silent for the first 10-30 minutes. Fix: drive sustained traffic for at least 10 minutes, then re-check. For the alerting strategy, see [Alert tuning](#alert-tuning). #### Subscription key 401 after a tier change Symptom: existing subscription keys return 401 after the APIM service is moved between tiers. Cause: a tier change on APIM rotates internal keys for some product or subscription configurations. Fix: re-fetch the primary key with `az rest --method post --url "https://management.azure.com/subscriptions//listSecrets?api-version=2023-09-01-preview"` and update the client application or scraper-env file. #### APIM 429s without a configured rate-limit policy Symptom: `OtherRequests` shows a high 429 rate even though no explicit `rate-limit-by-key` policy is defined on the API. Cause: the auto-created `starter` product on Consumption + Developer tiers includes a built-in throttle (~5 sustained requests / second per subscription key) that trips before any user-defined policy runs. Fix: edit the `starter` product policy to remove or adjust the built-in `` element, or move clients to the `unlimited` product (also auto-created), which does not include the built-in throttle. #### Bug 45942 case-mismatched dimension keys Symptom: every series carries both `metadata_apiid` and `metadata_ApiId`, both `metadata_hostname` and `metadata_Hostname`, both `metadata_location` and `metadata_Location`, doubling cardinality. Cause: opentelemetry-collector-contrib bug [#45942](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942) emits the same dimension under two casings on Microsoft.ApiManagement, Microsoft.Network/azureFirewalls, and a subset of Microsoft.Storage metrics. Fix: apply the `transform/apim_dim_lowercase` processor in the [Receiver configuration](#receiver-configuration) snippet. Revisit when the receiver releases a fix; remove the transform processor at that time. #### Cardinality blowup on Scout volume Symptom: Scout query latency degrades after onboarding APIM. Cause: the `metadata_GatewayResponseCode` × `metadata_BackendResponseCode` × `metadata_LastErrorReason` × `metadata_apiid` product can produce hundreds of series per metric on busy gateways. Fix: apply `dimensions.overrides` on the noisy metrics - see [Cardinality control](#cardinality-control). #### Scout OAuth2 returns 401 Symptom: `oauth2client` extension logs 401 from the token endpoint. Cause: stale `SCOUT_CLIENT_ID` / `SCOUT_CLIENT_SECRET` / `SCOUT_TOKEN_URL`. Fix: re-source `~/.config/base14/scout-otel-config.env` (or the equivalent secret store) and restart the collector. The `oauth2client` extension caches tokens for the configured TTL; restart is the fastest invalidation. ### Frequently Asked Questions #### When should I use APIM versus a self-hosted NGINX or Traefik gateway? Pick APIM when you need policy management at the gateway (per-API auth, transformation, caching, rate-limiting) without writing code, or when you need a developer portal for partner / customer API discovery. Pick a self-hosted gateway when policy is best-expressed as code, when latency overhead matters more than ergonomics (APIM adds 5-30 ms per request), or when you already operate Kubernetes ingress controllers and want telemetry to flow through the same Prometheus / OpenTelemetry pipeline. Both surface request counts and latency to Scout via OpenTelemetry; the metric vocabulary differs. #### What changes between Consumption, Developer, and the production tiers for monitoring? Metric coverage is largely the same across Developer / Basic / Standard / Premium / Premium v2 - they all publish the universal counters, latency, capacity, and Diagnostic-Settings-to-Event-Hubs egress metrics. Consumption is the outlier: it does not publish `Capacity`, `CpuPercent_Gateway`, `MemoryPercent_Gateway`, or any of the EventHub-egress family. The whitelist in this guide covers Consumption + Developer; expand it for production fleets per [Production-tier additions](#production-tier-additions). #### What metrics are unavailable on Consumption tier? Five whitelist entries return no data points on Consumption: `Capacity`, `CpuPercent_Gateway`, `MemoryPercent_Gateway`, `EventHubTotalEvents`, `EventHubTotalBytesSent`. The first three are gateway-resource metrics that don't apply to Consumption's serverless model. The last two require Diagnostic Settings → Event Hubs configuration which works on Consumption but is rarely set up for the lighter-weight tier. #### How do I detect a slow backend versus a slow APIM policy? `azure_duration_average` is end-to-end (client request received to client response sent). `azure_backendduration_average` is just the backend leg (APIM-to-backend send to backend response received). The difference, `Duration - BackendDuration`, is APIM's own overhead - policy execution, transformation, response caching, inbound / outbound formatting. On a healthy gateway with simple policies, the difference is sub-10 ms; if it climbs above 50 ms, investigate policy chain complexity (especially heavy XML / JSON transformations or external `send-request` policy lookups). #### How does APIM compare to AWS API Gateway for monitoring? Both are managed gateway products with similar request-counter and latency surfaces. Monitoring shape differs in collection pattern: APIM is pulled from Azure Monitor's metricDefinitions API via the azure_monitor receiver every 60 seconds; AWS API Gateway is pushed via CloudWatch Metrics Stream into the awscloudwatchmetricstreamreceiver. Metric coverage is broadly equivalent (request counts, latency, error rates) with vendor-specific names. APIM exposes a richer dimension set (especially `LastErrorReason` which has no AWS equivalent); AWS API Gateway exposes per-method breakdown directly at the metric level whereas APIM requires logs for per-operation attribution. Both surfaces flow through the same OTLP/HTTP exporter to Scout, so multi-cloud gateway dashboards are unified at query time. #### How do I add Azure API Management metrics to my existing OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.ApiManagement/service`, route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter, and grant the collector's service principal Monitoring Reader at the resource group containing your APIM service. The receiver polls Azure Monitor's REST API every 60 seconds. Consumption tier emits a smaller metric subset than Developer, Standard, Premium, and Premium v2; the receiver returns whatever the resource publishes without erroring on tier- gated metrics. #### Why are CpuPercent_Gateway and MemoryPercent_Gateway silent on Developer tier? Both metrics are published by Azure Monitor at PT5M (5-minute) granularity and only emit data points when gateway load is measurable. A freshly- provisioned Developer instance with low traffic can keep these metrics silent for the first 10 to 30 minutes after deploy. Instances with steady traffic report them right away. Wire alerts to fire on threshold crossings only when at least one data point has been observed in the prior hour; otherwise alert on series presence so a missing series does not trigger as a low-CPU positive. #### What is the difference between APIM gateway 429 and backend 429? APIM gateway 429 means the rate-limit-by-key or rate-limit-by-subscription policy on the API tripped before the request reached the backend. Visible as `metadata_BackendResponseCode` 0 plus `metadata_LastErrorReason` `RateLimitExceeded` on the `OtherRequests` metric. Backend 429 means the upstream service returned 429 to APIM, which forwarded it as-is to the client. Visible as `metadata_BackendResponseCode` 429 plus `metadata_LastErrorReason` None. The fix differs in each case. A gateway 429 means tuning the APIM policy. A backend 429 means adding upstream capacity. #### Why do my APIM dimensions appear with both PascalCase and lowercase keys? This is opentelemetry-collector-contrib bug #45942. The `azure_monitor` receiver currently emits `metadata_ApiId` alongside `metadata_apiid`, `metadata_Hostname` alongside `metadata_hostname`, and `metadata_Location` alongside `metadata_location` for the same metric series, doubling cardinality silently. Workaround: apply a transform processor in the collector pipeline to canonicalise the keys to lowercase. The bug is namespace-specific and has been observed on Azure Firewall, Azure Storage, and Azure API Management as of receiver v0.151.0. The issue was closed as inactive in June 2026 with no fix merged and no successor issue open, so treat the transform processor pattern in this guide as the permanent handling rather than a stopgap. Re-check the receiver's changelog before removing it. #### Should I run APIM Diagnostic Logs through this metrics collector? No. APIM diagnostic logs (`GatewayLogs`, `WebSocketConnectionLogs`, `DeveloperPortalAuditLogs`) are handled by Diagnostic Settings forwarding to Event Hubs, then ingested by the `azureeventhubreceiver` as OTel logs. That is a separate fragment under the long-lived shared scraper and is documented separately from this metrics-only guide. The two pipelines coexist in one collector but use different receivers and different metric or log signals. ### Reference - [Microsoft.ApiManagement supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-apimanagement-service-metrics) - [APIM diagnostic logs reference](https://learn.microsoft.com/azure/api-management/api-management-howto-use-azure-monitor) - [APIM rate-limit and quota policies](https://learn.microsoft.com/azure/api-management/api-management-policies#rate-limiting-and-quotas) - [opentelemetry-collector-contrib azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - [Receiver bug #45942 - case-mismatch dimension keys](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942) ### Related Guides - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - start here for the cross-surface story. - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure Front Door](./front-door.md) - global edge in front of APIM; pair both for a full edge-to-origin view. - [Azure Application Gateway](./application-gateway.md) - regional load balancer behind APIM in some VNet topologies. - [Azure Firewall](./azure-firewall.md) - exhibits the same Bug #45942 case-mismatch as APIM. --- ## Azure App Service Monitoring with OpenTelemetry - Requests, Health Checks & HTTP Logs ## Azure App Service Monitoring with OpenTelemetry > **Why Scout for Azure App Service observability?** > > Microsoft now emits OTel-shaped telemetry by default through the > Application Insights SDK 3.x and the Azure Monitor OpenTelemetry > Distro. Scout consumes those exact signals via OTLP and stores them > alongside your AWS, GCP, on-prem, and application telemetry in one > OTel-native query surface. > > Azure Monitor remains the data source for the control-plane metrics > in this guide - the receiver reads from it. What changes is the > destination: Scout instead of Application Insights / Log Analytics > for visualization, alerting, and long-term query. ### Overview App Service is three Azure resource types working together: the **site** (`Microsoft.Web/sites`), the **plan** that hosts it (`Microsoft.Web/serverFarms`), and an **Application Insights component** (`microsoft.insights/components`) attached for APM. End-to-end observability means signals from all three, plus the request-level detail that surface metrics cannot reach. This guide configures **two collector receivers** that together cover the control-plane and the diagnostic logs: - `azuremonitorreceiver` against the three resource-type namespaces. - `azure_event_hub` against a Diagnostic Settings → Event Hubs pipeline. The third path - application-level telemetry from inside your running app - is covered briefly here and in depth in the apps-side instrumentation guides. App Service does not have a single canonical in-system endpoint to scrape; the apps-side path is OTel SDK or AI SDK inside your code. ### Instrumentation paths for App Service The right shape depends on what your app already emits and what visibility gaps remain. Three paths exist; pick one, two, or all three based on the table below. | Path | What it covers | What it costs | Setup | | --- | --- | --- | --- | | **Platform metrics - Azure Monitor** (this guide) | Request rates and HTTP status distribution at the site; CPU / memory saturation at the plan; AI resource health. Per-site and per-plan resolution; minute-level grain. Does **not** see inside the app process. | Azure Monitor query cost: one query per metric per scrape (or one per resource with `use_batch_api: true`). At a 60s interval the daily cost runs in cents per site. | One Service Principal with `Monitoring Reader` on the resource group; one receiver block; one resource processor. | | **App-side telemetry - OTel SDK / App Insights** (cross-link) | Per-request traces, custom spans, dependency calls, exception stack traces, custom business metrics. Code-line resolution; sub-second grain. Sees inside the app process. | Telemetry ingest cost into Scout (per-record). Latency added per span: low single-digit microseconds with the SDK; ~milliseconds with an auto-instrumentation agent. | OTel SDK in the app (vendor-neutral) **or** Application Insights SDK auto-instrumentation. Both ultimately need a wire-protocol export to Scout. See the apps-side guides linked from Related Guides. | | **Resource logs - Diagnostic Settings → Event Hubs** (this guide, §Logs below) | Per-request access log (URL, status, response time, client IP, request size, response size); deploy / restart / config-change / scale audit. Per-request resolution; sub-second grain. | One Event Hubs Basic namespace (~$11/mo at 1 TU; 1 MB/s ingress absorbs ~150 requests/second of typical HTTP log records). Plus the Diagnostic Setting itself is free. | One Diagnostic Setting on the site with the categories you care about; one Event Hubs namespace + hub + Send/Listen SAS rules; one `azure_event_hub` receiver fragment. | #### Which path to pick Four decision criteria, in order of usual weight: 1. **Is your app already wired to Application Insights?** If yes, AI is the apps-side telemetry source already. Platform metrics are the **complement** that adds site- and plan-level signals, not a replacement for the apps-side data. 2. **Are you running one site per plan, or many?** Multi-site plans need both plan-level metrics (plan saturation tells you when the host runs out of CPU or memory) and per-site metrics (which app is the noisy neighbor). Single-site plans can lean on site-level alone for most alerts, with the plan as a tie-break for capacity questions. 3. **Linux or Windows runtime?** Some metrics emit differently across runtimes; `HealthCheckStatus` is Linux-only on the current API. Verify availability against your specific runtime version before pinning alerts on a runtime-conditional metric. 4. **What's your Diagnostic Settings volume budget?** `AppServiceHTTPLogs` is one record per HTTP request. At 100 req/s a site produces 360k records/hour. Event Hubs Basic 1 TU (1 MB/s) is fine up to ~4k records/sec at ~250-byte average payload; above that, move to Standard 2-20 TU or enable only a subset of categories. If you're starting from zero, platform metrics are the lowest-effort win and catch the broadest range of saturation incidents. Add resource logs when you need per-request distribution that aggregate metrics cannot give you. Add app-side telemetry when you need code-line attribution for errors and slow requests. ### What you'll monitor The receiver scrapes three Azure Monitor namespaces under one `services:` block and emits per-resource metrics under `cloud.platform: azure_app_service`. The per-record `azuremonitor.resource_id` dimension distinguishes same-named metrics across the three resource types. #### Site metrics (`Microsoft.Web/sites`) | Metric | Aggregation | What it tells you | | --- | --- | --- | | `CpuTime` | Total | CPU seconds consumed in the period. Compare against your plan's vCPU budget. | | `Requests` | Total | HTTP request count. Populates only in periods that received traffic. | | `BytesReceived` | Total | Inbound request body bytes. | | `BytesSent` | Total | Outbound response body bytes. | | `Http2xx` | Total | 2xx response count. Populates with traffic. | | `Http3xx` | Total | 3xx (redirect) response count. | | `Http4xx` | Total | 4xx (client error) response count. SLI candidate. | | `Http5xx` | Total | 5xx (server error) response count. Primary SLI. | | `HealthCheckStatus` | Average | 1 when `siteConfig.healthCheckPath` returns 200, otherwise 0. App Service probes this every minute independently of your traffic; the metric is continuous, not traffic-driven. | | `AverageResponseTime` | Average | Mean response time in seconds across requests in the period. Populates only during traffic. | | `MemoryWorkingSet` | Average | Process resident memory. Compare against the plan's RAM budget. | | `AverageMemoryWorkingSet` | Average | Time-averaged variant of the above. | **Operations footnote - `FileSystemUsage`:** The catalog exposes `FileSystemUsage` at a PT6H native grain. A receiver polling at 60s will not see it populate. If you need filesystem-usage visibility, run a second `azuremonitorreceiver` instance scoped to `FileSystemUsage` with `collection_interval: 6h` and merge its output into the same pipeline. Otherwise the App Service Plan storage quota alert in the Azure portal is the simpler path. **Catalog-available extras** (not whitelisted by default; add if you need finer breakdown): per-status-code counts (`Http101`, `Http401`, `Http403`, `Http404`, `Http406`), `HttpResponseTime` (alternative form of response time), `InstanceCount`, and per-I/O-operation counters (`IoReadBytesPerSecond`, `IoWriteBytesPerSecond`, `IoReadOperationsPerSecond`, `IoWriteOperationsPerSecond`). #### Plan metrics (`Microsoft.Web/serverFarms`) | Metric | Aggregation | What it tells you | | --- | --- | --- | | `CpuPercentage` | Average, Maximum | Plan vCPU saturation. Headline plan SLI. | | `MemoryPercentage` | Average, Maximum | Plan RAM saturation. Pairs with the above for capacity decisions. | | `DiskQueueLength` | Average | Disk request queue depth. Non-zero values indicate I/O contention. | | `HttpQueueLength` | Average | HTTP request queue depth. Non-zero values indicate the worker is saturated. | | `BytesReceived` | Total | Aggregate inbound bytes across all sites on the plan. | | `BytesSent` | Total | Aggregate outbound bytes across all sites on the plan. | | `TcpSynSent` | Average | Outbound TCP SYNs - new connection attempts. | | `TcpEstablished` | Average | Established outbound TCP connections. Persistent connection count. | All plan metrics populate continuously, even at idle, because the host worker reports them on a 60s heartbeat independent of HTTP traffic. **Catalog-available extras**: detailed TCP state breakdown (`TcpSynReceived`, `TcpFinWait1`, `TcpFinWait2`, `TcpClosing`, `TcpCloseWait`, `TcpLastAck`, `TcpTimeWait`) and socket-level counts (`SocketInboundAll`, `SocketOutboundAll`, `SocketOutboundEstablished`, `SocketOutboundTimeWait`, `SocketLoopback`). #### Application Insights *resource* metrics (`microsoft.insights/components`) > **These are APM-derived, not resource-health.** The metrics in this > namespace are aggregated from log records your app pushes to the > linked Log Analytics workspace via the Application Insights SDK. They > populate when your app is instrumented with the AI SDK using the > connection string you wired into `APPLICATIONINSIGHTS_CONNECTION_STRING`. > If your app emits OTel telemetry directly to Scout instead (the > app-side telemetry path above), **these metrics will be empty - that > is expected and not a misconfiguration.** Treat this sub-table as the > AI-SDK escape hatch for teams not yet ready to cut over to direct > OTel. | Metric | Aggregation | What it tells you | | --- | --- | --- | | `availabilityResults/availabilityPercentage` | Average | Percentage of AI Availability Tests passing. Requires availability tests configured on the AI resource. | | `requests/duration` | Average | Mean request duration as observed by the AI SDK in your app. | | `performanceCounters/processCpuPercentage` | Average | CPU consumed by the app process as reported by the AI SDK. | | `dependencies/duration` | Average | Outbound dependency call duration (HTTP / SQL / queue) as the AI SDK sees them. | | `exceptions/count` | Count | Application exception count as the AI SDK observes them. | **Catalog-available extras** (named here for completeness; the AI metrics namespace is rich): per-request counts and rates (`requests/count`, `requests/failed`, `requests/rate`), dependency detail (`dependencies/count`, `dependencies/failed`), performance counters (`performanceCounters/requestExecutionTime`, `requestsInQueue`, `requestsPerSecond`, `exceptionsPerSecond`, `processIOBytesPerSecond`, `processorCpuPercentage`, `memoryAvailableBytes`, `processPrivateBytes`), exceptions split (`exceptions/browser`, `exceptions/server`), availability detail (`availabilityResults/count`, `availabilityResults/duration`), `traces/count`, page-view metrics (`pageViews/count`, `pageViews/duration`), and browser timings (`browserTimings/networkDuration`, `processingDuration`, `receiveDuration`, `sendDuration`, `totalDuration`). ### Prerequisites | Requirement | Detail | | --- | --- | | App Service Plan SKU | Basic B1 or higher. Free F1 and Shared D1 do not support Diagnostic Settings to Event Hubs. | | Application Insights | Workspace-based (modern). Classic AI was retired Feb 2024. | | OTel Collector Contrib | v0.151+ (the `azure_monitor` and `azure_event_hub` receiver names are snake_case from v0.148.0; v0.151.0 is the current fleet). | | OpenTelemetry semconv | v1.41.0 (latest cloud and HTTP attributes). | | Azure CLI | 2.85+ for the `az monitor diagnostic-settings` flags used here. | | Azure providers registered | `Microsoft.Web`, `Microsoft.OperationalInsights`, `Microsoft.Insights`, `Microsoft.EventHub`. | | Collector runtime | See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) or [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for the runtime; this guide adds the App Service-specific receiver + processor blocks on top. | | Scout exporter | See [Scout exporter wiring](../../collector-setup/scout-exporter.md) for the `oauth2client` extension + `otlp_http/b14` exporter. This guide does not re-derive that block. | ### Access setup The receiver authenticates via a Service Principal scoped per resource group. Two role assignments are needed: | Role | Scope | Reason | | --- | --- | --- | | `Monitoring Reader` | Resource group containing the site + plan + AI | Lets the receiver list metric definitions and read metric values for all three namespaces. | | `Azure Event Hubs Data Receiver` | Event Hubs namespace (logs path only) | Lets the receiver consume the diagnostic event hub. Granted by the SAS rule's Listen permission via the connection string; if you use Azure AD auth instead, grant the role on the namespace. | If you are reusing an operator-permanent SP across many surfaces, both assignments are idempotent - re-running them on a previously granted SP is a no-op. Both roles propagate independently. The metrics path may flow before the logs path receives its first record, or vice versa. Smoke-test both on first run (a one-shot `az monitor metrics list` call against the site and an `az eventhubs eventhub consumer-group show` for the hub will fail-fast if RBAC has not propagated yet). ### Receiver configuration Add the following to your collector config alongside whatever is already wiring `azure_auth` and the Scout exporter. **You do not need to duplicate** the `oauth2client` extension or the `otlp_http/b14` exporter; those live in the shared base config per [Scout exporter wiring](../../collector-setup/scout-exporter.md). ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_monitor/appservice: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:APPSERVICE_RESOURCE_GROUP} services: - Microsoft.Web/sites - Microsoft.Web/serverFarms - microsoft.insights/components auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Web/sites": CpuTime: [Total] Requests: [Total] BytesReceived: [Total] BytesSent: [Total] Http2xx: [Total] Http3xx: [Total] Http4xx: [Total] Http5xx: [Total] HealthCheckStatus: [Average] AverageResponseTime: [Average] MemoryWorkingSet: [Average] AverageMemoryWorkingSet: [Average] "Microsoft.Web/serverFarms": CpuPercentage: [Average, Maximum] MemoryPercentage: [Average, Maximum] DiskQueueLength: [Average] HttpQueueLength: [Average] BytesReceived: [Total] BytesSent: [Total] TcpSynSent: [Average] TcpEstablished: [Average] "microsoft.insights/components": availabilityResults/availabilityPercentage: [Average] requests/duration: [Average] performanceCounters/processCpuPercentage: [Average] dependencies/duration: [Average] exceptions/count: [Count] processors: resource/appservice: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_app_service, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:APPSERVICE_REGION}", action: insert} # cloud.resource_id deliberately omitted - the bundle holds 3 distinct # resources (site + plan + AI). Per-record `azuremonitor.resource_id` # metric dimension splits same-named metrics across resources. - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:APPSERVICE_SERVICE_NAME}", action: insert} service: pipelines: metrics/appservice: receivers: [azure_monitor/appservice] processors: [memory_limiter, resource/appservice, batch] exporters: [otlp_http/b14] ``` **Why no `cloud.resource_id` resource attribute:** the bundle covers three distinct Azure resources (site + plan + AI). Pinning a single `cloud.resource_id` would clobber the per-record split that the receiver emits as the `azuremonitor.resource_id` metric dimension. Same-named metrics across the three resource types (`BytesReceived` on sites AND serverFarms, for example) stay distinct via that dimension; filter and group in Scout by `azuremonitor.resource_id` to split by resource. ### Environment variables ```bash title=".env" AZURE_SUBSCRIPTION_ID=... APPSERVICE_RESOURCE_GROUP=... # RG containing site + plan + AI APPSERVICE_REGION=... # for cloud.region; defaults to the RG region APPSERVICE_SERVICE_NAME=app-service-monitor ENVIRONMENT=production ``` Service Principal credentials (`AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET`) and Scout exporter credentials (`SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, `SCOUT_TOKEN_URL`, `SCOUT_OTLP_ENDPOINT`) come from the shared base config and are not listed here. See [Scout exporter wiring](../../collector-setup/scout-exporter.md). ### Operations #### RBAC propagation lag `Monitoring Reader` on the resource group typically propagates in under 30 seconds, occasionally up to 120 seconds. The first scrape after a fresh role assignment may return `403 AuthorizationFailed`. The receiver retries on the next 60s cycle; the noise clears within two polls. #### Diagnostic Settings ship cadence Resource-scope Diagnostic Settings first-batch ship lag commonly runs longer than Azure's documented 5-15 minute window on first attach. Budget at least **15 minutes** before treating an empty Event Hubs partition as a failure. Steady-state batches arrive every 1-3 minutes once the pipeline is warm. #### `HealthCheckStatus` depends on path config `HealthCheckStatus` emits only when `siteConfig.healthCheckPath` is set and the path returns HTTP 200. If the path returns 404 (default for an app that does not implement a health endpoint), the metric reads zero or no data. Configure the path explicitly: ```bash title="configure healthCheckPath" az webapp update \ --resource-group \ --name \ --set siteConfig.healthCheckPath=/healthz ``` Verify with `curl https://.azurewebsites.net/healthz` returning 200 before relying on the metric. #### Application Insights metrics are empty until your app pushes to AI This is the single biggest source of "why is half my dashboard empty" tickets. The microsoft.insights/components metric namespace is **not** populated by Azure - it is populated by your app emitting AI SDK telemetry that lands in the linked Log Analytics workspace. If your app emits OTel directly to Scout, the AI-namespace metrics show no data. That is correct. Either: - Treat the AI sub-table as documentation of what's available **if** you wire your app to the AI SDK. - Disable AI metrics in the receiver by removing the `microsoft.insights/components` entry from `services:` and `metrics:`. - Wire both: keep direct OTel as the primary path, enable the AI SDK for the AI-resource-derived metrics, accept the duplication cost. #### `FileSystemUsage` is hourly-grain only See the Operations footnote in the Site metrics table above. `FileSystemUsage` is the canonical PT6H-grain metric that fails to emit under a 60-second receiver. Use a separate slow-poll receiver instance or skip it. #### `AppServiceHTTPLogs` volume scaling `AppServiceHTTPLogs` emits one record per HTTP request. At 100 req/s a site produces 360,000 records/hour. Event Hubs Basic 1 TU absorbs roughly 4,000 records/second at ~250-byte average payload; busier sites need Event Hubs Standard (2-20 TU) or a subset of categories. #### Bicep `httpLoggingEnabled` reliability on Linux `AppServiceHTTPLogs` requires HTTP file-system logging enabled on the site. The Bicep `siteConfig.httpLoggingEnabled: true` property declares the intent, but on some Linux runtime versions the property does not get applied at deploy time. Re-assert post-deploy via `az`: ```bash title="enable HTTP file-system logging" az webapp log config \ --resource-group \ --name \ --web-server-logging filesystem ``` The CLI command is idempotent, so making it part of every deploy script is safe. If your records arrive in Event Hubs but `AppServiceHTTPLogs` records are missing while `AppServicePlatformLogs` flow normally, this is the most likely cause. #### Why two role assignments The metrics path needs `Monitoring Reader` on the resource group because the receiver enumerates resources within the RG and reads their metrics. The logs path needs `Azure Event Hubs Data Receiver` on the Event Hubs namespace because the `azure_event_hub` receiver consumes from the hub. The two roles are scoped to different resources and propagate independently; smoke-test both on first attach. ### Key alerts to configure Once metrics are flowing, set up alerts on these thresholds. The "Why" column gives the reasoning so you can adjust the thresholds for your traffic shape. | Signal | Warning | Critical | Why | | --- | --- | --- | --- | | `Http5xx` rate (1 min) | > 1% of `Requests` | > 5% of `Requests` | Server-side error rate; the primary SLI for App Service. 1% sustained suggests a broken release or upstream outage. | | `Http4xx` rate (1 min) | > 5% of `Requests` | > 20% of `Requests` | Client-error spikes indicate broken integrations, auth misconfiguration, or scanning traffic. | | `AverageResponseTime` (5 min) | > 1.5× rolling 24h mean | > 3× rolling 24h mean | Latency regression detector. Use a relative threshold rather than an absolute number so the alert tracks normal site behaviour. | | `HealthCheckStatus` (3 consecutive minutes) | < 1 on any instance | < 1 across all instances | Health probe failing on one instance is degraded; failing across all instances is an outage. App Service evaluates this every 60 s. | | `CpuPercentage` on the plan (5 min) | > 75% Average | > 90% Average | Plan saturation; sites on this plan will start to queue. | | `MemoryPercentage` on the plan (5 min) | > 80% Average | > 90% Average | Plan RAM pressure; risk of OOMKill on Linux containers above 95%. | | `HttpQueueLength` on the plan (3 min) | > 5 Average | > 20 Average | The plan worker is saturated; requests are queuing. Co-fires with CpuPercentage in most cases. | | `Requests` drop on the site (10 min) | < 50% of rolling 1h mean | < 10% of rolling 1h mean | Sudden traffic drop on a site that normally serves traffic indicates upstream (Front Door / Application Gateway) or DNS failure. | Configure the Scout-side alert rules through your dashboarding / alerting stack once thresholds are decided; the receiver pipeline above emits the underlying signals continuously. ### Logs App Service publishes a rich set of Diagnostic Settings categories that fill gaps the metric whitelist cannot. The §Logs path uses the `azure_event_hub` receiver against a Diagnostic Settings → Event Hubs sink. #### What logs uniquely fill Platform metrics aggregate. Logs disaggregate. The gaps logs uniquely cover for App Service: - **Per-request distribution**: URL × method × status code × client IP × response time × user agent. The metric whitelist gives you `Http5xx` count per minute; the access log gives you *which* requests failed and *from where*. - **Per-IP audit and rate**: ranking client IPs by request volume, correlating IP with 4xx burst signatures, detecting credential scans. No metric exposes this. - **Per-deployment-slot attribution**: deployment slot swaps emit their own metric series. Logs show **which** slot received which request, which deployment caused which restart, and the ordering of config changes across deploys. - **Per-instance source identification**: when a site scales to multiple instances (B1 supports manual scale to 3 workers), logs surface the originating instance ID so you can correlate a 5xx burst with one bad worker. #### Architecture ```text App Service site │ │ Diagnostic Setting (resource scope) │ categories: AppServiceHTTPLogs + AppServicePlatformLogs (default) ↓ Event Hubs namespace (Basic 1 TU) │ • diagsend SAS rule (Send) writes records │ • collectorlisten SAS rule (Listen) reads records ↓ azure_event_hub receiver │ • format: azure │ • apply_semantic_conventions: true │ • cloud.resource_id lifted from the per-record envelope ↓ otlp_http/b14 → Scout ``` The Diagnostic Setting targets the **site** resource directly. The plan and the AI component each have their own Diagnostic Settings categories; this guide enables only the site's. Adapt the pattern for the plan or AI if you need their event categories. #### Categories enabled by default | Category | What it covers | | --- | --- | | `AppServiceHTTPLogs` | Per-request access log: URL, method, status, response time, client IP, request size, response size, user agent. Volume scales with traffic. Requires HTTP file-system logging enabled on the site — see Operations → "Bicep `httpLoggingEnabled` reliability on Linux". | | `AppServicePlatformLogs` | Deploy / restart / config-change / scale audit. Per-operation control-plane events at site scope. Low volume. | **Health-probe records dominate low-traffic sites.** App Service's own health-check probe emits one `AppServiceHTTPLogs` record every 60 seconds at the configured `healthCheckPath`. On a site receiving fewer than 1 req/sec from real users, most records in the stream are the health probe. When you investigate the log stream and see only one URL pattern, filter by `userAgent != 'HealthCheck/1.0'` (or the actual probe UA observed in your records) to see real-traffic requests; otherwise the probe noise drowns out the signal. #### Optional categories Named here so you know they exist; enable per workload: - **`AppServiceConsoleLogs`** - stdout/stderr from the app process. Usually redundant with apps-side OTel logs; enable if your app does not yet emit OTel. - **`AppServiceAppLogs`** - app-emitted log records via App Service's logging API. Redundant with apps-side OTel; enable as a transition aid. - **`AppServiceAuditLogs`** - SCM / Kudu deployment authentication. Security-team scope; enable when you need audit trails for deploys. - **`AppServiceIPSecAuditLogs`** - hits against the site's IP restriction rules. Enable if you have IP allowlists and want forensics on blocked traffic. - **`AppServiceFileAuditLogs`** - file-system change audit. Premium V2/V3 and Isolated tier only; ignore on Basic / Standard. #### Receiver configuration (logs) ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_event_hub/appservicelogs: connection: ${env:APPSERVICELOGS_CONNECTION_STRING} partition: "" # resume across all partitions offset: "" # resume from last checkpoint format: azure # decode Azure resource-log envelope apply_semantic_conventions: true processors: resource/appservicelogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_app_service, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:APPSERVICELOGS_SOURCE_REGION}", action: insert} # cloud.resource_id is NOT pinned - the receiver lifts the per-record # Azure resource ID to this attribute automatically (UPPERCASED). - {key: deployment.environment.name, value: "${env:APPSERVICELOGS_ENVIRONMENT}", action: insert} - {key: environment, value: "${env:APPSERVICELOGS_ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:APPSERVICELOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/appservicelogs: receivers: [azure_event_hub/appservicelogs] processors: [memory_limiter, resource/appservicelogs, batch] exporters: [otlp_http/b14] ``` On first run with no stored checkpoint, the receiver starts from the earliest available record in the hub's retention window (1 day on Basic). On collector restart the receiver resumes from its last checkpoint, so an idle window during deployment does not lose records that arrived in the meantime. The `APPSERVICELOGS_CONNECTION_STRING` value is the Listen-permission SAS connection string for the namespace, **with `;EntityPath=` appended** so the receiver knows which hub to consume from. Fetch it once via: ```bash title="fetch the Listen connection string" az rest --method post \ --url "https://management.azure.com${COLLECTOR_LISTEN_RULE_ID}/listKeys?api-version=2024-01-01" \ --query primaryConnectionString -o tsv ``` Then append `;EntityPath=` and store the result in your collector's env file. #### Environment variables (logs) ```bash title=".env (logs path)" APPSERVICELOGS_CONNECTION_STRING=... # Listen SAS with ;EntityPath= APPSERVICELOGS_SOURCE_REGION=... # for cloud.region on log records APPSERVICELOGS_SERVICE_NAME=app-service-logs APPSERVICELOGS_ENVIRONMENT=production ``` Service Principal credentials and Scout exporter credentials are inherited from the shared base config as for the metrics path. #### Wiring the Diagnostic Setting ```bash title="attach the Diagnostic Setting" az monitor diagnostic-settings create \ --resource "" \ --name appservice-logs \ --event-hub \ --event-hub-rule "" \ --logs '[{"category":"AppServiceHTTPLogs","enabled":true}, {"category":"AppServicePlatformLogs","enabled":true}]' ``` The `--event-hub-rule` value is the resource ID of the namespace-scoped SAS rule with `Send` permission. The receiver uses a separate Listen rule; one Send rule and one Listen rule on the namespace is the canonical two-rule topology. #### Verifying the logs path After the Diagnostic Setting is attached and the site has served at least one request: 1. Wait 15 minutes for the first batch (resource-scope Diagnostic Settings first-batch lag). 2. Tail the collector debug exporter: `docker compose logs -f otel-collector | grep "otelcol.signal.*logs"`. 3. Expect batches of 10-30 log records every 60-90 seconds at low traffic; busier sites batch larger. 4. In Scout, filter `service.name = 'app-service-logs'` and group by `azure.category` to confirm both enabled categories populate. ### Troubleshooting #### `AuthorizationFailed` on the first scrape **Cause:** The `Monitoring Reader` role assignment on the resource group has not yet propagated. **Fix:** Wait two polling cycles (~2 minutes). The receiver retries automatically; the error self-clears. #### Scraper exits early with `service principal credentials missing` **Cause:** The collector container did not receive `AZURE_TENANT_ID` / `AZURE_CLIENT_ID` / `AZURE_CLIENT_SECRET`. **Fix:** Check your env file is sourced into the collector's environment and that the `azure_auth` extension references the variables exactly. The shared base config wires this; if you forked it, re-verify the extension block. #### Metric data points emit but values are all zero **Cause for the AI namespace:** This is the expected behaviour when the app does not push to Application Insights. See **Operations → Application Insights metrics are empty until your app pushes to AI** above. **Cause for site / plan metrics:** Check that the receiver and the Scout pipeline are filtering or processing values correctly. The `batch` processor truncates points only at the size cap (1024 by default); the `memory_limiter` drops points only under memory pressure. Neither should turn populated points into zero values. #### `HealthCheckStatus` reads no data despite a configured site **Cause:** The configured `healthCheckPath` returns a non-200 status. **Fix:** `curl https://.azurewebsites.net/`. If the response is 404, your app does not implement the path - either add a matching route to your app or change the configured path. #### First Event Hubs batch is empty after 20 minutes **Cause:** The Diagnostic Setting attached but the site has not yet served a matching event in the enabled categories. **Fix:** For `AppServiceHTTPLogs`, drive a single HTTP request against any route on the site. For `AppServicePlatformLogs`, trigger a config change (`az webapp config set --generic-configurations '{}'` is a no-op that emits a platform event). Then re-tail the collector debug logs. #### `azure_event_hub` receiver logs `MessagingGatewayBadRequest` **Cause:** The receiver is requesting a user-defined consumer group that does not exist on Event Hubs Basic. **Fix:** Basic tier rejects user-defined consumer groups - the receiver must consume from `$Default`, the implicit group. Remove any `consumer_group:` key from the receiver config or upgrade the namespace to Standard if you need multiple consumer groups. #### Logs path stops mid-run with no errors **Cause:** A Listen-SAS-key rotation or namespace deletion invalidated the connection string. **Fix:** Re-fetch the Listen connection string via `az rest --method post ... /listKeys` and reload the receiver. ### Frequently Asked Questions #### How do I monitor Azure App Service with OpenTelemetry? Three instrumentation paths complement each other. Platform metrics use `azure_monitor` against `Microsoft.Web/sites`, `Microsoft.Web/serverFarms`, and `microsoft.insights/components`. App-side telemetry is your app emitting OTel directly via the SDK, or Application Insights auto-instrumentation. Resource logs are `azure_event_hub` consuming Diagnostic Settings categories `AppServiceHTTPLogs` and `AppServicePlatformLogs`. Pick the paths based on what your app is wired to and what your debug-depth appetite is. #### What's the smallest App Service Plan that supports Diagnostic Settings? Basic B1 is the smallest tier that supports forwarding Diagnostic Settings to Event Hubs. Free F1 and Shared D1 reject Event Hubs as a Diagnostic Settings destination. B1 still supports HTTP file-system logging and all per-site metrics. #### Why are my Application Insights metrics empty in Scout? The `microsoft.insights/components` metric namespace exposes APM signals derived from log records your app pushes to Application Insights via the SDK. If your app emits OTel directly to Scout instead, these metrics will be empty. That is expected. Configure the AI connection string only if you want both AI-derived metrics and your direct OTel pipeline to coexist. #### What's the first-batch ship lag for App Service Diagnostic Settings? Resource-scope Diagnostic Settings on App Service ship the first batch 5 to 15 minutes after the setting is attached and the site emits its first matching event. Steady-state batches arrive every 1 to 3 minutes after that. Budget at least 15 minutes before treating an empty Event Hubs partition as a failure. #### Does HealthCheckStatus emit without a configured health path? No. App Service evaluates the health-check path you configure on the site every minute. If the path returns a non-200 response or is not configured, `HealthCheckStatus` reads zero or no data. Set `siteConfig.healthCheckPath` to a route your app actually serves, and verify with a `curl` probe before treating the metric as broken. #### Why does FileSystemUsage show no data at a 60-second collection interval? `FileSystemUsage` emits at a 6-hour grain on the Azure Monitor catalog. A receiver polling at 60 seconds will not see it populate. Either run a second `azuremonitorreceiver` instance at PT6H interval scoped to `FileSystemUsage`, or drop the metric from the whitelist and rely on quota alerts in the Azure portal instead. ### Related Guides #### Shared collector + Scout wiring - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - the runtime that hosts both receivers in this guide. - [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - alternative runtime for AKS-hosted collectors. - [Scout exporter wiring](../../collector-setup/scout-exporter.md) - the `oauth2client` extension + `otlp_http/b14` exporter block shared by all Azure guides. #### Apps-side instrumentation - [.NET Aspire](../../apps/auto-instrumentation/dotnet-aspire.md) - the canonical Microsoft path for new .NET apps. Emits OTel by default. - [OpenTelemetry .NET SDK](../../apps/auto-instrumentation/dotnet.md) - direct OTel for existing .NET apps not on Aspire. - For Python / Node / Java apps, use the OTel SDK for your language ([FastAPI](../../apps/auto-instrumentation/fast-api.md), [Express](../../apps/auto-instrumentation/express.md), [Spring Boot](../../apps/auto-instrumentation/spring-boot.md)) and point the OTLP exporter at Scout's collector. #### Adjacent Azure surfaces - [Azure Compute](./compute.md) - VMs, VM Scale Sets, and Managed Disks for the host layer beneath unmanaged or AKS workloads. - [Azure Front Door](./front-door.md) and [Azure Application Gateway](./application-gateway.md) - the edge layers in front of App Service. - [Azure SQL Database](./sql-database.md) and [Azure Cache for Redis](./cache-for-redis.md) - common data-tier dependencies. - [Azure Key Vault](./key-vault.md) - secrets store typically referenced from `APPLICATIONINSIGHTS_CONNECTION_STRING` and other app settings. --- ## Azure Application Gateway Monitoring with OpenTelemetry - Production Wiring for SREs ### Overview This guide is for engineers running **Azure Application Gateway Standard_v2** in production who want to add gateway telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API every 60 seconds for `Microsoft.Network/applicationGateways` metrics, transforms them to OTel-style names, and exports via OTLP/HTTP. The collector never touches Application Gateway's data plane. The receiver does not connect to Application Gateway directly. It queries Azure Monitor for any gateway your subscription auto-publishes to, so the same configuration covers Standard_v2 and WAF_v2 across any number of listeners, backend pools, and rules per gateway. Standard_v1 is deprecated and not covered. This guide is metrics-only. For Application Gateway access logs, firewall logs (WAF_v2), and health-probe logs, see [Logs](#logs). ### Front Door vs Application Gateway The two surfaces are sometimes confused because both are HTTP-aware fronts. Different scopes, different metrics: | Surface | Scope | Metric framing | | --- | --- | --- | | [**Azure Front Door**](./front-door.md) (`Microsoft.Cdn/profiles`) | Global CDN + edge | Per-edge: `RequestCount` × `ClientCountry`, `TotalLatency` (edge-to-client), `ByteHitRatio`, `OriginHealthPercentage`. | | **Azure Application Gateway** (this guide) | Regional L7 load balancer | Per-backend / per-listener: `HealthyHostCount` × `BackendSettingsPool`, `ApplicationGatewayTotalTime` × `Listener`, `BackendResponseStatus` × `BackendServer` × `HttpStatusGroup`. | Customers running both - global edge in front of regional backend selection - should monitor both surfaces. The receiver fragments coexist in a single collector; one Scout exporter serves every Azure surface. ### SKU choice | SKU | Covered by this guide | Notes | | --- | --- | --- | | Standard_v2 | yes | Default for new deployments. 17 metrics in the whitelist below. | | WAF_v2 | yes (extend the whitelist) | Adds Azwaf* metric family for matched-rule counts, mode, bot protection, and rate limiting. Listed in [WAF_v2 additions](#waf_v2-additions). | | Standard_v1 | no | Deprecated. Microsoft retired the v1 SKU for new deployments; use v2. | The remainder of this guide assumes Standard_v2 unless otherwise stated. ### Receiver configuration Add this fragment to your existing collector config. It contributes the `azure_auth` extension, an `azure_monitor` receiver, a resource processor, and a metrics pipeline. Component keys are suffixed `/applicationgateway` so the fragment composes cleanly with other Azure-surface receivers in the same collector. ```yaml showLineNumbers title="otel-collector.yaml (Application Gateway addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Authentication section below for the right choice per # collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/applicationgateway: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} # Add more entries to scrape gateways across multiple subscriptions # in one collector. Each subscription needs its own Monitoring Reader # role assignment on the configured identity; the receiver fans out # queries across all subscription x resource-group combinations. resource_groups: - ${env:APPGATEWAY_RESOURCE_GROUP} # Multi-resource-group scoping. Omit resource_groups entirely to # scrape every resource group in the listed subscriptions. services: - Microsoft.Network/applicationGateways auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Metrics Data Plane (metrics:getBatch). Raises the per-subscription # ceiling from 12k to 360k calls/hour and batches up to 50 resources # per call - the only setting that survives a real fleet. RBAC # propagates 5-30 min after the Monitoring Reader grant; flip to false # as a temporary fallback to the legacy ARM /metrics endpoint if you # see persistent 401s after that window. See Scale and rate limits. use_batch_api: true # Resource-list cache TTL in seconds. Receiver default is 86400 (24h); # the right setting for a stable fleet. Lower (e.g. 3600 or 600) only # if gateways are added or removed frequently. cache_resources: 86400 dimensions: enabled: true # Per-metric aggregations matching MS-documented defaults. Empty `[]` # requests all five aggregations Azure Monitor publishes for the # metric, which can cause rate-limit pressure on high-fanout fleets; # explicit single aggregations keep cardinality predictable. metrics: "Microsoft.Network/applicationGateways": # Traffic + latency Throughput: [average] TotalRequests: [total] FailedRequests: [total] ResponseStatus: [total] BytesReceived: [total] BytesSent: [total] ApplicationGatewayTotalTime: [average] # Backend health + per-backend response shape HealthyHostCount: [average] UnhealthyHostCount: [average] BackendResponseStatus: [total] BackendConnectTime: [average] BackendFirstByteResponseTime: [average] BackendLastByteResponseTime: [average] AvgRequestCountPerHealthyHost: [average] # Capacity + saturation (Standard_v2 autoscale signals) CapacityUnits: [average] ComputeUnits: [average] CurrentConnections: [total] processors: resource/applicationgateway: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_application_gateway, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:APPGATEWAY_REGION}", action: insert} # cloud.resource_id pins all metrics to one gateway. Drop this line # for multi-gateway fleets; the receiver injects azuremonitor.resource_id # per-resource automatically. - {key: cloud.resource_id, value: "${env:APPGATEWAY_RESOURCE_ID}", action: insert} - {key: deployment.environment.name, value: "${env:DEPLOYMENT_ENVIRONMENT}", action: insert} - {key: environment, value: "${env:DEPLOYMENT_ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:APPGATEWAY_SERVICE_NAME}", action: insert} service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/applicationgateway: receivers: [azure_monitor/applicationgateway] processors: [resource/applicationgateway, batch] # plus your existing processors exporters: [otlphttp/b14] # your Scout exporter ``` The receiver, resource processor, and pipeline are all keyed `/applicationgateway` so they coexist with other Azure receivers (Front Door, Service Bus, Cosmos DB, SQL Database, Storage) in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, the `subscription_ids:` list takes any number of entries; alternatively set `discover_subscriptions: true` to scrape every subscription the configured identity has `Monitoring Reader` on. See [Scale and rate limits](#scale-and-rate-limits). ### Authentication `azure_auth` supports four modes. Pick the one matching where the collector runs. | Collector deployment | Recommended mode | Why | | --- | --- | --- | | Azure Kubernetes Service (AKS) pod | `workload_identity` | Federated credential, no secret to rotate, scoped to the ServiceAccount. | | Container Apps | `managed_identity` (system or user-assigned) | First-class integration, no secret to rotate. | | Virtual Machine Scale Sets / Azure VM | `managed_identity` (user-assigned) | User-assigned identity survives instance replacement; the system-assigned identity dies with the VM or scale-set instance. | | External or on-prem | `service_principal` | Only option without an Azure-resident identity. | | Local dev / ad-hoc | `use_default: true` | Falls back to the Azure SDK default credential chain (CLI, env, managed identity). | The auth setup, RBAC scope, and credential-rotation guidance is identical across the Azure surfaces. See the Service Bus guide's [Authentication](./service-bus.md#authentication) section for the mode-by-mode YAML and the [Service principal credential lifecycle](./service-bus.md#service-principal-credential-lifecycle) section for rotation procedures. `Monitoring Reader` at the resource group containing your gateways is sufficient and minimal. The role grants read on metric definitions and metric data only, no control-plane write. `Reader` is not required. ```bash RG_ID=$(az group show --name --query id -o tsv) az role assignment create \ --assignee \ --role "Monitoring Reader" \ --scope "$RG_ID" ``` For multi-subscription fleets, repeat per subscription. RBAC propagation on the legacy ARM `/metrics` endpoint is immediate; the data-plane batch API at `*.metrics.monitor.azure.com` lags 5-30 minutes after grant. This guide defaults `use_batch_api: true`; if the data plane is still 401-ing past that window, flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint (RBAC there is immediate). ### What you'll monitor Seventeen metrics from `Microsoft.Network/applicationGateways`. The receiver renames them from Azure's PascalCase (e.g. `ApplicationGatewayTotalTime`) to OTel-style `azure__` (e.g. `azure_applicationgatewaytotaltime_average`). Every metric is whitelisted with its single MS-documented default aggregation. Empty `[]` (= all five aggregations) doubles or triples cardinality without adding signal: `_count` and `_total` on a duration metric are sums of latency values themselves and have no physical meaning; `_total` on a gauge-style metric (`HealthyHostCount`, `CapacityUnits`) is a sum of point-in-time samples and is similarly meaningless. | Azure REST name | OTel emitted | Unit | Splits by | What it tells you | | --- | --- | --- | --- | --- | | `Throughput` | `azure_throughput_average` | BytesPerSecond | (none) | Bytes-per-second the gateway is moving end-to-end. Capacity-utilization signal. | | `TotalRequests` | `azure_totalrequests_total` | Count | `BackendSettingsPool` | Successful requests served per minute, split by the backend-pool + HTTP-setting combination. | | `FailedRequests` | `azure_failedrequests_total` | Count | `BackendSettingsPool` | Requests the gateway could not satisfy (no healthy backend, timeout, etc.). Sustained > 0 is a page. | | `ResponseStatus` | `azure_responsestatus_total` | Count | `HttpStatusGroup` | Per-status-class response counts (`2XX` / `3XX` / `4XX` / `5XX`). Pair with `BackendResponseStatus` to attribute 5XX to gateway vs origin. | | `BytesReceived` | `azure_bytesreceived_total` | Bytes | `Listener` | Client → gateway bytes, per listener. Useful for ingress-traffic dashboards. | | `BytesSent` | `azure_bytessent_total` | Bytes | `Listener` | Gateway → client bytes, per listener. Pair with `BytesReceived` for response-size sanity. | | `ApplicationGatewayTotalTime` | `azure_applicationgatewaytotaltime_average` | MilliSeconds | `Listener` | End-to-end latency from gateway-receives-first-byte to gateway-finishes-sending-response. The user-perceived number; primary SLO metric. | | `HealthyHostCount` | `azure_healthyhostcount_average` | Count | `BackendSettingsPool` | Number of backend hosts passing the health probe. Below your steady-state count means a backend is failing the probe. | | `UnhealthyHostCount` | `azure_unhealthyhostcount_average` | Count | `BackendSettingsPool` | Inverse of `HealthyHostCount`. > 0 = at least one backend failing the probe. | | `BackendResponseStatus` | `azure_backendresponsestatus_total` | Count | `BackendServer` × `BackendPool` × `BackendHttpSetting` × `HttpStatusGroup` | Per-backend status code distribution. The most useful 5XX-triage metric: which backend is returning errors? | | `BackendConnectTime` | `azure_backendconnecttime_average` | MilliSeconds | `BackendServer` × `BackendPool` × `BackendHttpSetting` × `Listener` | Time to establish a connection with a backend. Slow values point at network or TLS-handshake issues. | | `BackendFirstByteResponseTime` | `azure_backendfirstbyteresponsetime_average` | MilliSeconds | (same as `BackendConnectTime`) | Time-to-first-byte from the backend, approximates backend processing time. | | `BackendLastByteResponseTime` | `azure_backendlastbyteresponsetime_average` | MilliSeconds | (same as `BackendConnectTime`) | Time-to-last-byte from the backend. Subtract `BackendFirstByteResponseTime` for response-streaming time. | | `AvgRequestCountPerHealthyHost` | `azure_avgrequestcountperhealthyhost_average` | Count | `BackendSettingsPool` | Per-minute load each healthy backend host is carrying. Useful when one backend in a pool starts showing latency spikes - confirms the load was even. | | `CapacityUnits` | `azure_capacityunits_average` | Count | (none) | Gateway-side compute units consumed. Standard_v2 charges per CU/hour; this is the line-item driver. | | `ComputeUnits` | `azure_computeunits_average` | Count | (none) | Internal CPU+memory metric used by the autoscaler. Stays close to `CapacityUnits` under steady load. | | `CurrentConnections` | `azure_currentconnections_total` | Count | (none) | Active TCP connections to the gateway. Sudden spikes can indicate a misbehaving client opening connections in a loop. | `metadata_*` dimensions ride alongside every metric: `metadata_Listener`, `metadata_BackendSettingsPool`, `metadata_BackendServer`, `metadata_BackendPool`, `metadata_BackendHttpSetting`, `metadata_HttpStatusGroup`. Receiver-injected attributes also appear: `azuremonitor.resource_id`, `azuremonitor.subscription_id`, `name`, `type`, `resource_group`, `location`. These are the most useful axes for Scout dashboards (per-listener latency, per-backend error rate, per-status-group response counts). #### Lazy-published metrics Azure Monitor publishes definitions for some metrics only after the underlying condition first occurs. On a brand-new gateway with no history, the receiver typically reports `metrics_definitions_count: 8-9` of the 17 whitelisted entries. The remainder appear once Azure has data points to back them: `BackendResponseStatus` per `HttpStatusGroup` after the first non-2XX response, `UnhealthyHostCount` after the first probe failure, the `Backend*Time` family after the first backend hit, etc. Production gateways with weeks of mixed traffic surface the full set immediately. The whitelist intentionally keeps all 17 so they start emitting automatically once Azure publishes their definitions. **Receiver caches the definitions list per container lifetime**: when Azure begins publishing a definition mid-run (e.g., the first 502 generates `BackendResponseStatus` per `5XX`), a long-running collector continues emitting only what it cached at startup until the cache TTL expires or the collector restarts. If you expect a metric to appear after a known condition and it does not within 30 minutes, restart the collector - the next discovery cycle picks up the fresh definition list. `CpuUtilization` from the MS metric reference is *not* in the whitelist. Azure Monitor does not publish a metric definition for it on Standard_v2 deployments; it appears in the documentation but the resource-level `metrics:list-definitions` response does not include it. Add it to the whitelist if your fleet starts surfacing the definition (a receiver restart picks up newly-published definitions). ### Backend protocol and health probes Application Gateway's default health probe binds to the backend HTTP setting's protocol and port. **A plain-HTTP probe to an HTTPS-only backend gets a 400 response**, marks the backend `Unhealthy` indefinitely, and your `HealthyHostCount` sticks at 0. Common HTTPS-only backends are Azure Storage static-website endpoints, App Service with HTTPS-only enabled, Azure Functions, and most third-party APIs. The standard topology terminates client TLS at Application Gateway and speaks HTTPS upstream: ```bicep backendHttpSettingsCollection: [ { name: 'appGwBackendHttpSettings' properties: { port: 443 protocol: 'Https' cookieBasedAffinity: 'Disabled' requestTimeout: 30 // Forward backend's hostname so SNI cert validation succeeds and // the backend's host-routing matches the request. pickHostNameFromBackendAddress: true } } ] ``` For backends that genuinely speak only HTTP (legacy services, internal admin tools), use a custom health probe with an explicit `match.statusCodes` range that accepts the actual probe response, rather than relying on the default probe's `200-399` band. When the backend is `Unhealthy`, the gateway returns 502 to clients - visible as `azure_responsestatus_total{metadata_httpstatusgroup="5XX"}` even though no request reached the backend. Pair `HealthyHostCount` and `ResponseStatus 5XX` on the same dashboard to distinguish gateway-side failures from backend-side failures. ### Verification After applying the fragment and restarting the collector, three signals confirm the pipeline is healthy. **1. Receiver discovers your gateway.** Within 30 seconds of collector startup (or reload), one line per discovery phase appears in the logs: ```text azuremonitorreceiver ... "Loaded the list of Azure Subscriptions" subscriptions_count=1 azuremonitorreceiver ... "Loaded the list of Azure Resources" resources_count=1 azuremonitorreceiver ... "Loaded the list of Azure Metrics Definitions" metrics_definitions_count=8 azuremonitorreceiver ... "Loaded the Azure Metrics" resource_id=/subscriptions/.../applicationGateways/ ``` `subscriptions_count` and `resources_count` should match your scope. `metrics_definitions_count` should approach 17 on a production gateway; fresh gateways surface only 8-9 (see [Lazy-published metrics](#lazy-published-metrics)). A wrong resource count, or a `metrics_definitions_count` of 0, indicates a configuration or RBAC issue; see [Troubleshooting](#troubleshooting). **2. Data points reach Scout.** Confirm via the collector's self-metrics on `:8888/metrics`: ```bash curl -s http://:8888/metrics \ | grep -E "(azure_monitor.applicationgateway|otlp.*b14)" ``` The receiver-accepted and exporter-sent counters should grow together (data flows end-to-end); `otelcol_exporter_send_failed_metric_points_total` should stay at zero. **3. Series visible in Scout.** Filter on either of: - `service.name = application-gateway-monitor` (or whatever you set `${APPGATEWAY_SERVICE_NAME}` to). - `cloud.platform = azure_application_gateway`. Initial series on a gateway with traffic: `azure_throughput_average`, `azure_totalrequests_total`, `azure_responsestatus_total`, `azure_healthyhostcount_average`. Group by `metadata_HttpStatusGroup` to split 2XX vs 4XX vs 5XX. Group by `metadata_BackendSettingsPool` for per-pool error rates and host counts. ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | --- | --- | --- | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Default in this guide. RBAC lags 5-30 min after the Monitoring Reader grant. | | Legacy ARM `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Temporary fallback if the data plane is still 401-ing after RBAC propagation should have completed. Immediate RBAC propagation. | At a 60-second collection interval, a single gateway costs roughly 60 calls per hour (one per metric per poll, deduplicated within the receiver). Even small fleets (5-10 gateways) benefit from `use_batch_api: true` because batched fan-out is more rate-limit-friendly across collectors that share a subscription. For multi-subscription discovery without an explicit list: ```yaml receivers: azure_monitor/applicationgateway: discover_subscriptions: true # any sub the identity has Monitoring Reader on services: [Microsoft.Network/applicationGateways] auth: { authenticator: azure_auth } use_batch_api: true # 360k/h ceiling per sub cache_resources: 86400 # receiver default (24h) ``` The receiver shares one rate-limit budget across all subscriptions in the list. Splitting heavy subscriptions across separate collector instances lifts the aggregate ceiling linearly. ### Cardinality control By default the receiver emits one OTel series per `(resource × metric × aggregation × dimension-combination)`. The 17-metric whitelist with single aggregations produces ~17 base series per gateway, multiplied by the dimension fan-out: - `BackendSettingsPool` × N backend pools × M HTTP settings. - `BackendServer` × N backend pools × M HTTP settings × K backends per pool. - `Listener` × number of listeners. - `HttpStatusGroup` × 4 (`2XX`, `3XX`, `4XX`, `5XX`). A 50-gateway fleet averaging 5 backend pools of 4 hosts each, with one listener each, produces roughly: ```text 17 base × 4 status × 4 backends × 5 pools × 50 gateways ≈ 68,000 active series ``` The dominant fan-out factor is `BackendServer` × `HttpStatusGroup` on `BackendResponseStatus`. Three control levers, in order of preference: 1. **`dimensions.overrides`** drops or whitelists dimensions per metric. Keep `BackendServer` only on `BackendResponseStatus` and the `Backend*Time` family; drop it on `HealthyHostCount` and `UnhealthyHostCount` where pool-level aggregation is enough. ```yaml azure_monitor/applicationgateway: dimensions: enabled: true overrides: "Microsoft.Network/applicationGateways": HealthyHostCount: - BackendSettingsPool UnhealthyHostCount: - BackendSettingsPool BackendResponseStatus: - BackendServer - HttpStatusGroup BackendConnectTime: - BackendServer ``` 2. **Drop low-signal metrics on noisy gateways.** `BytesReceived` / `BytesSent` per listener and `ComputeUnits` are the lowest-signal members of the whitelist for incident response; remove them on gateways where dashboard density matters more than capacity reporting. 3. **Per-fleet receiver instances.** Split high-cardinality gateways into separate `azure_monitor/applicationgateway-prod` and `azure_monitor/applicationgateway-quiet` receivers with different override profiles. Both contribute to the same `metrics/applicationgateway` pipeline. Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's Prometheus endpoint (port 8888 by default) to see actual cardinality after `overrides` apply. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points; derive your own from observed 99th percentile over a representative week. `azure_failedrequests_total` and `azure_responsestatus_total` (5XX bucket) only emit data points when their condition occurs (silent-when-quiet). Wire those alerts on series presence in window, not on numeric thresholds. | Metric (OTel name) | Warning | Critical | Why it matters | | --- | --- | --- | --- | | `azure_unhealthyhostcount_average` (per `BackendSettingsPool`) | > 0 for 2 min | sustained > 0 for 10 min | Below 100% pool health. Above ~50% means user requests are likely failing too. | | `azure_responsestatus_total{metadata_httpstatusgroup="5XX"}` | > 0 over 5 min | > 0 over 15 min | Sustained 5XX at the gateway. Cross-check with `BackendResponseStatus 5XX` to attribute to gateway vs origin. | | `azure_failedrequests_total` | > 0 over 5 min | > 0 over 15 min | Gateway could not satisfy a request (no healthy backend, timeout). Often paired with `UnhealthyHostCount > 0`. | | `azure_applicationgatewaytotaltime_average` (per `Listener`) | > P99 baseline | sustained > 2x P99 baseline | User-perceived latency anomaly. Pair with `BackendFirstByteResponseTime` to identify origin-side vs gateway-side latency. | | `azure_capacityunits_average` | > 80% of `maxCapacity` | > 95% of `maxCapacity` | Gateway approaching its autoscale ceiling. Raise `maxCapacity` or split traffic. | | `azure_currentconnections_total` (per gateway) | > 5x baseline / 15 min | sustained > 10x | Misbehaving client opening connections in a loop. Set baseline from a steady-state week. | #### RED method on the gateway If you run Application Gateway as part of a service backed by SLOs, frame its metrics as RED (rate, errors, duration) at the gateway: - **Rate.** `azure_totalrequests_total` per gateway, sliced by `BackendSettingsPool`. - **Errors.** Two SLIs: - **Gateway-availability error rate** = `(azure_failedrequests_total + azure_responsestatus_total{5XX}) / azure_totalrequests_total`. A spike here is "gateway or capacity envelope is broken"; route to platform on-call. - **Backend-availability error rate** = `azure_backendresponsestatus_total{5XX} / azure_backendresponsestatus_total`. A spike here is "the origin services are broken"; route to the owning service team. - **Duration.** `azure_applicationgatewaytotaltime_average` per `Listener` for total user-perceived latency; `azure_backendfirstbyteresponsetime_average` per `BackendServer` for origin-side latency. For saturation (the U in USE), pair `azure_capacityunits_average` / `maxCapacity` and `azure_currentconnections_total` per gateway. ### WAF_v2 additions WAF_v2 emits the same metrics as Standard_v2 plus a family of WAF metrics. When the gateway is WAF_v2, extend the whitelist: ```yaml metrics: "Microsoft.Network/applicationGateways": # ...all 17 from the Standard_v2 set above... AzwafTotalRequests: [total] # Total requests evaluated by WAF AzwafSecRule: [total] # Matched managed rules AzwafCustomRule: [total] # Matched custom rules AzwafBotProtection: [total] # Bot-protection matches BlockedCount: [total] # WAF-blocked requests by RuleGroup x RuleId MatchedCount: [total] # All matched rule distributions AzwafPenaltyBoxHits: [total] AzwafPenaltyBoxSize: [average] AzWAFCaptchaChallengeRequestCount: [total] AzWAFJSChallengeRequestCount: [total] ``` Most WAF metrics carry `Action` (`Block` / `Allow` / `Log`), `Mode` (`Detection` / `Prevention`), `PolicyName`, `PolicyScope`, and `RuleGroup` / `RuleID` dimensions. These multiply cardinality fast on a high-traffic gateway; apply `dimensions.overrides` to pin to the axes your security team uses. `MatchedCount` and `BlockedCount` are the headline operational metrics for a WAF-in-detection-mode rollout. Track the ratio `BlockedCount / MatchedCount` to see how many matched-rule events are actually being blocked vs logged. ### Logs Log-driven analysis fills three gaps that the metrics in this guide do not cover: - **Per-request URL and client-IP audit.** The metrics aggregate by listener, backend pool, and `HttpStatusGroup`. Access logs carry the actual request URL, query string, client IP, RuleName, server routed to, TLS protocol, and per-request sent / received bytes. Required for "why is this specific user's request slow" investigation and for any compliance regime that needs a per-request audit trail. - **WAF rule attribution.** `BlockedCount`, `BlockedReqCount`, and `MatchedCount` show how many requests were blocked or matched a WAF rule, but not which OWASP rule fired, what the anomaly score was, which fields matched, or whether Detection mode would have blocked. `ApplicationGatewayFirewallLog` records the rule ID, action, mode, and matched data per request. Required for tuning Detection-vs- Prevention thresholds and false-positive triage. - **Per-backend probe-failure timing.** `UnhealthyHostCount` shows the count of unhealthy backends per pool. A 1 → 0 transition is visible but not which backend address failed at which exact moment, with what response code or timeout. `ApplicationGatewayHealthProbeLog` records each probe result individually with backend address, probe response code, and probe response time. Application Gateway publishes three Diagnostic Settings categories on Standard_v2 and WAF_v2: | Category | What it contains | When to enable | | --- | --- | --- | | `ApplicationGatewayAccessLog` | Per-request audit: URL, query string, client IP, listener, RuleName, server routed to, response code, response time, TLS protocol, sent / received bytes. | Always | | `ApplicationGatewayFirewallLog` | Per-request WAF outcome: rule ID, action (Allowed / Blocked / Detected), mode, anomaly score, matched data, request ID. | WAF_v2 only | | `ApplicationGatewayHealthProbeLog` | Per-probe result per backend: backend address, probe response code, probe response time, transition direction. | Required for any deployment with multiple backends in a pool | `ApplicationGatewayPerformanceLog` is not listed: it was a Standard_v1 category and is not published by Standard_v2 / WAF_v2 (the equivalent data is in metrics). ```bash az monitor diagnostic-settings create \ --resource \ --name appgw-to-eventhubs \ --logs '[{"category":"ApplicationGatewayAccessLog","enabled":true}, {"category":"ApplicationGatewayFirewallLog","enabled":true}, {"category":"ApplicationGatewayHealthProbeLog","enabled":true}]' \ --event-hub \ --event-hub-rule ``` The recommended pattern is **Diagnostic Settings to Event Hubs to the `azure_event_hub` receiver** in the same collector. The receiver ingests events as OTel logs and routes them to Scout via the same `oauth2client` / `otlphttp/b14` pipeline used for metrics. The Storage logs example at `components/azure-storage-telemetry/` ships a runnable reference fragment (`config/scraper-fragment-logs.yaml`) plus `provision-logs.sh` / `teardown-logs.sh` that stand up an EH Basic namespace + Diagnostic Setting wiring; the same fragment shape adapts to Application Gateway by changing the `cloud.platform` resource attribute and the source Diagnostic Setting categories. Drop `ApplicationGatewayFirewallLog` from the `--logs` array if the gateway is Standard_v2 (no WAF). The two paths are complementary: metrics for SLI / SLO dashboards and alerts, logs for per-request investigation. ### Troubleshooting **`HealthyHostCount` stuck at 0 but the backend is reachable directly.** Backend HTTP setting protocol/port mismatch with the backend. The default health probe inherits `protocol` and `port` from the HTTP setting; an HTTP probe to an HTTPS-only backend gets a 400 and is treated as unhealthy. Switch the HTTP setting to `protocol: Https` / `port: 443` (or define a custom probe with a permissive `match.statusCodes` band). See [Backend protocol and health probes](#backend-protocol-and-health-probes). **`AuthorizationFailed` from the receiver.** Legacy ARM `/metrics` endpoint propagates `Monitoring Reader` immediately; data-plane batch API can lag 5-30 minutes. If `use_batch_api: true` is set and you've just granted the role, temporarily flip to `false` to confirm the role itself is correct. If using a service principal, check that the client secret has not expired (`az ad app credential list --id $AZURE_CLIENT_ID`). **`metrics_definitions_count` is 8 or 9, not 17.** Expected on a brand-new gateway; Azure Monitor lazy-publishes definitions per metric based on emit history. See [Lazy-published metrics](#lazy-published-metrics). Production gateways with weeks of history surface the full set immediately. **`BackendResponseStatus` for the 5XX bucket does not appear after the first 502.** Receiver caches the definitions list per container lifetime. Restart the collector; the next discovery cycle picks up the fresh definition. **`RequestThrottled` warnings from the receiver.** You have hit Azure Monitor's per-subscription rate ceiling (12,000 / hour on legacy or 360,000 / hour on batch). Lower polling rate (`collection_interval: 120s`), narrow scope (list specific `resource_groups:`), or split heavy subscriptions across multiple collector instances. `use_batch_api: true` is already the default in this guide. **Scout OAuth2 returns 401.** Verify `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, and `SCOUT_TOKEN_URL` match the values in your Scout console. The `endpoint_params.audience` must be `b14collector`. **`dial tcp: lookup login.microsoftonline.com: network is unreachable`** on first scrape after a sibling collector restart. Docker Desktop DNS glitch. Recreate the collector container (`docker compose down && docker compose up`) to refresh the resolver. ### Frequently Asked Questions #### How do I add Azure Application Gateway metrics to my OTel Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.Network/applicationGateways`, then route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter. The receiver polls Azure Monitor's REST API every 60 seconds and emits one OTel metric per Azure aggregation. The collector is read-only against Azure Monitor; it never touches Application Gateway's data plane. #### Should I use Application Gateway Standard_v2 or WAF_v2? Standard_v2 if you do not need a Web Application Firewall; WAF_v2 if you need OWASP rule sets, custom WAF rules, bot protection, or rate limiting at the gateway. WAF_v2 emits the same metrics as Standard_v2 plus a family of `Azwaf*` metrics covering matched-rule counts, mode (Detection vs Prevention), and bot scoring. Add those metrics to the whitelist when targeting WAF_v2; the rest of the receiver config is identical. Standard_v1 is deprecated and not covered by this guide. #### Front Door or Application Gateway - which is right for the metrics use case? Different scopes. [Front Door](./front-door.md) (`Microsoft.Cdn/profiles`) is a global CDN-and-edge service with metrics framed around edge POPs (`RequestCount` per `ClientCountry`, `OriginHealthPercentage`, `ByteHitRatio`). Application Gateway (`Microsoft.Network/applicationGateways`) is a regional L7 load balancer with metrics framed around backend pools and listeners (`HealthyHostCount` per `BackendSettingsPool`, `ApplicationGatewayTotalTime` per `Listener`, `BackendResponseStatus` per `BackendServer`). Customers running both - global edge plus regional backend selection - should monitor both surfaces; the receiver fragments coexist in one collector. #### Why does the backend HTTP setting use HTTPS:443 instead of HTTP:80? Many production backends - Azure Storage static-website endpoints, App Service, Azure Functions HTTPS-only, external APIs - serve only HTTPS. Application Gateway's default health probe is bound to the backend HTTP setting's protocol and port, so a plain-HTTP probe to an HTTPS-only backend gets a 400 and the backend is marked `Unhealthy` indefinitely. The standard pattern is to terminate client TLS at the gateway (or accept HTTP from clients in non-public scenarios) and speak HTTPS upstream to the backend. With `pickHostNameFromBackendAddress: true`, Application Gateway forwards the backend's hostname so SNI cert validation succeeds. #### How does lazy-publishing of metric definitions affect monitoring? Azure Monitor publishes metric definitions for Application Gateway lazily. A freshly-provisioned gateway typically surfaces 8-9 of the documented 24 definitions; the rest appear as the underlying behavior begins producing data points (a failed origin probe surfaces `UnhealthyHostCount`, a non-2XX response surfaces `BackendResponseStatus` per `HttpStatusGroup`, etc.). Whitelist the broader set anyway so they emit automatically as the gateway ages. The receiver caches the definitions list per container lifetime; if a metric Azure begins publishing mid-run still does not appear in Scout after several scrape cycles, restart the collector to pick up the fresh definition list. #### How does Scout compare to Application Insights for Application Gateway? Both surfaces draw from the same Azure Monitor REST API for metrics, so coverage is identical. The differences are commercial and operational: Scout is vendor-neutral OTLP, queryable via SQL, with ingest-volume pricing rather than per-GB ingestion fees; Application Insights uses Kusto Query Language only, is Azure-tenant-bound, and bills for log ingestion alongside metric storage. The collector also unifies multi-cloud surfaces under one pipeline: Application Gateway, Front Door, AWS Application Load Balancer, GCP Cloud Load Balancer all flow through the same exporter. ### Reference - **Receiver source.** [opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver). - **Auth extension source.** [opentelemetry-collector-contrib / extension / azureauthextension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/azureauthextension). - **Azure Monitor metric reference.** [Microsoft.Network/applicationGateways metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-applicationgateways-metrics). ### Related Guides - [Azure Front Door](./front-door.md) - global CDN and L7 edge with WAF, typically deployed in front of Application Gateway for global routing. - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure SQL Database](./sql-database.md) - managed relational database. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. --- ## Azure Firewall Monitoring with OpenTelemetry ### Overview This guide is the **execution playbook** for Azure Firewall (Standard SKU). For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. The collector polls Azure Monitor's REST API for `Microsoft.Network/azureFirewalls` every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. The receiver does not touch the firewall data plane. Azure Firewall is a managed L4-7 stateful firewall, distinct from Azure Web Application Firewall (which runs on Application Gateway and Front Door). This guide covers the stateful firewall surface: network-rule hits, application-rule hits, throughput, SNAT-port utilization, and threat-intel signals. For WAF metrics, see the [Application Gateway](./application-gateway.md) and [Front Door](./front-door.md) guides. ### SKU choice | SKU | Metric coverage | When to choose | | --- | --- | --- | | **Basic** | Reduced subset (no SNAT, no IDPS) | SMB-tier deployments below ~250 Mbps; not recommended for production fleets. | | **Standard** | Full 8-metric whitelist in this guide | Production default; covers rule hits, throughput, SNAT, health. | | **Premium** | Standard set + `SignatureLookupHits` (IDPS) | When intrusion detection or TLS inspection is required. | The receiver shape is identical across all three SKUs; the metric whitelist is the only thing that changes. ### Receiver configuration Add this fragment to your existing collector config. It contributes the `azure_auth` extension, an `azure_monitor` receiver scoped to the firewall namespace, a resource processor, a `transform` processor for the rule-hit dimensions, and a metrics pipeline. Component keys are suffixed `/firewall` so the fragment composes cleanly with other Azure-surface receivers in the same collector. The `transform/firewall_dim_lowercase` processor below is a workaround for receiver bug #45942 - the receiver currently emits the rule-hit metrics' dimensions in **both** `metadata_Status` and `metadata_status` forms, doubling cardinality. The transform lowercases and deduplicates them. See [Bug #45942](#bug-45942-case-mismatched-dimension-keys) for the full diagnosis; drop the processor block if doubled cardinality is acceptable. ```yaml showLineNumbers title="otel-collector.yaml (Firewall addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Authentication section below for the right choice per # collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/firewall: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:FIREWALL_RESOURCE_GROUP} # Multi-resource-group scoping. Omit resource_groups entirely to # scrape every resource group in the listed subscriptions. services: - Microsoft.Network/azureFirewalls auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Data-plane batch API. Lifts the per-subscription rate ceiling # from 12k to 360k calls/hour and is the recommended default. Flip # to false only as a temporary fallback while data-plane RBAC # propagates after a fresh Monitoring Reader grant (5-30 min lag). use_batch_api: true cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Network/azureFirewalls": ApplicationRuleHit: [Total] NetworkRuleHit: [Total] DataProcessed: [Total] SNATPortUtilization: [Average, Maximum] Throughput: [Average] FirewallHealth: [Average] ObservedCapacity: [Average, Maximum] # FirewallLatencyPng is in Preview. Surface it if you want # firewall-traversal latency, otherwise drop the line. FirewallLatencyPng: [Average] processors: resource/firewall: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_firewall, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:FIREWALL_REGION}", action: insert} # cloud.resource_id pins all metrics to one firewall. Drop this # line for multi-firewall fleets; the receiver injects # azuremonitor.resource_id per-resource automatically. - {key: cloud.resource_id, value: "${env:FIREWALL_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:FIREWALL_SERVICE_NAME}", action: insert} # Workaround for receiver bug #45942 (case-mismatch on metadata_* # dimensions, observed on v0.151.0). Lowercases the PascalCase # variants to deduplicate. The `set(...) where ... == nil` guard # prevents overwriting any legitimate lowercase value that the # receiver already emitted on the same data point. See Cardinality # control below. transform/firewall_dim_lowercase: metric_statements: - context: datapoint statements: - set(attributes["metadata_status"], attributes["metadata_Status"]) where attributes["metadata_Status"] != nil and attributes["metadata_status"] == nil - delete_key(attributes, "metadata_Status") where attributes["metadata_Status"] != nil - set(attributes["metadata_reason"], attributes["metadata_Reason"]) where attributes["metadata_Reason"] != nil and attributes["metadata_reason"] == nil - delete_key(attributes, "metadata_Reason") where attributes["metadata_Reason"] != nil - set(attributes["metadata_protocol"], attributes["metadata_Protocol"]) where attributes["metadata_Protocol"] != nil and attributes["metadata_protocol"] == nil - delete_key(attributes, "metadata_Protocol") where attributes["metadata_Protocol"] != nil service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/firewall: receivers: [azure_monitor/firewall] processors: [memory_limiter, resource/firewall, transform/firewall_dim_lowercase, batch] exporters: [otlphttp/b14] ``` The receiver, resource processor, transform processor, and pipeline are all keyed `/firewall` so they coexist with other Azure receivers in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, add entries to `subscription_ids:`. The alternative `discover_subscriptions: true` scrapes every subscription the identity has `Monitoring Reader` on; prefer the explicit list in production, since discovery silently includes sandbox and dormant subscriptions. ### Authentication and RBAC Pick the `azure_auth` mode for where the collector runs: - **AKS pod** - `workload_identity` (federated credential, no secret). - **Container Apps / VMSS / Azure VM** - `managed_identity` (user-assigned survives instance replacement; system-assigned dies with the instance). - **External or on-prem** - `service_principal`. - **Local dev only** - `use_default: true` (Azure SDK credential chain). Grant `Monitoring Reader` at the resource group containing your firewalls. For mode-by-mode YAML, federation-credential setup, and the `az role assignment create` snippet, see [Azure Service Bus § Authentication](./service-bus.md#authentication) - the configuration is identical except for the receiver's `services:` line and the resource processor's `cloud.platform` value. This guide defaults `use_batch_api: true` for the 360k-calls/hour ceiling. Data-plane RBAC lags 5-30 minutes after a fresh `Monitoring Reader` grant; if the receiver returns 401s in that window, temporarily flip to `false` (legacy ARM `/metrics`, immediate propagation) and revert once the data-plane RBAC settles. If you run a service principal (collector outside Azure), rotate the client secret before its expiry; procedure mirrors other azure-monitor surfaces - see [Service Bus § Service principal credential lifecycle](./service-bus.md#service-principal-credential-lifecycle). ### What you'll monitor Azure Firewall publishes 8 metrics on the `Microsoft.Network/azureFirewalls` namespace, all at PT1M time grain. The receiver renames Azure's PascalCase names (e.g. `NetworkRuleHit`) to OTel-style `azure__` (e.g. `azure_networkrulehit_total`). | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `NetworkRuleHit` | `azure_networkrulehit_total` | Count | Hits on network-rule collections (5-tuple TCP / UDP / ICMP filtering). Splits by `Status` (Allow / Deny / DNAT) and `Reason`. Primary L4 traffic-shape metric. | | `ApplicationRuleHit` | `azure_applicationrulehit_total` | Count | Hits on application-rule collections (FQDN-based filtering). Splits by `Status`, `Reason`, and `Protocol`. Only emits when application rules exist in the policy and traffic matches them. | | `DataProcessed` | `azure_dataprocessed_total` | Bytes | Total bytes processed by the firewall per minute. Primary data-volume metric; pairs with the data-processing fee ($0.016/GB) for cost forecasting. | | `Throughput` | `azure_throughput_average` | bps | Throughput in bits per second. Use for capacity-planning and alerting against the per-firewall ceiling - see [Azure Firewall performance](https://learn.microsoft.com/azure/firewall/firewall-performance) for current per-tier limits. | | `FirewallHealth` | `azure_firewallhealth_average` | % | Overall firewall health gauge. Below 100% indicates Azure-side degradation; cross-check Service Health for the region. | | `SNATPortUtilization` | `azure_snatportutilization_average` (and `_maximum`) | % | Percentage of allocated SNAT ports currently in use. Above 80% indicates approaching SNAT exhaustion on outbound traffic. Splits by `Protocol`. | | `ObservedCapacity` | `azure_observedcapacity_average` (and `_maximum`) | Count | Reported capacity-unit usage. Tracks horizontal scale of the firewall instance; per-CU throughput and connection limits are documented in the [Azure Firewall performance reference](https://learn.microsoft.com/azure/firewall/firewall-performance). | | `FirewallLatencyPng` | `azure_firewalllatencypng_average` | ms | (Preview) Estimated firewall-traversal latency from internal latency probes. Preview metrics may change shape or disappear between receiver versions; gate alerting accordingly and revalidate on each upgrade. | Three `metadata_*` dimensions split the rule-hit and health metrics: - `metadata_Status` (NetworkRuleHit, ApplicationRuleHit, FirewallHealth) - `Allow`, `Deny`, `DNAT`. The `Deny` slice on `NetworkRuleHit` is the primary security-incident signal. - `metadata_Reason` (NetworkRuleHit, ApplicationRuleHit, FirewallHealth) - short reason code per rule firing (e.g. `RuleNotMatched`, `Allowed`, `RuleMatched`). - `metadata_Protocol` (ApplicationRuleHit, SNATPortUtilization) - `TCP`, `UDP`, `ICMP`, `Any`. Receiver bug #45942 emits these dimensions in both PascalCase and lowercase forms on the same metric; the `transform` processor in the receiver config above normalises to lowercase. See [Bug #45942](#bug-45942-case-mismatched-dimension-keys). **Silent-when-quiet caveat.** Azure Monitor returns data points for `NetworkRuleHit`, `ApplicationRuleHit`, and `DataProcessed` only when matching activity occurs. A firewall with no traffic emits zero series for those three. Wire alerts to fire on series presence in window (any non-zero point) rather than threshold crossings, since absence is the steady state for under-utilised firewalls. `FirewallHealth`, `Throughput`, `SNATPortUtilization`, and `ObservedCapacity` flow continuously every minute regardless of traffic. ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. A single firewall with the full 8-metric whitelist costs roughly 60 calls per hour at 60s `collection_interval`. Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | --- | --- | --- | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Default in this guide. RBAC lags 5-30 min after the Monitoring Reader grant. | | Legacy Azure Resource Manager `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Temporary fallback if the data plane is still 401-ing after RBAC propagation should have completed. Immediate RBAC propagation. | A 50-firewall fleet polling at 60s costs ~3,000 calls/hour against the 360k ceiling - under 1% utilization, leaving room for sibling surfaces on the same collector. Even small fleets benefit from `use_batch_api: true`. ### Cardinality control The fan-out per firewall is moderate at baseline (~7 series for single-rule traffic, ~25 series for a multi-rule policy with non-trivial traffic). The dimension shape, however, has a significant gotcha: #### Bug 45942 case-mismatched dimension keys Receiver bug [#45942](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942) manifests on `Microsoft.Network/azureFirewalls`. The same logical dimension value appears under both PascalCase and lowercase keys on the same metric. For example, `azure_networkrulehit_total` for a single Allow rule firing emits data points with `metadata_Status = "Allow"` and separate data points with `metadata_status = "Allow"`. Aggregating across the case-mismatched values double-counts. Validation 2026-05-06 confirmed the bug applies to: - `azure_networkrulehit_total` (Status, Reason) - `azure_applicationrulehit_total` (Status, Reason, Protocol; less fully validated since application-rule hits are policy-shape dependent) - `azure_firewallhealth_average` (Status, Reason) - `azure_snatportutilization_*` (Protocol) Three remediations, in order of operational ease: 1. **Apply a `transform` processor** in the collector to lowercase the dimension keys before they ride downstream. The receiver configuration above includes this workaround. 2. **Normalise on the Scout side** in dashboard / alert queries by coalescing the two casing variants. Useful as a stop-gap while the transform processor is being rolled out. 3. **Drop the affected dimensions** via `dimensions.overrides` if per-Status / per-Reason granularity is not actionable for your alerting. Reduces fan-out at the cost of incident-investigation detail. Track the issue for upstream resolution; v0.151.0 (Apr 2026) has the bug, future releases may not - re-validate on each receiver upgrade. #### Standard cardinality levers The override config uses the **bare Azure dimension name** (e.g. `Status`, not `metadata_Status`); the receiver adds the `metadata_` prefix when it emits. Overrides apply at the receiver, *before* the `transform/firewall_dim_lowercase` processor runs - so the override key matches Azure's PascalCase regardless of what the transform emits downstream. For single-firewall fleets: ```yaml azure_monitor/firewall: dimensions: enabled: true overrides: "Microsoft.Network/azureFirewalls": NetworkRuleHit: - Status # keep # drop Reason if per-rule-firing-reason granularity is not actionable FirewallHealth: [] # drop all dimensions; metric is per-firewall and needs no splits SNATPortUtilization: - Protocol # keep; protocol-split helps SNAT-exhaustion triage ``` Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's port-8888 Prometheus endpoint to see actual cardinality after `overrides` apply. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points; derive your own from observed 99th-percentile baselines over a representative week. | Metric | Warning | Critical | Why it matters | | --- | --- | --- | --- | | `azure_firewallhealth_average` | < 100% over 5m | < 99% over 15m | Azure-side firewall degradation. Cross-check Azure Service Health for the region. | | `azure_snatportutilization_average` | > 80% over 5m | > 95% over 5m | SNAT-port exhaustion is imminent. Pool is **shared across every workload behind the firewall** (unlike Standard LB, where SNAT is per-backend), so a single noisy VM can exhaust the whole firewall - investigate the top-talker in firewall logs before scaling. Add public IPs (each adds ~2496 ports) once the offender is identified. | | `azure_networkrulehit_total` filtered to `metadata_status="Deny"` | sustained presence over 15m | spike > 10x baseline | Deny rules firing at unusual rate. Either you have a misconfigured client or an active probe / scan. Cross-check the Application / Network rule logs. | | `azure_observedcapacity_maximum` | sustained > 8 capacity units | sustained > 12 capacity units, or > 80% of your SKU's documented ceiling | Firewall is auto-scaling toward the per-instance limit. `ObservedCapacity` saturates before `Throughput` does, since the per-instance bandwidth ceiling moves with auto-scale state. Plan multi-firewall topology before this alert fires sustained. Verify your SKU's capacity-unit ceiling on the [Azure Firewall performance reference](https://learn.microsoft.com/azure/firewall/firewall-performance). | | `azure_throughput_average` | > 70% of capacity-unit headroom | > 90% of capacity-unit headroom | Approaching the firewall's bandwidth headroom (each capacity unit ≈ 250 Mbps). Use alongside `ObservedCapacity` rather than alone - the throughput ceiling moves with auto-scale state. | | `azure_applicationrulehit_total` filtered to `metadata_status="Deny"` | sustained presence over 15m | spike > 10x baseline | FQDN-rule denials. Indicates either policy misalignment with application traffic or active threat-intel-driven blocks (see Threat Intel section). | For Deny-filtered alerts, fire on series presence in window rather than numeric thresholds - see the [silent-when-quiet caveat](#what-youll-monitor) above. ### Threat-intel mode Azure Firewall has three threat-intel modes that affect how `ApplicationRuleHit` and `NetworkRuleHit` slices appear: - **Off** - threat-intel signals do not generate rule hits. - **Alert** (default) - threat-intel matches surface as `metadata_Reason="ThreatIntelAlert"` data points without blocking traffic. Some Azure Monitor slices also tag these with `metadata_Status="Deny"` even though the packet was forwarded unchanged. A `Deny`-rate alert in Alert mode therefore reads as "potentially-malicious traffic observed but allowed", **not** "traffic blocked." On-call runbooks must distinguish between the two - the metric on its own does not. - **Alert and deny** - threat-intel matches block traffic and the rule-hit metric records them as `Status=Deny, Reason=ThreatIntelDeny`. Same metric shape, different operational meaning. Document your firewall's threat-intel mode in runbooks; what reads as "the firewall is blocking attacks" in "Alert and deny" mode reads as "the firewall is observing potential threats" in "Alert" mode, and the same `metadata_status="Deny"` alert fires in both. ### Logs Azure Firewall logs are **not optional** for any non-trivial deployment. Log-driven analysis fills three gaps that the metrics in this guide do not cover: - **Per-flow forensics.** `ApplicationRuleHit` and `NetworkRuleHit` metrics aggregate by `metadata_Action`, `metadata_Status`, `metadata_Reason`, and `metadata_Protocol`. They do not carry the source IP, destination FQDN / IP, source port, destination port, or the specific rule name that fired. `AzureFirewallApplicationRule` and `AzureFirewallNetworkRule` records carry the full 5-tuple plus the matched rule collection and rule name - required for any incident requiring "which rule blocked which connection at which time" attribution. - **Threat-intel context.** The `metadata_Status="Deny"` slice of the rule-hit metrics tells you a deny happened. It does not say which threat-intel signature matched, the source IP's reputation tier, or whether the firewall was in Alert vs Alert-and-deny mode. `AzureFirewallThreatIntelLog` records every threat-intel match with source IP, destination, matched signature, and whether the action was alert-only or block - required for security-team triage and for "is this a real threat or noise" decisions. - **DNS-based exfiltration detection.** No metric in the namespace captures DNS request volume per source IP per destination FQDN. `AzureFirewallDnsProxy` records the firewall's DNS-proxy decisions - the canonical source for spotting beaconing patterns, suspicious TLD lookups, and DNS tunnelling exfiltration. Required for any fleet that uses Azure Firewall as the egress DNS resolver. Azure Firewall publishes four Diagnostic Settings categories on Standard SKU plus two Premium-only categories (covered in [Premium log categories](#premium-log-categories) below): | Log category | What it captures | SKU | | --- | --- | --- | | `AzureFirewallApplicationRule` | Per-flow application-rule hits with source IP, destination FQDN, rule collection, rule name, action. | Standard, Premium | | `AzureFirewallNetworkRule` | Per-flow network-rule hits with full 5-tuple plus rule collection, rule name, action. | Standard, Premium | | `AzureFirewallThreatIntelLog` | Threat-intel matches with signature ID, action (alert / deny), source / destination. | Standard, Premium | | `AzureFirewallDnsProxy` | DNS-proxy decisions with source IP, queried FQDN, response code, latency. | Standard, Premium (only when DNS proxy is enabled) | ```bash FW_RES_ID=$(az network firewall show -n -g --query id -o tsv) az monitor diagnostic-settings create \ --resource "$FW_RES_ID" \ --name "fw-to-eventhubs" \ --logs '[ {"category":"AzureFirewallApplicationRule","enabled":true}, {"category":"AzureFirewallNetworkRule","enabled":true}, {"category":"AzureFirewallThreatIntelLog","enabled":true}, {"category":"AzureFirewallDnsProxy","enabled":true} ]' \ --event-hub \ --event-hub-rule ``` The recommended pattern is **Diagnostic Settings to Event Hubs to the `azure_event_hub` receiver** in the same collector. The Storage logs example at `components/azure-storage-telemetry/` ships a runnable reference fragment (`config/scraper-fragment-logs.yaml`) plus `provision-logs.sh` that stands up an EH Basic namespace + 1 hub + 2 SAS rules; the same fragment shape adapts to Azure Firewall by changing the `cloud.platform` resource attribute (`azure_firewall`) and the source Diagnostic Setting categories. Pair the log stream with the metric stream to correlate alert firings with the specific source IPs, destination FQDNs, and rule names involved - the threat-intel mode caveat in [Threat-intel mode](#threat-intel-mode) above means metric alerts on their own often need log context to distinguish "blocked attack" from "observed potential threat." ### Premium SKU additions Premium SKU adds Intrusion Detection and Prevention System (IDPS) support on top of Standard, surfaced in two distinct streams: extra metrics on the same `azure_monitor` receiver, and extra log categories on the Diagnostic Settings stream described in [Logs](#logs). #### Premium metrics Extend the whitelist on the existing receiver - shape is identical to the Standard-tier metrics: ```yaml metrics: "Microsoft.Network/azureFirewalls": # ...the eight Standard-tier metrics above... SignatureLookupHits: [Total] # IDPS signature match rate ``` `SignatureLookupHits` is the only Premium-exclusive metric on the namespace. If you are running Standard, omit it; if you are running Premium, alert on sustained presence as a per-firewall security signal. #### Premium log categories Premium adds two log categories. They are not metrics - they ride the same Diagnostic Settings → Event Hubs → `azure_event_hub` path as the four Standard categories: ```bash # Append to the --logs JSON in the Diagnostic Settings command above. {"category":"AzureFirewallApplicationRuleAggregation","enabled":true}, {"category":"AzureFirewallIDPSSignatureMatch","enabled":true} ``` `AzureFirewallIDPSSignatureMatch` records each IDPS hit with the signature that triggered - pair it with the `SignatureLookupHits` metric to follow an alert back to the specific signatures. `AzureFirewallApplicationRuleAggregation` is a pre-aggregated form of `AzureFirewallApplicationRule` that lowers log volume when application-rule traffic is dense. ### Apps-side instrumentation This guide is metrics-only. Standard SKU is L4-7 transparent (the client and server applications do not see the firewall as a hop), so there is no apps-side trace integration on Standard. **Premium SKU caveat.** Premium TLS inspection decrypts and re-encrypts traffic on the firewall, so it is **not** transparent at L7 - `traceparent` headers and other request-context attributes may not survive the round-trip. Validate trace continuity end-to-end before relying on cross-firewall span propagation under Premium. The only "firewall in the trace" signal you can get from instrumentation is end-to-end client latency that includes the firewall hop; the metric `azure_firewalllatencypng_average` is the firewall's own estimate of that hop's latency. ### Troubleshooting #### `AuthorizationFailed` from the receiver Data-plane batch API (`use_batch_api: true`, the default) propagates `Monitoring Reader` 5-30 minutes after grant; legacy ARM `/metrics` (`use_batch_api: false`) propagates immediately. If you've just granted the role and the receiver is 401-ing, temporarily flip to `false` to confirm the role itself is correct, then revert. #### `403 Forbidden` from the receiver If using a service principal: the `client_secret` has expired. See [Service Bus § Service principal credential lifecycle](./service-bus.md#service-principal-credential-lifecycle). If using managed identity: check that the firewall is in a subscription / resource group where the managed identity has `Monitoring Reader`. #### Metrics never appear after a fresh firewall provision Two distinct delays compound: 1. **Firewall control-plane provisioning takes 20-30 minutes** for Standard SKU on a fresh deployment. Until the firewall reaches `provisioningState=Succeeded`, metrics do not flow regardless of the collector configuration. Verify with `az network firewall show -n -g --query provisioningState -o tsv`. 2. **The receiver caches metric definitions** for the `cache_resources` interval (default 86400s / 24h). On the first poll after a fresh firewall is created, Azure Monitor's metric-definition catalogue may not yet have populated. Restart the collector after the firewall reaches `Succeeded` to reset the discovery cache. The receiver log line `metrics_definitions_count: 0` confirms the diagnosis; recovery is verified when the next poll cycle logs `metrics_definitions_count: ` with `N > 0`. This is the same first-poll race documented for [Load Balancer](./load-balancer.md#metrics-never-appear-on-a-freshly-provisioned-lb) and [Storage](./storage.md#capacity-metrics-never-appear); the long firewall provisioning latency makes it more conspicuous. #### `ApplicationRuleHit` always zero The firewall policy contains only network-rule collections. Network rules and application rules are separate concepts; `ApplicationRuleHit` only emits data points when traffic matches an application-rule collection (FQDN-based filtering). Add an application-rule collection to the policy, generate matching traffic, and the metric will populate. If your deployment intends to be network-rules-only, drop `ApplicationRuleHit` from the whitelist to avoid alerting confusion. #### `metadata_*` dimensions appear with mixed casing Bug #45942. See [Cardinality control](#cardinality-control); apply the transform processor in the receiver configuration to normalise. #### `RequestThrottled` warnings from the receiver You have hit Azure Monitor's per-subscription rate ceiling. Either: - Lower polling rate: `collection_interval: 120s` for the fast receiver. - Confirm `use_batch_api: true` is set (the guide default). - Split heavy subscriptions across multiple collector instances. #### Cardinality blowup on Scout volume The case-mismatch bug is the most common cause; apply the transform processor first. If still high, apply `dimensions.overrides` (see [Cardinality control](#cardinality-control)) or split the noisy firewall into a separate receiver instance. #### Scout OAuth2 returns 401 Verify `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, and `SCOUT_TOKEN_URL` match the values in your Scout console. The `endpoint_params.audience` must be `b14collector`. ### Frequently Asked Questions #### How do I add Azure Firewall metrics to my OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.Network/azureFirewalls`, then route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter. The receiver polls Azure Monitor's REST API every 60 seconds and emits one OTel metric per Azure aggregation. RBAC requirement is `Monitoring Reader` at resource-group scope. Standard SKU emits the full metric set; Basic SKU emits a reduced subset. #### Why are my ApplicationRuleHit metrics not appearing? `ApplicationRuleHit` only emits when traffic matches an application-rule collection (FQDN-based filtering) in your firewall policy. If your policy contains only network-rule collections (5-tuple TCP / UDP / ICMP filtering), only `NetworkRuleHit` will emit. To validate the metric flow, add an application-rule collection that matches the traffic generated by your test backend. Threat-intel mode also affects whether `ApplicationRuleHit` slices include the Threat-Intel-derived blocks; see the threat-intel section above. #### Why are my rule-hit dimensions appearing twice with different casing? This is a known receiver bug - opentelemetry-collector-contrib issue 45942 - that manifests on `Microsoft.Network/azureFirewalls`. The same logical dimension value (`Status=Allow`, for example) appears under both `metadata_Status` and `metadata_status` keys, doubling cardinality silently. Workaround: apply a `transform` processor in the collector to lowercase the dimension keys, or normalise downstream in Scout queries. The bug is namespace-specific to Azure Firewall and Storage; it does not always manifest, but on Firewall the rule-hit and `FirewallHealth` metrics consistently show the doubling. #### How do I detect SNAT port exhaustion on the firewall? Alert on `azure_snatportutilization_average` above 80% over 5 minutes; warn at 60%. SNAT exhaustion on Azure Firewall presents differently from Standard Load Balancer: outbound connections from any backend behind the firewall start timing out or returning `EADDRNOTAVAIL` even when the firewall itself is healthy. The fix is to add more public IP frontends to the firewall (each adds 2496 SNAT ports per public IP, with the firewall preempting them as needed). #### Should I run Azure Firewall logs through this collector? Yes, but via Diagnostic Settings → Event Hubs → `azure_event_hub` receiver, not via this metrics collector. The four log categories (`AzureFirewallApplicationRule`, `AzureFirewallNetworkRule`, `AzureFirewallThreatIntelLog`, `AzureFirewallDnsProxy`) are not optional for any non-trivial Firewall deployment; they are the primary investigation surface during incidents. Configure once per firewall, ingest into the same collector via a separate fragment under the long-lived shared scraper. ### Reference - **Receiver source.** [opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver). - **Auth extension source.** [opentelemetry-collector-contrib / extension / azureauthextension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/azureauthextension). - **Azure Monitor metric reference.** [Microsoft.Network/azureFirewalls metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-azurefirewalls-metrics). - **Case-mismatch bug.** [opentelemetry-collector-contrib issue 45942](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942). - **Threat-intel mode reference.** [Azure Firewall threat intelligence](https://learn.microsoft.com/azure/firewall/threat-intel). - **Capacity-unit reference.** [Azure Firewall performance](https://learn.microsoft.com/azure/firewall/firewall-performance). ### Related Guides - [Azure Application Gateway](./application-gateway.md) - regional L7 load balancer with WAF v2. - [Azure Front Door](./front-door.md) - global CDN and L7 edge with WAF. - [Azure Load Balancer](./load-balancer.md) - L4 network load balancer. - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure Storage](./storage.md) - managed object/blob/queue/table/file storage. - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. --- ## Azure Cache for Redis Monitoring with OpenTelemetry - Hit Rate, Memory Pressure, and Connection Saturation ### Overview :::note Microsoft has announced the retirement of Azure Cache for Redis. The Enterprise and Enterprise Flash tiers retire on 31 March 2027, and the Basic, Standard, and Premium tiers on 30 September 2028; instances are disabled the day after each date. The replacement is Azure Managed Redis, which publishes a different metric namespace, so a cache you migrate needs its receiver reconfigured. This guide still applies to Cache for Redis instances until you move them. See [Microsoft's retirement FAQ](https://learn.microsoft.com/en-us/azure/azure-cache-for-redis/retirement-faq). ::: This guide is the **execution playbook** for Azure Cache for Redis. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running Azure Cache for Redis (PaaS) in production who want to add cache telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.Cache/Redis` metrics every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. The receiver does not connect to the cache on port 6380 and does not need the primary access key - it queries Azure Monitor for whatever your cache auto-publishes. The receiver does not connect to Redis directly. It queries Azure Monitor for any cache your subscription auto-publishes to, so the same configuration covers Basic, Standard, Premium, and Enterprise tiers across any number of caches and shards per cache. > **Self-hosted Redis?** If you run Redis on a VM, in a container, in > Kubernetes, or on-premises, use the > [Redis OpenTelemetry component guide](../../component/redis.md) which > scrapes raw INFO output via the OTel `redisreceiver`. The two paths > produce different metric sets and the dashboards differ accordingly. > Both can run in the same collector for hybrid deployments. This guide is metrics-only. For ingesting Cache for Redis diagnostic logs (`ConnectedClientList`, `MSEntraAuthenticationAuditLog`), see [Logs](#logs) for the Premium-tier handoff. ### Cache for Redis at a glance Azure Cache for Redis is a fully managed Redis-compatible PaaS: the application connects on TLS port 6380 with a primary access key (or Microsoft Entra ID on Premium), Azure handles patching, replication on Standard and above, persistence on Premium, and clustering on Premium and Enterprise. | Layer | What it produces | | --- | --- | | Listener | TLS connection accept, primary-key auth, optional Entra-ID auth on Premium. | | Command engine | Per-command counters split by command class (GET, SET), hit/miss counters, evictions, expirations. | | Memory subsystem | Used memory bytes + percentage, RSS bytes, eviction events when `maxmemory` trips. | | CPU subsystem | `serverLoad` - Redis is single-threaded, so this approximates per-core CPU saturation. | The receiver does not see per-key or per-database breakdowns - Azure Monitor publishes coarse aggregates. For per-key drill-down on Premium, ship logs via Diagnostic Settings. ### Tier choice Azure Cache for Redis has four pricing tiers as of 2026. Each gates feature availability, which in turn gates which metrics emit data. | Tier | Pricing model (centralindia, May 2026) | Connection cap | Metric coverage | | --- | --- | --- | --- | | **Basic** | C0 ~$16/mo (250 MB), C1 ~$30/mo (1 GB) up to C6 ~$770/mo (53 GB) | C0 256, C1 1000, C2 2000, C3+ 5000-20000 | Core metrics only. No replication, no clustering, no persistence telemetry. | | **Standard** | C1 ~$60/mo (1 GB) up to C6 ~$1700/mo (53 GB) | 1000-20000 depending on size | Same as Basic + replication-lag metrics + 99.9% SLA. | | **Premium** | P1 ~$420/mo (6 GB) up to P5 ~$5500/mo (120 GB) | 7500-40000 | Same as Standard + clustering + persistence (RDB/AOF) + geo-replication + VNet integration + Entra-ID auth + Diagnostic Logs data emission + `cacheLatency` per-shard. | | **Enterprise / Enterprise Flash** | Premium pricing tiers, contact Azure for quotes | 30000+ | Same as Premium + RedisJSON / RedisSearch / RedisBloom modules + Active-Active geo-replication. Ships under the `Microsoft.Cache/redisEnterprise` namespace, **not** covered by this guide. | The receiver configuration is identical across Basic, Standard, and Premium (all under `Microsoft.Cache/Redis`). Tier-gated metrics that the resource does not publish simply emit no data points - there is no error and no zero-valued series. The whitelist below intersects what every tier publishes; expand it for Premium fleets by adding geo-replication and persistence metrics from §[Premium-tier additions](#premium-tier-additions). Pick Basic for development, demo environments, and side projects where the 99.9% SLA is not required. Pick Standard for production workloads that need replication and the SLA but do not need clustering or persistence. Production caches with high throughput, multi-shard working sets, or audit-log requirements live on Premium. ### Receiver configuration Drop this into your existing collector. The receiver, resource processor, and pipeline are all keyed `/cacheforredis` so they coexist with other Azure receivers under one collector and one Scout exporter. The `Microsoft.Cache/Redis` namespace is not currently known to exhibit receiver bug #45942 (the case-mismatched-dimensions bug seen on `Microsoft.ApiManagement/service`, `Microsoft.Network/azureFirewalls`, and a subset of `Microsoft.Storage` metrics on `azuremonitorreceiver` v0.151.0), so no `transform` processor is required for this surface. Re-check on receiver upgrades. ```yaml extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/cacheforredis: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:CACHEFORREDIS_RESOURCE_GROUP} services: - Microsoft.Cache/Redis auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Cache/Redis": cachehits: [Total] cachemisses: [Total] cachemissrate: [Average] connectedclients: [Average, Maximum] evictedkeys: [Total] expiredkeys: [Total] getcommands: [Total] setcommands: [Total] operationsPerSecond: [Average, Maximum] totalcommandsprocessed: [Total] usedmemory: [Average, Maximum] usedmemorypercentage: [Average, Maximum] usedmemoryRss: [Average] serverLoad: [Average, Maximum] errors: [Total] cacheLatency: [Average] processors: resource/cacheforredis: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_cache_for_redis, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:CACHEFORREDIS_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:CACHEFORREDIS_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:CACHEFORREDIS_SERVICE_NAME}", action: insert} service: pipelines: metrics/cacheforredis: receivers: [azure_monitor/cacheforredis] processors: [resource/cacheforredis, batch] exporters: [otlp_http/b14] ``` The `service.name` env var should match what your alert routing expects - `cache-for-redis-monitor` is a reasonable default. The receiver emits 21 OTel series from the 16 whitelist entries (5 metrics are dual-aggregation Average + Maximum, producing two series each). ### Authentication and RBAC The collector authenticates to Azure Monitor as a service principal holding **`Monitoring Reader`** at the **resource group** containing the cache. Resource-group scope is the minimum necessary; subscription scope is acceptable but broader than needed. ```bash az role assignment create \ --assignee "$AZURE_CLIENT_ID" \ --role "Monitoring Reader" \ --scope "$(az group show --name --query id -o tsv)" ``` Two propagation delays apply after first assignment: 1. **Control-plane RBAC propagation** - typically 60-300 seconds before the receiver's `metricDefinitions` and `metrics` REST calls succeed. The receiver retries on its 60-second poll cycle. 2. **First-poll metric-definitions race** - Azure Monitor's metricDefinitions catalog can take 60-180 seconds to populate after `provisioningState: Succeeded`. The receiver caches an empty list if it polls during that window. Mitigation: restart the scraper 3-5 minutes after the cache reaches `Succeeded`, or accept the delay and the next poll cycle picks up the populated catalog. Cache for Redis does NOT require the receiver to know the primary access key. The key is only needed by clients connecting to the cache on port 6380. Scrub it from any collector configuration; the receiver exclusively uses Azure Monitor's REST API. ### What you'll monitor The 16-metric whitelist intersects the universal Cache for Redis metric surface (Basic and above). Five metrics are dual-aggregation (`Average` + `Maximum`) and produce two OTel series each, for 21 emitted series in total. | OTel series | Type | Unit | Use case | | --- | --- | --- | --- | | `azure_cachehits_total` | Counter (Gauge in OTel form) | Count | Throughput numerator for hit-rate calculation. | | `azure_cachemisses_total` | Counter | Count | Throughput denominator for hit-rate; cold-start spike is normal. | | `azure_cachemissrate_average` | Gauge | Percent | Pre-aggregated miss rate. Hit rate = 100 - cachemissrate. | | `azure_connectedclients_average` | Gauge | Count | Steady-state connection load. | | `azure_connectedclients_maximum` | Gauge | Count | SKU-cap saturation signal. | | `azure_evictedkeys_total` | Counter | Count | Memory-pressure back-pressure. Healthy caches show zero. | | `azure_expiredkeys_total` | Counter | Count | TTL lifecycle. Zero on workloads that don't set TTLs. | | `azure_getcommands_total` | Counter | Count | Read load. | | `azure_setcommands_total` | Counter | Count | Write load. | | `azure_operationspersecond_average` | Gauge | Ops/s | Steady-state throughput. | | `azure_operationspersecond_maximum` | Gauge | Ops/s | Burst envelope. | | `azure_totalcommandsprocessed_total` | Counter | Count | Aggregate throughput, including auth and ping overhead. | | `azure_usedmemory_average` | Gauge | Bytes | Working-set size, raw bytes. | | `azure_usedmemory_maximum` | Gauge | Bytes | Peak working-set within the aggregation window. | | `azure_usedmemorypercentage_average` | Gauge | Percent | Fraction of SKU max in use. The capacity-planning signal. | | `azure_usedmemorypercentage_maximum` | Gauge | Percent | Peak fraction of SKU max in use. | | `azure_usedmemoryrss_average` | Gauge | Bytes | Resident set size. Always ≥ used memory; gap = allocator overhead. | | `azure_serverload_average` | Gauge | Percent | Redis CPU-equivalent saturation, steady state. | | `azure_serverload_maximum` | Gauge | Percent | Peak CPU saturation within the aggregation window. | | `azure_errors_total` | Counter, splits by `metadata_errortype` | Count | Failure types (auth, RDB, AOF, failover). All zero on healthy caches; non-zero is the page. | | `azure_cachelatency_average` | Gauge | Microseconds | Internal command-processing latency. **Premium-tier data**; emits a baseline-zero series on lower tiers. | #### Operations notes - The `errors` metric splits across roughly 10 `metadata_errortype` dimensions: `MicrosoftEntraTokenExpired`, `MicrosoftEntraAuthenticationFailure`, `AADTokenExpired`, `AADAuthenticationFailure`, `Failover`, `UnresponsiveClients`, `Import`, `Export`, `RDB`, `AOF`. All zero on a healthy cache. Alert per type; route the page based on which type fired. - `cacheLatency` is documented by Microsoft as Premium-tier-only. The receiver may emit a baseline-zero series on Basic and Standard caches because the metric appears in the catalog. Treat sustained non-zero values as meaningful signal; treat near-zero on Basic / Standard as no-data-equivalent. - `evictedkeys` and `expiredkeys` are absolute counters that reset only on Redis restart - graph them as derivatives (`$perSecond`) to surface change rate. ### Cardinality control Cache for Redis emits resource-level dimensions only - no per-key, per-database, or per-shard breakdowns appear in metrics (Premium clustering produces per-shard splits via `metadata_shardid`, but that's the only built-in cardinality multiplier). The receiver attaches the following per-data-point attributes: | Attribute | Source | Cardinality | | --- | --- | --- | | `azuremonitor.resource_id` | Receiver | One per cache (low). | | `name` | Receiver | One per cache. | | `resource_group` | Receiver | One per RG. | | `type` | Receiver | Constant: `Microsoft.Cache/Redis`. | | `location` | Receiver | One per region. | | `metadata_shardid` | Azure Monitor | `0` on Basic / Standard (single shard); `0..N-1` on Premium clustered caches. | | `metadata_errortype` | Azure Monitor (`errors` only) | ~10 types per cache. | Cardinality stays bounded at 21 series per cache on Basic and Standard (single-shard, no per-error split until errors fire). `metadata_errortype` adds up to ten per-type splits on `azure_errors_total` when the cache produces errors, taking steady state to ~30 datapoints per scrape per cache. Premium clusters with N shards multiply the single-shard total by N - a 10-shard P3 cluster lands at ~210 datapoints per scrape per cache. Well within Scout's per-account default for fleets up to a few hundred caches. If you operate dozens of caches in one collector, scope the receiver to a single resource group per fragment under `_shared/azure/scraper/` to keep query latency predictable. ### Alert tuning Operational alerting on Cache for Redis follows the **RED method on the cache**: Rate (operations per second), Errors (errors counter), Duration (cacheLatency on Premium, serverLoad as a proxy on Basic / Standard). #### RED method on the cache | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **Hit rate** | `100 - azure_cachemissrate_average` | < 70% / 5m | < 50% / 15m | Cold-start excluded; first 30 min after deploy is unreliable. | | **Memory pressure** | `azure_usedmemorypercentage_average` | > 70% / 15m | > 90% / 5m | Eviction starts at 100%. The 90% critical gives time to scale the cache. | | **CPU saturation** | `azure_serverload_average` | > 80% / 15m | > 95% / 5m | Redis is single-threaded; 100% means no headroom. Premium clusters hide saturation behind shard splits. | | **Connection saturation** | `azure_connectedclients_maximum` | ≥ 80% of SKU cap | = SKU cap | Caps: Basic C0 256, C1 1000, Standard C1 1000, Premium P1 7500. Look up the cap for your SKU before setting the threshold. | | **Eviction events** | `$increase(azure_evictedkeys_total)` | > 0 / 5m sustained | > 0 / 1m sustained | Sustained eviction without expiration = under-sized cache. | | **Error events** | `$increase(azure_errors_total)` per `metadata_errortype` | > 0 / 5m | > 0 / 1m | Per-type routing: `RDB` / `AOF` to platform on-call; auth types to identity team. | | **Latency (Premium)** | `azure_cachelatency_average` | > 1000 / 5m (= 1 ms) | > 5000 / 5m (= 5 ms) | Metric publishes in microseconds. Premium-tier only. On lower tiers the metric reads zero or near-zero; alert only when emitting non-zero data. | #### Cold-start exclusion Hit rate alerts must respect cache warm-up. Common pattern: alert on hit rate only after the cache has been receiving traffic for at least 30 minutes (`absent_over_time` or equivalent), and only when the operations counter shows non-trivial throughput. Otherwise a paused service or an off-hours quiet period triggers as a low-hit-rate page. ### Premium-tier additions Premium tier emits additional metrics not exercised in this guide. Add them to the receiver whitelist when monitoring Premium fleets. | Metric (suggested whitelist additions) | Aggregation | What it covers | | --- | --- | --- | | `geoReplicationHealthy` | Average | Geo-replication link status, 0 or 1. | | `geoReplicationConnectivityLag` | Average | Time delta between primary and replica writes. | | `geoReplicationDataSyncOffset` | Average | Bytes-pending between primary and replica. | | `cacheRead` | Total | Bytes read from the cache. | | `cacheWrite` | Total | Bytes written to the cache. | | `usedmemoryscripts` | Average | Memory used by Lua scripts. | | `serverLoad` (per shard) | Average + Maximum | Splits by `metadata_shardid` on clustered Premium caches. | | `connectedclients` (per shard) | Average + Maximum | Splits by `metadata_shardid`. | The receiver does not need configuration changes to handle the per-shard splits - `metadata_shardid` simply takes more values once the cache is clustered. Existing dashboards and alerts that group by `metadata_shardid` work unchanged. For RedisJSON / RedisSearch / RedisBloom module metrics on Enterprise caches, the resource type is `Microsoft.Cache/redisEnterprise` and requires a separate receiver block. Out of scope for this guide. ### Apps-side instrumentation The metrics in this guide describe the cache itself. End-to-end visibility - application latency including cache lookup time, cache keys requested, miss-rate per code path - requires client-side OTel instrumentation in the application. The OTel auto-instrumentation agents for Java, .NET, Python, Node.js, and Go all wrap the standard Redis client libraries (StackExchange.Redis, lettuce, redis-py, ioredis, go-redis) and produce per-call spans with `db.system: redis` and `db.statement` set to the command + key. The cache-side metrics in this guide and the apps-side traces are complementary: cache metrics tell you whether the cache is healthy; apps-side spans tell you which code paths are using the cache and how. Wire both for full coverage. For self-hosted Redis where the cache itself runs in your infrastructure, see the [Redis OpenTelemetry component guide](../../component/redis.md) for INFO-driven scrape configuration. ### Logs On Premium tier, log-driven analysis fills three gaps that metrics do not cover: - **Per-IP audit** is what you reach for when correlating cache usage to specific source addresses. `ConnectedClientList` records every client IP connecting to the cache; the metrics surface only aggregate connection counts. - **Per-key-prefix audit** ties cache traffic to specific service principals or applications via the subscription key prefix used for each connection. The metrics carry no per-key dimension. - **Auth failure attribution** records the principal ID, error reason, and timestamp for every failed Entra-ID auth attempt in `MSEntraAuthenticationAuditLog`. The `azure_errors_total` metric with `metadata_errortype = MicrosoftEntraAuthenticationFailure` shows the count; the log shows who, why, and when. Cache for Redis publishes two Diagnostic Settings categories: | Category | What it contains | Tier emission | | --- | --- | --- | | `ConnectedClientList` | Periodic snapshot of currently-connected clients with source IP and the subscription key prefix. | Premium tier only. Listed by the API on Basic and Standard but no data emits. | | `MSEntraAuthenticationAuditLog` | Microsoft Entra ID authentication attempts against the cache, success and failure. | Premium tier only (Entra ID auth is itself Premium-only). | The recommended pattern on Premium is **Diagnostic Settings to Event Hubs to `azureeventhubreceiver`** in the same collector. The receiver ingests events as OTel logs and routes them to Scout via the same `oauth2client` / `otlphttp/b14` pipeline used for metrics. That configuration lives in a sibling fragment under `_shared/azure/scraper/conf.d/` and is documented separately. On Basic and Standard caches, the categories are listed by the API but emit no log data. Wiring the log pipeline produces no events; stay with the metrics-only configuration in this guide and revisit if the cache is upgraded to Premium. ### Troubleshooting #### `AuthorizationFailed` from the receiver in the first 60 seconds Symptom: scraper logs `AuthorizationFailed` or `403` shortly after provisioning. Cause: `Monitoring Reader` was granted but Azure RBAC is still propagating to the data-plane endpoint. Fix: wait 60-300 seconds. The receiver retries on its next poll cycle. If the error persists after 5 minutes, verify the role assignment with `az role assignment list --assignee --scope `. #### `metrics_definitions_count: 0` on first poll after provisioning Symptom: the receiver logs `metrics_definitions_count: 0` and emits no metrics. Cause: Azure Monitor's metricDefinitions catalog has not yet populated for the freshly-deployed cache (typically true within 60-180 seconds of `provisioningState: Succeeded`). Fix: restart the scraper after the cache has been up for at least 3 minutes, OR wait 5-10 minutes and the next 60-second poll picks up the now-populated catalog. #### `MAX_CLIENTS_REACHED` from the application Symptom: clients fail with `max number of clients reached` or `MAX_CLIENTS_REACHED`. Cause: the cache hit its SKU connection cap. Basic C0 caps at 256 clients; Basic C1 and Standard C1 at 1000; Basic C2 / Standard C2 at 2000; Premium P1 at 7500 scaling to 40000 on P5. Fix: scale the cache up (`az redis update --sku Standard --vm-size C1`), pool clients in the application (one connection multiplexed across requests), or move to Premium for higher caps. Pre-saturation alerting on `azure_connectedclients_maximum` at 80% of the SKU's documented cap gives time to act before traffic fails. #### `cacheLatency` reads near-zero on Basic / Standard Symptom: `azure_cachelatency_average` emits but stays near zero across all polls. Cause: the metric is documented by Microsoft as Premium-tier-only; the receiver still queries it on lower tiers because the catalog entry exists. Fix: this is expected behaviour on Basic and Standard. Either filter the metric out of dashboards on lower-tier caches, or accept the baseline-zero series. The metric becomes meaningful when the cache is upgraded to Premium. #### Hit rate stays low after warm-up Symptom: `100 - azure_cachemissrate_average` reads below 50% for hours after the cache is in steady state. Cause: working-set drift (application asks for keys it never wrote) or TTL aggression (keys expire before they can be reused). Fix: check TTL settings on SET commands; profile which keys the application reads vs writes; consider a key-prefix audit on Premium via `ConnectedClientList` logs. #### Eviction events without memory pressure Symptom: `azure_evictedkeys_total` increments while `azure_usedmemorypercentage_average` reads below 100%. Cause: Azure Cache for Redis aggregates `usedmemorypercentage` over the 1-minute window; brief spikes to 100% can trigger evictions before the metric average reflects them. Fix: cross-reference with `azure_usedmemory_maximum` over the same window; if max hits the SKU cap, eviction is correlated. #### Scout OAuth2 returns 401 Symptom: `oauth2client` extension logs 401 from the token endpoint. Cause: stale `SCOUT_CLIENT_ID` / `SCOUT_CLIENT_SECRET` / `SCOUT_TOKEN_URL`. Fix: re-source `~/.config/base14/scout-otel-config.env` (or the equivalent secret store) and restart the collector. The `oauth2client` extension caches tokens for the configured TTL; restart is the fastest invalidation. ### Frequently Asked Questions #### When should I use Cache for Redis versus a self-hosted Redis on AKS? Pick Azure Cache for Redis when you want a 99.9%+ SLA, automated patching, replication on Standard and above, and Premium-tier features (clustering, persistence, geo-replication) without operating Redis yourself. Pick self-hosted Redis on AKS or VMs when you need RedisJSON / RedisGraph / module support not available in Premium, when you have specific Redis configuration requirements not exposed by the PaaS, or when the unit economics at scale favour self-managed (Premium tier crossovers vary by workload). The metrics paths differ: this guide covers the PaaS surface via `azure_monitor`; self-hosted Redis is covered by the [Redis OpenTelemetry component guide](../../component/redis.md) via `redisreceiver` scraping INFO output. #### What changes between Basic, Standard, Premium, and Enterprise for monitoring? Basic and Standard publish identical metric sets (the metric whitelist in this guide covers both). Premium adds clustering (`metadata_shardid` splits), persistence (`RDB` and `AOF` error types become non-zero on disk-write failure), geo-replication metrics, Diagnostic Logs data emission (`ConnectedClientList`, `MSEntraAuthenticationAuditLog`), and Microsoft Entra ID authentication. Enterprise ships under a different resource type (`Microsoft.Cache/redisEnterprise`) with module-specific metrics not covered by this guide. For Premium fleets, expand the receiver whitelist with the metrics in §[Premium-tier additions](#premium-tier-additions). #### What metrics are unavailable on Basic tier? Basic tier does not emit data for Premium-only metrics: geo-replication families (`geoReplicationHealthy`, `geoReplicationConnectivityLag`, `geoReplicationDataSyncOffset`), Lua-script memory (`usedmemoryscripts`), and the per-shard splits of `serverLoad` / `connectedclients`. Diagnostic Settings categories are listed but emit no log data. The whitelist in this guide intersects what Basic publishes plus `cacheLatency` (which appears in the catalog on Basic but emits baseline-zero data). #### How do I detect a slow cache versus slow Redis client code? Cache metrics describe the cache itself: `cacheLatency` on Premium (internal command-processing time), `serverLoad` on all tiers (saturation), `connectedclients_maximum` (cap pressure). Sustained high `serverLoad` plus rising `cacheLatency` means the cache is overloaded - scale up or pool clients differently. If cache metrics stay healthy but the application reports slow Redis calls, the bottleneck is between the application and the cache: TLS handshake overhead per connection (use connection pooling), DNS resolution delays (cache the resolved hostname), or network latency between the app's region and the cache's region (collocate where possible). Apps-side OTel spans on the Redis client library distinguish these three cases by showing the wall-clock time of the call. #### How does Cache for Redis compare to AWS ElastiCache for monitoring? Both expose Redis-compatible APIs and ship metrics through the cloud's native monitoring service (Azure Monitor for Cache for Redis, CloudWatch for ElastiCache). The OTel paths differ: this guide uses `azure_monitor` (pull-based, polls every 60 s); ElastiCache uses CloudWatch metrics streams (push-based via Kinesis Firehose, near-real-time). Metric coverage is roughly equivalent at the SLI layer (hit rate, memory, evictions, server CPU); the dimensions and aggregation primitives differ. Scout dashboards normalise both into the same metric names where possible (`azure_cachehits_total` and `aws_elasticache_cachehits_sum` unify under one panel via Scout query overlays). #### How do I add Azure Cache for Redis metrics to my existing OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.Cache/Redis`, route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter, and grant the collector's service principal Monitoring Reader at the resource group containing your cache. The receiver polls Azure Monitor's REST API every 60 seconds. Basic tier emits a smaller metric subset than Standard, Premium, and Enterprise; the receiver returns whatever the resource publishes without erroring on tier-gated metrics. The collector itself does not connect to Redis on port 6380 and does not need the cache's primary access key. #### What is the difference between cache-managed metrics and self-hosted Redis metrics? Azure Cache for Redis publishes metrics through Azure Monitor at a 1-minute aggregation granularity with resource-level dimensions only. Self-hosted Redis exposes raw `INFO` output that the OTel `redisreceiver` scrapes every poll interval, producing per-key and per-database metrics that Azure Monitor does not surface. Pick the `azure_monitor` approach when running PaaS Cache for Redis. Pick the `redisreceiver` approach when running Redis on a VM, in a container, in Kubernetes, or on-premises. Both pipelines can coexist if you operate hybrid deployments. #### Why is my Cache for Redis hit rate under 50% on a freshly-deployed cache? Cold-cache misses dominate the first traffic window after a deploy because every key is a miss until the application has populated the working set. Hit rate climbs as keys are written and read back. Wait for at least 10 to 30 minutes of representative production traffic before reading the cachemissrate metric as an SLI. A hit rate that stays low after warm-up usually means one of two things: the application is asking for keys it never wrote (cache key drift), or TTLs are expiring faster than the access pattern reads the keys back. #### How do I monitor the SKU connection cap on Basic versus Premium? The `connectedclients` metric publishes both Average and Maximum aggregations. Alert on the Maximum approaching the SKU's documented cap: Basic C0 at 256, Basic C1 at 1000, Basic C2 at 2000, Standard C1 at 1000, Premium P1 at 7500 scaling up to 40000 on P5. Once the cap is reached, the application sees MAX_CLIENTS_REACHED errors, so alert on connectedclients_maximum at 80 percent of the cap to leave time to scale the cache or pool clients. Look up the cap for your specific SKU when setting the threshold rather than assuming a single value. #### Should I run Cache for Redis Diagnostic Logs through this metrics collector? No. Cache for Redis exposes two Diagnostic Settings categories - `ConnectedClientList` and `MSEntraAuthenticationAuditLog` - but both emit data only on Premium tier per Microsoft documentation. On Premium, the recommended pattern is Diagnostic Settings forwarding to Event Hubs with the `azureeventhubreceiver` ingesting events as OTel logs in the same collector. That fragment is documented separately. On Basic and Standard tiers, the categories are listed by the API but no log data is emitted, so wiring the log pipeline produces nothing useful. Stay with the metrics-only configuration in this guide unless you operate Premium fleets. ### Reference - [Microsoft.Cache/Redis supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-cache-redis-metrics) - [Cache for Redis Diagnostic Settings reference](https://learn.microsoft.com/azure/azure-cache-for-redis/cache-monitor-diagnostic-settings) - [Cache for Redis pricing tiers](https://azure.microsoft.com/pricing/details/cache/) - [opentelemetry-collector-contrib azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - [Self-hosted Redis component guide](../../component/redis.md) - the `redisreceiver` path for non-PaaS deployments. ### Related Guides - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - start here for the cross-surface story. - [Self-hosted Redis](../../component/redis.md) - same metric vocabulary via the `redisreceiver` for VM, container, or on-prem deployments. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure SQL Database](./sql-database.md) - managed relational database. Pairs with the self-hosted [SQL Server guide](../../component/sqlserver.md). - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. --- ## Azure Compute Monitoring with OpenTelemetry - VMs, VM Scale Sets, and Managed Disks ### Overview This guide is the **execution playbook** for Azure Compute (VMs, VM Scale Sets, and Managed Disks). For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running Azure Compute resources in production who want to add VM, VMSS, and Disk telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for the three Compute namespaces (`Microsoft.Compute/virtualMachines`, `Microsoft.Compute/virtualMachineScaleSets`, `Microsoft.Compute/disks`) every 60 seconds, and a sibling pipeline ingests Compute control-plane operations from the subscription Activity Log via Event Hubs as OTel logs. The receiver does not connect to the VM's data plane or the VMSS instances. It queries Azure Monitor for whatever your subscription auto-publishes at the platform layer - CPU percentage, network bytes, disk IOPS, available memory - so the same configuration covers Linux and Windows VMs, every SKU family, and any number of VMSS or Disk resources in the configured scope. > **Looking for guest-OS metrics?** This guide covers what Azure > publishes at the resource level. Guest-OS metrics (per-process CPU, > memory beyond `Available Memory Bytes`, custom Linux perf counters, > Windows perf counters) require an in-guest agent: either Azure > Monitor Agent (AMA) with a Data Collection Rule, or an in-guest > OpenTelemetry collector running > [hostmetricsreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/hostmetricsreceiver). > Both are out of scope here. The resource-level signal is sufficient > for capacity planning, SLO tracking, and SKU-level performance work. This guide ships both paths: metrics via the `azure_monitor` receiver and Compute control-plane audit logs via the `azure_event_hub` receiver fed from a **subscription-scope** Diagnostic Setting. See [Receiver configuration](#receiver-configuration) for metrics and [Logs](#logs) for the audit path. ### Compute resources at a glance The three resource types in this guide are typically monitored together: | Resource type | What it is | Why monitor it together | | --- | --- | --- | | `Microsoft.Compute/virtualMachines` | Standalone VM, single OS instance, single network interface, optionally one or more attached data disks. | The standalone VM is the unit of capacity for fixed-fleet workloads (databases, lift-and-shift apps, CI runners). | | `Microsoft.Compute/virtualMachineScaleSets` | Group of identical VMs managed as one logical resource, with manual or autoscaled capacity. | VMSS aggregates capacity for elastic workloads (App Service Premium plans run on VMSS underneath, AKS node pools are VMSS, batch jobs commonly use VMSS). | | `Microsoft.Compute/disks` | Managed Disk - the storage backing for VM OS disks and any explicitly attached data disks. | Per-disk metrics surface IOPS and bandwidth at the disk-resource layer; VM-level disk metrics aggregate across all attached disks but lose the per-disk split. | The three namespaces share most metric names. A single-fragment multi-namespace receiver is the recommended shape: one `services:` block listing all three, one `metrics:` block keyed by namespace. Output is split downstream by `azuremonitor.resource_id`. > **Implicit OS disks.** Every VM provisioned with the standard image > reference automatically creates an OS disk that Azure surfaces as a > `Microsoft.Compute/disks` resource. The receiver scrapes it > alongside any data disks you explicitly attached. Customers who > manage 50 VMs in one RG will see ~50 extra Disks-namespace series > from those auto-created OS disks. Drop `Microsoft.Compute/disks` > from `services:` if VM-level `Disk Read Bytes` / `Disk Write Bytes` > are sufficient for your case and the OS disk per-resource view is > noise. ### SKU choice and conditional metrics Azure offers ~40 VM SKU families across general-purpose, compute- optimized, memory-optimized, storage-optimized, GPU, and confidential compute, plus several Managed Disk tiers (Standard HDD, Standard SSD, Premium SSD P-series, Premium SSD v2, Ultra Disk). The whitelist in [Receiver configuration](#receiver-configuration) covers what every modern SKU emits at the resource level. **Several metrics are SKU-conditional - they only emit on specific instance types or disk tiers.** Add them to your whitelist when you operate the relevant SKU; they cost nothing on SKUs where they don't emit (Azure Monitor returns no series, the receiver shows zero datapoints for them). | Metric | Emits on | Add to whitelist? | | --- | --- | --- | | `Available Memory Bytes` | Current-generation Hyper-V Linux and Windows images (Ubuntu 22.04+, RHEL 8+, Windows Server 2019+). Older images may not emit it at all without Azure Monitor Agent. | **Yes by default** - included in the main whitelist. Verify on your image; drop and document in your runbook if absent. | | `CPU Credits Consumed`, `CPU Credits Remaining` | All B-series SKUs (any `Standard_B*` family - the burstable line, including the ARM-based `Bp*_v2` and `Bp*_v3` variants). | **Yes for B-series fleets.** Critical for capacity work - `CPU Credits Remaining` approaching zero is the leading indicator of the next throttling event. Absent on D-series, E-series, F-series, and every non-burstable SKU. | | `Disk Used Burst IO Credits Percentage`, `Disk Used Burst Bandwidth Percentage` | Premium SSD disks using **credit-based bursting** (default for P1-P50; the metrics emit when bursting is actively draining the credit pool). | **Yes for Premium SSD fleets** with workload that crosses baseline. `az monitor metrics list-definitions --resource ` shows whether your tier exposes them. | | `Disk On-demand Burst Operations`, `DiskPaidBurstIOPS` | Premium SSD P30+ disks with **on-demand bursting enabled** (`burstingEnabled: true` on the disk resource). On-demand bursting is opt-in and paid per-burst; these metrics record the count and rate of paid operations. | **Yes for Premium SSD P30+ fleets** that have explicitly enabled on-demand bursting. Absent on disks left at the default (credit-based) bursting behaviour, and on Premium SSD v2 / Ultra Disk (those have configurable per-disk IOPS / throughput settings rather than burst pools). | | `OS Disk Read/Write Bytes/sec`, `OS Disk Read/Write Operations/Sec`, `Data Disk *`, `Temp Disk *` | All VMs (per-disk-class breakdown of the VM-aggregate `Disk *` metrics in the main whitelist). | **Optional**. Useful when you want to attribute I/O between OS, data, and temp disks at the VM level without enabling per-disk Disks-namespace scrape. Adds 12 series per VM. | Pick the SKU family for application performance, not telemetry. Burstable B-series VMs are economical for variable workloads and emit two extra metrics that are operationally important for that family. Premium SSD P30+ with on-demand bursting trades higher per-second cost for headroom over baseline; the bursting metrics tell you whether the extra cost is being earned. D-series, E-series, and other non-burstable SKUs trade the credits metrics for steady-state performance and need fewer SKU-specific extras. ### Receiver configuration Drop this into your existing collector. The receiver, resource processor, and pipeline are all keyed `/compute` so they coexist with other Azure receivers under one collector and one Scout exporter. The three Compute namespaces are **not currently known to exhibit receiver bug #45942** (the case-mismatched-dimensions bug seen on `Microsoft.ApiManagement/service`, `Microsoft.Network/azureFirewalls`, and a subset of `Microsoft.Storage` metrics on `azuremonitorreceiver` v0.151.0), so no `transform` processor is required. Re-check on receiver upgrades. ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/compute: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:COMPUTE_RESOURCE_GROUP} services: - Microsoft.Compute/virtualMachines - Microsoft.Compute/virtualMachineScaleSets - Microsoft.Compute/disks auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Compute/virtualMachines": Percentage CPU: [Average, Maximum] Network In Total: [Total] Network Out Total: [Total] Disk Read Bytes: [Total] Disk Write Bytes: [Total] Disk Read Operations/Sec: [Average] Disk Write Operations/Sec: [Average] Available Memory Bytes: [Average] "Microsoft.Compute/virtualMachineScaleSets": Percentage CPU: [Average, Maximum] Network In Total: [Total] Network Out Total: [Total] Disk Read Bytes: [Total] Disk Write Bytes: [Total] Disk Read Operations/Sec: [Average] Disk Write Operations/Sec: [Average] Available Memory Bytes: [Average] "Microsoft.Compute/disks": Composite Disk Read Bytes/sec: [Average] Composite Disk Write Bytes/sec: [Average] Composite Disk Read Operations/sec: [Average] Composite Disk Write Operations/sec: [Average] processors: resource/compute: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_compute, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:COMPUTE_REGION}", action: insert} - {key: service.name, value: "${env:COMPUTE_SERVICE_NAME}", action: insert} service: pipelines: metrics/compute: receivers: [azure_monitor/compute] processors: [resource/compute, batch] exporters: [otlp_http/b14] ``` The 20-metric whitelist (8 VM + 8 VMSS + 4 Disk) renames to **13 unique OTel metric names** because the OTel-side names collapse the VM and VMSS-namespace duplicates - same metric kind, different Azure resource type. The receiver tags every datapoint with `azuremonitor.resource_id` to preserve the per-resource split. Per-scrape datapoint count scales with resource count and VMSS instance fan-out - see [Cardinality control](#cardinality-control) for the math. > **Burstable B-series fleets.** Add these to the > `Microsoft.Compute/virtualMachines` map if you operate B-series VMs: > > ```yaml > CPU Credits Consumed: [Average] > CPU Credits Remaining: [Average] > ``` > > The two metrics are not emitted on D-series or other non-burstable > SKUs and produce no series for those resources; safe to enable > globally if your fleet is mixed. > > **No fixed `cloud.resource_id` on the resource processor.** Unlike > single-resource-type fragments (Key Vault, Storage), this guide > scrapes three different resource types (VM + VMSS + Disk) under one > receiver. The receiver auto-injects `azuremonitor.resource_id` on > each datapoint with the correct per-resource ID; hard-coding > `cloud.resource_id` from a single env var would tag every series > with the same ID and break per-resource splitting downstream. Leave > it off the resource processor when the receiver covers more than > one resource type. ### Authentication and RBAC The collector authenticates to Azure Monitor as a service principal holding **`Monitoring Reader`** at the **resource group** containing the Compute resources. Resource-group scope is the minimum necessary; subscription scope is acceptable but broader than needed. ```bash az role assignment create \ --assignee "$AZURE_CLIENT_ID" \ --role "Monitoring Reader" \ --scope "$(az group show --name --query id -o tsv)" ``` `Monitoring Reader` is sufficient for the metrics path (`azuremonitorreceiver`). The collector **never** touches VM data planes - it cannot SSH or RDP, cannot read disk contents, cannot list VMSS instances by name beyond what the metric dimensions expose. None of the `Virtual Machine Contributor`, `Reader and Data Access`, or data-plane-equivalent roles are required. The logs path adds a separate auth requirement at subscription scope - see [Logs](#logs). Two propagation delays apply to the metrics path after first assignment: 1. **Control-plane RBAC propagation** - typically 60-300 seconds before the receiver's `metricDefinitions` and `metrics` REST calls succeed. The receiver retries on its 60-second poll cycle. 2. **First-poll metric-definitions race** - Azure Monitor's metricDefinitions catalog can take 60-180 seconds to populate after a freshly-deployed VM or VMSS reaches `provisioningState: Succeeded`. The receiver caches an empty list if it polls during that window. Mitigation: restart the collector 3-5 minutes after the resources reach `Succeeded`, or accept the delay and the next poll cycle picks up the populated catalog. ### What you'll monitor The 20-metric whitelist intersects what every Linux and Windows VM SKU emits at the resource level. `Percentage CPU` is dual-aggregation on both VM and VMSS namespaces (`Average` + `Maximum`), producing two series. The other metrics are single-aggregation. After OTel-side renaming the receiver emits **13 unique metric names** (the VM and VMSS namespaces share names like `azure_percentage_cpu_average`; the receiver keeps the data points separate via the per-datapoint `azuremonitor.resource_id` attribute). #### VMs (`Microsoft.Compute/virtualMachines`) | OTel series | Type | Unit | Use case | | --- | --- | --- | --- | | `azure_percentage_cpu_average` | Gauge | Percent | Mean CPU over the 1-minute window. Primary saturation signal. | | `azure_percentage_cpu_maximum` | Gauge | Percent | Peak CPU within the window. Spike-detection. | | `azure_network_in_total_total` | Counter | Bytes | NIC-level ingress bytes. Sum across all NICs on the VM. | | `azure_network_out_total_total` | Counter | Bytes | NIC-level egress bytes. | | `azure_disk_read_bytes_total` | Counter | Bytes | VM-aggregate read bytes across OS + every attached data disk. | | `azure_disk_write_bytes_total` | Counter | Bytes | VM-aggregate write bytes. | | `azure_disk_read_operations` | Gauge | Ops/sec | VM-aggregate read IOPS. | | `azure_disk_write_operations` | Gauge | Ops/sec | VM-aggregate write IOPS. | | `azure_available_memory_bytes_average` | Gauge | Bytes | Guest memory available to the OS. Emits without AMA on current-gen Hyper-V Linux and Windows images. | #### VMSS (`Microsoft.Compute/virtualMachineScaleSets`) Same eight metrics as VMs, aggregated across all instances. The `metadata_vmname` dimension splits per-instance (`_0`, `_1`, etc.) for instance-level breakdowns within the scale-set view. Per-instance namespace (`Microsoft.Compute/virtualMachineScaleSets/virtualMachines`) is **not in this whitelist** - see [Per-VMSS-instance scrape](#per-vmss-instance-scrape) below. #### Managed Disks (`Microsoft.Compute/disks`) | OTel series | Type | Unit | Use case | | --- | --- | --- | --- | | `azure_composite_disk_read_bytes` | Gauge | Bytes/sec | Per-disk read bandwidth. Reports zero when guest I/O is below the disk-tier baseline. | | `azure_composite_disk_write_bytes` | Gauge | Bytes/sec | Per-disk write bandwidth. Same baseline behaviour. | | `azure_composite_disk_read_operations` | Gauge | Ops/sec | Per-disk read IOPS. | | `azure_composite_disk_write_operations` | Gauge | Ops/sec | Per-disk write IOPS. | > **Composite Disk metrics on lightly-loaded disks may read zero.** > Production workloads at or above the disk tier's baseline (Premium > SSD P4: 25 MB/s, 120 IOPS; P10: 100 MB/s, 500 IOPS; P30: 200 MB/s, > 5000 IOPS) emit accurate `Composite Disk *` series. On idle or > lightly-loaded disks running well below baseline, Azure Monitor > may publish zero rather than the actual low rate. If you observe > zero on a disk you expect to be busy, cross-check via the VM-level > `azure_disk_*_bytes_total` / `azure_disk_*_operations` series to > confirm whether the I/O is genuinely zero or whether the > Disks-namespace metric is below its emit threshold for this tier. > Burst credit and on-demand bursting metrics are SKU-conditional - > see [SKU choice and conditional metrics](#sku-choice-and-conditional-metrics). #### Operations notes - **VMSS implicit per-instance NICs and Public IPs.** Scaling a VMSS up or down implicitly creates and deletes per-instance `Microsoft.Network/networkInterfaces` and `Microsoft.Network/publicIPAddresses` resources. These show up in the subscription Activity Log (and are filtered out by the logs-path filter processor below) but do not affect the metrics path - the receiver scrapes only the parent VMSS resource for metric purposes. - **OS disk auto-discovery.** Every VM creates an implicit OS disk that Azure surfaces as a `Microsoft.Compute/disks` resource. Expect `resources_count` to be `(data disks + 1 per VM)` when the receiver scopes to the Compute namespaces. - **Available Memory Bytes is Hyper-V image-version conditional.** On current-gen Linux and Windows images (Ubuntu 22.04+, RHEL 8+, Windows Server 2019+) the metric emits without AMA. On older images it may not emit at all. Verify presence on your chosen image: ```bash az monitor metrics list-definitions --resource \ --query "[?name.value=='Available Memory Bytes']" ``` Drop from the whitelist if absent and document the gap in your runbook so future debugging knows the metric is unavailable on this image. ### Cardinality control Compute metrics are bounded by the small per-VM dimension set the receiver emits, plus the per-instance fan-out on VMSS via `metadata_vmname`. | Attribute | Source | Cardinality | | --- | --- | --- | | `azuremonitor.resource_id` | Receiver | One per Compute resource (low). | | `name` | Receiver | One per resource. | | `resource_group` | Receiver | One per RG. | | `type` | Receiver | Constant per namespace: `Microsoft.Compute/virtualMachines`, `Microsoft.Compute/virtualMachineScaleSets`, `Microsoft.Compute/disks`. | | `location` | Receiver | One per region. | | `metadata_vmname` | Azure Monitor (VMSS only) | One per VMSS instance. **The fan-out vector** - a 50-instance VMSS produces 50× the per-metric series count. | A 10-VM RG with five 4-instance VMSSes and ~25 disks lands at: - VM: 10 resources × 9 series = 90 datapoints/scrape - VMSS: 5 resources × 9 series × 4 instances = 180 datapoints/scrape (with `metadata_vmname` fan-out) - Disk: 25 resources × 4 series = 100 datapoints/scrape Total: ~370 datapoints/scrape per minute = ~22k datapoints/hour - well within Scout's default capacity for any reasonable plan. #### Per-VMSS-instance scrape The `Microsoft.Compute/virtualMachineScaleSets/virtualMachines` sub-namespace exposes per-instance metrics with the same names as the VM and VMSS namespaces. Adding it to `services:` enables a per-instance view useful for diagnosing heterogeneous behaviour across instances (one instance hot, others idle) - the kind of investigation that the VMSS aggregate hides. The trade-off is cardinality. Each instance produces a full series set per metric. A 50-instance VMSS with the 8-metric whitelist produces 400 extra datapoints per scrape. For fixed-size scale sets in fault-tolerance mode (DBs on VMSS, etc.) this is fine; for elastic scale sets that grow into the hundreds of instances, the receiver's scrape duration grows proportionally and your storage cost grows linearly with instance count. Enable per-instance only when the investigation requires it; drop it once closed. ```yaml services: - Microsoft.Compute/virtualMachines - Microsoft.Compute/virtualMachineScaleSets - Microsoft.Compute/virtualMachineScaleSets/virtualMachines # opt-in - Microsoft.Compute/disks ``` ### Alert tuning Operational alerting on Compute follows the **USE method on each resource type**: Utilization, Saturation, Errors. For VMs and VMSS, saturation manifests as CPU near 100% or memory near zero; errors are sparse at the platform layer (Azure surfaces them in the Activity Log, not in metrics). #### Per-resource thresholds | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **CPU saturation** | `azure_percentage_cpu_average` (or `_maximum`) | > 70% / 5m | > 85% / 5m | The `_maximum` aggregation catches short spikes the `_average` smooths over. Use `_maximum` for spike-sensitive workloads (latency-critical APIs); use `_average` for batch / ETL where short bursts are expected. | | **Memory pressure** | `azure_available_memory_bytes_average` | < 20% of VM RAM | < 10% of VM RAM | Compute the threshold against the SKU's documented RAM (e.g. 8 GB on D2s_v3). Sustained low available memory indicates the OS is approaching swap / OOM. | | **Disk IOPS saturation** | `azure_disk_read_operations` + `azure_disk_write_operations` (sum) | > 70% of SKU IOPS limit | > 85% of SKU IOPS limit | SKU IOPS limits are documented per SKU (e.g. D2s_v3 baseline is 3200 IOPS). Use the appropriate Disks-namespace metric for per-disk view (`azure_composite_disk_*_operations`) when the VM hosts multiple disks. | | **Disk bandwidth saturation** | `azure_disk_read_bytes_total` + `azure_disk_write_bytes_total` rate | > 70% of SKU bandwidth limit | > 85% of SKU bandwidth limit | Convert the totals to bytes/sec at the query layer (`rate()` or `irate()` in Prometheus query languages, equivalent in Scout's query). | | **Network egress anomaly** | `azure_network_out_total_total` rate | configurable | configurable | Network egress is uncapped on most SKUs but is the cost vector for cross-region or internet egress. Alert on absolute byte/sec deltas over a baseline rather than fixed thresholds. | #### SKU-conditional thresholds Add these alert rules when the relevant SKU is in your fleet. The underlying metrics must be added to the whitelist - see [SKU choice and conditional metrics](#sku-choice-and-conditional-metrics). | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **B-series CPU credit drain** | `azure_cpu_credits_remaining_average` | < 25% of the SKU's max credits | < 10% of max | Credit drain is the leading throttling indicator. Compute the threshold against your SKU's max credits (look up the figure for your SKU in [Azure's B-series documentation](https://learn.microsoft.com/azure/virtual-machines/sizes-b-series-burstable) - it varies from ~144 on B1s to several thousand on the larger Bms variants). The VM enters baseline-throttled mode when credits hit zero. | | **Premium SSD credit-based burst drain** | OTel-renamed `Disk Used Burst IO Credits Percentage` series | > 70% / 5m | > 90% / 5m | Continuous credit consumption indicates the workload exceeds the disk tier's baseline IOPS. Either size up the disk or accept the eventual rate-limit when credits drain. The bandwidth-side counterpart (`Disk Used Burst Bandwidth Percentage`) follows the same threshold shape; many workloads saturate one before the other. | | **Spot eviction rate** | Count of Activity Log records with `operationName` matching `Microsoft.Compute/virtualMachines/preemptedSpotVm/action` (or the deallocate that follows the eviction) on Spot resources | > 1 / 1h | > 5 / 1h | Sourced from the logs path, not metrics. Frequent eviction means Azure is reclaiming capacity often; either tolerate restart cost in your batch design or move latency-sensitive paths to on-demand. | #### VMSS-specific tuning VMSS aggregates across instances and obscures heterogeneous behaviour. For most production VMSS, alerts on the aggregate CPU and memory are sufficient (the autoscaler reacts to averages too); when investigating per-instance issues, temporarily enable the per-instance scrape per [Per-VMSS-instance scrape](#per-vmss-instance-scrape). When the VMSS has autoscale enabled, alert on the **rate of capacity changes** as a secondary signal - frequent scale-in / scale-out oscillation indicates autoscale rule mismatch with workload pattern. The capacity change itself shows up in the Activity Log (`Microsoft.Compute/virtualMachineScaleSets/write`); see [Logs](#logs). ### Specialty SKU classes The metrics whitelist in this guide covers the universal Azure-side metric surface that every Compute SKU emits. Four SKU classes carry considerations beyond the universal set: - **Spot VMs** (`Standard_*` with `priority: Spot`). Same metrics whitelist as on-demand. Eviction events surface via the subscription Activity Log rather than as Azure Monitor metrics - Azure emits a `Microsoft.Compute/virtualMachines/preemptedSpotVm/action` record at the moment of preemption, followed by an implicit `deallocate`. The default filter in [Logs](#logs) passes both records as Microsoft.Compute, so Spot evictions appear automatically in the logs pipeline. Alert on the preemption operationName to catch batch workloads losing capacity. - **Confidential VMs** (`Standard_DC*s_v3`, `Standard_EC*s_v5`). Same metrics whitelist as general-purpose; attestation events surface via Activity Log. The `Microsoft.Compute/virtualMachines` namespace covers them. - **GPU and FPGA SKUs** (`Standard_NC*`, `Standard_NV*`, `Standard_NP*`, `Standard_PB*`). Same CPU + memory + disk + network whitelist as general-purpose - those metrics emit normally. **GPU utilization, GPU memory, and ML-framework metrics are NOT in Azure Monitor** - Azure does not surface in-GPU telemetry at the platform layer. Capture them with an in-guest agent (NVIDIA's `dcgm-exporter` for NVIDIA H100 / A100 / L4 / etc., AMD's ROCm exporter for MI series), scraped via the OTel `prometheusreceiver`. The GPU surface is out of scope for this guide. - **Ultra Disk and Premium SSD v2** (per-disk performance configured separately from the SKU tier). The four `Composite Disk *` metrics emit. Burst-credit metrics from the Premium SSD P-series do not apply - performance is reserved per-disk via configurable IOPS and throughput settings rather than via burst pools. Per-disk operation metrics (`Composite Disk *_operations`) and bandwidth (`*_bytes`) are the same; if you need to alert on configured-vs-consumed performance ratio, derive it at the query layer from the SKU's configured settings (visible via `az disk show --query "{iops:diskIOPSReadWrite, mbps:diskMBpsReadWrite}"`). ### Apps-side instrumentation The metrics in this guide describe the VMs and VMSS themselves. For end-to-end visibility - application latency, request volume, cache hit rates, downstream call timing - instrument your applications with the OTel auto-instrumentation agents for Java, .NET, Python, Node.js, or Go. The agents wrap the standard SDKs and emit traces and metrics that complement the VM-level signal. The VM-side metrics in this guide and the apps-side traces are complementary: VM metrics tell you whether the host is healthy (CPU saturated, memory exhausted, disk thrashing); apps-side spans tell you which code paths run on the host and how long each takes. Wire both for full coverage. See the per-language instrumentation guides under `instrument/{language}/` for SDK setup. ### Logs Resource-level metrics aggregate operations and capacity counters at 1-minute granularity. They cannot answer **who** restarted, resized, scaled, or detached a Compute resource, **from where**, **with what identity**, or **why**. Three operational gaps that the Compute control-plane Activity Log fills where metrics cannot: - **Per-operation control-plane audit** records each `Microsoft.Compute/virtualMachines/restart`, `Microsoft.Compute/virtualMachines/deallocate`, `Microsoft.Compute/virtualMachineScaleSets/scale`, and `Microsoft.Compute/disks/detach` operation with the requester's identity (UPN, app ID, OID), source IP, correlation ID, and result status. The metrics path has no concept of who or why - it sees CPU drop to zero on a deallocate but cannot attribute the action. - **Per-resource lifecycle** preserves the create / update / delete history of every Compute resource, useful for change diagnostics ("when did this VMSS last scale", "who increased the disk size last Tuesday") and capacity audits. - **Implicit Microsoft.Network correlation** is available in the same Activity Log stream - VMSS scaling generates implicit NIC and Public IP create/delete records. The default filter in this guide drops them so the Compute audit signal stays clean; broaden the filter (see [Filter expression](#filter-expression-broadening-and-narrowing)) if you need NIC-level forensics alongside Compute audit. Compute resources do **not** expose per-resource Diagnostic Settings categories. The audit signal lives in the **subscription-scope** Activity Log instead. This is the meaningful difference from the [Storage](./storage.md) and [Key Vault](./key-vault.md) logs paths, which use resource-scope Diagnostic Settings against the storage account or vault directly. The recommended pattern is **subscription Activity Log to Event Hubs to `azure_event_hub` plus a `filter` processor** in the same collector. The receiver ingests events as OTel logs, the filter scopes to Microsoft.Compute records only, and the resource processor tags them with `cloud.platform: azure_compute`. All routes to Scout via the same `oauth2client` / `otlp_http/b14` pipeline used for metrics. ```yaml showLineNumbers title="otel-collector.yaml (logs excerpt)" receivers: azure_event_hub/computelogs: connection: ${env:COMPUTELOGS_CONNECTION_STRING} partition: "" offset: "" format: azure apply_semantic_conventions: true processors: filter/computeonly: error_mode: ignore logs: log_record: - 'resource.attributes["cloud.resource_id"] == nil' - 'not IsMatch(resource.attributes["cloud.resource_id"], ".*/[Mm][Ii][Cc][Rr][Oo][Ss][Oo][Ff][Tt]\\.[Cc][Oo][Mm][Pp][Uu][Tt][Ee]/.*")' resource/computelogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_compute, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: service.name, value: "${env:COMPUTELOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/computelogs: receivers: [azure_event_hub/computelogs] processors: [filter/computeonly, resource/computelogs, batch] exporters: [otlp_http/b14] ``` The `connection` string must include the `EntityPath=` suffix so the receiver knows which hub to consume. The receiver defaults to consuming all partitions from the oldest available offset (`partition: ""`, `offset: ""`); on collector restart it re-reads from the saved offset, providing at-least-once delivery. > **Why the filter expression looks so paranoid.** The > `azure_event_hub` receiver with `format: azure` + > `apply_semantic_conventions: true` places the per-record Azure > resource ID at `resource.attributes["cloud.resource_id"]` (OTel > semantic-conventions form, **not** `azure.resource.id`). The full > resource ID is also UPPERCASED by the receiver. The filter regex > matches case-insensitively against `[Mm]icrosoft\.[Cc]ompute` to > handle the inconsistency in the wild and protect against future > Azure-side changes. The first rule > (`resource.attributes["cloud.resource_id"] == nil`) drops records > that arrive without a resource ID at all (rare but possible during > Azure-side outages). Together the two rules pass only records with a > Microsoft.Compute provider segment and drop everything else. #### Wiring the subscription Diagnostic Setting Subscription-scope Diagnostic Settings use a different `az` subcommand than resource-scope: `az monitor diagnostic-settings subscription create`. Three flag-name differences from resource-scope: | Resource-scope (Storage, Key Vault, etc.) | Subscription-scope (this guide) | | --- | --- | | `--event-hub ` | `--event-hub-name ` | | `--event-hub-rule ` | `--event-hub-auth-rule ` | | (no location flag) | `--location global` | ```bash az monitor diagnostic-settings subscription create \ --name compute-activity \ --location global \ --event-hub-name "$EVENT_HUB_NAME" \ --event-hub-auth-rule "$DIAG_SEND_RULE_ARM_ID" \ --logs '[{"category":"Administrative","enabled":true}]' ``` The `--event-hub-auth-rule` value is the full ARM resource ID of a namespace-level SAS authorization rule with `Send` rights. Microsoft's documentation is imprecise on the flag name (`--event-hub-auth-rule-id` is rejected on `az` CLI 2.85.0); use `--event-hub-auth-rule`. The `Administrative` category covers `create`, `update`, `delete`, `start`, `restart`, `deallocate`, `scale`, `detach`, and similar control-plane operations across every resource provider in the subscription. The collector-side filter processor then scopes it to Microsoft.Compute. Other categories (`Security`, `ServiceHealth`, `Alert`, `Recommendation`, `Policy`, `Autoscale`, `ResourceHealth`) are typically routed elsewhere - see [Why not other categories](#why-not-other-categories). #### Auth for the subscription Diagnostic Setting Creating a subscription-scope Diagnostic Setting requires **`Monitoring Contributor`** at **subscription scope**. This is broader than the metrics path's `Monitoring Reader` at RG scope, and a deliberate split: the role lives on the **operator's signed-in user identity** (a human Microsoft Entra ID account), not on the long-lived service principal that the collector uses for the metrics path. ```bash OPERATOR_OID="$(az ad signed-in-user show --query id -o tsv)" az role assignment create \ --assignee-object-id "$OPERATOR_OID" \ --assignee-principal-type User \ --role "Monitoring Contributor" \ --scope "/subscriptions/$AZURE_SUBSCRIPTION_ID" ``` The role assignment is permanent - the operator's account will continue to hold `Monitoring Contributor` at subscription scope after the Diagnostic Setting is created. Operators who manage compliance boundaries can revoke it once the Diagnostic Setting is in place: ```bash az role assignment delete \ --assignee "$OPERATOR_OID" \ --role "Monitoring Contributor" \ --scope "/subscriptions/$AZURE_SUBSCRIPTION_ID" ``` After revocation, the subscription Diagnostic Setting continues to ship records to Event Hubs; modifying it later requires re-granting the role. #### Diagnostic Settings ship cadence Azure batches subscription Activity Log records and ships them to Event Hubs on a non-real-time cadence. Subscription-scope routing is slower than resource-scope: - **First batch from a freshly-wired subscription Diagnostic Setting: 10-40 minutes**. Resource-scope Diagnostic Settings on Storage and Key Vault ship the first batch within 5-20 minutes; the subscription-scope routing adds an extra hop and stretches the upper bound. Plan for 40 minutes. - **Steady-state batches: 5-15 minutes**. After the first batch, subsequent ones arrive in the documented range. - **End-to-end latency from operation to Scout: 5-15 minutes steady-state, 10-40 minutes for the first batch**. Audit visibility is **not** real-time. For real-time control-plane security monitoring, use Microsoft Defender for Cloud or Azure Sentinel, which read the Activity Log directly with lower latency. The OTel path is appropriate for audit retention, compliance reporting, and forensic analysis where per-event minutes-of-lag is acceptable. #### Filter expression: broadening and narrowing The filter passes only records with `Microsoft.Compute` in the resource ID path. To **broaden** the filter to additional resource providers, add them to the regex alternation: ```yaml - 'not IsMatch(resource.attributes["cloud.resource_id"], ".*/(?:[Mm]icrosoft\\.[Cc]ompute|[Mm]icrosoft\\.[Nn]etwork|[Mm]icrosoft\\.[Ss]torage)/.*")' ``` To **narrow** the filter to specific Compute operations, add a second rule on `attributes["azure.operation.name"]`: ```yaml filter/computeonly: error_mode: ignore logs: log_record: - 'resource.attributes["cloud.resource_id"] == nil' - 'not IsMatch(resource.attributes["cloud.resource_id"], ".*/[Mm][Ii][Cc][Rr][Oo][Ss][Oo][Ff][Tt]\\.[Cc][Oo][Mm][Pp][Uu][Tt][Ee]/.*")' # Drop everything except VM lifecycle ops - 'not IsMatch(attributes["azure.operation.name"], ".*(?i:write|delete|restart|deallocate|start|powerOff)$")' ``` A multi-resource subscription typically sees 70-95% of subscription Activity Log records dropped by this filter - that is normal and the filter is doing real work. #### Why not other categories - **`Security`** records security-relevant events (Defender, Sentinel alerts). These flow through dedicated security pipelines (Sentinel workspace, Defender connectors) rather than the OTel logs path. - **`ServiceHealth`** records Azure service-health events (planned maintenance, regional outages). These are useful but better routed through Azure Service Health alerts or a separate service-health-only Diagnostic Setting. - **`Alert`** records firings of Azure Monitor alert rules. The alert system is the consumer; routing alert firings to Scout via the Activity Log creates feedback loops. - **`Recommendation`** is Azure Advisor output - not real-time operational telemetry. - **`Policy`** records Azure Policy compliance evaluations - belongs in a compliance pipeline, not vault-style audit. - **`Autoscale`** records autoscale rule firings on VMSS / App Service plans. Re-enable this if you operate VMSS autoscale at scale and want autoscale events alongside Compute control-plane audit. - **`ResourceHealth`** records per-resource health-state changes (Healthy / Degraded / Unavailable / Unknown). Worth enabling as a follow-on once Compute audit is in place. ### Troubleshooting #### `AuthorizationFailed` from the receiver in the first 60 seconds Symptom: scraper logs `AuthorizationFailed` or `403` shortly after provisioning. Cause: `Monitoring Reader` was granted but Azure RBAC is still propagating to the data-plane endpoint. Fix: wait 60-300 seconds. The receiver retries on its next poll cycle. If the error persists after 5 minutes, verify the role assignment with `az role assignment list --assignee --scope `. #### `metrics_definitions_count: 0` on first poll after provisioning Symptom: the receiver logs `metrics_definitions_count: 0` and emits no metrics for one or more Compute resources. Cause: Azure Monitor's metricDefinitions catalog has not yet populated for the freshly-deployed VM, VMSS, or Disk. Fix: restart the collector after the resources have been up for at least 3 minutes, OR wait 5-10 minutes and the next 60-second poll picks up the now-populated catalog. #### Receiver discovers more disks than expected Symptom: `resources_count` reports a Disks count higher than the number of Managed Disks you provisioned. Cause: every VM creates an implicit OS disk that Azure surfaces as a `Microsoft.Compute/disks` resource. With 10 VMs in the RG, expect (data disks + 10) Disks- namespace resources. Fix: this is expected. To suppress, drop `Microsoft.Compute/disks` from `services:` and rely on VM-level `azure_disk_*_bytes_total` for disk-I/O volume; per-disk burst metrics are lost in that mode. #### `Available Memory Bytes` series is empty Symptom: `azure_available_memory_bytes_average` returns no data for some VMs. Cause: older Linux or Windows images don't emit guest memory without AMA. Fix: redeploy with a current-gen image (Ubuntu 22.04+, RHEL 8+, Windows Server 2019+), OR install Azure Monitor Agent + Data Collection Rule, OR drop the metric from the whitelist and rely on the OS-level memory tooling. Verify the catalog with `az monitor metrics list-definitions --resource `. #### Compute logs path: empty Event Hubs for 30+ minutes after provisioning Symptom: `azure_event_hub/computelogs` receiver reports zero events for the first 30 or more minutes after the subscription Diagnostic Setting is created. Cause: subscription-scope Diagnostic Settings ship the first batch on a 10-40 minute cadence, slower than the resource-scope 5-20 minutes. Fix: wait. Subsequent batches arrive in 5-15 minutes per Azure's documented cadence. Verify the Diagnostic Setting is configured correctly with `az monitor diagnostic-settings subscription show --name compute-activity`. #### Filter processor drops all log records Symptom: `filter/computeonly` shows incoming records but `outgoing_items_total` stays at zero. Cause: the receiver places the resource ID at `resource.attributes["cloud.resource_id"]`, not `azure.resource.id`. A filter expression targeting the wrong attribute name will match all records and drop them. Fix: use the filter shape in this guide, which checks `resource.attributes["cloud.resource_id"]`. Also verify case- insensitive matching - the receiver UPPERCASES the resource ID, so literal `Microsoft.Compute` will not match a `MICROSOFT.COMPUTE` record. #### Subscription Diagnostic Setting rejects `--event-hub-auth-rule-id` Symptom: `az monitor diagnostic-settings subscription create` fails with `unrecognized arguments: --event-hub-auth-rule-id`. Cause: the flag is `--event-hub-auth-rule` (no `-id` suffix) on `az` CLI 2.85.0. Documentation in some sources mis-names the flag. Fix: use `--event-hub-auth-rule "$DIAG_SEND_RULE_ARM_ID"` exactly. #### Scout OAuth2 returns 401 Symptom: `oauth2client` extension logs 401 from the token endpoint. Cause: stale `SCOUT_CLIENT_ID` / `SCOUT_CLIENT_SECRET` / `SCOUT_TOKEN_URL`. Fix: re-source the Scout credential env file (or the equivalent secret store) and restart the collector. ### Frequently Asked Questions #### How do I monitor Azure VMs, VMSS, and Managed Disks with OpenTelemetry? Add the `azure_auth` extension and a single `azure_monitor` receiver with three namespaces under `services:` - `Microsoft.Compute/virtualMachines`, `Microsoft.Compute/virtualMachineScaleSets`, and `Microsoft.Compute/disks` - route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter, and grant the collector's service principal `Monitoring Reader` at the resource group containing your Compute resources. The receiver polls Azure Monitor every 60 seconds. The whitelist in this guide covers what every modern Linux and Windows VM SKU emits at the resource level (CPU, network, disk, memory). Guest-OS-level metrics beyond what Azure publishes (per-process CPU, memory beyond `Available Memory Bytes`, custom counters) require an in-guest agent and are out of scope. #### Why does my Compute receiver discover more disks than I provisioned? Every Azure VM has an implicit OS disk that Azure surfaces as a `Microsoft.Compute/disks` resource even though customers usually never declare it explicitly in their templates. The receiver scrapes it alongside any data disks you attached. Expect `resources_count` to be `(data disks + 1 per VM)` when scoping to Compute namespaces. Filter or scope per-RG if a multi-VM RG produces too many OS-disk series; alternatively, drop `Microsoft.Compute/disks` from `services:` entirely and rely on VM-level `azure_disk_*_bytes_total` for guest-I/O volume. #### What's the difference between resource-level and guest-OS metrics? Azure's resource-level metrics (`Percentage CPU`, `Network In Total`, `Disk Read Bytes`, etc.) are published by the Azure platform without any in-guest agent and are what the `azure_monitor` receiver in this guide collects. Guest-OS metrics (per-process CPU, memory beyond `Available Memory Bytes`, custom Linux performance counters, Windows perf counters) require either Azure Monitor Agent (AMA) plus a Data Collection Rule or an in-guest OpenTelemetry collector running `hostmetricsreceiver`. AMA is Azure-native; `hostmetricsreceiver` is OTel-native and ships directly via OTLP. Both are out of scope for this guide; the resource-level signal is sufficient for capacity, throttling, and SLO work on standard SKUs. #### How do I audit Compute control-plane operations? Compute resources don't expose per-resource Diagnostic Settings categories like Storage or Key Vault do. The audit signal lives in the subscription-scope Activity Log instead. Configure a subscription Diagnostic Setting forwarding the `Administrative` category to an Event Hubs hub, then point the `azure_event_hub` receiver at the hub. Apply a collector-side `filter` processor scoped to `cloud.resource_id` matching `Microsoft.Compute` so unrelated subscription activity is dropped. Subscription-scope routing is slower than resource-scope (10-40 min for first batch versus 5-15 min for resource-scope) so audit visibility is not real-time. Use Microsoft Defender for Cloud or Azure Sentinel for real-time control-plane security monitoring; the OTel path in this guide is appropriate for retention, compliance reporting, and forensic analysis. #### Why does my filter processor drop most subscription Activity Log records? The subscription Activity Log captures every resource provider in your sub - Microsoft.Compute, Microsoft.Network, Microsoft.Storage, Microsoft.KeyVault, and so on - while the filter in this guide passes only Microsoft.Compute records. On a multi-resource subscription it is normal to see drop ratios of 70-95%. Even on a Compute-only subscription, VMSS scaling implicitly creates and deletes Microsoft.Network NICs and Public IPs, which produce records the filter drops. To broaden the filter, add resource providers to the regex (`Microsoft.Compute|Microsoft.Network`); to narrow it further, scope by `operationName` via an additional rule. The filter must reference `resource.attributes["cloud.resource_id"]` not log-record attributes, because the receiver places the resource ID on the resource attributes set under `format: azure` with `apply_semantic_conventions: true`. #### Should I scrape per-VMSS-instance metrics? Not by default. The `Microsoft.Compute/virtualMachineScaleSets/virtualMachines` sub-namespace exposes per-instance metrics with the same names as the VM and VMSS namespaces, but cardinality fans out as one extra series per instance per metric. A 50-instance VMSS with the 8-metric whitelist produces 400 extra series per scrape just from per-instance views. The VMSS-resource-level aggregate (this guide's default) is sufficient for capacity work; per-instance scrape is meaningful only when you suspect heterogeneous behaviour across instances (one instance hot, others idle), in which case enable it for the affected VMSS and drop it again once the investigation closes. Add `Microsoft.Compute/virtualMachineScaleSets/virtualMachines` to `services:` to enable; keep an eye on receiver scrape duration. ### Reference - [Microsoft.Compute/virtualMachines supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-compute-virtualmachines-metrics) - [Microsoft.Compute/virtualMachineScaleSets supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-compute-virtualmachinescalesets-metrics) - [Microsoft.Compute/disks supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-compute-disks-metrics) - [Azure Monitor Activity Log schema](https://learn.microsoft.com/azure/azure-monitor/essentials/activity-log-schema) - [Subscription Diagnostic Settings reference](https://learn.microsoft.com/azure/azure-monitor/essentials/activity-log#diagnostic-settings) - [opentelemetry-collector-contrib azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - [opentelemetry-collector-contrib azureeventhubreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azureeventhubreceiver) ### Related Guides - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - start here for the cross-surface story. - [Azure Kubernetes Service](./aks.md) - managed Kubernetes built on VMSS underneath; Compute metrics on the VMSS namespace surface per-node-pool capacity in addition to the in-cluster signal. - [Azure Application Gateway](./application-gateway.md) - WAF + L7 load balancer commonly fronting VMSS-backed application tiers. - [Azure Load Balancer](./load-balancer.md) - L4 load balancer fronting VM and VMSS backends. - [Azure Storage](./storage.md) - object / blob / queue / table / file storage; per-resource Diagnostic Settings logs path companion to this guide's subscription-scope path. --- ## Azure Container Registry Monitoring with OpenTelemetry - Pull/Push Metrics and Audit Logs ### Overview This guide is the **execution playbook** for Azure Container Registry, the managed OCI (Open Container Initiative) registry behind your image pulls and pushes. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers who run a container registry in production and want pull/push, ACR Tasks, and storage telemetry plus a control-plane audit trail in an existing OpenTelemetry Collector, shipped to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.ContainerRegistry/registries` every 60 seconds, and a sibling pipeline ingests registry audit operations from a resource-scope Diagnostic Setting via Event Hubs as OTel logs. A managed registry has two real telemetry paths, and the third - the one that does not exist - is part of the decision: - **Platform metrics - Azure Monitor.** Pull/push counts, ACR Tasks run duration, accumulated storage. The default operational view of registry health and throughput. - **Repository and login audit - resource-scope Diagnostic Settings.** `ContainerRegistryRepositoryEvents` and `ContainerRegistryLoginEvents` through Event Hubs. The forensic and access-audit trail - who pushed or pulled what, and who logged in. - **There is no in-system scrape path.** A managed registry exposes no internal endpoint to scrape the way a self-hosted database does. The complementary signal is client-side: the CI pipeline that pushes and pulls can emit its own OpenTelemetry spans. That is an application-instrumentation concern, not a registry scrape - see the per-language guides under `instrument/{language}/`. > **Pull and push counts are traffic-gated.** In any minute with no > pull or push, `TotalPullCount` and `TotalPushCount` are zero. An > idle registry publishes zero counts and a flat storage gauge. This > is the single most important interpretation caveat: an empty count > in a minute with no pull or push is expected behaviour, not a receiver, > whitelist, or RBAC failure. > > **Metrics and audit logs need different traffic.** This is the > defining operational fact of this surface. `az acr import` and ACR > Tasks builds (`az acr build`) are server-side control-plane > operations: they move the pull/push **metric** counters but produce > **no audit log records**. The `ContainerRegistryRepositoryEvents` > and `ContainerRegistryLoginEvents` categories fire only on genuine > data-plane repository operations (`docker push`, `docker pull`, > delete, untag) and the token-exchange logins that authenticate them. > A CI pipeline built entirely on `az acr import` or ACR Tasks will > correctly show healthy pull/push metrics and no audit logs - that is > expected, and the §Logs section below tells you how to read it. ### What you'll monitor The table is keyed by the Azure metric name (the authoritative name from Microsoft's supported-metrics reference). The receiver emits each as a lowercase snake-cased `azure_*` series with the aggregation suffixed. | Azure metric | Aggregation | Use case | | --- | --- | --- | | `TotalPullCount` | Total | All image pull attempts. Traffic-gated - zero in any minute with no pulls. | | `SuccessfulPullCount` | Total | Pulls that returned success. `Total` minus `Successful` is the pull failure count. | | `TotalPushCount` | Total | All image push attempts. Traffic-gated. | | `SuccessfulPushCount` | Total | Pushes that returned success. The push failure count is the gap to `Total`. | | `RunDuration` | Total | ACR Tasks run wall-clock (milliseconds). Emits only when ACR Tasks run; one value per task run. | | `AgentPoolCPUTime` | Total | Dedicated ACR Tasks agent-pool CPU seconds. **Emits only with dedicated agent pools** - Quick-Task builds use the shared pool and do not drive it. Task-conditional, keep in the whitelist. | | `StorageUsed` | Average | Accumulated registry storage (bytes). The capacity-trend gauge. **Computed on a slow internal cadence** - a freshly populated registry shows an empty or flat series for tens of minutes to hours. Not a real-time signal. | `RunDuration`, `AgentPoolCPUTime`, and `StorageUsed` are **conditional by design**, not gaps: - `RunDuration` is zero on a registry used purely as an image store (no ACR Tasks). It is the task-execution signal, not a registry-health one. - `AgentPoolCPUTime` needs dedicated agent pools. Shared-pool Quick-Task builds never drive it. Keep it whitelisted - a metric that never emits produces no series, so it adds no cardinality or query cost - but do not alert on it unless you run dedicated pools. - `StorageUsed` populates on Azure Container Registry's own storage-accounting cadence. Treat an absent or flat series on a new or low-churn registry as expected; it is a slow trend line, not a live counter. ### Receiver configuration Drop this into your existing collector. The receiver, resource processor, and pipeline are all keyed `/acr` so they coexist with other Azure receivers under one collector and one Scout exporter. `Microsoft.ContainerRegistry/registries` emits **no `metadata_*` dimensions** (six of the seven metrics carry no dimensions at all; `StorageUsed` carries a single `Geolocation` dimension). The duplicate-case-dimension defect that `azuremonitorreceiver` exhibits on some Azure namespaces (a metric emitting both `metadata_Foo` and `metadata_foo`) therefore cannot occur here, so no `transform` processor is required. Re-verify after a receiver upgrade if you add metrics. ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/acr: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:ACR_RESOURCE_GROUP} services: - Microsoft.ContainerRegistry/registries auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.ContainerRegistry/registries": TotalPullCount: [Total] SuccessfulPullCount: [Total] TotalPushCount: [Total] SuccessfulPushCount: [Total] RunDuration: [Total] AgentPoolCPUTime: [Total] StorageUsed: [Average] processors: resource/acr: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_container_registry, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:ACR_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:ACR_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:ACR_SERVICE_NAME}", action: insert} service: pipelines: metrics/acr: receivers: [azure_monitor/acr] processors: [resource/acr, batch] exporters: [otlp_http/b14] ``` `StorageUsed` supports only the `Average` aggregation; the six counters support `Total`. The whitelist above uses each metric's correct aggregation - Azure Monitor rejects an unsupported aggregation request, so this matters. ### Authentication and RBAC The collector authenticates to Azure Monitor as a service principal holding **`Monitoring Reader`** at the **resource group** containing the registry. Resource-group scope is the minimum necessary; subscription scope works but is broader than needed. ```bash az role assignment create \ --assignee "$AZURE_CLIENT_ID" \ --role "Monitoring Reader" \ --scope "$(az group show --name --query id -o tsv)" ``` `Monitoring Reader` is sufficient for the metrics path. The collector never touches the registry data plane - it does not pull or push images. None of the `AcrPull` / `AcrPush` data-plane roles are required for telemetry. Disable the registry admin user (`adminUserEnabled: false`): it is a shared static credential and a supply-chain risk. Microsoft Entra ID token auth replaces it without changing the metric set. The logs path adds one separate requirement - see [Logs](#logs). A control-plane RBAC propagation delay applies after first assignment: typically 60-300 seconds before the receiver's `metricDefinitions` and `metrics` REST calls succeed. The receiver retries on its 60-second poll cycle. `metricDefinitions` populating and the counters reading non-zero are two independent conditions, and conflating them is the usual first-poll mistake: - **Definitions empty after RBAC propagates.** If a freshly created registry still shows `metrics_definitions_count: 0` after the 60-300 second propagation window, restart the collector once. - **Counters zero but definitions present.** This is not an error - the pull/push counters stay zero until the registry actually carries a pull or push (the traffic-gating caveat in the Overview). Restarting the collector will not change this; only traffic will. ### Cardinality control This namespace is one of the lowest-cardinality Azure surfaces. Six of the seven metrics carry no dimensions; `StorageUsed` carries a single `Geolocation` dimension (one value on Basic and Standard - geo-replica locations on Premium add one series per replica region). | Attribute | Source | Cardinality | | --- | --- | --- | | `azuremonitor.resource_id` | Receiver | One per registry (low). | | `name` | Receiver | One per registry. | | `resource_group` | Receiver | One per RG. | | `Geolocation` (`StorageUsed` only) | Azure Monitor | One on Basic/Standard; one per geo-replica region on Premium. Bounded. | A single registry lands at roughly seven series per scrape (one per metric, plus one extra `StorageUsed` series per geo-replica region on Premium). Series count scales linearly with registry count and is independent of registry traffic, so a fleet stays low-cardinality. ### Alert tuning Container-registry alerting centres on **operation failures** and **ACR Tasks health**. The pull/push counts themselves are workload volume, not an alerting signal. | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **Push failures** | `TotalPushCount` minus `SuccessfulPushCount` | > 0 sustained / 5m | rising / 5m | A healthy registry has `Total` equal to `Successful`. A sustained gap usually means image-size limits, quota, or auth. | | **Pull failures** | `TotalPullCount` minus `SuccessfulPullCount` | > 0 sustained / 5m | rising / 5m | A rising pull-failure delta usually means client auth or throttling - often a misconfigured deployment pulling with the wrong identity. | | **ACR Tasks duration** | `RunDuration` | no fixed threshold - see Notes | no fixed threshold - see Notes | Only meaningful if you run ACR Tasks. There is no absolute threshold: alert on a regression against the build's own rolling baseline (for example, a sustained increase over the task's trailing-7-day median across 3 consecutive runs). | | **Storage growth** | `StorageUsed` | trend | trend | Slow gauge. Use it for capacity-trend alerting (untagged-manifest bloat, missing retention policy), never for real-time signals. | `AgentPoolCPUTime` has no recommended alert unless you run dedicated agent pools; on shared-pool Quick Tasks it stays zero by design. ### Logs Resource-level metrics count pulls and pushes but cannot answer **who** did what to **which image**, **when**, **from where**, or **whether a login failed**. The registry audit categories fill exactly those gaps: - **Per-operation repository audit.** `ContainerRegistryRepositoryEvents` records each push, pull, delete, and untag per repository with the requesting identity, repository, tag, and digest. The metrics path sees the pull count rise but cannot attribute the pull to a principal or an image. - **Authentication audit.** `ContainerRegistryLoginEvents` records registry authentication attempts - success and failure, identity, source IP. This is the supply-chain access signal: an unexpected principal or source IP authenticating to the registry, or a burst of failed logins, shows up here and nowhere in the metrics. - **Change forensics.** The push/pull/delete history per repository is the audit trail for "when did this tag get overwritten" and "who removed this image", which the aggregate counters cannot reconstruct. A defining caveat applies before any wiring: **the audit categories capture only genuine data-plane operations and the logins that authenticate them.** `az acr import` and ACR Tasks builds move the pull/push metric counters but generate no audit records (see the Overview caveat). The operations that do produce an audit trail are `docker push` / `docker pull`, `az acr repository delete` / `untag`, and the `az acr login` / token-exchange that authenticates a client. A pipeline that only imports or runs Tasks builds produces metrics and no audit logs - expected, not a broken pipeline. Azure Container Registry exposes per-resource Diagnostic Settings categories, so this is the **resource-scope** Diagnostic Settings shape (the same as [Storage](./storage.md) and [Key Vault](./key-vault.md)), not the subscription-scope Activity Log path that [Compute](./compute.md) uses. The practical consequence: because the Diagnostic Setting is scoped to the registry, every record already belongs to it. There is no subscription-wide stream to filter down and no provider-scoping processor to maintain - a single guard that drops records with no resource ID is all the collector needs. The recommended pattern is **registry Diagnostic Settings to Event Hubs to `azure_event_hub`** in the same collector. The receiver ingests events as OTel logs and the resource processor tags them with `cloud.platform: azure_container_registry`. Everything routes to Scout via the same `oauth2client` / `otlp_http/b14` pipeline used for metrics. ```yaml showLineNumbers title="otel-collector.yaml (logs excerpt)" receivers: azure_event_hub/acrlogs: connection: ${env:ACRLOGS_CONNECTION_STRING} partition: "" offset: "" format: azure apply_semantic_conventions: true processors: filter/acronly: error_mode: ignore logs: log_record: - 'resource.attributes["cloud.resource_id"] == nil' resource/acrlogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_container_registry, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:ACRLOGS_REGION}", action: insert} - {key: service.name, value: "${env:ACRLOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/acrlogs: receivers: [azure_event_hub/acrlogs] processors: [filter/acronly, resource/acrlogs, batch] exporters: [otlp_http/b14] ``` The `connection` string must include the `EntityPath=` suffix so the receiver knows which hub to consume. The receiver defaults to all partitions from the oldest offset (`partition: ""`, `offset: ""`); on collector restart it re-reads from the saved offset, giving at-least-once delivery. > **Why the filter is one line, not a provider regex.** The > `azure_event_hub` receiver with `format: azure` plus > `apply_semantic_conventions: true` places the per-record Azure > resource ID at `resource.attributes["cloud.resource_id"]` (OTel > semantic-conventions form, **not** `azure.resource.id`) and > uppercases it. Because the Diagnostic Setting is registry-scoped, > every record already belongs to this registry - there is nothing to > filter out by provider. The single rule drops only records that > arrive without a resource ID at all. This is the structural > simplification of resource-scope over subscription-scope: no > provider scoping to maintain. #### Wiring the registry Diagnostic Setting Resource-scope Diagnostic Settings use `az monitor diagnostic-settings create` with `--resource `: ```bash az monitor diagnostic-settings create \ --name acr-audit \ --resource "$ACR_RESOURCE_ID" \ --event-hub "$EVENT_HUB_NAME" \ --event-hub-rule "$DIAG_SEND_RULE_ARM_ID" \ --logs '[{"category":"ContainerRegistryRepositoryEvents","enabled":true}, {"category":"ContainerRegistryLoginEvents","enabled":true}]' ``` `--event-hub-rule` is the full Azure Resource Manager (ARM) resource ID of a namespace-level Shared Access Signature (SAS) authorization rule with `Send` rights. Creating a resource-scope Diagnostic Setting requires write access on the registry and on the Event Hubs authorization rule; it does **not** need the subscription-scope `Monitoring Contributor` role or the operator identity split that a subscription-scope Activity Log path requires. This is the single-service-principal, Listen-SAS shape. #### Diagnostic Settings ship cadence Azure batches registry audit records and ships them to Event Hubs on a non-real-time cadence: - **First batch from a freshly-wired Diagnostic Setting: 5-20 minutes**, measured from the first genuine data-plane operation - not from when the Diagnostic Setting was created. With no eligible operations (import / Tasks-build only), no batch ever ships, which is correct behaviour and not a delay. - **Steady-state batches: 5-15 minutes.** - **End-to-end latency from operation to Scout: 5-20 minutes.** Audit visibility is **not** real-time. For real-time supply-chain monitoring use Microsoft Defender for Containers; the OTel path is for audit retention, compliance reporting, and forensic analysis where minutes of lag is acceptable. #### Why not other categories `Microsoft.ContainerRegistry/registries` exposes exactly the two audit categories above plus the `AllMetrics` metric category (covered by the Azure Monitor path, not the Diagnostic Setting). There is no equivalent of Storage's per-service split or Key Vault's policy categories - the two enabled categories are the complete audit surface. Enable both; there is nothing else to route elsewhere. ### Troubleshooting #### Pull or push counts are zero Symptom: the receiver discovers the registry but `TotalPullCount` / `TotalPushCount` stay at zero. Cause: the counts are traffic-gated - no pull or push happened in that minute. Fix: confirm activity with `az acr repository list --name `; this is expected behaviour on a quiet registry, not a receiver or RBAC fault. #### Metrics flow but no audit logs appear Symptom: pull/push metrics are healthy in Scout but no `ContainerRegistryRepositoryEvents` / `ContainerRegistryLoginEvents` records arrive, even after 30+ minutes. Cause: the traffic is `az acr import` or ACR Tasks builds only - server-side operations that drive metrics but generate no audit records. Fix: this is expected. Audit records require data-plane operations (`docker push`, `docker pull`, `az acr repository delete` / `untag`) and the token-exchange logins that authenticate them. Verify with the Event Hubs `IncomingMessages` metric: if it is zero, no eligible operations have occurred yet - the issue is upstream of the collector. #### `StorageUsed` is empty on a new registry Symptom: `StorageUsed` returns an empty series even though images are present. Cause: Azure Container Registry computes registry storage on a slow internal accounting cadence that lags the first push by tens of minutes to hours. Fix: wait; treat it as a slow capacity-trend gauge, not a real-time signal. Do not alert on its absence on a new registry. #### `AgentPoolCPUTime` stays at zero Symptom: `AgentPoolCPUTime` never emits a non-zero value. Cause: it emits only for dedicated ACR Tasks agent pools; `az acr build` Quick-Task runs use the shared managed pool. Fix: expected unless you run dedicated agent pools. Keep the metric whitelisted; it costs nothing when absent. #### Event Hubs empty for up to ~20 minutes after the first data-plane operation Symptom: `azure_event_hub/acrlogs` reports zero records for up to ~20 minutes after the first eligible operation. Cause: two waits run concurrently on a fresh collector - the receiver's initial consumer warm-up (~15-20 minutes) and the Diagnostic Setting first-batch cadence (5-20 minutes, measured from the first data-plane operation). The combined worst case is ~20 minutes; an already-warm receiver sees only the 5-20 minute first-batch wait. Fix: wait. Do not force-recreate the collector during the window - that resets the consumer warm-up clock and looks like the pipeline is dead. If it stays empty well past 20 minutes, check Event Hubs `IncomingMessages`: if it is zero, no eligible data-plane operations have occurred (the issue is upstream of the collector, not the receiver). #### Scout OAuth2 returns 401 Symptom: the `oauth2client` extension logs 401 from the token endpoint. Cause: stale `SCOUT_CLIENT_ID` / `SCOUT_CLIENT_SECRET` / `SCOUT_TOKEN_URL`. Fix: re-source the Scout credential env file (or the equivalent secret store) and restart the collector. ### Frequently Asked Questions #### How do I monitor Azure Container Registry with OpenTelemetry? Add the `azure_auth` extension and a single `azure_monitor` receiver scoped to `Microsoft.ContainerRegistry/registries`, route it into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter, and grant the collector's service principal `Monitoring Reader` at the resource group containing the registry. The receiver polls Azure Monitor every 60 seconds. The pull and push counters are traffic-gated: a registry with no pull or push activity in a given minute publishes zero counts, which is expected and not a misconfiguration. #### Why does my registry produce metrics but no audit logs? Pull and push metrics and the `ContainerRegistryRepositoryEvents` and `ContainerRegistryLoginEvents` audit logs are driven by different operations. `az acr import` and ACR Tasks builds are server-side control-plane operations: they move the pull and push metric counters but do not generate audit records. The audit categories fire only on genuine data-plane repository operations - `docker push`, `docker pull`, delete, untag - and the token-exchange logins that authenticate them. A CI pipeline that only uses `az acr import` or ACR Tasks will correctly show healthy pull and push metrics with no audit logs; that is expected, not a fault. #### Why is the StorageUsed metric empty on my new registry? `StorageUsed` is computed on Azure Container Registry's own internal storage-accounting cadence, which lags the first push by tens of minutes to hours. A freshly populated registry shows an empty or flat `StorageUsed` series for a while even though images are present. Treat it as the slow-moving capacity-trend gauge, not a real-time signal, and do not alert on its absence on a new registry. #### Why is AgentPoolCPUTime always zero? `AgentPoolCPUTime` emits only for dedicated ACR Tasks agent pools. Quick-Task builds (`az acr build`) run on the shared managed build pool, which does not drive this metric. If you do not run dedicated agent pools, `AgentPoolCPUTime` stays at zero by design - it is task-conditional, not a gap. Keep it whitelisted; a metric that never emits produces no series, so it adds no cardinality or query cost. #### How do I alert on push or pull failures? Each operation has a `Total` counter and a `Successful` counter (`TotalPushCount` vs `SuccessfulPushCount`, `TotalPullCount` vs `SuccessfulPullCount`). The gap between them is the failure count. Alert on a sustained non-zero `Total` minus `Successful` delta rather than a fixed threshold, since a healthy registry has `Total` equal to `Successful`. A rising delta on pulls usually means client authentication or quota problems; on pushes it usually means image-size or quota limits. #### How do I audit who pushed or pulled an image? Configure a resource-scope Diagnostic Setting on the registry forwarding `ContainerRegistryRepositoryEvents` and `ContainerRegistryLoginEvents` to an Event Hubs hub, point the `azure_event_hub` receiver at the hub, and ship the decoded records to Scout. RepositoryEvents records per-repository push, pull, delete, and untag with the requesting identity, repository, tag, and digest. LoginEvents records registry authentication attempts with identity and source IP. Because the Diagnostic Setting is scoped to the registry, every record already belongs to it - no provider filter is needed, unlike a subscription-scope Activity Log path. ### Reference - [Microsoft.ContainerRegistry/registries supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-containerregistry-registries-metrics) - [Azure Container Registry monitor reference (log categories)](https://learn.microsoft.com/azure/container-registry/monitor-container-registry-reference) - [Azure Monitor Activity Log schema](https://learn.microsoft.com/azure/azure-monitor/essentials/activity-log-schema) - [opentelemetry-collector-contrib azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - [opentelemetry-collector-contrib azureeventhubreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azureeventhubreceiver) ### Related Guides - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - start here for the cross-surface story. - [Azure Key Vault](./key-vault.md) - the closest companion: another pure-PaaS surface with a resource-scope Diagnostic Settings audit path through Event Hubs. - [Azure Storage](./storage.md) - resource-scope Diagnostic Settings logs counterpart; a common target for images and artifacts. - [Azure Compute](./compute.md) - the VMs and scale sets that pull images from this registry; the subscription-scope Activity Log contrast to this guide's resource-scope path. - [Azure Kubernetes Service](./aks.md) - the most common image-pull consumer of a registry; pair registry pull metrics with cluster workload telemetry. --- ## Azure Cosmos DB Monitoring with OpenTelemetry - Request Unit (RU) Consumption & Latency ### Overview This guide is the **execution playbook** for Cosmos DB. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide covers monitoring an **Azure Cosmos DB** account (SQL / NoSQL API) with the OpenTelemetry Collector's `azure_monitor` receiver. The collector polls Azure Monitor's REST API every 60 seconds for the metrics published by `Microsoft.DocumentDB/databaseAccounts`, transforms them to OTel-style names, and ships them via OTLP/HTTP to base14 Scout. The `azure_monitor` receiver does not connect to Cosmos directly. It queries Azure Monitor's metrics surface for any resource Cosmos auto-publishes to - so the same pattern applies to all five RU-based Cosmos APIs (SQL, Mongo, Cassandra, Gremlin, Table). This guide focuses on the SQL API; the configuration shape generalises. Cosmos DB for MongoDB vCore is a separate provider (`Microsoft.DocumentDB/mongoClusters`) and is NOT covered here. ### What you'll monitor Twelve metrics from `Microsoft.DocumentDB/databaseAccounts`, sufficient for Request Unit (RU) consumption, request rate, storage, and availability dashboards. The receiver renames them from Azure's PascalCase (e.g., `TotalRequests`) to OTel-style `azure__` (e.g., `azure_totalrequests_count`). A single Azure metric with multiple aggregations becomes one OTel metric per aggregation. | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `TotalRequests` | `azure_totalrequests_count` | Count | Request rate, with `metadata_statuscode` / `metadata_connectionmode` / `metadata_operationtype` dimensions for slicing 2xx vs 4xx vs 5xx, gateway vs direct | | `TotalRequestUnits` | `azure_totalrequestunits_{total,average,maximum}` | RUs | RU consumption - primary cost driver and capacity-planning input | | `MetadataRequests` | `azure_metadatarequests_count` | Count | Free-of-charge metadata calls (account/database/container introspection) | | `ServerSideLatencyDirect` | `azure_serversidelatencydirect_*` | ms | Server-side latency for direct-mode connections | | `ServerSideLatencyGateway` | `azure_serversidelatencygateway_*` | ms | Server-side latency for gateway-mode connections | | `DataUsage` | `azure_datausage_{total,average,maximum,minimum}` | Bytes | Storage consumed by user data | | `DocumentCount` | `azure_documentcount_{total,average}` | Count | Total document count | | `DocumentQuota` | `azure_documentquota_{total,average}` | Bytes | Storage quota - supersedes the deprecated `AvailableStorage` | | `IndexUsage` | `azure_indexusage_{total,average,maximum,minimum}` | Bytes | Index storage | | `ProvisionedThroughput` | `azure_provisionedthroughput_maximum` | RU/s | Throughput ceiling per database/container (rate, not count) | | `NormalizedRUConsumption` | `azure_normalizedruconsumption_{average,maximum}` | Percent | Sliding-window utilisation; rises before throttling actually starts | | `ServiceAvailability` | `azure_serviceavailability_{average,maximum,minimum}` | Percent | Account-level availability (PT1H grain; emitted hourly) | The latency pair (`ServerSideLatencyDirect` / `*Gateway`) emits zero series until a real workload exercises latency. `ServerSideLatency` (the parent metric) and `AvailableStorage` are deprecated by Microsoft (Aug 2025 / Sep 2023 respectively); use the `*LatencyDirect` / `*LatencyGateway` and `DocumentQuota` replacements above. ### Prerequisites | Requirement | Minimum | | --------------------------------- | -------------------------------- | | A Cosmos DB account (any API) | SQL / Mongo / Cassandra / Gremlin / Table | | OTel Collector contrib | v0.148+ (snake_case YAML keys) | | `Microsoft.DocumentDB` provider | registered on the subscription | | Service principal | `Monitoring Reader` on the Cosmos resource group | | base14 Scout | any tenant | This guide is the Cosmos-specific addition to a working OpenTelemetry Collector. For collector deployment + the Scout exporter pieces (which are the same for every Azure surface), see: - [Docker Compose Setup](../../collector-setup/docker-compose-example.md), or [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) / [Linux Setup](../../collector-setup/linux-setup.md) for other runtimes. - [Scout Exporter](../../collector-setup/scout-exporter.md) for the OAuth2 + OTLP/HTTP exporter config. ### Access setup The `azure_monitor` receiver needs `Monitoring Reader` on the resource group containing your Cosmos accounts. The role grants read on metric definitions and metric data only, no control-plane write. ```bash RG_ID=$(az group show --name --query id -o tsv) az role assignment create \ --assignee \ --role "Monitoring Reader" \ --scope "$RG_ID" ``` `azure_auth` supports four modes for the calling identity: `service_principal` (out-of-Azure collectors), `managed_identity` (Container Apps / Virtual Machine Scale Sets / Azure VM), `workload_identity` (Azure Kubernetes Service pods, federated to a ServiceAccount), and `use_default` (local dev). Full YAML for each mode and Workload Identity Federation setup is in the [Service Bus guide](./service-bus.md#authentication); the auth block is the only thing that differs between Azure surfaces, the rest of the config below is Cosmos-DB-specific. Role-Based Access Control (RBAC) propagation on the legacy Azure Resource Manager (ARM) `/metrics` endpoint is immediate. The data-plane batch API at `*.metrics.monitor.azure.com` requires separate propagation that lags 5-30 minutes after grant. This guide defaults `use_batch_api: true`; if the data plane is still 401-ing past that window, flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint (RBAC there is immediate). ### Receiver configuration This is the Cosmos-specific addition to your collector. Add the `azure_auth` extension and `azure_monitor` receiver to your existing config, then wire the receiver into a metrics pipeline that exports to Scout (see [Scout Exporter](../../collector-setup/scout-exporter.md) for the exporter half - it's the same OAuth2 + OTLP/HTTP setup used by every Azure surface). ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor: subscription_ids: ["${env:AZURE_SUBSCRIPTION_ID}"] resource_groups: ["${env:AZURE_RESOURCE_GROUP}"] services: ["Microsoft.DocumentDB/databaseAccounts"] auth: { authenticator: azure_auth } collection_interval: 60s # Metrics Data Plane (12k -> 360k calls/hour ceiling). RBAC propagates # 5-30 min after the Monitoring Reader grant; flip to false as a # temporary fallback to the legacy ARM /metrics endpoint if needed. use_batch_api: true cache_resources: 60 dimensions: { enabled: true } metrics: "Microsoft.DocumentDB/databaseAccounts": TotalRequests: [] TotalRequestUnits: [] MetadataRequests: [] ServerSideLatencyDirect: [] ServerSideLatencyGateway: [] DataUsage: [] DocumentCount: [] DocumentQuota: [] IndexUsage: [] ProvisionedThroughput: [] NormalizedRUConsumption: [] ServiceAvailability: [] processors: resource: attributes: - { key: cloud.provider, value: azure, action: insert } - { key: cloud.platform, value: azure_cosmosdb, action: insert } - { key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert } - { key: cloud.region, value: "${env:AZURE_REGION}", action: insert } - { key: cloud.resource_id, value: "${env:COSMOS_RESOURCE_ID}", action: insert } - { key: service.name, value: "${env:SERVICE_NAME}", action: insert } service: extensions: [azure_auth] # plus your existing extensions (oauth2client, etc.) pipelines: metrics: receivers: [azure_monitor] processors: [resource, batch] # plus your existing processors exporters: [otlphttp/b14] # the Scout exporter from the shared setup ``` Once `metrics:` is set for a namespace, the receiver only emits the metrics you list - there is no implicit "default + my picks" merge. The empty aggregation list `[]` per metric collects all aggregations Azure publishes for that metric. The same receiver works against Mongo, Cassandra, Gremlin, and Table-API Cosmos accounts - they all publish to `Microsoft.DocumentDB/databaseAccounts`. Replace the SQL-API metric set with the API-specific equivalents (e.g., `MongoRequests`, `MongoRequestCharge` for Mongo) when targeting other APIs. #### Environment variables ```bash showLineNumbers title=".env" # From `az ad sp create-for-rbac` output. AZURE_TENANT_ID= AZURE_CLIENT_ID= AZURE_CLIENT_SECRET= # From your Azure subscription / resource group. AZURE_SUBSCRIPTION_ID= AZURE_RESOURCE_GROUP= AZURE_REGION= COSMOS_RESOURCE_ID= # az cosmosdb show -g -n --query id -o tsv # Resource attribute defaults. SERVICE_NAME=azure-cosmosdb ``` ### Key alerts to configure Threshold guidance for the most operationally useful series. Tune to your workload and the throughput SKU; these are starting points for a provisioned-throughput SQL-API account with real traffic. | Metric (OTel name) | Warning | Critical | Why it matters | | ------------------------------------------------------ | ---------- | ----------- | -------------- | | `azure_normalizedruconsumption_maximum` | > 70% | > 90% | Sliding-window RU utilisation; rises before 429s actually start. Leading indicator for capacity. | | `azure_totalrequests_count` filtered to status 429 | > 0 / 5m | sustained > 0 / 15m | Throttling has started. Scale RU/s, partition the workload, or add retry budget. | | `azure_totalrequestunits_total` (per partition key) | > 80% of provisioned | > 95% | Hot-partition signal when one partition dominates total RU/s. | | `azure_serversidelatencydirect_average` | > 10ms | > 25ms | Server-side latency for direct-mode connections; user-facing latency depends on this + network. | | `azure_serversidelatencygateway_average` | > 25ms | > 50ms | Server-side latency for gateway-mode connections. | | `azure_datausage_maximum` | > 80% of `azure_documentquota_maximum` | > 95% | Approaching storage quota; container or account split may be needed. | | `azure_serviceavailability_minimum` | < 100% / 1h | < 99.9% / 1h | Account-level availability (PT1H grain). | The latency thresholds above are tuned for a healthy single-region account; adjust upward if you operate cross-region with consistency levels stronger than `Session`. For multi-region accounts, alert on the write-region's latency series specifically - read-region latency naturally tracks the consistency level. ### Operations - **Collection interval.** 60 seconds matches Azure Monitor's 1-3 minute ingestion lag - faster polls just re-read stale data and burn rate-limit budget. - **`cache_resources`.** This is the receiver's resource-list cache TTL in seconds (default 24h). The shipped config sets it to `60` so newly- created accounts are visible to the receiver on the next poll - appropriate for a validation pass or for environments where accounts come and go frequently. In a stable production fleet, raise it back toward the default (e.g., `3600` or higher) to skip the per-minute ARM resource-list call. - **RBAC propagation.** The legacy ARM `/metrics` endpoint propagates `Monitoring Reader` immediately. The newer data-plane batch API at `*.metrics.monitor.azure.com` requires separate RBAC propagation that can lag 5-30 minutes after grant. - **`use_batch_api: true` (default in this guide)** uses Azure Monitor's data-plane batch endpoint, which raises the per-tenant query rate ceiling from 12,000 to 360,000 calls/hour. RBAC propagation on the data plane lags 5-30 min after the Monitoring Reader grant; flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint if you see persistent 401s past that window. - **Filtering metrics.** Use `metrics:` (a namespace-keyed nested map) to whitelist; use `dimensions.overrides` to drop high-cardinality dimensions like `metadata_statuscode` if your Scout volume is dominated by per-status- code splits. - **Multi-region accounts.** The receiver scopes by subscription and optional resource-group filters; Azure Monitor publishes metrics globally regardless of the account's write regions. No extra config. - **Multi-API.** The same receiver works against Mongo, Cassandra, Gremlin, and Table-API Cosmos accounts - they all publish to `Microsoft.DocumentDB/databaseAccounts`. Replace the SQL-API metric set with the API-specific equivalents (e.g., `MongoRequests`, `MongoRequestCharge` for Mongo). Cosmos DB for MongoDB vCore is a separate provider (`Microsoft.DocumentDB/mongoClusters`) and is NOT covered by this config. ### Apps-side instrumentation This guide is metrics-only. For per-operation distributed traces (the Cosmos client span linked through the application's request span), instrument your application code with the Cosmos OTel client SDKs: - **.NET / C#:** `Microsoft.Azure.Cosmos` 3.x emits OpenTelemetry traces via the SDK's built-in source. Enable with `clientOptions.CosmosClientTelemetryOptions.DisableDistributedTracing = false`. - **Java:** `azure-cosmos` SDK 4.x emits OTel-compatible traces; the OTel Java agent picks them up automatically. - **Python:** `azure-cosmos` 4.5+ emits OTel spans when `OpenTelemetryTracingOptions` is configured on the client. - **Node.js:** `@azure/cosmos` 4.x with the `@azure/opentelemetry-instrumentation-azure-sdk` package. Run the apps-side spans alongside this metrics collector with distinct `service.name` values. ### Logs Log-driven analysis fills three gaps that the metrics in this guide do not cover: - **Per-request RU attribution.** `TotalRequestUnits` aggregates RU consumption account-wide; `NormalizedRUConsumption` shows utilization as a percentage of provisioned throughput. Neither shows which document operation, query, or partition key range consumed which RU. `DataPlaneRequests` log records carry the RU charge per request alongside the operation type, status code, and partition key range - required for cost attribution to specific workloads and for triaging "who is blowing the RU budget" incidents. - **Hot partition diagnosis.** `NormalizedRUConsumption` sliced by partition key range tells you that a hot partition exists but not which key value is hot. `PartitionKeyStatistics` records storage and request-rate distribution per partition key, surfacing the specific keys whose access patterns are skewing throughput consumption - required for sharding decisions and for re-keying proposals. - **Query plan insight.** `TotalRequests` and `TotalRequestUnits` aggregate request rate and RU consumption. They do not show that a single query is reading 1 M documents to return 10, or doing a cross-partition scan when a partition key was available. `QueryRuntimeStatistics` records per-query index lookups, retrieved document count, and output document count - required for query optimization and for catching N+1-style anti-patterns at the data layer. Cosmos DB publishes four Diagnostic Settings categories on `Microsoft.DocumentDB/databaseAccounts`: | Log category | What it captures | When to enable | | --- | --- | --- | | `DataPlaneRequests` | Per-request audit: RU charge, status code, partition key range, operation type. | Always | | `QueryRuntimeStatistics` | Per-query execution stats: index lookups, retrieved doc count, output doc count. | Cost / performance investigation | | `PartitionKeyStatistics` | Storage and request distribution per partition key. | Hot partition diagnosis | | `ControlPlaneRequests` | Account / container CRUD; throughput changes. | Audit, change tracking | ```bash az monitor diagnostic-settings create \ --resource \ --name cosmos-to-eventhubs \ --logs '[{"category":"DataPlaneRequests","enabled":true}, {"category":"QueryRuntimeStatistics","enabled":true}, {"category":"PartitionKeyStatistics","enabled":true}, {"category":"ControlPlaneRequests","enabled":true}]' \ --event-hub \ --event-hub-rule ``` The recommended pattern is **Diagnostic Settings to Event Hubs to the `azure_event_hub` receiver** in the same collector. The Storage logs example at `components/azure-storage-telemetry/` ships a runnable reference fragment (`config/scraper-fragment-logs.yaml`) plus `provision-logs.sh` that stands up an EH Basic namespace + 1 hub + 2 SAS rules; the same fragment shape adapts to Cosmos by changing the `cloud.platform` resource attribute (`azure_cosmosdb`) and the source Diagnostic Setting categories. ### Troubleshooting For common `azure_auth` and Azure Monitor issues (`AuthorizationFailed`, `403 Forbidden`, token-acquire 401, `RequestThrottled`, Docker DNS resolution, Scout OAuth2 401), see the [Service Bus troubleshooting section](./service-bus.md#troubleshooting); the same diagnoses apply to every Azure surface scraped via `azure_monitor`. Below are the issues specific to Azure Cosmos DB. #### No `TotalRequests` series in the first 3 minutes Azure Monitor's 1-3 minute ingestion lag for newly-provisioned resources. If after 5 minutes you still see nothing in Scout, generate data-plane traffic - the request-counter metrics only emit after the first read or write. Control-plane calls like `az cosmosdb show` do not drive `TotalRequests`; you need actual document operations against the account endpoint. #### `ServerSideLatencyDirect` / `ServerSideLatencyGateway` series missing Expected on idle accounts. Both metrics emit zero series until a real workload exercises latency on the matching connection mode (direct or gateway). #### `ServerSideLatency` or `AvailableStorage` series missing Expected. Microsoft deprecated `ServerSideLatency` (Aug 2025) and `AvailableStorage` (Sep 2023). Use `ServerSideLatencyDirect` / `ServerSideLatencyGateway` and `DocumentQuota` instead. The legacy names no longer publish. #### `NormalizedRUConsumption` flat at 0% on a busy account Check `DefaultExperience` on the account. Normalized RU is only published on accounts using provisioned throughput; serverless and autoscale accounts have different cost-tracking metrics. ### Frequently Asked Questions #### How do I monitor Azure Cosmos DB with OpenTelemetry? Run the OpenTelemetry Collector with the `azure_monitor` receiver targeting `Microsoft.DocumentDB/databaseAccounts`. The receiver polls Azure Monitor's REST API every 60 seconds, transforms metrics from Azure's PascalCase names (like `TotalRequests`) to OTel-style names (`azure_totalrequests_count`), and ships them via OTLP/HTTP to base14 Scout. Authentication uses the `azure_auth` extension in service-principal or managed-identity mode. #### What RBAC role does the receiver need on the Cosmos account? `Monitoring Reader` scoped to the resource group is sufficient. It grants read access to metric definitions and metric data without any control-plane write permissions. `Reader` is not needed unless a specific call returns `AuthorizationFailed`; `Monitoring Reader` alone covers the entire `azure_monitor` receiver surface. #### Why do some metrics show no data on a fresh Cosmos account? Azure Monitor only emits metrics when there is activity to measure. `ServerSideLatencyDirect` and `ServerSideLatencyGateway` emit zero series until a real workload exercises latency. `TotalRequests` and `TotalRequestUnits` start emitting after the first data-plane call. `DataUsage`, `DocumentCount`, `ProvisionedThroughput`, and `ServiceAvailability` emit immediately on every account, regardless of traffic. #### What is `NormalizedRUConsumption`? `NormalizedRUConsumption` is the per-minute maximum RU/s utilisation expressed as a percentage of provisioned throughput, sliced by partition key range. It rises before throttling actually starts (visible in 429 status codes), making it a leading indicator for capacity decisions. Alert at 80% sustained to give yourself room to scale before requests fail. #### Should I use the data-plane batch API for higher throughput? This guide already defaults `use_batch_api: true`, which uses Azure Monitor's data-plane batch endpoint and raises the query rate ceiling from 12,000 to 360,000 calls per hour. RBAC on the data plane propagates 5-30 minutes after the `Monitoring Reader` grant; flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint (immediate propagation, 12,000 calls / hour) if you see persistent 401s past that window. #### How does this differ from Application Insights for Cosmos DB? Application Insights for Cosmos DB is Azure-tenant-bound, billed per-GB ingested, and visualised in Azure dashboards or workbooks. The OpenTelemetry Collector is vendor-neutral - the same image ships to base14 Scout or any OTLP-compatible backend without redeployment. Multi-cloud customers and customers migrating off Application Insights prefer this. The metric coverage is identical - both surfaces draw from the same Azure Monitor REST API. ### Related Guides - [Azure SQL Database](./sql-database.md) - managed relational database. Pairs with the self-hosted [SQL Server guide](../../component/sqlserver.md). - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. - [AWS RDS PostgreSQL](../aws/rds.md) - equivalent guide for AWS managed PostgreSQL. Uses CloudWatch Metrics Stream (push) for infrastructure metrics plus the OTel PostgreSQL receiver for database internals; a hybrid pattern. --- ## Azure Database for MySQL Monitoring with OpenTelemetry - Platform Metrics, In-Database, and Resource Logs ## Azure Database for MySQL Monitoring with OpenTelemetry > **Why Scout for Azure Database for MySQL observability?** > > Azure Monitor's metric catalog gives you resource saturation and > connection lifecycle at minute grain - enough for capacity alerts but > not enough to attribute a slow-query spike to a specific statement or > table. The OTel `mysqlreceiver` reads `performance_schema` directly > over a TLS-required connection, giving you statement-event, table-I/O, > and lock-wait signals at 10-second grain. Scout consumes both > pipelines via OTLP and stores them alongside your AWS, GCP, on-prem, > and application telemetry in one OTel-native query surface. > > Single-server (`Microsoft.DBforMySQL/servers`) was retired by > Microsoft and is **not** covered by this guide. Flexible Server > (`Microsoft.DBforMySQL/flexibleServers`) is the only supported shape. ### Overview Azure Database for MySQL Flexible Server is a managed PaaS MySQL with public or VNet-integrated access, a fixed admin role that is not a `SUPER` user, and Server Parameters in place of `my.cnf`. Observability splits cleanly across three paths: - **Platform metrics** via the `azure_monitor` receiver against the `Microsoft.DBforMySQL/flexibleServers` namespace. - **In-database metrics** via the OpenTelemetry `mysqlreceiver` connecting to the server's public FQDN over TLS. Identical receiver config to self-hosted MySQL; only the auth, firewall, and TLS bits differ. See [self-hosted MySQL](../../component/mysql.md) for the full receiver reference and metric definitions; this guide documents only the Azure-specific deltas. - **Resource logs** via the `azure_event_hub` receiver against a Diagnostic Settings to Event Hubs pipeline. This guide configures the platform-metrics and resource-logs receivers in full and the in-database-scrape deltas. The in-database receiver block itself, the full metric list, and the collector pipeline structure live in the self-hosted MySQL guide. ### Instrumentation paths for Flexible Server Three paths exist; pick one, two, or all three based on the table below. | Path | What it covers | What it costs | Setup | | --- | --- | --- | --- | | **Platform metrics - Azure Monitor** (this guide, §What you'll monitor) | Resource saturation (CPU, memory, IO consumption, storage), connection lifecycle (active / total / aborted), network throughput, query and slow-query rates, replica lag. Per-server resolution; minute grain. Does **not** see inside the database. | Azure Monitor query cost: one query per metric per scrape. At a 60s interval the daily cost runs in cents per server. | One Service Principal with `Monitoring Reader` on the resource group; one receiver block; one resource processor. | | **In-database metrics - direct scrape** (this guide, §In-database metrics; details cross-linked to self-hosted MySQL) | Statement-event counts and wait times, table I/O, table size and row counts, read / write lock-wait counts and times, command counts, join operations, replica delay. Per-statement and per-table resolution; 10-second grain. Sees inside the database. | One `mysqlreceiver` block in your collector; a dedicated monitoring user with three global grants; an open TCP/3306 path from collector to server FQDN with TLS. | A Server Parameter sets `performance_schema = ON` (restart-bound, applied pre-flight); the monitoring user holds `PROCESS, REPLICATION CLIENT` and `SELECT ON performance_schema.*`; the receiver hits the public FQDN over TLS. | | **Resource logs - Diagnostic Settings to Event Hubs** (this guide, §Logs below) | Per-slow-statement detail: statements exceeding `long_query_time`, with lock time, rows examined, rows sent. Optional connection / DDL / DML audit via the audit-log category. Per-record resolution; sub-second grain. | One Event Hubs Basic namespace (~$11/mo at 1 TU; 1 MB/s ingress absorbs roughly 4,000 records/sec at typical record size). The Diagnostic Setting itself is free. | One Diagnostic Setting on the server with the categories you care about; one Event Hubs namespace + hub + Send/Listen SAS rules; one `azure_event_hub` receiver fragment. | #### Which path to pick Four decision criteria, in order of usual weight: 1. **Tier choice (Burstable / GeneralPurpose / MemoryOptimized).** Burstable B1ms / B2s is the cheapest shape but has a 2 GiB RAM ceiling. `performance_schema` carries a memory cost, and on Burstable some `events_statements_*` consumers default off to save memory. The in-database scrape adds tangible value only above Burstable - on Burstable the platform metrics cover the relevant saturation signals. Move to the in-database scrape plus full `performance_schema` instrumentation on GeneralPurpose and larger, where the working set fits comfortably. 2. **Existing collector posture.** If you already run a Kubernetes collector or a shared scraper container that consumes `azure_monitor` for other surfaces, fold platform-metrics scraping into that. The in-database scrape is a separate per-database concern - typically a small dedicated collector beside the application that owns the database, because it needs the egress path and per-database credentials the shared scraper does not carry. 3. **Diagnostic Settings volume budget.** `MySqlSlowLogs` is moderate-volume: one record per statement above `long_query_time`. The audit-log category (`MySqlAuditLogs`) adds connection, DDL, and DML records at much higher volume and requires extra Server Parameters. Run slow-log only by default; add the audit log only when you have a forensic or compliance need and the volume budget for it. 4. **Depth-of-debug appetite.** Resource saturation alerts only? Platform metrics alone. Per-statement attribution? The in-database scrape plus resource logs with the audit-log category when DDL / DML provenance matters. If you are starting from zero, platform metrics plus the slow-query log is the lowest-effort win and catches the broadest range of saturation and slow-statement incidents. Add the in-database scrape when investigations need `performance_schema` depth, and turn on the audit log only while you are actively chasing a provenance question. ### What you'll monitor The platform-metrics receiver scrapes one Azure Monitor namespace and emits metrics under `cloud.platform: azure_mysql_flexible_server`. #### Flexible Server metrics (`Microsoft.DBforMySQL/flexibleServers`) | Metric | Aggregation | What it tells you | | --- | --- | --- | | `cpu_percent` | Average, Maximum | Server-wide CPU utilisation. On Burstable tiers, sustained CPU above the SKU's base rate drains the CPU credit pool and the server then throttles to base rate. | | `memory_percent` | Average, Maximum | Server-wide RAM utilisation. Burstable B1ms (2 GiB) is the most memory-constrained SKU; treat the idle baseline as workload-relative rather than absolute. | | `io_consumption_percent` | Average, Maximum | Disk IOPS utilisation as a percentage of the SKU's IOPS ceiling. Sustained high values drive query latency tails. | | `storage_percent` | Average, Maximum | Provisioned storage utilisation. Pre-emptive: scale storage before this hits 90% (storage scaling is non-disruptive). | | `storage_used` | Average | Provisioned storage used in bytes. Pairs with `storage_percent` for absolute-byte alerting. | | `storage_limit` | Average | Provisioned storage ceiling in bytes. The denominator for `storage_used`. | | `active_connections` | Average, Maximum | Concurrent backends. Compare against the SKU's `max_connections` ceiling (around 85 on B1ms; scales with vCPU on larger SKUs). | | `total_connections` | Total | Connection attempts in the period. Pairs with `aborted_connections` for a connection-success view. | | `aborted_connections` | Total | Connection attempts that failed or were aborted. Sustained non-zero values indicate auth misconfiguration, firewall rejection, or upstream client churn. | | `network_bytes_egress` | Total | Bytes sent from the server to clients. | | `network_bytes_ingress` | Total | Bytes received from clients. | | `Queries` | Total | Statements executed in the period. The headline throughput signal. | | `Slow_queries` | Total | Statements that exceeded `long_query_time` in the period. The aggregate count; per-statement detail comes from the slow-query log (see §Logs). | | `replication_lag` | Maximum | Replica lag in seconds. See Operations footnote below. | | `backup_storage_used` | Average | Bytes used in automated backup storage. See Operations footnote below. | **Operations footnote - `replication_lag`:** This is a replica-only metric. A single-primary server with no read replicas attached has zero series to emit, so the metric stays empty. Treat an empty `replication_lag` on a primary as expected behaviour; the series populates once a read replica is attached. **Operations footnote - `backup_storage_used`:** The catalog exposes `backup_storage_used` at a PT15M native grain, and the series does not populate until the server's first automated backup completes, which is hours after a server is first created. A receiver polling at 60s will report `no recent data` for most cycles, and a freshly created server reports nothing at all until its first backup runs. Treat a sparse or absent series as expected; use the Azure portal's backup-quota view for backup-storage alerting instead of this metric. **Catalog-available extras** (the full catalog has 55 metrics; named here for completeness, add to your whitelist when the workload warrants): - Burstable credit health: `cpu_credits_consumed`, `cpu_credits_remaining` (PT15M grain). - Per-statement counters: `Com_*` (high cardinality; the in-database scrape covers statement depth at higher resolution). - InnoDB internals: `Innodb_buffer_pool_*`, `ibdata1_storage_used`, `trx_rseg_history_len` (the in-database scrape covers this). - Server-log storage: `serverlog_storage_percent`, `serverlog_storage_usage`, `serverlog_storage_limit` (only meaningful once server logs accumulate). - HA-only signals: `HA_*` (emitted only when zone-redundant HA is configured; not available on Burstable). - Concurrency detail: `active_transactions`, `Threads_running`, `lock_deadlocks`, `lock_timeouts`, `Sort_merge_passes`, `storage_io_count`, `binlog_storage_used`, `Uptime`. (The in-database scrape covers the concurrency and lock signals at higher resolution; whitelist them in Azure Monitor only if you do not run it.) ### Prerequisites | Requirement | Detail | | --- | --- | | Server tier | Flexible Server, any SKU. Burstable B1ms is the smallest tier covered here; GeneralPurpose and larger unlock the full in-database-scrape value (Burstable tiers have a 2 GiB RAM ceiling that constrains `performance_schema` and may leave some statement-event consumers off by default). | | MySQL version | 5.7, 8.0, or 8.4 (when GA in your region). The receiver works on all supported versions; 8.0+ is recommended. | | OTel Collector Contrib | v0.151+ (the `azure_monitor` and `azure_event_hub` receiver names are snake_case from v0.148.0; v0.151.0 is the current fleet). | | OpenTelemetry semconv | v1.41.0. | | Azure CLI | 2.85+ for the `az monitor diagnostic-settings` flags used here. | | Azure providers registered | `Microsoft.DBforMySQL` (metrics source), plus `Microsoft.EventHub` and `Microsoft.Insights` for the Diagnostic Settings logs path. All three must be `Registered` in the subscription, or the receiver returns no metrics and `az monitor diagnostic-settings create` fails. | | Collector runtime | See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) or [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for the runtime; this guide adds the MySQL-specific receiver + processor blocks on top. | | Scout exporter | See [Scout exporter wiring](../../collector-setup/scout-exporter.md) for the `oauth2client` extension + `otlp_http/b14` exporter. This guide does not re-derive that block. | ### Access setup One role assignment covers the metrics path; the logs path uses SAS auth on the Event Hubs Listen SAS rule and does not require an additional role. | Role | Scope | Reason | | --- | --- | --- | | `Monitoring Reader` | Resource group containing the Flexible Server | Lets the `azure_monitor` receiver list metric definitions and read metric values. This is the only role assignment the metrics path needs. | The role assignment is idempotent - re-running it on a previously granted Service Principal is a no-op. The logs path consumes the Diagnostic Settings hub through a Listen-permission SAS connection string on the Event Hubs namespace, not a second role assignment. The in-database receiver uses a **MySQL** user, not an Azure role. Connect as the server admin, create a dedicated monitoring user, and grant it exactly the three global privileges the receiver needs: ```sql title="setup monitoring user" CREATE USER 'otel_monitor'@'%' IDENTIFIED BY ''; GRANT PROCESS, REPLICATION CLIENT ON *.* TO 'otel_monitor'@'%'; GRANT SELECT ON performance_schema.* TO 'otel_monitor'@'%'; FLUSH PRIVILEGES; ``` The Azure Flexible Server admin is **not** a `SUPER` user. `GRANT ALL`, `WITH GRANT OPTION`, and any attempt to grant `SUPER` fail with `ERROR 1045` or `ERROR 1227`. The three grants above are exactly the self-hosted monitoring set and are all within what the Flexible Server admin can issue; do not widen them. ### Receiver configuration (platform metrics) ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_monitor/mysql: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:MYSQLFLEX_RESOURCE_GROUP} services: - Microsoft.DBforMySQL/flexibleServers auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.DBforMySQL/flexibleServers": cpu_percent: [Average, Maximum] memory_percent: [Average, Maximum] io_consumption_percent: [Average, Maximum] storage_percent: [Average, Maximum] storage_used: [Average] storage_limit: [Average] active_connections: [Average, Maximum] total_connections: [Total] aborted_connections: [Total] network_bytes_egress: [Total] network_bytes_ingress: [Total] replication_lag: [Maximum] backup_storage_used: [Average] Queries: [Total] Slow_queries: [Total] processors: resource/mysql: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_mysql_flexible_server, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:MYSQLFLEX_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:MYSQLFLEX_SERVER_RESOURCE_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:MYSQLFLEX_SERVICE_NAME}", action: insert} service: pipelines: metrics/mysql: receivers: [azure_monitor/mysql] processors: [memory_limiter, resource/mysql, batch] exporters: [otlp_http/b14] ``` The whitelist names match Azure's catalog exactly for this namespace. Still confirm them against `az monitor metrics list-definitions --resource ` for your MySQL version before treating an absent series as a config error. ### Environment variables (platform metrics) ```bash title=".env" AZURE_SUBSCRIPTION_ID=... MYSQLFLEX_RESOURCE_GROUP=... # RG containing the Flexible Server MYSQLFLEX_REGION=... # for cloud.region; defaults to the RG region MYSQLFLEX_SERVER_RESOURCE_ID=... # /subscriptions/.../flexibleServers/ MYSQLFLEX_SERVICE_NAME=mysqlflex-monitor ENVIRONMENT=production ``` Service Principal credentials (`AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET`) and Scout exporter credentials (`SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, `SCOUT_TOKEN_URL`, `SCOUT_OTLP_ENDPOINT`) come from the shared base config and are not listed here. See [Scout exporter wiring](../../collector-setup/scout-exporter.md). ### In-database metrics - direct scrape The Azure-specific deltas vs. the self-hosted [`mysqlreceiver` reference](../../component/mysql.md) are limited to five points. The receiver block, the full metric list, the resource processor, the pipeline, and the existing Troubleshooting (connection refused, authentication failed, statement-event metrics zero) all live in the self-hosted guide - follow that for the YAML and the metric definitions, and layer the deltas below on top. #### 1. Firewall rule for collector egress Public-access Flexible Server rejects all client IPs except those named in explicit firewall rules. Two rules are typical: ```bash title="firewall rules" # Allow Azure-internal traffic (Azure VMs, Container Apps, AKS pods) az mysql flexible-server firewall-rule create \ --resource-group --name \ --rule-name AllowAllAzureServicesAndResourcesWithinAzureIps \ --start-ip-address 0.0.0.0 --end-ip-address 0.0.0.0 # Allow your operator / collector IP az mysql flexible-server firewall-rule create \ --resource-group --name \ --rule-name otel-collector \ --start-ip-address \ --end-ip-address ``` The `0.0.0.0` start + end pair is the special-cased Flexible Server form that interprets the rule as "any Azure service in any subscription"; laptop / on-prem collectors hit it via the per-IP rule. #### 2. Monitoring user grants Repeated here from §Access setup because this is the single most common in-database-scrape-on-Azure pitfall: ```sql title="monitoring user" CREATE USER 'otel_monitor'@'%' IDENTIFIED BY ''; GRANT PROCESS, REPLICATION CLIENT ON *.* TO 'otel_monitor'@'%'; GRANT SELECT ON performance_schema.* TO 'otel_monitor'@'%'; FLUSH PRIVILEGES; ``` These three grants are exactly the self-hosted monitoring set. The Azure delta is that the Flexible Server admin is **not** `SUPER`, so do not attempt `GRANT ALL`, `WITH GRANT OPTION`, or `SUPER` - they fail with `ERROR 1045` or `ERROR 1227`. Verify the result with `SHOW GRANTS FOR 'otel_monitor'@'%';`. #### 3. `performance_schema` via Server Parameters Azure Flexible Server has no `my.cnf`; `performance_schema` is a Server Parameter: ```bash title="enable performance_schema" az mysql flexible-server parameter set \ --resource-group --server-name \ --name performance_schema --value ON ``` `performance_schema` is not hot-reloadable; setting this parameter queues a server restart and the change applies on the next boot. Sequence the work accordingly: apply it pre-flight (via Bicep `configurations` or before the server carries production traffic) so the server starts with `performance_schema` loaded rather than taking a restart mid-run. This is the MySQL analogue of the PostgreSQL `shared_preload_libraries` Server-Parameter load. #### 4. Statement-event consumers `performance_schema = ON` alone does not guarantee the `events_statements_*` consumers are enabled. On memory-constrained Burstable tiers some consumers default off to save memory, and the `mysqlreceiver` statement-event metrics then read zero. This is the exact "Statement event metrics always zero" case documented in the self-hosted guide - follow [self-hosted MySQL troubleshooting](../../component/mysql.md) to inspect `performance_schema.setup_consumers` and enable the `events_statements_*` rows. Do not duplicate that procedure here; the self-hosted guide is the single source for it. #### 5. Receiver config: TLS required The receiver block from the self-hosted guide works unchanged with the TLS bits flipped from the self-hosted defaults: ```yaml showLineNumbers title="mysqlreceiver delta for Azure Flex" receivers: mysql: endpoint: ".mysql.database.azure.com:3306" username: ${env:MYSQLFLEX_MONITORING_USER} password: ${env:MYSQLFLEX_MONITORING_PASSWORD} collection_interval: 10s allow_native_passwords: true tls: insecure: false # Flexible Server enforces TLS insecure_skip_verify: false # default CA bundle trusts Microsoft Root CA metrics: # see self-hosted MySQL guide for the full metrics block ... ``` Azure Flexible Server's server certificate chains to the Microsoft Root CA included in standard `ca-certificates` bundles. The `otel/opentelemetry-collector-contrib:0.151.0` image's default trust store accepts it without any custom `ca_file` configuration. Do not set `insecure_skip_verify: true` - that would bypass the cert verification you want on a public-internet connection. On Burstable B1ms the server's `max_connections` ceiling is around 85; the collector's single connection is well within that, but size application connection pools with the monitoring connection in mind so client traffic does not starve under load. The receiver shares the rest of its pipeline (processors, exporters) with whatever Scout-export pattern your collector already uses. See the self-hosted guide for the rest of the YAML. ### Operations #### `performance_schema` requires a server restart `performance_schema` is not hot-reloadable. Setting it via `az mysql flexible-server parameter set` queues a server restart; the change applies on the next boot. Application reconnect logic typically tolerates the restart window, but apply this parameter pre-flight and verify in staging before applying in production so you do not take an unplanned restart during a live workload. #### Statement-event metrics read zero on Burstable On Burstable tiers some `events_statements_*` consumers default off to save memory. The `mysqlreceiver` statement-event metrics stay zero until the consumers are enabled. Follow [self-hosted MySQL troubleshooting](../../component/mysql.md) to enable the `setup_consumers` rows. Above Burstable the consumers are typically on by default. #### Burstable credit burn On Burstable tiers, sustained CPU above the SKU's base rate drains a CPU credit pool. When credits exhaust, the server throttles to base rate. Whitelist `cpu_credits_remaining` and alert on it falling below a SKU-specific safety floor so you can scale up before throttling hits. #### `replication_lag` empty on a primary `replication_lag` is a replica-only metric. A single-primary server with no read replicas attached has zero series to emit. Treat an empty series on a primary as expected; it populates once a read replica is attached. #### `backup_storage_used` PT15M grain and first-backup lag See the Operations footnote in the metrics table above. The metric emits at a PT15M grain and does not populate until the first automated backup completes, hours after a server is first created. Treat a sparse or absent series as expected; use the Azure portal backup-quota view for backup-storage alerting. #### Diagnostic Settings ship cadence Resource-scope Diagnostic Settings first-batch ship lag on Flexible Server may take longer than Azure's documented 5-15 minute window on first attach. Steady-state batches arrive every few tens of seconds after that. Budget at least 15 minutes before treating an empty Event Hubs partition as a failure. #### RBAC propagation lag `Monitoring Reader` on the resource group typically propagates in under 30 seconds, occasionally up to 120 seconds. The first scrape after a fresh role assignment may return `403 AuthorizationFailed`. The receiver retries on the next 60s cycle; the noise clears within two polls. #### Resource provider registration The metrics path reads through the `Microsoft.DBforMySQL` resource provider; the logs path creates a Diagnostic Setting routed to Event Hubs. `Microsoft.DBforMySQL`, `Microsoft.EventHub`, and `Microsoft.Insights` must all be `Registered` in the subscription. If a provider is `NotRegistered`, metric scrapes return nothing or the Diagnostic Setting creation fails. Registration is a one-time, subscription-scoped action requiring a role with `*/register/action` (Contributor or Owner): ```bash az provider register --namespace Microsoft.DBforMySQL az provider register --namespace Microsoft.EventHub az provider register --namespace Microsoft.Insights ``` Confirm each with `az provider show --namespace --query registrationState -o tsv` (expect `Registered`). ### Key alerts to configure Once metrics are flowing, set up alerts on these thresholds. The "Why" column gives the reasoning so you can adjust thresholds for your workload. | Signal | Warning | Critical | Why | | --- | --- | --- | --- | | `cpu_percent` (5 min) | > 75% Average | > 90% Average | Saturation; on Burstable, sustained > base-rate burns credits. | | `memory_percent` (5 min) | > 80% Average | > 90% Average | Buffer-pool pressure; risk of swap on Burstable. | | `storage_percent` (10 min) | > 75% | > 90% | Pre-emptive scale-up; storage scaling is non-disruptive. | | `io_consumption_percent` (5 min) | > 75% | > 90% | I/O saturation drives query latency tail. | | `active_connections` vs `max_connections` (1 min) | > 75% | > 90% | Connection exhaustion is a hard failure mode. | | `aborted_connections` rate (5 min) | > 1/min sustained | > 10/min sustained | Auth or firewall misconfiguration; or upstream client churn. | | `Slow_queries` rate (5 min) | > 2x rolling 24h mean | > 5x rolling 24h mean | Slow-statement spike; pair with the slow-query log for per-statement attribution. | Configure the Scout-side alert rules through your dashboarding / alerting stack once thresholds are decided; the receiver pipeline above emits the underlying signals continuously. ### Logs Flexible Server publishes Diagnostic Settings categories that fill gaps the metric whitelist cannot. #### What logs uniquely fill Platform metrics aggregate. Logs disaggregate. The gaps logs uniquely cover for Flexible Server: - **Per-slow-statement attribution.** `Slow_queries` tells you the count of statements that crossed `long_query_time`; `MySqlSlowLogs` tells you **which** statements crossed it, in which database, with lock time, rows examined, and rows sent. No metric exposes the statement text or the per-statement cost. - **Lock-wait detail on slow statements.** A slow statement blocked on a lock shows its lock time in the slow-log record, so you can separate "slow because the plan is bad" from "slow because it waited on a lock". The aggregate `Slow_queries` metric cannot make that distinction. - **Rows-examined vs rows-sent skew.** The slow-log record carries both counts, which surfaces missing-index and full-scan patterns (high rows-examined, low rows-sent) that no aggregate metric exposes. - **Connection, DDL, and DML provenance (optional).** The audit-log category records who connected, from where, and which `CREATE` / `ALTER` / `DROP` / `INSERT` / `UPDATE` / `DELETE` ran. Required for change-management forensics and unauthorised-change detection; off by default because of its volume. #### Architecture ```text Flexible Server (Microsoft.DBforMySQL/flexibleServers) | | Diagnostic Setting (resource scope) | category: MySqlSlowLogs (default) v Event Hubs namespace (Basic 1 TU) | . diagsend SAS rule (Send) writes records | . collectorlisten SAS rule (Listen) reads records v azure_event_hub receiver | . format: azure | . apply_semantic_conventions: true | . cloud.resource_id lifted from the per-record envelope v otlp_http/b14 -> Scout ``` The Diagnostic Setting targets the **server** resource directly. The receiver authenticates with the Listen SAS connection string, not a namespace role assignment. #### Categories enabled by default | Category | What it covers | | --- | --- | | `MySqlSlowLogs` | Slow-query log: statements exceeding `long_query_time`, with lock time, rows examined, and rows sent. The single highest-signal category for routine query debugging on Flexible Server. | **Slow-query records depend on the threshold.** `MySqlSlowLogs` records a statement only when it exceeds `long_query_time`. A workload whose statements all run faster than the threshold produces an empty slow log even though the Diagnostic Setting is attached and the pipeline is healthy. Lower `long_query_time` to a value below the slowest queries you want to capture, or confirm the path end-to-end with a deliberate slow probe such as `SELECT SLEEP(2)` when `long_query_time` is `1` second. #### Optional category Named here so you know it exists; enable per workload: - **`MySqlAuditLogs`** - connection / DDL / DML audit. It requires the `audit_log_enabled` and `audit_log_events` Server Parameters and adds substantial Diagnostic Settings volume. Enable it only when you have a forensic or compliance need and the volume budget for it; disable it when the investigation closes. #### Receiver configuration (logs) ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_event_hub/mysqllogs: connection: ${env:MYSQLFLEXLOGS_CONNECTION_STRING} partition: "" # resume across all partitions offset: "" # resume from last checkpoint format: azure # decode Azure resource-log envelope apply_semantic_conventions: true processors: resource/mysqllogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_mysql_flexible_server, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:MYSQLFLEXLOGS_SOURCE_REGION}", action: insert} # cloud.resource_id is NOT pinned - the receiver lifts the per-record # Azure resource ID to this attribute automatically (UPPERCASED). - {key: deployment.environment.name, value: "${env:MYSQLFLEXLOGS_ENVIRONMENT}", action: insert} - {key: environment, value: "${env:MYSQLFLEXLOGS_ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:MYSQLFLEXLOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/mysqllogs: receivers: [azure_event_hub/mysqllogs] processors: [memory_limiter, resource/mysqllogs, batch] exporters: [otlp_http/b14] ``` On a freshly started collector the `azure_event_hub` receiver spends roughly 15 to 20 minutes establishing its Event Hubs consumer before it delivers the first record downstream, even when records are already in the hub. The Diagnostic Settings to Event Hubs leg itself is fast. Budget 20 minutes before treating an empty logs pipeline as broken, and do not restart the collector during that window - a restart resets the warm-up clock and you start the 20 minutes again. On collector restart after warm-up the receiver resumes from its last checkpoint, so an idle window during deployment does not lose records that arrived in the meantime (the hub retains 1 day on Basic). The `MYSQLFLEXLOGS_CONNECTION_STRING` value is the Listen-permission SAS connection string for the namespace, **with `;EntityPath=` appended** so the receiver knows which hub to consume from. Fetch it once via: ```bash title="fetch the Listen connection string" az rest --method post \ --url "https://management.azure.com${COLLECTOR_LISTEN_RULE_ID}/listKeys?api-version=2024-01-01" \ --query primaryConnectionString -o tsv ``` Then append `;EntityPath=` and store the result in your collector's env file. The connection string carries `;` separators, so single-quote it in the env file (`VAR='...'`) - an unquoted value is truncated at the first `;` when the env file is sourced. #### Environment variables (logs) ```bash title=".env (logs path)" MYSQLFLEXLOGS_CONNECTION_STRING='...' # Listen SAS with ;EntityPath=, single-quoted MYSQLFLEXLOGS_SOURCE_REGION=... # for cloud.region on log records MYSQLFLEXLOGS_SERVICE_NAME=mysqlflex-logs MYSQLFLEXLOGS_ENVIRONMENT=production ``` #### Wiring the Diagnostic Setting ```bash title="attach the Diagnostic Setting" az monitor diagnostic-settings create \ --resource "" \ --name mysqlflex-logs \ --event-hub \ --event-hub-rule "" \ --logs '[{"category":"MySqlSlowLogs","enabled":true}]' ``` The `--event-hub-rule` value is the resource ID of the namespace-scoped SAS rule with `Send` permission. The receiver uses a separate Listen rule; one Send rule and one Listen rule on the namespace is the canonical two-rule topology, and the Listen rule replaces a namespace role assignment for the receiver. #### Server Parameter prerequisites for log content The Diagnostic Settings path routes whatever the server writes to its slow log. To populate `MySqlSlowLogs` with useful content, set these Server Parameters: ```bash az mysql flexible-server parameter set --resource-group --server-name --name slow_query_log --value ON az mysql flexible-server parameter set --resource-group --server-name --name long_query_time --value 1 az mysql flexible-server parameter set --resource-group --server-name --name log_output --value FILE ``` Tune `long_query_time` to your slow-query threshold. A low-latency workload may stay under the default and produce an empty slow log; either lower the threshold or drive a deliberate `SELECT SLEEP(2)` probe to confirm the path before relying on it. #### Verifying the logs path After the Diagnostic Setting is attached and the server has executed at least one statement slower than `long_query_time`: 1. Wait for the receiver warm-up window (up to ~20 minutes on a fresh collector) plus the resource-scope Diagnostic Settings first-batch lag. Do not restart the collector during the warm-up. 2. Tail the collector debug exporter: `docker compose logs -f otel-collector | grep "otelcol.signal.*logs"`. 3. Expect slow-log records to arrive in small batches once the workload produces statements over the threshold. 4. In Scout, filter `service.name = 'mysqlflex-logs'` and `cloud.platform = 'azure_mysql_flexible_server'`; group by `azure.category` to confirm `MySqlSlowLogs` populates. ### Troubleshooting #### In-database receiver: authentication failed or grant error **Cause:** The monitoring user is missing one of the three required grants, or someone attempted `GRANT ALL` / `SUPER` (which the non-`SUPER` Flexible Server admin cannot issue). **Fix:** Re-run the three-grant block from §Access setup and verify with `SHOW GRANTS FOR 'otel_monitor'@'%';`. Do not widen beyond `PROCESS`, `REPLICATION CLIENT`, and `SELECT ON performance_schema.*`. #### In-database receiver: statement-event metrics always zero **Cause:** `performance_schema` is off, or the `events_statements_*` consumers are off (common on Burstable tiers). **Fix:** Confirm `performance_schema = ON` via the Server Parameter, then follow the [self-hosted MySQL "Statement event metrics always zero" troubleshooting](../../component/mysql.md) to enable the `setup_consumers` rows. Note the `performance_schema` Server Parameter change triggers a server restart, so apply it pre-flight. #### Platform-metrics `AuthorizationFailed` on the first scrape **Cause:** The `Monitoring Reader` role assignment on the resource group has not yet propagated. **Fix:** Wait two polling cycles (~2 minutes). The receiver retries automatically; the error self-clears. #### `connection refused` from the in-database receiver **Cause:** The collector's egress IP is not in the Flexible Server's firewall allowlist. **Fix:** Add the IP via `az mysql flexible-server firewall-rule create`. If the collector runs in Azure (VM, AKS), add the `0.0.0.0` Azure-services rule instead. #### Metric `replication_lag` shows no data **Cause:** Expected behaviour - `replication_lag` is replica-only and the server has no read replica attached. **Fix:** None needed on a primary. The series populates when a read replica is attached. #### Metric `backup_storage_used` shows `no recent data` in Scout **Cause:** Expected behaviour - PT15M grain at a 60s receiver interval, and the series does not populate until the first automated backup completes (hours after a server is first created). **Fix:** See Operations -> `backup_storage_used` PT15M grain and first-backup lag. #### First Event Hubs batch is empty after 20 minutes **Cause:** Either the `azure_event_hub` receiver is still in its consumer warm-up window, or the server has not yet produced a slow statement in the enabled category. **Fix:** Confirm the warm-up window has fully elapsed without a collector restart, then drive a slow statement (`mysql -h -u -p -e 'SELECT SLEEP(2)'`) so `MySqlSlowLogs` has a record to ship. #### `azure_event_hub` receiver logs `MessagingGatewayBadRequest` **Cause:** The receiver is requesting a user-defined consumer group that does not exist on Event Hubs Basic. **Fix:** Basic tier rejects user-defined consumer groups - the receiver must consume from `$Default`, the implicit group. Remove any `consumer_group:` key from the receiver config or upgrade the namespace to Standard if you need multiple consumer groups. #### `MySqlSlowLogs` records never arrive **Cause:** `long_query_time` is higher than your typical query latency, so no statement crosses the slow threshold. **Fix:** Drop `long_query_time` to a value below the slowest queries you want to capture, or run a deliberate `SELECT SLEEP(2)` probe to confirm the path end-to-end. ### Frequently Asked Questions #### How do I monitor Azure MySQL Flexible Server with OpenTelemetry? Three instrumentation paths complement each other. Platform metrics use `azure_monitor` against `Microsoft.DBforMySQL/flexibleServers` for resource saturation, connection counts, and network throughput. The in-database scrape uses the OpenTelemetry `mysqlreceiver` against the server's public FQDN over TLS for `performance_schema` depth: statement events, table I/O, lock waits, and per-query counters. Resource logs use `azure_event_hub` consuming the Diagnostic Settings category `MySqlSlowLogs` for per-slow-statement detail. Pick paths based on how deep the debug-attribution needs to go. #### Why can't my monitoring user read performance_schema on Azure MySQL? The Azure Database for MySQL Flexible Server admin is not a `SUPER` user, so `GRANT ALL` and `WITH GRANT OPTION` fail. The monitoring user needs exactly three global grants the admin can issue: `GRANT PROCESS, REPLICATION CLIENT ON *.*` and `GRANT SELECT ON performance_schema.*`. With those three grants the `mysqlreceiver` reads global status, replica status, and the `performance_schema` tables it scrapes. Anything broader than these three will fail with `ERROR 1045` or `ERROR 1227`. #### How do I enable performance_schema on Azure MySQL Flexible Server? `performance_schema` is enabled through a Server Parameter, not `my.cnf`. Set it with `az mysql flexible-server parameter set --name performance_schema --value ON`. This parameter requires a server restart, so apply it pre-flight (via Bicep `configurations` or before the server carries production traffic) and let the server boot with it loaded. `performance_schema` ON alone does not guarantee the `events_statements_*` consumers are enabled, especially on memory-constrained Burstable tiers; if statement-event metrics read zero, follow the self-hosted MySQL statement-event troubleshooting to enable the `setup_consumers` rows. #### Is backup_storage_used safe to alert on at a 60-second collection interval? No. `backup_storage_used` emits at a PT15M native grain on Azure Monitor and does not populate until the first automated backup completes, which is hours after a server is first created. A receiver polling at 60 seconds will report `no recent data` for most cycles, and a freshly created server reports nothing at all until its first backup. Treat a sparse or absent series as expected behaviour rather than a pipeline failure, and rely on the Azure portal backup-quota view for backup-storage alerting. #### Why is replication_lag empty on my Azure MySQL Flexible Server? `replication_lag` is a replica-only metric. On a single-primary server with no read replicas attached there are zero series to emit, so the metric stays empty. This is expected behaviour, not a broken whitelist. The series populates once a read replica is attached to the server. #### Why are MySqlSlowLogs records empty under my workload? `MySqlSlowLogs` records a statement only when its execution time exceeds `long_query_time`. A workload whose statements all run faster than the threshold produces an empty slow log even though the Diagnostic Setting is attached and the pipeline is healthy. Lower `long_query_time` to a value below the slowest queries you want to capture, or confirm the path end-to-end with a deliberate slow probe such as `SELECT SLEEP(2)` when `long_query_time` is `1` second. ### Related Guides #### Same surface, different paths - [Self-hosted MySQL](../../component/mysql.md) - the `mysqlreceiver` reference for the in-database scrape. This guide layers Azure-specific deltas (firewall, three-grant monitoring user, `performance_schema` via Server Parameters, TLS-required) on it, and cross-links its statement-event troubleshooting rather than duplicating it. #### Shared collector + Scout wiring - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - the runtime that hosts both receivers in this guide. - [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - alternative runtime for AKS-hosted collectors. - [Scout exporter wiring](../../collector-setup/scout-exporter.md) - the `oauth2client` extension + `otlp_http/b14` exporter block shared by all Azure guides. #### Apps-side instrumentation - [Spring Boot](../../apps/auto-instrumentation/spring-boot.md) - JVM apps connecting to Flexible Server over JDBC. - [Symfony](../../apps/auto-instrumentation/symfony.md) - PHP apps connecting to Flexible Server over PDO / Doctrine. #### Adjacent Azure surfaces - [Azure Database for PostgreSQL](./database-for-postgresql.md) - managed Postgres on Azure; the typical alternative when the workload needs Postgres rather than MySQL. - [Azure App Service](./app-service.md) - common host for web apps that connect to Flexible Server. - [Azure Cache for Redis](./cache-for-redis.md) - caching layer typically sat in front of MySQL. - [Azure Key Vault](./key-vault.md) - secrets store for the monitoring user's password. - [Azure SQL Database](./sql-database.md) - managed SQL Server on Azure; the alternative when the workload needs T-SQL. --- ## Azure Database for PostgreSQL Monitoring with OpenTelemetry - Platform Metrics, In-Database, and Resource Logs ## Azure Database for PostgreSQL Monitoring with OpenTelemetry > **Why Scout for Azure Database for PostgreSQL observability?** > > Azure Monitor's metric catalog gives you resource saturation and > connection lifecycle at minute grain - enough for capacity alerts but > not enough to attribute a 5xx burst to a specific query or table. The > OTel `postgresqlreceiver` reads the same `pg_stat_*` views directly > over a TLS-required connection, giving you per-database, per-table, > and per-WAL signals at 10-second grain. Scout consumes both pipelines > via OTLP and stores them alongside your AWS, GCP, on-prem, and > application telemetry in one OTel-native query surface. > > Single-server (`Microsoft.DBforPostgreSQL/servers`) was retired by > Microsoft and is **not** covered by this guide. Flexible Server > (`Microsoft.DBforPostgreSQL/flexibleServers`) is the only supported > shape. :::note Running this in production pgX adds query, lock, and connection analysis on top of these metrics. [Check out base14 pgX](https://base14.io/scout/pgx). ::: ### Overview Azure Database for PostgreSQL Flexible Server is a managed PaaS PostgreSQL with public or VNet-integrated access, a fixed admin role, and a curated allowlist of extensions. Observability splits cleanly across three paths: - **Platform metrics** via the `azure_monitor` receiver against the `Microsoft.DBforPostgreSQL/flexibleServers` namespace. - **In-database metrics** via the OpenTelemetry `postgresqlreceiver` connecting to the server's public FQDN over TLS. Identical receiver config to self-hosted Postgres; only the auth and TLS bits differ. See [self-hosted PostgreSQL](../../component/postgres.md) for the full receiver reference and metric definitions; this guide documents only the Azure-specific deltas. - **Resource logs** via the `azure_event_hub` receiver against a Diagnostic Settings → Event Hubs pipeline. This guide configures the platform-metrics and resource-logs receivers in full and the in-database-scrape deltas. The in-database receiver block itself, the full 33-metric list, and the collector pipeline structure live in the self-hosted Postgres guide. ### Instrumentation paths for Flexible Server Three paths exist; pick one, two, or all three based on the table below. | Path | What it covers | What it costs | Setup | | --- | --- | --- | --- | | **Platform metrics - Azure Monitor** (this guide, §What you'll monitor) | Resource saturation (CPU, memory, IOPS, storage), connection lifecycle (active / failed / succeeded), network throughput, transaction-log volume, hourly backup floor. Per-server resolution; minute grain. Does **not** see inside the database. | Azure Monitor query cost: one query per metric per scrape. At a 60s interval the daily cost runs in cents per server. | One Service Principal with `Monitoring Reader` on the resource group; one receiver block; one resource processor. | | **In-database metrics - direct scrape** (this guide, §In-database metrics; details cross-linked to self-hosted Postgres) | Per-database commits / rollbacks, tuple ops, WAL activity, replication lag, bgwriter health, index scans, table size, dead-tuple counts, lock contention. Per-database and per-table resolution; 10-second grain. Sees inside the database. | One `postgresqlreceiver` block in your collector; a dedicated monitoring user with `pg_monitor` + `azure_pg_admin` grants; an open TCP/5432 path from collector → server FQDN with TLS. | Bicep sets `shared_preload_libraries = pg_stat_statements` via Server Parameters; the monitoring user holds the two-role grant; the receiver hits the public FQDN over TLS. | | **Resource logs - Diagnostic Settings → Event Hubs** (this guide, §Logs below) | Per-connection and per-disconnection events (from `log_connections=on`, `log_disconnections=on`); slow queries above `log_min_duration_statement`; DDL audit (from `log_statement=ddl`); errors, lock waits, autovacuum runs. Per-record resolution; sub-second grain. | One Event Hubs Basic namespace (~$11/mo at 1 TU; 1 MB/s ingress absorbs roughly 4,000 records/sec at typical record size). The Diagnostic Setting itself is free. | One Diagnostic Setting on the server with the categories you care about; one Event Hubs namespace + hub + Send/Listen SAS rules; one `azure_event_hub` receiver fragment. | #### Which path to pick Four decision criteria, in order of usual weight: 1. **Tier choice (Burstable / GeneralPurpose / MemoryOptimized).** Burstable B1ms / B2s is the cheapest shape but has a 2 GiB RAM ceiling that limits `pg_stat_statements`'s working set. The in-database scrape adds tangible value only above Burstable - on Burstable the platform metrics cover the relevant signals. Move to the in-database scrape + `pg_stat_statements` analysis on GeneralPurpose D2s_v3 and larger. 2. **Existing collector posture.** If you already run a Kubernetes collector or a shared scraper container that consumes `azure_monitor` for other surfaces, fold platform-metrics scraping into that. The in-database scrape is a separate per-database concern - typically a small dedicated collector beside the application that owns the database. 3. **Diagnostic Settings volume budget.** `PostgreSQLLogs` plus `PostgreSQLFlexSessions` is moderate-volume: a couple of records per session lifecycle plus slow-query records above the threshold. The four Query Store-derived categories (`PostgreSQLFlexQueryStoreRuntime`, `PostgreSQLFlexQueryStoreWaitStats`, `PostgreSQLFlexTableStats`, `PostgreSQLFlexDatabaseXacts`) add per-query and per-table records at much higher volume - enable them only when tuning specific workloads. 4. **Depth-of-debug appetite.** Resource saturation alerts only? Platform metrics alone. Per-query attribution? The in-database scrape plus resource logs with Query Store-derived categories. If you are starting from zero, platform metrics plus resource logs (default categories) is the lowest-effort win and catches the broadest range of saturation and per-connection incidents. Add the in-database scrape when investigations need per-database depth, and turn on the Query Store categories when you are actively tuning queries. ### What you'll monitor The platform-metrics receiver scrapes one Azure Monitor namespace and emits metrics under `cloud.platform: azure_postgresql_flexible_server`. #### Flexible Server metrics (`Microsoft.DBforPostgreSQL/flexibleServers`) | Metric | Aggregation | What it tells you | | --- | --- | --- | | `cpu_percent` | Average, Maximum | Server-wide CPU utilisation. On Burstable tiers, sustained CPU above the SKU's base rate (5% on B1ms, 20% on B2s, 40% on B2ms) drains the CPU credit pool. | | `memory_percent` | Average, Maximum | Server-wide RAM utilisation. Burstable B1ms (2 GiB) is the most memory-constrained SKU; idle baseline depends on PG version and Query Store configuration. Treat the idle line as workload-relative rather than absolute. | | `iops` | Average, Maximum | Disk operations per second across read + write. Compare against the SKU's IOPS ceiling. | | `disk_bandwidth_consumed_percentage` | Average, Maximum | Disk throughput utilisation as a percentage of the SKU's bandwidth ceiling. | | `storage_percent` | Average, Maximum | Provisioned storage utilisation. Pre-emptive: scale storage before this hits 90%. | | `storage_used` | Average | Provisioned storage used in bytes. Pairs with `storage_percent` for absolute-byte alerting. | | `storage_free` | Average | Bytes of free storage. The complementary signal to `storage_used`. | | `active_connections` | Average, Maximum | Concurrent backends. Compare against the SKU's `max_connections` ceiling (50 on B1ms, scales with vCPU on larger SKUs). | | `connections_failed` | Total | Failed connection attempts in the period. Sustained non-zero values indicate auth misconfiguration, firewall rejection, or upstream client churn. | | `connections_succeeded` | Total | Successful connection attempts. Pairs with `connections_failed` for an auth-success rate. | | `network_bytes_egress` | Total | Bytes sent from the server to clients. | | `network_bytes_ingress` | Total | Bytes received from clients. | | `txlogs_storage_used` | Average | Bytes occupied by WAL on the server's transaction-log volume. Climbs under write-heavy workloads and during archive-recovery delays. Note the metric name has no underscore between `tx` and `logs`. | | `backup_storage_used` | Average | Bytes used in automated backup storage. See Operations footnote below. | **Operations footnote - `backup_storage_used`:** The catalog exposes `backup_storage_used` at a PT1H native grain. A receiver polling at 60s will see it populate once per hour and report `no recent data` for the intervening 59 cycles. Either run a second `azuremonitorreceiver` instance scoped to `backup_storage_used` with `collection_interval: 1h`, or drop the metric from the whitelist and use the Azure portal's backup-quota view instead. **Catalog-available extras** (the full catalog has 73 metrics; named here for completeness, add to your whitelist when the workload warrants): - Burstable credit health: `cpu_credits_consumed`, `cpu_credits_remaining`. - IO direction split: `read_iops`, `write_iops`, `read_throughput`, `write_throughput`. - IO saturation detail: `disk_iops_consumed_percentage`, `disk_queue_depth`. - Per-database PG stats: `tps`, `xact_total`, `xact_commit`, `xact_rollback`, `numbackends`, `deadlocks`, `tup_inserted`, `tup_updated`, `tup_deleted`, `tup_returned`, `tup_fetched`, `temp_files`, `temp_bytes`, `blks_read`, `blks_hit`. (The in-database scrape covers these at higher resolution; whitelist them in Azure Monitor only if you do not run it.) - Session detail: `sessions_by_state`, `sessions_by_wait_event_type`. - Replication: `oldest_backend_time_sec`, `oldest_backend_xmin`, `oldest_backend_xmin_age`. - Maintenance signal: `bloat_percent` (per-DB), `database_size_bytes`. - Pooled-connection details (when pgbouncer enabled): `client_connections_active`, `client_connections_waiting`, `server_connections_active`, `server_connections_idle`, `total_pooled_connections`, `tcp_connection_backlog`. - Health pulse: `is_db_alive`. Equivalent to `active_connections > 0`. ### Prerequisites | Requirement | Detail | | --- | --- | | Server tier | Flexible Server, any SKU. Burstable B1ms is the smallest tier covered here; GeneralPurpose D2s_v3 and larger unlock the full in-database-scrape value (Burstable tiers have a 2 GiB RAM ceiling that limits `pg_stat_statements`'s working set). | | PostgreSQL version | 13, 14, 15, 16, or 17 (when GA in your region). The receiver works on all supported versions. | | OTel Collector Contrib | v0.151+ (the `azure_monitor` and `azure_event_hub` receiver names are snake_case from v0.148.0; v0.151.0 is the current fleet). | | OpenTelemetry semconv | v1.41.0. | | Azure CLI | 2.85+ for the `az monitor diagnostic-settings` flags used here. | | Azure providers registered | `Microsoft.DBforPostgreSQL`, `Microsoft.EventHub`. The PostgreSQL provider in particular is often `NotRegistered` on fresh subscriptions and takes ~70 seconds to register. | | Collector runtime | See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) or [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) for the runtime; this guide adds the PostgreSQL-specific receiver + processor blocks on top. | | Scout exporter | See [Scout exporter wiring](../../collector-setup/scout-exporter.md) for the `oauth2client` extension + `otlp_http/b14` exporter. This guide does not re-derive that block. | ### Access setup Two role assignments cover the metrics path; the logs path uses SAS auth on the Event Hubs SAS rule and does not require an additional role. | Role | Scope | Reason | | --- | --- | --- | | `Monitoring Reader` | Resource group containing the Flex Server | Lets the `azure_monitor` receiver list metric definitions and read metric values. | | `Reader` (optional) | Subscription or resource group | Convenient for the same SP to enumerate other Azure surfaces in the same RG; not strictly required for the receiver. | Both metric-path assignments are idempotent - re-running them on a previously granted SP is a no-op. The in-database receiver uses a **PostgreSQL** role, not an Azure role. Connect as the server admin (or any user with `CREATEROLE`), create a dedicated monitoring user, and grant it both `pg_monitor` (standard) and `azure_pg_admin` (Azure-specific): ```sql title="setup monitoring user" CREATE USER postgres_exporter WITH PASSWORD ''; GRANT pg_monitor TO postgres_exporter; GRANT azure_pg_admin TO postgres_exporter; ``` The `azure_pg_admin` grant is the Azure-specific delta. Without it, the receiver fails to read `pg_stat_replication` and the `azure_*` system views, and emits a partial metric set with permission-denied warnings in its log. ### Receiver configuration (platform metrics) ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_monitor/postgresql: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:PGFLEX_RESOURCE_GROUP} services: - Microsoft.DBforPostgreSQL/flexibleServers auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.DBforPostgreSQL/flexibleServers": cpu_percent: [Average, Maximum] memory_percent: [Average, Maximum] iops: [Average, Maximum] disk_bandwidth_consumed_percentage: [Average, Maximum] storage_percent: [Average, Maximum] storage_used: [Average] storage_free: [Average] active_connections: [Average, Maximum] connections_failed: [Total] connections_succeeded: [Total] network_bytes_egress: [Total] network_bytes_ingress: [Total] txlogs_storage_used: [Average] backup_storage_used: [Average] processors: resource/postgresql: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_postgresql_flexible_server, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:PGFLEX_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:PGFLEX_SERVER_RESOURCE_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:PGFLEX_SERVICE_NAME}", action: insert} service: pipelines: metrics/postgresql: receivers: [azure_monitor/postgresql] processors: [memory_limiter, resource/postgresql, batch] exporters: [otlp_http/b14] ``` The metric name `txlogs_storage_used` carries no underscore between `tx` and `logs`. Azure's catalog uses the concatenated form. ### Environment variables (platform metrics) ```bash title=".env" AZURE_SUBSCRIPTION_ID=... PGFLEX_RESOURCE_GROUP=... # RG containing the Flex Server PGFLEX_REGION=... # for cloud.region; defaults to the RG region PGFLEX_SERVER_RESOURCE_ID=... # /subscriptions/.../flexibleServers/ PGFLEX_SERVICE_NAME=pgflex-monitor ENVIRONMENT=production ``` Service Principal credentials (`AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET`) and Scout exporter credentials (`SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, `SCOUT_TOKEN_URL`, `SCOUT_OTLP_ENDPOINT`) come from the shared base config and are not listed here. See [Scout exporter wiring](../../collector-setup/scout-exporter.md). ### In-database metrics - direct scrape The Azure-specific deltas vs. the self-hosted [`postgresqlreceiver` reference](../../component/postgres.md) are limited to four points. The receiver block, the 33-metric list, the resource processor, and the pipeline all live in the self-hosted guide - follow that for the YAML and the metric definitions, and layer the deltas below on top. #### 1. Firewall rule for collector egress Public-access Flex Server rejects all client IPs except those named in explicit firewall rules. Two rules are typical: ```bash title="firewall rules" # Allow Azure-internal traffic (Azure VMs, Container Apps, AKS pods) az postgres flexible-server firewall-rule create \ --resource-group --name \ --rule-name AllowAllAzureServicesAndResourcesWithinAzureIps \ --start-ip-address 0.0.0.0 --end-ip-address 0.0.0.0 # Allow your operator / collector IP az postgres flexible-server firewall-rule create \ --resource-group --name \ --rule-name AllowCollectorIp \ --start-ip-address \ --end-ip-address ``` The `0.0.0.0` start + end pair is the special-cased Flex Server form that interprets the rule as "any Azure service in any subscription"; laptop / on-prem collectors hit it via the per-IP rule. #### 2. Monitoring user grants Repeated here from §Access setup because this is the single most common in-database-scrape-on-Azure pitfall: ```sql title="monitoring user" CREATE USER postgres_exporter WITH PASSWORD ''; GRANT pg_monitor TO postgres_exporter; GRANT azure_pg_admin TO postgres_exporter; ``` The receiver scrapes `pg_stat_replication` (and several `azure_*` views) which require `azure_pg_admin`. Skip this grant and the receiver returns partial data with `permission denied` log entries. #### 3. `pg_stat_statements` via Server Parameters Azure Flex Server restricts `shared_preload_libraries` to an allowlist. Loading `pg_stat_statements` is a two-step Server Parameter change followed by a `CREATE EXTENSION`: ```bash title="enable pg_stat_statements" # Add to shared_preload_libraries (triggers a server restart) az postgres flexible-server parameter set \ --resource-group --server-name \ --name shared_preload_libraries --value pg_stat_statements # Add to Azure's extension allowlist az postgres flexible-server parameter set \ --resource-group --server-name \ --name azure.extensions --value PG_STAT_STATEMENTS ``` ```sql title="load extension after restart" CREATE EXTENSION IF NOT EXISTS pg_stat_statements; ``` The first command triggers a server restart. Sequence the work accordingly: schedule the parameter change during a maintenance window, wait for the server to come back up, then run the `CREATE EXTENSION` from a psql session. Without the `shared_preload_libraries` change the `pg_stat_statements` view is empty even after `CREATE EXTENSION` succeeds. #### 4. Receiver config: TLS required The receiver block from the self-hosted guide works unchanged with two tweaks: ```yaml showLineNumbers title="postgresqlreceiver delta for Azure Flex" receivers: postgresql: endpoint: ".postgres.database.azure.com:5432" transport: tcp collection_interval: 10s username: ${env:PGFLEX_MONITORING_USER} password: ${env:PGFLEX_MONITORING_PASSWORD} databases: - tls: insecure: false # Flex Server enforces TLS insecure_skip_verify: false # default CA bundle trusts Microsoft Root CA metrics: # see self-hosted Postgres guide for the 33-metric block ... ``` Azure Flex Server's server certificate chains to the Microsoft Root CA included in standard `ca-certificates` bundles. The `otel/opentelemetry-collector-contrib:0.151.0` image's default trust store accepts it without any custom `ca_file` configuration. Do not set `insecure_skip_verify: true` - that would bypass the cert verification you want on a public-internet connection. The receiver shares the rest of its pipeline (processors, exporters) with whatever Scout-export pattern your collector already uses. See the self-hosted guide for the rest of the YAML. ### Operations #### `azure_pg_admin` grant ordering When you create the monitoring user, the two grants (`pg_monitor`, `azure_pg_admin`) must come from a role that holds them. The server admin (the user named in `administratorLogin` on Bicep) has both by default. If you delegate user-management to a non-admin DBA role, verify the DBA role holds `azure_pg_admin` via `\du+ ` - the grant is not transferable to non-admin roles by default. #### `pg_stat_statements` requires server restart `shared_preload_libraries` is not hot-reloadable. Setting it via `az postgres flexible-server parameter set` queues a server restart; the change applies on the next boot. Application reconnect logic typically tolerates the 30-60 second restart window, but verify in staging before applying in production. #### Burstable credit burn On Burstable tiers, sustained CPU above the SKU's base rate (5% on B1ms, 20% on B2s, 40% on B2ms) drains a CPU credit pool. When credits exhaust, the server throttles to base rate. Alert on `cpu_credits_remaining` falling below a SKU-specific safety floor (50 credits for B1ms is a reasonable starting point) so you can scale up before throttling hits. #### `backup_storage_used` PT1H grain See the Operations footnote in the metrics table above. The metric populates once per hour; a 60s receiver sees `no recent data` for 59/60 cycles. Drop the metric or run a slow-poll receiver instance. #### Diagnostic Settings ship cadence Resource-scope Diagnostic Settings first-batch ship lag on Flex Server typically lands within Azure's documented 5-15 minute window on first attach. Steady-state batches arrive every 10 to 30 seconds after that. Budget at least 15 minutes before treating an empty Event Hubs partition as a failure. #### RBAC propagation lag `Monitoring Reader` on the resource group typically propagates in under 30 seconds, occasionally up to 120 seconds. The first scrape after a fresh role assignment may return `403 AuthorizationFailed`. The receiver retries on the next 60s cycle; the noise clears within two polls. #### Provider registration on first deploy A fresh Azure subscription often has `Microsoft.DBforPostgreSQL` in `NotRegistered` state. Registering takes ~70 seconds: ```bash az provider register --namespace Microsoft.DBforPostgreSQL ``` Confirm with `az provider show --namespace Microsoft.DBforPostgreSQL --query registrationState -o tsv` before triggering the Bicep deploy. ### Key alerts to configure Once metrics are flowing, set up alerts on these thresholds. The "Why" column gives the reasoning so you can adjust thresholds for your workload. | Signal | Warning | Critical | Why | | --- | --- | --- | --- | | `cpu_percent` (5 min) | > 75% Average | > 90% Average | Saturation; on Burstable, sustained > base-rate burns credits. | | `memory_percent` (5 min) | > 80% Average | > 90% Average | Buffer-cache pressure; risk of swap on Burstable. | | `storage_percent` (10 min) | > 75% | > 90% | Pre-emptive scale-up; storage scaling is non-disruptive. | | `iops` vs SKU ceiling (5 min) | > 75% of SKU IOPS | > 90% of SKU IOPS | I/O saturation drives query latency tail. | | `active_connections` vs `max_connections` (1 min) | > 75% | > 90% | Connection exhaustion is a hard failure mode. | | `connections_failed` rate (5 min) | > 1/min sustained | > 10/min sustained | Auth or firewall misconfiguration; or upstream client churn. | | `txlogs_storage_used` (1 hour) | > 2× rolling 24h mean | > 5× rolling 24h mean | WAL accumulation indicates write spike or archive-recovery delay. | Configure the Scout-side alert rules through your dashboarding / alerting stack once thresholds are decided; the receiver pipeline above emits the underlying signals continuously. ### Logs Flex Server publishes a rich set of Diagnostic Settings categories that fill gaps the metric whitelist cannot. #### What logs uniquely fill Platform metrics aggregate. Logs disaggregate. The gaps logs uniquely cover for Flex Server: - **Per-connection attribution.** `active_connections` tells you 50 backends are live; `PostgreSQLLogs` and `PostgreSQLFlexSessions` tell you **which** users, **from which IPs**, with **which application_name**, established each one. Required for tenant- attribution, credential-rotation forensics, and noisy-client detection. - **Per-query slow-query attribution.** `cpu_percent` tells you the server worked hard; `PostgreSQLLogs` (above `log_min_duration_statement`) tells you **which** statements crossed the slow threshold, in which database, by which user. No metric exposes this. - **DDL audit.** `log_statement = ddl` records every `CREATE`, `ALTER`, `DROP` against any schema. Required for change-management forensics and unauthorised-schema-change detection. - **Lock-wait detail.** PG records lock-wait events above `deadlock_timeout` (1 s default). Aggregated `deadlocks` metric tells you it happened; the log entry tells you which queries collided and on which row / table. - **Autovacuum / autoanalyze runs.** Per-table autovacuum events with start time, duration, and tuple-removal counts. The aggregated `bloat_percent` metric tells you a table is bloated; the log entry tells you which autovacuum runs completed (or were skipped) and why. - **Connection lifecycle events.** Per-session connect / disconnect with duration. `PostgreSQLFlexSessions` records these at higher resolution than `PostgreSQLLogs`'s connection-event log lines and carries `session_id`, `application_name`, `client_addr`, and `backend_type` for correlation. #### Architecture ```text Flex Server (Microsoft.DBforPostgreSQL/flexibleServers) │ │ Diagnostic Setting (resource scope) │ categories: PostgreSQLLogs + PostgreSQLFlexSessions (default) ↓ Event Hubs namespace (Basic 1 TU) │ • diagsend SAS rule (Send) writes records │ • collectorlisten SAS rule (Listen) reads records ↓ azure_event_hub receiver │ • format: azure │ • apply_semantic_conventions: true │ • cloud.resource_id lifted from the per-record envelope ↓ otlp_http/b14 → Scout ``` The Diagnostic Setting targets the **server** resource directly. #### Categories enabled by default | Category | What it covers | | --- | --- | | `PostgreSQLLogs` | Server log: connection / disconnection events (`log_connections = on`, `log_disconnections = on`), slow queries above `log_min_duration_statement`, DDL statements (`log_statement = 'ddl'`), errors, lock waits, autovacuum / autoanalyze runs. The single highest-signal category for routine debugging. | | `PostgreSQLFlexSessions` | Per-session connect / disconnect events with session_id, user, application_name, client_addr, backend_type, duration. Higher resolution than PostgreSQLLogs's connection events; required for per-tenant connection attribution. | **Slow-query records depend on the threshold.** PostgreSQLLogs records a query only when it exceeds `log_min_duration_statement`. Workloads with sub-second mean latency will see no slow-query records if you leave the threshold at the 1000 ms reference value used in §Server Parameter prerequisites below - drop it to `100` ms to capture sub-second slow queries, or set it to `-1` to log every statement (high volume; combine with sampling). #### Optional categories Named here so you know they exist; enable per workload: - **`PostgreSQLFlexQueryStoreRuntime`** - per-query execution stats (count, mean duration, p95). Query Store on PG 16 ships on by default, so the data exists; only the Diagnostic Settings forwarding is gated. - **`PostgreSQLFlexQueryStoreWaitStats`** - per-query wait events (Lock, IO, IPC, etc.). Pairs with the Runtime category for query-tuning analyses. - **`PostgreSQLFlexTableStats`** - per-table size + bloat snapshot. Useful for capacity planning across schemas. - **`PostgreSQLFlexDatabaseXacts`** - per-DB transaction counts. Cross-validation against the `xact_*` metrics in the platform-metrics catalog. The four Query Store-derived categories together produce significantly higher record volume than the defaults. Enable when you are tuning specific workloads and disable when you finish. #### Receiver configuration (logs) ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_event_hub/postgresqllogs: connection: ${env:PGFLEXLOGS_CONNECTION_STRING} partition: "" # resume across all partitions offset: "" # resume from last checkpoint format: azure # decode Azure resource-log envelope apply_semantic_conventions: true processors: resource/postgresqllogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_postgresql_flexible_server, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:PGFLEXLOGS_SOURCE_REGION}", action: insert} # cloud.resource_id is NOT pinned - the receiver lifts the per-record # Azure resource ID to this attribute automatically (UPPERCASED). - {key: deployment.environment.name, value: "${env:PGFLEXLOGS_ENVIRONMENT}", action: insert} - {key: environment, value: "${env:PGFLEXLOGS_ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:PGFLEXLOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/postgresqllogs: receivers: [azure_event_hub/postgresqllogs] processors: [memory_limiter, resource/postgresqllogs, batch] exporters: [otlp_http/b14] ``` On first run with no stored checkpoint, the receiver starts from the earliest available record in the hub's retention window (1 day on Basic). On collector restart the receiver resumes from its last checkpoint, so an idle window during deployment does not lose records that arrived in the meantime. The `PGFLEXLOGS_CONNECTION_STRING` value is the Listen-permission SAS connection string for the namespace, **with `;EntityPath=` appended** so the receiver knows which hub to consume from. Fetch it once via: ```bash title="fetch the Listen connection string" az rest --method post \ --url "https://management.azure.com${COLLECTOR_LISTEN_RULE_ID}/listKeys?api-version=2024-01-01" \ --query primaryConnectionString -o tsv ``` Then append `;EntityPath=` and store the result in your collector's env file. #### Environment variables (logs) ```bash title=".env (logs path)" PGFLEXLOGS_CONNECTION_STRING=... # Listen SAS with ;EntityPath= PGFLEXLOGS_SOURCE_REGION=... # for cloud.region on log records PGFLEXLOGS_SERVICE_NAME=pgflex-logs PGFLEXLOGS_ENVIRONMENT=production ``` #### Wiring the Diagnostic Setting ```bash title="attach the Diagnostic Setting" az monitor diagnostic-settings create \ --resource "" \ --name pgflex-logs \ --event-hub \ --event-hub-rule "" \ --logs '[{"category":"PostgreSQLLogs","enabled":true}, {"category":"PostgreSQLFlexSessions","enabled":true}]' ``` The `--event-hub-rule` value is the resource ID of the namespace-scoped SAS rule with `Send` permission. The receiver uses a separate Listen rule; one Send rule and one Listen rule on the namespace is the canonical two-rule topology. #### Server Parameter prerequisites for log content The Diagnostic Settings path routes whatever the server writes to its log. To populate the categories above with useful content, set these Server Parameters: ```bash az postgres flexible-server parameter set --resource-group --server-name --name log_statement --value ddl az postgres flexible-server parameter set --resource-group --server-name --name log_min_duration_statement --value 1000 az postgres flexible-server parameter set --resource-group --server-name --name log_connections --value on az postgres flexible-server parameter set --resource-group --server-name --name log_disconnections --value on ``` Tune `log_min_duration_statement` to your slow-query threshold. `log_statement = 'ddl'` is the security-relevant default; raise to `all` only with care and only with sampling. #### Verifying the logs path After the Diagnostic Setting is attached and the server has served at least one client connection: 1. Wait 5 minutes for the first batch (resource-scope Diagnostic Settings first-batch lag). 2. Tail the collector debug exporter: `docker compose logs -f otel-collector | grep "otelcol.signal.*logs"`. 3. Expect batches of 5-30 log records every 10-30 seconds at typical transaction rates. 4. In Scout, filter `service.name = 'pgflex-logs'` and `cloud.platform = 'azure_postgresql_flexible_server'`; group by `azure.category` to confirm both enabled categories populate. ### Troubleshooting #### In-database receiver logs `permission denied for view pg_stat_replication` **Cause:** The monitoring user holds `pg_monitor` but not `azure_pg_admin`. **Fix:** ```sql GRANT azure_pg_admin TO postgres_exporter; ``` Reconnect the receiver; the warning clears on the next scrape. #### In-database receiver: pg_stat_statements permission or missing-relation error **Cause:** `pg_stat_statements` is not loaded. Either `shared_preload_libraries` does not include it, `azure.extensions` does not allowlist it, or `CREATE EXTENSION` has not run. **Fix:** Run the three steps from §In-database metrics - direct scrape → 3. Note the `shared_preload_libraries` change triggers a server restart. #### Platform-metrics `AuthorizationFailed` on the first scrape **Cause:** The `Monitoring Reader` role assignment on the resource group has not yet propagated. **Fix:** Wait two polling cycles (~2 minutes). The receiver retries automatically; the error self-clears. #### `connection refused` from the in-database receiver **Cause:** The collector's egress IP is not in the Flex Server's firewall allowlist. **Fix:** Add the IP via `az postgres flexible-server firewall-rule create`. If the collector runs in Azure (VM, AKS), add the `0.0.0.0` Azure-services rule instead. #### Metric `backup_storage_used` shows `no recent data` in Scout **Cause:** Expected behaviour - PT1H grain at a 60s receiver interval. **Fix:** See Operations → `backup_storage_used` PT1H grain. #### Metric `txlogs_storage_used` is missing from emissions **Cause:** The whitelist used the incorrect name `tx_logs_storage_used` (with an underscore between `tx` and `logs`). **Fix:** The catalog name is `txlogs_storage_used` - no underscore. Patch the whitelist and reload the receiver. #### First Event Hubs batch is empty after 20 minutes **Cause:** The Diagnostic Setting attached but the server has not yet served a matching event in the enabled categories. **Fix:** For `PostgreSQLLogs`, drive at least one client connection (`psql -h -U -c 'SELECT 1'`). For `PostgreSQLFlexSessions`, the same connection triggers a session record on connect and a second on disconnect. #### `azure_event_hub` receiver logs `MessagingGatewayBadRequest` **Cause:** The receiver is requesting a user-defined consumer group that does not exist on Event Hubs Basic. **Fix:** Basic tier rejects user-defined consumer groups - the receiver must consume from `$Default`, the implicit group. Remove any `consumer_group:` key from the receiver config or upgrade the namespace to Standard if you need multiple consumer groups. #### PostgreSQLLogs records arrive but slow-query records are missing **Cause:** `log_min_duration_statement` is higher than your typical query latency. **Fix:** Drop the threshold to a value below the slowest queries you want to capture. `100` ms is a reasonable starting point for OLTP workloads; `-1` logs every statement (high volume). ### Frequently Asked Questions #### How do I monitor Azure Database for PostgreSQL Flexible Server with OpenTelemetry? Three instrumentation paths complement each other. Platform metrics use `azure_monitor` against `Microsoft.DBforPostgreSQL/flexibleServers` for resource saturation, connection counts, and network throughput. The in-database scrape uses the OpenTelemetry `postgresqlreceiver` against the server's public FQDN over TLS for per-database stats, WAL activity, replication, and table-level counters. Resource logs use `azure_event_hub` consuming Diagnostic Settings categories `PostgreSQLLogs` and `PostgreSQLFlexSessions` for per-connection and per-query audit detail. Pick paths based on how deep the debug-attribution needs to go. #### Why can't my monitoring user read pg_stat_replication on Flex Server? On Azure Database for PostgreSQL Flexible Server, the `pg_monitor` role alone is not sufficient. You also need to `GRANT azure_pg_admin TO` the monitoring user. The `azure_pg_admin` role unlocks `SELECT` on `pg_stat_replication` and a handful of `azure_*` views that the OTel `postgresqlreceiver` queries. Without it, the receiver logs a permission-denied warning and emits a partial metric set. #### How do I enable pg_stat_statements on PostgreSQL Flexible Server? `pg_stat_statements` requires two Server Parameter changes plus a `CREATE EXTENSION`. First, set `shared_preload_libraries` to include `pg_stat_statements` via `az postgres flexible-server parameter set` or Bicep, which triggers a server restart. Second, add `pg_stat_statements` to the `azure.extensions` allowlist. Third, run `CREATE EXTENSION pg_stat_statements` against the target database. The first two steps are non-negotiable on Azure even though self-hosted Postgres only requires the `CREATE EXTENSION` step. #### Is `backup_storage_used` safe to alert on at a 60-second collection interval? No. `backup_storage_used` emits at a PT1H native grain on Azure Monitor. A receiver polling at 60 seconds will see the metric populate once per hour and report `no recent data` for the other 59 cycles. Either run a second `azuremonitorreceiver` instance scoped to `backup_storage_used` with `collection_interval` set to `1h`, or drop the metric from the whitelist and rely on the Azure portal backup-quota view instead. #### What's the first-batch ship lag for PostgreSQL Flex Server Diagnostic Settings? Resource-scope Diagnostic Settings on Flex Server typically ship the first batch within Azure's documented 5-15 minute window on first attach. Steady-state batches arrive every 10 to 30 seconds after that. Budget at least 15 minutes before treating an empty Event Hubs partition as a failure. #### Why are PostgreSQLLogs slow-query records empty under my workload? PostgreSQLLogs records slow queries only when they exceed `log_min_duration_statement`. Workloads with sub-second mean latency will see only DDL events, connection events, errors, autovacuum, and lock waits in the stream if the threshold is left at the 1000 ms reference value used in §Server Parameter prerequisites. Lower it to 100 ms to capture sub-second slow queries, or set it to `-1` to capture every statement (high volume; combine with sampling). ### Related Guides - [Self-hosted PostgreSQL](../../component/postgres.md) - the `postgresqlreceiver` reference for the in-database scrape. This guide layers Azure-specific deltas (firewall, `azure_pg_admin`, `pg_stat_statements` via Server Parameters, TLS-required) on it. - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - the runtime that hosts both receivers in this guide. - [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - alternative runtime for AKS-hosted collectors. - [Scout exporter wiring](../../collector-setup/scout-exporter.md) - the `oauth2client` extension + `otlp_http/b14` exporter block shared by all Azure guides. - [FastAPI + Postgres](../../apps/auto-instrumentation/fast-api.md) - Python web app connecting to Flex Server over `psycopg`. --- ## Azure Event Hubs Monitoring with OpenTelemetry - Throughput, Connections, and Capture ### Overview This guide is the **execution playbook** for Azure Event Hubs. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running Event Hubs in production who want to add Event Hubs telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.EventHub/namespaces` metrics every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. The receiver does not touch the Event Hubs data plane. The receiver does not connect to Event Hubs directly. It queries Azure Monitor for any namespace your subscription auto-publishes to, so the same configuration covers Basic, Standard, Premium, and Dedicated tiers across any number of event hubs and consumer groups per namespace. This guide is metrics-only. For ingesting the events themselves into the collector pipeline as logs or traces, see [`azureeventhubreceiver` distinction](#azureeventhubreceiver-distinction). ### Event Hubs vs Service Bus Event Hubs and Service Bus are both messaging primitives in Azure, but they solve different problems. Pick by workload, not by metric overlap. | | Event Hubs | Service Bus | | --- | --- | --- | | Pattern | Streaming, partitioned, replay-capable | Queueing or pub/sub via topics | | Consumer model | Pull, consumer-tracks-offset (Kafka semantics) | Lock-and-ack, broker-tracks-offset | | Throughput | Millions of events/sec at Premium / Dedicated | Tens of thousands of msg/sec at Standard | | Retention | 1 day (Basic) up to 90 days (Premium) | Per-message TTL, dead-letter on failure | | Use cases | Telemetry pipelines, event sourcing, stream processing | Transactional messaging, work distribution, request/reply | | Compatible with | Apache Kafka clients (Standard+) | AMQP 1.0 + REST + .NET / Java SDKs | For the queueing surface, see [Azure Service Bus](./service-bus.md). The receiver configuration is nearly identical between the two; only the resource type and the metric whitelist change. ### Tier choice Azure Event Hubs has four pricing tiers. Each gates feature availability, which in turn gates which metrics emit data. | Tier | Throughput / quotas | Capture | Retention | Consumer groups | Metric coverage | | --- | --- | --- | --- | --- | --- | | **Basic** | 1-20 TUs (1 MB/s ingress, 2 MB/s egress per TU) | No | Max 1 day | `$Default` only - user-created groups rejected | 14 of 17 (all except Capture). `OutgoingMessages` and `OutgoingBytes` need an active consumer to emit. | | **Standard** | 1-20 TUs, same per-TU envelope | Yes (to Blob Storage / Data Lake) | Max 7 days | Up to 20 user-created | All 17 in this guide's whitelist | | **Premium** | Dedicated capacity units (CUs); per-CU envelope independent of TUs | Yes | Max 90 days | Up to 1,000 | All 17 + 4 Premium-only (`NamespaceCpuUsage`, `NamespaceMemoryUsage`, `ReplicationLagCount`, `ReplicationLagDuration`) | | **Dedicated** | Reserved cluster; multiple Premium namespaces share a cluster | Yes | Max 90 days | Up to 1,000 per namespace | Same as Premium | Start at Basic if you only need throughput and request metrics on a single producer-and-consumer pair. Move to Standard if you want Capture or named consumer groups. Premium and Dedicated are for fleets where per-TU throughput limits or 7-day retention are blockers, or where geo-disaster-recovery is a hard requirement. ### Receiver configuration Add this fragment to your existing collector config. It contributes the `azure_auth` extension, an `azure_monitor` receiver, a resource processor, and a metrics pipeline. Component keys are suffixed `/eventhubs` so the fragment composes cleanly with other Azure-surface receivers in the same collector. ```yaml showLineNumbers title="otel-collector.yaml (Event Hubs addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Authentication section below for the right choice per # collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/eventhubs: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} # Add more entries to scrape namespaces across multiple subscriptions # in one collector. Each subscription needs its own Monitoring Reader # role assignment on the configured identity. resource_groups: - ${env:AZURE_RESOURCE_GROUP} # Omit resource_groups entirely to scrape every resource group in # the listed subscriptions. services: - Microsoft.EventHub/namespaces auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Legacy ARM /metrics endpoint. Immediate RBAC propagation; 12k calls/h # per-subscription ceiling. Flip to true to use the Metrics Data Plane # batch API (360k/h ceiling) once the data-plane RBAC has propagated; # see Scale and rate limits. use_batch_api: false cache_resources: 86400 dimensions: enabled: true # The receiver only emits the metrics you list; there is no implicit # default + my picks merge. Each entry pins the Azure aggregation(s) # to emit per metric. metrics: "Microsoft.EventHub/namespaces": # Throughput (universal across Basic / Standard / Premium / Dedicated) IncomingMessages: [Total] OutgoingMessages: [Total] IncomingBytes: [Total] OutgoingBytes: [Total] IncomingRequests: [Total] SuccessfulRequests: [Total] ServerErrors: [Total] UserErrors: [Total] ThrottledRequests: [Total] QuotaExceededErrors: [Total] # Connections - Maximum aggregation only for Opened/Closed. ActiveConnections: [Average] ConnectionsOpened: [Maximum] ConnectionsClosed: [Maximum] # Sizing Size: [Average] # Capture (Standard+ feature; emits no points on Basic). CapturedMessages: [Total] CapturedBytes: [Total] CaptureBacklog: [Total] processors: resource/eventhubs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_event_hubs, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} # cloud.resource_id pins all metrics to one namespace. Drop this line # for multi-namespace fleets; the receiver injects azuremonitor.resource_id # per-resource automatically. - {key: cloud.resource_id, value: "${env:EVENTHUBS_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:EVENTHUBS_SERVICE_NAME}", action: insert} service: # Merge `azure_auth` into your top-level extensions: block (defines it) # AND list it under service.extensions: (enables it). The two lists are # independent. extensions: [azure_auth] pipelines: metrics/eventhubs: receivers: [azure_monitor/eventhubs] processors: [resource/eventhubs, batch] # plus your existing processors exporters: [otlphttp/b14] # your Scout exporter ``` The receiver, resource processor, and pipeline are all keyed `/eventhubs` so they coexist with other Azure receivers (Service Bus, Cosmos DB, Storage, Load Balancer, Firewall) in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, add entries to `subscription_ids:`. The alternative `discover_subscriptions: true` scrapes every namespace the identity has `Monitoring Reader` on; prefer the explicit list in production, since discovery silently includes sandbox and dormant subscriptions. See [Scale and rate limits](#scale-and-rate-limits). ### Authentication and RBAC Pick the `azure_auth` mode for where the collector runs: - **AKS pod** - `workload_identity` (federated credential, no secret). - **Container Apps / VMSS / Azure VM** - `managed_identity` (user-assigned survives instance replacement). - **External or on-prem** - `service_principal`. - **Local dev only** - `use_default: true` (Azure SDK credential chain). Grant `Monitoring Reader` at the resource group containing your namespaces. For mode-by-mode YAML, federation-credential setup, and the `az role assignment create` snippet, see [Azure Service Bus § Authentication](./service-bus.md#authentication) - the configuration is identical except for the receiver's `services:` line and the resource processor's `cloud.platform` value. This guide defaults `use_batch_api: false` to match the validated runnable example. Flip to `true` once the data-plane RBAC has settled (5-30 minutes after a fresh `Monitoring Reader` grant) for the 360k-calls/hour ceiling. ### What you'll monitor Seventeen metrics from `Microsoft.EventHub/namespaces`. The receiver renames them from Azure's PascalCase (e.g. `IncomingMessages`) to OTel-style `azure__` (e.g. `azure_incomingmessages_total`). | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `IncomingMessages` | `azure_incomingmessages_total` | Count | Producer ingestion rate per event hub (`metadata_EntityName`). | | `OutgoingMessages` | `azure_outgoingmessages_total` | Count | Consumer drain rate per event hub. Pair with `IncomingMessages` to see backlog growth. *Silent-when-quiet.* | | `IncomingBytes` | `azure_incomingbytes_total` | Bytes | Producer byte rate. Track against TU envelope (1 MB/s per TU on Basic and Standard). | | `OutgoingBytes` | `azure_outgoingbytes_total` | Bytes | Consumer byte rate. Track against TU egress envelope (2 MB/s per TU). *Silent-when-quiet.* | | `IncomingRequests` | `azure_incomingrequests_total` | Count | Per-minute producer API call count. | | `SuccessfulRequests` | `azure_successfulrequests_total` | Count | Successful subset of `IncomingRequests`. The `OperationResult` dimension (see [Cardinality control](#cardinality-control)) splits by Success / Failure / Throttle codes for cross-referencing the error counters. | | `ServerErrors` | `azure_servererrors_total` | Count | Service-side failures. Alert on series presence. *Silent-when-quiet.* | | `UserErrors` | `azure_usererrors_total` | Count | Client-induced errors (auth, malformed, oversize). High with low `ServerErrors` means producer / consumer code. *Silent-when-quiet.* | | `ThrottledRequests` | `azure_throttledrequests_total` | Count | TU ceiling hit. *Silent-when-quiet.* | | `QuotaExceededErrors` | `azure_quotaexceedederrors_total` | Count | Per-event-hub or per-message size / partition / send-quota breaches. *Silent-when-quiet.* | | `ActiveConnections` | `azure_activeconnections_average` | Count | AMQP / Kafka connection count to the namespace. | | `ConnectionsOpened` | `azure_connectionsopened_maximum` | Count | New connections established per poll. *Maximum-only aggregation* - `[Total]` silently emits nothing. | | `ConnectionsClosed` | `azure_connectionsclosed_maximum` | Count | Connections closed per poll. *Maximum-only aggregation.* | | `Size` | `azure_size_average` | Bytes | Bytes stored in the event hub. Pair with retention envelope. | | `CapturedMessages` | `azure_capturedmessages_total` | Count | Messages archived by Capture. *Standard+ feature.* | | `CapturedBytes` | `azure_capturedbytes_total` | Bytes | Bytes archived by Capture. *Standard+ feature.* | | `CaptureBacklog` | `azure_capturebacklog_total` | Count | Bytes pending capture. Climbing means Capture target storage is throttling. *Standard+ feature.* | `metadata_EntityName` rides alongside every per-event-hub metric, splitting the namespace-scope series into per-event-hub series automatically. For metrics that have no `EntityName` dimension at the Azure Monitor level (`ConnectionsOpened`, `ConnectionsClosed`), the receiver injects the sentinel value `metadata_EntityName: "-NamespaceOnlyMetric-"` so the dimension column is stable across the full metric set. `ActiveConnections` omits `metadata_EntityName` entirely. **Silent-when-quiet.** Azure Monitor returns data points for these metrics only when the underlying condition occurs. A healthy namespace emits zero series for `ServerErrors`, `UserErrors`, `ThrottledRequests`, and `QuotaExceededErrors`; a producer-only namespace with no consumer drain emits zero for `OutgoingMessages` and `OutgoingBytes`. Wire alerts on these metrics to fire on series presence in window (any non-zero point), not on threshold crossings. **Maximum-only aggregation.** `ConnectionsOpened` and `ConnectionsClosed` support `Maximum` aggregation only per the [Microsoft.EventHub/namespaces metric reference](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-eventhub-namespaces-metrics). Listing them with `[Total]` returns no data points and no error. **Standard+ feature.** Capture metrics (`CapturedMessages`, `CapturedBytes`, `CaptureBacklog`) emit only when Capture is configured, which requires Standard tier or higher and a target storage account. On Basic, the three metrics are silent. **Premium-only metrics.** `NamespaceCpuUsage`, `NamespaceMemoryUsage`, `ReplicationLagCount`, and `ReplicationLagDuration` are Premium-tier only; Basic and Standard return 401 if listed. See [Premium-tier additions](#premium-tier-additions). ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | --- | --- | --- | | Legacy Azure Resource Manager `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Default in this guide. Immediate RBAC propagation. | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Switch once data-plane RBAC has propagated (5-30 min after grant). | At a 60-second collection interval, a single resource costs roughly 60 calls per hour (one per metric per poll, deduplicated within the receiver). A 50-namespace fleet running on legacy `/metrics` consumes ~3,000 calls per hour - well within the 12k ceiling. Above ~150 namespaces per subscription, switch to `use_batch_api: true` to lift the per-subscription ceiling and benefit from batched fan-out. The receiver shares one rate-limit budget across all subscriptions in the list; it does not bypass per-subscription quotas. Splitting heavy subscriptions across separate collector instances lifts the aggregate ceiling linearly. `cache_resources` is the resource-list cache TTL in seconds. The receiver default is `86400` (24 hours), which is correct for a stable fleet. Lower to `3600` or `600` only if namespaces are created and destroyed frequently enough that 24-hour-stale resource lists become a problem. ### Cardinality control By default, the receiver emits one OTel series per `(resource × metric × aggregation × dimension-combination)`. With 17 metrics, one aggregation each, and `metadata_EntityName` as the sole dimension on per-event-hub metrics, a 1-event-hub namespace produces roughly 17 series. Multi-event-hub fan-out multiplies linearly on the 12 metrics that split by `EntityName`; the 5 metrics without `EntityName` (`ActiveConnections`, `ConnectionsOpened`, `ConnectionsClosed`, and the 2 namespace-level Capture rollups) emit once per namespace regardless of event-hub count. ```text ~5 + (12 × M event-hubs) per namespace × N namespaces ≈ active series ``` A worked example: 5 namespaces × 2 event hubs each ≈ 5 × (5 + 12 × 2) = 145 series before any `OperationResult` fan-out on the error counters. Partitions do not contribute extra series - partition is exposed via the SDK consumer-group offsets, not at the Azure Monitor namespace level. `OperationResult` adds a fan-out factor of 1.5-3x on `SuccessfulRequests`, `ServerErrors`, `UserErrors`, `ThrottledRequests`, and `QuotaExceededErrors` during error-heavy windows. Two control levers, in order of preference: 1. **`dimensions.overrides`** drops or whitelists dimensions per metric. Drop `EntityName` on namespaces where per-event-hub granularity is not actionable for alerting; drop `OperationResult` on metrics other than the error / throttle counters. The override config uses the **bare Azure dimension name** (e.g. `EntityName`, not `metadata_EntityName`); the receiver adds the `metadata_` prefix when it emits. ```yaml azure_monitor/eventhubs: dimensions: enabled: true overrides: "Microsoft.EventHub/namespaces": IncomingMessages: - EntityName # keep ServerErrors: - EntityName - OperationResult ThrottledRequests: - EntityName - OperationResult Size: [] # drop EntityName too; aggregate at namespace level ``` 2. **Per-namespace receiver instances.** Split high-cardinality namespaces into separate `azure_monitor/eventhubs-bigfleet` and `azure_monitor/eventhubs-quiet` receivers with different override profiles. Both contribute to the same `metrics/eventhubs` pipeline. Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's Prometheus self-telemetry endpoint (port 8888 by default) to see actual cardinality after `overrides` apply. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points; derive your own from observed 99th percentile over a representative week. `azure_throttledrequests_total`, `azure_servererrors_total`, `azure_usererrors_total`, and `azure_quotaexceedederrors_total` only emit data points when their condition occurs. Wire alerts on these to fire on series presence in window, not on numeric thresholds; a healthy namespace emits no points at all. | Metric (OTel name) | Warning | Critical | Why it matters | | --- | --- | --- | --- | | `azure_incomingbytes_total` (per `metadata_EntityName`) / TU envelope | > 70% | > 90% | TU ingress saturation. Each TU is 1 MB/s on Basic and Standard. | | `azure_outgoingbytes_total` (per `metadata_EntityName`) / TU egress envelope | > 70% | > 90% | TU egress saturation. Each TU is 2 MB/s. Egress saturation hits before ingress in fan-out-heavy workloads. | | `azure_throttledrequests_total` | `> 0` over 5m | `> 0` over 15m | TU ceiling hit. Add TUs (Basic / Standard scale-out) or upgrade to Premium. | | `azure_servererrors_total` | `> 0` over 5m | `> 0` over 15m | Service-side failures. Cross-check Azure Service Health. | | `azure_capturebacklog_total` (Standard+) | climbing | sustained climbing | Capture target storage is throttling or unreachable. Investigate the destination Blob / Data Lake account. | | `azure_size_average` per event hub / retention envelope | > 80% | > 95% | Approaching the per-event-hub byte cap. Drain consumer or split into more event hubs. | | `azure_activeconnections_average` (per namespace) | > 5x baseline / 15m | sustained > 10x | Misbehaving client opening connections in a loop. Set baseline from a steady-state week. | #### RED method on the broker If you run Event Hubs as part of a service backed by service-level objectives (SLOs), frame Event Hubs metrics as RED (rate, errors, duration) on the broker: - **Rate.** `azure_incomingrequests_total` per namespace, sliced by event hub. For consumer-side rate, instrument the apps-side Event Hubs client (see [Apps-side instrumentation](#apps-side-instrumentation)). - **Errors.** Split into two service-level indicators (SLIs): - **Availability error rate** = `(azure_servererrors_total + azure_throttledrequests_total + azure_quotaexceedederrors_total) / azure_incomingrequests_total`. Routes to platform on-call. - **Request-quality error rate** = `azure_usererrors_total / azure_incomingrequests_total`. Routes to the owning service team. - **Duration.** Event Hubs does not expose a broker-side latency metric (Service Bus's `ServerSendLatency` has no Event Hubs equivalent). For end-to-end producer-to-consumer latency, instrument the client. For saturation (the U in USE), pair `azure_incomingbytes_total / TU envelope`, `azure_outgoingbytes_total / TU envelope`, `azure_size_average / retention envelope`, and `azure_throttledrequests_total > 0`. On Premium, add `azure_namespacecpuusage_maximum` and `azure_namespacememoryusage_maximum` for direct messaging-unit utilisation. ### Premium-tier additions Premium adds dedicated capacity units, optional geo-disaster recovery (geo-DR), and a handful of extra metrics. When the namespace is Premium, extend the whitelist: ```yaml metrics: "Microsoft.EventHub/namespaces": # ...all 17 from the universal + Capture set above... NamespaceCpuUsage: [Average] # CU CPU saturation; alert > 70% NamespaceMemoryUsage: [Average] # CU memory saturation; alert > 70% ReplicationLagCount: [Maximum] # geo-DR lag in messages (paired only) ReplicationLagDuration: [Maximum] # geo-DR lag in seconds (paired only) ``` Aggregations match the rest of the whitelist: one per metric. CPU / memory use Average for steady-state alerting; replication lag uses Maximum because the worst-case lag is the operationally relevant number. The `Replica` dimension splits replication-lag metrics across paired namespaces. A geo-DR failover changes which replica is active without changing metric content. Pin dashboards to namespace name rather than resource id if you want continuity across failover. ### `azureeventhubreceiver` distinction This guide uses **`azuremonitorreceiver`** to read **metrics about** Event Hubs from Azure Monitor's REST API. It does not connect to Event Hubs itself. A separate receiver, **`azureeventhubreceiver`**, ingests **the events themselves** as OTel logs or traces into the collector pipeline. That is a different workflow - typically used for Diagnostic Settings logs forwarded from another Azure surface (Service Bus, Storage, AKS) into an Event Hub for centralised processing. It is covered separately, not in this guide. If you want both - metrics about Event Hubs and event-data ingestion via Event Hubs - run both receivers in the same collector. They do not interact. ### Apps-side instrumentation This guide is metrics-only. To produce per-message distributed traces (producer span linked through the broker to consumer span), instrument your producer / consumer code with one of these OTel Event Hubs integrations: - **.NET / C#:** `Azure.Messaging.EventHubs` ships built-in ActivitySource emission. Add `OpenTelemetry.Extensions.Hosting` and register `AddSource("Azure.Messaging.EventHubs")` to forward producer, consumer, and receive spans. - **Java:** the OTel Java agent (`opentelemetry-javaagent.jar`) auto-instruments the Azure SDK (`com.azure:azure-messaging-eventhubs`) via the `azure-core-tracing-opentelemetry` adapter. No code changes. - **Python:** community `opentelemetry-instrumentation-azure-eventhub` packages exist; verify span shape before promoting. - **Node.js / Go:** no first-party OTel instrumentation as of 2026-05. Manual span creation around `producer.sendBatch` and `consumer.receive` is the workaround. Run apps-side spans alongside this metrics collector with distinct `service.name` values to keep the broker view and the request-flow view separately filterable in Scout. ### Logs Two destinations, two purposes: - **Log Analytics workspace** (`--workspace`) - for ad-hoc query in the Azure Portal or Log Analytics. Not in the Scout pipeline. - **Event Hubs** (`--event-hub-rule`) - for OTel ingest via the `azureeventhubreceiver` into the same collector. Architecture in the [overview](./overview.md#choosing-pull-push-or-both). The Event Hubs log categories worth enabling: | Log category | What it captures | | --- | --- | | `OperationalLogs` | Namespace-level operational events | | `RuntimeAuditLogs` | Data-plane authentication and authorisation activity | | `KafkaCoordinatorLogs` (Standard+) | Kafka surface coordination events | | `KafkaUserErrorLogs` (Standard+) | Kafka client errors | ```bash # Log Analytics destination (ad-hoc query): az monitor diagnostic-settings create \ --resource \ --name eventhubs-to-loganalytics \ --logs '[{"category":"OperationalLogs","enabled":true},{"category":"RuntimeAuditLogs","enabled":true}]' \ --workspace ``` Activity logs (control-plane operations on the namespace) are **subscription-scoped**, not resource-scoped; configure them once per subscription via `az monitor diagnostic-settings subscription create`. ### Troubleshooting #### `AuthorizationFailed` from the receiver in the first 60 seconds `Monitoring Reader` propagation on the legacy ARM `/metrics` endpoint is fast but not instantaneous. Wait one minute after the role assignment before declaring an auth failure. If the data-plane batch API is in use (`use_batch_api: true`), allow 5-30 minutes for separate data-plane RBAC propagation; flip to `false` as a temporary fallback to confirm the role itself is correct. #### `metrics_definitions_count: 0` on first poll after provisioning Azure Monitor's metric-definition catalogue can lag a few minutes behind namespace provisioning. The receiver caches a zero-count for the `cache_resources` interval (default 86400 / 24 h) and stops re-discovering within that window - symptom: receiver scrapes successfully but emits zero metric points. **Workaround:** restart the collector once after the namespace reaches `provisioningState=Succeeded`. This resets the discovery cache. Tracked upstream as [issue #46047](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/46047). #### `OutgoingMessages` and `OutgoingBytes` stay at zero There is no consumer reading from the event hub. Azure Monitor only emits points for these metrics when a consumer is actively pulling. Producer-only validation runs are expected to see them silent - this is not a bug. Add a consumer (apps-side instrumentation) to drive the metrics. #### `ConnectionsOpened` or `ConnectionsClosed` returns no points `Maximum`-only aggregation; `[Total]` or `[Average]` returns no data and no error. See the [metric table](#what-youll-monitor) note. #### Capture metrics emit zero on Basic SKU Capture is a Standard+ feature. `CapturedMessages`, `CapturedBytes`, and `CaptureBacklog` will not emit points on Basic. Either upgrade to Standard to enable Capture, or remove the three metrics from the whitelist. #### Bicep deploy fails with `MessagingGatewayBadRequest` on consumer-group resource Basic tier rejects user-created consumer groups. Only the implicit `$Default` consumer group exists. Remove the `Microsoft.EventHub/namespaces/eventhubs/consumergroups@2024-01-01` child from your Bicep template, or upgrade the namespace SKU to Standard before deploying named consumer groups. #### Cardinality blowup on Scout volume A single high-fan-out namespace (many event hubs, all per-event-hub metrics enabled) can dominate volume. Apply `dimensions.overrides` (see [Cardinality control](#cardinality-control)) or split the noisy namespace into a separate receiver instance with a narrower whitelist. #### Scout OAuth2 returns 401 Verify `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, and `SCOUT_TOKEN_URL` match the values in your Scout console. The `endpoint_params.audience` must be `b14collector`. ### Frequently Asked Questions #### When should I use Event Hubs vs Service Bus? Event Hubs is a streaming primitive: high-throughput, partitioned, replay-capable, Kafka-compatible. Use it for telemetry pipelines, event sourcing, and stream processing where consumers track their own offsets. Service Bus is a queueing primitive: point-to-point or pub/sub via topics, with dead-letter queues, scheduled messages, and sessions. Use it for transactional messaging, work distribution, and request/reply patterns. Both expose Azure Monitor metrics through the same `azure_monitor` receiver; the resource type differs (`Microsoft.EventHub/namespaces` vs `Microsoft.ServiceBus/namespaces`) and the metric set emphasises throughput on Event Hubs vs message lifecycle on Service Bus. #### What changes between Basic, Standard, Premium, and Dedicated tiers for monitoring? Metric coverage is largely the same across tiers, but feature availability gates several metrics. Capture metrics (`CapturedMessages`, `CapturedBytes`, `CaptureBacklog`) require Standard or higher because Basic does not support Capture. `NamespaceCpuUsage` and `NamespaceMemoryUsage` are Premium-only since they report dedicated-capacity-unit utilisation. `ReplicationLagCount` and `ReplicationLagDuration` require geo-paired namespaces, which are Premium-only. Basic also rejects user-created consumer groups; only the implicit `$Default` consumer group exists. Start at Standard if you need Capture, named consumer groups, longer retention than 1 day, or the Kafka surface. #### What metrics are unavailable on Basic or without an active consumer? `OutgoingMessages` and `OutgoingBytes` only emit when a consumer is reading; a producer-only namespace shows them as silent in Azure Monitor (no points returned, not zero values). Capture metrics (`CapturedMessages`, `CapturedBytes`, `CaptureBacklog`) emit nothing on Basic because Capture is a Standard+ feature. `ServerErrors`, `UserErrors`, `ThrottledRequests`, and `QuotaExceededErrors` are silent-when-quiet: Azure Monitor returns data points only for time windows where the underlying condition occurred, so a healthy namespace emits no series for them. Wire alerts on these to fire on series presence in window, not on threshold crossings. #### How does Event Hubs compare to AWS Kinesis Data Streams for monitoring? Both are partitioned streaming primitives with similar producer-consumer-offset semantics. Monitoring shape differs in collection pattern: Event Hubs is pulled from Azure Monitor's `metricDefinitions` API via the `azure_monitor` receiver every 60 seconds; Kinesis is pushed via CloudWatch Metrics Stream into the `awscloudwatchmetricstreamreceiver`. Metric coverage is broadly equivalent (incoming and outgoing throughput, error counts, throttling) with vendor-specific names. Both surfaces flow through the same OTLP/HTTP exporter to Scout, so multi-cloud streaming dashboards are unified at query time. #### How do I instrument the producer and consumer code, not just the broker? This guide is metrics-only. For per-message distributed traces (producer span linked through the broker to consumer span), instrument your producer and consumer with an OTel Event Hubs client integration. .NET applications use `Azure.Messaging.EventHubs` which emits ActivitySource spans; register `OpenTelemetry.Extensions.Hosting` and `AddSource("Azure.Messaging.EventHubs")` to forward them. Java applications get auto-instrumentation via the OpenTelemetry Java agent and the `azure-core-tracing-opentelemetry` adapter. Python and Node.js client instrumentation is community-maintained; verify span shape before promoting. Run apps-side spans alongside this metrics collector with distinct `service.name` values to keep the broker view and the request-flow view separately filterable in Scout. ### Reference - **Receiver source.** [opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver). - **Auth extension source.** [opentelemetry-collector-contrib / extension / azureauthextension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/azureauthextension). - **Azure Monitor metric reference.** [Microsoft.EventHub/namespaces metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-eventhub-namespaces-metrics). - **Runnable example.** [`examples/components/azure-event-hubs-telemetry/`](https://github.com/base-14/examples/tree/main/components/azure-event-hubs-telemetry) - Bicep + provisioning wrappers + Python traffic generator. ### Related Guides - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. Pick Service Bus for transactional messaging and work distribution; pick Event Hubs for high-throughput partitioned streaming. - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - cross-surface architecture for the Azure track. - [Azure Storage](./storage.md) - managed object/blob/queue/table/file storage. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure SQL Database](./sql-database.md) - managed relational database. --- ## Azure Front Door Monitoring with OpenTelemetry - Production Wiring for SREs ### Overview This guide is the **execution playbook** for Front Door. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running **Azure Front Door Standard** in production who want to add Front Door telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API every 60 seconds for `Microsoft.Cdn/profiles` metrics, transforms them to OTel-style names, and exports via OTLP/HTTP. The collector never touches Front Door's data plane. The receiver does not connect to Front Door directly. It queries Azure Monitor for metrics any Front Door profile auto-publishes, so the same configuration covers Standard and Premium tiers and any number of endpoints, origins, and routes per profile. Premium-only WAF metrics (`WebApplicationFirewallRequestCount` and friends) are excluded from the default whitelist; add them when targeting Premium. Front Door **Classic** (`Microsoft.Network/frontDoors`) is deprecated for new customers and is NOT covered by this guide. See [Microsoft's Classic-to-Standard migration guide](https://learn.microsoft.com/azure/frontdoor/tier-migration) if you are still on Classic; the `azure_monitor` receiver supports it via a different `services:` value, but the metric namespace and aggregations differ. This guide is metrics-only. For per-request access logs, Web Application Firewall logs, and health-probe logs, see [Logs](#logs). ### What you'll monitor Ten metrics from `Microsoft.Cdn/profiles`. The receiver renames them from Azure's PascalCase (e.g., `RequestCount`) to OTel-style `azure__` (e.g., `azure_requestcount_total`). **Each metric uses a single MS-documented default aggregation** to work around upstream receiver issue [#43648](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/43648): the receiver's default of all five aggregations triggers `501 Sampling type is not found` from Azure Monitor for metrics that publish only a subset. Per-metric aggregations are mandatory. | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `RequestCount` | `azure_requestcount_total` | Count | Per-minute request rate at the edge. Splits by `metadata_HttpStatusGroup` (`2XX` / `3XX` / `4XX` / `5XX`), `metadata_ClientCountry`, `metadata_ClientRegion`. | | `ResponseSize` | `azure_responsesize_total` | Bytes | Bytes returned to clients. Pair with `RequestCount` for average response size by status group. | | `TotalLatency` | `azure_totallatency_average` | MilliSeconds | Edge-to-client latency. The user-perceived number; primary SLO metric. | | `ByteHitRatio`† | `azure_bytehitratio_average` | Percent | Fraction of bytes served from edge cache. Emits no data points when origin headers prevent caching; see [Cache configuration](#cache-configuration). | | `RequestSize`‡ | `azure_requestsize_total` | Bytes | Bytes received from clients (typically request headers + body). | | `OriginRequestCount`‡ | `azure_originrequestcount_total` | Count | Requests Front Door forwarded to origin (cache misses + fills). `RequestCount` minus `OriginRequestCount` is your cache-shielded request count. | | `OriginLatency`‡ | `azure_originlatency_average` | MilliSeconds | Origin-side latency for cache misses. Subtract from `TotalLatency` to estimate edge processing time. | | `OriginHealthPercentage`‡ | `azure_originhealthpercentage_average` | Percent | Probe-driven origin health. Drops below 100% when health-probe requests fail; useful for origin-fleet alerting. | | `Percentage4XX`‡ | `azure_percentage4xx_average` | Percent | 4XX rate at the edge. Pair with `metadata_HttpStatus` to find the dominant 4XX code. | | `Percentage5XX`‡ | `azure_percentage5xx_average` | Percent | 5XX rate at the edge. Sustained `> 0` is a page. | **`†` cache-conditional.** `ByteHitRatio` emits no data points when the origin returns `Cache-Control: no-store` (or any directive that prevents caching). Production origins serving cacheable static assets surface this metric without intervention; see [Cache configuration](#cache-configuration) for the override path when origin headers cannot be changed. **`‡` lazy-published.** Azure Monitor publishes definitions for these metrics only after the underlying condition first occurs (a failed origin probe, a 4XX response, a cache miss with origin pull, etc.). On brand-new profiles with no history, the receiver typically reports `metrics_definitions_count: 3-4` instead of 10. The remaining metrics appear once Azure has data points to back them; the lag depends on traffic shape (an origin-error metric does not surface without origin errors, a 4XX-rate metric does not surface without 4XX responses, etc.). Profiles with weeks of mixed production traffic surface the full set. See [Receiver behavior on a brand-new profile](#receiver-behavior-on-a-brand-new-profile) for the operational follow-up. `metadata_*` dimensions ride alongside every metric: `metadata_ClientCountry`, `metadata_ClientRegion`, `metadata_Endpoint`, `metadata_HttpStatus`, `metadata_HttpStatusGroup`. These are the most useful axes for Scout dashboards (per-country latency, per-status-code error rate, per-endpoint traffic split). See [Cardinality control](#cardinality-control) before enabling all of them on a high-traffic fleet. ### Prerequisites | Requirement | Minimum | | --- | --- | | Existing Front Door profile | Standard SKU (`Standard_AzureFrontDoor`) or Premium. | | Azure subscription | Pay-As-You-Go (Free Trial excludes `Microsoft.Cdn/profiles` entirely). | | OTel Collector | contrib v0.148+ (snake_case YAML keys). | | `Microsoft.Cdn` provider | registered on the subscription. | | Service principal or managed identity | with `Monitoring Reader` on the FD profile's resource group. | | base14 Scout | any tenant. | This guide is the Front-Door-specific addition to a working OpenTelemetry Collector. For collector deployment + the Scout exporter pieces (which are the same for every Azure surface), see: - [Docker Compose Setup](../../collector-setup/docker-compose-example.md), or [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) / [Linux Setup](../../collector-setup/linux-setup.md) for other runtimes. - [Scout Exporter](../../collector-setup/scout-exporter.md) for the OAuth2 + OTLP/HTTP exporter config. ### Access setup The `azure_monitor` receiver needs `Monitoring Reader` on the resource group containing your Front Door profile. The role grants read on metric definitions and metric data only, no control-plane write. `Reader` is not required. ```bash RG_ID=$(az group show --name --query id -o tsv) az role assignment create \ --assignee \ --role "Monitoring Reader" \ --scope "$RG_ID" ``` For multi-subscription fleets, repeat per subscription. The data-plane batch API at `*.metrics.monitor.azure.com` (`use_batch_api: true`, the default in this guide) lags 5-30 minutes after the role grant before RBAC propagates. The legacy ARM `/metrics` endpoint (`use_batch_api: false`) propagates immediately and is the temporary fallback if the data plane is still 401-ing past that window. The role assignment lifecycle for production: bind it to the resource group containing your Front Door profile (or to the subscription if you intend to scrape every profile in scope), grant once, and rotate the SP secret per [Service principal credential lifecycle](./service-bus.md#service-principal-credential-lifecycle). Workload Identity Federation eliminates the rotation entirely if the collector runs on AKS. ### Receiver configuration Add this fragment to your existing collector config. Component keys are suffixed `/frontdoor` so the fragment composes cleanly with other Azure-surface receivers in the same collector. ```yaml showLineNumbers title="otel-collector.yaml (Front Door addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Service Bus guide's Authentication section for the right # choice per collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/frontdoor: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:FRONTDOOR_RESOURCE_GROUP} services: - Microsoft.Cdn/profiles # NOT Microsoft.Network/frontDoors (Classic, deprecated) auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Metrics Data Plane (12k -> 360k calls/hour ceiling). RBAC propagates # 5-30 min after the Monitoring Reader grant; flip to false as a # temporary fallback to the legacy ARM /metrics endpoint if needed. use_batch_api: true cache_resources: 86400 dimensions: enabled: true # Issue #43648 workaround: explicit per-metric aggregations matching # MS-documented defaults. Empty `[]` (= all 5 aggregations) triggers # `501 Sampling type is not found` from Azure Monitor on this namespace. metrics: "Microsoft.Cdn/profiles": RequestCount: [total] TotalLatency: [average] ResponseSize: [total] RequestSize: [total] ByteHitRatio: [average] OriginRequestCount: [total] OriginLatency: [average] OriginHealthPercentage: [average] Percentage4XX: [average] Percentage5XX: [average] processors: resource/frontdoor: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_front_door, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:FRONTDOOR_REGION}", action: insert} # cloud.resource_id pins all metrics to one profile. Drop this line # for multi-profile fleets; the receiver injects azuremonitor.resource_id # per-resource automatically. - {key: cloud.resource_id, value: "${env:FRONTDOOR_RESOURCE_ID}", action: insert} - {key: deployment.environment.name, value: "${env:DEPLOYMENT_ENVIRONMENT}", action: insert} - {key: environment, value: "${env:DEPLOYMENT_ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:FRONTDOOR_SERVICE_NAME}", action: insert} service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/frontdoor: receivers: [azure_monitor/frontdoor] processors: [resource/frontdoor, batch] # plus your existing processors exporters: [otlphttp/b14] # your Scout exporter ``` The receiver, resource processor, and pipeline are all keyed `/frontdoor` so they coexist with other Azure receivers (Service Bus, Cosmos DB, SQL Database, Storage) in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, the `subscription_ids:` list takes any number of entries; alternatively set `discover_subscriptions: true` to scrape every subscription the configured identity has `Monitoring Reader` on. See [Multi-endpoint scaling](#multi-endpoint-scaling). ### Verification After applying the fragment and restarting the collector, three signals confirm the pipeline is healthy. **1. Receiver discovers your profile.** Within 30 seconds of collector startup (or reload), one line per discovery phase appears in the logs: ```text azuremonitorreceiver ... "Loaded the list of Azure Subscriptions" subscriptions_count=1 azuremonitorreceiver ... "Loaded the list of Azure Resources" resources_count=1 azuremonitorreceiver ... "Loaded the list of Azure Metrics Definitions" metrics_definitions_count=10 azuremonitorreceiver ... "Loaded the Azure Metrics" resource_id=/subscriptions/.../profiles/ ``` `subscriptions_count` and `resources_count` should match your scope. `metrics_definitions_count` should approach 10 on a production profile; fresh profiles surface only 3-4 (see [Receiver behavior on a brand-new profile](#receiver-behavior-on-a-brand-new-profile)). A wrong resource count, or a `metrics_definitions_count` of 0, indicates a configuration or RBAC issue; see [Troubleshooting](#troubleshooting). **2. Data points reach Scout.** Confirm via the collector's self-metrics on `:8888/metrics`: ```bash curl -s http://:8888/metrics \ | grep -E "(azure_monitor.frontdoor|otlp.*b14)" ``` Sample pattern after a few minutes of polling on a fresh profile (your counters will be much higher on a steady production fleet): ```text otelcol_receiver_accepted_metric_points_total{receiver="azure_monitor/frontdoor"} 11 otelcol_exporter_sent_metric_points_total{exporter="otlphttp/b14"} 11 otelcol_exporter_send_failed_metric_points_total{exporter="otlphttp/b14"} 0 otelcol_receiver_failed_metric_points_total{receiver="azure_monitor/frontdoor"} 0 ``` The two `*_total` counters should grow together (data flows end-to-end); the `*_failed_*` counters should stay at 0. **3. Series visible in Scout.** Filter on either of: - `service.name = front-door-monitor` (or whatever you set `${FRONTDOOR_SERVICE_NAME}` to). - `cloud.platform = azure_front_door`. Initial series on a fresh profile with traffic: `azure_requestcount_total`, `azure_responsesize_total`, `azure_totallatency_average`. Group by `metadata_HttpStatusGroup` to split 2XX vs 4XX vs 5XX traffic. Group by `metadata_ClientCountry` for geo distribution. If the receiver discovers the profile but the debug exporter logs `metrics: 0, data points: 0` after a few cycles, the lazy-published metrics simply have no Azure-side data yet. Wait for traffic, or generate synthetic traffic with `curl https://.azurefd.net/` in a loop; the first non-zero data point typically lands in Azure Monitor 2-5 minutes after traffic and reaches Scout one collector cycle later. ### Cache configuration `ByteHitRatio` only emits data points when Front Door actually caches responses. Front Door honors the origin's `Cache-Control` header by default. Origins that return `Cache-Control: no-store` (Azure Storage static-website endpoints are one example, plus most application backends serving dynamic content) make Front Door treat every request as cache-uncacheable and `ByteHitRatio` stays absent from the time series. Two ways to surface non-zero `ByteHitRatio`: **Option A. Origin sets meaningful `Cache-Control`.** Configure your origin to return `Cache-Control: max-age=`, or `s-maxage=` to apply only to proxies. This is the cleanest path; Front Door honors the directive and `ByteHitRatio` populates per minute. Most production CDN deployments already do this for static assets. **Option B. Front Door Rules Engine override.** When you cannot change the origin (third-party API, legacy backend, Storage static-website that you control but want to keep simple), attach a `RouteConfigurationOverride` action to the route: ```bash RG= PROFILE= az afd rule-set create -g $RG --profile-name $PROFILE \ --rule-set-name CacheRules az afd rule create -g $RG --profile-name $PROFILE \ --rule-set-name CacheRules --rule-name OverrideCache \ --order 1 \ --action-name RouteConfigurationOverride \ --enable-caching true \ --cache-behavior OverrideAlways \ --cache-duration "0.00:05:00" \ --query-string-caching-behavior IgnoreQueryString # Enable caching on the route and attach the rule set. az afd route update -g $RG --profile-name $PROFILE \ --endpoint-name -n \ --enable-caching true \ --rule-sets CacheRules ``` The `cacheBehavior: OverrideAlways` ignores the origin's `Cache-Control` and applies the configured `cacheDuration`. Both the rule and the route update need to propagate to FD edge POPs before caching takes effect; expect 10-30 minutes on cold profiles before repeated requests to the same URL begin returning `x-cache: TCP_HIT` and `ByteHitRatio` populates. The legacy `CacheExpiration` action is rejected on API versions newer than `2020-09-01`. Use `RouteConfigurationOverride` only. ### Operations #### Cardinality control Front Door's `metadata_*` dimensions multiply quickly: - `metadata_ClientCountry` × ~250 values. - `metadata_ClientRegion` × ~10 values. - `metadata_HttpStatus` × ~30 values commonly seen. - `metadata_HttpStatusGroup` × 5 values. - `metadata_Endpoint` × N (one per AFD endpoint). A 10-metric × 5-status × 250-country fleet can produce 12,500 active series per endpoint. Drop `metadata_ClientCountry` (or other high-cardinality dimensions) via `dimensions.overrides` on the receiver when per-country slicing is not actionable for your team: ```yaml receivers: azure_monitor/frontdoor: dimensions: enabled: true overrides: "Microsoft.Cdn/profiles": # List only the dimensions you want to keep; omitted dimensions # are dropped before emit. RequestCount: [HttpStatusGroup, Endpoint] ResponseSize: [HttpStatusGroup, Endpoint] TotalLatency: [HttpStatusGroup, Endpoint] # ...repeat for other metrics; use [] to drop ALL dimensions for a metric. ``` #### Multi-endpoint scaling `subscription_ids` and `resource_groups` are both lists; one collector can poll dozens of profiles across many subscriptions. With `Monitoring Reader` granted on each scope, the default `use_batch_api: true` (see [Receiver configuration](#receiver-configuration)) gives you the 360,000 calls/hour per-subscription ceiling and batched fan-out across resources. Flip to `false` only as a temporary fallback to the legacy ARM `/metrics` endpoint (12,000 calls/hour, immediate RBAC) while data-plane RBAC propagates. #### Edge propagation timing For new profiles or after configuration updates (cache rules, origin changes, route changes), treat actual endpoint behavior (a successful HTTPS GET returning the origin response) as the propagation gate, not the management-plane `deploymentStatus` field. The field has been observed to remain `NotStarted` indefinitely while the edge correctly serves traffic. Microsoft documents 5-15 minute propagation. Real-world propagation can run noticeably longer (sometimes an hour or more) on cold profiles or in less-trafficked regions. Plan the gap into your change windows. #### Receiver behavior on a brand-new profile (Skip this if your profile already serves production traffic.) Azure Monitor only publishes metric definitions for metrics that have data behind them. A freshly-provisioned Front Door profile typically surfaces only 3-4 of the 10 whitelisted metrics; the receiver logs `metrics_definitions_count: 3` (or similar). The remaining metrics (`OriginHealthPercentage`, `OriginLatency`, `OriginRequestCount`, `RequestSize`, `Percentage4XX`, `Percentage5XX`) appear once Azure has data points behind them, which depends on traffic shape (origin pulls, error responses, etc.). The whitelist intentionally keeps all 10 so they start emitting automatically once Azure publishes their definitions. Trimming to the visible 4 would silently lose them later. **Receiver caches the definitions list.** The `azuremonitorreceiver` fetches `metrics:list-definitions` per resource and caches the result. When Azure publishes a new metric definition (e.g., `ByteHitRatio` after cache traffic begins), a long-running collector continues emitting only what it cached at startup until either the cache TTL expires or the collector restarts. If you wire a cache rule for `ByteHitRatio` and the metric still does not appear in Scout after 30 minutes of cached traffic, restart the collector - the next discovery cycle will pick up the new definition and start emitting the metric on the following scrape. ### Key alerts Three alerts cover the bulk of actionable Front Door incidents. Tune thresholds to your traffic volume and SLO; the suggestions below are starting points. | Alert | Condition | Why | | --- | --- | --- | | Edge 5XX rate elevated | `avg(azure_percentage5xx_average) > 1` for 5 min | Sustained server-side error rate at the edge. The page-worthy alert. Pair with `metadata_HttpStatus` to identify the dominant 5XX. | | Origin unhealthy | `avg(azure_originhealthpercentage_average) < 100` for 2 min | Health probe failing. Below 100% means at least one origin in the pool is failing the probe; below ~50% means user requests are likely failing too. | | Edge latency spike | `avg(azure_totallatency_average) > ` for 5 min | User-perceived latency anomaly. Set the threshold from your last 30 days of data; a doubling typically indicates an origin slowdown or an edge POP issue. | Two metrics are useful for capacity / cost dashboards but not direct alerts: `azure_bytehitratio_average` (cache effectiveness; low values indicate origin egress costs are climbing) and `azure_originrequestcount_total` vs `azure_requestcount_total` (the ratio is your cache-shielding efficiency). `azure_percentage4xx_average` is noisier (clients sending malformed requests, scrapers, etc.) and is best left as a dashboard metric, not an alert. ### Logs Architecture for the Diagnostic Settings → Event Hubs → `azure_event_hub` path is in the [overview](./overview.md#choosing-pull-push-or-both). The Front Door-specific log categories worth enabling: | Log category | What it captures | Tier | | --- | --- | --- | | `FrontDoorAccessLog` | Per-request access log: client IP, route, cache outcome, backend latency | Standard, Premium | | `FrontDoorHealthProbeLog` | Backend health probe results | Standard, Premium | | `FrontDoorWebApplicationFirewallLog` | WAF rule matches and block decisions | Premium only | Metrics drive SLI / SLO dashboards and alerts; logs drive per-request investigation. WAF logs in particular are the path for security review and rule tuning - enable them on Premium tier. ### Troubleshooting **`BadRequest: Free Trial and Student account is forbidden for Azure Frontdoor resources`** during Bicep / portal provisioning. Upgrade subscription to PAYG; Front Door is on Microsoft's Free-Trial-excluded list. Production customers running existing Front Door profiles never see this. **`501 Sampling type is not found`** in collector logs against `Microsoft.Cdn/profiles`. Receiver's default aggregations triggered issue #43648; verify the `metrics:` whitelist sets exactly one aggregation per metric matching MS docs (the fragment above ships the correct list). **Endpoint returns 404 with `x-cache: CONFIG_NOCACHE` and a large default-error body.** Edge propagation incomplete. Microsoft documents 5-15 minute propagation, but on cold profiles or quieter regions it can run materially longer; wait and retry. The `deploymentStatus` field is unreliable as a propagation indicator; use actual endpoint behavior as the gate. **Endpoint returns 502 / 504 from origin.** Origin pull failing. Verify the origin hostname is reachable directly: `curl https:///`. Common causes: the origin rejects the `Host:` header Front Door forwards (set `originHostHeader` on the origin to whatever the backend expects), the origin requires client-cert auth (which Front Door doesn't present), or backing storage / app-service is down. **`metrics_definitions_count` is 3 or 4, not 10.** Expected on a brand-new profile; Azure lazy-publishes definitions per metric. See [Receiver behavior on a brand-new profile](#receiver-behavior-on-a-brand-new-profile). Production profiles with weeks of history surface all 10 immediately. **`ByteHitRatio` emits no data points even with traffic.** Origin returns `Cache-Control: no-store`. Apply the [Cache configuration](#cache-configuration) override. If the cache rule is already in place and `x-cache: TCP_HIT` shows on the responses but the metric still does not appear in Scout, restart the collector - the receiver caches the definitions list per container lifetime, so a metric that Azure begins publishing mid-run is only picked up after a fresh discovery cycle. **`AuthorizationFailed` / `403 Forbidden` on receiver poll.** Service principal's `Monitoring Reader` role hasn't propagated yet. Wait 60 seconds and retry; the legacy `/metrics` endpoint propagates immediately, but verify the role assignment landed via `az role assignment list`. **`dial tcp: lookup login.microsoftonline.com: network is unreachable`** on first scrape after a sibling collector restart. Docker Desktop DNS glitch. Recreate the collector container (`docker compose down && docker compose up`) to refresh the DNS resolver. ### Frequently Asked Questions **Should I use Front Door Standard, Premium, or Classic?** Standard for new deployments. Premium adds WAF metrics and Private Link origin support; Classic is deprecated and not on Microsoft's roadmap. The metric coverage in this guide applies to both Standard and Premium; Premium-only WAF metrics are documented but not in the default whitelist. #### Do I need to grant the SP `Reader` as well as `Monitoring Reader`? No. `Monitoring Reader` alone covers the entire `azure_monitor` receiver surface for Front Door. `Reader` is only needed if the receiver throws `AuthorizationFailed` on a specific call (rare). **Can I monitor multiple FD profiles with one collector?** Yes. Add their resource groups to the `resource_groups:` list, or omit the list entirely to scrape every profile in the listed subscriptions. The `cloud.resource_id` resource attribute should be dropped from the processor in that case (the receiver injects per-resource resource IDs automatically via `azuremonitor.resource_id`). **How does Scout compare to Application Insights for Front Door?** Both draw from the same Azure Monitor REST API for metrics; coverage is identical. Scout is vendor-neutral OTLP, queryable via SQL, with ingest-volume pricing. Application Insights is Azure-tenant-bound and KQL-only. The collector also unifies multi-cloud surfaces (Front Door, AWS CloudFront, GCP Cloud CDN) under one pipeline. **What does this cost beyond the FD profile itself?** The `azure_monitor` receiver makes one Azure Resource Manager call per metric per resource per collection interval. For one FD profile and the 10-metric whitelist polled every 60 seconds, that is roughly 14,400 ARM calls per day, well under the 12,000-per-hour per-subscription ceiling. Azure does not bill metric reads from the ARM `/metrics` endpoint separately. Scout-side, ingest is billed per data point; with one profile the volume is small (single-digit MB per day before cardinality multiplication). ### Related Guides - [Azure Application Gateway](./application-gateway.md) - regional L7 load balancer with WAF v2. Customers running both global edge and regional backend selection should monitor both surfaces. - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure SQL Database](./sql-database.md) - managed relational database. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure Kubernetes Service](../azure/aks.md) - managed Kubernetes. --- ## Azure Key Vault Monitoring with OpenTelemetry - API Latency, Throttling Saturation, and Per-Secret Audit Forensics ### Overview This guide is the **execution playbook** for Azure Key Vault. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running Azure Key Vault (Standard or Premium) in production who want to add vault telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.KeyVault/vaults` metrics every 60 seconds, and a sibling pipeline ingests AuditEvent records from the vault's Diagnostic Settings via Event Hubs as OTel logs. The receiver does not connect to the vault's data plane. It queries Azure Monitor for any vault your subscription auto-publishes to, so the same configuration covers Standard and Premium tiers across any number of vaults in the configured scope. > **Managed HSM?** If you operate `Microsoft.KeyVault/managedHSMs` > rather than `Microsoft.KeyVault/vaults`, the namespace is different, > the metric names differ, and the RBAC model is FIPS 140-2 Level 3 > rather than Level 2. The receiver pattern is the same shape, but > the whitelist below does not apply directly. Managed HSM coverage > is a separate roadmap entry. This guide ships both paths: metrics via the `azure_monitor` receiver and AuditEvent logs via the `azure_event_hub` receiver. See [Receiver configuration](#receiver-configuration) for metrics and [Logs](#logs) for the audit path. ### Key Vault at a glance Azure Key Vault is a fully managed secret, key, and certificate store. Applications fetch secrets over HTTPS to the vault's `{vault-name}.vault.azure.net` endpoint, authenticated by Microsoft Entra ID. | Layer | What it produces | | --- | --- | | Authentication | Microsoft Entra ID token negotiation per data-plane call (the "Authentication 401 then retry" pattern that dominates `ServiceApiResult` volume). | | Data plane | Per-operation counters (SecretGet, SecretSet, KeyGet, etc.) split by activity name and status code. Latency per operation. | | Throttling subsystem | `SaturationShoebox` reports proximity to the per-vault, per-region data-plane rate limit, which varies by operation. | | Availability subsystem | `Availability` percentage based on Microsoft's external probes. | The receiver does not see per-secret breakdowns - Azure Monitor publishes activity-level aggregates only. **Per-secret access attribution requires the AuditEvent log path, not metrics.** This is the design rationale for shipping §Logs alongside metrics for KV. ### Tier choice Azure Key Vault has two pricing tiers as of 2026, plus the separate Managed HSM offering. | Tier | Pricing model (region-dependent, current as of May 2026) | Key/secret protection | Metric coverage | | --- | --- | --- | --- | | **Standard** | Vault: $0/month; software-protected secret + key operations $0.03 per 10k. Certificate operations themselves are free; certificate renewals are billed separately (typically a few dollars per certificate per year, depending on issuer). | Software-protected, FIPS 140-2 Level 1 | Full metric surface (the 5-metric whitelist below). | | **Premium** | Same as Standard for vault + ops; HSM-protected keys add ~$1 per key per month for the first 250 keys, with per-key cost dropping at higher counts. | HSM-protected, FIPS 140-2 Level 2 | Identical metric surface to Standard. No additional metrics. | | **Managed HSM** | Per-HSM hourly billing (typically several dollars per hour), starting in the low thousands of dollars per month for the smallest SKU. | Fully managed dedicated HSM, FIPS 140-2 Level 3 | Different namespace (`Microsoft.KeyVault/managedHSMs`), different metric names. **Out of scope** - separate guide. | Pick Standard for nearly all use cases. Premium adds HSM-backed key protection with no metric surface change - the receiver configuration in this guide covers both. Managed HSM serves regulated workloads with strict isolation requirements at substantially higher cost; the receiver pattern is similar but the whitelist must be re-derived. ### Receiver configuration Drop this into your existing collector. The receiver, resource processor, and pipeline are all keyed `/keyvault` so they coexist with other Azure receivers under one collector and one Scout exporter. The `Microsoft.KeyVault/vaults` namespace is **not currently known to exhibit receiver bug #45942** (the case-mismatched-dimensions bug seen on `Microsoft.ApiManagement/service`, `Microsoft.Network/azureFirewalls`, and a subset of `Microsoft.Storage` metrics on `azuremonitorreceiver` v0.151.0), so no `transform` processor is required for this surface. Re-check on receiver upgrades. ```yaml extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/keyvault: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:KEYVAULT_RESOURCE_GROUP} services: - Microsoft.KeyVault/vaults auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.KeyVault/vaults": ServiceApiHit: [Total] ServiceApiLatency: [Average, Maximum] ServiceApiResult: [Total] Availability: [Average] SaturationShoebox: [Average] processors: resource/keyvault: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_key_vault, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:KEYVAULT_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:KEYVAULT_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:KEYVAULT_SERVICE_NAME}", action: insert} service: pipelines: metrics/keyvault: receivers: [azure_monitor/keyvault] processors: [resource/keyvault, batch] exporters: [otlp_http/b14] ``` The receiver emits 6 OTel series from the 5 whitelist entries (`ServiceApiLatency` is dual-aggregation Average + Maximum, producing two series). Activity-name and status-code dimensions further split the series at runtime; expect ~25-35 datapoints per poll on an active vault. ### Authentication and RBAC The collector authenticates to Azure Monitor as a service principal holding **`Monitoring Reader`** at the **resource group** containing the vault. Resource-group scope is the minimum necessary; subscription scope is acceptable but broader than needed. ```bash az role assignment create \ --assignee "$AZURE_CLIENT_ID" \ --role "Monitoring Reader" \ --scope "$(az group show --name --query id -o tsv)" ``` `Monitoring Reader` is sufficient for both the metrics path (`azuremonitorreceiver`) and the logs path (the receiver consumes from Event Hubs via a SAS token, no Key Vault data-plane role needed). The collector **never** touches the vault's data plane - it cannot read secrets, keys, or certificates and does not need any of the `Key Vault Secrets User`, `Key Vault Crypto User`, or `Key Vault Certificates User` roles. Two propagation delays apply after first assignment: 1. **Control-plane RBAC propagation** - typically 60-300 seconds before the receiver's `metricDefinitions` and `metrics` REST calls succeed. The receiver retries on its 60-second poll cycle. 2. **First-poll metric-definitions race** - Azure Monitor's metricDefinitions catalog can take 60-180 seconds to populate after `provisioningState: Succeeded`. The receiver caches an empty list if it polls during that window. Mitigation: restart the collector 3-5 minutes after the vault reaches `Succeeded`, or accept the delay and the next poll cycle picks up the populated catalog. ### What you'll monitor The 5-metric whitelist intersects the universal Key Vault metric surface. `ServiceApiLatency` is dual-aggregation (`Average` + `Maximum`) and produces two OTel series; the other four are single-aggregation, for 6 emitted series in total. | OTel series | Type | Unit | Use case | | --- | --- | --- | --- | | `azure_serviceapihit_total` | Counter (Gauge in OTel form) | Count | Throughput. Splits by `metadata_activitytype` + `metadata_activityname`. **Does NOT split by status code** - the throughput numerator is total ops, success or failure. | | `azure_serviceapilatency_average` | Gauge | Milliseconds | Mean per-operation latency. Splits by activity + `metadata_statuscode` + `metadata_statuscodeclass`. | | `azure_serviceapilatency_maximum` | Gauge | Milliseconds | Peak per-operation latency within the 1-minute aggregation window. Same dimensions as `_average`. | | `azure_serviceapiresult_total` | Counter | Count | Per-status-code throughput. Splits by activity + `metadata_statuscode` + `metadata_statuscodeclass`. **The SLI numerator** - split by `metadata_statuscodeclass = '2xx'` for success rate. | | `azure_availability_average` | Gauge | Percent | Microsoft's external availability probe result, 0-100. Single series per vault. | | `azure_saturationshoebox_average` | Gauge | Percent | Throttling capacity consumed, 0-100. KV's data-plane limits are per vault per region per 10s and depend on the operation (4,000 for secrets and most transactions, 300 for CREATE/IMPORT, 250-4,000 for key ops); this metric tracks proximity to whichever applies. **The capacity-planning signal.** | #### Operations notes - **Authentication 401 dominates `ServiceApiResult` volume on any active vault.** Every data-plane call begins with an unauthenticated probe (the Azure SDK pattern); the probe returns 401, then the SDK retries with a token. The receiver surfaces both the 401 from the probe and the 200 from the retry as separate datapoints. **Filter `metadata_activityname = 'authentication'` out of security alerts** - the 401s from this activity are expected. Alert on 401s on `secret*` / `key*` / `vaultget` activities, where they indicate a real authorization problem. - **Activity names emit lowercase in metric dimensions** (`secretset`, `secretget`, `vaultget`) but appear PascalCase in the Azure portal and AuditEvent log records. Cross-reference using case-insensitive matching when correlating metrics to logs. - **`ServiceApiHit` does NOT carry status code dimensions** - it's the total throughput counter. To compute success rate, use `azure_serviceapiresult_total{metadata_statuscodeclass='2xx'}` / `sum(azure_serviceapiresult_total)` rather than dividing `serviceapihit` by anything. - `Availability` is computed by Microsoft's external probes and smooths over short outages; spikes from full outages typically appear within 5 minutes. Treat sustained `< 100` as an active incident; treat single-point dips as probe noise. ### Cardinality control Key Vault metrics are bounded by the activity-name and status-code dimension space, both of which have small fixed cardinalities: | Attribute | Source | Cardinality | | --- | --- | --- | | `azuremonitor.resource_id` | Receiver | One per vault (low). | | `name` | Receiver | One per vault. | | `resource_group` | Receiver | One per RG. | | `type` | Receiver | Constant: `Microsoft.KeyVault/vaults`. | | `location` | Receiver | One per region. | | `metadata_activitytype` | Azure Monitor | ~5-10 distinct values per vault: `secret`, `key`, `certificate`, `vault`, `authentication`, `storageaccount` (legacy), `task`. | | `metadata_activityname` | Azure Monitor | ~30-50 across the activity-type space (e.g. `secretset`, `secretget`, `secretlist`, `secretdelete`, `secretpurge`, plus key/cert equivalents). | | `metadata_statuscode` | Azure Monitor (Latency / Result / Availability only) | ~5-10 distinct values: `200`, `204`, `400`, `401`, `403`, `404`, `409`, `429`, `500`. | | `metadata_statuscodeclass` | Azure Monitor (same as statuscode) | Constant set: `2xx`, `4xx`, `5xx`. | | `metadata_transactiontype` | Azure Monitor (`SaturationShoebox` only) | Single dimension partitioning the rate limit accounting. | **Per-secret name is NOT emitted by Azure Monitor for Key Vault.** This is by design - secret names can themselves be sensitive (naming conventions can leak schema, credentials, or business relationships). Per-secret attribution requires the AuditEvent log path; metrics aggregate to the activity level only. Cardinality stays bounded at 25-35 emitted datapoints per scrape per vault under typical activity. A fleet of 50 vaults under one collector lands at ~1500 datapoints per minute - well within Scout's default capacity for any reasonable plan. If you operate dozens of vaults in one collector, scope each `azure_monitor` receiver instance to a single resource group rather than letting one receiver span the whole subscription. Query latency stays predictable, and any per-RG outage is contained to that receiver instance. ### Alert tuning Operational alerting on Key Vault follows the **RED method on the vault**: Rate (operations per second), Errors (non-2xx status codes), Duration (`ServiceApiLatency`). #### RED method on the vault | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **Throttling proximity** | `azure_saturationshoebox_average` | > 70% / 5m | > 90% / 5m | The metric is a percentage of whichever per-operation cap applies, so alert on it directly. Alerting at 70% gives time to shard secrets or cache values application-side. | | **Auth failures (data plane)** | `$increase(azure_serviceapiresult_total{metadata_statuscode='401', metadata_activityname!='authentication'})` | > 0 / 5m | > 0 / 1m | Excludes the expected `authentication`/401 noise. Real 401s on `secret*` / `key*` operations indicate stale credentials or revoked role assignments. | | **Forbidden (RBAC denial)** | `$increase(azure_serviceapiresult_total{metadata_statuscode='403'})` | > 0 / 5m | > 5 / 1m | A caller has a token but lacks the required data-plane role. Indicates either misconfigured role assignment or attempted privilege escalation. | | **Throttled (429)** | `$increase(azure_serviceapiresult_total{metadata_statuscode='429'})` | > 0 / 5m | > 0 / 1m | Rate limit hit. Correlates with `SaturationShoebox` rising; if SaturationShoebox is healthy but 429s appear, suspect a single client burst rather than steady traffic. | | **Latency p95 (proxy via Maximum)** | `azure_serviceapilatency_maximum` | > 100 / 5m | > 500 / 5m | Milliseconds. Maximum approximates p95-p99 for the 1-min aggregation window. KV is normally `<10ms`; spikes above 100ms indicate Azure-side issues. | | **Availability dip** | `azure_availability_average < 100` | < 99% / 5m | < 95% / 5m | Microsoft's external probe. Sustained sub-100% indicates an active vault incident. | | **Server errors** | `$increase(azure_serviceapiresult_total{metadata_statuscodeclass='5xx'})` | > 0 / 5m | > 5 / 1m | Azure-side failures. Page platform on-call. | #### Authentication 401 exclusion The single most important alert filter for Key Vault metrics is excluding `metadata_activityname = 'authentication'` from any 401 alerting. Authentication 401s are a normal SDK pattern (probe → token → retry); on a vault serving 50 ops/min you may see 50 Authentication 401 records per minute. Without filtering, every 401 alert fires constantly. With filtering, 401s on data-plane operations become a meaningful signal. ### Premium-tier additions Premium tier is software-equivalent to Standard at the metrics layer. The receiver configuration above covers both tiers without modification. Premium adds HSM-backed key protection (FIPS 140-2 Level 2) without changing the metric surface. For deeper HSM telemetry, customers operating `Microsoft.KeyVault/managedHSMs` need a separate receiver block against that namespace; the metric names differ and are not covered by this guide. ### Apps-side instrumentation The metrics in this guide describe the vault itself. End-to-end visibility - application latency including secret-fetch time, secrets accessed, miss-rate per code path - requires client-side OTel instrumentation in the application. The OTel auto-instrumentation agents for Java, .NET, Python, Node.js, and Go all wrap the standard Azure SDKs (`Azure.Security.KeyVault.Secrets`, `azure-identity`, etc.). Calls emit HTTP-style client spans annotated with `azure.namespace: Microsoft.KeyVault`, the vault hostname under `server.address`, and the operation name (`SecretGet`, `KeyEncrypt`, etc.) under `azure.operation` per the OTel Azure SDK semantic conventions - not the `db.*` family, since Key Vault is not a database. The vault-side metrics in this guide and the apps-side traces are complementary: vault metrics tell you whether the vault is healthy; apps-side spans tell you which code paths are reading secrets and how often. Wire both for full coverage. ### Logs Metrics aggregate operations by activity type, status code, and transaction type - they cannot answer who, from where, on which specific secret, or with what client-side identity. Three operational gaps that AuditEvent logs fill where metrics cannot: - **Per-secret access attribution** records each `SecretGet`, `SecretSet`, `SecretDelete`, `SecretPurge` operation with the exact secret name. The metrics path collapses these to `metadata_activityname = 'secretget'` aggregates with no per-name dimension. Per-secret attribution is the canonical requirement for PCI / HIPAA / SOC 2 audits and incident-response forensics. - **Per-IP and per-identity audit** records the requester's source IP, user agent, and Microsoft Entra ID identity (UPN, app ID, OID) for every data-plane call. The metrics path has no source-IP dimension at all. Per-IP audit is the canonical requirement for security investigations after a credential compromise - without it, you cannot answer "did this stolen token actually touch my vault?". - **Per-key delete forensics** preserves the operation record beyond the soft-delete window. The metrics path shows `secretdelete` Count incremented; the log shows which principal deleted which secret at which timestamp from which IP, available even after the soft-delete catalog expires. Key Vault publishes one Diagnostic Settings category that fills these gaps: | Category | What it contains | Tier emission | | --- | --- | --- | | `AuditEvent` | One record per data-plane operation with `operationName`, `properties.requesterIpAddress`, `properties.userAgentHeader`, `identity.claim.appid`, `identity.claim.upn`, `properties.httpStatusCode`, and the affected resource (vault, secret name, key name). | All tiers (Standard and Premium). Emits regardless of whether RBAC or Access Policy auth model is used. | The recommended pattern is **Diagnostic Settings to Event Hubs to `azure_event_hub`** in the same collector. The receiver ingests events as OTel logs and routes them to Scout via the same `oauth2client` / `otlp_http/b14` pipeline used for metrics. ```yaml receivers: azure_event_hub/keyvaultlogs: connection: ${env:KEYVAULTLOGS_CONNECTION_STRING} partition: "" offset: "" format: azure apply_semantic_conventions: true processors: resource/keyvaultlogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_key_vault, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:KEYVAULTLOGS_SOURCE_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:KEYVAULTLOGS_SOURCE_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:KEYVAULTLOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/keyvaultlogs: receivers: [azure_event_hub/keyvaultlogs] processors: [resource/keyvaultlogs, batch] exporters: [otlp_http/b14] ``` The `connection` string must include the `EntityPath=` suffix so the receiver knows which hub to consume. The receiver defaults to consuming all partitions from the oldest available offset (`partition: ""`, `offset: ""`); on collector restart it re-reads from the saved offset, providing at-least-once delivery. #### Wiring the Diagnostic Setting Create the Diagnostic Setting against the vault, forwarding only the `AuditEvent` category to your Event Hubs hub: ```bash az monitor diagnostic-settings create \ --resource "$(az keyvault show --name --query id -o tsv)" \ --name keyvault-audit \ --event-hub "$EVENT_HUB_NAME" \ --event-hub-rule "$DIAG_SEND_RULE_ARM_ID" \ --logs '[{"category":"AuditEvent","enabled":true}]' ``` The flag is `--event-hub` (NOT `--event-hub-name`) on `az` CLI 2.85.0 and later. The `--event-hub-rule` value is the full ARM resource ID of a namespace-level SAS authorization rule with `Send` rights. #### Diagnostic Settings ship cadence Azure batches AuditEvent records and ships them to Event Hubs on a non-real-time cadence. Expect: - **First batch from a freshly-wired vault: 5-20 minutes**. Azure documents 5-15 minutes; the upper end can stretch to 20 minutes in practice on freshly-wired vaults. Plan for 20. - **Steady-state batches: 5-15 minutes**. After the first batch, subsequent ones arrive in the documented range. - **End-to-end latency from vault op to Scout: 5-15 minutes steady-state**. Audit visibility is NOT real-time. For real-time audit (e.g. live security monitoring), use Microsoft Defender for Cloud / Azure Sentinel, which read AuditEvent directly with lower latency. The OTel path is appropriate for audit retention, forensics, and compliance reporting where per-event minutes-of-lag is acceptable. #### Why not `AzurePolicyEvaluationDetails` or `AllMetrics`? - **`AzurePolicyEvaluationDetails`** records Azure Policy compliance evaluations against the vault. This is policy-engine telemetry rather than vault telemetry; it answers "is this vault compliant with policy X?" rather than "what is happening to this vault?". Customers using Azure Policy at scale should ship policy-engine events via a separate compliance pipeline. - **`AllMetrics`** duplicates the metric data the `azure_monitor` receiver already collects. Enabling it produces double-counted data in Scout. Stay with `AuditEvent` only. ### Troubleshooting #### `AuthorizationFailed` from the receiver in the first 60 seconds Symptom: scraper logs `AuthorizationFailed` or `403` shortly after provisioning. Cause: `Monitoring Reader` was granted but Azure RBAC is still propagating to the data-plane endpoint. Fix: wait 60-300 seconds. The receiver retries on its next poll cycle. If the error persists after 5 minutes, verify the role assignment with `az role assignment list --assignee --scope `. #### `metrics_definitions_count: 0` on first poll after provisioning Symptom: the receiver logs `metrics_definitions_count: 0` and emits no metrics. Cause: Azure Monitor's metricDefinitions catalog has not yet populated for the freshly-deployed vault. Fix: restart the collector after the vault has been up for at least 3 minutes, OR wait 5-10 minutes and the next 60-second poll picks up the now-populated catalog. #### Authentication 401 dominates `ServiceApiResult` Symptom: the largest series in `azure_serviceapiresult_total` is `metadata_activityname = 'authentication', metadata_statuscode = '401'`. Cause: Azure SDK's standard probe-then-token pattern. Each data-plane call begins with an unauthenticated probe that returns 401, followed by a retry with a token. Fix: this is normal and expected. **Filter `metadata_activityname = 'authentication'` out of 401 alerts** so real 401s on `secret*` / `key*` operations remain visible. #### 429 Too Many Requests under steady traffic Symptom: `azure_serviceapiresult_total{metadata_statuscode='429'}` fires repeatedly while `SaturationShoebox` reads below 70%. Cause: the per-vault rate limit is per-region, and a single bursty client can saturate the limit briefly even when the 1-minute aggregate looks healthy. Fix: identify the bursty client via the AuditEvent log path (`properties.requesterIpAddress`), then either pool calls client-side or shard secrets across multiple vaults to spread the rate-limit load. #### Empty Event Hubs for several minutes after provisioning the logs path Symptom: `azure_event_hub/keyvaultlogs` receiver reports zero events for the first 5-20 minutes after the Diagnostic Setting is created. Cause: this is the standard Azure Diagnostic Settings ship cadence - the first batch can take up to 20 minutes to ship from a freshly-wired vault. Fix: wait. Subsequent batches arrive in 5-15 minutes per Azure's documented cadence. The receiver is not broken; the EH is genuinely empty. #### `consumer_group` config key not accepted Symptom: collector boot fails with `unknown field 'consumer_group'`. Cause: the `azure_event_hub` receiver removed the top-level `consumer_group` field before contrib v0.151.0; user-defined consumer groups now require a separate receiver instance per group. Fix: omit the field; the receiver consumes from the implicit `$Default` consumer group, which works on Event Hubs Basic and above. #### Activity names case-mismatch between metrics and logs Symptom: a metric query for `metadata_activityname = 'SecretGet'` returns no data despite log records showing `operationName: SecretGet`. Cause: metric dimensions emit lowercase (`metadata_activityname = 'secretget'`); log records emit PascalCase (`operationName: SecretGet`). Fix: use lowercase in metric queries and PascalCase in log queries, or apply case-insensitive matching at the query layer. #### Scout OAuth2 returns 401 Symptom: `oauth2client` extension logs 401 from the token endpoint. Cause: stale `SCOUT_CLIENT_ID` / `SCOUT_CLIENT_SECRET` / `SCOUT_TOKEN_URL`. Fix: re-source `~/.config/base14/scout-otel-config.env` (or the equivalent secret store) and restart the collector. ### Frequently Asked Questions #### When should I use Key Vault versus a self-hosted secret store? Pick Azure Key Vault when you want a managed secret store with 99.99% SLA, automated patching, Entra-ID-integrated RBAC, soft-delete recovery, and Premium-tier HSM-backed protection without operating the secret store yourself. Pick HashiCorp Vault on Azure VMs / AKS when you need cross-cloud portability, more flexible authorization policies (Vault's policy DSL is more expressive than Azure RBAC), or HSM brands not available on Azure Premium. The metrics paths differ entirely: this guide covers Key Vault PaaS via `azure_monitor`; HashiCorp Vault is monitored via the OTel `prometheus` receiver against Vault's `/v1/sys/metrics` endpoint. #### How does AuditEvent logging compare to Microsoft Defender / Sentinel? Microsoft Defender for Cloud and Azure Sentinel both read AuditEvent directly from Azure's internal log store, with lower latency than the Diagnostic Settings → Event Hubs → receiver path. Defender / Sentinel are appropriate for real-time security monitoring and SIEM integration. The OTel path in this guide is appropriate for audit retention, compliance reporting, and forensic analysis where per-event minutes-of-lag is acceptable. Both can coexist; many production deployments ship to both for separate use cases. #### Can I monitor Managed HSM with this configuration? No. Managed HSM ships under the `Microsoft.KeyVault/managedHSMs` namespace with different metric names. The `azure_monitor` receiver pattern is similar but the whitelist must be re-derived from Azure Monitor's catalog for the HSM resource type. Managed HSM coverage is a separate roadmap entry. #### How does Key Vault compare to AWS Secrets Manager for monitoring? Both expose secret-store APIs and ship metrics through the cloud's native monitoring service (Azure Monitor for Key Vault, CloudWatch for Secrets Manager). The OTel paths differ: this guide uses `azure_monitor` (pull-based, polls every 60 s); AWS Secrets Manager typically uses CloudWatch metrics streams (push-based via Kinesis Firehose, near-real-time). Metric coverage at the SLI layer is roughly equivalent (request count, latency, error rate); per-secret audit on AWS uses CloudTrail rather than CloudWatch, which is the direct analogue to Azure's AuditEvent path through Diagnostic Settings. #### Should the collector run inside my private-endpoint Key Vault's VNet? If your vault uses Private Endpoints and disables public network access, the collector needs network reachability to Azure Monitor's public REST endpoints (which are NOT affected by Private Endpoints on the vault - Azure Monitor is a separate control-plane service). The collector must reach `management.azure.com` and the Event Hubs namespace endpoint on `*.servicebus.windows.net`. If the collector runs outside the vault's network entirely (e.g. on a different cloud), only outbound HTTPS to those Azure endpoints is required. Network architecture is independent of this telemetry pipeline. #### How do I add Azure Key Vault metrics to my existing OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.KeyVault/vaults`, route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter, and grant the collector's service principal Monitoring Reader at the resource group containing your vaults. The receiver polls Azure Monitor's REST API every 60 seconds. The five-metric whitelist (ServiceApiHit, ServiceApiLatency, `ServiceApiResult`, Availability, `SaturationShoebox`) covers Standard and Premium tiers identically. The collector does not connect to the vault's data plane and does not need any data-plane role assignment - it queries Azure Monitor for whatever your vaults auto-publish. #### Why does ServiceApiResult show many 401s on Authentication? Every Key Vault data-plane call begins with an unauthenticated probe that returns 401, then retries with a token. The receiver surfaces both the 401 from the probe and the 200 from the retry as separate `ServiceApiResult` datapoints, so a healthy vault under steady traffic shows a roughly 1:1 ratio of Authentication 401 records to data-plane 200 records. This is normal Azure SDK behaviour, not a security signal. Filter Authentication 401 records out of security alerts; alert on 401 against secret operations (SecretGet 401, SecretSet 401) instead. #### What is the difference between metrics and AuditEvent logs for Key Vault? Metrics aggregate operations by activity type, status code, and transaction type at one-minute granularity. AuditEvent logs record one entry per data- plane operation with the requester's source IP, user agent, Microsoft Entra ID identity (UPN and app ID), the specific operation name (SecretGet, SecretSet, etc.), and the HTTP status. Metrics tell you how many operations are happening and at what latency. AuditEvent logs record which identity called which operation on which secret, and from where. Metrics are enough for SLO and capacity work; logs are required for compliance, security forensics, and per-secret access patterns. Both ship in this guide: the metrics path via the `azure_monitor` receiver, and the logs path via Diagnostic Settings to Event Hubs to the azure_event_hub receiver. #### How do I monitor proximity to Key Vault's data-plane rate limit? Azure caps Key Vault data-plane operations per vault per region over a rolling 10 seconds, and the cap depends on the operation. Secrets and most other transactions get 4,000; CREATE secret, IMPORT certificate, and IMPORT key share 300 between them; key operations run from 250 to 4,000 depending on key type and size. The `SaturationShoebox` metric publishes the percentage of the applicable cap consumed, aggregated over a one-minute window, so you can alert on it without tracking which limit applies. Alert at 70 percent for warning and 90 percent for critical. Once the cap is reached, the application sees 429 Too Many Requests responses, so alerting on `SaturationShoebox` before that point leaves time to shard secrets across vaults, cache values application-side, or move high-throughput paths off Key Vault. The cap is per-vault per-region, so a regional fleet of vaults sharing a workload should be monitored individually. #### Should I enable AzurePolicyEvaluationDetails or AllMetrics? No, neither category is needed alongside this guide. `AzurePolicyEvaluationDetails` records Azure Policy compliance evaluations against the vault, which is policy-engine telemetry rather than vault telemetry, and ships through a separate compliance pipeline if at all. `AllMetrics` duplicates the metric data this guide already collects via the `azure_monitor` receiver, so enabling it produces double-counted data in Scout. Stay with AuditEvent only in the Diagnostic Setting; the receiver-fed metrics path covers the metric surface separately. ### Reference - [Microsoft.KeyVault/vaults supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-keyvault-vaults-metrics) - [Key Vault Diagnostic Logs reference](https://learn.microsoft.com/azure/key-vault/general/logging) - [Key Vault data-plane RBAC roles](https://learn.microsoft.com/azure/key-vault/general/rbac-guide) - [opentelemetry-collector-contrib azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - [opentelemetry-collector-contrib azureeventhubreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azureeventhubreceiver) ### Related Guides - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - start here for the cross-surface story. - [Azure Storage](./storage.md) - managed object/blob/queue/table/file storage. - [Azure Cache for Redis](./cache-for-redis.md) - managed Redis-compatible cache. - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure API Management](./api-management.md) - API gateway and management plane. --- ## Azure Load Balancer Monitoring with OpenTelemetry ### Overview This guide is the **execution playbook** for Azure Load Balancer (Standard SKU). For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. The collector polls Azure Monitor's REST API for `Microsoft.Network/loadBalancers` every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. The receiver does not touch the LB data plane. **Standard SKU only.** Basic Load Balancer reached end-of-life on 2025-09-30 and no longer supports the metric set covered here. The namespace `Microsoft.Network/loadBalancers` covers regional Standard LBs and Cross-region (Global) LBs. This guide focuses on regional LBs. Cross-region LBs use regional LBs as backends (a tier-2 fan-out topology) and add one extra metric, `GlobalBackendAvailability`. The receiver pattern works for both - add `GlobalBackendAvailability: [Average]` to the whitelist for Cross-region LBs. ### Topology preconditions Three Standard LB topology constraints determine whether the metrics in this guide reflect reality. Get these wrong before you deploy the collector and `DipAvailability` will read 100 even when the backend pool is empty, or `UsedSnatPorts` will double-account because two outbound paths share one frontend. Verify each before you start collecting. #### IP-based vs NIC-based backend pools Standard LB supports two backend-pool addressing modes. The operational difference is significant: | Mode | Backend specification | Constraint | When to use | | --- | --- | --- | --- | | **NIC-based** | NIC resource IDs of backend VMs | NIC and LB must share a region; cross-VNET allowed via VNET peering | Default for VM and VMSS backends. Survives backend IP changes. | | **IP-based** | Backend IPs directly | Backend IPs **must reside in the LB's VNET**; non-VNET IPs are silently rejected (the API accepts them, the pool stays empty) | Container-based backends, or backends without a NIC resource (private endpoints, etc.). | If you specify backend IPs for an IP-based pool from outside the LB's VNET, `az network lb show` returns `backendAddressPools[].backendAddresses` empty and `DipAvailability` flatlines at the default. Always verify with `az network lb show -g -n --query backendAddressPools[].backendAddresses` after pool changes. #### `disableOutboundSnat: true` when frontend is shared If the same frontend IP is referenced by both an LB rule (inbound) and an outbound rule, the LB rule's implicit SNAT and the explicit outbound rule double-account on `UsedSnatPorts` and `AllocatedSnatPorts`. Set `disableOutboundSnat: true` on the LB rule to delegate all SNAT to the outbound rule. The Azure API rejects deployments where the constraint is violated and the same frontend feeds both paths, but older `azure-cli` versions silently swallow the error; verify post-deploy with: ```bash az network lb rule show -g --lb-name -n \ --query disableOutboundSnat ``` **NAT Gateway preempts the LB SNAT path.** A subnet attached to NAT Gateway routes outbound traffic through NAT Gateway, not the LB. The LB's outbound rule still emits `AllocatedSnatPorts` and `UsedSnatPorts` series for the same frontend, but the values do not reflect actual outbound capacity for NAT-attached subnets - treat NAT Gateway's metrics as ground truth there. ### Receiver configuration Add this fragment to your existing collector config. It contributes the `azure_auth` extension, an `azure_monitor` receiver scoped to the LB namespace, a resource processor, and a metrics pipeline. Component keys are suffixed `/loadbalancer` so the fragment composes cleanly with other Azure-surface receivers in the same collector. ```yaml showLineNumbers title="otel-collector.yaml (Load Balancer addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Authentication section below for the right choice per # collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/loadbalancer: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:LOADBALANCER_RESOURCE_GROUP} # Multi-resource-group scoping. Omit resource_groups entirely to # scrape every resource group in the listed subscriptions. services: - Microsoft.Network/loadBalancers auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Data-plane batch API (*.metrics.monitor.azure.com). Lifts the # per-subscription rate ceiling from 12k to 360k calls/hour and is # the recommended default. Flip to false only as a temporary fallback # while data-plane RBAC propagates after a fresh Monitoring Reader # grant (5-30 min lag). use_batch_api: true cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Network/loadBalancers": # Availability VipAvailability: [Average] DipAvailability: [Average] # Traffic counters ByteCount: [Total] PacketCount: [Total] SYNCount: [Total] # SNAT SnatConnectionCount: [Total] AllocatedSnatPorts: [Average] UsedSnatPorts: [Average] processors: resource/loadbalancer: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_loadbalancer, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:LOADBALANCER_REGION}", action: insert} # cloud.resource_id pins all metrics to one LB. Drop this line for # multi-LB fleets; the receiver injects azuremonitor.resource_id # per-resource automatically. - {key: cloud.resource_id, value: "${env:LOADBALANCER_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:LOADBALANCER_SERVICE_NAME}", action: insert} service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/loadbalancer: receivers: [azure_monitor/loadbalancer] processors: [memory_limiter, resource/loadbalancer, batch] # plus your existing processors exporters: [otlphttp/b14] # your Scout exporter ``` The receiver, resource processor, and pipeline are all keyed `/loadbalancer` so they coexist with other Azure-surface receivers in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, add entries to `subscription_ids:`. The alternative `discover_subscriptions: true` scrapes every subscription the identity has `Monitoring Reader` on; prefer the explicit list in production, since discovery silently includes sandbox and dormant subscriptions. ### Authentication and RBAC Pick the `azure_auth` mode for where the collector runs: - **AKS pod** - `workload_identity` (federated credential, no secret). - **Container Apps / VMSS / Azure VM** - `managed_identity` (user-assigned survives instance replacement; system-assigned dies with the instance). - **External or on-prem** - `service_principal`. - **Local dev only** - `use_default: true` (Azure SDK credential chain). Grant `Monitoring Reader` at the resource group containing your load balancers. For mode-by-mode YAML, federation-credential setup, and the `az role assignment create` snippet, see [Azure Service Bus § Authentication](./service-bus.md#authentication) - the configuration is identical except for the receiver's `services:` line and the resource processor's `cloud.platform` value. This guide defaults `use_batch_api: true` for the 360k-calls/hour ceiling. Data-plane RBAC lags 5-30 minutes after a fresh `Monitoring Reader` grant; if the receiver returns 401s in that window, temporarily flip to `false` (legacy ARM `/metrics`, immediate propagation) and revert once the data-plane RBAC settles. ### What you'll monitor Load Balancer publishes 8 metrics on the `Microsoft.Network/loadBalancers` namespace, all at PT1M time grain. The receiver renames Azure's PascalCase names (e.g. `VipAvailability`) to OTel-style `azure__` (e.g. `azure_vipavailability_average`). | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `VipAvailability` | `azure_vipavailability_average` | % | Frontend availability. 100 means the LB itself is reachable; below 100 means Azure-side LB degradation in the region. | | `DipAvailability` | `azure_dipavailability_average` | % | Backend health-probe success rate. 100 means all backends pass; below 100 means probes are failing. The single most important per-backend signal. | | `ByteCount` | `azure_bytecount_total` | Bytes | Bytes transmitted through the LB per minute. Splits by `Direction` (Inbound / Outbound) and `FrontendPort`. | | `PacketCount` | `azure_packetcount_total` | Count | Packets transmitted. Splits same as ByteCount. Pair with ByteCount to compute average packet size. | | `SYNCount` | `azure_syncount_total` | Count | TCP SYN packets seen. New-connection-attempt rate; pair with `SnatConnectionCount` to see how many of those completed SNAT. | | `SnatConnectionCount` | `azure_snatconnectioncount_total` | Count | New SNAT connections created. Splits by `ConnectionState` (Pending / Successful / Failed). The Failed slice fires when SNAT exhaustion is occurring. | | `AllocatedSnatPorts` | `azure_allocatedsnatports_average` | Count | SNAT ports allocated to the backend pool by the outbound rule. Constant unless you change `allocatedOutboundPorts`. | | `UsedSnatPorts` | `azure_usedsnatports_average` | Count | SNAT ports currently in use. Divided by `AllocatedSnatPorts` gives utilisation; sustained > 80% indicates approaching SNAT exhaustion. | Eight `metadata_*` dimensions split these metrics: - `metadata_FrontendIPAddress`, `metadata_FrontendPort` (ByteCount, PacketCount, SYNCount) - one series per LB rule. - `metadata_BackendIPAddress`, `metadata_BackendPort` (DipAvailability) - one series per backend. - `metadata_Direction` (ByteCount, PacketCount, SYNCount) - `Inbound` / `Outbound`. - `metadata_Protocol`, `metadata_ProtocolType` (SnatConnectionCount, AllocatedSnatPorts, UsedSnatPorts) - `TCP` / `UDP`. - `metadata_ConnectionState` (SnatConnectionCount only) - `Pending` / `Successful` / `Failed`. See [Cardinality control](#cardinality-control) for shaping advice. **Silent-when-quiet caveat.** Azure Monitor returns data points for ByteCount, PacketCount, SYNCount, and SnatConnectionCount only when the underlying activity occurs. An LB with no traffic emits zero series for those four. Wire alerts to fire on series presence in window (any non-zero point) rather than threshold crossings, since absence of points is the steady state for under-utilised LBs. `VipAvailability` flows continuously every minute regardless of traffic. `DipAvailability` requires at least one backend and a configured health probe before it emits non-default values. ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. Single-namespace surfaces like Load Balancer cost roughly 60 calls per LB per hour at 60s `collection_interval` (one call per metric per poll, deduplicated). Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | --- | --- | --- | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Default in this guide. RBAC lags 5-30 min after the Monitoring Reader grant. | | Legacy Azure Resource Manager `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Temporary fallback if the data plane is still 401-ing after RBAC propagation should have completed. Immediate RBAC propagation. | Even small fleets benefit from `use_batch_api: true` because batched fan-out is more rate-limit-friendly than per-metric ARM calls. A 100-LB fleet polling at 60s costs ~6,000 calls/hour against the 360k ceiling (under 2% utilization), leaving room for sibling surfaces on the same collector. `cache_resources` is the resource-list cache TTL in seconds. The receiver default of `86400` (24 hours) is the right setting for a stable fleet. Lower to `3600` or `600` only if LBs are created and destroyed frequently enough that 24-hour-stale resource lists become a problem (see Troubleshooting § "Metrics never appear on a freshly provisioned LB"). ### Cardinality control By default the receiver emits one OTel series per `(resource × metric × aggregation × dimension-combination)`. The dimension shape on Load Balancer is moderate: a single LB with one frontend and one backend produces roughly 25 active series during steady traffic. Per-LB scaling factors: - `metadata_FrontendIPAddress` × `metadata_FrontendPort` - one series per LB rule. Most LBs have 1-3 rules. - `metadata_BackendIPAddress` - one series per backend. A 5-node backend pool produces 5x the per-rule fan-out on `DipAvailability`. - `metadata_ConnectionState` (SnatConnectionCount only) - three values (Pending, Successful, Failed). The Failed slice is where SNAT exhaustion shows up. - `metadata_Direction` (ByteCount, PacketCount, SYNCount) - Inbound and Outbound; doubles the fan-out on those three metrics. A 50-LB fleet with 2 rules and 5 backends per LB lands around ~1,650 active series (25 baseline + ~8 per LB for the extra rule and backends). Most fleets stay in the 1,500-3,500 range; trim with `dimensions.overrides` before crossing 5,000. Three control levers: 1. **`dimensions.overrides`** drops or whitelists dimensions per metric. Drop `metadata_BackendPort` on `DipAvailability` if you do not need per-port backend availability: ```yaml azure_monitor/loadbalancer: dimensions: enabled: true overrides: "Microsoft.Network/loadBalancers": DipAvailability: - metadata_BackendIPAddress # keep - metadata_FrontendIPAddress # keep # drop ProtocolType, BackendPort ``` 2. **Aggregation-list narrowing.** Replace `[]` with explicit lists (the snippet above already does this - `[Average]` and `[Total]` only). Adding `[Maximum, Minimum]` to gauges grows series by 2x without operational benefit on availability metrics. 3. **Per-account receiver instances.** Split the public-facing-LB tier (high cardinality on FrontendIPAddress) into a separate `azure_monitor/loadbalancer-public` receiver with a narrower override profile, while letting `azure_monitor/loadbalancer` stay broad on internal LBs. Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's port-8888 Prometheus endpoint to see actual cardinality after `overrides` apply. #### Receiver bug #45942 (case-mismatch dimensions) Receiver bug [#45942](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942) emits the same logical dimension under both PascalCase (`metadata_Status`) and lowercase (`metadata_status`) keys, doubling cardinality silently. Validation 2026-05-06 confirmed the bug manifests on `Microsoft.Network/azureFirewalls` and `Microsoft.Storage/storageAccounts` but **not** on `Microsoft.Network/loadBalancers` at receiver v0.151.0. If a future receiver version regresses and you see matched-pair keys (`metadata_Status` and `metadata_status`) on Load Balancer metrics, add this transform processor to the pipeline (see [Azure Firewall § Cardinality control](./azure-firewall.md#bug-45942-case-mismatched-dimension-keys) for the explanation): ```yaml processors: transform/loadbalancer_dim_lowercase: metric_statements: - context: datapoint statements: # Replicate this pair for each affected dimension. - set(attributes["metadata_status"], attributes["metadata_Status"]) where attributes["metadata_Status"] != nil and attributes["metadata_status"] == nil - delete_key(attributes, "metadata_Status") where attributes["metadata_Status"] != nil ``` Insert `transform/loadbalancer_dim_lowercase` into the `metrics/loadbalancer` pipeline's `processors:` list (after `resource/loadbalancer`, before `batch`). Re-validate on each receiver upgrade. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points; derive your own from observed 99th-percentile baselines over a representative week. | Metric | Warning | Critical | Why it matters | | --- | --- | --- | --- | | `azure_dipavailability_average` (per backend) | < 100% over 5m | < 50% over 5m | Backend health-probe failure. Below 50% means the backend is effectively unreachable and traffic is concentrating on the remaining healthy nodes. | | `azure_vipavailability_average` | < 99.9% over 5m | < 99.0% over 15m | LB-side degradation. Cross-check Azure Service Health for the region; this is rarely user-actionable. | | `azure_usedsnatports_average / azure_allocatedsnatports_average` | > 80% over 5m | > 95% over 5m | SNAT-port exhaustion is imminent. See SNAT exhaustion below. | | `azure_snatconnectioncount_total` filtered to `metadata_ConnectionState="Failed"` | `> 0` over 5m | `> 0` over 15m | SNAT exhaustion occurring now. Outbound from the backend pool is breaking. | | `azure_syncount_total / azure_packetcount_total` | tune to your fleet - no universal threshold | - | High SYN-to-packet ratio can indicate SYN floods or aggressive new-connection patterns, but the baseline ratio is entirely connection-pattern dependent (request-heavy services run high; long-lived bulk transfers run low). Establish a 7-day baseline before alerting; alert on deviation, not absolute value. | For `azure_snatconnectioncount_total` filtered to Failed, fire alerts on series presence in window rather than numeric thresholds - see the [silent-when-quiet caveat](#what-youll-monitor) above. #### SNAT port exhaustion SNAT-port exhaustion is the most common operational failure mode for Azure Load Balancer. The default outbound rule allocates 1024 SNAT ports per backend instance per frontend public IP. A single TCP connection holds one port for ~4 minutes after close (TIME_WAIT). Burst patterns where backends open many short-lived connections to the internet (microservice → managed PaaS over public endpoint, for example) exhaust the pool well before traffic levels become visible on the application side. Symptoms operators see: - `azure_usedsnatports_average / azure_allocatedsnatports_average` sustained > 80%. - `azure_snatconnectioncount_total` filtered to `metadata_ConnectionState="Failed"` non-zero. - Backend application logs show `connect: cannot assign requested address`, `EADDRNOTAVAIL`, or `connection timed out` errors against external hostnames. Three remediations, in order of operational ease: 1. **Increase `allocatedOutboundPorts` on the outbound rule.** Up to the per-VM cap, which varies by SKU. See [Microsoft Learn: outbound connections](https://learn.microsoft.com/azure/load-balancer/load-balancer-outbound-connections) for the current per-SKU limits. 2. **Add more frontend public IPs.** Each adds 1024 default SNAT ports per backend. Use this for fleets where increasing `allocatedOutboundPorts` per-rule is not enough. 3. **Move outbound traffic to NAT Gateway.** NAT Gateway preempts the LB SNAT pool with up to 64,512 ports per VNET, scaling independently of inbound LB traffic. Best fit when outbound throughput is the bottleneck. For a deeper look at the math, see Microsoft's [SNAT exhaustion article](https://learn.microsoft.com/azure/load-balancer/load-balancer-outbound-connections). ### Apps-side instrumentation This guide is metrics-only. Load Balancer is L4 (TCP / UDP) and is generally invisible to application-layer instrumentation. To produce per-request distributed traces, instrument your backend application code with an HTTP server SDK (e.g. OpenTelemetry instrumentation for your framework) - the LB itself does not emit per-connection traces. Run apps-side spans alongside this metrics collector with distinct `service.name` values to keep the platform view (this guide) and the request-flow view separately filterable in Scout. ### Logs Azure Load Balancer health-event logs ship via Diagnostic Settings. Architecture for the Diagnostic Settings → Event Hubs → `azure_event_hub` path is in the [overview](./overview.md#choosing-pull-push-or-both). ```bash LB_RES_ID=$(az network lb show -n -g --query id -o tsv) az monitor diagnostic-settings create \ --resource "$LB_RES_ID" \ --name "lb-to-eventhubs" \ --logs '[{"category":"LoadBalancerAlertEvent","enabled":true},{"category":"LoadBalancerProbeHealthStatus","enabled":true}]' \ --event-hub-rule ``` `LoadBalancerProbeHealthStatus` captures every health-probe state transition with the backend IP and probe details. Pair it with the `azure_dipavailability_average` metric to see which backends are behind a threshold-breach alert. ### Service principal credential lifecycle If you run a service principal (collector outside Azure), rotate the client secret before its expiry, not after. The procedure is identical to Service Bus and other azure-monitor surfaces; see [Service Bus § Service principal credential lifecycle](./service-bus.md#service-principal-credential-lifecycle). ### Troubleshooting #### `AuthorizationFailed` from the receiver Data-plane batch API (`use_batch_api: true`, the default) propagates `Monitoring Reader` 5-30 minutes after grant; legacy ARM `/metrics` (`use_batch_api: false`) propagates immediately. If you've just granted the role and the receiver is 401-ing, temporarily flip to `false` to confirm the role itself is correct, then revert once the data-plane RBAC has settled. #### `403 Forbidden` from the receiver If using a service principal: the `client_secret` has expired. See [Service principal credential lifecycle](#service-principal-credential-lifecycle). If using managed identity: check that the LB is in a subscription / resource group where the managed identity has `Monitoring Reader`. #### Metrics never appear on a freshly provisioned LB The receiver caches metric definitions for the `cache_resources` interval (default 86400s / 24h). On the first poll after a fresh LB is created, Azure Monitor's metric-definition catalogue may not yet have populated for the new resource - the receiver's first-poll `metrics_definitions_count: 0` log line confirms the diagnosis. Subsequent polls within the same `cache_resources` window will not retry the discovery. **Restart the collector** after the LB is fully provisioned (about 5 minutes after `az network lb create` completes). The restart resets the discovery cache. To verify recovery, look for `metrics_definitions_count: ` with `N > 0` on the next poll cycle. If `N` is still `0`, Azure Monitor's catalogue has not populated yet - wait 2-3 minutes and restart again. If restarting the collector is operationally heavy, the alternatives are: lower `cache_resources` to `600` for the first hour of a new LB's life (then revert to `86400`), or wait one full `cache_resources` cycle. #### `DipAvailability` stuck at 0 Backend health probe is failing. Three causes, in order of likelihood: 1. **NSG on the backend subnet blocks `AzureLoadBalancer`.** The service tag must be allowed inbound on the probe port. The Bicep pattern in this guide's example sets this up correctly. 2. **Backend application is not listening on the probe port** (or responding with an unexpected status). Check from inside the backend VM with `curl localhost:`. 3. **Backend is not in the LB's VNET.** Standard LB IP-based backend pools require the backend IPs to live in the LB's VNET; non-VNET IPs are silently rejected and `backendAddressPools[].backendAddresses` appears empty. Verify with `az network lb show -g -n --query backendAddressPools[].backendAddresses`. #### `RequestThrottled` warnings from the receiver You have hit Azure Monitor's per-subscription rate ceiling (12,000 / hour on legacy, 360,000 / hour on batch). Either: - Lower polling rate: `collection_interval: 120s` for the fast receiver. - Confirm `use_batch_api: true` is set (the guide default) - the legacy ARM endpoint caps at 12k/h versus 360k/h on data-plane batch. - Split heavy subscriptions across multiple collector instances. #### Cardinality blowup on Scout volume A high-fanout LB (many frontend IPs, many backends) can dominate volume. Apply `dimensions.overrides` (see [Cardinality control](#cardinality-control)) or split the noisy LB into a separate receiver instance with a narrower whitelist. #### Scout OAuth2 returns 401 Verify `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, and `SCOUT_TOKEN_URL` match the values in your Scout console. The `endpoint_params.audience` must be `b14collector`. ### Frequently Asked Questions #### How do I add Azure Load Balancer metrics to my OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.Network/loadBalancers`, then route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter. The receiver polls Azure Monitor's REST API every 60 seconds and emits one OTel metric per Azure aggregation. Standard SKU only; Basic SKU is end-of-life as of 2025-09-30. #### Why are my Load Balancer metrics not appearing after I provision a new LB? Two common causes. First, the receiver caches metric definitions for the `cache_resources` interval (24h by default); if the LB was created after the receiver started, restart the collector to force re-discovery. Second, the LB needs a healthy backend with a working health probe before `VipAvailability` and `DipAvailability` emit non-default values; verify with `az network lb show` that `backendAddressPools[].backendAddresses` is populated and the NSG on the backend subnet allows the `AzureLoadBalancer` service tag. #### How do I detect SNAT port exhaustion? Alert on `azure_usedsnatports_average / azure_allocatedsnatports_average` above 80% over a 5-minute window. SNAT port exhaustion presents as outbound connection failures from the backend pool to the internet, even when the LB itself is healthy. The fix is to either increase `allocatedOutboundPorts` on the outbound rule, add more frontend public IPs (each adds 1024 default SNAT ports), or move outbound traffic to NAT Gateway. #### Should I use a service principal or managed identity for the collector? Managed identity if the collector runs in Azure, service principal if it does not. AKS pods use Workload Identity Federation with a federated credential bound to a Kubernetes ServiceAccount; Container Apps and Virtual Machine Scale Sets use system-assigned or user-assigned managed identity; out-of-Azure collectors fall back to service principal. The `azure_auth` extension's mode block is the only thing that changes; the rest of the receiver config is identical. RBAC requirement is `Monitoring Reader` at resource-group scope. #### What is the difference between this guide and Azure Application Gateway? Azure Load Balancer is L4 (TCP / UDP), regional, and exposes metrics on the `Microsoft.Network/loadBalancers` namespace. Application Gateway is L7 (HTTP / HTTPS), regional, and exposes WAF v2 plus path-based routing on `Microsoft.Network/applicationGateways`. The receiver shape is identical for both; only the metric whitelist and dimensions differ. Run both in the same collector via separate fragments under the long-lived shared scraper pattern. ### Reference - **Receiver source.** [opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver). - **Auth extension source.** [opentelemetry-collector-contrib / extension / azureauthextension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/azureauthextension). - **Azure Monitor metric reference.** [Microsoft.Network/loadBalancers metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-loadbalancers-metrics). - **SNAT exhaustion deep-dive.** [Microsoft Learn: outbound connections](https://learn.microsoft.com/azure/load-balancer/load-balancer-outbound-connections). - **Basic SKU EOL announcement.** [Azure Updates: Basic Load Balancer retirement](https://azure.microsoft.com/updates/azure-basic-load-balancer-will-be-retired-on-30-september-2025-upgrade-to-standard-load-balancer/). ### Related Guides - [Azure Application Gateway](./application-gateway.md) - regional L7 load balancer with WAF v2. - [Azure Front Door](./front-door.md) - global CDN and L7 edge with WAF. - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure Storage](./storage.md) - managed object/blob/queue/table/file storage. - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. --- ## Azure Logic Apps Monitoring with OpenTelemetry - Run Health, Billable Executions & Workflow Logs ## Azure Logic Apps Monitoring with OpenTelemetry > **Why Scout for Azure Logic Apps observability?** > > Microsoft now emits OTel-shaped telemetry by default through the Azure > Monitor OpenTelemetry Distro and SDK 3.x. Scout consumes those exact > signals via OTLP and stores them alongside your AWS, GCP, on-prem, and > application telemetry in one OTel-native query surface. > > Azure Monitor remains the data source for the metrics in this guide - > the receiver reads from it. What changes is the destination: Scout > instead of Application Insights / Log Analytics for visualization, > alerting, and long-term query. ### Overview Logic Apps Consumption is a single Microsoft-managed workflow resource (`Microsoft.Logic/workflows`) billed per execution. End-to-end observability means the run / action / trigger lifecycle and the billable-execution count from the control plane, plus the per-action detail that aggregate metrics cannot reach. This guide configures the `azure_monitor` receiver for control-plane metrics and the `azure_event_hub` receiver for the `WorkflowRuntime` Diagnostic Settings log category. ### Instrumentation paths for Logic Apps Consumption exposes exactly two telemetry paths. Pick one or both based on the table below. | Path | What it covers | What it costs | Setup | | --- | --- | --- | --- | | **Platform metrics - Azure Monitor** (this guide) | Run / action / trigger lifecycle counts, run / action / trigger latency, and billable executions, aggregated per workflow at minute grain. Answers most "is my workflow healthy and what is it costing me?" questions on its own. Does **not** see which action inside a run failed. | Azure Monitor query cost: one query per metric per scrape (or one per resource with `use_batch_api: true`). At a 60s interval the daily cost runs in cents per workflow. | One Service Principal with `Monitoring Reader` on the resource group; one receiver block; one resource processor. | | **Resource logs - Diagnostic Settings → Event Hubs** (this guide, §Logs) | Per-action drill-down: which action ran, its status and error code, per-trigger payload attribution, per-run forensic ordering. Optionally the full trigger / action inputs and outputs. The detail surface metrics structurally cannot provide. | One Event Hubs Basic namespace (~$11/mo at 1 TU; 1 MB/s ingress absorbs far more than a typical workflow's record rate). The Diagnostic Setting itself is free. | One Diagnostic Setting on the workflow with the `WorkflowRuntime` category; one Event Hubs namespace + hub + Send/Listen SAS rules; one `azure_event_hub` receiver fragment. | There is **no third (in-system scrape) path**. Logic Apps Consumption's runtime is fully Microsoft-managed with no data-plane endpoint to scrape. The in-database or in-broker pull pattern used for PostgreSQL or Redis does not apply here. If you arrived expecting a "scrape the engine" option, that is why it is absent. Standard hosting (`Microsoft.Web/sites` with `kind=workflowapp`) exposes App Service Plan signals instead; see [Azure App Service](./app-service.md). #### Which path to pick Four decision criteria, in order of usual weight: 1. **Consumption or Standard hosting?** This guide is Consumption (`Microsoft.Logic/workflows`). Standard emits `Microsoft.Web/sites`-shaped metrics plus App Service Plan saturation signals - a different namespace and a different receiver scope. Confirm which hosting model your workflow uses before configuring the receiver; mixing them silently yields an empty metric set. 2. **Is cost attribution your priority?** `TotalBillableExecutions` is the single most actionable Consumption metric - Consumption bills per billable execution. If cost control is the whole reason you are here, the platform-metrics path alone is sufficient; you do not need logs. 3. **Do you need to know which action failed?** Surface metrics aggregate. `ActionsFailed` tells you an action in some run failed, not which action, in which run, with what error. Debugging failed runs needs the `WorkflowRuntime` logs path. 4. **Are your trigger or action payloads sensitive?** `IncludeContent` on the Diagnostic Setting captures trigger and action inputs and outputs verbatim. Leave it off for PII-bearing workflows; enable it only when you need payload-level forensics and have reviewed the privacy trade-off. If you are starting from zero, platform metrics are the lowest-effort win and cover run health plus cost. Add the logs path when you need per-action attribution for failed or slow runs. ### What you'll monitor The receiver scrapes the `Microsoft.Logic/workflows` namespace and emits per-workflow metrics under `cloud.platform: azure_logic_apps`. These metrics carry **no Azure Monitor metadata dimensions** - each is a single series per workflow, so cardinality stays minimal and there is no dimensional fan-out to budget for. | Metric | Aggregation | What it tells you | | --- | --- | --- | | `RunsStarted` | Total | Runs initiated. Pairs with `RunsCompleted` to expose in-flight backlog. | | `RunsCompleted` | Total | Runs that reached a terminal state. | | `RunsSucceeded` | Total | Runs that completed successfully. | | `RunsFailed` | Total | Failed runs. Primary run-health SLI. | | `RunsCancelled` | Total | Cancelled runs. | | `RunLatency` | Average, Maximum | End-to-end run duration. Average for trend, Maximum for tail. Traffic-driven. | | `ActionsStarted` | Total | Actions begun across all runs. | | `ActionsCompleted` | Total | Actions that reached a terminal state. | | `ActionsSucceeded` | Total | Actions that succeeded. | | `ActionsFailed` | Total | Failed actions. Tells you an action failed, not which - see §Logs. | | `ActionsSkipped` | Total | Actions skipped by `runAfter` conditions. | | `ActionLatency` | Average, Maximum | Per-action duration, aggregated. Traffic-driven. | | `TriggersStarted` | Total | Trigger evaluations begun. | | `TriggersCompleted` | Total | Trigger evaluations completed. | | `TriggersSucceeded` | Total | Successful trigger evaluations. | | `TriggersFailed` | Total | Failed / rejected trigger evaluations. | | `TriggersFired` | Total | Triggers that fired a run. The inbound-request counter for an HTTP Request trigger. | | `TriggersSkipped` | Total | Trigger evaluations that did not fire. | | `TriggerLatency` | Average, Maximum | Trigger evaluation duration. Traffic-driven. | | `TotalBillableExecutions` | Total | Billable executions. The canonical Consumption cost SLI. Traffic-driven. | | `BillableActionExecutions` | Total | Action-side billing split. Traffic-driven. | | `BillableTriggerExecutions` | Total | Trigger-side billing split. Traffic-driven. | **Traffic-driven vs continuous.** The count metrics (`Runs*`, `Actions*`, `Triggers*`) publish an explicit `0` every minute even at idle. The latency series (`RunLatency`, `ActionLatency`, `TriggerLatency`) and the three billing metrics publish data points **only for minutes that contain completed runs**. On a low-traffic workflow these are sparse by design - an empty `RunLatency` minute means no runs that minute, not a broken pipeline. When verifying the pipeline, drive traffic and read the metrics within the same active window. ### Prerequisites | Requirement | Detail | | --- | --- | | Hosting model | Consumption (`Microsoft.Logic/workflows`). Standard is out of scope - see [Azure App Service](./app-service.md). | | OTel Collector Contrib | v0.151+ (the `azure_monitor` and `azure_event_hub` receiver names are snake_case from v0.148.0). | | OpenTelemetry semconv | v1.41.0 (latest cloud attributes). | | Azure CLI | 2.85+ for the `az monitor diagnostic-settings` flags used here. | | Azure providers registered | `Microsoft.Logic`, plus `Microsoft.EventHub` and `Microsoft.Insights` for the logs path. | | Collector runtime | See [Docker Compose Setup](../../collector-setup/docker-compose-example.md) or [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md); this guide adds the Logic Apps receiver + processor blocks on top. | | Scout exporter | See [Scout exporter wiring](../../collector-setup/scout-exporter.md) for the `oauth2client` extension + `otlp_http/b14` exporter. This guide does not re-derive that block. | ### Access setup The metrics receiver authenticates via a Service Principal scoped to the resource group: | Role | Scope | Reason | | --- | --- | --- | | `Monitoring Reader` | Resource group containing the workflow | Lets the receiver list metric definitions and read metric values for `Microsoft.Logic/workflows`. | The logs path does **not** need a second role assignment. The `azure_event_hub` receiver consumes the diagnostic hub through the namespace-scoped SAS rule's `Listen` permission carried in its connection string; no `Azure Event Hubs Data Receiver` role on the namespace is required unless you switch the receiver to Azure AD auth. If you reuse one Service Principal across many surfaces, the assignment is idempotent - re-running it on an already-granted SP is a no-op. It typically propagates in under 30 seconds; the first scrape after a fresh assignment may return `403 AuthorizationFailed` and self-clears on the next 60s cycle. ### Receiver configuration Add the following alongside whatever already wires `azure_auth` and the Scout exporter. **You do not need to duplicate** the `oauth2client` extension or the `otlp_http/b14` exporter; those live in the shared base config per [Scout exporter wiring](../../collector-setup/scout-exporter.md). ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_monitor/logicapps: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:LOGICAPPS_RESOURCE_GROUP} services: - Microsoft.Logic/workflows auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Logic/workflows": RunsStarted: [Total] RunsCompleted: [Total] RunsSucceeded: [Total] RunsFailed: [Total] RunsCancelled: [Total] RunLatency: [Average, Maximum] ActionsStarted: [Total] ActionsCompleted: [Total] ActionsSucceeded: [Total] ActionsFailed: [Total] ActionsSkipped: [Total] ActionLatency: [Average, Maximum] TriggersStarted: [Total] TriggersCompleted: [Total] TriggersSucceeded: [Total] TriggersFailed: [Total] TriggersFired: [Total] TriggersSkipped: [Total] TriggerLatency: [Average, Maximum] TotalBillableExecutions: [Total] BillableActionExecutions: [Total] BillableTriggerExecutions: [Total] processors: resource/logicapps: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_logic_apps, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:LOGICAPPS_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:LOGICAPPS_RESOURCE_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: insert} - {key: environment, value: "${env:ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:LOGICAPPS_SERVICE_NAME}", action: insert} service: pipelines: metrics/logicapps: receivers: [azure_monitor/logicapps] processors: [memory_limiter, resource/logicapps, batch] exporters: [otlp_http/b14] ``` `use_batch_api: false` issues one query per metric per scrape. A single Consumption workflow is a small query budget; switch to `true` only if you scale this receiver across many workflows in one subscription. ### Environment variables ```bash title=".env" AZURE_SUBSCRIPTION_ID=... LOGICAPPS_RESOURCE_GROUP=... # RG containing the workflow LOGICAPPS_REGION=... # for cloud.region; defaults to the RG region LOGICAPPS_RESOURCE_ID=... # full ARM ID of the workflow LOGICAPPS_SERVICE_NAME=logic-apps-monitor ENVIRONMENT=production ``` Service Principal credentials (`AZURE_TENANT_ID`, `AZURE_CLIENT_ID`, `AZURE_CLIENT_SECRET`) and Scout exporter credentials come from the shared base config and are not listed here. See [Scout exporter wiring](../../collector-setup/scout-exporter.md). ### Operations #### RBAC propagation lag `Monitoring Reader` on the resource group typically propagates in under 30 seconds, occasionally up to 120 seconds. The first scrape after a fresh assignment may return `403 AuthorizationFailed`; the receiver retries on the next 60s cycle and the noise clears within two polls. #### Latency and billing metrics are traffic-driven `RunLatency`, `ActionLatency`, `TriggerLatency`, and the three billing metrics publish data points only for minutes that contain completed runs. The count metrics publish a continuous `0`. Do not alert on the *absence* of latency data points - alert on the values when present. When smoke-testing, drive a run and read the metric inside the same minute window; a read several minutes after the last run shows only the continuous count series. #### Metrics aggregate per workflow only `Microsoft.Logic/workflows` metrics carry no metadata dimensions. There is no per-action or per-trigger breakdown in the metric stream - `ActionsFailed` is a workflow-wide counter. Per-action attribution is the job of the `WorkflowRuntime` logs path (§Logs). This also means the metric cardinality is one series per metric per workflow, so the receiver's query and storage footprint scales linearly with workflow count and nothing else. #### Consumption concurrency throttling An HTTP Request trigger enforces a per-workflow concurrency limit. Aggressive callers receive `HTTP 429` with a `Retry-After` header rather than queuing unbounded. This surfaces as `TriggersFailed` / `TriggersSkipped` in the metric stream; if you see them climb under load, the caller is exceeding the workflow's concurrency budget, not the pipeline failing. #### `WorkflowRuntime` logs warm-up On a freshly started collector the `azure_event_hub` receiver spends roughly 15-20 minutes establishing its Event Hubs consumer before the first record is delivered downstream, even when records are already in the hub. The Diagnostic Settings → Event Hubs leg is fast for Logic Apps Consumption (records reach the hub within minutes of a run). Budget 20 minutes before treating an empty logs pipeline as broken, and **do not restart the collector during that window** - a restart resets the warm-up. ### Key alerts to configure Once metrics are flowing, set up alerts on these thresholds. The "Why" column gives the reasoning so you can adjust for your traffic shape. | Signal | Warning | Critical | Why | | --- | --- | --- | --- | | `RunsFailed` / `RunsCompleted` ratio (5 min) | > 1% | > 5% | Run failure rate; the primary Logic Apps SLI. Sustained failure usually means a downstream dependency or a bad workflow revision. | | `ActionsFailed` rate (5 min) | > 1% of `ActionsCompleted` | > 5% of `ActionsCompleted` | A single action failing repeatedly. Pair with the logs path to identify which action. | | `RunLatency` Average (5 min) | > 1.5× rolling 24h mean | > 3× rolling 24h mean | Run-duration regression. Relative thresholds track normal workflow behaviour better than absolute seconds. | | `TriggersFailed` (5 min) | > 0 sustained | > 1% of `TriggersFired` | Rejected or throttled trigger calls; co-fires with caller `HTTP 429`. | | `TotalBillableExecutions` (1 h) | > 1.5× rolling 7d hourly mean | > 3× rolling 7d hourly mean | Cost-runaway detector. A workflow change that adds actions or loops shows here first. | | `RunsStarted` − `RunsCompleted` backlog (10 min) | > 10 sustained | > 50 sustained | In-flight runs not completing; indicates a stuck action or a downstream timeout. | Configure the Scout-side alert rules through your dashboarding / alerting stack once thresholds are decided; the receiver pipeline above emits the underlying signals continuously. ### Logs The `WorkflowRuntime` Diagnostic Settings category fills the gaps the metric whitelist structurally cannot. The §Logs path uses the `azure_event_hub` receiver against a Diagnostic Settings → Event Hubs sink. #### What logs uniquely fill Platform metrics aggregate per workflow. Logs disaggregate. The gaps logs uniquely cover for Logic Apps: - **Which action failed.** `ActionsFailed` is a workflow-wide counter. The log stream names the action, its status, its error code, and the run it belonged to. - **Per-trigger attribution.** Which caller / source fired which run, with the client tracking id, in what order across a burst. - **Per-run forensic ordering.** The sequence of trigger fired → actions started → actions ended → run completed for a specific run, which metrics flatten into per-minute counts. - **Trigger and action payloads (opt-in).** With `IncludeContent` enabled, the verbatim inputs and outputs of the trigger and each action - the only way to see what data a specific run actually processed. #### Architecture ```text Logic Apps workflow (Consumption) │ │ Diagnostic Setting (resource scope) │ category: WorkflowRuntime ↓ Event Hubs namespace (Basic 1 TU) │ • diagsend SAS rule (Send) writes records │ • collectorlisten SAS rule (Listen) reads records ↓ azure_event_hub receiver │ • format: azure │ • apply_semantic_conventions: true │ • multi-record envelopes decoded into individual log records ↓ otlp_http/b14 → Scout ``` The Diagnostic Setting targets the workflow resource directly. #### Category enabled by default | Category | What it covers | | --- | --- | | `WorkflowRuntime` | Workflow run events: trigger fired (source, client tracking id), action started / succeeded / failed (per-action name, status, error code), run completed (final status, duration). With `IncludeContent: true`, also the verbatim trigger and action inputs / outputs. The only Logic Apps log category; `AllMetrics` is the metrics surface, covered by the metrics path above. | **`IncludeContent` is an opt-in knob, not a default.** Leave it off unless you need per-run inputs and outputs. When enabled, trigger and action payloads are captured verbatim - review against your PII policy before turning it on, and budget for Event Hubs Standard rather than Basic if your workflows move large JSON payloads (records approach the 256 KB per-event Basic limit and can throttle 1 TU on bursty traffic). #### Receiver configuration (logs) ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" receivers: azure_event_hub/logicappslogs: connection: ${env:LOGICAPPSLOGS_CONNECTION_STRING} partition: "" # consume all partitions offset: "" # resume from last checkpoint format: azure # decode the Azure resource-log envelope apply_semantic_conventions: true processors: resource/logicappslogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_logic_apps, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:LOGICAPPSLOGS_SOURCE_REGION}", action: insert} - {key: cloud.resource_id, value: "${env:LOGICAPPSLOGS_SOURCE_RESOURCE_ID}", action: insert} - {key: deployment.environment.name, value: "${env:LOGICAPPSLOGS_ENVIRONMENT}", action: insert} - {key: environment, value: "${env:LOGICAPPSLOGS_ENVIRONMENT}", action: insert} - {key: service.name, value: "${env:LOGICAPPSLOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/logicappslogs: receivers: [azure_event_hub/logicappslogs] processors: [memory_limiter, resource/logicappslogs, batch] exporters: [otlp_http/b14] ``` The receiver decodes multi-record Azure envelopes into individual OTel log records, so the downstream record count is higher than the raw envelope count the receiver reports - that fan-out is expected, not duplication. #### Environment variables (logs) ```bash title=".env (logs path)" LOGICAPPSLOGS_CONNECTION_STRING=... # Listen SAS with ;EntityPath= LOGICAPPSLOGS_SOURCE_REGION=... # for cloud.region on log records LOGICAPPSLOGS_SOURCE_RESOURCE_ID=... # workflow ARM ID for cloud.resource_id LOGICAPPSLOGS_SERVICE_NAME=logic-apps-logs LOGICAPPSLOGS_ENVIRONMENT=production ``` Quote the connection string in your env file. It carries `;`-separated segments - `Endpoint=...`, `SharedAccessKeyName=...`, `SharedAccessKey=...`, `EntityPath=...`. Sourced unquoted into a shell, the `;` truncates the value at the first segment. Most env-file loaders handle this, but a shell-sourced `.env` needs single quotes. #### Wiring the Diagnostic Setting ```bash title="attach the Diagnostic Setting" az monitor diagnostic-settings create \ --resource "" \ --name logicapps-runtime \ --event-hub \ --event-hub-rule "" \ --logs '[{"category":"WorkflowRuntime","enabled":true}]' ``` The `--event-hub-rule` value is the resource ID of the namespace-scoped SAS rule with `Send` permission. The receiver uses a separate `Listen` rule; one Send rule and one Listen rule on the namespace is the canonical two-rule topology. To capture payloads, add `"includeContent":true` to the log setting (review the PII trade-off first). #### Verifying the logs path After the Diagnostic Setting is attached and the workflow has completed at least one run: 1. Wait up to 20 minutes. The Diagnostic Settings → Event Hubs leg is fast (records reach the hub within minutes), but the `azure_event_hub` receiver takes 15-20 minutes to establish its consumer on a freshly started collector. Do not restart the collector during this window - a restart resets the warm-up. 2. Tail the collector debug exporter: `docker compose logs -f otel-collector | grep "otelcol.signal.*logs"`. 3. Expect batches of log records every 60-90 seconds while runs are flowing; the receiver-reported envelope count is lower than the downstream record count because envelopes carry multiple records. 4. In Scout, filter `service.name = 'logic-apps-logs'` and `cloud.platform = 'azure_logic_apps'` to confirm records land. ### Troubleshooting #### `AuthorizationFailed` on the first scrape **Cause:** The `Monitoring Reader` assignment on the resource group has not propagated yet. **Fix:** Wait two polling cycles (~2 minutes). The receiver retries automatically; the error self-clears. #### Latency or billing metrics show no data **Cause:** These metrics are traffic-driven - Azure publishes data points only for minutes containing completed runs. **Fix:** Drive a run and read the metric inside the same minute. An idle workflow shows only the continuous count series; that is correct behaviour, not a gap. #### Logs pipeline empty for ~20 minutes after wiring **Cause:** The `azure_event_hub` receiver's initial consumer establishment takes 15-20 minutes on a freshly started collector. **Fix:** Wait it out. Confirm records are arriving in the hub (`az monitor metrics list --metric IncomingMessages` on the Event Hubs namespace shows non-zero) to prove the Diagnostic Setting is delivering; the gap is downstream warm-up, not the Diagnostic Setting. Do not restart the collector to "kick" it - that resets the warm-up clock. #### Caller receives `HTTP 429` from the trigger **Cause:** The workflow's per-instance concurrency limit. **Fix:** Space the calls out or raise the workflow's concurrency control. This is Logic Apps protecting the workflow, not a telemetry fault; it shows as `TriggersFailed` / `TriggersSkipped` in the metric stream. #### `azure_event_hub` receiver logs `MessagingGatewayBadRequest` **Cause:** The receiver is requesting a user-defined consumer group that does not exist on Event Hubs Basic. **Fix:** Basic rejects user-defined consumer groups - the receiver must consume from `$Default`, the implicit group. Remove any `consumer_group:` key, or move the namespace to Standard if you need multiple consumers. #### Metric set is empty although the workflow exists **Cause:** The workflow is Standard hosting (`Microsoft.Web/sites` `kind=workflowapp`), not Consumption. **Fix:** This guide's receiver scopes `Microsoft.Logic/workflows`. For Standard, follow [Azure App Service](./app-service.md). ### Frequently Asked Questions #### How do I monitor Azure Logic Apps with OpenTelemetry? Logic Apps Consumption has two telemetry paths. Platform metrics use the `azure_monitor` receiver against `Microsoft.Logic/workflows` for run, action, and trigger lifecycle counts, latency, and billable executions. Resource logs use the `azure_event_hub` receiver consuming the `WorkflowRuntime` Diagnostic Settings category for per-action drill-down. There is no in-system scrape path: the Consumption runtime is fully Microsoft-managed with no data-plane endpoint. #### Why are RunLatency and billable-execution metrics empty on my Logic App? Logic Apps latency and billable-execution metrics are traffic-driven: Azure publishes data points only for minutes that contain completed runs. The run, action, and trigger count metrics publish an explicit zero every minute even at idle, but latency and billing series are sparse by design on a low-traffic workflow. An empty minute means no runs that minute, not a broken pipeline. #### Which Logic Apps cost metric should I alert on? `TotalBillableExecutions` is the canonical Consumption cost SLI - Consumption bills per billable execution. `BillableActionExecutions` and `BillableTriggerExecutions` split that total between action and trigger executions so you can attribute cost growth to a specific workflow change. #### Why does the WorkflowRuntime logs pipeline take ~20 minutes? On a freshly started collector the `azure_event_hub` receiver spends roughly 15 to 20 minutes establishing its Event Hubs consumer before it delivers the first record downstream, even when records are already in the hub. The Diagnostic Settings to Event Hubs leg itself is fast for Logic Apps Consumption - records reach the hub within minutes of a run. Budget 20 minutes before treating an empty logs pipeline as broken, and do not restart the collector during that window because a restart resets the warm-up. #### Can surface metrics tell me which action in my workflow failed? No. `Microsoft.Logic/workflows` metrics carry no metadata dimensions - they aggregate per workflow only. `ActionsFailed` tells you an action failed, not which one. The `WorkflowRuntime` logs path gives per-action name, status, and error code, so debugging a failed run needs the logs path. #### Does this guide cover Logic Apps Standard? No. Standard hosting runs on `Microsoft.Web/sites` with `kind=workflowapp` and emits App Service-shaped metrics plus App Service Plan signals. Follow [Azure App Service](./app-service.md) for Standard. This guide is Consumption only (`Microsoft.Logic/workflows`). ### Related Guides #### Shared collector + Scout wiring - [Docker Compose Setup](../../collector-setup/docker-compose-example.md) - the runtime that hosts both receivers in this guide. - [Kubernetes / Helm Setup](../../collector-setup/kubernetes-helm-setup.md) - alternative runtime for AKS-hosted collectors. - [Scout exporter wiring](../../collector-setup/scout-exporter.md) - the `oauth2client` extension + `otlp_http/b14` exporter shared by all Azure guides. #### Adjacent Azure surfaces - [Azure App Service](./app-service.md) - where Logic Apps Standard runs; the path for workflow apps not on Consumption. - [Azure Event Hubs](./event-hubs.md) - the streaming layer this guide's logs path runs through; monitor the hub itself when log volume grows. - [Azure Service Bus](./service-bus.md) - the messaging backbone many workflows trigger from or publish to. - [Azure API Management](./api-management.md) - the gateway that commonly fronts HTTP-triggered workflows. - [Azure Key Vault](./key-vault.md) - the secrets store workflows reference for connection credentials. #### Migrating from Application Insights - [Application Insights migration](../../apps/auto-instrumentation/dotnet.md) - moving app-side telemetry off Application Insights while keeping Azure Monitor as the metric source for this guide. --- ## Azure Network Primitives Monitoring with OpenTelemetry - Public IPs, NICs, NAT Gateways, and Private Endpoints ### Overview This guide is the **execution playbook** for the Azure network primitives - Public IPs, Network Interfaces, NAT Gateways, and Private Endpoints. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers who run Azure network plumbing in production and want to add Public IP, NIC, NAT Gateway, and Private Endpoint telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for the four `Microsoft.Network` namespaces every 60 seconds, and a sibling pipeline ingests network control-plane operations from the subscription Activity Log via Event Hubs as OTel logs. These four resource types are monitored together because individually each carries thin signal; together they answer one operational question: **is my workload's network path healthy end to end** - outbound (NAT Gateway plus its Public IP), the NIC itself, and private-link traffic (Private Endpoint). Treat them as one network-path story, not four unrelated surfaces. > **Every metric here is traffic-gated.** Azure publishes nothing for > an idle Public IP, a detached NIC, an unused NAT Gateway, or a > Private Endpoint that carries no traffic. The series are absent or > zero until the resource actually moves packets. This is the single > most important interpretation caveat for this set: an empty > scrape on a quiet resource is expected behaviour, not a receiver, > whitelist, or RBAC failure. Confirm traffic is actually flowing > before treating absent series as a fault. This guide ships both paths: metrics via the `azure_monitor` receiver, and network control-plane audit logs via the `azure_event_hub` receiver fed from a **subscription-scope** Diagnostic Setting. See [Receiver configuration](#receiver-configuration) for metrics and [Logs](#logs) for the audit path. ### Network primitives at a glance | Resource type | What it is | Why monitor it in the set | | --- | --- | --- | | `Microsoft.Network/publicIPAddresses` | A static or dynamic public IP, attached to a NAT Gateway, a Load Balancer front end, or directly to a VM NIC. | The **weak member** of this set (see below). Useful only as a plain VM front end, and even then only for raw byte/packet counts. | | `Microsoft.Network/networkInterfaces` | The NIC attached to a VM. Throughput and packet rate at the interface layer. | The per-VM network throughput vantage. Strong signal whenever the attached VM passes traffic. | | `Microsoft.Network/natGateways` | Managed outbound SNAT for a subnet. The modern replacement for outbound-rule Load Balancers and instance-level public IPs. | The outbound-path health vantage. SNAT connection counts and packet-drop are where outbound saturation shows up first. | | `Microsoft.Network/privateEndpoints` | A private-link network interface into a PaaS resource (Storage, SQL, Key Vault, and so on) inside your VNet. | The private-link traffic-volume vantage. Confirms data is actually flowing over the PE and not leaking to the public endpoint. | The four namespaces share several metric names (`ByteCount` and `PacketCount` appear on both `publicIPAddresses` and `natGateways`). A single-fragment multi-namespace receiver is the recommended shape: one `services:` block listing all four, one `metrics:` block keyed by namespace. Output is split downstream by `azuremonitor.resource_id`, so same-named metrics from different resource types stay distinct. #### The Public IP namespace is the weak member - plan around it `Microsoft.Network/publicIPAddresses` does not behave like the other three. Its emission depends entirely on **how the Public IP is attached**: - **Attached to a NAT Gateway:** the Public IP publishes **no byte or packet metrics at all**. Outbound traffic through that IP is accounted on the `Microsoft.Network/natGateways` namespace instead. A NAT-fronting Public IP is effectively metric-silent. - **Attached directly to a VM as a front end:** the Public IP emits only `ByteCount` and `PacketCount`, and only while it carries direct inbound traffic. These two counters are coarse and rarely the signal you want when the NIC namespace already gives you throughput. - **`SynCount` and `VipAvailability`** emit only behind a **Standard Load Balancer** front end. They never emit on a NAT-attached or plain VM Public IP. Keep them in the whitelist (they cost nothing when absent) but do not expect them outside a Load Balancer topology - the [Azure Load Balancer guide](./load-balancer.md) covers that vantage. The operational consequence: **do not build alerts or dashboards on the Public IP namespace for NAT or plain-VM topologies.** The network-path signal in this set lives on `natGateways`, `networkInterfaces`, and `privateEndpoints`. The Public IP namespace stays in the whitelist for the Load-Balancer-front-end case and for completeness, not because it carries the set's signal. ### Topology choices and conditional metrics The whitelist in [Receiver configuration](#receiver-configuration) covers what these four resource types emit at the platform layer. Several metrics are **topology-conditional** - they emit only in specific network designs. Keep them in the whitelist regardless; they cost nothing on topologies where they do not emit (Azure Monitor returns no series and the receiver shows zero datapoints). | Metric | Emits when | Keep in whitelist? | | --- | --- | --- | | `publicIPAddresses` / `ByteCount`, `PacketCount` | Only on a Public IP used as a **plain VM front end** carrying direct inbound. Silent when the Public IP fronts a NAT Gateway. | **Yes**, but expect silence in NAT topologies. Not an alerting signal. | | `publicIPAddresses` / `SynCount`, `VipAvailability` | Only behind a **Standard Load Balancer** front end. | **Yes** for Load-Balancer-fronted Public IPs. Never emits on NAT or plain VM attachment - see the [Load Balancer guide](./load-balancer.md). | | `natGateways` / `PacketDropCount` | Always present; sits at **zero on a healthy NAT Gateway** and rises only on SNAT port exhaustion. | **Yes** - the leading SNAT-exhaustion signal. Zero is the healthy state, not absence. | | `natGateways` / `SNATConnectionCount` (with `ConnectionState`) | Always present once the subnet sends outbound traffic. The `ConnectionState` dimension splits attempted / failed connections. | **Yes** - the primary outbound-saturation signal. | | `privateEndpoints` / `PEBytesIn`, `PEBytesOut` | Only when traffic actually traverses the Private Endpoint - which requires the consumer to resolve the PaaS FQDN to the PE private IP via a linked Private DNS Zone. | **Yes** - the private-link volume signal. Asymmetric In-vs-Out is normal and reflects the workload's read/write mix. | | Public IP **DDoS family** (`BytesDroppedDDoS`, `IfUnderDDoSAttack`, `PacketsInDDoS`, ...) | Only with a **DDoS Protection Standard** plan attached (~$3k/mo). | **Not in this whitelist.** Add the DDoS metrics and the resource-scope DDoS log categories only if you run the plan. | Choose the network design for the workload, not for telemetry. The practical reading: if you run a NAT Gateway for outbound, your signal is on `natGateways` plus `networkInterfaces`; the NAT-fronting Public IP is plumbing you will not see in metrics. If you front a VM directly with a Public IP, you get coarse byte/packet counts on that IP but the NIC namespace remains the better throughput vantage. If you front a Standard Load Balancer, `SynCount` and `VipAvailability` come alive - but that is the Load Balancer guide's territory. ### Receiver configuration Drop this into your existing collector. The receiver, resource processor, and pipeline are all keyed `/network` so they coexist with other Azure receivers under one collector and one Scout exporter. The four Network namespaces are **not currently known to exhibit receiver bug #45942** (the case-mismatched-dimensions bug seen on `Microsoft.ApiManagement/service`, `Microsoft.Network/azureFirewalls`, and a subset of `Microsoft.Storage` metrics on `azuremonitorreceiver` v0.151.0). These four namespaces emit **no `metadata_*` dimensions at all**, so a case-pair collision is structurally impossible and no `transform` processor is required. Re-check on receiver upgrades. ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/network: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} resource_groups: - ${env:NETWORK_RESOURCE_GROUP} services: - Microsoft.Network/publicIPAddresses - Microsoft.Network/networkInterfaces - Microsoft.Network/natGateways - Microsoft.Network/privateEndpoints auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s use_batch_api: false cache_resources: 86400 dimensions: enabled: true metrics: "Microsoft.Network/publicIPAddresses": ByteCount: [Total] PacketCount: [Total] SynCount: [Total] VipAvailability: [Average] "Microsoft.Network/networkInterfaces": BytesSentRate: [Total] BytesReceivedRate: [Total] PacketsSentRate: [Total] PacketsReceivedRate: [Total] "Microsoft.Network/natGateways": SNATConnectionCount: [Total] TotalConnectionCount: [Total] PacketCount: [Total] PacketDropCount: [Total] ByteCount: [Total] DatapathAvailability: [Average] "Microsoft.Network/privateEndpoints": PEBytesIn: [Total] PEBytesOut: [Total] processors: resource/network: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_network, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:NETWORK_REGION}", action: insert} - {key: service.name, value: "${env:NETWORK_SERVICE_NAME}", action: insert} service: pipelines: metrics/network: receivers: [azure_monitor/network] processors: [resource/network, batch] exporters: [otlp_http/b14] ``` The 16-metric whitelist (4 Public IP + 4 NIC + 6 NAT Gateway + 2 Private Endpoint) renames on the OTel side to lowercase snake-cased series with the aggregation appended (for example `Microsoft.Network/natGateways` `ByteCount` `[Total]` becomes the `azure_byte_count_total` series). `ByteCount` and `PacketCount` exist on both `publicIPAddresses` and `natGateways`; the receiver tags every datapoint with `azuremonitor.resource_id` to keep the per-resource split, so a NAT Gateway's `ByteCount` and a Public IP's `ByteCount` never collide downstream. > **No fixed `cloud.resource_id` on the resource processor.** This > set scrapes four different resource types under one receiver. The > receiver auto-injects `azuremonitor.resource_id` on each datapoint > with the correct per-resource ID. Hard-coding `cloud.resource_id` > from a single env var would tag every series with the same ID and > break the per-resource split downstream. Leave it off the resource > processor whenever the receiver covers more than one resource type > (the same rule applies to the Compute and App Service guides). ### Authentication and RBAC The collector authenticates to Azure Monitor as a service principal holding **`Monitoring Reader`** at the **resource group** containing the network resources. Resource-group scope is the minimum necessary; subscription scope works but is broader than needed. ```bash az role assignment create \ --assignee "$AZURE_CLIENT_ID" \ --role "Monitoring Reader" \ --scope "$(az group show --name --query id -o tsv)" ``` `Monitoring Reader` is sufficient for the metrics path. The collector never touches a data plane - it cannot open a socket through the NAT Gateway, read packets off a NIC, or send traffic through a Private Endpoint. None of the `Network Contributor` or data-plane-equivalent roles are required. The logs path adds a separate auth requirement at subscription scope - see [Logs](#logs). Two propagation delays apply to the metrics path after first assignment: 1. **Control-plane RBAC propagation** - typically 60-300 seconds before the receiver's `metricDefinitions` and `metrics` REST calls succeed. The receiver retries on its 60-second poll cycle. 2. **First-poll metric-definitions race** - Azure Monitor's `metricDefinitions` catalog can take 60-180 seconds to populate after a freshly-deployed network resource reaches `provisioningState: Succeeded`. The receiver caches an empty list if it polls during that window. Mitigation: restart the collector 3-5 minutes after the resources reach `Succeeded` **and** traffic has started, or accept the delay and the next poll cycle picks up the populated catalog. ### What you'll monitor The tables below are keyed by the Azure metric name (the authoritative name from Microsoft's supported-metrics reference). The receiver emits each as a lowercase snake-cased `azure_*` series with the aggregation suffixed. Every series is traffic-gated. #### Public IPs (`Microsoft.Network/publicIPAddresses`) | Azure metric | Aggregation | Use case | | --- | --- | --- | | `ByteCount` | Total | Bytes through the Public IP. **Emits only on a plain VM front end carrying direct inbound. Silent when the Public IP fronts a NAT Gateway** - that traffic is on the NAT Gateway namespace. | | `PacketCount` | Total | Packets through the Public IP. Same plain-VM-front-end-only behaviour as `ByteCount`. | | `SynCount` | Total | TCP SYN count. Emits only behind a Standard Load Balancer front end - never on NAT or plain VM attachment. | | `VipAvailability` | Average | Data-path availability of the VIP. Emits only behind a Standard Load Balancer front end. | Read this namespace as low-signal by design for NAT and plain-VM topologies. Its purpose in this set is completeness and the Load-Balancer-front-end case; the byte/packet counters here are not an alerting signal in a NAT design. #### Network Interfaces (`Microsoft.Network/networkInterfaces`) | Azure metric | Aggregation | Use case | | --- | --- | --- | | `BytesSentRate` | Total | NIC egress throughput. Strong signal whenever the attached VM passes traffic. | | `BytesReceivedRate` | Total | NIC ingress throughput. The primary per-VM network-volume vantage. | | `PacketsSentRate` | Total | NIC egress packet rate. Pairs with `BytesSentRate` to derive average packet size. | | `PacketsReceivedRate` | Total | NIC ingress packet rate. | > **Private Endpoints inject their own NICs.** Every Private Endpoint > creates an auto-generated `Microsoft.Network/networkInterfaces` > resource. That PE NIC is **metric-silent by design** - it publishes > no Azure Monitor series. Expect the NIC resource count to exceed > your VM count by the number of Private Endpoints in scope. When > correlating NIC throughput to a VM, select the NIC whose > `virtualMachine` property is set; the PE NICs have a nil > `virtualMachine` and no series. This is expected and needs no > filter - the PE NICs simply contribute nothing to the metrics > pipeline. #### NAT Gateways (`Microsoft.Network/natGateways`) | Azure metric | Aggregation | Use case | | --- | --- | --- | | `SNATConnectionCount` | Total | Outbound SNAT connections. Carries a `ConnectionState` dimension (attempted / failed) and a `Protocol` dimension. **The primary outbound-saturation signal.** | | `TotalConnectionCount` | Total | Total active connections through the NAT Gateway. | | `PacketCount` | Total | Packets through the NAT Gateway (the outbound-path counterpart to the silent NAT-attached Public IP). | | `PacketDropCount` | Total | Dropped packets. **Sits at zero on a healthy NAT Gateway and rises only on SNAT port exhaustion.** Any sustained non-zero value is actionable. | | `ByteCount` | Total | Bytes through the NAT Gateway. The outbound volume vantage. | | `DatapathAvailability` | Average | NAT Gateway data-path availability. | `PacketDropCount` at zero is the **healthy** state, not an absent series - the NAT Gateway always reports it once the subnet sends outbound traffic. SNAT port exhaustion is the NAT-Gateway-specific failure mode; see [Alert tuning](#alert-tuning). #### Private Endpoints (`Microsoft.Network/privateEndpoints`) | Azure metric | Aggregation | Use case | | --- | --- | --- | | `PEBytesIn` | Total | Bytes into the Private Endpoint (from the consumer toward the PaaS resource). | | `PEBytesOut` | Total | Bytes out of the Private Endpoint (PaaS resource back to the consumer). | > **Private Endpoint metrics require the DNS link to be correct.** > `PEBytesIn` / `PEBytesOut` count only traffic that actually > traverses the Private Endpoint. The consumer must resolve the linked > PaaS FQDN (for example `.blob.core.windows.net`) to the > PE's private IP, which requires a Private DNS Zone (for example > `privatelink.blob.core.windows.net`) linked to the consumer's VNet. > Without that link the consumer resolves the resource's public > endpoint, the application keeps working, and the PE metrics stay at > zero because no traffic crosses the PE. An In-vs-Out asymmetry is > normal and reflects the workload's read/write mix. Service Endpoints > have **no equivalent metrics at all** - PE metrics exist only for > Private Endpoints. #### Operations notes - **Idle and detached resources publish nothing.** A reserved-but-idle Public IP, a NIC on a stopped VM, a NAT Gateway on a quiet subnet, and a Private Endpoint with no traffic all emit zero or absent series. This is expected; do not alert on absence alone for these resource types. - **`SynCount` / `VipAvailability` need a Standard Load Balancer.** They never emit on NAT-attached or plain VM Public IPs. If you need these, the resource you actually care about is a Load Balancer - see the [Load Balancer guide](./load-balancer.md). - **NAT Gateway vs Load Balancer outbound.** SNAT exhaustion metrics live on `natGateways` only when the subnet's outbound path is a NAT Gateway. If outbound is via a Load Balancer outbound rule instead, the SNAT signal is on the Load Balancer namespace - the network-path story moves with the design. - **DDoS metrics are plan-gated.** The Public IP DDoS family (`BytesDroppedDDoS`, `IfUnderDDoSAttack`, and so on) and the resource-scope DDoS log categories require a DDoS Protection Standard plan (~$3k/mo). They are intentionally absent from this whitelist; add them only if you run the plan. ### Cardinality control These four namespaces emit a small, bounded dimension set and **no `metadata_*` dimensions at all**, so cardinality is low and predictable. The only fan-out vector is the `ConnectionState` / `Protocol` split on the NAT Gateway's `SNATConnectionCount`. | Attribute | Source | Cardinality | | --- | --- | --- | | `azuremonitor.resource_id` | Receiver | One per network resource (low). | | `name` | Receiver | One per resource. | | `resource_group` | Receiver | One per RG. | | `type` | Receiver | Constant per namespace (four values). | | `location` | Receiver | One per region. | | `ConnectionState`, `Protocol` | Azure Monitor (NAT `SNATConnectionCount` only) | A few values (attempted / failed; TCP / UDP). Bounded - not a fan-out risk. | A resource group with 10 VMs (10 NICs), one NAT Gateway, its Public IP, and 5 Private Endpoints (5 metric-silent PE NICs) lands at roughly: - Public IP: 1 resource, mostly silent on NAT topology - ~0-2 datapoints/scrape. - NICs: 10 VM NICs x 4 series = 40 datapoints/scrape (the 5 PE NICs contribute nothing). - NAT Gateway: 1 resource x 6 series, with `SNATConnectionCount` split by `ConnectionState` - ~8 datapoints/scrape. - Private Endpoints: 5 resources x 2 series = 10 datapoints/scrape. Total: roughly 60 datapoints/scrape per minute - negligible against Scout's default capacity for any reasonable plan. Network primitives are one of the lowest-cardinality Azure surfaces. ### Alert tuning Network-primitive alerting centres on the **outbound path** (NAT Gateway) and **per-VM throughput** (NIC). The Public IP namespace is not an alerting surface in NAT or plain-VM topologies. #### NAT Gateway - SNAT port exhaustion SNAT port exhaustion is the single most important network-primitive failure mode and the one customers hit in production. The exhaustion signature is a rising failed-state `SNATConnectionCount` together with a non-zero, rising `PacketDropCount`. | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **SNAT connection failures** | `SNATConnectionCount` filtered to the `ConnectionState` = failed dimension | > 0 sustained / 5m | rising trend / 5m | A healthy NAT Gateway has near-zero failed connections. Any sustained failed-state count means the SNAT port pool is under pressure. Add NAT Gateway public IPs or a Public IP Prefix to expand the port pool. | | **Packet drop** | `PacketDropCount` | > 0 / 5m | rising trend / 5m | Zero is the healthy state. Non-zero means SNAT ports are exhausted and connections are being dropped. This is a hard customer-facing failure - treat any sustained non-zero value as critical. | | **Datapath availability** | `DatapathAvailability` | < 100% / 5m | < 99% / 5m | The NAT Gateway data path itself degrading. Rare; an Azure-side issue rather than a workload one. | | **Outbound volume anomaly** | `ByteCount` rate | configurable | configurable | Alert on absolute byte/sec deltas over a baseline rather than fixed thresholds. Useful for catching a runaway egress process or a data-exfiltration anomaly. | #### NIC - throughput saturation | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **Egress saturation** | `BytesSentRate` | > 70% of the VM SKU's network cap / 5m | > 85% / 5m | Each VM SKU has a documented network bandwidth cap (for example a D2s_v3 caps around 1 Gbps). Compute the threshold against the SKU's published cap. | | **Ingress saturation** | `BytesReceivedRate` | > 70% of cap / 5m | > 85% / 5m | Same SKU-cap reasoning as egress. | | **Packet-rate anomaly** | `PacketsSentRate` / `PacketsReceivedRate` | configurable | configurable | A high packet rate with low byte rate indicates many tiny packets (chatty protocol, SYN flood, or a misbehaving client). Derive average packet size from the byte/packet ratio at the query layer. | #### Private Endpoint - volume and continuity | Signal | Source metric | Warning | Critical | Notes | | --- | --- | --- | --- | --- | | **Traffic stopped** | `PEBytesIn` + `PEBytesOut` | sustained zero during expected-traffic window | sustained zero / 15m | A Private Endpoint that was carrying traffic and goes to zero during a window you expect activity often means a DNS regression (the consumer started resolving the public endpoint) or a connection-approval state change. Cross-check the Private DNS Zone link and the PE connection state. | The Public IP namespace has no recommended alert rule for NAT or plain-VM topologies. If your Public IP fronts a Standard Load Balancer, `VipAvailability` and `SynCount` become meaningful - that alerting is covered in the [Load Balancer guide](./load-balancer.md). ### Host and app-side network telemetry The metrics in this guide describe the network primitives at the Azure platform layer - the NIC, the NAT Gateway, the Private Endpoint as resources. They do not describe per-process or per-connection network behaviour inside the VM. For that vantage: - **In-guest host network counters** via the OTel [hostmetricsreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/hostmetricsreceiver) running on the VM (the `network` scraper), or Azure Monitor Agent with a Data Collection Rule. This gives per-interface, per-protocol, and connection-state counters from inside the OS - depth the platform-layer NIC metrics cannot reach. See the [Azure Compute guide](./compute.md) for the in-guest collector pattern. - **App-side network telemetry** via the OTel auto-instrumentation agents for Java, .NET, Python, Node.js, or Go. The agents emit client/server spans with peer addresses and latencies, which is the right vantage for "which downstream call is slow" rather than "is the NIC saturated". See the per-language guides under `instrument/{language}/`. These are complementary vantages, not alternatives: the platform-layer metrics in this guide tell you whether the network path is healthy; the in-guest and app-side telemetry tell you which process and which code path is responsible for the traffic. This guide ships the platform-layer path end to end; the host and app-side paths are cross-links, not validated here. ### Logs Resource-level metrics aggregate counters at 1-minute granularity. They cannot answer **who** attached or detached a Public IP, **who** approved a Private Endpoint connection, **when** a NAT Gateway was bound to or unbound from a subnet, **from where**, **with what identity**, or **why**. Three operational gaps the network control-plane Activity Log fills where metrics cannot: - **Per-operation control-plane audit** records each Public IP associate/disassociate, Private Endpoint connection approval or rejection, NAT Gateway subnet binding change, and NIC attach/detach, with the requester's identity (UPN, app ID, OID), source IP, correlation ID, and result status. The metrics path sees throughput drop to zero on a disassociation but cannot attribute the action. - **Per-resource lifecycle** preserves the create / update / delete history of every network primitive, useful for change diagnostics ("when did this Private Endpoint connection get re-approved", "who moved the NAT Gateway off this subnet last Tuesday") and capacity audits. - **Cross-provider correlation** is available in the same Activity Log stream - the network changes that accompany a VM resize or a VMSS scale event appear alongside the Compute records. The default filter scopes to `Microsoft.Network`; broaden it (see [Filter expression](#filter-expression-broadening-and-narrowing)) when you need correlated forensics across providers. Network primitive resource types do **not** expose useful per-resource Diagnostic Settings categories. `publicIPAddresses` has DDoS-only categories that require a DDoS Protection Standard plan; `networkInterfaces`, `natGateways`, and `privateEndpoints` have none. The control-plane audit signal lives in the **subscription-scope** Activity Log instead. This is the same shape as the [Compute](./compute.md) logs path, and the meaningful difference from the resource-scope Diagnostic Settings used by [Storage](./storage.md) and [Key Vault](./key-vault.md). The recommended pattern is **subscription Activity Log to Event Hubs to `azure_event_hub` plus a `filter` processor** in the same collector. The receiver ingests events as OTel logs, the filter scopes to `Microsoft.Network` records only, and the resource processor tags them with `cloud.platform: azure_network`. Everything routes to Scout via the same `oauth2client` / `otlp_http/b14` pipeline used for metrics. ```yaml showLineNumbers title="otel-collector.yaml (logs excerpt)" receivers: azure_event_hub/networklogs: connection: ${env:NETWORKLOGS_CONNECTION_STRING} partition: "" offset: "" format: azure apply_semantic_conventions: true processors: filter/networkonly: error_mode: ignore logs: log_record: - 'resource.attributes["cloud.resource_id"] == nil' - 'not IsMatch(resource.attributes["cloud.resource_id"], ".*/[Mm][Ii][Cc][Rr][Oo][Ss][Oo][Ff][Tt]\\.[Nn][Ee][Tt][Ww][Oo][Rr][Kk]/.*")' resource/networklogs: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_network, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: service.name, value: "${env:NETWORKLOGS_SERVICE_NAME}", action: insert} service: pipelines: logs/networklogs: receivers: [azure_event_hub/networklogs] processors: [filter/networkonly, resource/networklogs, batch] exporters: [otlp_http/b14] ``` The `connection` string must include the `EntityPath=` suffix so the receiver knows which hub to consume. The receiver defaults to consuming all partitions from the oldest available offset (`partition: ""`, `offset: ""`); on collector restart it re-reads from the saved offset, providing at-least-once delivery. > **Why the filter expression looks so paranoid.** The > `azure_event_hub` receiver with `format: azure` plus > `apply_semantic_conventions: true` places the per-record Azure > resource ID at `resource.attributes["cloud.resource_id"]` (OTel > semantic-conventions form, **not** `azure.resource.id`), and > UPPERCASES it. The filter regex matches case-insensitively against > `[Mm]icrosoft\.[Nn]etwork` to handle the inconsistency and protect > against future Azure-side changes. The first rule > (`resource.attributes["cloud.resource_id"] == nil`) drops records > that arrive without a resource ID at all. Together the two rules > pass only records with a `Microsoft.Network` provider segment and > drop everything else. #### Wiring the subscription Diagnostic Setting Subscription-scope Diagnostic Settings use a different `az` subcommand than resource-scope: `az monitor diagnostic-settings subscription create`. Three flag-name differences from resource-scope: | Resource-scope (Storage, Key Vault, etc.) | Subscription-scope (this guide) | | --- | --- | | `--event-hub ` | `--event-hub-name ` | | `--event-hub-rule ` | `--event-hub-auth-rule ` | | (no location flag) | `--location global` | ```bash az monitor diagnostic-settings subscription create \ --name network-activity-log \ --location global \ --event-hub-name "$EVENT_HUB_NAME" \ --event-hub-auth-rule "$DIAG_SEND_RULE_ARM_ID" \ --logs '[{"category":"Administrative","enabled":true}]' ``` The `--event-hub-auth-rule` value is the full ARM resource ID of a namespace-level SAS authorization rule with `Send` rights. Microsoft's documentation is imprecise on the flag name (`--event-hub-auth-rule-id` is rejected on `az` CLI 2.85.0); use `--event-hub-auth-rule`. The `Administrative` category covers `create`, `update`, `delete`, associate, disassociate, and similar control-plane operations across **every** resource provider in the subscription - including the Public IP, NIC, NAT Gateway, and Private Endpoint operations this guide cares about. The collector-side filter then scopes it to `Microsoft.Network`. Other categories (`Security`, `ServiceHealth`, `Alert`, `Recommendation`, `Policy`, `Autoscale`, `ResourceHealth`) are typically routed elsewhere - see [Why not other categories](#why-not-other-categories). #### Auth for the subscription Diagnostic Setting Creating a subscription-scope Diagnostic Setting requires **`Monitoring Contributor`** at **subscription scope**. This is broader than the metrics path's `Monitoring Reader` at RG scope, and a deliberate split: the role lives on the **operator's signed-in user identity** (a human Microsoft Entra ID account), not on the long-lived service principal that the collector uses for the metrics path. ```bash OPERATOR_OID="$(az ad signed-in-user show --query id -o tsv)" az role assignment create \ --assignee-object-id "$OPERATOR_OID" \ --assignee-principal-type User \ --role "Monitoring Contributor" \ --scope "/subscriptions/$AZURE_SUBSCRIPTION_ID" ``` The role assignment is permanent unless revoked. Operators who manage compliance boundaries can revoke it once the Diagnostic Setting is in place: ```bash az role assignment delete \ --assignee "$OPERATOR_OID" \ --role "Monitoring Contributor" \ --scope "/subscriptions/$AZURE_SUBSCRIPTION_ID" ``` After revocation, the subscription Diagnostic Setting continues to ship records to Event Hubs; modifying it later requires re-granting the role. #### Diagnostic Settings ship cadence Azure batches subscription Activity Log records and ships them to Event Hubs on a non-real-time cadence. Subscription-scope routing is slower than resource-scope: - **First batch from a freshly-wired subscription Diagnostic Setting: 10-40 minutes.** Resource-scope Diagnostic Settings ship the first batch within 5-20 minutes; subscription-scope routing adds a hop and stretches the upper bound. Plan for 40 minutes and do not treat an empty pipeline in that window as a failure. - **Steady-state batches: 5-15 minutes.** - **End-to-end latency from operation to Scout: 5-15 minutes steady-state, 10-40 minutes for the first batch.** Audit visibility is **not** real-time. For real-time control-plane security monitoring, use Microsoft Defender for Cloud or Azure Sentinel. The OTel path is appropriate for audit retention, compliance reporting, and forensic analysis where per-event minutes-of-lag is acceptable. #### Filter expression: broadening and narrowing The subscription Activity Log spans **every** resource provider in the subscription, while the filter passes only `Microsoft.Network` records. On any real subscription the filter drops the large majority of records - that is normal and the filter is doing real work. Even a network-focused resource group also holds `Microsoft.Compute` (the VMs whose NICs you monitor), `Microsoft.Storage` (Private Endpoint targets), and `Microsoft.EventHub` (this sink), all of which produce Activity Log records the filter drops. To **broaden** the filter to additional providers, add them to the regex alternation: ```yaml - 'not IsMatch(resource.attributes["cloud.resource_id"], ".*/(?:[Mm]icrosoft\\.[Nn]etwork|[Mm]icrosoft\\.[Cc]ompute)/.*")' ``` To **narrow** to specific network operations, add a second rule on the operation name: ```yaml filter/networkonly: error_mode: ignore logs: log_record: - 'resource.attributes["cloud.resource_id"] == nil' - 'not IsMatch(resource.attributes["cloud.resource_id"], ".*/[Mm][Ii][Cc][Rr][Oo][Ss][Oo][Ff][Tt]\\.[Nn][Ee][Tt][Ww][Oo][Rr][Kk]/.*")' # Drop everything except associate/disassociate/write/delete ops - 'not IsMatch(attributes["azure.operation.name"], ".*(?i:write|delete|join|action)$")' ``` #### Why not other categories - **`Security`** records Defender / Sentinel alerts. These flow through dedicated security pipelines rather than the OTel logs path. - **`ServiceHealth`** records Azure service-health events. Better routed through Azure Service Health alerts or a separate service-health-only Diagnostic Setting. - **`Alert`** records firings of Azure Monitor alert rules. Routing alert firings back through the Activity Log creates feedback loops. - **`Recommendation`** is Azure Advisor output - not real-time operational telemetry. - **`Policy`** records Azure Policy compliance evaluations - belongs in a compliance pipeline. - **`Autoscale`** records autoscale rule firings. Re-enable it if you correlate autoscale events (which churn NICs and Public IPs) with network control-plane audit. - **`ResourceHealth`** records per-resource health-state changes. Worth enabling as a follow-on once network audit is in place - Private Endpoint and NAT Gateway health transitions show up here. ### Troubleshooting #### Empty scrape on a resource that exists Symptom: the receiver discovers the Public IP / NIC / NAT Gateway / Private Endpoint but emits no datapoints for it. Cause: every metric on these namespaces is traffic-gated. An idle Public IP, a NIC on a stopped VM, a NAT Gateway on a quiet subnet, or a Private Endpoint with no traffic publishes nothing. Fix: confirm traffic is actually flowing before treating this as a fault. This is expected behaviour, not a receiver, whitelist, or RBAC problem. #### Public IP publishes no byte/packet metrics Symptom: a Public IP resource is discovered but `ByteCount` / `PacketCount` stay empty. Cause: the Public IP is attached to a NAT Gateway, which accounts that traffic on the `natGateways` namespace instead - a NAT-fronting Public IP is metric-silent by design. Fix: read the outbound signal off `Microsoft.Network/natGateways` (`ByteCount`, `PacketCount`, `SNATConnectionCount`). The Public IP namespace only emits byte/packet counts on a plain VM front end. #### NIC count exceeds VM count Symptom: `resources_count` reports more NICs than you have VMs, and the extra NICs emit nothing. Cause: every Private Endpoint injects an auto-created NIC that is metric-silent by design. Fix: this is expected. When correlating NIC throughput to a VM, select the NIC whose `virtualMachine` property is set; the PE NICs have a nil `virtualMachine` and contribute no series. #### Private Endpoint metrics are zero but the app works Symptom: `PEBytesIn` / `PEBytesOut` stay at zero while the application successfully reaches the PaaS resource. Cause: the consumer is resolving the resource's public endpoint, not the Private Endpoint private IP, so traffic never crosses the PE. Fix: confirm a Private DNS Zone (for example `privatelink.blob.core.windows.net`) is linked to the consumer's VNet and that the PaaS FQDN resolves to a private VNet address from inside the consumer subnet (`dig +short .blob.core.windows.net` should return a private VNet address, not a public one). #### `metrics_definitions_count: 0` on first poll after provisioning Symptom: the receiver logs `metrics_definitions_count: 0` and emits no metrics for one or more network resources. Cause: Azure Monitor's `metricDefinitions` catalog has not yet populated for the freshly-deployed resource, or the resource has not yet carried traffic. Fix: ensure traffic is flowing, then restart the collector after the resources have been up for at least 3 minutes, OR wait and the next 60-second poll picks up the now-populated catalog. #### `AuthorizationFailed` from the receiver in the first 60 seconds Symptom: the receiver logs `AuthorizationFailed` or `403` shortly after provisioning. Cause: `Monitoring Reader` was granted but Azure RBAC is still propagating. Fix: wait 60-300 seconds; the receiver retries on its next poll cycle. If it persists past 5 minutes, verify the assignment with `az role assignment list --assignee --scope `. #### Network logs path: empty Event Hubs for 30+ minutes Symptom: `azure_event_hub/networklogs` reports zero events for the first 30 or more minutes after the subscription Diagnostic Setting is created. Cause: subscription-scope Diagnostic Settings ship the first batch on a 10-40 minute cadence. Fix: wait. Subsequent batches arrive in 5-15 minutes. Verify the Diagnostic Setting with `az monitor diagnostic-settings subscription show --name network-activity-log`. #### Filter processor drops all log records Symptom: `filter/networkonly` shows incoming records but `outgoing_items_total` stays at zero. Cause: the receiver places the resource ID at `resource.attributes["cloud.resource_id"]`, not `azure.resource.id`, and UPPERCASES it. A filter expression targeting the wrong attribute name or doing a case-sensitive match drops every record. Fix: use the filter shape in this guide, which checks `resource.attributes["cloud.resource_id"]` case-insensitively. #### Subscription Diagnostic Setting rejects `--event-hub-auth-rule-id` Symptom: `az monitor diagnostic-settings subscription create` fails with `unrecognized arguments: --event-hub-auth-rule-id`. Cause: the flag is `--event-hub-auth-rule` (no `-id` suffix) on `az` CLI 2.85.0. Fix: use `--event-hub-auth-rule "$DIAG_SEND_RULE_ARM_ID"` exactly. #### Scout OAuth2 returns 401 Symptom: the `oauth2client` extension logs 401 from the token endpoint. Cause: stale `SCOUT_CLIENT_ID` / `SCOUT_CLIENT_SECRET` / `SCOUT_TOKEN_URL`. Fix: re-source the Scout credential env file (or the equivalent secret store) and restart the collector. ### Frequently Asked Questions #### How do I monitor Azure network primitives with OpenTelemetry? Add the `azure_auth` extension and a single `azure_monitor` receiver with four namespaces under `services:` - `Microsoft.Network/publicIPAddresses`, `Microsoft.Network/networkInterfaces`, `Microsoft.Network/natGateways`, and `Microsoft.Network/privateEndpoints` - route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter, and grant the collector's service principal `Monitoring Reader` at the resource group containing the network resources. The receiver polls Azure Monitor every 60 seconds. Every metric on these namespaces is traffic-gated: an idle Public IP, a detached NIC, an unused NAT Gateway, or a Private Endpoint carrying no traffic publishes nothing, which is expected and not a misconfiguration. #### Why does my Public IP publish almost no metrics? The `Microsoft.Network/publicIPAddresses` namespace is the weak member of this set. A Public IP attached to a NAT Gateway publishes no byte or packet metrics at all - that traffic is accounted on the `Microsoft.Network/natGateways` namespace instead. A Public IP used as a plain VM front end emits only `ByteCount` and `PacketCount`, and only while it carries direct inbound traffic. `SynCount` and `VipAvailability` emit only behind a Standard Load Balancer front end, never on a NAT-attached or plain VM Public IP. The operationally meaningful network-path signal in this set lives on `natGateways`, `networkInterfaces`, and `privateEndpoints`; treat `publicIPAddresses` as low-signal by design and do not build alerts on it for NAT or plain-VM topologies. #### My receiver discovers more NICs than I have VMs. Why? Every Private Endpoint injects its own auto-created network interface into the resource group. That PE NIC is a real `Microsoft.Network/networkInterfaces` resource but it publishes no Azure Monitor metrics - it is metric-silent by design. Expect the NIC resource count to exceed your VM count by the number of Private Endpoints in scope. When correlating NIC throughput to a VM, select the NIC whose `virtualMachine` property is set; the PE NICs have a nil `virtualMachine` and no series. This is expected and needs no filter. #### How do I alert on NAT Gateway SNAT port exhaustion? SNAT port exhaustion is the NAT-Gateway-specific failure mode. Watch `SNATConnectionCount` split by its `ConnectionState` dimension - a rising count in the failed state, together with a non-zero and rising `PacketDropCount`, is the exhaustion signature. `PacketDropCount` sits at zero on a healthy NAT Gateway and rises only when SNAT ports are exhausted, so any sustained non-zero value is actionable. If your outbound path uses a Load Balancer rather than a NAT Gateway, SNAT metrics live on the Load Balancer namespace instead - see the [Azure Load Balancer guide](./load-balancer.md). #### Why are my Private Endpoint metrics zero even though the app works? `PEBytesIn` and `PEBytesOut` count only traffic that actually traverses the Private Endpoint. They emit only when the consumer resolves the linked PaaS FQDN to the Private Endpoint's private IP, which requires a Private DNS Zone (for example `privatelink.blob.core.windows.net`) linked to the consumer's VNet. Without that DNS link the consumer resolves the resource's public endpoint, the application still works, and the Private Endpoint metrics stay at zero because no traffic crosses the PE. Confirm the VNet DNS link and that the FQDN resolves to a private VNet address from inside the consumer subnet. Service Endpoints have no equivalent metrics at all - PE metrics exist only for Private Endpoints. #### How do I audit who attached a Public IP or approved a Private Endpoint connection? Network primitive resource types do not expose per-resource Diagnostic Settings categories (aside from DDoS categories on Public IPs that require a DDoS Protection Standard plan). The control-plane audit signal lives in the subscription-scope Activity Log. Configure a subscription Diagnostic Setting forwarding the `Administrative` category to an Event Hubs hub, point the `azure_event_hub` receiver at the hub, and apply a collector-side `filter` processor scoped to `cloud.resource_id` matching `Microsoft.Network`. The subscription Activity Log spans every resource provider, so a large fraction of records is dropped by the filter - that is expected and the filter is doing real work. Subscription-scope routing is not real-time; plan for 10-40 minutes to the first batch and 5-15 minutes steady-state. ### Reference - [Microsoft.Network/publicIPAddresses supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-publicipaddresses-metrics) - [Microsoft.Network/networkInterfaces supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-networkinterfaces-metrics) - [Microsoft.Network/natGateways supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-natgateways-metrics) - [Microsoft.Network/privateEndpoints supported metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-network-privateendpoints-metrics) - [NAT Gateway SNAT and port exhaustion](https://learn.microsoft.com/azure/nat-gateway/nat-gateway-resource) - [Azure Monitor Activity Log schema](https://learn.microsoft.com/azure/azure-monitor/essentials/activity-log-schema) - [Subscription Diagnostic Settings reference](https://learn.microsoft.com/azure/azure-monitor/essentials/activity-log#diagnostic-settings) - [opentelemetry-collector-contrib azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - [opentelemetry-collector-contrib azureeventhubreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azureeventhubreceiver) ### Related Guides - [Azure Monitoring with OpenTelemetry - Architecture](./overview.md) - start here for the cross-surface story. - [Azure Load Balancer](./load-balancer.md) - the L4 outbound and front-end alternative to a NAT Gateway; `SynCount` and `VipAvailability` on a Public IP belong to this surface. - [Azure Compute](./compute.md) - the VMs behind the NICs in this set; the in-guest `hostmetrics` network counters and the subscription-scope Activity Log path are companions to this guide. - [Azure Storage](./storage.md) - a common Private Endpoint target; resource-scope Diagnostic Settings logs path counterpart to this guide's subscription-scope path. - [Azure Application Gateway](./application-gateway.md) - WAF + L7 load balancer that often fronts the same VNet-internal workloads. --- ## Azure Monitoring with OpenTelemetry - Architecture for base14 Scout ### Overview This guide is the architectural landing for monitoring Azure infrastructure with **base14 Scout** through the **OpenTelemetry Collector**. It explains how Scout consumes signals from Azure Monitor, what to expect on freshness and limits, where Workload Identity Federation fits, and what is and is not in scope (the trace gap, in particular). For execution, jump to the per-surface guides linked below. The reader profile is **DevOps and SRE engineers** running production Azure workloads, evaluating or operating Scout, who want to understand the shape of the pipeline before configuring it for any of the Azure surfaces covered in the per-surface guides below. :::tip TL;DR base14 Scout consumes Azure telemetry through two parallel paths and production deployments typically run **both**. **Metrics pull** via the `azure_monitor` receiver against Azure Monitor's REST API, and a **metrics-and-logs push** via Diagnostic Settings to Event Hubs, consumed by the `azure_event_hub` receiver. Authentication is via the `azureauthextension`; Workload Identity Federation is the recommended default where the runtime supports it, with managed identity, service principal, and default-credential chain also supported. Metric freshness is a few minutes when pulling from the Metrics REST API (3-minute export floor plus your scrape interval) and single-digit seconds when consuming from Event Hubs. Azure infrastructure resources do not emit distributed traces; instrument your application with the Azure Monitor OpenTelemetry Distro to get traces into Scout. ::: ### The Azure observability landscape Every Azure resource emits two signal types natively: - **Platform metrics** - time-series numeric data (CPU, RU consumption, request rates, latency percentiles). Stored in the Azure Monitor metrics database. Available without configuration. Free at the platform tier. - **Resource logs** - structured event data (audit, query store, WAF blocks, AKS control-plane events). Off by default; enabled per-resource via Diagnostic Settings. Billed at the destination (Log Analytics, Event Hubs, or Storage). Activity logs (subscription-level control-plane events: deployments, RBAC changes, policy assignments) are a third signal in the same family, collected automatically and exported via Diagnostic Settings. There is a fourth signal Azure does not emit at the infrastructure layer: **distributed traces**. Traces in the Azure ecosystem come from your application code, not from the managed services it talks to. We cover the implications in [What about traces?](#what-about-traces) below. Microsoft's [Application Insights overview](https://learn.microsoft.com/en-us/azure/azure-monitor/app/app-insights-overview) recommends the Azure Monitor OpenTelemetry Distro for code-based server-side instrumentation: "For most code-based server-side scenarios, the recommended setup uses the Azure Monitor OpenTelemetry Distro." That puts customer applications on OTel-shaped emission natively. Scout is the OTel-native destination such applications can target without going through Azure Monitor as a middleman. The vendor-neutral pipeline this guide describes makes that destination swap a configuration change rather than a re-instrumentation. ### Architecture at a glance ```text ┌───────────────────── Azure ────────────────────┐ ┌────── base14 Scout ────────┐ │ │ │ │ │ Per-resource Diagnostic Setting │ │ │ │ ├── push metrics ─┐ │ │ │ │ └── push logs ──┼──▶ Event Hubs namespace │──▶ │ azure_event_hub receiver │ │ │ (per region) │ │ (push, beta) │ │ │ │ │ │ │ │ │ │ azure_monitor receiver │ │ Metrics REST API ◀──┴─────────────────────────┼────│ (pull, alpha) │ │ (use_batch_api: true) │ │ │ │ │ │ azureauthextension │ │ │ │ (alpha; WIF / MI / SP) │ └────────────────────────────────────────────────┘ │ │ │ ───────── OTLP ────────▶ │ │ │ └────────────────────────────┘ ``` Three pieces, one picture: - **`azure_monitor` receiver** polls Azure Monitor's Metrics REST API on a scrape interval. Use the batch API ([`use_batch_api: true`](#limits-throttling-and-cost-framing)) to raise the rate ceiling from 12,000 to 360,000 calls per hour per subscription. - **`azure_event_hub` receiver** consumes from an Event Hubs namespace that Diagnostic Settings pushes into. Decodes Azure Resource Logs and platform metrics from the Event Hub payload (platform metrics arrive as Gauge points with Total / Min / Max / Avg / Count datapoints, per the receiver's [native Azure decoder](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azureeventhubreceiver)); beta stability for both signals. - **`azureauthextension`** holds one identity per shard, federated to the runtime that hosts the collector (most often an AKS service account). Every receiver references it via `auth.authenticator: azure_auth`. Per-surface guides spell out the exact YAML for each piece. ### Authentication The `azureauthextension` supports four authentication methods, all peers from the extension's perspective: **managed identity**, **workload identity** (federated, the case where Microsoft Entra ID trusts a token from an external identity provider), **service principal** with client secret or certificate, and the Azure **default credential** chain. Pick the one that matches how your collector runtime authenticates today. For collectors running in AKS, EKS, GKE, on-prem Kubernetes, GitHub Actions, or any runtime Microsoft Entra ID can federate with, **Workload Identity Federation (WIF)** is the recommended default. It eliminates client secrets entirely, which removes the largest silent-zero failure mode (expired SP secrets are indistinguishable from "no traffic" on dashboards). Microsoft documents the value plainly in [Microsoft Entra Workload Identity Federation](https://learn.microsoft.com/en-us/entra/workload-id/workload-identity-federation): > "These credentials pose a security risk and have to be stored securely > and rotated regularly. You also run the risk of service downtime if the > credentials expire." > > "You eliminate the maintenance burden of manually managing credentials > and eliminates the risk of leaking secrets or having certificates > expire." Service principal with client secret remains fully supported for deployments where federation is not available (e.g., shrink-wrapped on-prem environments, runtimes outside the federation matrix); rotate the secret on a schedule and alarm on expiry. Reference snippet (used by every per-surface guide): ```yaml extensions: azure_auth: workload_identity: client_id: ${env:AZURE_CLIENT_ID} tenant_id: ${env:AZURE_TENANT_ID} federated_token_file: /var/run/secrets/azure/tokens/azure-identity-token receivers: azure_monitor: auth: authenticator: azure_auth # ... rest of config ``` The federated token is short-lived (typically one hour) and renewed automatically by the cluster's projected service account token. There is no expiry alarm because there is no static credential. ### Choosing pull, push, or both | Aspect | Pull (`azure_monitor`) | Push (`azure_event_hub`) | | --- | --- | --- | | **What it consumes** | Metrics REST API | Diagnostic Settings → Event Hubs | | **Stability** | alpha | beta | | **Freshness** | ~3 minutes export + receiver `collection_interval` | Single-digit seconds | | **Volume ceiling** | 360,000 API calls/hour/subscription | Bounded by Event Hubs throughput units | | **Best for** | Slow / definitive metrics; resource types without streaming support; drift detection | High-volume metrics; resource logs; any signal you alert on | | **Per-resource config** | None per resource | One Diagnostic Setting per resource | | **Cost driver** | Free (REST API reads) | Event Hubs namespace + throughput units | The decision rule for a real production deployment is **both**. Pull with `azure_monitor` for the metrics that change slowly (storage size, capacity, billing-class counters) and as the safety net that confirms the pushed data matches Azure's own metrics database. Use the Event Hubs push for the metrics and logs your dashboards and alert rules actually depend on. The largest single resilience improvement available today is adding the Event Hubs push to a pull-only deployment. It cuts REST read volume 5-10x for a typical multi-surface customer, drops alerting freshness to seconds, and unblocks resource log ingestion at the same time. ### Latency expectations by signal End-to-end latency for the signal types Scout consumes from Azure. The platform-metrics (pull) and resource-logs notes quote [Microsoft's published ingestion-time documentation](https://learn.microsoft.com/en-us/azure/azure-monitor/logs/data-ingestion-time); the inactive-backoff note is from the [Diagnostic Settings reference](https://learn.microsoft.com/en-us/azure/azure-monitor/essentials/diagnostic-settings). | Signal | Latency floor | Notes | | --- | --- | --- | | Platform metrics (`azure_monitor` pull) | ~3 minutes export + your scrape interval | "Available in under a minute in the metrics database, but they take another three minutes to be exported to the data collection endpoint" | | Platform metrics (Event Hubs push) | Single-digit seconds | Diagnostic Settings to Event Hubs is push-mode through Microsoft's own pipeline | | Resource logs | 3 to 10 minutes typical | "Azure SQL Database and Azure Virtual Network currently provide their logs every five minutes" | | Activity logs | 3 to 20 minutes | Subscription-level control-plane events | | Inactive resource backoff | up to 15 minutes after 1 hour idle; up to 2 hours after 7 days idle | Diagnostic Settings backs off zero-value emissions to reduce export cost | Two operational consequences worth surfacing in customer dashboards: - **No real-time alerting on resource logs.** Design alert rules with 5-10 minute freshness as the floor for resource logs and 5-25 minutes for activity logs. Real-time alerting needs the Event Hubs push. - **Inactive resource backoff is not a bug.** An idle resource's exported metrics back off incrementally and resume the normal ~3-minute latency once nonzero values return; this affects exported metrics only, not metrics-based alerts or autoscale. Mark expected-idle resources on dashboards so the gap does not page as "data missing". ### Limits, throttling, and cost framing The numbers that drive the design, drawn from [Azure Monitor service limits](https://learn.microsoft.com/en-us/azure/azure-monitor/fundamentals/service-limits), the [Diagnostic Settings reference](https://learn.microsoft.com/en-us/azure/azure-monitor/essentials/diagnostic-settings), and the Metrics Data Plane API behaviour (see the throttling FAQ below). The `Source` column carries the precise per-row attribution: | Limit | Default | With batch API | Source | | --- | --- | --- | --- | | Metrics REST API reads / hour / subscription | 12,000 | 360,000 | Metrics Data Plane API | | Resources per `metrics:getBatch` request | n/a | 50 | Receiver README | | Diagnostic settings per resource | 5 | 5 (max) | Service limits | | Logs Ingestion API requests / minute / DCR | 12,000 | n/a | Service limits | | Log Analytics ingestion volume rate threshold | 500 MB compressed (~6 GB/min uncompressed) | n/a | Service limits | Three constraints worth budgeting around explicitly: - **`use_batch_api: true` is non-negotiable** for any production `azure_monitor` config. The 360,000 calls/hour ceiling is what makes multi-surface monitoring viable; the 12,000 default will throttle on any real estate. - **5 Diagnostic Settings per resource** is a hard cap. Onboarding scripts must check existing settings count before provisioning a new one. If a customer is already on 5, the Scout setting either replaces a duplicate or merges destinations. - **Same-region constraint**: Event Hubs and Storage destinations must be in the same region as the resource being monitored. The recommended topology is **one Event Hubs namespace per region per subscription**, not a single global hub. A multi-region, multi-subscription customer ends up with `R × S` Event Hubs namespaces; each per-surface guide shows the Bicep / IaC for one of them and you fan out from there. - **Networking caveat for VNet-bound destinations**: when an Event Hubs namespace or Storage account has VNet rules enabled, Diagnostic Settings cannot reach it unless the namespace also has **"Allow trusted Microsoft services"** set. The Diagnostic Settings reference flags this explicitly. If your destinations are public-endpoint, this does not apply. - **Diagnostic Settings scope varies by surface.** Most surfaces attach a Diagnostic Setting per resource; a few (Compute, App Service, Logic Apps) use a single subscription-scope setting instead. The per-surface guide states which and gives the exact command. #### Cost framing Sending Azure metrics and logs through Event Hubs adds one new Azure cost and one Scout cost: - **Event Hubs namespace and throughput units.** One throughput unit handles roughly 1 MB/s ingress or ~1,000 events per second; size it to your Diagnostic Settings volume. - **Scout-side ingest**, per the [Scout pricing page](https://base14.io/pricing). An existing Log Analytics workspace kept running alongside costs the same as before: a single Diagnostic Setting can send to a workspace and an Event Hubs namespace at the same time, so the workspace is neither added to nor removed by this setup. ### What about traces? Azure infrastructure resources do **not** emit OpenTelemetry traces. There is no infrastructure-level distributed trace describing, for example, "this Cosmos DB request was served by partition X, replicated to region Y, took 12 ms in the index lookup." That kind of telemetry exists inside Microsoft's fleet but is not exposed to customers in OTel trace format on any documented Azure surface. Distributed traces in the Azure ecosystem come from **application instrumentation**: - **Azure Monitor OpenTelemetry Distro** - Microsoft's recommended path for code-based server-side instrumentation. Outputs OTLP-shaped traces that target Scout directly without going through Azure Monitor. - **Vanilla OpenTelemetry SDKs** for any language Scout's [App Instrumentation guides](/instrument/apps/auto-instrumentation/) cover. - **Application Insights JavaScript SDK** for browser apps - per Microsoft's [overview](https://learn.microsoft.com/en-us/azure/azure-monitor/app/app-insights-overview), the JS SDK is not OpenTelemetry. Browser telemetry is a separate path from this guide. The trace path is therefore: ```text Customer application │ │ instrumented with OTel SDK / Azure Monitor Distro ▼ OTLP traces ───── direct ─────▶ base14 Scout ``` The Azure Monitor pipeline this guide describes is **not in that path**. The per-surface guides cover infrastructure metrics and logs only. The one transitional case where Azure Monitor *does* carry traces is the **Application Insights migration window**: customers transitioning off Application Insights can dual-emit AppRequests and AppDependencies records through Diagnostic Settings to Event Hubs, where the `azure_event_hub` receiver decodes them. This is a bridge during cutover, not a sustainable architecture; the long-term path is the Distro shipping OTLP directly. ### Per-surface guides Pick the guide that matches the resource you're configuring. Each is the execution playbook for that surface, including exact YAML, RBAC scope, metric tables, and surface-specific gotchas. | Surface | What you'll monitor | Guide | | --- | --- | --- | | **Azure Kubernetes Service (AKS)** - in-cluster pattern | Pod / node / cluster-state metrics plus zero-code app auto-instrumentation, via the OTel Operator (DaemonSet + Cluster Deployment + kube-state-metrics) | [AKS guide](./aks.md) | | **AKS via Helm** | Same AKS scope, deployed through the OTel Helm chart | [AKS with Helm guide](./aks-with-helm.md) | | **Azure Compute** | VM, VM Scale Set, and Managed Disk metrics (CPU, network, disk IOPS / bytes, available memory) plus the subscription-scope Activity Log path | [Compute guide](./compute.md) | | **Azure App Service** | Control-plane request and health-check metrics plus HTTP and platform logs | [App Service guide](./app-service.md) | | **Azure Cosmos DB** (SQL / NoSQL API) | RU consumption, request rates, server-side latency, document count, storage, availability | [Cosmos DB guide](./cosmos-db.md) | | **Azure SQL Database** | DTU / vCore utilisation, connections, deadlocks, storage, geo-replication lag | [SQL Database guide](./sql-database.md) | | **Azure Database for PostgreSQL** (Flexible Server) | Platform metrics, in-database scrape (`postgresqlreceiver`), and resource logs | [PostgreSQL guide](./database-for-postgresql.md) | | **Azure Database for MySQL** (Flexible Server) | Platform metrics, in-database scrape (`mysqlreceiver`), and resource logs | [MySQL guide](./database-for-mysql.md) | | **Azure Cache for Redis** | Hit rate, memory pressure, server-load saturation, connection cap, Premium-tier diagnostic logs | [Cache for Redis guide](./cache-for-redis.md) | | **Azure Service Bus** | Active / dead-letter message counts, throughput, request counts, server errors | [Service Bus guide](./service-bus.md) | | **Azure Event Hubs** | Throughput, connections, Capture metrics, partition cardinality | [Event Hubs guide](./event-hubs.md) | | **Azure Logic Apps** (Consumption) | Run / action / trigger lifecycle, billable-execution metrics, per-action workflow logs | [Logic Apps guide](./logic-apps.md) | | **Azure Front Door** (Standard / Premium) | Request count, request size, response size, latency, WAF metrics | [Front Door guide](./front-door.md) | | **Azure Application Gateway** (v2 / WAF_v2) | Throughput, healthy / unhealthy host count, response status, backend latency; WAF_v2 rule matches | [Application Gateway guide](./application-gateway.md) | | **Azure Load Balancer** (Standard SKU) | VIP / DIP availability, SYN count, byte / packet counters, SNAT-port exhaustion | [Load Balancer guide](./load-balancer.md) | | **Azure Firewall** (Standard SKU) | Rule-hit metrics, throughput, SNAT-port utilisation, threat-intel mode | [Azure Firewall guide](./azure-firewall.md) | | **Azure Storage** (Blob / Queue / Table / File) | Multi-namespace transaction, latency, and capacity metrics across sub-services | [Storage guide](./storage.md) | | **Azure API Management** | Gateway and backend latency, request counts, rate-limit attribution, Diagnostic Settings logs | [API Management guide](./api-management.md) | | **Azure Key Vault** | API latency, throttling-proximity saturation, per-secret AuditEvent forensics | [Key Vault guide](./key-vault.md) | Every per-surface guide assumes you have read this overview for the shared concepts (auth, push vs pull, latency, trace gap) and links back here for those topics rather than re-explaining. ### How these guides stay current The OpenTelemetry collector-contrib `azure_monitor` and `azure_event_hub` receivers move quickly, and Microsoft renames or deprecates platform metrics from time to time. Scout tracks both upstream changelogs as part of weekly maintenance, pins the validated contrib image in the example configs, and refreshes per-surface guides when receiver behaviour changes. When you copy a config snippet from a per-surface guide, the version it was validated against is specified - verify behaviour against the versions you run. ### Frequently Asked Questions #### How does base14 Scout consume Azure Monitor metrics? Two ways. The `azure_monitor` receiver pulls from Azure Monitor's REST API on a configurable interval. For higher volume and lower freshness, Diagnostic Settings push metrics to an Event Hubs namespace, where the `azure_event_hub` receiver consumes them and forwards via OTLP to Scout. Most production deployments run both: pull slow or definitive metrics with `azure_monitor`, and consume fast metrics like latency and throttle counters from Event Hubs. #### Do I need to install an agent on my Azure resources? No. Both paths use Azure-native interfaces (Metrics REST API and Diagnostic Settings) that every Azure resource exposes. You run the OpenTelemetry Collector somewhere that can reach those interfaces, typically inside an AKS cluster or as an Azure Container Apps job. Nothing is installed onto Cosmos DB, SQL Database, AKS control plane, or any other managed resource. #### What permissions does Scout need on my Azure subscription? When pulling metrics with `azure_monitor`: **Monitoring Reader** on each subscription you want to scrape. That role grants read access to metric definitions and metric values without any control-plane write permissions. When pushing through Diagnostic Settings to Event Hubs: the customer's IaC needs **Monitoring Contributor** (or higher) at the time it provisions Diagnostic Settings; Scout's runtime collector needs `Manage`, `Send`, and `Listen` on the Event Hubs shared access policy it consumes from. Both are documented inline in each per-surface guide. #### How fresh is metric data once it reaches Scout? Pulling from the Metrics REST API: a few minutes end-to-end. Microsoft documents that platform metrics are available in the metrics database in under a minute, then take another three minutes to be exported to a data collection endpoint; the receiver's `collection_interval` sits on top of that and is yours to tune. Consuming from Event Hubs: single-digit seconds in steady state. Use the Event Hubs push for any signal you want to alert on quickly. #### Why do I not see distributed traces from Cosmos DB, SQL Database, or AKS? Azure infrastructure resources do not emit OpenTelemetry traces describing their own internal operations. Distributed traces come from your application code, instrumented with the Azure Monitor OpenTelemetry Distro or a vanilla OTel SDK, sent over OTLP directly to Scout. The Azure Monitor pipeline this guide describes carries metrics and logs only. Tracing your application code is a separate setup covered in the [App Instrumentation guides](/instrument/apps/auto-instrumentation/). #### Can Scout coexist with my existing Log Analytics workspace? Yes. A single Diagnostic Setting can fan out to a Log Analytics workspace and an Event Hubs namespace simultaneously. Customers commonly keep their Azure portal KQL workbooks running while Scout becomes the primary observability surface. The data is duplicated, the cost on the Log Analytics side is unchanged, and Scout adds the Event Hubs charge on top. #### Should I use service principal secrets or workload identity? If the runtime hosting your collector can federate with Microsoft Entra ID (AKS, EKS, GKE, on-prem Kubernetes with workload identity, GitHub Actions, Azure Pipelines), **Workload Identity Federation** is the recommended default - it eliminates client secrets and the silent-zero failure mode that comes with secret expiry. Service principal with client secret is fully supported for runtimes where federation is not available; rotate the secret on a schedule and alarm on expiry. Managed identity and the default credential chain are also supported by the `azureauthextension` and pick themselves in the right runtimes. #### How does Azure Monitor REST API throttling work, and how do I avoid 429s? Set `use_batch_api: true` on the `azure_monitor` receiver. That switches to the Metrics Data Plane API (`metrics:getBatch`), which raises the per-subscription rate ceiling from 12,000 to 360,000 calls per hour and lets a single REST call fetch metrics for up to 50 resources. Tune the scrape interval and the resource set per shard so the projected call rate stays inside that budget. If you operate at fleet scale and want explicit headroom, shard by `(subscription, region)` so each shard's ceiling is independent. #### What is the difference between the `azure_monitor` and `azure_event_hub` receivers? `azure_monitor` pulls. It calls Azure Monitor's REST API on a schedule and emits OTel metrics. Use it for slow or definitive signals and for resource types that do not yet support streaming export. `azure_event_hub` consumes. It reads from an Event Hubs namespace that Diagnostic Settings has been configured to push into, and it decodes Azure Resource Logs and platform metrics natively. Use it for high-volume, low-latency signals and for any resource log surfacing in Scout. Production deployments run both. #### Does Scout support Azure Government or Azure China clouds? Yes. Both the `azure_monitor` and `azure_event_hub` receivers support Azure Government, Azure China, and the Azure US Government cloud variants by setting the `cloud` parameter and the appropriate management endpoint. The auth model is identical to Azure public cloud. Per-surface guides note any region-specific caveats for the resource type they cover. ### Related Guides - **App instrumentation** for distributed traces - see [App Instrumentation](/instrument/apps/auto-instrumentation/) for OTel SDK setup in Node, Python, .NET, Java, Go, PHP, and Ruby. - **base14 Scout** - the OTel-native observability platform this guide is written for. See [base14.io](https://base14.io) for platform details and pricing. ### References - **Diagnostic Settings in Azure Monitor.** Universal entry point for resource logs and metric streaming. [learn.microsoft.com/azure/azure-monitor/essentials/diagnostic-settings](https://learn.microsoft.com/en-us/azure/azure-monitor/essentials/diagnostic-settings) - **Log data ingestion time in Azure Monitor.** Latency expectations quoted in this guide. [learn.microsoft.com/azure/azure-monitor/logs/data-ingestion-time](https://learn.microsoft.com/en-us/azure/azure-monitor/logs/data-ingestion-time) - **Microsoft Entra Workload Identity Federation.** The secret-free auth path Scout standardises on. [learn.microsoft.com/entra/workload-id/workload-identity-federation](https://learn.microsoft.com/en-us/entra/workload-id/workload-identity-federation) - **`azure_monitor` receiver README.** Metrics-pull receiver, alpha stability. [github.com/open-telemetry/opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver) - **`azure_event_hub` receiver README.** Event Hubs push receiver, beta stability. [github.com/open-telemetry/opentelemetry-collector-contrib / receiver / azureeventhubreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azureeventhubreceiver) --- ## Azure Service Bus Monitoring with OpenTelemetry - Production Wiring for SREs ### Overview This guide is the **execution playbook** for Service Bus. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running Azure Service Bus in production who want to add Service Bus telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.ServiceBus/namespaces` metrics every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. Nothing on the data plane. The receiver does not connect to Service Bus directly. It queries Azure Monitor for any namespace your subscription auto-publishes to, so the same configuration covers Basic, Standard, and Premium tiers and any number of queues, topics, and subscriptions per namespace. This guide is metrics-only. For per-message distributed traces, instrument your producer and consumer code with an OTel Service Bus client integration (see [Apps-side instrumentation](#apps-side-instrumentation)). ### Receiver configuration Add this fragment to your existing collector config. It contributes the `azure_auth` extension, an `azure_monitor` receiver, a resource processor, and a metrics pipeline. Component keys are suffixed `/servicebus` so the fragment composes cleanly with other Azure-surface receivers in the same collector. ```yaml showLineNumbers title="otel-collector.yaml (Service Bus addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Authentication section below for the right choice per # collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/servicebus: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} # Add more entries to scrape namespaces across multiple subscriptions # in one collector. Each subscription needs its own Monitoring Reader # role assignment on the configured identity; the receiver fans out queries across # all subscription x resource-group combinations. resource_groups: - ${env:AZURE_RESOURCE_GROUP} # Multi-resource-group scoping. Omit resource_groups entirely to scrape every resource group # in the listed subscriptions. services: - Microsoft.ServiceBus/namespaces auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Metrics Data Plane (metrics:getBatch). Raises the per-subscription # ceiling from 12k to 360k calls/hour and batches up to 50 resources # per call - the only setting that survives a real fleet. RBAC # propagates 5-30 min after the Monitoring Reader grant; flip to false # as a temporary fallback to the legacy ARM /metrics endpoint if you # see persistent 401s after that window. See Scale and rate limits below. use_batch_api: true # Resource-list cache TTL in seconds. The receiver default is 86400 (24h), # which is the right setting for a stable fleet. Lower (e.g. 3600 or 600) # only if namespaces are added or removed frequently. cache_resources: 86400 dimensions: enabled: true # The receiver only emits the metrics you list; there is no implicit # default + my picks merge. Empty aggregation list `[]` requests all # aggregations Azure Monitor publishes for the metric. metrics: "Microsoft.ServiceBus/namespaces": IncomingRequests: [] SuccessfulRequests: [] ServerErrors: [] UserErrors: [] ThrottledRequests: [] ServerSendLatency: [] IncomingMessages: [] OutgoingMessages: [] ActiveMessages: [] DeadletteredMessages: [] ScheduledMessages: [] Size: [] ActiveConnections: [] processors: resource/servicebus: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_service_bus, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:AZURE_REGION}", action: insert} # cloud.resource_id pins all metrics to one namespace. Drop this line # for multi-namespace fleets; the receiver injects azuremonitor.resource_id # per-resource automatically. - {key: cloud.resource_id, value: "${env:SERVICEBUS_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:SERVICEBUS_SERVICE_NAME}", action: insert} service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/servicebus: receivers: [azure_monitor/servicebus] processors: [resource/servicebus, batch] # plus your existing processors exporters: [otlphttp/b14] # your Scout exporter ``` The receiver, resource processor, and pipeline are all keyed `/servicebus` so they coexist with other Azure receivers (Cosmos DB, SQL Database, Storage) in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, the `subscription_ids:` list takes any number of entries; alternatively set `discover_subscriptions: true` to scrape every subscription the configured identity has `Monitoring Reader` on, with no explicit list. See [Scale and rate limits](#scale-and-rate-limits). ### Authentication `azure_auth` supports four modes. Pick the one matching where the collector runs. | Collector deployment | Recommended mode | Why | | ------------------------------- | --------------------- | ------------------------------------------------------------------------- | | Azure Kubernetes Service (AKS) pod | `workload_identity` | Federated credential, no secret to rotate, scoped to the ServiceAccount. | | Container Apps | `managed_identity` (system or user-assigned) | First-class integration, no secret to rotate. | | Virtual Machine Scale Sets / Azure VM | `managed_identity` (user-assigned) | User-assigned identity survives instance replacement; the system-assigned identity dies with the VM or scale-set instance. | | External or on-prem | `service_principal` | Only option without an Azure-resident identity. | | Local dev / ad-hoc | `use_default: true` | Falls back to the Azure SDK default credential chain (CLI, env, managed identity). | #### Workload Identity Federation (Azure Kubernetes Service) The cleanest production auth. Bind a federated credential on a Microsoft Entra app registration to your collector's Kubernetes ServiceAccount; the collector mounts a token file and exchanges it for an Azure access token on every request. No client secret. No rotation. ```yaml extensions: azure_auth: workload_identity: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} # the user-assigned managed identity's clientId federated_token_file: /var/run/secrets/azure/tokens/azure-identity-token ``` Setup: 1. Enable the workload-identity addon on the AKS cluster (`az aks update --enable-workload-identity --enable-oidc-issuer`). 2. Create a user-assigned managed identity, capture its `clientId` and `principalId`. 3. Add a federated credential to the managed identity scoped to your ServiceAccount: ```bash az identity federated-credential create \ --name otel-collector-fed \ --identity-name otel-collector-mi \ --resource-group \ --issuer "$(az aks show -g -n --query oidcIssuerProfile.issuerUrl -o tsv)" \ --subject "system:serviceaccount::" ``` 4. Annotate the ServiceAccount: `azure.workload.identity/client-id: `. 5. Label the collector pod: `azure.workload.identity/use: "true"`. 6. Grant `Monitoring Reader` to the managed identity's `principalId` on every Service Bus resource group it should scrape. #### Managed Identity (Container Apps, Virtual Machine Scale Sets, Azure VM) ```yaml extensions: azure_auth: managed_identity: # System-assigned: omit client_id; the resource's identity is used. # User-assigned: provide the client_id of the assigned managed identity. client_id: ${env:AZURE_CLIENT_ID} # optional for system-assigned ``` Container Apps: assign system-assigned managed identity on the app (`az containerapp identity assign --system-assigned`); grant the resulting `principalId` `Monitoring Reader` on each target resource group. #### Service Principal (out-of-Azure collectors) ```yaml extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} ``` `AZURE_CLIENT_SECRET` is the only credential that needs rotation; see [Service principal credential lifecycle](#service-principal-credential-lifecycle). #### RBAC scope `Monitoring Reader` at the resource group containing your namespaces is sufficient and minimal. The role grants read on metric definitions and metric data only, no control-plane write. `Reader` is not required. ```bash RG_ID=$(az group show --name --query id -o tsv) az role assignment create \ --assignee \ --role "Monitoring Reader" \ --scope "$RG_ID" ``` For multi-subscription fleets, repeat the assignment on each subscription's resource group. Subscription-scoped assignments work too if the managed identity or service principal should see every namespace in a subscription. RBAC propagation on the legacy Azure Resource Manager `/metrics` endpoint is immediate. The data-plane batch API at `*.metrics.monitor.azure.com` requires separate propagation that lags 5-30 minutes after grant. This guide defaults `use_batch_api: true`; if the data plane is still 401-ing past that window, flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint (RBAC there is immediate). ### What you'll monitor Thirteen metrics from `Microsoft.ServiceBus/namespaces`. The receiver renames them from Azure's PascalCase (e.g. `IncomingMessages`) to OTel-style `azure__` (e.g. `azure_incomingmessages_total`). Counter-style metrics emit five aggregations per poll (`_average`, `_count`, `_maximum`, `_minimum`, `_total`); gauge-style metrics emit only `_average` when the aggregation list is empty. | Azure REST name | OTel emitted | Unit | What it tells you | | ---------------------- | ---------------------------------- | ----- | ------------------------------------------------------------------------------------------------------------ | | `IncomingRequests` | `azure_incomingrequests_*` | Count | Per-minute API call count to the namespace (sends, receives, control-plane). | | `SuccessfulRequests` | `azure_successfulrequests_*` | Count | Successful subset of `IncomingRequests`. Pair with `ServerErrors` + `UserErrors` via the `OperationResult` dimension. | | `ServerErrors`† | `azure_servererrors_*` | Count | Service-side failures. Sustained > 0 is a page. | | `UserErrors`† | `azure_usererrors_*` | Count | Client-induced errors (auth, malformed, filter mismatch). High with low `ServerErrors` means producer / consumer code. | | `ThrottledRequests`† | `azure_throttledrequests_*` | Count | Capacity-ceiling hits. `MessagingErrorSubCode` dimension splits 50001 (throughput), 50002 (size quota), 50009 (unit credit). | | `ServerSendLatency` | `azure_serversendlatency_average`‡ | ms | Broker-side send latency. Excludes network and client. | | `IncomingMessages` | `azure_incomingmessages_total` | Count | Producer ingestion rate per entity (`EntityName` dimension). | | `OutgoingMessages`† | `azure_outgoingmessages_total` | Count | Consumer drain rate per entity. Pair with `IncomingMessages` to see backlog growth. | | `ActiveMessages` | `azure_activemessages_average` | Count | Queue / topic backlog gauge: visible-but-not-locked messages. The primary depth metric. | | `DeadletteredMessages` | `azure_deadletteredmessages_average` | Count | Dead-letter queue depth per entity. Climbing means consumer is failing past `maxDeliveryCount`. | | `ScheduledMessages` | `azure_scheduledmessages_average` | Count | Messages scheduled for future delivery (set via `ScheduledEnqueueTimeUtc`). | | `Size` | `azure_size_average` | Bytes | Bytes consumed per queue / topic. Standard quota is 1 GB / entity; alert at 80%. | | `ActiveConnections` | `azure_activeconnections_*` | Count | AMQP connection count to the namespace. | `EntityName` and `EntityType` ride alongside every message-flow and entity-state metric, splitting the namespace-scope series into per-queue, per-topic, and per-subscription series automatically. Subscriptions appear under `EntityName` as `/` once the subscription has its own activity (a receiver pulling messages, dead-letter accumulation). A topic that is only fanned out without consumers does not surface a subscription dimension. **`†` silent-when-quiet.** Azure Monitor returns data points for these metrics only when the underlying condition occurs. A healthy namespace emits zero series for `ServerErrors`, `UserErrors`, and `ThrottledRequests`; a producer-only namespace with no consumer drain emits zero for `OutgoingMessages`. Wire alerts on these metrics to fire on series presence in window (any non-zero point), not on threshold crossings, since the absence of points is the steady state. **`‡` latency aggregations.** `ServerSendLatency` is a duration metric, but the receiver still emits all five aggregations. Only `_average`, `_minimum`, and `_maximum` are operationally meaningful; `_count` and `_total` are sums of the latency values themselves and not call counts. Drop the count and total via aggregation-list narrowing if Scout cardinality matters: `ServerSendLatency: [Average, Minimum, Maximum]`. **Gauge `_total` caveat.** The same logic applies to `ActiveConnections`, `ActiveMessages`, `DeadletteredMessages`, `ScheduledMessages`, and `Size` when they are configured to emit multiple aggregations. `_total` on a gauge is a sum of point-in-time samples and has no physical meaning. Alert on `_average`, `_minimum`, or `_maximum` for these metrics, never on `_total`. **First poll after a namespace is added.** Azure Monitor publishes `Size` and `ActiveConnections` immediately on a freshly-created namespace. Every other metric requires real traffic to emit its first data point; expect 1-3 minutes of empty series after the producer or consumer makes its first call. This applies any time a namespace is added to scope (provisioning, expanding `subscription_ids`, or `cache_resources` TTL expiry refreshing the resource list). Premium-only metrics (`NamespaceCpuUsage`, `NamespaceMemoryUsage`, `ReplicationLagCount`, `ReplicationLagDuration`) and deprecated metrics (`CPUXNS`, `WSXNS`) are intentionally excluded. Listing Premium-only metrics on a Standard namespace returns 401 from Azure Monitor and the receiver burns rate-limit budget retrying. Add them when targeting Premium; see [Premium-tier additions](#premium-tier-additions). ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | ------------------------------------------- | ----------------------- | ------------------------------------- | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Default in this guide. RBAC lags 5-30 min after the Monitoring Reader grant. | | Legacy Azure Resource Manager `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Temporary fallback if the data plane is still 401-ing after RBAC propagation should have completed. Immediate RBAC propagation. | At a 60-second collection interval, a single resource costs roughly 60 calls per hour (one per metric per poll, deduplicated within the receiver). Even small fleets benefit from `use_batch_api: true` because batched fan-out is more rate-limit-friendly across collectors that share a subscription. ```yaml receivers: azure_monitor/servicebus: # Pick one of two scoping patterns: # 1. Explicit list: subscription_ids: [...] (predictable, audit-friendly). # 2. Discovery: discover_subscriptions: true (any sub the configured identity has # Monitoring Reader on; no list to maintain as orgs add subs). subscription_ids: - ${env:HUB_SUB_ID} - ${env:WORKLOAD_SUB_1} - ${env:WORKLOAD_SUB_2} - ${env:WORKLOAD_SUB_3} # discover_subscriptions: true # alternative to subscription_ids # No resource_groups: at all; receiver scrapes every resource group in every sub. services: [Microsoft.ServiceBus/namespaces] auth: { authenticator: azure_auth } use_batch_api: true # 360k/h ceiling per sub cache_resources: 86400 # receiver default (24h) ``` The receiver shares one rate-limit budget across all subscriptions in the list; it does not bypass per-subscription quotas. Splitting heavy subscriptions across separate collector instances lifts the aggregate ceiling linearly. `cache_resources` is the resource-list cache TTL in seconds. The receiver default is `86400` (24 hours), which is correct for a stable fleet. Lower to `3600` or `600` only if namespaces are created and destroyed frequently enough that 24-hour-stale resource lists become a problem; per-minute resource-list calls otherwise burn Azure Resource Manager rate-limit budget for no benefit. ### Cardinality control By default, the receiver emits one OTel series per `(resource × metric × aggregation × dimension-combination)`. The 13-metric whitelist splits as 9 counter-style metrics (5 aggregations each: `_average`, `_count`, `_maximum`, `_minimum`, `_total`) plus 4 gauge-style metrics (`_average` only). That is `9 × 5 + 4 × 1 = 49` series per resource per poll before dimension fan-out. A measured baseline (one namespace, one queue + one topic + one subscription, dimensions enabled) emits ~29 active series during steady producer-only traffic. Extrapolating to a 50-namespace fleet averaging 200 entities per namespace: ```text ~29 series × (50 namespaces / 1) × (200 entities / 3) ≈ 100,000 active series ``` `OperationResult` (on `SuccessfulRequests`, `ServerErrors`, `UserErrors`, `ThrottledRequests`) and `MessagingErrorSubCode` (on `ThrottledRequests`) multiply on those specific metrics, adding another 1.5-3x growth on the error and throttle counters during incidents. Three control levers, in order of preference: 1. **`dimensions.overrides`** drops or whitelists dimensions per metric. Drop `EntityName` on namespaces where per-queue granularity is not actionable for alerting (transactional outbox, internal scratch namespaces); drop `OperationResult` and `MessagingErrorSubCode` on metrics other than the error / throttle counters. ```yaml azure_monitor/servicebus: dimensions: enabled: true overrides: "Microsoft.ServiceBus/namespaces": IncomingMessages: - EntityName # keep OutgoingMessages: - EntityName ServerErrors: - EntityName - OperationResult ThrottledRequests: - EntityName - MessagingErrorSubCode Size: [] # drop EntityName too; aggregate at namespace level ``` 2. **Aggregation-list narrowing.** Replace `[]` with explicit lists to drop the high-cost aggregations. For latency metrics, `[Average, Minimum, Maximum]` saves two series per resource. For counter metrics, the `_count` and `_total` aggregations are usually redundant on the same metric (Azure publishes both as the same value); pick one. 3. **Per-namespace receiver instances.** Split high-cardinality namespaces into separate `azure_monitor/servicebus-bigfleet` and `azure_monitor/servicebus-quiet` receivers with different override profiles. Both contribute to the same `metrics/servicebus` pipeline. Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's Prometheus self-telemetry endpoint (port 8888 by default) to see actual cardinality after `overrides` apply. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points for a Standard tier namespace with steady traffic; derive your own from observed 99th percentile over a representative week. `azure_throttledrequests_total` and `azure_servererrors_total` only emit data points when their condition occurs (silent-when-quiet, see metric table). Wire alerts on these to fire on series presence in window, not on numeric thresholds; a healthy namespace emits no points at all. | Metric (OTel name) | Warning | Critical | Why it matters | | --------------------------------------------------------- | -------------------- | -------------------- | ------------------------------------------------------------------------------------------------------------- | | `azure_activemessages_average` (per `EntityName`) | > 99th percentile baseline | sustained > 2x 99th percentile | Consumer is not keeping up. Pair with `IncomingMessages` to confirm send rate has not spiked. | | `azure_deadletteredmessages_average` (per `EntityName`) | > 0 / 5m | sustained > 0 / 30m | Consumer is failing past `maxDeliveryCount`. These messages are stuck. | | `azure_throttledrequests_total` | `> 0` over 5m | `> 0` over 15m | Capacity ceiling hit. Upgrade to Premium or split namespaces. Use `count_over_time(...) > 0` semantics; healthy namespaces emit no points. | | `azure_servererrors_total` | `> 0` over 5m | `> 0` over 15m | Service-side failures. Cross-check Azure Service Health for incidents. Same presence-based alerting as `ThrottledRequests`. | | `azure_size_average` / 1 GB | > 80% | > 95% | Standard tier per-entity quota is 1 GB. Approaching the cap means consumers must drain or you must split. | | `azure_serversendlatency_average` | > 100 ms | > 500 ms | Broker-side send latency. Excludes client and network. | | `azure_activeconnections_total` (per namespace) | > 5x baseline / 15m | sustained > 10x | Misbehaving client opening connections in a loop. Set baseline from a steady-state week. | #### RED method on the broker If you run Service Bus as part of a service backed by service-level objectives (SLOs), frame Service Bus metrics as RED (rate, errors, duration) on the broker: - **Rate.** `azure_incomingrequests_total` per namespace, sliced by entity. - **Errors.** Split into two service-level indicators (SLIs), since they map to different remediation: - **Availability error rate** = `(azure_servererrors_total + azure_throttledrequests_total) / azure_incomingrequests_total`. A spike here is "Service Bus or your capacity envelope is broken"; route to platform on-call. - **Request-quality error rate** = `azure_usererrors_total / azure_incomingrequests_total`. A spike here is "your producer or consumer code is broken"; route to the owning service team. - **Duration.** `azure_serversendlatency_average` (and `_minimum` / `_maximum`) per entity. Broker-side only; client + network adds round-trip cost. For end-to-end producer-to-consumer latency, instrument the client (see [Apps-side instrumentation](#apps-side-instrumentation)). For saturation (the U in USE), pair `azure_size_average / quota`, `azure_activeconnections_total / 1000` (per-namespace AMQP connection limit), and `azure_throttledrequests_total > 0` (capacity-ceiling proxy). On Premium, add `azure_namespacecpuusage_maximum` and `azure_namespacememoryusage_maximum` for direct messaging-unit utilisation. ### Premium-tier additions Premium adds dedicated messaging units, optional geo disaster recovery (geo-DR), and a handful of extra metrics. When the namespace is Premium, extend the whitelist: ```yaml metrics: "Microsoft.ServiceBus/namespaces": # ...all 13 from the Standard set above... NamespaceCpuUsage: [] # Messaging-unit CPU saturation; alert > 70% NamespaceMemoryUsage: [] # Messaging-unit memory saturation; alert > 70% ReplicationLagCount: [] # geo-DR lag in messages (geo-paired only) ReplicationLagDuration: [] # geo-DR lag in seconds (geo-paired only) MessagingActiveGeoDR: [] # 1 on the active replica, 0 on the secondary PendingCheckpointOperationCount: [] # Internal checkpoint queue depth ``` The `Replica` dimension splits replication-lag and `MessagingActiveGeoDR` metrics across paired namespaces. On Premium-with-partitions namespaces (generally available 2024), the same dimension also splits `NamespaceCpuUsage` and `NamespaceMemoryUsage` per partition, which changes series shape vs. non-partitioned Premium; verify with one poll against your namespace before pre-allocating dashboards. A geo-DR failover changes which replica is active without changing metric content. Pin dashboards to namespace name rather than resource id if you want continuity across failover, and alert on `MessagingActiveGeoDR == 1` per replica to detect unexpected role changes. ### Service principal credential lifecycle If you run a service principal (collector outside Azure), rotate the client secret before its expiry, not after. #### Proactive rotation (zero-downtime) ```bash # 0. Capture the current credential's keyId BEFORE rotating, so step 4 # knows which one to revoke. (Multiple credentials with similar names # accumulate; sort by endDateTime to pick the oldest active one.) OLD_KEY_ID=$(az ad app credential list --id "$AZURE_CLIENT_ID" \ --query "sort_by([], &endDateTime)[0].keyId" -o tsv) # 1. Append a new credential alongside the existing one. --append is what # makes this zero-downtime: without it, the previous credential is # revoked immediately and the collector errors until the new value # reaches its secret store. NEW_RESULT=$(az ad app credential reset \ --id "$AZURE_CLIENT_ID" \ --append \ --years 1 \ -o json) NEW_SECRET=$(echo "$NEW_RESULT" | jq -r .password) # The new keyId is also returned; useful for audit. NEW_KEY_ID=$(echo "$NEW_RESULT" | jq -r .keyId) # 2. Update the collector's secret store with $NEW_SECRET. Examples: # kubectl create secret generic otel-azure-sp \ # --from-literal=AZURE_CLIENT_SECRET="$NEW_SECRET" \ # --dry-run=client -o yaml | kubectl apply -f - # External Secrets Operator + Azure Key Vault auto-rotation # Azure Key Vault Container Storage Interface driver with auto-rotation # 3. Restart or hot-reload the collector. Wait for /metrics on the # collector's self-telemetry to confirm it auth'd successfully, then: # 4. Revoke the old credential. az ad app credential delete --id "$AZURE_CLIENT_ID" --key-id "$OLD_KEY_ID" ``` Set a calendar alert 30 days before secret expiry. `az ad app credential list --id $AZURE_CLIENT_ID --query "[].{keyId:keyId, endDateTime:endDateTime}" -o table` shows every active credential with its expiry. Tag credentials with `displayName` at creation if you want to identify them later by purpose rather than `keyId`. #### Eliminate rotation entirely If the collector runs in Azure, switch to managed identity or Workload Identity Federation; rotation goes away. Federated credentials and managed identities do not have client secrets; the platform mints short-lived tokens on demand. ### Apps-side instrumentation This guide is metrics-only. To produce per-message distributed traces (producer span linked through the broker to consumer span), instrument your producer / consumer code with one of these OTel Service Bus integrations: - **.NET / C#:** `Azure.Messaging.ServiceBus` ships built-in ActivitySource emission. Add `OpenTelemetry.Extensions.Hosting` and register `AddSource("Azure.Messaging.ServiceBus")` to forward producer, consumer, and receive spans. - **Java:** the OTel Java agent (`opentelemetry-javaagent.jar`) auto-instruments the Azure SDK (`com.azure:azure-messaging-servicebus`) via the `azure-core-tracing-opentelemetry` adapter. No code changes. - **Python:** the OTel community `opentelemetry-instrumentation-azure-servicebus` package wraps `azure-servicebus`. Less mature than .NET / Java; verify span shape before promoting. - **Node.js / Go:** no first-party OTel instrumentation as of 2026-05. Manual span creation around `sender.sendMessages` and `receiver.receiveMessages` is the workaround. Run the apps-side spans alongside this metrics collector with distinct `service.name` values to keep the broker view and the request-flow view separately filterable in Scout. ### Logs Architecture for the Diagnostic Settings → Event Hubs → `azure_event_hub` path is in the [overview](./overview.md#choosing-pull-push-or-both). The Service Bus log categories worth enabling: | Log category | What it captures | | --- | --- | | `OperationalLogs` | Namespace-level operational events | | `RuntimeAuditLogs` | Data-plane authentication and authorisation activity | | `ApplicationMetricsLogs` | Application-level metric events (where supported by your tier) | ```bash az monitor diagnostic-settings create \ --resource \ --name servicebus-to-eventhubs \ --logs '[{"category":"OperationalLogs","enabled":true},{"category":"RuntimeAuditLogs","enabled":true}]' \ --event-hub-rule ``` Activity logs (control-plane operations on the namespace) are **subscription-scoped**, not resource-scoped; configure them once per subscription via `az monitor diagnostic-settings subscription create`. ### Troubleshooting #### `AuthorizationFailed` from the receiver Legacy Azure Resource Manager `/metrics` endpoint propagates `Monitoring Reader` immediately; data-plane batch API can lag 5-30 minutes. If `use_batch_api: true` is set and you've just granted the role, temporarily flip to `false` to confirm the role itself is correct. #### `403 Forbidden` from the receiver If using a service principal: the client_secret has expired. See [Service principal credential lifecycle](#service-principal-credential-lifecycle) for the rotation procedure. If using managed identity: check that the namespace is in a subscription / resource group where the managed identity has `Monitoring Reader`. #### `RequestThrottled` warnings from the receiver You have hit Azure Monitor's per-subscription rate ceiling (12,000 / hour on legacy, 360,000 / hour on batch). Either: - Lower polling rate: `collection_interval: 120s`. - Narrow scope: list specific `resource_groups:` rather than scraping every resource group. - Split heavy subscriptions across multiple collector instances; each consumes a separate per-subscription rate budget. `use_batch_api: true` is already the default in this guide. #### Cardinality blowup on Scout volume A single high-fanout namespace can dominate volume. Apply `dimensions.overrides` (see [Cardinality control](#cardinality-control)) or split the noisy namespace into a separate receiver instance with a narrower whitelist. #### `OutgoingMessages` flat while `IncomingMessages` rises Producer is healthy; consumer has stopped or slowed. Cross-check `ActiveMessages_average` (rising = backlog accumulating) and `DeadletteredMessages_average` (rising = consumer failing past `maxDeliveryCount`). Page on the consumer service, not Service Bus itself. #### Scout OAuth2 returns 401 Verify `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, and `SCOUT_TOKEN_URL` match the values in your Scout console. The `endpoint_params.audience` must be `b14collector`. ### Frequently Asked Questions #### How do I add Azure Service Bus metrics to my existing OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to `Microsoft.ServiceBus/namespaces`, then route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter. The receiver polls Azure Monitor's REST API every 60 seconds and emits one OTel metric per Azure aggregation. No data-plane connection to Service Bus; the broker is never on the collector's path. #### Should I use a service principal or managed identity for the collector? Managed identity if the collector runs in Azure, service principal if it does not. AKS pods use Workload Identity Federation with a federated credential bound to a Kubernetes ServiceAccount; Container Apps and Virtual Machine Scale Sets use system-assigned or user-assigned managed identity; out-of-Azure collectors fall back to service principal. The `azure_auth` extension's mode block is the only thing that changes; the rest of the receiver config is identical. #### How do I scope the receiver to multiple subscriptions and resource groups? `subscription_ids` and `resource_groups` are both lists. The receiver fans out queries across all combinations, sharing one Azure Resource Manager rate-limit budget per subscription. With `Monitoring Reader` granted on each scope, one collector can poll dozens of namespaces across many subscriptions. The default `use_batch_api: true` (see [Receiver configuration](#receiver-configuration)) gives you the 360,000 calls / hour per-subscription ceiling and batched fan-out across resources; flip to `false` only as a temporary fallback to the legacy ARM `/metrics` endpoint while data-plane RBAC propagates. #### How do I keep metric cardinality under control with thousands of entities? By default the receiver emits a series per entity per metric per aggregation; a 50-namespace fleet with 200 entities each and 13 whitelisted metrics produces roughly 100,000 active series. Use `dimensions.overrides` on the receiver to drop `EntityName` or `OperationResult` on namespaces where per-entity granularity is not actionable. Drop `_count` and `_total` aggregations on latency metrics; only `_average`, `_minimum`, and `_maximum` are operationally meaningful for durations. #### How does Scout compare to Application Insights for Service Bus? Both surfaces draw from the same Azure Monitor REST API, so metric coverage is identical. The differences are commercial and operational: Scout is vendor-neutral OTLP, queryable via SQL, with ingest-volume pricing rather than per-GB ingestion fees; Application Insights uses Kusto Query Language only, is Azure-tenant-bound, and bills for log ingestion alongside metric storage. The collector also unifies multi-cloud surfaces under one pipeline: Service Bus, Cosmos DB, Azure Kubernetes Service, and AWS or GCP equivalents flow through the same exporter. #### What is the service principal secret rotation procedure? Generate a new credential with `az ad app credential reset --append` (the `--append` flag preserves the existing credential so the collector can roll over without downtime), update the `AZURE_CLIENT_SECRET` secret store the collector reads from, restart or hot-reload the collector, then revoke the old credential. The federated-credential alternative (Workload Identity Federation for AKS, system-assigned managed identity for Container Apps) eliminates the rotation entirely; if the collector runs in Azure, prefer that path. #### Do I need this guide AND Diagnostic Settings to Log Analytics? Yes if you want logs alongside metrics. This guide ships metrics. For activity logs, operational logs, and runtime audit logs from the namespace, configure Diagnostic Settings on the namespace to forward to Log Analytics or to Event Hubs and pipe Event Hubs into the collector via the `azure_event_hub` receiver. The two paths are complementary: metrics for SLI and SLO dashboards and alerts, logs for incident investigation. ### Reference - **Receiver source.** [opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver). - **Auth extension source.** [opentelemetry-collector-contrib / extension / azureauthextension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/azureauthextension). - **Azure Monitor metric reference.** [Microsoft.ServiceBus/namespaces metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-servicebus-namespaces-metrics). ### Related Guides - [Azure Event Hubs](./event-hubs.md) - managed event-streaming platform (Kafka-compatible, partitioned, replay-capable). Pick Event Hubs for high-throughput streaming workloads (telemetry pipelines, event sourcing); pick Service Bus for transactional messaging and work distribution. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure SQL Database](./sql-database.md) - managed relational database. Pairs with the self-hosted [SQL Server guide](../../component/sqlserver.md). - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. - [Amazon MQ](../aws/amazonMQ.md) - managed messaging on AWS. Different collection pattern (CloudWatch Metrics Stream) and protocol, but the same observability question: depth, drain rate, dead-letter, throttling. --- ## Azure SQL Database Monitoring with OpenTelemetry - Database Transaction Unit (DTU), Connections & Deadlocks ### Overview This guide is the **execution playbook** for Azure SQL Database. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide covers monitoring an **Azure SQL Database** (the managed Platform-as-a-Service, PaaS) with the OpenTelemetry Collector's `azure_monitor` receiver. The collector polls Azure Monitor's REST API every 60 seconds for the metrics published by `Microsoft.Sql/servers/databases`, transforms them to OTel-style names, and ships them via OTLP/HTTP to base14 Scout. The `azure_monitor` receiver does not connect to SQL directly. It queries Azure Monitor's metrics surface for any database Azure auto-publishes to - so the same pattern applies across all SKUs (DTU model, vCore, Serverless, Hyperscale), single databases and elastic pools, and to other Azure services like Cosmos DB, Storage, and Service Bus. The configuration shape below generalises to those. ### Self-hosted SQL Server vs Azure SQL Database If you run SQL Server yourself - on a VM, on-premises, or in a container - use the [self-hosted SQL Server guide](../../component/sqlserver.md) instead. That path uses the OTel `sqlserverreceiver` to scrape Dynamic Management Views (DMVs) directly, which works without an Azure subscription and surfaces internals (query plans, wait stats, buffer cache hit ratio) that Azure Monitor doesn't expose. | Surface | Mechanism | Subscription | Internals | | --- | --- | --- | --- | | Azure SQL Database (PaaS) | `azure_monitor` receiver, this guide | Required | DTU, connections, storage | | SQL Server (VM / on-prem / container) | `sqlserverreceiver`, [other guide](../../component/sqlserver.md) | Not required | DMV scrapes - wait stats, query plans, buffer pool | **Pick exactly one per database.** Running both against the same workload produces double-counted dashboards because the metric names overlap with different dimensions. ### What you'll monitor Two Azure namespaces, scraped together on each poll: 1. **`Microsoft.Sql/servers/databases`** - per-database metrics: Database Transaction Unit (DTU), connections, storage, deadlocks, replication lag, in-memory Online Transaction Processing (OLTP) usage. 2. **`Microsoft.Sql/servers/elasticPools`** - pool-level capacity and saturation. Omitted if no elastic pools exist on the target server. The receiver emits one OTel metric per Azure aggregation. Two shapes: - **Gauge-style** (`dtu_consumption_percent`, `cpu_percent`, `storage_percent`, `sessions_percent`, `workers_percent`, `xtp_storage_percent`, `replication_lag_seconds`) - Azure publishes Average / Maximum / Minimum, the receiver emits `_average`, `_maximum`, `_minimum`. - **Counter-style** (`connection_successful`, `connection_failed`, `connection_failed_user_error`, `blocked_by_firewall`, `deadlock`) - Azure publishes Total (Sum) and Count, the receiver emits `_total` and `_count`. The two carry the same information at the per-minute grain; pick one for dashboards. `availability` is the exception: Azure publishes all five aggregations (Average, Maximum, Minimum, Count, Total), so the receiver emits five OTel series. Use `_average` for SLO dashboards. #### Database-level (`Microsoft.Sql/servers/databases`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `cpu_percent` | `azure_cpu_percent_{average,maximum,minimum}` | Percent | Database CPU usage. Page at sustained 80%+. | | `dtu_consumption_percent` | `azure_dtu_consumption_percent_*` | Percent | Composite DTU saturation (DTU model only). | | `dtu_used` / `dtu_limit` | `azure_dtu_used_*` / `azure_dtu_limit_*` | Count (DTU) | Absolute DTU consumption + tier ceiling. | | `cpu_used` / `cpu_limit` | `azure_cpu_used_*` / `azure_cpu_limit_*` | Count (vCore) | Absolute vCore consumption + tier ceiling (vCore SKUs only). | | `log_write_percent` | `azure_log_write_percent_*` | Percent | Write-log throughput saturation. | | `physical_data_read_percent` | `azure_physical_data_read_percent_*` | Percent | Read-IO saturation (page reads from storage). | | `storage` | `azure_storage_{average,maximum,minimum}` | Bytes | Allocated storage in bytes. | | `storage_percent` | `azure_storage_percent_*` | Percent | % of `maxSizeBytes` used. Alert at 80%. | | `sessions_percent` | `azure_sessions_percent_*` | Percent | Sessions vs. tier ceiling. | | `workers_percent` | `azure_workers_percent_*` | Percent | Workers vs. tier ceiling. | | `connection_successful` | `azure_connection_successful_{count,total}` | Count | Successful connections per minute. | | `connection_failed` | `azure_connection_failed_{count,total}` | Count | Failed connections - system errors (auth, firewall, TLS). Silent-when-quiet: data points only when at least one failure occurs in the grain. | | `connection_failed_user_error` | `azure_connection_failed_user_error_{count,total}` | Count | Failed connections - user errors (login_failed, invalid_db). Different alert posture from `connection_failed`. | | `blocked_by_firewall` | `azure_blocked_by_firewall_{count,total}` | Count | Connections rejected by server firewall rules. Silent-when-quiet. | | `deadlock` | `azure_deadlock_{count,total}` | Count | Deadlock count - page on any non-zero. Silent-when-quiet. | | `availability` | `azure_availability_{average,maximum,minimum,count,total}` | Percent | Database availability % (PT1H grain). All 5 aggregations published. | | `replication_lag_seconds` | `azure_replication_lag_seconds_*` | Seconds | Geo-replication / active geo-replication lag. Emitted on the primary database when active geo-replication is configured (Standard tier and above; Basic excluded). | | `xtp_storage_percent` | `azure_xtp_storage_percent_*` | Percent | In-memory Online Transaction Processing (OLTP) storage. Premium / Business Critical only (in-memory OLTP is not available below Premium). | #### Pool-level (`Microsoft.Sql/servers/elasticPools`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `eDTU_limit`, `eDTU_used` | `azure_edtu_limit_*`, `azure_edtu_used_*` | Count (eDTU) | Pool capacity vs. used (DTU pools). | | `dtu_consumption_percent` | `azure_dtu_consumption_percent_*` | Percent | Pool DTU saturation. | | `cpu_percent`, `log_write_percent`, `physical_data_read_percent` | `azure_cpu_percent_*`, `azure_log_write_percent_*`, `azure_physical_data_read_percent_*` | Percent | Pool CPU + I/O saturation. | | `storage_used`, `storage_limit`, `storage_percent` | `azure_storage_used_*`, `azure_storage_limit_*`, `azure_storage_percent_*` | Bytes / Percent | Pool storage capacity vs. used. | | `allocated_data_storage`, `allocated_data_storage_percent` | `azure_allocated_data_storage_*` | Bytes / Percent | Allocated-data view of pool storage. | | `sessions_percent`, `sessions_count`, `workers_percent` | `azure_sessions_percent_*`, `azure_sessions_count_*`, `azure_workers_percent_*` | Percent / Count | Pool connection pressure. | | `xtp_storage_percent` | `azure_xtp_storage_percent_*` | Percent | Pool-level in-memory OLTP storage. | `connection_failed`, `connection_failed_user_error`, `blocked_by_firewall`, and `deadlock` are silent-when-quiet: Azure Monitor publishes a data point only when at least one event occurs in the time grain. Empty buckets return no point rather than a zero. Wire alerts on these to fire on series presence in window, not on numeric thresholds. (Note: this is not a universal "Azure Monitor doesn't emit zeros" rule. `availability` and several gauge metrics emit a point every grain regardless.) The receiver also discovers the system `master` database alongside your application database and emits the same database-scope series for both. Filter by `cloud.resource_id` (which encodes the full Azure resource ID for each emitted series) if you want to drop `master` in Scout. #### What Azure Monitor does NOT see Wait stats, buffer pool hit ratio, query store, individual replica health on Business Critical / Hyperscale, and the deadlock graph XML are SQL Server *internals* - Azure Monitor doesn't expose them. Point the OTel `sqlserverreceiver` at the SQL endpoint to add that depth; see the [self-hosted SQL Server guide](../../component/sqlserver.md). The two paths are complementary, not redundant - run both with distinct `service.name` values when you need both views. ### Prerequisites | Requirement | Minimum | | --------------------------------- | -------------------------------- | | An Azure SQL Database (any tier) | DTU, vCore, Serverless, Hyperscale | | OTel Collector contrib | v0.148+ (snake_case YAML keys) | | `Microsoft.Sql` provider | registered on the subscription | | Service principal | `Monitoring Reader` on the SQL resource group | | base14 Scout | any tenant | This guide is the SQL-DB-specific addition to a working OpenTelemetry Collector. For collector deployment + the Scout exporter pieces (which are the same for every Azure surface), see: - [Docker Compose Setup](../../collector-setup/docker-compose-example.md), or [Kubernetes Helm Setup](../../collector-setup/kubernetes-helm-setup.md) / [Linux Setup](../../collector-setup/linux-setup.md) for other runtimes. - [Scout Exporter](../../collector-setup/scout-exporter.md) for the OAuth2 + OTLP/HTTP exporter config. ### Access setup The `azure_monitor` receiver needs `Monitoring Reader` on the resource group containing your SQL servers. The role grants read on metric definitions and metric data only, no control-plane write. ```bash RG_ID=$(az group show --name --query id -o tsv) az role assignment create \ --assignee \ --role "Monitoring Reader" \ --scope "$RG_ID" ``` `azure_auth` supports four modes for the calling identity: `service_principal` (out-of-Azure collectors), `managed_identity` (Container Apps / Virtual Machine Scale Sets / Azure VM), `workload_identity` (Azure Kubernetes Service pods, federated to a ServiceAccount), and `use_default` (local dev). Full YAML for each mode and Workload Identity Federation setup is in the [Service Bus guide](./service-bus.md#authentication); the auth block is the only thing that differs between Azure surfaces, the rest of the config below is SQL-Database-specific. Role-Based Access Control (RBAC) propagation on the legacy Azure Resource Manager (ARM) `/metrics` endpoint is immediate. The data-plane batch API at `*.metrics.monitor.azure.com` requires separate propagation that lags 5-30 minutes after grant. This guide defaults `use_batch_api: true`; if the data plane is still 401-ing past that window, flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint (RBAC there is immediate). ### Receiver configuration This is the SQL-DB-specific addition to your collector. Add the `azure_auth` extension and `azure_monitor` receiver to your existing config, then wire the receiver into a metrics pipeline that exports to Scout (see [Scout Exporter](../../collector-setup/scout-exporter.md) for the exporter half - it's the same OAuth2 + OTLP/HTTP setup used by every Azure surface). ```yaml showLineNumbers title="otel-collector.yaml (excerpt)" extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor: subscription_ids: ["${env:AZURE_SUBSCRIPTION_ID}"] resource_groups: ["${env:AZURE_RESOURCE_GROUP}"] services: - Microsoft.Sql/servers/databases - Microsoft.Sql/servers/elasticPools auth: { authenticator: azure_auth } collection_interval: 60s # Metrics Data Plane (12k -> 360k calls/hour ceiling). RBAC propagates # 5-30 min after the Monitoring Reader grant; flip to false as a # temporary fallback to the legacy ARM /metrics endpoint if needed. use_batch_api: true cache_resources: 60 dimensions: { enabled: true } metrics: "Microsoft.Sql/servers/databases": cpu_percent: [] dtu_consumption_percent: [] dtu_used: [] dtu_limit: [] physical_data_read_percent: [] log_write_percent: [] storage: [] storage_percent: [] connection_successful: [] connection_failed: [] blocked_by_firewall: [] deadlock: [] sessions_percent: [] workers_percent: [] availability: [] replication_lag_seconds: [] xtp_storage_percent: [] "Microsoft.Sql/servers/elasticPools": cpu_percent: [] dtu_consumption_percent: [] eDTU_limit: [] eDTU_used: [] physical_data_read_percent: [] log_write_percent: [] storage_used: [] storage_limit: [] storage_percent: [] allocated_data_storage: [] allocated_data_storage_percent: [] sessions_percent: [] sessions_count: [] workers_percent: [] xtp_storage_percent: [] processors: resource: attributes: - { key: cloud.provider, value: azure, action: insert } - { key: cloud.platform, value: azure_sql_database, action: insert } - { key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert } - { key: cloud.region, value: "${env:AZURE_REGION}", action: insert } - { key: cloud.resource_id, value: "${env:AZURE_SQL_DATABASE_RESOURCE_ID}", action: insert } - { key: service.name, value: "${env:SERVICE_NAME}", action: insert } service: extensions: [azure_auth] # plus your existing extensions (oauth2client, etc.) pipelines: metrics: receivers: [azure_monitor] processors: [resource, batch] # plus your existing processors exporters: [otlphttp/b14] # the Scout exporter from the shared setup ``` Once `metrics:` is set for a namespace, the receiver only emits the metrics you list - there is no implicit "default + my picks" merge. Extend the list to add more (e.g., `tempdb_data_size: []` on Premium tier). The empty aggregation list `[]` per metric collects all aggregations Azure publishes for that metric. #### Environment variables ```bash showLineNumbers title=".env" # From `az ad sp create-for-rbac` output. AZURE_TENANT_ID= AZURE_CLIENT_ID= AZURE_CLIENT_SECRET= # From your Azure subscription / resource group. AZURE_SUBSCRIPTION_ID= AZURE_RESOURCE_GROUP= AZURE_REGION= AZURE_SQL_DATABASE_RESOURCE_ID= # az sql db show -g -s -n --query id -o tsv # Resource attribute defaults. SERVICE_NAME=azure-sql-database ``` `AZURE_SQL_DATABASE_RESOURCE_ID` is the full ARM resource ID of the database whose metrics you want to label most explicitly with `cloud.resource_id`. The `azure_monitor` receiver discovers every database in the configured resource group; this attribute is for the dashboard / filter convention, not for scoping the scrape. ### Key alerts to configure Threshold guidance for the most operationally useful series. Tune to your workload; these are starting points for a Basic/Standard tier with real traffic. | Metric (OTel name) | Warning | Critical | Why it matters | | ------------------------------------------- | --------- | --------- | -------------- | | `azure_dtu_consumption_percent_average` | > 75% / 5m | > 90% / 5m | Sustained DTU saturation throttles queries; precedes connection failures. | | `azure_cpu_percent_average` | > 80% / 5m | > 95% / 5m | CPU-bound workload; correlate with query plans before scaling tier. | | `azure_storage_percent_average` | > 75% | > 90% | Approaching `maxSizeBytes`; out-of-space halts writes on Basic / Standard. | | `azure_sessions_percent_average` | > 70% | > 90% | Connection-pool exhaustion; tier ceiling differs per SKU. | | `azure_workers_percent_average` | > 70% | > 90% | Concurrent-request ceiling; tier-specific. | | `azure_log_write_percent_average` | > 80% / 5m | > 95% / 5m | Write-throughput saturation; impacts replication lag. | | `azure_connection_failed_total` | > 0 / 5m | sustained > 0 / 15m | Auth, firewall, or TLS issues; investigate immediately when sustained. | | `azure_blocked_by_firewall_total` | > 0 / 5m | > 10 / 5m | Firewall blocking traffic; usually a misconfiguration. | | `azure_deadlock_total` | > 0 | > 5 / 5m | Application-side concurrency bug; any non-zero deserves investigation. | | `azure_replication_lag_seconds_average` | > 5s | > 30s | Geo-replication / read-scale-out drift; only relevant on Premium / BC / Hyperscale. | | `azure_availability_average` | < 100% / 1h | < 99.9% / 1h | SLA-compliant availability; PT1H grain. | For elastic pools, mirror `azure_dtu_consumption_percent_*`, `azure_storage_percent_*`, `azure_sessions_percent_*`, and `azure_workers_percent_*` against the pool resource using the same thresholds. ### Operations - **Collection interval.** 60 seconds is the sweet spot - Azure Monitor's ingestion lag is 1-3 minutes, so faster polls just re-read stale data. - **`cache_resources`.** This is the receiver's resource-list cache TTL in seconds (default 24h). The shipped config sets it to `60` so newly- created databases are visible to the receiver on the next poll - appropriate for a validation pass or for environments where databases come and go frequently. In a stable production fleet, raise it back toward the default (e.g., `3600` or higher) to skip the per-minute ARM resource-list call. - **RBAC propagation.** The legacy ARM `/metrics` endpoint propagates `Monitoring Reader` immediately. The newer data-plane batch API at `*.metrics.monitor.azure.com` requires separate RBAC propagation that can lag 5-30 minutes after grant. - **`use_batch_api: true` (default in this guide)** uses Azure Monitor's data-plane batch endpoint, which raises the per-tenant query rate ceiling from 12,000 to 360,000 calls/hour. RBAC propagation on the data plane lags 5-30 min after the Monitoring Reader grant; flip to `false` as a temporary fallback to the legacy ARM `/metrics` endpoint if you see persistent 401s past that window. - **System `master` database.** The receiver auto-discovers the system `master` database alongside your application databases and emits the same database-scope series for both. `master` is mostly noise - filter by `cloud.resource_id` in Scout if you want to ignore it. - **Tier-gated metrics.** A few names in the whitelist only emit when the underlying feature is configured: - `replication_lag_seconds` requires active geo-replication on the primary database. Available on Standard tier and above; Basic excluded. Only emitted on the primary, never on the secondary. - `xtp_storage_percent` requires Premium or Business Critical (in-memory Online Transaction Processing is not available below Premium). - `app_cpu_billed` and `app_cpu_percent` only emit on Serverless databases. The receiver polls these names regardless and silently returns no series on tiers that don't support the underlying feature, so the same config works across Database Transaction Unit (DTU), vCore, Serverless, and Hyperscale fleets. - **`InstanceAndAppAdvanced` category.** Add `tempdb_data_size`, `tempdb_log_size`, `tempdb_log_used_percent`, `sql_instance_cpu_percent`, and `sql_instance_memory_percent` to the whitelist if you want the detailed `tempdb` and instance-level series. They are not tier-gated - Microsoft's reference lists them without a tier minimum - but they emit only on databases not configured as data warehouses. ### Apps-side instrumentation This guide is metrics-only. For per-query distributed traces (the SQL client span linked through the application's request span), instrument your application code with the OTel SQL client integrations: - **.NET / C#:** `Microsoft.Data.SqlClient` 5.1+ emits OpenTelemetry spans via its built-in ActivitySource. Register `AddSource("OpenTelemetry.Instrumentation.SqlClient")` or use the `OpenTelemetry.Instrumentation.SqlClient` package. - **Java:** the OTel Java agent auto-instruments JDBC drivers including `mssql-jdbc`. No code changes. - **Python:** `opentelemetry-instrumentation-pymssql` and `opentelemetry-instrumentation-pyodbc` wrap the respective drivers. Run the apps-side spans alongside this metrics collector with distinct `service.name` values to keep the database-server view and the request-flow view separately filterable in Scout. ### Logs Architecture for the Diagnostic Settings → Event Hubs → `azure_event_hub` path is in the [overview](./overview.md#choosing-pull-push-or-both). The SQL Database log categories worth enabling: | Log category | What it captures | | --- | --- | | `SQLInsights` | Performance insights from Query Store | | `QueryStoreRuntimeStatistics` | Per-query execution stats: duration, rows, CPU | | `AutomaticTuning` | Index recommendations and applied actions | | `Errors` | Server-side errors | | `Deadlocks` | Deadlock graphs (the gold-standard signal for contention) | | `Blocks` | Blocking sessions | | `Timeouts` | Query timeouts | ```bash az monitor diagnostic-settings create \ --resource \ --name sql-to-eventhubs \ --logs '[{"category":"SQLInsights","enabled":true},{"category":"AutomaticTuning","enabled":true},{"category":"QueryStoreRuntimeStatistics","enabled":true},{"category":"Errors","enabled":true},{"category":"Deadlocks","enabled":true},{"category":"Blocks","enabled":true},{"category":"Timeouts","enabled":true}]' \ --event-hub-rule ``` Activity logs (control-plane operations on the SQL server) are **subscription-scoped**, not resource-scoped; configure them once per subscription via `az monitor diagnostic-settings subscription create`. ### Troubleshooting For common `azure_auth` and Azure Monitor issues (`AuthorizationFailed`, `403 Forbidden`, token-acquire 401, `RequestThrottled`, Docker DNS resolution, Scout OAuth2 401), see the [Service Bus troubleshooting section](./service-bus.md#troubleshooting); the same diagnoses apply to every Azure surface scraped via `azure_monitor`. Below are the issues specific to Azure SQL Database. #### No metrics in the first 3 minutes Azure Monitor has a 1-3 minute ingestion lag. `azure_storage` and `azure_dtu_limit` emit on every database from the first poll. Database Transaction Unit (DTU), connection, and lock metrics only show non-zero values after real workload on the database - control-plane calls (`az sql db show`) don't drive them. If the database is idle, that's expected. #### `connection_failed` / `blocked_by_firewall` / `deadlock` are absent Expected. These metrics are silent-when-quiet: Azure Monitor publishes a data point only when at least one event occurs in the time grain. Empty buckets return no point rather than a zero. Wire alerts on these to fire on series presence in window, not on numeric thresholds. #### `master` system database appears alongside application databases Expected. The `azure_monitor` receiver auto-discovers the system `master` database alongside your application database and emits the same database-scope series for both. `master` is mostly noise; filter by `cloud.resource_id` in Scout if you want to drop it. #### `replication_lag_seconds` series missing on the secondary Expected. The metric is only emitted on the primary database in an active geo-replication pair. The secondary's replication lag is observable from the primary's series, not from the secondary's. #### `xtp_storage_percent` series missing on Standard tier Expected. In-memory Online Transaction Processing (OLTP) is only available on Premium and Business Critical tiers; the metric is never published on lower tiers. Same for `app_cpu_billed` and `app_cpu_percent`, which only emit on Serverless databases. ### Frequently Asked Questions #### How do I monitor Azure SQL Database with OpenTelemetry? Run the OpenTelemetry Collector with the `azure_monitor` receiver targeting `Microsoft.Sql/servers/databases` (and optionally `Microsoft.Sql/servers/elasticPools` for pool-level metrics). The receiver polls Azure Monitor's REST API every 60 seconds, transforms metrics from Azure's lowercase names (like `dtu_consumption_percent`) to OTel-style names (`azure_dtu_consumption_percent_average`), and ships them via OTLP/HTTP to base14 Scout. Authentication uses the `azure_auth` extension in service-principal or managed-identity mode. #### Should I use this guide or the self-hosted SQL Server guide? Use this guide for Azure SQL Database (the managed PaaS). Use the [self-hosted SQL Server guide](../../component/sqlserver.md) if you run SQL Server yourself on a VM, on-premises, or in a container - that path uses `sqlserverreceiver` to scrape DMVs directly instead of polling Azure Monitor. The two are complementary, not redundant: `azure_monitor` reports Azure's external view (DTU billing, blocked-by-firewall, geo-replication lag, storage-vs-cap), while `sqlserverreceiver` reports SQL Server internals (wait stats, buffer pool, query store). Production deployments commonly run both with distinct `service.name` values to keep the two views separate in dashboards. #### Why does `connection_failed` return no data points? `connection_failed` is silent-when-quiet: Azure Monitor publishes a data point only when at least one connection failure (auth error, firewall block, TLS handshake failure) occurs in the time grain. Empty buckets return no point rather than a zero. Same shape applies to `connection_failed_user_error`, `blocked_by_firewall`, and `deadlock`. Wire alerts on these to fire on series presence in window, not on numeric thresholds. #### Why does the receiver emit both `_count` and `_total` suffixes for `connection_successful`? Azure Monitor publishes `connection_successful` with two supported aggregations: `Total` (sum) and `Count`. The receiver emits one OTel metric per published aggregation, producing `azure_connection_successful_total` and `azure_connection_successful_count` for the same source metric. Same applies to `connection_failed`, `blocked_by_firewall`, and `deadlock`. Pick whichever aggregation you prefer for dashboards; they carry the same information at the per-minute grain. #### Which metrics need higher tiers to emit non-zero values? `replication_lag_seconds` requires active geo-replication on the primary database (available on Standard tier and above; Basic excluded; only emitted on the primary). `xtp_storage_percent` requires Premium or Business Critical (in-memory Online Transaction Processing is not available below Premium). `app_cpu_billed` and `app_cpu_percent` only emit on Serverless databases. The receiver always polls these names; they simply return no series on tiers that don't support the underlying feature. #### Can I monitor elastic pools alongside individual databases? Yes - the shipped config covers both `Microsoft.Sql/servers/databases` and `Microsoft.Sql/servers/elasticPools`. The receiver returns no series for the elastic-pool namespace if the target server has no pools, so the same config is safe to run against servers that don't use pools. #### How does this differ from Application Insights for Azure SQL Database? Application Insights for Azure SQL is Azure-tenant-bound, billed per-GB ingested, and visualised in Azure dashboards or workbooks. The OpenTelemetry Collector is vendor-neutral - the same image ships to base14 Scout or any OTLP-compatible backend without redeployment. The metric coverage is identical - both surfaces draw from the same Azure Monitor REST API. ### Related Guides - [Self-hosted SQL Server](../../component/sqlserver.md) - paired guide for SQL Server you run yourself (VM, on-prem, container). Uses `sqlserverreceiver` to scrape DMVs directly. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. --- ## Azure Storage Monitoring with OpenTelemetry - Multi-Service Wiring for SREs ### Overview This guide is the **execution playbook** for Azure Storage. For the cross-surface architecture (auth, push vs pull, latency, the trace gap), read [Azure Monitoring with OpenTelemetry - Architecture for base14 Scout](./overview.md) first. This guide is for engineers running Azure Storage in production who want to add Storage telemetry to an existing OpenTelemetry Collector and ship it to base14 Scout. The collector polls Azure Monitor's REST API for `Microsoft.Storage/storageAccounts` (account-level rollup) **and the four sub-service namespaces** (`blobServices`, `queueServices`, `tableServices`, `fileServices`) every 60 seconds, emits OTel metric series, and exports via OTLP/HTTP. Nothing on the data plane. A storage account aggregates four otherwise-separate services. The `azure_monitor` receiver lets one config block scrape all of them in a single call, with the `azuremonitor.resource_id` data-point attribute splitting same-named metrics (`Transactions`, `Ingress`, `Egress`) across the account rollup and each sub-service. Drop sub-services you do not use by removing them from both `services:` and the `metrics:` map. This guide is metrics-only. For per-blob and per-queue audit trails (SAS-token usage, bucket-level access, individual operation logs), instrument with Diagnostic Settings (see [Logs](#logs)). ### Receiver configuration Add this fragment to your existing collector config. It contributes the `azure_auth` extension, an `azure_monitor` receiver scoped to all five Storage namespaces, a resource processor, and a metrics pipeline. Component keys are suffixed `/storage` so the fragment composes cleanly with other Azure-surface receivers in the same collector. ```yaml showLineNumbers title="otel-collector.yaml (Storage addition)" extensions: azure_auth: # Pick one of: service_principal, managed_identity, workload_identity. # See the Authentication section below for the right choice per # collector deployment surface. service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} receivers: azure_monitor/storage: subscription_ids: - ${env:AZURE_SUBSCRIPTION_ID} # Add more entries to scrape accounts across multiple subscriptions # in one collector. Each subscription needs its own Monitoring Reader # role assignment on the configured identity; the receiver fans out # queries across all subscription x resource-group combinations. resource_groups: - ${env:STORAGE_RESOURCE_GROUP} # Multi-resource-group scoping. Omit resource_groups entirely to # scrape every resource group in the listed subscriptions. services: - Microsoft.Storage/storageAccounts - Microsoft.Storage/storageAccounts/blobServices - Microsoft.Storage/storageAccounts/queueServices - Microsoft.Storage/storageAccounts/tableServices - Microsoft.Storage/storageAccounts/fileServices auth: authenticator: azure_auth collection_interval: 60s initial_delay: 1s # Data-plane batch API (*.metrics.monitor.azure.com). Lifts the # per-subscription rate ceiling from 12k to 360k calls/hour and is # the recommended default for fleets. Flip to false only as a # temporary fallback while data-plane RBAC propagates after a fresh # Monitoring Reader grant (5-30 min lag); the legacy ARM /metrics # endpoint propagates immediately. See Scale and rate limits. use_batch_api: true # Resource-list cache TTL in seconds. 86400 (24h) is the receiver # default and the right setting for a stable fleet. cache_resources: 86400 dimensions: enabled: true # The receiver only emits the metrics you list; there is no # implicit default + my picks merge. Empty aggregation list `[]` # requests all aggregations Azure Monitor publishes for the metric; # explicit lists narrow further (see Cardinality control). metrics: "Microsoft.Storage/storageAccounts": UsedCapacity: [Average] Transactions: [Total] Ingress: [Total] Egress: [Total] SuccessE2ELatency: [Average] SuccessServerLatency: [Average] Availability: [Average] "Microsoft.Storage/storageAccounts/blobServices": BlobCapacity: [Average] BlobCount: [Average] ContainerCount: [Average] IndexCapacity: [Average] Transactions: [Total] Ingress: [Total] Egress: [Total] "Microsoft.Storage/storageAccounts/queueServices": QueueCapacity: [Average] QueueCount: [Average] QueueMessageCount: [Average] Transactions: [Total] "Microsoft.Storage/storageAccounts/tableServices": TableCapacity: [Average] TableCount: [Average] TableEntityCount: [Average] Transactions: [Total] "Microsoft.Storage/storageAccounts/fileServices": FileCapacity: [Average] FileCount: [Average] FileShareCount: [Average] Transactions: [Total] processors: resource/storage: attributes: - {key: cloud.provider, value: azure, action: insert} - {key: cloud.platform, value: azure_storage, action: insert} - {key: cloud.account.id, value: "${env:AZURE_SUBSCRIPTION_ID}", action: insert} - {key: cloud.region, value: "${env:STORAGE_REGION}", action: insert} # cloud.resource_id pins all metrics to one account. Drop this line # for multi-account fleets; the receiver injects azuremonitor.resource_id # per-resource automatically (with the sub-service path appended on # blob/queue/table/file series). - {key: cloud.resource_id, value: "${env:STORAGE_RESOURCE_ID}", action: insert} - {key: service.name, value: "${env:STORAGE_SERVICE_NAME}", action: insert} service: extensions: [azure_auth] # keep your existing extensions alongside pipelines: metrics/storage: receivers: [azure_monitor/storage] processors: [memory_limiter, resource/storage, batch] # plus your existing processors exporters: [otlphttp/b14] # your Scout exporter ``` The receiver, resource processor, and pipeline are all keyed `/storage` so they coexist with other Azure receivers (Service Bus, Cosmos DB, SQL Database, Front Door, Application Gateway) in a single collector. Your Scout exporter (`oauth2client` + `otlphttp/b14`) stays unchanged; one Scout pipeline serves every Azure surface. For multi-subscription scoping, the `subscription_ids:` list takes any number of entries; alternatively set `discover_subscriptions: true` to scrape every subscription the configured identity has `Monitoring Reader` on: ```yaml receivers: azure_monitor/storage: discover_subscriptions: true # replaces subscription_ids ``` See [Scale and rate limits](#scale-and-rate-limits) for the trade-off between explicit lists and discovery. #### Removing Storage from the collector To stop scraping Storage without affecting other surfaces in the same collector: delete the `azure_monitor/storage` receiver block, the `resource/storage` processor, and the `metrics/storage` pipeline; drop the storage-specific environment variables; and restart the collector. The `azure_auth` extension and Scout exporter stay, serving every other Azure surface in the same config. Revoke the `Monitoring Reader` role assignment on the resource group only if no other surface uses the same identity scope. ### Authentication `azure_auth` supports five modes. Pick the one matching where the collector runs. | Collector deployment | Recommended mode | Why | | --- | --- | --- | | Azure Kubernetes Service (AKS) pod | `workload_identity` | Federated credential, no secret to rotate, scoped to the ServiceAccount. | | Container Apps | `managed_identity` (system or user-assigned) | First-class integration, no secret to rotate. | | Virtual Machine Scale Sets / Azure VM | `managed_identity` (user-assigned) | User-assigned identity survives instance replacement; system-assigned dies with the instance. | | External or on-prem | `service_principal` | Only option without an Azure-resident identity. | | Local dev / ad-hoc | `use_default: true` | Falls back to the Azure SDK default credential chain (CLI, env, managed identity). | #### Workload Identity Federation (Azure Kubernetes Service) Bind a federated credential on a Microsoft Entra app registration to your collector's Kubernetes ServiceAccount; the collector mounts a token file and exchanges it for an Azure access token on every request. No client secret, no rotation, scoped to the ServiceAccount. ```yaml extensions: azure_auth: workload_identity: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} # the user-assigned managed identity's clientId federated_token_file: /var/run/secrets/azure/tokens/azure-identity-token ``` Setup: 1. Enable the workload-identity addon on the AKS cluster (`az aks update --enable-workload-identity --enable-oidc-issuer`). 2. Create a user-assigned managed identity, capture its `clientId` and `principalId`. 3. Add a federated credential to the managed identity scoped to your ServiceAccount: ```bash az identity federated-credential create \ --name otel-collector-fed \ --identity-name otel-collector-mi \ --resource-group \ --issuer "$(az aks show -g -n --query oidcIssuerProfile.issuerUrl -o tsv)" \ --subject "system:serviceaccount::" ``` 4. Annotate the ServiceAccount: `azure.workload.identity/client-id: `. 5. Label the collector pod: `azure.workload.identity/use: "true"`. 6. Grant `Monitoring Reader` to the managed identity's `principalId` on every Storage resource group it should scrape. #### Managed Identity (Container Apps, Virtual Machine Scale Sets, Azure VM) ```yaml extensions: azure_auth: managed_identity: # System-assigned: omit client_id; the resource's identity is used. # User-assigned: provide the client_id of the assigned managed identity. client_id: ${env:AZURE_CLIENT_ID} # optional for system-assigned ``` Container Apps: assign system-assigned managed identity on the app (`az containerapp identity assign --system-assigned`); grant the resulting `principalId` `Monitoring Reader` on each target resource group. #### Service Principal (out-of-Azure collectors) ```yaml extensions: azure_auth: service_principal: tenant_id: ${env:AZURE_TENANT_ID} client_id: ${env:AZURE_CLIENT_ID} client_secret: ${env:AZURE_CLIENT_SECRET} ``` `AZURE_CLIENT_SECRET` is the only credential that needs rotation; see [Service principal credential lifecycle](#service-principal-credential-lifecycle). #### RBAC scope `Monitoring Reader` at the resource group containing your storage accounts is sufficient and minimal. The role grants read on metric definitions and metric data only; no control-plane write, no data-plane access. `Reader` is not required. ```bash RG_ID=$(az group show --name --query id -o tsv) az role assignment create \ --assignee \ --role "Monitoring Reader" \ --scope "$RG_ID" ``` The collector's identity needs only `Monitoring Reader`. The four data-plane roles (`Storage Blob Data Contributor`, `Storage Queue Data Contributor`, `Storage Table Data Contributor`, `Storage File Data SMB Share Contributor`) are for **operators uploading test content or applications doing data-plane I/O**, not for the collector. Granting them to the collector identity is unnecessary and expands blast radius. For multi-subscription fleets, repeat the assignment on each subscription's resource group. Subscription-scoped assignments work too if the managed identity or service principal should see every storage account in a subscription. This guide defaults `use_batch_api: true` (data-plane batch API at `*.metrics.monitor.azure.com`) for the higher rate ceiling. RBAC on that endpoint lags 5-30 minutes after a fresh `Monitoring Reader` grant. If the receiver returns 401s in that window, temporarily flip to `use_batch_api: false` (legacy ARM `/metrics`, immediate propagation) and revert once the data-plane RBAC settles. ### What you'll monitor Storage publishes metrics across **five namespaces**: the account-level rollup plus four sub-services. The receiver renames Azure's PascalCase metric names (e.g. `BlobCapacity`) to OTel-style `azure__` (e.g. `azure_blobcapacity_average`). The metric tables below cover Standard-tier accounts; Premium block-blob and Premium file-share accounts publish additional series - see [Premium-tier additions](#premium-tier-additions). The metrics split into two grain bands with very different operational characteristics: - **PT1M Transaction-class** (request throughput, byte-throughput, latency, availability) - flow through the receiver within 2-3 minutes of the first traffic. Drives request-flow dashboards, latency SLOs, and availability alerts. - **PT1H Capacity-class** (capacity, count, message-count) - known receiver gap under v0.151.0 with sub-hour `collection_interval`. See [The PT1H capacity-metric gap](#the-pt1h-capacity-metric-gap). #### Account rollup (`Microsoft.Storage/storageAccounts`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `Transactions` | `azure_transactions_total` | Count | Per-minute API call count to the account, summed across all sub-services. The headline rate metric. | | `Ingress` | `azure_ingress_total` | Bytes | Total ingress bytes per minute, all sub-services. | | `Egress` | `azure_egress_total` | Bytes | Total egress bytes per minute, all sub-services. | | `SuccessE2ELatency` | `azure_successe2elatency_average` | ms | End-to-end latency including network. | | `SuccessServerLatency` | `azure_successserverlatency_average` | ms | Server-side latency excluding network. Subtract from `SuccessE2ELatency` to get network round-trip. | | `Availability` | `azure_availability_average` | Percent | Fraction of successful billable requests, across the account. Drop below 99.9% is page-worthy. | | `UsedCapacity` | `azure_usedcapacity_average` | Bytes | Account-level total bytes stored. **PT1H grain - see capacity gap.** | #### Blob service (`.../blobServices`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `Transactions` | `azure_transactions_total` | Count | Blob-only API calls. Pairs with account-level `Transactions` to see Blob's share of total traffic. | | `Ingress` | `azure_ingress_total` | Bytes | Blob-service ingress bytes. | | `Egress` | `azure_egress_total` | Bytes | Blob-service egress bytes. | | `BlobCapacity` | `azure_blobcapacity_average` | Bytes | Bytes stored in blobs. Splits by `BlobType` (BlockBlob, PageBlob, AppendBlob) and `Tier` (Hot, Cool, Cold, Archive). **PT1H grain.** | | `BlobCount` | `azure_blobcount_average` | Count | Number of blobs. **PT1H grain.** | | `ContainerCount` | `azure_containercount_average` | Count | Number of containers in the account. **PT1H grain.** | | `IndexCapacity` | `azure_indexcapacity_average` | Bytes | ADLS Gen2 hierarchical-namespace index size. **PT1H grain.** Always 0 for non-HNS accounts. | #### Queue service (`.../queueServices`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `Transactions` | `azure_transactions_total` | Count | Queue-only API calls (PutMessage, GetMessages, DeleteMessage, etc.). | | `QueueCapacity` | `azure_queuecapacity_average` | Bytes | Bytes stored across all queues. **PT1H grain.** | | `QueueCount` | `azure_queuecount_average` | Count | Number of queues in the account. **PT1H grain.** | | `QueueMessageCount` | `azure_queuemessagecount_average` | Count | Total unexpired queue messages. **PT1H grain.** Use the rate of change as a proxy for backlog growth, since the gauge itself is hourly. | #### Table service (`.../tableServices`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `Transactions` | `azure_transactions_total` | Count | Table-only API calls (InsertEntity, QueryEntities, DeleteEntity, etc.). | | `TableCapacity` | `azure_tablecapacity_average` | Bytes | Bytes stored across all tables. **PT1H grain.** | | `TableCount` | `azure_tablecount_average` | Count | Number of tables in the account. **PT1H grain.** | | `TableEntityCount` | `azure_tableentitycount_average` | Count | Total entities across all tables. **PT1H grain.** | #### File service (`.../fileServices`) | Azure REST name | OTel emitted | Unit | What it tells you | | --- | --- | --- | --- | | `Transactions` | `azure_transactions_total` | Count | File-only API calls (CreateFile, PutRange, ReadFile, etc.). | | `FileCapacity` | `azure_filecapacity_average` | Bytes | Bytes stored across all file shares. Splits by `FileShare` and `Tier`. **PT1H grain.** | | `FileCount` | `azure_filecount_average` | Count | Number of files across all shares. **PT1H grain.** | | `FileShareCount` | `azure_filesharecount_average` | Count | Number of file shares in the account. **PT1H grain.** | The same five `metadata_*` dimensions ride alongside Transactions / Ingress / Egress / latency / availability metrics: `metadata_apiname`, `metadata_authentication`, `metadata_geotype`, `metadata_responsetype`, and `metadata_transactiontype`. They split the namespace-scope series into per-operation, per-auth-mode, and per-error-class series automatically. See [Cardinality control](#cardinality-control) for shaping advice. **Silent-when-quiet caveat.** Azure Monitor returns data points for the latency and availability metrics only when the underlying activity occurs. A blob-only account with no traffic emits zero series for `Transactions`, `Ingress`, `Egress`, `SuccessE2ELatency`, `SuccessServerLatency`, and `Availability` until the first request. Wire alerts on these to fire on series presence in window (any non-zero point), not on threshold crossings, since the absence of points is the steady state. **`Availability` per sub-service.** Microsoft Learn exposes `Availability` (and the latency / Ingress / Egress metrics) at each sub-service namespace too. The whitelist above scopes them at account-level only because the account rollup is the SLI most operators alert on; if you need per-sub-service availability, add the metric to the relevant namespace in `metrics:` and validate end-to-end on a representative account before committing dashboards. ### The PT1H capacity-metric gap Capacity-class metrics (`UsedCapacity`, `BlobCapacity`, `BlobCount`, `ContainerCount`, `IndexCapacity`, `QueueCapacity`, `QueueCount`, `QueueMessageCount`, `TableCapacity`, `TableCount`, `TableEntityCount`, `FileCapacity`, `FileCount`, `FileShareCount`) are published by Azure Monitor at PT1H grain only. Direct probes via `az monitor metrics list --interval PT1H` confirm Azure Monitor has the data within the first hour after account creation; `azure monitor metrics list-definitions --resource ` lists each capacity metric with its time-grain shown as PT1H. Under the v0.151.0 `azuremonitorreceiver`, capacity-class metrics do **not reliably surface** with a `collection_interval` shorter than the metric's own time grain. The receiver's `loadMetricsValues` passes each metric's `metricAvailabilities[0].TimeGrain` directly as both `Interval` and `Timespan` to Azure Monitor's metrics REST API; the resulting query window is too narrow for hourly-aggregated metrics to come back populated, particularly for accounts younger than a couple of hours. Issue [#46047](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/46047) in opentelemetry-collector-contrib tracks the underlying class of problem. Three workarounds, ordered by operational fit: #### 1. Run a separate slow-poll receiver instance for capacity The cleanest fix. Keep the fast receiver at `collection_interval: 60s` for Transaction-class metrics, add a second receiver at `collection_interval: 3600s` scoped to capacity-class metrics only. ```yaml receivers: azure_monitor/storage: # ...existing 60s config keeps Transaction-class metrics flowing... metrics: "Microsoft.Storage/storageAccounts": Transactions: [Total] Ingress: [Total] Egress: [Total] SuccessE2ELatency: [Average] SuccessServerLatency: [Average] Availability: [Average] "Microsoft.Storage/storageAccounts/blobServices": Transactions: [Total] Ingress: [Total] Egress: [Total] # ...trim capacity entries from this fast receiver... azure_monitor/storage-capacity: subscription_ids: [${env:AZURE_SUBSCRIPTION_ID}] resource_groups: [${env:STORAGE_RESOURCE_GROUP}] services: - Microsoft.Storage/storageAccounts - Microsoft.Storage/storageAccounts/blobServices - Microsoft.Storage/storageAccounts/queueServices - Microsoft.Storage/storageAccounts/tableServices - Microsoft.Storage/storageAccounts/fileServices auth: { authenticator: azure_auth } collection_interval: 3600s # match the PT1H grain metrics: "Microsoft.Storage/storageAccounts": UsedCapacity: [Average] "Microsoft.Storage/storageAccounts/blobServices": BlobCapacity: [Average] BlobCount: [Average] ContainerCount: [Average] IndexCapacity: [Average] "Microsoft.Storage/storageAccounts/queueServices": QueueCapacity: [Average] QueueCount: [Average] QueueMessageCount: [Average] "Microsoft.Storage/storageAccounts/tableServices": TableCapacity: [Average] TableCount: [Average] TableEntityCount: [Average] "Microsoft.Storage/storageAccounts/fileServices": FileCapacity: [Average] FileCount: [Average] FileShareCount: [Average] service: pipelines: metrics/storage: receivers: [azure_monitor/storage, azure_monitor/storage-capacity] processors: [memory_limiter, resource/storage, batch] exporters: [otlphttp/b14] ``` Both receivers share the same pipeline and resource processor; only the receiver-list contains both. Capacity metrics flow once per hour per resource, which is the rate Azure Monitor publishes them anyway. The slow receiver consumes ~24 ARM API calls per resource per day, negligible against the 12,000/hour per-subscription ceiling. #### 2. Diagnostic Settings forwarding (Log Analytics or Event Hubs) Two distinct paths under one option, depending on whether you want the capacity data inside Scout or queryable separately: - **Log Analytics (KQL only).** Configure Diagnostic Settings on each account to forward `AllMetrics` to a Log Analytics workspace. Capacity is queryable via KQL against the `AzureMetrics` table. This path keeps capacity outside Scout - useful if Log Analytics is already the source of truth for capacity reports, but dashboards alongside Scout metrics need a separate query surface. - **Event Hubs → `azure_event_hub` receiver.** Configure Diagnostic Settings to forward `AllMetrics` to an Event Hub, then ingest into the same collector via the `azure_event_hub` receiver. Capacity lands as OTel metrics in Scout under a different namespace from the `azure_*` receiver-emitted series; alert and dashboard queries must select on the new metric names. Pick Log Analytics if you only want trend visibility outside Scout; pick Event Hubs if you need capacity in the same Scout dashboards as the rest of the Storage telemetry. #### 3. Compute capacity from `az` CLI on a cron Lightweight scripted approach for low-account-count environments: poll `az monitor metrics list --interval PT1H` from a cron and emit to a `pushgateway`-style receiver. Acceptable for fewer than 20 accounts; does not scale to fleets. Note that this lands as a separate metric series, not under the `azure_*` namespace; query and dashboard names will not match the receiver-emitted series. ### Scale and rate limits The receiver fans out per-resource queries to Azure Monitor's REST API. Multi-namespace scoping multiplies the per-account query rate by the number of sub-services scraped: a single account with all five namespaces scoped is **5x the query rate** of a single-namespace surface like Cosmos DB. Azure Monitor enforces two ceilings: | Endpoint | Rate limit | When it applies | | --- | --- | --- | | Data-plane batch (`use_batch_api: true`) | 360,000 calls / hour / subscription | Default in this guide. RBAC lags 5-30 min after the Monitoring Reader grant. | | Legacy Azure Resource Manager `/metrics` (`use_batch_api: false`) | 12,000 calls / hour / subscription | Temporary fallback if the data plane is still 401-ing after RBAC propagation should have completed. Immediate RBAC propagation. | At a 60-second collection interval with all five namespaces and ~25 metrics whitelisted across them, a single storage account costs roughly 300 calls per hour to Azure Monitor (one call per resource per metric per poll, deduplicated within the receiver). Even small fleets benefit from `use_batch_api: true` because batched fan-out is more rate-limit-friendly than per-metric ARM calls; flip to `false` only as a temporary fallback while data-plane RBAC settles. Storage's multi-namespace shape makes the budget calculation more sensitive to namespace coverage than to account count: dropping the File or Table sub-service from `services:` and `metrics:` reduces query rate proportionally. If your fleet uses only Blob and Queue, shed the other two namespaces. ```yaml receivers: azure_monitor/storage: # Pick one of two scoping patterns: # 1. Explicit list: subscription_ids: [...] (predictable, audit-friendly). # 2. Discovery: discover_subscriptions: true (any sub the configured # identity has Monitoring Reader on; no list to maintain as orgs # add subs). subscription_ids: - ${env:HUB_SUB_ID} - ${env:WORKLOAD_SUB_1} - ${env:WORKLOAD_SUB_2} services: - Microsoft.Storage/storageAccounts - Microsoft.Storage/storageAccounts/blobServices - Microsoft.Storage/storageAccounts/queueServices # File and Table dropped - the workload uses only Blob and Queue. auth: { authenticator: azure_auth } use_batch_api: true # 360k/h ceiling per sub cache_resources: 86400 # receiver default (24h) ``` The receiver shares one rate-limit budget across all subscriptions in the list; it does not bypass per-subscription quotas. Splitting heavy subscriptions across separate collector instances lifts the aggregate ceiling linearly. `cache_resources` is the resource-list cache TTL in seconds. The receiver default is `86400` (24 hours). Lower to `3600` or `600` only if storage accounts are created and destroyed frequently enough that 24-hour-stale resource lists become a problem; per-minute resource-list calls otherwise burn ARM rate-limit budget for no benefit. ### Cardinality control By default, the receiver emits one OTel series per `(resource × metric × aggregation × dimension-combination)`. Storage's `metadata_*` dimension shape produces high cardinality on `Transactions` and the latency / availability metrics: - `metadata_apiname` - one value per distinct Storage API operation (PutBlob, GetBlob, PutMessage, GetMessages, InsertEntity, QueryEntities, CreateFile, PutRange, etc.). Typical fleets exercise 20-50 distinct API operations per account; this is the dominant cardinality multiplier. - `metadata_authentication` - `OAuth`, `AccountKey`, or `SAS`. Two-to-three values in mixed-mode environments; one-or-two in single-mode. - `metadata_geotype` - `Primary` for LRS / ZRS; both `Primary` and `Secondary` for GRS / RA-GRS / GZRS. - `metadata_responsetype` - `Success` plus error classes (`ClientThrottlingError`, `ClientOtherError`, `ServerOtherError`, `ServerTimeoutError`, etc.) emitted only when the condition occurs. Silent-when-quiet on healthy accounts. - `metadata_transactiontype` - `user` plus optionally `system` for internal operations. A representative single-account baseline emits roughly **220 active series** during steady traffic across all five namespaces with all six PT1M metrics enabled and ~10 distinct API operations exercised. Extrapolating to a 50-account fleet averaging 30 distinct API operations and dual-mode auth: ```text ~50 accounts × 5 namespaces × ~6 metrics × 30 apiname × 2 auth ≈ 90,000 active series ``` `metadata_responsetype` adds another 1.5-3x growth on the `Transactions` series during error spikes. Three control levers, in order of preference: 1. **`dimensions.overrides`** drops or whitelists dimensions per metric. Drop `metadata_apiname` on namespaces where per-operation granularity is not actionable for alerting; drop `metadata_authentication` where authentication mode does not change incident routing. ```yaml azure_monitor/storage: dimensions: enabled: true overrides: "Microsoft.Storage/storageAccounts": Transactions: - metadata_apiname # keep - metadata_responsetype # keep Ingress: - metadata_apiname # keep # drop authentication, geotype, transactiontype SuccessE2ELatency: - metadata_apiname # keep for per-op latency # drop the rest; reduces five-dim fan-out to one ``` 2. **Aggregation-list narrowing.** Replace `[]` with explicit lists to drop the high-cost aggregations. For latency metrics, `[Average, Minimum, Maximum]` saves two series per resource per dimension combination. The `_count` and `_total` aggregations on a duration metric are sums of the latency values themselves, not call counts; they are usually noise. 3. **Per-account receiver instances.** Split high-cardinality accounts (the hub account that everyone writes to) into a separate `azure_monitor/storage-bigfleet` receiver with a narrower `metadata_*` override profile, while letting `azure_monitor/storage` stay broad on lower-traffic accounts. Both contribute to the same `metrics/storage` pipeline. Watch the `otelcol_processor_batch_metadata_cardinality` self-metric on the collector's Prometheus self-telemetry endpoint (port 8888 by default) to see actual cardinality after `overrides` apply. #### Storage-specific cardinality bug to watch Issue [#45942](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942) (open as of 2026-05): for Microsoft.Storage namespaces, `metadata_*` attributes occasionally arrive case-mismatched (for example, `Standard_LRS` versus `standard_lrs` on certain SKU-related dimensions). Aggregating across the case-mismatched values double-counts. The bug is intermittent and namespace-specific to Storage; it does not always manifest. Workaround: normalise the dimension fields downstream with the collector's `transform` processor, or apply lower-casing in Scout queries. Track the issue for resolution; v0.151.0 has the bug, future releases may not. ### Alert tuning Threshold guidance for the high-signal series. Numbers are starting points for a Standard_LRS account with steady traffic; derive your own from observed 99th-percentile baselines over a representative week. For `azure_responsetype`-split error series and the `Availability` metric, fire alerts on series presence in window rather than numeric thresholds - see the [silent-when-quiet caveat](#what-youll-monitor) above. | Metric (OTel name) | Warning | Critical | Why it matters | | --- | --- | --- | --- | | `azure_availability_average` (account-level) | < 99.9% over 5m | < 99.0% over 15m | Below 99.9% indicates Azure Storage degradation in the region or capacity-quota issues on the account. | | `azure_transactions_total` filtered to `metadata_responsetype="ClientThrottlingError"` | `> 0` over 5m | `> 0` over 15m | Account-level throttling. Either traffic exceeded the per-account request-rate ceiling (varies by account kind and SKU; see [scalability targets](https://learn.microsoft.com/azure/storage/common/scalability-targets-standard-account)) or per-partition limits hit. | | `azure_transactions_total` filtered to `metadata_responsetype="ServerTimeoutError"` | `> 0` over 5m | `> 0` over 15m | Server-side errors. Cross-check Azure Service Health for incidents. | | `azure_successe2elatency_average` (per `metadata_apiname`) | > 1000 ms | > 5000 ms | End-to-end latency including network. Compare with `azure_successserverlatency_average` to localise to network vs server. | | `azure_blobcapacity_average` / quota (PT1H, capacity gap caveat) | > 80% of account quota | > 95% | Standard accounts have a 5 PiB per-account capacity ceiling. Approach with at least 30 days of buffer at the current growth rate. | | `azure_queuemessagecount_average` per queue (PT1H, capacity gap caveat) | > 99th-pct baseline | sustained > 5x baseline | Queue backlog growing faster than consumers drain. Pair with `Transactions` filtered to `metadata_apiname="GetMessages"` to confirm consumer side. | #### RED method on the storage account For SLO-backed services, map Storage metrics as follows: | RED letter | Metric | Slicing | | --- | --- | --- | | Rate | `azure_transactions_total` | per account; slice by `metadata_apiname` for per-operation rate. | | Errors (availability) | `azure_transactions_total` filtered to `metadata_responsetype` in `ClientThrottlingError`, `ServerTimeoutError`, `ServerOtherError` | platform-on-call signal: Azure or capacity envelope broken. | | Errors (request-quality) | `azure_transactions_total` filtered to `metadata_responsetype="ClientOtherError"` | service-team signal: application is misusing Storage. | | Duration | `azure_successe2elatency_average` (and `_minimum` / `_maximum`) | per `metadata_apiname`. Subtract `azure_successserverlatency_average` for network round-trip. | For saturation (the U in USE), pair `azure_usedcapacity_average / account_quota` (PT1H), `azure_transactions_total` against the [per-account scalability ceiling](https://learn.microsoft.com/azure/storage/common/scalability-targets-standard-account), and the throttling-response signal above. Per-operation client-side latency belongs in the application code - see [Apps-side instrumentation](#apps-side-instrumentation). ### Premium-tier additions Premium block-blob accounts (`kind: BlockBlobStorage`) and Premium file shares (`kind: FileStorage` or premium share within a StorageV2 account) carry a different metric subset. Premium block blob adds: - `BlobProvisionedSize` (account capacity ceiling, separate from `BlobCapacity` actual usage). Premium file shares add: - `FileShareProvisionedIOPS` (provisioned IOPS per share). - `FileShareProvisionedBandwidthMiBps` (provisioned bandwidth per share). - `FileShareMaxUsedIOPS` (peak IOPS used in the latest minute). - `FileShareMaxUsedBandwidthMiBps` (peak bandwidth used). - `FileShareAvailableBurstCredits` (burst credits remaining). - `FileShareSnapshotCount`, `FileShareSnapshotSize` (snapshot metrics). - `PercentFileShareUtilization` (utilisation gauge, SLI category). When the account is Premium, extend the whitelist on the relevant sub-namespace: ```yaml metrics: "Microsoft.Storage/storageAccounts/fileServices": # ...the four Standard-tier metrics above... FileShareProvisionedIOPS: [Average] FileShareProvisionedBandwidthMiBps: [Average] FileShareMaxUsedIOPS: [Maximum] FileShareMaxUsedBandwidthMiBps: [Maximum] FileShareAvailableBurstCredits: [Average] PercentFileShareUtilization: [Average] ``` The `FileShare` dimension splits these per share; alert on `PercentFileShareUtilization > 80%` to stay ahead of provisioned-IOPS exhaustion. ### Service principal credential lifecycle If you run a service principal (collector outside Azure), rotate the client secret before its expiry, not after. #### Proactive rotation (zero-downtime) ```bash # 0. Capture the current credential's keyId BEFORE rotating, so step 4 # knows which one to revoke. OLD_KEY_ID=$(az ad app credential list --id "$AZURE_CLIENT_ID" \ --query "sort_by([], &endDateTime)[0].keyId" -o tsv) # 1. Append a new credential alongside the existing one. --append is # what makes this zero-downtime: without it, the previous # credential is revoked immediately and the collector errors until # the new value reaches its secret store. NEW_RESULT=$(az ad app credential reset \ --id "$AZURE_CLIENT_ID" \ --append \ --years 1 \ -o json) NEW_SECRET=$(echo "$NEW_RESULT" | jq -r .password) NEW_KEY_ID=$(echo "$NEW_RESULT" | jq -r .keyId) # 2. Update the collector's secret store with $NEW_SECRET. # 3. Restart or hot-reload the collector. Wait for /metrics on the # collector's self-telemetry to confirm it auth'd successfully. # 4. Revoke the old credential. az ad app credential delete --id "$AZURE_CLIENT_ID" --key-id "$OLD_KEY_ID" ``` Set a calendar alert 30 days before secret expiry. The federated-credential alternative (Workload Identity Federation for AKS, system-assigned managed identity for Container Apps) eliminates the rotation entirely; if the collector runs in Azure, prefer that path. ### Apps-side instrumentation This guide is metrics-only. To produce per-operation distributed traces (client span linked through the storage call to server-side processing), instrument your application code with one of these OTel Storage SDK integrations: - **.NET / C#:** `Azure.Storage.Blobs`, `Azure.Storage.Queues`, `Azure.Data.Tables`, `Azure.Storage.Files.Shares` ship built-in ActivitySource emission. Add `OpenTelemetry.Extensions.Hosting` and register `AddSource("Azure.*")` (or specific `Azure.Storage.Blobs`, etc.) to forward client spans. - **Java:** the OTel Java agent (`opentelemetry-javaagent.jar`) auto-instruments the Azure SDK (`com.azure:azure-storage-blob`, `com.azure:azure-storage-queue`, etc.) via the `azure-core-tracing-opentelemetry` adapter. No code changes. - **Python:** the OTel community `opentelemetry-instrumentation-azure-storage` package wraps `azure-storage-blob`, `azure-storage-queue`, `azure-data-tables`, and `azure-storage-file-share`. Verify span shape per language version before promoting. - **Node.js / Go:** no first-party OTel auto-instrumentation as of 2026-05. Manual span creation around `BlobClient.upload`, `QueueClient.sendMessage`, etc., is the workaround. Run apps-side spans alongside this metrics collector with distinct `service.name` values to keep the platform view (this guide) and the request-flow view separately filterable in Scout. ### Logs Log-driven analysis fills three gaps that the metrics in this guide do not cover: - **Per-IP read audit.** `Transactions` carries dimensions like `metadata_authentication` and `metadata_responsetype` but no client IP or blob path. `StorageRead` log records carry the requester IP, the requested URL, and the blob / object key in their `properties` envelope - required for any compliance regime that needs a per-request audit trail. - **Per-blob write attribution.** `Ingress` and account-level `Transactions` show write throughput and counts but not which blob was overwritten by which principal at which timestamp. `StorageWrite` records carry the `identity` block (token type plus principal / oauth-app ID) alongside the blob path, etag, and request URL - required for ransomware-style investigation and for tying writes to specific service principals or applications. - **Per-key delete forensics.** Deletes are the destructive event most often investigated post-hoc; the metrics show counts only. `StorageDelete` records carry the blob path, the deleting identity, the snapshot etag (so snapshot deletes are distinguishable from current-blob deletes), and a per-request `requestId` for cross-correlation with application logs. Storage publishes per-sub-service log categories. All four sub-services expose the same three categories; enable per sub-service whose data you want to audit: | Sub-service | Log category | What it captures | | --- | --- | --- | | `blobServices` | `StorageRead`, `StorageWrite`, `StorageDelete` | Per-blob operations with identity, requester IP, URL, status, etag, server-latency. | | `queueServices` | `StorageRead`, `StorageWrite`, `StorageDelete` | Per-message operations (peek, put, dequeue, clear). | | `tableServices` | `StorageRead`, `StorageWrite`, `StorageDelete` | Per-entity operations (query, insert, merge, delete). | | `fileServices` | `StorageRead`, `StorageWrite`, `StorageDelete` | Per-file SMB and REST operations. | ```bash SA_RES_ID=$(az storage account show -n -g --query id -o tsv) for SUB in blobServices queueServices tableServices fileServices; do az monitor diagnostic-settings create \ --resource "$SA_RES_ID/$SUB/default" \ --name "$SUB-to-eventhubs" \ --logs '[{"category":"StorageRead","enabled":true},{"category":"StorageWrite","enabled":true},{"category":"StorageDelete","enabled":true}]' \ --event-hub \ --event-hub-rule done ``` The recommended pattern is **Diagnostic Settings to Event Hubs to the `azure_event_hub` receiver** in the same collector. The receiver ingests the Azure resource log envelope (`format: azure`, `apply_semantic_conventions: true`), lifts each `records[]` entry into a structured OTel log carrying the envelope's `time`, `category`, `operationName`, `identity`, and `properties` fields, and routes them to Scout via the same `oauth2client` / `otlphttp/b14` pipeline used for metrics. Verify the exact OTel attribute names produced by your collector version against the receiver's documentation before pinning alert rules to specific paths. Reference fragment lives at `components/azure-storage-telemetry/config/scraper-fragment-logs.yaml` in the example, with a runnable `provision-logs.sh` that stands up an EH Basic-tier namespace + 1 hub + 2 SAS rules (`diagsend` Send for Diagnostic Settings, `collectorlisten` Listen for the receiver) in ~30-60 seconds. Two operational notes for production fleets: - **At-least-once delivery on collector restart.** The receiver tracks partition offsets in memory by default. A rolling-restart deploy replays unflushed records from the EH offset, producing duplicates equal to whatever was in the in-flight batch at restart time. Add a `storage:` extension wired to a checkpoint store (Azure Blob Storage container or local volume) when exactly-once semantics are required. Alternatively, downstream-deduplicate on the envelope's `(time, operationName, objectKey)` triple, or on the per-request `requestId` UUID generated by the storage service. - **Log volume is workload-driven.** A blob-heavy workload (background ETL, log ingestion pipelines, image hosts) generates 1-3 records per client operation; a quiet account costs a few records per minute. `StorageDelete` is the lowest-volume, highest-value category if budget pressure forces selective enablement. Activity logs (control-plane operations on the account itself - account creation, SKU change, key rotation) are **subscription-scoped** and not part of the per-sub-service Diagnostic Settings configured above. Configure once per subscription via `az monitor diagnostic-settings subscription create`; the same `azure_event_hub` receiver consumes them from the EH namespace once wired. ### Troubleshooting #### `AuthorizationFailed` from the receiver Data-plane batch API (`use_batch_api: true`, the default) propagates `Monitoring Reader` 5-30 minutes after grant; legacy ARM `/metrics` (`use_batch_api: false`) propagates immediately. If you've just granted the role and the receiver is 401-ing, temporarily flip to `false` to confirm the role itself is correct, then revert once the data-plane RBAC has settled. #### `403 Forbidden` from the receiver If using a service principal: the `client_secret` has expired. See [Service principal credential lifecycle](#service-principal-credential-lifecycle). If using managed identity: check that the storage account is in a subscription / resource group where the managed identity has `Monitoring Reader`. #### Capacity metrics never appear This is the [PT1H capacity-metric gap](#the-pt1h-capacity-metric-gap) covered above. PT1M Transaction-class metrics flow within minutes; PT1H Capacity-class metrics need either a separate slow-poll receiver instance, Diagnostic Settings to Log Analytics, or a scripted `az monitor metrics list` cron. Do not confuse this with authentication failure; check `otelcol_receiver_accepted_metric_points_total` on the collector's self-telemetry: if Transactions are flowing but capacity is not, the gap is the receiver, not RBAC. #### Sub-service metrics missing for a specific service Verify both the `services:` list and the `metrics:` map include the sub-namespace key. Both must be present; listing one without the other silently drops the sub-service. Check the receiver log for `Loaded the list of Azure Metrics Definitions` per resource - there should be one log line per `(account + sub-service)` pair on each poll cycle. #### `RequestThrottled` warnings from the receiver You have hit Azure Monitor's per-subscription rate ceiling (12,000 / hour on legacy, 360,000 / hour on batch). Multi-namespace Storage scoping makes this easier to hit than single-namespace surfaces. Either: - Lower polling rate: `collection_interval: 120s` for the fast receiver. - Narrow scope: drop unused sub-services from `services:` and `metrics:`. - Confirm `use_batch_api: true` is set (the guide default) - the legacy ARM endpoint caps at 12k/h versus 360k/h on data-plane batch. - Split heavy subscriptions across multiple collector instances. #### Cardinality blowup on Scout volume A single high-fanout account can dominate volume - `metadata_apiname` is the prime offender. Apply `dimensions.overrides` (see [Cardinality control](#cardinality-control)) or split the noisy account into a separate receiver instance with a narrower whitelist. #### `metadata_*` values look case-mismatched Issue [#45942](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/45942) in opentelemetry-collector-contrib. Storage-specific. Workaround in [Cardinality control](#cardinality-control) (transform processor or Scout-side normalisation). #### Scout OAuth2 returns 401 Verify `SCOUT_CLIENT_ID`, `SCOUT_CLIENT_SECRET`, and `SCOUT_TOKEN_URL` match the values in your Scout console. The `endpoint_params.audience` must be `b14collector`. #### Docker Desktop DNS glitch on a sibling-fragment restart If you run multiple Azure surfaces in one collector and restart the collector to pick up a sibling fragment change, the first poll sometimes fails with `dial tcp: lookup login.microsoftonline.com: network is unreachable`. This is a Docker Desktop networking quirk on container restart, not a receiver bug. A second restart resolves it. ### Frequently Asked Questions #### How do I add Azure Storage metrics to my existing OpenTelemetry Collector? Add the `azure_auth` extension and an `azure_monitor` receiver scoped to all five Storage namespaces (`Microsoft.Storage/storageAccounts` plus the four sub-services `blobServices`, `queueServices`, `tableServices`, `fileServices`), then route the receiver into a metrics pipeline that exports to Scout via the `oauth2client`-authenticated OTLP/HTTP exporter. The receiver polls Azure Monitor's REST API every 60 seconds and emits one OTel metric per Azure aggregation; the `azuremonitor.resource_id` data-point attribute splits each series by sub-service. No data-plane connection to Storage; the account is never on the collector's path. #### Why don't UsedCapacity and BlobCount appear on a new storage account? Capacity-class metrics on Microsoft.Storage namespaces have a PT1H time grain - Azure Monitor publishes them once per hour, not per minute. The v0.151.0 `azuremonitorreceiver` passes each metric's natural time grain as both `Interval` and `Timespan` when querying Azure Monitor; for fresh accounts this query window can fall outside the publishing schedule and capacity points get skipped. PT1M Transaction-class metrics (`Transactions`, `Ingress`, `Egress`, `Availability`, latency) flow within 2-3 minutes; for capacity observability run a second receiver instance with `collection_interval: 3600s`, or fall back to Diagnostic Settings to Log Analytics. Issue [#46047](https://github.com/open-telemetry/opentelemetry-collector-contrib/issues/46047) tracks the underlying class of problem. #### How do I attribute Transactions to Blob vs Queue vs Table vs File? Whitelist `Transactions` on each of the five namespaces in the `metrics:` map. The receiver emits one `azure_transactions_total` series per resource scope, distinguishable by the `azuremonitor.resource_id` data-point attribute - account-level rollup uses `.../storageAccounts/`, sub-services append `/Services/default`. The account-level series is the rollup; sub-service series are per-service. If you only care about totals, drop the sub-services from `services:` and `metrics:`; if you need per-sub-service granularity, keep all five. #### How do I keep cardinality under control on the metadata_* dimensions? By default each `Transactions` data point carries `metadata_apiname`, `metadata_authentication`, `metadata_geotype`, `metadata_responsetype`, and `metadata_transactiontype`. `metadata_apiname` has the highest cardinality - one value per distinct Storage API operation. For a 50-account fleet doing 30 distinct API operations across all six PT1M metrics with dual-mode auth (`AccountKey` plus `OAuth`), the active series count grows to roughly 50 × 5 × ~6 × 30 × 2 ≈ 90,000 series, with `metadata_responsetype` adding another 1.5-3x during error spikes. Use `dimensions.overrides` on the receiver to drop `metadata_apiname` on noisy accounts, drop `metadata_authentication` where authentication mode does not change incident routing, and drop `metadata_responsetype` where ResponseType-split alerting is not needed. #### Should I use a service principal or managed identity for the collector? Managed identity if the collector runs in Azure, service principal if it does not. AKS pods use Workload Identity Federation with a federated credential bound to a Kubernetes ServiceAccount; Container Apps and Virtual Machine Scale Sets use system-assigned or user-assigned managed identity; out-of-Azure collectors fall back to service principal. The `azure_auth` extension's mode block is the only thing that changes; the rest of the receiver config is identical. Storage's RBAC is the same `Monitoring Reader` role at resource-group scope as every other `azure_monitor` surface. #### Do I need this guide AND Diagnostic Settings to Log Analytics? Yes if you want logs alongside metrics, and yes if you want to fill the PT1H capacity-metric gap noted above. This guide ships PT1M Transaction-class metrics. For activity logs, audit logs, and per-blob/queue/table/file operation logs from the storage account, configure Diagnostic Settings on each sub-service to forward to Log Analytics or to Event Hubs and pipe Event Hubs into the collector via the `azure_event_hub` receiver. The two paths are complementary: metrics for SLI and SLO dashboards and alerts, logs for incident investigation and capacity-trend analysis. ### Reference - **Receiver source.** [opentelemetry-collector-contrib / receiver / azuremonitorreceiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/azuremonitorreceiver). - **Auth extension source.** [opentelemetry-collector-contrib / extension / azureauthextension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/azureauthextension). - **Azure Monitor metric reference (account-level).** [Microsoft.Storage/storageAccounts metrics](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-storage-storageaccounts-metrics). - **Azure Monitor metric reference (sub-services).** [blobServices](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-storage-storageaccounts-blobservices-metrics) · [queueServices](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-storage-storageaccounts-queueservices-metrics) · [tableServices](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-storage-storageaccounts-tableservices-metrics) · [fileServices](https://learn.microsoft.com/azure/azure-monitor/reference/supported-metrics/microsoft-storage-storageaccounts-fileservices-metrics). ### Related Guides - [Azure Service Bus](./service-bus.md) - managed message broker for queues and topics. - [Azure Cosmos DB](./cosmos-db.md) - globally-distributed multi-model NoSQL database. - [Azure SQL Database](./sql-database.md) - managed relational database. - [Azure Front Door](./front-door.md) - global CDN and L7 edge with WAF. - [Azure Application Gateway](./application-gateway.md) - regional L7 load balancer with WAF v2. - [Azure Kubernetes Service](./aks.md) - managed Kubernetes. --- ## GCP API Gateway and Self-Managed nginx Monitoring with OpenTelemetry "API gateway" on GCP means one of two unrelated things, and they are instrumented completely differently. This guide covers both: Google's managed **API Gateway** service, and a **self-managed nginx** gateway running on GKE or Compute Engine. Read [GCP Monitoring overview](./overview.md) first — it covers the collector image, IAM, and resource attributes this guide assumes. :::note API Gateway is not nginx Google Cloud API Gateway is built on **Envoy** by way of ESPv2, not nginx. If you are looking for nginx instrumentation because you run nginx, skip to [Part B](#part-b-self-managed-nginx). If you use Google's managed service, [Part A](#part-a-gcp-api-gateway) applies and nginx is irrelevant to you. The two parts of this page do not overlap. ::: :::note Running this in production Storing and querying this telemetry at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### Choosing your part | You run | Read | Telemetry source | |---|---|---| | Google Cloud API Gateway (managed, ESPv2/Envoy) | [Part A](#part-a-gcp-api-gateway) | Cloud Monitoring + Cloud Logging | | ingress-nginx on GKE | [Part B](#part-b-self-managed-nginx) | Prometheus scrape + filelog | | nginx on Compute Engine | [Part B](#part-b-self-managed-nginx) | Prometheus scrape + filelog + OTel module | | Envoy or Traefik directly | [Envoy](../../component/envoy.md), [Traefik](../../component/traefik.md) | Native OTel support | --- ### Part A: GCP API Gateway API Gateway publishes a small, fixed metric set to Cloud Monitoring under `apigateway.googleapis.com/`. The monitored resource is `apigateway.googleapis.com/Gateway`, with labels for `gateway_id`, `location` and `project_id`. Metrics additionally carry `api_config`, which is the dimension to group by during a config rollout, and `response_code_class`. Confirm each metric name in **Monitoring → Metrics Explorer** with the **Active** toggle enabled before relying on it — API Gateway's published metric set has changed more than most. #### Receiver configuration ```yaml showLineNumbers title="api-gateway-config.yaml" receivers: # ...your existing receivers... googlecloudmonitoring/apigateway: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: - metric_name: "apigateway.googleapis.com/request_count" # Distributions — collector v0.129.0 or later only - metric_name: "apigateway.googleapis.com/request_latencies" - metric_name: "apigateway.googleapis.com/request_sizes" - metric_name: "apigateway.googleapis.com/response_sizes" processors: resource/apigateway: attributes: - {key: service.name, value: apigateway-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_api_gateway, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/apigateway: receivers: [googlecloudmonitoring/apigateway] processors: [memory_limiter, resource/apigateway, batch] exporters: [otlphttp/base14] ``` :::warning Three of these four are distributions `request_latencies`, `request_sizes` and `response_sizes` are all `DELTA` + `DISTRIBUTION`, which needs collector **v0.129.0 or later**. On an older build they produce invalid data points that fail the entire scrape batch, so `request_count` disappears along with them. If you cannot upgrade, delete the three marked lines and collect `request_count` alone. That leaves you with error rate and traffic volume, and no latency at all — API Gateway publishes latency only as a distribution. ::: #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` #### What you'll monitor | Metric | Kind | Unit | Use case | |---|---|---|---| | `request_count` | **Delta** sum | count | Request rate, labelled by `response_code` and `response_code_class`. | | `request_latencies` | **Delta** histogram | ms | End-to-end gateway latency, including the backend. | | `request_sizes` | **Delta** histogram | bytes | Payload sizes; where request-size limit rejections originate. | | `response_sizes` | **Delta** histogram | bytes | Response volume, and egress cost. | That is the whole set. API Gateway exposes no per-route breakdown in metrics, no backend-versus-gateway latency split, and no authentication outcome dimension. For any of those you need the logs. #### Logs API Gateway request logs go to Cloud Logging under `resource.type="apigateway.googleapis.com/Gateway"`. Route them through the sink you set up in [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md): ```bash showLineNumbers gcloud logging sinks create scout-apigateway-logs \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='resource.type="apigateway.googleapis.com/Gateway"' ``` Entries carry an `httpRequest` block, which the `google_cloud_logentry_encoding` extension maps to `http.request.method`, `url.full`, `http.response.status_code`, `http.request.server.duration` and `network.peer.address`. The API config and route that matched appear in the payload. If your backend runs ESPv2 on Cloud Run directly rather than behind API Gateway, it also publishes under `serviceruntime.googleapis.com/api/` — a richer set including per-method breakdowns and quota metrics. #### Alert tuning | Signal | Source metric | Warning | Critical | |---|---|---|---| | Error rate | `request_count` where `response_code_class = 500` | > 1% for 5m | > 5% for 5m | | Client errors | `request_count` where `response_code_class = 400` | > 10% for 15m | > 25% for 15m | | Latency | `request_latencies` p99 | > 1s for 10m | > 3s for 5m | | Traffic stop | `request_count` | zero for 10m | zero for 30m | A high 4xx rate on API Gateway usually means authentication or schema validation rejections rather than genuine client bugs — the gateway rejects before the backend sees anything. The logs distinguish them. --- ### Part B: Self-managed nginx nginx exposes four numbers by default, through the `stub_status` module. Getting useful gateway telemetry means choosing among three sources, which stack. | Source | Gives you | Cost | |---|---|---| | `nginx` receiver via `stub_status` | 4 connection and request counters | Trivial | | `prometheus` receiver via `nginx-prometheus-exporter` | Per-upstream, per-status detail | One extra process | | `filelog` receiver on the access log | Per-request detail, any field you log | Log volume | | `nginx-module-otel` | Real distributed traces | A module build | The receiver configuration for all four is documented once in [nginx component](../../component/nginx.md). This section covers only what changes when nginx is a GCP API gateway. #### ingress-nginx on GKE ingress-nginx already exposes Prometheus metrics on port 10254 — no exporter needed. Scrape it with the `prometheus` receiver: ```yaml showLineNumbers title="nginx-gateway-config.yaml" receivers: # ...your existing receivers... prometheus/nginx: config: scrape_configs: - job_name: ingress-nginx scrape_interval: 30s kubernetes_sd_configs: - role: pod namespaces: names: [ingress-nginx] relabel_configs: - source_labels: [__meta_kubernetes_pod_container_port_name] action: keep regex: metrics processors: resource/nginx: attributes: - {key: service.name, value: nginx-gateway-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_kubernetes_engine, action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/nginx: receivers: [prometheus/nginx] processors: [memory_limiter, resource/nginx, batch] exporters: [otlphttp/base14] ``` The `service.name` here is deliberately not `apigateway-metrics`. A managed API Gateway and a self-managed nginx gateway publish different metric vocabularies, and `ServiceName` is the leading sort key in the Scout data lake — sharing one makes every query read both. ingress-nginx metrics carry an `ingress` and `host` label, giving you the per-route breakdown that neither the `nginx` receiver nor GCP API Gateway provides. :::warning ingress-nginx path labels `nginx_ingress_controller_requests` is labelled by ingress name rather than raw path, so it is bounded. If you enable the optional per-path histogram metrics, they are not — the label takes the request URI verbatim, and any URL containing an id becomes its own series. Normalize the path in the collector before it reaches Scout, or leave those metrics off. ::: #### Access logs Configure nginx to log JSON so the collector does not have to parse a custom format: ```nginx showLineNumbers title="nginx.conf" log_format otel_json escape=json '{"time":"$time_iso8601",' '"http.request.method":"$request_method",' '"url.path":"$uri",' '"http.response.status_code":$status,' '"http.request.server.duration":$request_time,' '"network.peer.address":"$remote_addr",' '"user_agent.original":"$http_user_agent",' '"server.address":"$upstream_addr",' '"trace_id":"$otel_trace_id"}'; access_log /var/log/nginx/access.log otel_json; ``` Naming the JSON keys after semantic conventions means the `filelog` receiver's `json_parser` produces correctly named attributes with no mapping step. `$otel_trace_id` is available only when `nginx-module-otel` is loaded, and is what links these logs to traces. #### Traces `nginx-module-otel` gives nginx real distributed tracing — it starts or continues a trace at the gateway, so every downstream span sits under a root span that includes the gateway's own time. base14 publishes a prebuilt module at [base-14/nginx-otel-build](https://github.com/base-14/nginx-otel-build). Configuration is in [nginx component](../../component/nginx.md). **A self-managed nginx gateway can emit traces; GCP API Gateway cannot.** #### Correlating with the load balancer An nginx gateway on GCP almost always sits behind a Cloud Load Balancer. That means two hops recording the same request, and comparing them is diagnostic: - Latency at the LB but not at nginx points at the network between them, or at a backend the LB served without forwarding. - Requests at the LB that never appear in the nginx access log were rejected by the LB or Cloud Armor. - Status codes that differ between the two hops mean something is rewriting responses. See [Cloud Load Balancing](./load-balancing.md) for the LB side. Use the same `deployment.environment.name` on both so they line up. --- ### Cardinality control The two paths fail differently here, which is worth knowing before you enable either. | Attribute | Path | Cardinality | Keep? | |---|---|---|---| | `gateway_id`, `location` | API Gateway | One per gateway | Yes | | `api_config` | API Gateway | One per published config revision | Only during a rollout | | `response_code_class` | Both | 4 | Yes | | `ingress`, `host` | ingress-nginx | One per ingress or hostname | Yes | | Request path | ingress-nginx optional metrics | Unbounded | No | Managed API Gateway is naturally bounded — it publishes four metrics with a handful of labels, and `api_config` is the only one that grows, one value per config you publish. nginx is the opposite. Its optional per-path histograms label by raw request URI, so `/orders/8a3f-…` and `/orders/9b2c-…` become separate series forever. Either leave those metrics off, or normalize the path before export: ```yaml showLineNumbers title="nginx-gateway-config.yaml" processors: transform/nginx: error_mode: ignore metric_statements: - context: datapoint statements: - replace_pattern(attributes["path"], "/[0-9a-f-]{8,}", "/{id}") - replace_pattern(attributes["path"], "/[0-9]+", "/{id}") ``` --- ### Verify 1. **The collector starts cleanly** — check for `PermissionDenied` (Part A) or scrape errors (Part B) in its logs. 2. **Confirm metrics landed.** For API Gateway: ```sql showLineNumbers SELECT MetricName, count() AS points, sum(Value) AS total FROM otel_metrics_sum WHERE ServiceName = 'apigateway-metrics' AND MetricName = 'apigateway.googleapis.com/request_count' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` 3. **For nginx, confirm the scrape target is up.** The `prometheus` receiver emits an `up` series per target; a value of 0 means the target was discovered but did not respond. --- ### Troubleshooting **API Gateway metrics are empty although the gateway serves traffic.** Confirm `project_id` is the project holding the gateway, not the one holding the backend. Managed API Gateway and its Cloud Run backend are frequently in different projects. **All API Gateway metrics stopped after adding latency.** `request_latencies`, `request_sizes` and `response_sizes` are all distributions and need collector v0.129.0 or later. **ingress-nginx scrape returns nothing.** The metrics port is not named `metrics` in your Helm values, so the relabel rule drops it. Check the container port name on the controller pod rather than assuming the default. **nginx access logs have no trace id.** `$otel_trace_id` is only populated when `nginx-module-otel` is loaded and tracing is enabled for that location block. Without the module the variable expands to an empty string. **The series count exploded after enabling nginx path metrics.** The per-path histograms label by raw request URI. Normalize the path before export or leave those metrics disabled. **Request counts differ between the load balancer and nginx.** That is usually correct rather than a collection bug — see [Correlating with the load balancer](#correlating-with-the-load-balancer). ### FAQ #### Is Google Cloud API Gateway based on nginx? No — Google Cloud API Gateway runs ESPv2, which is built on Envoy. If you are looking for nginx telemetry, you are running nginx yourself, and Part B of this guide applies rather than Part A. #### How do I monitor GCP API Gateway with OpenTelemetry? Use the `googlecloudmonitoring` receiver against the `apigateway.googleapis.com/` prefix for its four metrics, and route `resource.type="apigateway.googleapis.com/Gateway"` logs through a Log Router sink for per-request detail. #### Can GCP API Gateway emit distributed traces? GCP API Gateway emits metrics and request logs only, never traces. A self-managed nginx gateway can emit traces using `nginx-module-otel`, which is one of the stronger arguments for running your own gateway if tracing matters to you. #### What is the best way to get metrics from ingress-nginx on GKE? Scrape its built-in Prometheus endpoint on port 10254 with the `prometheus` receiver. It already exposes per-ingress and per-host metrics, so no separate exporter is needed. #### Why does the nginx receiver give me so few metrics? It reads `stub_status`, which nginx open source limits to four values. Use `nginx-prometheus-exporter` or, on Kubernetes, ingress-nginx's own Prometheus endpoint for anything more detailed. #### Should I collect metrics at the load balancer or at nginx? Collect at both. They see different things, and the difference between them is itself diagnostic — requests the load balancer rejected never reach nginx, and latency added between the two hops shows up nowhere else. ### Reference - [API Gateway monitoring](https://docs.cloud.google.com/api-gateway/docs/monitoring) - [ESPv2 on Cloud Run](https://docs.cloud.google.com/endpoints/docs/openapi/get-started-cloud-run) - [ingress-nginx metrics](https://kubernetes.github.io/ingress-nginx/user-guide/monitoring/) - [base-14/nginx-otel-build](https://github.com/base-14/nginx-otel-build) ### Related Guides - [GCP Monitoring overview](./overview.md) - which collector image carries the receivers both halves of this page need. - [nginx component](../../component/nginx.md) - the full receiver, access log and tracing configuration Part B builds on. - [Cloud Load Balancing](./load-balancing.md) - the hop in front of the gateway, and how to correlate the two. - [Envoy component](../../component/envoy.md) - if you run Envoy directly rather than through API Gateway. --- ## Google Cloud Run Monitoring with OpenTelemetry - Traces, Metrics & Logs Cloud Run is the one GCP surface in these guides where your own code runs, so it is the one that can emit real distributed traces. This guide leads with a collector sidecar for application telemetry, then adds the platform metrics — instance count, cold starts, billable time — that your application cannot see about itself. Read [GCP Monitoring overview](./overview.md) first — it covers the collector image, IAM, and resource attributes this guide assumes. :::note Running this in production Storing and querying this telemetry at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### Overview The two pipelines answer different questions: | Source | Signals | Answers | |---|---|---| | **Collector sidecar** | Traces, application metrics, logs | What is my code doing, and why is this request slow? | | **Cloud Monitoring** | Platform metrics | How many instances am I running, how often am I cold-starting, what does this cost? | Run both. The sidecar cannot see instance counts or billable time; Cloud Monitoring cannot see a span. ```text ┌───────────────── Cloud Run service ─────────────────┐ │ │ │ ┌─────────────┐ OTLP ┌──────────────────────┐ │ │ │ Your app │─────────▶│ Collector sidecar │──┼──▶ Scout │ │ (OTel SDK) │ :4317 │ (contrib image) │ │ │ └─────────────┘ └──────────────────────┘ │ │ │ stdout │ └─────────┼───────────────────────────────────────────┘ ▼ Cloud Logging ─── sink ──▶ Pub/Sub ──▶ collector ──▶ Scout ▲ Cloud Monitoring ◀── polled by googlecloudmonitoring ──▶ Scout ``` --- ### The collector sidecar Cloud Run supports multiple containers per service. Run the collector alongside your application, listening on localhost, and point your OTel SDK at it. #### Collector configuration ```yaml showLineNumbers title="cloud-run-collector.yaml" receivers: otlp: protocols: grpc: endpoint: 0.0.0.0:4317 http: endpoint: 0.0.0.0:4318 processors: resourcedetection/gcp: detectors: [env, gcp] timeout: 5s override: false resource/cloudrun: attributes: - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_cloud_run, action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} memory_limiter: limit_mib: 128 spike_limit_mib: 32 check_interval: 1s batch: timeout: 5s send_batch_size: 512 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} retry_on_failure: enabled: true initial_interval: 2s max_interval: 10s max_elapsed_time: 30s service: pipelines: traces: receivers: [otlp] processors: [memory_limiter, resourcedetection/gcp, resource/cloudrun, batch] exporters: [otlphttp/base14] metrics: receivers: [otlp] processors: [memory_limiter, resourcedetection/gcp, resource/cloudrun, batch] exporters: [otlphttp/base14] logs: receivers: [otlp] processors: [memory_limiter, resourcedetection/gcp, resource/cloudrun, batch] exporters: [otlphttp/base14] ``` `resourcedetection` with the `gcp` detector fills in `cloud.region`, `cloud.account.id`, `faas.name` (your service name), `faas.version` (the revision) and `faas.instance` automatically. Leave `service.name` to your application's SDK — unlike the pull-based GCP guides, Cloud Run telemetry has a real service behind it. :::warning faas.id was renamed Contrib collector v0.147 removed the `removeGCPFaasID` feature gate, making `faas.instance` the only name for the Cloud Run instance identifier. Dashboards or queries written against `faas.id` on an older collector will stop matching after you upgrade. ::: #### Service definition ```yaml showLineNumbers title="service.yaml" apiVersion: serving.knative.dev/v1 kind: Service metadata: name: my-service annotations: run.googleapis.com/launch-stage: BETA spec: template: metadata: annotations: run.googleapis.com/container-dependencies: '{"app":["collector"]}' run.googleapis.com/cpu-throttling: "false" spec: containers: - name: app image: gcr.io/PROJECT_ID/my-app ports: - containerPort: 8080 env: - name: OTEL_EXPORTER_OTLP_ENDPOINT value: http://localhost:4317 - name: OTEL_SERVICE_NAME value: my-service - name: collector image: otel/opentelemetry-collector-contrib startupProbe: tcpSocket: port: 4317 failureThreshold: 10 periodSeconds: 2 ``` Two annotations do most of the work here. `container-dependencies` makes the application container wait for the collector, so early spans are not dropped into a closed socket during startup. :::warning CPU throttling drops telemetry Cloud Run throttles a container's CPU to near zero between requests unless CPU is always allocated. A sidecar collector batches on a timer, so with throttling on, its export runs only when a request happens to be in flight — and telemetry buffered when the instance scales to zero is lost outright. Set `run.googleapis.com/cpu-throttling: "false"` as above, which bills for the instance's whole lifetime rather than only during requests. If that cost is unacceptable, lower the batch `timeout` to a second or two and accept that some telemetry from the last request before scale-down will not arrive. ::: Keep the collector's `memory_limiter` low. It shares the service's memory allocation with your application, and a sidecar that grows will push the application into an out-of-memory restart. --- ### Platform metrics The sidecar sees requests your code handled. It cannot see how many instances exist, how often Cloud Run cold-started one, or what any of it costs. Those come from Cloud Monitoring. ```yaml showLineNumbers title="cloud-run-platform-config.yaml" receivers: # ...on your central collector, not the sidecar... googlecloudmonitoring/cloudrun: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: - metric_name: "run.googleapis.com/request_count" - metric_name: "run.googleapis.com/container/instance_count" - metric_name: "run.googleapis.com/container/billable_instance_time" - metric_name: "run.googleapis.com/container/cpu/utilizations" - metric_name: "run.googleapis.com/container/memory/utilizations" - metric_name: "run.googleapis.com/container/network/received_bytes_count" - metric_name: "run.googleapis.com/container/network/sent_bytes_count" processors: resource/cloudrun_platform: attributes: - {key: service.name, value: cloudrun-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_cloud_run, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} service: pipelines: metrics/cloudrun: receivers: [googlecloudmonitoring/cloudrun] processors: [memory_limiter, resource/cloudrun_platform, batch] exporters: [otlphttp/base14] ``` #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` Run the platform-metrics receiver on your central collector rather than the sidecar. A sidecar polls once per instance, so an autoscaled service would poll the Monitoring API dozens of times over and produce duplicate series. :::warning This config needs collector v0.129.0 or later `container/cpu/utilizations` and `container/memory/utilizations` are `DELTA` + `DISTRIBUTION`, as are `request_latencies`, `container/startup_latencies` and `container/max_request_concurrencies`. Distributions need collector v0.129.0 or later; on an older build they fail the entire scrape batch and take `request_count` and `instance_count` down with them. The two `utilizations` metrics are in the list above because saturation is worth the version dependency. Add `request_latencies` and `container/startup_latencies` alongside them — both are listed in [What you'll monitor](#what-youll-monitor) and both are hard to operate Cloud Run without. If you are stuck on an older collector, remove every distribution and you are left with `request_count`, `container/instance_count`, `container/billable_instance_time` and the network counters. ::: #### Jobs Cloud Run jobs use the `cloud_run_job` resource and a different metric family: ```yaml showLineNumbers title="cloud-run-platform-config.yaml" metrics_list: - metric_name: "run.googleapis.com/job/completed_execution_count" - metric_name: "run.googleapis.com/job/completed_task_attempt_count" - metric_name: "run.googleapis.com/job/running_executions" ``` --- ### What you'll monitor | Metric | Kind | Unit | Use case | |---|---|---|---| | `request_count` | **Delta** sum | count | Request rate by `response_code_class`. Includes requests your app never saw — 429s from concurrency limits, 503s during scale-up. | | `request_latencies` | **Delta** histogram | ms | Includes queue time before your handler ran, which your own spans do not. | | `container/instance_count` | Gauge | count | Labelled by `state` (`active`, `idle`). The scaling picture. | | `container/billable_instance_time` | **Delta** sum | seconds | What you actually pay for. Rises sharply when CPU throttling is disabled. | | `container/startup_latencies` | **Delta** histogram | ms | Cold start duration. The metric to watch when p99 latency has a long tail nothing in your code explains. | | `container/cpu/utilizations` | **Delta** histogram | ratio | CPU against the allocation, distributed across instances. | | `container/memory/utilizations` | **Delta** histogram | ratio | Memory against the allocation. Approaching 1.0 means restarts are coming. | | `container/max_request_concurrencies` | **Delta** histogram | count | Concurrency against the configured limit; where 429s come from. | | `container/network/sent_bytes_count` | **Delta** sum | bytes | Egress volume and cost. | :::tip Two latency numbers that should disagree `request_latencies` measures from when Cloud Run received the request; your application spans measure from when the handler started. The gap is queue time and cold start. If platform latency looks bad while your traces look fine, you have a scaling problem, not a code problem — and `startup_latencies` alongside `instance_count` will confirm it. ::: --- ### Cardinality control | Attribute | Source | Cardinality | Keep? | |---|---|---|---| | `service_name` | Resource label | One per service | Yes | | `revision_name` | Resource label | **One per deployment** | Usually not | | `location` | Resource label | Small | Yes | | `state` | Metric label on `instance_count` | 2 | Yes | | `response_code` | Metric label | Tens | Yes | `revision_name` is the one to watch. Cloud Run creates a new revision on every deploy, so a service deployed twenty times a week accumulates a thousand revision values a year — each one a distinct series that keeps its history forever while never receiving another point. Drop it unless you actively compare revisions: ```yaml showLineNumbers title="cloud-run-platform-config.yaml" processors: transform/cloudrun: error_mode: ignore metric_statements: - context: datapoint statements: - delete_key(attributes, "revision_name") ``` For the sidecar pipeline, `faas.version` carries the same risk. It is more defensible there — knowing which revision a trace came from is genuinely useful during a rollout — but it is a resource attribute on every span, so weigh it against your trace volume. --- ### Alert tuning | Signal | Source metric | Warning | Critical | Notes | |---|---|---|---|---| | Error rate | `request_count` where `response_code_class = 500` | > 1% for 5m | > 5% for 5m | Includes platform 503s during scale-up, not only your errors. | | Concurrency rejection | `request_count` where `response_code = 429` | any sustained | > 1% | Raise concurrency or maximum instances. | | Cold start latency | `container/startup_latencies` p95 | > 5s | > 15s | Consider minimum instances if this is user-facing. | | Memory pressure | `container/memory/utilizations` p95 | > 0.8 | > 0.95 | Cloud Run kills the instance at the limit with no graceful shutdown. | | Scaling ceiling | `container/instance_count` where `state = active` | approaching maximum | at maximum | Traffic is being queued or rejected above this. | | Cost anomaly | `container/billable_instance_time` | 2x baseline | 5x baseline | Disabling CPU throttling moves this permanently; alert on the new baseline. | --- ### Logs Anything your container writes to stdout or stderr goes to Cloud Logging under `resource.type="cloud_run_revision"`. You have two ways to get it into Scout, and they are mutually exclusive in practice: **Through the sidecar.** Emit logs via the OTel SDK to the collector's OTLP endpoint. They arrive already correlated with trace and span ids, and never touch Cloud Logging. This is the better path when your application controls its own logging. **Through Cloud Logging.** Route `resource.type="cloud_run_revision"` through a Log Router sink into Pub/Sub, as in [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md): ```bash showLineNumbers gcloud logging sinks create scout-cloudrun-logs \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='resource.type="cloud_run_revision"' ``` This path also captures Cloud Run's own request logs and platform messages, which the sidecar never sees, and works for containers you did not write. The encoding extension maps the `httpRequest` block to HTTP semantic conventions and preserves trace ids Cloud Run injected. --- ### Verify 1. **The sidecar started before the app.** Check the Cloud Run revision logs for the collector container reporting `Everything is ready. Begin running and processing data.` 2. **Traces reach Scout.** Send a request and confirm a trace appears with `cloud.platform = gcp_cloud_run` and a populated `faas.name`. 3. **Platform metrics landed:** ```sql showLineNumbers SELECT MetricName, count() AS points, max(Value) AS latest FROM otel_metrics_gauge WHERE ServiceName = 'cloudrun-metrics' AND MetricName = 'run.googleapis.com/container/instance_count' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` 4. **Scale to zero and back.** Leave the service idle past its scale-down window, send a request, and confirm the spans from that request arrive. This is the test that catches CPU-throttling telemetry loss. --- ### Troubleshooting **Traces from the first requests after a deploy are missing.** The application started before the collector. Add the `run.googleapis.com/container-dependencies` annotation. **Telemetry stops arriving when traffic is low.** CPU throttling. With `cpu-throttling: "true"` the sidecar gets almost no CPU between requests, so its batch timer never fires. Set it to `"false"` or shorten the batch timeout. **The service restarts under load with no application error.** The sidecar's memory is counted against the service's allocation. Lower the collector's `memory_limiter`, or raise the service memory. **`faas.id` disappeared from spans after upgrading the collector.** It was renamed to `faas.instance` when contrib v0.147 removed the `removeGCPFaasID` feature gate. **Platform metrics are duplicated.** The `googlecloudmonitoring` receiver is running in the sidecar, so every instance polls independently. Move it to a central collector. **Platform request counts exceed what your traces show.** Correct, and useful. Cloud Run counts requests it rejected — 429s at the concurrency limit, 503s during scale-up — that never reached your handler. ### FAQ #### How do I send Cloud Run traces to base14 Scout? Run an OpenTelemetry Collector as a sidecar container listening on `localhost:4317`, point your application's SDK at it, and export to Scout over OTLP. Use the `container-dependencies` annotation so the app waits for the collector at startup. #### Why does my Cloud Run telemetry stop when traffic is idle? Cloud Run throttles container CPU between requests, so the sidecar's batch timer does not fire. Set `run.googleapis.com/cpu-throttling: "false"`, or shorten the collector's batch timeout and accept losing the last batch before scale-down. #### Do I need both the sidecar and Cloud Monitoring? You need both for a complete picture. The sidecar gives you traces and application metrics; Cloud Monitoring gives you instance counts, cold start latency and billable time, none of which your application can observe about itself. #### Why is Cloud Run latency higher than my application spans show? `request_latencies` starts when Cloud Run receives the request, so it includes queue time and cold start. Your spans start when the handler runs. The gap is the platform, and `container/startup_latencies` confirms whether cold starts explain it. #### How do I avoid a cardinality explosion from Cloud Run revisions? Drop the `revision_name` attribute with a `transform` processor. Every deploy creates a new revision, so the label grows without bound and each value keeps its history after it stops receiving points. #### Should Cloud Run logs go through the sidecar or Cloud Logging? Send them through the sidecar if your application controls its logging, because they arrive already correlated with trace ids. Use Cloud Logging if you also want Cloud Run's own request logs and platform messages, or if you did not write the container. ### Reference - [Cloud Run monitoring](https://docs.cloud.google.com/run/docs/monitoring) - [Cloud Run sidecar containers](https://docs.cloud.google.com/run/docs/deploying#sidecars) - [OTel Collector sidecar on Cloud Run](https://docs.cloud.google.com/stackdriver/docs/instrumentation/opentelemetry-collector-cloud-run) - [Cloud Run CPU allocation](https://docs.cloud.google.com/run/docs/configuring/cpu-allocation) ### Related Guides - [GCP Monitoring overview](./overview.md) - the platform-metrics half of this page in its general form, across every GCP surface. - [Pub/Sub](./pub-sub.md) - where push subscriptions terminate, and the trace-context caveat that affects them. - [Cloud Load Balancing](./load-balancing.md) - the hop in front of a Cloud Run service exposed to the internet. - [Cloud SQL](./cloud-sql.md) - the database most Cloud Run services talk to. --- ## Google Cloud SQL Monitoring with OpenTelemetry - Metrics, Logs & Alerts Cloud SQL publishes host-level and engine-level metrics to Cloud Monitoring automatically. This guide collects them into Scout with the `googlecloudmonitoring` receiver, adds database logs through the Cloud Logging path, and shows where an in-database scrape fills the gaps that Cloud Monitoring cannot reach. Read [GCP Monitoring overview](./overview.md) first — it covers the collector image, IAM, and resource attributes this guide assumes. :::note Running this in production Storing and querying these metrics at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### Overview Cloud SQL splits into two metric families that behave differently: - **Host metrics** (`database/cpu/`, `database/memory/`, `database/disk/`, `database/network/`) describe the managed instance — the VM, its disk, and its quota. Only Cloud Monitoring has these. - **Engine metrics** (`database/postgresql/`, `database/mysql/`, `database/sqlserver/`) are a curated subset of what the engine's own statistics views expose. Useful, but thin compared to what you get by querying the database directly. Neither family sees individual queries, tables, locks or index usage. For that you need the in-database path described under [Alternative: scraping the engine directly](#alternative-scraping-the-engine-directly). ### Cloud SQL at a glance All Cloud SQL metric types start `cloudsql.googleapis.com/`, elided below. | Layer | Source | Metric prefix | Collected by | |---|---|---|---| | Instance host | Cloud SQL | `database/` | `googlecloudmonitoring` | | Engine counters | Cloud SQL | `database/postgresql/`, `database/mysql/`, `database/sqlserver/` | `googlecloudmonitoring` | | Query and table detail | The database | `postgresql.*`, `mysql.*` | `postgresql` / `mysql` receiver | | Database logs | Cloud Logging | `resource.type="cloudsql_database"` | `googlecloudpubsub` | The monitored resource is `cloudsql_database`, whose labels (`project_id`, `database_id`, `region`) arrive as resource attributes alongside `gcp.resource_type`. `database_id` has the form `PROJECT_ID:INSTANCE_ID` — it is the field to group by when you run several instances. --- ### Receiver configuration ```yaml showLineNumbers title="cloud-sql-config.yaml" receivers: # ...your existing receivers... googlecloudmonitoring/cloudsql: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: # Host — CPU, memory, disk, network - metric_name: "cloudsql.googleapis.com/database/cpu/utilization" - metric_name: "cloudsql.googleapis.com/database/memory/utilization" - metric_name: "cloudsql.googleapis.com/database/memory/total_usage" - metric_name: "cloudsql.googleapis.com/database/disk/utilization" - metric_name: "cloudsql.googleapis.com/database/disk/quota" - metric_name: "cloudsql.googleapis.com/database/disk/bytes_used" - metric_name: "cloudsql.googleapis.com/database/disk/read_ops_count" - metric_name: "cloudsql.googleapis.com/database/disk/write_ops_count" - metric_name: "cloudsql.googleapis.com/database/network/connections" - metric_name: "cloudsql.googleapis.com/database/network/sent_bytes_count" - metric_name: "cloudsql.googleapis.com/database/network/received_bytes_count" - metric_name: "cloudsql.googleapis.com/database/instance_state" # Replication - metric_name: "cloudsql.googleapis.com/database/replication/replica_lag" - metric_name: "cloudsql.googleapis.com/database/replication/network_lag" # PostgreSQL engine — drop this block on MySQL instances - metric_name: "cloudsql.googleapis.com/database/postgresql/num_backends" - metric_name: "cloudsql.googleapis.com/database/postgresql/transaction_count" - metric_name: "cloudsql.googleapis.com/database/postgresql/deadlock_count" - metric_name: "cloudsql.googleapis.com/database/postgresql/temp_bytes_written_count" processors: resource/cloudsql: attributes: - {key: service.name, value: cloudsql-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_cloud_sql, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: cloud.region, value: "${env:GCP_REGION}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/cloudsql: receivers: [googlecloudmonitoring/cloudsql] processors: [memory_limiter, resource/cloudsql, batch] exporters: [otlphttp/base14] ``` On a MySQL instance, replace the PostgreSQL block with the counters you care about under `cloudsql.googleapis.com/database/mysql/` — `queries`, `questions`, `innodb_pages_read`, and the `innodb_buffer_pool_*` family are the usual starting set. #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id GCP_REGION=asia-south1 ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` #### Collecting the whole service To take everything Cloud SQL emits rather than naming each metric: ```yaml showLineNumbers title="cloud-sql-config.yaml" metrics_list: - metric_descriptor_filter: 'metric.type = starts_with("cloudsql.googleapis.com/")' ``` Cloud SQL publishes around 100 metric types, so expect a correspondingly larger Monitoring API bill and more series in Scout. Start with the explicit list and widen it once you know what you use. --- ### Authentication and IAM `roles/monitoring.viewer` on the project, granted to the collector's service account. Nothing Cloud SQL-specific is required — the full setup is in [GCP Monitoring overview](./overview.md#authentication). The in-database path needs a separate database user; see [below](#alternative-scraping-the-engine-directly). --- ### What you'll monitor | Metric | Kind | Unit | Use case | |---|---|---|---| | `database/cpu/utilization` | Gauge, `DOUBLE` | ratio | Saturation. Sustained above 0.8 usually means the tier is undersized. | | `database/memory/utilization` | Gauge, `DOUBLE` | ratio | Buffer-cache pressure; rising utilization with falling cache hit rate is the signal to look for. | | `database/memory/total_usage` | Gauge, `INT64` | bytes | Absolute usage, for capacity planning against the tier. | | `database/disk/utilization` | Gauge, `DOUBLE` | ratio | Cloud SQL auto-grows storage and never shrinks it, so a full disk costs money permanently as well as stopping writes. | | `database/disk/quota` | Gauge, `INT64` | bytes | Denominator for the above; also shows auto-growth events. | | `database/disk/bytes_used` | Gauge, `INT64` | bytes | Growth rate, for forecasting. | | `database/disk/read_ops_count` | **Delta** sum | ops | IOPS against the tier's limit. | | `database/disk/write_ops_count` | **Delta** sum | ops | Write amplification and checkpoint behavior. | | `database/network/connections` | Gauge, `INT64` | count | Compare against `max_connections`; the classic exhaustion signal. | | `database/network/sent_bytes_count` | **Delta** sum | bytes | Egress volume, which is billable across regions. | | `database/instance_state` | Gauge, `BOOL` | — | Whether the instance is running. | | `database/replication/replica_lag` | Gauge, `DOUBLE` | seconds | Read-replica staleness. | | `database/replication/network_lag` | Gauge, `INT64` | seconds | Splits replica lag into transport versus apply delay. | | `database/postgresql/num_backends` | Gauge, `INT64` | count | Per-database connection counts. | | `database/postgresql/transaction_count` | **Delta** sum | count | Throughput, split by commit and rollback. | | `database/postgresql/deadlock_count` | **Delta** sum | count | Should be flat at zero; any sustained value is a bug. | | `database/postgresql/temp_bytes_written_count` | **Delta** sum | bytes | Spills to disk — `work_mem` is too small for the queries running. | None of these are distributions, so this receiver's most disruptive failure mode does not apply to Cloud SQL. The delta-marked rows arrive with delta temporality; see [Metric kinds and temporality](./overview.md#metric-kinds-and-temporality). --- ### Cardinality control The resource labels here are bounded by how many instances you run, so this surface stays small on its own. | Attribute | Source | Cardinality | Keep? | |---|---|---|---| | `database_id` | Resource label | One per instance | Yes — the grouping key | | `region` | Resource label | Small | Yes | | `project_id` | Resource label | One per project | Yes | | `database` | Metric label on `postgresql/*` | One per database in the instance | Yes, unless you run many databases per instance | If a single instance hosts dozens of databases, the `database/postgresql/num_backends` series count multiplies accordingly. Drop the label if you only track the instance total: ```yaml showLineNumbers title="cloud-sql-config.yaml" processors: transform/cloudsql: error_mode: ignore metric_statements: - context: datapoint statements: - delete_key(attributes, "database") ``` --- ### Alert tuning | Signal | Source metric | Warning | Critical | Notes | |---|---|---|---|---| | Disk full | `database/disk/utilization` | > 0.80 for 15m | > 0.90 for 5m | Auto-growth buys time but raises cost permanently. | | CPU saturation | `database/cpu/utilization` | > 0.80 for 15m | > 0.95 for 5m | Correlate with `transaction_count` before resizing. | | Connection exhaustion | `database/network/connections` | > 80% of `max_connections` | > 95% | Usually a pooler problem, not a database one. | | Replica lag | `database/replication/replica_lag` | > 30s for 5m | > 300s for 5m | Thresholds depend on what reads the replica. | | Deadlocks | `database/postgresql/deadlock_count` | any for 5m | sustained | Alert on presence, not on a rate. | | Instance down | `database/instance_state` | — | not running | Pair with your own connectivity probe. | --- ### Logs Cloud SQL writes engine logs to Cloud Logging under `resource.type="cloudsql_database"`. Route them with a Log Router sink into the Pub/Sub topic your collector already subscribes to — the setup is in [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md). ```bash showLineNumbers gcloud logging sinks create scout-cloudsql-logs \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='resource.type="cloudsql_database"' ``` The log streams that matter, by `logName` suffix: | Engine | `logName` suffix | Contents | |---|---|---| | PostgreSQL | `postgres.log` | Server log — errors, slow queries if `log_min_duration_statement` is set, connection events | | MySQL | `mysql-general.log` | General query log; off by default and expensive to enable | | MySQL | `mysql.err` | Error log — crashes, replication failures, InnoDB messages | | MySQL | `mysql-slow.log` | Slow query log, gated on `slow_query_log` | PostgreSQL slow-query logging is a database flag, not a Cloud SQL setting: set `log_min_duration_statement` on the instance, then the entries appear in `postgres.log` and flow through the same sink. --- ### Alternative: scraping the engine directly Cloud Monitoring cannot see inside the database. For per-query, per-table and lock detail, run a collector inside the VPC with the `postgresql` or `mysql` receiver pointed at the instance, in addition to the Cloud Monitoring pipeline above. The two overlap very little. Reaching the instance takes one of: - **Private IP** — the collector runs in a VPC peered with the Cloud SQL instance's network. Simplest if you already run workloads there. - **Cloud SQL Auth Proxy** — a sidecar next to the collector, which handles IAM authentication and TLS. Needed for public-IP instances and the usual choice on GKE. Create a monitoring user with no data access: ```sql showLineNumbers -- PostgreSQL CREATE USER otel_monitor WITH PASSWORD ''; GRANT pg_monitor TO otel_monitor; ``` Then follow [PostgreSQL](../../component/postgres.md) or [MySQL](../../component/mysql.md) for the receiver configuration. Give the direct-scrape pipeline its own `service.name` so the two views stay distinguishable in Scout. :::note Two complementary views Cloud Monitoring gives you the host — CPU, memory, disk, quota, replication lag — and cannot see the workload. The engine receiver gives you the workload — connections by state, table and index statistics, locks, WAL — and cannot see the host. Production instances are worth instrumenting both ways. ::: For deeper query-level analysis on PostgreSQL, see [base14 pgX](../../../operate/pgx/overview.md). Note that pgX's Cloud SQL integration is not yet available; point it at the instance the same way you would any other PostgreSQL server. --- ### Verify 1. **The collector starts cleanly.** Check its logs for `PermissionDenied` or `could not find default credentials`: ```bash showLineNumbers # The exact command depends on your deployment: # Docker: docker logs # systemd: journalctl -u otelcol # Kubernetes: kubectl logs deploy/ -n ``` 2. **Metrics appear in Scout.** Allow at least one full `collection_interval` plus export time. 3. **Confirm the series landed under the right name:** ```sql showLineNumbers SELECT MetricName, count() AS points, max(Value) AS latest FROM otel_metrics_gauge WHERE ServiceName = 'cloudsql-metrics' AND MetricName = 'cloudsql.googleapis.com/database/cpu/utilization' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` The delta counters (`*_count`) live in `otel_metrics_sum`, not `otel_metrics_gauge`. --- ### Troubleshooting **The engine metrics never appear, but host metrics do.** You are listing PostgreSQL metrics against a MySQL instance or the other way round. The `database/postgresql/` and `database/mysql/` families are mutually exclusive per instance. **`database/replication/replica_lag` returns nothing.** The metric only exists on instances that have a replica. A primary with no replica emits no series at all, which reads as a collection failure but is not. **Metrics stop for one instance after a maintenance window.** Cloud SQL restarts change nothing about metric names, but a failover changes `database_id` if you point at the replica by name. Group by the resource attribute rather than pinning an instance in a query. **Everything arrives under `unknown_service`.** The `resource/cloudsql` processor is missing from the pipeline, or a blanket `resource` processor elsewhere in the same pipeline is overwriting `service.name`. See [Give each surface its own pipeline](./overview.md#resource-attributes-every-gcp-pipeline-sets). **Connection counts look far lower than the application reports.** `database/network/connections` counts connections to the instance. If a connection pooler sits in front, you are seeing pooled connections, not application ones. ### FAQ #### How do I monitor Cloud SQL with OpenTelemetry? Use the `googlecloudmonitoring` receiver against the `cloudsql.googleapis.com/` metric prefix. It needs only `roles/monitoring.viewer` and reaches every host and engine metric Cloud SQL publishes, with no agent on the instance. #### What Cloud SQL metrics should I alert on first? Alert on disk utilization, CPU utilization, connection count and replica lag first. Disk is the most urgent of the four because a full Cloud SQL disk stops writes, and auto-growth raises your bill permanently rather than reverting. #### Can I get query-level detail from Cloud Monitoring? Cloud Monitoring exposes host metrics and a curated set of engine counters, but never individual queries, tables, indexes or locks. Run the `postgresql` or `mysql` receiver against the instance for those. #### Do I need the Cloud SQL Auth Proxy? The Cloud SQL Auth Proxy is needed only for the direct-scrape path, and only when the collector cannot reach the instance over private IP. The Cloud Monitoring path talks to the Monitoring API and never connects to the database at all. #### Why are my Cloud SQL counters flat when I graph them as rates? Counters such as `database/disk/read_ops_count` have `DELTA` kind, so each point is already the change over the interval. Sum them over the window instead of applying counter-rate logic. #### How do I collect Cloud SQL slow query logs? Enable them at the engine level — `log_min_duration_statement` on PostgreSQL, `slow_query_log` on MySQL — then route `resource.type="cloudsql_database"` through a Log Router sink into Pub/Sub, as described in the Logs section above. ### Reference - [Cloud SQL metrics](https://docs.cloud.google.com/monitoring/api/metrics_gcp_c#gcp-cloudsql) - [Cloud SQL Auth Proxy](https://docs.cloud.google.com/sql/docs/postgres/connect-auth-proxy) - [Cloud SQL logging](https://docs.cloud.google.com/sql/docs/postgres/logging) ### Related Guides - [GCP Monitoring overview](./overview.md) - why most of these counters are delta rather than cumulative, and what that changes. - [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) - the sink and subscription setup the Logs section above depends on. - [PostgreSQL component](../../component/postgres.md) - the in-database receiver, for the detail Cloud Monitoring cannot reach. - [MySQL component](../../component/mysql.md) - the same for MySQL instances. - [Memorystore](./memorystore.md) - the caching tier usually sitting in front of this database. --- ## Sending Google Cloud Logging Logs to Scout via Pub/Sub and OpenTelemetry This guide shows you how to stream logs from **Google Cloud Logging** into your Scout collector using a Pub/Sub subscription and the OpenTelemetry `googlecloudpubsub` receiver. The same pattern works for any Cloud Logging log source: change the inclusion filter. Throughout this guide we use **Load Balancer access logs** as the worked example. :::note Running this in production Storing and querying these logs at production volume is what base14 Scout does. [Check out Scout Logs](https://base14.io/scout/logs). ::: ### How it works Cloud Logging does not push to OpenTelemetry directly. Instead you route the logs you care about into a Pub/Sub topic with a **Log Router sink**, and your Scout collector consumes that topic: ```text Log source (e.g. Load Balancer) │ ▼ Cloud Logging ──▶ Log Router sink ──▶ Pub/Sub topic │ ▼ subscription │ ▼ Scout collector (pubsub receiver) │ ▼ Scout ``` Pub/Sub retains undelivered messages (7 days by default), so the collector picks up a backlog on startup as well as new logs. ### Prerequisites - A Scout collector deployed and exporting to Scout (the `otlphttp/base14` exporter). See the [collector setup guides](../../collector-setup/otel-collector-config.md) for deployment options. - Permission to manage Cloud Logging, Pub/Sub, and IAM in your GCP project. - `gcloud` and/or Google Cloud console access. Replace these placeholders as you go: | Placeholder | Meaning | |---|---| | `PROJECT_ID` | Your GCP project **ID** (not the display name or number) | :::note This guide assumes the logs and the collector are in the **same** GCP project. If they're in different projects, see [Variant: cross-project](#variant-cross-project) at the end. ::: --- ### Step 1 — Decide what to export, and confirm it is being logged A Log Router sink selects logs with an **inclusion filter** based on `resource.type`. For the Load Balancer example, the resource type depends on the LB type: | Load balancer type | `resource.type` | |---|---| | Global external / classic Application LB (HTTP/S) | `http_load_balancer` | | Regional external Application LB | `http_external_regional_lb_rule` | | Internal Application LB | `internal_http_lb_rule` | | Regional/internal proxy Network LB | `l4_proxy_rule` | | Global external / classic proxy Network LB | `tcp_ssl_proxy_rule` | **Load balancer logs must be enabled first**, and logging is **per backend service**. Enable it on every backend service behind the LB (logging is not retroactive — only requests served *after* you enable it are logged): ```bash showLineNumbers gcloud compute backend-services update BACKEND_SERVICE \ --global \ --enable-logging \ --logging-sample-rate=1.0 ``` Use `--region=REGION` instead of `--global` for a regional LB. :::tip **Not sure which resource type your source uses?** In **Logs Explorer**, set a wide time range, generate some activity, and expand **Resource type** in the **Log fields** panel — it lists every resource type that has actually produced logs. Use that value as your filter. (Pick the `resource.type` for any other log source the same way.) ::: --- ### Step 2 — Create the Pub/Sub topic and subscription #### CLI ```bash showLineNumbers gcloud pubsub topics create scout-logs gcloud pubsub subscriptions create scout-logs-sub \ --topic=scout-logs \ --ack-deadline=30 ``` #### Console 1. **Pub/Sub → Topics → Create topic**, ID `scout-logs`. 2. Leave **Add a default subscription** checked — this creates a Pull subscription named `scout-logs-sub` automatically. 3. **Create**. The subscription **must be Pull** (the default) — the receiver does not create it. --- ### Step 3 — Create the Log Router sink #### CLI ```bash showLineNumbers gcloud logging sinks create scout-logs-sink \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='resource.type="http_load_balancer"' ``` #### Console 1. **Logging → Log Router → Create sink**. Name `scout-logs-sink`. **Next**. 2. **Sink service = Cloud Pub/Sub topic**, select `scout-logs`. **Next**. 3. Inclusion filter: `resource.type="http_load_balancer"`. **Next** → **Create sink**. Then grant the sink's **writer identity** permission to publish to the topic: #### CLI — grant publish permission ```bash showLineNumbers WRITER=$(gcloud logging sinks describe scout-logs-sink \ --format='value(writerIdentity)') gcloud pubsub topics add-iam-policy-binding scout-logs \ --member="$WRITER" \ --role="roles/pubsub.publisher" ``` #### Console — grant publish permission Log Router → sink's 3-dot menu → **View sink details** → copy the writer identity → Pub/Sub → Topics → `scout-logs` → permissions panel → **Add principal** → paste it (drop the `serviceAccount:` prefix) → role **Pub/Sub Publisher**. --- ### Step 4 — Authenticate the collector to Pub/Sub The collector needs a Google service account (GSA) with **Pub/Sub Subscriber** on the subscription. It discovers credentials via [Application Default Credentials](https://cloud.google.com/docs/authentication/application-default-credentials), so how you provide them depends on your deployment. #### a. Create the GSA ```bash showLineNumbers gcloud iam service-accounts create scout-logs-reader \ --display-name="Scout collector - Cloud Logging reader" ``` #### b. Grant Subscriber on the subscription ```bash showLineNumbers gcloud pubsub subscriptions add-iam-policy-binding scout-logs-sub \ --member="serviceAccount:scout-logs-reader@PROJECT_ID.iam.gserviceaccount.com" \ --role="roles/pubsub.subscriber" ``` #### c. Provide credentials to the collector ##### Service account key file (any environment) Create a key, place it on the host running the collector, and set the `GOOGLE_APPLICATION_CREDENTIALS` environment variable to its path: ```bash showLineNumbers gcloud iam service-accounts keys create \ scout-logs-reader-key.json \ --iam-account=scout-logs-reader@PROJECT_ID.iam.gserviceaccount.com ``` ```bash showLineNumbers title=".env" GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-logs-reader-key.json ``` The receiver picks this up automatically via Application Default Credentials. :::tip GKE Workload Identity On GKE with Workload Identity enabled, you can skip the key file entirely. Instead, bind the collector's Kubernetes ServiceAccount (KSA) to the GSA: ```bash gcloud iam service-accounts add-iam-policy-binding \ scout-logs-reader@PROJECT_ID.iam.gserviceaccount.com \ --role="roles/iam.workloadIdentityUser" \ --member="serviceAccount:PROJECT_ID.svc.id.goog[NAMESPACE/COLLECTOR_SERVICE_ACCOUNT]" ``` Then annotate the KSA: ```yaml serviceAccount: annotations: iam.gke.io/gcp-service-account: "scout-logs-reader@PROJECT_ID.iam.gserviceaccount.com" ``` No key file needed — the collector authenticates automatically. ::: --- ### Step 5 — Configure the collector Add the `googlecloudpubsub` receiver and a logs pipeline to your collector config: ```yaml showLineNumbers title="cloud-logging-config.yaml" receivers: # ...your existing receivers... googlecloudpubsub/cloud_logging: project: ${env:GCP_PROJECT_ID} subscription: projects/${env:GCP_PROJECT_ID}/subscriptions/scout-logs-sub encoding: cloud_logging # see "Choosing the encoding" below processors: memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... logs/cloud_logging: receivers: [googlecloudpubsub/cloud_logging] processors: [memory_limiter, batch] exporters: [otlphttp/base14] ``` #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity (see Step 4c) GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-logs-reader-key.json ``` #### Choosing the encoding Depending on your collector version, you may need to add an extension explicitly for the receiver to decode Cloud Logging entries: | Collector version | Encoding | Notes | |---|---|---| | **below 0.132** | `encoding: cloud_logging` | Built-in. No extension needed. | | **0.132 to 0.147** | `googlecloudlogentry_encoding` extension | The built-in `cloud_logging` was removed at 0.132. | | **0.142 and above** | same extension | Also parses Application LB logs into structured `gcp.load_balancing.*` attributes. | | **0.148 and above** | `google_cloud_logentry_encoding` extension | The type was renamed at 0.148. The old name was unavailable on 0.148 to 0.150 and came back at 0.151 as a deprecated alias. | If your collector version is above 0.132, here is how you add the extension. The examples use the current `google_cloud_logentry_encoding` type; on 0.132 to 0.147 use `googlecloudlogentry_encoding` instead. ```yaml showLineNumbers title="cloud-logging-config.yaml" extensions: # ...existing extensions... google_cloud_logentry_encoding: handle_json_payload_as: "json" handle_proto_payload_as: "json" receivers: googlecloudpubsub/cloud_logging: project: ${env:GCP_PROJECT_ID} subscription: projects/${env:GCP_PROJECT_ID}/subscriptions/scout-logs-sub encoding: google_cloud_logentry_encoding service: extensions: [google_cloud_logentry_encoding] pipelines: logs/cloud_logging: receivers: [googlecloudpubsub/cloud_logging] processors: [memory_limiter, batch] exporters: [otlphttp/base14] ``` On versions below 0.142 (with either encoding), the log record arrives as **JSON in the log body** rather than structured attributes. That's fine to ingest — see [Promoting JSON fields to attributes](#optional-promoting-json-fields-to-attributes) to break it out without upgrading. --- ### Step 6 — Verify 1. **Messages are in the subscription** (peek without consuming): ```bash showLineNumbers gcloud pubsub subscriptions pull scout-logs-sub --limit=5 ``` Empty? The problem is upstream (logging not enabled / sink filter / publisher grant). 2. **The collector has valid credentials.** Check the collector logs for authentication errors: ```bash showLineNumbers # Look for permission or credential errors # The exact command depends on your deployment: # Docker: docker logs # systemd: journalctl -u otelcol # Kubernetes: kubectl logs deploy/ -n ``` Look for `PermissionDenied` or `could not find default credentials` messages. 3. **The collector is consuming.** Once running, the subscription's **unacked message count drops** (the collector acks messages as it exports them). In the GCP console, check **Pub/Sub → Subscriptions → scout-logs-sub → Monitoring** for the unacked message graph. 4. **Logs appear in Scout.** Allow a short lag (seconds to a minute) end to end. --- ### Optional: Promoting JSON fields to attributes To turn the JSON body into queryable log attributes — without changing the collector image — add a `transform` processor to the logs pipeline. Inspect a sample message first (Step 6.1) to confirm the field paths, then: ```yaml showLineNumbers title="cloud-logging-config.yaml" processors: transform/cloud_logging: log_statements: - context: log statements: - set(attributes["http.status_code"], body["httpRequest"]["status"]) - set(attributes["http.request.method"], body["httpRequest"]["requestMethod"]) - set(attributes["url.full"], body["httpRequest"]["requestUrl"]) # ...add the fields you need... ``` Add `transform/cloud_logging` to the pipeline's `processors` list (after `memory_limiter`, before `batch`). --- ### Variant: cross-project If the logs/Pub/Sub live in one project (`LOGS_PROJECT`) and the collector in another (`COLLECTOR_PROJECT`): - **Create the GSA in `COLLECTOR_PROJECT`** (Step 4a, add `--project=COLLECTOR_PROJECT`). - **Grant Subscriber across projects** (Step 4b): member is the `COLLECTOR_PROJECT` GSA, but the subscription resource is in `LOGS_PROJECT` (`--project=LOGS_PROJECT`). - **The receiver points at `LOGS_PROJECT`** — `project:` and `subscription:` both reference `LOGS_PROJECT`, even though the GSA lives in the collector project. If using GKE Workload Identity, the WI binding uses the collector project's pool: `COLLECTOR_PROJECT.svc.id.goog[NAMESPACE/COLLECTOR_SERVICE_ACCOUNT]`. --- ### Troubleshooting **`http_load_balancer` (or your resource type) does not appear in Logs Explorer.** The resource-type picker only lists types that have logged something in the time window. Either no logs have been produced yet (logging not enabled, no traffic since enabling, or sampling at 0), or your source uses a different `resource.type` (see the table in Step 1). **Logs in the subscription but not in Scout.** Check, in order: the collector has valid credentials, collector logs show no auth errors, and that you added the **pipeline** — a receiver not referenced by any pipeline is loaded but never consumes. Also confirm the receiver's `subscription:` path is correct. **`PermissionDenied` on the subscription.** The Subscriber grant (Step 4b) has not propagated yet (allow a few minutes), or was granted in the wrong project for cross-project setups. **"could not find default credentials".** `GOOGLE_APPLICATION_CREDENTIALS` is not set or points to a missing file. On GKE, this means the Workload Identity binding or ServiceAccount annotation is missing. **Backlog never drains.** The collector is not consuming. This is almost always auth (above) or a missing pipeline. A draining backlog means the path works: acking is how Pub/Sub confirms delivery, and the data has gone to Scout rather than being lost. ### FAQ #### How do I send Google Cloud Logging logs to OpenTelemetry? Route the logs into a Pub/Sub topic with a Log Router sink, then consume that topic with the `googlecloudpubsub` receiver in your Scout collector. There is no direct pull API for Cloud Logging. #### How does the collector authenticate to Pub/Sub? Through Google Application Default Credentials. Set `GOOGLE_APPLICATION_CREDENTIALS` to a service account key file, or use GKE Workload Identity and skip key files entirely. #### Can I stream logs from multiple GCP projects into one Scout collector? Yes. Create the service account in the collector's project, grant it Pub/Sub Subscriber on the subscription in the logs project, and point the receiver at that cross-project subscription. #### What encoding should I use for the googlecloudpubsub receiver? On collector versions below 0.132, use the built-in `cloud_logging` encoding. On 0.132 and above, use the Cloud Logging LogEntry encoding extension, which also parses structured attributes from 0.142 onward. The extension's type is `google_cloud_logentry_encoding` from 0.148 and `googlecloudlogentry_encoding` before that. #### Why are my Cloud Logging logs not appearing in Scout? Check in order: messages are reaching the Pub/Sub subscription, the collector has valid GCP credentials, the collector logs show no permission errors, and the receiver is actually referenced in a logs pipeline. ### Related Guides - [GCP Monitoring overview](./overview.md) - the architecture behind this path, and the resource attributes every GCP pipeline should set. - [GCP Cloud Monitoring](./gcp-cloud-monitoring-to-scout.md) - the metrics path, which needs none of the Pub/Sub setup above. - [VPC](./vpc.md) - flow logs, the highest-volume consumer of this pipeline. - [Cloud Load Balancing](./load-balancing.md) - what the access logs used as this guide's example actually contain. - [Cloud Run](./cloud-run.md) - request and application logs, and when to use a sidecar instead of this path. --- ## Sending GCP Managed Service Metrics to Scout with OpenTelemetry This guide shows you how to collect metrics for **GCP managed services** — Cloud SQL, Memorystore, Pub/Sub, Cloud Run, BigQuery, Compute Engine — into Scout using the OpenTelemetry `googlecloudmonitoring` receiver. If you also want GCP **logs**, that is a separate mechanism: see [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md). For the architecture behind both, and the resource attributes every GCP pipeline should set, start at the [GCP Monitoring overview](./overview.md). :::note Running this in production Storing and querying these metrics at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### How it works Anything visible in Cloud Monitoring's Metrics Explorer can be collected. The receiver **pulls** from the Cloud Monitoring API on an interval — nothing is pushed to it: ```text Managed service (e.g. Cloud SQL) │ (GCP publishes metrics automatically) ▼ Cloud Monitoring │ Monitoring API (polled) ▼ Scout collector (googlecloudmonitoring receiver) │ ▼ Scout ``` Because it is a pull, there is no Log Router sink, Pub/Sub topic, subscription, or publisher IAM binding to create. The setup is one IAM role and a list of metrics. :::note Metrics are pulled on a schedule, not streamed. If the collector is down for a period, that window is not backfilled — unlike the logs path, where Pub/Sub retains a backlog. ::: ### Prerequisites - A Scout collector deployed and exporting to Scout (the `otlphttp/base14` exporter). See the [collector setup guides](../../collector-setup/otel-collector-config.md) for deployment options. - Permission to manage IAM in your GCP project. - `gcloud` and/or Google Cloud console access. - The managed services you want to monitor are already running — GCP publishes their metrics automatically, with nothing to enable. Replace these placeholders as you go: | Placeholder | Meaning | |---|---| | `PROJECT_ID` | Your GCP project **ID** (not the display name or number) | :::note This guide assumes the metrics and the collector are in the **same** GCP project. For multiple projects, add one receiver instance per project — a receiver takes a single `project_id`. ::: --- ### Step 1 — Choose your metrics Every metric is identified by its full **metric type**, for example `cloudsql.googleapis.com/database/cpu/utilization`. Find the ones you want in **Monitoring → Metrics Explorer**. Two things to check while you are there: 1. **Confirm the metric is actually being emitted.** Enable the **Active** toggle in the metric picker, which hides metrics that have produced no data. Names vary between projects for the same service, so a name copied from documentation may return nothing in yours. 2. **Note the metric's Kind and Type** (shown in the picker as, for example, `GAUGE`, `DOUBLE`). This matters — see [Metric kinds and types](#metric-kinds-and-types) below. :::tip Finding the full list for a service Google publishes every metric it emits, split across alphabetical pages under [Google Cloud metrics](https://docs.cloud.google.com/monitoring/api/metrics_gcp). Each entry gives the metric type, kind, value type, and unit — so this is also where you check whether a metric is a distribution. - [Cloud SQL](https://docs.cloud.google.com/monitoring/api/metrics_gcp_c#gcp-cloudsql) — around 100 metrics, including engine-specific ones under `database/postgresql/`, `database/mysql/`, and `database/sqlserver/`. - [Memorystore for Redis](https://docs.cloud.google.com/monitoring/api/metrics_gcp_p_z#gcp-redis) — around 40 metrics under `stats/`, `clients/`, `commands/`, `replication/`, and `server/`. Use these to discover candidates, then confirm each one against Metrics Explorer's **Active** toggle before adding it to your config. The lists are exhaustive for the service, but no project emits all of them. ::: --- ### Step 2 — Authenticate the collector The collector needs a Google service account (GSA) with the **Monitoring Viewer** role. It discovers credentials via [Application Default Credentials](https://cloud.google.com/docs/authentication/application-default-credentials), so how you provide them depends on your deployment. If you already set up [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md), reuse that service account and add the role below — no second identity needed. #### a. Create the GSA ```bash showLineNumbers gcloud iam service-accounts create scout-metrics-reader \ --display-name="Scout collector - Cloud Monitoring reader" ``` #### b. Grant Monitoring Viewer This is a **project-level** role — metrics are read per project, not per resource: ```bash showLineNumbers gcloud projects add-iam-policy-binding PROJECT_ID \ --member="serviceAccount:scout-metrics-reader@PROJECT_ID.iam.gserviceaccount.com" \ --role="roles/monitoring.viewer" \ --condition=None ``` :::note `roles/monitoring.viewer` is read-only. It grants no ability to write metrics, change alerting, or read logs. ::: #### c. Provide credentials to the collector ##### Service account key file (any environment) ```bash showLineNumbers gcloud iam service-accounts keys create \ scout-metrics-reader-key.json \ --iam-account=scout-metrics-reader@PROJECT_ID.iam.gserviceaccount.com ``` ```bash showLineNumbers title=".env" GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-metrics-reader-key.json ``` :::tip GKE Workload Identity On GKE with Workload Identity enabled, skip the key file. Bind the collector's Kubernetes ServiceAccount (KSA) to the GSA: ```bash gcloud iam service-accounts add-iam-policy-binding \ scout-metrics-reader@PROJECT_ID.iam.gserviceaccount.com \ --role="roles/iam.workloadIdentityUser" \ --member="serviceAccount:PROJECT_ID.svc.id.goog[NAMESPACE/COLLECTOR_SERVICE_ACCOUNT]" ``` Then annotate the KSA: ```yaml serviceAccount: annotations: iam.gke.io/gcp-service-account: "scout-metrics-reader@PROJECT_ID.iam.gserviceaccount.com" ``` ::: :::warning Deployment, not DaemonSet Put this receiver on a collector **Deployment**, not a DaemonSet. It scrapes a remote API rather than local state, so every replica repeats the same calls — a 3-replica DaemonSet triples your API usage and produces duplicate series. Where the GSA annotation lives determines which collector can authenticate at all. ::: --- ### Step 3 — Configure the collector Add the `googlecloudmonitoring` receiver and a metrics pipeline: ```yaml showLineNumbers title="cloud-monitoring-config.yaml" receivers: # ...your existing receivers... googlecloudmonitoring: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: # Cloud SQL - metric_name: "cloudsql.googleapis.com/database/cpu/utilization" - metric_name: "cloudsql.googleapis.com/database/memory/utilization" - metric_name: "cloudsql.googleapis.com/database/disk/bytes_used" - metric_name: "cloudsql.googleapis.com/database/disk/quota" - metric_name: "cloudsql.googleapis.com/database/disk/utilization" # Memorystore for Redis - metric_name: "redis.googleapis.com/stats/memory/usage_ratio" - metric_name: "redis.googleapis.com/stats/cpu_utilization_main_thread" - metric_name: "redis.googleapis.com/clients/connected" - metric_name: "redis.googleapis.com/stats/keyspace_hits" - metric_name: "redis.googleapis.com/stats/keyspace_misses" - metric_name: "redis.googleapis.com/stats/evicted_keys" processors: memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/gcp: receivers: [googlecloudmonitoring] processors: [memory_limiter, batch] exporters: [otlphttp/base14] ``` #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity (see Step 2c) GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-metrics-reader-key.json ``` #### Receiver options | Field | Default | Notes | |---|---|---| | `project_id` | — | **Required.** One project per receiver instance. | | `metrics_list` | — | **Required.** One entry per metric or filter. | | `collection_interval` | `300s` | Minimum `60s`. Shorter intervals cost more API quota. | | `initial_delay` | `1s` | Delay before the first scrape. | | `timeout` | `1m` | Timeout for Monitoring API calls. | | `endpoint` | `monitoring.googleapis.com:443` | Override only for non-standard universe domains. | #### Collecting a whole service at once Instead of naming every metric, an entry can use `metric_descriptor_filter` with a `starts_with` expression on `metric.type`: ```yaml showLineNumbers metrics_list: - metric_descriptor_filter: 'metric.type = starts_with("cloudsql.googleapis.com/")' ``` An entry must set **either** `metric_name` **or** `metric_descriptor_filter` — never both. Only `project` and `metric.type` are supported in the filter. :::warning A broad prefix collects everything the service emits, including high-cardinality and distribution-valued metrics you may not want. Start with an explicit `metric_name` list, and move to a prefix filter only once you know what a service emits. ::: --- ### Step 4 — Verify 1. **The collector starts cleanly.** Check its logs for `PermissionDenied` or `could not find default credentials`: ```bash showLineNumbers # The exact command depends on your deployment: # Docker: docker logs # systemd: journalctl -u otelcol # Kubernetes: kubectl logs deploy/ -n ``` 2. **Metrics appear in Scout.** Allow at least one full `collection_interval` plus export time before concluding anything. 3. **Check the metric landed where you expect.** The GCP metric kind does not reliably predict which OTel metric type the receiver produces — a `CUMULATIVE` metric can arrive as a gauge. If a metric is missing from one view in Scout, look for it as the other type before assuming it failed. --- ### Metric kinds and types Each GCP metric has a **kind** (`GAUGE`, `DELTA`, `CUMULATIVE`) and a **value type** (`INT64`, `DOUBLE`, `DISTRIBUTION`). Scalar metrics are straightforward. Distributions need care: | Value type | Behaviour | |---|---| | `INT64`, `DOUBLE`, `BOOL` | Collected normally. | | `DELTA` + `DISTRIBUTION` | Supported from collector v0.129.0. | | `GAUGE` + `DISTRIBUTION` | **Not supported.** Can fail the scrape. | :::warning One bad metric can drop all of them A `GAUGE`-kind `DISTRIBUTION` can yield an invalid data point that fails the **entire scrape batch** — dropping every metric from that receiver instance, not just the offending one. Metrics that worked yesterday all vanish after one new entry is added. If metrics disappear after a config change, remove the distribution-valued metric you added and confirm the rest return. Latency metrics (`*_latencies`, `*_times`) are the usual culprits. ::: Most managed-service metrics are scalars. Check a metric's value type in Metrics Explorer before adding it. --- ### Common services Prefixes to use with Metrics Explorer or `metric_descriptor_filter`: | Service | Metric type prefix | Guide | |---|---|---| | Cloud SQL | `cloudsql.googleapis.com/` | [Cloud SQL](./cloud-sql.md) | | Memorystore for Redis | `redis.googleapis.com/` | [Memorystore](./memorystore.md) | | Memorystore for Valkey | `memorystore.googleapis.com/instance/` | [Memorystore](./memorystore.md) | | Pub/Sub | `pubsub.googleapis.com/` | [Pub/Sub](./pub-sub.md) | | Cloud Run | `run.googleapis.com/` | [Cloud Run](./cloud-run.md) | | Cloud Load Balancing | `loadbalancing.googleapis.com/` | [Cloud Load Balancing](./load-balancing.md) | | API Gateway | `apigateway.googleapis.com/` | [API Gateway and nginx](./api-gateway.md) | | Cloud NAT | `router.googleapis.com/nat/` | [VPC](./vpc.md) | | BigQuery | `bigquery.googleapis.com/` | - | | Compute Engine | `compute.googleapis.com/` | - | | Cloud Storage | `storage.googleapis.com/` | - | :::tip Managed service vs. self-hosted This receiver only sees **GCP-managed** services. Software you run yourself on a VM or in Kubernetes — Redis on Compute Engine, self-hosted PostgreSQL — publishes nothing to Cloud Monitoring beyond VM-level metrics. For those, use the matching [component receiver](../../component/redis.md) instead. ::: :::note Managed databases: two complementary views For Cloud SQL, this receiver gives you host-level metrics — CPU, memory, disk, quota. It cannot see inside the database. For query, table, lock, and connection detail, point [base14 pgX](../../../operate/pgx/overview.md) at the instance as well. The two overlap very little. ::: --- ### Troubleshooting **No metrics at all, and the collector logs `PermissionDenied`.** The `roles/monitoring.viewer` grant (Step 2b) is missing or has not propagated yet — allow a few minutes. Confirm it applies to the project named in `project_id`. **"could not find default credentials".** `GOOGLE_APPLICATION_CREDENTIALS` is unset or points at a missing file. On GKE, the Workload Identity binding or the KSA annotation is missing. **One specific metric never appears.** Usually the name is wrong or that project does not emit it. Paste the exact metric type into Metrics Explorer with the **Active** toggle on. Projects legitimately differ in which variants of a metric family they emit. **Everything stopped after adding a metric.** See [Metric kinds and types](#metric-kinds-and-types) — a distribution-valued metric can fail the whole scrape batch. **Metrics are duplicated, or API quota is higher than expected.** More than one collector replica is running the receiver. Each replica polls independently. Run this receiver on a single-replica Deployment. **The receiver is configured but nothing happens.** Confirm it is referenced in a **pipeline**. A receiver that no pipeline lists is loaded but never runs. ### FAQ #### How do I send GCP managed service metrics to OpenTelemetry? Use the `googlecloudmonitoring` receiver. It polls the Cloud Monitoring API on an interval and needs only the `roles/monitoring.viewer` IAM role. No Pub/Sub topic, subscription, or Log Router sink is involved. #### Do GCP metrics need Pub/Sub like Cloud Logging logs do? No. Logs are pushed through a Log Router sink into Pub/Sub, but metrics are pulled straight from the Cloud Monitoring API by the collector. There is no sink, topic, subscription, or publisher IAM binding to create. #### How does the collector authenticate to Cloud Monitoring? Through Application Default Credentials. On GKE, use Workload Identity so no key file is needed. Elsewhere, set `GOOGLE_APPLICATION_CREDENTIALS` to a service account key file. #### Can I collect a whole GCP service without listing every metric? Yes. Use `metric_descriptor_filter` with a `starts_with` expression on `metric.type`, for example `metric.type = starts_with("cloudsql.googleapis.com/")`, instead of naming each metric individually. #### Why did all my GCP metrics stop arriving after adding one metric? A GAUGE-kind DISTRIBUTION metric can produce an invalid data point that fails the whole scrape batch, dropping every metric from that receiver instance. Remove the distribution-valued metric and the rest resume. --- ## Google Cloud Load Balancing Monitoring with OpenTelemetry Cloud Load Balancing is the outermost hop in most GCP architectures, and the only place that sees every request — including the ones that never reach a backend. This guide collects its metrics with the `googlecloudmonitoring` receiver and its access logs through the Cloud Logging path, where the encoding extension maps them onto HTTP semantic conventions. Read [GCP Monitoring overview](./overview.md) first — it covers the collector image, IAM, and resource attributes this guide assumes. :::note Running this in production Storing and querying this telemetry at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### Overview Cloud Load Balancing metrics are organized by load balancer family, and each family has its own metric namespace and monitored resource. Pick the one matching what you actually run: | Load balancer | Metric namespace | Monitored resource | |---|---|---| | Global external Application LB | `loadbalancing.googleapis.com/https/` | `https_lb_rule` | | Regional external Application LB | `loadbalancing.googleapis.com/https/` | `http_external_regional_lb_rule` | | Internal Application LB | `loadbalancing.googleapis.com/https/internal/` | `internal_http_lb_rule` | | External proxy Network LB | `loadbalancing.googleapis.com/tcp_ssl_proxy/` | `tcp_ssl_proxy_rule` | | Internal passthrough Network LB | `loadbalancing.googleapis.com/l3/internal/` | `internal_tcp_lb_rule`, `internal_udp_lb_rule` | | External passthrough Network LB | `loadbalancing.googleapis.com/l3/external/` | `tcp_lb_rule`, `udp_lb_rule` | The Application LB families carry HTTP semantics — status codes, routes, cache results. The Network LB families are connection and byte counters only, with no HTTP dimension at all. ### What each signal tells you Metrics and logs answer different questions here, and production deployments want both: - **Metrics** give you rates and latency distributions cheaply, at a fixed cost regardless of traffic volume. They cannot tell you which URL was slow or which client was blocked. - **Access logs** give you per-request detail — the path, the backend chosen, the `statusDetails` string explaining a 502 — at a cost proportional to request volume. --- ### Receiver configuration ```yaml showLineNumbers title="load-balancing-config.yaml" receivers: # ...your existing receivers... googlecloudmonitoring/loadbalancing: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: # Request rates and volume - metric_name: "loadbalancing.googleapis.com/https/request_count" - metric_name: "loadbalancing.googleapis.com/https/request_bytes_count" - metric_name: "loadbalancing.googleapis.com/https/response_bytes_count" - metric_name: "loadbalancing.googleapis.com/https/backend_request_count" # Latency — all distributions, see the warning below - metric_name: "loadbalancing.googleapis.com/https/total_latencies" - metric_name: "loadbalancing.googleapis.com/https/backend_latencies" - metric_name: "loadbalancing.googleapis.com/https/frontend_tcp_rtt" processors: resource/loadbalancing: attributes: - {key: service.name, value: loadbalancing-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_load_balancing, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} transform/loadbalancing: error_mode: ignore metric_statements: - context: datapoint statements: - delete_key(attributes, "client_country") - delete_key(attributes, "proxy_continent") memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/loadbalancing: receivers: [googlecloudmonitoring/loadbalancing] processors: [memory_limiter, resource/loadbalancing, transform/loadbalancing, batch] exporters: [otlphttp/base14] ``` The `transform/loadbalancing` processor is not optional in most deployments — see [Cardinality control](#cardinality-control) for why. :::warning The latency metrics are distributions `total_latencies`, `backend_latencies` and `frontend_tcp_rtt` are all `DELTA` + `DISTRIBUTION`, which is supported from collector v0.129.0 and lands in `otel_metrics_histogram` with delta temporality. On an older collector they will fail, and a distribution failure drops the **entire scrape batch** — every metric from this receiver, not just the latency one. If your request-rate metrics vanish after you add latency, this is why. ::: #### Internal and Network load balancers For internal Application LBs, swap the `https/` prefix for `https/internal/`. For passthrough Network LBs there is no HTTP family at all — use the byte and packet counters: ```yaml showLineNumbers title="load-balancing-config.yaml" metrics_list: - metric_name: "loadbalancing.googleapis.com/l3/internal/ingress_bytes_count" - metric_name: "loadbalancing.googleapis.com/l3/internal/egress_bytes_count" - metric_name: "loadbalancing.googleapis.com/l3/internal/ingress_packets_count" - metric_name: "loadbalancing.googleapis.com/l3/internal/rtt_latencies" ``` #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` --- ### Authentication and IAM `roles/monitoring.viewer` for metrics, plus `roles/pubsub.subscriber` on the subscription if you also collect access logs. See [GCP Monitoring overview](./overview.md#authentication). --- ### What you'll monitor | Metric | Kind | Unit | Use case | |---|---|---|---| | `https/request_count` | **Delta** sum | count | Request rate, split by `response_code_class`. The error-rate numerator and denominator both come from here. | | `https/backend_request_count` | **Delta** sum | count | Requests the LB actually forwarded. The gap against `request_count` is what the LB served or rejected itself — cache hits, redirects, Cloud Armor blocks. | | `https/total_latencies` | **Delta** histogram | ms | End-to-end, proxy receive to client ACK. This is what your users experience. | | `https/backend_latencies` | **Delta** histogram | ms | Proxy to backend round trip. Subtract from total to isolate network and client-side time. | | `https/frontend_tcp_rtt` | **Delta** histogram | ms | Client-to-proxy RTT. Rises for geographically distant clients, independent of your backends. | | `https/request_bytes_count` | **Delta** sum | bytes | Ingress volume; upload-heavy workloads spot problems here first. | | `https/response_bytes_count` | **Delta** sum | bytes | Egress volume, which is directly billable. | Every one of these is `DELTA`, so sum the points over your window rather than treating them as monotonic counters. The labels worth grouping by: | Label | Values | Why it matters | |---|---|---| | `response_code` | Exact status | Distinguishing 502 from 503 changes the diagnosis | | `response_code_class` | `200`, `300`, `400`, `500` | The cheap error-rate dimension | | `cache_result` | `HIT`, `MISS`, `DISABLED`, and others | Cloud CDN effectiveness | | `protocol` | `HTTP/1.1`, `HTTP/2`, `HTTP/3` | Protocol-specific regressions | | `client_country` | ~250 ISO codes | Useful, and expensive in proportion | | `proxy_continent` | 6 or so | Which GFE region served the request | --- ### Cardinality control Cloud Load Balancing is the highest-cardinality metric surface in this set, because its labels multiply. | Attribute | Source | Cardinality | Keep? | |---|---|---|---| | `forwarding_rule_name`, `url_map_name` | Resource label | One per LB | Yes | | `backend_target_name` | Resource label | One per backend service | Yes | | `response_code_class` | Metric label | 4 | Yes | | `response_code` | Metric label | Tens | Usually | | `cache_result` | Metric label | ~6 | If you use Cloud CDN | | `proxy_continent` | Metric label | ~6 | Rarely | | `client_country` | Metric label | ~250 | No, by default | `client_country` × `response_code` × `protocol` × `cache_result` on a single forwarding rule produces tens of thousands of series before you have added a second load balancer. The `transform` processor in the config above drops the two worst offenders. If you do want geographic breakdown, take it from the **access logs** rather than the metrics. Logs carry the client IP and geo fields per request without multiplying a permanent time series. --- ### Alert tuning | Signal | Source metric | Warning | Critical | Notes | |---|---|---|---|---| | Error rate | `https/request_count` where `response_code_class = 500` | > 1% for 5m | > 5% for 5m | Compute against the total, not against a fixed count. | | Backend latency | `https/backend_latencies` p99 | > 1s for 10m | > 3s for 5m | Use backend rather than total, so client network conditions do not page you. | | Frontend-backend divergence | `total_latencies` p99 minus `backend_latencies` p99 | growing | — | A widening gap points at the client network or the proxy, not your service. | | Backend unreachable | `https/backend_request_count` vs `request_count` | ratio drops | ratio near zero | Sudden divergence means the LB is failing requests before they reach a backend. | | Cache hit rate | `https/request_count` where `cache_result = HIT` | falling | — | Only meaningful with Cloud CDN enabled. | | Egress spike | `https/response_bytes_count` | 2x baseline | 5x baseline | Cost control as much as an incident signal. | --- ### Logs Access logs are where per-request detail lives. The [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) guide uses load balancer logs as its worked example, including the `resource.type` table for each LB family — follow it for the sink, topic and subscription, then return here for what the entries contain. Enable logging on the backend service first; it is off by default: ```bash showLineNumbers gcloud compute backend-services update BACKEND_SERVICE \ --global \ --enable-logging \ --logging-sample-rate=1.0 ``` Lower `--logging-sample-rate` on high-volume load balancers. A sample rate of `0.1` still gives usable error analysis at a tenth of the volume, and errors are what these logs are mostly for. #### What the encoding extension produces With `google_cloud_logentry_encoding`, load balancer entries are recognized as `gcp.load-balancer` format and mapped onto semantic conventions rather than left as an opaque JSON body: | Log field | OTel attribute | |---|---| | `httpRequest.requestMethod` | `http.request.method` | | `httpRequest.requestUrl` | `url.full`, plus parsed `url.path`, `url.query`, `url.domain` | | `httpRequest.status` | `http.response.status_code` | | `httpRequest.latency` | `http.request.server.duration` | | `httpRequest.remoteIp` | `network.peer.address` | | `httpRequest.userAgent` | `user_agent.original` | | `statusDetails` | `gcp.load_balancing.status_details` | | `proxyStatus` | `gcp.load_balancing.proxy_status` | | `cacheDecision` | `gcp.load_balancing.cache.decision` | | `tls.protocol` | `tls.protocol.name` | `statusDetails` is the single most useful field for debugging a 5xx — it distinguishes `backend_connection_closed_before_data_sent_to_client` from `failed_to_pick_backend` from `client_disconnected_before_any_response`, which are three entirely different problems behind the same status code. #### Cloud Armor If Cloud Armor fronts the load balancer, its decisions appear in the same log stream and the extension maps them to `gcp.armor.*` — the rule that matched, its priority, the configured action, and the outcome, plus `tls.client.ja3` and `tls.client.ja4` fingerprints. Blocked requests appear in the LB metrics as 403s but only the logs say which rule did it. --- ### Verify 1. **The collector starts cleanly** — check for `PermissionDenied` in its logs. 2. **The latency metrics did not break the batch.** If `request_count` stopped arriving when you added them, see the warning above. 3. **Confirm the metrics landed:** ```sql showLineNumbers SELECT MetricName, count() AS points, sum(Value) AS total FROM otel_metrics_sum WHERE ServiceName = 'loadbalancing-metrics' AND MetricName = 'loadbalancing.googleapis.com/https/request_count' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` Latency metrics are in `otel_metrics_histogram`. 4. **Confirm the logs landed and were decoded.** Look for `http.response.status_code` as an attribute rather than raw JSON in the body — if the body is unparsed JSON, the encoding extension is not wired into the pipeline. --- ### Troubleshooting **Metrics arrive but the load balancer is not the one you meant.** Several LB families share the `https/` prefix but use different monitored resources. Group by `forwarding_rule_name` to see which rules are actually reporting. **Access logs are empty despite the sink existing.** Logging is off by default on backend services. Run the `gcloud compute backend-services update --enable-logging` command above, and confirm with `--logging-sample-rate` set above zero. **Log bodies are raw JSON with no HTTP attributes.** The `google_cloud_logentry_encoding` extension is missing from the receiver's `encoding` field or from the `service.extensions` list. See [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md). **The series count is far higher than expected.** `client_country` alone contributes around 250 values, multiplied by every other label. Add the `transform` processor from the config above. **`backend_latencies` is missing but `total_latencies` is present.** Requests are being served without reaching a backend — cache hits, redirects, or Cloud Armor denials. That divergence is itself the useful signal. ### FAQ #### How do I monitor a Google Cloud load balancer with OpenTelemetry? Use the `googlecloudmonitoring` receiver against the `loadbalancing.googleapis.com/` prefix for metrics, and route access logs through a Log Router sink into Pub/Sub for the `googlecloudpubsub` receiver. Metrics give you rates and latency distributions; logs give you per-request detail. #### Which Cloud Load Balancing metrics matter most? Error rate comes from `https/request_count` split by `response_code_class`, and latency from `https/backend_latencies`. Backend latency is the better alerting signal than total latency, because total includes client network conditions you cannot fix. #### Why did all my load balancer metrics stop after adding latency? The latency metrics are distributions, which need collector v0.129.0 or later. On older builds an invalid distribution data point fails the entire scrape batch, dropping every metric from that receiver instance. #### How do I control load balancer metric cardinality? Drop `client_country` and `proxy_continent` with a `transform` processor. `client_country` alone has around 250 values and multiplies against every other label. Take geographic analysis from the access logs instead, where it costs nothing permanent. #### What is the difference between total_latencies and backend_latencies? `total_latencies` measures from when the proxy received the request to when the client acknowledged the response, so it includes client network time. `backend_latencies` measures only the proxy-to-backend round trip. A widening gap between them points at the network, not your service. #### Do I need Cloud Armor logs separately? Cloud Armor decisions appear in the same load balancer log stream, so no second sink is needed. The encoding extension maps them to `gcp.armor.*` attributes automatically. ### Reference - [Cloud Load Balancing metrics](https://docs.cloud.google.com/load-balancing/docs/metrics) - [Application Load Balancer logging](https://docs.cloud.google.com/load-balancing/docs/https/https-logging-monitoring) - [statusDetails reference](https://docs.cloud.google.com/load-balancing/docs/https/https-logging-monitoring#what_is_logged) ### Related Guides - [GCP Monitoring overview](./overview.md) - why the distribution metrics on this page need a recent collector build. - [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) - the sink and encoding setup the Logs section depends on. - [API Gateway and nginx](./api-gateway.md) - the gateway layer that usually sits behind this load balancer. - [Cloud Run](./cloud-run.md) - a common backend, and where the traces that correlate with these requests originate. --- ## Memorystore for Redis and Valkey Monitoring with OpenTelemetry Memorystore publishes cache metrics to Cloud Monitoring for all three of its engines. This guide collects them into Scout with the `googlecloudmonitoring` receiver, and covers the metric-namespace differences between Redis, Redis Cluster and Valkey — which are larger than the product naming suggests. Read [GCP Monitoring overview](./overview.md) first — it covers the collector image, IAM, and resource attributes this guide assumes. :::note Running this in production Storing and querying these metrics at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### Overview Memorystore is three products under one name, and each publishes to a different metric prefix. Getting this wrong is the most common reason a Memorystore config returns no data at all. | Product | Metric prefix | Monitored resource | |---|---|---| | Memorystore for Redis (Basic, Standard) | `redis.googleapis.com/` | `redis_instance` | | Memorystore for Redis Cluster | `redis.googleapis.com/cluster/` | `redis_instance` | | Memorystore for Valkey | `memorystore.googleapis.com/instance/` | `memorystore.googleapis.com/Instance` | Check which you have before writing a config: **Monitoring → Metrics Explorer**, type the prefix, and turn on the **Active** toggle so it hides metrics with no data. ### Memorystore at a glance | Layer | What it tells you | Where it comes from | |---|---|---| | Cache effectiveness | Hit ratio, evictions, expirations | Cloud Monitoring | | Memory pressure | Usage ratio, system memory, maxmemory | Cloud Monitoring | | Client health | Connected, blocked and rejected clients | Cloud Monitoring | | Replication | Replica lag, offset difference | Cloud Monitoring | | Command detail | Per-command call counts and latency | Cloud Monitoring (high cardinality) or the `redis` receiver | | Keyspace contents | Key counts, TTL distribution | The `redis` receiver | --- ### Receiver configuration The block below is for **Memorystore for Redis**. Swap the metric names for the Valkey or Cluster set shown afterwards if that is what you run. ```yaml showLineNumbers title="memorystore-config.yaml" receivers: # ...your existing receivers... googlecloudmonitoring/memorystore: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: # Cache effectiveness - metric_name: "redis.googleapis.com/stats/cache_hit_ratio" - metric_name: "redis.googleapis.com/stats/keyspace_misses" - metric_name: "redis.googleapis.com/stats/evicted_keys" # Memory - metric_name: "redis.googleapis.com/stats/memory/usage" - metric_name: "redis.googleapis.com/stats/memory/usage_ratio" - metric_name: "redis.googleapis.com/stats/memory/maxmemory" - metric_name: "redis.googleapis.com/stats/memory/system_memory_usage_ratio" # Clients and connections - metric_name: "redis.googleapis.com/clients/connected" - metric_name: "redis.googleapis.com/clients/blocked" - metric_name: "redis.googleapis.com/stats/connections/total" - metric_name: "redis.googleapis.com/stats/reject_connections_count" # Load and keyspace - metric_name: "redis.googleapis.com/stats/cpu_utilization" - metric_name: "redis.googleapis.com/stats/cpu_utilization_main_thread" - metric_name: "redis.googleapis.com/stats/network_traffic" - metric_name: "redis.googleapis.com/keyspace/keys" - metric_name: "redis.googleapis.com/server/uptime" # Replication — Standard tier only - metric_name: "redis.googleapis.com/replication/master/slaves/lag" - metric_name: "redis.googleapis.com/replication/offset_diff" processors: resource/memorystore: attributes: - {key: service.name, value: memorystore-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_memorystore, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: cloud.region, value: "${env:GCP_REGION}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/memorystore: receivers: [googlecloudmonitoring/memorystore] processors: [memory_limiter, resource/memorystore, batch] exporters: [otlphttp/base14] ``` #### Memorystore for Valkey Valkey uses an entirely different namespace, and splits metrics between instance scope and node scope: ```yaml showLineNumbers title="memorystore-config.yaml" metrics_list: - metric_name: "memorystore.googleapis.com/instance/cpu/average_utilization" - metric_name: "memorystore.googleapis.com/instance/cpu/maximum_utilization" - metric_name: "memorystore.googleapis.com/instance/memory/total_used_memory" - metric_name: "memorystore.googleapis.com/instance/memory/utilization" - metric_name: "memorystore.googleapis.com/instance/keyspace/total_keys" - metric_name: "memorystore.googleapis.com/instance/stats/total_keyspace_hits_count" - metric_name: "memorystore.googleapis.com/instance/stats/total_keyspace_misses_count" - metric_name: "memorystore.googleapis.com/instance/stats/total_connections_received_count" - metric_name: "memorystore.googleapis.com/instance/replication/average_ack_lag" - metric_name: "memorystore.googleapis.com/instance/node/clients/connected_clients" - metric_name: "memorystore.googleapis.com/instance/node/memory/usage" - metric_name: "memorystore.googleapis.com/instance/node/stats/evicted_keys_count" ``` Note that Valkey has **no equivalent of `cache_hit_ratio`** — it publishes `total_keyspace_hits_count` and `total_keyspace_misses_count` as separate cumulative counters, so compute the ratio at query time. Memorystore for Redis is the reverse: it publishes the ready-made ratio and `keyspace_misses`, but no hits counter. Node-scoped metrics carry a `node_id` label. On a large cluster that multiplies your series count by the shard count; see [Cardinality control](#cardinality-control). #### Collecting the whole service ```yaml showLineNumbers title="memorystore-config.yaml" metrics_list: - metric_descriptor_filter: 'metric.type = starts_with("redis.googleapis.com/")' ``` Around 40 metric types for Redis, considerably more for Valkey. Both are small enough that the whole-service filter is reasonable here, unlike Cloud SQL. #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id GCP_REGION=asia-south1 ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` --- ### Authentication and IAM `roles/monitoring.viewer` on the project. Nothing Memorystore-specific — see [GCP Monitoring overview](./overview.md#authentication). --- ### What you'll monitor | Metric | Kind | Unit | Use case | |---|---|---|---| | `stats/cache_hit_ratio` | Gauge | ratio | A falling ratio means the working set has outgrown the instance, or TTLs are too short. | | `stats/keyspace_misses` | Cumulative sum | count | Absolute miss volume. The ratio can hold steady while misses climb with traffic, which costs the backend either way. | | `stats/evicted_keys` | Cumulative sum | count | The instance is at `maxmemory` and discarding data. Any sustained value means it is undersized. | | `stats/memory/usage_ratio` | Gauge | ratio | Memory used against `maxmemory`. Above 0.9 and evictions become likely. | | `stats/memory/system_memory_usage_ratio` | Gauge | ratio | Whole-VM memory, including replication buffers. Can be high while `usage_ratio` looks fine. | | `stats/memory/maxmemory` | Gauge | bytes | The cap the ratio is measured against; also shows tier changes. | | `clients/connected` | Gauge | count | Client count against the tier's limit. | | `clients/blocked` | Gauge | count | Clients waiting on `BLPOP` and friends. Sustained non-zero suggests a stuck consumer. | | `stats/reject_connections_count` | Cumulative sum | count | Connections refused at the limit. Should be zero. | | `stats/cpu_utilization` | Gauge | seconds | CPU seconds per minute across the whole server process. | | `stats/cpu_utilization_main_thread` | Gauge | seconds | The one that matters. Redis executes commands on a single thread, so this saturates long before whole-process CPU looks busy. | | `stats/network_traffic` | Cumulative sum | bytes | Bandwidth, which is what large-value workloads actually hit first. | | `keyspace/keys` | Gauge | count | Total keys. A cliff here usually means a flush or a mass expiry. | | `replication/master/slaves/lag` | Gauge | seconds | Standard-tier replica staleness, and your failover data-loss window. | | `server/uptime` | Gauge | seconds | A reset to near zero is an unplanned restart. | None of these are distributions, so the scrape-batch failure mode does not apply to Memorystore. --- ### Cardinality control | Attribute | Source | Cardinality | Keep? | |---|---|---|---| | `instance_id` | Resource label | One per instance | Yes — the grouping key | | `region`, `project_id` | Resource label | Small | Yes | | `node_id` | Resource label (Cluster, Valkey) | One per shard and replica | Only if you debug per-shard skew | | `cmd` | Metric label on `commands/calls` | One per Redis command used | No, unless you are specifically profiling | | `role` | Metric label | Two (`primary`, `replica`) | Yes | The per-command metrics — `redis.googleapis.com/commands/calls` and `commands/usec_per_call` — are where this surface gets expensive. Redis has over 200 commands, and a busy application touches dozens. They are worth their cost while you profile a latency problem, and not afterwards. Add them deliberately, and drop them again. To keep node-scoped metrics but collapse the shards: ```yaml showLineNumbers title="memorystore-config.yaml" processors: transform/memorystore: error_mode: ignore metric_statements: - context: datapoint statements: - delete_key(attributes, "node_id") ``` --- ### Alert tuning | Signal | Source metric | Warning | Critical | Notes | |---|---|---|---|---| | Hit rate collapse | `stats/cache_hit_ratio` | < 0.85 for 15m | < 0.70 for 15m | Exclude the first minutes after a restart, when the cache is legitimately cold. | | Memory pressure | `stats/memory/usage_ratio` | > 0.85 for 10m | > 0.95 for 5m | Read alongside the eviction counter — the ratio alone does not say whether data is being lost. | | Eviction | `stats/evicted_keys` | any sustained | rising | On a pure cache this may be acceptable; on anything session-shaped it is data loss. | | Rejected connections | `stats/reject_connections_count` | any | sustained | The client-connection limit, not memory. | | Replica lag | `replication/master/slaves/lag` | > 10s for 5m | > 60s for 5m | Standard tier only; this is your failover data-loss window. | | Unplanned restart | `server/uptime` | drops below 300 | — | Correlate with `keyspace/keys` falling to zero. | --- ### Logs Memorystore does not write application-level logs to Cloud Logging. Instance lifecycle events — creation, scaling, failover, maintenance — appear as Cloud Audit Logs. Route them alongside your other GCP logs if you want maintenance windows visible next to the metrics: ```bash showLineNumbers gcloud logging sinks create scout-memorystore-audit \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='protoPayload.serviceName="redis.googleapis.com"' ``` The `google_cloud_logentry_encoding` extension recognizes audit entries and maps them to `gcp.audit.*` attributes plus `user.email` and `client.address`. See [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md). --- ### Alternative: the Redis receiver The OTel `redis` receiver connects to the instance and parses `INFO` output directly. It produces OTel-native metric names (`redis.memory.used`, `redis.keyspace.hits`) rather than GCP metric types, with cumulative temporality, and reaches things Cloud Monitoring never exposes — per-database key and TTL breakdowns, fragmentation ratio, fork duration, and RDB change counts. Memorystore adds two caveats: - **The collector must reach the instance.** Memorystore is private-IP only, so the collector has to run inside the VPC or a peered one. - **Coverage is not identical.** Memorystore restricts `CONFIG`, so receiver metrics derived from it — `redis.maxmemory` among them — return nothing. The `INFO` fields Google restricts vary by tier. Configuration is in [Redis component](../../component/redis.md). Set `password` to the instance's AUTH string if AUTH is enabled, enable `tls` if in-transit encryption is on, and give the pipeline its own `service.name` so the two views stay separable. :::note Managed versus self-hosted If you run Redis or Valkey yourself on Compute Engine or GKE rather than using Memorystore, this guide does not apply — those instances publish nothing to Cloud Monitoring beyond VM-level metrics. Use [Redis component](../../component/redis.md) directly. ::: --- ### Verify 1. **The collector starts cleanly** — check for `PermissionDenied` or `could not find default credentials` in its logs. 2. **The prefix is right for your product.** This is the failure that looks like everything else. Paste your prefix into Metrics Explorer with the **Active** toggle on; if nothing lists, you are on the wrong namespace for the engine you run. 3. **Confirm the series landed:** ```sql showLineNumbers SELECT MetricName, count() AS points, max(Value) AS latest FROM otel_metrics_gauge WHERE ServiceName = 'memorystore-metrics' AND MetricName = 'redis.googleapis.com/stats/memory/usage_ratio' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` The cumulative counters (`keyspace_misses`, `evicted_keys`) are in `otel_metrics_sum`. --- ### Troubleshooting **No metrics at all, and the metric names look correct.** Almost always the wrong prefix for the engine. Valkey is `memorystore.googleapis.com/instance/`, not `redis.googleapis.com/`, and Redis Cluster puts everything under `redis.googleapis.com/cluster/`. **Replication metrics return nothing.** `replication/master/slaves/lag` exists only on Standard-tier instances. Basic tier has no replica, so no series is emitted. **`cache_hit_ratio` is missing on Valkey.** Valkey does not publish it. Compute it from `total_keyspace_hits_count` and `total_keyspace_misses_count` at query time. **Series count jumped after adding one metric.** You added `commands/calls` or `commands/usec_per_call`, which carry a per-command label. See [Cardinality control](#cardinality-control). **Everything arrives under `unknown_service`.** The `resource/memorystore` processor is missing, or a blanket `resource` processor in the same pipeline is overwriting `service.name`. ### FAQ #### How do I monitor Memorystore with OpenTelemetry? Use the `googlecloudmonitoring` receiver against the metric prefix for your engine — `redis.googleapis.com/` for Memorystore for Redis, `redis.googleapis.com/cluster/` for Redis Cluster, and `memorystore.googleapis.com/instance/` for Valkey. It needs only `roles/monitoring.viewer`. #### What is the difference between the Redis and Valkey metric namespaces? They share almost no metric names. Valkey publishes under `memorystore.googleapis.com/instance/` with separate instance-scoped and node-scoped families, and omits some Redis conveniences such as `cache_hit_ratio`. Configs are not portable between the two. #### Which Memorystore metrics should I alert on? Alert on cache hit ratio, memory usage ratio, evicted keys and rejected connections, plus replica lag on Standard tier. Evictions and rejected connections matter most because both mean the instance is actively refusing work. #### Can I use the OTel redis receiver against Memorystore? The OTel `redis` receiver works against Memorystore from a collector inside the VPC, and gives you keyspace and fragmentation detail Cloud Monitoring never exposes. Metrics derived from `CONFIG` will be missing, because Memorystore restricts that command. #### Why does system memory usage look high when memory usage ratio looks fine? `stats/memory/usage_ratio` measures data against `maxmemory`, while `system_memory_usage_ratio` measures the whole VM, which also holds replication buffers and client output buffers. A large replication backlog raises the second without touching the first. #### Are evicted keys always a problem? On a pure read-through cache, some eviction is the design working. On anything holding sessions, rate-limit counters or queues, an eviction is data loss. Decide per instance rather than alerting uniformly. ### Reference - [Memorystore for Redis metrics](https://docs.cloud.google.com/memorystore/docs/redis/supported-monitoring-metrics) - [Memorystore for Valkey metrics](https://docs.cloud.google.com/memorystore/docs/valkey/supported-monitoring-metrics) - [Memorystore for Redis Cluster metrics](https://docs.cloud.google.com/memorystore/docs/cluster/supported-monitoring-metrics) ### Related Guides - [GCP Monitoring overview](./overview.md) - the one-time IAM and collector setup this guide assumes you already have. - [Redis component](../../component/redis.md) - the direct-scrape receiver, and the guide to use for self-hosted Redis or Valkey. - [Cloud SQL](./cloud-sql.md) - the database this cache usually sits in front of. --- ## GCP Monitoring with OpenTelemetry - Architecture for base14 Scout This is the architectural landing page for monitoring Google Cloud infrastructure with **base14 Scout** through the **OpenTelemetry Collector**. It covers the three paths telemetry can take out of GCP, the IAM each one needs, and the resource attributes every per-service guide sets. Read it once, then jump to the guide for the surface you are instrumenting. :::note Running this in production Storing and querying this telemetry at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### The three paths Google Cloud emits telemetry in three shapes, and a production deployment usually runs all three. ```text ┌──────────────────────── Google Cloud ─────────────────────────┐ │ │ │ Managed service (Cloud SQL, Pub/Sub, Cloud Run, LB, ...) │ │ │ │ │ │ │ metrics │ logs │ │ ▼ ▼ │ │ Cloud Monitoring Cloud Logging │ │ │ │ │ │ │ Log Router sink │ │ │ ▼ │ │ │ Pub/Sub topic │ │ │ │ │ └────────┼──────────────────────────┼───────────────────────────┘ │ Monitoring API (pull) │ subscription (push) ▼ ▼ googlecloudmonitoring googlecloudpubsub receiver receiver │ │ └──────────┬───────────────┘ │ ┌─────────────────────────────────┐ │ │ In-VPC collector │ │◀───────┤ postgresql / mysql / redis / │ │ │ nginx / prometheus receivers │ │ │ Cloud Run OTLP sidecar │ │ └─────────────────────────────────┘ ▼ OpenTelemetry Collector │ OTLP ▼ Scout ``` | Path | Component | Signals | Freshness | Main cost driver | |---|---|---|---|---| | **Cloud Monitoring pull** | `googlecloudmonitoring` receiver | Metrics | 60s floor plus GCP's own export delay (often 3-5 min) | Monitoring API read quota | | **Cloud Logging push** | `googlecloudpubsub` receiver + `google_cloud_logentry_encoding` | Logs | Seconds | Pub/Sub delivery and egress | | **Direct scrape** | `postgresql`, `mysql`, `redis`, `nginx`, `prometheus` receivers | Metrics | Your `collection_interval` | Collector compute; no GCP API cost | The first two are documented once, as mechanism guides: - [GCP Cloud Monitoring](./gcp-cloud-monitoring-to-scout.md) — the pull path, IAM, and the metric-kind rules. - [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) — the Log Router sink, Pub/Sub topic and subscription, and log encoding. The per-service guides below assume you have read whichever of those two applies, and cover only what is specific to their surface. ### What about traces? **No GCP managed service emits distributed traces.** Cloud SQL, Pub/Sub, Cloud Load Balancing, API Gateway and VPC produce metrics and logs only. Traces in a GCP architecture come from two places: - **Your application code**, instrumented with an OpenTelemetry SDK. On Cloud Run, a collector sidecar is the cleanest way to get them out — see [Cloud Run](./cloud-run.md). - **Google Cloud client libraries**, which emit client spans for calls into managed services. Be aware that the Pub/Sub client libraries emit `rpc.*` attributes only and no `messaging.*` attributes at all; see [Pub/Sub](./pub-sub.md) for what that means downstream. ### Which collector image to run Run **`otel/opentelemetry-collector-contrib`**. None of the GCP components — `googlecloudmonitoring`, `googlecloudpubsub`, the `google_cloud_logentry_encoding` extension — ship in the core collector distribution, and none of them are in the Scout collector distribution either. The same is true of the `postgresql`, `mysql`, `redis` and `nginx` receivers the alternative paths use. If you already run a Scout collector for application telemetry, add a **second collector** for the GCP receivers rather than swapping the image on the first one. That also gives you the separate pipeline the next section requires. :::warning Run the pull receiver on a single replica `googlecloudmonitoring` polls on an interval. Every replica polls independently, so a three-replica Deployment triples your Monitoring API usage and produces duplicate series. Put it on a single-replica Deployment, never a DaemonSet. ::: ### Resource attributes every GCP pipeline sets The `googlecloudmonitoring` receiver sets `gcp.resource_type` and the monitored-resource labels as resource attributes — and **no `service.name`**. Without one, every GCP metric arrives as `unknown_service`, which in the Scout data lake means it shares a sort-key prefix with everything else that went unnamed. Set one per surface, following the convention already used for infra telemetry across the fleet (`system-metrics`, `kubernetes-metrics`): | Surface | `service.name` | `cloud.platform` | |---|---|---| | Cloud SQL | `cloudsql-metrics` | `gcp_cloud_sql` | | Memorystore | `memorystore-metrics` | `gcp_memorystore` | | Cloud Load Balancing | `loadbalancing-metrics` | `gcp_load_balancing` | | API Gateway (managed) | `apigateway-metrics` | `gcp_api_gateway` | | nginx gateway (self-managed) | `nginx-gateway-metrics` | `gcp_kubernetes_engine` | | Pub/Sub | `pubsub-metrics` | `gcp_pubsub` | | Cloud Run | `cloudrun-metrics` | `gcp_cloud_run` | | VPC | `vpc-logs` (flow logs), `vpc-metrics` (Cloud NAT) | `gcp_vpc` | The block each guide repeats, with its own values substituted: ```yaml showLineNumbers title="gcp-common.yaml" processors: resource/cloudsql: attributes: - {key: service.name, value: cloudsql-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_cloud_sql, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} # Regional surfaces only — omit for Pub/Sub, Cloud Load Balancing and VPC - {key: cloud.region, value: "${env:GCP_REGION}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} ``` `cloud.region` belongs only on surfaces that have one. Cloud SQL and Memorystore instances live in a region; Pub/Sub topics, global load balancers and VPC networks do not, and stamping a region on them invents a dimension that is not real. :::warning Give each surface its own pipeline The `insert` action on `service.name` and the `/cloudsql` suffix on the processor are both load-bearing. A blanket `resource` processor that `upsert`s a single `service.name` across a shared pipeline will stamp your application's name onto every GCP metric, and they become indistinguishable from application telemetry. Keep one `receiver/processor/pipeline` triple per surface, all suffix-keyed, so they coexist in one collector without overwriting each other. ::: ### Metric kinds and temporality Each GCP metric has a **kind** (`GAUGE`, `DELTA`, `CUMULATIVE`) and a **value type** (`INT64`, `DOUBLE`, `DISTRIBUTION`). The receiver maps them like this: | GCP kind and type | OTel result | Temporality | |---|---|---| | `GAUGE` + scalar | Gauge | — | | `CUMULATIVE` + scalar | Monotonic sum | Cumulative | | `DELTA` + scalar | Sum | **Delta** | | `DELTA` + `DISTRIBUTION` | Histogram | **Delta** | | `GAUGE` + `DISTRIBUTION` | **Unsupported** | — | Two consequences: **Most GCP counters are `DELTA`.** `request_count`, `ack_message_count`, `disk/read_ops_count` and their siblings all arrive as delta sums, not cumulative ones. A panel or rollup that assumes a monotonically increasing counter — one that applies `rate()`-style logic, or subtracts consecutive points — will be wrong against them. Sum delta points over the window instead. **A `GAUGE`-kind `DISTRIBUTION` can drop everything.** It yields an invalid data point that fails the *entire scrape batch*, so every metric from that receiver instance disappears, not just the offending one. If metrics vanish after a config change, remove the distribution-valued metric you just added. Latency metrics (`*_latencies`, `*_times`) are the usual culprits. Each per-service guide flags its distributions. ### Authentication Both GCP receivers use **Application Default Credentials**. Create one Google service account (GSA) and grant it what the paths you use need: | Path | Role | Scope | |---|---|---| | Cloud Monitoring pull | `roles/monitoring.viewer` | Project | | Cloud Logging push | `roles/pubsub.subscriber` | The subscription | ```bash showLineNumbers gcloud iam service-accounts create scout-telemetry-reader \ --display-name="base14 Scout telemetry reader" gcloud projects add-iam-policy-binding PROJECT_ID \ --member="serviceAccount:scout-telemetry-reader@PROJECT_ID.iam.gserviceaccount.com" \ --role="roles/monitoring.viewer" ``` :::tip GKE Workload Identity On GKE, bind the GSA to the collector's Kubernetes service account and skip key files entirely: ```bash showLineNumbers gcloud iam service-accounts add-iam-policy-binding \ scout-telemetry-reader@PROJECT_ID.iam.gserviceaccount.com \ --role="roles/iam.workloadIdentityUser" \ --member="serviceAccount:PROJECT_ID.svc.id.goog[NAMESPACE/KSA_NAME]" ``` Then annotate the KSA: ```yaml showLineNumbers metadata: annotations: iam.gke.io/gcp-service-account: scout-telemetry-reader@PROJECT_ID.iam.gserviceaccount.com ``` ::: Elsewhere, point `GOOGLE_APPLICATION_CREDENTIALS` at a service account key file. Both mechanism guides cover this in full. ### One project per receiver `project_id` is singular. To collect from several projects, add one receiver instance per project, each suffix-keyed: ```yaml showLineNumbers title="multi-project.yaml" receivers: googlecloudmonitoring/prod: project_id: my-prod-project metrics_list: - metric_descriptor_filter: 'metric.type = starts_with("cloudsql.googleapis.com/")' googlecloudmonitoring/staging: project_id: my-staging-project metrics_list: - metric_descriptor_filter: 'metric.type = starts_with("cloudsql.googleapis.com/")' ``` Grant the GSA `roles/monitoring.viewer` in each project. ### Verifying data has landed GCP telemetry lands in the base `otel_metrics_*` and `otel_logs` tables, with the GCP labels in the `ResourceAttributes` and `Attributes` maps. The metric name is the **raw GCP metric type**, not a translated one — so `MetricName` is literally `cloudsql.googleapis.com/database/cpu/utilization`. Every verification query in these guides filters on `ServiceName`, `MetricName` and a bounded one-hour window, and caps itself: ```sql showLineNumbers SELECT MetricName, count() AS points, max(Value) AS latest FROM otel_metrics_gauge WHERE ServiceName = 'cloudsql-metrics' AND MetricName = 'cloudsql.googleapis.com/database/cpu/utilization' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` Delta counters land in `otel_metrics_sum` and distributions in `otel_metrics_histogram` — if a metric is missing from one table, look for it in the other before concluding it failed. ### Per-surface guides | Guide | Lead path | Covers | |---|---|---| | [Cloud SQL](./cloud-sql.md) | Cloud Monitoring | Host and engine metrics, database logs, in-database scraping | | [Memorystore](./memorystore.md) | Cloud Monitoring | Redis, Redis Cluster and Valkey engines | | [Cloud Load Balancing](./load-balancing.md) | Cloud Monitoring + Logging | Request rates, latency distributions, access logs | | [API Gateway and nginx](./api-gateway.md) | Cloud Monitoring / Prometheus | Managed API Gateway and self-managed nginx gateways | | [Pub/Sub](./pub-sub.md) | Cloud Monitoring | Topic and subscription health, backlog alerting | | [Cloud Run](./cloud-run.md) | OTLP sidecar | Application traces, platform metrics, request logs | | [VPC](./vpc.md) | Cloud Logging | Flow logs, Cloud NAT, network metrics | ### FAQ #### How does base14 Scout collect Google Cloud telemetry? base14 Scout collects Google Cloud telemetry through the OpenTelemetry Collector, along three paths. The `googlecloudmonitoring` receiver pulls metrics from the Cloud Monitoring API, the `googlecloudpubsub` receiver consumes logs that a Log Router sink pushes into Pub/Sub, and standard receivers such as `postgresql` and `redis` scrape services directly from inside the VPC. #### Which collector distribution do I need for GCP? GCP telemetry needs the `otel/opentelemetry-collector-contrib` distribution. The GCP receivers and the Cloud Logging encoding extension are contrib components, present in neither the core collector nor the Scout collector distribution. #### Do GCP managed services emit distributed traces? No GCP managed service emits distributed traces. Cloud SQL, Pub/Sub, Cloud Load Balancing, API Gateway and VPC emit metrics and logs only. Traces come from your own application code, or from Google Cloud client libraries emitting client spans. #### Why do my GCP metrics show up as unknown_service? The `googlecloudmonitoring` receiver does not set `service.name`. Add a `resource` processor that inserts one per surface — `cloudsql-metrics`, `pubsub-metrics`, and so on. Because `ServiceName` is the leading sort key in the Scout data lake, leaving it unset makes queries far more expensive. #### Why does my GCP counter graph look wrong? Most GCP counters have `DELTA` kind and arrive as delta sums, not cumulative ones. Sum the points over your window rather than applying counter-rate logic that assumes a monotonically increasing series. #### Can one collector serve several GCP projects? One collector can serve several projects, but `project_id` is singular per receiver — add one receiver instance per project, and grant the service account `roles/monitoring.viewer` in each. ### Reference - [Google Cloud metrics list](https://docs.cloud.google.com/monitoring/api/metrics_gcp) - [googlecloudmonitoring receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/googlecloudmonitoringreceiver) - [googlecloudpubsub receiver](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/receiver/googlecloudpubsubreceiver) - [Cloud Logging LogEntry encoding extension](https://github.com/open-telemetry/opentelemetry-collector-contrib/tree/main/extension/encoding/googlecloudlogentryencodingextension) - [OTel cloud resource semantic conventions](https://opentelemetry.io/docs/specs/semconv/resource/cloud/) ### Related Guides - [GCP Cloud Monitoring](./gcp-cloud-monitoring-to-scout.md) - the pull path in full, including IAM and metric selection. - [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) - the Log Router sink and Pub/Sub subscription setup every log guide reuses. - [Collector setup](../../collector-setup/otel-collector-config.md) - deployment options for the collector itself. --- ## Google Cloud Pub/Sub Monitoring with OpenTelemetry - Backlog and Delivery A stalled Pub/Sub consumer raises no error. The backlog grows, messages age, and the first hard failure is a message dropped at the retention limit hours later. This guide collects Pub/Sub's topic and subscription metrics into Scout, and covers what its client-library spans do and do not carry. Read [GCP Monitoring overview](./overview.md) first — it covers the collector image, IAM, and resource attributes this guide assumes. :::note Pub/Sub appears twice in these guides This page monitors Pub/Sub **as a service you run**. The [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) guide uses Pub/Sub as the **transport** carrying GCP logs into your collector. They are unrelated setups, and you can run either without the other. ::: :::note Running this in production Storing and querying these metrics at production volume is what base14 Scout does. [Check out Scout Metrics](https://base14.io/scout/metrics). ::: ### Overview Pub/Sub metrics split across two monitored resources, and the split matters because they answer different questions: | Resource | Prefix | Answers | |---|---|---| | `pubsub_topic` | `pubsub.googleapis.com/topic/` | Are publishers succeeding, and what are they sending? | | `pubsub_subscription` | `pubsub.googleapis.com/subscription/` | Are consumers keeping up, and is anything being lost? | Almost all operational value is on the subscription side. A topic is healthy or it is not; a subscription can be failing in half a dozen distinguishable ways. ### Pub/Sub at a glance | Concern | Metric | Shape | |---|---|---| | Backlog size | `subscription/num_undelivered_messages` | Gauge | | Backlog age | `subscription/oldest_unacked_message_age` | Gauge, seconds | | Consumer throughput | `subscription/ack_message_count` | Delta sum | | Delivery attempts | `subscription/sent_message_count` | Delta sum | | Redelivery pressure | `subscription/expired_ack_deadlines_count` | Delta sum | | Permanent failure | `subscription/dead_letter_message_count` | Delta sum | | Publish health | `topic/send_request_count` | Delta sum | --- ### Receiver configuration ```yaml showLineNumbers title="pubsub-config.yaml" receivers: # ...your existing receivers... googlecloudmonitoring/pubsub: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: # Subscription health — the operational core - metric_name: "pubsub.googleapis.com/subscription/num_undelivered_messages" - metric_name: "pubsub.googleapis.com/subscription/oldest_unacked_message_age" - metric_name: "pubsub.googleapis.com/subscription/backlog_bytes" - metric_name: "pubsub.googleapis.com/subscription/ack_message_count" - metric_name: "pubsub.googleapis.com/subscription/sent_message_count" - metric_name: "pubsub.googleapis.com/subscription/expired_ack_deadlines_count" - metric_name: "pubsub.googleapis.com/subscription/dead_letter_message_count" - metric_name: "pubsub.googleapis.com/subscription/pull_request_count" - metric_name: "pubsub.googleapis.com/subscription/push_request_count" # Topic health - metric_name: "pubsub.googleapis.com/topic/send_request_count" - metric_name: "pubsub.googleapis.com/topic/byte_cost" processors: resource/pubsub: attributes: - {key: service.name, value: pubsub-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_pubsub, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} memory_limiter: limit_mib: 512 spike_limit_mib: 128 check_interval: 5s batch: timeout: 10s send_batch_size: 1024 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: pipelines: # ...your existing pipelines... metrics/pubsub: receivers: [googlecloudmonitoring/pubsub] processors: [memory_limiter, resource/pubsub, batch] exporters: [otlphttp/base14] ``` :::warning topic/message_sizes is a distribution `pubsub.googleapis.com/topic/message_sizes` is `DELTA` + `DISTRIBUTION`, supported from collector v0.129.0. It is deliberately omitted from the list above because message size is rarely the thing you are debugging, and a distribution failure drops every metric from the receiver. Add it only if you need it, and only on v0.129.0 or later. ::: #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` #### Collecting the whole service ```yaml showLineNumbers title="pubsub-config.yaml" metrics_list: - metric_descriptor_filter: 'metric.type = starts_with("pubsub.googleapis.com/")' ``` This pulls in the distribution metrics too, so confirm your collector version first. --- ### Authentication and IAM `roles/monitoring.viewer` on the project. Note that this is a **different grant** from the `roles/pubsub.subscriber` needed when Pub/Sub carries your logs — monitoring Pub/Sub never reads a message. See [GCP Monitoring overview](./overview.md#authentication). --- ### What you'll monitor | Metric | Kind | Unit | Use case | |---|---|---|---| | `subscription/num_undelivered_messages` | Gauge | count | Backlog depth. A rising line means consumers are slower than publishers. | | `subscription/oldest_unacked_message_age` | Gauge | seconds | **The single most important Pub/Sub metric.** Backlog depth can look stable while the oldest message ages toward its retention limit. | | `subscription/backlog_bytes` | Gauge | bytes | Backlog in bytes, for storage cost and large-payload workloads. | | `subscription/ack_message_count` | **Delta** sum | count | Consumer throughput, labelled by `delivery_type`. | | `subscription/sent_message_count` | **Delta** sum | count | Delivery attempts. Divide `ack_message_count` by this for the success ratio. | | `subscription/expired_ack_deadlines_count` | **Delta** sum | count | Messages redelivered because the consumer did not ack in time. Sustained non-zero means the deadline is too short or the handler too slow. | | `subscription/dead_letter_message_count` | **Delta** sum | count | Messages that exhausted their retry policy. Every one is a message your system failed to process. | | `subscription/pull_request_count` | **Delta** sum | count | Labelled by `response_code`; where pull-side errors show up. | | `subscription/push_request_count` | **Delta** sum | count | Labelled by `response_code` and `delivery_type`; push endpoint health. | | `topic/send_request_count` | **Delta** sum | count | Publish rate and publish errors, by `response_code`. | | `topic/byte_cost` | **Delta** sum | bytes | Billable volume, by `operation_type`. | The two gauges are the alerting metrics. Everything else is context for explaining them. :::tip Depth and age tell different stories A backlog of 10,000 messages with an oldest-age of 5 seconds is a busy, healthy system. A backlog of 50 messages with an oldest-age of 40 minutes is a stuck consumer holding a poison message. Depth alone cannot tell these apart, which is why `oldest_unacked_message_age` is the one to page on. ::: --- ### Cardinality control Pub/Sub is well behaved here. The resource labels are bounded by how many topics and subscriptions you have. | Attribute | Source | Cardinality | Keep? | |---|---|---|---| | `subscription_id` | Resource label | One per subscription | Yes — the grouping key | | `topic_id` | Resource label | One per topic | Yes | | `response_code` | Metric label | Tens | Yes | | `delivery_type` | Metric label | A few | Yes | | `operation_type` | Metric label | A few | Yes | The risk is growth rather than width: a system that creates subscriptions programmatically — one per tenant, per worker, per deployment — grows its series count without any label changing. If you do that, filter to the subscriptions you actually operate: ```yaml showLineNumbers title="pubsub-config.yaml" processors: filter/pubsub: error_mode: ignore metrics: datapoint: - 'not IsMatch(resource.attributes["subscription_id"], "^(orders|payments|notifications)-")' ``` --- ### Alert tuning | Signal | Source metric | Warning | Critical | Notes | |---|---|---|---|---| | Backlog age | `subscription/oldest_unacked_message_age` | > 300s for 5m | > 25% of the retention window | Scale the threshold to what the subscription does, not to a fleet-wide number. | | Backlog growth | `subscription/num_undelivered_messages` | rising for 15m | rising for 1h | Alert on the trend, not an absolute — normal depth varies enormously between subscriptions. | | Dead lettering | `subscription/dead_letter_message_count` | any | sustained | Each one is a permanently failed message. Alert on presence. | | Ack deadline expiry | `subscription/expired_ack_deadlines_count` | > 1% of `sent_message_count` | > 10% | Usually the deadline is shorter than the handler's real runtime. | | Delivery failures | `subscription/push_request_count` where `response_code` is not 2xx | > 1% for 5m | > 5% | Push subscriptions only. | | Publish failures | `topic/send_request_count` where `response_code` is not 2xx | > 0.1% for 5m | > 1% | Publisher-side problems, usually IAM or quota. | | Consumer stopped | `subscription/ack_message_count` | zero for 10m | zero for 30m | Only meaningful on subscriptions with steady traffic. | Set the backlog-age critical threshold from the subscription's message retention (7 days by default). Past that point messages are dropped permanently, so paging at a quarter of the window leaves room to react. --- ### Tracing Pub/Sub The Google Cloud Pub/Sub client libraries emit spans for publish and subscribe operations, which flow to Scout through your application's normal OTLP pipeline. There is a significant caveat. :::warning Pub/Sub spans carry no messaging.* attributes Unlike Kafka or RabbitMQ instrumentation, the GCP Pub/Sub client libraries emit **`rpc.system`, `rpc.service` and `rpc.method` only** — no `messaging.system`, `messaging.destination.name` or `messaging.operation`. The spans also arrive as `SpanKind = Client` rather than `Producer` or `Consumer`. If you build any messaging view, dashboard or aggregation that keys on `messaging.*`, Pub/Sub traffic will be invisible to it. Resolve the system from `rpc.service` instead, and treat `Client` spans with an `rpc.service` of `google.pubsub.v1.Publisher` or `Subscriber` as your producer and consumer spans. ::: Trace context does not propagate through a Pub/Sub message by default. To link publisher and consumer traces, inject the W3C `traceparent` into a message attribute at publish time and extract it at consume time. The attribute survives the broker; the span context does not travel on its own. --- ### Logs Pub/Sub emits no data-plane logs — individual publishes and deliveries are not logged. Administrative operations (topic and subscription creation, IAM changes, schema updates) appear as Cloud Audit Logs: ```bash showLineNumbers gcloud logging sinks create scout-pubsub-audit \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='protoPayload.serviceName="pubsub.googleapis.com"' ``` Useful for correlating a metric change with a configuration change — an ack deadline edit, a retry policy change — but not for debugging message flow. For that, the metrics above and your consumer's own logs are what you have. --- ### Verify 1. **The collector starts cleanly** — check for `PermissionDenied` in its logs. 2. **Confirm the gauges landed:** ```sql showLineNumbers SELECT MetricName, count() AS points, max(Value) AS latest FROM otel_metrics_gauge WHERE ServiceName = 'pubsub-metrics' AND MetricName = 'pubsub.googleapis.com/subscription/oldest_unacked_message_age' AND TimeUnix >= now() - INTERVAL 1 HOUR GROUP BY MetricName SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` The counters (`ack_message_count` and the rest) are in `otel_metrics_sum` with delta temporality. 3. **Sanity-check against reality.** Publish a message to a topic with a subscription nobody is consuming, and confirm `num_undelivered_messages` rises within two collection intervals. --- ### Troubleshooting **`oldest_unacked_message_age` is missing for some subscriptions.** The metric is only emitted while a backlog exists, so an empty subscription reports nothing. That silence is the healthy state. **Backlog depth is flat but consumers are clearly behind.** Check `oldest_unacked_message_age` instead. **`expired_ack_deadlines_count` is high but nothing is failing.** Messages are being redelivered and eventually acked, so no data is lost, but you are doing the work more than once. Raise the ack deadline or extend it from the handler. **Dead letter count is rising with no corresponding errors in the app.** The consumer is nacking or timing out rather than throwing. Check the subscription's retry policy and maximum delivery attempts. **Pub/Sub spans do not appear in messaging views.** They carry `rpc.*` attributes only, not `messaging.*`. See [Tracing Pub/Sub](#tracing-pubsub). **Metrics stopped for a subscription that still exists.** Confirm the subscription id has not changed. Recreating a subscription with the same name produces a new resource as far as Cloud Monitoring is concerned only if the id changed; if the id is stable, check the receiver is still listing that project. ### FAQ #### How do I monitor Pub/Sub with OpenTelemetry? Use the `googlecloudmonitoring` receiver against the `pubsub.googleapis.com/` prefix, with `roles/monitoring.viewer`. Focus the metric list on the subscription family, where the operational signals are. #### What is the difference between undelivered messages and backlog age? Depth counts messages waiting; age measures how long the oldest one has waited. A large, fast-moving backlog is healthy; a small, old backlog is a stuck consumer, and depth alone cannot tell them apart. Alert on `subscription/oldest_unacked_message_age`, at a fraction of your retention window. #### Why do Pub/Sub traces not show messaging attributes? The Google Cloud Pub/Sub client libraries emit `rpc.system`, `rpc.service` and `rpc.method` rather than the `messaging.*` semantic conventions, and their spans are `Client` kind rather than `Producer` or `Consumer`. Resolve the system from `rpc.service` when building any messaging view. #### How do I propagate trace context through Pub/Sub? Inject the W3C `traceparent` header into a message attribute when publishing and extract it when consuming. Trace context does not travel through the broker on its own. #### Is monitoring Pub/Sub the same as sending GCP logs through Pub/Sub? No — the two are independent setups. This guide reads Pub/Sub's own metrics from the Monitoring API and needs `roles/monitoring.viewer`. Sending logs through Pub/Sub uses the `googlecloudpubsub` receiver to consume messages and needs `roles/pubsub.subscriber`. They are independent. ### Reference - [Pub/Sub metrics](https://docs.cloud.google.com/monitoring/api/metrics_gcp#gcp-pubsub) - [Pub/Sub monitoring guide](https://docs.cloud.google.com/pubsub/docs/monitoring) - [Handling message failures](https://docs.cloud.google.com/pubsub/docs/handling-failures) ### Related Guides - [GCP Monitoring overview](./overview.md) - how delta counters like `ack_message_count` land in the data lake. - [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) - Pub/Sub in its other role, as the transport for GCP logs. - [Cloud Run](./cloud-run.md) - a common Pub/Sub consumer, and where push subscriptions usually terminate. --- ## Google Cloud VPC Monitoring with OpenTelemetry - Flow Logs and Cloud NAT VPC telemetry is mostly logs. Flow logs are the record of which workloads talked to which, and they answer questions no metric can. They are also high-volume and high-cardinality, so how you sample and filter them matters more than how you collect them. Read [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) first — this guide builds directly on the sink and subscription it sets up. :::note Running this in production Storing and querying these logs at production volume is what base14 Scout does. [Check out Scout Logs](https://base14.io/scout/logs). ::: ### Overview "VPC monitoring" covers three separate sources: | Source | Signal | Where it comes from | |---|---|---| | **VPC Flow Logs** | Logs | Cloud Logging, `resource.type="gce_subnetwork"` | | **Cloud NAT** | Metrics | Cloud Monitoring, `router.googleapis.com/nat/` | | **Instance network** | Metrics | Cloud Monitoring, `compute.googleapis.com/instance/network/` | Flow logs answer most of the questions. The metrics exist to catch two network failures that are silent from inside a VM: NAT port exhaustion and dropped packets. :::warning Flow logs are expensive by default At full sampling, a busy VPC produces more log volume than every other source in these guides combined. Enable them per subnet rather than per network, sample below 1.0, and filter in the collector. The [Volume control](#volume-control) section is not optional reading. ::: --- ### Enabling flow logs Flow logs are configured per subnet and are off by default: ```bash showLineNumbers gcloud compute networks subnets update SUBNET_NAME \ --region=REGION \ --enable-flow-logs \ --logging-aggregation-interval=interval-5-sec \ --logging-flow-sampling=0.5 \ --logging-metadata=include-all ``` Those three logging flags are the whole cost model: | Flag | Effect | Recommendation | |---|---|---| | `--logging-aggregation-interval` | How long flows are aggregated before a log entry is written. Longer means fewer, coarser entries. | `interval-5-sec` for debugging, `interval-30-sec` or higher for steady state | | `--logging-flow-sampling` | Fraction of flows logged, 0.0 to 1.0 | Start at `0.5`; drop to `0.1` on high-traffic subnets | | `--logging-metadata` | Whether instance, geo and AS details are included | `include-all` while investigating, `exclude-all` otherwise | Sampling applies to flows, not packets, so a sampled flow log still reports that flow's complete byte and packet counts. Halving the sample rate halves your log volume without halving the accuracy of any individual flow you do see. --- ### Receiver configuration Flow logs travel the standard Cloud Logging path. If you already run that pipeline, add the subnet filter to your existing sink rather than building a second one. ```bash showLineNumbers gcloud logging sinks create scout-vpc-flow-logs \ pubsub.googleapis.com/projects/PROJECT_ID/topics/scout-logs \ --log-filter='resource.type="gce_subnetwork" AND logName:"compute.googleapis.com%2Fvpc_flows"' ``` ```yaml showLineNumbers title="vpc-config.yaml" extensions: # ...your existing extensions... google_cloud_logentry_encoding: handle_json_payload_as: "json" handle_proto_payload_as: "json" receivers: # ...your existing receivers... googlecloudpubsub/vpc: project: ${env:GCP_PROJECT_ID} subscription: projects/${env:GCP_PROJECT_ID}/subscriptions/scout-vpc-flow-sub encoding: google_cloud_logentry_encoding processors: resource/vpc: attributes: - {key: service.name, value: vpc-logs, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_vpc, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} filter/vpc: error_mode: ignore logs: log_record: # Drop health check chatter from the GCP probe ranges - 'attributes["source.address"] != nil and (IsMatch(attributes["source.address"], "^35\\.191\\.") or IsMatch(attributes["source.address"], "^130\\.211\\."))' memory_limiter: limit_mib: 1024 spike_limit_mib: 256 check_interval: 5s batch: timeout: 10s send_batch_size: 2048 exporters: otlphttp/base14: endpoint: ${env:OTEL_EXPORTER_OTLP_ENDPOINT} service: extensions: [google_cloud_logentry_encoding] pipelines: # ...your existing pipelines... logs/vpc: receivers: [googlecloudpubsub/vpc] processors: [memory_limiter, resource/vpc, filter/vpc, batch] exporters: [otlphttp/base14] ``` Note the larger `memory_limiter` and `send_batch_size` than the other guides use. Flow logs arrive in bursts, and Pub/Sub will happily deliver faster than a conservatively sized collector can export. #### Environment variables ```bash showLineNumbers title=".env" GCP_PROJECT_ID=your-gcp-project-id ENVIRONMENT=production OTEL_EXPORTER_OTLP_ENDPOINT=https://.base14.io # Not needed if using GKE Workload Identity GOOGLE_APPLICATION_CREDENTIALS=/path/to/scout-telemetry-reader-key.json ``` --- ### Why the encoding extension matters here This is the strongest case anywhere in the GCP guides for `google_cloud_logentry_encoding` over the raw log body. The extension recognizes flow log entries as `gcp.vpcflow` format and maps them onto network semantic conventions, so they are queryable as structured attributes rather than as a JSON blob you have to parse at read time: | Flow log field | OTel attribute | |---|---| | `connection.src_ip` | `source.address` | | `connection.dest_ip` | `destination.address` | | `connection.src_port` | `source.port` | | `connection.dest_port` | `destination.port` | | `connection.protocol` | `network.transport` | | `bytes_sent` | `gcp.vpc.flow.bytes_sent` | | `packets_sent` | `gcp.vpc.flow.packets_sent` | | `rtt_msec` | `gcp.vpc.flow.network.rtt_ms` | | `reporter` | `gcp.vpc.flow.reporter` | | `src_instance.vm_name` | `gcp.vpc.flow.source.instance.vm.name` | | `dest_instance.vm_name` | `gcp.vpc.flow.destination.instance.vm.name` | | `src_vpc.subnetwork_name` | `gcp.vpc.flow.source.subnet.name` | | `src_location.country` | `gcp.vpc.flow.source.geo.country.iso_code.alpha3` | | `src_location.asn` | `gcp.vpc.flow.source.asn` | `gcp.vpc.flow.reporter` says whether the source or destination VM recorded the flow. Both ends log the same connection when both are in instrumented subnets, so a naive byte total double-counts internal traffic. Filter on one reporter value when summing. The instance and geo attributes only exist if you set `--logging-metadata=include-all`. --- ### Volume control Three levers, in the order to reach for them: 1. **Sample at the subnet.** `--logging-flow-sampling=0.1` cuts volume by 90% before anything is written, which makes it the cheapest of the three by a wide margin. 2. **Enable only the subnets you care about.** Flow logs are per-subnet. A subnet running batch jobs that talk only to Cloud Storage rarely earns its log volume. 3. **Filter in the collector.** Health check probes from Google's ranges (`35.191.0.0/16` and `130.211.0.0/22`) are noise in most deployments, and the `filter/vpc` processor above drops them. Add your own patterns for anything else high-volume and uninteresting. You can also narrow at the sink, which stops the data before it reaches Pub/Sub and so avoids the delivery cost entirely: ```bash showLineNumbers --log-filter='resource.type="gce_subnetwork" AND logName:"compute.googleapis.com%2Fvpc_flows" AND jsonPayload.connection.dest_port!=443' ``` :::warning Never key an aggregation on an IP address Source and destination addresses are unbounded — every internet client that reaches your VPC contributes a value. They are exactly what you want to search and filter on, and exactly what you must not group by in a rollup or dashboard. Aggregate on subnet, VM name, port or protocol instead, and keep IPs for the drill-down. ::: --- ### Network metrics A dropped or rejected connection produces no flow at all, so two metric families exist to catch what the logs cannot show you. Add these to the same collector as the flow log pipeline — the block below shows only the new keys, to merge into the config above rather than replace it. ```yaml showLineNumbers title="vpc-config.yaml (additions)" receivers: googlecloudmonitoring/vpc: collection_interval: 60s project_id: ${env:GCP_PROJECT_ID} metrics_list: # Cloud NAT — port exhaustion is silent from inside the VM - metric_name: "router.googleapis.com/nat/allocated_ports" - metric_name: "router.googleapis.com/nat/port_usage" - metric_name: "router.googleapis.com/nat/dropped_sent_packets_count" - metric_name: "router.googleapis.com/nat/sent_bytes_count" - metric_name: "router.googleapis.com/nat/received_bytes_count" - metric_name: "router.googleapis.com/nat/open_connections" # Instance network - metric_name: "compute.googleapis.com/instance/network/sent_bytes_count" - metric_name: "compute.googleapis.com/instance/network/received_bytes_count" processors: # Separate from resource/vpc — these are metrics, not flow logs resource/vpc_metrics: attributes: - {key: service.name, value: vpc-metrics, action: insert} - {key: cloud.provider, value: gcp, action: insert} - {key: cloud.platform, value: gcp_vpc, action: insert} - {key: cloud.account.id, value: "${env:GCP_PROJECT_ID}", action: insert} - {key: deployment.environment.name, value: "${env:ENVIRONMENT}", action: upsert} - {key: environment, value: "${env:ENVIRONMENT}", action: upsert} service: pipelines: metrics/vpc: receivers: [googlecloudmonitoring/vpc] processors: [memory_limiter, resource/vpc_metrics, batch] exporters: [otlphttp/base14] ``` The metrics pipeline uses `vpc-metrics` rather than the `vpc-logs` name the flow log pipeline sets. Keeping the two apart means a query for network metrics never scans flow log volume, which on this surface is a large difference. `nat/dropped_sent_packets_count` deserves particular attention. When a Cloud NAT gateway runs out of ports, outbound connections fail from inside the VM with a generic timeout, and nothing in the application logs explains it. This metric is the only direct evidence. :::note Instance network metrics scale with your fleet `compute.googleapis.com/instance/network/*` produces one series per instance. On a large autoscaled fleet that is a lot of series with high churn. Collect them only if you need per-instance network attribution; otherwise the NAT and flow log data usually suffices. ::: --- ### Alert tuning | Signal | Source | Warning | Critical | Notes | |---|---|---|---|---| | NAT port exhaustion | `nat/dropped_sent_packets_count` | any | sustained | Every dropped packet is a failed outbound connection. | | NAT port pressure | `nat/port_usage` vs `nat/allocated_ports` | > 0.7 | > 0.9 | The leading indicator for the row above. | | Unexpected egress | `gcp.vpc.flow.bytes_sent` to external destinations | 2x baseline | 5x baseline | Cost and exfiltration both show up here. Filter to one `reporter` value. | | New external destination | Flow logs by `destination.address` | — | — | Better as a scheduled review than a page. | | Cross-region traffic | Flow logs by subnet pair | rising | — | Cross-region egress is billable and often accidental. | --- ### Verify 1. **The subscription is receiving.** Check the Pub/Sub subscription's unacked message count in the console. If it is zero and growing nowhere, the sink filter matches nothing. 2. **Entries were decoded, not passed through raw.** Look for `source.address` as an attribute. If the body is unparsed JSON, the encoding extension is missing from `service.extensions` or from the receiver's `encoding` field. 3. **Confirm logs landed:** ```sql showLineNumbers SELECT count() AS entries FROM otel_logs WHERE ServiceName = 'vpc-logs' AND TimestampTime >= now() - INTERVAL 1 HOUR SETTINGS max_execution_time = 30, max_rows_to_read = 50000000 ``` 4. **Check your volume before leaving it running.** Compare the entry count above against what you expected. This is the one source where a misconfiguration gets expensive within hours rather than weeks. --- ### Troubleshooting **No flow logs at all, but the sink exists.** Flow logs are enabled per subnet, not per network. Confirm with `gcloud compute networks subnets describe SUBNET --region=REGION` and look for `enableFlowLogs: true`. **Log bodies are raw JSON with no network attributes.** The `google_cloud_logentry_encoding` extension is not wired in. It must appear in both the receiver's `encoding` field and the `service.extensions` list. **Instance names and geo fields are missing.** `--logging-metadata` is set to `exclude-all` or to a metadata subset that excludes them. **Byte totals are roughly double what the billing console shows.** Both ends of an internal flow log it — filter on a single `gcp.vpc.flow.reporter` value when aggregating. **The collector falls behind and Pub/Sub backlog grows.** Flow logs burst. Raise `memory_limiter` and `send_batch_size`, and reduce volume at the source with sampling before scaling the collector. **Outbound connections fail intermittently but flow logs show nothing.** A connection that never established produces no flow. Check `router.googleapis.com/nat/dropped_sent_packets_count` for NAT port exhaustion. ### FAQ #### How do I send GCP VPC Flow Logs to OpenTelemetry? Enable flow logs on the subnet, route `resource.type="gce_subnetwork"` through a Log Router sink into a Pub/Sub topic, and consume it with the `googlecloudpubsub` receiver using the `google_cloud_logentry_encoding` extension. #### Why should I use the encoding extension for flow logs? The `google_cloud_logentry_encoding` extension recognizes the `gcp.vpcflow` format and maps fields onto network semantic conventions — `source.address`, `destination.port`, `network.transport` — so entries are queryable as structured attributes instead of a JSON blob parsed at read time. #### How do I reduce VPC Flow Log volume? Sample at the subnet with `--logging-flow-sampling`, enable flow logs only on subnets you care about, and filter health check probe ranges in the collector. Sampling is by far the most effective of the three because it acts before anything is written. #### Are VPC Flow Log byte counts double-counted? Between two instrumented subnets, yes — both the source and the destination VM log the same flow, so a naive sum reports roughly twice the real volume. Filter on a single `gcp.vpc.flow.reporter` value. #### What VPC metrics should I alert on? Alert on `router.googleapis.com/nat/dropped_sent_packets_count` above all else. NAT port exhaustion makes outbound connections fail with generic timeouts that nothing in the application logs explains, and this metric is the only direct evidence. #### Can I group dashboards by source IP address? No — IP addresses are unbounded and will produce an enormous number of series. Filter and search on them freely, but aggregate on subnet, VM name, port or protocol. ### Reference - [VPC Flow Logs](https://docs.cloud.google.com/vpc/docs/flow-logs) - [Flow log record format](https://docs.cloud.google.com/vpc/docs/flow-logs#record_format) - [Cloud NAT metrics](https://docs.cloud.google.com/nat/docs/monitoring) ### Related Guides - [GCP Cloud Logging](./gcp-cloud-logging-to-scout.md) - the sink, topic and subscription this guide builds on. - [GCP Monitoring overview](./overview.md) - the Cloud NAT metrics path in its general form, and the IAM it needs. - [Cloud Load Balancing](./load-balancing.md) - the other high-volume log source, and where external traffic enters before it reaches a subnet. --- ## Edge Collector Patterns for IoT with OpenTelemetry ## Edge Collector Patterns for IoT An edge Collector runs next to the devices, on the gateway or the site server, between your fleet and the backhaul that carries telemetry to the cloud. That position is where the hard IoT constraints live: the uplink is intermittent, bandwidth is metered or thin, and some devices run on a battery you do not want to drain on routine reporting. This guide covers four Collector patterns that handle those constraints, each one a small piece of configuration you can adopt independently. The companion runnable example lives at [examples/iot/edge-collector-store-forward](https://github.com/base-14/examples/tree/main/iot/edge-collector-store-forward). ### The topology The edge Collector receives OTLP from local devices and forwards to an upstream Collector across the backhaul. Only the upstream hop authenticates to Scout; the edge stays simple and local. ```text devices ──> edge collector ──backhaul──> upstream collector ──> Scout buffer · downsample · route · drop ``` Splitting edge from upstream is what makes the buffering testable: sever the backhaul and the devices keep talking to the edge, which holds their data until the link returns. It also matches real deployments, where the edge box is yours and the upstream is a regional aggregation point. ### Pattern 1: Disk-buffered store-and-forward A dropped backhaul should cost you nothing. The `file_storage` extension gives the exporter a persistent send queue: batches that have not been acked by the upstream are written to disk, so they survive both a network outage and a restart of the Collector process itself. ```yaml extensions: file_storage: directory: /var/lib/otelcol/storage timeout: 10s exporters: otlp_http/upstream: endpoint: ${env:UPSTREAM_ENDPOINT} sending_queue: enabled: true storage: file_storage # queue lives on disk, not just in memory queue_size: 1000 retry_on_failure: enabled: true initial_interval: 5s max_interval: 30s service: extensions: [file_storage] ``` When the upstream is unreachable, the exporter retries and the unacked batches accumulate in the on-disk queue. When the link returns, the queue drains. Because OTLP carries the original event timestamp, the late data lands in the correct place in the series rather than bunched at the recovery moment. Size `queue_size` (measured in batches) for your worst-case outage at your batch rate. The queue is bounded by that count, not by a byte budget, so on a constrained gateway choose a value whose on-disk footprint fits the partition, and watch `otelcol_exporter_queue_size`. When the queue is full, new batches are dropped while the already-queued data is kept. ### Pattern 2: Downsampling high-frequency gauges A sensor sampling every two seconds produces far more datapoints than most dashboards or alerts need. The `interval` processor aggregates a time window into a single datapoint, cutting the volume crossing the backhaul. ```yaml processors: interval: interval: 30s # one datapoint per gauge per 30s window ``` For gauges the processor emits the last value seen in each window. That loses sub-window detail, which is the deliberate trade: you accept coarser resolution on routine metrics in exchange for a fraction of the bandwidth. Keep this for metrics only. Traces are not downsampled here - sampling trace data is a separate decision, made on its own terms. ### Pattern 3: Routing high-priority fleets at full resolution Downsampling everything is rarely right. A critical line of equipment may need every datapoint while a shelf of environmental sensors does not. The `routing` connector splits the stream on a resource attribute - `fleet.priority` here - so high-priority fleets bypass the downsampler. ```yaml connectors: routing: default_pipelines: [metrics/downsample] table: - context: resource condition: 'attributes["fleet.priority"] == "high"' pipelines: [metrics/full-rate] service: pipelines: metrics/ingest: receivers: [otlp] processors: [memory_limiter] exporters: [routing] metrics/full-rate: receivers: [routing] processors: [batch] exporters: [otlp_http/upstream] metrics/downsample: receivers: [routing] processors: [interval, batch] exporters: [otlp_http/upstream] ``` Routing on the `resource` context keeps each device's stream intact: every metric from a high-priority device follows the full-rate path, and everything else is downsampled. Extend the table to carve out more priorities; the default route is the downsampler. ### Pattern 4: Battery-aware dropping For battery-powered devices, the uplink itself costs energy. When a device reports a low battery, dropping its non-essential telemetry at the edge extends its working life. The `filter` processor expresses that policy with OTTL. ```yaml processors: filter/low-battery: error_mode: ignore metrics: datapoint: - >- resource.attributes["device.battery.level"] != nil and resource.attributes["device.battery.level"] < 20 and resource.attributes["fleet.priority"] != "critical" ``` Place this before routing so it applies to every device. The `device.battery.level` and `fleet.priority` attributes come from the device's resource (see the [IoT resource-attribute schema](./index.md)). The threshold and the critical-fleet exemption are a policy choice: tune them per device class. This drops metrics only; traces are unaffected. ### Clock skew and late arrival Replayed data keeps its original OTLP timestamp, so a backhaul recovery restores the true shape of the series rather than a spike at reconnect. This depends on the device clocks being roughly correct. Keep them on NTP or a periodic sync; a device whose clock is hours off will deposit its late data in the wrong window, which no amount of edge buffering can correct. ### Sending to Scout The edge Collector forwards plain OTLP to the upstream Collector, which is the hop that authenticates to Scout with the OAuth2 client-credentials extension and the `otlp_http/b14` exporter. That wiring is the same as any Scout Collector deployment - see [Scout exporter wiring](../collector-setup/scout-exporter.md). Keeping authentication on the upstream means the edge configuration carries no credentials. ### Troubleshooting - **Queue grows and never drains.** The upstream is unreachable or rejecting data. Check connectivity across the backhaul and the upstream Collector's own logs; the edge is doing its job by holding the data. - **Queue resets to zero after a restart.** The `sending_queue` is not backed by storage. Confirm `storage: file_storage` on the exporter and that the `file_storage` directory is writable and on a persistent volume. - **Downsampling has no effect.** The metrics may be arriving already aggregated, or the SDK export interval is longer than the `interval` window. Confirm the source exports faster than the window you set. - **High-priority data is being downsampled.** Check the `routing` connector condition and that the device's resource actually carries `fleet.priority`; resources without the attribute take the default (downsample) route. - **Retry storms on reconnect.** A large backlog flushing at once can overwhelm the upstream. Tune `retry_on_failure` intervals and the upstream's `batch` settings to smooth the recovery. ### Related guides - [MQTT Trace Propagation](./mqtt-trace-propagation.md) - the producer and consumer this example reuses as traffic generators. - [IoT & Edge overview](./index.md) - the resource-attribute conventions, including `device.battery.level` and `fleet.priority`. - [Scout exporter wiring](../collector-setup/scout-exporter.md) - the OAuth2 extension and exporter the upstream Collector uses. --- ## ESP32 Firmware to OpenTelemetry OpenTelemetry has no C SDK and no microcontroller story today. The C++ SDK is POSIX-only and far too heavy for an ESP32, and a full OTLP/HTTP + protobuf + TLS stack does not fit the default firmware build. So getting telemetry off a constrained device and into an OTLP pipeline means choosing where the conversion happens. This guide puts it at the edge: the firmware emits a small, versioned JSON envelope over MQTT, and a bridge service turns it into ordinary OpenTelemetry. The companion runnable example lives at [examples/iot/esp32-firmware](https://github.com/base-14/examples/tree/main/iot/esp32-firmware). ### Why a bridge, not OTLP from the device You could, in principle, generate C structs for the OTLP protobuf definitions and emit real OTLP over MQTT from the device. It is a valid path, and the appendix sketches it. But for a reference example it trades away the two things that make this useful: a payload you can read on one screen, and a firmware image that is mostly Wi-Fi and TLS rather than serialization code. So the device speaks a compact format - the Scout MCU Envelope, SME-v1 - and the bridge is what makes it OpenTelemetry. The envelope is the replaceable piece. A team that needs strict wire-level OTLP can swap it for the protobuf path and keep the bridge, the Collector, and Scout exactly as they are. ### The SME-v1 envelope One JSON object per reading, published to `{prefix}/{device_id}/telemetry`: ```json { "v": 1, "device": { "id": "esp32-dev-01", "model": "esp32-s3-devkitc", "firmware": { "version": "0.1.0", "channel": "dev" }, "fleet": { "id": "fleet-demo", "tenant": "acme" } }, "ts_ms": 1712347200000, "ts_source": "sntp", "trace": { "traceparent": "00-4bf9...4736-00f0...02b7-01" }, "metrics": [ { "name": "mcu.cpu.temp_c", "kind": "gauge", "value": 42.1, "unit": "Cel" }, { "name": "mcu.uptime", "kind": "counter", "value": 12345, "unit": "s" } ], "events": [ { "name": "wifi.reconnect", "severity": "warn", "attrs": { "rssi": -78 } } ] } ``` The `device` block is the device's resource. `metrics` are levels (`gauge`) or running totals (`counter`). `events` are point-in-time log records. `trace.traceparent` is optional and present when the device wants a specific publish correlated. The version field `v` is the contract: a bridge accepts only the versions it implements and rejects the rest rather than guessing. ### Generate trace context on the device The device mints W3C trace context itself, so a publish can be tied into a trace before it ever reaches a backend. The format is a fixed string - version, 16-byte trace ID, 8-byte span ID, sampled flag: ```c void traceparent_generate(char *out, size_t len) { uint8_t trace_id[16], span_id[8]; esp_fill_random(trace_id, sizeof(trace_id)); esp_fill_random(span_id, sizeof(span_id)); char tid[33], sid[17]; to_hex(tid, trace_id, 16); tid[32] = '\0'; to_hex(sid, span_id, 8); sid[16] = '\0'; snprintf(out, len, "00-%s-%s-01", tid, sid); } ``` One caveat worth stating plainly: `esp_random()` is a true CSPRNG only once the RF subsystem (Wi-Fi or Bluetooth) is running. During cold boot it falls back to a weaker source. The firmware holds its first publish until Wi-Fi connects, so trace IDs are strong - but do not market this as cryptographic randomness without that ordering guarantee. ### The publish loop The loop is deliberately small: read sensors, stamp a timestamp, build the envelope, publish at QoS 1, sleep. The clock source is recorded so a consumer knows whether to trust the timestamp: ```c if (time_synced) { // SNTP succeeded after Wi-Fi up gettimeofday(&tv, NULL); ts_ms = (int64_t)tv.tv_sec * 1000 + tv.tv_usec / 1000; ts_source = "sntp"; } else { // no network time yet ts_ms = esp_timer_get_time() / 1000; ts_source = "uptime"; } ``` `ts_source` rides along on every datapoint as an attribute, so a chart built on these metrics can distinguish wall-clock readings from uptime-relative ones after a clock jump. The device also registers an MQTT Last Will on `{prefix}/{device_id}/offline` at connect, so the broker announces an ungraceful drop without the bridge polling for liveness - the same pattern the [Sparkplug decoder](./sparkplug.md) relies on for NDEATH. ### What the bridge does The bridge subscribes to the telemetry and offline topics and turns each envelope into OpenTelemetry signals. **Per-device resource.** The `device` block becomes an OTel `Resource`, so device identity is a resource attribute, not a datapoint attribute: ```python def resource_attrs(device): attrs = {"device.id": device["id"], "device.kind": "mcu"} attrs["device.model.identifier"] = device.get("model") fw = device.get("firmware", {}) attrs["device.firmware.version"] = fw.get("version") attrs["device.firmware.channel"] = fw.get("channel") fleet = device.get("fleet", {}) attrs["fleet.id"] = fleet.get("id") attrs["fleet.tenant"] = fleet.get("tenant") return attrs ``` **Counters arrive as totals.** The device sends `mcu.uptime` as a running total, so the bridge models it as an observable monotonic Sum reading the latest cached value - it stays rate-able in Scout even though the device never sends a delta: ```python def callback(_options, _series=series): return [Observation(value, attrs) for value, attrs in _series.values()] meter.create_observable_counter(name, unit=unit, callbacks=[callback]) ``` **Events become logs, traces continue.** Each event is a log record at its severity. When an envelope carries a `traceparent`, the bridge starts an `mcu.publish` span in that extracted context, so the device's publish joins a trace: ```python parent = TraceContextTextMapPropagator().extract({"traceparent": tp}) tracer.start_span("mcu.publish", context=parent, attributes=attrs).end() ``` **Bad input is counted, not fatal.** Malformed JSON increments `sme_bridge.parse_errors_total`; an unknown `v` increments `sme_bridge.version_rejected_total`. `sme_bridge.messages_total` breaks down by result. A single bad frame never takes the bridge down. ### Resource attributes Device identity maps onto the [IoT resource schema](./index.md). A microcontroller is a compute device, so it uses `device.*` with `device.kind=mcu`, not the `asset.*` namespace that physical equipment uses. | Attribute | Source | Example | | --- | --- | --- | | `service.name` | bridge | `sme-bridge` | | `device.id` | envelope | `esp32-dev-01` | | `device.kind` | fixed | `mcu` | | `device.model.identifier` | envelope | `esp32-s3-devkitc` | | `device.firmware.version` | envelope | `0.1.0` | | `device.firmware.channel` | envelope | `dev` | | `fleet.id` | envelope | `fleet-demo` | | `fleet.tenant` | envelope | `acme` | ### Firmware footprint Footprint is the number that decides whether an approach fits a device, so measure it on your own build rather than trusting a quoted figure - it moves with the ESP-IDF version, the target chip, and the config: ```bash idf.py size # total flash + RAM idf.py size-components # per-component: Wi-Fi, mbedTLS, esp-mqtt, app ``` A clean build of this firmware (ESP-IDF v5.5.2, target `esp32s3`, the checked-in `sdkconfig.defaults`) gives a baseline to reason against. The app image is about 897 KB (`0xe0320`, 918,304 bytes), which leaves 12% free in a 1 MB app partition: | Memory | Used | Detail | |------------|-----------|---------------------------------------| | Flash Code | 674,638 B | `.text` (executable code) | | Flash Data | 132,284 B | `.rodata` 132,028 B + app descriptor | | DIRAM | 112,331 B | 32.87% of 341,760 B internal RAM | | IRAM | 16,384 B | cache-locked instruction region, full | The per-component breakdown is the useful part. The Wi-Fi and TLS stacks dominate: `libnet80211.a` (Wi-Fi MAC) is ~146 KB, `liblwip.a` (TCP/IP) ~105 KB, `libmbedcrypto.a` (TLS) ~79 KB, and the `libwpa_supplicant.a`/`libpp.a` Wi-Fi pair another ~129 KB combined. The telemetry path is small against that: esp-mqtt (`libmqtt.a`) ~26 KB, cJSON (`libjson.a`) ~3 KB, and the application itself - the SME-v1 serializer plus the publish loop - ~3.2 KB. That distribution is the real argument for the bridge pattern. The expensive parts of the firmware are the network and crypto you need for any backend at all; the telemetry encoding rides along for a few kilobytes. Once a device is on the network, adding structured telemetry is close to free in flash terms. ### Security hardening The example is plaintext and anonymous so it runs with no setup. Before production: - **Transport.** Switch to `mqtts://` with TLS. The ESP32 has the mbedTLS stack already linked; the cost is in the footprint table above. - **Authentication.** Replace anonymous broker access with per-device credentials, ideally client certificates over mutual TLS. - **Identity provisioning.** Devices need a provisioning flow that issues per-device keys or certs, not a shared secret baked into the image. - **Topic ACLs.** Scope each device to its own topic subtree so a compromised device cannot publish as another. - **Public brokers.** `test.mosquitto.org` is fine for the Wokwi demo and nowhere near production. Never send real telemetry through a public broker. ### Appendix: real OTLP over the wire If you need strict wire-level OTLP rather than a custom envelope, the path is [nanopb](https://github.com/nanopb/nanopb): generate C structs from the OTLP `metrics.proto` and `trace.proto`, encode them on-device, and publish the protobuf bytes over MQTT to a Collector with an MQTT receiver (or a thin bridge that forwards bytes). This is **not implemented in the example.** It costs more flash and a harder-to-read payload, and it buys wire compatibility - worth it when a downstream consumer expects OTLP protobuf directly and you cannot run a translating bridge. ### Why this isn't a Collector receiver today Beyond the [missing `mqttreceiver`](./index.md) the rest of the track works around, the constrained-device path also has no embedded OTel SDK to emit OTLP from the device itself. The clean future is an SDK or codec the device links directly, paired with that upstream receiver; until then, keep the envelope versioned and the bridge thin so swapping either side later is a contained change. ### Troubleshooting - **Nothing reaches the bridge.** Check the device and bridge agree on the broker and topic prefix. On the shared `test.mosquitto.org`, a collision with another user's prefix looks like silence; use a unique prefix on both sides. - **`version_rejected_total` climbing.** A device is sending a `v` the bridge does not implement. Bump the bridge, do not loosen the check. - **Timestamps look wrong after boot.** The device published before SNTP synced; those datapoints carry `mcu.ts_source=uptime`. Filter or annotate on that attribute. - **Counter renders as a sawtooth.** A running-total metric was sent as a `gauge`. Send it as `kind: counter` so the bridge exports a Sum. - **Nothing reaches Scout.** Confirm the Collector picked up the four `SCOUT_*` values; the debug exporter prints to stdout regardless, which separates a bridge problem from an export problem. ### Related guides - [IoT & Edge overview](./index.md) - the resource attribute conventions every IoT example follows. - [MQTT trace propagation](./mqtt-trace-propagation.md) - the broker and trace-context pattern this firmware extends to the device. - [Edge Collector patterns](./edge-collector-patterns.md) - the store-and-forward Collector this example reuses for the backhaul. - [Sparkplug B decoder](./sparkplug.md) - the other MQTT-to-OTLP bridge in this track; compare the envelope-versus-protobuf tradeoff. - [Scout exporter wiring](../collector-setup/scout-exporter.md) - the `oauth2client` extension and `otlp_http/b14` exporter used here. --- ## IoT & Edge Observability with OpenTelemetry ## IoT & Edge Observability IoT and edge systems break the assumptions most observability tooling is built on. Devices are constrained, links are intermittent, fleets are large, and the thing emitting telemetry is often not the thing being measured. These guides cover instrumenting that world with OpenTelemetry and shipping the signals to base14 Scout, vendor-neutral and OTLP-native from the device up. ### Why IoT is different A web service has a stable host, a fast network, and an SDK that speaks OTLP natively. An IoT estate has none of those guarantees: - **Constrained devices.** Microcontrollers have kilobytes of RAM and no room for a full OTLP/HTTP + protobuf stack. There is no OpenTelemetry C SDK and no MCU story today, so the device-to-edge hop needs a compact, transport-friendly encoding. - **Intermittent connectivity.** Cellular and radio links drop. Spans and metrics have to be buffered at the edge and forwarded on reconnect, with clock-skew repair so late data lands on the right timeline. - **Fleet scale and proxy identity.** Thousands of devices report through a handful of gateways. When a gateway speaks for a device, the telemetry has to carry whose signal it is, which the current semantic conventions do not express. - **Industrial protocols.** OPC-UA and Sparkplug B dominate the factory floor, and neither has a Collector receiver in contrib. Bridging them to OTLP is on you until that lands upstream. ### The state of OpenTelemetry for IoT The ecosystem is early here, and these guides are built around the gaps rather than pretending they do not exist: - **No protocol receivers.** Contrib ships `snmpreceiver` plus the generic log receivers, but no MQTT, CoAP, OPC-UA, or Sparkplug B receiver. The bridge examples in this track are the workaround, and a working model for the receiver these protocols still lack. Each bridge is built so that swapping in a future receiver is a deletion, not a rewrite: declarative mapping, state held explicitly, and instruments created the way a receiver would. The clean end state is an `mqttreceiver` that subscribes and decodes, paired with protocol-specific processors for the stateful work; until that lands, the bridges stand in. - **No constrained-device SDK.** The embedded C effort is not active in the OpenTelemetry org, and the C++ and Rust embedded tracks are unresolved. Firmware emits a compact payload that an edge Collector translates into OTLP. - **No fleet or device semantic-convention group.** Firmware version, provisioning identity, gateway hop, battery, and signal strength are all undefined upstream. The conventions below are Scout's working schema until that group exists. - **No canonical end-to-end example.** There is no IoT equivalent of the OpenTelemetry demo. This track is one, built phase by phase, from a microcontroller through the edge to Scout. ### Guides in this track Each phase ships a runnable example and a guide. Every example runs locally with Docker, no cloud account required. | Phase | Guide | What it covers | Status | | --- | --- | --- | --- | | 1 | [MQTT trace context propagation](./mqtt-trace-propagation.md) | Trace context flowing across an MQTT 5 broker via user properties, visualized as one end-to-end trace in Scout. | Available | | 2 | [Edge Collector patterns](./edge-collector-patterns.md) | Disk-buffered store-and-forward, interval downsampling, priority routing, and battery-aware filtering at the edge, surviving simulated disconnects. | Available | | 3 | [OPC-UA to OTel bridge](./opcua.md) | A bridge that subscribes to an OPC-UA server and emits OTLP metrics with industrial asset attributes, fault logs, and session spans. | Available | | 4 | [Sparkplug B decoder](./sparkplug.md) | Decoding NBIRTH / DBIRTH / DDATA into OTLP metrics with device lifecycle state and sequence-gap detection. | Available | | 5 | [ESP32 firmware to OTel](./esp32.md) | Constrained-device firmware (ESP-IDF, C) emitting a compact SME-v1 JSON payload over MQTT, bridged to OTLP and shipped through an edge Collector. | Available | :::tip Flagship example Phase 5 is the constrained-device payoff: a real ESP32 firmware emitting OpenTelemetry in a world with no C SDK. If you want the end-to-end constrained-device story - on-device trace context, a versioned wire envelope, and a bridge to OTLP - start there. ::: ### Resource attributes we use Consistency across the phases above matters more than waiting for upstream alignment, so the schema is locked here before any example uses it. These are **Scout conventions pending upstream discussion**, not ratified semantic conventions. Where an attribute reuses an existing convention it is noted; the rest are proposed for a future `device.*` / `fleet.*` working group, justified by the concrete usage these examples provide. #### Compute devices (`device.*`) Sensors, microcontrollers, gateways, and network gear. | Attribute | Meaning | | --- | --- | | `device.id` | Unique device identifier. Upstream `device.id` is opt-in under recent semconv; Scout treats it as opt-in by default. | | `device.manufacturer` | Device maker (existing mobile-origin attribute). | | `device.model.identifier` | Model identifier (existing mobile-origin attribute). | | `device.serial` | Hardware serial number. | | `device.firmware.version` | Running firmware version. | | `device.firmware.channel` | Release channel, e.g. `stable` / `beta`. | | `device.power.source` | Power source, e.g. `mains` / `battery`. | | `device.battery.level` | Battery level where applicable. | | `device.provisioning.method` | How the device obtained its identity. | | `device.kind` | Discriminator: `sensor` \| `gateway` \| `mcu` \| `network`. | #### Fleet (`fleet.*`) | Attribute | Meaning | | --- | --- | | `fleet.id` | Fleet the device belongs to. | | `fleet.tenant` | Owning tenant. | | `fleet.priority` | `critical` \| `high` \| `normal` \| `low`. Used by edge filters. | #### Gateway (`gateway.*`) | Attribute | Meaning | | --- | --- | | `gateway.id` | Gateway the device reports through. | | `gateway.hop` | Hop count from device to backend. | #### Network (`network.*`) | Attribute | Meaning | | --- | --- | | `network.signal.rssi` | Received signal strength. | #### Physical assets (`asset.*`) Pumps, conveyors, ovens, and lines, distinct from compute devices. | Attribute | Meaning | | --- | --- | | `asset.id` | Unique identifier for the physical asset. | | `asset.type` | `pump` \| `conveyor` \| `oven` \| `line` \| ... | | `asset.name` | Human-readable label. | | `asset.parent_id` | Parent asset, for hierarchy chains. | Asset hierarchy is expressed with `asset.parent_id` chains. Do not introduce ad-hoc grouping attributes such as `asset.group`, `asset.edge_node`, or `asset.line`; encode those relationships as `asset.parent_id` instead. #### Site (`site.*`) | Attribute | Meaning | | --- | --- | | `site.id` | Physical location identifier. | | `site.name` | Human-readable location name. | ### Next steps The MQTT trace-propagation guide is the entry point and a prerequisite for the Sparkplug and ESP32 phases. All five phases are live; the table above links each. For shipping the resulting telemetry, see the [OpenTelemetry Collector Setup](../collector-setup/docker-compose-example.md) guides and [Scout exporter wiring](../collector-setup/scout-exporter.md). --- ## MQTT Trace Context Propagation with OpenTelemetry ## MQTT Trace Context Propagation Message brokers break the call stack. An HTTP request carries its trace context in headers, but when a service publishes to MQTT and another service consumes from it later, the link is lost unless you carry the context across the broker yourself. This guide shows how to do that with MQTT 5 user properties, so a producer, a consumer, and a downstream HTTP service show up as one connected trace in Scout. The companion runnable example lives at [examples/iot/mqtt-trace-propagation](https://github.com/base-14/examples/tree/main/iot/mqtt-trace-propagation). ### Why the broker can stay "dark" Mosquitto, like most MQTT brokers, has no OpenTelemetry integration, so it produces no spans. That sounds like a gap in the trace, but it is not one that matters. Distributed tracing does not require every hop to be instrumented; it requires the endpoints to agree on a trace context. As long as the producer injects the context and the consumer extracts it, the two spans share one `trace_id` and the broker being invisible is just an unlabeled edge between them. Trying to instrument the broker would add operational weight for a span that tells you little the producer and consumer spans do not already. ### Architecture ```text producer (Python) consumer (Python) echo (FastAPI) publish span MQTT 5 process span HTTP server span inject traceparent ---------> extract context -------> (auto-instr.) into user props Mosquitto continue trace \ (dark) | / \________________ all export OTLP -> Collector -> Scout / ``` The producer opens a span per reading, serializes the trace context into the PUBLISH user properties, and publishes. The consumer reads those user properties back, restores the context, and opens a child span that also wraps an instrumented HTTP call to the echo service. That last hop proves the context flows past MQTT into an ordinary request span. ### Producer: inject context into user properties The W3C TraceContext propagator writes into a plain dictionary. MQTT 5 user properties are a list of string key-value pairs. The bridge is just turning one into the other: ```python from opentelemetry.propagate import inject from paho.mqtt.packettypes import PacketTypes from paho.mqtt.properties import Properties def context_to_user_properties(context=None): carrier = {} inject(carrier, context=context) return list(carrier.items()) # per publish, inside the producer span: props = Properties(PacketTypes.PUBLISH) props.UserProperty = context_to_user_properties(ctx) client.publish(topic, payload, qos=1, properties=props) ``` The span is opened before the publish and closed on the QoS 1 `PUBACK`, so its duration reflects the real broker round-trip. A message-id to span map correlates the asynchronous ack callback back to the right span. ### Consumer: extract context and continue the trace On the receiving side, hand the user properties back to the propagator as a carrier and start the consumer span as a child of the result: ```python from opentelemetry import trace from opentelemetry.propagate import extract from opentelemetry.trace import SpanKind def user_properties_to_context(user_property): carrier = dict(user_property or []) return extract(carrier) # in on_message: parent = user_properties_to_context(message.properties.UserProperty) span = tracer.start_span( f"process {message.topic}", context=parent, kind=SpanKind.CONSUMER ) ``` Starting the span with the extracted context as its parent gives you a single unbroken trace. Use a span **link** instead of a parent when one consumer fans a batch of messages into separate units of work, where a single parent would misrepresent the structure; for the one-message-per -reading case here, a child span is the right choice. ### Messaging semantic-convention attributes Both spans follow the OpenTelemetry messaging conventions so they render consistently and are queryable by destination and operation: | Attribute | Producer | Consumer | | --- | --- | --- | | `messaging.system` | `mqtt` | `mqtt` | | `messaging.destination.name` | the publish topic | the received topic | | `messaging.operation.type` | `publish` | `process` | | `messaging.message.id` | per-message UUID | echoed from payload | Span names follow the convention `{operation} {destination}`, giving `publish sensors/sensor-001/reading` on the producer and `process sensors/sensor-001/reading` on the consumer. ### Handling missing context A message can arrive without trace context, for example from a client that does not speak MQTT 5. The consumer must not drop it. Detect the absence and start a new root span tagged so these orphans are easy to find: ```python if not has_trace_context(user_props): span = tracer.start_span( f"process {topic}", kind=SpanKind.CONSUMER, attributes={"mqtt.missing_context": True}, ) ``` Querying for `mqtt.missing_context=true` in Scout surfaces every message that crossed the broker without a usable context, which is how you catch a misconfigured or legacy publisher. ### Troubleshooting - **Producer and consumer trace IDs do not match.** Confirm both clients connect with `protocol=MQTTv5`. On MQTT 3.1.1 there are no user properties, so the context never leaves the producer. - **Consumer spans are all roots with `mqtt.missing_context=true`.** The publisher is not injecting context, or is publishing on 3.1.1. Check the producer is setting `UserProperty` on a `PacketTypes.PUBLISH` properties object. - **Producer spans look instantaneous.** With QoS 0 there is no `PUBACK` to end the span on, so it closes as soon as the packet is handed to the client. Use QoS 1 if you want the span to measure the publish round-trip. - **Nothing reaches Scout.** Verify the Collector picked up the four `SCOUT_*` values and that the OAuth2 token endpoint is reachable; the Collector's debug exporter prints spans to stdout regardless, which isolates a propagation problem from an export problem. ### MQTT 3.1.1 note MQTT 3.1.1 has no user properties. Carrying trace context on 3.1.1 means encoding it into the message payload itself, which couples the transport to your schema and is out of scope here. MQTT 5 is required for the clean, header-style propagation this guide uses. ### Related guides - [IoT & Edge overview](./index.md) - the resource attribute conventions every IoT example follows. - [Collector Setup](../collector-setup/docker-compose-example.md) - the runtime that hosts the Collector in this example. - [Scout exporter wiring](../collector-setup/scout-exporter.md) - the `oauth2client` extension and `otlp_http/b14` exporter used here. --- ## OPC-UA to OpenTelemetry Bridge OPC-UA is the lingua franca of the factory floor, and the OpenTelemetry Collector has no receiver for it. Until one lands in contrib, getting machine telemetry into an OTLP pipeline means writing a bridge: a service that speaks OPC-UA on one side and OTLP on the other. This guide builds that bridge, maps factory nodes to metrics with a declarative file, and turns equipment faults into logs and session lifecycle into spans. The companion runnable example lives at [examples/iot/opcua-bridge](https://github.com/base-14/examples/tree/main/iot/opcua-bridge). ### Why a bridge, not a receiver A Collector receiver would be the clean answer, but nothing in contrib speaks OPC-UA today. A bridge is the pragmatic stand-in, and it is not throwaway work: the shape of a good bridge - subscribe to nodes, cache their values, expose them as observable instruments read at collection time, drive the mapping from config rather than code - is exactly the shape a receiver would take, so the work transfers cleanly when one lands (the [receiver direction this track follows](./index.md)). The other reason a bridge earns its keep is that OPC-UA values are not OTLP metrics one-to-one. A node carrying a pump's status string is not a gauge; it is a state worth logging when it changes. A monotonic counter node is a `Sum`, not a `Gauge`. The bridge is where you encode those decisions, and a declarative map keeps them out of the code path. ### Architecture ```text opcua-server (asyncua) bridge (Python) otel-collector 6 simulated nodes OPC-UA subscribe + cache OTLP oauth2 -> b14 flow, vibration, -------> observable metrics -----> exporter ---> Scout status, speed, :4840 fault logs temp, throughput session span ``` The bridge holds one OPC-UA subscription. Each data change updates an in-memory cache keyed by node ID. OTel observable instruments read that cache at collection time, so the export cadence is decoupled from the OPC-UA update rate - the server can push at 500ms while the Collector scrapes every few seconds. ### Map nodes to metrics declaratively The mapping lives in `node_map.yaml`, not in code. Each entry binds one OPC-UA node to an OTLP metric, its unit, its kind, and the `asset.*` attributes that identify the physical equipment: ```yaml nodes: - node_id: "ns=2;s=Pump1/Flow" metric: name: factory.pump.flow_rate unit: "L/min" kind: gauge # gauge | counter | status description: Pump discharge flow rate attributes: asset.id: pump-1 asset.type: pump asset.name: Transfer Pump 1 asset.parent_id: line-1 - node_id: "ns=2;s=Line1/ThroughputCounter" metric: name: factory.line.throughput unit: "{item}" kind: counter # monotonic Sum, not a Gauge description: Items produced on the line attributes: asset.id: line-1 asset.type: line asset.name: Assembly Line 1 ``` `kind` is the important field. A `gauge` becomes an observable gauge, a `counter` an observable counter (a monotonic `Sum`), and a `status` is not a metric at all - it becomes a fault-log source, covered below. Adding or remapping a node is a config edit; the bridge code never changes. ### Read the cache from observable callbacks Each gauge or counter is an observable instrument. Its callback reads the node's latest value out of the shared cache; if no value has arrived yet it returns nothing rather than a zero, so the series starts when real data does: ```python def _callback(node_id, attributes, cache): def cb(_options): value = cache.get(node_id) if value is None: return [] return [Observation(float(value), attributes)] return cb meter.create_observable_gauge( name, callbacks=[cb], unit=unit, description=description ) ``` The subscription handler is the only writer to the cache: ```python def datachange_notification(self, node, val, _data): cache[node.nodeid.to_string()] = val ``` This split - subscription writes, callbacks read - is what decouples the OPC-UA update rate from the OTLP export interval, and it is the same contract a Collector receiver would implement internally. ### Turn status changes into fault logs A pump's status is a string that matters at the moment it changes, not as a continuous series. Map it as `kind: status` and the bridge logs each transition instead of emitting a metric. Because the logger is wired to an OTel `LoggingHandler`, the `extra={}` dict becomes log-record attributes: ```python if val == "fault": bridge_log.warning("asset entered fault state", extra=attributes) elif previous is not None: bridge_log.info("asset recovered", extra=attributes) ``` In Scout these arrive as log records carrying `asset.id`, `asset.type`, `asset.parent_id`, and `asset.status`, so you can pivot from a metric anomaly straight to the fault event on the same asset. Logging the transition rather than sampling the status as a metric keeps cardinality down and makes the event queryable as an event. ### Wrap the session in a span The OPC-UA session lifecycle is modeled as one `opcua.session` span. It opens when the bridge connects and closes when the connection drops, so its duration is the uptime of one session and a reconnect is a new span: ```python async with Client(ENDPOINT) as client: with tracer.start_as_current_span("opcua.session", kind=SpanKind.CLIENT) as span: span.set_attribute("opcua.endpoint", ENDPOINT) span.set_attribute("opcua.security_policy", "None") # ... subscribe and serve until the connection drops ``` When a server restart or network blip ends the session, the span closes with an error status carrying the exception, and the bridge reconnects with exponential backoff (1s, doubling, capped at 30s). Each error span is therefore one connection-loss event - a clean signal to alert on, and a sequence that tells the reconnection story without extra plumbing. ### Detect a half-open connection A dropped TCP connection does not always raise on the subscription. The bridge issues a periodic lightweight read so a silently dead session is caught and triggers a reconnect rather than going quiet: ```python while running: await asyncio.sleep(3) await client.get_node(subscribe_ids[0]).read_value() ``` Without this probe a half-open socket can leave the bridge "connected" but receiving nothing, and metrics simply stop with no error to explain why. The read turns that silent failure into the same reconnect path as an explicit drop. ### Resource attributes The bridge sets site and fleet identity on the resource; the per-asset attributes come from the node map. This follows the [IoT resource schema](./index.md): | Attribute | Source | Example | | --- | --- | --- | | `service.name` | bridge | `opcua-bridge` | | `site.id` / `site.name` | resource | `site-hq` / `HQ Plant` | | `fleet.id` | resource | `factory-floor` | | `asset.id` / `asset.type` | node map | `pump-1` / `pump` | | `asset.parent_id` | node map | `line-1` | Asset hierarchy is expressed with `asset.parent_id` chains, not ad-hoc grouping attributes - the pump points at the line it sits on, and a deeper tree just adds links. ### Security The example server runs `NoSecurity` and the bridge connects anonymously, which keeps the demo to one `docker compose up`. Production OPC-UA should not. Pick a security policy (for example `Basic256Sha256`) and an authentication mode (certificate or username), and set both on the client: ```python await client.set_security_string( "Basic256Sha256,SignAndEncrypt,client_cert.pem,client_key.pem" ) ``` Record the chosen policy on the session span's `opcua.security_policy` attribute so the security posture is visible in traces, not just in config. ### Troubleshooting - **Bridge cannot connect.** Confirm the endpoint path matches the server exactly (`opc.tcp://host:4840/factory/`); OPC-UA endpoint URLs are path-sensitive. Check the server is reachable on 4840 from the bridge's network. - **Metrics never appear but no errors log.** A half-open connection. The periodic `read_value()` probe exists to catch this; confirm it is running and that the reconnect path fires. - **Counter resets to zero in Scout.** A monotonic node mapped as `kind: gauge` will look like a sawtooth. Map cumulative nodes as `kind: counter` so they export as a `Sum`. - **Fault log has no asset attributes.** The attributes come from the `status` node's `attributes:` block in `node_map.yaml`; an entry with no attributes logs a bare message. - **asyncua floods the logs.** The library logs every publish callback at INFO. Quiet it with `logging.getLogger("asyncua").setLevel(logging.WARNING)` so the bridge's own records are the signal. - **Nothing reaches Scout.** Confirm the Collector picked up the four `SCOUT_*` values; the debug exporter prints to stdout regardless, which separates a bridge problem from an export problem. ### Related guides - [IoT & Edge overview](./index.md) - the resource attribute conventions every IoT example follows. - [Edge Collector patterns](./edge-collector-patterns.md) - buffer, downsample, and route this telemetry once it is on the wire. - [Scout exporter wiring](../collector-setup/scout-exporter.md) - the `oauth2client` extension and `otlp_http/b14` exporter used here. --- ## Sparkplug B to OpenTelemetry Decoder Sparkplug B is the structured payload spec that turns plain MQTT into a self-describing IIoT protocol, and it is everywhere on the plant floor. The OpenTelemetry Collector has no decoder for it, so getting Sparkplug telemetry into an OTLP pipeline means writing a bridge that speaks the protobuf wire format, tracks session state, and resolves the metric aliases Sparkplug uses to keep DATA messages small. This guide builds that decoder. The companion runnable example lives at [examples/iot/sparkplug-bridge](https://github.com/base-14/examples/tree/main/iot/sparkplug-bridge). ### Why Sparkplug needs a decoder, not just an MQTT receiver A generic MQTT receiver would hand you opaque protobuf bytes. Sparkplug is stateful in a way that a per-message receiver cannot handle on its own: a metric is defined once, in a BIRTH message, with a name, a datatype, and a numeric alias. Every later DATA message refers to that metric by alias only. Decode a DATA message in isolation and all you have is `alias 3 = 71.2` with no idea what metric 3 is. The decoder's core job is to hold the alias table from BIRTH and resolve DATA against it. That state requirement is exactly why this is a bridge with memory, not a stateless receiver. ### Sparkplug B primer Topics follow `spBv1.0/{group}/{message_type}/{edge_node}/{device?}`. The message types that carry telemetry: | Type | Meaning | | --- | --- | | `NBIRTH` | Edge node online; advertises node metrics with aliases. | | `DBIRTH` | Device online under a node; advertises device metrics. | | `NDATA` / `DDATA` | Metric updates, by alias only. | | `DDEATH` | Device gone. | | `NDEATH` | Edge node gone - delivered as the MQTT Last Will. | | `NCMD` / `DCMD` | Commands (control, not telemetry - ignored here). | Two rules are load-bearing: - **BIRTH before DATA.** You cannot resolve a DATA alias without the BIRTH that defined it. A consumer that starts mid-stream must wait for the next BIRTH (or, as a host application, request a rebirth). - **Sequence numbers.** Every payload from an edge node carries a `seq` field, 0-255, incremented on each message and wrapping at 256. NBIRTH resets it to 0. A value other than `(previous + 1) mod 256` means messages were lost between the edge node and you. ### Decoder state machine ```text NBIRTH DBIRTH ────────────────► edge node ────────────────► device alive (reset seq, store alive, (store device (resolve DDATA node aliases) seq=0 aliases) against aliases) ▲ │ │ NDEATH (Last Will) DDATA ────────┘ (check seq; │ gap -> counter) edge node dead ◄────────────── device dead ◄──── DDEATH ``` On NBIRTH the decoder resets the edge node's sequence counter, stores its metric aliases, and clears any prior device state (a node rebirth invalidates it). DBIRTH stores per-device aliases. DDATA resolves each alias and records the value; an unresolved alias is counted, not guessed. DDEATH and NDEATH mark the device or node dead and emit a lifecycle event. ### Resolve aliases from BIRTH The alias table is the heart of the decoder. Build it from the BIRTH metrics, which carry name, datatype, and alias together: ```python def defs_from_birth(payload): defs = {} for m in payload.metrics: if m.HasField("alias"): defs[m.alias] = MetricDef(name=m.name, datatype=m.datatype) return defs ``` Then on DDATA, look each alias up and record the resolved metric; if the alias is unknown, count it rather than emitting a mystery series: ```python definition = state.resolve(group, edge_node, device, metric.alias) if definition is None: tel.count_unresolved(attrs) # alias_unresolved_total continue tel.record(definition.name, value, definition.datatype in INT_TYPES, attrs) ``` A steady stream of `alias_unresolved_total` is the signal that the decoder is seeing DATA without the matching BIRTH - usually a consumer that started after the edge node, or a missed BIRTH. ### Detect sequence gaps The `seq` counter is per edge node and spans the node's own messages and all its devices'. Check continuity with a wrap-aware comparison: ```python def check_seq(self, group, edge_node, seq): node = self._node(group, edge_node) gap = node.last_seq is not None and seq != (node.last_seq + 1) % 256 node.last_seq = seq return gap ``` A gap increments `sparkplug.decoder.seq_gap_total`. Because the counter carries the asset attributes, you can see which edge node or device is losing messages, which usually points at the network between the edge node and the broker, not at the decoder. ### Map Sparkplug datatypes to OTel instruments Sparkplug metric sets are runtime-defined by BIRTH, so instruments are created on first sight rather than from static config. The kind is inferred from the datatype and the metric name: | Sparkplug datatype | OTel instrument | Notes | | --- | --- | --- | | Double, Float | gauge | Current value. | | Boolean | gauge (0/1) | Booleans render as a 0/1 gauge. | | Int (monotonic name) | observable counter | `*Counter`, `*Total`, `Throughput`. | | Int (other) | gauge | Non-cumulative integers. | Sparkplug does not flag which integers are monotonic counters, so the decoder infers it from the metric name and exposes an override list. The tradeoff of dynamic creation is cardinality: a BIRTH that advertises hundreds of metrics creates hundreds of instruments. An allowlist in config is the mitigation when a plant publishes more than you want to store. ### Emit lifecycle as events, not spans BIRTH and DEATH are state transitions, not operations with a duration, so they map to OTel log records rather than spans: ```python # device online -> INFO, device offline / edge node offline -> WARN bridge_log.warning("edge node offline", extra=asset_attributes) ``` NDEATH is special: it is the MQTT Last Will the edge node registered at connect, so the broker publishes it even when the node drops ungracefully. That makes "edge node offline" a reliable event you can alert on, without the decoder polling for liveness. ### Resource attributes The Sparkplug topology maps onto the [IoT resource schema](./index.md): the group is the site, the edge node is the parent asset, and each device is an asset under it. | Attribute | Source | Example | | --- | --- | --- | | `service.name` | decoder | `sparkplug-decoder` | | `site.id` | Sparkplug group | `FactoryA` | | `fleet.id` | resource | `factory-floor` | | `asset.id` | device | `Machine1` | | `asset.type` | fixed | `sparkplug_device` | | `asset.parent_id` | edge node | `EdgeNode1` | Hierarchy is expressed with `asset.parent_id` chains, not ad-hoc grouping attributes - the device points at its edge node, and a deeper topology just adds links. ### Why this isn't a Collector receiver today The [track's end state](./index.md) is an `mqttreceiver` paired with protocol-specific processors; for Sparkplug that processor is the piece holding the alias and sequence state. The decoder here is the working stand-in and the reference for that proposal - alias resolution, sequence tracking, and dynamic instrument creation are the parts that would move upstream. ### Troubleshooting - **Every alias is unresolved.** The decoder started after the edge node birthed and is seeing DATA only. Ensure the consumer subscribes before the publisher births (the example gates the simulator on decoder readiness), or run a host application that requests a rebirth. - **A counter looks like a sawtooth.** A monotonic metric was mapped as a gauge. Add its name to the monotonic-name list so it exports as a Sum. - **`seq_gap_total` climbing steadily.** Real message loss between the edge node and the broker, or two publishers sharing one edge-node id and interleaving their sequence numbers. - **No NDEATH on an unplugged device.** The edge node did not register a Last Will at connect. NDEATH is an MQTT LWT, not something the decoder can synthesize. - **Nothing reaches Scout.** Confirm the Collector picked up the four `SCOUT_*` values; the debug exporter prints to stdout regardless, which separates a decode problem from an export problem. ### Related guides - [IoT & Edge overview](./index.md) - the resource attribute conventions every IoT example follows. - [MQTT trace propagation](./mqtt-trace-propagation.md) - the broker pattern this example reuses, for trace context rather than Sparkplug. - [OPC-UA bridge](./opcua.md) - the other industrial-protocol bridge in this track; compare when choosing between OPC-UA and Sparkplug. - [Scout exporter wiring](../collector-setup/scout-exporter.md) - the `oauth2client` extension and `otlp_http/b14` exporter used here. --- ## Android Instrumentation - Native Kotlin RUM with scout-android ## Android `scout-android` is a native Kotlin SDK that ships **zero-config OpenTelemetry RUM** for Android. One `Scout.initialize(...)` call auto-captures the full Real User Monitoring event set — taps, screens, crashes, ANR, jank, startup, lifecycle — and exports it as OTLP traces, metrics, and logs to a Scout collector. ```kotlin Scout.initialize( this, ScoutConfig( serviceName = "my-app", endpoint = "https://otel.example.com", ), ) ``` That's the only code you write. Every tap, screen view, crash, ANR, frozen frame, and startup is gathered automatically — no manual `Scout.track(...)` calls anywhere in your app. HTTP tracking is the one opt-in (add one OkHttp interceptor — see below). :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What You Get | Capability | Signal | Mechanism | |---|---|---| | Screen / navigation | `screen_view` (long-lived **root span**) + `screen_load` + `view_session` | `ActivityLifecycleCallbacks` (250 ms post-resume debounce); Compose via `NavController.trackScoutScreens()`. Root span is resurrected on the next launch if the process dies mid-screen | | App startup | `app_startup` span with `app_startup.type = cold \| warm` | Cold: `Process.getStartUptimeMillis()` → first resume. Warm: `onStart` | | FBC vital (First Build Complete) | `app_vital` span with `vital.name = fbc` | Emitted from cold start; ready as a first-class dashboard vital | | INV vital (Interaction → Next View) | `app_vital` span with `vital.name = inv` | Tap timestamp correlated with the next `screen_view` within 5 s | | Lifecycle | `app_lifecycle.changed` (`device.app.lifecycle.resumed` / `.paused`) | `ProcessLifecycleOwner`; also drives session foreground/background | | Tap tracking | `user_interaction` span (`ui.type = tap`, target, name source, x/y) | `Window.Callback` wrap intercepting `ACTION_UP`. Label resolved from Compose semantics (contentDescription / text / testTag) or the View tree (contentDescription → resource id → `TextView` text → class name) | | HTTP requests | `http.request` CLIENT span with method, URL, status, duration | `ScoutOkHttpInterceptor` — **opt-in**: add it to your `OkHttpClient`. Injects a W3C `traceparent` on first-party hosts | | Errors (handled) | `error` span with `error.fingerprint`, breadcrumbs | `Scout.reportError(...)` | | JVM crashes | `app_crash` span with `error.type`, `error.stack_trace`, `error.fingerprint`, `crash.last_screen`, breadcrumbs | `Thread.setDefaultUncaughtExceptionHandler` persists synchronously; replayed on next launch | | Native crashes | `native_crash` span with signal info, registers, stack, memory map, binary images (ELF build-ids) | Custom NDK signal handler (`libscout_crash`) + `ApplicationExitInfo` (API 30+). Each OS death is reported exactly once (persisted watermark); normal exits (swipe-away, Force Stop, `exit()`) are never reported as crashes | | ANR | `anr` span with thread dump + breadcrumbs | Main-thread watchdog (`scout-anr-watchdog`, polls at `anrThresholdMs / 5`, clamped 200-1000 ms) + `ApplicationExitInfo` `REASON_ANR` post-mortem tombstone | | Jank | `long_task` (≥ `longTaskThresholdMs`) + `frozen_frame` (≥ `frozenFrameThresholdMs`) | AndroidX `JankStats` per Activity window | | Memory (opt-in) | `android.memory.usage` gauge (`By`) | `scout-metrics` thread polling every `vitalsCollectionIntervalSeconds` (60 s). Off by default (`enableMemoryMetrics`) | | CPU (opt-in) | `android.cpu.usage` gauge (`%`) | Reads `/proc/self/stat`. Off by default (`enableCpuMetrics`) | | Frame (opt-in) | `android.frame.build_time` gauge (`ms`) | Drains `FrameStats` averages. Off by default (`enableFrameMetrics`) | | Device / network context | `network.connection.type`, device attributes | `DynamicAttributes` + `DeviceResources` as resource attributes (always on) | | Logs | OTLP logs | `Scout.log*()` | | Anonymous user id | `user.anonymous_id` on every span | UUID minted on first launch, persisted | ### Prerequisites | Requirement | Version | |---|---| | `minSdkVersion` | ≥ 26 (`ApplicationExitInfo` features activate from API 30+) | | `compileSdkVersion` | 35 | | Android Gradle Plugin | ≥ 8.0 | | Gradle | ≥ 7 | | JDK | 17 | | NDK (bundled native crash handler) | 27.1.12297006 | | CMake | 3.22.1 | The native signal handler ships as a prebuilt `libscout_crash` inside the artifact for `arm64-v8a`, `x86_64`, `armeabi-v7a`, and `x86` — no NDK setup is required in your app. ### Installation `scout-android` is published on Maven Central. Add `mavenCentral()` to your repositories and the dependency to your module: ```kotlin // settings.gradle.kts dependencyResolutionManagement { repositories { google() mavenCentral() } } // app/build.gradle.kts dependencies { implementation("io.base14:scout-android:0.1.7") } ``` `scout-android` re-exports `scout-core` transitively (`api(...)`) — you do not add `scout-core` yourself. ### Initialization Initialize once, as early as possible — in your `Application.onCreate()` so the crash handler is armed and cold-start timing is anchored before the first Activity: ```kotlin import android.app.Application import io.base14.scout.android.Scout import io.base14.scout.core.ScoutConfig class MyApp : Application() { override fun onCreate() { super.onCreate() Scout.initialize( this, ScoutConfig( serviceName = "my-app", serviceVersion = "1.0.0", endpoint = "https://otel.example.com", headers = mapOf("Authorization" to "Bearer …"), ), ) } } ``` `initialize` is **idempotent** — a second call is a no-op. Read-only state is available on `Scout`: `isInitialized`, `sessionId`, `userId`, `anonymousId`. #### Screen tracking with Compose Navigation Activity screens are tracked automatically. For Compose Navigation, attach the tracker to your `NavController` so route changes emit `screen_view`: ```kotlin val navController = rememberNavController() navController.trackScoutScreens() ``` You can also set the current screen manually at any time — `Scout.setScreen("Checkout")` switches the screen tracker to manual mode. #### HTTP tracking (opt-in) HTTP is the one signal you wire up. Add `ScoutOkHttpInterceptor` to your client: ```kotlin val client = OkHttpClient.Builder() .addInterceptor(ScoutOkHttpInterceptor()) .build() ``` It emits an `http.request` span per call, skips the collector endpoint and any `ignoreUrlPatterns`, and injects a W3C `traceparent` header on hosts listed in `firstPartyHosts`. #### Setting user identity ```kotlin Scout.setUser( id = "user-123", attributes = mapOf( "email" to "jane@example.com", "plan" to "pro", ), ) // On logout: Scout.clearUser() ``` `user.id` and every attribute ride on every span until cleared. #### Setting session attributes ```kotlin Scout.setSessionAttributes(mapOf("tenant" to "acme", "ab_bucket" to "B")) Scout.clearSessionAttributes() ``` They attach to every subsequent span, metric, and log for the rest of the session, and persist until cleared. ### Configuration `ScoutConfig` is the single config object. `serviceName` and `endpoint` are the only **required** fields; everything else has a sensible default. #### Identity | Field | Type | Default | Description | |---|---|---|---| | `serviceName` | `String` | **(required)** | Logical app identifier. Used as `service.name`. Must be non-blank. | | `endpoint` | `String` | **(required)** | OTLP-HTTP collector URL. `/v1/traces`, `/v1/metrics`, `/v1/logs` are appended automatically. Must be non-blank. | | `serviceVersion` | `String?` | `null` | Maps to `service.version`. Auto-detected if null. | | `environment` | `String?` | `null` | Deployment environment (e.g. `production`). | | `headers` | `Map` | `{}` | Extra HTTP headers on every OTLP export. Use for auth. | | `resourceAttributes` | `Map` | `{}` | Extra attributes merged into every signal's `Resource`. | #### Sessions | Field | Type | Default | Description | |---|---|---|---| | `sessionSampleRate` | `Double (0-100)` | `1.0` | Percent of sessions sampled — default **1%**. Decided once per session; a sampled session sends everything (spans, metrics, logs), an unsampled one sends nothing. | | `alwaysCaptureErrors` | `Boolean` | `true` | Error / crash / ANR-class spans bypass `sessionSampleRate` and are always exported. | | `sessionTimeoutMinutes` | `Int` | `30` | Inactivity timeout before a new `session.id` is minted. | | `maxSessionDurationMinutes` | `Int` | `60` | Hard cap on session lifetime. | #### Network | Field | Type | Default | Description | |---|---|---|---| | `firstPartyHosts` | `List` | `[]` | Hosts that receive a W3C `traceparent` header. Supports exact match or `*.host` wildcards. | | `ignoreUrlPatterns` | `List` | `[]` | URL substrings excluded from HTTP tracking. | #### Thresholds | Field | Type | Default | Description | |---|---|---|---| | `anrThresholdMs` | `Long` | `5000` | Main-thread block duration that fires an `anr` span. | | `longTaskThresholdMs` | `Long` | `100` | Frame duration that qualifies as a `long_task`. | | `frozenFrameThresholdMs` | `Long` | `700` | Frame duration that qualifies as a `frozen_frame`. | #### Batching & export (applies to spans, metrics, AND logs) | Field | Type | Default | Description | |---|---|---|---| | `exportIntervalSeconds` | `Int` | `30` | One export cadence for spans, metrics, and logs (coerced ≥ 1). | | `maxExportBatchSize` | `Int` | `512` | Max items per export batch, per signal. | | `maxQueueSize` | `Int` | `2048` | Max items buffered awaiting export; overflow is dropped. | | `maxRetries` | `Int` | `0` | Delivery attempts after a failed export. Default **0 = at-most-once**. | | `metricExportIntervalSeconds` | `Int?` | `null` | Metrics-only override of `exportIntervalSeconds`. | | `vitalsCollectionIntervalSeconds` | `Int` | `60` | How often memory/CPU/frame gauges are polled (when enabled). | #### Per-metric switches The SDK ships **no metrics by default** — each gauge is opt-in. | Field | Default | Description | |---|---|---| | `enableMetrics` | `true` | Master switch for the metrics pipeline. Individual gauges still need their own switch below. | | `enableMemoryMetrics` | `false` | `android.memory.usage` gauge. | | `enableCpuMetrics` | `false` | `android.cpu.usage` gauge. | | `enableFrameMetrics` | `false` | `android.frame.build_time` gauge. | #### Auto-instrumentation toggles Every auto-instrumentation can be turned off independently. Span and log instrumentation defaults to **on**; metric collection defaults to **off** (see [Per-metric switches](#per-metric-switches)). | Toggle | Default | What you lose when `false` | |---|---|---| | `enableScreenTracking` | `true` | `screen_view` / `screen_load` / `view_session` spans. | | `enableTapTracking` | `true` | All `user_interaction` spans. | | `enableHttpTracking` | `true` | `http.request` spans from `ScoutOkHttpInterceptor`. | | `enableErrorTracking` | `true` | `error` spans — including manual `Scout.reportError(...)` calls, which become no-ops. | | `enableCrashTracking` | `true` | JVM `app_crash` + NDK `native_crash` + `ApplicationExitInfo` fallback. | | `enableAnrTracking` | `true` | `anr` spans (watchdog + tombstone). | | `enableJankTracking` | `true` | `long_task` / `frozen_frame` spans. | | `enableLifecycleTracking` | `true` | `app_lifecycle.changed` spans and the session foreground/background transitions they drive. | | `enableStartupTracking` | `true` | `app_startup` spans and the FBC vital. | | `enableLogging` | `true` | `Scout.log*()` calls become no-ops. | #### Offline buffer Offline buffering is **fully disabled by default** — nothing is written to disk, and a batch that fails to export is dropped (strict at-most-once delivery). | Field | Type | Default | Description | |---|---|---|---| | `offlineBufferEnabled` | `Boolean` | `false` | Master toggle. Persist failed batches and replay them on next `initialize()` or connectivity change. | | `maxOfflineStorageMb` | `Int` | `5` | Cap on the on-disk offline buffer. Once it is exceeded, the oldest persisted batches are pruned first (FIFO). Only active when `offlineBufferEnabled` is on. | When `offlineBufferEnabled` is on, the persisted queue is also bounded by `maxQueueSize` and `maxExportBatchSize` — the same limits the in-memory path uses. #### Diagnostics | Field | Type | Default | Description | |---|---|---|---| | `debugLogging` | `Boolean` | `false` | Print SDK-internal export logging to Logcat. Use it to confirm batches are leaving the device; leave it off in release builds. | #### Filtering — `beforeSend` ```kotlin ScoutConfig( // … beforeSend = { name, attributes -> // Mutate attributes to scrub; return false to drop the signal. attributes.remove("user.email") val isHealthCheck = (attributes["http.url"] as? String) ?.contains("/health") == true !isHealthCheck }, ) ``` `beforeSend` runs synchronously on every span / metric / log before export. It sees per-signal attributes — resource attributes (`service.name`, `os.*`, `device.*`) are not in the payload. ### Native crash setup No app-side setup is required — the JVM handler, the NDK signal handler, and the `ApplicationExitInfo` reader all install automatically inside `Scout.initialize`. #### JVM crashes A `Thread.setDefaultUncaughtExceptionHandler` (chaining any previous handler) catches uncaught exceptions on **any** thread, persists a report synchronously (`error.type`, `error.message`, `error.stack_trace`, `error.fingerprint`, `crash.last_screen`, breadcrumbs) before the process dies, and replays it as an `app_crash` span on the **next launch**. #### Native (NDK) crashes A custom in-process signal handler (`libscout_crash`) catches SIGSEGV / SIGABRT / SIGBUS / SIGILL / SIGFPE, writes a compact report to `cacheDir` (signal info, registers, stack, memory map, binary images with ELF build-ids), and emits it as a `native_crash` span on the next launch. #### ApplicationExitInfo fallback (API 30+) On Android 11+, scout-android reads `ActivityManager.getHistoricalProcessExitReasons` and emits a span for any OS-recorded death newer than a persisted watermark — **each death exactly once across launches**. `REASON_CRASH_NATIVE` → `native_crash`, `REASON_CRASH` → `app_crash`, `REASON_ANR` → `anr` (with a tombstone thread dump, capped at 128 KB). Benign exits (`user_requested`, `user_stopped`, `exit_self`) are filtered out. This catches deaths the OS killed before in-process handlers could run (OOM, hard watchdog). Because crashes drain on the **next** launch, to test: trigger a real fault, relaunch the app, then check the collector. ### Manual API Every method is `@JvmStatic` and a no-op if the SDK is not initialized. | Method | Purpose | |---|---| | `setScreen(name)` | Set the current screen (switches to manual mode). | | `setUser(id, attributes = {})` / `setUserAttributes(attributes)` / `clearUser()` | User identity. | | `setAccount(id, name = null)` / `clearAccount()` | Account / org context. | | `setFeatureFlag(name, value)` / `clearFeatureFlags()` | Feature-flag values. | | `setSessionAttributes(attributes)` / `clearSessionAttributes()` | Session attributes. | | `addBreadcrumb(type, message)` / `setBreadcrumbs(list)` | Breadcrumb trail. | | `reportError(throwable, handled = true)` | Report an error from a `Throwable` (`error` span). | | `reportError(type, message, stackTrace)` | Report an error from string fields. | | `logDebug / logInfo / logWarning / logError(message, attributes = {})` | Emit a log at that level. | | `log(level, message, attributes = {})` | Emit a log at an explicit `ScoutLogLevel`. | | `logEvent(name, attributes = {})` | Emit a named custom event. | | `addTiming(name)` | Record a named timing marker. | | `startVital(name)` / `endVital(name, description = null)` | Custom vital measurement. | | `recordOperationStep(name, step, key = null, failureReason = null)` | Step in a multi-step operation. | | `reportHttp(method, url, statusCode, startEpochNanos, endEpochNanos)` | Manually emit an `http.request` span. | | `reportLongTask(durationMs)` | Manually emit a `long_task` span. | | `reportTap(target, targetType, x, y)` | Manually emit a `user_interaction` span. | | `emitGauge(name, value, unit)` | Emit a custom gauge metric. | | `recordScreenLoad(name, durationMs)` / `recordViewSession(name, durationMs)` | Timing spans. | | `recordSpan(name, durationMs, attributes = {})` | Emit an arbitrary named span. | ### What happens when export fails Delivery is **at-most-once by default** (`maxRetries = 0`): a batch gets one attempt, and a failed batch is dropped rather than risking a duplicate delivery. A retried timeout whose first request the collector already ingested would store the same events twice. A batch counts as delivered only on an HTTP 2xx. Any other status, or a transport exception, is a failure. | Failure | What Scout does (defaults) | |---|---| | Any export failure, `maxRetries = 0` (default) | One attempt; batch dropped. No duplicates, ever. | | `maxRetries = n` configured | Up to `n + 1` attempts total, retried back-to-back with no backoff. Duplicate risk on ambiguous failures. | | Failure with `offlineBufferEnabled = true` | Batch persisted to `cacheDir` and replayed on a later launch. | | Queue overflow (`maxQueueSize`, default 2048) | Oldest items dropped before they are ever exported. | | Process dies mid-interval | Anything emitted since the last export is lost — there is no flush-on-background hook. Crash evidence is the exception: it is persisted synchronously at crash time and replayed on the next launch. | Set `debugLogging = true` to print each batch's destination and HTTP status to Logcat. ### Troubleshooting | Symptom | Likely cause + fix | |---|---| | No `http.request` spans | HTTP is opt-in — add `ScoutOkHttpInterceptor` to your `OkHttpClient`. | | `native_crash` / `app_crash` not appearing after a crash | Crashes drain on the *next* launch. Relaunch the app, then check the collector. | | Android `native_crash` empty on API < 30 | `ApplicationExitInfo` requires API 30+. Older devices only get whatever the in-process NDK handler caught. | | Crash button gives a graceful shutdown | You're calling `exit()`, which no crash reporter intercepts. Trigger a real fault (uncaught exception, or a native null-deref). | | Compose screens not tracked | Attach `NavController.trackScoutScreens()`, or call `Scout.setScreen(...)` manually. | | Tap labels are class names | The tapped widget has no `contentDescription` / `testTag` / text to resolve a friendlier name. Add a `contentDescription` or `Modifier.testTag(...)`. | | Requests not getting `traceparent` | The host isn't in `firstPartyHosts`. Add it (`api.example.com`) or a wildcard (`*.example.com`). | | No telemetry at all | Set `debugLogging = true` to print export attempts and their HTTP status to Logcat, then confirm the endpoint is reachable from the device. Remember the default `sessionSampleRate` is **1%**. | ### Performance considerations - **Unified 30 s batching.** Spans, metrics, and logs each flush once per `exportIntervalSeconds` (default 30 s). - **No metrics unless enabled.** The default configuration ships zero metric data points; the memory / CPU / frame gauges are opt-ins. - **Zero disk usage by default.** Offline buffering is off; the only disk writes are crash evidence. - **Sampling.** `sessionSampleRate` drops *full sessions* — never individual events — so session traces stay coherent. - **Idempotent init.** A second `initialize` is a no-op. ### Security considerations - **PII scrubbing.** Use `beforeSend` to mutate attributes (`attributes.remove("user.email")`) or drop signals (return `false`). - **Custom headers for auth.** Pass `headers = mapOf("Authorization" to "Bearer …")`. - **No telemetry-to-disk PII by default.** The offline buffer is off; when enabled, scrub in `beforeSend` before batches hit disk. ### FAQ #### Does scout-android require the NDK in my app? No. The native crash handler ships prebuilt for all four ABIs inside the artifact. #### Will init block app startup? `Scout.initialize` does its work inline but is lightweight; call it in `Application.onCreate()`. Instrumentation runs on background threads. #### Can I add custom spans, metrics, or logs? Yes — `recordSpan`, `emitGauge`, and `log*` are the manual entry points. They go through the same sampling / export pipeline. #### Does it work with Java-only apps? Yes — every method is `@JvmStatic`; call `Scout.initialize(this, config)` from Java the same way. ### What's next - [Configure your collector](/instrument/collector-setup/docker-compose-example/) to receive OTLP-HTTP on `:4318` - Instrument [iOS](/instrument/mobile/ios) for the Swift counterpart, or [Kotlin Multiplatform](/instrument/mobile/kotlin-multiplatform) to cover both from shared code - Ship [Flutter](/instrument/mobile/flutter) apps on the same backend ### References - scout-kotlin-multiplatform repo: [github.com/base-14/scout-kotlin-multiplatform](https://github.com/base-14/scout-kotlin-multiplatform) - Android ApplicationExitInfo: [developer.android.com/reference/android/app/ApplicationExitInfo](https://developer.android.com/reference/android/app/ApplicationExitInfo) - AndroidX JankStats: [developer.android.com/reference/androidx/metrics/performance/JankStats](https://developer.android.com/reference/androidx/metrics/performance/JankStats) --- ## Flutter RUM with Flutterific OpenTelemetry Full Real User Monitoring (RUM) for Flutter apps using OpenTelemetry. Traces and metrics are exported to any OTLP-compatible collector endpoint. Attribute names follow [OTel semantic conventions](https://opentelemetry.io/docs/specs/semconv/). :::tip TL;DR Add `flutterrific_opentelemetry`, create a `lib/otel/` directory with the files below, wrap your `main.dart`, and you get automatic session, device, navigation, cold start, jank, ANR, breadcrumbs, battery-aware sampling, W3C trace propagation, and flush-on-background telemetry on every span. ::: :::info Looking for the manual SDK approach? If you prefer lower-level control with the `opentelemetry` Dart SDK, see the [Flutter OpenTelemetry guide](./flutter.md). ::: :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### Architecture ![Flutter RUM Architecture](/img/docs/flutter-rum-architecture.png) Mobile devices send OTLP telemetry through a load balancer / API gateway (with authentication and rate limiting) to an OTel collector (with server-side sampling), which forwards to Scout. ### What You Get | Signal | Span / Metric | Automatic? | | :--- | :--- | :--- | | Session | `session.id`, `session.start`, `session.duration_ms` on **every** span | Yes | | Device | `device.model.identifier`, `device.model.name`, `device.manufacturer`, `device.id` | Yes | | Battery | `device.battery.level`, `device.battery.state` on **every** span | Yes | | App | `service.version`, `app.build_id`, `app.installation.id`, `service.name` | Yes | | Network | `network.type` (wifi / cellular / ethernet / none) - live updates | Yes | | Current Screen | `app.screen.name` on **every** span | Yes | | Cold Start | `app.cold_start` span + `app.cold_start_ms` histogram | Yes | | Screen Load | `screen.load` span + `screen.load_time_ms` histogram | Yes | | Screen Dwell | `screen.dwell` span + `screen.dwell_time_ms` histogram | Yes | | Navigation | `navigation.push` / `pop` / `replace` / `remove` spans | Yes | | Breadcrumbs | Last 20 user actions attached to error spans as `error.breadcrumbs` | Yes | | App Lifecycle | `app_lifecycle.changed` spans (active, inactive, paused, etc.) | Yes | | Jank / ANR | `jank.frame` spans + `anr.detected` spans + counters + histograms | Yes | | Flutter Errors | Error spans with screen context, session ID, and breadcrumbs | Yes | | Flush on Background | Pending spans flushed when app enters background | Yes | | Battery-Aware Sampling | Reduces telemetry when battery is low (50% at 10–20%, 20% below 10%) | Yes | | W3C Trace Context | `traceparent` header injected on all HTTP requests | Yes | | Error Boundary | Catches render-time errors with retry UI + `error_boundary.caught` span | Manual | | User Identity | `enduser.id`, `enduser.email`, `enduser.role` on all spans (when set) | Manual | | Button Clicks | `interaction.*.click` spans | Manual | | List Selections | `interaction.*.list_selection` spans | Manual | | Rage Clicks | `rage_click.detected` spans + `rage_click.count` counter | Manual | | Custom Events | `custom_event.*` spans | Manual | | HTTP Requests | `http.*` spans with URL, status code, size, traceparent | Manual | ### Add Dependencies ```yaml title="pubspec.yaml" dependencies: flutterrific_opentelemetry: ^0.3.2 device_info_plus: ^11.0.0 package_info_plus: ^8.0.0 connectivity_plus: ^6.0.0 battery_plus: ^6.0.0 ``` ```bash flutter pub get ``` ### Create the `lib/otel/` Directory All instrumentation code lives in `lib/otel/`. Create these files: #### `rum_session.dart` - Central RUM State Singleton that holds session, user, device, app, screen, network, battery, and breadcrumb context. Every span gets a snapshot of this state via `getCommonAttributes()`. Attribute names follow OTel semantic conventions: - [session.*](https://opentelemetry.io/docs/specs/semconv/general/session/) - [device.*](https://opentelemetry.io/docs/specs/semconv/resource/device/) - [app.*](https://opentelemetry.io/docs/specs/semconv/registry/attributes/app/) ```dart title="lib/otel/rum_session.dart" import 'dart:async'; import 'dart:convert'; import 'dart:io'; import 'dart:math'; import 'package:battery_plus/battery_plus.dart'; import 'package:connectivity_plus/connectivity_plus.dart'; import 'package:device_info_plus/device_info_plus.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; import 'package:package_info_plus/package_info_plus.dart'; class RumSession { RumSession._(); static final RumSession instance = RumSession._(); // --- Session (semconv: session.*) --- String sessionId = 'pending'; DateTime sessionStart = DateTime.now(); // --- User --- String? _userId; String? _userEmail; String? _userRole; // --- Current Screen (semconv: app.screen.*) --- String _currentScreen = '/'; DateTime _screenEnteredAt = DateTime.now(); // --- Device (semconv: device.*) --- String _deviceModelIdentifier = 'unknown'; String _deviceModelName = 'unknown'; String _deviceManufacturer = 'unknown'; String _deviceId = 'unknown'; // --- App (semconv: app.*, service.*) --- String _appVersion = 'unknown'; String _appBuildId = 'unknown'; String _appPackageName = 'unknown'; String _appInstallationId = 'unknown'; // --- Network --- String _networkType = 'unknown'; StreamSubscription>? _connectivitySub; // --- Cold Start --- Duration? coldStartDuration; // --- Breadcrumbs --- static const int _maxBreadcrumbs = 20; final List> _breadcrumbs = []; // --- Battery --- final Battery _battery = Battery(); int _batteryLevel = 100; String _batteryState = 'unknown'; StreamSubscription? _batterySub; bool _forceSample = false; final Random _random = Random(); Future initialize() async { sessionId = DateTime.now().microsecondsSinceEpoch.toRadixString(36); sessionStart = DateTime.now(); await _loadDeviceInfo(); await _loadPackageInfo(); await _initConnectivity(); await _initBattery(); } // --- User identification API --- void setUser({String? id, String? email, String? role}) { _userId = id; _userEmail = email; _userRole = role; } void clearUser() { _userId = null; _userEmail = null; _userRole = null; } // --- Screen tracking --- void setCurrentScreen(String screen) { _currentScreen = screen; _screenEnteredAt = DateTime.now(); } String get currentScreen => _currentScreen; Duration get currentScreenDwellTime => DateTime.now().difference(_screenEnteredAt); // --- Breadcrumb API --- /// Records a breadcrumb. Keeps the last [_maxBreadcrumbs] entries (FIFO). void recordBreadcrumb(String type, String label, [Map? data]) { final crumb = { 'ts': DateTime.now().toIso8601String(), 'type': type, 'label': label, }; if (data != null) crumb.addAll(data); _breadcrumbs.add(crumb); if (_breadcrumbs.length > _maxBreadcrumbs) { _breadcrumbs.removeAt(0); } } /// Returns JSON-encoded breadcrumb list for attaching to error spans. String getBreadcrumbString() => jsonEncode(_breadcrumbs); // --- Battery-aware sampling --- /// Returns true if this span should be sampled based on battery level. /// Error spans should call [forceNextSample] beforehand to guarantee capture. bool shouldSample() { if (_forceSample) { _forceSample = false; return true; } if (_batteryState == 'charging' || _batteryLevel > 20) { return true; // 100% sampling } if (_batteryLevel > 10) { return _random.nextDouble() < 0.5; // 50% sampling } return _random.nextDouble() < 0.2; // 20% sampling } /// Ensures the next call to [shouldSample] returns true. void forceNextSample() => _forceSample = true; /// Refreshes battery level on demand (e.g. when app resumes). Future refreshBatteryState() async { _batteryLevel = await _battery.batteryLevel; } // --- Common attributes for every span (OTel semconv) --- Attributes getCommonAttributes() { final map = { // Session - semconv: session.* 'session.id': sessionId, 'session.start': sessionStart.toIso8601String(), 'session.duration_ms': DateTime.now().difference(sessionStart).inMilliseconds, // Current screen - semconv: app.screen.* 'app.screen.name': _currentScreen, // Device - semconv: device.* 'device.model.identifier': _deviceModelIdentifier, 'device.model.name': _deviceModelName, 'device.manufacturer': _deviceManufacturer, 'device.id': _deviceId, 'os.type': Platform.operatingSystem, 'os.version': Platform.operatingSystemVersion, // App - semconv: app.*, service.* 'service.version': _appVersion, 'app.build_id': _appBuildId, 'app.installation.id': _appInstallationId, 'service.name': _appPackageName, // Network 'network.type': _networkType, // Battery 'device.battery.level': _batteryLevel, 'device.battery.state': _batteryState, }; if (_userId != null) map['enduser.id'] = _userId!; if (_userEmail != null) map['enduser.email'] = _userEmail!; if (_userRole != null) map['enduser.role'] = _userRole!; if (coldStartDuration != null) { map['app.cold_start_ms'] = coldStartDuration!.inMilliseconds; } return map.toAttributes(); } Future _loadDeviceInfo() async { final deviceInfo = DeviceInfoPlugin(); if (Platform.isAndroid) { final android = await deviceInfo.androidInfo; _deviceModelIdentifier = android.model; _deviceModelName = android.model; _deviceManufacturer = android.manufacturer; _deviceId = android.id; _appInstallationId = android.id; } else if (Platform.isIOS) { final ios = await deviceInfo.iosInfo; _deviceModelIdentifier = ios.utsname.machine; _deviceModelName = ios.name; _deviceManufacturer = 'Apple'; _deviceId = ios.identifierForVendor ?? 'unknown'; _appInstallationId = ios.identifierForVendor ?? 'unknown'; } } Future _loadPackageInfo() async { final info = await PackageInfo.fromPlatform(); _appVersion = info.version; _appBuildId = info.buildNumber; _appPackageName = info.packageName; } Future _initConnectivity() async { final connectivity = Connectivity(); final results = await connectivity.checkConnectivity(); _updateNetworkType(results); _connectivitySub = connectivity.onConnectivityChanged.listen(_updateNetworkType); } void _updateNetworkType(List results) { if (results.contains(ConnectivityResult.wifi)) { _networkType = 'wifi'; } else if (results.contains(ConnectivityResult.mobile)) { _networkType = 'cellular'; } else if (results.contains(ConnectivityResult.ethernet)) { _networkType = 'ethernet'; } else if (results.contains(ConnectivityResult.none)) { _networkType = 'none'; } else { _networkType = 'other'; } } Future _initBattery() async { try { _batteryLevel = await _battery.batteryLevel; final state = await _battery.batteryState; _updateBatteryState(state); _batterySub = _battery.onBatteryStateChanged.listen(_updateBatteryState); } catch (_) { // Battery info unavailable (e.g. emulator) - keep defaults. } } void _updateBatteryState(BatteryState state) { switch (state) { case BatteryState.charging: _batteryState = 'charging'; case BatteryState.discharging: _batteryState = 'discharging'; case BatteryState.full: _batteryState = 'full'; case BatteryState.connectedNotCharging: _batteryState = 'connected_not_charging'; case BatteryState.unknown: _batteryState = 'unknown'; } } void dispose() { _connectivitySub?.cancel(); _batterySub?.cancel(); } } ``` #### `rum_span_processor.dart` - Span Enrichment + Battery-Aware Sampling Wraps the real `BatchSpanProcessor` and injects RUM context into **every** span at `onStart`. Also implements battery-aware sampling: when battery is low, non-error spans may be dropped to conserve power. | Battery State | Sampling Rate | | :--- | :--- | | Charging or above 20% | 100% | | 10–20% | 50% | | Below 10% | 20% | | Error spans | Always 100% (use `forceNextSample()`) | ```dart title="lib/otel/rum_span_processor.dart" // ignore: depend_on_referenced_packages import 'package:dartastic_opentelemetry/dartastic_opentelemetry.dart' as sdk; // ignore: depend_on_referenced_packages import 'package:dartastic_opentelemetry_api/dartastic_opentelemetry_api.dart'; import 'rum_session.dart'; class RumSpanProcessor implements sdk.SpanProcessor { RumSpanProcessor(this._delegate); final sdk.SpanProcessor _delegate; final Set _droppedSpans = {}; @override Future onStart(sdk.Span span, Context? parentContext) async { // Battery-aware sampling - drop non-essential spans when battery is low. if (!RumSession.instance.shouldSample()) { _droppedSpans.add(span.hashCode); return; } final rumAttributes = RumSession.instance.getCommonAttributes(); span.addAttributes(rumAttributes); return _delegate.onStart(span, parentContext); } @override Future onEnd(sdk.Span span) { if (_droppedSpans.remove(span.hashCode)) { return Future.value(); } return _delegate.onEnd(span); } @override Future onNameUpdate(sdk.Span span, String newName) => _delegate.onNameUpdate(span, newName); @override Future shutdown() => _delegate.shutdown(); @override Future forceFlush() => _delegate.forceFlush(); } ``` #### `rum_route_observer.dart` - Navigation + Screen Load/Dwell + Breadcrumbs Attach to `MaterialApp.navigatorObservers`. Automatically tracks: - `navigation.push` / `pop` / `replace` / `remove` spans with route names - `screen.load` - time from `Navigator.push` to first frame rendered - `screen.dwell` - time user spent on each screen - **Breadcrumbs** - records every navigation event for crash context ```dart title="lib/otel/rum_route_observer.dart" import 'package:flutter/scheduler.dart'; import 'package:flutter/widgets.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; import 'rum_session.dart'; class RumRouteObserver extends NavigatorObserver { final _tracer = FlutterOTel.tracer; final Map _screenPushTimes = {}; final Map _dwellStartTimes = {}; @override void didPush(Route route, Route? previousRoute) { final routeName = route.settings.name ?? 'unknown'; final previousName = previousRoute?.settings.name; _endDwellSpan(previousName); RumSession.instance.setCurrentScreen(routeName); RumSession.instance.recordBreadcrumb('navigation', 'push $routeName'); _screenPushTimes[routeName] = DateTime.now(); final span = _tracer.startSpan('navigation.push'); span.setStringAttribute('app.navigation.action', 'push'); span.setStringAttribute('app.screen.name', routeName); if (previousName != null) { span.setStringAttribute( 'app.screen.previous_name', previousName); } span.end(); _startDwellTracking(routeName); SchedulerBinding.instance.addPostFrameCallback((_) { _recordScreenLoadTime(routeName); }); } @override void didPop(Route route, Route? previousRoute) { final routeName = route.settings.name ?? 'unknown'; final previousName = previousRoute?.settings.name; _endDwellSpan(routeName); _screenPushTimes.remove(routeName); RumSession.instance.recordBreadcrumb('navigation', 'pop $routeName'); if (previousName != null) { RumSession.instance.setCurrentScreen(previousName); _startDwellTracking(previousName); } final span = _tracer.startSpan('navigation.pop'); span.setStringAttribute('app.navigation.action', 'pop'); span.setStringAttribute('app.screen.name', routeName); if (previousName != null) { span.setStringAttribute( 'app.screen.previous_name', previousName); } span.end(); } @override void didReplace({Route? newRoute, Route? oldRoute}) { final oldName = oldRoute?.settings.name; final newName = newRoute?.settings.name ?? 'unknown'; _endDwellSpan(oldName); RumSession.instance.setCurrentScreen(newName); _startDwellTracking(newName); RumSession.instance.recordBreadcrumb('navigation', 'replace to $newName'); final span = _tracer.startSpan('navigation.replace'); span.setStringAttribute('app.navigation.action', 'replace'); span.setStringAttribute('app.screen.name', newName); if (oldName != null) { span.setStringAttribute('app.screen.previous_name', oldName); } span.end(); } @override void didRemove(Route route, Route? previousRoute) { final routeName = route.settings.name ?? 'unknown'; _endDwellSpan(routeName); final span = _tracer.startSpan('navigation.remove'); span.setStringAttribute('app.navigation.action', 'remove'); span.setStringAttribute('app.screen.name', routeName); span.end(); } void _startDwellTracking(String routeName) { _dwellStartTimes[routeName] = DateTime.now(); } void _endDwellSpan(String? routeName) { if (routeName == null) return; final startTime = _dwellStartTimes.remove(routeName); if (startTime == null) return; final dwellMs = DateTime.now().difference(startTime).inMilliseconds; final span = _tracer.startSpan('screen.dwell'); span.setStringAttribute('app.screen.name', routeName); span.setIntAttribute('app.screen.dwell_time_ms', dwellMs); span.end(); FlutterOTel.meter(name: 'rum.screen') .createHistogram( name: 'screen.dwell_time_ms', unit: 'ms', description: 'Time user spent on screen', ) .record(dwellMs.toDouble()); } void _recordScreenLoadTime(String routeName) { final pushTime = _screenPushTimes[routeName]; if (pushTime == null) return; final loadMs = DateTime.now().difference(pushTime).inMilliseconds; final span = _tracer.startSpan('screen.load'); span.setStringAttribute('app.screen.name', routeName); span.setIntAttribute('app.screen.load_time_ms', loadMs); span.end(); FlutterOTel.meter(name: 'rum.screen') .createHistogram( name: 'screen.load_time_ms', unit: 'ms', description: 'Time from navigation push to first frame rendered', ) .record(loadMs.toDouble()); } } ``` #### `rum_cold_start.dart` - Startup Time Measures time from `main()` entry to the first frame painted on screen. ```dart title="lib/otel/rum_cold_start.dart" import 'package:flutter/scheduler.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; import 'rum_session.dart'; class RumColdStart { RumColdStart._(); static DateTime? _mainStartTime; /// Call as the VERY FIRST line in main(). static void markMainStart() { _mainStartTime = DateTime.now(); } /// Call after runApp(). Schedules a post-frame callback to measure total /// cold start duration and emit a span + metric. static void measureFirstFrame() { if (_mainStartTime == null) return; SchedulerBinding.instance.addPostFrameCallback((_) { final duration = DateTime.now().difference(_mainStartTime!); RumSession.instance.coldStartDuration = duration; final tracer = FlutterOTel.tracer; final span = tracer.startSpan('app.cold_start'); span.setIntAttribute('app.cold_start_ms', duration.inMilliseconds); span.setStringAttribute('app.start_type', 'cold'); span.end(); FlutterOTel.meter(name: 'rum.app') .createHistogram( name: 'app.cold_start_ms', unit: 'ms', description: 'Time from main() to first frame rendered', ) .record(duration.inMilliseconds.toDouble()); }); } } ``` #### `jank_detector.dart` - Frame Jank + ANR Detection Monitors every frame for jank (above 16 ms) and runs a background isolate watchdog for ANR (main thread blocked over 5 s). ```dart title="lib/otel/jank_detector.dart" import 'dart:async'; import 'dart:isolate'; // ignore: depend_on_referenced_packages import 'package:dartastic_opentelemetry_api/dartastic_opentelemetry_api.dart' as api; import 'package:flutter/scheduler.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; class JankDetector { JankDetector({ required UITracer tracer, required UIMeter meter, this.jankThresholdMs = 16.0, this.severeJankThresholdMs = 100.0, this.anrThresholdMs = 5000.0, }) : _tracer = tracer, _meter = meter; final UITracer _tracer; final UIMeter _meter; final double jankThresholdMs; final double severeJankThresholdMs; final double anrThresholdMs; late final api.APICounter _jankCounter; late final api.APICounter _severeJankCounter; late final api.APICounter _anrCounter; late final api.APIHistogram _buildDurationHistogram; late final api.APIHistogram _rasterDurationHistogram; Isolate? _watchdogIsolate; SendPort? _heartbeatPort; Timer? _heartbeatTimer; ReceivePort? _anrReceivePort; bool _paused = false; void start() { _initMetrics(); _startFrameTimingCallback(); _startAnrWatchdog(); } void stop() { _heartbeatTimer?.cancel(); _watchdogIsolate?.kill(priority: Isolate.immediate); _anrReceivePort?.close(); } void pause() { _paused = true; _heartbeatTimer?.cancel(); } void resume() { _paused = false; _startHeartbeats(); } void _initMetrics() { _jankCounter = _meter.createCounter( name: 'app.jank.count', description: 'Number of janky frames (>16ms)', ); _severeJankCounter = _meter.createCounter( name: 'app.jank.severe.count', description: 'Number of severely janky frames (>100ms)', ); _anrCounter = _meter.createCounter( name: 'app.anr.count', description: 'Number of ANR events (main thread blocked >5s)', ); _buildDurationHistogram = _meter.createHistogram( name: 'app.frame.build_duration_ms', unit: 'ms', description: 'Frame build phase duration in milliseconds', ); _rasterDurationHistogram = _meter.createHistogram( name: 'app.frame.raster_duration_ms', unit: 'ms', description: 'Frame raster phase duration in milliseconds', ); } void _startFrameTimingCallback() { SchedulerBinding.instance.addTimingsCallback((timings) { for (final timing in timings) { final buildMs = timing.buildDuration.inMicroseconds / 1000.0; final rasterMs = timing.rasterDuration.inMicroseconds / 1000.0; final totalMs = buildMs + rasterMs; _buildDurationHistogram.record(buildMs); _rasterDurationHistogram.record(rasterMs); if (totalMs > jankThresholdMs) { _jankCounter.add(1); final span = _tracer.startSpan('jank.frame'); span.setDoubleAttribute('frame.build_duration_ms', buildMs); span.setDoubleAttribute('frame.raster_duration_ms', rasterMs); span.setDoubleAttribute('frame.total_duration_ms', totalMs); if (totalMs > severeJankThresholdMs) { _severeJankCounter.add(1); span.setStringAttribute('jank.severity', 'severe'); span.setStatus(SpanStatusCode.Error, 'Severe jank detected'); } else { span.setStringAttribute('jank.severity', 'minor'); } span.end(); } } }); } Future _startAnrWatchdog() async { _anrReceivePort = ReceivePort(); _watchdogIsolate = await Isolate.spawn( _watchdogEntryPoint, _WatchdogConfig( mainSendPort: _anrReceivePort!.sendPort, anrThresholdMs: anrThresholdMs, ), ); _anrReceivePort!.listen((message) { if (message is SendPort) { _heartbeatPort = message; _startHeartbeats(); } else if (message == 'ANR') { _onAnrDetected(); } }); } void _startHeartbeats() { _heartbeatTimer?.cancel(); if (_paused) return; _heartbeatTimer = Timer.periodic( const Duration(seconds: 1), (_) => _heartbeatPort?.send('heartbeat'), ); } void _onAnrDetected() { _anrCounter.add(1); final span = _tracer.startSpan('anr.detected'); span.setDoubleAttribute('anr.threshold_ms', anrThresholdMs); span.setStatus(SpanStatusCode.Error, 'ANR: main thread unresponsive'); span.end(); FlutterOTel.reportError( 'ANR detected: main thread unresponsive for ' '>${anrThresholdMs.toInt()}ms', Exception('ANR detected'), StackTrace.current, ); } static void _watchdogEntryPoint(_WatchdogConfig config) { final receivePort = ReceivePort(); config.mainSendPort.send(receivePort.sendPort); DateTime lastHeartbeat = DateTime.now(); receivePort.listen((message) { if (message == 'heartbeat') { lastHeartbeat = DateTime.now(); } }); Timer.periodic(const Duration(seconds: 1), (_) { final elapsed = DateTime.now().difference(lastHeartbeat).inMilliseconds; if (elapsed > config.anrThresholdMs) { config.mainSendPort.send('ANR'); lastHeartbeat = DateTime.now(); } }); } } class _WatchdogConfig { const _WatchdogConfig({ required this.mainSendPort, required this.anrThresholdMs, }); final SendPort mainSendPort; final double anrThresholdMs; } ``` #### `rum_http_client.dart` - Instrumented HTTP Client + W3C Trace Context Drop-in replacement for `http.Client`. Creates OTel spans around every HTTP request and injects [W3C `traceparent`](https://www.w3.org/TR/trace-context/#traceparent-header) headers for distributed tracing. ```dart title="lib/otel/rum_http_client.dart" import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; // ignore: depend_on_referenced_packages import 'package:http/http.dart' as http; import 'rum_session.dart'; class RumHttpClient extends http.BaseClient { RumHttpClient([http.Client? inner]) : _inner = inner ?? http.Client(); final http.Client _inner; @override Future send(http.BaseRequest request) async { final tracer = FlutterOTel.tracer; final span = tracer.startSpan('http.${request.method.toLowerCase()}'); span.setStringAttribute('http.request.method', request.method); span.setStringAttribute('url.full', request.url.toString()); span.setStringAttribute('server.address', request.url.host); span.setStringAttribute('url.path', request.url.path); if (request.contentLength != null && request.contentLength! > 0) { span.setIntAttribute('http.request.body.size', request.contentLength!); } // W3C Trace Context propagation - inject traceparent header // Format: version-traceId-spanId-traceFlags (00-{32hex}-{16hex}-01) final traceId = span.spanContext.traceId.hexString; final spanId = span.spanContext.spanId.hexString; request.headers['traceparent'] = '00-$traceId-$spanId-01'; request.headers['tracestate'] = ''; // Record breadcrumb for this HTTP request RumSession.instance.recordBreadcrumb( 'http', '${request.method} ${request.url.host}${request.url.path}', ); try { final response = await _inner.send(request); span.setIntAttribute('http.response.status_code', response.statusCode); if (response.contentLength != null) { span.setIntAttribute( 'http.response.body.size', response.contentLength!); } if (response.statusCode >= 400) { span.setStatus( SpanStatusCode.Error, 'HTTP ${response.statusCode} ${response.reasonPhrase}', ); } span.end(); return response; } catch (error, stackTrace) { span.setStringAttribute( 'error.type', error.runtimeType.toString()); span.setStringAttribute('error.message', error.toString()); span.setStatus(SpanStatusCode.Error, error.toString()); FlutterOTel.reportError( 'HTTP request failed: ${request.method} ${request.url}', error, stackTrace, ); span.end(); rethrow; } } @override void close() { _inner.close(); super.close(); } } ``` #### `rum_rage_click_detector.dart` - Frustration Signal Detects rapid repeated taps on the same UI element (3+ within 2 seconds). ```dart title="lib/otel/rum_rage_click_detector.dart" import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; class RumRageClickDetector { RumRageClickDetector._(); static final RumRageClickDetector instance = RumRageClickDetector._(); static const int _rageThreshold = 3; static const Duration _rageWindow = Duration(seconds: 2); final Map> _clickHistory = {}; /// Record a tap on [elementId]. Returns true if rage click was detected. bool recordClick(String elementId) { final now = DateTime.now(); final history = _clickHistory.putIfAbsent(elementId, () => []); history.removeWhere((t) => now.difference(t) > _rageWindow); history.add(now); if (history.length >= _rageThreshold) { _emitRageClick(elementId, history.length); history.clear(); return true; } return false; } void _emitRageClick(String elementId, int clickCount) { final tracer = FlutterOTel.tracer; final span = tracer.startSpan('rage_click.detected'); span.setStringAttribute('rage_click.element_id', elementId); span.setIntAttribute('rage_click.count', clickCount); span.setIntAttribute( 'rage_click.window_ms', _rageWindow.inMilliseconds); span.setStatus( SpanStatusCode.Error, 'Rage click detected on $elementId', ); span.end(); FlutterOTel.meter(name: 'rum.interaction') .createCounter( name: 'rage_click.count', description: 'Number of rage click events detected', ) .add(1); } } ``` #### `rum_events.dart` - Custom Business Events Fire-and-forget API for custom business events. RUM context is automatically attached. ```dart title="lib/otel/rum_events.dart" import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; class RumEvents { RumEvents._(); static void logEvent(String name, {Map? attributes}) { final tracer = FlutterOTel.tracer; final span = tracer.startSpan('custom_event.$name'); span.setStringAttribute('event.name', name); span.setStringAttribute('event.domain', 'business'); if (attributes != null) { for (final entry in attributes.entries) { final value = entry.value; if (value is String) { span.setStringAttribute(entry.key, value); } else if (value is int) { span.setIntAttribute(entry.key, value); } else if (value is double) { span.setDoubleAttribute(entry.key, value); } } } span.end(); } static void logTimedEvent( String name, Duration duration, { Map? attributes, }) { final allAttrs = { 'event.duration_ms': duration.inMilliseconds, ...?attributes, }; logEvent(name, attributes: allAttrs); } } ``` #### `error_boundary_widget.dart` - Error Boundary Catches render-time errors in a subtree and shows a fallback UI with a retry button. Records an `error_boundary.caught` span with the error message, current screen, and breadcrumb trail. ```dart title="lib/otel/error_boundary_widget.dart" import 'package:flutter/material.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; import 'rum_session.dart'; class ErrorBoundaryWidget extends StatefulWidget { const ErrorBoundaryWidget({ super.key, required this.child, this.fallbackBuilder, }); final Widget child; /// Custom fallback UI builder. Receives the error and a retry callback. /// If null, a default error card with retry button is shown. final Widget Function(Object error, VoidCallback retry)? fallbackBuilder; @override State createState() => _ErrorBoundaryWidgetState(); } class _ErrorBoundaryWidgetState extends State { Object? _error; bool _hasError = false; @override Widget build(BuildContext context) { if (_hasError) { if (widget.fallbackBuilder != null) { return widget.fallbackBuilder!(_error!, _retry); } return _defaultFallback(); } return widget.child; } void handleError(Object error, StackTrace stack) { setState(() { _error = error; _hasError = true; }); final tracer = FlutterOTel.tracer; final span = tracer.startSpan('error_boundary.caught'); span.setStringAttribute( 'error.type', error.runtimeType.toString()); span.setStringAttribute('error.message', error.toString()); span.setStringAttribute( 'app.screen.name', RumSession.instance.currentScreen); span.setStringAttribute( 'error.breadcrumbs', RumSession.instance.getBreadcrumbString()); span.setStatus(SpanStatusCode.Error, error.toString()); span.end(); RumSession.instance.recordBreadcrumb( 'error', 'error_boundary caught: ${error.runtimeType}', ); } void _retry() { RumSession.instance.recordBreadcrumb('ui', 'error_boundary retry'); setState(() { _error = null; _hasError = false; }); } Widget _defaultFallback() { return Center( child: Card( margin: const EdgeInsets.all(16), child: Padding( padding: const EdgeInsets.all(24), child: Column( mainAxisSize: MainAxisSize.min, children: [ const Icon(Icons.error_outline, size: 48, color: Colors.red), const SizedBox(height: 16), const Text( 'Something went wrong', style: TextStyle(fontSize: 18, fontWeight: FontWeight.bold), ), const SizedBox(height: 8), Text( _error.toString(), style: const TextStyle(fontSize: 12, color: Colors.grey), maxLines: 3, overflow: TextOverflow.ellipsis, ), const SizedBox(height: 16), ElevatedButton.icon( onPressed: _retry, icon: const Icon(Icons.refresh), label: const Text('Retry'), ), ], ), ), ), ); } } ``` #### `otel_config.dart` - Wire Everything Together Central initialization. Call `OTelConfig.initialize()` once before `runApp()`. Replace the endpoint URLs with your OTLP collector endpoint. ```dart title="lib/otel/otel_config.dart" import 'package:flutter/widgets.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; import 'jank_detector.dart'; import 'rum_http_client.dart'; import 'rum_route_observer.dart'; import 'rum_session.dart'; import 'rum_span_processor.dart'; class OTelConfig { OTelConfig._(); static JankDetector? _jankDetector; static RumHttpClient? _httpClient; static RumSpanProcessor? _rumProcessor; /// Call once before runApp(). static Future initialize() async { WidgetsFlutterBinding.ensureInitialized(); // ── Configure your collector endpoint ────────────────────────── // Replace these with your public OTel collector URL. const traceEndpoint = String.fromEnvironment( 'OTEL_TRACE_ENDPOINT', defaultValue: 'https://otel-collector.example.com', ); const metricEndpoint = String.fromEnvironment( 'OTEL_METRIC_ENDPOINT', defaultValue: 'https://otel-collector.example.com', ); // ─────────────────────────────────────────────────────────────── // Initialize RUM session FIRST - before FlutterOTel, because // FlutterOTel.initialize() creates lifecycle spans that trigger // RumSpanProcessor, which needs RumSession to be ready. await RumSession.instance.initialize(); // Trace exporter (OTLP/HTTP) final spanExporter = OtlpHttpSpanExporter( OtlpHttpExporterConfig(endpoint: traceEndpoint), ); final batchProcessor = BatchSpanProcessor(spanExporter); // Wrap in RumSpanProcessor to enrich ALL spans with RUM context // and apply battery-aware sampling. _rumProcessor = RumSpanProcessor(batchProcessor); // Metric exporter (OTLP/gRPC) final metricExporter = OtlpGrpcMetricExporter( OtlpGrpcMetricExporterConfig( endpoint: metricEndpoint, insecure: false, // set true for non-TLS endpoints ), ); await FlutterOTel.initialize( serviceName: 'your-app-name', serviceVersion: '1.0.0', tracerName: 'your-app', spanProcessor: _rumProcessor!, metricExporter: metricExporter, enableMetrics: true, secure: true, // set false for non-TLS endpoints ); // Start jank/ANR detection. _jankDetector = JankDetector( tracer: FlutterOTel.tracer, meter: FlutterOTel.meter(name: 'jank_detector'), ); _jankDetector!.start(); // Create instrumented HTTP client. _httpClient = RumHttpClient(); } /// Attach to MaterialApp.navigatorObservers. static RumRouteObserver get routeObserver => RumRouteObserver(); static OTelLifecycleObserver get lifecycleObserver => FlutterOTel.lifecycleObserver; static OTelInteractionTracker get interactionTracker => FlutterOTel.interactionTracker; /// Use this for all HTTP requests instead of http.Client(). static RumHttpClient get httpClient => _httpClient ?? RumHttpClient(); static void pauseJankDetection() => _jankDetector?.pause(); static void resumeJankDetection() => _jankDetector?.resume(); /// Force-flush all pending spans to the collector. static Future flush() async { await _rumProcessor?.forceFlush(); } /// Flush and shut down the span processor. static Future shutdown() async { await flush(); await _rumProcessor?.shutdown(); } static void dispose() { _jankDetector?.stop(); _httpClient?.close(); RumSession.instance.dispose(); } } ``` ### Create the Instrumented Entry Point Create `lib/main_otel.dart` - a wrapper around your existing `main.dart` that adds OTel initialization, error handlers with breadcrumbs, cold start measurement, lifecycle-aware flushing, and battery refresh. ```dart title="lib/main_otel.dart" import 'dart:ui'; import 'package:flutter/material.dart'; import 'package:flutterrific_opentelemetry/flutterrific_opentelemetry.dart'; import 'main.dart'; // Your existing app import 'otel/otel_config.dart'; import 'otel/rum_cold_start.dart'; import 'otel/rum_session.dart'; Future main() async { RumColdStart.markMainStart(); // FIRST LINE - records main() entry time. // Capture Flutter framework errors with breadcrumbs + flush. FlutterError.onError = (details) { FlutterError.presentError(details); RumSession.instance.forceNextSample(); RumSession.instance.recordBreadcrumb( 'error', 'flutter_error: ${details.exceptionAsString()}', ); FlutterOTel.reportError( details.exceptionAsString(), details.exception, details.stack, attributes: { 'app.screen.name': RumSession.instance.currentScreen, 'session.id': RumSession.instance.sessionId, 'error.breadcrumbs': RumSession.instance.getBreadcrumbString(), }, ); OTelConfig.flush(); // Fire-and-forget flush for crash data. }; // Capture uncaught async errors. PlatformDispatcher.instance.onError = (error, stack) { RumSession.instance.forceNextSample(); RumSession.instance.recordBreadcrumb( 'error', 'uncaught_error: ${error.runtimeType}', ); FlutterOTel.reportError( 'Uncaught error', error, stack, attributes: { 'app.screen.name': RumSession.instance.currentScreen, 'session.id': RumSession.instance.sessionId, 'error.breadcrumbs': RumSession.instance.getBreadcrumbString(), }, ); OTelConfig.flush(); return true; }; await OTelConfig.initialize(); WidgetsBinding.instance.addObserver(OTelConfig.lifecycleObserver); // Lifecycle listener - flush on background, shutdown on exit. AppLifecycleListener( onPause: () { OTelConfig.flush(); OTelConfig.pauseJankDetection(); }, onResume: () { OTelConfig.resumeJankDetection(); RumSession.instance.refreshBatteryState(); }, onExitRequested: () async { await OTelConfig.shutdown(); return AppExitResponse.exit; }, ); runApp(const MyApp()); RumColdStart.measureFirstFrame(); } ``` Run with: ```bash flutter run --target=lib/main_otel.dart ``` ### Wire Into Your App #### Navigator Observer Add the route observer to your `MaterialApp` (or `CupertinoApp`): ```dart MaterialApp( navigatorObservers: [OTelConfig.routeObserver], // ... ) ``` #### Named Routes For screen load/dwell tracking to work, every `Navigator.push` must include a `RouteSettings` with a name: ```dart Navigator.push( context, MaterialPageRoute( settings: const RouteSettings(name: '/song_detail'), builder: (context) => const SongDetailPage(), ), ); ``` Without `RouteSettings`, the route name defaults to `'unknown'`. ### Manual Instrumentation Everything above is automatic once wired. The following are opt-in for richer telemetry. #### User Identification Call after login: ```dart RumSession.instance.setUser( id: 'user_123', email: 'user@example.com', role: 'premium', ); ``` Call on logout: ```dart RumSession.instance.clearUser(); ``` Once set, `enduser.id`, `enduser.email`, and `enduser.role` appear on every subsequent span. #### Error Boundary Wrap any widget subtree to catch render-time errors with a retry UI: ```dart ErrorBoundaryWidget( child: MyFragileWidget(), ) ``` With a custom fallback: ```dart ErrorBoundaryWidget( fallbackBuilder: (error, retry) => Column( children: [ Text('Error: $error'), TextButton(onPressed: retry, child: const Text('Try again')), ], ), child: MyFragileWidget(), ) ``` #### Breadcrumbs Breadcrumbs are recorded automatically for navigation and HTTP requests. You can also record custom breadcrumbs: ```dart RumSession.instance.recordBreadcrumb('ui', 'tapped checkout button'); RumSession.instance.recordBreadcrumb('api', 'fetched user profile', { 'user_id': '123', }); ``` The last 20 breadcrumbs are attached to every error span as a JSON array in `error.breadcrumbs`. #### Interaction Tracking Use `OTelConfig.interactionTracker` in `onPressed` / `onTap` callbacks: ```dart // Button click ElevatedButton( onPressed: () { OTelConfig.interactionTracker .trackButtonClick(context, 'checkout_button'); // ... your logic }, child: const Text('Checkout'), ) // List item selection ListView.builder( itemBuilder: (context, index) { return ListTile( onTap: () { OTelConfig.interactionTracker .trackListItemSelected(context, 'product_list', index); // ... your logic }, ); }, ) ``` #### Rage Click Detection Add alongside interaction tracking for elements users might frustration-tap: ```dart onTap: () { OTelConfig.interactionTracker .trackListItemSelected(context, 'song_list', index); RumRageClickDetector.instance.recordClick('song_card_$index'); // ... your logic } ``` #### Custom Business Events ```dart // Simple event RumEvents.logEvent('purchase_completed', attributes: { 'item.id': 'SKU-123', 'item.price': 29.99, 'payment.method': 'credit_card', }); // Timed event (e.g., how long a search took) final stopwatch = Stopwatch()..start(); final results = await searchApi(query); stopwatch.stop(); RumEvents.logTimedEvent('search_completed', stopwatch.elapsed, attributes: { 'search.query': query, 'search.result_count': results.length, }); ``` #### Instrumented HTTP Client Use `OTelConfig.httpClient` instead of `http.Client()`: ```dart final response = await OTelConfig.httpClient.get( Uri.parse('https://api.example.com/songs'), ); ``` Every request automatically gets an `http.get` (or `http.post`, etc.) span with URL, status code, response size, and a `traceparent` header for distributed tracing. RUM context is attached by the `RumSpanProcessor`. ### Configuration #### Collector Endpoint Set at build time via `--dart-define`: ```bash flutter run \ --dart-define=OTEL_TRACE_ENDPOINT=https://otel.yourcompany.com \ --dart-define=OTEL_METRIC_ENDPOINT=https://otel.yourcompany.com ``` Or hardcode in `otel_config.dart`. #### Jank Thresholds In `otel_config.dart`, customize the `JankDetector`: ```dart _jankDetector = JankDetector( tracer: FlutterOTel.tracer, meter: FlutterOTel.meter(name: 'jank_detector'), jankThresholdMs: 16.0, // Minimum frame duration to flag severeJankThresholdMs: 100.0, // Threshold for "severe" jank anrThresholdMs: 5000.0, // Main thread blocked threshold ); ``` #### Service Name Change `serviceName` and `tracerName` in `OTelConfig.initialize()`: ```dart await FlutterOTel.initialize( serviceName: 'my-flutter-app', // Appears as service.name in traces serviceVersion: '2.1.0', tracerName: 'my-flutter-app', // ... ); ``` ### Initialization Order The order matters. `RumSession.initialize()` **must** be called before `FlutterOTel.initialize()` because `FlutterOTel.initialize()` creates lifecycle spans during startup, which trigger `RumSpanProcessor.onStart()`, which calls `RumSession.instance.getCommonAttributes()`. If the session isn't ready, you get stale default values. 1. `RumColdStart.markMainStart()` - records timestamp 2. Set error handlers - catches errors during init, attaches breadcrumbs 3. `RumSession.instance.initialize()` - loads device info, network, battery, session ID 4. `FlutterOTel.initialize(...)` - creates lifecycle spans (RumSession must be ready) 5. `JankDetector.start()` - frame monitoring begins 6. `WidgetsBinding.addObserver(...)` - lifecycle observer 7. `AppLifecycleListener` - flush on background, shutdown on exit 8. `runApp(...)` - app starts 9. `RumColdStart.measureFirstFrame()` - schedules post-frame callback ### Telemetry Reference #### Spans | Span Name | Source | Key Attributes | | :--- | :--- | :--- | | `app.cold_start` | `RumColdStart` | `app.cold_start_ms`, `app.start_type` | | `navigation.push` | `RumRouteObserver` | `app.screen.name`, `app.screen.previous_name`, `app.navigation.action` | | `navigation.pop` | `RumRouteObserver` | `app.screen.name`, `app.screen.previous_name`, `app.navigation.action` | | `navigation.replace` | `RumRouteObserver` | `app.screen.name`, `app.screen.previous_name`, `app.navigation.action` | | `navigation.remove` | `RumRouteObserver` | `app.screen.name`, `app.navigation.action` | | `screen.load` | `RumRouteObserver` | `app.screen.name`, `app.screen.load_time_ms` | | `screen.dwell` | `RumRouteObserver` | `app.screen.name`, `app.screen.dwell_time_ms` | | `app_lifecycle.changed` | `OTelLifecycleObserver` | `app_lifecycle.state`, `app_lifecycle.previous_state` | | `jank.frame` | `JankDetector` | `frame.build_duration_ms`, `frame.raster_duration_ms`, `jank.severity` | | `anr.detected` | `JankDetector` | `anr.threshold_ms` | | `http.` | `RumHttpClient` | `http.request.method`, `url.full`, `http.response.status_code`, `http.response.body.size` | | `error_boundary.caught` | `ErrorBoundaryWidget` | `error.type`, `error.message`, `app.screen.name`, `error.breadcrumbs` | | `interaction.*.click` | `OTelInteractionTracker` | `interaction.target`, `interaction.type` | | `interaction.*.list_selection` | `OTelInteractionTracker` | `interaction.target`, `list_selected_index` | | `rage_click.detected` | `RumRageClickDetector` | `rage_click.element_id`, `rage_click.count` | | `custom_event.` | `RumEvents` | `event.name`, `event.domain`, custom attributes | | `error.*` | Error handlers | `app.screen.name`, `session.id`, `error.breadcrumbs` | #### Attributes on Every Span (via RumSpanProcessor) Attribute names follow [OTel semantic conventions](https://opentelemetry.io/docs/specs/semconv/). | Attribute | Semconv Source | Example Value | | :--- | :--- | :--- | | `session.id` | [session](https://opentelemetry.io/docs/specs/semconv/general/session/) | `hgbat8zso5` | | `session.start` | - | `2026-03-03T18:26:04.137259` | | `session.duration_ms` | - | `14614` | | `app.screen.name` | [app](https://opentelemetry.io/docs/specs/semconv/registry/attributes/app/) | `/song_detail` | | `device.model.identifier` | [device](https://opentelemetry.io/docs/specs/semconv/resource/device/) | `akita` | | `device.model.name` | [device](https://opentelemetry.io/docs/specs/semconv/resource/device/) | `Pixel 8a` | | `device.manufacturer` | [device](https://opentelemetry.io/docs/specs/semconv/resource/device/) | `Google` | | `device.id` | [device](https://opentelemetry.io/docs/specs/semconv/resource/device/) | `BP4A.260105.004.E1` | | `device.battery.level` | - | `78` | | `device.battery.state` | - | `discharging` | | `os.type` | - | `android` | | `os.version` | - | `15` | | `service.version` | - | `1.0.0` | | `app.build_id` | [app](https://opentelemetry.io/docs/specs/semconv/registry/attributes/app/) | `1` | | `app.installation.id` | [app](https://opentelemetry.io/docs/specs/semconv/registry/attributes/app/) | `BP4A.260105.004.E1` | | `service.name` | - | `dev.flutter.platform_design` | | `network.type` | - | `wifi` | | `app.cold_start_ms` | - | `1305` | | `enduser.id` | - | `user_123` (when set) | | `enduser.email` | - | `user@example.com` (when set) | | `enduser.role` | - | `premium` (when set) | #### Metrics | Metric Name | Type | Unit | | :--- | :--- | :--- | | `app.cold_start_ms` | Histogram | ms | | `screen.load_time_ms` | Histogram | ms | | `screen.dwell_time_ms` | Histogram | ms | | `app.jank.count` | Counter | - | | `app.jank.severe.count` | Counter | - | | `app.anr.count` | Counter | - | | `app.frame.build_duration_ms` | Histogram | ms | | `app.frame.raster_duration_ms` | Histogram | ms | | `rage_click.count` | Counter | - | ### File Structure ```text lib/ ├── main.dart # Original app (no OTel imports needed) ├── main_otel.dart # Instrumented entry point └── otel/ ├── otel_config.dart # Central initialization + flush/shutdown ├── rum_session.dart # Session/device/user/screen/network/battery/breadcrumbs ├── rum_span_processor.dart # Enriches spans + battery-aware sampling ├── rum_route_observer.dart # Navigation + screen load/dwell + breadcrumbs ├── rum_cold_start.dart # Cold start measurement ├── rum_http_client.dart # HTTP client + W3C traceparent ├── rum_rage_click_detector.dart # Frustration signal detection ├── rum_events.dart # Custom business events ├── error_boundary_widget.dart # Error boundary with retry UI └── jank_detector.dart # Frame jank + ANR detection ``` ### Quick Start Checklist - [ ] Add dependencies to `pubspec.yaml` (including `battery_plus`) and run `flutter pub get` - [ ] Copy the `lib/otel/` directory into your project - [ ] Update `otel_config.dart` with your collector endpoint and service name - [ ] Create `main_otel.dart` wrapping your existing app - [ ] Add `navigatorObservers: [OTelConfig.routeObserver]` to `MaterialApp` - [ ] Add `RouteSettings(name: '/route_name')` to all `Navigator.push` calls - [ ] Wrap fragile widgets in `ErrorBoundaryWidget` - [ ] Add `OTelConfig.interactionTracker.trackButtonClick(...)` to key buttons - [ ] Use `OTelConfig.httpClient` for all HTTP requests - [ ] Run with `flutter run --target=lib/main_otel.dart` - [ ] Verify spans in your collector/backend ### Next Steps - [Flutter Mobile Observability guide](/guides/flutter-mobile-observability/) for comparing this approach with the manual SDK - [Create Your First Dashboard](/guides/create-your-first-dashboard/) to build dashboards from your mobile telemetry data - [Troubleshooting Missing Telemetry Data](/guides/troubleshooting-missing-data/) if spans are not arriving at your collector --- ## Flutter Instrumentation - Mobile + Web RUM with scout_flutter ## Flutter `scout_flutter` is a single Dart package that ships **zero-config OpenTelemetry RUM** for Flutter on iOS, Android, macOS, and web. Auto- captures the full Real User Monitoring event set (except Session Replay and Profiling) and exports it as OTLP traces, metrics, and logs to a Scout collector. ```dart await ScoutFlutter.initialize( config: ScoutFlutterConfig( serviceName: 'my-app', endpoint: 'https://otel.example.com', ), ); runApp(const MyApp()); ``` That's all the code you write. Every tap, navigation, HTTP request, error, crash, scroll, and frame metric is gathered automatically — no manual `Scout.track(...)` calls anywhere in your app. :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What You Get | Capability | Signal | Mechanism | |---|---|---| | Tap tracking | `user_interaction` span (`type=tap`, target, name_source, permanent_id, x/y) | Global `GestureBinding.instance.pointerRouter` interception | | Screen / route navigation | `screen_view` span with `view.id`, `view.loading_type`, `view.referrer`, `view.is_active` | `AutoNameNavigatorObserver` attached to every `Navigator` | | Screen load time | `screen_load` span with `screen.load_time` | First-frame measurement after route push | | App startup | `app_startup` span with `app_startup.type = cold \| warm`, `app_startup.duration` | `WidgetsBinding.addPostFrameCallback` on first frame | | FBC vital (First Build Complete) | `app_vital` span with `vital.name = fbc` | Emitted alongside cold-start; ready for dashboards as a first-class vital | | INV vital (Interaction → Next View) | `app_vital` span with `vital.name = inv`, `vital.from_screen`, `vital.to_screen` | Tap timestamp correlated with next `screen_view` within 5 s | | Errors (Flutter framework) | `error` span with `error.id`, `error.fingerprint`, `error.handled`, breadcrumbs | `FlutterError.onError` + `PlatformDispatcher.instance.onError` | | Manual error reporting | `error` span | `ScoutFlutter.reportError(e, stackTrace)` | | Native crashes (iOS) | `native_crash` span with `crash.reason`, registers (FAR/ESR), mach_exception, callstack_tree, binary_images | KSCrash 2.x all five monitors + MetricKit `MXCrashDiagnostic` / `MXHangDiagnostic` | | Native crashes (Android) | `native_crash` span with `crash.reason`, signal info, tombstone (≤ 128 KB, configurable), `crash.os_reason_*`, PSS/RSS | Custom NDK signal handler + `ApplicationExitInfo` (API 30+; reflective subReason on API 31+). Each OS death is reported exactly once (persisted watermark); normal exits (swipe-away, Force Stop, `exit()`) are never reported as crashes | | ANR | `anr` span with `anr.duration`, `anr.threshold`, `anr.thread_count`, `anr.threads_json`, `anr.main_thread_stack`, and breadcrumbs | iOS: `AppHangWatchdog` (5 s default). Android: native ping watchdog polling every 100 ms (deterministic detection, fires once per hang) + ApplicationExitInfo `REASON_ANR` post-mortem. Captures a full thread dump at detection time. | | UI hang (iOS) | `ui_hang` span with `ui_hang.duration`, `ui_hang.threshold` | iOS-only sub-ANR watchdog at 250 ms (configurable). Complements KSCrash mainThreadDeadlock and the 5 s ANR detector | | Long tasks | `long_task` span with `long_task.duration`, `long_task.threshold` | Dart isolate event-loop polling | | HTTP requests | `http.request` span with method, URL, status, duration, headers | `HttpOverrides` global wrap + Dio interceptor (optional) | | Distributed tracing | W3C `traceparent` header injected into outgoing requests to hosts in `firstPartyHosts` | Wrap on the HTTP client | | Scroll depth | `display.scroll.max_depth`, `display.scroll.max_depth_scroll_top`, `display.scroll.max_scroll_height`, `display.scroll.max_scroll_height_time_ms` on `screen_view` | `ScoutScrollObserver` widget wrapping `NotificationListener` | | Lifecycle | `app_paused`, `app_resumed` spans + force-flush on background | `AppLifecycleListener` | | Frame metrics (opt-in) | `flutter.frame.build_time`, `flutter.frame.raster_time` histograms | `WidgetsBinding.instance.addTimingsCallback`. Off by default (`enableFrameMetrics`) — records on every frame, one stream per screen | | Memory + CPU (opt-in) | `flutter.memory.usage`, `flutter.cpu.usage` gauges | Platform channel poll every `vitalsCollectionIntervalSeconds` (60 s). Off by default (`enableMemoryMetrics` / `enableCpuMetrics`) | | Network connectivity | `network.connection.type` resource attribute (`wifi`, `cellular`, `none`) | `connectivity_plus` listener | | Battery | `device.battery.level`, `device.battery.state`, `device.battery.discharge_rate` resource attributes | `battery_plus` + platform channel | | Device orientation | `device.orientation` resource attribute (`portrait` / `landscape`) | Orientation-change listener | | Device integrity | `device.is_jail_broken` resource attribute | Jailbreak / root heuristic via platform channel | | Logs | OTLP logs | `ScoutFlutter.log*()` and (opt-in) `print` / `debugPrint` capture | | Anonymous user id | `user.anonymous_id` on every span | UUID v4 minted on first launch, persisted to temp dir | | WebView bridge | Embedded web pages adopt the native `session.id` + `user.anonymous_id`; their spans flow back as `span.source = "webview"` | `ScoutWebViewBridge.attach()` + `injectShim()` on every page finish | ### Prerequisites | Requirement | Version | |---|---| | Flutter SDK | ≥ 3.7.0 | | Dart SDK | ≥ 3.7.0 | | iOS deployment target | ≥ 12.0 | | Android `minSdkVersion` | ≥ 21 (`ApplicationExitInfo` features activate from API 30+) | | `compileSdkVersion` | ≥ 34 (recommended) | | CocoaPods | ≥ 1.11 | | NDK (Android, for native crash) | ≥ 25 (matches Flutter default) | ### Installation scout_flutter is published on [pub.dev](https://pub.dev/packages/scout_flutter). Add it to your `pubspec.yaml`: ```yaml # pubspec.yaml dependencies: scout_flutter: ^0.2.0 ``` Or: ```bash flutter pub add scout_flutter ``` :::note What changed in 0.2.0 The native engine now starts alongside the Flutter SDK on both platforms. This is additive for a pure-Flutter app: Flutter telemetry is unchanged, and you also get native crash capture and CPU/memory vitals under a native scope (`base14.scout.android` or `base14.scout.ios`) next to `base14.scout.flutter`. The same mechanism lets a native host app share one session with embedded Flutter. See [Hybrid (Native + Flutter)](./hybrid.md). ::: #### iOS — CocoaPods install The first build after adding scout_flutter triggers a pod install for the KSCrash 2.x and MetricKit dependencies. Make sure your iOS Podfile has `platform :ios, '12.0'` or higher: ```ruby # ios/Podfile platform :ios, '12.0' ``` Then: ```bash cd ios && pod install --repo-update && cd .. ``` #### Android — NDK setup The native signal handler is built automatically as part of the plugin's Gradle build. No app-side configuration needed beyond ensuring your project has the NDK available (`flutter doctor` will warn if not). ### Initialization In your `main.dart`, before `runApp()`: ```dart import 'package:flutter/material.dart'; import 'package:scout_flutter/scout_flutter.dart'; void main() async { WidgetsFlutterBinding.ensureInitialized(); // Fire-and-forget — never block app startup on SDK init. unawaited( ScoutFlutter.initialize( config: ScoutFlutterConfig( serviceName: 'my-app', serviceVersion: '1.0.0', endpoint: 'https://otel.example.com', headers: {'Authorization': 'Bearer …'}, ), ), ); // Wrap your root widget with the scroll observer so per-screen // scroll metrics decorate the active screen_view span. runApp(ScoutFlutter.observeScroll(child: const MyApp())); } ``` #### Navigation tracking Attach `ScoutFlutter.navigatorObserver` to **every** `Navigator` in your app — the root `MaterialApp` / `CupertinoApp` plus each nested `Navigator` (commonly inside `CupertinoTabView`, `Navigator` widgets used for bottom-sheet stacks, etc.): ```dart MaterialApp( navigatorObservers: [ScoutFlutter.navigatorObserver], // … ); // And per CupertinoTabView: CupertinoTabView( navigatorObservers: [ScoutFlutter.navigatorObserver], builder: (context) => const SongsTab(), ); ``` `navigatorObserver` returns a **fresh instance on every read**, so attaching it to multiple Navigators does not trip Flutter's "observer already has a navigator" assertion. All instances funnel events into shared static state so dashboards see one coherent screen timeline regardless of which Navigator pushed a route. #### Setting user identity ```dart ScoutFlutter.setUser( id: 'user-123', attributes: { 'email': 'jane@example.com', // → user.email 'plan': 'pro', // → user.plan 'role': 'admin', // → user.role }, ); // On logout: ScoutFlutter.clearUser(); ``` `id` is optional. `user.id` and every attribute ride on every span until cleared — bare attribute keys are auto-prefixed with `user.`, and keys already starting with `user.` pass through unchanged. `setUser` **replaces** the whole user map, so pass everything you want each call. #### Setting session attributes Session attributes attach to every subsequent span, metric, and log for the rest of the session. Keys are stored verbatim (no auto-prefix). ```dart // Replaces all existing session attributes. ScoutFlutter.setSessionAttributes({'tenant': 'acme', 'ab_bucket': 'B'}); // Add one without clobbering the rest — merge with the current view: ScoutFlutter.setSessionAttributes({ ...ScoutFlutter.sessionAttributes, 'feature.new_checkout': 'true', }); // Clear all. ScoutFlutter.clearSessionAttributes(); ``` They persist until you call `clearSessionAttributes()` — they are **not** cleared automatically on session rotation. ### Configuration `ScoutFlutterConfig` is the single config object. **Required fields** are flagged below; everything else has a sensible default and is opt-in. #### Identity | Field | Type | Default | Description | |---|---|---|---| | `serviceName` | `String` | **(required)** | Logical app identifier. Used as `service.name`. | | `endpoint` | `String` | **(required)** | OTLP-HTTP collector URL. `/v1/traces`, `/v1/metrics`, `/v1/logs` are appended automatically. | | `serviceVersion` | `String?` | `null` | Maps to `service.version`. Set to your app build version. | | `secure` | `bool` | `true` | When `endpoint` has no scheme, prefix `https://` (true) or `http://` (false). | | `headers` | `Map?` | `null` | Extra HTTP headers on every OTLP export. Use for auth. | | `resourceAttributes` | `Map?` | `null` | Extra attributes merged into every signal's `Resource`. Use for `deployment.region`, `team`, etc. Static — set once at init. | #### Network | Field | Type | Default | Description | |---|---|---|---| | `enableNetworkTracking` | `bool` | `true` | Wraps `HttpOverrides` globally. Disable if you wire `ScoutFlutter.dioInterceptor` manually. | | `firstPartyHosts` | `List?` | `null` | Hosts that receive a W3C `traceparent` header for distributed tracing. Supports exact match or `*.host` wildcards. | | `ignoreUrlPatterns` | `List?` | `null` | URLs matching any pattern are not auto-instrumented. | #### Sessions | Field | Type | Default | Description | |---|---|---|---| | `sessionTimeoutMinutes` | `int` | `30` | Inactivity timeout before a new `session.id` is minted. | | `maxSessionDurationMinutes` | `int` | `60` | Hard cap on session lifetime; rotates on the next ID read past this age regardless of activity. `0` disables. | | `sessionSampleRate` | `double (0-100)` | `1.0` | Percent of sessions sampled — default **1%**. The decision is made once per session and applies uniformly to **spans, metrics, and logs**: a sampled session sends everything, an unsampled session sends nothing. | | `alwaysCaptureErrors` | `bool` | `true` | Error / crash / ANR-class spans and error-level logs bypass `sessionSampleRate` and are always exported. Set `false` to subject them to the same gate. | #### Thresholds | Field | Type | Default | Min | Description | |---|---|---|---|---| | `longTaskThresholdMs` | `int` | `100` | `20` | Dart isolate task duration that qualifies as a `long_task` span. | | `anrThresholdMs` | `int` | `5000` | `1000` | Main-thread block duration that fires an `anr` span. | | `iosHangThresholdMs` | `int` | `250` | `50` (or `0` to disable) | iOS only — sub-ANR `ui_hang` watchdog. Complements ANR (5 s) and KSCrash `mainThreadDeadlock` (5 s+). Catches micro-stutter / jank. | | `maxTombstoneBytes` | `int` | `131072` | `4096` | Max bytes of Android `ApplicationExitInfo` tombstone (ANR / native post-mortem) captured per report. | #### Batching & export (applies to spans, metrics, AND logs) All three signals share one batching model. Each exporter also holds a single keep-alive HTTP connection for its lifetime (idle timeout sized to outlive the export interval), so TLS handshakes happen once per app session per signal — not once per export. | Field | Type | Default | Min | Description | |---|---|---|---|---| | `exportIntervalSeconds` | `int` | `30` | `1` | One export cadence for spans, metrics, and logs. | | `maxExportBatchSize` | `int` | `512` | `1` | Max items per export batch, per signal. | | `maxQueueSize` | `int` | `2048` | `1` | Max items buffered awaiting export; overflow is dropped. | | `maxRetries` | `int` | `0` | `0` | Delivery attempts after a failed export, for every signal. Default **0 = at-most-once**: retrying an ambiguous failure (a timeout whose request the collector may already have ingested) delivers duplicate events. | | `metricExportIntervalSeconds` | `int?` | `null` | `1` | Metrics-only override of `exportIntervalSeconds`. Unset means metrics follow the unified interval. | | `vitalsCollectionIntervalSeconds` | `int` | `60` | `1` | How often memory/CPU are polled natively (when the gauges are enabled). | #### Per-metric switches The SDK ships **no metrics by default** — each gauge/histogram family is opt-in. | Field | Default | Description | |---|---|---| | `enableFrameMetrics` | `false` | `flutter.frame.build_time` / `flutter.frame.raster_time` histograms. They record on **every rendered frame** with one stream per screen — by far the highest-volume metrics the SDK can produce. Frozen-frame detection (the `frozen_frame` span) stays on regardless. | | `enableMemoryMetrics` | `false` | The `flutter.memory.usage` gauge. When off, the native poll is skipped entirely. | | `enableCpuMetrics` | `false` | The `flutter.cpu.usage` gauge, same behavior. | #### Offline buffer Offline buffering is **fully disabled by default** — nothing is written to disk, and a batch that fails to export is dropped (strict at-most-once delivery). Opt in for durability at the cost of possible duplicate delivery on replay. | Field | Type | Default | Description | |---|---|---|---| | `offlineBufferEnabled` | `bool` | `false` | Master toggle. Set `true` to persist failed batches and replay them on next `initialize()` or connectivity change. | | `offlineMaxTraceItems` | `int` | `0` | FIFO cap on persisted span items (`0` = signal disabled in the queue). Oldest evicted first. | | `offlineMaxMetricItems` | `int` | `0` | Same, for metric data points. | | `offlineMaxLogItems` | `int` | `0` | Same, for log records. | | `maxOfflineStorageMb` | `int` | `5` | Coarse total-disk cap that runs alongside the per-signal `offlineMax*Items` caps when buffering is enabled — whichever limit is reached first wins. | #### Auto-instrumentation toggles Every auto-instrumentation can be turned off independently. Span and log instrumentation defaults to **on**; metric collection defaults to **off** (see [Per-metric switches](#per-metric-switches)). | Toggle | Default | What you lose when set to `false` | |---|---|---| | `enableAutoTapTracking` | `true` | All `user_interaction` spans. | | `enableErrorTracking` | `true` | `error` spans from `FlutterError.onError` and `PlatformDispatcher.onError`. Manual `reportError()` still works. | | `enableLifecycleTracking` | `true` | `app_paused` / `app_resumed` spans and the background-flush hook. Heavy loss — recommend leaving on. | | `enableStartupTracking` | `true` | `app_startup` cold/warm spans **and** the FBC vital. | | `enableConnectivityTracking` | `true` | `network.connection.type` resource attr updates on network transitions. | | `enablePerformanceMetrics` | `true` | Master switch for the whole metrics pipeline (exporter + reader). With it on, individual gauges still need their per-metric switches. | | `enableLongTaskDetection` | `true` | `long_task` spans. Tune with `longTaskThresholdMs` instead of disabling. | | `enableAnrDetection` | `true` | `anr` spans **and** the iOS `ui_hang` watchdog. | | `enableNetworkTracking` | `true` | `http.request` spans + `traceparent` injection. | | `enableLogging` | `true` | `ScoutFlutter.log*()` calls become no-ops. | | `capturePrintStatements` | `false` | (Off by default) When `true`, mirrors `print` / `debugPrint` calls to OTLP logs. Original console output is preserved. | #### Filtering — `beforeSend` ```dart ScoutFlutterConfig( // … beforeSend: (event) { // event keys: 'type' ('span'|'metric'|'log'), 'name', plus // per-span attributes. Return null to drop the event. if ((event['http.url'] as String?)?.contains('/health') == true) { return null; } event.remove('user.email'); return event; }, ) ``` **Sees per-span attributes only.** Resource attributes set on the OTel `Resource` (e.g. `service.name`, `os.name`, `device.*`) are **not** in the event payload. ### Native crash setup #### iOS — KSCrash + MetricKit The plugin auto-installs **KSCrash 2.5+** with all five monitors: - Mach exceptions - POSIX signals - C++ exceptions - NSException - Main-thread deadlock (5 s+ — complementary to the 250 ms `iosHangThresholdMs` watchdog) On every launch, scout_flutter drains any persisted KSCrash reports from the previous run and emits them as `native_crash` spans carrying: - `crash.reason`, `crash.type`, `crash.signal`, `crash.os_name`, `crash.os_version`, `crash.kernel` - `crash.registers_json` — full CPU register dump including FAR and ESR - `crash.mach_exception`, `crash.mach_code`, `crash.mach_subcode` - `crash.nsexception_name` (when applicable) - `crash.callstack_tree_json` — symbolicated stack tree of every thread - `crash.binary_images_json` — loaded image list for offline symbolication - The prior session's last 20 breadcrumbs In parallel, an `MXMetricManagerSubscriber` collects asynchronous `MXCrashDiagnostic` and `MXHangDiagnostic` payloads that Apple delivers the morning after a crash — useful for catching kernel-killed crashes that KSCrash couldn't intercept. ##### Triggering a crash (testing) scout_flutter does not ship a "simulate crash" API. To validate end-to-end capture, trigger a real fault — and **never** use `exit()`, which is a graceful shutdown that no crash reporter intercepts: ```dart // Uncaught Dart error → `error` span (and, if fatal, `app_crash` on relaunch). throw StateError('test crash'); ``` For a true native signal (SIGSEGV on Android, `fatalError()` on iOS), add a small platform-channel method on the app side. The repo's `example/` app and the [`flutter/samples/platform_design`](https://github.com/flutter/samples/tree/main/platform_design) sample ship ready-made crash / ANR / deadlock buttons for exactly this. #### Android — NDK signal handler + ApplicationExitInfo The plugin auto-installs a **custom NDK signal handler** that catches SIGSEGV / SIGABRT / SIGBUS / SIGILL / SIGFPE before they kill the process. A compact crash report (signal info, registers, stack, memory map, binary images with ELF build-ids) is persisted to disk and emitted on next launch as a `native_crash` span. In parallel, on API 30+ (Android 11+), scout_flutter polls `ActivityManager.getHistoricalProcessExitReasons` and emits a `native_crash` span for any OS-recorded death newer than the persisted watermark — **each death is reported exactly once across launches**. Only crash-class exit reasons are reported (`anr`, `jvm_crash`, `native_crash`, `low_memory`); benign exits such as the user swiping the app away (`user_requested`), Force Stop (`user_stopped`), or a normal `exit()` (`exit_self`) are filtered out and never counted as crashes. Captured attributes: - `crash.type` / `crash.reason` - `crash.subreason` (API 31+ via reflection) - `crash.exit_status`, `crash.importance`, `crash.death_timestamp_ms`, `crash.process_name`, `crash.pid`, `crash.pss_kb`, `crash.rss_kb` - `crash.tombstone` — the OS's full thread dump with native frames (capped at 128 KB by default; tune with `maxTombstoneBytes`) The two pipelines complement each other: NDK fires in-process at crash time, ApplicationExitInfo catches deaths that the OS killed before in-process handlers could write to disk (OOM, hard watchdog, etc.). ### Background flush scout_flutter calls `forceFlush()` on every signal provider when the app transitions to `AppLifecycleState.paused` / `inactive` / `hidden`. This drains the BatchSpanProcessor, metric reader, and log processor before the OS suspends the process — without it, events emitted in the last few seconds (the ones leading up to a crash) would die with the in-memory batch queue. If the in-memory exporter still doesn't deliver in time (OS kills us mid-POST), the batch is dropped under the default at-most-once delivery. Enable the **offline buffer** (`offlineBufferEnabled: true` plus per-signal caps) to persist such batches to disk and replay them on next `initialize()`. ### WebView bridge Embed a WebView showing a page instrumented with `@base14/scout-react` (web entry) v0.1.5+, and `scout_flutter` will flatten the WebView's RUM session into the **native** session — both runtimes share one `session.id` and `user.anonymous_id`, and the embedded page's spans flow back into the native pipeline tagged with `span.source = "webview"`. ```dart import 'package:scout_flutter/scout_flutter.dart'; import 'package:webview_flutter/webview_flutter.dart'; final controller = WebViewController() ..setJavaScriptMode(JavaScriptMode.unrestricted) ..setNavigationDelegate( NavigationDelegate( onPageFinished: (_) { // Re-inject the shim on every navigation. The shim has a // sentinel so re-injecting in the same page is a no-op. ScoutWebViewBridge.injectShim( runJavaScript: controller.runJavaScript, ); }, ), ); ScoutWebViewBridge.attach( addJavaScriptChannel: (name, onMessage) { controller.addJavaScriptChannel( name, onMessageReceived: (m) => onMessage(m.message), ); }, ); await controller.loadRequest(Uri.parse('https://app.example.com')); ``` The bridge: 1. Registers a JavaScript channel (default name `ScoutBridge`) the page can `postMessage` into. 2. Injects a JS shim that polls `window.Scout` and calls `setWebViewBridge({sessionId, anonymousId, send})` once the page's web SDK appears. 3. Receives bridged span payloads via the channel and re-emits them as native spans with `span.source = "webview"`, `session.id`, `user.anonymous_id`, and the rest of the native common attributes. The bridge is currently a **parallel** transport — both the web SDK's own OTLP exporter and the native bridge ship a copy of each span. Configure the web SDK with an unreachable endpoint, or filter everything with `beforeSend` returning `null`, to make the bridge the sole transport. The bridge is generic — `attach()` accepts bare callbacks rather than a typed `WebViewController`, so it works with `webview_flutter`, `flutter_inappwebview`, or any future plugin. Adapt the integration glue (~6 lines) per your plugin of choice. ### What happens when export fails Delivery is **at-most-once by default** (`maxRetries: 0`): a batch gets one attempt, and a failed batch is dropped rather than risking a duplicate delivery (a retried timeout whose first request the collector already ingested would store the same events twice). | Failure | What Scout does (defaults) | |---|---| | Any export failure, `maxRetries: 0` (default) | One attempt; batch dropped on failure. No duplicates, ever. | | `maxRetries > 0` configured | Failed batches are retried up to that many times — with the corresponding duplicate risk on ambiguous failures. | | Failure with `offlineBufferEnabled: true` configured | Batch persisted to disk and replayed on next `initialize()` or connectivity change (single replay attempt). | | Disk write fails (quota, permissions) | Caught and swallowed; batch dropped. | | App crash mid-batch | The background-flush hook drains buffers on `paused`; anything emitted after the last flush is lost with the process. | ### Running the example app The repo ships a runnable example at `example/`. For physical-device testing of the full diagnostic suite (UI hang, ANR, real SIGSEGV crash, WebView bridge) the [`flutter/samples/platform_design`](https://github.com/flutter/samples/tree/main/platform_design) sample is a good starting point. ```bash # iOS simulator cd example flutter run -d "iPhone 17" # Android emulator / physical device flutter run -d # For physical Android: reverse-forward your local collector adb reverse tcp:34318 tcp:34318 ``` ### Troubleshooting | Symptom | Likely cause + fix | |---|---| | `ui_hang` never fires on iOS | `iosHangThresholdMs: 0` disables it; check your config. Or the main thread genuinely isn't hanging — try a 300 ms `while` loop to confirm the watchdog is armed. | | Two `screen_view` per nav | You attached `ScoutFlutter.navigatorObserver` to both the root `MaterialApp` Navigator and a nested `CupertinoTabView` Navigator. That's correct — each Navigator emits its own `screen_view`. Filter dashboards by `view.id` to dedupe. | | `native_crash` not appearing after iOS crash | KSCrash writes asynchronously; the report drains on the *next* launch. Force-quit and relaunch the app, then check the collector log. | | Android `native_crash` empty on API < 30 | `ApplicationExitInfo` requires API 30+. Older devices only get whatever the in-process NDK handler caught. | | WebView spans not tagged `span.source = webview` | Either the embedded page isn't `@base14/scout-react` v0.1.5+ (no `window.Scout`), or your `NavigationDelegate.onPageFinished` is missing the `injectShim(...)` call. | | `Observer already has a Navigator` assertion | `navigatorObserver` returns a fresh instance on every read, so attaching it to multiple Navigators is fine. If you hit this, you're caching one instance and reusing it — read `ScoutFlutter.navigatorObserver` afresh per Navigator. | | HTTP requests not getting `traceparent` | The host isn't in `firstPartyHosts`. Add it explicitly (e.g. `'api.example.com'`) or use a wildcard (`'*.example.com'`). | | Crash button gives a graceful shutdown instead of SIGSEGV | You're calling `exit()`, which is graceful — no crash reporter intercepts it. Trigger a real fault instead (an uncaught error, or a native null-deref via your own platform-channel method). | ### Performance considerations - **Unified 30 s batching.** Spans, metrics, and logs each flush once per `exportIntervalSeconds` (default 30 s) — including logs, which are buffered and batched rather than posted per line. - **Connection reuse.** Each signal holds one keep-alive HTTP connection for the app session — TLS handshakes happen ~3 times per session, not once per export. - **No metrics unless enabled.** The default configuration ships zero metric data points; the vitals gauges and frame histograms are per-app opt-ins. - **Zero disk usage by default.** Offline buffering is off; the only disk writes are crash evidence (crash reports, breadcrumbs, session marker). - **Sampling.** `sessionSampleRate` drops *full sessions* — spans, metrics, and logs together — never individual events, so session traces stay coherent. - **Async init.** `ScoutFlutter.initialize()` is fire-and-forget. The app boot does not wait on it. ### Security considerations - **PII scrubbing.** Use `beforeSend` to redact attributes (`event.remove('user.email')`) or drop entire events (return `null`). It runs synchronously on every span / metric / log before export. - **Custom headers for auth.** Pass `headers: {'Authorization': 'Bearer …'}` to authenticate the OTLP export. Headers are sent on every request including offline-replay POSTs. - **No telemetry-to-disk PII by default.** The offline buffer writes the same OTLP JSON your live exporter would have sent — it doesn't add anything extra. If you don't want sensitive attrs on disk, scrub them in `beforeSend` *before* the batch hits the buffer. - **TLS.** Set `secure: true` (default) or pass an explicit `https://` endpoint. No CA pinning by default; if you need it, wrap the outbound HTTP client yourself. ### FAQ #### Does scout_flutter work on macOS / web / Linux / Windows desktop? iOS and Android are fully supported, including native crash capture. macOS works for the Dart-side instrumentation (taps, navigation, HTTP, errors, lifecycle, logs) but the KSCrash / MetricKit / ApplicationExitInfo pipelines are mobile-only. Web works for Dart-side instrumentation — for richer web RUM, use `@base14/scout-react` directly in a web app and (for hybrid apps) bridge with the WebView bridge. #### Will the SDK ever block my app's boot? No. `ScoutFlutter.initialize()` is async and fire-and-forget — wrap it in `unawaited(...)` as shown above. If init fails (network down, disk full, etc.) the error is swallowed; your app keeps running. #### How big are crash reports on the wire? A KSCrash report with full register dump + callstack tree typically serializes to 30–80 KB. ApplicationExitInfo tombstones are capped at 128 KB by default (`maxTombstoneBytes`). They're sent as part of the next launch's first batch — each death exactly once. #### Can I add custom spans? Yes — the underlying OTel Tracer is accessible. Custom spans go through the same beforeSend / sampling / export pipeline as auto-instrumented ones. #### Can I emit metrics or logs manually? Yes. `ScoutFlutter` exposes log and metric helpers that emit through the same exporter as the automatic telemetry: ```dart ScoutFlutter.logInfo('checkout started', attributes: {'cart.size': 3}); ScoutFlutter.logError('payment failed', attributes: {'order.id': 'ord-1'}); // For an error with a stack trace, use reportError (emits an `error` span): ScoutFlutter.reportError(e, st); ``` ### What's next - [Configure your collector](/instrument/collector-setup/docker-compose-example/) to receive OTLP-HTTP on `:4318` - Explore the data in [RUM](/operate/rum/getting-started) - crashes, sessions, screens, and network performance for the app you just instrumented - Read [RUM with OpenTelemetry](/instrument/mobile/rum-opentelemetry) if you need the span names and attributes behind those views - Look at [React Native + React Web instrumentation](/instrument/mobile/react-native) for the JavaScript equivalent (and the WebView bridge counterpart) ### References - scout_flutter repo: [github.com/base-14/scout-flutter](https://github.com/base-14/scout-flutter) - scout-react repo (web + RN companion): [github.com/base-14/scout-react](https://github.com/base-14/scout-react) - KSCrash: [github.com/kstenerud/KSCrash](https://github.com/kstenerud/KSCrash) - Apple MetricKit: [developer.apple.com/documentation/metrickit](https://developer.apple.com/documentation/metrickit) - Android ApplicationExitInfo: [developer.android.com/reference/android/app/ApplicationExitInfo](https://developer.android.com/reference/android/app/ApplicationExitInfo) --- ## Hybrid Instrumentation - Native + Flutter RUM in one session ## Hybrid (Native + Flutter) An add-to-app hybrid is a native Android (Kotlin) or iOS (Swift) app that embeds Flutter for some screens. To instrument one, initialize the native SDK and `scout_flutter` with the same `serviceName` and `endpoint`. The Flutter SDK detects the native SDK and delegates to it, and both layers report under one `session.id`. :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What You Get | Capability | Owner | Notes | |---|---|---| | Unified session | Native | The native side mints the session; the Flutter side adopts its `session.id`. One session across both scopes | | Export pipeline | Native | Flutter forwards spans, logs, and metrics over the bridge. Same-process, one exporter for both layers; different-process, one per process | | Breadcrumbs, user and session attributes | Shared | Set on either side, visible to both | | Native Android telemetry | `scout-android` | Screens, taps, HTTP, JVM and NDK crashes, ANR, jank, vitals. See [Android](./android.md) | | Native iOS telemetry | Bridge engine | Screens, KSCrash native crashes, app hangs, MetricKit diagnostics, HTTP, jank, vitals. Taps and startup tracking are off in bridge mode | | Flutter telemetry | `scout_flutter` | Screens, taps, HTTP, errors, and jank from the Flutter layer, forwarded to the native side. See [Flutter](./flutter.md) | | Crash de-duplication | Native | In hybrid mode `scout_flutter` drains and discards its own crash files, so a crash is reported once | ### How it works - The native SDK (`scout-android` on Android; the Kotlin/Native engine that ships inside `scout_flutter` on iOS) and the Flutter SDK (`scout_flutter`) both run inside your app. - `scout_flutter` delegates to the native SDK, forwarding its spans, logs, and metrics to the native side, which owns the export pipeline. Same-process, that is a single OTLP exporter for both layers. In a separate `:flutter` process each process runs its own exporter, described in [Different-process](#different-process). - The native side owns the session; the Flutter side adopts that `session.id`. Breadcrumbs and user/session attributes are shared. In your backend you see one service (the shared service name) with two OpenTelemetry instrumentation scopes, all under one `session.id`: | Platform | Native scope | Flutter scope | | --- | --- | --- | | Android | `base14.scout.android` | `base14.scout.flutter` | | iOS | `base14.scout.ios` | `base14.scout.flutter` | #### Process models | Platform | Same-process | Different-process | | --- | --- | --- | | Android | Default (no `android:process`) | `android:process=":flutter"` | | iOS | Only mode; iOS apps are single-process | Not applicable | ### Prerequisites | Requirement | Version | | --- | --- | | Android native SDK | `io.base14:scout-android:0.1.7` (Maven Central) | | Flutter SDK | `scout_flutter` `^0.2.0` | | iOS native engine | Ships inside `scout_flutter`; no separate dependency | The hybrid bridge lands in `scout_flutter` 0.2.0. The `0.1.x` line does not include the native delegation bridge, so use `0.2.0` or later for hybrid apps. Both inits must use the same `serviceName` and `endpoint`. That is what ties the two layers to one service; the bridge then unifies the session automatically. --- ### Android On Android you initialize the native `scout-android` SDK in your native host and initialize `scout_flutter` in Dart. The native SDK becomes the session owner and the sole exporter; `scout_flutter` detects it and bridges automatically. #### 1. Dependencies `android/app/build.gradle.kts` (native host): ```kotlin dependencies { implementation("io.base14:scout-android:0.1.7") } ``` `pubspec.yaml` (Flutter module): ```yaml dependencies: scout_flutter: ^0.2.0 ``` #### 2. Initialize the native SDK (session owner) Initialize Scout in `Application.onCreate`, once per process, before any `Activity` starts, whether that is your native host or the embedded `FlutterActivity`: ```kotlin package com.example.myapp import android.app.Application import io.base14.scout.android.Scout import io.base14.scout.core.ScoutConfig class MyApplication : Application() { override fun onCreate() { super.onCreate() Scout.initialize( this, ScoutConfig( serviceName = "my-hybrid-app", // MUST match Flutter endpoint = "https:///otlp", // MUST match Flutter headers = mapOf("Authorization" to "Bearer "), // Leave `role` at its ScoutRole.AUTO default; see Different-process. ), ) } } ``` Register it in `AndroidManifest.xml`: ```xml ``` This also auto-instruments your native screens (Compose and Views), taps, HTTP, crashes, ANR, and frame metrics. See [Android](./android.md). #### 3. Initialize scout_flutter (same service name + endpoint) In your Flutter module's `main()`: ```dart import 'package:flutter/widgets.dart'; import 'package:scout_flutter/scout_flutter.dart'; Future main() async { // Required: initialize() talks to the native side over a platform channel, // which needs the binding in place. WidgetsFlutterBinding.ensureInitialized(); await ScoutFlutter.initialize( config: ScoutFlutterConfig( serviceName: 'my-hybrid-app', // MUST match native endpoint: 'https:///otlp', // MUST match native headers: const {'Authorization': 'Bearer '}, ), ); runApp(const MyApp()); } ``` `scout_flutter` detects the already-initialized native SDK and delegates to it, forwarding all Flutter telemetry through the bridge and adopting the native `session.id`. No extra wiring is required. #### 4. Launch Flutter from the native host Add a `FlutterActivity` subclass for the Flutter UI (a bare subclass is enough; add a `MethodChannel` only if you call native code from Dart): ```kotlin package com.example.myapp import io.flutter.embedding.android.FlutterActivity class MainActivity : FlutterActivity() ``` Then present it from your native host: ```kotlin startActivity(Intent(this, MainActivity::class.java)) ``` :::note Init ordering You don't need to hand-sequence the two SDKs. Initialize each at its own entry point: native in `Application.onCreate`, Flutter in `main()`. `onCreate` runs before any `Activity`, so the native session owner is always in place by the time the Flutter side attaches. Same-process is order-independent regardless: whichever SDK initializes first establishes the shared owner. ::: #### 5. Choose a process model ##### Same-process (default, recommended) The Flutter `Activity` runs in the same OS process as the native host. Declare it in `AndroidManifest.xml` without an `android:process` attribute: ```xml ``` Unification happens in memory: the native and Flutter SDKs share the same process, so the Flutter side reads the native session directly. This is the default. ##### Different-process If your Flutter `Activity` must run in a separate OS process, usually for memory isolation, add `android:process=":flutter"`: ```xml ``` `Application.onCreate` runs again in the `:flutter` process, so `Scout.initialize` runs there too. That process cannot read the main process's in-memory owner, so the bridge queries `ScoutBridgeProvider` instead. This is a `ContentProvider` that `scout-android` declares in its own manifest with authority `${applicationId}.scout.bridge`, `android:exported="false"`, and `android:multiprocess="false"`, so a single instance runs in the main process. It returns the live session context, and the `:flutter` process adopts the same `session.id`. You do not declare the provider yourself; the manifest merger pulls it in. :::warning Keep `role` at `ScoutRole.AUTO` here The Android bridge only performs the cross-process lookup when `role` is not `OWNER`. Setting `role = ScoutRole.OWNER` skips it, so the `:flutter` process mints its own session and you get two sessions. `AUTO`, the default, resolves ownership correctly in both process models. The `flutter-android-example` app in the `scout-kotlin-multiplatform` repo does set `ScoutRole.OWNER`. That is safe there because it runs same-process, where the lookup is not needed. Do not copy it into a different-process app. ::: In the backend you still get one session across both scopes, but each process runs its own exporter: the main process exports native telemetry, the `:flutter` process exports the forwarded Flutter telemetry. That is two export pipelines and two processes, which is the overhead this mode costs you. :::tip Choosing a process model Prefer same-process unless you have a specific reason to isolate Flutter, such as a memory-heavy Flutter surface you want the OS to reclaim independently. Both produce one unified session. ::: --- ### iOS iOS apps are single-process, so there is only one process model. You do not write any native Scout initialization for the bridge. `scout_flutter` starts the native iOS engine in bridge mode for you. #### 1. Dependency Add `scout_flutter` to your Flutter module. The iOS native engine is bundled with the plugin (no separate native dependency). ```yaml dependencies: scout_flutter: ^0.2.0 ``` #### 2. Initialize scout_flutter In your Flutter module's `main()`, same as Android: ```dart Future main() async { WidgetsFlutterBinding.ensureInitialized(); await ScoutFlutter.initialize( config: ScoutFlutterConfig( serviceName: 'my-hybrid-app', endpoint: 'https:///otlp', headers: const {'Authorization': 'Bearer '}, ), ); runApp(const MyApp()); } ``` On iOS, `scout_flutter` starts the native Kotlin/Native engine in bridge mode internally (via `Scout.startBridge`). That engine emits the `base14.scout.ios` scope and shares one `session.id` with the Flutter layer. No native Swift init code is required. #### 3. Present Flutter from the native host Standard add-to-app: keep a cached `FlutterEngine` and present a `FlutterViewController`: ```swift lazy var flutterEngine = FlutterEngine(name: "my_engine") func application(_ application: UIApplication, didFinishLaunchingWithOptions launchOptions: ...) -> Bool { flutterEngine.run() GeneratedPluginRegistrant.register(with: flutterEngine) return super.application(application, didFinishLaunchingWithOptions: launchOptions) } func presentFlutter() { let vc = FlutterViewController(engine: flutterEngine, nibName: nil, bundle: nil) vc.modalPresentationStyle = .fullScreen keyWindow?.rootViewController?.present(vc, animated: true) } ``` :::note What bridge mode leaves out on iOS The engine `scout_flutter` starts for you covers sessions, screen views, KSCrash native crashes, app hangs, MetricKit `MXCrashDiagnostic` / `MXHangDiagnostic` diagnostics, HTTP, jank, and vitals on the native side. Two things are off in bridge mode: - Tap tracking (`enableTapTracking` defaults to `false`). - Startup and cold-start tracking (`enableStartupTracking` defaults to `false`). To get both, call `Scout.start(...)` yourself in `application(_:didFinishLaunchingWithOptions:)` **before** `flutterEngine.run()`, using the same `serviceName` and `endpoint` as the Flutter config. The engine is a first-wins singleton: whichever of `Scout.start` and the plugin's `Scout.startBridge` runs first configures it, and the later call is a no-op. Calling `Scout.start` after Flutter has started has no effect. See [iOS](./ios.md). ::: --- ### Configuration in hybrid mode - Service name and endpoint must match on both sides. A mismatch produces two separate services and no session unification. - The native SDK is the exporter. Batching and retry settings on the native config govern what actually leaves the device; the Flutter side forwards to it rather than exporting directly. In different-process, each process applies these settings to its own exporter. - The Flutter config is forwarded to the native side through the bridge: `exportIntervalSeconds`, `maxExportBatchSize`, `maxQueueSize`, `maxRetries`, `metricExportIntervalSeconds`, `firstPartyHosts`, and `debugLogging`. - Crash and ANR/app-hang reporting is handled by the native side in hybrid mode. - For the per-layer configuration options, see the platform pages: [Android](./android.md), [iOS](./ios.md), and [Flutter](./flutter.md). ### Troubleshooting | Symptom | Cause | Fix | | --- | --- | --- | | **Two separate services** in the backend instead of one | The native and Flutter inits used a different `serviceName` or `endpoint` | Make `serviceName` and `endpoint` identical on both sides. That is what ties them to one service. | | **Flutter screens/events don't appear** (native data does) | `ScoutFlutter.initialize(...)` never ran, or ran with a non-hybrid build of `scout_flutter` | Ensure `ScoutFlutter.initialize` runs in `main()` before `runApp`, using `scout_flutter` `0.2.0` or later. | | **`main()` throws on startup** before any telemetry appears | `ScoutFlutter.initialize` reaches the native side over a platform channel, which needs the binding | Call `WidgetsFlutterBinding.ensureInitialized()` as the first line of `main()`. | | **Flutter data lands but under a different `session.id`** than native (not unified) | Different-process only: `role` was set to `ScoutRole.OWNER`, so the `:flutter` process skipped the cross-process lookup and minted its own session | Leave `role` at its `ScoutRole.AUTO` default. Same-process is unaffected. | | **Native screens/events don't appear on Android** | The native SDK was never initialized | Call `Scout.initialize` in `Application.onCreate`. | | **No native taps or cold-start spans on iOS** | Bridge mode leaves tap tracking and startup tracking off | Call `Scout.start(...)` in `application(_:didFinishLaunchingWithOptions:)` before `flutterEngine.run()`. Screens, KSCrash crashes, hangs, and MetricKit diagnostics are already covered without it. | ### FAQ #### Do I need to change my Flutter code for hybrid? No. The same `ScoutFlutter.initialize` call works. It detects the native SDK and delegates automatically. Matching `serviceName` and `endpoint` is the only requirement. #### What happens if I use `scout_flutter` 0.1.x in a hybrid app? The `0.1.x` line has no delegation bridge, so both SDKs export independently. You get two sessions under one service instead of one unified session. #### Does the bridge change anything for pure-Flutter apps? Yes. From 0.2.0 the native engine starts alongside the Flutter SDK on both platforms, even with no native host. A pure-Flutter app gains a native scope with native crash capture and CPU/memory vitals. Flutter telemetry is unchanged. #### Can the two layers use different service names? No. A different `serviceName` or `endpoint` on either side produces two separate services and no session unification. #### Does iOS need a separate native dependency? No. The iOS engine ships inside `scout_flutter` through the `scout-kotlin-multiplatform` Swift package. ### What's next - [Configure your collector](/instrument/collector-setup/docker-compose-example/) to receive OTLP-HTTP on `:4318` - Explore the data in [RUM](/operate/rum/getting-started) - both layers appear under the one session you just unified - Read the per-layer pages for the configuration options this page does not cover: [Android](/instrument/mobile/android), [iOS](/instrument/mobile/ios), and [Flutter](/instrument/mobile/flutter) - Read [RUM with OpenTelemetry](/instrument/mobile/rum-opentelemetry) if you need the span names and attributes behind those views ### References - scout_flutter repo: [github.com/base-14/scout-flutter](https://github.com/base-14/scout-flutter) - scout-kotlin-multiplatform repo: [github.com/base-14/scout-kotlin-multiplatform](https://github.com/base-14/scout-kotlin-multiplatform) - Flutter add-to-app: [docs.flutter.dev/add-to-app](https://docs.flutter.dev/add-to-app) - Android manifest `android:process`: [developer.android.com/guide/topics/manifest/activity-element#proc](https://developer.android.com/guide/topics/manifest/activity-element#proc) --- ## iOS Instrumentation - Native Swift RUM with scout-ios ## iOS Scout for iOS is a native Swift SDK that ships **zero-config OpenTelemetry RUM**. One `Scout.start(...)` call auto-captures the full Real User Monitoring event set — taps, screens, native crashes, app hangs, jank, startup, lifecycle, HTTP — and exports it as OTLP traces, metrics, and logs to a Scout collector. ```swift import ScoutKit Scout.start( serviceName: "my-app", endpoint: "https://otel.example.com" ) ``` That's the only code you write. The SDK is a thin Swift layer (`ScoutKit`) over a Kotlin/Native engine (`ScoutNative`) that does all the instrumentation — you import `ScoutKit` and call the `Scout` type it declares. :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What You Get | Capability | Signal | Mechanism | |---|---|---| | App startup | `app_startup` span + `app_vital` (`vital.name = fbc`) on first screen | Process-start nanos → first init | | Lifecycle | `app_lifecycle.changed` | `UIApplicationDidBecomeActive` / `DidEnterBackground` notifications; drives session foreground/background | | Screen views | `screen_view` span | `UIViewController.viewDidAppear` IMP swizzle; class name (last path component); container controllers (Nav / Tab / Split / Page) skipped | | Screen load | `screen_load` span | `viewDidLoad` → `viewDidAppear` timing via `CACurrentMediaTime` | | View session | `view_session` span | Time-on-screen, emitted on screen change | | Navigation vital | `app_vital` (`vital.name = inv`) | Tap → next-screen latency within 5 s | | Tap tracking | `user_interaction` span (`ui.type = tap`, target, x/y) | Non-consuming `UITapGestureRecognizer` on every key window; label resolved via hit-test accessibility label / identifier / button title / `UILabel`, then the deepest accessibility element, then a cleaned class name | | HTTP requests | `http.request` span with method, URL, status, duration | Global pass-through `NSURLProtocol`; times every request; skips the collector host to avoid loops; covers `URLSession` + Ktor/Darwin | | Distributed tracing | W3C `traceparent` header injected into requests to `firstPartyHosts` | The http span's trace/span id is propagated so backend spans join the same trace. First-party only — third-party hosts get no header | | Long task (UI hang) | `long_task` span | `CADisplayLink` on the main runloop; frame interval ≥ 100 ms | | Frozen frame | `frozen_frame` span | Same `CADisplayLink`; frame interval ≥ 700 ms | | App hang / ANR | `anr` span with a mach main-thread backtrace + breadcrumbs | `AppHangWatchdog` — a background-queue heartbeat to the main queue; fires once at threshold cross (default 5 s). MetricKit `MXHangDiagnostic` also → `anr` | | Native crashes | `native_crash` **and** `app_crash` spans with `crash.reason`, registers, mach exception, symbolicated callstack tree, binary images, breadcrumbs | KSCrash 2.x (all monitors: mach exception, signal, C++ exception, NSException, main-thread deadlock, user-reported). Drained on the next launch. MetricKit `MXCrashDiagnostic` also → `native_crash` | | Errors (handled) | `error` span | `Scout.reportError(...)` | | Memory (opt-in) | `process.memory.usage` gauge (`By`) | mach `task_info(TASK_VM_INFO)` `phys_footprint` — the value iOS jetsam charges against the per-app limit and that Xcode's memory gauge shows. Polled every `vitalsCollectionIntervalSeconds`. Off by default (`enableMemoryMetrics`) | | CPU (opt-in) | `process.cpu.usage` gauge | mach `thread_info` non-idle CPU sum. Off by default (`enableCpuMetrics`) | | Logs | OTLP logs | `Scout.log*()` | | Anonymous user id | `user.anonymous_id` on every span | UUID minted on first launch, persisted | ### Prerequisites | Requirement | Version | |---|---| | iOS deployment target | ≥ 13.0 | | Xcode | ≥ 15 (Swift tools 5.9) | | Swift Package Manager | Bundled with Xcode | ### Installation The iOS SDK is distributed via **Swift Package Manager** from the `scout-kotlin-multiplatform` repository. It exposes two products: `Scout` (the Swift `ScoutKit` layer — your public API) and `ScoutNative` (the Kotlin/Native engine, delivered as a hosted `xcframework`). Adding `Scout` pulls in `ScoutNative` transitively. Release tags are `ios-` — **not** semver — so pin by **revision**, not a version range: ```swift // Package.swift dependencies: [ .package( url: "https://github.com/base-14/scout-kotlin-multiplatform", revision: "ios-0.1.9" ) ], targets: [ .target( name: "MyApp", dependencies: [ .product(name: "Scout", package: "scout-kotlin-multiplatform") ] ) ] ``` In Xcode: **File → Add Package Dependencies…**, enter `https://github.com/base-14/scout-kotlin-multiplatform`, set the dependency rule to **Commit / Branch** = `ios-0.1.9`, and add the **Scout** library product. :::note The product you depend on is `Scout`, but the module you import is `ScoutKit`: ```swift import ScoutKit // not `import Scout` ``` `Scout` is the name of the Kotlin/Native engine framework inside `ScoutNative`. `import Scout` compiles, but it gives you the engine types (`ScoutEngine`, `ScoutConfig`) rather than the `Scout` entry point with `start(...)`, so the call in your app won't resolve. ::: ### Initialization Call `Scout.start(...)` once, as early as possible — in `application(_:didFinishLaunchingWithOptions:)` — so the crash handler is armed and cold-start timing is anchored: ```swift import ScoutKit import UIKit @main class AppDelegate: UIResponder, UIApplicationDelegate { func application( _ application: UIApplication, didFinishLaunchingWithOptions launchOptions: [UIApplication.LaunchOptionsKey: Any]? ) -> Bool { Scout.start( serviceName: "my-app", endpoint: "https://otel.example.com", headers: ["Authorization": "Bearer …"] ) return true } } ``` `start` is **idempotent** — a second call is a no-op for both the engine and the hang watchdog. #### Screen tracking in SwiftUI Screen tracking swizzles `UIViewController.viewDidAppear`, so a UIKit app gets screen names for free. A SwiftUI app is hosted inside a single `UIHostingController`, so the automatic name collapses to that one host. Set the name yourself at each navigation point: ```swift Scout.setScreen("Checkout") ``` The same applies to tap labels: give tappable views an `.accessibilityLabel(...)` or `.accessibilityIdentifier(...)` so `user_interaction` spans carry something friendlier than a class name. #### Setting user identity ```swift Scout.setUser(id: "user-123", attributes: [ "email": "jane@example.com", "plan": "pro", ]) // On logout: Scout.clearUser() ``` #### Setting session attributes ```swift Scout.setSessionAttributes(["tenant": "acme", "ab_bucket": "B"]) Scout.clearSessionAttributes() ``` They attach to every subsequent span, metric, and log for the rest of the session. ### Configuration `Scout.start(...)` takes its configuration as named parameters. Only `serviceName` and `endpoint` are required. #### Identity | Parameter | Type | Default | Description | |---|---|---|---| | `serviceName` | `String` | **(required)** | Logical app identifier. Used as `service.name`. Must be non-blank. | | `endpoint` | `String` | **(required)** | OTLP-HTTP collector URL. `/v1/traces`, `/v1/metrics`, `/v1/logs` are appended automatically. Must be non-blank. | | `serviceVersion` | `String?` | `nil` | Maps to `service.version`. | | `environment` | `String?` | `nil` | Deployment environment (e.g. `production`). | | `headers` | `[String: String]` | `[:]` | Extra HTTP headers on every OTLP export. Use for auth. | | `resourceAttributes` | `[String: String]` | `[:]` | Extra attributes merged into every signal's `Resource`. | #### Sessions | Parameter | Type | Default | Description | |---|---|---|---| | `sessionSampleRate` | `Double (0-100)` | `1.0` | Percent of sessions sampled — default **1%**. Decided once per session; a sampled session sends everything (spans, metrics, logs), an unsampled one sends nothing. | | `alwaysCaptureErrors` | `Bool` | `true` | Error / crash / ANR-class spans bypass `sessionSampleRate` and are always exported. | | `sessionTimeoutMinutes` | `Int` | `30` | Inactivity timeout before a new `session.id` is minted. | | `maxSessionDurationMinutes` | `Int` | `60` | Hard cap on session lifetime. | #### Network | Parameter | Type | Default | Description | |---|---|---|---| | `firstPartyHosts` | `[String]` | `[]` | Hosts that receive a W3C `traceparent` header for distributed tracing. Exact match or `*.host` wildcards. Empty = no propagation. | | `ignoreUrlPatterns` | `[String]` | `[]` | URL substrings excluded from HTTP tracking. | #### Thresholds | Parameter | Type | Default | Description | |---|---|---|---| | `anrThresholdMs` | `Double` | `5000` | Main-thread hang duration that fires an `anr` span (drives `AppHangWatchdog`). | | `longTaskThresholdMs` | `Int` | `100` | Frame interval that qualifies as a `long_task`. | | `frozenFrameThresholdMs` | `Int` | `700` | Frame interval that qualifies as a `frozen_frame`. | #### Batching & export (applies to spans, metrics, AND logs) | Parameter | Type | Default | Description | |---|---|---|---| | `exportIntervalSeconds` | `Int` | `30` | One export cadence for spans, metrics, and logs (coerced ≥ 1). | | `maxExportBatchSize` | `Int` | `512` | Max items per export batch, per signal. | | `maxQueueSize` | `Int` | `2048` | Max items buffered awaiting export; overflow is dropped. | | `maxRetries` | `Int` | `0` | Delivery attempts after a failed export. Default **0 = at-most-once**. | | `metricExportIntervalSeconds` | `Int` | `-1` | Metrics-only override of `exportIntervalSeconds`. Any value ≤ 0 means "inherit". | | `vitalsCollectionIntervalSeconds` | `Int` | `60` | How often memory / CPU gauges are polled (when enabled). | #### Per-metric switches The SDK ships **no metrics by default** — each gauge is opt-in. | Parameter | Default | Description | |---|---|---| | `enableMetrics` | `true` | Master switch for the metrics pipeline. Individual gauges still need their own switch below. | | `enableMemoryMetrics` | `false` | `process.memory.usage` gauge. | | `enableCpuMetrics` | `false` | `process.cpu.usage` gauge. | | `enableFrameMetrics` | `false` | Accepted for parity with Android, but iOS emits no frame gauge. Frame timing arrives as `long_task` / `frozen_frame` spans instead, governed by `enableJankTracking`. | #### Auto-instrumentation toggles Every auto-instrumentation can be turned off independently. Span and log instrumentation defaults to **on**; metric collection defaults to **off** (see [Per-metric switches](#per-metric-switches)). | Toggle | Default | What you lose when `false` | |---|---|---| | `enableScreenTracking` | `true` | `screen_view` / `screen_load` / `view_session` spans. | | `enableTapTracking` | `true` | All `user_interaction` spans. | | `enableHttpTracking` | `true` | `http.request` spans from the pass-through `NSURLProtocol`. | | `enableErrorTracking` | `true` | `error` spans — including manual `Scout.reportError(...)` calls, which become no-ops. | | `enableCrashReporting` | `true` | KSCrash native crash capture and the MetricKit subscriber. | | `enableAnrTracking` | `true` | `anr` spans from `AppHangWatchdog`. | | `enableJankTracking` | `true` | `long_task` / `frozen_frame` spans. | | `enableLifecycleTracking` | `true` | `app_lifecycle.changed` spans. | | `enableStartupTracking` | `true` | `app_startup` spans and the FBC vital. | | `enableLogging` | `true` | `Scout.log*()` calls become no-ops. | Crash reporting and hang detection are separate switches. Setting `enableCrashReporting = false` leaves `AppHangWatchdog` running, and setting `enableAnrTracking = false` leaves KSCrash installed. #### Offline buffer Offline buffering is **fully disabled by default** — nothing is written to disk, and a batch that fails to export is dropped (strict at-most-once delivery). | Parameter | Type | Default | Description | |---|---|---|---| | `offlineBufferEnabled` | `Bool` | `false` | Master toggle. Persist failed batches and replay them on the next launch. | | `maxOfflineStorageMb` | `Int` | `5` | Cap on the on-disk offline buffer. Once it is exceeded, the oldest persisted batches are pruned first (FIFO). Only active when `offlineBufferEnabled` is on. | When `offlineBufferEnabled` is on, the persisted queue is also bounded by `maxQueueSize` and `maxExportBatchSize` — the same limits the in-memory path uses. #### Diagnostics | Parameter | Type | Default | Description | |---|---|---|---| | `debugLogging` | `Bool` | `false` | Print SDK-internal export logging to the console. Use it to confirm batches are leaving the device; leave it off in release builds. | ### Native crash setup No app-side setup is required — KSCrash and the MetricKit subscriber install automatically when `enableCrashReporting` is on (the default). #### KSCrash On `start`, the engine installs **KSCrash 2.x** with all monitors: mach exceptions, POSIX signals, C++ exceptions, NSException, and main-thread deadlock. KSCrash writes reports out-of-process at crash time. On the **next launch**, Scout drains any persisted reports and emits **both** a `native_crash` span (full crash detail) and an `app_crash` span (`error.handled = false`, `error.source.type = ios`) — the latter is parity with Android's `app_crash`. Captured attributes include: - `crash.reason`, `crash.type`, `crash.signal` - `crash.registers_json` — full CPU register dump - `crash.mach_exception` / `crash.mach_code` / `crash.mach_subcode` - `crash.callstack_tree_json` — symbolicated stack tree of every thread - `crash.binary_images_json` — loaded image list for offline symbolication - The prior session's breadcrumb trail + last screen #### MetricKit An `MXMetricManagerSubscriber` (iOS 14+) collects asynchronous `MXCrashDiagnostic` (→ `native_crash`) and `MXHangDiagnostic` (→ `anr`) payloads Apple delivers the morning after — useful for kernel-killed crashes KSCrash couldn't intercept. #### App hangs `AppHangWatchdog` is a Swift-side heartbeat that detects a hung main thread and emits an `anr` span with a mach frame-pointer backtrace once the hang crosses `anrThresholdMs` (default 5 s). It is gated by `enableAnrTracking`, not `enableCrashReporting` — the two run independently. Because crashes drain on the **next** launch, to test: trigger a real fault (`fatalError()`, an out-of-bounds access — never `exit()`, which is graceful), relaunch the app, then check the collector. ### Manual API All methods are `static` on the `Scout` type. ```swift // Errors & logs Scout.reportError(error) // → `error` span Scout.logInfo("checkout started", attributes: ["cart.size": "3"]) Scout.logError("payment failed") Scout.logWarning("…"); Scout.logDebug("…") Scout.logEvent("promo_applied", attributes: ["code": "SAVE10"]) // Identity Scout.setUser(id: "user-123", attributes: ["plan": "pro"]) Scout.setUserAttributes(["role": "admin"]); Scout.clearUser() // Session / account / feature flags Scout.setSessionAttributes(["tenant": "acme"]); Scout.clearSessionAttributes() Scout.setAccount(id: "org-1", name: "Acme"); Scout.clearAccount() Scout.setFeatureFlag(name: "new_checkout", value: "true") Scout.clearFeatureFlags() // Screens & custom spans Scout.setScreen("Checkout") Scout.recordScreenLoad(name: "Checkout", durationMs: 320) Scout.recordViewSession(name: "Checkout", durationMs: 8400) Scout.recordSpan(name: "sync", durationMs: 120, attributes: ["items": "12"]) // Manual instrumentation // reportHttp also takes `responseSize:` (default -1) and // `errorMessage:` (default nil) between statusCode and the timestamps. Scout.reportHttp(method: "GET", url: "https://api…", statusCode: 200, startEpochNanos: t0, endEpochNanos: t1) // → `http.request` Scout.reportLongTask(durationMs: 180) // → `long_task` Scout.reportTap(target: "Buy", targetType: "Button", x: 40, y: 88) Scout.emitGauge(name: "queue.depth", value: 12, unit: "1") // Vitals / operations / breadcrumbs Scout.addTiming("first_paint") Scout.startVital("checkout"); Scout.endVital("checkout", description: "ok") Scout.recordOperationStep(name: "checkout", step: "payment") Scout.addBreadcrumb(type: "tap", message: "Buy") ``` ### What happens when export fails Delivery is **at-most-once by default** (`maxRetries: 0`): a batch gets one attempt, and a failed batch is dropped rather than risking a duplicate delivery. A retried timeout whose first request the collector already ingested would store the same events twice. A batch counts as delivered only on an HTTP 2xx. Any other status, or a transport exception, is a failure. | Failure | What Scout does (defaults) | |---|---| | Any export failure, `maxRetries: 0` (default) | One attempt; batch dropped. No duplicates, ever. | | `maxRetries: n` configured | Up to `n + 1` attempts total, retried back-to-back with no backoff. Duplicate risk on ambiguous failures. | | Failure with `offlineBufferEnabled: true` | Batch persisted to disk and replayed on a later launch. | | Queue overflow (`maxQueueSize`, default 2048) | Oldest items dropped before they are ever exported. | | Process dies mid-interval | Anything emitted since the last export is lost — there is no flush-on-background hook. Crash evidence is the exception: KSCrash writes it at crash time and Scout drains it on the next launch. | Set `debugLogging: true` to print each batch's destination and HTTP status to the console. ### Troubleshooting | Symptom | Likely cause + fix | |---|---| | `native_crash` not appearing after a crash | KSCrash writes asynchronously; the report drains on the *next* launch. Force-quit and relaunch, then check the collector. | | Crash button gives a graceful shutdown | You're calling `exit()`, which no crash reporter intercepts. Trigger a real fault (`fatalError()`, out-of-bounds access). | | `anr` never fires | The main thread genuinely isn't hanging, or `anrThresholdMs` is higher than your hang. Try a 6 s `Thread.sleep` on the main thread to confirm the watchdog is armed. | | Tap labels are class names like `ComposeCanvas` | The tapped surface is a single canvas view (SwiftUI/Compose) with no per-widget accessibility label. Add `.accessibilityLabel(...)` / `.accessibilityIdentifier(...)` to the tappable view. | | SPM can't resolve the package | Pin by `revision: "ios-0.1.9"` — the tags are not semver, so `from:` / `exact:` version rules won't match. | | HTTP spans missing for a custom session | The pass-through `NSURLProtocol` covers `URLSession.shared` and default configs; a session with a custom `protocolClasses` that omits it won't be traced. | | No telemetry at all | Set `debugLogging: true` to print export attempts and their HTTP status, then confirm the endpoint is reachable from the device. Remember the default `sessionSampleRate` is **1%**. | ### Performance considerations - **Unified 30 s batching.** Spans, metrics, and logs each flush once per `exportIntervalSeconds` (default 30 s). - **No metrics unless enabled.** The default configuration ships zero metric data points; the memory / CPU gauges are opt-ins. - **Zero disk usage by default.** Offline buffering is off; the only disk writes are crash evidence (KSCrash reports, breadcrumbs). - **Sampling.** `sessionSampleRate` drops *full sessions* — never individual events. ### Security considerations - **Custom headers for auth.** Pass `headers: ["Authorization": "Bearer …"]` — sent on every OTLP export. - **No `beforeSend` on this path.** The core `beforeSend` filter is not exposed as a `Scout.start(...)` parameter, so attribute scrubbing is not available to a pure-Swift app. Reaching it means driving the SDK from shared Kotlin — see [Kotlin Multiplatform](/instrument/mobile/kotlin-multiplatform). - **No telemetry-to-disk PII by default.** The offline buffer is off; crash reports contain register / stack detail, not app data. - **TLS.** Use an `https://` endpoint. ### FAQ #### What's the difference between `native_crash` and `app_crash`? iOS emits both for one crash: `native_crash` carries the full KSCrash detail (registers, mach exception, symbolicated tree), and `app_crash` is the cross-platform crash record (parity with Android). Dedupe in dashboards by crash fingerprint if you want a single row. #### Do I need to add ScoutNative separately? No — depending on the `Scout` product pulls the `ScoutNative` xcframework in transitively. #### Can I add custom spans, metrics, or logs? Yes — `recordSpan`, `emitGauge`, and `log*` are the manual entry points. ### What's next - [Configure your collector](/instrument/collector-setup/docker-compose-example/) to receive OTLP-HTTP on `:4318` - Instrument [Android](/instrument/mobile/android) for the Kotlin counterpart, or [Kotlin Multiplatform](/instrument/mobile/kotlin-multiplatform) to cover both from shared code - Ship [Flutter](/instrument/mobile/flutter) apps on the same backend ### References - scout-kotlin-multiplatform repo: [github.com/base-14/scout-kotlin-multiplatform](https://github.com/base-14/scout-kotlin-multiplatform) - KSCrash: [github.com/kstenerud/KSCrash](https://github.com/kstenerud/KSCrash) - Apple MetricKit: [developer.apple.com/documentation/metrickit](https://developer.apple.com/documentation/metrickit) --- ## Kotlin Multiplatform Instrumentation - RUM with scout-kmp ## Kotlin Multiplatform `scout-kmp` is the unified Kotlin Multiplatform entry point for Scout RUM. One `commonMain` call routes to the native `scout-android` and `scout-ios` engines, so a KMP app gets the full native Real User Monitoring event set on both platforms: taps, screens, crashes, ANR, jank, startup, lifecycle, and HTTP. ```kotlin import io.base14.scout.core.ScoutConfig import io.base14.scout.kmp.Scout Scout.initialize( ScoutConfig( serviceName = "my-app", endpoint = "https://otel.example.com", ), ) ``` That is the whole setup, in shared code — no Android `Context` argument to thread through. HTTP on Android is the one exception: it needs an OkHttp interceptor registered in `androidMain` (see [HTTP tracking](#http-tracking-on-android)). :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What You Get `scout-kmp` delegates to the platform SDKs, so you get the **same capabilities** documented for each platform, driven from common code: - **Android** — the full [scout-android](/instrument/mobile/android) set: Activity/Compose screens, taps, JVM + NDK crashes, `ApplicationExitInfo`, ANR, jank, startup, lifecycle, HTTP. - **iOS** — the [scout-ios](/instrument/mobile/ios) set: screens, taps, KSCrash native crashes, app hangs, jank, startup, lifecycle, HTTP, and MetricKit `MXCrashDiagnostic` / `MXHangDiagnostic` diagnostics. Every signal flows through the shared `scout-core` engine — the same sessions, sampling, batching, and OTLP export on both platforms. Each export additionally carries a `scout.kmp.version` resource attribute so you can tell KMP-originated telemetry apart. | Signal | Android | iOS | |---|---|---| | Screen / navigation (`screen_view`, `screen_load`, `view_session`) | ✓ | ✓ | | Tap tracking (`user_interaction`) | ✓ | ✓ | | App startup (`app_startup`) + FBC/INV vitals (`app_vital`) | ✓ | ✓ | | Lifecycle (`app_lifecycle.changed`) | ✓ | ✓ | | HTTP (`http.request`) | ✓ (add `ScoutOkHttpInterceptor`) | ✓ (automatic) | | Native crashes (`native_crash` / `app_crash`) | ✓ (NDK + ExitInfo) | ✓ (KSCrash) | | ANR (`anr`) | ✓ | ✓ | | Jank (`long_task`, `frozen_frame`) | ✓ | ✓ | | Errors (`error`) | ✓ | ✓ | | Memory / CPU gauges (opt-in) | ✓ | ✓ | | Frame gauge (opt-in) | ✓ (`android.frame.build_time`) | — (jank still arrives as `long_task` / `frozen_frame` spans) | | Logs | ✓ | ✓ | See the [Android](/instrument/mobile/android) and [iOS](/instrument/mobile/ios) docs for the exact span attributes and per-platform mechanisms. ### Prerequisites | Requirement | Version | |---|---| | Kotlin | 2.x (multiplatform) | | Android `minSdkVersion` | ≥ 26 | | Android `compileSdkVersion` | 35 | | iOS deployment target | ≥ 13.0 | | Targets | Android (via the AGP `androidLibrary` KMP plugin), `iosArm64`, `iosSimulatorArm64` | `scout-kmp` publishes `iosArm64` and `iosSimulatorArm64` only. There is no `iosX64` artifact, so the **Intel iOS simulator is unsupported** — on an Intel Mac the link step fails with no matching binary. ### Installation `scout-kmp` is published on Maven Central. Add it to your shared module's `commonMain`: ```kotlin // shared/build.gradle.kts kotlin { sourceSets { commonMain.dependencies { implementation("io.base14:scout-kmp:0.1.9") } } } ``` Make sure `mavenCentral()` is in your `dependencyResolutionManagement` repositories. `scout-kmp` pins and re-exports the platform SDKs transitively — you don't add them yourself: | Module | Version | Reaches your build as | |---|---|---| | `scout-core` | 0.1.7 | Maven artifact `io.base14:scout-core` | | `scout-android` | 0.1.7 | Maven artifact `io.base14:scout-android` | | `scout-ios` | 0.1.9 | Kotlin/Native klib, linked into your iOS framework | A pure-Swift app consumes `scout-ios` differently — as the `Scout` SPM package described in the [iOS](/instrument/mobile/ios) docs. Under KMP you never add it yourself. ### Initialization Call `Scout.initialize(config)` once from shared code, as early as possible in each platform's startup path (e.g. from a shared `initialize()` you invoke in Android's `Application.onCreate()` and the iOS app entry point). ```kotlin import io.base14.scout.core.ScoutConfig import io.base14.scout.kmp.Scout fun startTelemetry() { Scout.initialize( ScoutConfig( serviceName = "my-app", serviceVersion = "1.0.0", endpoint = "https://otel.example.com", headers = mapOf("Authorization" to "Bearer …"), ), ) } ``` **No Android `Context` argument.** On Android, `scout-kmp` captures the `Application` automatically via a `ContentProvider` (`ScoutInitProvider`) auto-registered in the library manifest, which runs before your app's `onCreate` — so `initialize` needs nothing platform-specific. On iOS it delegates straight to the native engine. Both platforms inject the `scout.kmp.version` resource attribute. #### HTTP tracking on Android Android HTTP tracking is opt-in and is the one piece of setup that does not live in `commonMain`. Register `ScoutOkHttpInterceptor` on the `OkHttpClient` in your `androidMain` source set: ```kotlin // androidMain import io.base14.scout.android.http.ScoutOkHttpInterceptor import okhttp3.OkHttpClient val client = OkHttpClient.Builder() .addInterceptor(ScoutOkHttpInterceptor()) .build() ``` The interceptor skips your collector endpoint and anything matching `ignoreUrlPatterns`, and injects a W3C `traceparent` on hosts listed in `firstPartyHosts`. On iOS nothing is required — the engine installs a pass-through `NSURLProtocol` that times every request automatically. #### Setting user identity & session attributes ```kotlin Scout.setUser(id = "user-123", attributes = mapOf("plan" to "pro")) Scout.clearUser() Scout.setSessionAttributes(mapOf("tenant" to "acme")) Scout.clearSessionAttributes() ``` ### Configuration `ScoutConfig` is the single shared config object (from `scout-core`). `serviceName` and `endpoint` are the only **required** fields. #### Identity | Field | Type | Default | Description | |---|---|---|---| | `serviceName` | `String` | **(required)** | Logical app identifier (`service.name`). Must be non-blank. | | `endpoint` | `String` | **(required)** | OTLP-HTTP collector URL. `/v1/traces`, `/v1/metrics`, `/v1/logs` are appended automatically. Must be non-blank. | | `serviceVersion` | `String?` | `null` | Maps to `service.version`. | | `environment` | `String?` | `null` | Deployment environment. | | `headers` | `Map` | `{}` | Extra HTTP headers on every OTLP export. Use for auth. | | `resourceAttributes` | `Map` | `{}` | Extra attributes merged into every signal's `Resource`. | #### Sessions | Field | Type | Default | Description | |---|---|---|---| | `sessionSampleRate` | `Double (0-100)` | `1.0` | Percent of sessions sampled — default **1%**. Decided once per session; a sampled session sends everything (spans, metrics, logs), an unsampled one sends nothing. | | `alwaysCaptureErrors` | `Boolean` | `true` | Error / crash / ANR-class spans bypass `sessionSampleRate` and are always exported. | | `sessionTimeoutMinutes` | `Int` | `30` | Inactivity timeout before a new session. | | `maxSessionDurationMinutes` | `Int` | `60` | Hard cap on session lifetime. | #### Network | Field | Type | Default | Description | |---|---|---|---| | `firstPartyHosts` | `List` | `[]` | Hosts that receive a W3C `traceparent`. Exact match or `*.host` wildcards. | | `ignoreUrlPatterns` | `List` | `[]` | URL substrings excluded from HTTP tracking. | #### Thresholds | Field | Type | Default | Description | |---|---|---|---| | `anrThresholdMs` | `Long` | `5000` | Main-thread block duration that fires an `anr` span. | | `longTaskThresholdMs` | `Long` | `100` | Frame duration that qualifies as a `long_task`. | | `frozenFrameThresholdMs` | `Long` | `700` | Frame duration that qualifies as a `frozen_frame`. | #### Batching & export (applies to spans, metrics, AND logs) | Field | Type | Default | Description | |---|---|---|---| | `exportIntervalSeconds` | `Int` | `30` | One export cadence for spans, metrics, and logs (coerced ≥ 1). | | `maxExportBatchSize` | `Int` | `512` | Max items per export batch, per signal. | | `maxQueueSize` | `Int` | `2048` | Max items buffered awaiting export; overflow dropped. | | `maxRetries` | `Int` | `0` | Delivery attempts after a failed export. Default **0 = at-most-once**. | | `metricExportIntervalSeconds` | `Int?` | `null` | Metrics-only override of `exportIntervalSeconds`. | | `vitalsCollectionIntervalSeconds` | `Int` | `60` | How often memory / CPU / frame gauges are polled (when enabled). | #### Per-metric switches The SDK ships **no metrics by default** — each gauge is opt-in. | Field | Default | Description | |---|---|---| | `enableMetrics` | `true` | Master switch for the metrics pipeline. Individual gauges still need their own switch below. | | `enableMemoryMetrics` | `false` | Memory gauge. | | `enableCpuMetrics` | `false` | CPU gauge. | | `enableFrameMetrics` | `false` | Frame gauge. Android only — iOS emits no frame gauge. | #### Auto-instrumentation toggles Every auto-instrumentation can be turned off independently. Span and log instrumentation defaults to **on**; metric collection defaults to **off** (see [Per-metric switches](#per-metric-switches)). | Toggle | Default | What you lose when `false` | |---|---|---| | `enableScreenTracking` | `true` | `screen_view` / `screen_load` / `view_session` spans. | | `enableTapTracking` | `true` | All `user_interaction` spans. | | `enableHttpTracking` | `true` | `http.request` spans on both platforms. | | `enableErrorTracking` | `true` | `error` spans — including manual `Scout.reportError(...)` calls, which become no-ops. | | `enableCrashTracking` | `true` | Android JVM + NDK crashes and iOS KSCrash capture. | | `enableAnrTracking` | `true` | `anr` spans on both platforms. | | `enableJankTracking` | `true` | `long_task` / `frozen_frame` spans. | | `enableLifecycleTracking` | `true` | `app_lifecycle.changed` spans and the session foreground/background transitions they drive. | | `enableStartupTracking` | `true` | `app_startup` spans and the FBC vital. | | `enableLogging` | `true` | `Scout.log*()` calls become no-ops. | #### Offline buffer Disabled by default (strict at-most-once). `offlineBufferEnabled` (`false`) is the master toggle. When the buffer is on, `maxOfflineStorageMb` (`5`) caps the on-disk buffer — once the cap is exceeded the oldest persisted batches are pruned first (FIFO) — and the persisted queue is additionally bounded by `maxQueueSize` and `maxExportBatchSize`. #### Diagnostics | Field | Type | Default | Description | |---|---|---|---| | `debugLogging` | `Boolean` | `false` | Print SDK-internal export logging to the platform console. Use it to confirm batches are leaving the device; leave it off in release builds. | #### Filtering — `beforeSend` ```kotlin ScoutConfig( // … beforeSend = { name, attributes -> // Return false to drop the signal; mutate attributes for scrubbing. attributes.remove("user.email") true }, ) ``` Runs synchronously on every span / metric / log before export; sees per-signal attributes only (not resource attributes). ### Native crash setup Crash capture is on by default (`enableCrashTracking`) and needs no app-side setup on either platform: - **Android** — JVM `app_crash` (uncaught handler, replayed next launch), NDK `native_crash` (signal handler), and `ApplicationExitInfo` fallback (API 30+). - **iOS** — KSCrash emits both `native_crash` and `app_crash`, drained on the next launch. On both platforms crashes are persisted at crash time and **exported on the next launch** — to test, trigger a real fault, relaunch, then check the collector. See the platform docs for the full attribute set. ### Manual API The common `Scout` object exposes the same manual API on every platform (a no-op before `initialize`): | Method | Purpose | |---|---| | `setScreen(name)` | Set the current screen / view name. | | `setUser(id)` / `setUser(id, attributes)` / `setUserAttributes(attributes)` / `clearUser()` | User identity. | | `setSessionAttributes(attributes)` / `clearSessionAttributes()` | Session attributes. | | `setAccount(id, name)` / `clearAccount()` | Account / org context. | | `setFeatureFlag(name, value)` / `clearFeatureFlags()` | Feature-flag values. | | `reportError(throwable)` | Report a handled exception (`error` span). | | `reportError(type, message, stackTrace)` | Report an error from string fields. | | `logInfo / logWarning / logError / logDebug(message)` (+ `logInfo(message, attributes)`) | Emit a log. | | `logEvent(name)` / `logEvent(name, attributes)` | Emit a named custom event. | | `addTiming(name)` | Record a named timing marker. | | `startVital(name)` / `endVital(name, description)` | Custom vital measurement. | | `recordOperationStep(name, step, key, failureReason)` | Step in a multi-step operation. | | `reportHttp(method, url, statusCode, startEpochNanos, endEpochNanos)` | Manually emit an `http.request` span. | | `reportLongTask(durationMs)` | Manually emit a `long_task` span. | | `reportTap(target, targetType, x, y)` | Manually emit a `user_interaction` span. | | `emitGauge(name, value, unit)` | Emit a custom gauge metric. | | `recordScreenLoad(name, durationMs)` / `recordViewSession(name, durationMs)` | Timing spans. | | `recordSpan(name, durationMs, attributes)` | Emit an arbitrary named span. | | `addBreadcrumb(type, message)` | Add a breadcrumb. | ### What happens when export fails Both platforms share `scout-core`'s exporter, so the behaviour is identical on Android and iOS. Delivery is **at-most-once by default** (`maxRetries = 0`): a batch gets one attempt, and a failed batch is dropped rather than risking a duplicate delivery. A batch counts as delivered only on an HTTP 2xx. Any other status, or a transport exception, is a failure. | Failure | What Scout does (defaults) | |---|---| | Any export failure, `maxRetries = 0` (default) | One attempt; batch dropped. No duplicates, ever. | | `maxRetries = n` configured | Up to `n + 1` attempts total, retried back-to-back with no backoff. Duplicate risk on ambiguous failures. | | Failure with `offlineBufferEnabled = true` | Batch persisted to disk and replayed on a later launch. | | Queue overflow (`maxQueueSize`, default 2048) | Oldest items dropped before they are ever exported. | | Process dies mid-interval | Anything emitted since the last export is lost — there is no flush-on-background hook. Crash evidence is the exception: it is persisted at crash time and replayed on the next launch. | Set `debugLogging = true` to print each batch's destination and HTTP status to the platform console. ### Troubleshooting | Symptom | Likely cause + fix | |---|---| | No telemetry on Android | Confirm `initialize` runs early (the `ScoutInitProvider` captures the `Application` before `onCreate`, but `initialize` itself must still be called). | | No `http.request` spans on Android | Android HTTP is opt-in — add `ScoutOkHttpInterceptor` to your `OkHttpClient`. iOS HTTP is automatic. | | Crashes not appearing | They drain on the *next* launch on both platforms. Relaunch, then check the collector. | | Telemetry hard to distinguish from native SDK data | KMP exports carry a `scout.kmp.version` resource attribute — filter on it. | | No telemetry at all | Set `debugLogging = true` to print export attempts and their HTTP status, then confirm the endpoint is reachable from the device. Remember the default `sessionSampleRate` is **1%**. | ### Performance considerations - **Unified 30 s batching.** Spans, metrics, and logs each flush once per `exportIntervalSeconds` (default 30 s), on both platforms. - **No metrics unless enabled.** The default configuration ships zero metric data points; the memory, CPU, and frame gauges are opt-ins. - **Zero disk usage by default.** Offline buffering is off; the only disk writes are crash evidence. - **Sampling.** `sessionSampleRate` drops *full sessions* — never individual events — so session traces stay coherent. - **Idempotent init.** `Scout.initialize` is a no-op once the SDK is running, on both platforms. ### Security considerations - **PII scrubbing.** Use `beforeSend` to mutate attributes (`attributes.remove("user.email")`) or drop signals (return `false`). It runs in shared code, so one filter covers both platforms. - **Custom headers for auth.** Pass `headers = mapOf("Authorization" to "Bearer …")`. - **No telemetry-to-disk PII by default.** The offline buffer is off; when enabled, scrub in `beforeSend` before batches hit disk. - **TLS.** Use an `https://` endpoint. ### FAQ #### Do I need to add `scout-android` and `scout-ios` separately? No. `scout-kmp` depends on them with `api(...)`, so both come in transitively at the versions listed under [Installation](#installation). #### Does the iOS side go through `ScoutKit`? No. `scout-kmp` calls the Kotlin engine (`ScoutEngine`) directly rather than the Swift `Scout.start(...)` entry point. KSCrash still installs, ANR detection still runs — from the Kotlin watchdog, gated by `enableAnrTracking`, instead of the Swift `AppHangWatchdog` — and the engine subscribes to MetricKit, so Apple's asynchronous `MXCrashDiagnostic` / `MXHangDiagnostic` payloads are collected. The full [iOS](/instrument/mobile/ios) capability table applies. #### How do I track screens in a Compose Multiplatform app? Call `Scout.setScreen("Checkout")` from shared code at each navigation point. The automatic trackers key off platform view containers (Activities on Android, `UIViewController` on iOS), and a Compose Multiplatform app presents one host container per platform — so automatic screen names collapse to that single host. #### Can I still use the platform-specific APIs? Yes. The common `Scout` object exposes the cross-platform surface; from `androidMain` you can call `io.base14.scout.android.Scout` directly for Android-only helpers such as `NavController.trackScoutScreens()` and `setBreadcrumbs(...)`, which have no common equivalent. #### How do I tell KMP telemetry apart from native SDK telemetry? Every export carries a `scout.kmp.version` resource attribute. Filter on it. ### What's next - [Configure your collector](/instrument/collector-setup/docker-compose-example/) to receive OTLP-HTTP on `:4318` - Read the [Android](/instrument/mobile/android) and [iOS](/instrument/mobile/ios) docs for per-platform attribute detail - Ship [Flutter](/instrument/mobile/flutter) apps on the same backend ### References - scout-kotlin-multiplatform repo: [github.com/base-14/scout-kotlin-multiplatform](https://github.com/base-14/scout-kotlin-multiplatform) --- ## React Native OpenTelemetry Instrumentation - Mobile RUM and Crash Reporting ## React Native + React Web `@base-14/scout-react` is a single npm package that ships **zero-config OpenTelemetry RUM** for three runtimes: | Runtime | Entry import | Native bridge required? | |---|---|---| | **React Native (iOS + Android)** | `import Scout from '@base-14/scout-react/native'` | Yes — Expo module (auto-linked) | | **React (web)** | `import Scout from '@base-14/scout-react'` | No | | **React-on-web hooks** | `import { ScoutErrorBoundary } from '@base-14/scout-react/react'` | No | The SDK auto-captures the full Real User Monitoring (RUM) event set (except Session Replay and Profiling) and exports it as OTLP traces, metrics, and logs to a Scout collector. No manual `Scout.track(...)` calls anywhere in your app — every tap, navigation, HTTP request, error, crash, scroll, and frame metric is gathered automatically. :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### What You Get | Capability | Signal Shape | Mechanism | |---|---|---| | Tap / press tracking | `user_interaction` span (`type=tap`, target, name_source, permanent_id, x/y) | Babel plugin wraps every `onPress` at build time | | Web click tracking | `user_interaction` span (`type=click`, target.selector, composed_path_selector, width/height) | `document.addEventListener('click', …, capture)` | | Frustration signals | `user_interaction.action.frustration.type` (`rage_click`, `dead_click`, `error_click`) | DOM mutation observer + error correlation (web only) | | Screen / page navigation | `screen_view` ROOT span with `view.id`, `view.loading_type`, `view.referrer`, `view.is_active`, per-view counters | `@react-navigation` integration + `history` listener (web) | | HTTP requests | `http.request` span with method / url / status / duration / size / provider classification / GraphQL parse | Wraps `fetch` + `XMLHttpRequest` globally | | Errors | `error` span with `error.id`, `fingerprint`, `handling`, `source`, `causes_json`, `time_since_app_start_ms`, breadcrumbs | `ErrorUtils.setGlobalHandler` (RN) + `window.onerror` + `unhandledrejection` | | Native crashes (iOS) | `native_crash` span with FAR/ESR registers, mach_exception, signal, NSException, callstack tree, binary images | KSCrash 2.5+ + MetricKit subscriber | | Native crashes (Android) | `native_crash` span with NDK signal info, tombstone, ApplicationExitInfo subreason, PSS/RSS | Custom NDK signal handler (`scout_signal_handler.c`) + `ApplicationExitInfo` (API 30+) + JVM uncaught handler | | Frame metrics (RN) | `react_native.frame.refresh_rate`, `slow_frames_rate`, `freeze_rate`, `frozen_frame` spans | rAF-based polling loop + `view.slow_frames_json` | | Long tasks | `long_task` span with `id`, `duration`, `threshold` | `PerformanceObserver('longtask')` (web) + main-thread polling (RN) | | ANRs (with thread dumps) | `anr` span with `duration`, `threshold`, `source_thread` (`main`/`js`), `main_thread_stack`, `threads_json`, `thread_count`, breadcrumbs | Native `ScoutAnrWatchdog` on a dedicated background thread tracks both main-thread (Looper / `DispatchQueue.main`) **and** JS-thread heartbeats. On Android captures `Thread.getAllStackTraces()` (32 KB / 64 frames-per-thread cap); on iOS captures the main thread via Mach `thread_suspend` + frame-pointer walking + `dladdr()` symbolication | | iOS UI hang | `ui_hang` span with `duration`, `threshold`, `main_thread_stack`, breadcrumbs | `AppHangWatchdog` `CFRunLoop` heartbeat at the configured `iosHangThresholdMs` (default 250 ms — sub-ANR) | | `screen_load` span | `screen.name`, `screen.load_time` (seconds), `view.loading_time_ms` | Emitted on every React Navigation transition; backs per-screen Avg/P95 Load Time dashboard panels | | Screen attribution on every span | `screen.name` stamped via `Scout.commonAttributes()` on every span/metric | `Scout.setCurrentScreen(name)` called by the built-in route trackers; reads via `getCurrentScreen()` | | Session attributes | `setSessionAttributes({ … })` stamps arbitrary key-value pairs on every subsequent span/metric/log until cleared | In-memory map merged into `Scout.commonAttributes()` | | CPU usage gauge | `react_native.cpu.usage` (percent) | Periodic 10 s sampling — Android reads `/proc//stat` ticks via wall-clock delta; iOS sums `cpu_usage` across task threads via Mach `thread_basic_info` | | Device orientation | `device.orientation` runtime attribute (`portrait`/`landscape`) | Auto-updated on `Dimensions.change` | | Jailbreak / root detection | `device.is_jail_broken` resource attribute (`"true"`/`"false"`) | Path probes — `/Applications/Cydia.app` etc. on iOS, `Build.TAGS=test-keys` + su-binary + Magisk packages on Android | | Battery discharge rate (Android) | `device.battery.discharge_rate` runtime attribute (µA, sampled every 60 s) | `BatteryManager.BATTERY_PROPERTY_CURRENT_NOW` | | NDK build-id (Android) | `ndk.build_id` resource attribute (40-char SHA1) | Parses `.note.gnu.build-id` ELF section from `libscout_signal_handler.so` (works whether the `.so` is extracted to `nativeLibraryDir` or loaded directly from inside the APK) | | `app_crash` + `native_crash` carry the crashed session | `crash.previous_session_id`, `crash.session_started_at`, `crash.last_screen` | Persisted across the crash boundary via the marker file (`app_crash`), NDK signal-handler globals (Android `native_crash`), and `KSCrash.userInfo` (iOS `native_crash`) | | Scroll depth | `display.scroll.max_depth`, `max_depth_scroll_top`, `max_scroll_height`, `max_scroll_height_time_ms` on `screen_view` | `RN.ScrollView` lazy-getter wrap (RN) + `window.scroll` listener (web) | | Web vitals | `web_vital` span with `name`, `value`, `rating` (LCP, INP, CLS, FCP, TTFB) | `web-vitals` library on web | | CSP violations | `error` span with `error.csp.violated_directive`, `blocked_uri`, `disposition` | `securitypolicyviolation` event listener (web) | | Page lifecycle | `view.page_states_json`, `view.in_foreground_periods_json` | `visibilitychange` + `freeze`/`resume` events (web), `AppState` (RN) | | Session management | `session.id` UUID, `session.type: user`, `user.anonymous_id` persisted across sessions | AsyncStorage (RN) / localStorage (web) | | Resource attributes | `service.*`, `device.*`, `os.*`, `network.*`, `a11y.*` (~20 a11y flags), `screen.*`, `viewport.*`, `application.current_locale` | Collected at init | | Configurable batching | `traceExportIntervalMs`, `traceMaxQueueSize`, `traceMaxExportBatchSize`, `logExportScheduledDelayMs`, `metricExportIntervalMs`, `exportTimeoutMs` | OTel `BatchSpanProcessor` config | | Retry with backoff | Exponential backoff + full jitter on network errors / 408 / 429 / 5xx; default 3 retries, 1s initial, 30s cap | Custom `wrapWithRetry` exporter wrapper | | On-disk offline buffer | Persists retry-exhausted batches to AsyncStorage / localStorage; replays on init + on resume / online / `visibilitychange=visible` | Per-signal item caps (`offlineBuffer.maxItems.{traces,metrics,logs}`) | | Background flush | Force-flush all in-flight batches on `AppState=background` / `visibilitychange=hidden` / `pagehide` | Lifecycle hook calls `Scout.flush()` | ### Prerequisites - **React Native 0.74+** (Hermes recommended) for RN apps, or **React 18+** for web - **Node 20 or 22** (for SDK build / Metro) - **Xcode 15+** + CocoaPods for iOS, **Android Studio** + NDK r25+ for Android - **Scout Collector** reachable from your app — see [Docker Compose Setup](/instrument/collector-setup/docker-compose-example/) for local dev #### Compatibility Matrix | Component | Minimum | Recommended | |---|---|---| | React | 18.0 | 18.3+ | | React Native | 0.74 | 0.76+ | | Expo SDK (if using) | 51 | 53+ | | Node (build) | 20 | 22 | | iOS deployment target | 13.0 | 16.0+ | | Android `minSdkVersion` | 24 (Android 7.0) | 31+ (Android 12+) for ApplicationExitInfo | | `@react-navigation/native` (optional, for screen tracking) | 6.0 | 6.1+ | ### Installation ```bash npm install @base-14/scout-react ``` For React Native apps with the bare workflow: ```bash cd ios && pod install && cd .. ``` For Expo workflow no extra step — the Expo module auto-links on `prebuild`. #### Upgrading ```bash npm install @base-14/scout-react@latest ``` Or pin to a specific version: ```bash npm install @base-14/scout-react@0.1.11 ``` #### Babel plugin (React Native only) Tap tracking on React Native uses a Babel plugin that wraps every `onPress` prop at compile time. Add it to `babel.config.js`: ```js title="babel.config.js" module.exports = function (api) { api.cache(true); return { presets: ['babel-preset-expo'], plugins: ['@base-14/scout-react/babel-plugin'], }; }; ``` The plugin transforms: ```jsx ``` into: ```jsx { if (typeof globalThis.__scoutTap === 'function') { globalThis.__scoutTap({ componentName: 'Pressable', accessibilityLabel: 'Buy now', testID: undefined, children: undefined, }, $scoutArgs); } return handleTap && handleTap.apply(this, $scoutArgs); }} accessibilityLabel="Buy now" /> ``` This runs **before** any other JSX transform, so it catches every `Pressable`, `TouchableOpacity`, `TouchableHighlight`, `TouchableWithoutFeedback`, `TouchableNativeFeedback`, and `Button` regardless of how they're imported. ### Initialization #### React Native ```ts title="index.js" import Scout from '@base-14/scout-react/native'; import App from './App'; await Scout.initialize({ serviceName: 'my-app', endpoint: 'http://localhost:34318', serviceVersion: '1.0.0', }); Scout.registerRootComponent(App); ``` `registerRootComponent` is a drop-in replacement for Expo's `registerRootComponent` (or RN's `AppRegistry.registerComponent`). It wraps your root tree with `ScoutRootBoundary` so render errors become `error` spans automatically. #### Navigation tracking (React Native) Attach `@react-navigation`'s ref in `onReady`: ```tsx title="App.tsx" import { NavigationContainer, useNavigationContainerRef } from '@react-navigation/native'; export default function App() { const navRef = useNavigationContainerRef(); return ( Scout.attachNavigationContainer(navRef)} > {/* … */} ); } ``` The SDK buffers the navigationRef if `attachNavigationContainer` is called before `Scout.initialize` resolves, and installs the tracker once init completes — safe to call from `onReady` regardless of init timing. #### Web ```tsx title="main.tsx" import Scout from '@base-14/scout-react'; import { ScoutErrorBoundary } from '@base-14/scout-react/react'; import { BrowserRouter } from 'react-router-dom'; import { createRoot } from 'react-dom/client'; import App from './App'; await Scout.initialize({ serviceName: 'my-app', endpoint: 'https://otel.example.com', }); createRoot(document.getElementById('root')!).render( , ); ``` #### SSR-aware initialization For any setup where the same React tree renders both server-side (SSR / SSG) and in the browser — Next.js, Remix, Astro, Gatsby, Docusaurus — `Scout.initialize()` must run only in the browser. The SDK depends on `window`, `document`, and `localStorage`, all of which are absent during SSR build time. Two common patterns: **`useEffect`-gated (Next.js client component, Remix client-only, etc.):** ```tsx 'use client'; import { useEffect } from 'react'; import Scout from '@base-14/scout-react'; let initialized = false; export function ScoutBootstrap() { useEffect(() => { if (initialized) return; initialized = true; void Scout.initialize({ serviceName: 'my-web-app', endpoint: 'https://rum.example.com//otlp', secure: true, headers: { Authorization: `Bearer ${process.env.NEXT_PUBLIC_SCOUT_TOKEN}` }, captureConsole: true, }); }, []); return null; } ``` Render `` once at the root of your app. **`typeof window !== 'undefined'` guard (any framework, top-level module):** ```ts title="src/scout-client.ts" import Scout from '@base-14/scout-react'; let initialized = false; if (typeof window !== 'undefined' && !initialized) { initialized = true; void Scout.initialize({ serviceName: 'my-web-app', endpoint: 'https://rum.example.com//otlp', secure: true, headers: { Authorization: `Bearer ${YOUR_TOKEN}` }, captureConsole: true, }); } ``` Import this module once from your client entry (Vite `main.tsx`, CRA `index.tsx`, Next.js `app/layout.tsx`, Docusaurus `clientModules`, etc.). The `!initialized` flag is a belt-and-braces idempotency check — bundlers and HMR sometimes re-evaluate top-level modules, and you don't want a second Scout instance attached. ### Configuration Every option you can pass to `Scout.initialize()`: #### Identity | Field | Type | Default | Description | |---|---|---|---| | `serviceName` | `string` | **required** | `service.name` resource attribute | | `endpoint` | `string` | **required** | OTLP-HTTP collector URL (suffixes `/v1/{traces,metrics,logs}` appended automatically) | | `serviceVersion` | `string` | `'1.0.0'` | `service.version` | | `applicationId` | `string?` | — | Maps to `application.id` | | `buildId` | `string?` | — | Build hash; maps to `app.build_id` | | `secure` | `boolean` | `true` | Prefix `https://` when scheme is missing | #### Transport | Field | Type | Default | Description | |---|---|---|---| | `headers` | `Record` | `{}` | Extra HTTP headers (auth tokens, tenant IDs) | | `firstPartyHosts` | `Array` | `[]` | Hosts that get a `traceparent` injected for distributed tracing | | `ignoreUrlPatterns` | `RegExp[]` | `[]` | URLs matching these are not auto-instrumented | #### Batching | Field | Type | Default | Description | |---|---|---|---| | `traceExportIntervalMs` | `number` | `5000` | Trace flush interval | | `traceMaxQueueSize` | `number` | `2048` | Max spans buffered before drop | | `traceMaxExportBatchSize` | `number` | `512` | Max spans per HTTP POST | | `metricExportIntervalMs` | `number` | `30000` | Metric reader interval | | `logExportScheduledDelayMs` | `number` | `5000` | Log flush interval | | `logMaxQueueSize` | `number` | `2048` | | | `logMaxExportBatchSize` | `number` | `512` | | | `exportTimeoutMs` | `number` | `30000` | Per-export HTTP timeout | #### Retry + Offline | Field | Type | Default | Description | |---|---|---|---| | `exportRetry.maxRetries` | `number` | `3` | Retries per batch on retryable failures (5xx / 408 / 429 / network). `0` disables. | | `exportRetry.initialDelayMs` | `number` | `1000` | First retry backoff | | `exportRetry.maxDelayMs` | `number` | `30000` | Cap on exponential backoff | | `offlineBuffer.enabled` | `boolean` | `true` | Persist retry-exhausted batches to disk | | `offlineBuffer.maxItems.traces` | `number` | `5000` | FIFO item cap | | `offlineBuffer.maxItems.metrics` | `number` | `2000` | | | `offlineBuffer.maxItems.logs` | `number` | `5000` | | | `maxOfflineStorageMb` | `number` | `5` | Coarse total-disk cap that runs alongside the per-signal item caps. Lower priority than `offlineBuffer.maxItems.*`. | #### Sessions | Field | Type | Default | Description | |---|---|---|---| | `sessionTimeoutMinutes` | `number` | `30` | Inactivity before new session | | `sessionSampleRate` | `number (0-100)` | `1` | Per-session binary sampling rate. Default is `1` (1% of sessions) to bound telemetry volume for production. Error / crash / ANR / UI-hang spans bypass this gate (controlled by `alwaysCaptureErrors`) so failures are always captured regardless of sampling. Below `100`, full sessions are dropped (never partial) so traces stay coherent. | #### Thresholds | Field | Type | Default | Min | Description | |---|---|---|---|---| | `longTaskThresholdMs` | `number` | `100` | `20` | JS task duration that qualifies as a `long_task` span. Below `20` is clamped up. | | `anrThresholdMs` | `number` | `5000` | `1000` | Main-thread / JS-thread block duration that fires an `anr` span. Below `1000` is clamped up. Watchdog polls every `threshold/10` ms (min 200 ms). | | `iosHangThresholdMs` | `number` | `250` | `50` | iOS-only sub-ANR threshold that fires a `ui_hang` span. Set to `0` to disable. Catches micro-stutters (tap → 300 ms freeze → recover) that the 5 s ANR threshold misses. | | `maxTombstoneBytes` | `number` | `131072` | `4096` | Android-only cap on `crash.tombstone` payload size for `ApplicationExitInfo` crashes. Some tombstones are multi-MB; this prevents span-payload bloat. | #### Resource attributes | Field | Type | Description | |---|---|---| | `resourceAttributes` | `Record` | Extra attrs merged into every signal's `Resource` block (e.g. `deployment.region`, `team`). Static — set once at init, never re-evaluated. | #### Auto-instrumentation toggles Every auto-instrumentation can be turned off independently. **All default to `true`** except `captureConsole` / `capturePrintStatements`. | Toggle | Default | What you lose when set to `false` | |---|---|---| | `enableAutoTapTracking` | `true` | All `user_interaction` spans (taps on RN, clicks on web). Babel-plugin compile-time wrap still runs but the runtime hook is inert. | | `enableErrorTracking` | `true` | `error` spans from `FlutterError.onError` / `window.onerror` / `unhandledrejection` / `ErrorUtils.setGlobalHandler`. Manual `Scout.reportError(…)` still works. | | `enableLifecycleTracking` | `true` | `app_paused`/`app_resumed` spans, background flush, screen_view ROOT span end on background. Heavy loss — recommend leaving on. | | `enableStartupTracking` | `true` | `app_startup` span (cold + warm start measurement). | | `enableConnectivityTracking` | `true` | `network.connection.type`, `network.cellular.carrier_name` resource attrs and changes on network transitions. | | `enablePerformanceMetrics` | `true` | `react_native.memory.usage` metric, generic perf samples. | | `enableLongTaskDetection` | `true` | `long_task` spans (use `longTaskThresholdMs` to tune sensitivity instead of disabling). | | `enableAnrDetection` | `true` | `anr` spans, iOS hang watchdog, Android ANR detector. | | `enableFrameMetrics` | `true` | `react_native.frame.refresh_rate` / `slow_frames_rate` / `freeze_rate` metrics + `frozen_frame` spans + `view.slow_frames_json` attribute. | | `enableMemoryMetrics` | `true` | RN-only process memory polling. | | `enableCpuMetrics` | `true` | `react_native.cpu.usage` gauge. Android reads `/proc//stat` and computes percentage via wall-clock delta; iOS uses Mach `thread_info` summed across all task threads. Sampled every 10 s. | | `enableWebVitals` | `true` | Web-only LCP / INP / CLS / FCP / TTFB spans. | | `enableBatteryTracking` | `true` | `device.battery.level` / `device.battery.state` on every span. | | `enableNetworkTracking` | `true` | `http.request` spans, fetch/XHR wrap, GraphQL parse, provider classification, `traceparent` injection. | | `enableLogging` | `true` | `Scout.log*()` calls become no-ops (or the OTel log pipeline never gets created). | | `captureConsole` | `false` | (Off by default) When true, mirrors `console.log/info/warn/error/debug` to OTLP logs. Original `console` output is preserved. | | `capturePrintStatements` | `false` | Alias of `captureConsole` for Flutter-flavored naming consistency. | #### Filtering | Field | Type | Description | |---|---|---| | `beforeSend` | `(event) => event \| null` | Runs on every span / metric / log before export. Return `null` to drop. Mutate the passed object to redact PII. **Sees per-span attributes only; resource attributes set on the OTel `Resource` (e.g. `service.name`, `os.name`, `device.*`) are not in the event payload.** | ### Identifying the user and setting custom attributes Once `Scout.initialize(...)` has resolved you can attach identity, account, feature-flag, and free-form attributes that **ride on every subsequent span, metric, and log** until you change or clear them. Five APIs cover the common cases: #### `Scout.setUser(id, attributes?)` — end-user identity ```ts Scout.setUser('user-123', { email: 'jane@example.com', name: 'Jane Doe', plan: 'pro', signupDate: '2025-08-14', }); ``` Maps to OpenTelemetry semantic-convention attributes — `user.id` is the primary key; everything else in the `attributes` map is prefixed `user.` so it lands as `user.email`, `user.plan`, etc. Errors and crashes captured after this call carry these attributes automatically — your dashboard can filter "errors for users on plan=pro." #### `Scout.setAccount(id, name?)` — B2B tenant ```ts Scout.setAccount('acme-corp', 'Acme Corp'); ``` For multi-tenant apps. Emits `account.id` and (optionally) `account.name`. Useful for grouping sessions by tenant in dashboards. #### `Scout.setFeatureFlag(name, value)` — flag values at error time ```ts Scout.setFeatureFlag('new-checkout', true); Scout.setFeatureFlag('checkout-variant', 'B'); ``` Each flag becomes a `feature_flag.` attribute. The killer use case: when an error span is emitted, the flag values **active at error time** are attached to it, so you can correlate "this crash only happens when `new-checkout=true`." #### `Scout.setSessionAttributes(attrs)` — session-scoped attribute bag ```ts Scout.setSessionAttributes({ 'tenant.id': 'acme', 'tenant.plan': 'enterprise', 'build.flavor': 'play', }); ``` A simple key-value map merged into `commonAttributes()` on every span, metric, and log. Survives session rotations until you call `Scout.clearSessionAttributes()`. Use for stable integrator-supplied context that isn't a user identity (tenant id, deployment region, build flavor, A/B test cohort). Mirrors `scout-flutter`'s `ScoutFlutter.setSessionAttributes`. #### `Scout.setRuntimeAttribute(key, value)` — free-form session attribute This is the general-purpose hook for any custom attribute you want on every signal in this session — A/B experiments, app theme, route prefix, current locale, anything that doesn't fit the named APIs above. ```ts Scout.setRuntimeAttribute('experiment.cohort', 'B'); Scout.setRuntimeAttribute('app.theme', 'dark'); Scout.setRuntimeAttribute('subscription.tier', 'pro'); ``` The key is used verbatim as the attribute name — no namespacing — so you control the schema. Supported value types: `string`, `number`, `boolean`, or arrays of those. #### `Scout.addBreadcrumb(type, message)` — action trail (not an attribute, related) Not strictly an attribute, but related: every breadcrumb you record lands in a ring buffer that gets serialized onto every subsequent `error` / `app_crash` / `native_crash` span. Useful for "what did the user do in the 20 actions before this crash?" ```ts Scout.addBreadcrumb('checkout', 'added item to cart'); Scout.addBreadcrumb('navigation', 'screen: /payment'); ``` #### Removing attributes | To remove | Call | |---|---| | The user identity (and all `user.*` attributes) | `Scout.clearUser()` | | The B2B account identity | `Scout.clearAccount()` | | A single feature flag | `Scout.setFeatureFlag(name, null)` | | All feature flags at once | `Scout.clearFeatureFlags()` | | All session attributes | `Scout.clearSessionAttributes()` | | A single runtime attribute | `Scout.setRuntimeAttribute(key, null)` (`null` or `undefined` deletes the key) | | All breadcrumbs (rarely needed) | They roll out of the ring buffer naturally; no explicit clear | A typical sign-out flow: ```ts async function signOut() { await api.signOut(); Scout.clearUser(); Scout.clearAccount(); Scout.clearFeatureFlags(); Scout.setRuntimeAttribute('experiment.cohort', null); } ``` #### Lifetime and persistence These attributes live in memory for the SDK instance — i.e., **for the lifetime of the session**. They are NOT persisted across app restarts. If you want a user identity to be reattached on every launch, call `Scout.setUser(...)` again in your initialization code (typically inside a `useEffect` that re-reads from your auth store). The OpenTelemetry session lifecycle (the `session.id` resource attribute) rotates after `sessionTimeoutMinutes` of inactivity (default 30 min) — but user / account / runtime attributes you set survive that rotation as long as the JS context is alive. ### Native crash setup #### iOS (KSCrash + MetricKit) The Expo module auto-installs **KSCrash 2.5+** with all five monitors: - Mach exceptions - POSIX signals - C++ exceptions - NSExceptions - Main-thread deadlocks Plus a **MetricKit** subscriber that collects delayed crash + hang diagnostic payloads the OS delivers asynchronously, up to 24 h after the event. On the next launch after a crash, both pipelines drain into the same `native_crash` span with full attribute coverage: ```text crash.type: mach | signal | nsexception | cppexception crash.reason: EXC_BREAKPOINT crash.mach_exception: EXC_BREAKPOINT crash.mach_code: KERN_INVALID_ADDRESS crash.signal: SIGTRAP crash.signal_code: 0 crash.cpu_arch: arm64 crash.os_name: iOS crash.os_version: 17.5 crash.kernel_version: Darwin Kernel Version 24.5.0... crash.device_model: iPhone17,2 crash.machine: arm64e crash.build_type: debug crash.report_id: 04446A8C-65BC-486C-A7CD-F7A65DAB797B crash.bundle_id: io.base14.example crash.app_id: io.base14.example (alias of crash.bundle_id) crash.app_version: 1.4.2 (build 412) crash.stack_trace: libswiftCore.dylib 0x… $ss17_assertionFailure… crash.registers_json: { "basic": { "pc": …, "lr": …, "sp": …, "fp": …, "x0": …, …, "x29": … }, "exception": { "far": …, "esr": …, "exception": 0 } } crash.binary_images_json: [ { "name": …, "uuid": …, "image_addr": …, … }, … ] crash.callstack_tree_json: [ { "thread_id": …, "crashed": true, "backtrace": … }, … ] ``` The **FAR** (Fault Address Register) and **ESR** (Exception Syndrome Register) values are the gold standard for ARM64 fault diagnosis — they tell the backend exactly what memory access caused the fault. #### Android (NDK signal handler + ApplicationExitInfo) The plugin ships: - A **custom NDK signal handler** in `android/src/main/cpp/scout_signal_handler.c` that catches `SIGSEGV` / `SIGABRT` / `SIGBUS` / `SIGFPE` / `SIGILL` / `SIGTRAP` and writes a JSON report to disk before re-raising. - A **JVM uncaught exception handler** for Kotlin / Java crashes. - An **`ApplicationExitInfo` collector** (Android 11 / API 30+) that drains every historical process death reason — including ANRs, OOM kills, low-memory kills, user force-stops — with tombstone payload and (on API 31+, via reflection) the `subReason` int. Resulting attributes: ```text crash.type: native_crash | jvm_exception | anr | low_memory | … crash.reason: signal name or exception message crash.signal: SIGSEGV (signal source only) crash.signal_code: SEGV_MAPERR crash.signal_address: 0x0 crash.tombstone: (truncated to 32 KB) full Android tombstone text crash.subreason: 12 (e.g. SUBREASON_TOO_MANY_EMPTY) crash.exit_status: 139 crash.importance: 300 crash.pss_kb: 125440 crash.rss_kb: 145200 crash.death_timestamp_ms: 1747469392458 crash.process_name: com.example.myapp crash.pid / .tid / .uid crash.abi: arm64-v8a crash.build_fingerprint: google/sdk_gphone64_arm64/... crash.kernel: Linux version 5.15.… crash.process_uptime_secs: 847 crash.last_screen: OrderDetailScreen crash.pc / .lr / .fp / .sp (NDK arm64 register snapshot) crash.exception_register: x16: 0x… x17: 0x… (NDK arm64; PAC/BTI diagnosis) crash.registers / .memory_map (NDK path only) ``` ### Native ANR detection with thread dumps The SDK runs a native watchdog on a dedicated background thread that tracks **two heartbeats** independently — the native main thread (Android `Looper.getMainLooper()` / iOS `DispatchQueue.main`) **and** the JS thread (via a periodic `notifyJsAlive()` call from JS at `anrThresholdMs / 5` intervals). If either is silent past `anrThresholdMs`, the watchdog fires immediately while the thread is still blocked — captures the dump, ships it via a native event (`ScoutAnr`), and JS attaches it to an `anr` span when it processes the event. This is critical for React Native: a pure-JS busy loop blocks the JS thread but the Android UI thread keeps responding, so the OS-level ANR never fires. The watchdog's JS-thread heartbeat fills that gap. Attributes on the `anr` span: ```text anr.duration: 5.391 (seconds) anr.threshold: 5.0 anr.source_thread: js (or "main") anr.thread_count: 44 anr.main_thread_stack: "android.os.MessageQueue.nativePollOnce ..." anr.threads_json: [{"name":"main", "state":"RUNNABLE", "frames":[…]}, …] (~25 KB) breadcrumbs: [] screen.name: "Profile" ``` #### Implementation per platform - **Android** — `ScoutAnrWatchdog.kt` on a `HandlerThread`; posts heartbeat runnables to the main `Looper`; `ScoutThreadDumpCollector` serializes every thread via `Thread.getAllStackTraces()` capped at 32 KB / 64 frames per thread. - **iOS** — `AppHangWatchdog.swift` runs two tiers — `ui_hang` at `iosHangThresholdMs` (default 250 ms), `anr` at `anrThresholdMs` (default 5000 ms). `ScoutThreadBacktrace.swift` captures the main thread via Mach `thread_suspend` + `thread_get_state` + FP/LR frame walking + `dladdr()` symbolication, arm64 + x86_64. #### Testing it from the example diagnostics panel The Expo example (`examples/platform-design-mobile`) ships six test buttons that exercise the SDK's failure-mode paths: | Button | Triggers | Expected span | |---|---|---| | **anr (JS thread, 6s freeze)** | `while (Date.now() < end) {}` on JS thread | `anr` with `source_thread=js` | | **anr (UI thread, 6s freeze)** | `ScoutCrash.__debugBlockMainThread(6000)` blocks the Android UI thread / iOS main thread for 6s | `anr` with `source_thread=main` | | **anr (JS thread, 12s long freeze)** | Same as JS freeze, longer duration | `anr` with `duration ≈ 12s` | | **ui_hang (UI thread, 500ms)** | iOS-only — 500 ms main-thread block triggers `AppHangWatchdog` at default 250 ms threshold | `ui_hang` (iOS only) | | **manual breadcrumb** | `Scout.addBreadcrumb('manual', '')` | breadcrumb in the next captured span's trail | | **log info / warn / error** | `Scout.logInfo(…)` / `logWarning(…)` / `logError(…)` | three OTel log records | ### React Native lifecycle integration The SDK installs an `AppState` listener that: 1. **On `background` / `inactive`** — ends the active `screen_view` ROOT span (so its decorated `display.scroll.*`, `view.slow_frames_json`, `view.page_states_json` attrs flush), emits an `app_paused` span, and force-flushes every batch processor so taps emitted in the last few seconds don't die with the OS suspending the process. 2. **On `active`** — rotates session if inactivity timeout elapsed, restarts the `screen_view` ROOT for the current route (so spans after resume are properly parented), emits `app_resumed`, drains the offline buffer. The fire-and-forget initialization means `Scout.initialize()` never blocks the host UI even if the collector is unreachable or init internally throws — the host app renders normally and telemetry just no-ops. ### What happens when export fails Three layers of resilience, in order: 1. **Retry with jitter**: `wrapWithRetry` wraps every OTLP exporter. On a retryable failure (network error / 408 / 429 / 5xx), the batch is re-sent after exponential backoff with full jitter (configurable via `exportRetry`). Permanent 4xx failures (400 / 401 / 403) drop immediately so we don't waste retries. 2. **On-disk offline buffer**: after `maxRetries` exhausts, the batch is serialized to OTLP-compliant JSON via `@opentelemetry/otlp-transformer` and persisted to AsyncStorage (RN) / localStorage (web) under per-signal keys. Per-signal FIFO caps (`offlineBuffer.maxItems`) bound storage. 3. **Replay on next opportunity**: persisted batches are drained when: - `Scout.initialize()` resolves - On RN, `AppState` transitions to `active` - On web, `visibilitychange → visible` or `online` fires The replay POSTs each batch directly via `fetch` (using your configured `headers` so auth still applies) and stops on the first failure, leaving the remaining batches on disk for the next attempt. What's still lost: - Process killed before a batch is even queued (very rare). - Disk write fails (`QuotaExceededError` on web, sandbox issues on RN) — the batch is silently dropped. - Storage cap is hit during a long outage — oldest items evict first; your most-recent telemetry survives. ### Running the example app The repo ships a runnable Expo example at `examples/platform-design-mobile`. Its `package.json` depends on the published SDK (`"@base-14/scout-react": "^0.1.11"`): ```bash git clone https://github.com/base-14/scout-react.git cd scout-react/examples/platform-design-mobile npm install # iOS sim npx expo run:ios # Android emulator / device npx expo run:android ``` Tap around — every interaction generates spans. The example points at `http://localhost:34318` by default; edit `App.tsx` if your collector lives elsewhere. For Android, also run `adb reverse tcp:34318 tcp:34318` so the emulator can reach the collector on the host. ### Troubleshooting | Symptom | Likely cause | Fix | |---|---|---| | Bundle JS error: `globalThis.__scoutTap?.call is not a function` | Babel plugin not picked up by Metro cache | Restart Metro with `--clear` | | Taps captured as `target: "pressable"` / `target.type: "Component"` with same `permanent_id` every time | The responder system is intercepting at the wrong layer | Make sure the babel plugin is in `babel.config.js` (not just the deprecated runtime patch) | | `scout_anonymous_id` not present | First launch; `AsyncStorage` write failed silently | Verify file system permissions; check device storage isn't full | | No `screen_view` spans | `attachNavigationContainer(navRef)` never called | Add it to `NavigationContainer.onReady` | | No `display.scroll.*` attrs | App was on the same screen when backgrounded (root span never ended) | The bg-flush hook ends it on background; otherwise navigate to flush | | iOS sim: `Failed to load script` red box | `adb reverse`-style port forwarding missing | iOS sim shares host network — no extra step needed; check Metro on port 8081 | | Android: `localhost` unreachable from app | Android emulator doesn't share host network like iOS sim | `adb reverse tcp:8081 tcp:8081` and `adb reverse tcp:34318 tcp:34318` | | `dist/` not found inside `node_modules/@base-14/scout-react` | Corrupt install, partial download | `rm -rf node_modules package-lock.json && npm install` | | Web: `Scout.flush()` doesn't drain anything | Page already navigated; service worker may be intercepting | Use `pagehide` listener (already wired internally) | ### Performance considerations - **Tap spans**: ~0.5 ms per tap (synchronous fiber walk for descriptor extraction, async OTLP queue). - **Span size**: ~5 KB per scout-react span average — ~3-5× the typical backend span because of rich RUM context (battery, network, a11y, device, session, enduser, screen). - **Default trace flush**: 5 s — at 100 spans/s a busy app generates ~500 KB/flush. Tune `traceExportIntervalMs` + `traceMaxExportBatchSize` for your traffic shape. - **Offline buffer**: default 5000 trace items ≈ 25 MB worst case on disk. Drop to `traces: 2000` (10 MB) for low-end Android. - **Babel plugin overhead**: zero runtime cost — the wrapping happens at compile time. ### Security considerations - **PII redaction**: use the `beforeSend` callback to scrub fields before export: ```ts beforeSend: (event) => { delete event['user.email']; delete event['http.url']; // if it contains tokens in query string return event; } ``` - **No silent SDK failure logging in production**: `Scout.initialize()` rejections are silently caught by the example app's fire-and-forget pattern. Don't propagate them to the user-facing error UI. - **Headers contain credentials**: anything you pass in `headers` (e.g. Authorization Bearer tokens) is replayed on offline-buffer drain too. Use short-lived tokens or rotate frequently. - **Anonymous user ID is persistent**: stored in `${ApplicationDocuments}/scout_anonymous_id` (RN) or `localStorage` (web). Clear it on logout if your use case requires it. ### FAQ #### Does scroll tracking work on FlatList? Yes. The SDK patches `RN.ScrollView`'s lazy getter at module load — since `FlatList → VirtualizedList → ScrollView`, every list's `onScroll` flows through the same observer. Custom `ScrollView` subclasses you don't pull from `react-native` won't be tracked. #### Will the babel plugin break my existing `onPress` handlers? No. The plugin's wrapper preserves `this` binding, forwards all arguments, returns the original handler's return value, and uses a `typeof === 'function'` guard so the call short-circuits cleanly when the SDK isn't loaded. #### What if I'm on React Native 0.71 (old architecture)? Mostly fine. The babel plugin works on any React/Babel version >= 7. The `ScrollView` lazy-getter patch relies on RN's `react-native/index.js` using lazy `get`-based exports — this has been the case since RN 0.60. KSCrash 2.5+ requires iOS 13.0 minimum. #### Can I use this with React Navigation v6 AND v7? Yes. The integration depends only on `NavigationContainerRef`'s `addListener('state', fn)` API which is stable across both major versions. ### What's next - [Configure your collector](/instrument/collector-setup/docker-compose-example/) to receive OTLP-HTTP on `:4318` - Look at [Flutter mobile instrumentation](/instrument/mobile/flutter) for the Dart equivalent - Read the [React web guide](/instrument/apps/auto-instrumentation/react/) if you are instrumenting a browser app with the same SDK - [Query your RUM data in Scout](/operate/rum/getting-started/) once sessions, crashes, and screen performance are flowing ### References - Repository: [github.com/base-14/scout-react](https://github.com/base-14/scout-react) - OpenTelemetry JS SDK: [opentelemetry-js](https://github.com/open-telemetry/opentelemetry-js) - KSCrash: [kstenerud/KSCrash](https://github.com/kstenerud/KSCrash) - MetricKit overview: [Apple Developer docs](https://developer.apple.com/documentation/metrickit) - ApplicationExitInfo: [Android Developer docs](https://developer.android.com/reference/android/app/ApplicationExitInfo) --- ## Sending RUM Data to base14 - OpenTelemetry Integration Guide ## Sending RUM Data to base14 This is a data-model reference for sending mobile [RUM](../../operate/rum/getting-started.md) telemetry to base14 Scout. Use it when you build your own instrumentation (rather than using a prebuilt SDK like [scout_flutter](./flutter.md)) and need to know exactly which spans and attributes each RUM view expects. RUM data is plain OpenTelemetry: every value is a standard resource or span attribute, so it lines up with any traces and logs you already send to Scout. Each RUM feature is powered by a span with a specific `span.name` and a specific set of attributes - get the names and attribute placement right and the corresponding view populates automatically. --- :::note Running this in production Storing and querying these sessions at production volume is what base14 Scout does. [Check out Scout RUM](https://base14.io/scout/rum). ::: ### Transport | Setting | Value | | ------- | ----- | | **Protocol** | OTLP - traces sent to `.../v1/traces` | | **Endpoint** | The OTLP URL base14 provides for your account, e.g. `https://rum..base14.io//otlp` | | **Auth** | `Authorization: Bearer ` header (base14 provisions the token) | --- ### Identity and Attribute Placement Read this section before wiring up any spans - most integration problems come from putting an attribute on the wrong scope, or letting an identity value drift between builds. #### `service.name` is fixed `service.name` is a **resource** attribute and is your app's identity in base14. Agree the value with base14 and keep it **constant** across builds and environments. Use `service.version` for build axes and `environment` for deployment axes - never encode those into `service.name`, or your data fragments into many "apps". #### `[R]` resource vs `[S]` span Throughout this guide: - **`[R]`** marks a **resource** attribute - set once per export on the OpenTelemetry `Resource`. - **`[S]`** marks a **span** attribute - set per span. Putting a span key on the resource (or vice versa) is the most common reason a view comes up empty. #### Duration units are not uniform Most durations are in **seconds**, but app startup is in **milliseconds**. | Attribute | Unit | | --------- | ---- | | `screen.load_time` | seconds | | `view.time_spent` | seconds | | `long_task.duration` | seconds | | `anr.duration` | seconds | | `app_startup.duration` | **milliseconds** | :::warning `app_startup.duration` is the one exception - it is in milliseconds. Sending it in seconds makes every startup look ~1000x too fast. ::: --- ### Shared Attribute Sets To avoid repeating the same lists on every span, this guide refers to two shared sets. #### Standard resource set `[R]` Unless a span says otherwise, it carries these resource attributes: ```text service.name, service.version, environment, os.name, os.version, device.manufacturer, device.model.name, network.connection.type ``` Crash-related spans (`error`, `native_crash`, `app_crash`) add: ```text host.arch, app.version, app.build, app.bundle_id ``` #### Standard session identity `[S]` Unless a span says otherwise, it carries this identity block: ```text session.id, session.start_time, session.sampled, session.sample_rate, session.type, user.id, user.anonymous_id, screen.name ``` - `session.start_time` - ISO-8601; constant for the session's whole life. - `user.id` / `user.anonymous_id` - send at least one. The crash **Affected Users** panel is populated from these, so set them on crash spans too. --- ### Spans Each span is recognized by its **exact** `span.name`. All RUM spans use `SpanKind = Internal`. #### `screen_view` A screen or route was shown. - **Resource:** standard set - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `view.id` | Unique id for this view instance | | `view.loading_type` | `initial_load` or `route_change` | | `view.is_active` | Whether the view is currently active | | `view.referrer` | The previous screen/route | **Powers:** screen list and per-screen stats, session screen counts, active users. #### `screen_load` Time to display a screen. - **Resource:** standard set - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `screen.load_time` | Load time in **seconds** (float) | **Powers:** average and p95 screen-load time per screen. #### `view_session` Time spent on a screen. Emit when leaving it. - **Resource:** standard set - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `view.time_spent` | Time on screen in **seconds** (float) | **Powers:** average time-spent per screen. #### `long_task` A main-thread block / jank event. - **Resource:** standard set - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `long_task.duration` | Block duration in **seconds** | | `long_task.threshold` | Threshold that classified it, in **seconds** | | `display.scroll.max_depth` | Max scroll depth reached | | `display.scroll.max_depth_scroll_top` | Scroll-top at max depth | | `display.scroll.max_scroll_height` | Max scrollable height | | `display.scroll.max_scroll_height_time_ms` | Time to reach max height (ms) | **Powers:** long-task counts per screen; session timeline. #### `http.request` A network request. :::warning Span name and dual keys The span name must be exactly `http.request` (not `http`), or no network data is recorded. Send **both** keys in each pair below with the **same value** - different views read different names. Request latency is taken from the span's own start/end time, so set those correctly. ::: - **Resource:** standard set - **Span:** standard identity, plus: | Attribute(s) | Description | | ------------ | ----------- | | `url.full` **and** `http.url` | Full URL (same value in both) | | `http.request.method` **and** `http.method` | Method (same value in both) | | `http.response.status_code` **and** `http.status_code` | Status (same value in both) | | `http.duration_ms` | Latency in ms | | `http.response.body.size` | Response body size | | `http.error` | Error flag/message, if the request failed | **Powers:** network dashboard (top endpoints, error rate, latency p50/p95/p99); session timeline. #### `app_startup` A cold or warm start. - **Resource:** standard set - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `app_startup.type` | `cold` or `warm` | | `app_startup.duration` | Startup time in **milliseconds** (not seconds) | **Powers:** average cold/warm start, cold/warm counts. #### `error` A handled or unhandled error (JS / Dart / app-level). `app_crash` is treated as the same `javascript` kind as `error` and shares this attribute set (grouped by `error.message`). - **Resource:** standard set **+ crash additions** - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `error.message` | Title and grouping key - keep it **stable** (no timestamps/ids) | | `error.type` | Error type/class | | `error.stack_trace` | Full stack trace | | `error.handled` | Whether the error was caught | | `error.library` | Library/framework that raised it | | `breadcrumbs` | JSON array of `{time, type, message}` | | `dart.build_id` | Dart build id (for symbol resolution) | **Powers:** crash list, crash detail, crash-free rate, per-user error counts. #### `native_crash` A native crash (signal / Mach / exit-info / JVM). Grouped and addressed by `(crash.type, crash.reason)`. - **Resource:** standard set **+ crash additions** - **Span:** standard identity, plus the crash keys and detail below. **Crash keys (grouping):** | Attribute | Description | | --------- | ----------- | | `crash.type` | Grouping key | | `crash.reason` | Grouping key / title | | `crash.stack_trace` | Native stack trace | **Crash detail** (send what the platform provides): | Group | Attributes | | ----- | ---------- | | Report / identity | `crash.timestamp`, `crash.report_id`, `crash.last_screen`, `crash.previous_session_id`, `crash.started_at`, `crash.status`, `crash.error_type`, `crash.subreason` | | Signal / Mach (Apple) | `crash.signal`, `crash.signal_code`, `crash.signal_address`, `crash.mach_exception`, `crash.mach_code`, `crash.mach_subcode`, `crash.nsexception_name`, `crash.exception_type`, `crash.exception_code`, `crash.cpp_exception_name`, `crash.fault_address_register`, `crash.exception_syndrome_register`, `crash.os_reason_code`, `crash.os_reason_name` | | Thread / process | `crash.thread`, `crash.thread_name`, `crash.process_name`, `crash.queue`, `crash.pid`, `crash.tid`, `crash.uid`, `crash.ppid`, `crash.process_uptime_secs`, `crash.importance` | | Memory | `crash.pss_kb`, `crash.rss_kb`, `crash.hang_duration_ms` | | Device / OS / build | `crash.cpu_arch`, `crash.machine`, `crash.os_name`, `crash.os_version`, `crash.kernel_version`, `crash.kernel`, `crash.device_model`, `crash.abi`, `crash.build_fingerprint`, `crash.build_type`, `crash.region_format` | | App version | `crash.app_version`, `crash.application_version`, `crash.application_build_version`, `crash.bundle_id` | | Android exit-info | `crash.exit_status`, `crash.death_timestamp_ms` | | Heavy blobs (raw JSON / text) | `crash.tombstone`, `crash.binary_images_json`, `crash.registers_json`, `crash.callstack_tree_json`, `crash.memory_map`, `crash.registers` | | Breadcrumbs | `breadcrumbs` - JSON array of `{time, type, message}` | **Powers:** native crash list and detail, crash-free rate, affected devices/users, frequency over time, top crashing screens, post-crash recovery flag. #### `app_crash` An app-level crash. Handled together with `error` (the `javascript` crash kind), grouped by `error.message`. - **Resource:** standard set **+ crash additions** - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `error.message` | Title and grouping key - keep it **stable** | | `crash.type` | Crash type | | `crash.last_screen` | Screen active when the crash occurred | #### `anr` Application Not Responding (Android). Grouped and scoped by `screen.name`. - **Resource:** standard set - **Span:** standard identity, plus: | Attribute | Description | | --------- | ----------- | | `anr.duration` | ANR duration in **seconds** | | `anr.threshold` | Threshold that classified it, in **seconds** | | `anr.main_thread_stack` | Main-thread stack at the freeze | | `anr.thread_count` | Number of threads captured | | `anr.threads_json` | All-threads dump (JSON) | **Powers:** ANR list/detail, ANR duration by app-version/OS/device. #### `user_interaction` A tap/click, for the session timeline. - **Resource:** `service.name`, `environment`, `os.name`, `device.model.name` - **Span:** `session.id`, `session.start_time`, `user.id`, `user.anonymous_id`, `screen.name`, plus: | Attribute | Description | | --------- | ----------- | | `user_interaction.target` | Tapped element's label (mobile) | | `user_interaction.target.type` | Element type | | `target_element` | Tapped element (web) | | `target_xpath` | Element xpath (web) | | `user_interaction.type` | e.g. `tap` | | `user_interaction.target.name_source` | Source of the target's name | | `user_interaction.target.permanent_id` | Stable element id | | `user_interaction.target.x` / `.y` | Tap coordinates | | `user_interaction.id` | Unique id for the interaction | **Powers:** session timeline (tap events). #### `app_vital` FBC / interaction-to-next-view vitals, for the session timeline. - **Resource:** `service.name`, `environment`, `os.name` - **Span:** `session.id`, `session.start_time`, `user.id`, `user.anonymous_id`, `screen.name`, plus: | Attribute | Description | | --------- | ----------- | | `vital.name` | e.g. `fbc`, `inv` | | `vital.type` | `startup` or `navigation` | | `vital.duration_ms` | Duration in ms | | `vital.from_screen` | Source screen | | `vital.to_screen` | Destination screen | **Powers:** session timeline (vitals). #### `frozen_frame` A frozen frame, for the session timeline. - **Span:** `session.id`, `session.start_time`, `user.id`, `user.anonymous_id`, `screen.name`, plus: | Attribute | Description | | --------- | ----------- | | `frozen_frame.duration` | Frozen-frame duration | **Powers:** session timeline. #### `web_vital` Core Web Vitals (web), for the session timeline. - **Span:** `session.id`, `session.start_time`, `user.id`, `user.anonymous_id`, plus: | Attribute | Description | | --------- | ----------- | | `web.vital.name` | Vital name (e.g. LCP, CLS) | | `web.vital.value` | Measured value | | `web.vital.rating` | Rating bucket (good / needs-improvement / poor) | **Powers:** session timeline. --- ### Minimum Viable Payload To get RUM working with the smallest possible surface: **On every export (resource):** ```text service.name, environment, service.version, os.name, os.version, device.model.name, device.manufacturer, network.connection.type ``` **On every span:** ```text session.id, session.start_time, session.sampled user.id or user.anonymous_id ``` Mirror the user identity onto crash spans so **Affected Users** counts work. **Emit at least these spans:** - `screen_view` - with `screen.name` - `app_startup` - with `app_startup.type` and `app_startup.duration` (ms) - `http.request` - with span duration set and the HTTP key pairs from [`http.request`](#httprequest) - `error` and/or `native_crash` - with a stable `error.message` / `crash.reason` Add `screen_load`, `view_session`, `long_task`, and `anr` for full screen-performance and stability coverage. --- ### Common Mistakes | Symptom | Cause and fix | | ------- | ------------- | | Data fragments into many "apps" | A changing `service.name` per build/env. Keep it fixed; use `environment` / `service.version` for those axes. | | A view is empty | Resource keys on the span, or span keys on the resource. `service.version` / `os.*` / `device.*` are `[R]`; `session.*` / `user.*` / `screen.name` / per-span fields are `[S]`. | | Crash **Affected Users** empty | The panel reads `user.id` / `user.anonymous_id`. Set them on crash spans too. | | Every startup looks ~1000x too fast | `app_startup.duration` sent in seconds - it must be **milliseconds**. | | No network data / partial network views | Only one HTTP naming convention sent. Send both `url.full` + `http.url`, `http.request.method` + `http.method`, `http.response.status_code` + `http.status_code`, and set the span's own duration. | | Crashes don't group (one row each) | Unstable `error.message` / `crash.reason` containing timestamps or ids. Keep titles stable. | | No network data at all | Span named `http` instead of `http.request`. | | Session never registers | Missing or unparseable `session.start_time`. Send valid ISO-8601. | --- ### Related Guides - [RUM Overview](../../operate/rum/overview.md) - the product these spans power - [Instrument a Flutter app](./flutter.md) - a prebuilt SDK that emits all of the above - [Sessions](../../operate/rum/sessions.md) - how session-timeline spans render - [Crashes](../../operate/rum/crashes.md) - how crash spans render --- ## OpenTelemetry-Native Observability Platform ## Introduction Scout provides comprehensive observability capabilities through a fully Cloud-native and OpenTelemetry-native platform. ### Key Features - **Unified Data Collection**: Collect all telemetry signals (logs, metrics, traces) through a single OpenTelemetry pipeline - **Real-time Monitoring**: Monitor your applications and infrastructure with near real-time visibility - **Distributed Tracing**: Track requests across service boundaries with detailed trace visualization - **Metrics Analysis**: Analyze system and application metrics with powerful querying and visualization - **Automated Instrumentation**: Leverage OpenTelemetry auto-instrumentation for popular frameworks and libraries - **Custom Instrumentation**: Flexibility to add custom instrumentation for business-specific telemetry ### Architecture Benefits ![Scout OTel Native Architecture](/img/scout-architecture-v3.svg) - Native OpenTelemetry support ensures future-proof observability - Scalable collection and processing of telemetry data - Efficient storage optimized for different signal types - Correlation between logs, metrics, and traces - Built-in support for service maps and dependency analysis ### Getting Started Let's setup **Scout in less than 5 minutes**. We will follow the steps below: 1. **Install the Scout Collector**: The Scout Collector is a vendor-agnostic implementation of the OpenTelemetry specification. It can receive, process, and export telemetry data. You can install it using Docker, Kubernetes, or directly on your machine. The installation method will depend on your environment and preferences. - [Docker Compose](./instrument/collector-setup/docker-compose-example) - [OpenTelemetry Operator](./instrument/collector-setup/opentelemetry-operator-setup.md) \- Recommended setup for Kubernetes deployment - [Linux](./instrument/collector-setup/linux-setup) - [Using Otel Binary](./instrument/collector-setup/otel-collector-binary-example.md) 2. **Configure the Scout Collector**: Step 1 should help you get started with a collector that can receive, process, and export telemetry data. For advanced configurations, you can refer to [detailed Scout Collector configuration guide](./instrument/collector-setup/otel-collector-co